Search Results: "ed"

26 November 2024

Sandro Knau : Akademy 2024 in W rzburg

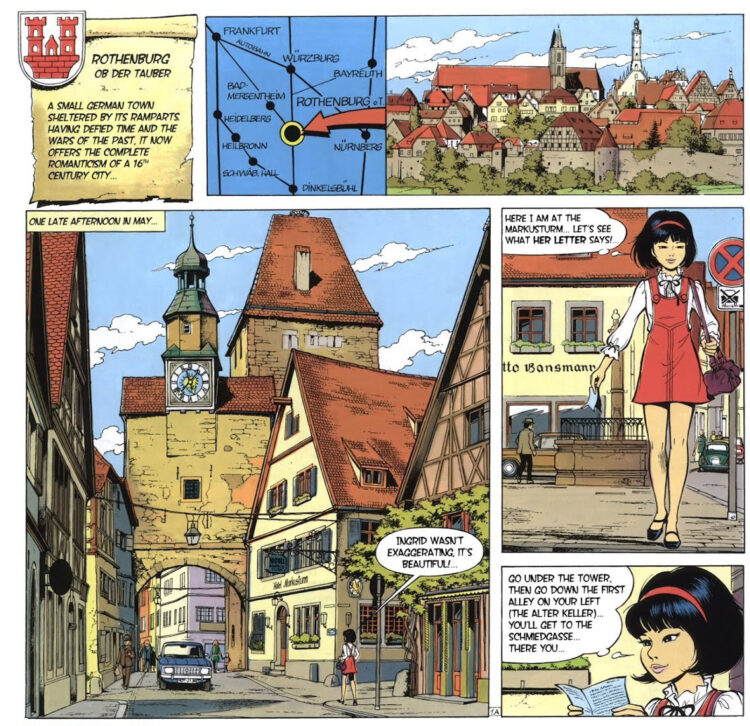
In order to prepare for the Akademy I started some days before to give my Librem 5 ( an Open Hardware Phone) another try and ended up with a non starting Plasma 6. Actually this issue was known already, but hasn't been addressed. In the end I reached the Akademy with my Librem 5 having phosh installed (which is Gnome based), in order to have something working. I met Bushan and Bart who took care and the issue was fixed two days later I could finally install Plasma 6 on it. The last time I tested my Librem 5 with Plasma 5 it felt sluggish and not well working. But this time I was impressed how well the system reacts. Sure there are some things here and there, but in the bigger picture it is quite useable. One annoying issue is that the camera is only working with one app and the other issue is the battery capacity, you have to charge it once a day. Because of missing a QR reader that can use the camera, getting data to the phone was quite challenging. Unfortunately the conference Wifi separated the devices and I couldn't use KDE Connect to transfer data. In the end the only way to import data was taking five photos from the QR Code to import my D-Ticket to Itinerary. With a device with Plasma Mobile, it directly was used for a experiment: How well does Dolphin works on a Plasma Mobile device. Together with Felix Ernst we tried it out and were quite impressed, that Dolphin does work very well on Plasma Mobile, after some simple modifications on the UI. That resulted in a patch to add a mobile UI for Dolphin !826. With more time to play with my Librem 5 I also found an bug in KWeather, that is missing a Refresh option, when used in a Plasma Mobile environment #493656. Akademy is a good place to identify and solve some issues. It is always like that, you chat with someone and they can tell you who to ask to answer the concrete question and in the end you can solve things, that seems unsolvable in the beginning. There was also time to look into the travelling app Itinerary. A lot people are faced with a lot of real world issues, when not in their home town. Itinerary is the best traveling apps I know about. It can import nearly every ticket you have and can get location information from restaurant websites and allow routing to that place. It does add many useful information, while traveling like current delays, platform changes, live updates for elevator, weather information at the destination, a station map and all those features with strong focus on privacy. In detail I found some small things to improve: I additionally learned that it has a lot of details that helps people who have special needs. That is the reason why Daniel Kraut wants to get Itinerary available for iOS. As spoken out, that Daniel wants to reach this goal, others already started to implement the first steps to build apps for iOS. This year I was volunteering in helping out at Akademy. For me it was a lot of fun to meet everyone at the infodesk or help the speakers setup the beamer and microphone. It is also a good opportunity to meet many new faces and get in contact with them. I see also room for improvement. As we were quite busy at the Welcome Event to get out the badges to everyone, I couldn't answer the questions from newcomers, as the queue was too long. I propose that some people volunteer to be available for questions from newcomers. Often it is hard for newcomers to get their first contact(s) in a new community. There is a lot of space for improvement to make it easier for newcomers to join. Some ideas in my head are: Make an event for the newcomers to get them some links into the community and show that everyone is friendly. The tables at the BoFs should make a circle, so everyone can see each other. It was also hard for me to understand everyone as they mostly spoken towards the front. And then BoFs are sometimes full of very specific words and if you are not already deep in the topic you are lost. I can see the problem, on the one side BoFs are also the place where the person that knows the topic already wants to get things done. On the other side new comers join BoFs, are overwhelmed by to many new words get frustrated and think, that they are not welcome. Maybe at least everyone should present itself with name and ask new faces, why they joined the BoF to help them joining. I'm happy, that the food provided for the attendees was very delicious and that I'm not the only one mostly vegetarian with a big amount to be vegan. At the conference the KDE Eco initiation really caught me, as I see a lot of new possibilities in giving more reasons to switch to an Open Source system. The talk from Natalie was great to see how pupils get excited about Open Source and also help their grandparents to move to a Linux system. As I also will start to work as a teacher, I really got ideas what I can do at school. Together with Joseph and Nicole, we finally started to think about how to drive an exploration on what kind of old hardware is still KDE software running. The ones with the oldest hardware will get an old KDE shirt. For more information see #40. The conference was very motivating for me, I also had still energy at the evening to do some Debian packaging and finally pushed kweathercore to Debian and started to work on KWeather. Now I'm even more interested in the KDE apps focusing the mobile world, as I now have some hardware that can actually use those apps. I really enjoyed the workshop how to contribute to Qt by Volker Hilsheimer, especially the way how Volker explained things in a very friendly way, answered every question, sometime postponed some questions but came back to them later. All in all I now have a good overview how Qt is doing development and how I can fix bugs. The daytrip to Rothenburg ob der Tauber was very interesting for me. It was the first time I visited the village. But in my memory it feels like I know the village already. I grew up with reading a lot of comic albums including the good SiFi comic album series "Yoku Tsuno" created by the Belgian writer Roger Leloup. Yoku Tsuno is an electronics engineer, raised in Japan but now living in Belgium. In "On the edge of life" she helps her friend Ingard, who actually lives in Rothenburg. Leloup invested a lot of time to travel to make the make his drawings as accurate as possible. a comic page with Yoko Tsuno in Rothenburg ob der Tauber In order to not have a hard cut from Akademy to normal life, I had a lunch with Carlos, to discuss KDE Neon and how we can improve the interaction with Debian. In the future this should have less friction and make both communities work together more smoothly. Additionally as I used to develop on KDEPIM with the help of Docker images based on Neon I ask for a meta kf6 dev meta package. That should help to get rid of most hand written lists of dev packages in the Docker file in order to make it more simple for new contributors to start hacking on KDEPIM. The rest of the day I finally found time to do the normal tourist stuff: Going to the Wine bridge and having a walk to the castle of W rzburg. Unfortunately you hear a lot of car noises up there, but I could finally relaxe in a Japanese designed garden. Finally at Saturday I started my trip back. The trains towards Eberswalde are broken and I needed to find alternative routing. I got a little bit nervous, as it was the first time I travelled with my Librem 5 and Itinerary only and needed to reach the next train in less than two mins. With the indoor maps provided, I could prepare my run through the train station so I reached successfully my next train. By the way, also if you only only use KDE software, I would recommend everyone to join Akademy ;)

24 November 2024

Edward Betts: A mini adventure at MiniDebConf Toulouse

A mini adventure at MiniDebConf Toulouse Last week, I ventured to Toulouse, for a delightful mix of coding, conversation, and crepes at MiniDebConf Toulouse, part of the broader Capitole du Libre conference, akin to the more well-known FOSDEM but with a distinctly French flair. This was my fourth and final MiniDebConf of the year. no jet bridge My trek to Toulouse was seamless. I hopped on a bus from my home in Bristol to the airport, then took a short flight. I luxuriated in seat 1A, making me the first to disembark a mere ten minutes later, I was already on the bus heading to my hotel.

Exploring the Pink City pink img 29 duck shop Once settled, I wasted no time exploring the charms of Toulouse. Just a short stroll from my hotel, I found myself beside a tranquil canal, its waters mirroring the golden hues of the trees lining its banks. Autumn in Toulouse painted the city in warm oranges and reds, creating a picturesque backdrop that was a joy to wander through. Every corner of the street revealed more of the city's rich cultural tapestry and striking architecture. Known affectionately as 'La Ville Rose' (The Pink City) for its unique terracotta brickwork, Toulouse captivated me with its blend of historical allure and vibrant modern life.

MiniDebCamp FabLab sign laptop setup Prior to the main event, the MiniDebCamp provided two days of hacking at Artilect FabLab a space as creative as it was welcoming. It was a pleasure to reconnect with familiar faces and forge new friendships.

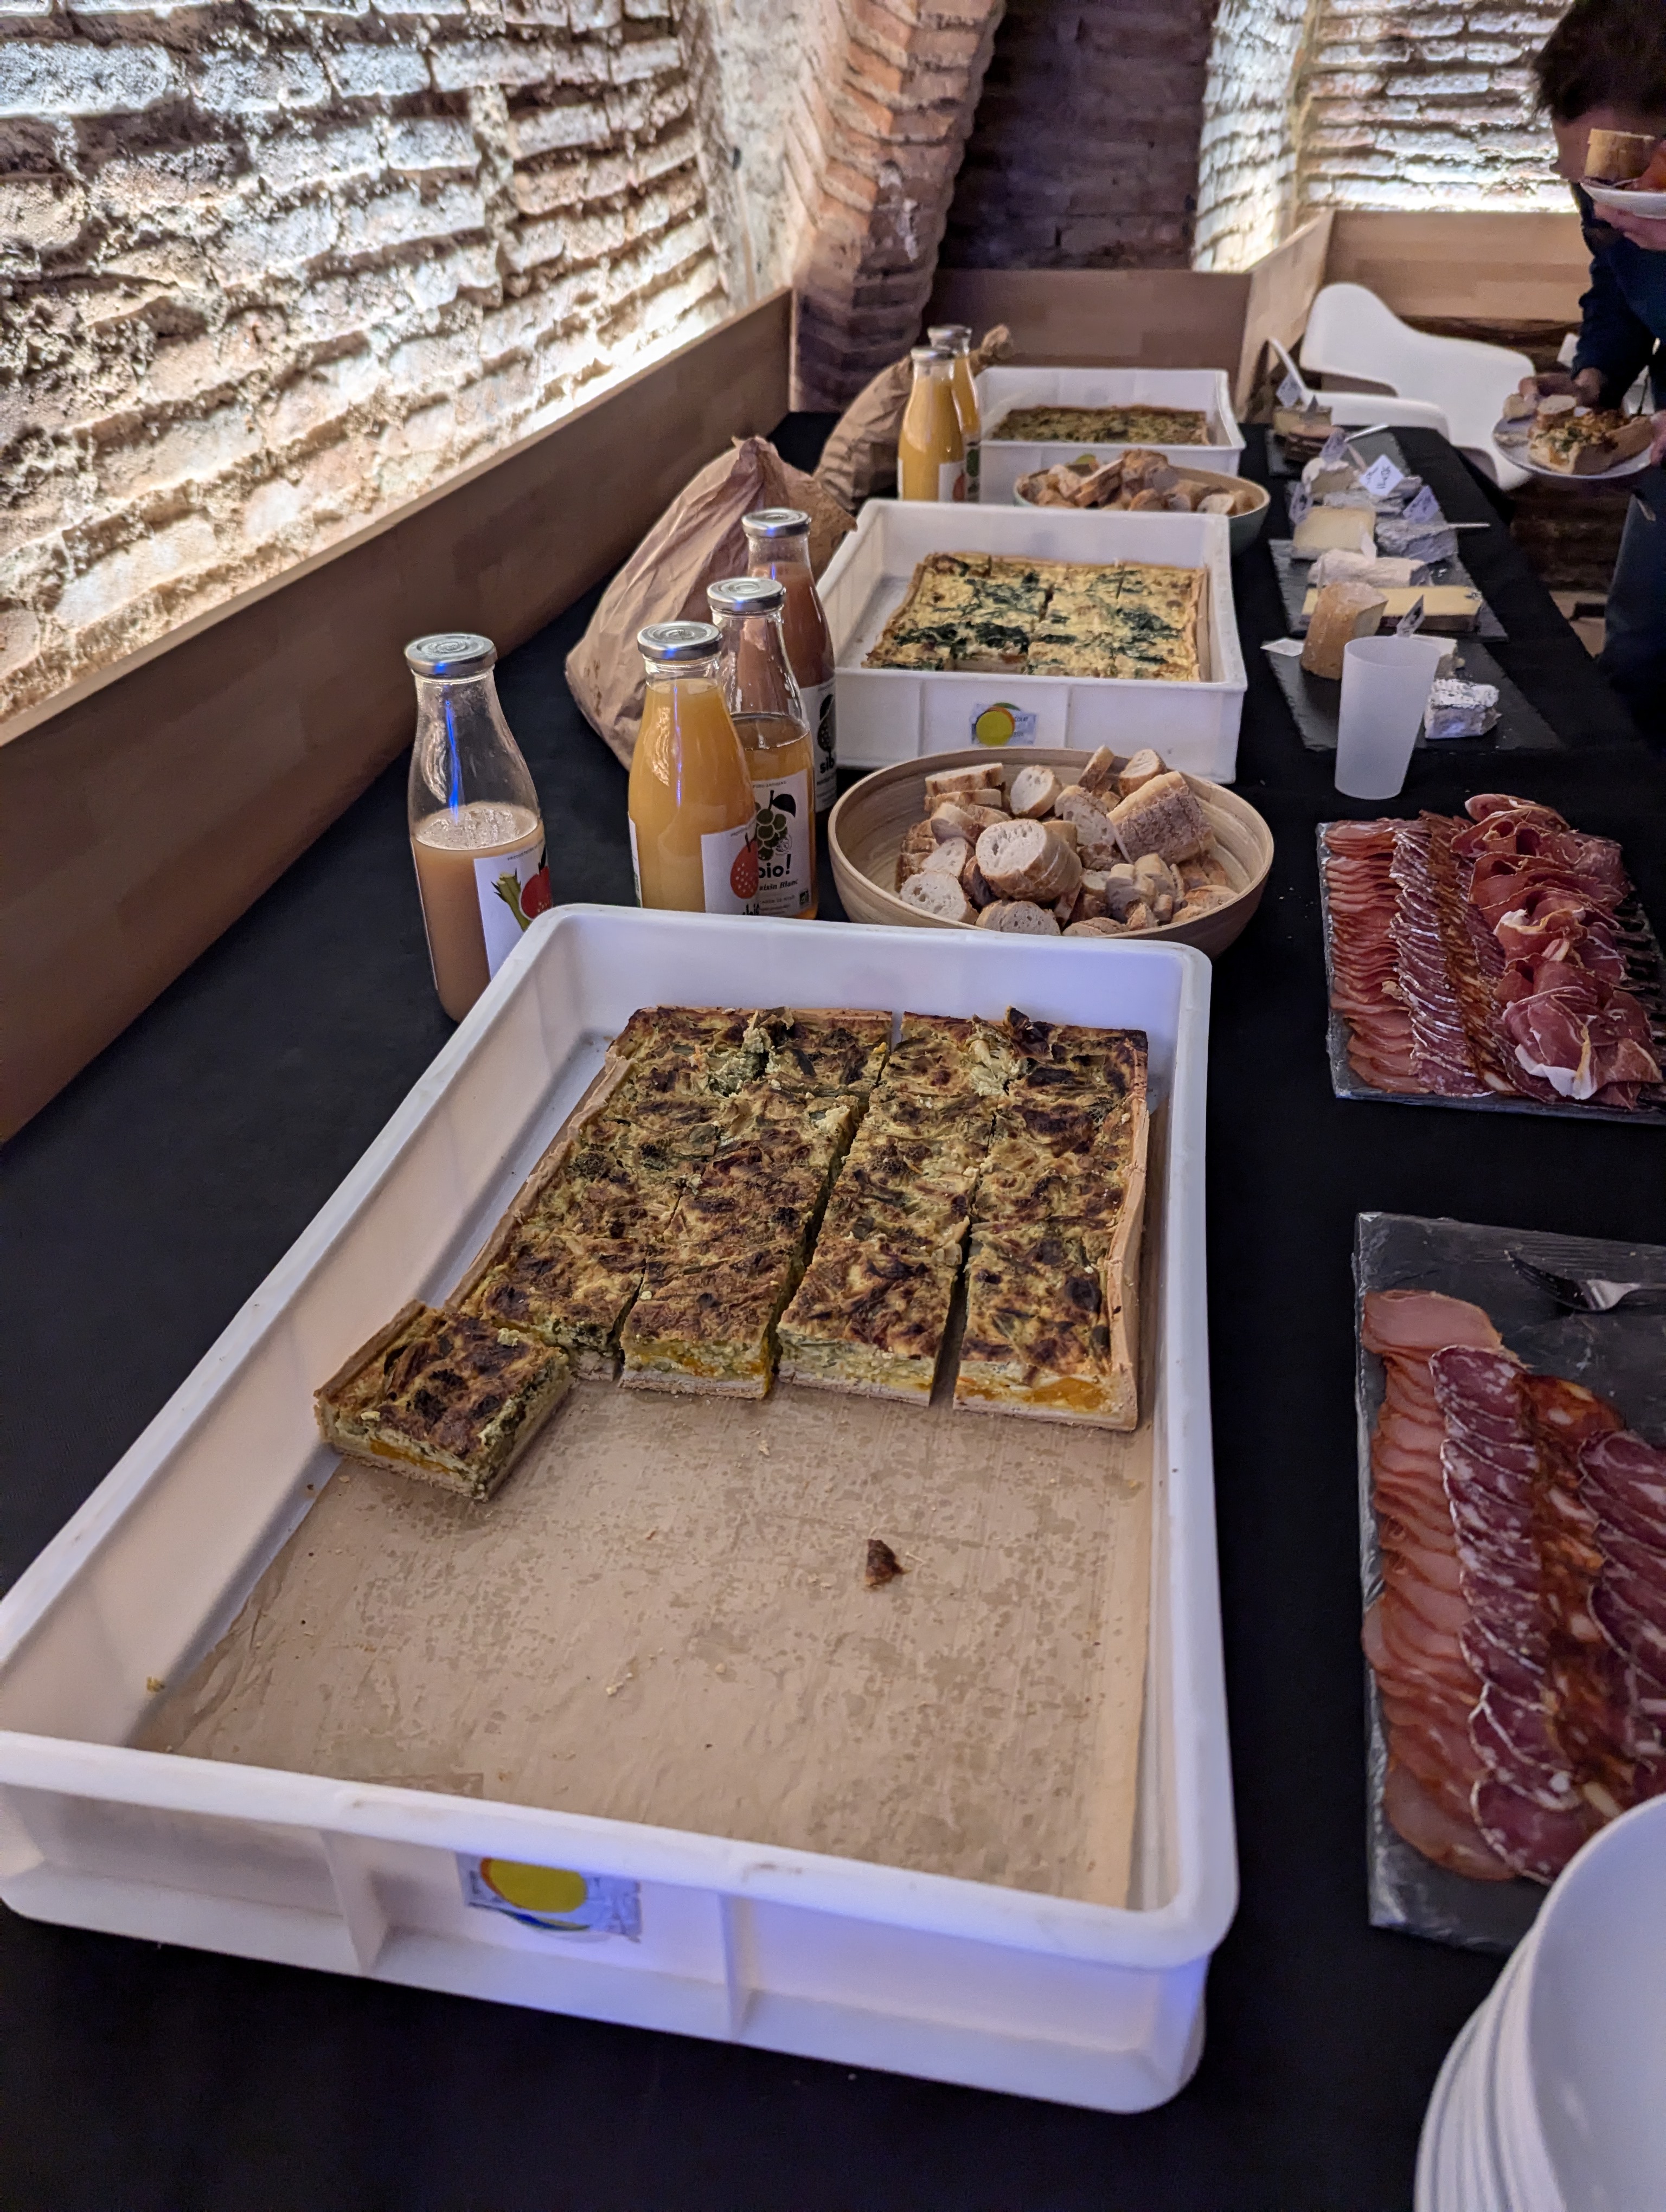
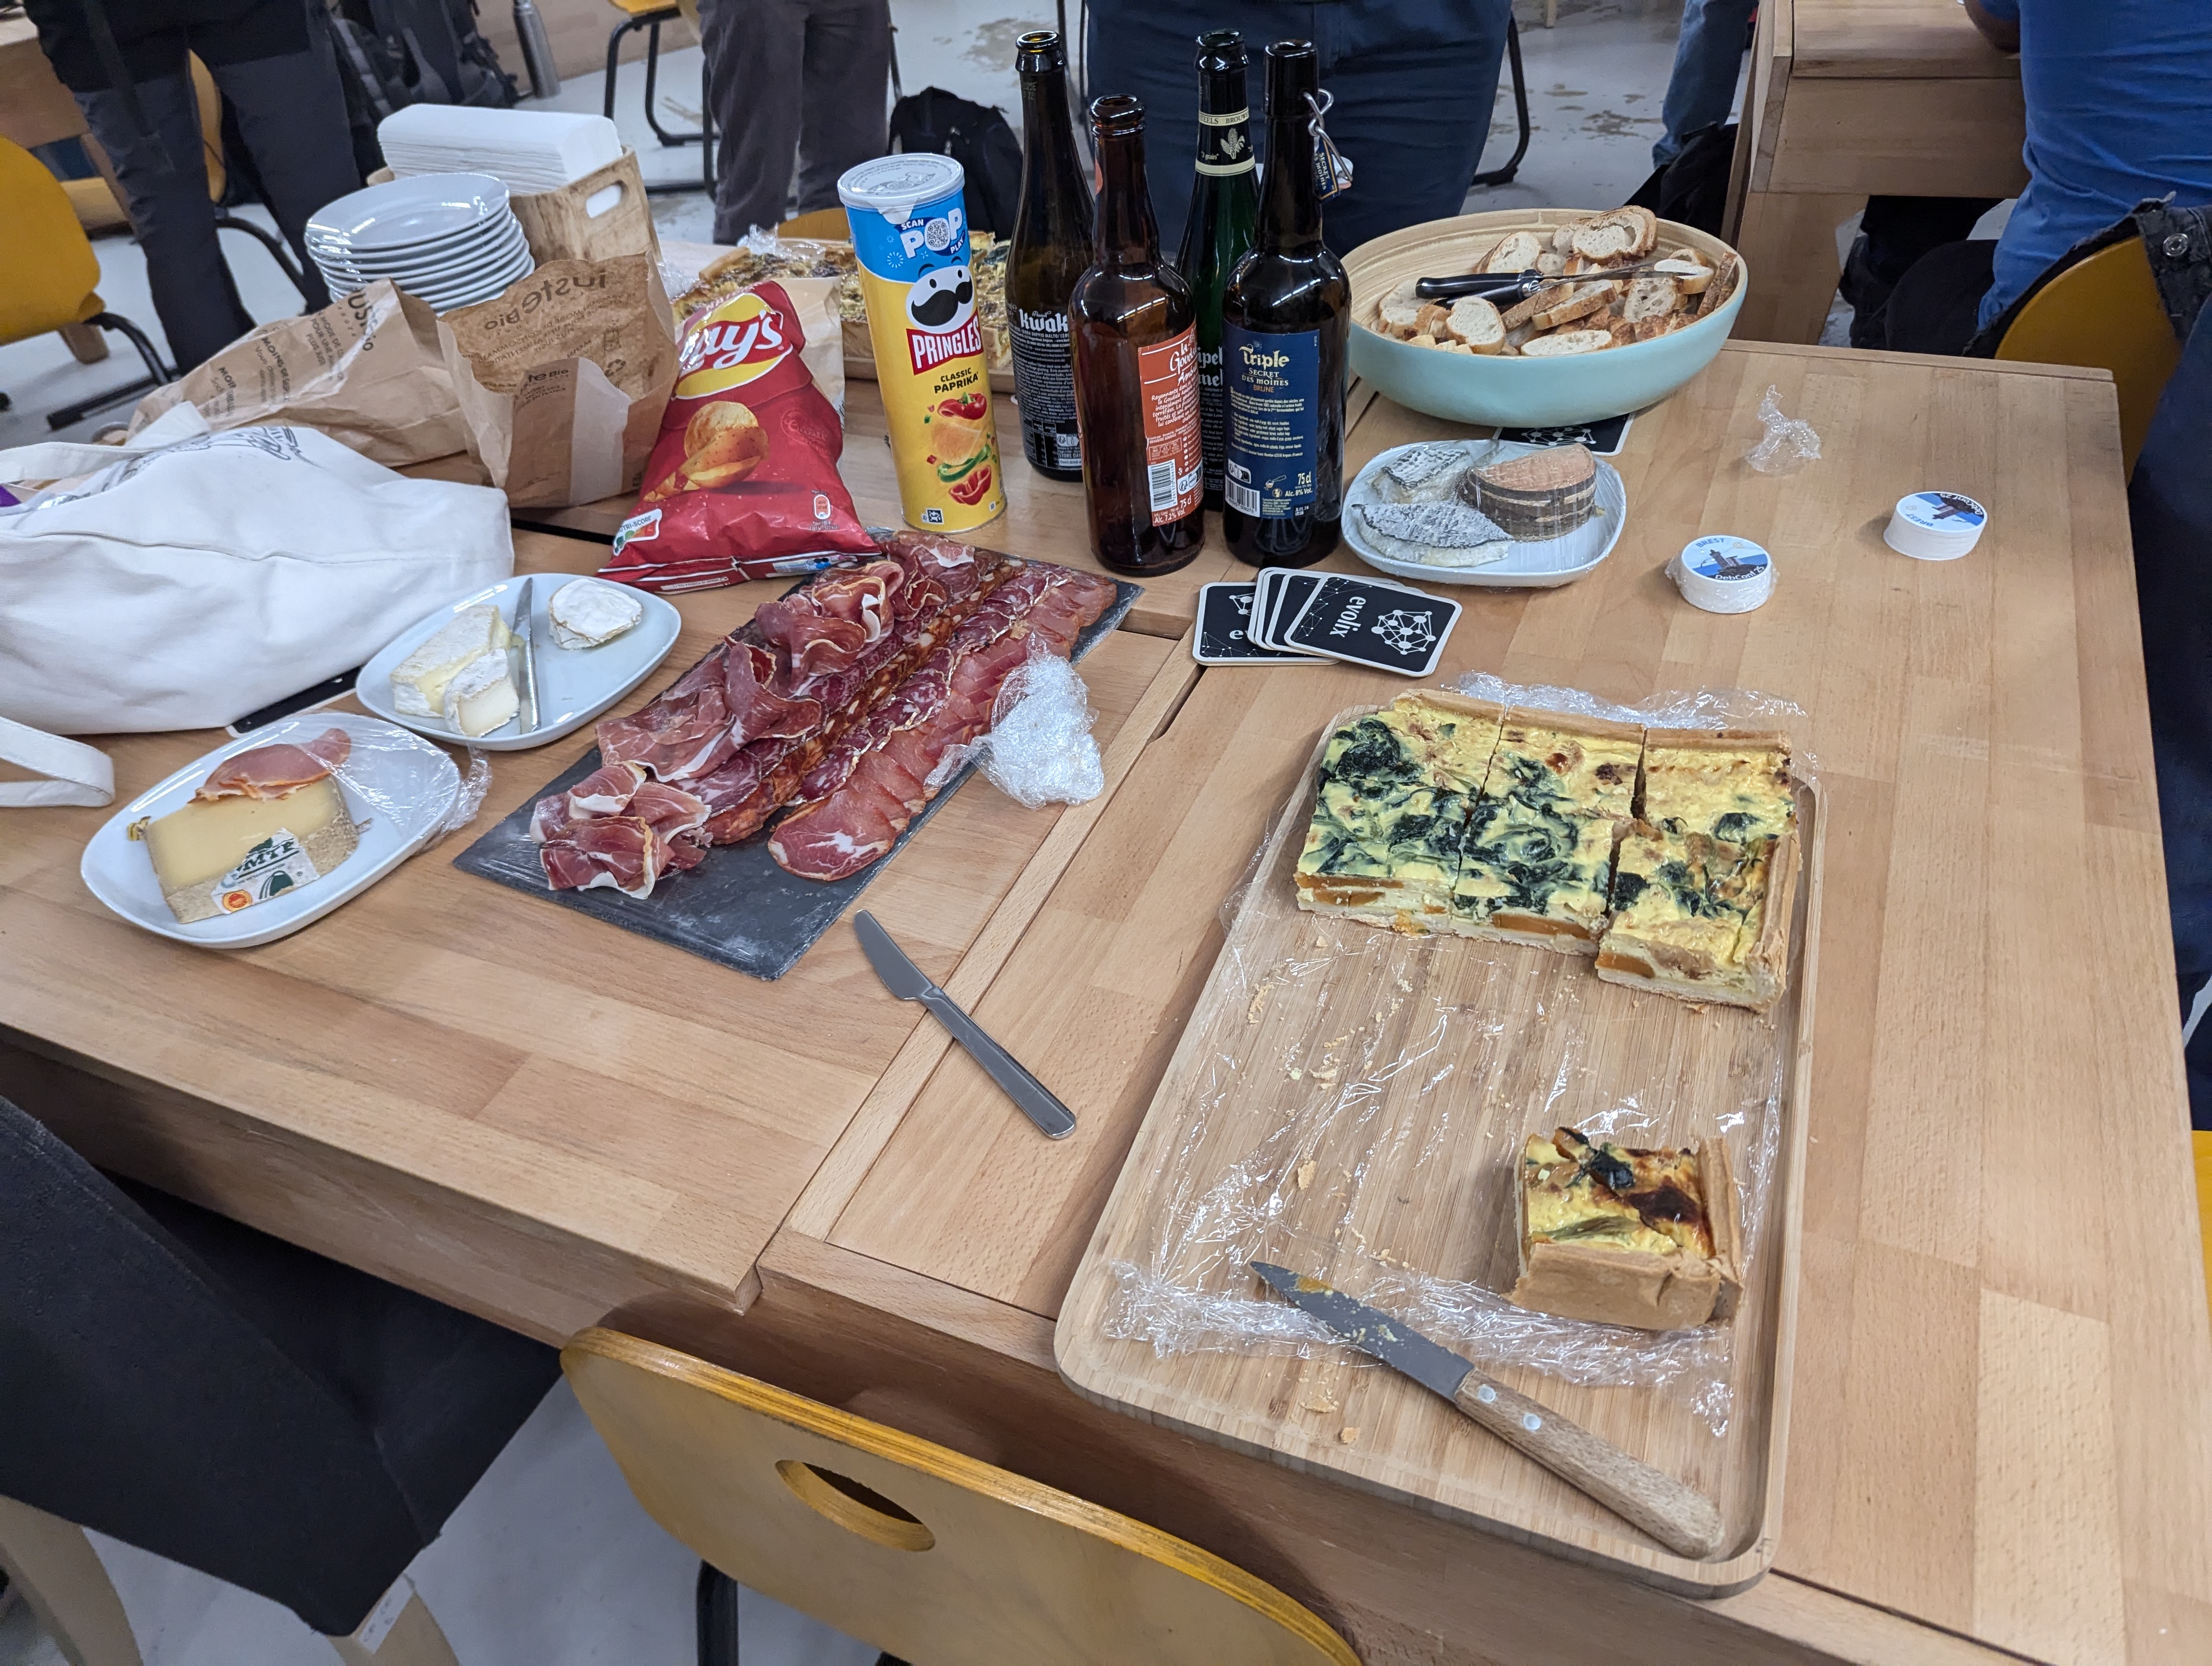
Culinary delights lunch 1 img 14 img 15 img 16 img 17 cakes The hospitality was exceptional. Our lunches boasted a delicious array of quiches, an enticing charcuterie board, and a superb selection of cheeses, all perfectly complemented by exquisite petite fours. Each item was not only a feast for the eyes but also a delight for the palate.

Wine and cheese wine and cheese 1 wine and cheese 2 Leftovers from these gourmet feasts fuelled our impromptu cheese and wine party on Thursday evening a highlight where informal chats blended seamlessly with serious software discussions.

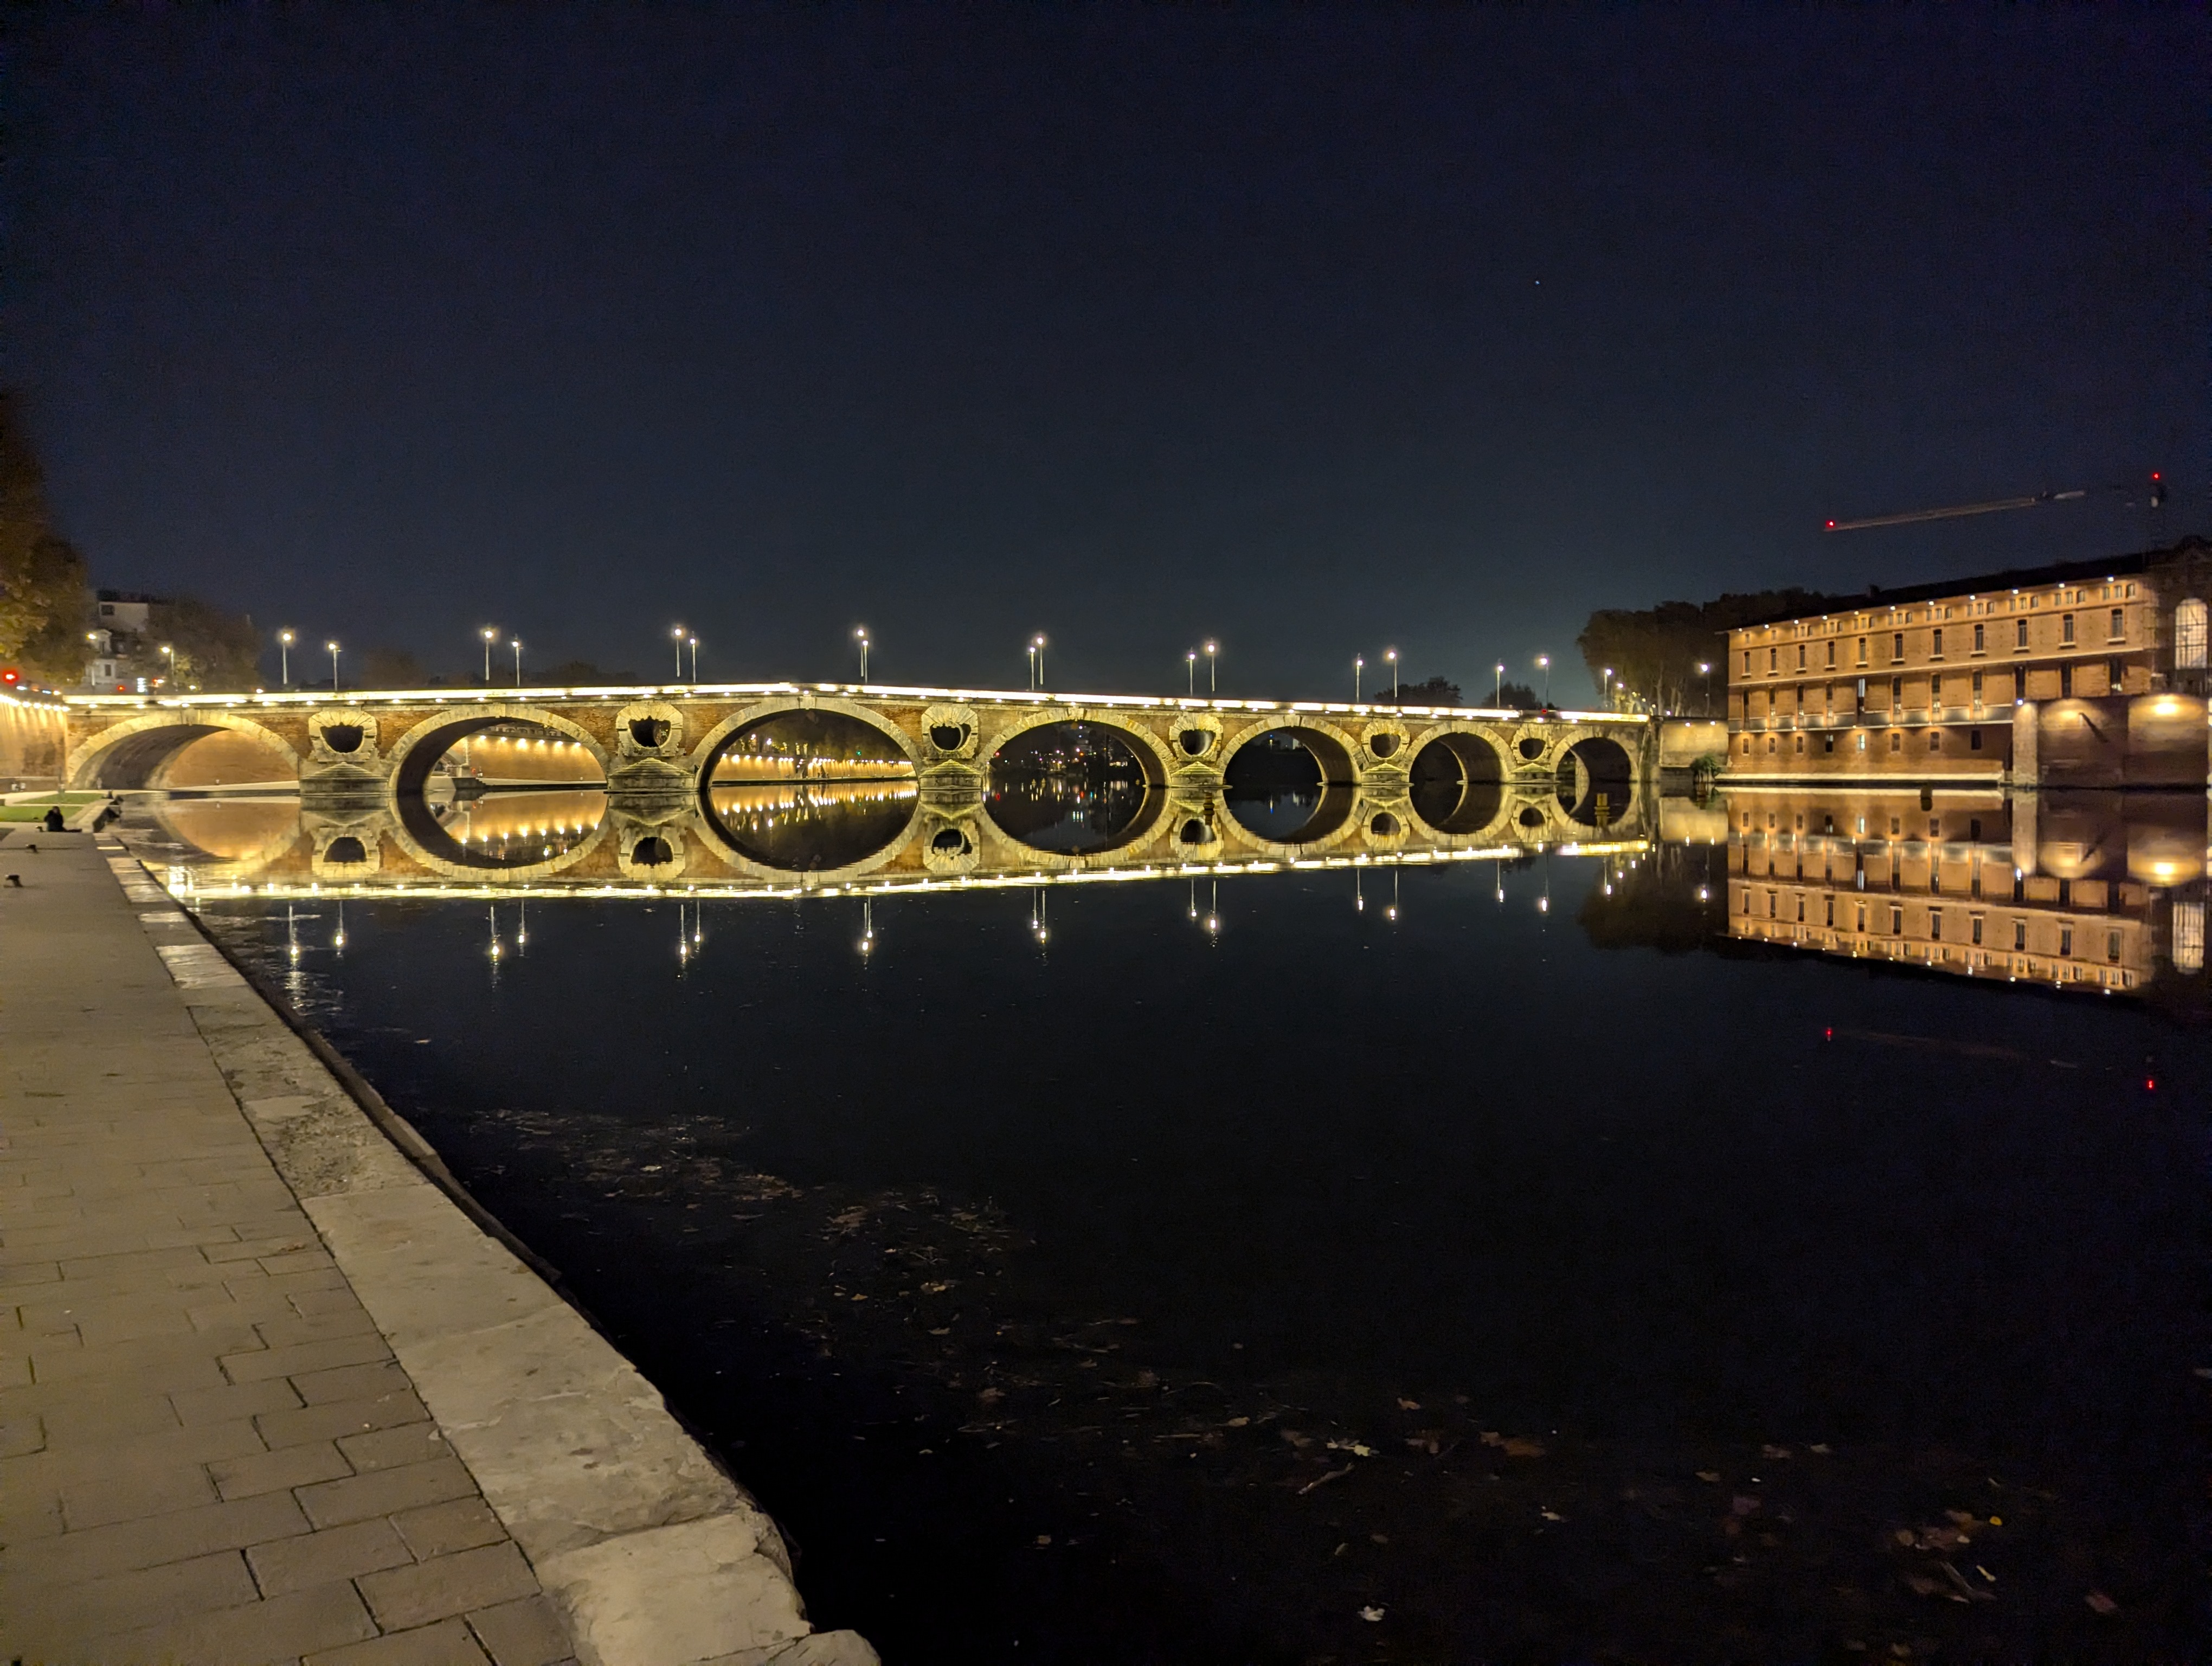
The river at night night river 1 night river 2 night river 3 night river 4 The enchantment of Toulouse doesn't dim with the setting sun; instead, it transforms. My evening strolls took me along the banks of the Garonne, under a sky just turning from twilight to velvet blue. The river, a dark mirror, perfectly reflected the illuminated grandeur of the city's architecture. Notably, the dome of the H pital de La Grave stood out, bathed in a warm glow against the night sky. This architectural gem, coupled with the soft lights of the bridge and the serene river, created a breathtaking scene that was both tranquil and awe-inspiring.

Capitole du Libre making crepes The MiniDebConf itself, part of the larger Capitole du Libre event, was a fantastic immersion into the world of free software. Unlike the ticket-free FOSDEM, this conference required QR codes for entry and even had bag searches, adding an unusual layer of security for a software conference. Highlights included the crepe-making by the organisers, reminiscent of street food scenes from larger festivals. The availability of crepes for MiniDebConf attendees and the presence of food trucks added a festive air, albeit with the inevitable long queues familiar to any festival-goer.

v l Toulouse bike cyclocity The city's bike rental system was a boon easy to use with handy bike baskets perfect for casual city touring. I chose pedal power over electric, finding it a pleasant way to navigate the streets and absorb the city's vibrant atmosphere.

Markets market flatbreads Toulouse's markets were a delightful discovery. From a spontaneous visit to a market near my hotel upon arrival, to cycling past bustling marketplaces, each day presented new local flavours and crafts to explore. The Za'atar flatbread from a Syrian stall was a particularly memorable lunch pick.

La brasserie Les Arcades img 25 img 26 img 27 Our conference wrapped up with a spontaneous gathering at La Brasserie Les Arcades in Place du Capitole. Finding a caf that could accommodate 30 of us on a Sunday evening without a booking felt like striking gold. What began with coffee and ice cream smoothly transitioned into dinner, where I enjoyed a delicious braised duck leg with green peppercorn sauce. This meal rounded off the trip with lively conversations and shared experiences.

The journey back home img 30 img 31 img 32 img 33 Returning from Toulouse, I found myself once again in seat 1A, offering the advantage of being the first off the plane, both on departure and arrival. My flight touched down in Bristol ahead of schedule, and within ten minutes, I was on the A1 bus, making my way back into the heart of Bristol.

Anticipating DebConf 25 in Brittany My trip to Toulouse for MiniDebConf was yet another fulfilling experience; the city was delightful, and the talks were insightful. While I frequently travel, these journeys are more about continuous learning and networking than escape. The food in Toulouse was particularly impressive, a highlight I've come to expect and relish on my trips to France. Looking ahead, I'm eagerly anticipating DebConf in Brest next year, especially the opportunity to indulge once more in the excellent French cuisine and beverages.

22 November 2024

Matthew Palmer: Your Release Process Sucks

For the past decade-plus, every piece of software I write has had one of two release processes. Software that gets deployed directly onto servers (websites, mostly, but also the infrastructure that runs Pwnedkeys, for example) is deployed with nothing more than git push prod main. I ll talk more about that some other day. Today is about the release process for everything else I maintain Rust / Ruby libraries, standalone programs, and so forth. To release those, I use the following, extremely intricate process:
  1. Create an annotated git tag, where the name of the tag is the software version I m releasing, and the annotation is the release notes for that version.
  2. Run git release in the repository.
  3. There is no step 3.
Yes, it absolutely is that simple. And if your release process is any more complicated than that, then you are suffering unnecessarily. But don t worry. I m from the Internet, and I m here to help.

Sidebar: annotated what-now?!? The annotated tag is one git s best-kept secrets. They ve been available in git for practically forever (I ve been using them since at least 2014, which is practically forever in software development), yet almost everyone I mention them to has never heard of them. A tag , in git parlance, is a repository-unique named label that points to a single commit (as identified by the commit s SHA1 hash). Annotating a tag is simply associating a block of free-form text with that tag. Creating an annotated tag is simple-sauce: git tag -a tagname will open up an editor window where you can enter your annotation, and git tag -a -m "some annotation" tagname will create the tag with the annotation some annotation . Retrieving the annotation for a tag is straightforward, too: git show tagname will display the annotation along with all the other tag-related information. Now that we know all about annotated tags, let s talk about how to use them to make software releases freaking awesome.

Step 1: Create the Annotated Git Tag As I just mentioned, creating an annotated git tag is pretty simple: just add a -a (or --annotate, if you enjoy typing) to your git tag command, and WHAM! annotation achieved. Releases, though, typically have unique and ever-increasing version numbers, which we want to encode in the tag name. Rather than having to look at the existing tags and figure out the next version number ourselves, we can have software do the hard work for us. Enter: git-version-bump. This straightforward program takes one mandatory argument: major, minor, or patch, and bumps the corresponding version number component in line with Semantic Versioning principles. If you pass it -n, it opens an editor for you to enter the release notes, and when you save out, the tag is automagically created with the appropriate name. Because the program is called git-version-bump, you can call it as a git command: git version-bump. Also, because version-bump is long and unwieldy, I have it aliased to vb, with the following entry in my ~/.gitconfig:
[alias]
    vb = version-bump -n
Of course, you don t have to use git-version-bump if you don t want to (although why wouldn t you?). The important thing is that the only step you take to go from here is our current codebase in main to everything as of this commit is version X.Y.Z of this software , is the creation of an annotated tag that records the version number being released, and the metadata that goes along with that release.

Step 2: Run git release As I said earlier, I ve been using this release process for over a decade now. So long, in fact, that when I started, GitHub Actions didn t exist, and so a lot of the things you d delegate to a CI runner these days had to be done locally, or in a more ad-hoc manner on a server somewhere. This is why step 2 in the release process is run git release . It s because historically, you can t do everything in a CI run. Nowadays, most of my repositories have this in the .git/config:
[alias]
    release = push --tags
Older repositories which, for one reason or another, haven t been updated to the new hawtness, have various other aliases defined, which run more specialised scripts (usually just rake release, for Ruby libraries), but they re slowly dying out. The reason why I still have this alias, though, is that it standardises the release process. Whether it s a Ruby gem, a Rust crate, a bunch of protobuf definitions, or whatever else, I run the same command to trigger a release going out. It means I don t have to think about how I do it for this project, because every project does it exactly the same way.

The Wiring Behind the Button
It wasn t the button that was the problem. It was the miles of wiring, the hundreds of miles of cables, the circuits, the relays, the machinery. The engine was a massive, sprawling, complex, mind-bending nightmare of levers and dials and buttons and switches. You couldn t just slap a button on the wall and expect it to work. But there should be a button. A big, fat button that you could press and everything would be fine again. Just press it, and everything would be back to normal.
  • Red Dwarf: Better Than Life
Once you ve accepted that your release process should be as simple as creating an annotated tag and running one command, you do need to consider what happens afterwards. These days, with the near-universal availability of CI runners that can do anything you need in an isolated, reproducible environment, the work required to go from annotated tag to release artifacts can be scripted up and left to do its thing. What that looks like, of course, will probably vary greatly depending on what you re releasing. I can t really give universally-applicable guidance, since I don t know your situation. All I can do is provide some of my open source work as inspirational examples. For starters, let s look at a simple Rust crate I ve written, called strong-box. It s a straightforward crate, that provides ergonomic and secure cryptographic functionality inspired by the likes of NaCl. As it s just a crate, its release script is very straightforward. Most of the complexity is working around Cargo s inelegant mandate that crate version numbers are specified in a TOML file. Apart from that, it s just a matter of building and uploading the crate. Easy! Slightly more complicated is action-validator. This is a Rust CLI tool which validates GitHub Actions and Workflows (how very meta) against a published JSON schema, to make sure you haven t got any syntax or structural errors. As not everyone has a Rust toolchain on their local box, the release process helpfully build binaries for several common OSes and CPU architectures that people can download if they choose. The release process in this case is somewhat larger, but not particularly complicated. Almost half of it is actually scaffolding to build an experimental WASM/NPM build of the code, because someone seemed rather keen on that. Moving away from Rust, and stepping up the meta another notch, we can take a look at the release process for git-version-bump itself, my Ruby library and associated CLI tool which started me down the Just Tag It Already rabbit hole many years ago. In this case, since gemspecs are very amenable to programmatic definition, the release process is practically trivial. Remove the boilerplate and workarounds for GitHub Actions bugs, and you re left with about three lines of actual commands. These approaches can certainly scale to larger, more complicated processes. I ve recently implemented annotated-tag-based releases in a proprietary software product, that produces Debian/Ubuntu, RedHat, and Windows packages, as well as Docker images, and it takes all of the information it needs from the annotated tag. I m confident that this approach will successfully serve them as they expand out to build AMIs, GCP machine images, and whatever else they need in their release processes in the future.

Objection, Your Honour! I can hear the howl of the but, actuallys coming over the horizon even as I type. People have a lot of Big Feelings about why this release process won t work for them. Rather than overload this article with them, I ve created a companion article that enumerates the objections I ve come across, and answers them. I m also available for consulting if you d like a personalised, professional opinion on your specific circumstances.

DVD Bonus Feature: Pre-releases Unless you re addicted to surprises, it s good to get early feedback about new features and bugfixes before they make it into an official, general-purpose release. For this, you can t go past the pre-release. The major blocker to widespread use of pre-releases is that cutting a release is usually a pain in the behind. If you ve got to edit changelogs, and modify version numbers in a dozen places, then you re entirely justified in thinking that cutting a pre-release for a customer to test that bugfix that only occurs in their environment is too much of a hassle. The thing is, once you ve got releases building from annotated tags, making pre-releases on every push to main becomes practically trivial. This is mostly due to another fantastic and underused Git command: git describe. How git describe works is, basically, that it finds the most recent commit that has an associated annotated tag, and then generates a string that contains that tag s name, plus the number of commits between that tag and the current commit, with the current commit s hash included, as a bonus. That is, imagine that three commits ago, you created an annotated release tag named v4.2.0. If you run git describe now, it will print out v4.2.0-3-g04f5a6f (assuming that the current commit s SHA starts with 04f5a6f). You might be starting to see where this is going. With a bit of light massaging (essentially, removing the leading v and replacing the -s with .s), that string can be converted into a version number which, in most sane environments, is considered newer than the official 4.2.0 release, but will be superceded by the next actual release (say, 4.2.1 or 4.3.0). If you re already injecting version numbers into the release build process, injecting a slightly different version number is no work at all. Then, you can easily build release artifacts for every commit to main, and make them available somewhere they won t get in the way of the official releases. For example, in the proprietary product I mentioned previously, this involves uploading the Debian packages to a separate component (prerelease instead of main), so that users that want to opt-in to the prerelease channel simply modify their sources.list to change main to prerelease. Management have been extremely pleased with the easy availability of pre-release packages; they ve been gleefully installing them willy-nilly for testing purposes since I rolled them out. In fact, even while I ve been writing this article, I was asked to add some debug logging to help track down a particularly pernicious bug. I added the few lines of code, committed, pushed, and went back to writing. A few minutes later (next week s job is to cut that in-process time by at least half), the person who asked for the extra logging ran apt update; apt upgrade, which installed the newly-built package, and was able to progress in their debugging adventure. Continuous Delivery: It s Not Just For Hipsters.

+1, Informative Hopefully, this has spurred you to commit your immortal soul to the Church of the Annotated Tag. You may tithe by buying me a refreshing beverage. Alternately, if you re really keen to adopt more streamlined release management processes, I m available for consulting engagements.

Matthew Palmer: Invalid Excuses for Why Your Release Process Sucks

In my companion article, I made the bold claim that your release process should consist of no more than two steps:
  1. Create an annotated Git tag;
  2. Run a single command to trigger the release pipeline.
As I have been on the Internet for more than five minutes, I m aware that a great many people will have a great many objections to this simple and straightforward idea. In the interests of saving them a lot of wear and tear on their keyboards, I present this list of common reasons why these objections are invalid. If you have an objection I don t cover here, the comment box is down the bottom of the article. If you think you ve got a real stumper, I m available for consulting engagements, and if you turn out to have a release process which cannot feasibly be reduced to the above two steps for legitimate technical reasons, I ll waive my fees.

But I automatically generate my release notes from commit messages! This one is really easy to solve: have the release note generation tool feed directly into the annotation. Boom! Headshot.

But all these files need to be edited to make a release! No, they absolutely don t. But I can see why you might think you do, given how inflexible some packaging environments can seem, and since that s how we ve always done it .

Language Packages Most languages require you to encode the version of the library or binary in a file that you want to revision control. This is teh suck, but I m yet to encounter a situation that can t be worked around some way or another. In Ruby, for instance, gemspec files are actually executable Ruby code, so I call code (that s part of git-version-bump, as an aside) to calculate the version number from the git tags. The Rust build tool, Cargo, uses a TOML file, which isn t as easy, but a small amount of release automation is used to take care of that.

Distribution Packages If you re building Linux distribution packages, you can easily apply similar automation faffery. For example, Debian packages take their metadata from the debian/changelog file in the build directory. Don t keep that file in revision control, though: build it at release time. Everything you need to construct a Debian (or RPM) changelog is in the tag version numbers, dates, times, authors, release notes. Use it for much good.

The Dreaded Changelog Finally, there s the CHANGELOG file. If it s maintained during the development process, it typically has an archive of all the release notes, under version numbers, with an Unreleased heading at the top. It s one more place to remember to have to edit when making that preparing release X.Y.Z commit, and it is a gift to the Demon of Spurious Merge Conflicts if you follow the policy of every commit must add a changelog entry . My solution: just burn it to the ground. Add a line to the top with a link to wherever the contents of annotated tags get published (such as GitHub Releases, if that s your bag) and never open it ever again.

But I need to know other things about my release, too! For some reason, you might think you need some other metadata about your releases. You re probably wrong it s amazing how much information you can obtain or derive from the humble tag so think creatively about your situation before you start making unnecessary complexity for yourself. But, on the off chance you re in a situation that legitimately needs some extra release-related information, here s the secret: structured annotation. The annotation on a tag can be literally any sequence of octets you like. How that data is interpreted is up to you. So, require that annotations on release tags use some sort of structured data format (say YAML or TOML or even XML if you hate your release manager), and mandate that it contain whatever information you need. You can make sure that the annotation has a valid structure and contains all the information you need with an update hook, which can reject the tag push if it doesn t meet the requirements, and you re sorted.

But I have multiple packages in my repo, with different release cadences and versions! This one is common enough that I just refer to it as the monorepo drama . Personally, I m not a huge fan of monorepos, but you do you, boo. Annotated tags can still handle it just fine. The trick is to include the package name being released in the tag name. So rather than a release tag being named vX.Y.Z, you use foo/vX.Y.Z, bar/vX.Y.Z, and baz/vX.Y.Z. The release automation for each package just triggers on tags that match the pattern for that particular package, and limits itself to those tags when figuring out what the version number is.

But we don t semver our releases! Oh, that s easy. The tag pattern that marks a release doesn t have to be vX.Y.Z. It can be anything you want. Relatedly, there is a (rare, but existent) need for packages that don t really have a conception of releases in the traditional sense. The example I ve hit most often is automatically generated bindings packages, such as protobuf definitions. The source of truth for these is a bunch of .proto files, but to be useful, they need to be packaged into code for the various language(s) you re using. But those packages need versions, and while someone could manually make releases, the best option is to build new per-language packages automatically every time any of those definitions change. The versions of those packages, then, can be datestamps (I like something like YYYY.MM.DD.N, where N starts at 0 each day and increments if there are multiple releases in a single day). This process allows all the code that needs the definitions to declare the minimum version of the definitions that it relies on, and everything is kept in sync and tracked almost like magic.

Th-th-th-th-that s all, folks! I hope you ve enjoyed this bit of mild debunking. Show your gratitude by buying me a refreshing beverage, or purchase my professional expertise and I ll answer all of your questions and write all your CI jobs.

20 November 2024

Ian Jackson: The Rust Foundation's 2nd bad draft trademark policy

tl;dr: The Rust Foundation s new trademark policy still forbids unapproved modifications: this would forbid both the Rust Community s own development work(!) and normal Free Software distribution practices. Background In April 2023 I wrote about the Rust Foundation s ham-fisted and misguided attempts to update the Rust trademark policy. This turned into drama. The new draft Recently, the Foundation published a new draft. It s considerably less bad, but the most serious problem, which I identified last year, remains. It prevents redistribution of modified versions of Rust, without pre-approval from the Rust Foundation. (Subject to some limited exceptions.) The people who wrote this evidently haven t realised that distributing modified versions is how free software development works. Ie, the draft Rust trademark policy even forbids making a github branch for an MR to contribute to Rust! It s also very likely unacceptable to Debian. Rust is still on track to repeat the Firefox/Iceweasel debacle. Below is a copy of my formal response to the consultation. The consultation closes at 07:59:00 UTC tomorrow (21st November), ie, at the end of today (Wednesday) US Pacific time, so if you want to reply, do so quickly. My consultation response
Hi. My name is Ian Jackson. I write as a Rust contributor and as a Debian Developer with first-hand experience of Debian s approach to trademarks. (But I am not a member of the Debian Rust Packaging Team.) Your form invites me to state any blocking concerns. I m afraid I have one: PROBLEM The policy on distributing modified versions of Rust (page 4, 8th bullet) is far too restrictive. PROBLEM - ASPECT 1 On its face the policy forbids making a clone of the Rust repositories on a git forge, and pushing a modified branch there. That is publicly distributing a modified version of Rust. I.e., the current policy forbids the Rust s community s own development workflow! PROBLEM - ASPECT 2 The policy also does not meet the needs of Software-Freedom-respecting downstreams, including community Linux distributions such as Debian. There are two scenarios (fuzzy, and overlapping) which provide a convenient framing to discuss this: Firstly, in practical terms, Debian may need to backport bugfixes, or sometimes other changes. Sometimes Debian will want to pre-apply bugfixes or changes that have been contributed by users, and are intended eventually to go upstream, but are not included upstream in official Rust yet. This is a routine activity for a distribution. The policy, however, forbids it. Secondly, Debian, as a point of principle, requires the ability to diverge from upstream if and when Debian decides that this is the right choice for Debian s users. The freedom to modify is a key principle of Free Software. This includes making changes that the upstream project disapproves of. Some examples of this, where Debian has made changes, that upstream do not approve of, have included things like: removing user-tracking code, or disabling obsolescence timebombs that stop a particular version working after a certain date. Overall, while alignment in values between Debian and Rust seems to be very good right now, modifiability it is a matter of non-negotiable principle for Debian. The 8th bullet point on page 4 of the PDF does not give Debian (and Debian s users) these freedoms. POSSIBLE SOLUTIONS Other formulations, or an additional permission, seem like they would be able to meet the needs of both Debian and Rust. The first thing to recognise is that forbidding modified versions is probably not necessary to prevent language ecosystem fragmentation. Many other programming languages are distributed under fully Free Software licences without such restrictive trademark policies. (For example, Python; I m sure a thorough survey would find many others.) The scenario that would be most worrying for Rust would be embrace - extend - extinguish . In projects with a copyleft licence, this is not a concern, but Rust is permissively licenced. However, one way to address this would be to add an additional permission for modification that permits distribution of modified versions without permission, but if the modified source code is also provided, under the original Rust licence. I suggest therefore adding the following 2nd sub-bullet point to the 8th bullet on page 4:
  • changes which are shared, in source code form, with all recipients of the modified software, and publicly licenced under the same licence as the official materials.
This means that downstreams who fear copyleft have the option of taking Rust s permissive copyright licence at face value, but are limited in the modifications they may make, unless they rename. Conversely downstreams such as Debian who wish to operate as part of the Free Software ecosystem can freely make modifications. It also, obviously, covers the Rust Community s own development work. NON-SOLUTIONS Some upstreams, faced with this problem, have offered Debian a special permission: ie, said that it would be OK for Debian to make modifications that Debian wants to. But Debian will not accept any Debian-specific permissions. Debian could of course rename their Rust compiler. Debian has chosen to rename in the past: infamously, a similar policy by Mozilla resulted in Debian distributing Firefox under the name Iceweasel for many years. This is a PR problem for everyone involved, and results in a good deal of technical inconvenience and makework. Debian could seek approval for changes, and the Rust Foundation would grant that approval quickly . This is unworkable on a practical level - requests for permission do not fit into Debian s workflow, and the resulting delays would be unacceptable. But, more fundamentally, Debian rightly insists that it must have the freedom to make changes that the Foundation do not approve of. (For example, if a future Rust shipped with telemetry features Debian objected to.) Debian and Rust could compromise . However, Debian is an ideological as well as technological project. The principles I have set out are part of Debian s Foundation Documents - they are core values for Debian. When Debian makes compromises, it does so very slowly and with great deliberation, using its slowest and most heavyweight constitutional governance processes. Debian is not likely to want to engage in such a process for the benefit of one programming language. Users will get Rust from upstream . This is currently often the case. Right now, Rust is moving very quickly, and by Debian standards is very new. As Rust becomes more widely used, more stable, and more part of the infrastructure of the software world, it will need to become part of standard, stable, reliable, software distributions. That means Debian.
(The consultation was a Google Forms page with a single text field, so the formatting isn t great. I have edited the formatting very lightly to avoid rendering bugs here on my blog.)

comment count unavailable comments

Russell Coker: Solving Spam and Phishing for Corporations

Centralisation and Corporations An advantage of a medium to large company is that it permits specialisation. For example I m currently working in the IT department of a medium sized company and because we have standardised hardware (Dell Latitude and Precision laptops, Dell Precision Tower workstations, and Dell PowerEdge servers) and I am involved in fixing all Linux compatibility issues on that I can fix most problems in a small fraction of the time that I would take to fix on a random computer. There is scope for a lot of debate about the extent to which companies should standardise and centralise things. But for computer problems which can escalate quickly from minor to serious if not approached in the correct manner it s clear that a good deal of centralisation is appropriate. For people doing technical computer work such as programming there s a large portion of the employees who are computer hobbyists who like to fiddle with computers. But if the support system is run well even they will appreciate having computers just work most of the time and for a large portion of the failures having someone immediately recognise the problem, like the issues with NVidia drivers that I have documented so that first line support can implement workarounds without the need for a lengthy investigation. A big problem with email in the modern Internet is the prevalence of Phishing scams. The current corporate approach to this is to send out test Phishing email to people and then force computer security training on everyone who clicks on them. One problem with this is that attackers only need to fool one person on one occasion and when you have hundreds of people doing something on rare occasions that s not part of their core work they will periodically get it wrong. When every test Phishing run finds several people who need extra training it seems obvious to me that this isn t a solution that s working well. I will concede that the majority of people who click on the test Phishing email would probably realise their mistake if asked to enter the password for the corporate email system, but I think it s still clear that this isn t a great solution. Let s imagine for the sake of discussion that everyone in a company was 100% accurate at identifying Phishing email and other scam email, if that was the case would the problem be solved? I believe that even in that hypothetical case it would not be a solved problem due to the wasted time and concentration. People can spend minutes determining if a single email is legitimate. On many occasions I have had relatives and clients forward me email because they are unsure if it s valid, it s great that they seek expert advice when they are unsure about things but it would be better if they didn t have to go to that effort. What we ideally want to do is centralise the anti-Phishing and anti-spam work to a small group of people who are actually good at it and who can recognise patterns by seeing larger quantities of spam. When a spam or Phishing message is sent to 600 people in a company you don t want 600 people to individually consider it, you want one person to recognise it and delete/block all 600. If 600 people each spend one minute considering the matter then that s 10 work hours wasted! The Rationale for Human Filtering For personal email human filtering usually isn t viable because people want privacy. But corporate email isn t private, it s expected that the company can read it under certain circumstances (in most jurisdictions) and having email open in public areas of the office where colleagues might see it is expected. You can visit gmail.com on your lunch break to read personal email but every company policy (and common sense) says to not have actually private correspondence on company systems. The amount of time spent by reception staff in sorting out such email would be less than that taken by individuals. When someone sends a spam to everyone in the company instead of 500 people each spending a couple of minutes working out whether it s legit you have one person who s good at recognising spam (because it s their job) who clicks on a remove mail from this sender from all mailboxes button and 500 messages are deleted and the sender is blocked. Delaying email would be a concern. It s standard practice for CEOs (and C*Os at larger companies) to have a PA receive their email and forward the ones that need their attention. So human vetting of email can work without unreasonable delays. If we had someone checking all email for the entire company probably email to the senior people would never get noticeably delayed and while people like me would get their mail delayed on occasion people doing technical work generally don t have notifications turned on for email because it s a distraction and a fast response isn t needed. There are a few senders where fast response is required, which is mostly corporations sending a click this link within 10 minutes to confirm your password change email. Setting up rules for all such senders that are relevant to work wouldn t be difficult to do. How to Solve This Spam and Phishing became serious problems over 20 years ago and we have had 20 years of evolution of email filtering which still hasn t solved the problem. The vast majority of email addresses in use are run by major managed service providers and they haven t managed to filter out spam/phishing mail effectively so I think we should assume that it s not going to be solved by filtering. There is talk about what AI technology might do for filtering spam/phishing but that same technology can product better crafted hostile email to avoid filters. An additional complication for corporate email filtering is that some criteria that are used to filter personal email don t apply to corporate mail. If someone sends email to me personally about millions of dollars then it s obviously not legit. If someone sends email to a company then it could be legit. Companies routinely have people emailing potential clients about how their products can save millions of dollars and make purchases over a million dollars. This is not a problem that s impossible to solve, it s just an extra difficulty that reduces the efficiency of filters. It seems to me that the best solution to the problem involves having all mail filtered by a human. A company could configure their mail server to not accept direct external mail for any employee s address. Then people could email files to colleagues etc without any restriction but spam and phishing wouldn t be a problem. The issue is how to manage inbound mail. One possibility is to have addresses of the form it+russell.coker@example.com (for me as an employee in the IT department) and you would have a team of people who would read those mailboxes and forward mail to the right people if it seemed legit. Having addresses like it+russell.coker means that all mail to the IT department would be received into folders of the same account and they could be filtered by someone with suitable security level and not require any special configuration of the mail server. So the person who read the is mailbox would have a folder named russell.coker receiving mail addressed to me. The system could be configured to automate the processing of mail from known good addresses (and even domains), so they could just put in a rule saying that when Dell sends DMARC authenticated mail to is+$USER it gets immediately directed to $USER. This is the sort of thing that can be automated in the email client (mail filtering is becoming a common feature in MUAs). For a FOSS implementation of such things the server side of it (including extracting account data from a directory to determine which department a user is in) would be about a day s work and then an option would be to modify a webmail program to have extra functionality for approving senders and sending change requests to the server to automatically direct future mail from the same sender. As an aside I have previously worked on a project that had a modified version of the Horde webmail system to do this sort of thing for challenge-response email and adding certain automated messages to the allow-list. The Change One of the first things to do is configuring the system to add every recipient of an outbound message to the allow list for receiving a reply. Having a script go through the sent-mail folders of all accounts and adding the recipients to the allow lists would be easy and catch the common cases. But even with processing the sent mail folders going from a working system without such things to a system like this will take some time for the initial work of adding addresses to the allow lists, particularly for domain wide additions of all the sites that send password confirmation messages. You would need rules to direct inbound mail to the old addresses to the new style and then address a huge amount of mail that needs to be categorised. If you have 600 employees and the average amount of time taken on the first day is 10 minutes per user then that s 100 hours of work, 12 work days. If you had everyone from the IT department, reception, and executive assistants working on it that would be viable. After about a week there wouldn t be much work involved in maintaining it. Then after that it would be a net win for the company. The Benefits If the average employee spends one minute a day dealing with spam and phishing email then with 600 employees that s 10 hours of wasted time per day. Effectively wasting one employee s work! I m sure that s the low end of the range, 5 minutes average per day doesn t seem unreasonable especially when people are unsure about phishing email and send it to Slack so multiple employees spend time analysing it. So you could have 5 employees being wasted by hostile email and avoiding that would take a fraction of the time of a few people adding up to less than an hour of total work per day. Then there s the training time for phishing mail. Instead of having every employee spend half an hour doing email security training every few months (that s 300 hours or 7.5 working weeks every time you do it) you just train the few experts. In addition to saving time there are significant security benefits to having experts deal with possibly hostile email. Someone who deals with a lot of phishing email is much less likely to be tricked. Will They Do It? They probably won t do it any time soon. I don t think it s expensive enough for companies yet. Maybe government agencies already have equivalent measures in place, but for regular corporations it s probably regarded as too difficult to change anything and the costs aren t obvious. I have been unsuccessful in suggesting that managers spend slightly more on computer hardware to save significant amounts of worker time for 30 years.

Arnaud Rebillout: Installing an older Ansible version via pipx

Latest Ansible requires Python 3.8 on the remote hosts ... and therefore, hosts running Debian Buster are now unsupported. Monday, I updated the system on my laptop (Debian Sid), and I got the latest version of ansible-core, 2.18:
$ ansible --version   head -1
ansible [core 2.18.0]
To my surprise, Ansible started to fail with some remote hosts:
ansible-core requires a minimum of Python version 3.8. Current version: 3.7.3 (default, Mar 23 2024, 16:12:05) [GCC 8.3.0]
Yep, I do have to work with hosts running Debian Buster (aka. oldoldstable). While Buster is old, it's still out there, and it's still supported via Freexian s Extended LTS. How are we going to keep managing those machines? Obviously, we'll need an older version of Ansible. Pipx to the rescue TL;DR
pipx install --include-deps ansible==10.6.0
pipx inject ansible dnspython    # for community.general.dig
Installing Ansible via pipx Lately I discovered pipx and it's incredibly simple, so I thought I'd give it a try for this use-case. Reminder: pipx allows users to install Python applications in isolated environments. In other words, it doesn't make a mess with your system like pip does, and it doesn't require you to learn how to setup Python virtual environments by yourself. It doesn't ask for root privileges either, as it installs everything under ~/.local/. First thing to know: pipx install ansible won't cut it, it doesn't install the whole Ansible suite. Instead we need to use the --include-deps flag in order to install all the Ansible commands. The output should look something like that:
$ pipx install --include-deps ansible==10.6.0
  installed package ansible 10.6.0, installed using Python 3.12.7
  These apps are now globally available
    - ansible
    - ansible-community
    - ansible-config
    - ansible-connection
    - ansible-console
    - ansible-doc
    - ansible-galaxy
    - ansible-inventory
    - ansible-playbook
    - ansible-pull
    - ansible-test
    - ansible-vault
done!      
Note: at the moment 10.6.0 is the latest release of the 10.x branch, but make sure to check https://pypi.org/project/ansible/#history and install whatever is the latest on this branch. The 11.x branch doesn't work for us, as it's the branch that comes with ansible-core 2.18, and we don't want that. Next: do NOT run pipx ensurepath, even though pipx might suggest that. This is not needed. Instead, check your ~/.profile, it should contain these lines:
# set PATH so it includes user's private bin if it exists
if [ -d "$HOME/.local/bin" ] ; then
    PATH="$HOME/.local/bin:$PATH"
fi
Meaning: ~/.local/bin/ should already be in your path, unless it's the first time you installed a program via pipx and the directory ~/.local/bin/ was just created. If that's the case, you have to log out and log back in. Now, let's open a new terminal and check if we're good:
$ which ansible
/home/me/.local/bin/ansible
$ ansible --version   head -1
ansible [core 2.17.6]
Yep! And that's working already, I can use Ansible with Buster hosts again. What's cool is that we can run ansible to use this specific Ansible version, but we can also run /usr/bin/ansible to run the latest version that is installed via APT. Injecting Python dependencies needed by collections Quickly enough, I realized something odd, apparently the plugin community.general.dig didn't work anymore. After some research, I found a one-liner to test that:
# Works with APT-installed Ansible? Yes!
$ /usr/bin/ansible all -i localhost, -m debug -a msg="  lookup('dig', 'debian.org./A')  "
localhost   SUCCESS =>  
    "msg": "151.101.66.132,151.101.2.132,151.101.194.132,151.101.130.132"
 
# Works with pipx-installed Ansible? No!
$ ansible all -i localhost, -m debug -a msg="  lookup('dig', 'debian.org./A')  "
localhost   FAILED! =>  
  "msg": "An unhandled exception occurred while running the lookup plugin 'dig'.
  Error was a <class 'ansible.errors.AnsibleError'>, original message: The dig
  lookup requires the python 'dnspython' library and it is not installed."
 
The issue here is that we need python3-dnspython, which is installed on my system, but is not installed within the pipx virtual environment. It seems that the way to go is to inject the required dependencies in the venv, which is (again) super easy:
$ pipx inject ansible dnspython
  injected package dnspython into venv ansible
done!      
Problem fixed! Of course you'll have to iterate to install other missing dependencies, depending on which Ansible external plugins are used in your playbooks. Closing thoughts Hopefully there's nothing left to discover and I can get back to work! If there's more quirks and rough edges, drop me an email so that I can update this blog post. Let me also credit another useful blog post on the matter: https://unfriendlygrinch.info/posts/effortless-ansible-installation/

19 November 2024

Aurelien Jarno: AI crawlers should be smarter

It would be fantastic if all those AI companies dedicated some time to make their web crawlers smarter (what about using AI?). Noawadays most of them still stupidly follow every link on a Git frontend. Hint: Changing the display options does not provide more training data!

Melissa Wen: Display/KMS Meeting at XDC 2024: Detailed Report

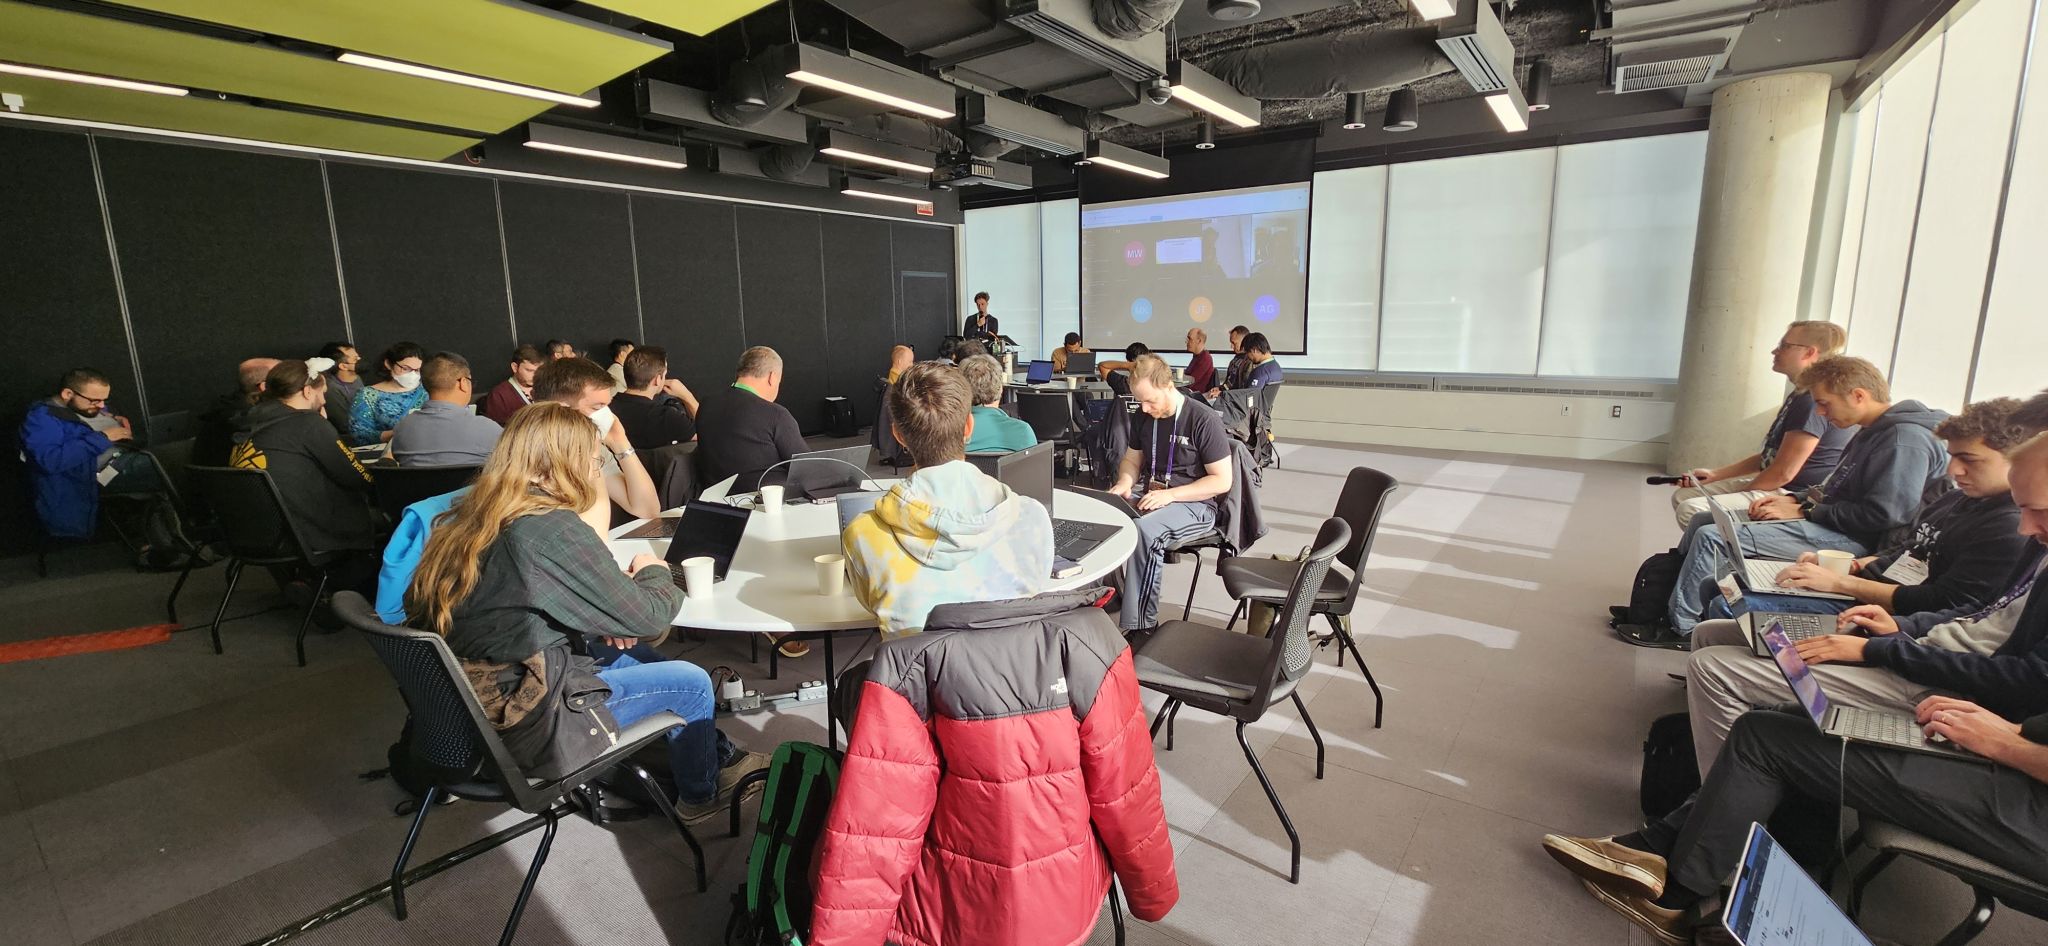
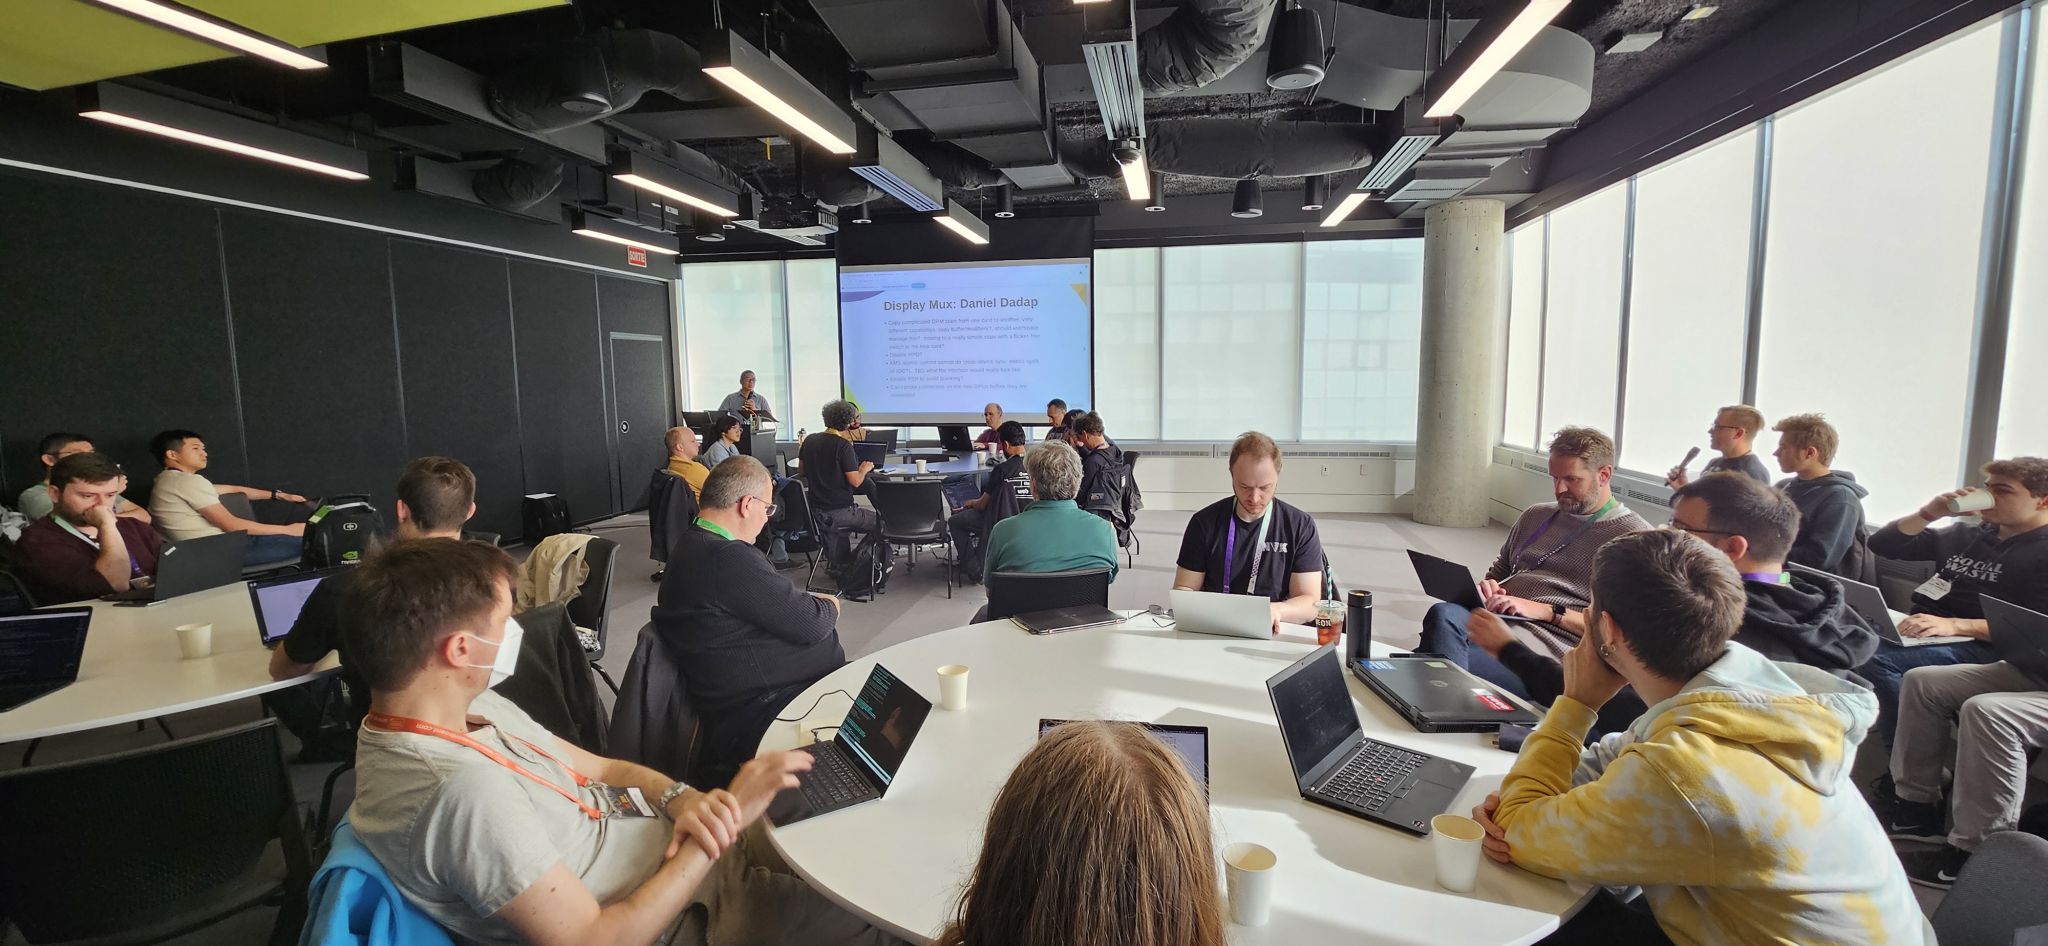
XDC 2024 in Montreal was another fantastic gathering for the Linux Graphics community. It was again a great time to immerse in the world of graphics development, engage in stimulating conversations, and learn from inspiring developers. Many Igalia colleagues and I participated in the conference again, delivering multiple talks about our work on the Linux Graphics stack and also organizing the Display/KMS meeting. This blog post is a detailed report on the Display/KMS meeting held during this XDC edition. Short on Time?
  1. Catch the lightning talk summarizing the meeting here (you can even speed up 2x):
  1. For a quick written summary, scroll down to the TL;DR section.

TL;DR This meeting took 3 hours and tackled a variety of topics related to DRM/KMS (Linux/DRM Kernel Modesetting):
  • Sharing Drivers Between V4L2 and KMS: Brainstorming solutions for using a single driver for devices used in both camera capture and display pipelines.
  • Real-Time Scheduling: Addressing issues with non-blocking page flips encountering sigkills under real-time scheduling.
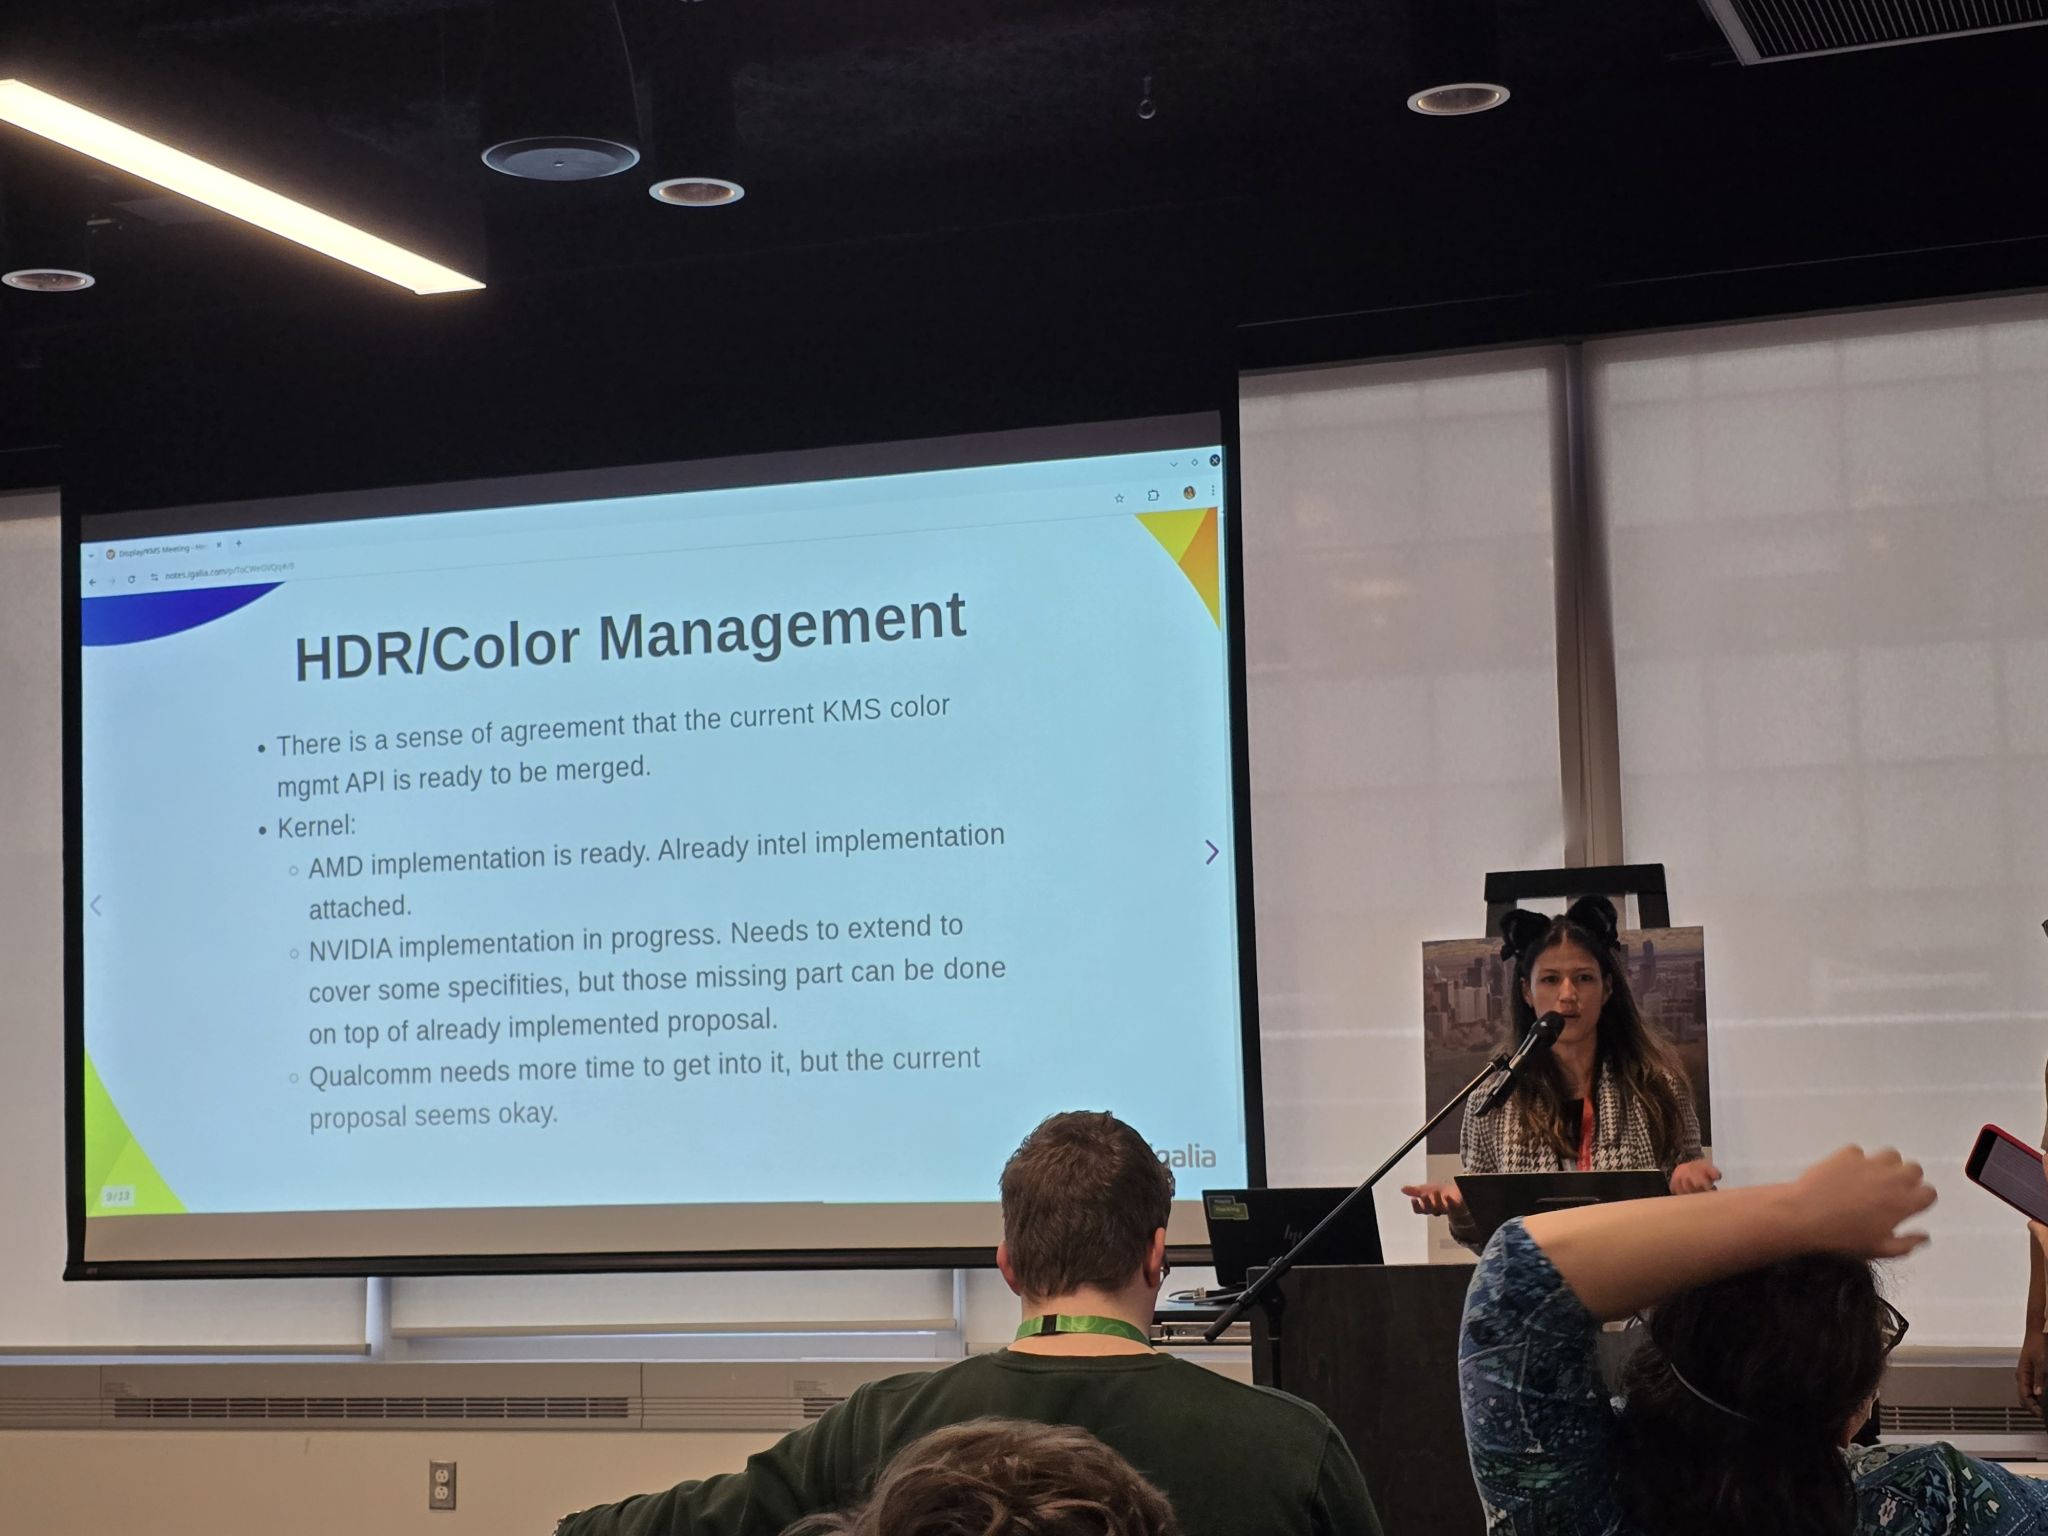
  • HDR/Color Management: Agreement on merging the current proposal, with NVIDIA implementing its special cases on VKMS and adding missing parts on top of Harry Wentland s (AMD) changes.
  • Display Mux: Collaborative design discussions focusing on compositor control and cross-sync considerations.
  • Better Commit Failure Feedback: Exploring ways to equip compositors with more detailed information for failure analysis.

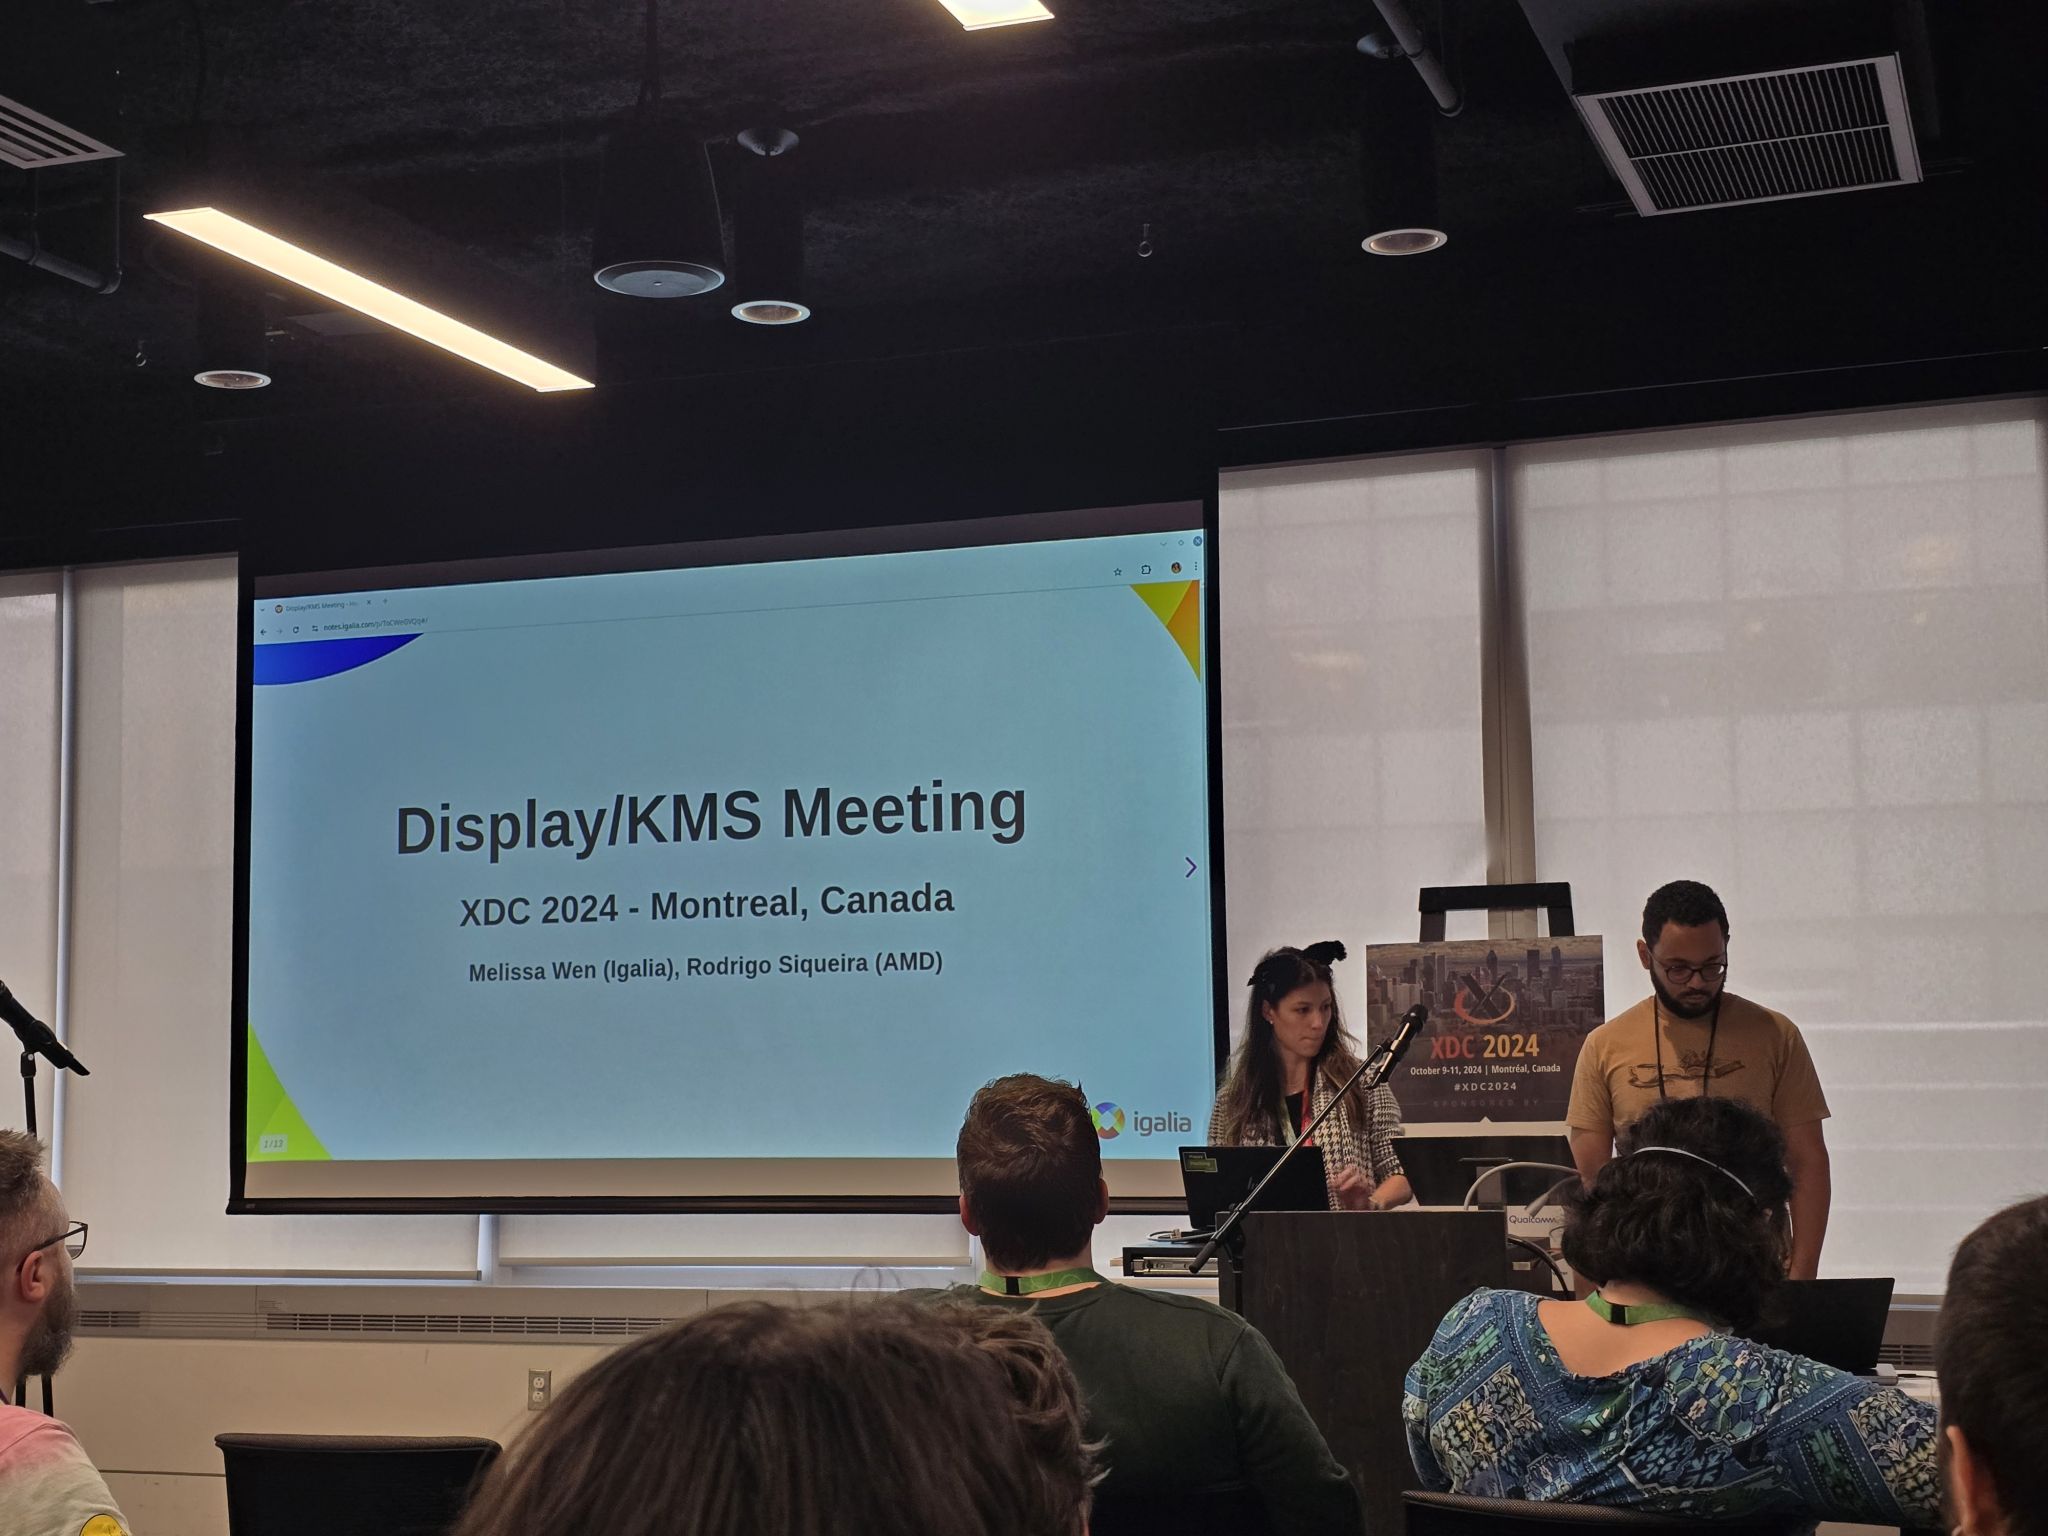
Bringing together Linux display developers in the XDC 2024 While I didn t present a talk this year, I co-organized a Display/KMS meeting (with Rodrigo Siqueira of AMD) to build upon the momentum from the 2024 Linux Display Next hackfest. The meeting was attended by around 30 people in person and 4 remote participants. Speakers: Melissa Wen (Igalia) and Rodrigo Siqueira (AMD) Link: https://indico.freedesktop.org/event/6/contributions/383/ Topics: Similar to the hackfest, the meeting agenda was built over the first two days of the conference and mixed talks follow-up with new ideas and ongoing community efforts. The final agenda covered five topics in the scheduled order:
  1. How to share drivers between V4L2 and DRM for bridge-like components (new topic);
  2. Real-time Scheduling (problems encountered after the Display Next hackfest);
  3. HDR/Color Management (ofc);
  4. Display Mux (from Display hackfest and XDC 2024 talk, bringing AMD and NVIDIA together);
  5. (Better) Commit Failure Feedback (continuing the last minute topic of the Display Next hackfest).

Unpacking the Topics Similar to the hackfest, the meeting agenda evolved over the conference. During the 3 hours of meeting, I coordinated the room and discussion rounds, and Rodrigo Siqueira took notes and also contacted key developers to provide a detailed report of the many topics discussed. From his notes, let s dive into the key discussions!

How to share drivers between V4L2 and KMS for bridge-like components. Led by Laurent Pinchart, we delved into the challenge of creating a unified driver for hardware devices (like scalers) that are used in both camera capture pipelines and display pipelines.
  • Problem Statement: How can we design a single kernel driver to handle devices that serve dual purposes in both V4L2 and DRM subsystems?
  • Potential Solutions:
    1. Multiple Compatible Strings: We could assign different compatible strings to the device tree node based on its usage in either the camera or display pipeline. However, this approach might raise concerns from device tree maintainers as it could be seen as a layer violation.
    2. Separate Abstractions: A single driver could expose the device to both DRM and V4L2 through separate abstractions: drm-bridge for DRM and V4L2 subdev for video. While simple, this approach requires maintaining two different abstractions for the same underlying device.
    3. Unified Kernel Abstraction: We could create a new, unified kernel abstraction that combines the best aspects of drm-bridge and V4L2 subdev. This approach offers a more elegant solution but requires significant design effort and potential migration challenges for existing hardware.

Real-Time Scheduling Challenges We have discussed real-time scheduling during this year Linux Display Next hackfest and, during the XDC 2024, Jonas Adahl brought up issues uncovered while progressing on this front.
  • Context: Non-blocking page-flips can, on rare occasions, take a long time and, for that reason, get a sigkill if the thread doing the atomic commit is a real-time schedule.
  • Action items:
    • Explore alternative backtraces during the busy wait (e.g., ftrace).
    • Investigate the maximum thread time in busy wait to reproduce issues faced by compositors. Tools like RTKit (mutter) can be used for better control (Michel D nzer can help with this setup).

HDR/Color Management This is a well-known topic with ongoing effort on all layers of the Linux Display stack and has been discussed online and in-person in conferences and meetings over the last years. Here s a breakdown of the key points raised at this meeting:
  • Talk: Color operations for Linux color pipeline on AMD devices: In the previous day, Alex Hung (AMD) presented the implementation of this API on AMD display driver.
  • NVIDIA Integration: While they agree with the overall proposal, NVIDIA needs to add some missing parts. Importantly, they will implement these on top of Harry Wentland s (AMD) proposal. Their specific requirements will be implemented on VKMS (Virtual Kernel Mode Setting driver) for further discussion. This VKMS implementation can benefit compositor developers by providing insights into NVIDIA s specific needs.
  • Other vendors: There is a version of the KMS API applied on Intel color pipeline. Apart from that, other vendors appear to be comfortable with the current proposal but lacks the bandwidth to implement it right now.
  • Upstream Patches: The relevant upstream patches were can be found here. [As humorously notes, this series is eagerly awaiting your Acked-by (approval)]
  • Compositor Side: The compositor developers have also made significant progress.
    • KDE has already implemented and validated the API through an experimental implementation in Kwin.
    • Gamescope currently uses a driver-specific implementation but has a draft that utilizes the generic version. However, some work is still required to fully transition away from the driver-specific approach. AP: work on porting gamescope to KMS generic API
    • Weston has also begun exploring implementation, and we might see something from them by the end of the year.
  • Kernel and Testing: The kernel API proposal is well-refined and meets the DRM subsystem requirements. Thanks to Harry Wentland effort, we already have the API attached to two hardware vendors and IGT tests, and, thanks to Xaver Hugl, a compositor implementation in place.
Finally, there was a strong sense of agreement that the current proposal for HDR/Color Management is ready to be merged. In simpler terms, everything seems to be working well on the technical side - all signs point to merging and shipping the DRM/KMS plane color management API!

Display Mux During the meeting, Daniel Dadap led a brainstorming session on the design of the display mux switching sequence, in which the compositor would arm the switch via sysfs, then send a modeset to the outgoing driver, followed by a modeset to the incoming driver.
  • Context:
  • Key Considerations:
    • HPD Handling: There was a general consensus that disabling HPD can be part of the sequence for internal panels and we don t need to focus on it here.
    • Cross-Sync: Ensuring synchronization between the compositor and the drivers is crucial. The compositor should act as the drm-master to coordinate the entire sequence, but how can this be ensured?
    • Future-Proofing: The design should not assume the presence of a mux. In future scenarios, direct sharing over DP might be possible.
  • Action points:
    • Sharing DP AUX: Explore the idea of sharing DP AUX and its implications.
    • Backlight: The backlight definition represents a problem in the mux switch context, so we should explore some of the current specs available for that.

Towards Better Commit Failure Feedback In the last part of the meeting, Xaver Hugl asked for better commit failure feedback.
  • Problem description: Compositors currently face challenges in collecting detailed information from the kernel about commit failures. This lack of granular data hinders their ability to understand and address the root causes of these failures.
To address this issue, we discussed several potential improvements:
  • Direct Kernel Log Access: One idea is to directly load relevant kernel logs into the compositor. This would provide more detailed information about the failure and potentially aid in debugging.
  • Finer-Grained Failure Reporting: We also explored the possibility of separating atomic failures into more specific categories. Not all failures are critical, and understanding the nature of the failure can help compositors take appropriate action.
  • Enhanced Logging: Currently, the dmesg log doesn t provide enough information for user-space validation. Raising the log level to capture more detailed information during failures could be a viable solution.
By implementing these improvements, we aim to equip compositors with the necessary tools to better understand and resolve commit failures, leading to a more robust and stable display system.

A Big Thank You! Huge thanks to Rodrigo Siqueira for these detailed meeting notes. Also, Laurent Pinchart, Jonas Adahl, Daniel Dadap, Xaver Hugl, and Harry Wentland for bringing up interesting topics and leading discussions. Finally, thanks to all the participants who enriched the discussions with their experience, ideas, and inputs, especially Alex Goins, Antonino Maniscalco, Austin Shafer, Daniel Stone, Demi Obenour, Jessica Zhang, Joan Torres, Leo Li, Liviu Dudau, Mario Limonciello, Michel D nzer, Rob Clark, Simon Ser and Teddy Li. This collaborative effort will undoubtedly contribute to the continued development of the Linux display stack. Stay tuned for future updates!

18 November 2024

Dirk Eddelbuettel: RcppArmadillo 14.2.0-1 on CRAN: New Upstream Minor

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1191 other packages on CRAN, downloaded 37.2 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 603 times according to Google Scholar. Conrad released a minor version 14.2.0 a few days ago after we spent about two weeks with several runs of reverse-dependency checks covering corner cases. After a short delay at CRAN due to a false positive on a test, a package failing tests we also failed under the previous version, and some concern over new deprecation warnings _whem using the headers directly as _e.g. mlpack R package does we are now on CRAN. I noticed a missing feature under large 64bit word (for large floating-point matrices) and added an exporter for icube going to double to support the 64-bit integer range (as we already did, of course, for vectors and matrices). Changes since the last CRAN release are summarised below.

Changes in RcppArmadillo version 14.2.0-1 (2024-11-16)
  • Upgraded to Armadillo release 14.2.0 (Smooth Caffeine)
    • Faster handling of symmetric matrices by inv() and rcond()
    • Faster handling of hermitian matrices by inv(), rcond(), cond(), pinv(), rank()
    • Added solve_opts::force_sym option to solve() to force the use of the symmetric solver
    • More efficient handling of compound expressions by solve()
  • Added exporter specialisation for icube for the ARMA_64BIT_WORD case

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

C.J. Collier: Managing HPE SAS Controllers

Notes to self. And anyone else who might find them useful. Following are some ssacli commands which I use infrequently enough that they fall out of cache. This may repeat information in other blogs, but since I search my posts first when commands slip my mind, I thought I d include them here, too. hpacucli is the wrong command. Use ssacli instead.
$ KR='/usr/share/keyrings/hpe.gpg'
$ for fingerprint in \
  882F7199B20F94BD7E3E690EFADD8D64B1275EA3 \
  57446EFDE098E5C934B69C7DC208ADDE26C2B797 \
  476DADAC9E647EE27453F2A3B070680A5CE2D476 ; do \
    curl "https://keyserver.ubuntu.com/pks/lookup?op=get&search=0x$ fingerprint " \
        gpg --no-default-keyring --keyring "$ KR " --import ; \
  done
$ gpg --list-keys --no-default-keyring --keyring "$ KR " 
/usr/share/keyrings/hpe.gpg
---------------------------
pub   rsa2048 2012-12-04 [SC] [expired: 2022-12-02]
      476DADAC9E647EE27453F2A3B070680A5CE2D476
uid           [ expired] Hewlett-Packard Company RSA (HP Codesigning Service)
pub   rsa2048 2014-11-19 [SC] [expired: 2024-11-16]
      882F7199B20F94BD7E3E690EFADD8D64B1275EA3
uid           [ expired] Hewlett-Packard Company RSA (HP Codesigning Service) - 1
pub   rsa2048 2015-12-10 [SCEA] [expires: 2025-12-07]
      57446EFDE098E5C934B69C7DC208ADDE26C2B797
uid           [ unknown] Hewlett Packard Enterprise Company RSA-2048-25 
$ echo "deb [signed-by=$ KR ] http://downloads.linux.hpe.com/SDR/repo/mcp bookworm/current non-free" \
    sudo dd of=/etc/apt/sources.list.d status=none
$ sudo apt-get update
$ sudo apt-get install -y -qq ssacli > /dev/null 2>&1
$ sudo ssacli ctrl all show status
HPE Smart Array P408i-p SR Gen10 in Slot 3
   Controller Status: OK
   Cache Status: OK
   Battery/Capacitor Status: OK
$ sudo ssacli ctrl all show detail
HPE Smart Array P408i-p SR Gen10 in Slot 3
   Bus Interface: PCI
   Slot: 3
   Serial Number: PFJHD0ARCCR1QM
   RAID 6 Status: Enabled
   Controller Status: OK
   Hardware Revision: B
   Firmware Version: 2.65
   Firmware Supports Online Firmware Activation: True
   Driver Supports Online Firmware Activation: True
   Rebuild Priority: High
   Expand Priority: Medium
   Surface Scan Delay: 3 secs
   Surface Scan Mode: Idle
   Parallel Surface Scan Supported: Yes
   Current Parallel Surface Scan Count: 1
   Max Parallel Surface Scan Count: 16
   Queue Depth: Automatic
   Monitor and Performance Delay: 60  min
   Elevator Sort: Enabled
   Degraded Performance Optimization: Disabled
   Inconsistency Repair Policy: Disabled
   Write Cache Bypass Threshold Size: 1040 KiB
   Wait for Cache Room: Disabled
   Surface Analysis Inconsistency Notification: Disabled
   Post Prompt Timeout: 15 secs
   Cache Board Present: True
   Cache Status: OK
   Cache Ratio: 10% Read / 90% Write
   Configured Drive Write Cache Policy: Disable
   Unconfigured Drive Write Cache Policy: Default
   Total Cache Size: 2.0
   Total Cache Memory Available: 1.8
   Battery Backed Cache Size: 1.8
   No-Battery Write Cache: Disabled
   SSD Caching RAID5 WriteBack Enabled: True
   SSD Caching Version: 2
   Cache Backup Power Source: Batteries
   Battery/Capacitor Count: 1
   Battery/Capacitor Status: OK
   SATA NCQ Supported: True
   Spare Activation Mode: Activate on physical drive failure (default)
   Controller Temperature (C): 53
   Cache Module Temperature (C): 43
   Capacitor Temperature  (C): 40
   Number of Ports: 2 Internal only
   Encryption: Not Set
   Express Local Encryption: False
   Driver Name: smartpqi
   Driver Version: Linux 2.1.18-045
   PCI Address (Domain:Bus:Device.Function): 0000:11:00.0
   Negotiated PCIe Data Rate: PCIe 3.0 x8 (7880 MB/s)
   Controller Mode: Mixed
   Port Max Phy Rate Limiting Supported: False
   Latency Scheduler Setting: Disabled
   Current Power Mode: MaxPerformance
   Survival Mode: Enabled
   Host Serial Number: 2M20040D1Q
   Sanitize Erase Supported: True
   Sanitize Lock: None
   Sensor ID: 0
      Location: Capacitor
      Current Value (C): 40
      Max Value Since Power On: 42
   Sensor ID: 1
      Location: ASIC
      Current Value (C): 53
      Max Value Since Power On: 55
   Sensor ID: 2
      Location: Unknown
      Current Value (C): 43
      Max Value Since Power On: 45
   Sensor ID: 3
      Location: Cache
      Current Value (C): 43
      Max Value Since Power On: 44
   Primary Boot Volume: None
   Secondary Boot Volume: None
$ sudo ssacli ctrl all show config
HPE Smart Array P408i-p SR Gen10 in Slot 3  (sn: PFJHD0ARCCR1QM)
   Internal Drive Cage at Port 1I, Box 2, OK
   Internal Drive Cage at Port 2I, Box 2, OK
   Port Name: 1I (Mixed)
   Port Name: 2I (Mixed)
   Array A (SAS, Unused Space: 0  MB)
      logicaldrive 1 (1.64 TB, RAID 6, OK)
      physicaldrive 1I:2:1 (port 1I:box 2:bay 1, SAS HDD, 300 GB, OK)
      physicaldrive 1I:2:2 (port 1I:box 2:bay 2, SAS HDD, 1.2 TB, OK)
      physicaldrive 1I:2:3 (port 1I:box 2:bay 3, SAS HDD, 300 GB, OK)
      physicaldrive 1I:2:4 (port 1I:box 2:bay 4, SAS HDD, 1.2 TB, OK)
      physicaldrive 2I:2:5 (port 2I:box 2:bay 5, SAS HDD, 300 GB, OK)
      physicaldrive 2I:2:6 (port 2I:box 2:bay 6, SAS HDD, 300 GB, OK)
      physicaldrive 2I:2:7 (port 2I:box 2:bay 7, SAS HDD, 1.2 TB, OK)
      physicaldrive 2I:2:8 (port 2I:box 2:bay 8, SAS HDD, 1.2 TB, OK)
   SEP (Vendor ID HPE, Model Smart Adapter) 379  (WWID: 51402EC013705E88, Port: Unknown)
$ sudo ssacli ctrl slot=3 pd 2I:2:7 show detail
HPE Smart Array P408i-p SR Gen10 in Slot 3
   Array A
      physicaldrive 2I:2:7
         Port: 2I
         Box: 2
         Bay: 7
         Status: OK
         Drive Type: Data Drive
         Interface Type: SAS
         Size: 1.2 TB
         Drive exposed to OS: False
         Logical/Physical Block Size: 512/512
         Rotational Speed: 10000
         Firmware Revision: U850
         Serial Number: KZGN1BDE
         WWID: 5000CCA01D247239
         Model: HGST    HUC101212CSS600
         Current Temperature (C): 46
         Maximum Temperature (C): 51
         PHY Count: 2
         PHY Transfer Rate: 6.0Gbps, Unknown
         PHY Physical Link Rate: 6.0Gbps, Unknown
         PHY Maximum Link Rate: 6.0Gbps, 6.0Gbps
         Drive Authentication Status: OK
         Carrier Application Version: 11
         Carrier Bootloader Version: 6
         Sanitize Erase Supported: False
         Shingled Magnetic Recording Support: None
         Drive Unique ID: 5000CCA01D247238
2024-12-09 update I was experiencing a disk failure or predictive failure when I walked into my office this afternoon. I checked this blog post and found the command I used to check the status of the sas array.
cjac@server0:~$ sudo ssacli ctrl all show config
HPE Smart Array P408i-p SR Gen10 in Slot 3  (sn: PFJHD0ARCCR1QM)
   Internal Drive Cage at Port 1I, Box 2, OK
   Internal Drive Cage at Port 2I, Box 2, OK
   Port Name: 1I (Mixed)
   Port Name: 2I (Mixed)
   Array A (SAS, Unused Space: 0  MB)
      logicaldrive 1 (1.64 TB, RAID 6, OK)
      physicaldrive 1I:2:1 (port 1I:box 2:bay 1, SAS HDD, 300 GB, OK)
      physicaldrive 1I:2:2 (port 1I:box 2:bay 2, SAS HDD, 1.2 TB, Predictive Failure)
      physicaldrive 1I:2:3 (port 1I:box 2:bay 3, SAS HDD, 300 GB, OK)
      physicaldrive 1I:2:4 (port 1I:box 2:bay 4, SAS HDD, 1.2 TB, OK)
      physicaldrive 2I:2:5 (port 2I:box 2:bay 5, SAS HDD, 300 GB, OK)
      physicaldrive 2I:2:6 (port 2I:box 2:bay 6, SAS HDD, 300 GB, OK)
      physicaldrive 2I:2:7 (port 2I:box 2:bay 7, SAS HDD, 1.2 TB, OK)
      physicaldrive 2I:2:8 (port 2I:box 2:bay 8, SAS HDD, 300 GB, OK)
   SEP (Vendor ID HPE, Model Smart Adapter) 379  (WWID: 51402EC013705E88, Port: Unknown)
At this point I engaged the under-study to have the flashing disk replaced
cjac@server0:~$ sudo ssacli ctrl all show config
[sudo] password for cjac: 
HPE Smart Array P408i-p SR Gen10 in Slot 3  (sn: PFJHD0ARCCR1QM)
   Internal Drive Cage at Port 1I, Box 2, OK
   Internal Drive Cage at Port 2I, Box 2, OK
   Port Name: 1I (Mixed)
   Port Name: 2I (Mixed)
   Array A (SAS, Unused Space: 0  MB)
      logicaldrive 1 (1.64 TB, RAID 6, Recovering, 56.43% complete)
      physicaldrive 1I:2:1 (port 1I:box 2:bay 1, SAS HDD, 300 GB, OK)
      physicaldrive 1I:2:2 (port 1I:box 2:bay 2, SAS HDD, 300 GB, Rebuilding)
      physicaldrive 1I:2:3 (port 1I:box 2:bay 3, SAS HDD, 300 GB, OK)
      physicaldrive 1I:2:4 (port 1I:box 2:bay 4, SAS HDD, 1.2 TB, OK)
      physicaldrive 2I:2:5 (port 2I:box 2:bay 5, SAS HDD, 300 GB, OK)
      physicaldrive 2I:2:6 (port 2I:box 2:bay 6, SAS HDD, 300 GB, OK)
      physicaldrive 2I:2:7 (port 2I:box 2:bay 7, SAS HDD, 1.2 TB, OK)
      physicaldrive 2I:2:8 (port 2I:box 2:bay 8, SAS HDD, 300 GB, OK)
   SEP (Vendor ID HPE, Model Smart Adapter) 379  (WWID: 51402EC013705E88, Port: Unknown)
In the next and future output, I will elide duplicate lines
cjac@server0:~$ date ; sudo ssacli ctrl all show config
Mon Dec  9 07:36:44 PM PST 2024 ... logicaldrive 1 (1.64 TB, RAID 6, Recovering, 66.85% complete)...
Mon Dec  9 07:39:25 PM PST 2024 ... logicaldrive 1 (1.64 TB, RAID 6, Recovering, 68.97% complete) ...
cjac@server0:~$ date ; sudo ssacli ctrl all show config   grep Recovering
Mon Dec  9 07:43:05 PM PST 2024 ... logicaldrive 1 (1.64 TB, RAID 6, Recovering, 71.85% complete)
Mon Dec  9 07:43:57 PM PST 2024 ... logicaldrive 1 (1.64 TB, RAID 6, Recovering, 72.55% complete)
cjac@server0:~$ sleep 5m ; date ; sudo ssacli ctrl all show config   grep Recovering
Mon Dec  9 07:49:43 PM PST 2024 ... logicaldrive 1 (1.64 TB, RAID 6, Recovering, 77.00% complete)
cjac@server0:~$ date ; sudo ssacli ctrl all show config   grep -e 1I:2:2 -e logicaldrive
Mon Dec  9 11:36:14 PM PST 2024 ... logicaldrive 1 (1.64 TB, RAID 6, OK)
physicaldrive 1I:2:2 (port 1I:box 2:bay 2, SAS HDD, 300 GB, OK)

Philipp Kern: debian.org now supports Security Key-backed SSH keys

debian.org's infrastructure now supports using Security Key-backed SSH keys. DDs (and guests) can use the mail gateway to add SSH keys of the types sk-ecdsa-sha2-nistp256@openssh.com and sk-ssh-ed25519@openssh.com to their LDAP accounts.This was done in support of hardening our infrastructure: Hopefully we can require these hardware-backed keys for sensitive machines in the future, to have some assertion that it is a human that is connecting to them.
As some of us shell to machines a little too often, I also wrote a small SSH CA that issues short-lived certificates (documentation). It requires the user to login via SSH using an SK-backed key and then issues a certificate that is valid for less than a day. For cases where you need to frequently shell to a machine or to a lot of machines at once that should be a nice compromise of usability vs. security.The capabilities of various keys differ a lot and it is not always easy to determine what feature set they support. Generally SK-backed keys work with FIDO U2F keys, if you use the ecdsa key type. Resident keys (i.e. keys stored on the token, to be used from multiple devices) require FIDO2-compatible keys. no-touch-required is its own maze, e.g. the flag is not properly restored today when pulling the public key from a resident key. The latter is also one reason for writing my own CA.SomeoneTM should write up a matrix on what is supported where and how. In the meantime it is probably easiest to generate an ed25519 key - or if that does not work an ecdsa key - and make a backup copy of the resulting on-disk key file. And copy that around to other devices (or OSes) that require access to the key.

Russ Allbery: Review: Delilah Green Doesn't Care

Review: Delilah Green Doesn't Care, by Ashley Herring Blake
Series: Bright Falls #1
Publisher: Jove
Copyright: February 2022
ISBN: 0-593-33641-0
Format: Kindle
Pages: 374
Delilah Green Doesn't Care is a sapphic romance novel. It's the first of a trilogy, although in the normal romance series fashion each book follows a different protagonist and has its own happy ending. It is apparently classified as romantic comedy, which did not occur to me while reading but which I suppose I can see in retrospect. Delilah Green got the hell out of Bright Falls as soon as she could and tried not to look back. After her father died, her step-mother lavished all of her perfectionist attention on her overachiever step-sister, leaving Delilah feeling like an unwanted ghost. She escaped to New York where there was space for a queer woman with an acerbic personality and a burgeoning career in photography. Her estranged step-sister's upcoming wedding was not a good enough reason to return to the stifling small town of her childhood. The pay for photographing the wedding was, since it amounted to three months of rent and trying to sell photographs in galleries was not exactly a steady living. So back to Bright Falls Delilah goes. Claire never left Bright Falls. She got pregnant young and ended up with a different life than she expected, although not a bad one. Now she's raising her daughter as a single mom, running the town bookstore, and dealing with her unreliable ex. She and Iris are Astrid Parker's best friends and have been since fifth grade, which means she wants to be happy for Astrid's upcoming wedding. There's only one problem: the groom. He's a controlling, boorish ass, but worse, Astrid seems to turn into a different person around him. Someone Claire doesn't like. Then, to make life even more complicated, Claire tries to pick up Astrid's estranged step-sister in Bright Falls's bar without recognizing her. I have a lot of things to say about this novel, but here's the core of my review: I started this book at 4pm on a Saturday because I hadn't read anything so far that day and wanted to at least start a book. I finished it at 11pm, having blown off everything else I had intended to do that evening, completely unable to put it down. It turns out there is a specific type of romance novel protagonist that I absolutely adore: the sarcastic, confident, no-bullshit character who is willing to pick the fights and say the things that the other overly polite and anxious characters aren't able to get out. Astrid does not react well to criticism, for reasons that are far more complicated than it may first appear, and Claire and Iris have been dancing around the obvious problems with her surprise engagement. As the title says, Delilah thinks she doesn't care: she's here to do a job and get out, and maybe she'll get to tweak her annoying step-sister a bit in the process. But that also means that she is unwilling to play along with Astrid's obsessively controlling mother or her obnoxious fiance, and thus, to the barely disguised glee of Claire and Iris, is a direct threat to the tidy life that Astrid's mother is trying to shoehorn her daughter into. This book is a great example of why I prefer sapphic romances: I think this character setup would not work, at least for me, in a heterosexual romance. Delilah's role only works if she's a woman; if a male character were the sarcastic conversational bulldozer, it would be almost impossible to avoid falling into the gender stereotype of a male rescuer. If this were a heterosexual romance trying to avoid that trap, the long-time friend who doesn't know how to directly confront Astrid would have to be the male protagonist. That could work, but it would be a tricky book to write without turning it into a story focused primarily on the subversion of gender roles. Making both protagonists women dodges the problem entirely and gives them so much narrative and conceptual space to simply be themselves, rather than characters obscured by the shadows of societal gender rules. This is also, at it's core, a book about friendship. Claire, Astrid, and Iris have the sort of close-knit friend group that looks exclusive and unapproachable from the outside. Delilah was the stereotypical outsider, mocked and excluded when they thought of her at all. This, at least, is how the dynamics look at the start of the book, but Blake did an impressive job of shifting my understanding of those relationships without changing their essential nature. She fleshes out all of the characters, not just the romantic leads, and adds complexity, nuance, and perspective. And, yes, past misunderstanding, but it's mostly not the cheap sort that sometimes drives romance plots. It's the misunderstanding rooted in remembered teenage social dynamics, the sort of misunderstanding that happens because communication is incredibly difficult, even more difficult when one has no practice or life experience, and requires knowing oneself well enough to even know what to communicate. The encounter between Delilah and Claire in the bar near the start of the book is cornerstone of the plot, but the moment that grabbed me and pulled me in was Delilah's first interaction with Claire's daughter Ruby. That was the point when I knew these were characters I could trust, and Blake never let me down. I love how Ruby is handled throughout this book, with all of the messy complexity of a kid of divorced parents with her own life and her own personality and complicated relationships with both parents that are independent of the relationship their parents have with each other. This is not a perfect book. There's one prank scene that I thought was excessively juvenile and should have been counter-productive, and there's one tricky question of (nonsexual) consent that the book raises and then later seems to ignore in a way that bugged me after I finished it. There is a third-act breakup, which is not my favorite plot structure, but I think Blake handles it reasonably well. I would probably find more niggles and nitpicks if I re-read it more slowly. But it was utterly engrossing reading that exactly matched my mood the day that I picked it up, and that was a fantastic reading experience. I'm not much of a romance reader and am not the traditional audience for sapphic romance, so I'm probably not the person you should be looking to for recommendations, but this is the sort of book that got me to immediately buy all of the sequels and start thinking about a re-read. It's also the sort of book that dragged me back in for several chapters when I was fact-checking bits of my review. Take that recommendation for whatever it's worth. Content note: Reviews of Delilah Green Doesn't Care tend to call it steamy or spicy. I have no calibration for this for romance novels. I did not find it very sex-focused (I have read genre fantasy novels with more sex), but there are several on-page sex scenes if that's something you care about one way or the other. Followed by Astrid Parker Doesn't Fail. Rating: 9 out of 10

17 November 2024

Russ Allbery: Review: Dark Deeds

Review: Dark Deeds, by Michelle Diener
Series: Class 5 #2
Publisher: Eclipse
Copyright: January 2016
ISBN: 0-6454658-4-4
Format: Kindle
Pages: 340
Dark Deeds is the second book of the self-published Class 5 science fiction romance series. It is a sequel to Dark Horse and will spoil the plot of that book, but it follows the romance series convention of switching to a new protagonist in the same universe and telling a loosely-connected story. Fiona, like Rose in the previous book, was kidnapped by the Tecran in one of their Class 5 ships, although that's not entirely obvious at the start of the story. The book opens with her working as a slave on a Garmman trading ship while its captain works up the nerve to have her killed. She's spared this fate when the ship is raided by Krik pirates. Some brave fast-talking, and a touch of honor among thieves, lets her survive the raid and be rescued by a pursuing Grih battleship, with a useful electronic gadget as a bonus. The author uses the nickname "Fee" for Fiona throughout this book and it was like nails on a chalkboard every time. I had to complain about that before getting into the review. If you've read Dark Horse, you know the formula: lone kidnapped human woman, major violations of the laws against mistreatment of sentient beings that have the Grih furious on her behalf, hunky Grih starship captain who looks like a space elf, all the Grih are fascinated by her musical voice, she makes friends with a secret AI... Diener found a formula that worked well enough that she tried it again, and it would not surprise me if the formula repeated through the series. You should not go into this book expecting to be surprised. That said, the formula did work the first time, and it largely does work again. I thoroughly enjoyed Dark Horse and wanted more, and this is more, delivered on cue. There are worse things, particularly if you're a Kindle Unlimited reader (I am not) and are therefore getting new installments for free. The Tecran fascination with kidnapping human women is explained sufficiently in Fiona's case, but I am mildly curious how Diener will keep justifying it through the rest of the series. (Maybe the formula will change, but I doubt it.) To give Diener credit, this is not a straight repeat of the first book. Fiona is similar to Rose but not identical; Rose had an unshakable ethical calm, and Fiona is more of a scrapper. The Grih are not stupid and, given the amount of chaos Rose unleashed in the previous book, treat the sudden appearance of another human woman with a great deal more caution and suspicion. Unfortunately, this also means far less of my favorite plot element of the first book: the Grih being constantly scandalized and furious at behavior the protagonist finds sadly unsurprising. Instead, this book has quite a bit more action. Dark Horse was mostly character interactions and tense negotiations, with most of the action saved for the end. Dark Deeds replaces a lot of the character work with political plots and infiltrating secret military bases and enemy ships. The AI (named Eazi this time) doesn't show up until well into the book and isn't as much of a presence as Sazo. Instead, there's a lot more of Fiona being drafted into other people's fights, which is entertaining enough while it's happening but which wasn't as delightful or memorable as Rose's story. The writing continues to be serviceable but not great. It's a bit cliched and a bit awkward. Also, Diener uses paragraph breaks for emphasis. It's hard to stop noticing it once you see it. Thankfully, once the story gets going and there's more dialogue, she tones that down, or perhaps I stopped noticing. It's that kind of book (and that kind of series): it's a bit rough to get started, but then there's always something happening, the characters involve a whole lot of wish-fulfillment but are still people I like reading about, and it's the sort of unapologetic "good guys win" type of light science fiction that is just the thing when one simply wants to be entertained. Once I get into the book, it's easy to overlook its shortcomings. I spent Dark Horse knowing roughly what would happen but wondering about the details. I spent Dark Deeds fairly sure of the details and wondering when they would happen. This wasn't as fun of an experience, but the details were still enjoyable and I don't regret reading it. I am hoping that the next book will be more of a twist, or will have a character more like Rose (or at least a character with a better nickname). Sort of recommended if you liked Dark Horse and really want more of the same. Followed by Dark Minds, which I have already purchased. Rating: 6 out of 10

14 November 2024

Reproducible Builds: Reproducible Builds mourns the passing of Lunar

The Reproducible Builds community sadly announces it has lost its founding member. J r my Bobbio aka Lunar passed away on Friday November 8th in palliative care in Rennes, France. Lunar was instrumental in starting the Reproducible Builds project in 2013 as a loose initiative within the Debian project. Many of our earliest status reports were written by him and many of our key tools in use today are based on his design. Lunar was a resolute opponent of surveillance and censorship, and he possessed an unwavering energy that fueled his work on Reproducible Builds and Tor. Without Lunar s far-sightedness, drive and commitment to enabling teams around him, Reproducible Builds and free software security would not be in the position it is in today. His contributions will not be forgotten, and his high standards and drive will continue to serve as an inspiration to us as well as for the other high-impact projects he was involved in. Lunar s creativity, insight and kindness were often noted. He will be greatly missed.

Other tributes:

Stefano Zacchiroli: In memory of Lunar

In memory of Lunar I've had the incredible fortune to share the geek path of Lunar through life on multiple occasions. First, in Debian, beginning some 15+ years ago, where we were fellow developers and participated in many DebConf editions together. Then, on the deontology committee of Nos Oignons, a non-profit organization initiated by Lunar to operate Tor relays in France. This was with the goal of diversifying relay operators and increasing access to censorship-resistance technology for everyone in the world. It was something truly innovative and unheard of at the time in France. Later, as a member of the steering committee of Reproducible Builds, a project that Lunar brought to widespread geek popularity with a seminal "Birds of a Feather" session at DebConf13 (and then many other talks with fellow members of the project in the years to come). A decade later, Reproducible Builds is having a major impact throughout the software industry, primarily due to growing fears about the security of the software supply chain. Finally, we had the opportunity to recruit Lunar a couple of years ago at Software Heritage, where he insisted on working until he was able to, as part of a team he loved, and that loved him back. In addition to his numerous technical contributions to the initiative, he also facilitated our first ever multi-day team seminar. The event was so successful that it has been confirmed as a long-awaited yearly recurrence by all team members. I fondly remember one of the last conversations I had with Lunar, a few months ago, when he told me how proud he was not only of having started Nos Oignons and contributed to the ignition of Reproducible Builds, but specifically about the fact that both initiatives were now thriving without being dependent on him. He was likely thinking about a future world without him, but also realizing how impactful his activism had been on the past and present world. Lunar changed the world for the better and left behind a trail of love and fond memories. Che la terra ti sia lieve, compagno. --- Zack

13 November 2024

Russell Coker: Modern Sleep

Julius wrote an insightful blog post about the modern sleep issue with Windows [1]. Basically Microsoft decided that the right way to run laptops is to never entirely sleep, which uses more battery but gives better options for waking up and doing things. I agree with Microsoft in concept and this is something that is a problem that can be solved. A phone can run for 24+ hours without ever fully sleeping, a laptop has a more power hungry CPU and peripherals but also has a much larger battery so it should be able to do the same. Some of the reviews for Snapdragon Windows laptops claim up to 22 hours of actual work without charging! So having suspend not really stop the system should be fine. The ability of a phone to never fully sleep is a change in quality of the usage experience, it means that you can access it and immediately have it respond and it means that all manner of services can be checked for new updates which may require a notification to the user. The XMPP protocol (AKA Jabber) was invented in 1999 which was before laptops were common and Instant Message systems were common long before then. But using Jabber or another IM system on a desktop was a very different experience to using it on a laptop and using it on a phone is different again. The modern sleep allows laptops to act like phones in regard to such messaging services. Currently I have Matrix IM clients running on my Android phone and Linux laptop, if I get a notification that takes much typing for a response then I get out my laptop to respond. If I had an ARM based laptop that never fully shut down I would have much less need for Matrix on a phone. Making modern sleep popular will lead to more development of OS software to work with it. For Linux this will hopefully mean that regular Linux distributions (as opposed to Android which while running a Linux kernel is very different to Debian etc) get better support for such things and therefore become more usable on phones. Debian on a Librem 5 or PinePhonePro isn t very usable due to battery life issues. A laptop with an LTE card can be used for full mobile phone functionality. With modern sleep this is a viable option. I am tempted to make a laptop with LTE card and bluetooth headset a replacement for my phone. Some people will say what if someone tries to call you when it s not convenient to have your laptop with you , my response is what if people learn to not expect me to answer the phone at any time as they managed that in the 90s . Seriously SMS or Matrix me if you want an instant response and if you want a long chat schedule it via SMS or Matrix. Dell has some useful advice about how to use their laptops (and probably most laptops from recent times) in this regard [2]. You can t close the lid before unplugging the power cable you have to unplug first and then close. You shouldn t put a laptop in a sealed bag for travel either. This is a terrible situation, you can put a tablet in a bag and don t need to take any special precautions when unplugging and laptops should work the same. The end result of what Microsoft, Dell, Intel, and others are doing will be good but they are making some silly design choices along the way! I blame Intel mostly for selling laptop CPUs with TDPs >40W! For an amusing take on this Linus Tech Tips has a video about being forced to use MacBooks by Microsoft s implementation of Modern Sleep [3]. I ll try out some ARM laptops in the near future and blog about how well they work on Debian.

Louis-Philippe V ronneau: Montreal's Debian & Stuff - November 2024

Our Debian User Group met on November 2nd after a somewhat longer summer hiatus than normal. It was lovely to see a bunch of people again and to be able to dedicate a whole day to hacking :) Here is what we did: lavamind: pollo: anarcat: LeLutin: tvaz: tassia: Pictures This time around, we went back to Foulab. Thanks for hosting us! As always, the hacklab was full of interesting stuff and I took a few (bad) pictures for this blog post: Two old video cameras and a 'My First Sony' tape recorder An ALP HT-286 machine with a very large 'turbo' button A New Hampshire 'IPROUTE' vanity license plate

12 November 2024

Paul Tagliamonte: Complex for Whom?

In basically every engineering organization I ve ever regarded as particularly high functioning, I ve sat through one specific recurring conversation which is not a conversation about complexity . Things are good or bad because they are or aren t complex, architectures needs to be redone because it s too complex some refactor of whatever it is won t work because it s too complex. You may have even been a part of some of these conversations or even been the one advocating for simple light-weight solutions. I ve done it. Many times. Rarely, if ever, do we talk about complexity within its rightful context complexity for whom. Is a solution complex because it s complex for the end user? Is it complex if it s complex for an API consumer? Is it complex if it s complex for the person maintaining the API service? Is it complex if it s complex for someone outside the team maintaining it to understand? Complexity within a problem domain I ve come to believe, is fairly zero-sum there s a fixed amount of complexity in the problem to be solved, and you can choose to either solve it, or leave it for those downstream of you to solve that problem on their own. That being said, while I believe there is a lower bound in complexity to contend with for a problem, I do not believe there is an upper bound to the complexity of solutions possible. It is always possible, and in fact, very likely that teams create problems for themselves while trying to solve a problem. The rest of this post is talking to the lower bound. When getting feedback on an early draft of this blog post, I ve been informed that Fred Brooks coined a term for what I call lower bound complexity Essential Complexity , in the paper No Silver Bullet Essence and Accident in Software Engineering , which is a better term and can be used interchangeably.

Complexity Culture In a large enough organization, where the team is high functioning enough to have and maintain trust amongst peers, members of the team will specialize. People will begin to engage with subsets of the work to be done, and begin to have their efficacy measured against that part of the organization s problems. Incentives shift, and over time it becomes increasingly likely that two engineers may have two very different priorities when working on the same system together. Someone accountable for uptime and tasked with responding to outages will begin to resist changes. Someone accountable for rapidly delivering features will resist gates between them and their users. Companies (either wittingly or unwittingly) will deal with this by tasking engineers with both production (feature development) and operational tasks (maintenance), so the difference in incentives isn t usually as bad as it could be. When we get a bunch of folks from far-flung corners of an organization in a room, fire up a slide deck and throw up some aspirational to-be architecture diagram in order to get a sign-off to solve some problem (be it someone needs a credible promotion packet, new feature needs to get delivered, or the system has begun to fail and needs fixing), the initial reaction will, more often than I d like, start to devolve into a discussion of how this is going to introduce a bunch of complexity, going to be hard to maintain, why can t you make it less complex? Right around here is when I start to try and contextualize the conversation happening around me understand what complexity is that being discussed, and understand who is taking on that burden. Think about who should be owning that problem, and work through the tradeoffs involved. Is it best solved here, or left to consumers (be them other systems, developers, or users). Should something become an API call s optional param, taking on all the edge-cases and on, or should users have to implement the logic using the data you return (leaving everyone else to take on all the edge-cases and maintenance)? Should you process the data, or require the user to preprocess it for you? Frequently it s right to make an active and explicit decision to simplify and leave problems to be solved downstream, since they may not actually need to be solved or perhaps you expect consumers will want to own the specifics of how the problem is solved, in which case you leave lots of documentation and examples. Many other times, especially when it s something downstream consumers are likely to hit, it s best solved internal to the system, since the only thing that can come of leaving it unsolved are bugs, frustration and half-correct solutions. This is a grey-space of tradeoffs, not a clear decision tree. No one wants the software manifestation of a katamari ball or a junk drawer, nor does anyone want a half-baked service unable to handle the simplest use-case.

Head-in-sand as a Service Popoffs about how complex something is, are, to a first approximation, best understood as meaning complicated for the person making comments . A lot of the #thoughtleadership believe that an AWS hosted EKS k8s cluster running images built by CI talking to an AWS hosted PostgreSQL RDS is not complex. They re right. Mostly right. This is less complex less complex for them. It s not, however, without complexity and its own tradeoffs it s just complexity that they do not have to deal with. Now they don t have to maintain machines that have pesky operating systems or hard drive failures. They don t have to deal with updating the version of k8s, nor ensuring the backups work. No one has to push some artifact to prod manually. Deployments happen unattended. You click a button and get a cluster. On the other hand, developers outside the ops function need to deal with troubleshooting CI, debugging access control rules encoded in turing complete YAML, permissions issues inside the cluster due to whatever the fuck a service mesh is, everyone needs to learn how to use some k8s tools they only actually use during a bad day, likely while doing some x.509 troubleshooting to connect to the cluster (an internal only endpoint; just port forward it) not to mention all sorts of rules to route packets to their project (a single repo s binary being run in 3 containers on a single vm host). Beyond that, there s the invisible complexity complexity on the interior of a service you depend on. I think about the dozens of teams maintaining the EKS service (which is either run on EC2 instances, or alternately, EC2 instances in a trench coat, moustache and even more shell scripts), the RDS service (also EC2 and shell scripts, but this time accounting for redundancy, backups, availability zones), scores of hypervisors pulled off the shelf (xen, kvm) smashed together with the ones built in-house (firecracker, nitro, etc) running on hardware that has to be refreshed and maintained continuously. Every request processed by network ACL rules, AWS IAM rules, security group rules, using IP space announced to the internet wired through IXPs directly into ISPs. I don t even want to begin to think about the complexity inherent in how those switches are designed. Shitloads of complexity to solve problems you may or may not have, or even know you had. What s more complex? An app running in an in-house 4u server racked in the office s telco closet in the back running off the office Verizon line, or an app running four hypervisors deep in an AWS datacenter? Which is more complex to you? What about to your organization? In total? Which is more prone to failure? Which is more secure? Is the complexity good or bad? What type of Complexity can you manage effectively? Which threaten the system? Which threaten your users?

COMPLEXIVIBES This extends beyond Engineering. Decisions regarding what tools are we able to use be them existing contracts with cloud providers, CIO mandated SaaS products, a list of the only permissible open source projects will incur costs in terms of expressed complexity . Pinning open source projects to a fixed set makes SBOM production less complex . Using only one SaaS provider s product suite (even if its terrible, because it has all the types of tools you need) makes accreditation less complex . If all you have is a contract with Pauly T s lowest price technically acceptable artisinal cloudary and haberdashery, the way you pay for your compute is less complex for the CIO shop, though you will find yourself building your own hosted database template, mechanism to spin up a k8s cluster, and all the operational and technical burden that comes with it. Or you won t and make it everyone else s problem in the organization. Nothing you can do will solve for the fact that you must now deal with this problem somewhere because it was less complicated for the business to put the workloads on the existing contract with a cut-rate vendor. Suddenly, the decision to reduce complexity because of an existing contract vehicle has resulted in a huge amount of technical risk and maintenance burden being onboarded. Complexity you would otherwise externalize has now been taken on internally. With a large enough organizations (specifically, in this case, i m talking about you, bureaucracies), this is largely ignored or accepted as normal since the personnel cost is understood to be free to everyone involved. Doing it this way is more expensive, more work, less reliable and less maintainable, and yet, somehow, is, in a lot of ways, less complex to the organization. It s particularly bad with bureaucracies, since screwing up a contract will get you into much more trouble than delivering a broken product, leaving basically no reason for anyone to care to fix this. I can t shake the feeling that for every story of technical mandates gone awry, somewhere just out of sight there s a decisionmaker optimizing for what they believe to be the least amount of complexity least hassle, fewest unique cases, most consistency as they can. They freely offload complexity from their accreditation and risk acceptance functions through mandates. They will never have to deal with it. That does not change the fact that someone does.

TC;DR (TOO COMPLEX; DIDN T REVIEW) We wish to rid ourselves of systemic Complexity after all, complexity is bad, simplicity is good. Removing upper-bound own-goal complexity ( accidental complexity in Brooks s terms) is important, but once you hit the lower bound complexity, the tradeoffs become zero-sum. Removing complexity from one part of the system means that somewhere else maybe outside your organization or in a non-engineering function must grow it back. Sometimes, the opposite is the case, such as when a previously manual business processes is automated. Maybe that s a good idea. Maybe it s not. All I know is that what doesn t help the situation is conflating complexity with everything we don t like legacy code, maintenance burden or toil, cost, delivery velocity.
  • Complexity is not the same as proclivity to failure. The most reliable systems I ve interacted with are unimaginably complex, with layers of internal protection to prevent complete failure. This has its own set of costs which other people have written about extensively.
  • Complexity is not cost. Sometimes the cost of taking all the complexity in-house is less, for whatever value of cost you choose to use.
  • Complexity is not absolute. Something simple from one perspective may be wildly complex from another. The impulse to burn down complex sections of code is helpful to have generally, but sometimes things are complicated for a reason, even if that reason exists outside your codebase or organization.
  • Complexity is not something you can remove without introducing complexity elsewhere. Just as not making a decision is a decision itself; choosing to require someone else to deal with a problem rather than dealing with it internally is a choice that needs to be considered in its full context.
Next time you re sitting through a discussion and someone starts to talk about all the complexity about to be introduced, I want to pop up in the back of your head, politely asking what does complex mean in this context? Is it lower bound complexity? Is this complexity desirable? Is what they re saying mean something along the lines of I don t understand the problems being solved, or does it mean something along the lines of this problem should be solved elsewhere? Do they believe this will result in more work for them in a way that you don t see? Should this not solved at all by changing the bounds of what we should accept or redefine the understood limits of this system? Is the perceived complexity a result of a decision elsewhere? Who s taking this complexity on, or more to the point, is failing to address complexity required by the problem leaving it to others? Does it impact others? How specifically? What are you not seeing? What can change? What should change?

Sven Hoexter: fluxcd: Validate flux-system Root Kustomization

Not entirely sure how people use fluxcd, but I guess most people have something like a flux-system flux kustomization as the root to add more flux kustomizations to their kubernetes cluster. Here all of that is living in a monorepo, and as we're all humans people figure out different ways to break it, which brings the reconciliation of the flux controllers down. Thus we set out to do some pre-flight validations. Note1: We do not use flux variable substitutions for those root kustomizations, so if you use those, you've to put additional work into the validation and pipe things through flux envsubst. First Iteration: Just Run kustomize Like Flux Would Do It With a folder structure where we've a cluster folder with subfolders per cluster, we just run a for loop over all of them:
for CLUSTER in $ CLUSTERS ; do
    pushd clusters/$ CLUSTER 
    # validate if we can create and build a flux-system like kustomization file
    kustomize create --autodetect --recursive
    if ! kustomize build . -o /dev/null 2> error.log; then
        echo "Error building flux-system kustomization for cluster $ CLUSTER "
        cat error.log
    fi
    popd
done
Second Iteration: Make Sure Our Workload Subfolder Have a kustomization.yaml Next someone figured out that you can delete some yaml files from a workload subfolder, including the kustomization.yaml, but not all of them. That left around a resource definition which lacks some other referenced objects, but is still happily included into the root kustomization by kustomize create and flux, which of course did not work. Thus we started to catch that as well in our growing for loop:
for CLUSTER in $ CLUSTERS ; do
    pushd clusters/$ CLUSTER 
    # validate if we can create and build a flux-system like kustomization file
    kustomize create --autodetect --recursive
    if ! kustomize build . -o /dev/null 2> error.log; then
        echo "Error building flux-system kustomization for cluster $ CLUSTER "
        cat error.log
    fi
    # validate if we always have a kustomization file in folders with yaml files
    for CLFOLDER in $(find . -type d); do
        test -f $ CLFOLDER /kustomization.yaml && continue
        test -f $ CLFOLDER /kustomization.yml && continue
        if [[ $(find $ CLFOLDER  -maxdepth 1 \( -name '*.yaml' -o -name '*.yml' \) -type f wc -l) != 0 ]]; then
            echo "Error Cluster $ CLUSTER  folder $ CLFOLDER  lacks a kustomization.yaml"
        fi
    done
    popd
done
Note2: I shortened those snippets to the core parts. In our case some things are a bit specific to how we implemented the execution of those checks in GitHub action workflows. Hope that's enough to transport the idea of what to check for.

Next.

Previous.