Search Results: "cas"

6 June 2021

Evgeni Golov: Controlling Somfy roller shutters using an ESP32 and ESPHome

Our house has solar powered, remote controllable roller shutters on the roof windows, built by the German company named HEIM & HAUS. However, when you look closely at the remote control or the shutter motor, you'll see another brand name: SIMU. As the shutters don't have any wiring inside the house, the only way to control them is via the remote interface. So let's go on the Internet and see how one can do that, shall we? ;) First thing we learn is that SIMU remote stuff is just re-branded Somfy. Great, another name! Looking further we find that Somfy uses some obscure protocol to prevent (replay) attacks (spoiler: it doesn't!) and there are tools for RTL-SDR and Arduino available. That's perfect! Always sniff with RTL-SDR first! Given the two re-brandings in the supply chain, I wasn't 100% sure our shutters really use the same protocol. So the first "hack" was to listen and decrypt the communication using RTL-SDR:
$ git clone https://github.com/dimhoff/radio_stuff
$ cd radio_stuff
$ make -C converters am_to_ook
$ make -C decoders decode_somfy
$ rtl_fm -M am -f 433.42M -s 270K   ./am_to_ook -d 10 -t 2000 -    ./decode_somfy
<press some buttons on the remote>
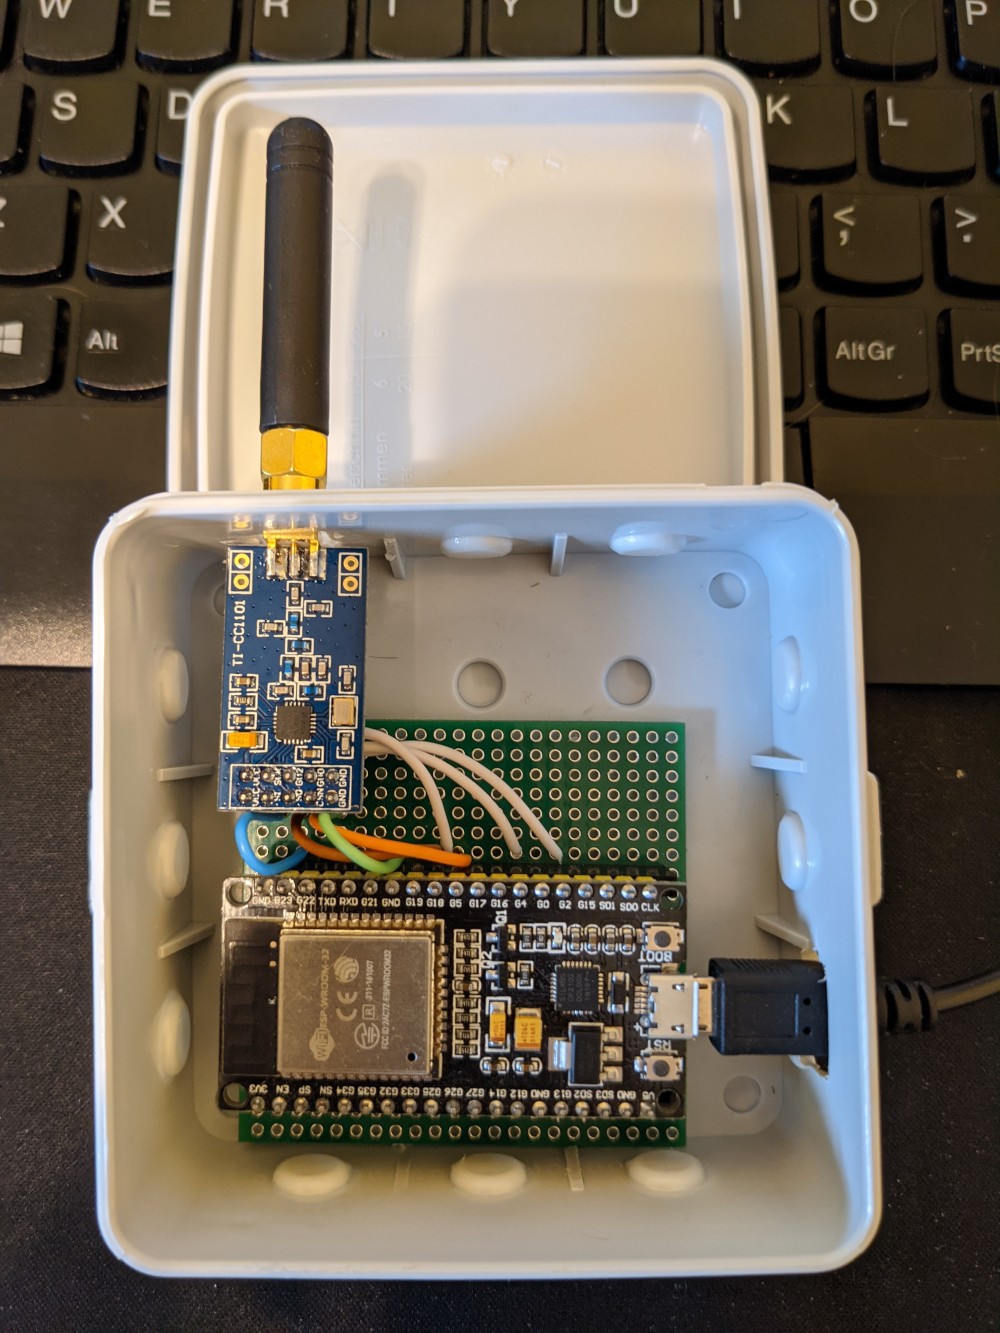
The output contains the buttons I pressed, but also the id of the remote and the command counter (which is supposed to prevent replay attacks). At this point I could just use the id and the counter to send own commands, but if I'd do that too often, the real remote would stop working, as its counter won't increase and the receiver will drop the commands when the counters differ too much. But that's good enough for now. I know I'm looking for the right protocol at the right frequency. As the end result should be an ESP32, let's move on! Acquiring the right hardware Contrary to an RTL-SDR, one usually does not have a spare ESP32 with 433MHz radio at home, so I went shopping: a NodeMCU-32S clone and a CC1101. The CC1101 is important as most 433MHz chips for Arduino/ESP only work at 433.92MHz, but Somfy uses 433.42MHz and using the wrong frequency would result in really bad reception. The CC1101 is essentially an SDR, as you can tune it to a huge spectrum of frequencies. Oh and we need some cables, a bread board, the usual stuff ;) The wiring is rather simple: ESP32 wiring for a CC1101 And the end result isn't too beautiful either, but it works: ESP32 and CC1101 in a simple case Acquiring the right software In my initial research I found an Arduino sketch and was totally prepared to port it to ESP32, but luckily somebody already did that for me! Even better, it's explicitly using the CC1101. Okay, okay, I cheated, I actually ordered the hardware after I found this port and the reference to CC1101. ;) As I am using ESPHome for my ESPs, the idea was to add a "Cover" that's controlling the shutters to it. Writing some C++, how hard can it be? Turns out, not that hard. You can see the code in my GitHub repo. It consists of two (relevant) files: somfy_cover.h and somfy.yaml. somfy_cover.h essentially wraps the communication with the Somfy_Remote_Lib library into an almost boilerplate Custom Cover for ESPHome. There is nothing too fancy in there. The only real difference to the "Custom Cover" example from the documentation is the split into SomfyESPRemote (which inherits from Component) and SomfyESPCover (which inherits from Cover) -- this is taken from the Custom Sensor documentation and allows me to define one "remote" that controls multiple "covers" using the add_cover function. The first two params of the function are the NVS name and key (think database table and row), and the third is the rolling code of the remote (stored in somfy_secrets.h, which is not in Git). In ESPHome a Cover shall define its properties as CoverTraits. Here we call set_is_assumed_state(true), as we don't know the state of the shutters - they could have been controlled using the other (real) remote - and setting this to true allows issuing open/close commands at all times. We also call set_supports_position(false) as we can't tell the shutters to move to a specific position. The one additional feature compared to a normal Cover interface is the program function, which allows to call the "program" command so that the shutters can learn a new remote. somfy.yaml is the ESPHome "configuration", which contains information about the used hardware, WiFi credentials etc. Again, mostly boilerplate. The interesting parts are the loading of the additional libraries and attaching the custom component with multiple covers and the additional PROG switches:
esphome:
  name: somfy
  platform: ESP32
  board: nodemcu-32s
  libraries:
    - SmartRC-CC1101-Driver-Lib@2.5.6
    - Somfy_Remote_Lib@0.4.0
    - EEPROM
  includes:
    - somfy_secrets.h
    - somfy_cover.h
 
cover:
  - platform: custom
    lambda:  -
      auto somfy_remote = new SomfyESPRemote();
      somfy_remote->add_cover("somfy", "badezimmer", SOMFY_REMOTE_BADEZIMMER);
      somfy_remote->add_cover("somfy", "kinderzimmer", SOMFY_REMOTE_KINDERZIMMER);
      App.register_component(somfy_remote);
      return somfy_remote->covers;
    covers:
      - id: "somfy"
        name: "Somfy Cover"
      - id: "somfy2"
        name: "Somfy Cover2"
switch:
  - platform: template
    name: "PROG"
    turn_on_action:
      - lambda:  -
          ((SomfyESPCover*)id(somfy))->program();
  - platform: template
    name: "PROG2"
    turn_on_action:
      - lambda:  -
          ((SomfyESPCover*)id(somfy2))->program();
The switch to trigger the program mode took me a bit. As the Cover interface of ESPHome does not offer any additional functions besides movement control, I first wrote code to trigger "program" when "stop" was pressed three times in a row, but that felt really cumbersome and also had the side effect that the remote would send more than needed, sometimes confusing the shutters. I then decided to have a separate button (well, switch) for that, but the compiler yelled at me I can't call program on a Cover as it does not have such a function. Turns out, you need to explicitly cast to SomfyESPCover and then it works, even if the code becomes really readable, NOT. Oh and as the switch does not have any code to actually change/report state, it effectively acts as a button that can be pressed. At this point we can just take an existing remote, press PROG for 5 seconds, see the blinds move shortly up and down a bit and press PROG on our new ESP32 remote and the shutters will learn the new remote. And thanks to the awesome integration of ESPHome into HomeAssistant, this instantly shows up as a new controllable cover there too. Future Additional Work I started writing this post about a year ago And the initial implementation had some room for improvement More than one remote The initial code only created one remote and one cover element. Sure, we could attach that to all shutters (there are 4 of them), but we really want to be able to control them separately. Thankfully I managed to read enough ESPHome docs, and learned how to operate std::vector to make the code dynamically accept new shutters. Using ESP32's NVS The ESP32 has a non-volatile key-value storage which is much nicer than throwing bits at an emulated EEPROM. The first library I used for that explicitly used EEPROM storage and it would have required quite some hacking to make it work with NVS. Thankfully the library I am using now has a plugable storage interface, and I could just write the NVS backend myself and upstream now supports that. Yay open-source! Remaining issues Real state is unknown As noted above, the ESP does not know the real state of the shutters: a command could have been lost in transmission (the Somfy protocol is send-only, there is no feedback) or the shutters might have been controlled by another remote. At least the second part could be solved by listening all the time and trying to decode commands heard over the air, but I don't think this is worth the time -- worst that can happen is that a closed (opened) shutter receives another close (open) command and that is harmless as they have integrated endstops and know that they should not move further. Can't program new remotes with ESP only To program new remotes, one has to press the "PROG" button for 5 seconds. This was not exposed in the old library, but the new one does support "long press", I just would need to add another ugly switch to the config and I currently don't plan to do so, as I do have working remotes for the case I need to learn a new one.

4 June 2021

Matthew Garrett: Mike Lindell's Cyber "Evidence"

Mike Lindell, notable for absolutely nothing relevant in this field, today filed a lawsuit against a couple of voting machine manufacturers in response to them suing him for defamation after he claimed that they were covering up hacks that had altered the course of the US election. Paragraph 104 of his suit asserts that he has evidence of at least 20 documented hacks, including the number of votes that were changed. The citation is just a link to a video called Absolute 9-0, which claims to present sufficient evidence that the US supreme court will come to a 9-0 decision that the election was tampered with.

The claim is that Lindell was provided with a set of files on the 9th of January, and gave these to some cyber experts to verify. These experts identified them as packet captures. The video contains scrolling hex, and we are told that this is the raw encrypted data from the files. In reality, the hex values correspond very clearly to printable ASCII, and appear to just be the Pennsylvania voter roll. They're not encrypted, and they're not packet captures (they contain no packet headers).

20 of these packet captures were then selected and analysed, giving us the tables contained within Exhibit 12. The alleged source IPs appear to correspond to the networks the tables claim, and the latitude and longitude presumably just come from a geoip lookup of some sort (although clearly those values are far too precise to be accurate). But if we look at the target IPs, we find something interesting. Most of them resolve to the website for the county that was the nominal target (eg, 198.108.253.104 is www.deltacountymi.org). So, we're supposed to believe that in many cases, the county voting infrastructure was hosted on the county website.

Unfortunately we're not given the destination port, but 198.108.253.104 isn't listening on anything other than 80 and 443. We're told that the packet data is encrypted, so presumably it's over HTTPS. So, uh, how did they decrypt this to figure out how many votes were switched? If Mike's hackers have broken TLS, they really don't need to be dealing with this.

We're also given some background information on how it's impossible to reconstruct packet captures after the fact (untrue), or that modifying them would change their hashes (true, but in the absence of known good hash values that tells us nothing), but it's pretty clear that nothing we're shown actually demonstrates what we're told it does.

In summary: yes, any supreme court decision on this would be 9-0, just not the way he's hoping for.

Update: It was pointed out that this data appears to be part of a larger dataset. This one is even more dubious - it somehow has MAC addresses for both the source and destination (which is impossible), and almost none of these addresses are in actual issued ranges.

comment count unavailable comments

3 June 2021

John Goerzen: Roundup of Unique Data/Storage Hosting Options

Recently I have been taking another look at the services at rsync.net and it got me thinking: what would I do with a lot of storage? What might I want to run with it, if it were fairly cheap? Let s start taking a look at what s out there. I m going to try to focus on things that are unique for some reason: pricing, features, etc. Incidentally, good reviews are hard to find due to the proliferation of affiliate links. I have no affiliate relationships with anyone mentioned here and there are no affiliate links in this post. I ll start with the highest-end community and commercial options (though both are quite competitive on price for what they are), and then move on to the cheaper options. Community option: SDF SDF is somewhat hard to define. What is SDF? could prompt answers like: There s a lot there. SDF lets you use things for yourself, of course, but you can also join a community. It s not a commercial service backed by SLAs it s best-effort but it s been around more than 30 years and has a great track record. Top commercial option for backup storage: rsync.net rsync.net offers storage broadly over SSH: sftp, rsync, scp, borg, rclone, restic, git-annex, git, and such. You do not get a shell, but you do get to run a few noninteractive commands via ssh. You can, for instance, run git clone on the rsync server. The rsync special sauce is in ZFS. They run raidz3 on their arrays (and also offer dual location setups for an additional fee), offer both free and paid ZFS snapshots, etc. The service is designed to be extremely reliable, particularly for backups, and it seems to me to meet those goals. Basic storage is $0.025 per GB/mo, but with certain account types such as borg, can be had for $0.015 per GB/mo. The minimum size is 400GB or $10/mo. There are no bandwidth charges. This makes it quite economical even compared to, say, S3. Additional discounts start at 10TB, so 10TB with rsync.net would cost $204.80/mo or $81.92 on the borg plan. You won t run Nextcloud on this thing, but for backups that must be reliable, or even a photo collection or something, it makes perfect sense. When you look into other options, you ll find that other providers are a lot more vague about their storage setup than rsync.net. Various offerings from Hetzner Hetzner is one of Europe s large hosting companies, and they have several options of interest. Their Storage Box competes directly with the rsync.net service. Their per-GB storage cost is lower than rsync.net, and although they do include a certain amount of free bandwidth with each account, bandwidth is not unlimited and could result in charges. Still, if you don t drive 2x or more your storage usage in bandwidth each month, it would be cheaper than rsync. The Storage Box also uses ZFS with some kind of redundancy, though they don t specifcy details. What differentiates them from rsync.net is the protocol support. They support sftp, scp, Borg, ssh, rsync, etc. just as rsync.net does. But then they also throw in Samba/CIFS, FTPS, HTTPS, and WebDAV all optionally enabled or disabled by you. Although things like sshfs exist, they aren t particularly optimal for some use cases, and CIFS support may just be what you need in some situations. 10TB with Hetzner would cost EUR 39.90/mo, or about $48.84/mo. (This figure is higher for Europeans, who also have to pay VAT.) Hetzner also offers a Storage Share, which is a private Nextcloud instance. 10TB of that is exactly the same cost as 10TB of the Storage Box. You can add your own users, groups, etc. to this as your are the Nextcloud admin of your instance. Hetzner throws in automatic updates (which is great, as updates have been a pain in my side for a long time). Nextcloud is ideal for things like photo sharing, even has email and chat built in, etc. For about the same price at 2TB of Google One, you can have 2TB of Nextcloud with all those services for yourself. Not bad. You can also mount a Nextcloud instance with WebDAV. Interestingly, Nextcloud supports external storages as backend for the data. It supports another Nextcloud instance, OpenStack or S3 object storage, and SFTP, SMB/CIFS, and WebDAV. If you re thinking you d like both SFTP and Nextcloud access to a pool of storage, I imagine you could always get a large Storage Box from Hetzner (internal transfer is free), pair it with a small Nextcloud instance, and link the two with Nextcloud external storage. Dedicated Servers If you want a more DIY approach, you can find some interesting deals on actual dedicated server hardware you get the entire machine to yourself. I ve been using OVH s SoYouStart for a number of years, with good experienaces, and they have a number of server configurations available. For instance, for $45.99, you can get a Xeon box with 4x2TB drives and 32GB RAM. With RAID5 or raidz1, that s 6TB of available space and cheaper than the 6TB from rsync.net (though less redundant) plus you get the whole box to yourself too. OVH directly has some more storage servers; for instance, you can get a box with 4x4TB + 1x500GB SSD for $86.75/mo, giving you 12TB available with RAID5/raidz1, plus a 16GB server to do what you want with. Hetzner also has some larger options available, for instance 2x4TB at EUR39 or 2x8TB at EUR54, both with 64GB of RAM. Bargain Corner Yes, you can find 10TB for $25/mo. It s hosted on ceph, by what appears to be mostly a single person (though with a lot of experience and a fair bit of transparency). You re not going to have the round-the-clock support experience as with rsync.net, nor its raidz3 level of redundancy but if you don t need that, there are quite a few options. Let s start with Lima Labs. Yes, 10TB is $25/mo, and they support sftp, rsync, borg, and even NFS mounts on storage backed by Ceph. The owner, Sam, seems to be a nice guy but the service isn t going to be on the scale of rsync.net or Hetzner. That may or may not be OK for your needs I mean, you can even get 1TB for $5/mo, so there are some fantastic deals to be had here. BorgBase does Borg hosting and borg hosting only. You can get 1TB for $6.67/mo or, for instance, 10TB for $53.46. They don t say much about their infrastructure and it s hard to get a read on the company, but for Borg backups, it could be a nice option. Bargain Corner Part 2: Seedboxes There s a market out there of companies offering BitTorrent seeding and downloading services. Typically, these services offer you Unix ssh access to a shell, give you a bunch of space on completely non-redundant drives (theory being that the data on them is transient), lots of bandwidth, for a low price. Some people use them for BitTorrent, others for media serving and such. If you are willing to take the lowest in drive redundancy, there are some deals to be had. Whatbox is a popular leader here, and has an extensive wiki with info. Or you can find some seedbox.io shared storage plans for instance, 12TB for $32.49/mo. But it s completely non-redundant drives. Seedbox has a partner company, Walker Servers, with some interesting deals; for instance, 4x8TB for EUR 52.45. Not bad for 24TB usable with RAID5 but Walker Servers is completely unknown to me and doesn t publish a phone number. So, YMMV. Conclusion I m sure I ve left out many quality options here, but hopefully this is enough to lay out a general lay of the land. Leave other suggestions in the comments.

2 June 2021

Joachim Breitner: Verifying the code of the Internet Identity service

The following post was meant to be posted at https://forum.dfinity.org/, but that discourse instance didn t like it; maybe too much inline code, so I m posting it here instead. To my regular blog audience, please excuse the lack of context. Please comment at the forum post. The text was later also posted on the DFINITY medium blog You probably have used https://identity.ic0.app/ to log into various applications (the NNS UI, OpenChat etc.) before, and if you do that, you are trusting this service to take good care of your credentials. Furthermore, you might want to check that the Internet Identity is really not tracking you. So you want to know: Is this really running the code we claim it to run? Of course the following applies to other canisters as well, but I ll stick to the Internet Identity in this case. I ll walk you through the steps of verifying that:

Find out what is running A service on the Internet Computer, i.e. a canister, is a WebAssembly module. The Internet Computer does intentionally not allow you to just download the Wasm code of any canisters, because maybe some developer wants to keep their code private. But it does expose a hash of the Wasm module. The easiest way to get it is using dfx:
$ dfx canister --no-wallet --network ic info rdmx6-jaaaa-aaaaa-aaadq-cai
Controller: r7inp-6aaaa-aaaaa-aaabq-cai
Module hash: 0xd4af9277f3e8d26fd8cdc7874a9f47b6456587fbb2a64d61b6b6880d144d3c04
The controller here is the canister id of the governance canister. This tells you that the Internet Identity is controlled by the Network Nervous System (NNS), and its code can only be changed via proposals that are voted on. This is good; if the controller was just, say, me, I could just change the code of the Internet Identity and take over all your identities. The Module hash is the SHA-256 hash of the .wasm that was deployed. So let s follow that trace.

Finding the right commit Since upgrades to the Internet Identity are done via proposals to the NNS, we should find a description of such a proposal in the https://github.com/ic-association/nns-proposals repository, in the proposals/network_canister_management directory.
Github s list of recent NNS proposalsGithub s list of recent NNS proposals
We have to find the latest proposal upgrading the Internet Identity. The folder unfortunately contains proposals for many canisters, and the file naming isn t super helpful. I usually go through the list from bottom and look at the second column, which contains the title of the latest commit creating or modifying a file. In this case, the second to last is the one we care about: https://github.com/ic-association/nns-proposals/blob/main/proposals/network_canister_management/20210527T2203Z.md. This file lists rationales, gives an overview of changes and, most importantly, says that bd51eab is the commit we are upgrading to. The file also says that the wasm hash is d4a c04, which matches what we saw above. This is good: it seems we really found the youngest proposal upgrading the Internet Identity, and that the proposal actually went through. WARNING: If you are paranoid, don t trust this file. There is nothing preventing a proposal proposer to create a file pointing to one revision, but actually including other code in the proposal. That s why the next steps are needed.

Getting the source Now that we have the revision, we can get the source and check out revision bd51eab:
/tmp $ git clone https://github.com/dfinity/internet-identity
Klone nach 'internet-identity' ...
remote: Enumerating objects: 3959, done.
remote: Counting objects: 100% (344/344), done.
remote: Compressing objects: 100% (248/248), done.
remote: Total 3959 (delta 161), reused 207 (delta 92), pack-reused 3615
Empfange Objekte: 100% (3959/3959), 6.05 MiB   3.94 MiB/s, Fertig.
L se Unterschiede auf: 100% (2290/2290), Fertig.
/tmp $ cd internet-identity/
/tmp/internet-identity $ git checkout bd51eab
/tmp/internet-identity $ git log --oneline -n 1
bd51eab (HEAD, tag: mainnet-20210527T2203Z) Registers the seed phrase before showing it (#301)
In the last line you see that the Internet Identity team has tagged that revision with a tag name that contains the proposal description file name. Very tidy!

Reproducing the build The README.md has the following build instructions:

Official build The official build should ideally be reproducible, so that independent parties can validate that we really deploy what we claim to deploy. We try to achieve some level of reproducibility using a Dockerized build environment. The following steps should build the official Wasm image
docker build -t internet-identity-service .
docker run --rm --entrypoint cat internet-identity-service /internet_identity.wasm > internet_identity.wasm
sha256sum internet_identity.wasm
The resulting internet_identity.wasm is ready for deployment as rdmx6-jaaaa-aaaaa-aaadq-cai, which is the reserved principal for this service.

It actually suffices to run the first command, as it also prints the hash (we don t need to copy the .wasm out of the Docker canister):
/tmp/internet-identity $ docker build -t internet-identity-service .
 
Step 26/26 : RUN sha256sum internet_identity.wasm
 ---> Running in 1a04644b544c
d4af9277f3e8d26fd8cdc7874a9f47b6456587fbb2a64d61b6b6880d144d3c04  internet_identity.wasm
Removing intermediate container 1a04644b544c
 ---> bfe6a63a7980
Successfully built bfe6a63a7980
Successfully tagged internet-identity-service:latest
Success! The hashes match. You don t believe me? Try it yourself (and let us know if you get a different hash, maybe I got hacked). This may fail if you have too little RAM configured for Docker, 8GB should be enough. At this point you have a trust path from the code sitting in front of you to the Internet Identity running at https://identity.ic0.app, including the front-end code, and you can start auditing the source code.

What about the canister id? If you payed close attention you might have noticed that we got the module has for canister rdmx6-jaaaa-aaaaa-aaadq-cai, but we are accessing a web application at https://identity.ic0.app. So where is this connection? In the future, I expect some form of a DNS-like nice host name registry on the Internet Computer that stores a mapping from nice names to canister ids, and that you will be able to query that to for which canister serves rdmx6-jaaaa-aaaaa-aaadq-cai in a secure way (e.g. using certified variables). But since we don t have that yet, but still want you to be able to use a nice name for the Internet Identity (and not have to change the name later, which would cause headaches), we have hard-coded this mapping for now. The relevant code here is the Certifying Service Worker that your browser downloads when accessing any *.ic0.app URL. This piece of code will then intercept all requests to that domain, map it to an query call, and then use certified variables to validate the response. And indeed, the mapping is in the code there:
const hostnameCanisterIdMap: Record<string, [string, string]> =  
  'identity.ic0.app': ['rdmx6-jaaaa-aaaaa-aaadq-cai', 'ic0.app'],
  'nns.ic0.app': ['qoctq-giaaa-aaaaa-aaaea-cai', 'ic0.app'],
  'dscvr.ic0.app': ['h5aet-waaaa-aaaab-qaamq-cai', 'ic0.page'],
 ;

What about other canisters? In principle, the same approach works for other canisters, whether it s OpenChat, the NNS canisters etc. But the details will differ, as every canister developer might have their own way of
  • communicating the location and revision of the source for their canisters
  • building the canisters
In particular, without a reproducible way of building the canister, this will fail, and that s why projects like https://reproducible-builds.org/ are so important in general.

Matthew Garrett: Producing a trustworthy x86-based Linux appliance

Let's say you're building some form of appliance on top of general purpose x86 hardware. You want to be able to verify the software it's running hasn't been tampered with. What's the best approach with existing technology?

Let's split this into two separate problems. The first is to do as much as we can to ensure that the software can't be modified without our consent[1]. This requires that each component in the boot chain verify that the next component is legitimate. We call the first component in this chain the root of trust, and in the x86 world this is the system firmware[2]. This firmware is responsible for verifying the bootloader, and the easiest way to do this on x86 is to use UEFI Secure Boot. In this setup the firmware contains a set of trusted signing certificates and will only boot executables with a chain of trust to one of these certificates. Switching the system into setup mode from the firmware menu will allow you to remove the existing keys and install new ones.

(Note: You shouldn't use the trusted certificate directly for signing bootloaders - instead, the trusted certificate should be used to sign another certificate and the key for that certificate used to sign your bootloader. This way, if you ever need to revoke the signing certificate, you can simply sign a new one with the trusted parent and push out a revocation update instead of having to provision new keys)

But what do you want to sign? In the general purpose Linux world, we use an intermediate bootloader called Shim to bridge from the Microsoft signing authority to a distribution one. Shim then verifies the signature on grub, and grub in turn verifies the signature on the kernel. This is a large body of code that exists because of the use cases that general purpose distributions need to support - primarily, booting on arbitrary off the shelf hardware, and allowing arbitrary and complicated boot setups. This is unnecessary in the appliance case, where the hardware target can be well defined, where there's no need for interoperability with the Microsoft signing authority, and where the boot configuration can be extremely static.

We can skip all of this complexity using systemd-boot's unified Linux image support. This has the format described here, but the short version is that it's simply a kernel and initramfs linked into a small EFI executable that will run them. Instructions for generating such an image are here, and if you follow them you'll end up with a single static image that can be directly executed by the firmware. Signing this avoids dealing with a whole host of problems associated with relying on shim and grub, but note that you'll be embedding the initramfs as well. Again, this should be fine for appliance use-cases, but you'll need your build system to support building the initramfs at image creation time rather than relying on it being generated on the host.

At this point we have a single image that can be verified by the firmware and will get us to the point of a running kernel and initramfs. Unless you've got enough RAM that you can put your entire workload in the initramfs, you're going to want a filesystem as well, and you're going to want to verify that that filesystem hasn't been tampered with. The easiest approach to this is to use dm-verity, a device-mapper layer that uses a hash tree to verify that the filesystem contents haven't been modified. The kernel needs to know what the root hash is, so this can either be embedded into your initramfs image or into the kernel command line. Either way, it'll end up in the signed boot image, so nobody will be able to tamper with it.

It's important to note that a dm-verity partition is read-only - the kernel doesn't have the cryptographic secret that would be required to generate a new hash tree if the partition is modified. So if you require the ability to write data or logs anywhere, you'll need to add a new partition for that. If this partition is unencrypted, an attacker with access to the device will be able to put whatever they want on there. You should treat any data you read from there as untrusted, and ensure that it's validated before use (ie, don't just feed it to a random parser written in C and expect that everything's going to be ok). On the other hand, if it's encrypted, remember that you can't just put the encryption key in the boot image - an attacker with access to the device is going to be able to dump that and extract it. You'll probably want to use a TPM-sealed encryption secret, which will be discussed later on.

At this point everything in the boot process is cryptographically verified, and so should be difficult to tamper with. Unfortunately this isn't really sufficient - on x86 systems there's typically no verification of the integrity of the secure boot database. An attacker with physical access to the system could attach a programmer directly to the firmware flash and rewrite the secure boot database to include keys they control. They could then replace the boot image with one that they've signed, and the machine would happily boot code that the attacker controlled. We need to be able to demonstrate that the system booted using the correct secure boot keys, and the only way we can do that is to use the TPM.

I wrote an introduction to TPMs a while back. The important thing to know here is that the TPM contains a set of Platform Configuration Registers that are large enough to contain a cryptographic hash. During boot, each component of the boot process will generate a "measurement" of other security critical components, including the next component to be booted. These measurements are a representation of the data in question - they may simply be a hash of the object being measured, or the hash of a structure containing various pieces of metadata. Each measurement is passed to the TPM, along with the PCR it should be measured into. The TPM takes the new measurement, appends it to the existing value, and then stores the hash of this concatenated data in the PCR. This means that the final PCR value depends not only on the measurement, but also on every previous measurement. Without breaking the hash algorithm, there's no way to set the PCR to an arbitrary value. The hash values and some associated data are stored in a log that's kept in system RAM, which we'll come back to later.

Different PCRs store different pieces of information, but the one that's most interesting to us is PCR 7. Its use is documented in the TCG PC Client Platform Firmware Profile (section 3.3.4.8), but the short version is that the firmware will measure the secure boot keys that are used to boot the system. If the secure boot keys are altered (such as by an attacker flashing new ones), the PCR 7 value will change.

What can we do with this? There's a couple of choices. For devices that are online, we can perform remote attestation, a process where the device can provide a signed copy of the PCR values to another system. If the system also provides a copy of the TPM event log, the individual events in the log can be replayed in the same way that the TPM would use to calculate the PCR values, and then compared to the actual PCR values. If they match, that implies that the log values are correct, and we can then analyse individual log entries to make assumptions about system state. If a device has been tampered with, the PCR 7 values and associated log entries won't match the expected values, and we can detect the tampering.

If a device is offline, or if there's a need to permit local verification of the device state, we still have options. First, we can perform remote attestation to a local device. I demonstrated doing this over Bluetooth at LCA back in 2020. Alternatively, we can take advantage of other TPM features. TPMs can be configured to store secrets or keys in a way that renders them inaccessible unless a chosen set of PCRs have specific values. This is used in tpm2-totp, which uses a secret stored in the TPM to generate a TOTP value. If the same secret is enrolled in any standard TOTP app, the value generated by the machine can be compared to the value in the app. If they match, the PCR values the secret was sealed to are unmodified. If they don't, or if no numbers are generated at all, that demonstrates that PCR 7 is no longer the same value, and that the system has been tampered with.

Unfortunately, TOTP requires that both sides have possession of the same secret. This is fine when a user is making that association themselves, but works less well if you need some way to ship the secret on a machine and then separately ship the secret to a user. If the user can simply download the secret via some API, so can an attacker. If an attacker has the secret, they can modify the secure boot database and re-seal the secret to the new PCR 7 value. That means having to add some form of authentication, along with a strong binding of machine serial number to a user (in order to avoid someone with valid credentials simply downloading all the secrets).

Instead, we probably want some mechanism that uses asymmetric cryptography. A keypair can be generated on the TPM, which will refuse to release an unencrypted copy of the private key. The public key, however, can be exported and stored. If it's acceptable for a verification app to connect to the internet then the public key can simply be obtained that way - if not, a certificate can be issued to the key, and this exposed to the verifier via a QR code. The app then verifies that the certificate is signed by the vendor, and if so extracts the public key from that. The private key can have an associated policy that only permits its use when PCR 7 has an appropriate value, so the app then generates a nonce and asks the user to type that into the device. The device generates a signature over that nonce and displays that as a QR code. The app verifies the signature matches, and can then assert that PCR 7 has the expected value.

Once we can assert that PCR 7 has the expected value, we can assert that the system booted something signed by us and thus infer that the rest of the boot chain is also secure. But this is still dependent on the TPM obtaining trustworthy information, and unfortunately the bus that the TPM sits on isn't really terribly secure (TPM Genie is an example of an interposer for i2c-connected TPMs, but there's no reason an LPC one can't be constructed to attack the sort usually used on PCs). TPMs do support encrypted communication channels, but bootstrapping those isn't straightforward without firmware support. The easiest way around this is to make use of a firmware-based TPM, where the TPM is implemented in software running on an ancillary controller. Intel's solution is part of their Platform Trust Technology and runs on the Management Engine, AMD run it on the Platform Security Processor. In both cases it's not terribly feasible to intercept the communications, so we avoid this attack. The downside is that we're then placing more trust in components that are running much more code than a TPM would and which have a correspondingly larger attack surface. Which is preferable is going to depend on your threat model.

Most of this should be achievable using Yocto, which now has support for dm-verity built in. It's almost certainly going to be easier using this than trying to base on top of a general purpose distribution. I'd love to see this become a largely push button receive secure image process, so might take a go at that if I have some free time in the near future.

[1] Obviously technologies that can be used to ensure nobody other than me is able to modify the software on devices I own can also be used to ensure that nobody other than the manufacturer is able to modify the software on devices that they sell to third parties. There's no real technological solution to this problem, but we shouldn't allow the fact that a technology can be used in ways that are hostile to user freedom to cause us to reject that technology outright.
[2] This is slightly complicated due to the interactions with the Management Engine (on Intel) or the Platform Security Processor (on AMD). Here's a good writeup on the Intel side of things.

comment count unavailable comments

1 June 2021

Robert McQueen: Next steps for the GNOME Foundation

As the President of the GNOME Foundation Board of Directors, I m really pleased to see the number and breadth of candidates we have for this year s election. Thank you to everyone who has submitted their candidacy and volunteered their time to support the Foundation. Allan has recently blogged about how the board has been evolving, and I wanted to follow that post by talking about where the GNOME Foundation is in terms of its strategy. This may be helpful as people consider which candidates might bring the best skills to shape the Foundation s next steps. Around three years ago, the Foundation received a number of generous donations, and Rosanna (Director of Operations) gave a presentation at GUADEC about her and Neil s (Executive Director, essentially the CEO of the Foundation) plans to use these funds to transform the Foundation. We would grow our activities, increasing the pace of events, outreach, development and infrastructure that supported the GNOME project and the wider desktop ecosystem and, crucially, would grow our funding to match this increased level of activity. I think it s fair to say that half of this has been a great success we ve got a larger staff team than GNOME has ever had before. We ve widened the GNOME software ecosystem to include related apps and projects under the GNOME Circle banner, we ve helped get GTK 4 out of the door, run a wider-reaching program in the Community Engagement Challenge, and consistently supported better infrastructure for both GNOME and the Linux app community in Flathub. Aside from another grant from Endless (note: my employer), our fundraising hasn t caught up with this pace of activities. As a result, the Board recently approved a budget for this financial year which will spend more funds from our reserves than we expect to raise in income. Due to our reserves policy, this is essentially the last time we can do this: over the next 6-12 months we need to either raise more money, or start spending less. For clarity the Foundation is fit and well from a financial perspective we have a very healthy bank balance, and a very conservative 12 month run rate reserve policy to handle fluctuations in income. If we do have to slow down some of our activities, we will return to a steady state where our regular individual donations and corporate contributions can support a smaller staff team that supports the events and infrastructure we ve come to rely on. However, this isn t what the Board wants to do the previous and current boards were unanimous in their support of the idea that we should be ambitious: try to do more in the world and bring the benefits of GNOME to more people. We want to take our message of trusted, affordable and accessible computing to the wider world. Typically, a lot of the activities of the Foundation have been very inwards-facing supporting and engaging with either the existing GNOME or Open Source communities. This is a very restricted audience in terms of fundraising many corporate actors in our community already support GNOME hugely in terms of both financial and in-kind contributions, and many OSS users are already supporters either through volunteer contributions or donating to those nonprofits that they feel are most relevant and important to them. To raise funds from new sources, the Foundation needs to take the message and ideals of GNOME and Open Source software to new, wider audiences that we can help. We ve been developing themes such as affordability, privacy/trust and education as promising areas for new programs that broaden our impact. The goal is to find projects and funding that allow us to both invest in the GNOME community and find new ways for FOSS to benefit people who aren t already in our community. Bringing it back to the election, I d like to make clear that I see this reaching the outside world, and finding funding to support that as the main priority and responsibility of the Board for the next term. GNOME Foundation elections are a slightly unusual process that filters our board nominees by being existing Foundation members, which means that candidates already work inside our community when they stand for election. If you re a candidate and are already active in the community THANK YOU you re doing great work, keep doing it! That said, you don t need to be a Director to achieve things within our community or gain the support of the Foundation: being a community leader is already a fantastic and important role. The Foundation really needs support from the Board to make a success of the next 12-18 months. We need to understand our financial situation and the trade-offs we have to make, and help to define the strategy with the Executive Director so that we can launch some new programs that will broaden our impact and funding for the future. As people cast their votes, I d like people to think about what kind of skills building partnerships, commercial background, familiarity with finances, experience in nonprofit / impact spaces, etc will help the Board make the Foundation as successful as it can be during the next term.

Russell Coker: Internode NBN with Arris CM8200 on Debian

I ve recently signed up for Internode NBN while using the Arris CM8200 device supplied by Optus (previously used for a regular phone service). I took the configuration mostly from Dean s great blog post on the topic [1]. One thing I changed was the /etc/networ/interfaces configuration, I used the following:
# VLAN ID 2 for Internode's NBN HFC.
auto eth1.2
iface eth1.2 inet manual
  vlan-raw-device eth1
auto nbn
iface nbn inet ppp
    pre-up /bin/ip link set eth1.2 up
    provider nbn
There is no need to have a section for eth1 when you have a section for eth1.2. IPv6 IPv6 for only one system With a line in /etc/ppp/options containing only ipv6 , you get an IPv6 address automatically for the ppp0 interface after starting pppd. IPv6 for your lan Internode has documented how to configure the WIDE DHCPv6 client to get an IPv6 prefix (subnet) [2]. Just install the wide-dhcpv6-client package and put your interface names in a copy of the Internode example config and that works. That gets you a /64 assigned to your local Ethernet. Here s an example of /etc/wide-dhcpv6/dhcp6c.conf:
interface ppp0  
    send ia-pd 0;
    script "/etc/wide-dhcpv6/dhcp6c-script";
 ;
id-assoc pd  
    prefix-interface br0  
        sla-id 0;
        sla-len 8;
     ;
 ;
For providing addresses to other systems on your LAN they recommend radvd version 1.1 or greater, Debian/Bullseye will ship with version 2.18. Here is an example /etc/radvd.conf that will work with it. It seems that you have to manually (or with a script) set the value to use in place of xxxx:xxxx:xxxx:xxxx from the value that is assigned to eth0 (or whichever interface you are using) by the wide-dhcpv6-client.
interface eth0   
        AdvSendAdvert on;
        MinRtrAdvInterval 3; 
        MaxRtrAdvInterval 10;
        prefix xxxx:xxxx:xxxx:xxxx::/64   
                AdvOnLink on; 
                AdvAutonomous on; 
                AdvRouterAddr on; 
         ;
 ;
Either the configuration of the wide dhcp client or radvd removes the default route from ppp0, so you need to run a command like
ip -6 route add default dev ppp0 to put it back. Probably having ipv6 , is the wrong thing to do when using wide-dhcp-client and radvd. On a client machine with bridging I needed to have net.ipv6.conf.br0.accept_ra=2 in /etc/sysctl.conf to allow it to accept route advisory messages on the interface (in this case eth0), for machines without bridging I didn t need that. Firewalling The default model for firewalling nowadays seems to be using NAT and only configuring specific ports to be forwarded to machines on the LAN. With IPv6 on the LAN every system can directly communicate with the rest of the world which may be a bad thing. The following lines in a firewall script will drop all inbound packets that aren t in response to packets that are sent out. This will give an equivalent result to the NAT firewall people are used to and you can always add more rules to allow specific ports in.
ip6tables -A FORWARD -i ppp+ -m state --state ESTABLISHED,RELATED -j ACCEPT
ip6tables -A FORWARD -i ppp+ -i DROP

Russ Allbery: Review: The Horse and His Boy

Review: The Horse and His Boy, by C.S. Lewis
Illustrator: Pauline Baynes
Series: Chronicles of Narnia #5
Publisher: Collier Books
Copyright: 1954
Printing: 1978
ISBN: 0-02-044200-9
Format: Mass market
Pages: 217
The Horse and His Boy was the fifth published book in the Chronicles of Narnia, but it takes place during the last chapter of The Lion, the Witch and the Wardrobe, in the midst of the golden age of Narnia. It's the only true side story of the series and it doesn't matter much where in sequence you read it, as long as it's after The Lion, the Witch and the Wardrobe and before The Last Battle (which would spoil its ending somewhat). MAJOR SPOILERS BELOW. The Horse and His Boy is also the only book of the series that is not a portal fantasy. The Pevensie kids make an appearance, but as the ruling kings and queens of Narnia, and only as side characters. The protagonists are a boy named Shasta, a girl named Aravis, and horses named Bree and Hwin. Aravis is a Calormene, a native of the desert (and extremely Orientalist, but more on that later) kingdom to the south of Narnia and Archenland. Shasta starts the book as the theoretically adopted son but mostly slave of a Calormene fisherman. The Horse and His Boy is the story of their journey from Calormen north to Archenland and Narnia, just in time to defend Narnia and Archenland from an invasion. This story starts with a great hook. Shasta's owner is hosting a passing Tarkaan, a Calormene lord, and overhears a negotiation to sell Shasta to the Tarkaan as his slave (and, in the process, revealing that he rescued Shasta as an infant from a rowboat next to a dead man). Shasta starts talking to the Tarkaan's horse and is caught by surprise when the horse talks back. He is a Talking Horse from Narnia, kidnapped as a colt, and eager to return to Narnia and the North. He convinces Shasta to attempt to escape with him. This has so much promise. For once, we're offered a story where one of the talking animals of Narnia is at least a co-protagonist and has some agency in the story. Bree takes charge of Shasta, teaches him to ride (or, mostly, how to fall off a horse), and makes most of the early plans. Finally, a story that recognizes that Narnia stories don't have to revolve around the humans! Unfortunately, Bree is an obnoxious, arrogant character. I wanted to like him, but he makes it very hard. This gets even worse when Shasta is thrown together with Aravis, a noble Calormene girl who is escaping an arranged marriage on her own talking mare, Hwin. Bree is a warhorse, Hwin is a lady's riding mare, and Lewis apparently knows absolutely nothing about horses, because every part of Bree's sexist posturing and Hwin's passive meekness is awful and cringe-worthy. I am not a horse person, so will link to Judith Tarr's much more knowledgeable critique at Tor.com, but suffice it to say that mares are not meekly deferential or awed by stallions. If Bree had behaved that way with a real mare, he would have gotten the crap beaten out of him (which might have improved his attitude considerably). As is, we have to put up with rather a lot of Bree's posturing and Hwin (who I liked much better) barely gets a line and acts disturbingly like she was horribly abused. This makes me sad, because I like Bree's character arc. He's spent his whole life being special and different from those around him, and while he wants to escape this country and return home, he's also gotten used to being special. In Narnia, he will just be a normal talking horse. To get everything else he wants, he also has to let go of the idea that he's someone special. If Lewis had done more with this and made Bree a more sympathetic character, this could have been very effective. As written, it only gets a few passing mentions (mostly via Bree being weirdly obsessed with whether talking horses roll) and is therefore overshadowed by Shasta's chosen one story and Bree's own arrogant behavior. The horses aside, this is a passable adventure story with some well-done moments. The two kids and their horses end up in Tashbaan, the huge Calormene capital, where they stumble across the Narnians and Shasta is mistaken for one of their party. Radagast, the prince of Calormen, is proposing marriage to Susan, and the Narnians are in the process of realizing he doesn't plan to take no for an answer. Aravis, meanwhile, has to sneak out of the city via the Tisroc's gardens, which results in her hiding behind a couch as she hears Radagast's plans to invade Archenland and Narnia to take Susan as his bride by force. Once reunited, Shasta, Aravis, and the horses flee across the desert to bring warning to Archenland and then Narnia. Of all the Narnia books, The Horse and His Boy leans the hardest into the personal savior angle of Christianity. Parts of it, such as Shasta's ride over the pass into Narnia, have a strong "Footprints" feel to them. Most of the events of the book are arranged by Aslan, starting with Shasta's early life. Readers of the series will know this when a lion shows up early to herd the horses where they need to go, or when a cat keeps Shasta company in the desert and frightens away jackals. Shasta only understands near the end. I remember this being compelling stuff as a young Christian reader. This personal attention and life shaping from God is pure Christian wish fulfillment of the "God has a plan for your life" variety, even more so than Shasta turning out to be a lost prince. As an adult re-reader, I can see that Lewis is palming the theodicy card rather egregiously. It's great that Aslan was making everything turn out well in the end, but why did he have to scare the kids and horses half to death in the process? They were already eager to do what he wanted, but it's somehow inconceivable that Aslan would simply tell them what to do rather than manipulate them. There's no obvious in-story justification why he couldn't have made the experience much less terrifying. Or, for that matter, prevented Shasta from being kidnapped as an infant in the first place and solved the problem of Radagast in a more direct way. This sort of theology takes as an unexamined assumption that a deity must refuse to use his words and instead do everything in weirdly roundabout and mysterious ways, which makes even less sense in Narnia than in our world given how directly and straightforwardly Aslan has acted in previous books. It was also obvious to me on re-read how unfair Lewis's strict gender roles are to Aravis. She's an excellent rider from the start of the book and has practiced many of the things Shasta struggles to do, but Shasta is the boy and Aravis is the girl, so Aravis has to have girl adventures involving tittering princesses, luxurious baths, and eavesdropping behind couches, whereas Shasta has boy adventures like riding to warn the king or bringing word to Narnia. There's nothing very objectionable about Shasta as a character (unlike Bree), but he has such a generic character arc. The Horse and Her Girl with Aravis and Hwin as protagonists would have been a more interesting story, and would have helpfully complicated the whole Narnia and the North story motive. As for that storyline, wow the racism is strong in this one, starting with the degree that The Horse and His Boy is deeply concerned with people's skin color. Shasta is white, you see, clearly marking him as from the North because all the Calormenes are dark-skinned. (This makes even less sense in this fantasy world than in our world because it's strongly implied in The Magician's Nephew that all the humans in Calormen came from Narnia originally.) The Calormenes all talk like characters from bad translations of the Arabian Nights and are shown as cruel, corrupt slavers with a culture that's a Orientalist mishmash of Arab, Persian, and Chinese stereotypes. Everyone is required to say "may he live forever" after referencing the Tisroc, which is an obvious and crude parody of Islam. This stereotype fest culminates in the incredibly bizarre scene that Aravis overhears, in which the grand vizier literally grovels on the floor while Radagast kicks him and the Tisroc, Radagast's father, talks about how Narnia's freedom offends him and the barbarian kingdom would be more profitable and orderly when conquered. The one point to Lewis's credit is that Aravis is also Calormene, tells stories in the same style, and is still a protagonist and just as acceptable to Aslan as Shasta is. It's not enough to overcome the numerous problems with Lewis's lazy world-building, but it makes me wish even more that Aravis had gotten her own book and more meaningful scenes with Aslan. I had forgotten that Susan appears in this book, although that appearance doesn't add much to the general problem of Susan in Narnia except perhaps to hint at Lewis's later awful choices. She is shown considering marriage to the clearly villainous Radagast, and then only mentioned later with a weird note that she doesn't ride to war despite being the best archer of the four. I will say again that it's truly weird to see the Pevensie kids as (young) adults discussing marriage proposals, international politics, and border wars while remembering they all get dumped back into their previous lives as British schoolkids. This had to have had dramatic effects on their lives that Lewis never showed. (I know, the real answer is that Lewis is writing these books according to childhood imaginary adventure logic, where adventures don't have long-term consequences of that type.) I will also grumble once more at how weirdly ineffectual Narnians are until some human comes to tell them what to do. Calormen is obviously a threat; Susan just escaped from an attempted forced marriage. Archenland is both their southern line of defense and is an ally separated by a mountain pass in a country full of talking eagles, among other obvious messengers. And yet, it falls to Shasta to ride to give warning because he's the human protagonist of the story. Everyone else seems to be too busy with quirky domesticity or endless faux-medieval chivalric parties. The Horse and His Boy was one of my favorites when I was a kid, but reading as an adult I found it much harder to tolerate Bree or read past the blatant racial and cultural stereotyping. The bits with Aslan also felt less magical to me than they did as a kid because I was asking more questions about why Aslan had to do everything in such an opaque and perilous way. It's still not a bad adventure; Aravis is a great character, the bits in Tashbaan are at least memorable, and I still love the Hermit of the Southern March and want to know more about him. But I would rank it below the top tier of Narnia books, alongside Prince Caspian as a book with some great moments and some serious flaws. Followed in original publication order by The Magician's Nephew. Rating: 7 out of 10

31 May 2021

Dirk Eddelbuettel: inline 0.3.19: Another Update

A new release of the inline package got to CRAN today, following and further updating the recent update from earlier in the month. inline facilitates writing code in-line in simple string expressions or short files. The package was used quite extensively by Rcpp in the days before Rcpp Attributes arrived on the scene providing an even better alternative for its use cases. inline is still used by rstan and a number of other packages. This release builds on and extends the work of the recent 0.3.18 release and tweaks some of the test. We cannot fully test all platforms used by CRAN so some times iterations such as this one are needed. The package was uploaded a few days ago, but it sometimes takes a few days to clarify changes over email to the CRAN maintainers whose work is still greatly appreciated. The NEWS extract follows and details the changes some more.

Changes in inline version 0.3.19 (2021-05-25)
  • Documentation for moveDLL was updated and extended (Johannes in #22).
  • A few more tests were made conditional the test platform (Dirk in #24).

Courtesy of my CRANberries, there is a comparison to the previous release. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Russell Coker: Some Ideas About Storage Reliability

Hard Drive Brands When people ask for advice about what storage to use they often get answers like use brand X, it works well for me and brand Y had a heap of returns a few years ago . I m not convinced there is any difference between the small number of manufacturers that are still in business. One problem we face with reliability of computer systems is that the rate of change is significant, so every year there will be new technological developments to improve things and every company will take advantage of them. Storage devices are unique among computer parts for their requirement for long-term reliability. For most other parts in a computer system a fault that involves total failure is usually easy to fix and even a fault that causes unreliable operation usually won t spread it s damage too far before being noticed (except in corner cases like RAM corruption causing corrupted data on disk). Every year each manufacturer will bring out newer disks that are bigger, cheaper, faster, or all three. Those disks will be expected to remain in service for 3 years in most cases, and for consumer disks often 5 years or more. The manufacturers can t test the new storage technology for even 3 years before releasing it so their ability to prove the reliability is limited. Maybe you could buy some 8TB disks now that were manufactured to the same design as used 3 years ago, but if you buy 12TB consumer grade disks, the 20TB+ data center disks, or any other device that is pushing the limits of new technology then you know that the manufacturer never tested it running for as long as you plan to run it. Generally the engineering is done well and they don t have many problems in the field. Sometimes a new range of disks has a significant number of defects, but that doesn t mean the next series of disks from the same manufacturer will have problems. The issues with SSDs are similar to the issues with hard drives but a little different. I m not sure how much of the improvements in SSDs recently have been due to new technology and how much is due to new manufacturing processes. I had a bad experience with a nameless brand SSD a couple of years ago and now stick to the better known brands. So for SSDs I don t expect a great quality difference between devices that have the names of major computer companies on them, but stuff that comes from China with the name of the discount web store stamped on it is always a risk. Hard Drive vs SSD A few years ago some people were still avoiding SSDs due to the perceived risk of new technology. The first problem with this is that hard drives have lots of new technology in them. The next issue is that hard drives often have some sort of flash storage built in, presumably a SSHD or Hybrid Drive gets all the potential failures of hard drives and SSDs. One theoretical issue with SSDs is that filesystems have been (in theory at least) designed to cope with hard drive failure modes not SSD failure modes. The problem with that theory is that most filesystems don t cope with data corruption at all. If you want to avoid losing data when a disk returns bad data and claims it to be good then you need to use ZFS, BTRFS, the NetApp WAFL filesystem, Microsoft ReFS (with the optional file data checksum feature enabled), or Hammer2 (which wasn t production ready last time I tested it). Some people are concerned that their filesystem won t support wear levelling for SSD use. When a flash storage device is exposed to the OS via a block interface like SATA there isn t much possibility of wear levelling. If flash storage exposes that level of hardware detail to the OS then you need a filesystem like JFFS2 to use it. I believe that most SSDs have something like JFFS2 inside the firmware and use it to expose what looks like a regular block device. Another common concern about SSD is that it will wear out from too many writes. Lots of people are using SSD for the ZIL (ZFS Intent Log) on the ZFS filesystem, that means that SSD devices become the write bottleneck for the system and in some cases are run that way 24*7. If there was a problem with SSDs wearing out I expect that ZFS users would be complaining about it. Back in 2014 I wrote a blog post about whether swap would break SSD [1] (conclusion it won t). Apart from the nameless brand SSD I mentioned previously all of my SSDs in question are still in service. I have recently had a single Samsung 500G SSD give me 25 read errors (which BTRFS recovered from the other Samsung SSD in the RAID-1), I have yet to determine if this is an ongoing issue with the SSD in question or a transient thing. I also had a 256G SSD in a Hetzner DC give 23 read errors a few months after it gave a SMART alert about Wear_Leveling_Count (old age). Hard drives have moving parts and are therefore inherently more susceptible to vibration than SSDs, they are also more likely to cause vibration related problems in other disks. I will probably write a future blog post about disks that work in small arrays but not in big arrays. My personal experience is that SSDs are at least as reliable as hard drives even when run in situations where vibration and heat aren t issues. Vibration or a warm environment can cause data loss from hard drives in situations where SSDs will work reliably. NVMe I think that NVMe isn t very different from other SSDs in terms of the actual storage. But the different interface gives some interesting possibilities for data loss. OS, filesystem, and motherboard bugs are all potential causes of data loss when using a newer technology. Future Technology The latest thing for high end servers is Optane Persistent memory [2] also known as DCPMM. This is NVRAM that fits in a regular DDR4 DIMM socket that gives performance somewhere between NVMe and RAM and capacity similar to NVMe. One of the ways of using this is Memory Mode where the DCPMM is seen by the OS as RAM and the actual RAM caches the DCPMM (essentially this is swap space at the hardware level), this could make multiple terabytes of RAM not ridiculously expensive. Another way of using it is App Direct Mode where the DCPMM can either be a simulated block device for regular filesystems or a byte addressable device for application use. The final option is Mixed Memory Mode which has some DCPMM in Memory Mode and some in App Direct Mode . This has much potential for use of backups and to make things extra exciting App Direct Mode has RAID-0 but no other form of RAID. Conclusion I think that the best things to do for storage reliability are to have ECC RAM to avoid corruption before the data gets written, use reasonable quality hardware (buy stuff with a brand that someone will want to protect), and avoid new technology. New hardware and new software needed to talk to new hardware interfaces will have bugs and sometimes those bugs will lose data. Filesystems like BTRFS and ZFS are needed to cope with storage devices returning bad data and claiming it to be good, this is a very common failure mode. Backups are a good thing.

30 May 2021

Russell Coker: Wifi Performance on Linux

Wifi usually just works. In the past I haven t had to worry much about performance as for home use things have always been bearable and at work it s never been my job so I just file a bug report with the relevant people when things go wrong. But a few years ago I had some problems. For my home network I got a free Wifi AP which wasn t performing well. My AP supported 802.11 modes b/g or g/n (b, g, and n are slow, medium, and fast speeds). I initially had the AP running in b/g mode because I had an 802.11b USB wifi device that I used. When I replaced that with one that did 802.11g I tried changing the AP to g/n mode but performance was even worse on my laptop (although quite good on phones) so I switched back. For phones it appeared to work well giving 54Mb/s while on my laptop (a second hand Thinkpad X1 Carbon) it was giving 11Mb/s at best and often much less than that. The best demonstration of problems was to start transferring a large file while pinging a system on the LAN the AP was connected to. Usually it would give ping times of 1s or more, sometimes 5s+ ping times. While this was happening the Invalid misc count increased rapidly, often by more than 100 per second. The results of Google searches suggest that Invalid misc is due to interference and recommend changing the channel. My AP had been on channel 1 which had performed poorly, channels 2-8 were ok, and channel 9 seemed reasonably good. As an aside trying all channels manually is not a good idea, it takes a lot of time and gives little useful data. After changing to channel 9 it still only gave about 500KB/s when transferring large files with ping times of about 100ms, but that s a big improvement. I tried running iwlist scanning to scan the Wifi network for other APs, that showed that channel 1 was used a lot but didn t make it clear what I should do other than that. The next thing I tried was the Wifi Analyser app on Android [1] (which doesn t work on my latest phone, I don t know if it s still being actively maintained, it will definitely work on older phones). That has a nice graph mode that shows which channels are used and how the frequencies spread and interfere with other channels. One thing I hadn t realised before I looked at the graphs is that 802.11n uses 4 channels and interferes past that. If you have two 802.11n devices you don t have much space left out of the 14 channels available. To make more space I configured the Wifi AP in my ADSL modem to 802.11b/g mode and assigned it a channel away from the others making 4 channels available with no interference. After that iwconfig reported between 60 and 120Mb/s and I got consistent transfer rates over 1.5MB/s while ping times remained below 100ms. The 5GHz frequency range is less congested. But at the time I didn t feel like buying 5GHz equipment. Since that time I had signed up with an ISP that had a good deal on a Wifi AP that had 5GHz. Now I have all my devices configured to use 5GHz or 2.4GHz depending on which they think is best. So there s less devices on 2.4GHz and the AP is configured for 20MHz channel width in the 2.4GHz range (which means 802.11b/g). Conclusion 802.11n seems to be a bad idea unless you run the only AP in an area. In a suburban area you will have 3 other houses broadcasting in your area and 802.11n is bad for everyone. The worst case scenario would be one person using 802.11n and interfering with everyone else s 802.11g and then having everyone else turn on 802.11n to try and make things faster. 5GHz is less congested as most people run old hardware. It also has a shorter range which has the upside of getting less interference from other people. I m considering installing 5GHz APs at both ends of my house and configuring all my new devices to not use 2.4GHz. Wifi spectrum analysis software is much better than manual testing of channels or trying to deduce things from the output if iwlist scanning .

Russell Coker: HP ML110 Gen9

I ve just bought a HP ML110 Gen9 as a personal workstation, here are my notes about it and documentation on running Debian on it. Why a Server? I bought this is because the ML350p Gen8 turned out to be too noisy for my taste [1]. I ve just been editing my page about Memtest86+ RAM speeds [2], over the course of 10 years (high end laptop in 2001 to low end server in 2011) RAM speed increased by a factor of 100. RAM speed has been increasing at a lower rate than CPU speed and is becoming an increasing bottleneck on system performance. So while I could get a faster white-box system the cost of a second-hand server isn t that great and I m getting a system that s 100* faster than what was adequate for most tasks in 2001. HP makes some nice workstation class machines with ECC RAM (think server without remote management, hot-swap disks, or redundant PSU but with sound hardware). But they are significantly more expensive on the second hand market than servers. This server cost me $650 and came with 2*480G DC grade SSDs (Intel but with HPE stickers). I hope that more than half of the purchase price will be recovered from selling the SSDs (I will use NVMe). Also 64G of non-ECC RAM costs $370 from my local store. As I want lots of RAM for testing software on VMs it will probably turn out that the server cost me less than the cost of new RAM once I ve sold the SSDs! Monitoring
wget -O /usr/local/hpePublicKey2048_key1.pub https://downloads.linux.hpe.com/SDR/hpePublicKey2048_key1.pub
echo "# HP monitoring" >> /etc/apt/sources.list
echo "deb [signed-by=/usr/local/hpePublicKey2048_key1.pub] http://downloads.linux.hpe.com/SDR/downloads/MCP/Debian/ stretch/current-gen9 non-free" >> /etc/apt/sources.list
The above commands will make the management utilities installable on Debian/Buster. If using Bullseye (Testing at the moment) then you need to have Buster repositories in APT for dependencies, HP doesn t seem to have packaged all their utilities for Buster.
wget -r -np -A Contents-amd64.bz2 http://downloads.linux.hpe.com/SDR/repo/mcp/debian/dists
To find out which repositories had the programs I need I ran the above recursive wget and then uncompressed them for grep -R (as an aside it would be nice if bzgrep supported -R). I installed the hp-health package which has hpasmcli for viewing and setting many configuration options and hplog for viewing event log data and thermal data (among a few other things). I ve added a new monitor to etbemon hp-temp.monitor to monitor HP server temperatures, I haven t made a configuration option to change the thresholds for what is considered normal because I don t expect server class systems to be routinely running above the warning temperature. For the linux-temp.monitor script I added a command-line option for the percentage of the high temperature that is an error condition as well as an option for the number of CPU cores that need to be over-temperature, having one core permanently over the high temperature due to a web browser seems standard for white-box workstations nowadays. The hp-health package depends on libc6-i686 lib32gcc1 even though none of the programs it contains use lib32gcc1. Depending on lib32gcc1 instead of lib32gcc1 lib32gcc-s1 means that installing hp-health requires removing mesa-opencl-icd which probably means that BOINC can t use the GPU among other things. I solved this by editing /var/lib/dpkg/status and changing the package dependencies to what I desired. Note that this is not something for a novice to do, make a backup and make sure you know what you are doing! Issues The HPE Dynamic Smart Array B140i is a software RAID device. While it s convenient for some users that software RAID gets supported in the UEFI boot process, generally software RAID is a bad idea. Also my system has hot-swap drive caddies but the controller doesn t support hot-swap. So the first thing to do was to configure the array controller to run in AHCI mode and give up on using hot-swap drive caddies for hot-swap. I tested all the documented ways of scanning for new devices and nothing other than a reboot made the kernel recognise a new SATA disk. According to specs provided by Dell and HP the ML110 Gen9 makes less noise than the PowerEdge T320, according to my own observations the reverse is the case. I don t know if this is because of Dell being more conservative in their specs than HP or because of how dBA is measured vs my own personal annoyance thresholds for sounds. As the system makes more noise than I m comfortable with I plan to build a rubber enclosure for the rear of the system to reduce noise, that will be the subject of another post. For Australian readers Bunnings has some good deals on rubber floor mats that can be used to reduce server noise. The server doesn t have sound hardware, while one could argue that servers don t need sound there are some server uses for sound hardware such as using line input as a source of entropy. Also for a manufacturer it might be a benefit to use the same motherboard for workstations and servers. Fortunately a friend gave me a nice set of Logitech USB speakers a few years ago that I hadn t previously had a cause to use, so that will solve the problem for me (I don t need line-in on a workstation). UEFI and Memtest I decided to try UEFI boot for something new (in the past I d only used UEFI boot for a server that only had large disks). In the past I ve booted all my own systems with BIOS boot because I m familiar with it and they all have SSDs for booting which are less than 2TB in size (until recently 2TB SSDs weren t affordable for my personal use). The Debian UEFI wiki page is worth reading [3]. The Debian Wiki page about ProLiant servers [4] is worth reading too. Memtest86+ doesn t support EFI booting (just goes to a black screen) even though Debian/Buster puts in a GRUB entry for it (Debian bug #695246 was filed for this in 2012). Also on my ML110 Memtest86+ doesn t report the RAM speed (a known issue on Memtest86+). Comments on the net say that Memtest86+ hasn t been maintained for a long time and Memtest86 (the non-free version) has been updated more recently. So far I haven t seen a system with ECC RAM have a memory problem that could be detected by Memtest86+, the memory problems I ve seen on ECC systems have been things that prevent booting (RAM not being recognised correctly), that are detected by the BIOS as ECC errors before booting, or that are reported by the kernel as ECC errors at run time (happened years ago and I can t remember the details). Overall I m not a fan of EFI with the way it currently works in Debian. It seems to add some of the GRUB functionality into the BIOS and then use that to load GRUB. It seems that EFI can do everything you need and it would be better to just have a single boot loader not two of them chained. Power Supply There are a range of PSUs for the ML110, the one I have has the smallest available PSU (350W) and doesn t have a PCIe power cable (the one used for video cards). Here is the HP document which shows the cabling for the various ML110 Gen8 PSUs [5], I have the 350W PSU. One thing I ve considered is whether I could make an adaptor from the drive bay power to the PCIe connector. A quick web search indicates that 4 SAS disks when active can take up to 75W more power than a system with no disks. If that s the case then the 2 spare drive bay connectors which can each handle 4 disks should be able to supply 150W. As a 6 pin PCIe power cable (GPU power cable) is rated at 75W that should be fine in theory (here s a page with the pinouts for PCIe power connectors [6]). My video card is a Radeon R7 260X which apparently takes about 113W all up so should be taking less than 75W from the PCIe power cable. All I really want is YouTube, Netflix, and text editing at 4K resolution. So I don t need much in terms of 3D power. KDE uses some of the advanced features of modern video cards, but it doesn t compare to 3D gaming. According to the Wikipedia page for Radeon RX 500 series [7] the RX560 supports DisplayPort 1.4 and HDMI 2.0 (both of which do 4K@60Hz) and has a TDP of 75W. So a RX560 video card seems like a good option that will work in any system that doesn t have a spare PCIe power cable. I ve just ordered one of those for $246 so hopefully that will arrive in a week or so. PCI Fan The ML110 Gen9 has an optional PCIe fan and baffle to cool PCIe cards (part number 784580-B21). Extra cooling of PCIe cards is a good thing, but $400 list price (and about $50 ebay price) for the fan and baffle is unpleasant. When I boot the system with a PCIe dual-ethernet card and two PCIe NVMe cards it gives a BIOS warning on boot, when I add a video card it refuses to boot without the extra fan. It s nice that the system makes sure it doesn t get into a thermal overload situation, but it would be nicer if they just shipped all necessary fans with it instead of trying to get more money out of customers. I just bought a PCI fan and baffle kit for $60. Conclusion In spite of the unexpected expense of a new video card and PCI fan the overall cost of this system is still low, particularly when considering that I ll find another use for the video card which needs and extra power connector. It is disappointing that HP didn t supply a more capable PSU and fit all the fans to all models, the expectation of a server is that you can just do server stuff not have to buy extra bits before you can do server stuff. If you want to install Tesla GPUs or something then it s expected that you might need to do something unusual with a server, but the basic stuff should just work. A single processor tower server should be designed to function as a deskside workstation and be able to handle an average video card. Generally it s a nice computer, I look forward to getting the next deliveries of parts so I can make it work properly.

Russ Allbery: Review: The Silver Chair

Review: The Silver Chair, by C.S. Lewis
Illustrator: Pauline Baynes
Series: Chronicles of Narnia #4
Publisher: Collier
Copyright: 1953
Printing: 1978
ISBN: 0-02-044250-5
Format: Mass market
Pages: 217
The Silver Chair is a sequel to The Voyage of the Dawn Treader and the fourth book of the Chronicles of Narnia in original publication order. (For more about publication order, see the introduction to my review of The Lion, the Witch and the Wardrobe.) Apart from a few references to The Voyage of the Dawn Treader at the start, it stands sufficiently on its own that you could read it without reading the other books, although I have no idea why you'd want to. We have finally arrived at my least favorite of the Narnia books and the one that I sometimes skipped during re-reads. (One of my objections to the new publication order is that it puts The Silver Chair and The Last Battle back-to-back, and I don't think you should do that to yourself as a reader.) I was hoping that there would be previously unnoticed depth to this book that would redeem it as an adult reader. Sadly, no; with one very notable exception, it's just not very good. MAJOR SPOILERS BELOW. The Silver Chair opens on the grounds of the awful school to which Eustace's parents sent him: Experiment House. That means it opens (and closes) with a more extended version of Lewis's rant about schools. I won't get into this in detail since it's mostly a framing device, but Lewis is remarkably vicious and petty. His snide contempt for putting girls and boys in the same school did not age well, nor did his emphasis at the end of the book that the incompetent head of the school is a woman. I also raised an eyebrow at holding up ordinary British schools as a model of preventing bullying. Thankfully, as Lewis says at the start, this is not a school story. This is prelude to Jill meeting Eustace and the two of them escaping the bullies via a magical door into Narnia. Unfortunately, that's the second place The Silver Chair gets off on the wrong foot. Jill and Eustace end up in what the reader of the series will recognize as Aslan's country and almost walk off the vast cliff at the end of the world, last seen from the bottom in The Voyage of the Dawn Treader. Eustace freaks out, Jill (who has a much better head for heights) goes intentionally close to the cliff in a momentary impulse of arrogance before realizing how high it is, Eustace tries to pull her back, and somehow Eustace falls over the edge. I do not have a good head for heights, and I wonder how much of it is due to this memorable scene. I certainly blame Lewis for my belief that pulling someone else back from the edge of a cliff can result in you being pushed off, something that on adult reflection makes very little sense but which is seared into my lizard brain. But worse, this sets the tone for the rest of the story: everything is constantly going wrong because Eustace and Jill either have normal human failings that are disproportionately punished or don't successfully follow esoteric and unreasonably opaque instructions from Aslan. Eustace is safe, of course; Aslan blows him to Narnia and then gives Jill instructions before sending her afterwards. (I suspect the whole business with the cliff was an authorial cheat to set up Jill's interaction with Aslan without Eustace there to explain anything.) She and Eustace have been summoned to Narnia to find the lost Prince, and she has to memorize four Signs that will lead her on the right path. Gah, the Signs. If you were the sort of kid that I was, you immediately went back and re-read the Signs several times to memorize them like Jill was told to. The rest of this book was then an exercise in anxious frustration. First, Eustace is an ass to Jill and refuses to even listen to the first Sign. They kind of follow the second but only with heavy foreshadowing that Jill isn't memorizing the Signs every day like she's supposed to. They mostly botch the third and have to backtrack to follow it. Meanwhile, the narrator is constantly reminding you that the kids (and Jill in particular) are screwing up their instructions. On re-reading, it's clear they're not doing that poorly given how obscure the Signs are, but the ominous foreshadowing is enough to leave a reader a nervous wreck. Worse, Eustace and Jill are just miserable to each other through the whole book. They constantly bicker and snipe, Eustace doesn't want to listen to her and blames her for everything, and the hard traveling makes it all worse. Lewis does know how to tell a satisfying redemption arc; one of the things I have always liked about Edmund's story is that he learns his lesson and becomes my favorite character in the subsequent stories. But, sadly, Eustace's redemption arc is another matter. He's totally different here than he was at the start of The Voyage of the Dawn Treader (to the degree that if he didn't have the same name in both books, I wouldn't recognize him as the same person), but rather than a better person he seems to have become a different sort of ass. There's no sign here of the humility and appreciation for friendship that he supposedly learned from his time as a dragon. On top of that, the story isn't very interesting. Rilian, the lost Prince, is a damp squib who talks in the irritating archaic accent that Lewis insists on using for all Narnian royalty. His story feels like Lewis lifted it from medieval Arthurian literature; most of it could be dropped into a collection of stories of knights of the Round Table without seeming out of place. When you have a country full of talking animals and weirdly fascinating bits of theology, it's disappointing to get a garden-variety story about an evil enchantress in which everyone is noble and tragic and extremely stupid. Thankfully, The Silver Chair has one important redeeming quality: Puddleglum. Puddleglum is a Marsh-wiggle, a bipedal amphibious sort who lives alone in the northern marshes. He's recruited by the owls to help the kids with their mission when they fail to get King Caspian's help after blowing the first Sign. Puddleglum is an absolute delight: endlessly pessimistic, certain the worst possible thing will happen at any moment, but also weirdly cheerful about it. I love Eeyore characters in general, but Puddleglum is even better because he gives the kids' endless bickering exactly the respect that it deserves.
"But we all need to be very careful about our tempers, seeing all the hard times we shall have to go through together. Won't do to quarrel, you know. At any rate, don't begin it too soon. I know these expeditions usually end that way; knifing one another, I shouldn't wonder, before all's done. But the longer we can keep off it "
It's even more obvious on re-reading that Puddleglum is the only effective member of the party. Jill has only a couple of moments where she gets the three of them past some obstacle. Eustace is completely useless; I can't remember a single helpful thing he does in the entire book. Puddleglum and his pessimistic determination, on the other hand, is right about nearly everything at each step. And he's the one who takes decisive action to break the Lady of the Green Kirtle's spell near the end. I was expecting a bit of sexism and (mostly in upcoming books) racism when re-reading these books as an adult given when they were written and who Lewis was, but what has caught me by surprise is the colonialism. Lewis is weirdly insistent on importing humans from England to fill all the important roles in stories, even stories that are entirely about Narnians. I know this is the inherent weakness of portal fantasy, but it bothers me how little Lewis believes in Narnians solving their own problems. The Silver Chair makes this blatantly obvious: if Aslan had just told Puddleglum the same information he told Jill and sent a Badger or a Beaver or a Mouse along with him, all the evidence in the book says the whole affair would have been sorted out with much less fuss and anxiety. Jill and Eustace are far more of a hindrance than a help, which makes for frustrating reading when they're supposedly the protagonists. The best part of this book is the underground bits, once they finally get through the first three Signs and stumble into the Lady's kingdom far below the surface. Rilian is a great disappointment, but the fight against the Lady's mind-altering magic leads to one of the great quotes of the series, on par with Reepicheep's speech in The Voyage of the Dawn Treader.
"Suppose we have only dreamed, or made up, all those things trees and grass and sun and moon and stars and Aslan himself. Suppose we have. Then all I can say is that, in that case, the made-up things seem a good deal more important than the real ones. Suppose this black pit of a kingdom of yours is the only world. Well, it strikes me as a pretty poor one. And that's a funny thing, when you come to think of it. We're just babies making up a game, if you're right. But four babies playing a game can make a play-world which licks your real world hollow. That's why I'm going to stand by the play world. I'm on Aslan's side even if there isn't any Aslan to lead it. I'm going to live as like a Narnian as I can even if there isn't any Narnia. So, thanking you kindly for our supper, if these two gentlemen and the young lady are ready, we're leaving your court at once and setting out in the dark to spend our lives looking for Overland. Not that our lives will be very long, I should think; but that's small loss if the world's as dull a place as you say."
This is Puddleglum, of course. And yes, I know that this is apologetics and Lewis is talking about Christianity and making the case for faith without proof, but put that aside for the moment, because this is still powerful life philosophy. It's a cynic's litany against cynicism. It's a pessimist's defense of hope. Suppose we have only dreamed all those things like justice and fairness and equality, community and consensus and collaboration, universal basic income and effective environmentalism. The dreary magic of the realists and the pragmatists say that such things are baby's games, silly fantasies. But you can still choose to live like you believe in them. In Alasdair Gray's reworking of a line from Dennis Lee, "work as if you live in the early days of a better nation." That's one moment that I'll always remember from this book. The other is after they kill the Lady of the Green Kirtle and her magic starts to fade, they have to escape from the underground caverns while surrounded by the Earthmen who served her and who they believe are hostile. It's a tense moment that turns into a delightful celebration when they realize that the Earthmen were just as much prisoners as the Prince was. They were forced from a far deeper land below, full of living metals and salamanders who speak from rivers of fire. It's the one moment in this book that I thought captured the magical strangeness of Narnia, that sense that there are wonderful things just out of sight that don't follow the normal patterns of medieval-ish fantasy. Other than a few great lines from Puddleglum and some moments in Aslan's country, the first 60% of this book is a loss and remarkably frustrating to read. The last 40% isn't bad, although I wish Rilian had any discernible character other than generic Arthurian knight. I don't know what Eustace is doing in this book at all other than providing a way for Jill to get into Narnia, and I wish Lewis had realized Puddleglum could be the protagonist. But as frustrating as The Silver Chair can be, I am still glad I re-read it. Puddleglum is one of the truly memorable characters of children's literature, and it's a shame he's buried in a weak mid-series book. Followed, in the original publication order, by The Horse and His Boy. Rating: 6 out of 10

29 May 2021

Shirish Agarwal: Planes, Pandemic and Medical Devices I

The Great Electric Airplane Race It took me quite sometime to write as have been depressed about things. Then a few days back saw Nova s The Great Electric Airplane Race. While it was fabulous and a pleasure to see and know that there are more than 200 odd startups who are in the race of making an electric airplane which works and has FAA certification. I was disappointed though that there no coverage of any University projects. From what little I know, almost all advanced materials which U.S. had made has been first researched in mostly Universities and when it is close to fruition then either spin-off as a startup or give to some commercial organization/venture to make it scalable and profitable. If they had, I am sure more people could be convinced to join sciences and engineering in college. I actually do want to come to this as part of both general medicine and vaccine development in U.S. but will come later. The idea that industry works alone should be discouraged, but that perhaps may require another article to articulate why I believe so.

Medical Device Ventilators in India Before the pandemic, probably most didn t know what a ventilator is and was, at least I didn t, although I probably used it during my somewhat brief hospital stay a couple of years ago. It entered into the Indian twitter lexicon more so in the second wave as the number of people who got infected became more and more and the ventilators which were serving them became less and less just due to sheer mismatch of numbers and requirements. Rich countries donated/gifted ventilators to India on which GOI put GST of 28%. Apparently, they are a luxury item, just like my hearing aid. Last week Delhi High Court passed a judgement that imposition of GST should not be on a gift like ventilators or oxygenators. The order can be found here. Even without reading the judgement the shout from the right was judicial activism while after reading it is a good judgement which touches on several points. The first, in itself, stating the dichotomy that if a commercial organization wanted to import a ventilator or an oxygenator the IGST payable is nil while for an individual it is 12%. The State (here State refers to State Government in this case Gujarat Govt.) did reduce the IGST for state from 12% to NIL IGST for federal states but that to till only 30.06.2021. No relief to individuals on that account. The Court also made use of Mr. Arvind Datar, as Amicus Curiae or friend of court. The petitioner, an 85-year-old gentleman who has put it up has put broad assertions under Article 21 (right to live) and the court in its wisdom also added Article 14 which enshrines equality of everyone before law. The Amicus Curiae, as his duty, guided the court into how the IGST law works and shared a brief history of the law and the changes happening before and after it. During his submissions, he also shared the Mega Exemption Notification no. 50/2017 under which several items are there which are exempted from putting IGST. The Amicus Curiae did note that such exemptions were also there before Mega Exemption Notification had come into play. However, DGFT (Directorate General of Foreign Trade) on 30-04-2021 issued notification No. 4/2015-2020 through which oxygenators had been exempted from Custom Duty/BCD (Basic Customs Duty. In another notification on no. 30/2021 dated 01.05.2021 it reduced IGST from 28% to 12% for personal use. If however the oxygenator was procured by a canalizing agency (bodies such as State Trading Corporation of India (STC) or/and Metals and Minerals Corporation (MMTC) and such are defined as canalising agents) then it will be fully exempted from paying any sort of IGST, albeit subject to certain conditions. What the conditions are were not shared in the open court. The Amicus Curiae further observed that it is contrary to practice where both BCD and IGST has been exempted for canalising agents and others, some IGST has to be paid for personal use. To share within the narrow boundaries of the topic, he shared entry no. 607A of General Exemption no.190 where duty and IGST in case of life-saving drugs are zero provided the life-saving drugs imported have been provided by zero cost from an overseas supplier for personal use. He further shared that the oxygen generator would fall in the same entry of 607A as it fulfills all the criteria as shared for life-saving medicines and devices. He also used the help of Drugs and Cosmetics Act 1940 which provides such a relief. The Amicus Curiae further noted that GOI amended its foreign trade policy (2015-2020) via notification no.4/2015-2020, dated 30.04.2021, issued by DGFT where Rakhi and life-saving drugs for personal use has been exempted from BCD till 30-07-2021. No reason not to give the same exemption to oxygenators which fulfill the same thing. The Amicus Curiae, further observes that there are exceptional circumstances provisions as adverted to in sub-section (2) of Section 25 of the Customs Act, whereby Covid-19 which is known and labelled as a pandemic where the distinctions between the two classes of individuals or agencies do not make any sense. While he did make the observation that exemption from duty is not a right, in the light of the pandemic and Article 14, it does not make sense to have distinctions between the two classes of importers. He further shared from Circular no. 9/2014-Customs, dated 19.08.2014 by CBEC (Central Board of Excise and Customs) which gave broad exemptions under Section 25 (2) of the same act in respect of goods and services imported for safety and rehabilitation of people suffering and effected by natural disasters and epidemics. He further submits that the impugned notification is irrational as there is no intelligible differentia rule applied or observed in classifying the import of oxygen concentrators into two categories. One, by the State and its agencies; and the other, by an individual for personal use by way of gift. So there was an absence of adequate determining principle . To bolster his argument, he shared the judgements of

a) Union of India vs. N.S. Rathnam & Sons, (2015) 10 SCC 681 (N.S. Ratnams and Sons Case) b) Shayara Bano vs. Union of India, (2017) 9 SCC 1 (Shayara Bano Case) The Amicus Curiae also rightly observed that the right to life also encompasses within it, the right to health. You cannot have one without the other and within that is the right to have affordable treatment. He further stated that the state does not only have a duty but a positive obligation is cast upon it to ensure that the citizen s health is secured. He again cited Navtej Singh Johars vs Union of India (Navtej Singh Johar Case) in defence of right to life. Mr. Datar also shared that unlike in normal circumstances, it is and should be enough to show distinct and noticeable burdensomeness which is directly attributable to the impugned/questionable tax. The gentleman cited Indian Express Newspapers (Bombay) Private Limited vs. Union of India, (1985) 1 SCC 641 (Indian Express case) 1985 which shared both about Article 19 (1) (a) and Article 21. Bloggers note At this juncture, I should point out which I am sharing the judgement and I would be sharing only the Amicus Curiae POV and then the judge s final observations. While I was reading it, I was stuck by the fact that the Amicus Curiae had cited 4 cases till now, 3 of them are pretty well known both in the legal fraternity and even among public at large. Another 3 which have been shared below which are also of great significance. Hence, felt the need to share the whole judgement. The Amicus Curiae further observed that this tax would have to be disproportionately will have to be paid by the old and the infirm, and they might find it difficult to pay the amounts needed to pay the customs duty/IGST as well as find the agent to pay in this pandemic. Blogger Note The situation with the elderly is something like this. Now there are a few things to note, only Central Govt. employees and pensioners get pensions which has been freezed since last year. The rest of the elderly population does not. The rate of interest has fallen to record lows from 5-6% in savings interest rate to 2% and on Fixed Deposits at 4.9% while the nominal inflation rate has up by 6% while CPI and real inflation rates are and would be much more. And this is when there is absolutely no demand in the economy. To add to all this, RBI shared a couple of months ago that fraud of 5 trillion rupees has been committed between 2015 and 2019 in banks. And this is different from the number of record NPA s that have been both in Public and Private Sector banks. To get out of this, the banks have squeezed their customers and are squeezing as well as asking GOI for bailouts. How much GOI is responsible for the frauds as well as NPA s would probably require its own space. And even now, RBI and banks have made heavy provisions as lockdowns are still a facet and are supposed to remain a facet till the end of the year or even next year (all depending upon when we get the vaccine). The Amicus Curiae further argued that the ventilators which are available locally are of bad quality. The result of all this has resulted in a huge amount of unsurmountable pressure on hospitals which they are unable to overcome. Therefore, the levy of IGST on oxygenators has direct impact on health of the citizen. So the examination of the law should not be by what intention it was but how it is affecting citizen rights now. For this he shared R.C.Cooper vs Union of India (another famous case R.C. Cooper vs Union of India) especially paragraph 49 and Federation of Hotel & Restaurant Association of India vs. Union of India, (1989) at paragraph 46 (Federation of Hotel Case) Mr. Datar further shared the Supreme Court order dated 18.12.2020, passed in Suo Moto Writ Petition(Civil) No.7/2020, to buttress the plea that the right to health includes the right to affordable treatment. Blogger s Note For those, who don t know Suo Moto is when the Court, whether Supreme Court or the High Courts take up a matter for public good. It could be in anything, law and order, Banking, Finance, Public Health etc. etc. This was the norm before 2014. The excesses of the executive were curtailed by both the Higher and the lower Judiciary. That is and was the reason that Judiciary is and was known as the third pillar of Indian democracy. A good characterization of Suo Moto can be found here. Before ending his submission, the learned Amicus Curiae also shared Jeeja Ghosh vs. Union of India, (2016) (Jeeja Ghosh Case, an outstanding case as it deals with people with disabilities and their rights and the observations made by the Division Bench of Hon ble Mr. Justice A. K. Sikri as well as Hon ble Mr. Justice R. K. Agrawal.) After Amicus Curiae completed his submissions, it was the turn of Mr. Sudhir Nandrajog, and he adopted the arguments and submissions made by the Amicus Curiae. The gentleman reiterated the facts of the case and how the impugned notification was violative of both Article 14 and 21 of the Indian Constitution. Blogger s Note The High Court s judgement which shows all the above arguments by the Amicus Curiae and the petitioner s lawyer also shared the State s view. It is only on page 24, where the Delhi High Court starts to share its own observations on the arguments of both sides. Judgement continued The first observation that the Court makes is that while the petitioner demonstrated that the impugned tax imposition would have a distinct and noticeable burdensomeness while the State did not state or share in any way how much of a loss it would incur if such a tax were let go and how much additional work would have to be done in order to receive this specific tax. It didn t need to do something which is down the wire or mathematically precise, but it didn t even care to show even theoretically how many people will be affected by the above. The counter-affidavit by the State is silent on the whole issue. The Court also contended that the State failed to prove how collecting IGST from the concerned individuals would help in fighting coronavirus in any substantial manner for the public at large. The High Court shared observations from the Navtej Singh Johar case where it is observed that the State has both negative and positive obligations to ensure that its citizens are able to enjoy the right to health. The High Court further made the point that no respectable person does like to be turned into a charity case. If the State contends that those who obey the law should pay the taxes then it is also obligatory on the state s part to lessen exactions such as taxes at the very least in times of war, famine, floods, epidemics and pandemics. Such an approach would lead a person to live a life of dignity which is part of Article 21 of the Constitution. Another point that was made by the State that only the GST council is able to make any changes as regards to exemptions rather than the State were found to be false as the State had made some exemptions without going to the GST council using its own powers under Section 25 of the Customs Act. The Court also points out that it does send a discriminatory pattern when somebody like petitioner has to pay the tax for personal use while those who are buying it for commercial use do not have to pay the tax. The Court agreed of the view of the Amicus Curiae, Mr. Datar that oxygenator should be taxed at NIL rate at IGST as it is part of life-saving drugs and oxygenator fits the bill as medical equipment as it is used in the treatment, mitigation and prevention of spread of Coronavirus. Mr. Datar also did show that oxygenator is placed at the same level as other life-saving drugs. The Court felt further emboldened as the observations by Supreme Court in State of Andhra Pradesh vs. Linde India Limited, 2020 ( State of Andhra Pradesh vs Linde Ltd.) The Court further shared many subsequent notifications from the State and various press releases by the State itself which does make the Court s point that oxygenators indeed are drugs as defined in the court case above. The State should have it as part of notification 190. This would preserve the start of the notification date from 03.05.2021 and the state would not have to issue a new notification. The Court further went to postulate that any persons similar to the petitioner could avail of the same, if they furnish a letter of undertaking to an officer designated by the State that the medical equipment would not be put to commercial use. Till the state does not do that, in the interim the importer could give the same undertaking to Joint Secretary, Customs or their nominee can hand over the same to custom officer. The Court also shared that it does not disagree with the State s arguments but the challenges which have arisen are in a unique time period/circumstances, so they are basing their judgement based on how the situation is. The Court also mentioned an order given by Supreme Court Diary No. 10669/2020 passed on 20.03.2020 where SC has taken pains to understand the issues faced by the citizens. The court also mentioned the Small Scale Industrial Manufactures Association Case (both of these cases I don t know) . So in conclusion, the Court holds the imposition of IGST on oxygenator which are imported by individuals as gifts from their relatives as unconstitutional. They also shared that any taxes taken by GOI in above scenario have to be returned. The relief to the state is they will not have to pay interest cost on the same. To check misuse of the same, the petitioner or people who are in similar circumstances would have to give a letter of undertaking to an officer designated by the State within 7 days of the state notifying the patient or anybody authorized by him/her to act on their behalf to share the letter of undertaking with the State. And till the State doesn t provide an officer, the above will continue. Hence, both the writ petition and the pending application are disposed off. The Registry is directed to release any money deposited by the petitioner along with any interest occurred on it (if any) . At the end they record appreciation of Mr. Arvind Datar, Mr. Zoheb Hossain, Mr. Sudhir Nandrajog as well as Mr. Siddharth Bambha. It is only due to their assistance that the court could reach the conclusion it did. For Delhi High Court RAJIV SHAKDHER, J. TALWANT SINGH, J. May 21, 2020 Blogger s Observations Now, after the verdict GOI does have few choices, either accept the verdict or appeal in the SC. A third choice is to make a committee and come to the same conclusions via the committee. GOI has done something similar in the past. If that happens and the same conclusions are reached as before, then the aggrieved may have no choice but to appear in the highest court of law. And this will put the aggrieved at a much more vulnerable place than before as SC court fees, lawyer fees etc. are quite high compared to High Courts. So, there is a possibility that the petitioner may not even approach unless and until some non-profit (NGO) does decide to fight and put it up as common cause or something similar. There is another judgement that I will share, probably tomorrow. Thankfully, that one is pretty short compared to this one. So it should be far more easier to read. FWIW, I did learn about the whole freeenode stuff and many channels who have shifted from freenode to libera. I will share my own experience of the same but that probably will take a day or two.
Zeeshan of IYC (India Youth Congress) along with Salman Khan s non-profit Being Human getting oxygenators

The above picture of Zeeshan. There have been a whole team of Indian Youth Congress workers (main opposition party to the ruling party) who have doing lot of relief effort. They have been buying Oxygenators from abroad with help of Being Human Foundation started by Salman Khan, an actor who works in A-grade movies in Bollywood.

28 May 2021

Jonathan McDowell: Trying to understand Kubernetes networking

I previously built a single node Kubernetes cluster as a test environment to learn more about it. The first thing I want to try to understand is its networking. In particular the IP addresses that are listed are all 10.* and my host s network is a 192.168/24. I understand each pod gets its own virtual ethernet interface and associated IP address, and these are generally private within the cluster (and firewalled out other than for exposed services). What does that actually look like?
$ ip route
default via 192.168.53.1 dev enx00e04c6851de
172.17.0.0/16 dev docker0 proto kernel scope link src 172.17.0.1 linkdown
192.168.0.0/24 dev weave proto kernel scope link src 192.168.0.1
192.168.53.0/24 dev enx00e04c6851de proto kernel scope link src 192.168.53.147
Huh. No sign of any way to get to 10.107.66.138 (the IP my echoserver from the previous post is available on directly from the host). What about network interfaces? (under the cut because it s lengthy)
ip addr
1: lo: <LOOPBACK,UP,LOWER_UP> mtu 65536 qdisc noqueue state UNKNOWN group default qlen 1000
    link/loopback 00:00:00:00:00:00 brd 00:00:00:00:00:00
    inet 127.0.0.1/8 scope host lo
       valid_lft forever preferred_lft forever
2: enx00e04c6851de: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc pfifo_fast state UP group default qlen 1000
    link/ether 00:e0:4c:68:51:de brd ff:ff:ff:ff:ff:ff
    inet 192.168.53.147/24 brd 192.168.53.255 scope global dynamic enx00e04c6851de
       valid_lft 41571sec preferred_lft 41571sec
3: wlp1s0: <BROADCAST,MULTICAST> mtu 1500 qdisc noop state DOWN group default qlen 1000
    link/ether 74:d8:3e:70:3b:18 brd ff:ff:ff:ff:ff:ff
4: docker0: <NO-CARRIER,BROADCAST,MULTICAST,UP> mtu 1500 qdisc noqueue state DOWN group default
    link/ether 02:42:18:04:9e:08 brd ff:ff:ff:ff:ff:ff
    inet 172.17.0.1/16 brd 172.17.255.255 scope global docker0
       valid_lft forever preferred_lft forever
5: datapath: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1376 qdisc noqueue state UNKNOWN group default qlen 1000
    link/ether d2:5a:fd:c1:56:23 brd ff:ff:ff:ff:ff:ff
7: weave: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1376 qdisc noqueue state UP group default qlen 1000
    link/ether 12:82:8f:ed:c7:bf brd ff:ff:ff:ff:ff:ff
    inet 192.168.0.1/24 brd 192.168.0.255 scope global weave
       valid_lft forever preferred_lft forever
9: vethwe-datapath@vethwe-bridge: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1376 qdisc noqueue master datapath state UP group default
    link/ether b6:49:88:d6:6d:84 brd ff:ff:ff:ff:ff:ff
10: vethwe-bridge@vethwe-datapath: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1376 qdisc noqueue master weave state UP group default
    link/ether 6e:6c:03:1d:e5:0e brd ff:ff:ff:ff:ff:ff
11: vxlan-6784: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 65535 qdisc noqueue master datapath state UNKNOWN group default qlen 1000
    link/ether 9a:af:c5:0a:b3:fd brd ff:ff:ff:ff:ff:ff
13: vethwepl534c0a6@if12: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1376 qdisc noqueue master weave state UP group default
    link/ether 1e:ac:f1:85:61:9a brd ff:ff:ff:ff:ff:ff link-netnsid 0
15: vethwepl9ffd6b6@if14: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1376 qdisc noqueue master weave state UP group default
    link/ether 56:ca:71:2a:ab:39 brd ff:ff:ff:ff:ff:ff link-netnsid 1
17: vethwepl62b369d@if16: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1376 qdisc noqueue master weave state UP group default
    link/ether e2:a0:bb:ee:fc:73 brd ff:ff:ff:ff:ff:ff link-netnsid 2
23: vethwepl6669168@if22: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1376 qdisc noqueue master weave state UP group default
    link/ether f2:e7:e6:95:e0:61 brd ff:ff:ff:ff:ff:ff link-netnsid 3
That looks like a collection of virtual ethernet devices that are being managed by the weave networking plugin, and presumably partnered inside each pod. They re bridged to the weave interface (the master weave bit). Still no clues about the 10.* range. What about ARP?
ip neigh
192.168.53.1 dev enx00e04c6851de lladdr e4:8d:8c:35:98:d5 DELAY
192.168.0.4 dev datapath lladdr da:22:06:96:50:cb STALE
192.168.0.2 dev weave lladdr 66:eb:ce:16:3c:62 REACHABLE
192.168.53.136 dev enx00e04c6851de lladdr 00:e0:4c:39:f2:54 REACHABLE
192.168.0.6 dev weave lladdr 56:a9:f0:d2:9e:f3 STALE
192.168.0.3 dev datapath lladdr f2:42:c9:c3:08:71 STALE
192.168.0.3 dev weave lladdr f2:42:c9:c3:08:71 REACHABLE
192.168.0.2 dev datapath lladdr 66:eb:ce:16:3c:62 STALE
192.168.0.6 dev datapath lladdr 56:a9:f0:d2:9e:f3 STALE
192.168.0.4 dev weave lladdr da:22:06:96:50:cb STALE
192.168.0.5 dev datapath lladdr fe:6f:1b:14:56:5a STALE
192.168.0.5 dev weave lladdr fe:6f:1b:14:56:5a REACHABLE
Nope. That just looks like addresses on the weave managed bridge. Alright. What about firewalling?
nft list ruleset
table ip nat  
	chain DOCKER  
		iifname "docker0" counter packets 0 bytes 0 return
	 
	chain POSTROUTING  
		type nat hook postrouting priority srcnat; policy accept;
		 counter packets 531750 bytes 31913539 jump KUBE-POSTROUTING
		oifname != "docker0" ip saddr 172.17.0.0/16 counter packets 1 bytes 84 masquerade 
		counter packets 525600 bytes 31544134 jump WEAVE
	 
	chain PREROUTING  
		type nat hook prerouting priority dstnat; policy accept;
		 counter packets 180 bytes 12525 jump KUBE-SERVICES
		fib daddr type local counter packets 23 bytes 1380 jump DOCKER
	 
	chain OUTPUT  
		type nat hook output priority -100; policy accept;
		 counter packets 527005 bytes 31628455 jump KUBE-SERVICES
		ip daddr != 127.0.0.0/8 fib daddr type local counter packets 285425 bytes 17125524 jump DOCKER
	 
	chain KUBE-MARK-DROP  
		counter packets 0 bytes 0 meta mark set mark or 0x8000 
	 
	chain KUBE-MARK-MASQ  
		counter packets 0 bytes 0 meta mark set mark or 0x4000 
	 
	chain KUBE-POSTROUTING  
		mark and 0x4000 != 0x4000 counter packets 4622 bytes 277720 return
		counter packets 0 bytes 0 meta mark set mark xor 0x4000 
		 counter packets 0 bytes 0 masquerade 
	 
	chain KUBE-KUBELET-CANARY  
	 
	chain INPUT  
		type nat hook input priority 100; policy accept;
	 
	chain KUBE-PROXY-CANARY  
	 
	chain KUBE-SERVICES  
		meta l4proto tcp ip daddr 10.96.0.10  tcp dport 9153 counter packets 0 bytes 0 jump KUBE-SVC-JD5MR3NA4I4DYORP
		meta l4proto tcp ip daddr 10.107.66.138  tcp dport 8080 counter packets 1 bytes 60 jump KUBE-SVC-666FUMINWJLRRQPD
		meta l4proto tcp ip daddr 10.111.16.129  tcp dport 443 counter packets 0 bytes 0 jump KUBE-SVC-EZYNCFY2F7N6OQA2
		meta l4proto tcp ip daddr 10.96.9.41  tcp dport 443 counter packets 0 bytes 0 jump KUBE-SVC-EDNDUDH2C75GIR6O
		meta l4proto tcp ip daddr 192.168.53.147  tcp dport 443 counter packets 0 bytes 0 jump KUBE-XLB-EDNDUDH2C75GIR6O
		meta l4proto tcp ip daddr 10.96.9.41  tcp dport 80 counter packets 0 bytes 0 jump KUBE-SVC-CG5I4G2RS3ZVWGLK
		meta l4proto tcp ip daddr 192.168.53.147  tcp dport 80 counter packets 0 bytes 0 jump KUBE-XLB-CG5I4G2RS3ZVWGLK
		meta l4proto tcp ip daddr 10.96.0.1  tcp dport 443 counter packets 0 bytes 0 jump KUBE-SVC-NPX46M4PTMTKRN6Y
		meta l4proto udp ip daddr 10.96.0.10  udp dport 53 counter packets 0 bytes 0 jump KUBE-SVC-TCOU7JCQXEZGVUNU
		meta l4proto tcp ip daddr 10.96.0.10  tcp dport 53 counter packets 0 bytes 0 jump KUBE-SVC-ERIFXISQEP7F7OF4
		 fib daddr type local counter packets 3312 bytes 198720 jump KUBE-NODEPORTS
	 
	chain KUBE-NODEPORTS  
		meta l4proto tcp  tcp dport 31529 counter packets 0 bytes 0 jump KUBE-MARK-MASQ
		meta l4proto tcp  tcp dport 31529 counter packets 0 bytes 0 jump KUBE-SVC-666FUMINWJLRRQPD
		meta l4proto tcp ip saddr 127.0.0.0/8  tcp dport 30894 counter packets 0 bytes 0 jump KUBE-MARK-MASQ
		meta l4proto tcp  tcp dport 30894 counter packets 0 bytes 0 jump KUBE-XLB-EDNDUDH2C75GIR6O
		meta l4proto tcp ip saddr 127.0.0.0/8  tcp dport 32740 counter packets 0 bytes 0 jump KUBE-MARK-MASQ
		meta l4proto tcp  tcp dport 32740 counter packets 0 bytes 0 jump KUBE-XLB-CG5I4G2RS3ZVWGLK
	 
	chain KUBE-SVC-NPX46M4PTMTKRN6Y  
		 counter packets 0 bytes 0 jump KUBE-SEP-Y6PHKONXBG3JINP2
	 
	chain KUBE-SEP-Y6PHKONXBG3JINP2  
		ip saddr 192.168.53.147  counter packets 0 bytes 0 jump KUBE-MARK-MASQ
		meta l4proto tcp   counter packets 0 bytes 0 dnat to 192.168.53.147:6443
	 
	chain WEAVE  
		# match-set weaver-no-masq-local dst  counter packets 135966 bytes 8160820 return
		ip saddr 192.168.0.0/24 ip daddr 224.0.0.0/4 counter packets 0 bytes 0 return
		ip saddr != 192.168.0.0/24 ip daddr 192.168.0.0/24 counter packets 0 bytes 0 masquerade 
		ip saddr 192.168.0.0/24 ip daddr != 192.168.0.0/24 counter packets 33 bytes 2941 masquerade 
	 
	chain WEAVE-CANARY  
	 
	chain KUBE-SVC-JD5MR3NA4I4DYORP  
		  counter packets 0 bytes 0 jump KUBE-SEP-6JI23ZDEH4VLR5EN
		 counter packets 0 bytes 0 jump KUBE-SEP-FATPLMAF37ZNQP5P
	 
	chain KUBE-SEP-6JI23ZDEH4VLR5EN  
		ip saddr 192.168.0.2  counter packets 0 bytes 0 jump KUBE-MARK-MASQ
		meta l4proto tcp   counter packets 0 bytes 0 dnat to 192.168.0.2:9153
	 
	chain KUBE-SVC-TCOU7JCQXEZGVUNU  
		  counter packets 0 bytes 0 jump KUBE-SEP-JTN4UBVS7OG5RONX
		 counter packets 0 bytes 0 jump KUBE-SEP-4TCKAEJ6POVEFPVW
	 
	chain KUBE-SEP-JTN4UBVS7OG5RONX  
		ip saddr 192.168.0.2  counter packets 0 bytes 0 jump KUBE-MARK-MASQ
		meta l4proto udp   counter packets 0 bytes 0 dnat to 192.168.0.2:53
	 
	chain KUBE-SVC-ERIFXISQEP7F7OF4  
		  counter packets 0 bytes 0 jump KUBE-SEP-UPZX2EM3TRFH2ASL
		 counter packets 0 bytes 0 jump KUBE-SEP-KPHYKKPVMB473Z76
	 
	chain KUBE-SEP-UPZX2EM3TRFH2ASL  
		ip saddr 192.168.0.2  counter packets 0 bytes 0 jump KUBE-MARK-MASQ
		meta l4proto tcp   counter packets 0 bytes 0 dnat to 192.168.0.2:53
	 
	chain KUBE-SEP-4TCKAEJ6POVEFPVW  
		ip saddr 192.168.0.3  counter packets 0 bytes 0 jump KUBE-MARK-MASQ
		meta l4proto udp   counter packets 0 bytes 0 dnat to 192.168.0.3:53
	 
	chain KUBE-SEP-KPHYKKPVMB473Z76  
		ip saddr 192.168.0.3  counter packets 0 bytes 0 jump KUBE-MARK-MASQ
		meta l4proto tcp   counter packets 0 bytes 0 dnat to 192.168.0.3:53
	 
	chain KUBE-SEP-FATPLMAF37ZNQP5P  
		ip saddr 192.168.0.3  counter packets 0 bytes 0 jump KUBE-MARK-MASQ
		meta l4proto tcp   counter packets 0 bytes 0 dnat to 192.168.0.3:9153
	 
	chain KUBE-SVC-666FUMINWJLRRQPD  
		 counter packets 1 bytes 60 jump KUBE-SEP-LYLDBZYLHY4MT3AQ
	 
	chain KUBE-SEP-LYLDBZYLHY4MT3AQ  
		ip saddr 192.168.0.4  counter packets 0 bytes 0 jump KUBE-MARK-MASQ
		meta l4proto tcp   counter packets 1 bytes 60 dnat to 192.168.0.4:8080
	 
	chain KUBE-XLB-EDNDUDH2C75GIR6O  
		 fib saddr type local counter packets 0 bytes 0 jump KUBE-MARK-MASQ
		 fib saddr type local counter packets 0 bytes 0 jump KUBE-SVC-EDNDUDH2C75GIR6O
		 counter packets 0 bytes 0 jump KUBE-SEP-BLQHCYCSXY3NRKLC
	 
	chain KUBE-XLB-CG5I4G2RS3ZVWGLK  
		 fib saddr type local counter packets 0 bytes 0 jump KUBE-MARK-MASQ
		 fib saddr type local counter packets 0 bytes 0 jump KUBE-SVC-CG5I4G2RS3ZVWGLK
		 counter packets 0 bytes 0 jump KUBE-SEP-5XVRKWM672JGTWXH
	 
	chain KUBE-SVC-EDNDUDH2C75GIR6O  
		 counter packets 0 bytes 0 jump KUBE-SEP-BLQHCYCSXY3NRKLC
	 
	chain KUBE-SEP-BLQHCYCSXY3NRKLC  
		ip saddr 192.168.0.5  counter packets 0 bytes 0 jump KUBE-MARK-MASQ
		meta l4proto tcp   counter packets 0 bytes 0 dnat to 192.168.0.5:443
	 
	chain KUBE-SVC-CG5I4G2RS3ZVWGLK  
		 counter packets 0 bytes 0 jump KUBE-SEP-5XVRKWM672JGTWXH
	 
	chain KUBE-SEP-5XVRKWM672JGTWXH  
		ip saddr 192.168.0.5  counter packets 0 bytes 0 jump KUBE-MARK-MASQ
		meta l4proto tcp   counter packets 0 bytes 0 dnat to 192.168.0.5:80
	 
	chain KUBE-SVC-EZYNCFY2F7N6OQA2  
		 counter packets 0 bytes 0 jump KUBE-SEP-JYW326XAJ4KK7QPG
	 
	chain KUBE-SEP-JYW326XAJ4KK7QPG  
		ip saddr 192.168.0.5  counter packets 0 bytes 0 jump KUBE-MARK-MASQ
		meta l4proto tcp   counter packets 0 bytes 0 dnat to 192.168.0.5:8443
	 
 
table ip filter  
	chain DOCKER  
	 
	chain DOCKER-ISOLATION-STAGE-1  
		iifname "docker0" oifname != "docker0" counter packets 0 bytes 0 jump DOCKER-ISOLATION-STAGE-2
		counter packets 0 bytes 0 return
	 
	chain DOCKER-ISOLATION-STAGE-2  
		oifname "docker0" counter packets 0 bytes 0 drop
		counter packets 0 bytes 0 return
	 
	chain FORWARD  
		type filter hook forward priority filter; policy drop;
		iifname "weave"  counter packets 213 bytes 54014 jump WEAVE-NPC-EGRESS
		oifname "weave"  counter packets 150 bytes 30038 jump WEAVE-NPC
		oifname "weave" ct state new counter packets 0 bytes 0 log group 86 
		oifname "weave" counter packets 0 bytes 0 drop
		iifname "weave" oifname != "weave" counter packets 33 bytes 2941 accept
		oifname "weave" ct state related,established counter packets 0 bytes 0 accept
		 counter packets 0 bytes 0 jump KUBE-FORWARD
		ct state new  counter packets 0 bytes 0 jump KUBE-SERVICES
		ct state new  counter packets 0 bytes 0 jump KUBE-EXTERNAL-SERVICES
		counter packets 0 bytes 0 jump DOCKER-USER
		counter packets 0 bytes 0 jump DOCKER-ISOLATION-STAGE-1
		oifname "docker0" ct state related,established counter packets 0 bytes 0 accept
		oifname "docker0" counter packets 0 bytes 0 jump DOCKER
		iifname "docker0" oifname != "docker0" counter packets 0 bytes 0 accept
		iifname "docker0" oifname "docker0" counter packets 0 bytes 0 accept
	 
	chain DOCKER-USER  
		counter packets 0 bytes 0 return
	 
	chain KUBE-FIREWALL  
		 mark and 0x8000 == 0x8000 counter packets 0 bytes 0 drop
		ip saddr != 127.0.0.0/8 ip daddr 127.0.0.0/8  ct status dnat counter packets 0 bytes 0 drop
	 
	chain OUTPUT  
		type filter hook output priority filter; policy accept;
		ct state new  counter packets 527014 bytes 31628984 jump KUBE-SERVICES
		counter packets 36324809 bytes 6021214027 jump KUBE-FIREWALL
		meta l4proto != esp  mark and 0x20000 == 0x20000 counter packets 0 bytes 0 drop
	 
	chain INPUT  
		type filter hook input priority filter; policy accept;
		 counter packets 35869492 bytes 5971008896 jump KUBE-NODEPORTS
		ct state new  counter packets 390938 bytes 23457377 jump KUBE-EXTERNAL-SERVICES
		counter packets 36249774 bytes 6030068622 jump KUBE-FIREWALL
		meta l4proto tcp ip daddr 127.0.0.1 tcp dport 6784 fib saddr type != local ct state != related,established  counter packets 0 bytes 0 drop
		iifname "weave" counter packets 907273 bytes 88697229 jump WEAVE-NPC-EGRESS
		counter packets 34809601 bytes 5818213726 jump WEAVE-IPSEC-IN
	 
	chain KUBE-KUBELET-CANARY  
	 
	chain KUBE-PROXY-CANARY  
	 
	chain KUBE-EXTERNAL-SERVICES  
	 
	chain KUBE-NODEPORTS  
		meta l4proto tcp  tcp dport 32196 counter packets 0 bytes 0 accept
		meta l4proto tcp  tcp dport 32196 counter packets 0 bytes 0 accept
	 
	chain KUBE-SERVICES  
	 
	chain KUBE-FORWARD  
		ct state invalid counter packets 0 bytes 0 drop
		 mark and 0x4000 == 0x4000 counter packets 0 bytes 0 accept
		 ct state related,established counter packets 0 bytes 0 accept
		 ct state related,established counter packets 0 bytes 0 accept
	 
	chain WEAVE-NPC-INGRESS  
	 
	chain WEAVE-NPC-DEFAULT  
		# match-set weave-;rGqyMIl1HN^cfDki~Z$3]6!N dst  counter packets 14 bytes 840 accept
		# match-set weave-P.B !ZhkAr5q=XZ?3 tMBA+0 dst  counter packets 0 bytes 0 accept
		# match-set weave-Rzff h:=]JaaJl/G;(XJpGjZ[ dst  counter packets 0 bytes 0 accept
		# match-set weave-]B*(W?)t*z5O17G044[gUo#$l dst  counter packets 0 bytes 0 accept
		# match-set weave-iLgO^ o=U/*%KE[@=W:l~ 9T dst  counter packets 9 bytes 540 accept
	 
	chain WEAVE-NPC  
		ct state related,established counter packets 124 bytes 28478 accept
		ip daddr 224.0.0.0/4 counter packets 0 bytes 0 accept
		# PHYSDEV match --physdev-out vethwe-bridge --physdev-is-bridged counter packets 3 bytes 180 accept
		ct state new counter packets 23 bytes 1380 jump WEAVE-NPC-DEFAULT
		ct state new counter packets 0 bytes 0 jump WEAVE-NPC-INGRESS
	 
	chain WEAVE-NPC-EGRESS-ACCEPT  
		counter packets 48 bytes 3769 meta mark set mark or 0x40000 
	 
	chain WEAVE-NPC-EGRESS-CUSTOM  
	 
	chain WEAVE-NPC-EGRESS-DEFAULT  
		# match-set weave-s_+ChJId4Uy_$ G;WdH ~TK)I src  counter packets 0 bytes 0 jump WEAVE-NPC-EGRESS-ACCEPT
		# match-set weave-s_+ChJId4Uy_$ G;WdH ~TK)I src  counter packets 0 bytes 0 return
		# match-set weave-E1ney4o[ojNrLk.6rOHi;7MPE src  counter packets 31 bytes 2749 jump WEAVE-NPC-EGRESS-ACCEPT
		# match-set weave-E1ney4o[ojNrLk.6rOHi;7MPE src  counter packets 31 bytes 2749 return
		# match-set weave-41s)5vQ^o/xWGz6a20N:~?# E src  counter packets 0 bytes 0 jump WEAVE-NPC-EGRESS-ACCEPT
		# match-set weave-41s)5vQ^o/xWGz6a20N:~?# E src  counter packets 0 bytes 0 return
		# match-set weave-sui%__gZ kX~oZgI_Ttqp=Dp src  counter packets 0 bytes 0 jump WEAVE-NPC-EGRESS-ACCEPT
		# match-set weave-sui%__gZ kX~oZgI_Ttqp=Dp src  counter packets 0 bytes 0 return
		# match-set weave-nmMUaDKV*YkQcP5s?Q[R54Ep3 src  counter packets 17 bytes 1020 jump WEAVE-NPC-EGRESS-ACCEPT
		# match-set weave-nmMUaDKV*YkQcP5s?Q[R54Ep3 src  counter packets 17 bytes 1020 return
	 
	chain WEAVE-NPC-EGRESS  
		ct state related,established counter packets 907425 bytes 88746642 accept
		# PHYSDEV match --physdev-in vethwe-bridge --physdev-is-bridged counter packets 0 bytes 0 return
		fib daddr type local counter packets 11 bytes 640 return
		ip daddr 224.0.0.0/4 counter packets 0 bytes 0 return
		ct state new counter packets 50 bytes 3961 jump WEAVE-NPC-EGRESS-DEFAULT
		ct state new mark and 0x40000 != 0x40000 counter packets 2 bytes 192 jump WEAVE-NPC-EGRESS-CUSTOM
	 
	chain WEAVE-IPSEC-IN  
	 
	chain WEAVE-CANARY  
	 
 
table ip mangle  
	chain KUBE-KUBELET-CANARY  
	 
	chain PREROUTING  
		type filter hook prerouting priority mangle; policy accept;
	 
	chain INPUT  
		type filter hook input priority mangle; policy accept;
		counter packets 35716863 bytes 5906910315 jump WEAVE-IPSEC-IN
	 
	chain FORWARD  
		type filter hook forward priority mangle; policy accept;
	 
	chain OUTPUT  
		type route hook output priority mangle; policy accept;
		counter packets 35804064 bytes 5938944956 jump WEAVE-IPSEC-OUT
	 
	chain POSTROUTING  
		type filter hook postrouting priority mangle; policy accept;
	 
	chain KUBE-PROXY-CANARY  
	 
	chain WEAVE-IPSEC-IN  
	 
	chain WEAVE-IPSEC-IN-MARK  
		counter packets 0 bytes 0 meta mark set mark or 0x20000
	 
	chain WEAVE-IPSEC-OUT  
	 
	chain WEAVE-IPSEC-OUT-MARK  
		counter packets 0 bytes 0 meta mark set mark or 0x20000
	 
	chain WEAVE-CANARY  
	 
 
Wow. That s a lot of nftables entries, but it explains what s going on. We have a nat entry for:
meta l4proto tcp ip daddr 10.107.66.138 tcp dport 8080 counter packets 1 bytes 60 jump KUBE-SVC-666FUMINWJLRRQPD
which ends up going to KUBE-SEP-LYLDBZYLHY4MT3AQ and:
meta l4proto tcp counter packets 1 bytes 60 dnat to 192.168.0.4:8080
So packets headed for our echoserver are eventually ending up in a container that has a local IP address of 192.168.0.4. Which we can see in our routing table via the weave interface. Mystery explained. We can see the ingress for the externally visible HTTP service as well:
meta l4proto tcp ip daddr 192.168.33.147 tcp dport 80 counter packets 0 bytes 0 jump KUBE-XLB-CG5I4G2RS3ZVWGLK
which ends up redirected to:
meta l4proto tcp counter packets 0 bytes 0 dnat to 192.168.0.5:80
So from that we d expect the IP inside the echoserver pod to be 192.168.0.4 and the IP address instead our nginx ingress pod to be 192.168.0.5. Let s look:
root@udon:/# docker ps   grep echoserver
7cbb177bee18   k8s.gcr.io/echoserver                 "/usr/local/bin/run. "   3 days ago   Up 3 days             k8s_echoserver_hello-node-59bffcc9fd-8hkgb_default_c7111c9e-7131-40e0-876d-be89d5ca1812_0
root@udon:/# docker exec -it 7cbb177bee18 /bin/bash
root@hello-node-59bffcc9fd-8hkgb:/# awk '/32 host/   print f    f=$2 ' <<< "$(</proc/net/fib_trie)"   sort -u
127.0.0.1
192.168.0.4
It s a slightly awkward method of determining the local IPs addresses due to the stripped down nature of the container, but it clearly shows the expected 192.168.0.4 address. I ve touched here upon the ability to actually enter a container and have a poke around its running environment by using docker directly. Next step is to use that to investigate what containers have actually been spun up and what they re doing. I ll also revisit networking when I get to the point of building a multi-node cluster, to examine how the bridging between different hosts is done.

27 May 2021

Wouter Verhelst: SReview and pandemics

The pandemic was a bit of a mess for most FLOSS conferences. The two conferences that I help organize -- FOSDEM and DebConf -- are no exception. In both conferences, I do essentially the same work: as a member of both video teams, I manage the postprocessing of the video recordings of all the talks that happened at the respective conference(s). I do this by way of SReview, the online video review and transcode system that I wrote, which essentially crowdsources the manual work that needs to be done, and automates as much as possible of the workflow. The original version of SReview consisted of a database, a (very basic) Mojolicious-based webinterface, and a bunch of perl scripts which would build and execute ffmpeg command lines using string interpolation. As a quick hack that I needed to get working while writing it in my spare time in half a year, that approach was workable and resulted in successful postprocessing after FOSDEM 2017, and a significant improvement in time from the previous years. However, I did not end development with that, and since then I've replaced the string interpolation by an object oriented API for generating ffmpeg command lines, as well as modularized the webinterface. Additionally, I've had help reworking the user interface into a system that is somewhat easier to use than my original interface, and have slowly but surely added more features to the system so as to make it more flexible, as well as support more types of environments for the system to run in. One of the major issues that still remains with SReview is that the administrator's interface is pretty terrible. I had been planning on revamping that for 2020, but then massive amounts of people got sick, travel was banned, and both the conferences that I work on were converted to an online-only conference. These have some very specific requirements; e.g., both conferences allowed people to upload a prerecorded version of their talk, rather than doing the talk live; since preprocessing a video is, technically, very similar to postprocessing it, I adapted SReview to allow people to upload a video file that it would then validate (in terms of length, codec, and apparent resolution). This seems like easy to do, but I decided to implement this functionality so that it would also allow future use for in-person conferences, where occasionally a speaker requests that modifications would be made to the video file in a way that SReview is unable to do. This made it marginally more involved, but at least will mean that a feature which I had planned to implement some years down the line is now already implemented. The new feature works quite well, and I'm happy I've implemented it in the way that I have. In order for the "upload" processing and the "post-event" processing to not be confused, however, I decided to import the conference schedules twice: once as the conference itself, and once as a shadow version of that conference for the prerecordings. That way, I could track the progress through the system of the prerecording completely separately from the progress of the postprocessing of the video (which adds opening/closing credits, and transcodes to multiple variants of the same video). Schedule parsing was something that had not been implemented in a generic way yet, however; since that made doubling the schedule in that way rather complex, I decided to bite the bullet and (finally) implement schedule parsing in a generic way. Currently, schedule parsers exist for two formats (Pentabarf XML and the Wafer variant of that same format which is almost, but not quite, entirely the same). The API for that is quite flexible, and I'm happy with the way things have been implemented there. I've also implemented a set of "virtual" parsers, which allow mangling the schedule in various ways (by either filtering out talks that we don't want, or by generating the shadow version of the schedule that I talked about earlier). While the SReview settings have reasonable defaults, occasionally the output of SReview is not entirely acceptable, due to more complicated matters that then result in encoding artifacts. As a result, the DebConf video team has been doing a final review step, completely outside of SReview, to ensure that such encoding artifacts don't exist. That seemed suboptimal, so recently I've been working on integrating that into SReview as well. First tests have been run, and seem to be acceptable, but there's still a few loose ends to be finalized. As part of this, I've also reworked the way comments could be entered into the system. Previously the presence of a comment would signal that the video has some problems that an administrator needed to look at. Unfortunately, that was causing some confusion, with some people even thinking it's a good place to enter a "thank you for your work" style of comment... which it obviously isn't. Turning it into a "comment log" system instead fixes that, and also allows for better two-way communication between administrators and reviewers. Hopefully that'll improve things in that area as well. Finally, the audio normalization in SReview -- for which I've long used bs1770gain -- is having problems. First of all, bs1770gain will sometimes alter the timing of the video or audio file that it's passed, which is very problematic if I want to process it further. There is an ffmpeg loudnorm filter which implements the same algorithm, so that should make things easier to use. Secondly, the author of bs1770gain is a strange character that I'd rather not be involved with. Before I knew about the loudnorm filter I didn't really have a choice, but now I can just rip bs1770gain out and replace it by the loudnorm filter. That will fix various other bugs in SReview, too, because SReview relies on behaviour that isn't actually there (but which I didn't know at the time when I wrote it). All in all, the past year-and-a-bit has seen a lot of development for SReview, with multiple features being added and a number of long-standing problems being fixed. Now if only the pandemic would subside, allowing the whole "let's do everything online only" wave to cool down a bit, so that I can finally make time to implement the admin interface...

26 May 2021

Ian Jackson: Disconnecting from Freenode

I have just disconnected from irc.freenode.net for the last time. You should do the same. The awful new de facto operators are using user numbers as a public justification for their behaviour. Specifically, I recommend that you: Note that mentioning libera in the channel topic of your old channels on freenode is likely to get your channel forcibly taken over by the new de facto operators of freenode. They won't tolerate you officially directing people to the competition. I did an investigation and writeup of this situation for the Xen Project. It's a little out of date - it doesn't have the latest horrible behaviours from the new regime - but I think it is worth pasting it here:
Message-ID: <24741.12566.639691.461134@mariner.uk.xensource.com>
From: Ian Jackson <iwj@xenproject.org>
To: xen-devel@lists.xenproject.org
CC: community.manager@xenproject.org
Subject: IRC networks
Date: Wed, 19 May 2021 16:39:02 +0100
Summary:
We have for many years used the Freenode IRC network for real-time
chat about Xen.  Unfortunately, Freenode is undergoing a crisis.
There is a dispute between, on the one hand, Andrew Lee, and on the
other hand, all (or almost all) Freenode volunteer staff.  We must
make a decision.
I have read all the publicly available materials and asked around with
my contacts.  My conclusions:
 * We do not want to continue to use irc.freenode.*.
 * We might want to use libera.chat, but:
 * Our best option is probably to move to OFTC https://www.oftc.net/
Discussion:
Firstly, my starting point.
I have been on IRC since at least 1993.  Currently my main public
networks are OFTC and Freenode.
I do not have any personal involvement with public IRC networks.  Of
the principals in the current Freenode dispute, I have only heard of
one, who is a person I have experience of in a Debian context but have
not worked closely with.
George asked me informally to use my knowledge and contacts to shed
light on the situation.  I decided that, having done my research, I
would report more formally and publicly here rather than just
informally to George.
Historical background:
 * Freenode has had drama before.  In about 2001 OFTC split off from
   Freenode after an argument over governance.  IIRC there was drama
   again in 2006.  Significant proportion of the Free Software world,
   including Debian, now use OFTC.  Debian switched in 2006.
Facts that I'm (now) pretty sure of:
 * Freenode's actual servers run on donated services; that is,
   the hardware is owned by those donating the services, and the
   systems are managed by Freenode volunteers, known as "staff".
 * The freenode domain names are currently registered to a limited
   liability company owned by Andrew Lee (rasengan).
 * At least 10 Freenode staff have quit in protest, writing similar
   resignation letters protesting about Andrew Lee's actions [1].  It
   does not appear that any Andrew Lee has the public support of any
   Freenode staff.
 * Andrew Lee claims that he "owns" Freenode.[2]
 * A large number of channel owners for particular Free Software
   projects who previously used Freenode have said they will switch
   away from Freenode.
Discussion and findings on Freenode:
There is, as might be expected, some murk about who said what to whom
when, what promises were made and/or broken, and so on.  The matter
was also complicated by the leaking earlier this week of draft(s) of
(at least one of) the Freenode staffers' resignation letters.
Andrew Lee has put forward a position statement [2].  A large part of
the thrust of that statement is allegations that the current head of
Freenode staff, tomaw, "forced out" the previous head, christel.  This
allegation is strongly disputed by by all those current (resigning)
Freenode staff I have seen comment.  In any case it does not seem to
be particularly germane; in none of my reading did tomaw seem to be
playing any kind of leading role.  tomaw is not mentioned in the
resignation letters.
Some of the links led to me to logs of discussions on #freenode.  I
read some of these in particular[3].  MB I haven't been able to verify
that these logs have not been tampered with.  Having said that and
taking the logs at face value, I found the rasengan writing there to
be disingenuous and obtuse.
Andrew Lee has been heavily involved in Bitcoin.  Bitcoin is a hive of
scum and villainy, a pyramid scheme, and an environmental disaster,
all rolled into one.  This does not make me think well of Lee.
Additionally, it seems that Andrew Lee has been involved in previous
governance drama involving a different IRC network, Snoonet.
I have come to the very firm conclusion that we should have nothing to
do with Andrew Lee, and avoid using services that he has some
effective control over.
Alternatives:
The departing Freenode staff are setting up a replacement,
"libera.chat".  This is operational but still suffering from teething
problems and of course has a significant load as it deals with an
influx of users on a new setup.
On the staff and trust question: As I say, I haven't heard of any of
the Freenode staff, with one exception.  Unfortunately the one
exception does not inspire confidence in me[4] - although NB that is
only one data point.
On the other hand, Debian has had many many years of drama-free
involvement with OFTC.  OFTC has a formal governance arrangement and
it is associated with Software in the Public Interest.  I notice that
the last few OFTC'[s annual officer elections have been run partly by
Steve McIntyre.  Steve is a friend of mine (and he is a former Debian
Project Leader) and I take his involvement as a good sign.
I recommend that we switch to using OFTC as soon as possible.
Ian.
References:
Starting point for the resigning Freenode staff's side [1]:
  https://gist.github.com/joepie91/df80d8d36cd9d1bde46ba018af497409
Andrew Lee's side [2]:
  https://gist.github.com/realrasengan/88549ec34ee32d01629354e4075d2d48
[3]
https://paste.sr.ht/~ircwright/7e751d2162e4eb27cba25f6f8893c1f38930f7c4
[4] I won't give the name since I don't want to be shitposting.


comment count unavailable comments

25 May 2021

Vincent Bernat: Jerikan+Ansible: a configuration management system for network

There are many resources for network automation with Ansible. Most of them only expose the first steps or limit themselves to a narrow scope. They give no clue on how to expand from that. Real network environments may be large, versatile, heterogeneous, and filled with exceptions. The lack of real-world examples for Ansible deployments, unlike Puppet and SaltStack, leads many teams to build brittle and incomplete automation solutions. We have released under an open-source license our attempt to tackle this problem: Here is a quick demo to configure a new peering:
This work is the collective effort of C dric Hasco t, Jean-Christophe Legatte, Lo c Pailhas, S bastien Hurtel, Tchadel Icard, and Vincent Bernat. We are the network team of Blade, a French company operating Shadow, a cloud-computing product. In May 2021, our company was bought by Octave Klaba and the infrastructure is being transferred to OVHcloud, saving Shadow as a product, but making our team redundant. Our network was around 800 devices, spanning over 10 datacenters with more than 2.5 Tbps of available egress bandwidth. The released material is therefore a substantial example of managing a medium-scale network using Ansible. We have left out the handling of our legacy datacenters to make the final result more readable while keeping enough material to not turn it into a trivial example.

Jerikan The first component is Jerikan. As input, it takes a list of devices, configuration data, templates, and validation scripts. It generates a set of configuration files for each device. Ansible could cover this task, but it has the following limitations:
  • it is slow;
  • errors are difficult to debug;1 and
  • the hierarchy to look up a variable is rigid.
Jerikan inputs and outputs
If you want to follow the examples, you only need to have Docker and Docker Compose installed. Clone the repository and you are ready!

Source of truth We use YAML files, versioned with Git, as the single source of truth instead of using a database, like NetBox, or a mix of a database and text files. This provides many advantages:
  • anyone can use their preferred text editor;
  • the team prepares changes in branches;
  • the team reviews changes using merge requests;
  • the merge requests expose the changes to the generated configuration files;
  • rollback to a previous state is easy; and
  • it is fast.
The first file is devices.yaml. It contains the device list. The second file is classifier.yaml. It defines a scope for each device. A scope is a set of keys and values. It is used in templates and to look up data associated with a device.
$ ./run-jerikan scope to1-p1.sk1.blade-group.net
continent: apac
environment: prod
groups:
- tor
- tor-bgp
- tor-bgp-compute
host: to1-p1.sk1
location: sk1
member: '1'
model: dell-s4048
os: cumulus
pod: '1'
shorthost: to1-p1
The device name is matched against a list of regular expressions and the scope is extended by the result of each match. For to1-p1.sk1.blade-group.net, the following subset of classifier.yaml defines its scope:
matchers:
  - '^(([^.]*)\..*)\.blade-group\.net':
      environment: prod
      host: '\1'
      shorthost: '\2'
  - '\.(sk1)\.':
      location: '\1'
      continent: apac
  - '^to([12])-[as]?p(\d+)\.':
      member: '\1'
      pod: '\2'
  - '^to[12]-p\d+\.':
      groups:
        - tor
        - tor-bgp
        - tor-bgp-compute
  - '^to[12]-(p ap)\d+\.sk1\.':
      os: cumulus
      model: dell-s4048
The third file is searchpaths.py. It describes which directories to search for a variable. A Python function provides a list of paths to look up in data/ for a given scope. Here is a simplified version:2
def searchpaths(scope):
    paths = [
        "host/ scope[location] / scope[shorthost] ",
        "location/ scope[location] ",
        "os/ scope[os] - scope[model] ",
        "os/ scope[os] ",
        'common'
    ]
    for idx in range(len(paths)):
        try:
            paths[idx] = paths[idx].format(scope=scope)
        except KeyError:
            paths[idx] = None
    return [path for path in paths if path]
With this definition, the data for to1-p1.sk1.blade-group.net is looked up in the following paths:
$ ./run-jerikan scope to1-p1.sk1.blade-group.net
[ ]
Search paths:
  host/sk1/to1-p1
  location/sk1
  os/cumulus-dell-s4048
  os/cumulus
  common
Variables are scoped using a namespace that should be specified when doing a lookup. We use the following ones:
  • system for accounts, DNS, syslog servers,
  • topology for ports, interfaces, IP addresses, subnets,
  • bgp for BGP configuration
  • build for templates and validation scripts
  • apps for application variables
When looking up for a variable in a given namespace, Jerikan looks for a YAML file named after the namespace in each directory in the search paths. For example, if we look up a variable for to1-p1.sk1.blade-group.net in the bgp namespace, the following YAML files are processed: host/sk1/to1-p1/bgp.yaml, location/sk1/bgp.yaml, os/cumulus-dell-s4048/bgp.yaml, os/cumulus/bgp.yaml, and common/bgp.yaml. The search stops at the first match. The schema.yaml file allows us to override this behavior by asking to merge dictionaries and arrays across all matching files. Here is an excerpt of this file for the topology namespace:
system:
  users:
    merge: hash
  sampling:
    merge: hash
  ansible-vars:
    merge: hash
  netbox:
    merge: hash
The last feature of the source of truth is the ability to use Jinja2 templates for keys and values by prefixing them with ~ :
# In data/os/junos/system.yaml
netbox:
  manufacturer: Juniper
  model: "~  model upper  "
# In data/groups/tor-bgp-compute/system.yaml
netbox:
  role: net_tor_gpu_switch
Looking up for netbox in the system namespace for to1-p2.ussfo03.blade-group.net yields the following result:
$ ./run-jerikan scope to1-p2.ussfo03.blade-group.net
continent: us
environment: prod
groups:
- tor
- tor-bgp
- tor-bgp-compute
host: to1-p2.ussfo03
location: ussfo03
member: '1'
model: qfx5110-48s
os: junos
pod: '2'
shorthost: to1-p2
[ ]
Search paths:
[ ]
  groups/tor-bgp-compute
[ ]
  os/junos
  common
$ ./run-jerikan lookup to1-p2.ussfo03.blade-group.net system netbox
manufacturer: Juniper
model: QFX5110-48S
role: net_tor_gpu_switch
This also works for structured data:
# In groups/adm-gateway/topology.yaml
interface-rescue:
  address: "~  lookup('topology', 'addresses').rescue  "
  up:
    - "~ip route add default via   lookup('topology', 'addresses').rescue ipaddr('first_usable')   table rescue"
    - "~ip rule add from   lookup('topology', 'addresses').rescue ipaddr('address')   table rescue priority 10"
# In groups/adm-gateway-sk1/topology.yaml
interfaces:
  ens1f0: "~  lookup('topology', 'interface-rescue')  "
This yields the following result:
$ ./run-jerikan lookup gateway1.sk1.blade-group.net topology interfaces
[ ]
ens1f0:
  address: 121.78.242.10/29
  up:
  - ip route add default via 121.78.242.9 table rescue
  - ip rule add from 121.78.242.10 table rescue priority 10
When putting data in the source of truth, we use the following rules:
  1. Don t repeat yourself.
  2. Put the data in the most specific place without breaking the first rule.
  3. Use templates with parsimony, mostly to help with the previous rules.
  4. Restrict the data model to what is needed for your use case.
The first rule is important. For example, when specifying IP addresses for a point-to-point link, only specify one side and deduce the other value in the templates. The last rule means you do not need to mimic a BGP YANG model to specify BGP peers and policies:
peers:
  transit:
    cogent:
      asn: 174
      remote:
        - 38.140.30.233
        - 2001:550:2:B::1F9:1
      specific-import:
        - name: ATT-US
          as-path: ".*7018$"
          lp-delta: 50
  ix-sfmix:
    rs-sfmix:
      monitored: true
      asn: 63055
      remote:
        - 206.197.187.253
        - 206.197.187.254
        - 2001:504:30::ba06:3055:1
        - 2001:504:30::ba06:3055:2
    blizzard:
      asn: 57976
      remote:
        - 206.197.187.42
        - 2001:504:30::ba05:7976:1
      irr: AS-BLIZZARD

Templates The list of templates to compile for each device is stored in the source of truth, under the build namespace:
$ ./run-jerikan lookup edge1.ussfo03.blade-group.net build templates
data.yaml: data.j2
config.txt: junos/main.j2
config-base.txt: junos/base.j2
config-irr.txt: junos/irr.j2
$ ./run-jerikan lookup to1-p1.ussfo03.blade-group.net build templates
data.yaml: data.j2
config.txt: cumulus/main.j2
frr.conf: cumulus/frr.j2
interfaces.conf: cumulus/interfaces.j2
ports.conf: cumulus/ports.j2
dhcpd.conf: cumulus/dhcp.j2
default-isc-dhcp: cumulus/default-isc-dhcp.j2
authorized_keys: cumulus/authorized-keys.j2
motd: linux/motd.j2
acl.rules: cumulus/acl.j2
rsyslog.conf: cumulus/rsyslog.conf.j2
Templates are using Jinja2. This is the same engine used in Ansible. Jerikan ships some custom filters but also reuse some of the useful filters from Ansible, notably ipaddr. Here is an excerpt of templates/junos/base.j2 to configure DNS and NTP servers on Juniper devices:
system  
  ntp  
 % for ntp in lookup("system", "ntp") % 
    server   ntp  ;
 % endfor % 
   
  name-server  
 % for dns in lookup("system", "dns") % 
      dns  ;
 % endfor % 
   
 
The equivalent template for Cisco IOS-XR is:
 % for dns in lookup('system', 'dns') % 
domain vrf VRF-MANAGEMENT name-server   dns  
 % endfor % 
!
 % for syslog in lookup('system', 'syslog') % 
logging   syslog   vrf VRF-MANAGEMENT
 % endfor % 
!
There are three helper functions provided:
  • devices() returns the list of devices matching a set of conditions on the scope. For example, devices("location==ussfo03", "groups==tor-bgp") returns the list of devices in San Francisco in the tor-bgp group. You can also omit the operator if you want the specified value to be equal to the one in the local scope. For example, devices("location") returns devices in the current location.
  • lookup() does a key lookup. It takes the namespace, the key, and optionally, a device name. If not provided, the current device is assumed.
  • scope() returns the scope of the provided device.
Here is how you would define iBGP sessions between edge devices in the same location:
 % for neighbor in devices("location", "groups==edge") if neighbor != device % 
   % for address in lookup("topology", "addresses", neighbor).loopback tolist % 
protocols bgp group IPV  address ipv  -EDGES-IBGP  
  neighbor   address    
    description "IPv  address ipv  : iBGP to   neighbor  ";
   
 
   % endfor % 
 % endfor % 
We also have a global key-value store to save information to be reused in another template or device. This is quite useful to automatically build DNS records. First, capture the IP address inserted into a template with store() as a filter:
interface Loopback0
 description 'Loopback:'
  % for address in lookup('topology', 'addresses').loopback tolist % 
 ipv  address ipv   address   address store('addresses', 'Loopback0') ipaddr('cidr')  
  % endfor % 
!
Then, reuse it later to build DNS records by iterating over store():4
 % for device, ip, interface in store('addresses') % 
   % set interface = interface replace('/', '-') replace('.', '-') replace(':', '-') % 
   % set name = ' . '.format(interface lower, device) % 
  name  . IN   'A' if ip ipv4 else 'AAAA'     ip ipaddr('address')  
 % endfor % 
Templates are compiled locally with ./run-jerikan build. The --limit argument restricts the devices to generate configuration files for. Build is not done in parallel because a template may depend on the data collected by another template. Currently, it takes 1 minute to compile around 3000 files spanning over 800 devices.
Jerikan outputs when building templates
Output of Jerikan after building configuration files for six devices
When an error occurs, a detailed traceback is displayed, including the template name, the line number and the value of all visible variables. This is a major time-saver compared to Ansible!
templates/opengear/config.j2:15: in top-level template code
    config.interfaces.  interface  .netmask   adddress   ipaddr("netmask")  
        continent  = 'us'
        device     = 'con1-ag2.ussfo03.blade-group.net'
        environment = 'prod'
        host       = 'con1-ag2.ussfo03'
        infos      =  'address': '172.30.24.19/21' 
        interface  = 'wan'
        location   = 'ussfo03'
        loop       = <LoopContext 1/2>
        member     = '2'
        model      = 'cm7132-2-dac'
        os         = 'opengear'
        shorthost  = 'con1-ag2'
_ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _
value = JerkianUndefined, query = 'netmask', version = False, alias = 'ipaddr'
[ ]
        # Check if value is a list and parse each element
        if isinstance(value, (list, tuple, types.GeneratorType)):
            _ret = [ipaddr(element, str(query), version) for element in value]
            return [item for item in _ret if item]
>       elif not value or value is True:
E       jinja2.exceptions.UndefinedError: 'dict object' has no attribute 'adddress'
We don t have general-purpose rules when writing templates. Like for the source of truth, there is no need to create generic templates able to produce any BGP configuration. There is a balance to be found between readability and avoiding duplication. Templates can become scary and complex: sometimes, it s better to write a filter or a function in jerikan/jinja.py. Mastering Jinja2 is a good investment. Take time to browse through our templates as some of them show interesting features.

Checks Optionally, each configuration file can be validated by a script in the checks/ directory. Jerikan looks up the key checks in the build namespace to know which checks to run:
$ ./run-jerikan lookup edge1.ussfo03.blade-group.net build checks
- description: Juniper configuration file syntax check
  script: checks/junoser
  cache:
    input: config.txt
    output: config-set.txt
- description: check YAML data
  script: checks/data.yaml
  cache: data.yaml
In the above example, checks/junoser is executed if there is a change to the generated config.txt file. It also outputs a transformed version of the configuration file which is easier to understand when using diff. Junoser checks a Junos configuration file using Juniper s XML schema definition for Netconf.5 On error, Jerikan displays:
jerikan/build.py:127: RuntimeError
-------------- Captured syntax check with Junoser call --------------
P: checks/junoser edge2.ussfo03.blade-group.net
C: /app/jerikan
O:
E: Invalid syntax:  set system syslog archive size 10m files 10 word-readable
S: 1

Integration into GitLab CI The next step is to compile the templates using a CI. As we are using GitLab, Jerikan ships with a .gitlab-ci.yml file. When we need to make a change, we create a dedicated branch and a merge request. GitLab compiles the templates using the same environment we use on our laptops and store them as an artifact.
Merge requests in GitLab for a change
Merge request to add a new port in USSFO03. The templates were compiled successfully but approval from another team member is still required to merge.
Before approving the merge request, another team member looks at the changes in data and templates but also the differences for the generated configuration files:
Differences for generated configuration files
The change configures a port on the Juniper device, adds records to DNS, and updates NetBox with the new IP addresses (not shown).

Ansible After Jerikan has built the configuration files, Ansible takes over. It is also packaged as a Docker image to avoid the trouble to maintain the right Python virtual environment and ensure everyone is using the same versions.

Inventory Jerikan has generated an inventory file. It contains all the managed devices, the variables defined for each of them and the groups converted to Ansible groups:
ob1-n1.sk1.blade-group.net ansible_host=172.29.15.12 ansible_user=blade ansible_connection=network_cli ansible_network_os=ios
ob2-n1.sk1.blade-group.net ansible_host=172.29.15.13 ansible_user=blade ansible_connection=network_cli ansible_network_os=ios
ob1-n1.ussfo03.blade-group.net ansible_host=172.29.15.12 ansible_user=blade ansible_connection=network_cli ansible_network_os=ios
none ansible_connection=local
[oob]
ob1-n1.sk1.blade-group.net
ob2-n1.sk1.blade-group.net
ob1-n1.ussfo03.blade-group.net
[os-ios]
ob1-n1.sk1.blade-group.net
ob2-n1.sk1.blade-group.net
ob1-n1.ussfo03.blade-group.net
[model-c2960s]
ob1-n1.sk1.blade-group.net
ob2-n1.sk1.blade-group.net
ob1-n1.ussfo03.blade-group.net
[location-sk1]
ob1-n1.sk1.blade-group.net
ob2-n1.sk1.blade-group.net
[location-ussfo03]
ob1-n1.ussfo03.blade-group.net
[in-sync]
ob1-n1.sk1.blade-group.net
ob2-n1.sk1.blade-group.net
ob1-n1.ussfo03.blade-group.net
none
in-sync is a special group for devices which configuration should match the golden configuration. Daily and unattended, Ansible should be able to push configurations to this group. The mid-term goal is to cover all devices. none is a special device for tasks not related to a specific host. This includes synchronizing NetBox, IRR objects, and the DNS, updating the RPKI, and building the geofeed files.

Playbook We use a single playbook for all devices. It is described in the ansible/playbooks/site.yaml file. Here is a shortened version:
- hosts: adm-gateway:!done
  strategy: mitogen_linear
  roles:
    - blade.linux
    - blade.adm-gateway
    - done
- hosts: os-linux:!done
  strategy: mitogen_linear
  roles:
    - blade.linux
    - done
- hosts: os-junos:!done
  gather_facts: false
  roles:
    - blade.junos
    - done
- hosts: os-opengear:!done
  gather_facts: false
  roles:
    - blade.opengear
    - done
- hosts: none:!done
  gather_facts: false
  roles:
    - blade.none
    - done
A host executes only one of the play. For example, a Junos device executes the blade.junos role. Once a play has been executed, the device is added to the done group and the other plays are skipped. The playbook can be executed with the configuration files generated by the GitLab CI using the ./run-ansible-gitlab command. This is a wrapper around Docker and the ansible-playbook command and it accepts the same arguments. To deploy the configuration on the edge devices for the SK1 datacenter in check mode, we use:
$ ./run-ansible-gitlab playbooks/site.yaml --limit='edge:&location-sk1' --diff --check
[ ]
PLAY RECAP *************************************************************
edge1.sk1.blade-group.net  : ok=6    changed=0    unreachable=0    failed=0    skipped=3    rescued=0    ignored=0
edge2.sk1.blade-group.net  : ok=5    changed=0    unreachable=0    failed=0    skipped=1    rescued=0    ignored=0
We have some rules when writing roles:
  • --check must detect if a change is needed;
  • --diff must provide a visualization of the planned changes;
  • --check and --diff must not display anything if there is nothing to change;
  • writing a custom module tailored to our needs is a valid solution;
  • the whole device configuration is managed;6
  • secrets must be stored in Vault;
  • templates should be avoided as we have Jerikan for that; and
  • avoid duplication and reuse tasks.7
We avoid using collections from Ansible Galaxy, the exception being collections to connect and interact with vendor devices, like cisco.iosxr collection. The quality of Ansible Galaxy collections is quite random and it is an additional maintenance burden. It seems better to write roles tailored to our needs. The collections we use are in ci/ansible/ansible-galaxy.yaml. We use Mitogen to get a 10 speedup on Ansible executions on Linux hosts. We also have a few playbooks for operational purpose: upgrading the OS version, isolate an edge router, etc. We were also planning on how to add operational checks in roles: are all the BGP sessions up? They could have been used to validate a deployment and rollback if there is an issue. Currently, our playbooks are run from our laptops. To keep tabs, we are using ARA. A weekly dry-run on devices in the in-sync group also provides a dashboard on which devices we need to run Ansible on.

Configuration data and templates Jerikan ships with pre-populated data and templates matching the configuration of our USSFO03 and SK1 datacenters. They do not exist anymore but, we promise, all this was used in production back in the days!
Network architecture for Blade datacenter
The latest iteration of our network infrastructure for SK1, USSFO03, and future data centers. The production network is using BGPttH using a spine-leaf fabric. The out-of-band network is using a simple L2 design, using the spanning tree protocol, as well as a set of console servers.
Notably, you can find the configuration for:
our edge routers
Some are running on Junos, like edge2.ussfo03, the others on IOS-XR, like edge1.sk1. The implemented functionalities are similar in both cases and we could swap one for the other. It includes the BGP configuration for transits, peerings, and IX as well as the associated BGP policies. PeeringDB is queried to get the maximum number of prefixes to accept for peerings. bgpq3 and a containerized IRRd help to filter received routes. A firewall is added to protect the routing engine. Both IPv4 and IPv6 are configured.
our BGP-based fabric
BGP is used inside the datacenter8 and is extended on bare-metal hosts. The configuration is automatically derived from the device location and the port number.9 Top-of-the-rack devices are using passive BGP sessions for ports towards servers. They are also serving a provisioning network to let them boot using DHCP and PXE. They also act as a DHCP server. The design is multivendor. Some devices are running Cumulus Linux, like to1-p1.ussfo03, while some others are running Junos, like to1-p2.ussfo03.
our out-of-band fabric
We are using Cisco Catalyst 2960 switches to build an L2 out-of-band network. To provide redundancy and saving a few bucks on wiring, we build small loops and run the spanning-tree protocol. See ob1-p1.ussfo03. It is redundantly connected to our gateway servers. We also use OpenGear devices for console access. See con1-n1.ussfo03
our administrative gateways
These Linux servers have multiple purposes: SSH jump boxes, rescue connection, direct access to the out-of-band network, zero-touch provisioning of network devices,10 Internet access for management flows, centralization of the console servers using Conserver, and API for autoconfiguration of BGP sessions for bare-metal servers. They are the first servers installed in a new datacenter and are used to provision everything else. Check both the generated files and the associated Ansible tasks.

  1. Ansible does not even provide a line number when there is an error in a template. You may need to find the problem by bisecting.
    $ ansible --version
    ansible 2.10.8
    [ ]
    $ cat test.j2
    Hello   name  !
    $ ansible all -i localhost, \
    >  --connection=local \
    >  -m template \
    >  -a "src=test.j2 dest=test.txt"
    localhost   FAILED! =>  
        "changed": false,
        "msg": "AnsibleUndefinedVariable: 'name' is undefined"
     
    
  2. You may recognize the same concepts as in Hiera, the hierarchical key-value store from Puppet. At first, we were using Jerakia, a similar independent store exposing an HTTP REST interface. However, the lookup overhead is too large for our use. Jerikan implements the same functionality within a Python function.
  3. The list of available filters is mangled inside jerikan/jinja.py. This is a remain of the fact we do not maintain Jerikan as a standalone software.
  4. This is a bit confusing: we have a store() filter and a store() function. With Jinja2, filters and functions live in two different namespaces.
  5. We are using a fork with some modifications to be able to validate our configurations and exposing an HTTP service to reduce the time spent on each configuration check.
  6. There is a trend in network automation to automate a configuration subset, for example by having a playbook to create a new BGP session. We believe this is wrong: with time, your configuration will get out-of-sync with its expected state, notably hand-made changes will be left undetected.
  7. See ansible/roles/blade.linux/tasks/firewall.yaml and ansible/roles/blade.linux/tasks/interfaces.yaml. They are meant to be called when needed, using import_role.
  8. We also have some datacenters using BGP EVPN VXLAN at medium-scale using Juniper devices. As they are still in production today, we didn t include this feature but we may publish it in the future.
  9. In retrospect, this may not be a good idea unless you are pretty sure everything is uniform (number of switches for each layer, number of ports). This was not our case. We now think it is a better idea to assign a prefix to each device and write it in the source of truth.
  10. Non-linux based devices are upgraded and configured unattended. Cumulus Linux devices are automatically upgraded on install but the final configuration has to be pushed using Ansible: we didn t want to duplicate the configuration process using another tool.

Shirish Agarwal: Pandemic, Toolkit and India

Pandemic Situation in India. I don t know from where I should start. This is probably a good start. I actually would recommend Indiacable as they do attempt to share some things happening in India from day to day but still there is a lot thatt they just can t cover, nobody can cover. There were two reports which kind of shook me all inside. One which sadly came from the UK publication Independent, probably as no Indian publication would dare publish it. The other from Rural India. I have been privileged in many ways, including friends who have asked me if I need any financial help. But seeing reports like above, these people need more help, guidance and help than I. While I m never one to say give to Foundations. If some people do want to help people from Maharashtra, then moneylifefoundation could be a good place where they could donate. FWIW, they usually use the foundation to help savers and investors be safe and help in getting money when taken by companies with dubious intentions. That is their drive. Two articles show their bent. The first one is about the Algo scam which I have written previously about the same in this blog. Interestingly, when I talk about this scam, all Modi supporters are silent. The other one does give some idea as to why the Govt. is indifferent. That is going to a heavy cross for all relatives to bear. There has been a lot that has been happening. Now instead of being limited to cities, Covid has now gone hinterland in a big way. One could ask also Praveen as he probably knows what would be good for Kerala and surrounding areas. The biggest change, however, has been that India is now battling not just the pandemic but also Mucormycosis also known as black fungus and its deadlier cousin the white fungus. Mucormycosis came largely due to an ill-advise given that applying cow dung gives protection to Corona. And many applied it due to faith. And people who know science do know that in fact it has that bacteria. Sadly, those of us who are and were more interested in law, computer science etc. has now also have to keep on top of what is happening in the medical field. It isn t that I hate it, but it has a lot of costs. From what I could gather on various social media and elsewhere, a single injection of anti-fungal for the above costs INR 3k/- and that needs to be 5 times in a day and that course has to be for three weeks. So even the relatively wealthy people can and will become poor in no time. No wonder thousands of those went to UK, US, Dubai or wherever they could find safe-harbor from the pandemic with no plans of arriving back soon. There was also the whole bit about FBS or Fetal Bovin Serum. India ordered millions of blood serum products from abroad and continues to. This was quickly shut down as news on Social Media. Apparently, it is only the Indian cow which is worthy of reverence. All other cows and their children are fair game according to those in power. Of course, that discussion was quickly shut down as was the discussion about IGP (Indian Genome Project). People over the years had asked me why India never participated for the HGP (Human Gnome Project). I actually had no answer for that. Then in 2020, there was idea of IGP which was put up and then it was quickly shot down as the results could damage a political party s image. In fact, a note to people who want to join Indian civil services tells the reason exactly. While many countries in the world are hypocrites, including the U.S. none can take the place that India has made for itself in that field.

The Online experience The vaccination process has been made online and has led to severe heartburn and trouble for many including many memes. For e.g.

Daily work, get up, have a bath, see if you got a slot on the app, sleep.
People trying desperately to get a slot, taken from Hindi Movie Dilwale Dulhania Le Jaygenge.
Just to explain what is happening, one has to go to the website of cowin. Sharing a screenshot of the same.
Cowin app. sceeenshot
I have deliberately taken a screenshot of the cowin app. in U.P. which is one of the areas where the ruling party, BJP has. I haven t taken my state for the simple reason, even if a slot is open, it is of no use as there are no vaccines. As have been shared in India Cable as well as in many newspapers, it is the Central Govt. which holds the strings for the vaccines. Maharashtra did put up an international tender but to no effect. All vaccine manufacturers want only Central Govt. for purchases for multiple reasons. And GOI is saying it has no money even though recently it got loans as well as a dividend from RBI to the tune of 99k crore. For what all that money is, we have no clue. Coming back though, to the issue at hand. the cowin app. is made an open api. While normally, people like us should and are happy when an API is open, it has made those who understand how to use git, compile, etc. better than others. A copy of the public repo. of how you can do the same can be found on Github. Now, obviously, for people like me and many others it has ethical issues.

Kiran s Interview in Times of India (TOI) There isn t much to say apart from I haven t used it. I just didn t want to. It just is unethical. Hopefully, in the coming days GOI does something better. That is the only thing we are surviving on, hope.

The Toolkit saga A few days before, GOI shared a toolkit apparently made by Congress to defame the party in power. That toolkit was shared before the press and Altnews did the investigation and promptly shredded the claims. Congress promptly made an FIR in Chhattisgarh where it is in power. The gentleman who made the claims Mr. Sambit Patra refused to appear against the police without evidence citing personal reasons and asking 1 week to appear before them. Apart from Altnews which did a great job, sadly many people didn t even know that there is something called WYSIWYG. I had to explain that so many Industries, whether it is politics, creative industries, legal, ad industries, medical transcription, and imaging all use this, and all the participants use the same version of the software. The reason being that in most Industries, there is a huge loss and issue of legal liabilities if something untoward happens. For e.g. if medical transcription is done in India is wrong (although his or her work will be checked by a superior in the West), but for whatever reason is not, and a wrong diagnosis is put (due to wrong color or something) then a patient could die and the firm who does that work could face heavy penalties which could be the death of them. There is another myth that Congress has unlimited wealth or huge wealth. I asked if that was the case, why didn t they shift to Mac. Of course, none have answers on this one. There is another reason why they didn t want to appear. The Rona Wilson investigation by Arsenal Experts also has made them cautious. Previously, they had a free run. Nowadays, software forensic tools are available to one and all. For e.g. Debian itself has a good variety of tools for the same. I remember Vipin s sharing few years back. For those who want to start, just install the apps. and try figuring out. Expertise on using the tools takes years though, as you use the tool day in night. Update 25/05/2021 Apparently because Twitter made and showcased few tweets as Manipulated Media , those in Govt. are and were dead against it. So they conducted a raid against Twitter India headquarters, knowing fully well that there would be nobody except security. The moment I read this, my mind went to the whole Fruit of the poisonous tree legal doctrine. Sadly though, India doesn t recognize it and in fact, still believes in the pre-colonial era that evidence however collected is good. A good explanation of the same can be found here. There are some exceptions to the rule, but they are done so fine that more often than not, they can t be used in the court of law in India. Although a good RTI was shared by Mr. Saket Gokhale on the same issue, which does raise some interesting points
Twitter India Raid, Saket Gokhale RTI 1
Saket Gokhale RTI query , Twitter India Raid 2
FWIW, Saket has been successful in getting his prayers heard either as answers to RTI queries or then following it up in the various High Courts of India. Of course, those who are in the ruling party ridicule him but are unable to find faults in his application of logic. And quite a few times, I have learned from his applications as well as nuances or whatever is there in law, a judgment or a guideline which he invokes in his prayer. For e.g. the Lalitha Kumari Guidelines which the gentleman has shared in his prayer can be found here. Hence now, it would be upto the Delhi Police Cell to prove their case in response to RTI. He has also trapped them as he has shared they can t give excuses/exemptions which they have tried before. As I had shared earlier, High Courts in India have woken up, whether it is Delhi, Mumbai, Aurangabad, Madhya Pradesh, Uttar Pradesh, Odisha or Kerala. Just today i.e. on 25th May 2021, Justices Bela Trivedi and Justice Kalra had asked how come all the hospitals don t have NOC from the Fire De[partment. They also questioned the ASG (Assistant Solicitor General) as how BU (Building Use Certificate) has been granted as almost all the 400 hospitals are in residential area. To which the ASG replies, it is the same state in almost 4000 schools as well as 6000 odd factories in Ahemdabad alone, leave the rest of the district and state alone. And this is when last year strict instuctions were passed. They chose to do nothing sadly. I will share a link on this when bar and bench gives me  The Hindu also shared the whole raid on twitter saga.

Conclusion In conclusion, I sincerely do not where we are headed. The only thing I know is that we cannot expect things to be better before year-end and maybe even after that. It all depends on the vaccines and their availability. After that ruralindia article, I had to see quite a few movies and whatnot just to get that out of my head. And this is apart from the 1600 odd teachers and workers who have died in the U.P. poll duty. Now, what a loss, not just to the family members of the victims, but a whole generation of school children who would not be able to get quality teaching and be deprived of education. What will be their future, God only knows. The only good Bollywood movie which I saw was Ramprasad ki Teravi . The movie was an accurate representation of most families in and around me. There was a movie called Sansar (1987) which showed the breakup of the joint family and into a nuclear family. This movie could very well have been a continuation of the same. Even Marathi movies which at one time were very progressive have gone back to the same boy, girl love story routine. Sameer, though released in late 2020, was able to see it only recently. Vakeel Saab was an ok copy of Pink . I loved Sameer as, unlike Salman Khan films, it showed pretty much an authentic human struggle of a person who goes to the Middle East without any qualifications and works as a laborer and the trials he goes through. Somehow, Malayalam movies have a knack for showing truth without much of budget. Most of the Indian web series didn t make an impact. I think many of them were just going through the motions, it seems as everybody is concerned with the well-being of their near and dear ones. There was also this (Trigger Warning: This story discusses organized campaigns glorifying and advocating sexual violence against Muslim women.) Hoping people somehow make it to the other side of the pandemic.

24 May 2021

Antoine Beaupr : Leaving Freenode

The freenode IRC network has been hijacked. TL;DR: move to libera.chat or OFTC.net, as did countless free software projects including Gentoo, CentOS, KDE, Wikipedia, FOSDEM, and more. Debian and the Tor project were already on OFTC and are not affected by this.

What is freenode and why should I care? freenode is the largest remaining IRC network. Before this incident, it had close to 80,000 users, which is small in terms of modern internet history -- even small social networks are larger by multiple orders of magnitude -- but is large in IRC history. The IRC network is also extensively used by the free software community, being the default IRC network on many programs, and used by hundreds if not thousands of free software projects. I have been using freenode since at least 2006. This matters if you care about IRC, the internet, open protocols, decentralisation, and, to a certain extent, federation as well. It also touches on who has the right on network resources: the people who "own" it (through money) or the people who make it work (through their labor). I am biased towards open protocols, the internet, federation, and worker power, and this might taint this analysis.

What happened? It's a long story, but basically:
  1. back in 2017, the former head of staff sold the freenode.net domain (and its related company) to Andrew Lee, "American entrepreneur, software developer and writer", and, rather weirdly, supposedly "crown prince of Korea" although that part is kind of complex (see House of Yi, Yi Won, and Yi Seok). It should be noted the Korean Empire hasn't existed for over a century at this point (even though its flag, also weirdly, remains)
  2. back then, this was only known to the public as this strange PIA and freenode joining forces gimmick. it was suspicious at first, but since the network kept running, no one paid much attention to it. opers of the network were similarly reassured that Lee would have no say in the management of the network
  3. this all changed recently when Lee asserted ownership of the freenode.net domain and started meddling in the operations of the network, according to this summary. this part is disputed, but it is corroborated by almost a dozen former staff which collectively resigned from the network in protest, after legal threats, when it was obvious freenode was lost.
  4. the departing freenode staff founded a new network, irc.libera.chat, based on the new ircd they were working on with OFTC, solanum
  5. meanwhile, bot armies started attacking all IRC networks: both libera and freenode, but also OFTC and unrelated networks like a small one I help operate. those attacks have mostly stopped as of this writing (2021-05-24 17:30UTC)
  6. on freenode, however, things are going for the worse: Lee has been accused of taking over a channel, in a grotesque abuse of power; then changing freenode policy to not only justify the abuse, but also remove rules against hateful speech, effectively allowing nazis on the network (update: the change was reverted, but not by Lee)
Update: even though the policy change was reverted, the actual conversations allowed on freenode have already degenerated into toxic garbage. There are also massive channel takeovers (presumably over 700), mostly on channels that were redirecting to libera, but also channels that were still live. Channels that were taken over include #fosdem, #wikipedia, #haskell... Instead of working on the network, the new "so-called freenode" staff is spending effort writing bots and patches to basically automate taking over channels. I run an IRC network and this bot is obviously not standard "services" stuff... This is just grotesque. At this point I agree with this HN comment:
We should stop implicitly legitimizing Andrew Lee's power grab by referring to his dominion as "Freenode". Freenode is a quarter-century-old community that has changed its name to libera.chat; the thing being referred to here as "Freenode" is something else that has illegitimately acquired control of Freenode's old servers and user database, causing enormous inconvenience to the real Freenode.
I don't agree with the suggested name there, let's instead call it "so called freenode" as suggested later in the thread.

What now? I recommend people and organisations move away from freenode as soon as possible. This is a major change: documentation needs to be fixed, and the migration needs to be coordinated. But I do not believe we can trust the new freenode "owners" to operate the network reliably and in good faith. It's also important to use the current momentum to build a critical mass elsewhere so that people don't end up on freenode again by default and find an even more toxic community than your typical run-of-the-mill free software project (which is already not a high bar to meet). Update: people are moving to libera in droves. It's now reaching 18,000 users, which is bigger than OFTC and getting close to the largest, traditionnal, IRC networks (EFnet, Undernet, IRCnet are in the 10-20k users range). so-called freenode is still larger, currently clocking 68,000 users, but that's a huge drop from the previous count which was 78,000 before the exodus began. We're even starting to see the effects of the migration on netsplit.de. Update 2: the isfreenodedeadyet.com site is updated more frequently than netsplit and shows tons more information. It shows 25k online users for libera and 61k for so-called freenode (down from ~78k), and the trend doesn't seem to be stopping for so-called freenode. There's also a list of 400+ channels that have moved out. Keep in mind that such migrations take effect over long periods of time.

Where do I move to? The first thing you should do is to figure out which tool to use for interactive user support. There are multiple alternatives, of course -- this is the internet after all -- but here is a short list of suggestions, in preferred priority order:
  1. irc.libera.chat
  2. irc.OFTC.net
  3. Matrix.org, which bridges with OFTC and (hopefully soon) with libera as well, modern IRC alternative
  4. XMPP/Jabber also still exists, if you're into that kind of stuff, but I don't think the "chat room" story is great there, at least not as good as Matrix
Basically, the decision tree is this:
  • if you want to stay on IRC:
    • if you are already on many OFTC channels and few freenode channels: move to OFTC
    • if you are more inclined to support the previous freenode staff: move to libera
    • if you care about matrix users (in the short term): move to OFTC
  • if you are ready to leave IRC:
    • if you want the latest and greatest: move to Matrix
    • if you like XML and already use XMPP: move to XMPP
Frankly, at this point, everyone should seriously consider moving to Matrix. The user story is great, the web is a first class user, it supports E2EE (although XMPP as well), and has a lot of momentum behind it. It even bridges with IRC well (which is not the case for XMPP) so if you're worried about problems like this happening again. (Indeed, I wouldn't be surprised if similar drama happens on OFTC or libera in the future. The history of IRC is full of such epic controversies, takeovers, sabotage, attacks, technical flamewars, and other silly things. I am not sure, but I suspect a federated model like Matrix might be more resilient to conflicts like this one.) Changing protocols might mean losing a bunch of users however: not everyone is ready to move to Matrix, for example. Graybeards like me have been using irssi for years, if not decades, and would take quite a bit of convincing to move elsewhere. I have mostly kept my channels on IRC, and moved either to OFTC or libera. In retrospect, I think I might have moved everything to OFTC if I would have thought about it more, because almost all of my channels are there. But I kind of expect a lot of the freenode community to move to libera, so I am keeping a socket open there anyways.

How do I move? The first thing you should do is to update documentation, websites, and source code to stop pointing at freenode altogether. This is what I did for feed2exec, for example. You need to let people know in the current channel as well, and possibly shutdown the channel on freenode. Since my channels are either small or empty, I took the radical approach of:
  • redirecting the channel to ##unavailable which is historically the way we show channels have moved to another network
  • make the channel invite-only (which effectively enforces the redirection)
  • kicking everyone out of the channel
  • kickban people who rejoin
  • set the topic to announce the change
In IRC speak, the following commands should do all this:
/msg ChanServ set #anarcat mlock +if ##unavailable
/msg ChanServ clear #anarcat users moving to irc.libera.chat
/msg ChanServ set #anarcat restricted on
/topic #anarcat this channel has moved to irc.libera.chat
If the channel is not registered, the following might work
/mode #anarcat +if ##unavailable
Then you can leave freenode altogether:
/disconnect Freenode unacceptable hijack, policy changes and takeovers. so long and thanks for all the fish.
Keep in mind that some people have been unable to setup such redirections, because the new freenode staff have taken over their channel, in which case you're out of luck... Some people have expressed concern about their private data hosted at freenode as well. If you care about this, you can always talk to NickServ and DROP your nick. Be warned, however, that this assumes good faith of the network operators, which, at this point, is kind of futile. I would assume any data you have registered on there (typically: your NickServ password and email address) to be compromised and leaked. If your password is used elsewhere (tsk, tsk), change it everywhere. Update: there's also another procedure, similar to the above, but with a different approach. Keep in mind that so-called freenode staff are actively hijacking channels for the mere act of mentioning libera in the channel topic, so thread carefully there.

Last words This is a sad time for IRC in general, and freenode in particular. It's a real shame that the previous freenode staff have been kicked out, and it's especially horrible that if the new policies of the network are basically making the network open to nazis. I wish things would have gone out differently: now we have yet another fork in the IRC history. While it's not the first time freenode changes name (it was called OPN before), now the old freenode is still around and this will bring much confusion to the world, especially since the new freenode staff is still claiming to support FOSS. I understand there are many sides to this story, and some people were deeply hurt by all this. But for me, it's completely unacceptable to keep pushing your staff so hard that they basically all (except one?) resign in protest. For me, that's leadership failure at the utmost, and a complete disgrace. And of course, I can't in good conscience support or join a network that allows hate speech. Regardless of the fate of whatever we'll call what's left of freenode, maybe it's time for this old IRC thing to die already. It's still a sad day in internet history, but then again, maybe IRC will never die...

Next.

Previous.