Search Results: "ag"

23 August 2011

Nathan Handler: Google Summer of Code Report #5

This is my fifth and final report about dextools for the 2011 Google Summer of Code program. During the summer, I worked with Matt Zimmerman and Stefano Zacchiroli to create a replacement web dashboard for the Debian Derivatives Exchange (DEX). The dashboard displays a list of projects and their respective tasks and then allows users to easily update the status of these tasks. The dashboard also contains two graphs for tracking the progress of projects and providing instant recognition of all contributions to a project. At the start of the summer, I knew that I wanted to to work on improving the DEX infrastructure. I had worked with the team on the ancient-merges project, and while a lot of good work was accomplished, the process for tracking our progress was a bit clunky and difficult to interact with. Anyone who read my initial proposal for the Summer of Code would probably agree that it was quite vague. I really did not have a solid plan for what I wanted to accomplish. This began to change after my initial phone call with my mentor, Matt Zimmerman. We decided that the first thing I would work on would be a basic dashboard. Our plan was to have all of the data stored on the Debian BTS. This would allow Debian Maintainers to benefit from DEX without needing to learn about DEX s tools and workflows. The dashboard would support multiple derivatives and multiple projects for each derivative. Each project would be made up of a list of tasks, where each task is linked to a BTS bug. I prepared a mockup and some initial code based on that plan. The dashboard was able to successfully display a list of BTS bugs and their information. It generated the lists by assuming that bugs would be usertagged with a user of debian-derivatives@lists.debian.org and a tag in the format of dex
. At this point, we started trying to make sure that the dashboard would work for things like the ancient-patches, python2.7, and the upcoming large-merges projects. It did not take long to determine that it would not work for all of these things. The ancient-patches project started with a simple list of patch names. While most of these patches eventually ended up as bugs on the BTS, they did not start this way. The dashboard would need to support specifying a list of task names. This meant that it would also need to store data itself and that not all data could be located on the BTS. This is when we first started to define what a task is. The dashboard tracks tasks. It does not directly track bugs or patches. A task is nothing more than a title and status with an optional assignee, note, and bug. This made it simple to convert a list of patch names or a list of bug numbers to a list of tasks. During the early early stages of the project, the dashboard moved around a lot. We hoped to have it end up on dex.alioth.debian.org, but we were not sure whether Alioth would meet all of our needs. This was right around the time of the Alioth migration. Thanks to some tips, I figured out that I could use a simple cronjob on wagner to pull the git repository for vasks. This would allow the running instance of the dashboard to always be up-to-date. The Alioth admins have also been quite supportive. They have installed several additional packages for me that were necessary to keep the dashboard running. From the start, Matt felt it was important to have some public documentation about the project. This would allow us to point people to something other than my blog posts. I decided to put this information on the wiki. At one point, I also had a copy of the wiki page stored in the git repository. This file was updated via a cronjob, and I then committed and pushed it when I had code changes. I ultimately decided that the best approach would be to maintain the page on the wiki. A basic README file is included in the git repository that simply links to the wiki page. On wagner, I have a cronjob running to pull a copy of the wiki page so that it can be accessed via the web. Since Matt was traveling/moving this Summer, he arranged for Stefano Zacchiroli to fill in for him as my mentor temporarily. It was at this point in the summer that I began working on the first graph script. The goal was to have a script to parse the list of tasks and generate a graph showing the number of open tasks versus time. This would allow us to easily track our progress, estimate when a project will be complete, and detect periods of slowing down. We decided that while we liked the Ubuntu burndown charts, they were a bit more complex than we needed, so we did not reuse their code. A dashboard that can t be modified is not that useful. An early goal of this project was to allow users to update the dashboard via the web. This proved to be a bit more difficult than I initially thought. First, all of the html files that make up the dashboard are generated by a script. This means that if you modify one of the html files directly, all changes will be lost the next time the script runs. When you make a change on a web form and hit submit, you usually expect to see the changes the next time you visit the page. In order to accomplish this, I made the form processing script directly modify the html files. However, at this point, we did not have a way to locally store extended information about tasks, causing the python script to delete all changes made via the web form. This issue was rectified fairly quickly. There is now a changes file that stores all information submitted via the web form. The python script reads this file and applies the changes when it is generating the html files. A second problem concerned the text inputs that were being used in most of the cells on the table. By default, some fields would have text cut-off if the string was too long. Text inputs have a size attribute that is meant to specify the number of visible characters. I attempted to set this attribute in a script to the length of the input s value. Strangely, the inputs ended up with a lot of extra whitespace following the text. This resulted in the table being stretched horizontally. After many hours of research and testing, I was unable to find a solution to this problem. We ultimately decided to simply remove the size attribute and accept that text will be cut-off. My code got some early testing from Allison Randal and other people working on the dex-ubuntu-python2.7 project. They were a huge help in providing feedback and finding bugs in the code. While the dashboard was unable to meet all of their needs (due to being in the early stages of development), I hope that it at least helped to make it easier to track the project s status. Whenever a script is accepting input from a user, it is important to validate it. Although the dashboard uses a select box to limit the choices for the status , it is still trivial to submit an arbitrary status for a task. That is why I added some validation to the form processing script. It will ignore any unknown values, ensuring that all tasks have a valid status. The other fields are a bit more tricky. They were designed to be arbitrary text fields. As a result, almost anything can be entered. There is no way to tell if something is a title or a person. We thought of a few ways we could change this, but most of them involved locking down the dashboard and restricting changes. The old dashboard treated the fields as arbitrary text, so we decided to not include any validation in the new one. One popular feature request was the ability to link directly to a project. Early versions of the dashboard had one main dex.html page that used javascript to pull in the various projects. To get around this, I first trying using the query string to allow users to specify a distribution and project. While this worked, it resulted in long and ugly URLs. It took a while for me to be able to implement a cleaner solution. However, I eventually split each project into its own static HTML file. This meant that people could simply copy the URL from the address bar to link to a particular project. The main reason for doing this was that we felt the typical person would be interested in working on a specific project; most people won t be interested in navigating between the different projects. This change also allowed links that utilized the #graph anchor to function properly. Before, due to the way the page went about loading the project, trying to specify a specific project and #graph in the URL did not work properly. There is a plugin for jquery that allows tables to be sorted by particular columns. For tables that just contain text, this works fine without any issues. However, once I started using select boxes and text inputs, things got a bit messed up. After some research, I finally figured out how to use addParser to instruct the tablesorter plugin in how to sort each column in the table. In some of the earlier versions, I used some zebra stripes to make the table easy to read. Thanks to a suggestion from Paul Wise (pabs), I got rid of this striping and modified the code to color the rows based on the task s status. Complete tasks are green, in progress tasks are yellow, and incomplete tasks are red. This makes it very easy to find tasks that still need work as well as measure the overall status of a project. Sometimes, a large task list can feel very intimidating. That is why I added the ability to hide completed tasks with the check of a box. Matt wanted to take this one step farther; he wanted the ability to also hide tasks with a closed bug. This is why you will find 2 checkboxes at the top of the dashboard that allow you to custimize which tasks are visible. Eventually, I might add support for specifying this in the URL to allow groups to link to a particular view of the dashboard. In order to make it as easy as possible for new contributors to get involved with DEX projects, I wanted to have a way to document what a project is about and how to handle tasks. I decided to use the wiki for this. All of the per-project documentation lives at http://wiki.debian.org/DEX//
. You can even take advantage of wiki markup to format the documentation. The script will parse the HTML files generated by the wiki, do some minor cleanup, and then display the documentation at the top of the page. My original plan was to use the ?action=raw output, but the lack of formatting proved too restrictive. My second plan was to try and use something like BeautifulSoup or a regex to filter non-whitelisted tags out of the wiki-generated html. This failed and proved to be unnecessary. The wiki does a pretty decent job of preventing malicious markup from ending up on the dashboard. There is a second graph that is displayed on the dashboard. This graph shows the number of tasks each person has completed. The graph is sorted so that the tallest bars on the left, and the goal is to provide some immediate recognition of work done by contributors. Since we essentially allow anyone to go ahead and modify the dashboard, we knew it was important to have a method in place for dealing with abuse. Any malicious edits made on the wiki can easily be reverted. This idea of reverting to an earlier revision is what inspired me to use a second local git repository to store the projects/ directory. This directory stores all of the changes made via the web interface. Whenever the form is submitted or the script runs to update the list of tasks, any changes made to the projects/ directory are committed. This means that if a malicious user decides to delete everything on the dashboard, we can quickly and easily revert the changes. The revision history might also be interesting to analyze at a future date. When multiple people are collaborating on a project, an issue tracker can be quite useful. For some reason, we did not set one up until quite late into the project. Despite that, we are still using it to track known bugs and feature requests. The issue tracker will become even more useful once the dashboard starts to be utilized by more people. I spent a fair bit of time working on having the dashboard immediately respond to changes. For example, if you change the status of a task, the row color will instantly update. The form will also be submitted in the background, eliminating the need to hit submit to save the change. I also use ajax in some new dialogs that allow the user to create new projects and/or tasks via the web. While these forms are submitted in the background via ajax, I am unable to have the changes show up on the dashboard immediately. The generation of the task list is a bit slow, so having the script run more often is not really a good idea. The next step for the dashboard is to really open it up for testing. We hope to start up a new DEX project shortly. This will allow us to see which features work and which need fixing. It will also help us find some of the bugs that are probably hiding in the code. Finally, if you are interested in helping out with DEX or dextools, my code is available in a git repository (http://anonscm.debian.org/gitweb/?p=dex/gsoc2011.git) on alioth. There is also the issue tracker (https://alioth.debian.org/tracker/index.php?group_id=100600&atid=413120) where you can report bugs and request new features. Finally, you can join the debian-derivatives mailing list, join #debian-derivatives on OFTC, or contact me directly via email or on IRC (nhandler). I have really enjoyed working on dextools this summer. I would like to thank Matt Zimmerman, Stefano Zacchiroli, and everyone else who helped with the project. I look forward to working with all of you more in the future.

Vincent Bernat: SSL termination: stunnel, nginx & stud

Here is the short version: to get better performance on your SSL terminator, use stud on 64bit system with patch from meric Brun for SSL session reuse with some AES cipher suite (128 or 256, does not really matter), without DHE, on as many cores as needed, a key size of 1024 bits unless more is needed.

Introduction A quick note: when I say SSL, you should read TLS v1 instead. Look at the article for TLS on Wikipedia for some background on this. One year ago, Adam Langley, from Google, stated SSL was not computationally expensive any more:
In January this year (2010), Gmail switched to using HTTPS for everything by default. Previously it had been introduced as an option, but now all of our users use HTTPS to secure their email between their browsers and Google, all the time. In order to do this we had to deploy no additional machines and no special hardware. On our production frontend machines, SSL/TLS accounts for less than 1% of the CPU load, less than 10KB of memory per connection and less than 2% of network overhead. Many people believe that SSL takes a lot of CPU time and we hope the above numbers (public for the first time) will help to dispel that. If you stop reading now you only need to remember one thing: SSL/TLS is not computationally expensive any more.
This is a very informative post containing tips on how to enhance SSL performance by reducing latency. However, unlike Gmail, you may still be worried by SSL raw performances. Maybe each of your frontends is able to serve 2000 requests per second and CPU overhead for SSL is therefore significative. Maybe you want to terminate SSL in your load balancer (even if you know this is not the best way to scale).

Tuning SSL There are a lot of knobs you can use to get better performances from SSL: choosing the best implementation, using more CPU cores, switching to 64bit system, choosing the right cipher suite and the appropriate key size and enabling a session cache. We will consider three SSL terminators. They all use OpenSSL behind the hood. stunnel is the oldest one and uses a threaded model. stud is a recent attempt to write a simple SSL terminator which is efficient and scalable. It uses the one-process-per-core model. nginx is a web server and it can be used as reverse proxy and therefore act as SSL terminator. It is known to be one of the most efficient web server, hence the choice here. It also features built-in basic load balancing. Since stud and stunnel does not have this feature, we use them with HAProxy, an high performance load-balancer that usually defers the SSL part to stunnel (but stud can act as a drop-in replacement here). Those implementations were already tested by Matt Stancliff. He first concluded nginx sucked at SSL then that nginx did not suck at SSL (in the first case, nginx was the only one to select a DHE cipher suite). The details were very scarce. I hope to bring here more details. This brings the importance of the selected cipher suite. The client and the server must agree on the cipher suite to use for symmetric encryption. The server will select the strongest one it supports from the list proposed by the client. If you enable some expensive cipher suite on your server, it is likely to be selected. The last important knob is SSL session reuse. It matters for both performance and latency. During the first handshake, the server will send a session ID. The client can use this session ID to request an abbreviated handshake. This handshake is shorter (latency improvement by one round-trip) and allows to reuse the previously negociated master secret (performance improvement by skipping the costliest part of the handshake). See the article from Adam Langley for additional information (with helpful drawings). The following table shows what cipher suite is selected by some major web sites. I have also indicated wheter they support session reuse. See this post from Matt Palmer to know how to check this.
Site Cipher Session reuse?
www.google.com RC4-SHA
www.facebook.com RC4-MD5
twitter.com AES256-SHA
windowsupdate.microsoft.com RC4-MD5
www.paypal.com AES256-SHA
www.cmcicpaiement.fr DHE-RSA-AES256-SHA
RFC 5077 defines another mechanism for session resumption that does not require any server-side state. I did not investigate much how this works but it does not rely on the session ID.

Benchmarks All those benchmarks have been run on a HP DL 380 G7, with two Xeon L5630 (running at 2.13GHz for a total of 8 cores), without hyperthreading, using a 2.6.39 kernel (HZ is set to 250) and two Intel 82576 NIC. Linux conntrack subsystem has been disabled and file limits have been raised over 100,000. A Spirent Avalanche 2900 appliance is used to run the benchmarks. We are interested in raw SSL performances in term of handshakes per second. Because we want to observe the effects of session reuse, the scenario runs by most tests lets clients doing four successive requests and reusing the SSL session for three of them. There is no HTTP keepalive. There is no compression. The size of the HTTP answer from the server is 1024 bytes. Those choices are done because our primary target is the number of SSL handshakes per second. It should also be noted that HAProxy alone is able to handle 22,000 TPS on one core. During the tests, it was never the bottleneck.

Implementation We run a first bench to compare nginx, stud and stunnel on one core. This bench runs on a 32bit system, with AES128-SHA1 cipher suite and a 1024bit key size. Here is the result for stud (version 0.1, with meric Brun s patch for SSL session reuse): stud, 1 CPU The most important plot is the top one. The blue line is the attempted number of transactions per second (TPS) while the green one is the successful number of TPS. When the two lines start to diverge, this means we reach some kind of maximum: the number of unsuccessful TPS also starts to raise (the red line). There are several noticeable points: the maximum TPS (788 TPS), the maximum TPS with an average response time less than 100 ms (766 TPS), less than 500 ms (776 TPS) and the maximum TPS with less than 0.01% of packet loss (783 TPS). Let s have a look at nginx (version 1.0.5): nginx, 1 CPU It is able to get the same performance as stud (763 TPS). However, over 512 TPS, you get more than 100 ms of response time. Over 556 TPS, you even get more than 500 ms! I get this behaviour in every bench with nginx (with or without proxy_buffering, with or without tcp_nopush, with or without tcp_nodelay) and I am unable to explain it. Maybe there is something wrong in the configuration. After hitting this limit, nginx starts to process connections by bursts. Therefore, the number of successful TPS is plotted using a dotted line while the moving average over 20 seconds is plotted with a solid line. On the next plot, you can see the compared performance of the three implementations. On this kind of plot, the number of TPS that we keep is the maximum number of TPS where loss is less than 0.1% and average response time is less than 100 ms. stud achieves a performance of 766 TPS while nginx and stunnel are just above 500 TPS. stunnel vs stud vs nginx, 1 CPU

Number of cores With multiple cores, we can affect several of them to do SSL hard work. To get better performance, we pin each processes to a dedicated CPU. Here is the repartition used during the tests:
1 core 2 cores 4 cores 6 cores
CPU 1, Core 1 network network network network + haproxy
CPU 1, Core 2 haproxy haproxy haproxy SSL
CPU 1, Core 3 SSL SSL SSL SSL
CPU 1, Core 4 - SSL SSL SSL
CPU 2, Core 5 - - network SSL
CPU 2, Core 6 - - SSL SSL
CPU 2, Core 7 - - SSL SSL
CPU 2, Core 8 system system system system + haproxy
Remember, we have two CPU, 4 cores on each CPU. Cores on the same CPU share the same L2 cache (on this model). Therefore, the arrangement inside a CPU is not really important. When possible, we try to keep things together on the same CPU. The SSL processes always get exclusive use of a core since they will always be the most busy. The repartition is done with cpuset(7) for userland processes and by setting smp_affinity for network card interrupts. We keep one core for the system. It is quite important to be able to connect and monitor the system correctly even when it is loaded. With so many cores, we can afford to reserve one core for this usage. Beware! There is a trap when pining processes or IRQ to a core. You need to check /proc/cpuinfo to discover the mapping between kernel processors and physical cores. Sometimes, second kernel processor can be the first core of the second physical processor (instead of the second core of the first physical processor). stunnel vs stud vs nginx, 6 CPU As you can see in the plot above, only stud is able to scale properly. stunnel is not able to take advantage of the cores and its performances are worse than with a single core. I think this may be due to its threaded model and the fact that the userland for this 32bit system is a bit old. nginx is able to achieve the same TPS than stud but is disqualified because of the increased latency. We won t use stunnel in the remaining tests.

32bit vs 64bit The easiest way to achieve a performance boost is to switch to a 64bit system. TPS are doubled. On our 64bit system, thanks to the use of a version of OpenSSL with the appropriate support, AES-NI, a CPU extension to improve the speed of AES encryption/decryption, is enabled. Remaining tests are done with a 64bit system. stud vs nginx, 64bit

Ciphers and key sizes In our tests, the influence of ciphers is minimal. There is almost no difference between AES256 and AES128. Using RC4 adds some latency. The use of AES-NI may have helped to avoid this latency for AES. On the other hand, using a 2048bit key size has a huge performance hit. TPS are divided by 5. stud: cipher suites and key sizes

Session cache The last thing to check is the influence of SSL session reuse. Since we are on a local network, we see only one of the positive effects of session reuse: better TPS because of reduced CPU usages. If there was a latency penalty, we should also have seen better TPS thanks to the removed round-trip. stud: session reuse This plot also explains why stud performances fall after the maximum: because of the failed transactions, the session cache is not as efficient. This phenomenon does not exist when session reuse is not enabled.

Conclusion Here is a summary of the maximum TPS reached during the benchmark (with an average response time below 100ms). Our control use case is the following: 64bit, 6 cores, AES128, SHA1, 1024bit key, 4 requests into the same SSL session.
Context nginx 1.0.5 stunnel 4.41 stud 0.1 (patched)
1 core, 32bit 512 TPS 503 TPS 766 TPS
2 cores, 32bit 599 TPS - -
32bit 804 TPS 501 TPS 4251 TPS
- 1799 TPS - 9000 TPS
AES256 - - 8880 TPS
RC4-MD5 - - 7370 TPS
2048bit - - 1643 TPS
no session reuse - - 5844 TPS
80 requests per SSL session - - 10797 TPS
Therefore, stud in our control scenario is able to sustain 1500 TPS per core. It seems to be the best current option for a SSL termination. It is not available in Debian yet, but I intend to package it. Here is how stud is invoked:
# ulimit -n 100000
# stud  -n 2 -f 172.31.200.15,443 -b 127.0.0.1,80 -c ALL \
>   -B 1000 -C 20000 --write-proxy \
>   =(cat server1024.crt server1024.key dhe1024)
You may also want to look at HAProxy configuration, nginx configuration and stunnel configuration.

Matthew Palmer: UPSes in Datacentres

(This was going to be a comment on this blog post, but it s a Turdpress site that wants JS and cookies to comment. Bugger that for a game of skittles. Rimuhosting s recent extended outage due to power problems was apparently caused by a transfer switch failure at their colo provider. This has led people to wonder if putting UPSes in individual racks is a wise move. The theory is that in the event of a small outage, the UPS can keep things humming, and in an extended outage you can gracefully shut things down rather than having a hard thump. I happen to think this theory is bunkum. Your UPS is a newly instituted single point of failure. I d be willing to bet that the cost of purchasing, installing, and maintaining the UPSes, as well as the cost of the outages that inevitably result from their occasional failure, would be far greater than the cost of the occasional power outage you get in a well-managed facility. Good facilities don t have small outages. They don t have squirrels in the roof cavities, and they don t have people dropping spanners across busbars. The only outages they have are the big ones, when some piece of overengineered equipment turns out to be not so overengineered the multi-hour (or multi-day) ones where your UPS isn t going to stop you from going down. Your SLA credit and customer goodwill is already toast, so all you re saving is the incremental cost of a little bit more downtime while you get fscks run. If you want the best possible power reliability, get yourself into a really well engineered facility, and run dual-power on everything. Definitely run the numbers before you go down the UPS road; I ll bet you find they re not worth it.

Matthew Palmer: Oh HP, you Bucket of Fail

I recently got given a new printer, a HP LaserJet Professional 1 P1102w. It s fairly loudly touted on HP s website that this printer has Full support under Linux. And yet, it won t work with my Linux-based print server. Why? Because it uses a proprietary driver plugin, and that plugin is only available for x86 and amd64, and my print server is ARM-based. Well done, HP. You ve managed to revive the old all the world s a VAX philosophy, on an OS that is more than capable of running on practically anything. You got that for free. Why do you insist on screwing with it? As an added bonus, when I try to Ask a Question on the HPLIP website, to politely (ha!) inquire as to the possibility of an ARM binary, I get sent to Launchpad, which does nothing more than tell me that there is an Invalid OpenID transaction . That s the entire content of the page. Useful. Lies, damned lies, and a double helping of proprietary software fail. My day is complete.
  1. I use scarequotes around Professional because, as far as I can tell, this is just an entry-level personal laser printer. There is nothing particularly professional about it.

Rudy Godoy: Compute clusters for Debian development and building final report

Compute clusters for Debian development and building final report Summary
-
The goal of this project was intended to have Eucalyptus cloud to
support ARM images so it allows Debian developers and users to be able
to use such facility for taks such package building, software
development (ie. Android) under a Debian pre-set image,
software testing many others. What was expected to have at the end is a modified version of Eucalyptus
Cloud that supports ARM images on the first place. To date this goal has
been reached but is not complete, read production-ready. Extensive test
needs to be done. Besides that we have another goal which is to get
Debian community to use this new extended tool. Project overview
-
Eucalyptus is a hybrid cloud computing platform which has a Open Source
(FLOSS) version. It s targetted to be used for PaaS (Platform as a
Service), IaaS (Infrastructure as a Service) and other distribution
models. It can be used also for cloud management. Given that it has
implemented the EC2, for computing, and the S3, for storage, API, it s
compatible with existing public clouds such Amazon EC2. Currently it
supports running i386 and amd64 images or NC (Node Controllers) in
Eucalyptus naming. Eucalyptus is a complex piece of software. It s architechture it s
modular composed by five components. Cloud Controller (CLC), Walrus (W),
Storage Controller (SC), Cluster Controller (CC) and Node Controller
(NC). The first three are written in Java and the remaining are written
in C. Our project modifications was targetted to the NC component,
altough there is a remaining task for hacking the UI to allow setting
the arch of the uploaded NC image instance. The Node Controller is in charge of setting the proper information for
Eucalyptus to be able to run virtualized images. Eucalyptus uses XEN and
KVM hyphervisor to handle internal virtualization subsystem, and
Libvirt, which is an abstraction of the existing virtualization
libraries, for program interfacing. Having that in mind we are back to our project. For our project to be
sucessful we had various tasks to do. Beginning with understanding such
complex piece of software, followed by hacking the requiered bits and
later integrate the work so it results in a useful tool. Our approach to
the project was then inline with such description. The project s history
I started my participation in GSoC approaching Steffen to discuss about
what was expected, or more accurately, what was in his mind. We
exchanged emails previous to my application and that resulted on my
application being submitted. From the beginning I should tell that I
wasn t much clear on the final product of the project, however we
refined ideas and goals during the weeks following to the official
begining of the project. What was clear for me, after all, is that for
this to see the light and gain adoption Eucalyptus code needed to be
dealt with. Our first task was review ARM image creation from scratch, using the
work done by Aurelien and Dominique in previous GSoC. I ve managed to
get an updated ARM image running under qemu-system-arm. The issues
presented in the past were almost unexistant now that the versatile
kernel is official. You can see this on my first report. After that being done and sometimes in parallel my main goal was then understand
the internals of the Eucalyptus software in order to figure out it s
feasibility, where do we need to extend and how big the task is, we
didn t knew upfront. From the beginning of the project Steffen was kind
to introduce me to the Eucalyptus developers and that have resulted in a
good outcome for Debian, IMHO, to date. Understanding Eucalyptus internals was quite a fun task to say the less. As you
can see on the first part of the report Eucalyptus is modularized and
the component I was expected to work with was the NC (Node
Controller). Given that I isolated my work focus, I started to focus on
learning the internals about that component. Node Controller as described is in charge of talking with
virtualization hyphervisors in order to arrange things to run guest
image instances. The module has basically one main component: handler.c,
in charge to talk to the appropiate hyphervisor and there are
extensions (think of OOP polymorphism but acknoledge it s plain C)
that interact with KVM or XEN. I figured that if qemu-kvm is ran in Hyphervisor mode we can manage to
run an ARM image with qemu-system-arm. Given that Eucalyptus has
interaction with KVM hyphervisor in place, this answered the question of
the project s feasibility. First green light on.
>From this point the scope reduced to interacting with the KVM handler
(node/handler_kvm.c) and extend it to support running an image that is
not amd64 or i386. NC makes use of libvirt to abstract interaction with Hyphervisors. So,
the next phase was learning about it s API and figure what s needed to
be modified next. Libvirt uses a XML file for setting Domain (in
libvirt s naming) definitions. So, Eucalyptus provides a Perl wrapper to
generate this file on runtime and allow the NC to invoke libvirt s API
to run the instance. Next task then, was adapt such script to support
ARM arch. The current script is taiolred for amd64 and i383. I worked on
that front and managed to get a script prototype, that can later be
improved and support more arch s. Generating an adequate Libvirt s XML Domain definition file for ARM can
be a heroic task. There are many things to have in mind given the
diversity of the ARM processor and vendors. I focused on the versatile
flavour given that I was going to test the image I built on the first
place and it ran fine under qemu-system-arm.
The Perl script wrapper then was adapted for such configuration and it
can be tested independently by issuing the following command: $ tools/gen_kvm_libvirt_xml arch arm The arch parameter is what I implemented and it s intended to be
called from the kvm handler on instance creation. With the extensibility
in mind I ve created a hash to associate the arch with their
corresponding emulator. our %arches = (
amd64 => /usr/bin/kvm ,
arm => /usr/bin/qemu-system-arm ,
); Added the arch parameter to the GetOptions() function and used
conditions to tell whether the user is looking for a particular arch,
arm in our case. The most important parts to be considered are the
, and entries. hvm $local_kvm There s also and that require to be tailored for arm. root=0800 As output the script generates an XML template that can be adapted to
your needs and it could be used and tested with tools like Libvirt s
virsh. So that, it can be useful independently of Eucalyptus. I managed
to get to this point before the midterm evaluation. Now that we had the XML wrapper almost done, the next task was to make
the handler call pass the arch as an argument to the script, so the
image is loaded with the proper settings and we are able to run it. Eucalyptus doesn t have a arch field for NC s instances. So, after approaching
Eucalyptus developers, with whom we had already being interacting, I
settled to my proposal of extending the ncInstance struct with an arch
field (util/data.h). The ncInstance_t struct stores the metadata for the
instance being created. It s used for storing runtime data as well as
network configuration and more. It was indeed the right place to add a
new field. I did so by creating the archId field.
Now I needed to make sure the arch information is stored and later used on the
libvirt s call. typedef struct ncInstance_t
char instanceId[CHAR_BUFFER_SIZE];
char imageId[CHAR_BUFFER_SIZE];
char imageURL[CHAR_BUFFER_SIZE];
char kernelId[CHAR_BUFFER_SIZE];
char kernelURL[CHAR_BUFFER_SIZE];
char ramdiskId[CHAR_BUFFER_SIZE];
char ramdiskURL[CHAR_BUFFER_SIZE];
char reservationId[CHAR_BUFFER_SIZE];
char userId[CHAR_BUFFER_SIZE];
char archId[CHAR_BUFFER_SIZE];
int retries; /* state as reported to CC & CLC */
char stateName[CHAR_BUFFER_SIZE]; /* as string */
int stateCode; /* as int */ /* state as NC thinks of it */
instance_states state; char keyName[CHAR_BUFFER_SIZE*4];
char privateDnsName[CHAR_BUFFER_SIZE];
char dnsName[CHAR_BUFFER_SIZE];
int launchTime; // timestamp of RunInstances request arrival
int bootTime; // timestamp of STAGING->BOOTING transition
int terminationTime; // timestamp of when resources are released (->TEARDOWN transition) virtualMachine params;
netConfig ncnet;
pthread_t tcb; /* passed into NC via runInstances for safekeeping */
char userData[CHAR_BUFFER_SIZE*10];
char launchIndex[CHAR_BUFFER_SIZE];
char groupNames[EUCA_MAX_GROUPS][CHAR_BUFFER_SIZE];
int groupNamesSize; /* updated by NC upon Attach/DetachVolume */
ncVolume volumes[EUCA_MAX_VOLUMES];
int volumesSize;
ncInstance; With that in place what was left was modifying the functions that
store/update the ncInstance data, and also the libvirt s function that
calls the gen_kvm_libvirt_xml script. I ve modified the following files:
- util/data.c
- node/handlers_kvm.c
- node/handlers. c,h
- node/test.c
- node/client-marshall-adb.c Most important the allocate_instance() function that is in charge of setting up
the instance metadata a prepare it to pass it to the handler, then
hyphervisor trough Libvirt s API. The function now has a new archId
parameter as well, to keep coherence with the field name. It also
handles whether the field is set or not. We (Eucalyptus developers and
I) haven t settled wether to initialize this field with a default value
or not. I d stepped up and initialized with a NULL value for this string
type var. if (archId != NULL)
strncpy(inst->archId, archId, CHAR_BUFFER_SIZE);
Stores the value only if it s passed to the function. This is essential to
don t break existing functionality and keep consistency for later releases.
With this we almost finished the part of extending Eucalyptus to support
arm images. It took quite long to get to that point. Next step: test. As I mentioned in my previous report the current Eucalyptus packaging
has issues. From the beginning I ve approached the pkg-eucalyptus team,
who were very hepful. So I myself set me up and joined the pkg team with
commit access to the repo. Even the GSoC is not intended for packaging
labour, I needed to clear things on that side because what we want is
adoption so anyone, say a DSA or a user, could setup a cloud that has
support for running arm instances under amd64 arch. Over the weeks between mid-term evaluation and past week I ve worked on
that front. Results were good, as you can see in the pkg-eucalyptus
mailing list and SVN repo.
Eucalyptus has a couple of issues that because of it s nature and complexity
triggered build errors. Those issues came from the Java side of the project and
few form the C-side. The C-part was a problem with AXIS2 Jar used to generate
stubs for later inclusion on build-time. There s no definitive solution to date
because one of the Makefile on gatherlog/Makefile issues a subshell call that
doesn t catches the AXIS_HOME environment variable. I ve worked around this
by defining it as a session env var from .zshrc. The other problem is related
to the Java libary versioning and most likely (we had to investigate further)
to groovy versioning. As I explained Eucalyptus has 3 components written in Java. The Java code uses
extensively the AXIS2 library for implementing webservices calls, the groovy
language for JVM, and many other Java libaries. Eucalyptus open source version
ships both online and offline versions. The difference is basically that
the offline version ships the Java libaries JAR files inside the source code,
so you can build with all required deps. Our former packaging used a file to list which Java libraries the package
depends on and it symlinked them using system wide installed packages. This
rather than helping out triggered a lot of problems I explaing with more detail
on the pkg-eucalyptus ml. I worked around this by telling the debian/rules
not to use such file to symlink and instead use the existing ones from
the source. The last weekend I managed to get to that point and built
sucessfully the software under Debian. I ve done that in order to have a
complete build-cycle for my changes, and then test. In fact today I ve
spotted and fixed a couple of bugs there. What s available now

To date we have a Eucalyptus branch where my patches are sent. The level of
extension is nearly complete, more testing needed. One missing bit is to
change the UI so that the user selects which arch her image is and that
value is passed to the corresponding functions on the Node Controller
component. We also have an ARM image that can be tested and later automated. I ve
recently learned about David Went s VMBuilder repo that extends Ubuntu s
vmbuilder to support image creationg. I might talk to him to adapt the tool
in order to support creation of arm images and use it to upload to an
Eucalyptus cloud. I ve also created a wiki page with different bits on which I was working on.
I ve yet need to craft it to be more educational. I guess I m going to use
this report as a source :) We also had more strong cooperation with the Eucalyptus project and
involved their developers on the packaging and this project, which is
something I consider a great outcome for this project and GSoC goals:
to attract more people to contribute to FLOSS. I ve also been contacted by
people from the Panda Project and we might cooperate also. Future work

I plan to keep working on the project regardless the GSoC ends. Our goal
as Debian could be integrating this into the Eucalyptus upstream
branch. We have good relations with them so expect news from that side.
I also plan to keep working with the Eucalyptus team and related
software in Debian, given that I m familiarized with the tools and
projects.
I m also planning to advocate SoC for Debian in my faculty. To date we
had already 4 students, IIRC, that have participated in the past. Project challenges and lessons
During the project I faced many challenges both in the personal side
and in the technical one. This part is a bit personal but I expect we
learn from this. First challenge was the where do I sit problem. My project was
particular, indeed quite different from the others on it s nature. I had
to work on a software that is not Debian s and then come and say Hey we
have this nice tool for you, come test it! . So, indeed, my focus was on
the understanding of such tool, Eucalyptus, and not much on looking back
at Debian because I didn t feel I had something to advertise yet and
indeed I got most valuable/useful feedback from Eucalyptus developers
rather than Debian s, which for the case is OK IMHO. I had great
mentoring. This situation probably looked a bit of isolation from my
side, from Debian s POV, but it was not intended it s just how it needed
to be IMHO. I felt that I wasn t contributing directly to the
project. I ve spoke about such thing with Steffen a couple of times. I d
like to say that it was also my concern but I probably failed on
communicating this, second challenge. Third challenge was more technical and related to the first one. Since I
was not writing any code for a Debian native package/program but instead for
other project I faced the situation of where to publish my
contributions. Eucalyptus had some issues on managing their FLOSS repo
and the current development one is outdated comparing to the
-src-offline 2.0.3 release. The project didn t fit pkg-eucalyptus repo
neither, even we thought to branch the existing trunk and ship my
contribs as quilt patches, but it involved a lot of more work and burn
on reworking something that has issues now. Later on time I branched the
bzr eucalyptus-devel Launchpad repo and synced there with the
src-offline code. I was slow to react on thing I can say. Fourth challenge was also technical and still dealing with. I was looking to
setup a machine to set a cloud and test my branch. The Dean of my faculty
kindly offered a machine but I ve never managed to get things arranged
with the technical team. Steffen and I discussed about this and evaluated
options, at the end we settled on pushing adoption rather than showcasing it.
Since for adoption we need a use case, I ve spend some SoC money on hardware
for doing this. I should have news this week on that side :) Finally, I d like to thank everyone on the Debian SoC team for this
opportunity to participate. I like to thank Steffen for his effort on
arranging things for me, Graziano from Eucalyptus for his advice on
working with the software code. The different people from Eucalyptus I
interacted with and showed interest on the project s sucess. My
classmates and teachers from the Computer Science School at UCSP in
Arequipa-Peru, friends from the computing community in Peru SPC and
finally my family. Thank you, I learned a lot, specially on the personal
side. As Randy Pausch put: The brick walls are there to give us a
chance to show how badly we want something. Resources
Please see the Wiki page[1] for any reference to the project s resources. 1- http://wiki.debian.org/SummerOfCode2011/BuildWithEucalyptus/ProjectLog Best regards,
Rudy

22 August 2011

Debian Med: Experimenting with Amazon ... cloud and shop

Amazon has recently renewed a voucher for their AWS cloud services. It is enough to keep 4 machines up 24/7 for two years ... or to experiment with this and that with some confidence not to be surprised at the month's end. Thank you, Amazon. And you all, if there is something you want to experiment with, tell me to start it ... or inform me / pressure me to finally find out how I can delegate my credentials.

Something I would like you all to play with is to start shopping through the many links to your right, where most of you should find an Amazon store close to you. Tell me what country is missing. There is sadly no earnings for what I buy personally, but for everything I get someone else to buy through those links, there is up to 5%. This shall pay someone's travel to the next sprint, so I hoped. But so far it is only the tons of canned dog food my wife bought through Amazon (which is great, she did not need to carry it and it was a free delivery), that contributed to it all with 6 Euros. I do not see who bought what or what is bought in a single order (well, there are not too many orders), but I see what was bought ... not that it matters much, but you should know.

Just recently I discovered the Amazon personal Shops, so I created a Debian Med Shop. This allows to mention various products easily. And we can use it to point each other to some good stuff that has crossed our ways. I put a pointer to "The Cell" there, which may be obvious to many of you, but it is not for the typical IT guy approaching bioinformatics outside the UK/US bookmarket. And Kensington stopped my RSI problems ten years back, together with Microsoft, admittedly. What is missing? We should possibly have more of such shops, but give me feedback on how easy it is to switch to one's home Amazon. An I should then check if indeed one gets any earnings assigned when the Amazon is changed - would be positively surprised if so.

All this Amazon partnering has the gigantic disadvantage that it is personal to me. So you need to trust me that I indeed forward the money. I can of course just paste the summary Amazon gives me, but you still need to trust me. And you need to send me the items you wish to see in the shop and ... annoying. Please comment with better ideas ... and if in need of something consider doing that shopping through the links to the right ... it might accumulate to something and help the one or other patch / new package during the next Debian Med Sprint on Bioinformatics.

Mesutcan Kurt: Python Multi-Build for Python Extensions Packaging - Report 5

<meta content="text/html; charset=utf-8" equiv="content-type">
Hi everybody,

This is the 5th and the final report of my Google Summer of Code project for Debian,
Python Multi-Build for Python Extensions Packaging.

During the Google's Summer of Code 2011 period, I coded a tool to packaging Python extensions which can be built by distutils, autotools, cmake and scons. I finished tool for Python3.X (py3build), its CDBS files and working on integrating it with debhelper's sequencer and the tool for Python2.X (pybuild) and its BDS/DebHelper files. I will surely continue after GSoC finished and will continue improving the tool. The tool's git repository is here[1].

I'm a bit behind of my schedule. I finished all plugins for Python3.X except packaging module. Instead of that I worked on CDBS and DebHelper files. I finished CDBS files, also write a DebHelper but we decided to do DH file a different way. So I need to change it. I will port the tool to Python2.X.

In git repository there is contrib/ directory to contain CDBS and DebHelper files. CDBS files are in contrib/cdbs/ directory and debhelper files are in contrib/debhelper/ directory. I put original files if they exists (with .orig suffix) and modified files. I also created a new file for CDBS, called python-py3build.mk.in for handling all build systems. And modified python-distutils.mk.in and pyt<wbr>hon-autotools.mk.in files. All they are in git repository.

I'm still working on DebHelper file. After that I'll work on pybuild. And surely testing all of them and if any bug or problem occurs I will fix it.

Also, I need to improve my build system detection algorithm. At first, I thought that if there is multiple build system matches then show which are usable and then exit but I realized that in CDBS and DebHelper I need one build system. So even if there is multiple matches, it should return something. I'm also working on that.

For now that's all. Thanks everybody. It is a pleasure to contribute to Debian and participating from Google's Summer of Code. I will be in touch with Debian Project as a contributor.

[1] git://git.debian.org/~<wbr>mesutcan-guest/py3multibuild.<wbr>git

21 August 2011

Chris Lamb: Timezone bingo in debian/changelog files

Tim pointed out that it's worth travelling simply for the new timezone in your debian/changelog entries. We can use AptFs to work out who has collected the most so far:
import os
import glob
import itertools
import collections
from dateutil.parser import parse
from debian.changelog import Changelog
data = collections.defaultdict(set)
for package in glob.glob('/apt/*'):
    if os.path.islink(package):
        continue # Consider source packages only
    try:
        changelog = Changelog(open('%s/debian/changelog' % package))
    except:
        continue # Ignore invalid changelogs
    for entry in changelog:
        try:
            data[entry.author].add(parse(entry.date).strftime('%z'))
        except ValueError:
            pass # Ignore invalid dates
fn = lambda x: len(x[1])
top = sorted(data.items(), key=fn, reverse=True)
for k, g in itertools.groupby(top, key=fn):
    print "\n%d timezone(s):" % k
    for author, timezones in sorted(g):
        print " * %s (%s)" % (
            author.encode('utf8', 'ignore'),
            ', '.join(sorted(timezones, reverse=True)),
        )
14 timezone(s):
 * Bdale Garbee <bdale@gag.com> (-0800, -0700, -0600, -0500, -0400, -0300,
   +1300, +1100, +1030, +0900, +0300, +0200, +0100, +0000)
12 timezone(s):
 * Joey Hess <joeyh@debian.org> (-1000, -0900, -0800, -0700, -0500, -0400,
   -0300, -0200, +0300, +0200, +0100, +0000)
11 timezone(s):
 * Paul Wise <pabs@debian.org> (-0400, -0300, +1300, +1100, +1000, +0930,
   +0900, +0800, +0200, +0100, +0000)
9 timezone(s):
 * Barak A. Pearlmutter <bap@debian.org> (-0700, -0600, -0500, -0400, +0500,
   +0300, +0200, +0100, +0000)
 * Martin Michlmayr <tbm@cyrius.com> (-1000, -0700, -0300, +1100, +1000,
   +0300, +0200, +0100, +0000)
 * Martin Pitt <mpitt@debian.org> (-0800, -0700, -0600, -0500, -0400, +0300,
   +0200, +0100, +0000)
 * Sam Hocevar (Debian packages) <sam+deb@zoy.org> (-0700, -0500, -0400, -0300,
   +0930, +0300, +0200, +0100, +0000)
Full output. However, something tells me we aren't going to see widespread gamification of Debian development.

Vincent Sanders: A year of entropy

It has been a couple of years now since the release of the Entropy Key Around a year ago we finally managed to have enough stock on hand that I obtained a real production unit and installed it in my border router.

I installed the Debian packages, configured the ekeyd into EGD server mode and installed the EGD client packages on my other machines and pretty much forgot about it.

The recent new release of the ekey host software (version 1.1.4) reminded me that I had been quietly collecting statistics for almost a whole year and had some munin graphs to share.

The munin graphs of the generated output is pretty dull. Aside from the minor efficiency improvement in the 1.1.3 release installed mid December the generated rate has been a flat 3.93 Kilobytes a second.
The temperature sensor on the Entropy key shows a good correlation with the on-board CPU thermal sensors within the host system.
The host border router/server is a busy box which provides most network services including secure LDAP and SSL web services, it shows no sign of not having enough entropy at any point in the year.
The sites main file server and compile engine is a 4 core 8 gigabyte system with 12 drives. This system is heavily used with high load almost all the time but without the EGD client running has almost no entropy available.
The next system is my personal workstation. This machine often gets rebooted and is usually turned off overnight which is why there are gaps in the graph and odd discontinuities. Nonetheless entropy is always available just like the rest of my systems ;-)
And almost as a "control" here is a file server on the same network which has not been running EGD client (Ok, Ok already it was misconfigured and I am an idiot ;-)
In conclusion it seems an entropy key can keep at least this small network completely filled up with all the entropy it needs without much fuss. YAY!

Christian Perrier: 10 years being Debian Developer - part 1: before 1992

So, on July 31st 2011, it was exactly 10 years since I am a Debian developer. What happened in the meantime? What lead me to this? What turned this unskilled dude into a sometimes quite visible contributor of one of the major free software projects? If you're interested in that, please read on. Otherwise, well, this is just yet another "bubulle talks about self" post and you can skip it. Well, first of all, how did I end up being a DD? And first of firsts, how did I end up not being a random user of Windows, playing games on his desktop computer at work? I am not a computer scientist, an "informaticien" as we sometimes say in French (most often, what people who are not in computing stuff say...thinking that all folks working more or less closely to computers know everything about them). I graduated with a PhD in Materials science, in 1989 after conducting a research on "Influence of Yttrium Oxide dispersion on the strength of titanium alloys", at Onera, a French public research institution for aerospace and defence. I was then hired, still at Onera (where I'm still working, 25 years after starting my PhD work) to lead the Mechanical Testing Laboratory in the Materials Science department. So, my lab had many big machines designed to conduct creep and fatigue tests often at interestingly high temperatures such as 2000 C, on samples of various materials that are used in aircrafts structures, engines, etc. or in various space thingies (remember Herm s, the european shuttle?) or in various "things that fly but just one way and you shouldn't be there when they land". So, we had computers handling data acquisition for these tests. So I became involved with designing data acquisition setups, or even programming data acquisition programs (one of mine, written in Forth, ran all Onera creep tests until 2004 and successfully passed Y2K because I knew that 2000 was a leap year. It could even pass 2100 as I knew this is not a leap year..:-) One day, I had to buy a modem in order to communicate with out italian counterpart (CIRA) and exchange tests results. Then I had to learn how modems work in MS-Dos(yeah...). Then, I discovered "online" resources...indeed more that strange world that was then called "BBS" (Bulletin Board Systems), those mysterious things ran by some happy few who were using modems at their home place to communicate in "forums" and everything related to technology. PC-Board, Remote Access, Fidonet, etc. became familiar to me these days, back in 1988-1990. So familiar that I ended up running my own BBS at home, killing our phone bills and using very sophisticated techniques such as US Robotics "High Speed Transfer" modems that could be used at 19200bps asymetrical for very high speed transfers of kilobytes and kilobytes of useless MS-Dos "freeware" and "shareware". Indeed, my very first BBS didn't even have one of these: it was using a cheaper V.22bis modem operating at 2400bps. I was waiting for my order of a sophisticated HST modem to arrive from USA through obscure import channels meant to circumvent the French telephone company regulations that were forbidding the use of "unapproved" systems, in order to protect the famous French Telephone System from interferences brought by Bad American Material. Bubulle System was born. During those years, I discovered very interesting things: computers can run together once you draw a wire between them. That's called Local Area Network and you can even transfer data at 1Mbps between two computers, assuming you don't forget to put terminating resistors at the end of the line on these funny 10-baseT connectors at the back of your home-assembled PC that was using 2MB of RAM (bought for very cheap through the help of an American friend who was in touch with some Chinese folks who were selling 256kb RAM sticks for half the retail price....assuming you want to drive in a mysterious storing place close to Charles de Gaulle airport or Eurodisney). Hello Gordon. Yes, I know, we're still friends on Facebook and you're probably still using that weird programming language which you were, IIRC, the only person in the world to use. 2MB, that should be enough for barely anything, including running *multitasking* software where, miracle, I could run two tasks at the same time on my one and only PC at home. Miracle, I don't have to shutdown my BBS if I want to read forums on my friends BBS. Yay for Desqview/386! Multitasking for dummies Still, I have to build one of these "networks" at home. Elizabeth won't like that as it means one more box (home-made of course) in our living room and some more wires. And why the hell is it running 24/7? So that friends can visit the BBS, darling... And I can even communicate with them: I write a message, I get an answer the day after and so on. In one full week, we can have a great conversation that would have taken *minutes* to have in the real life. Isn't this the miracle of technlogy? And, yes, this is a good reason for having phone bills raising up to 500 Francs/month: people can "exchange" programs through my BBS, that horrible white box running in the living room. Often, these programs are written for free and some of them are even given with "source code", which allows people to *modify* them. And that even makes friends, you know? Imagine that some day we have to move from one house to another: then I can just call out "who wants to help bubulle moving?", and probably a dozen of (sometimes scary but always nice and polite...and sometimes even showered) geeks will pop up and happily carry boxes full of my vinyl LP collection all day long. An entire world of friends. "bubulle", you say, dear? What's that? That's my nickname. It was invented by one of these friends, a really strange guy named Ren Cougnenc who wrote this "free software" program anmed BBTH, which allows you to use modems to connect to BBS, and even to those many "Minitel" BBS we have in France, thanks to our wonderful world-leading technology using V.23 communication. Many people know me as "bubulle" because, you know, Perrier water has bubbles and Ren likes Gaston Lagaffe fish companion who he named "bubulle". Ren , I love you. You chose to leave this world back in 1998. We'll no longer have our "p'tits midis" in Antony where you were showing me the marvels of what's coming in next episode. All this was around 1988 and about 1992, doing all these mysterious things at home (between Jean-Baptiste and Sophie's diapers) while still working with data acquisition MS-Dos machines at work. How did this end up being a Debian Developer? You'll know in the next episode..:-)

Matthew Palmer: Unintended Consequences: Why Evidence Matters

If you were trying to get rid of hiring discrimination (on grounds irrelevant to the ability to do the job), you d think a good way to do it would be to reduce the ability of the hiring manager to discriminate, by restricting their access to irrelevant (but possibly prejudicial) information. It s certainly what I might come up with as an early idea in a brainstorming session. I m not alone: France had this same idea, and gave it a go, by passing a law requiring companies to anonymise resumes before they got to any decision makers. So far, so average. But rather than just coming up with an idea and inflicting it on everyone by a blanket law, they did what should be done with all new ideas: they trialled it (with 50 large corporations, according to the report) before making it universal, to make sure that the theory matched reality. Then, after giving it a good shake, they examined the evidence, and found that the idea had some unintended consequences:
Applicants with foreign names, or who lived in under privileged areas were found to be less likely to be called in for an interview without the listing of their name and address. Researchers reasoned that this was because employers and recruiters made allowances for subpar presentation or limited French speaking if their performance could be explained by deprivation or foreign birth.
The icing on the cake is that now the evidence is in, they re now planning on making it optional (I m not sure how that s different from killing it entirely, but I guess it s worth the same in the end). So we ve got the quinella of decision-making awesome: Far too often, we get far too attached to our ideas, and don t let them go when reality doesn t fit our preconceptions. Kudos to the people involved in this idea for not letting their egos get in the way of good government. Let it be an object lesson for us all.

20 August 2011

Thorsten Glaser: FrOSCon 2011, Day 1

Built the ISO in the morning, today. Finally. Whew. It was much too warm in the m nsa, and why did I have to get up so early anyway? Real Conferences don t start before 10 o clock, and there are no sensible activities before 11 o clock anyway Talked to a lot of people, introduced my favourite Fedora Packager to Geocaching. Now my throat is sore and I m tired. Social Event was not my case, as usual. (And even the vegetarian food now costs money as opposed to, I think, two years ago.) At least dry and not too loud. Still, best thing of FrOSCon is the Friday Evening Jugoslawian Food Mealtime ;-)

19 August 2011

Cyril Brulebois: Squeeze backports for Xorg

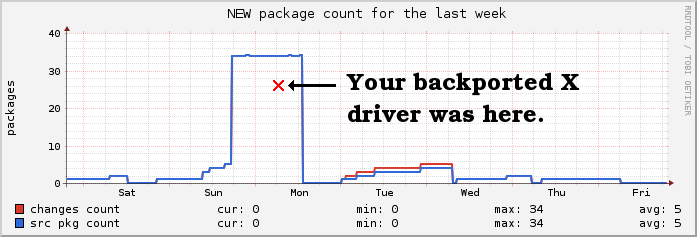
It took some time but it finally happened! NEW queue for backports Rule of thumb: if you're happy with Squeeze s X, stick to it. If you need a newer driver, for example for Intel Sandy Bridge, then give squeeze-backports a shot, and cross fingers! As usual, x.debian.net contains the relevant documentation. Hopefully, the short squeeze-backports instructions will be sufficient. If you encounter some issues, feel free to contact debian-x@.

Michael Prokop: Use of VCS in Debian packages some stats

Everyone loves stats, ok well at least I do. I was doing some research with regards to package maintenance within the Debian distribution and since the results might be interesting for someone else there we are. On 19th of August 2011 there have been: Therefore ~59% of all packages in Debian/sid are officially managed with a version control system (VCS). Now, which VCS do those packages use?
  1. Svn: 4939
  2. Git: 4377
  3. Darcs: 284
  4. Bzr: 247
  5. Hg: 61
  6. Cvs: 31
  7. Arch: 28
  8. Mtn: 10
I ve retrieved the numbers from the Ultimate Debian Database (UDD). Sadly there s a bug in UDD regarding the Vcs-Type information, see #637524. Therefore I ve extracted a list of 80 packages where a Vcs-Browser header is available but the Vcs-Type entry is empty in UDD. 29 packages of them are managed inside CVS but don t appear as such in UDD, so I manually corrected the number for CVS in the numbers above. The remaining 51 packages have a Vcs-Browser field set but lack the according Vcs-* entry, some of them pointing to upstream VCS instead of the according Debian package repository, some of them result in 404 errors, etc. As a result I ve reported bugs where applicable (#638466, #638468, #638469, #638470, #638471, #638472, #638474, #638475, #638476, #638477, #638479, #638482, #638486, #638488, #638493, #638497, #638501, #638475, #638475, #638502, #638503, #638505, #638506, #638508, #638509, #638510, #638511, #638512, #638513, #638516, #638518, #638519, #638520, #638522, #638523, #638524, #638525, #638526, #638527, #638528, #638529, #638530, #638516, #638531). Disclaimer: I found Debian s Statistics wiki page and Zack s VCS usage stats after starting to play with my own stats. AFAICT Zack s slightly higher numbers are the result of looking at multiple versions for the same source packages, as you ll see when comparing numbers from UDD s sources_uniq view (which I used) with either 1) UDD s sources table, 2) source table count from projectb or 3) Package count from http://$DEBIAN_MIRROR/debian/dists/unstable/ main,contrib,non-free /source/Sources.bz2. Conclusion: 9316 packages are officially managed with Subversion and Git as of today, representing ~94% of the VCS managed packages. This means ~55% of all the Debian (source) packages are available through either a Git or Subversion repository and that s actually the number I was originally interested in. Thanks to Alexander Wirt, Christian Hofstaedter, Gerfried Fuchs, J rg Jaspert and Michael Renner for hints in forming up the final stats results.

Kai Wasserb ch: wine-unstable: partly broken on amd64

Just a short entry, as I've already got a few e-mails about this: the JPEG is broken at the moment for my unofficial wine-unstable packages on amd64. This is due to #638543 in ia32-libs-dev. Please see the bug report for a detailed explanation. A rebuild with libjpeg62-dev isn't an option, as other build dependencies pull libjpeg8-dev in anyway. Thus forcing the older version on amd64 just generates a FTBFS. Full multi-arch support in the toolchain (including dpkg) or an update for ia32-libs are the two viable solutions for this as far as I can tell.

Alexander Reichle-Schmehl: How to read ftp-masters package numbers table

In my previous blog about Debian's growing archive size I pointed as reference to an hard to read table on the ftp-master server, and missed that the table is not self explanatory and on the first glance hard to read. The table currently looks like the following:
                  e      s     p-u     t      u    t-p-u   l-r    s-u     o    o-p-u   s-r   
---------------------------------------------------------------------------------------------
     all         1096  12034     70  14442  15784     20      1     12   8910    230      0  
    alpha           -      -      -      -      -      -      -      -  13183    297      -  
    amd64        1164  16997    242  18581  19605     39      -     21  13964    342      -  
     arm            -      -      -      -      -      -      -      -  13251    291      -  
    armel         988  16401    239  17879  18680     39      -     21  13411    327      -  
     hppa           -      -      -      -      -      -      -      -  13227    264      -  
  hurd-i386       445      -      -      -  12622      -      -      -      -      -      -  
     i386        1178  17188    242  18727  19751     39      -     21  14377    350      -  
     ia64         951  16036    239  17303  18045     39      -     21  13554    329      -  
kfreebsd-amd64    807  14499    231  15905  16480     39      -     21      -      -      -  
kfreebsd-i386     826  14491    231  15881  16498     39      -     21      -      -      -  
     mips         974  16269    241  17730  18504     39      -     21  13638    323      -  
    mipsel        984  16291    239  17807  18558     39      -     21  13600    319      -  
   powerpc       1078  16677    239  18156  19036     39      -     21  13872    332      -  
     s390        1030  16252    239  17678  18469     39      -     21  13331    327      -  
    source        522  14974     51  16376  17405      1     19      6  12519     75    151  
    sparc         992  16423    239  17895  18673     39      -     21  13542    329      -  
The lines represent different hardware architectures Debian supports, like amd64 (for 64-Bit PCs), i386 (for 32-Bit PCs), etc. Two lines are kind of special, the one marked source and the one marked all. Let's start with the source line: That counts the number of source packages. Those are rarely seen by end users. Source packages contain the actual source needed to build a package, as well as Debian specific changes and a blue print on how to create an actual installable binary package from the source. As you can see Debian supports quite some architectures, which leads to a small problem on the mirrors: Quite a lot shipped in Debian is actually architecture independent. For example documentation, most sound and graphic files, or level data for a game. To avoid storing the very same date multiple times, Debian makes haeavy use of so called arch: all packages. You might have noticed them already while installing them:
Hole:5 ftp://ftp.rrzn.uni-hannover.de/debian/debian/ squeeze/main extremetuxracer-data all 0.4-4 [28,1 MB]
Hole:6 ftp://ftp.rrzn.uni-hannover.de/debian/debian/ squeeze/main extremetuxracer amd64 0.4-4 [273 kB]
In this example I installed a quite small game on the amd64 architecture, which depends on a quite big architecture independent package (notice the all between package name and version) containing it's data.So, to get the actual number of packages a user can install on a specific architecture, one has to add the number in the all line to the number in the specific architecture line. But what column to pick? The columns represent so called suites. The s is for stable, currently Debian 6.0 aka Squeeze and o for oldstable, aka Debian 5.0 Lenny. The t is for testing, aka Wheezy or the upcoming Debian 7.0. The u is for unstable aka sid. The e is for experimental, used for stuff probably not yet ready to be part of a stable release and therefore not uploaded to unstable. The rest is not that interesting (as you see it's mostly empty anyway), like s-u for stable updates, several p-u suites for proposed-updates (that is stuff that might end up in the next point release, and should be tested). And then we have s-r and l-r which I forgot what they are about... Sorry. But back to topic: As I explained briefly a source package is mostly used internally, but may create several binary packages, which a user can install. So the most interesting number for users is the number of binary packages on an arch. So we usually publish this number. So for example, using squeeze on i386 you can install: 17'188 (architecture dependent packages, column s row i386) + 12'034 (architecture independent packages columns s row all) = 29'222 packages. And for completeness: They are build from 14'974 source packages (row source column s). So if look that up for unstable on amd64 you should get to the result 35'389 binary packages build from 17'405 source packages. Slightly less than I reported yesterday, because we removed some old stuff e.g. obsolete libraries in the meantime. Update: J rg just explained me, that the s-r and l-r are there to ensure Debian complies with the GPL. They hold the sources of everything shipped in the original lenny and squeeze releases. Update 2: J rg explained it to me again: s-r and l-r contains sources used without being referenced by a package, and so might get lost otherwise. One example is the kernel used by the debian installation system. You have to boot a kernel somehow, so it can't be packaged. But we still need to save the sources, so it is referenced in these suites and won't get lost.

Vincent Bernat: jchroot: chroot with more isolation

Linux 2.6.24, released more than three years ago, introduced two very interesting features: PID and network namespaces. They allow to create a process that does not share the same PID namespace or the same network namespace than other processes. Those namespaces are then inherited by the children (unless they are assigned new namespaces).

PID & mount namespaces A PID namespace is a view of the processes running on the system. Each PID namespace will have its own numbering of the processes contained in its namespace (including the namespace of the children). Other processes are hidden and therefore, it is not possible to issue any operation requiring a PID on them, like kill(2). Moreover, the process that was created first in a namespace will get PID 1. If it gets killed, the namespace is destroyed and all other processes contained in this namespace are killed as well. systemd, a system and service manager for Linux, targeted as a replacement for the old SysV init, uses could use this feature to launch daemons in their own PID namespace and keep track of them without relying on their cooperation. When it needs to kill a daemon, it just kills the process with PID 1 (which has another PID in the global namespace) and the kernel will do the hard work of killing all processes that were started in this namespace. You can get more details about this namespace in the manual page of clone(2) (search for CLONE_NEWPID). UPDATED: In fact, systemd does not use PID namespaces but cgroups to group processes together. There is no PID numbering here but spawned processes are all enclosed into one cgroup and therefore can be killed easily. For example, here is the result of pstree -p inside a PID namespace:
root@guybrush:/# pstree -p
bash(1) pstree(8)
         sleep(7)
The PID of sleep is 7. In the global namespace, it is 31762 instead. But it is the same processus!
root@guybrush:/# ps -eo pid,command   grep sleep
31762 sleep 1000
Linux have also supported mount namespaces since a long time. Each process can have its own mount points that will be visible only by processes in the same namespace or in children namespaces. When the namespace is destroyed (when no process left), the kernel will do the cleanup itself.

chroot A common way to test experimental software or do packaging work is to build a chroot: debootstrap is used to build a new complete system inside a directory and chroot allows to enter into this new system. Tools like schroot can become handy if you need to do that often. Unfortunately, you only get an isolated filesystem. When you start launching daemons and mounting partitions, you need to keep track of all your actions to undo them. Quitting the chroot will not kill any daemon nor unmount any partition. Extending an existing tool, like schroot to use PID and mount namespaces seems the best way to prevent such problems. I have filed bug #637870 for this purpose. However, this is not as simple as it seems since schroot allows to run a process into an existing session. When the session is a chroot, this is quite easy: just chroot into the same root filesystem and launch the process here. With other kind of namespaces, you need to use a new system call, setns(), to change the current namespace of the running process. However, some bits are still missing. First, the GNU C Library does not implement the appropriate wrapper. Second, Linux (as of 3.0) does not contain the support to change the PID namespace of a running process yet. Other tools exist, like lxc (aka Linux Containers). However, it is more targeted at providing a complete container. I have reported that lxc-execute is not able to spawn a standalone shell but got no luck. UPDATED: systemd ships with systemd-nspawn which was exactly what I needed. However, it requires systemd. Otherwise, it seems less basic than the alternative that I describe below (some sensible mount points are setup, the console is correctly configured, signals are correctly transmitted, ). If you use systemd, look at it!

jchroot Building a chroot clone using namespaces is quite easy. The only difficulty is the use of clone(2). Here is a sketch:
int main()  
  pid_t pid;
  int ret;
  long stack_size = sysconf(_SC_PAGESIZE);
  void *stack = alloca(stack_size) + stack_size;
  /* New process with its own PID/IPC/NS namespace */
  pid = clone(step2,
              stack,
              SIGCHLD   CLONE_NEWPID   CLONE_NEWIPC  
              CLONE_NEWNS   CLONE_FILES,
              NULL);
  /* Wait for the child to terminate */
  while (waitpid(pid, &ret, 0) < 0 && errno == EINTR)
    continue;
  return WIFEXITED(ret)?WEXITSTATUS(ret):EXIT_FAILURE;
 
static int step2(void *a)  
  /* Mount /proc as an example */
  mount("proc", "/proc", "proc", 0, "");
  /* Chroot */
  chroot("/srv/debian");
  chdir("/");
  /* Drop privileges */
  setgid(1000);
  setgroups(0, NULL);
  setuid(1000);
  /* Exec shell */
  execl("/bin/bash", "/bin/bash", NULL);
 
Add command flags, error handling and fstab parsing for the definition of mount points and you get jchroot. Here is an example of use:
$ cat fstab
proc     /proc  proc    defaults                  0  0
sys      /sys   sysfs   defaults                  0  0
/home    /home  none    bind,rw                   0  0
/dev/pts /dev/pts none  bind,rw                   0  0
/var/run /var/run tmpfs rw,nosuid,noexec,mode=755 0  0
/etc/resolv.conf /etc/resolv.conf none bind,ro    0  0
$ sudo jchroot -f fstab -n test /srv/debian/squeeze /bin/bash
# hostname
test
# ps auxww
USER       PID %CPU %MEM    VSZ   RSS TTY      STAT START   TIME COMMAND
root         1  0.0  0.0  19480  1888 pts/1    S    15:18   0:00 /bin/bash
root         3  0.0  0.0  16536  1184 pts/1    R+   15:18   0:00 ps auxww
# /etc/init.d/postgresql start
Starting PostgreSQL 9.0 database server: main.
# exit
$ ps auxwwc   grep postgres
$
I hope that jchroot won t live for too long and that its features will be integrated into regular chroot tools. I was thinking at proposing a patch for chroot(8). Anyone knows if this would have a chance to be accepted?

Matthew Palmer: Stream of Consciousness

This forum post on requiring formal letters of resignation made me smile:
HR does silly stuff like this all the time. Somebody s following some policy that was created because somebody verbally resigned nine years ago and then wanted to come back and some executive said where s their letter and HR said we don t have one and the exec said that s not good and we oughta not be doing stuff to help people leave unless they re really leaving and HR said okay we ll have a policy and the exec said that s good. And the exec s not there anymore.
I ll leave everyone to make their own conclusions as to why I was reading that particular thread.

18 August 2011

Thorsten Glaser: How not to create DEB files

Once upon a time, there was Deb and Ian. That was about exactly 18 years ago. We don t talk about the 0.939000 format any more, but they eventually settled on:

	$ ar rc pkg_1.0_all.deb debian-binary control.tar.gz data.tar.gz
	$ hexdump -C pkg_1.0_all.deb   head
	00000000  21 3c 61 72 63 68 3e 0a  64 65 62 69 61 6e 2d 62   !<arch>.debian-b 
	00000010  69 6e 61 72 79 20 20 20  31 33 31 33 36 38 33 35   inary   13136835 
	00000020  32 39 20 20 31 30 30 36  20 20 32 30 30 20 20 20   29  1006  200    
	00000030  31 30 30 36 34 34 20 20  34 20 20 20 20 20 20 20   100644  4        
	00000040  20 20 60 0a 32 2e 30 0a  63 6f 6e 74 72 6f 6c 2e      .2.0.control. 
	00000050  74 61 72 2e 67 7a 20 20  31 33 31 33 36 38 33 35   tar.gz  13136835 
	00000060  32 39 20 20 31 30 30 36  20 20 32 30 30 20 20 20   29  1006  200    
	00000070  31 30 30 36 34 34 20 20  31 33 39 31 20 20 20 20   100644  1391     
	00000080  20 20 60 0a 1f 8b 08 00  00 00 00 00 00 03 ed 59      ............Y 
	00000090  eb 6f db 36 10 f7 d7 f0  af b8 3a 5e 9b 74 b1 f5   .o.6......:^.t.. 
 

By then, systems were a.out(5), and everything was good. (Of course, if you look at the mtimes, you ll notice I faked this. But it s really equivalent to the real thing.

But oh horror! GNU binutils, not always everyone s friend, switched from using BSD style Unix Archiver libraries in ar(1) to SYSV style libraries on elf(5) systems:

	$ ar rc on-elf debian-binary control.tar.gz data.tar.gz
	$ hexdump -C on-elf   head
	00000000  21 3c 61 72 63 68 3e 0a  64 65 62 69 61 6e 2d 62   !<arch>.debian-b 
	00000010  69 6e 61 72 79 2f 20 20  31 33 31 33 36 38 33 35   inary/  13136835 
	00000020  32 39 20 20 31 30 30 36  20 20 32 30 30 20 20 20   29  1006  200    
	00000030  31 30 30 36 34 34 20 20  34 20 20 20 20 20 20 20   100644  4        
	00000040  20 20 60 0a 32 2e 30 0a  63 6f 6e 74 72 6f 6c 2e      .2.0.control. 
	00000050  74 61 72 2e 67 7a 2f 20  31 33 31 33 36 38 33 35   tar.gz/ 13136835 
	00000060  32 39 20 20 31 30 30 36  20 20 32 30 30 20 20 20   29  1006  200    
	00000070  31 30 30 36 34 34 20 20  31 33 39 31 20 20 20 20   100644  1391     
	00000080  20 20 60 0a 1f 8b 08 00  00 00 00 00 00 03 ed 59      ............Y 
	00000090  eb 6f db 36 10 f7 d7 f0  af b8 3a 5e 9b 74 b1 f5   .o.6......:^.t.. 
 

Can you spot the difference?

Of course, ELF is what you want , so there is little choice. Unix Archiver libraries are system dependent, and no format has ever been normed, but DEB files use it as format so what is one to do?

	$ GNUTARGET=a.out-i386-linux ar rc with-aout \
	> debian-binary control.tar.gz data.tar.gz
	$ md5sum pkg_1.0_all.deb with-aout on-elf
	248f78d42f8ca8f2a3560f9800b2bf01  pkg_1.0_all.deb
	248f78d42f8ca8f2a3560f9800b2bf01  with-aout
	09eca70c9b11b6b55bbadcab5c3201fb  on-elf
 

OK, and what do I do on my Debian/m68k system?

ar(1) uses bfd, and GNU binutils can not only forcibly set the target emulation but also show them:

debian_m68k$ ar -h 2>&1 grep '^ar: supported targets'
ar: supported targets: elf32-m68k a.out-m68k-linux elf32-little elf32-big plugin srec symbolsrec verilog tekhex binary ihex trad-core
debian_i386$ ar -h 2>&1 grep '^ar: supported targets'
ar: supported targets: elf32-i386 a.out-i386-linux pei-i386 elf32-little elf32-big elf64-x86-64 elf32-x86-64 pei-x86-64 elf64-l1om elf64-k1om elf64-little elf64-big plugin srec symbolsrec verilog tekhex binary ihex trad-core
debian_i386$ ar -h 2>&1 grep '^ar: supported targets' # binutils-multiarch
ar: supported targets: elf32-i386 a.out-i386-linux pei-i386 elf32-little elf32-big elf64-alpha ecoff-littlealpha elf64-little elf64-big elf32-littlearm elf32-bigarm elf32-hppa-linux elf32-hppa elf64-x86-64 elf32-x86-64 elf64-l1om elf64-k1om elf64-ia64-little elf64-ia64-big pei-ia64 elf32-m68k a.out-m68k-linux coff-m68k versados ieee a.out-zero-big elf32-tradbigmips elf32-tradlittlemips ecoff-bigmips ecoff-littlemips elf32-ntradbigmips elf64-tradbigmips elf32-ntradlittlemips elf64-tradlittlemips elf32-powerpc aixcoff-rs6000 elf32-powerpcle ppcboot elf64-powerpc elf64-powerpcle aixcoff64-rs6000 aix5coff64-rs6000 elf32-s390 elf64-s390 elf32-shbig-linux elf32-sh-linux elf32-sh64-linux elf32-sh64big-linux elf64-sh64-linux elf64-sh64big-linux elf32-sparc a.out-sparc-linux elf64-sparc a.out-sunos-big pei-x86-64 elf32-m32r-linux elf32-m32rle-linux elf32-spu plugin srec symbolsrec verilog tekhex binary ihex trad-core
mirbsd_i386$ ar -h 2>&1 grep '^ar: supported targets'
ar: supported targets: elf32-i386 coff-a29k-big a.out.adobe aix5coff64-rs6000 a.out-zero-big a.out-mips-little epoc-pe-arm-big epoc-pe-arm-little epoc-pei-arm-big epoc-pei-arm-little coff-arm-big coff-arm-little a.out-arm-netbsd pe-arm-big pe-arm-little pei-arm-big pei-arm-little b.out.big b.out.little efi-app-ia32 efi-app-ia64 elf32-avr elf32-big elf32-bigarc elf32-bigarm elf32-bigarm-symbian elf32-bigarm-vxworks elf32-bigmips elf32-cr16c elf32-cris elf32-crx elf32-d10v elf32-d30v elf32-dlx elf32-fr30 elf32-frv elf32-frvfdpic elf32-h8300 elf32-hppa-linux elf32-hppa-netbsd elf32-hppa elf32-i370 elf32-i386-freebsd elf32-i386-vxworks elf32-i860-little elf32-i860 elf32-i960 elf32-ia64-hpux-big elf32-ip2k elf32-iq2000 elf32-little elf32-littlearc elf32-littlearm elf32-littlearm-symbian elf32-littlearm-vxworks elf32-littlemips elf32-m32r elf32-m32rle elf32-m32r-linux elf32-m32rle-linux elf32-m68hc11 elf32-m68hc12 elf32-m68k elf32-m88k elf32-mcore-big elf32-mcore-little elf32-mn10200 elf32-mn10300 elf32-msp430 elf32-nbigmips elf32-nlittlemips elf32-ntradbigmips elf32-ntradlittlemips elf32-openrisc elf32-or32 elf32-pj elf32-pjl elf32-powerpc elf32-powerpc-vxworks elf32-powerpcle elf32-s390 elf32-sh elf32-shbig-linux elf32-shl elf32-shl-symbian elf32-sh-linux elf32-shl-nbsd elf32-sh-nbsd elf32-sh64 elf32-sh64l elf32-sh64l-nbsd elf32-sh64-nbsd elf32-sh64-linux elf32-sh64big-linux elf32-sparc elf32-tradbigmips elf32-tradlittlemips elf32-us-cris elf32-v850 elf32-vax elf32-xstormy16 elf32-xtensa-be elf32-xtensa-le elf64-alpha-freebsd elf64-alpha elf64-big elf64-bigmips elf64-hppa-linux elf64-hppa elf64-ia64-big elf64-ia64-hpux-big elf64-ia64-little elf64-little elf64-littlemips elf64-mmix elf64-powerpc elf64-powerpcle elf64-s390 elf64-sh64 elf64-sh64l elf64-sh64l-nbsd elf64-sh64-nbsd elf64-sh64-linux elf64-sh64big-linux elf64-sparc elf64-tradbigmips elf64-tradlittlemips elf64-x86-64 mmo pe-powerpc pei-powerpc pe-powerpcle pei-powerpcle a.out-cris demo64 ecoff-bigmips ecoff-biglittlemips ecoff-littlemips ecoff-littlealpha coff-go32 coff-go32-exe coff-h8300 coff-h8500 a.out-hp300hpux a.out-i386 a.out-i386-bsd coff-i386 a.out-i386-freebsd a.out-i386-lynx coff-i386-lynx msdos a.out-i386-netbsd i386os9k pe-i386 pei-i386 coff-i860 coff-Intel-big coff-Intel-little ieee coff-m68k coff-m68k-un a.out-m68k-lynx coff-m68k-lynx a.out-m68k-netbsd coff-m68k-sysv coff-m88kbcs a.out-m88k-mach3 a.out-m88k-openbsd mach-o-be mach-o-le mach-o-fat coff-maxq pe-mcore-big pe-mcore-little pei-mcore-big pei-mcore-little pe-mips pei-mips a.out-newsos3 nlm32-alpha nlm32-i386 nlm32-powerpc nlm32-sparc coff-or32-big a.out-pc532-mach a.out-ns32k-netbsd a.out-pdp11 pef pef-xlib ppcboot aixcoff64-rs6000 aixcoff-rs6000 coff-sh-small coff-sh coff-shl-small coff-shl pe-shl pei-shl coff-sparc a.out-sparc-little a.out-sparc-linux a.out-sparc-lynx coff-sparc-lynx a.out-sparc-netbsd a.out-sunos-big sym a.out-tic30 coff-tic30 coff0-beh-c54x coff0-c54x coff1-beh-c54x coff1-c54x coff2-beh-c54x coff2-c54x coff-tic80 a.out-vax-bsd a.out-vax-netbsd a.out-vax1k-netbsd versados vms-alpha vms-vax coff-w65 coff-we32k coff-z8k elf32-am33lin elf32-ms1 srec symbolsrec tekhex binary ihex netbsd-core

Wow. While binutils share no single supported working target, they can be built multiarch, or (on MirBSD) with --enable-targets=all --enable-64-bit-bfd. Doesn t help if you want to stay portable: GNUTARGET=srec is common on all Debian (sid) binutils versions (single or multiarch), but errors out on older binutils. The a.out-* targets are not common. Sure, you could hack around things, but this is tedious. If you follow things or know me a little, you might already have guessed that I wouldn t let that stand.

pax(1) to the rescue. On MirBSD, we use paxtar, which has cpio(1) and tar(1) front-ends and supports multiple formats (4 cpio and 2 tar variants) and has already been extended a lot and is lovingly called paxmirabilis (mirabilos peace in Latin) it has options to anonymise archives: set uid and gid to zero, set mtime to zero, (for ustar) only write the numeric uid and gid to the archive, (for cpio formats) serialise inodes and device information, write content of hardlinked files only once (breaks partial extraction but saves a lot of space, e.g. 2 MiB off the Grml initrd.gz). And, recently, the ability to append a trailing slash to pathnames of ustar members which are directories (GNU tar does it and I thought some Debian utilities check for it). So why not (the -M dist and fakeroot set the uid/gid to 0)

	$ find debian-binary control.tar.gz data.tar.gz   \
	> mircpio -oHar -Mdist >with-mircpio
	$ mirpax -w -M dist -f with-mirpax -x ar \
	> debian-binary control.tar.gz data.tar.gz
	$ mirtar -M dist -A -cf with-mirtar \
	> debian-binary control.tar.gz data.tar.gz
	$ GNUTARGET=a.out-i386-linux fakeroot ar rc with-aout-ar \
	> debian-binary control.tar.gz data.tar.gz
	$ md5sum with-*
	a466e2fd57cdee141fe585a43245548f  with-aout-ar
	a466e2fd57cdee141fe585a43245548f  with-mircpio
	a466e2fd57cdee141fe585a43245548f  with-mirpax
	a466e2fd57cdee141fe585a43245548f  with-mirtar
 

Voil . I got it, and even appending is possible. It supports the BSD format with special focus on DEB files, and deals with long filenames, but not symbol or filename tables (used by ranlib(1) or strange formats, respectively, but since we don t create *.a files to use with some native linker/binder/loader, we don t need that anyway).

On extraction (oh, and listing!) it deals with SYSV style filenames as well.

	$ mirtar tvf on-elf
	-rw-r--r--  1 tg       tg          4 Aug 18 16:05 debian-binary
	-rw-r--r--  1 tg       tg       1391 Aug 18 16:05 control.tar.gz
	-rw-r--r--  1 tg       tg      18135 Aug 18 16:05 data.tar.gz
	$ mirtar tvf with-aout
	-rw-r--r--  1 tg       tg          4 Aug 18 16:05 debian-binary
	-rw-r--r--  1 tg       tg       1391 Aug 18 16:05 control.tar.gz
	-rw-r--r--  1 tg       tg      18135 Aug 18 16:05 data.tar.gz
 

One of the real benefits is that you can use the front-ends interchangably for example, mirtar tzf foo.cpio.gz would work (which GNU tar can t do), and mircpio s ustar implementation, unlike GNU cpio s, is not horribly broken. Of course, there are some drawbacks: it s not GNU tar or GNU cpio, so there are absolutely zero --long-options. Some of their features are missing (but tar s -O is implemented now), so it s no replacement (but very well usable alongside it). The format called pax, committee-designed to replace ustar, isn t yet supported ironically, but that s on the TODO.

So, what do you think?

	tg@frozenfish:~/Debs/dists/sid/wtf/Pkgs/mircpio $ ll *.deb
	-rw-r--r-- 2 tg freewrt 78140 Aug 17 11:04 mircpio_20110817-0wtf2_amd64.deb
	-rw-r--r-- 3 tg freewrt 72262 Aug 17 11:00 mircpio_20110817-0wtf2_i386.deb
	-rw-r--r-- 1 tg freewrt 67446 Aug 17 18:21 mircpio_20110817-0wtf2_m68k.deb
 

Should I upload this to Debian proper? As for the licence: 3-clause UCB (and 2-clause BSD, which is a subset of it), so no problem. I m asking because the other package which I had been using for a long time and not uploaded, jupp, got uploaded recently (during DebConf) on user input (people wondered why it did not yet exist in Debian proper). I guess the old saying if it s not in Debian, it doesn t exist holds true in many parts of the OSS world. It s up to date wrt. standards btw, and lintian-clean save for two pedantic-class warnings (no upstream changelog file, no homepage link) which aren t fulfillable (could link this wlog entry as homepage). If you know Alioth you re familiar with the software formerly known as SourceForge, formerly known as GForge, currently known as FusionForge. My employer both uses it and contributes to it, we run an adapted (mostly themed, prototyping new functions that often end up in FusionForge itself, and backporting functions from FF to our production codebase ) version.

I ve backported the extratabs plugin to appease project managers and other non-technical people while we move our codebase to FF 5.1, and I did so on an installed version of the plugin rather than the source because the latter was tightly integrated with rather heavy packaging style changes.

	[ ]
	dh_builddeb
	# create fusionforge-plugin-extratabs binary package
	toplev=$$(pwd); cd plugins/fusionforge-plugin-extratabs; \
	p=$$(print -r -- $$(sed -n '/^Package: /s///p' C/control   head -1)); \
	v=$$(print -r -- $$(sed -n '/^Version: /s///p' C/control   head -1)); \
	a=$$(print -r -- $$(sed -n '/^Architecture: /s///p' C/control   head -1)); \
	d=$$ p _$$ v _$$ a .deb; \
	rm -f $$toplev/../$$d control.tar.gz data.tar.gz; \
	(cd control; find .   fgrep -v /.svn   sort   \
	    mircpio -oC512 -Hustar -M0x0B -Mgslash)   gzip -n9 >control.tar.gz; \
	(cd data; find .   fgrep -v /.svn   sort   \
	    mircpio -oC512 -Hustar -M0x0B -Mgslash)   gzip -n9 >data.tar.gz; \
	mirtar -M dist -Acf $$toplev/../$$d debian-binary cont*gz dat*gz; \
	rm -f control.tar.gz data.tar.gz; \
	cd $$toplev; dpkg-distaddfile $$d non-free/devel optional
 

The hardest part of extending debian/rules with that was to get the autobuild and dpkg-distaddfile call right. This works, even though I d call it a temporary kludge. (No need to tell me I should have used && I know. And I only shell out to mksh(1) because the inner part was already there from before, when I still used ar(1). This was slightly edited for the wlog.) In the meanwhile, apt-extracttemplates can deal with SYSV style filenames in DEB files on Debian sid, but not on Kubuntu hardy, which some people are using as Desktop OS still

Thorsten Glaser: FrOSCon 2011

This year without our friends from Grml, but The MirOS Project (all two active developers and our Booth Babe gecko2@) will of course attend FrOSCon, nicknamed Froschkon, again. We ll have a pre-event meal time at my favourite Jugoslawian Restaurant on Friday (20:00 CEST) contact me privately for the co rdinates if interested. On Saturday and Sunday we ll staff a booth and answer questions about the many projects we have (more or less) running, including but not limited to paxmirabilis (aka MirCPIO), The MirBSD Korn Shell aka mksh(1), jupp the editor, and developers private projects such as slowly undermining Debian or Google-Go. While slow we are still working on World Domination. And teaching people good shell programming by example code. We might even bring CDs, but I m still working on the ISO last night s build aborted because the OS grew a bit making the floppy image not fit any more. (Solution, drop ping(8) and rtsol(8), but re-add sf(4) and bce(4) now that they fit again.)

Next.

Previous.