Otto Kek l inen: SpacemiT K3 is a compelling RISC-V AI CPU, but difficult to buy

 The RISC-V CPU architecture has been gaining a lot of popularity since it launched in 2014, and now that the industry is standardizing on the RVA23 level that includes vector support as a mandatory extension, we are likely to see a lot more edge- and IoT devices with the ability to run local LLMs at reasonable speed, and most importantly at very compelling prices.
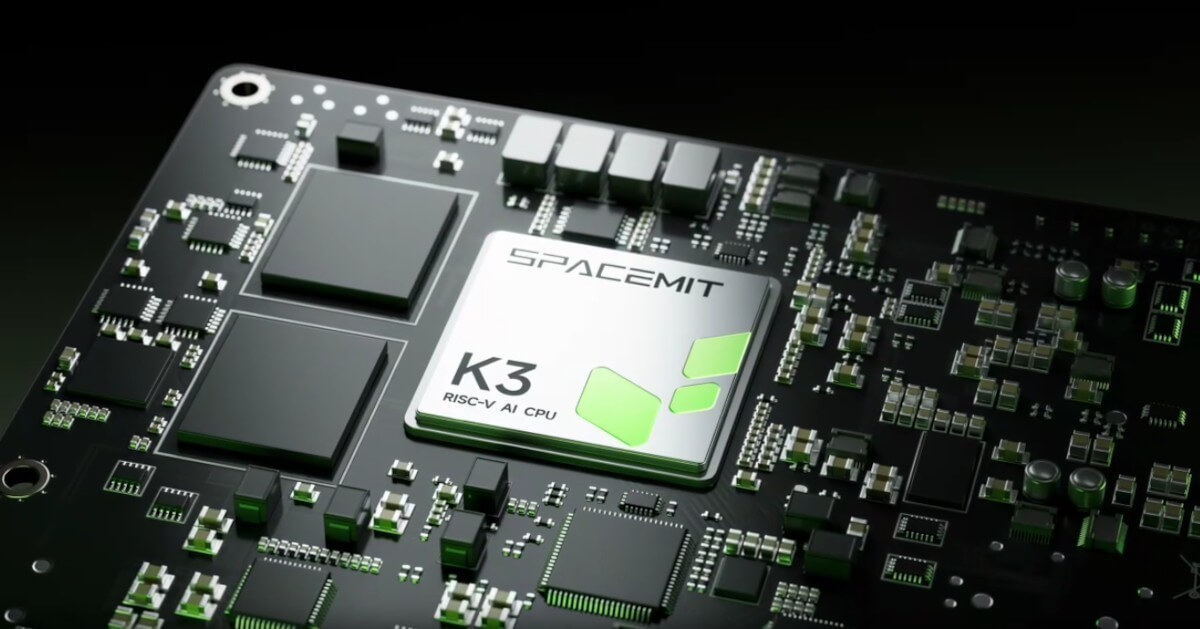
SpacemiT is a Chinese RISC-V CPU manufacturer that launched on May 11th, 2026, their long-anticipated next-gen RISC-V AI chip K3. It is among the earliest RISC-V CPUs that adhere to the RVA23 standard and performance-wise it is quite capable, providing 130 KDMIPS general computing power, 60 TOPS on INT4 which translates to about 15 tokens per second when running a 30 billion parameter large language model.
The aspect that really makes it stand out is:
- the RISC-V CPU architecture is open source,
- the price point is within reach of home and small business users and
- the overall feature set makes it an ideal platform to build local and offline AI systems.
Comparing the resellers
SpacemiT does not sell anything directly to consumers. Instead you need to buy a board that includes the K3 chip from an integrator. Currently the main resellers are:
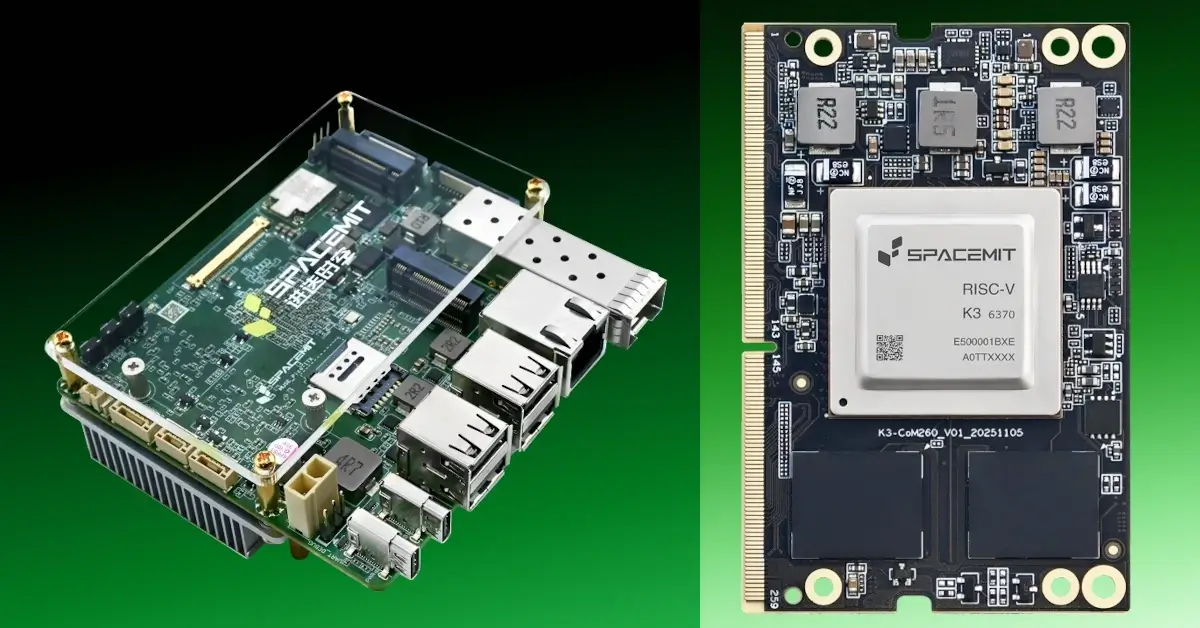
All of the above are Chinese companies that ship to customers both inside and outside China. DeepComputing stands out as the only one that actually has done real integration and ships the K3 on a custom board, while the others simply resell the SpacemiT-produced K3 pico-ITX and K3 CoM260 Kit.
Milk-V
Milk-V is a RISC-V specialized integrator, as the name already implies. They sell the K3 under the name Jupiter2. Of all the K3 pico-ITX reseller product pages, the Jupiter2 presentation is the nicest and most detailed. Unfortunately their order page at arace.tech only states that it is a pre-order with no information about shipping schedule, taxes, or other details like what SSD is included (if any). Based on the pictures it does ship with a Milk-V branded case. The 32 GB RAM lists at 504 EUR, which is a very reasonable price. The @MilkV_Official account on X recently promoted the K3.
Documentation and support
As of this writing, the Milk-V Jupiter2 documentation site is just a stub and has no actual content, and only two links to the SpacemiT K3 documentation site. For support there is a web forum with a dedicated Jupiter2 section. There is also a Matrix space, but unlike their other products, there is no dedicated Jupiter (neither v1 nor v2) channel.
Community size and open source involvement
At least one prior Milk-V product was certified by Canonical, which indicates there is some collaboration in progress. Canonical also lists the Milk-V Titan on its official Ubuntu for RISC-V partner-built hardware page.
Sipeed
The Sipeed K3 announcement is well written (in English) with all the relevant details and links to additional PDF manuals. However, their main page at sipeed.com says nothing about the K3, so one must know the subpage URL to access it. They offer both the K3 CoM260 kit compatible with Jetson Orin Nano carrier boards, and the stand-alone K3 pico-ITX-sized motherboard. The CoM260 kit is only 10 USD cheaper than the full pico-ITX motherboard, so choosing the latter is a no-brainer if starting from scratch. The pico-ITX model with 32 GB DDR5 RAM sells for 639 USD. The product page does not mention anything about hard disk size, so you don t really know exactly what you will be getting if placing an order. There is no indication about case, Wi-Fi antennas or power supply either, so most likely they are not included.
Their store.sipeed.com website does not work at all, and their Taobao and AliExpress stores are not public and only accessible to registered users. The order page also says nothing about shipping time, delivery time, or taxes. The X account @SipeedIO is active and recently posted pictures of shipments in progress.
Documentation and support
The main documentation wiki does not yet have any K3 content at the time of writing. There is a Discord channel for general RISC-V discussion, and their MaixHub also has a discussion board, but I didn t find anything K3-specific.
Community size and open source involvement
Sipeed has had at least one of their previous devices certified by Canonical, which indicates they are active in the community.
Note that the other RISC-V company SiFive that also has had hardware certified and officially supported by Canonical is a different company, despite the very similar name.
Banana Pi
Banana Pi announced that they offer both the K3 CoM260 kit and the K3 pico-ITX motherboard version. Their product page for the K3 confusingly shows a MediaTek product in the page banner rather than the SpacemiT K3. Based on the product description and the fact they renamed the product as BPI-SM10, it seems to ship with some carrier board. The product pictures look identical to the SpacemiT documentation and there is no picture of the carrier board, and details are very sparse. The pico-ITX version with 8 GB RAM and 128 GB SSD sells for 293 USD and the CoM260 developer kit with the same specs sells for 287 USD and the 32 GB RAM with 128 GB SSD model sells for 595 USD. The shop page shows only five orders so far and items are currently out of stock. As there was no 32 GB RAM version of the pico-ITX available at all, this isn t an option for me as I want to run 30B parameter models that need the larger memory version.
Of all of these resellers, the Banana Pi website seems the most outdated. It does not have a search feature, it is not mobile-friendly, pictures can t be pinched to zoom in and so forth. Product names are also almost all identical, and as the product listings only show the beginning of the product name, figuring out what product is what requires extra effort that just makes the online purchase experience plain bad.
Documentation and support
I was only able to find the documentation page for the CoM260 kit, but none for the pico-ITX version. For support there is a forum, but the category list does not show any section for K3, and the forum search prohibits using the search term k3 as too short.
Community size and open source involvement
Banana Pi has a long history in the ARM single-board computer market, but their presence in the RISC-V ecosystem is still growing. Their X account @sinovoip has posted only once about the K3 and otherwise promotes their ARM boards. However, their community culture page does express a commitment to open hardware in general, but there is no visible K3-specific community activity.
Firefly
Firefly s K3 product page is comprehensive. Based on the details, they do not offer the K3 pico-ITX variant at all, but only the K3 CoM260 board inside the AIBOX-K3 Firefly RISC-V Edge Mini PC product. This is a feature-complete offering with a Jetson Orin Nano carrier board and case. The AIBOX-K3 with 32 GB RAM and 128 GB SSD in a case sells for 689 USD in their own Firefly.store. Unfortunately it only has HDMI and there is no USB-C with DisplayPort support, which is a deal-breaker for me personally.
Interestingly, Firefly also offers rack-mounted servers with K3 as the CPU.
Documentation and support
The wiki link on the product page is broken. The Firefly wiki does have a section for the AIBOX-K3, but it too has a broken link. It seems that as of the time of writing, there is no wiki section for this product yet.
For support there is a web forum, which does have at least one K3 thread covering guides such as Hermes Agent installation, though broader K3-specific sections are still sparse.
Community size and open source involvement
Firefly s X account @TeeFirefly has had no posts since 2024, and their GitLab/T-Firefly shows mostly 2024 activity, with only one repository updated in 2025 and nothing in 2026. Historically they have built a moderate community around their ARM-based Rockchip boards, with active forums and wiki contributions for those product lines. Their RISC-V K3 offerings are newer, and likely need a lot more polish to be attractive products overall.
DeepComputing
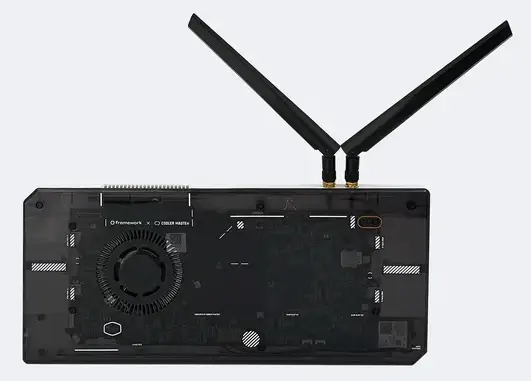
Last, but certainly not least, is the laptop manufacturer DeepComputing that offers a Framework laptop compatible motherboard with the SpacemiT K3 chip. They also sell the plain motherboard, or with the Cooler Master case, which allows one to easily connect it to an external monitor and keyboard and use it as a desktop computer. The plain board with 32 GB RAM and no SSD sells for about 882 EUR. Shipping of the first batch is expected to start by end of June 2026. Their X account @DeepComputingio promotes this DC-ROMA RISC-V Mainboard III as their flagship product, so they seem to put a lot of effort into it.
The overall product design and packaging seems good. Of all the K3 resellers and integrators that I was able to find, DeepComputing is the only one that actually designs their own boards with the K3 processor, while all the other vendors above are simply reselling the vanilla K3 boards with or without a case.
After reviewing all these options I decided to buy the DC-ROMA RISC-V Mainboard III for Framework Laptop 13 with 32 GB RAM, 1 TB SSD and the Cooler Master case, totalling about 1100 EUR.
Documentation and support
DeepComputing maintains product information for their RISC-V hardware at github.com/DC-DeepComputing/Framework, with documentation of the newest Mainboard III (FML13V05) still being finalized ahead of the first batch shipment. They provide community support through Discord and web forum, although the latter has very little activity.
Community size and open source involvement
DeepComputing has established itself as a pioneer in RISC-V laptops, beginning with the DC-ROMA. I have seen their stand at FOSDEM, which shows they are genuinely active in the open source community. Canonical lists DeepComputing s first mainboard / FML13V01 on its official Ubuntu for RISC-V partner-built hardware page, and it seems likely that they will continue to collaborate with Canonical with the new model once it ships. While the underlying Linux enablement depends on SpacemiT s upstream efforts, DeepComputing s involvement helps bridge the gap between reference hardware and consumer-ready products.
Conclusion
After weighing all the options, I ended up placing an order with DeepComputing for their custom K3 board with the Cooler Master case. Despite the premium price, the active community support and the properly documented promise of a complete, working system made it easy to place an order with confidence.
The SpacemiT K3 is poised to be one of the most significant RISC-V chips for local AI workloads, thanks to its RVA23 compliance and high tokens per second potential. Yet the buying experience in mid-2026 remains fragmented and incomplete. Hopefully this is just because the product is new, and they will get the purchase experience polished soon.
What struck me most during this process was how poor the customer experience is across nearly all of these vendor websites: broken links, missing search functions, outdated product banners, pages that show the wrong product entirely, and no information about shipping times, stock levels, taxes, and so on. One wonders why these companies don t fully invest in their web presence.
Personally I would assume they likely have enough customers already, primarily through domestic channels like Taobao and JD.com, that they do not feel any pressure to improve their international-facing sites. However, I did also review what was offered on Taobao, and the product details were very incomplete there too. Taobao, however, has a built-in live chat with almost all sellers, which can be used to ask questions and thus compensate for missing product details.
I don t fully understand why the sales process seems unpolished. The websites feel almost like an afterthought a checkbox to claim global reach while the real business apparently happens elsewhere via closed platforms or via inaccessible reseller channels. It is a frustrating reminder that in the RISC-V hardware world, the technology may be open and global, but the purchase experience is less so.
Documentation and support
As of this writing, the Milk-V Jupiter2 documentation site is just a stub and has no actual content, and only two links to the SpacemiT K3 documentation site. For support there is a web forum with a dedicated Jupiter2 section. There is also a Matrix space, but unlike their other products, there is no dedicated Jupiter (neither v1 nor v2) channel.
Community size and open source involvement
At least one prior Milk-V product was certified by Canonical, which indicates there is some collaboration in progress. Canonical also lists the Milk-V Titan on its official Ubuntu for RISC-V partner-built hardware page.
Sipeed
The Sipeed K3 announcement is well written (in English) with all the relevant details and links to additional PDF manuals. However, their main page at sipeed.com says nothing about the K3, so one must know the subpage URL to access it. They offer both the K3 CoM260 kit compatible with Jetson Orin Nano carrier boards, and the stand-alone K3 pico-ITX-sized motherboard. The CoM260 kit is only 10 USD cheaper than the full pico-ITX motherboard, so choosing the latter is a no-brainer if starting from scratch. The pico-ITX model with 32 GB DDR5 RAM sells for 639 USD. The product page does not mention anything about hard disk size, so you don t really know exactly what you will be getting if placing an order. There is no indication about case, Wi-Fi antennas or power supply either, so most likely they are not included.
Their store.sipeed.com website does not work at all, and their Taobao and AliExpress stores are not public and only accessible to registered users. The order page also says nothing about shipping time, delivery time, or taxes. The X account @SipeedIO is active and recently posted pictures of shipments in progress.
Documentation and support
The main documentation wiki does not yet have any K3 content at the time of writing. There is a Discord channel for general RISC-V discussion, and their MaixHub also has a discussion board, but I didn t find anything K3-specific.
Community size and open source involvement
Sipeed has had at least one of their previous devices certified by Canonical, which indicates they are active in the community.
Note that the other RISC-V company SiFive that also has had hardware certified and officially supported by Canonical is a different company, despite the very similar name.
Banana Pi
Banana Pi announced that they offer both the K3 CoM260 kit and the K3 pico-ITX motherboard version. Their product page for the K3 confusingly shows a MediaTek product in the page banner rather than the SpacemiT K3. Based on the product description and the fact they renamed the product as BPI-SM10, it seems to ship with some carrier board. The product pictures look identical to the SpacemiT documentation and there is no picture of the carrier board, and details are very sparse. The pico-ITX version with 8 GB RAM and 128 GB SSD sells for 293 USD and the CoM260 developer kit with the same specs sells for 287 USD and the 32 GB RAM with 128 GB SSD model sells for 595 USD. The shop page shows only five orders so far and items are currently out of stock. As there was no 32 GB RAM version of the pico-ITX available at all, this isn t an option for me as I want to run 30B parameter models that need the larger memory version.
Of all of these resellers, the Banana Pi website seems the most outdated. It does not have a search feature, it is not mobile-friendly, pictures can t be pinched to zoom in and so forth. Product names are also almost all identical, and as the product listings only show the beginning of the product name, figuring out what product is what requires extra effort that just makes the online purchase experience plain bad.
Documentation and support
I was only able to find the documentation page for the CoM260 kit, but none for the pico-ITX version. For support there is a forum, but the category list does not show any section for K3, and the forum search prohibits using the search term k3 as too short.
Community size and open source involvement
Banana Pi has a long history in the ARM single-board computer market, but their presence in the RISC-V ecosystem is still growing. Their X account @sinovoip has posted only once about the K3 and otherwise promotes their ARM boards. However, their community culture page does express a commitment to open hardware in general, but there is no visible K3-specific community activity.
Firefly
Firefly s K3 product page is comprehensive. Based on the details, they do not offer the K3 pico-ITX variant at all, but only the K3 CoM260 board inside the AIBOX-K3 Firefly RISC-V Edge Mini PC product. This is a feature-complete offering with a Jetson Orin Nano carrier board and case. The AIBOX-K3 with 32 GB RAM and 128 GB SSD in a case sells for 689 USD in their own Firefly.store. Unfortunately it only has HDMI and there is no USB-C with DisplayPort support, which is a deal-breaker for me personally.
Interestingly, Firefly also offers rack-mounted servers with K3 as the CPU.
Documentation and support
The wiki link on the product page is broken. The Firefly wiki does have a section for the AIBOX-K3, but it too has a broken link. It seems that as of the time of writing, there is no wiki section for this product yet.
For support there is a web forum, which does have at least one K3 thread covering guides such as Hermes Agent installation, though broader K3-specific sections are still sparse.
Community size and open source involvement
Firefly s X account @TeeFirefly has had no posts since 2024, and their GitLab/T-Firefly shows mostly 2024 activity, with only one repository updated in 2025 and nothing in 2026. Historically they have built a moderate community around their ARM-based Rockchip boards, with active forums and wiki contributions for those product lines. Their RISC-V K3 offerings are newer, and likely need a lot more polish to be attractive products overall.
DeepComputing
Last, but certainly not least, is the laptop manufacturer DeepComputing that offers a Framework laptop compatible motherboard with the SpacemiT K3 chip. They also sell the plain motherboard, or with the Cooler Master case, which allows one to easily connect it to an external monitor and keyboard and use it as a desktop computer. The plain board with 32 GB RAM and no SSD sells for about 882 EUR. Shipping of the first batch is expected to start by end of June 2026. Their X account @DeepComputingio promotes this DC-ROMA RISC-V Mainboard III as their flagship product, so they seem to put a lot of effort into it.
The overall product design and packaging seems good. Of all the K3 resellers and integrators that I was able to find, DeepComputing is the only one that actually designs their own boards with the K3 processor, while all the other vendors above are simply reselling the vanilla K3 boards with or without a case.
After reviewing all these options I decided to buy the DC-ROMA RISC-V Mainboard III for Framework Laptop 13 with 32 GB RAM, 1 TB SSD and the Cooler Master case, totalling about 1100 EUR.
Documentation and support
DeepComputing maintains product information for their RISC-V hardware at github.com/DC-DeepComputing/Framework, with documentation of the newest Mainboard III (FML13V05) still being finalized ahead of the first batch shipment. They provide community support through Discord and web forum, although the latter has very little activity.
Community size and open source involvement
DeepComputing has established itself as a pioneer in RISC-V laptops, beginning with the DC-ROMA. I have seen their stand at FOSDEM, which shows they are genuinely active in the open source community. Canonical lists DeepComputing s first mainboard / FML13V01 on its official Ubuntu for RISC-V partner-built hardware page, and it seems likely that they will continue to collaborate with Canonical with the new model once it ships. While the underlying Linux enablement depends on SpacemiT s upstream efforts, DeepComputing s involvement helps bridge the gap between reference hardware and consumer-ready products.
Conclusion
After weighing all the options, I ended up placing an order with DeepComputing for their custom K3 board with the Cooler Master case. Despite the premium price, the active community support and the properly documented promise of a complete, working system made it easy to place an order with confidence.
The SpacemiT K3 is poised to be one of the most significant RISC-V chips for local AI workloads, thanks to its RVA23 compliance and high tokens per second potential. Yet the buying experience in mid-2026 remains fragmented and incomplete. Hopefully this is just because the product is new, and they will get the purchase experience polished soon.
What struck me most during this process was how poor the customer experience is across nearly all of these vendor websites: broken links, missing search functions, outdated product banners, pages that show the wrong product entirely, and no information about shipping times, stock levels, taxes, and so on. One wonders why these companies don t fully invest in their web presence.
Personally I would assume they likely have enough customers already, primarily through domestic channels like Taobao and JD.com, that they do not feel any pressure to improve their international-facing sites. However, I did also review what was offered on Taobao, and the product details were very incomplete there too. Taobao, however, has a built-in live chat with almost all sellers, which can be used to ask questions and thus compensate for missing product details.
I don t fully understand why the sales process seems unpolished. The websites feel almost like an afterthought a checkbox to claim global reach while the real business apparently happens elsewhere via closed platforms or via inaccessible reseller channels. It is a frustrating reminder that in the RISC-V hardware world, the technology may be open and global, but the purchase experience is less so.
Community size and open source involvement
Sipeed has had at least one of their previous devices certified by Canonical, which indicates they are active in the community.
Note that the other RISC-V company SiFive that also has had hardware certified and officially supported by Canonical is a different company, despite the very similar name.
Banana Pi
Banana Pi announced that they offer both the K3 CoM260 kit and the K3 pico-ITX motherboard version. Their product page for the K3 confusingly shows a MediaTek product in the page banner rather than the SpacemiT K3. Based on the product description and the fact they renamed the product as BPI-SM10, it seems to ship with some carrier board. The product pictures look identical to the SpacemiT documentation and there is no picture of the carrier board, and details are very sparse. The pico-ITX version with 8 GB RAM and 128 GB SSD sells for 293 USD and the CoM260 developer kit with the same specs sells for 287 USD and the 32 GB RAM with 128 GB SSD model sells for 595 USD. The shop page shows only five orders so far and items are currently out of stock. As there was no 32 GB RAM version of the pico-ITX available at all, this isn t an option for me as I want to run 30B parameter models that need the larger memory version.
Of all of these resellers, the Banana Pi website seems the most outdated. It does not have a search feature, it is not mobile-friendly, pictures can t be pinched to zoom in and so forth. Product names are also almost all identical, and as the product listings only show the beginning of the product name, figuring out what product is what requires extra effort that just makes the online purchase experience plain bad.
Documentation and support
I was only able to find the documentation page for the CoM260 kit, but none for the pico-ITX version. For support there is a forum, but the category list does not show any section for K3, and the forum search prohibits using the search term k3 as too short.
Community size and open source involvement
Banana Pi has a long history in the ARM single-board computer market, but their presence in the RISC-V ecosystem is still growing. Their X account @sinovoip has posted only once about the K3 and otherwise promotes their ARM boards. However, their community culture page does express a commitment to open hardware in general, but there is no visible K3-specific community activity.
Firefly
Firefly s K3 product page is comprehensive. Based on the details, they do not offer the K3 pico-ITX variant at all, but only the K3 CoM260 board inside the AIBOX-K3 Firefly RISC-V Edge Mini PC product. This is a feature-complete offering with a Jetson Orin Nano carrier board and case. The AIBOX-K3 with 32 GB RAM and 128 GB SSD in a case sells for 689 USD in their own Firefly.store. Unfortunately it only has HDMI and there is no USB-C with DisplayPort support, which is a deal-breaker for me personally.
Interestingly, Firefly also offers rack-mounted servers with K3 as the CPU.
Documentation and support
The wiki link on the product page is broken. The Firefly wiki does have a section for the AIBOX-K3, but it too has a broken link. It seems that as of the time of writing, there is no wiki section for this product yet.
For support there is a web forum, which does have at least one K3 thread covering guides such as Hermes Agent installation, though broader K3-specific sections are still sparse.
Community size and open source involvement
Firefly s X account @TeeFirefly has had no posts since 2024, and their GitLab/T-Firefly shows mostly 2024 activity, with only one repository updated in 2025 and nothing in 2026. Historically they have built a moderate community around their ARM-based Rockchip boards, with active forums and wiki contributions for those product lines. Their RISC-V K3 offerings are newer, and likely need a lot more polish to be attractive products overall.
DeepComputing
Last, but certainly not least, is the laptop manufacturer DeepComputing that offers a Framework laptop compatible motherboard with the SpacemiT K3 chip. They also sell the plain motherboard, or with the Cooler Master case, which allows one to easily connect it to an external monitor and keyboard and use it as a desktop computer. The plain board with 32 GB RAM and no SSD sells for about 882 EUR. Shipping of the first batch is expected to start by end of June 2026. Their X account @DeepComputingio promotes this DC-ROMA RISC-V Mainboard III as their flagship product, so they seem to put a lot of effort into it.
The overall product design and packaging seems good. Of all the K3 resellers and integrators that I was able to find, DeepComputing is the only one that actually designs their own boards with the K3 processor, while all the other vendors above are simply reselling the vanilla K3 boards with or without a case.
After reviewing all these options I decided to buy the DC-ROMA RISC-V Mainboard III for Framework Laptop 13 with 32 GB RAM, 1 TB SSD and the Cooler Master case, totalling about 1100 EUR.
Documentation and support
DeepComputing maintains product information for their RISC-V hardware at github.com/DC-DeepComputing/Framework, with documentation of the newest Mainboard III (FML13V05) still being finalized ahead of the first batch shipment. They provide community support through Discord and web forum, although the latter has very little activity.
Community size and open source involvement
DeepComputing has established itself as a pioneer in RISC-V laptops, beginning with the DC-ROMA. I have seen their stand at FOSDEM, which shows they are genuinely active in the open source community. Canonical lists DeepComputing s first mainboard / FML13V01 on its official Ubuntu for RISC-V partner-built hardware page, and it seems likely that they will continue to collaborate with Canonical with the new model once it ships. While the underlying Linux enablement depends on SpacemiT s upstream efforts, DeepComputing s involvement helps bridge the gap between reference hardware and consumer-ready products.
Conclusion
After weighing all the options, I ended up placing an order with DeepComputing for their custom K3 board with the Cooler Master case. Despite the premium price, the active community support and the properly documented promise of a complete, working system made it easy to place an order with confidence.
The SpacemiT K3 is poised to be one of the most significant RISC-V chips for local AI workloads, thanks to its RVA23 compliance and high tokens per second potential. Yet the buying experience in mid-2026 remains fragmented and incomplete. Hopefully this is just because the product is new, and they will get the purchase experience polished soon.
What struck me most during this process was how poor the customer experience is across nearly all of these vendor websites: broken links, missing search functions, outdated product banners, pages that show the wrong product entirely, and no information about shipping times, stock levels, taxes, and so on. One wonders why these companies don t fully invest in their web presence.
Personally I would assume they likely have enough customers already, primarily through domestic channels like Taobao and JD.com, that they do not feel any pressure to improve their international-facing sites. However, I did also review what was offered on Taobao, and the product details were very incomplete there too. Taobao, however, has a built-in live chat with almost all sellers, which can be used to ask questions and thus compensate for missing product details.
I don t fully understand why the sales process seems unpolished. The websites feel almost like an afterthought a checkbox to claim global reach while the real business apparently happens elsewhere via closed platforms or via inaccessible reseller channels. It is a frustrating reminder that in the RISC-V hardware world, the technology may be open and global, but the purchase experience is less so.
Documentation and support
I was only able to find the documentation page for the CoM260 kit, but none for the pico-ITX version. For support there is a forum, but the category list does not show any section for K3, and the forum search prohibits using the search term k3 as too short.
Community size and open source involvement
Banana Pi has a long history in the ARM single-board computer market, but their presence in the RISC-V ecosystem is still growing. Their X account @sinovoip has posted only once about the K3 and otherwise promotes their ARM boards. However, their community culture page does express a commitment to open hardware in general, but there is no visible K3-specific community activity.
Firefly
Firefly s K3 product page is comprehensive. Based on the details, they do not offer the K3 pico-ITX variant at all, but only the K3 CoM260 board inside the AIBOX-K3 Firefly RISC-V Edge Mini PC product. This is a feature-complete offering with a Jetson Orin Nano carrier board and case. The AIBOX-K3 with 32 GB RAM and 128 GB SSD in a case sells for 689 USD in their own Firefly.store. Unfortunately it only has HDMI and there is no USB-C with DisplayPort support, which is a deal-breaker for me personally.
Interestingly, Firefly also offers rack-mounted servers with K3 as the CPU.
Documentation and support
The wiki link on the product page is broken. The Firefly wiki does have a section for the AIBOX-K3, but it too has a broken link. It seems that as of the time of writing, there is no wiki section for this product yet.
For support there is a web forum, which does have at least one K3 thread covering guides such as Hermes Agent installation, though broader K3-specific sections are still sparse.
Community size and open source involvement
Firefly s X account @TeeFirefly has had no posts since 2024, and their GitLab/T-Firefly shows mostly 2024 activity, with only one repository updated in 2025 and nothing in 2026. Historically they have built a moderate community around their ARM-based Rockchip boards, with active forums and wiki contributions for those product lines. Their RISC-V K3 offerings are newer, and likely need a lot more polish to be attractive products overall.
DeepComputing
Last, but certainly not least, is the laptop manufacturer DeepComputing that offers a Framework laptop compatible motherboard with the SpacemiT K3 chip. They also sell the plain motherboard, or with the Cooler Master case, which allows one to easily connect it to an external monitor and keyboard and use it as a desktop computer. The plain board with 32 GB RAM and no SSD sells for about 882 EUR. Shipping of the first batch is expected to start by end of June 2026. Their X account @DeepComputingio promotes this DC-ROMA RISC-V Mainboard III as their flagship product, so they seem to put a lot of effort into it.
The overall product design and packaging seems good. Of all the K3 resellers and integrators that I was able to find, DeepComputing is the only one that actually designs their own boards with the K3 processor, while all the other vendors above are simply reselling the vanilla K3 boards with or without a case.
After reviewing all these options I decided to buy the DC-ROMA RISC-V Mainboard III for Framework Laptop 13 with 32 GB RAM, 1 TB SSD and the Cooler Master case, totalling about 1100 EUR.
Documentation and support
DeepComputing maintains product information for their RISC-V hardware at github.com/DC-DeepComputing/Framework, with documentation of the newest Mainboard III (FML13V05) still being finalized ahead of the first batch shipment. They provide community support through Discord and web forum, although the latter has very little activity.
Community size and open source involvement
DeepComputing has established itself as a pioneer in RISC-V laptops, beginning with the DC-ROMA. I have seen their stand at FOSDEM, which shows they are genuinely active in the open source community. Canonical lists DeepComputing s first mainboard / FML13V01 on its official Ubuntu for RISC-V partner-built hardware page, and it seems likely that they will continue to collaborate with Canonical with the new model once it ships. While the underlying Linux enablement depends on SpacemiT s upstream efforts, DeepComputing s involvement helps bridge the gap between reference hardware and consumer-ready products.
Conclusion
After weighing all the options, I ended up placing an order with DeepComputing for their custom K3 board with the Cooler Master case. Despite the premium price, the active community support and the properly documented promise of a complete, working system made it easy to place an order with confidence.
The SpacemiT K3 is poised to be one of the most significant RISC-V chips for local AI workloads, thanks to its RVA23 compliance and high tokens per second potential. Yet the buying experience in mid-2026 remains fragmented and incomplete. Hopefully this is just because the product is new, and they will get the purchase experience polished soon.
What struck me most during this process was how poor the customer experience is across nearly all of these vendor websites: broken links, missing search functions, outdated product banners, pages that show the wrong product entirely, and no information about shipping times, stock levels, taxes, and so on. One wonders why these companies don t fully invest in their web presence.
Personally I would assume they likely have enough customers already, primarily through domestic channels like Taobao and JD.com, that they do not feel any pressure to improve their international-facing sites. However, I did also review what was offered on Taobao, and the product details were very incomplete there too. Taobao, however, has a built-in live chat with almost all sellers, which can be used to ask questions and thus compensate for missing product details.
I don t fully understand why the sales process seems unpolished. The websites feel almost like an afterthought a checkbox to claim global reach while the real business apparently happens elsewhere via closed platforms or via inaccessible reseller channels. It is a frustrating reminder that in the RISC-V hardware world, the technology may be open and global, but the purchase experience is less so.
Community size and open source involvement
Firefly s X account @TeeFirefly has had no posts since 2024, and their GitLab/T-Firefly shows mostly 2024 activity, with only one repository updated in 2025 and nothing in 2026. Historically they have built a moderate community around their ARM-based Rockchip boards, with active forums and wiki contributions for those product lines. Their RISC-V K3 offerings are newer, and likely need a lot more polish to be attractive products overall.
DeepComputing
Last, but certainly not least, is the laptop manufacturer DeepComputing that offers a Framework laptop compatible motherboard with the SpacemiT K3 chip. They also sell the plain motherboard, or with the Cooler Master case, which allows one to easily connect it to an external monitor and keyboard and use it as a desktop computer. The plain board with 32 GB RAM and no SSD sells for about 882 EUR. Shipping of the first batch is expected to start by end of June 2026. Their X account @DeepComputingio promotes this DC-ROMA RISC-V Mainboard III as their flagship product, so they seem to put a lot of effort into it.
The overall product design and packaging seems good. Of all the K3 resellers and integrators that I was able to find, DeepComputing is the only one that actually designs their own boards with the K3 processor, while all the other vendors above are simply reselling the vanilla K3 boards with or without a case.
After reviewing all these options I decided to buy the DC-ROMA RISC-V Mainboard III for Framework Laptop 13 with 32 GB RAM, 1 TB SSD and the Cooler Master case, totalling about 1100 EUR.
Documentation and support
DeepComputing maintains product information for their RISC-V hardware at github.com/DC-DeepComputing/Framework, with documentation of the newest Mainboard III (FML13V05) still being finalized ahead of the first batch shipment. They provide community support through Discord and web forum, although the latter has very little activity.
Community size and open source involvement
DeepComputing has established itself as a pioneer in RISC-V laptops, beginning with the DC-ROMA. I have seen their stand at FOSDEM, which shows they are genuinely active in the open source community. Canonical lists DeepComputing s first mainboard / FML13V01 on its official Ubuntu for RISC-V partner-built hardware page, and it seems likely that they will continue to collaborate with Canonical with the new model once it ships. While the underlying Linux enablement depends on SpacemiT s upstream efforts, DeepComputing s involvement helps bridge the gap between reference hardware and consumer-ready products.
Conclusion
After weighing all the options, I ended up placing an order with DeepComputing for their custom K3 board with the Cooler Master case. Despite the premium price, the active community support and the properly documented promise of a complete, working system made it easy to place an order with confidence.
The SpacemiT K3 is poised to be one of the most significant RISC-V chips for local AI workloads, thanks to its RVA23 compliance and high tokens per second potential. Yet the buying experience in mid-2026 remains fragmented and incomplete. Hopefully this is just because the product is new, and they will get the purchase experience polished soon.
What struck me most during this process was how poor the customer experience is across nearly all of these vendor websites: broken links, missing search functions, outdated product banners, pages that show the wrong product entirely, and no information about shipping times, stock levels, taxes, and so on. One wonders why these companies don t fully invest in their web presence.
Personally I would assume they likely have enough customers already, primarily through domestic channels like Taobao and JD.com, that they do not feel any pressure to improve their international-facing sites. However, I did also review what was offered on Taobao, and the product details were very incomplete there too. Taobao, however, has a built-in live chat with almost all sellers, which can be used to ask questions and thus compensate for missing product details.
I don t fully understand why the sales process seems unpolished. The websites feel almost like an afterthought a checkbox to claim global reach while the real business apparently happens elsewhere via closed platforms or via inaccessible reseller channels. It is a frustrating reminder that in the RISC-V hardware world, the technology may be open and global, but the purchase experience is less so.


 It's been ten years since I configured
 This was a particularly busy month for me in terms of Debian
contributions.
It started with a week in Hamburg for the MiniDebConf. I talked to
many colleagues face-to-face and worked on various bugs and
maintenance tasks. I m pleased to have finally found the time to
reproduce and fix the
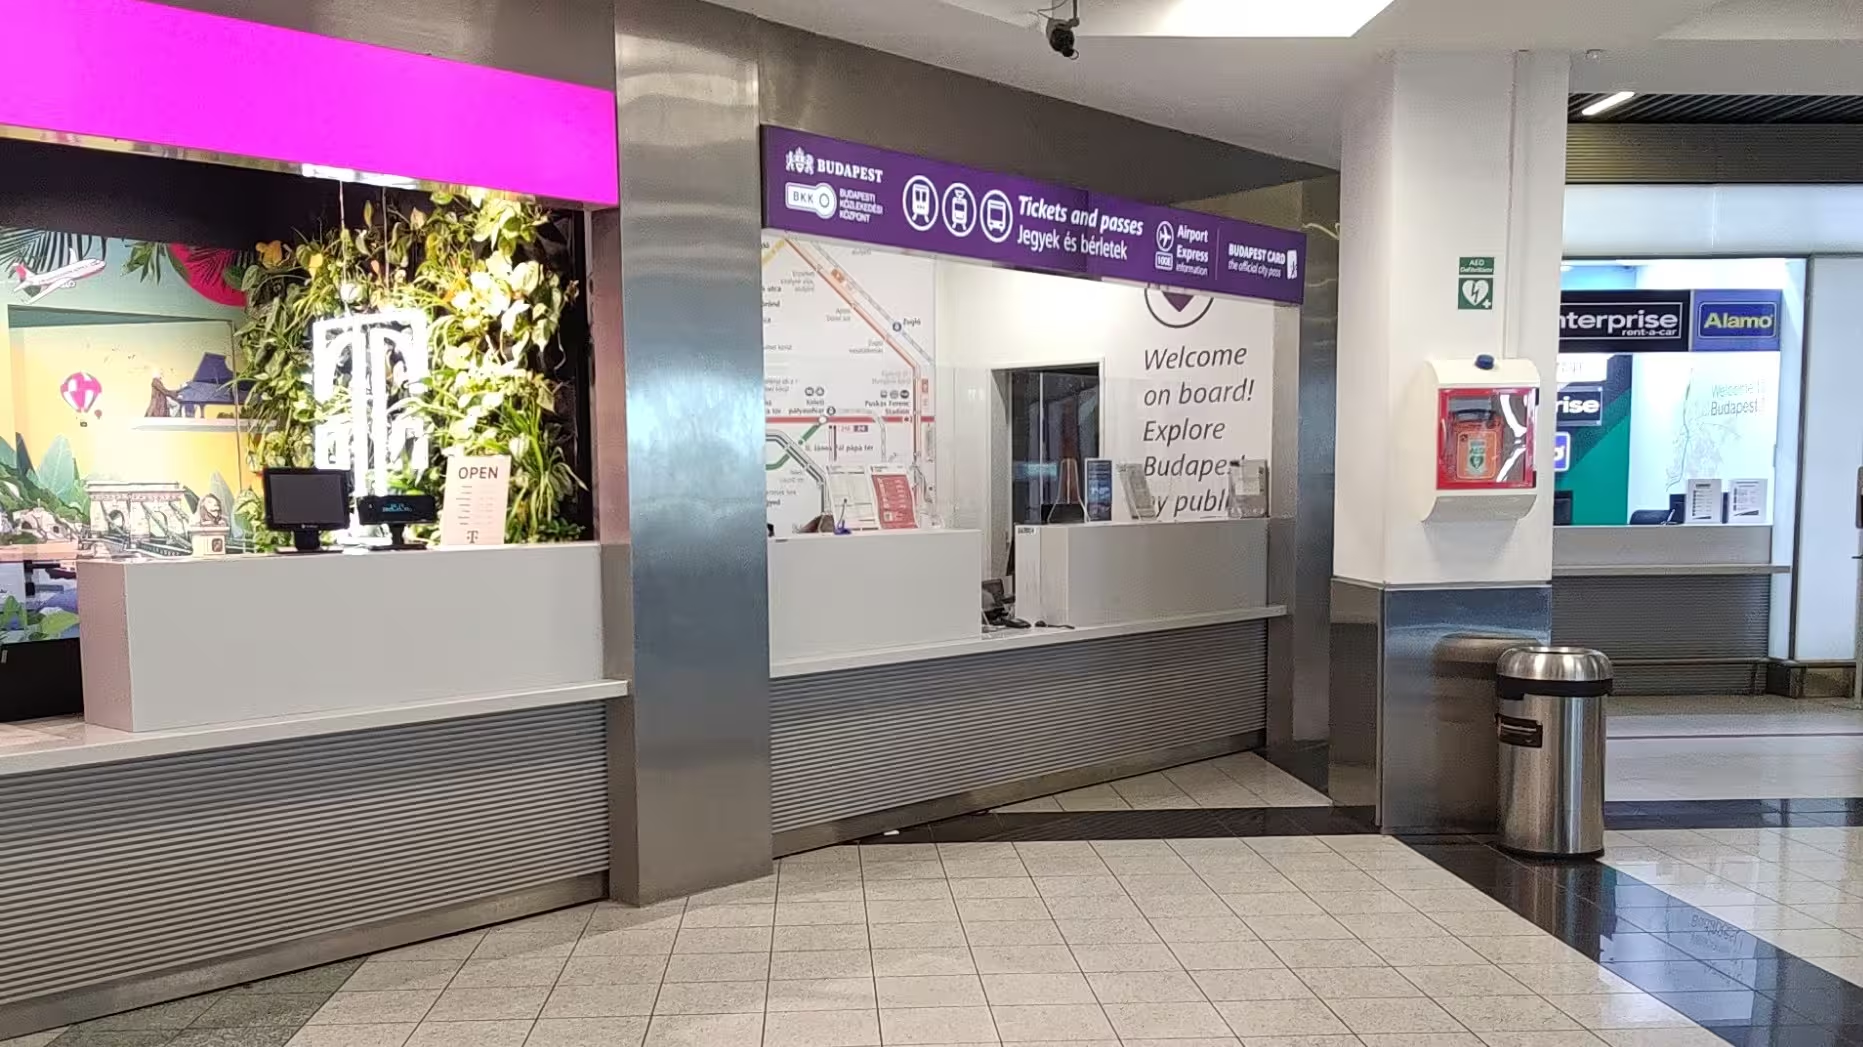 This is the counter from where I bought my public transport pass.
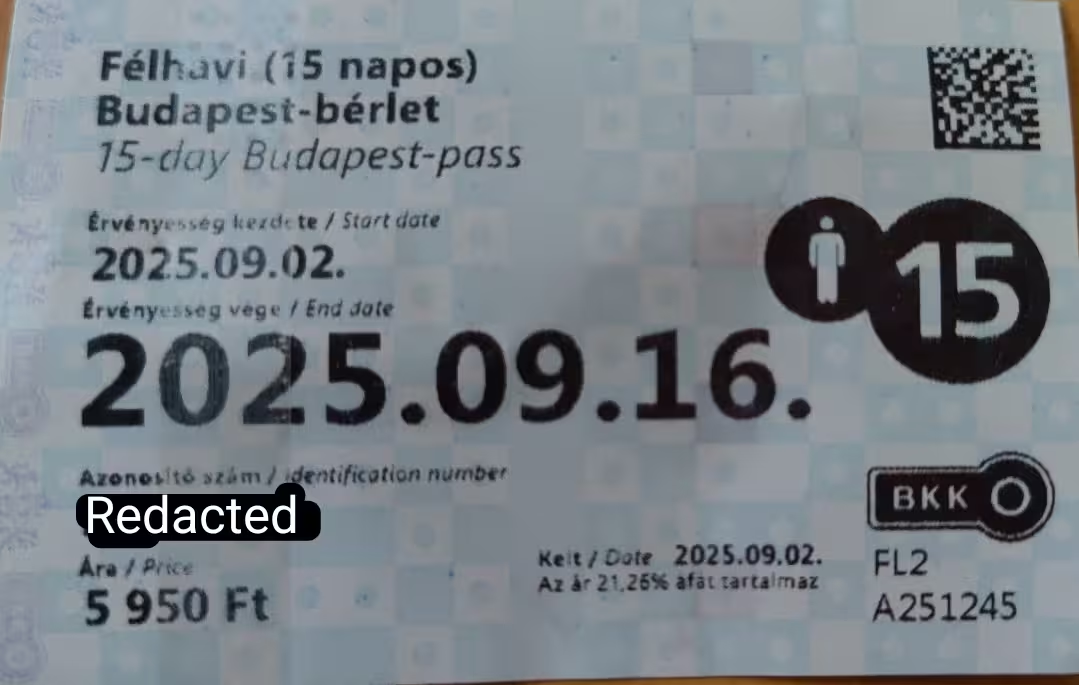 My unlimited public transport pass for Budapest. I have redacted my passport number from it.
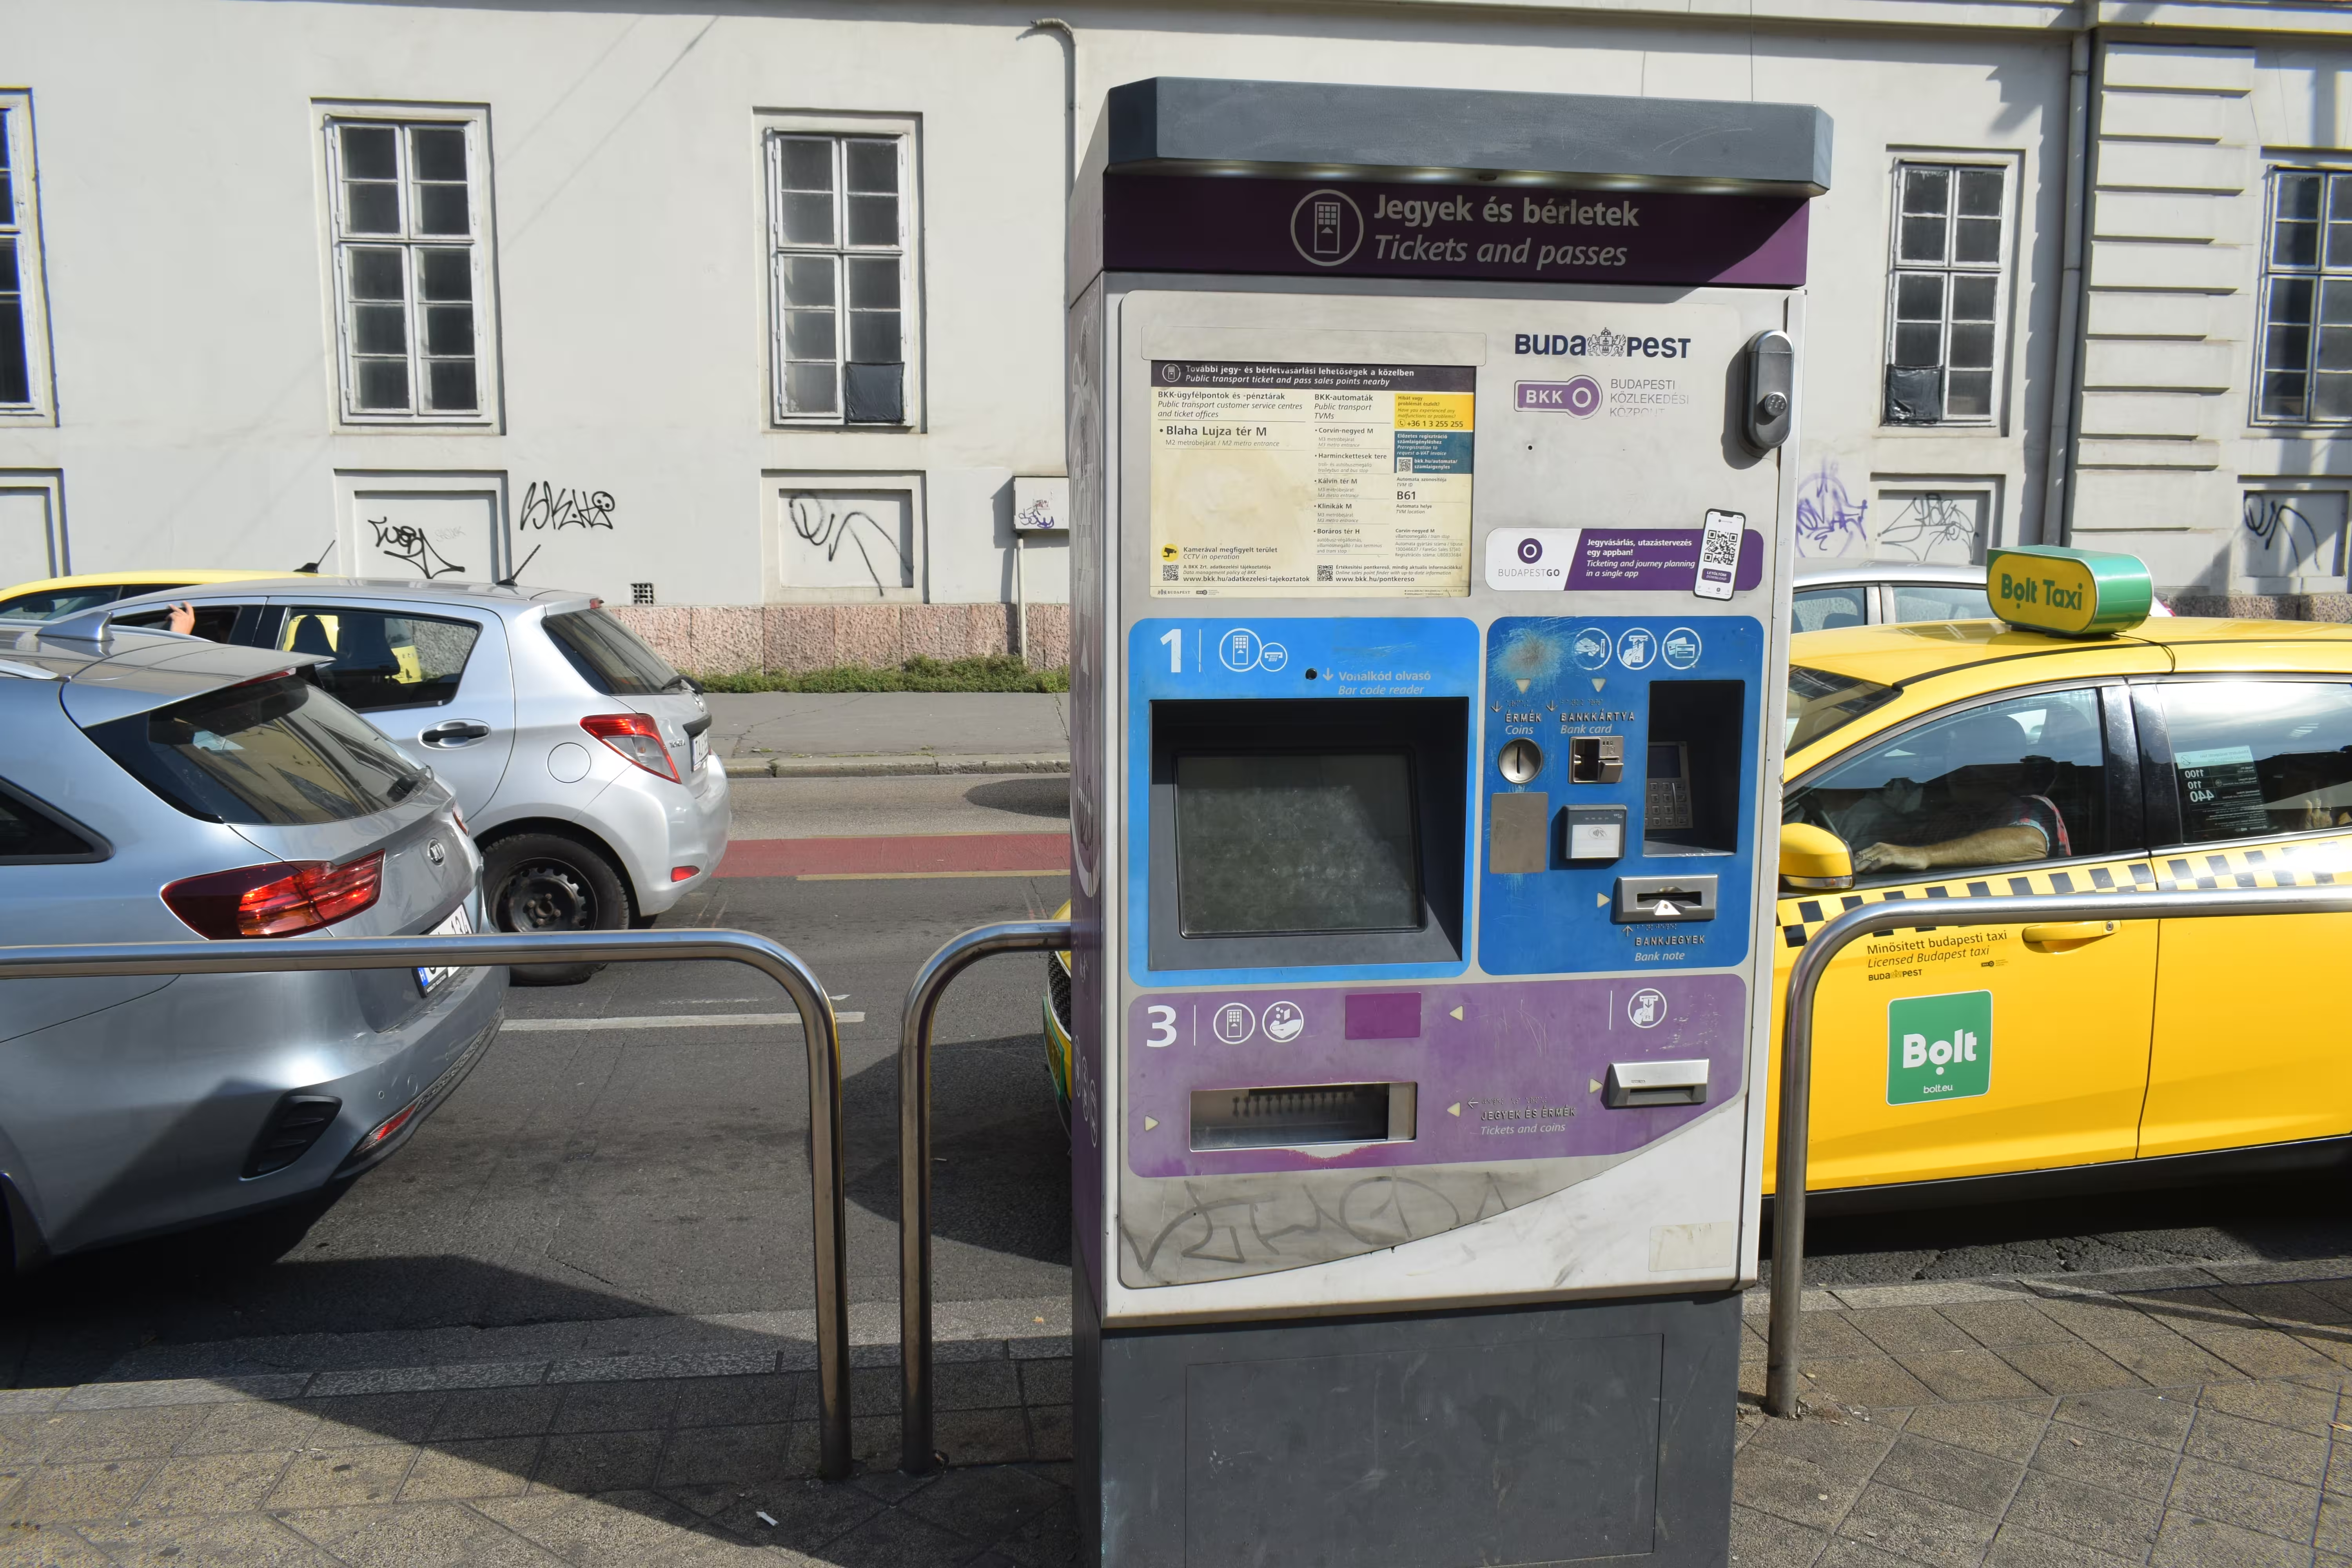 An automatic ticket machine at a tram station in Budapest.
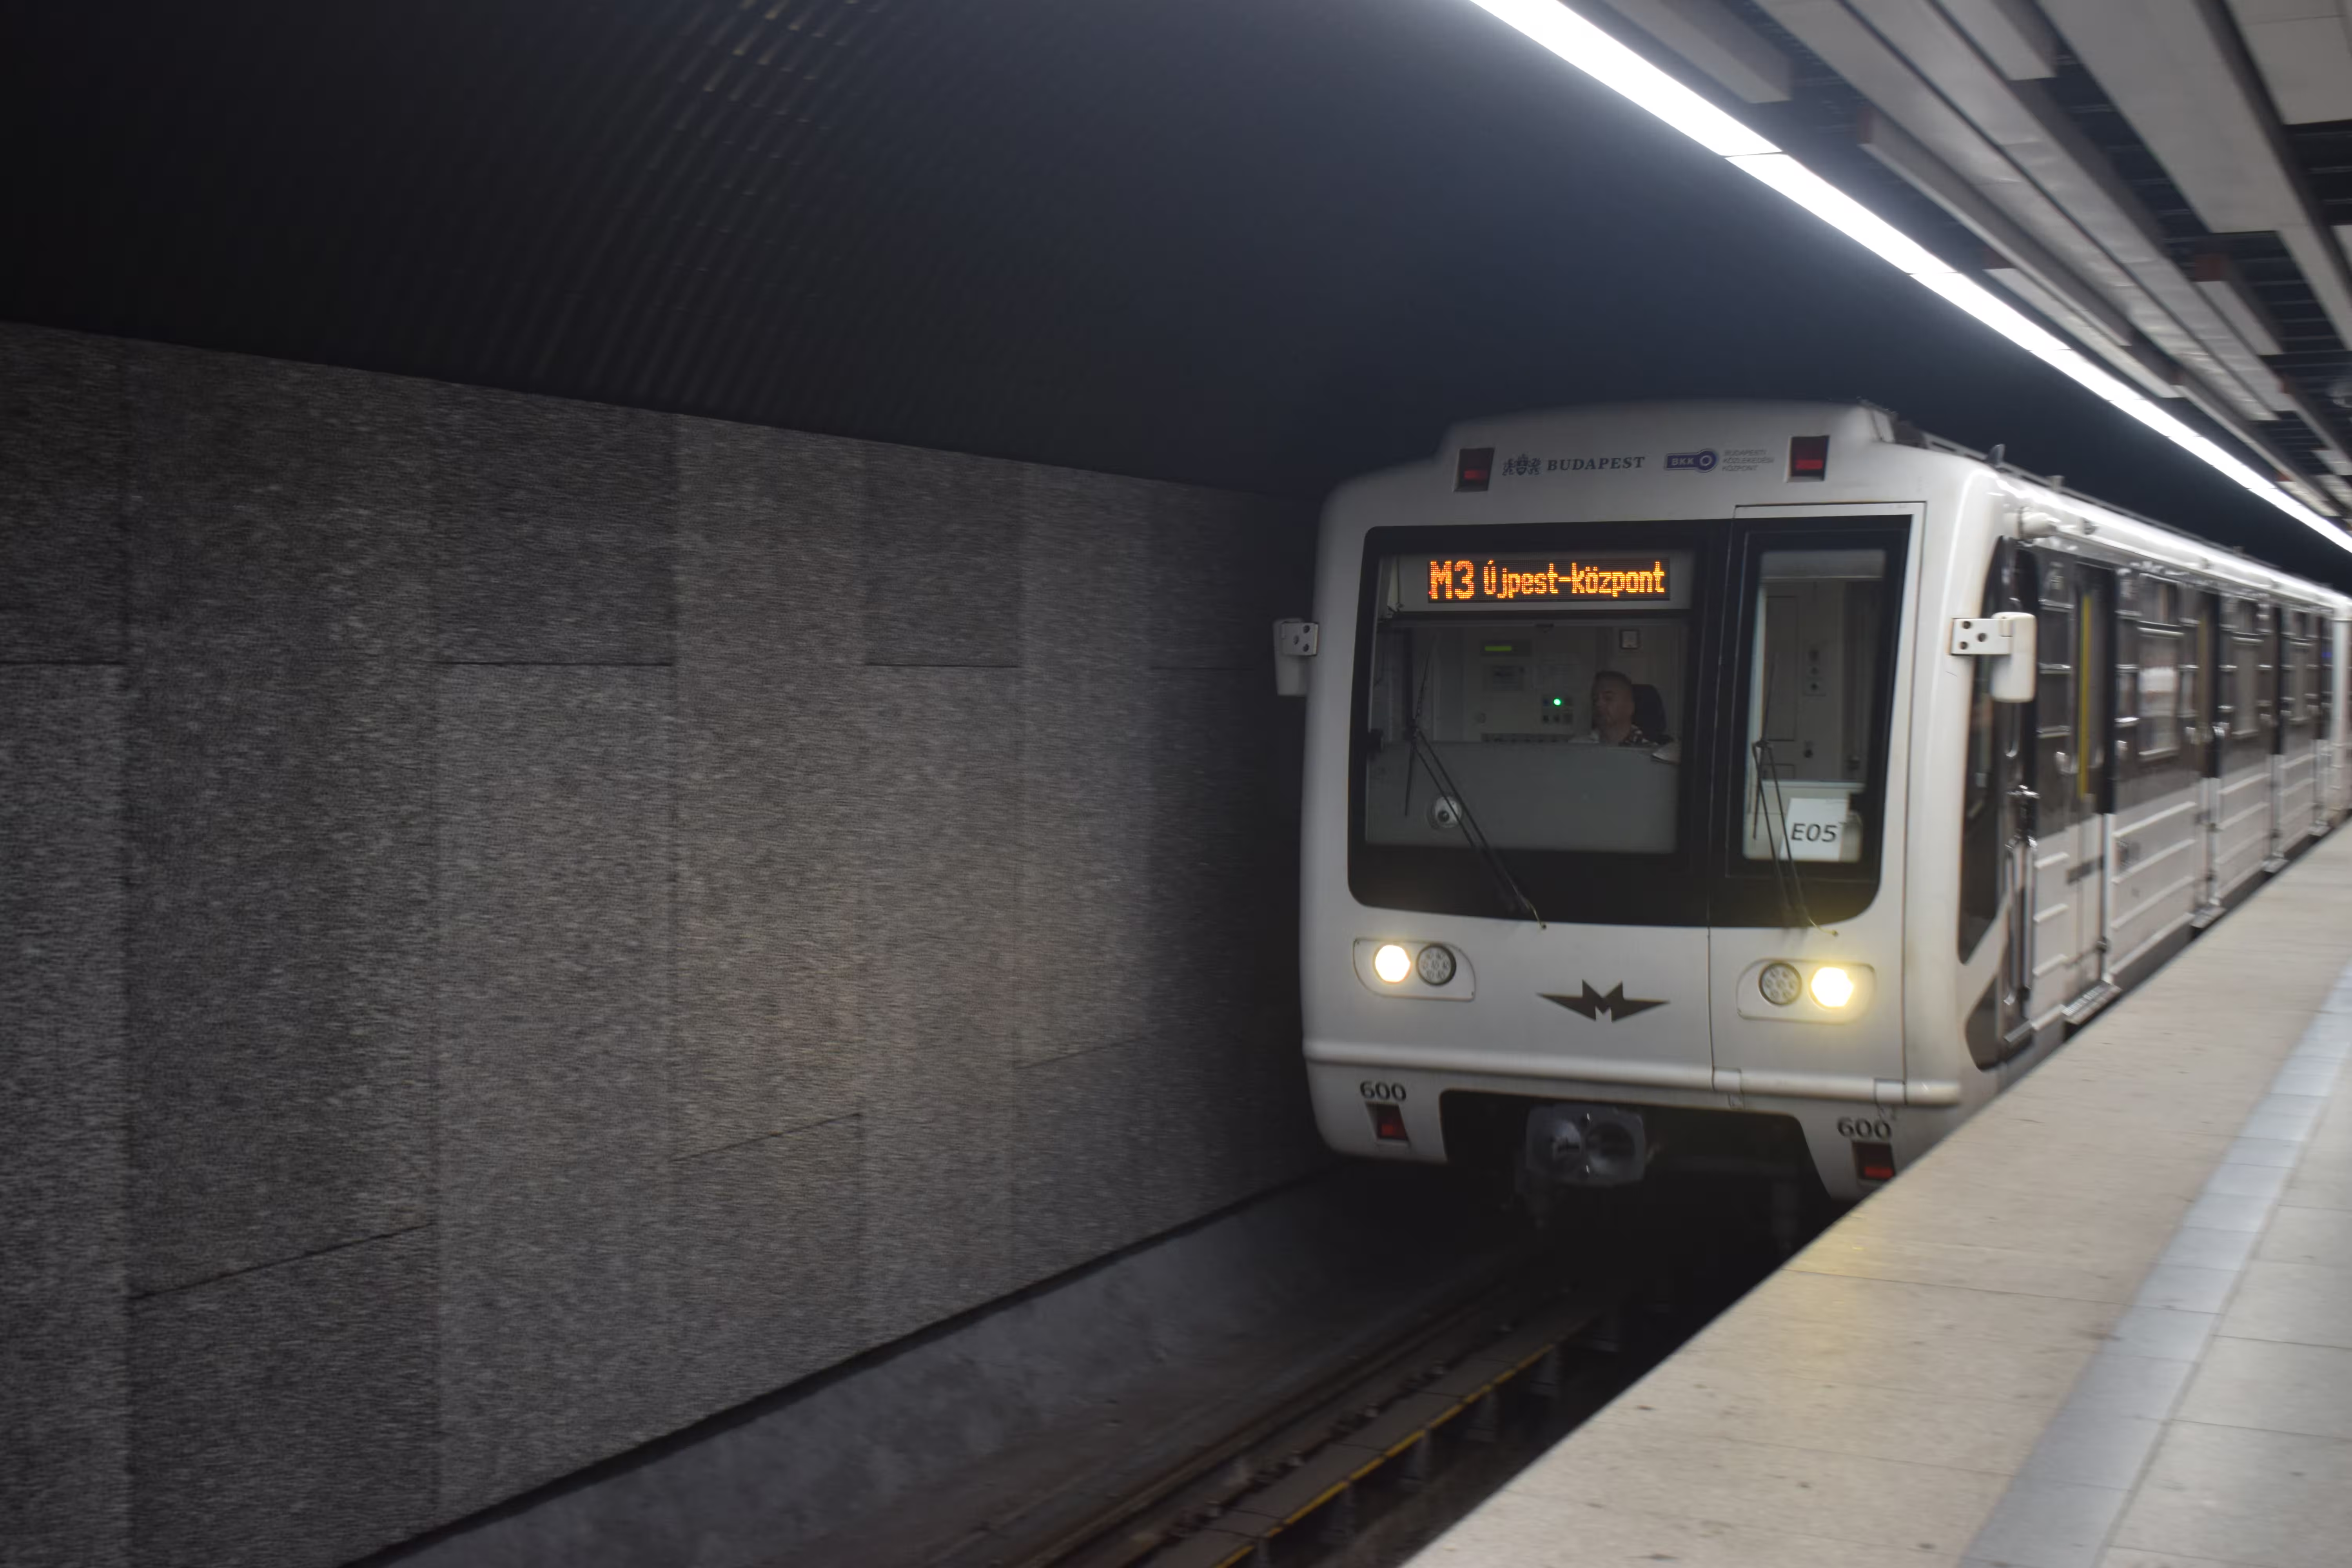 An M3 line metro in Budapest.
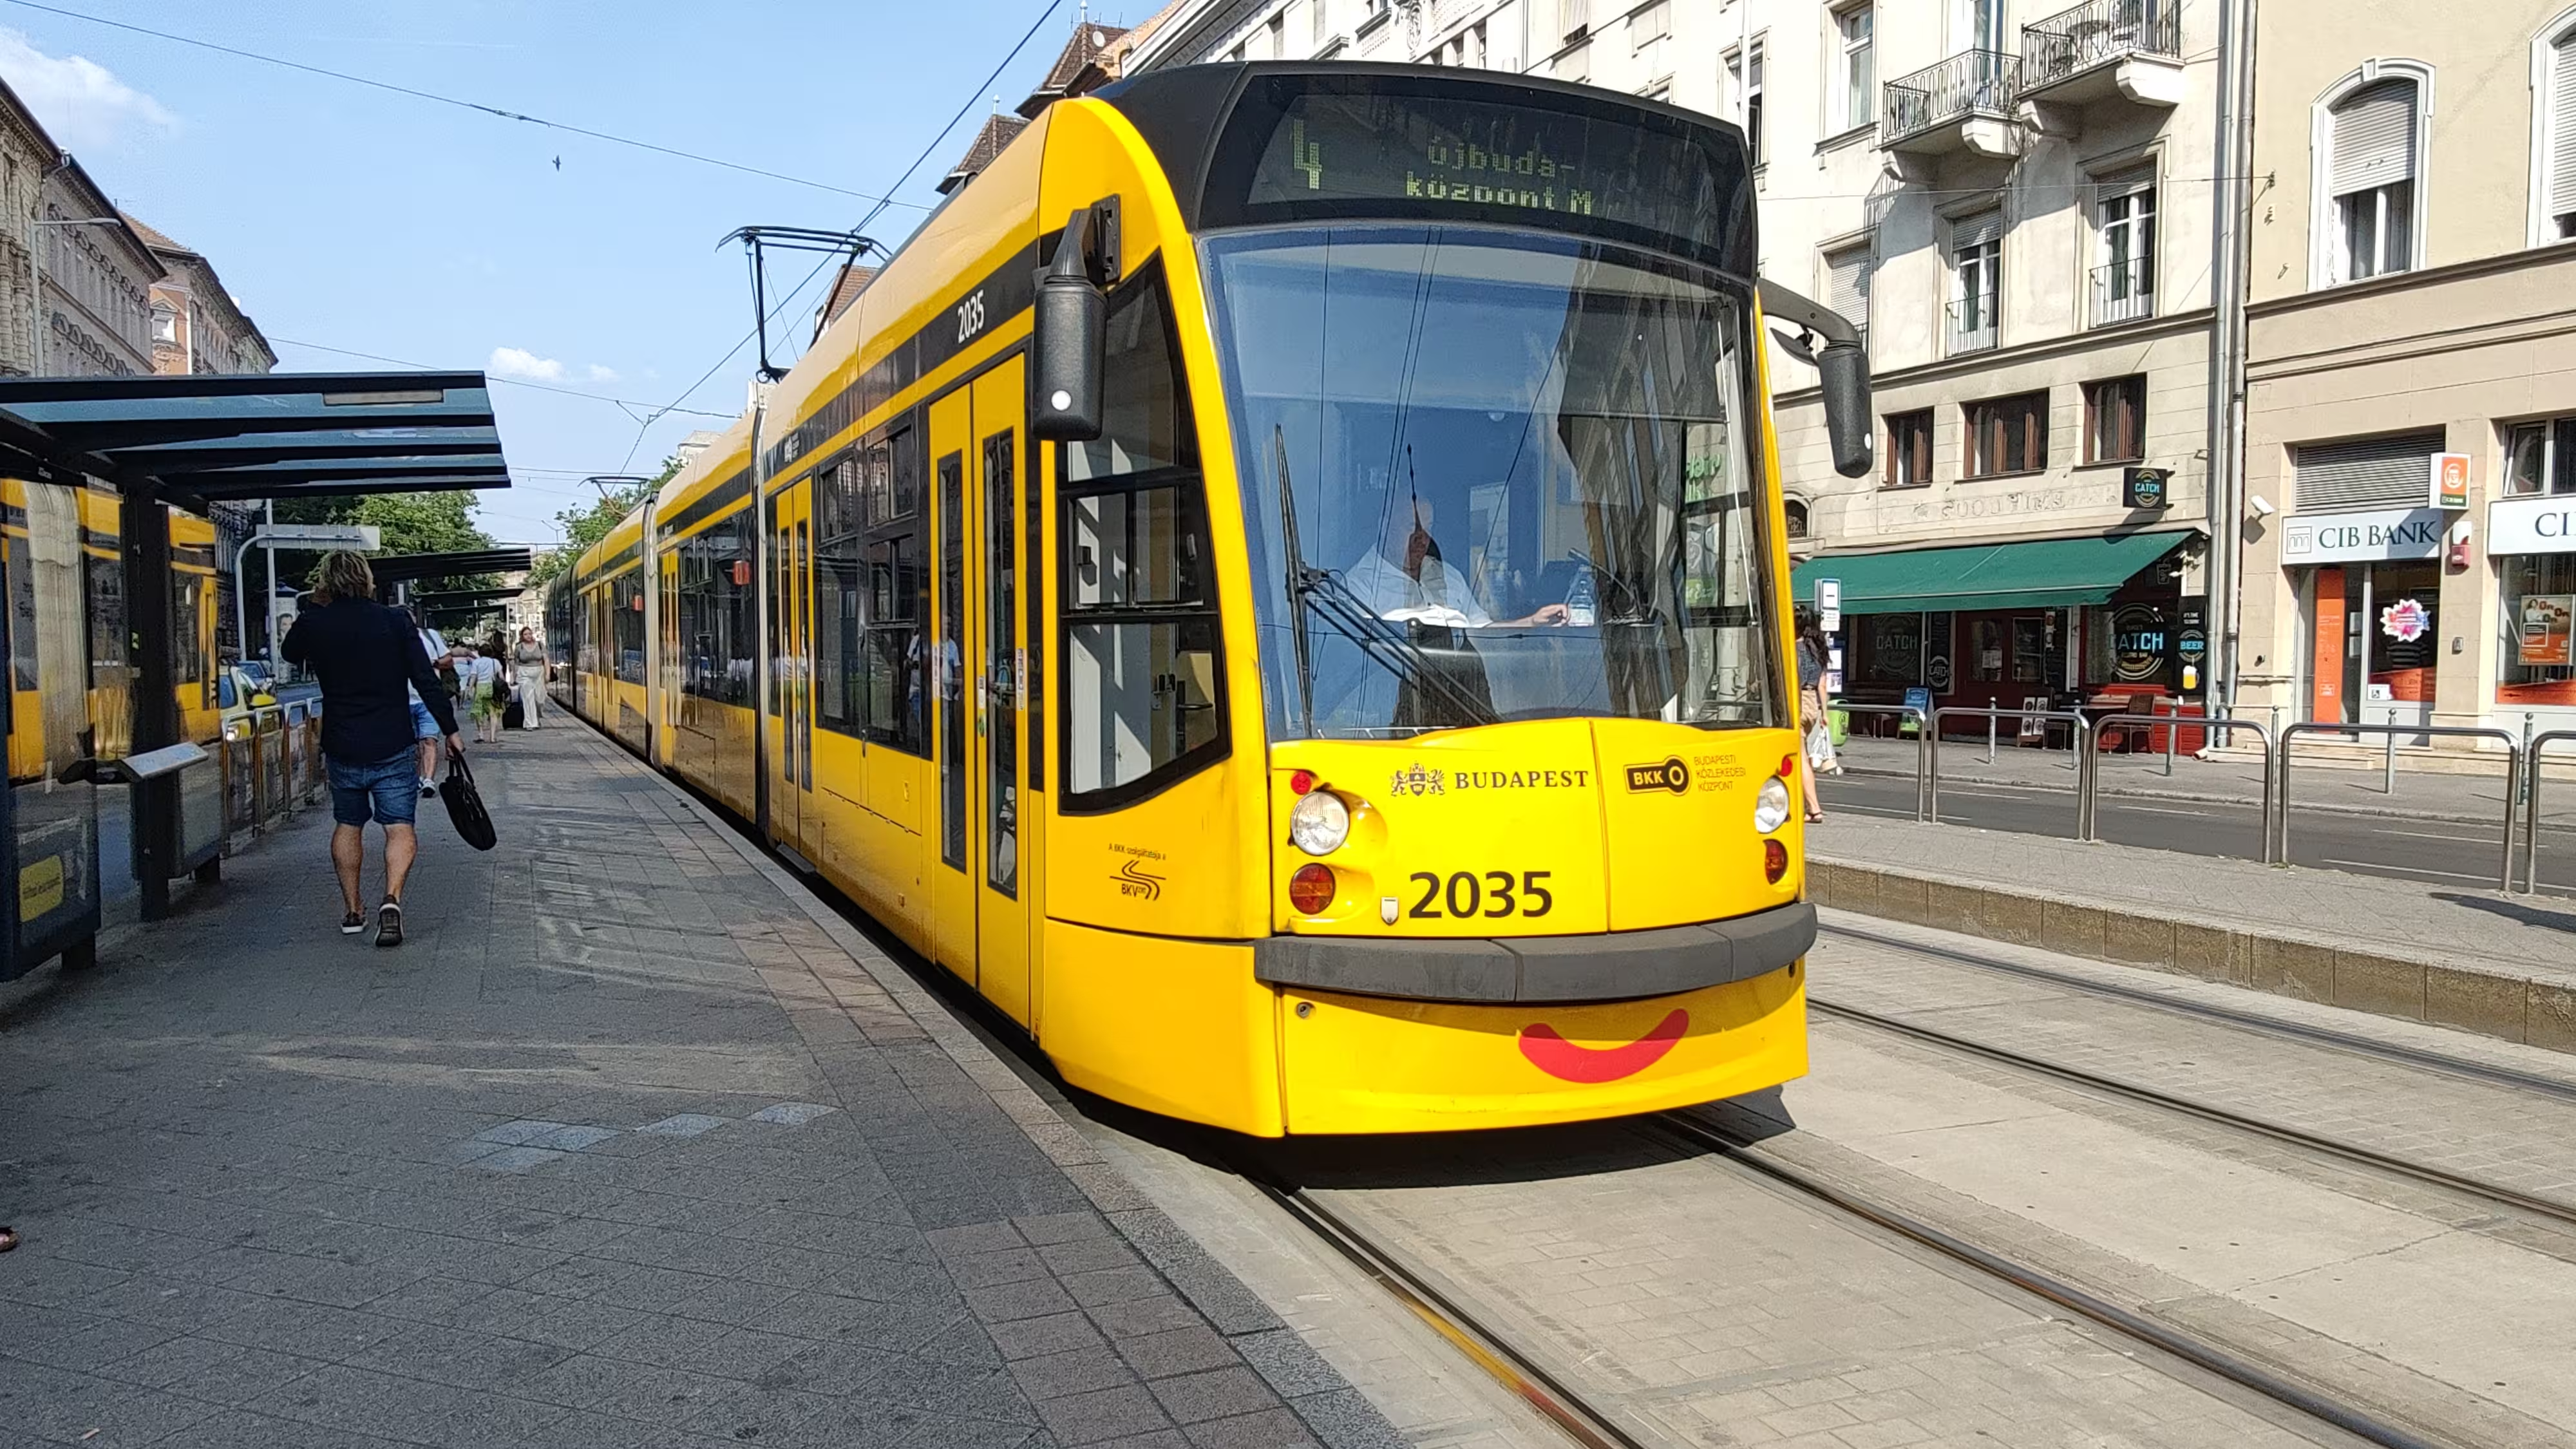 A tram in Budapest having a smiley face at the front.
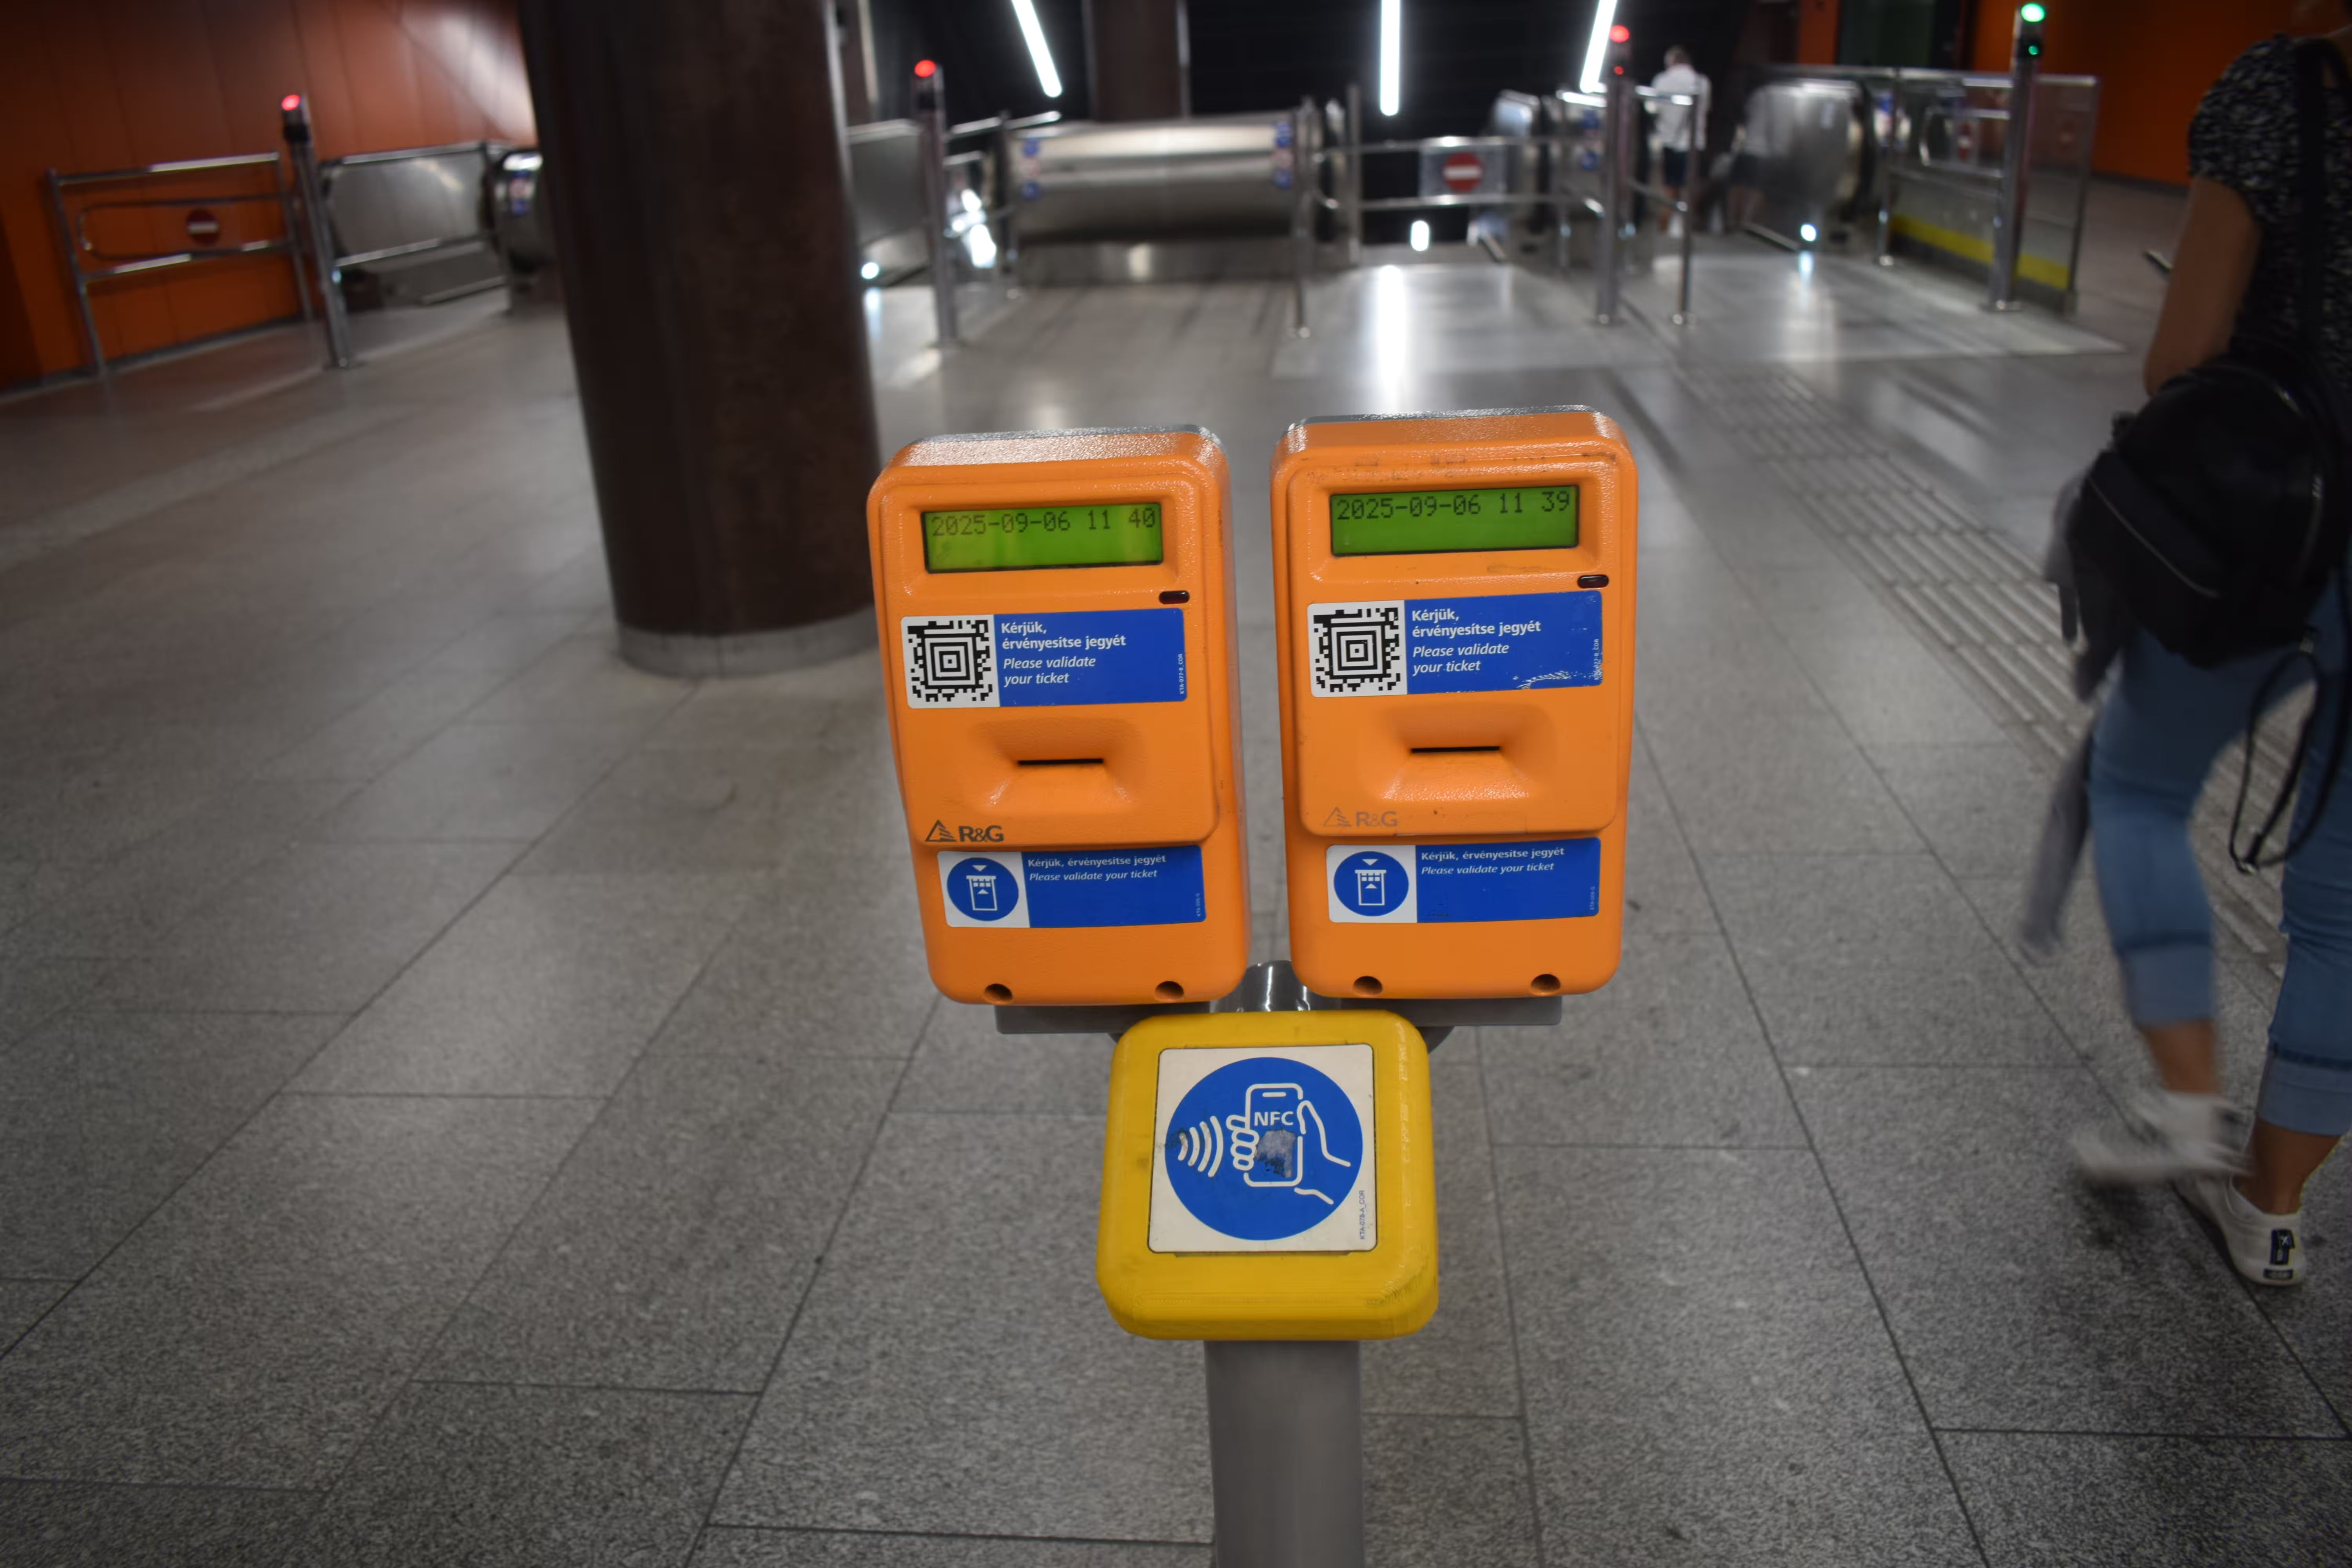 A ticket validator at a metro station in Budapest.
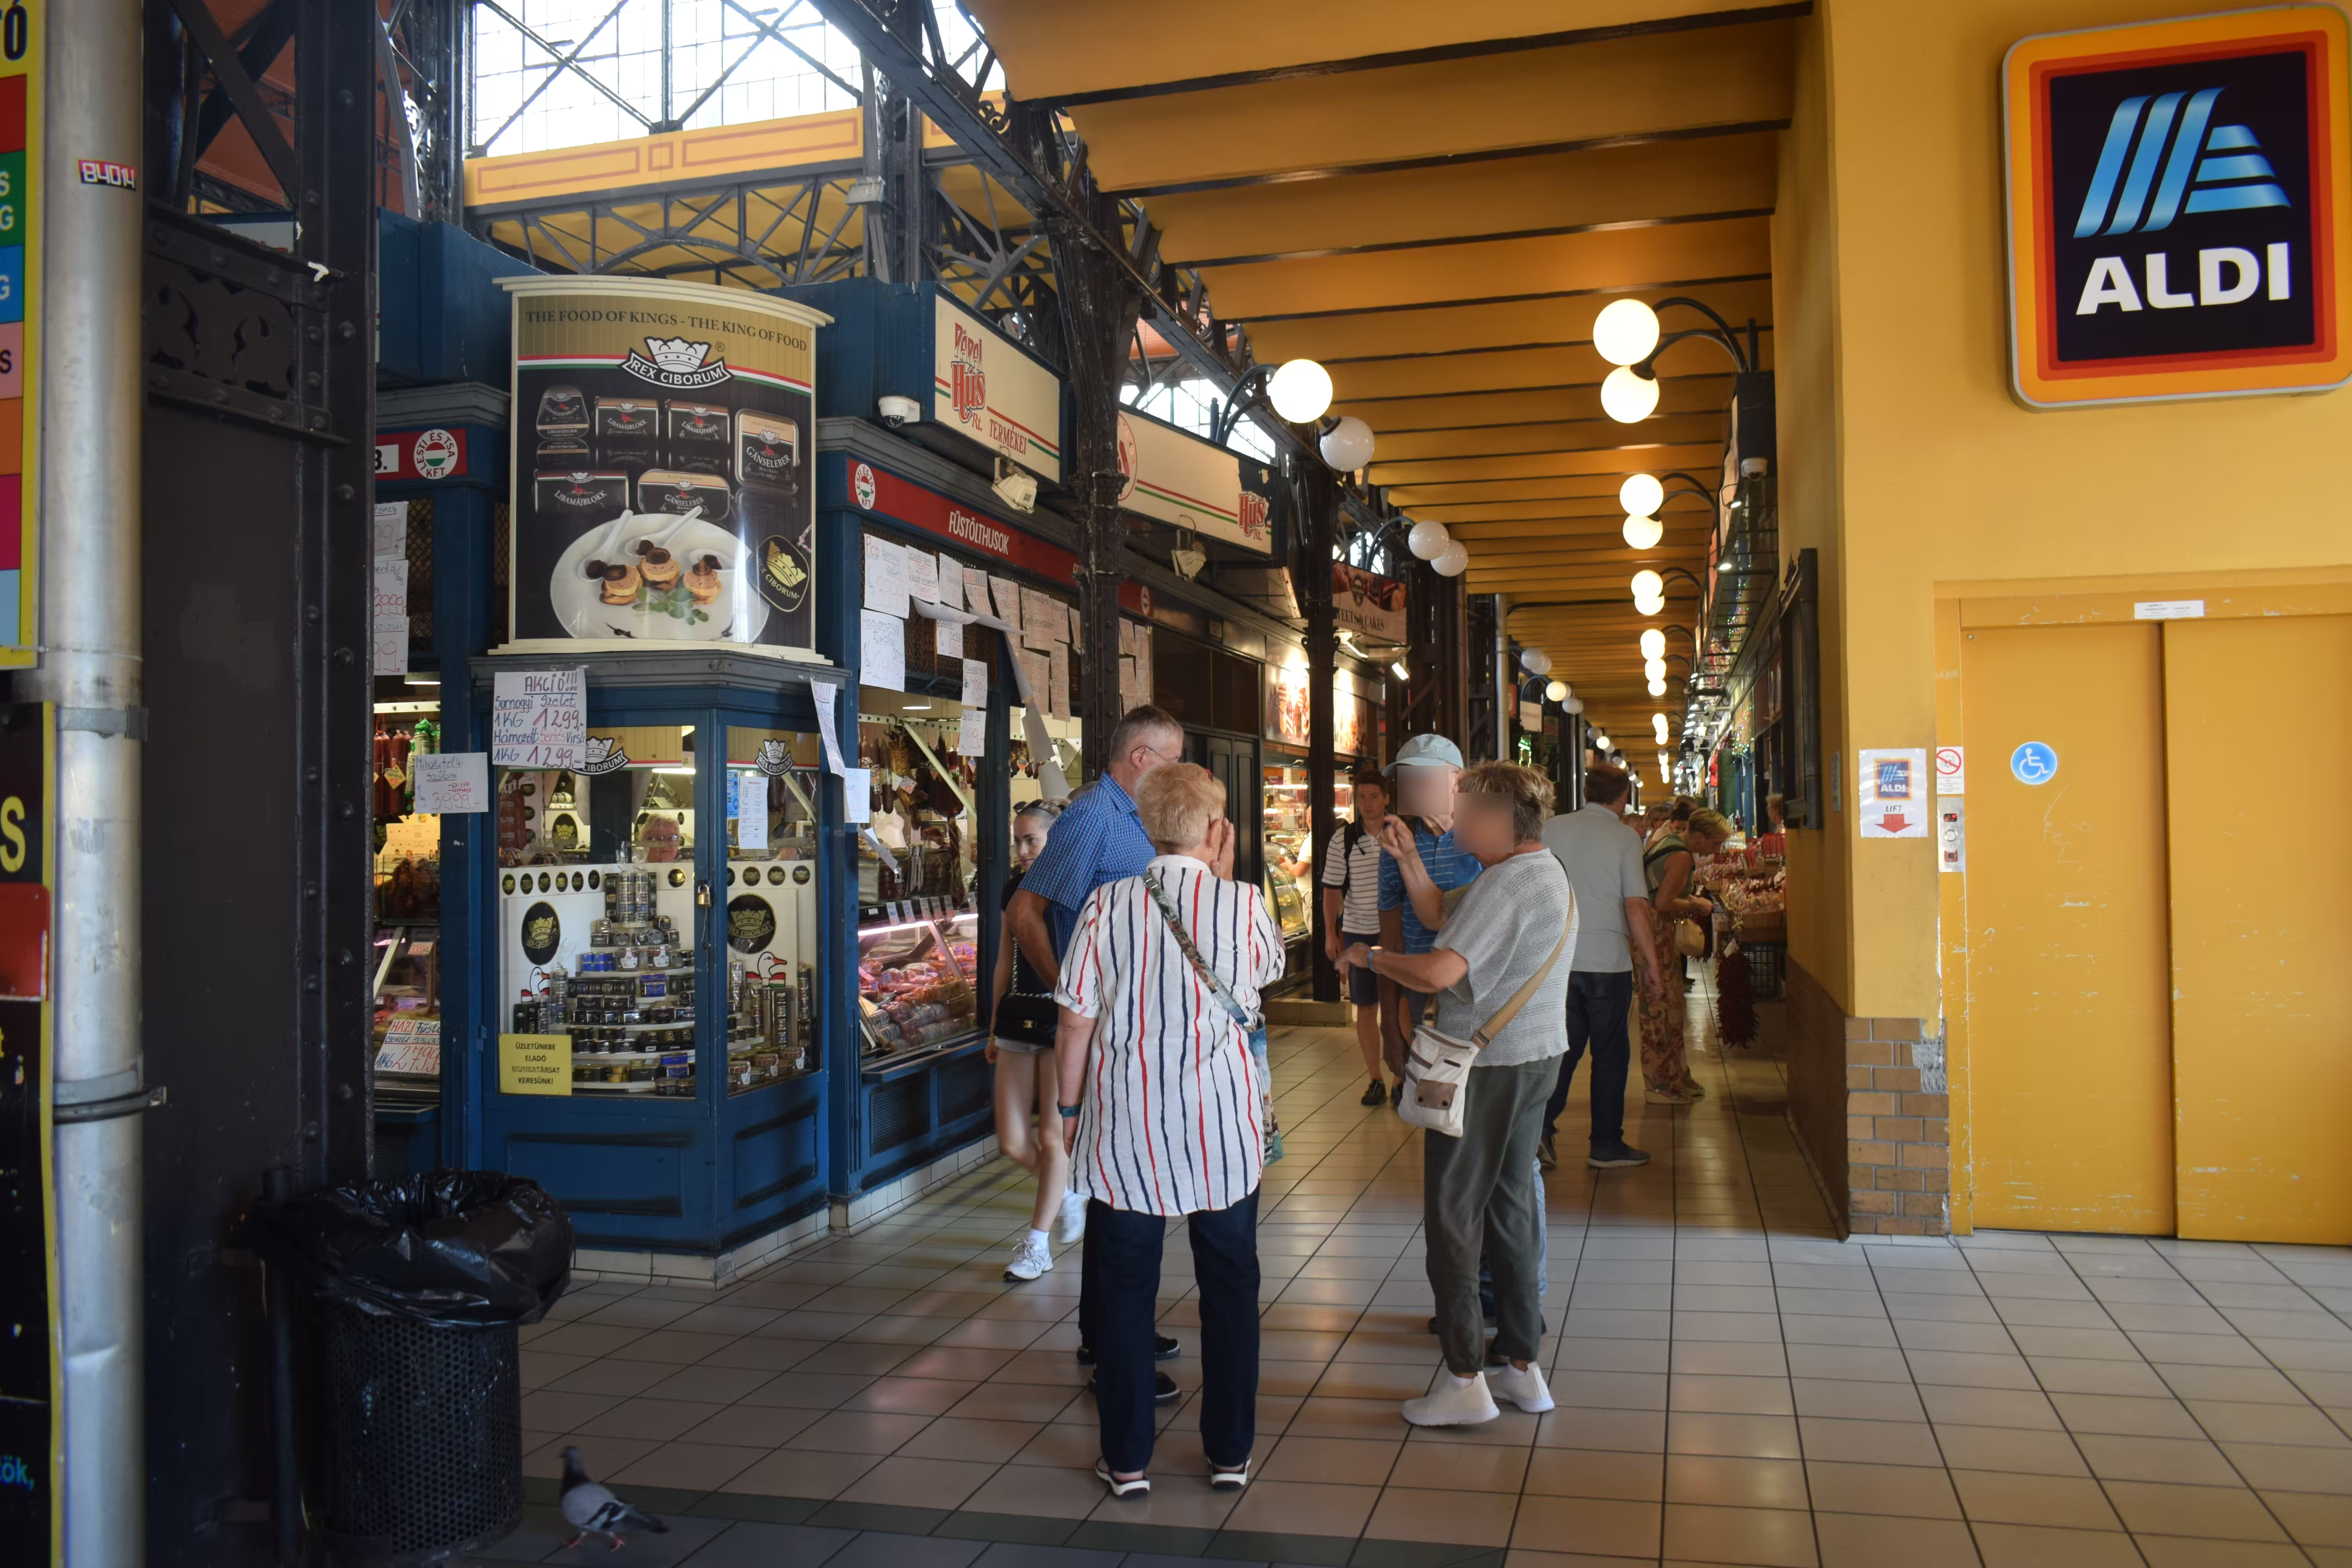 Central market.
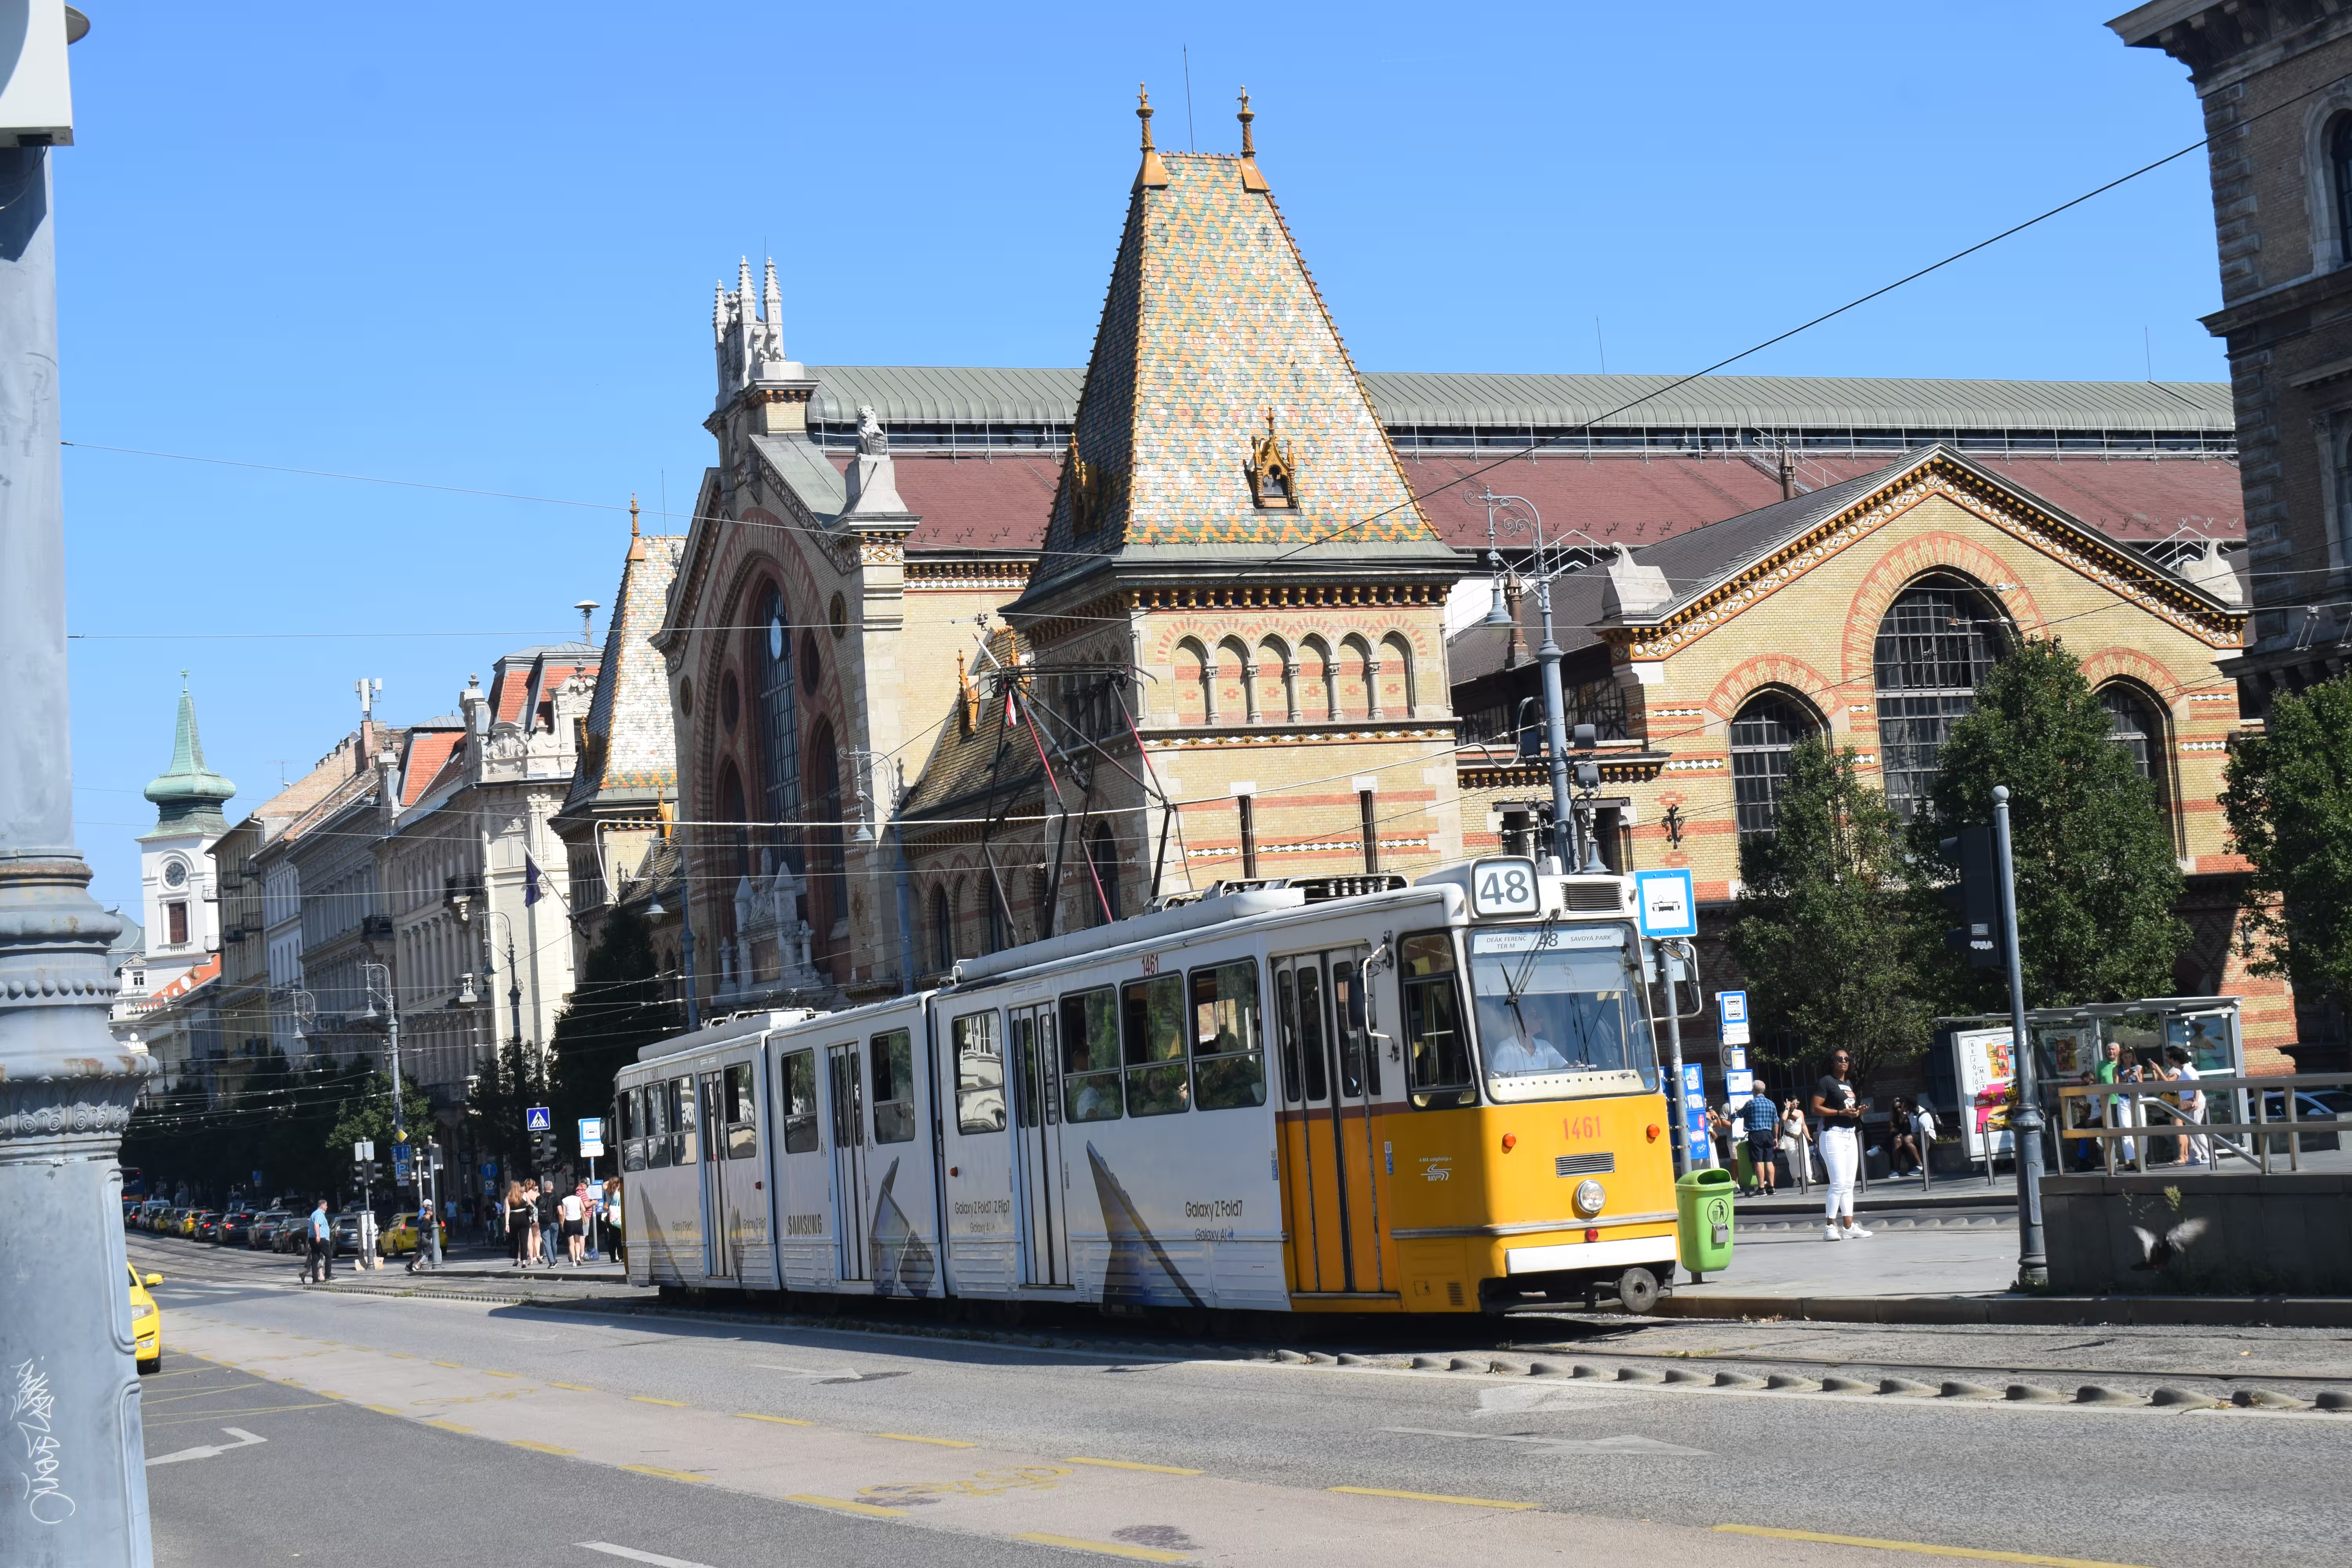 The building right behind the tram is the central market building.
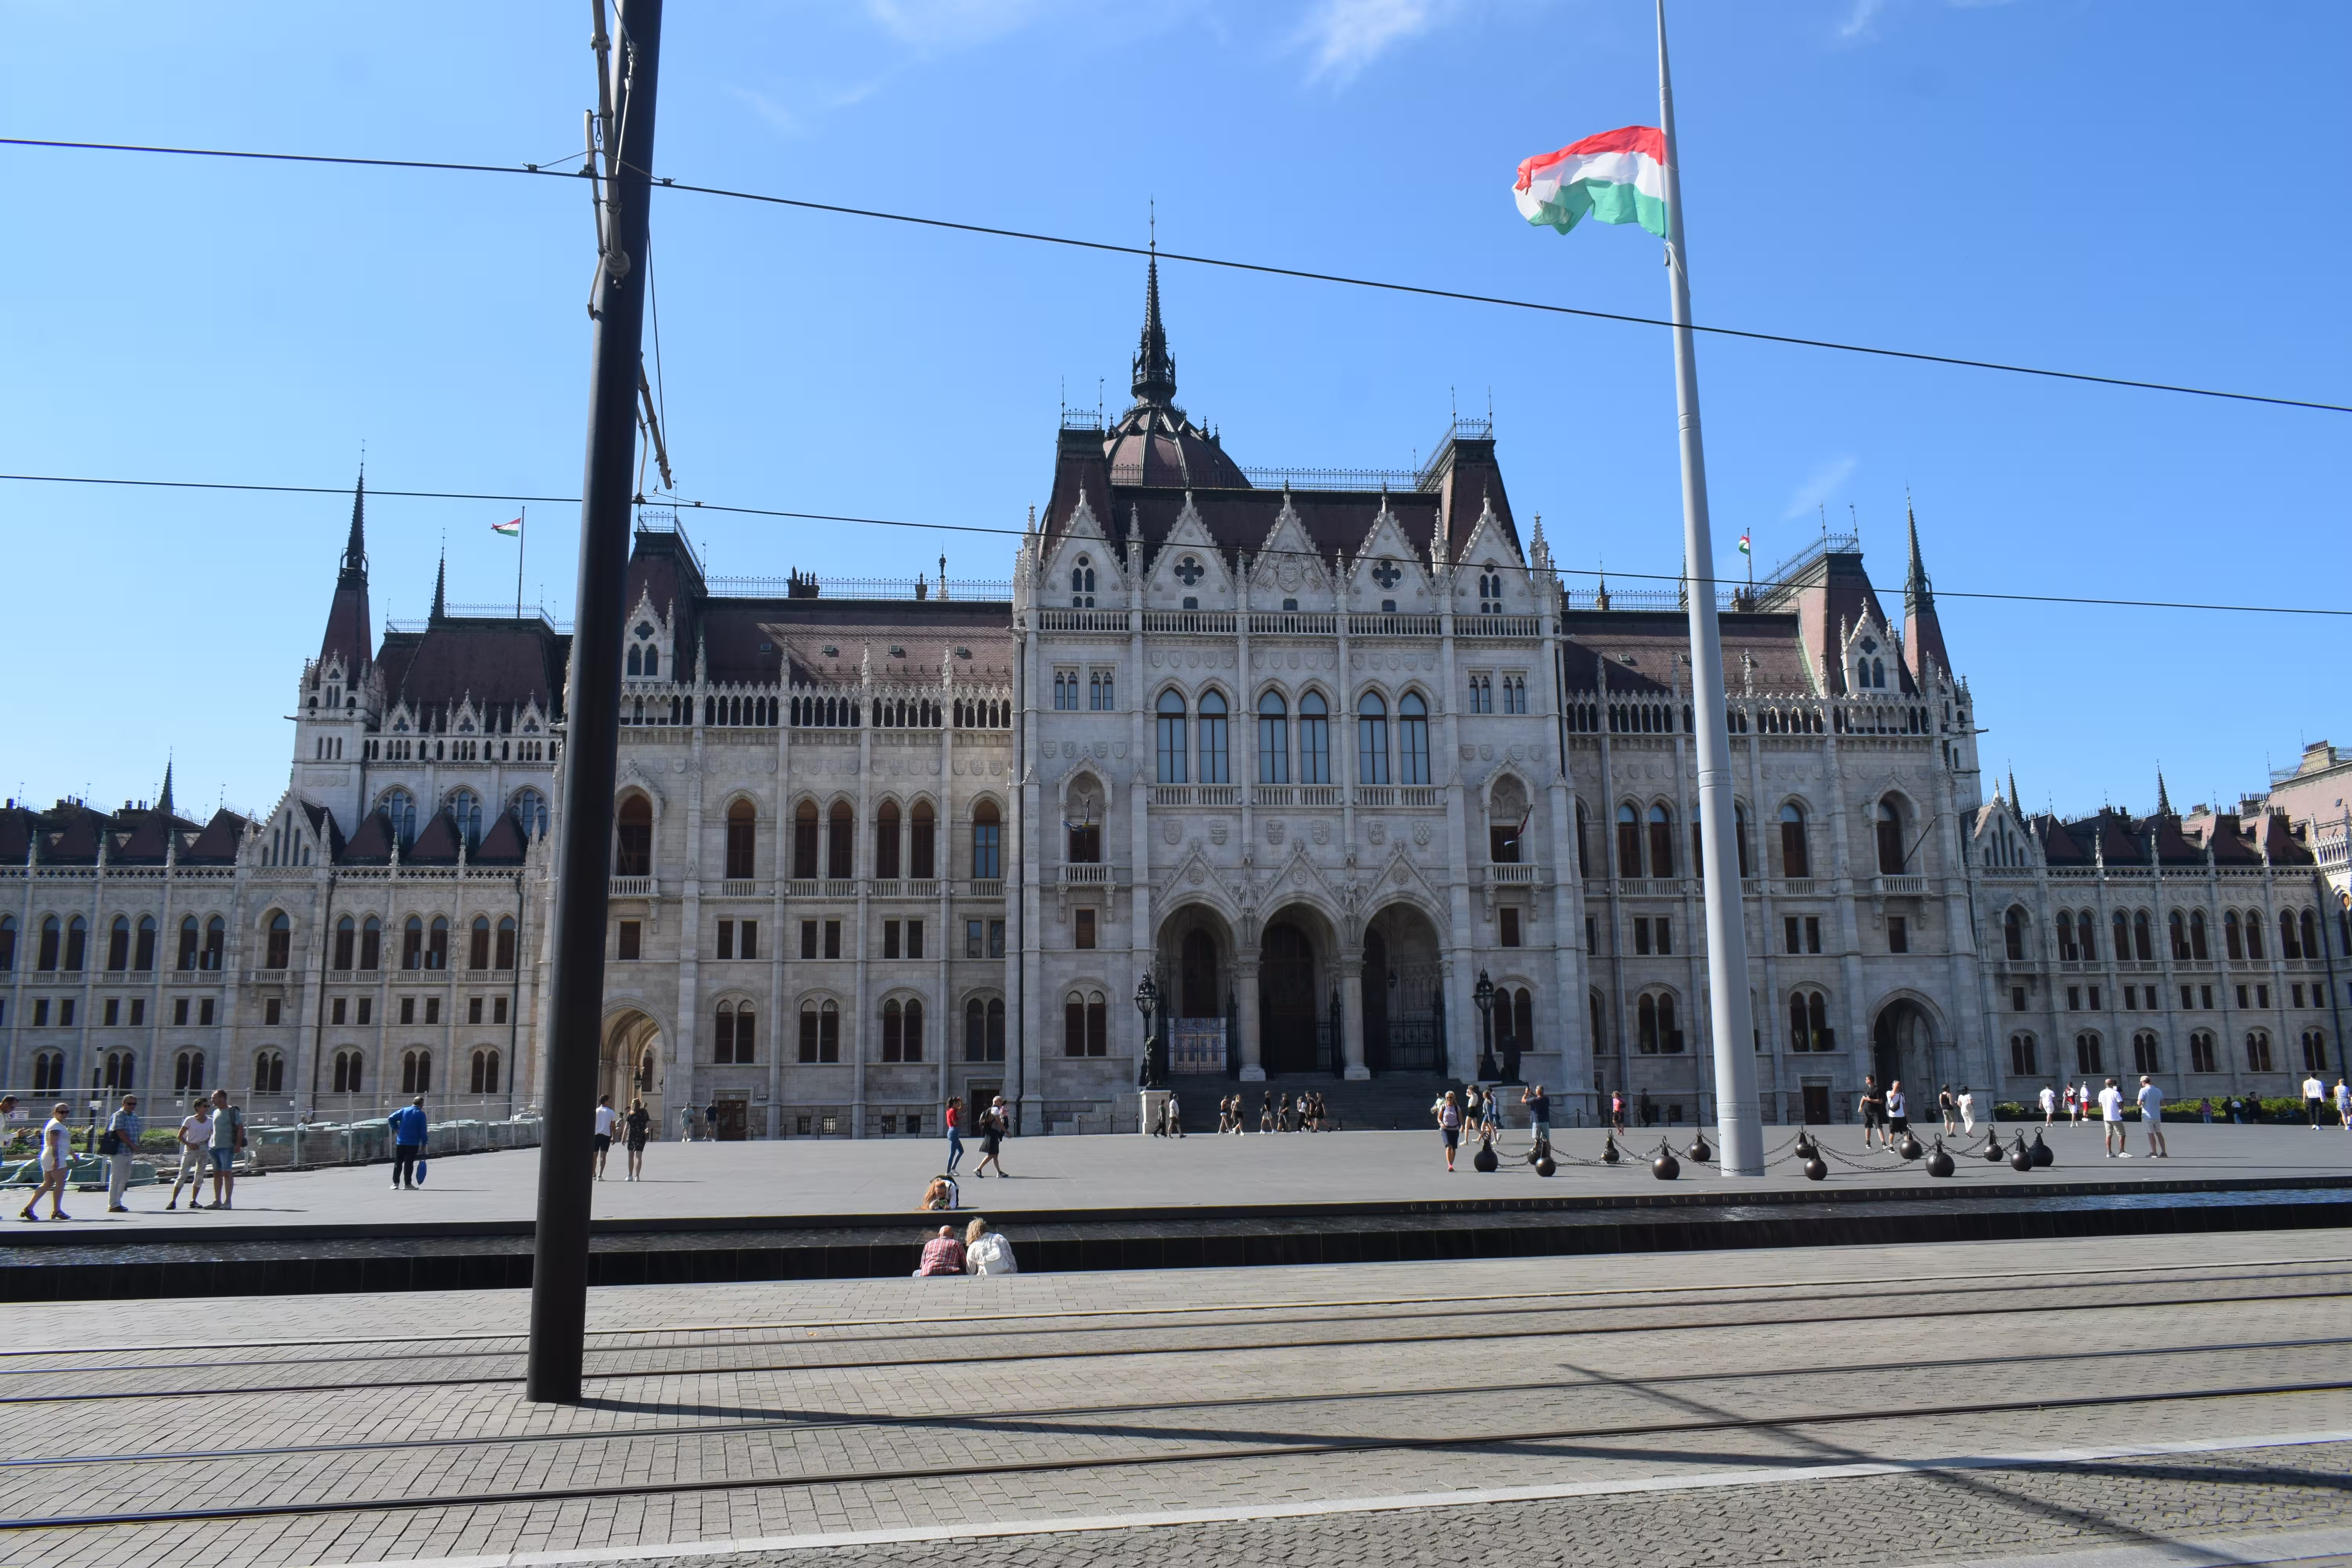 Hungarian Parliament building.
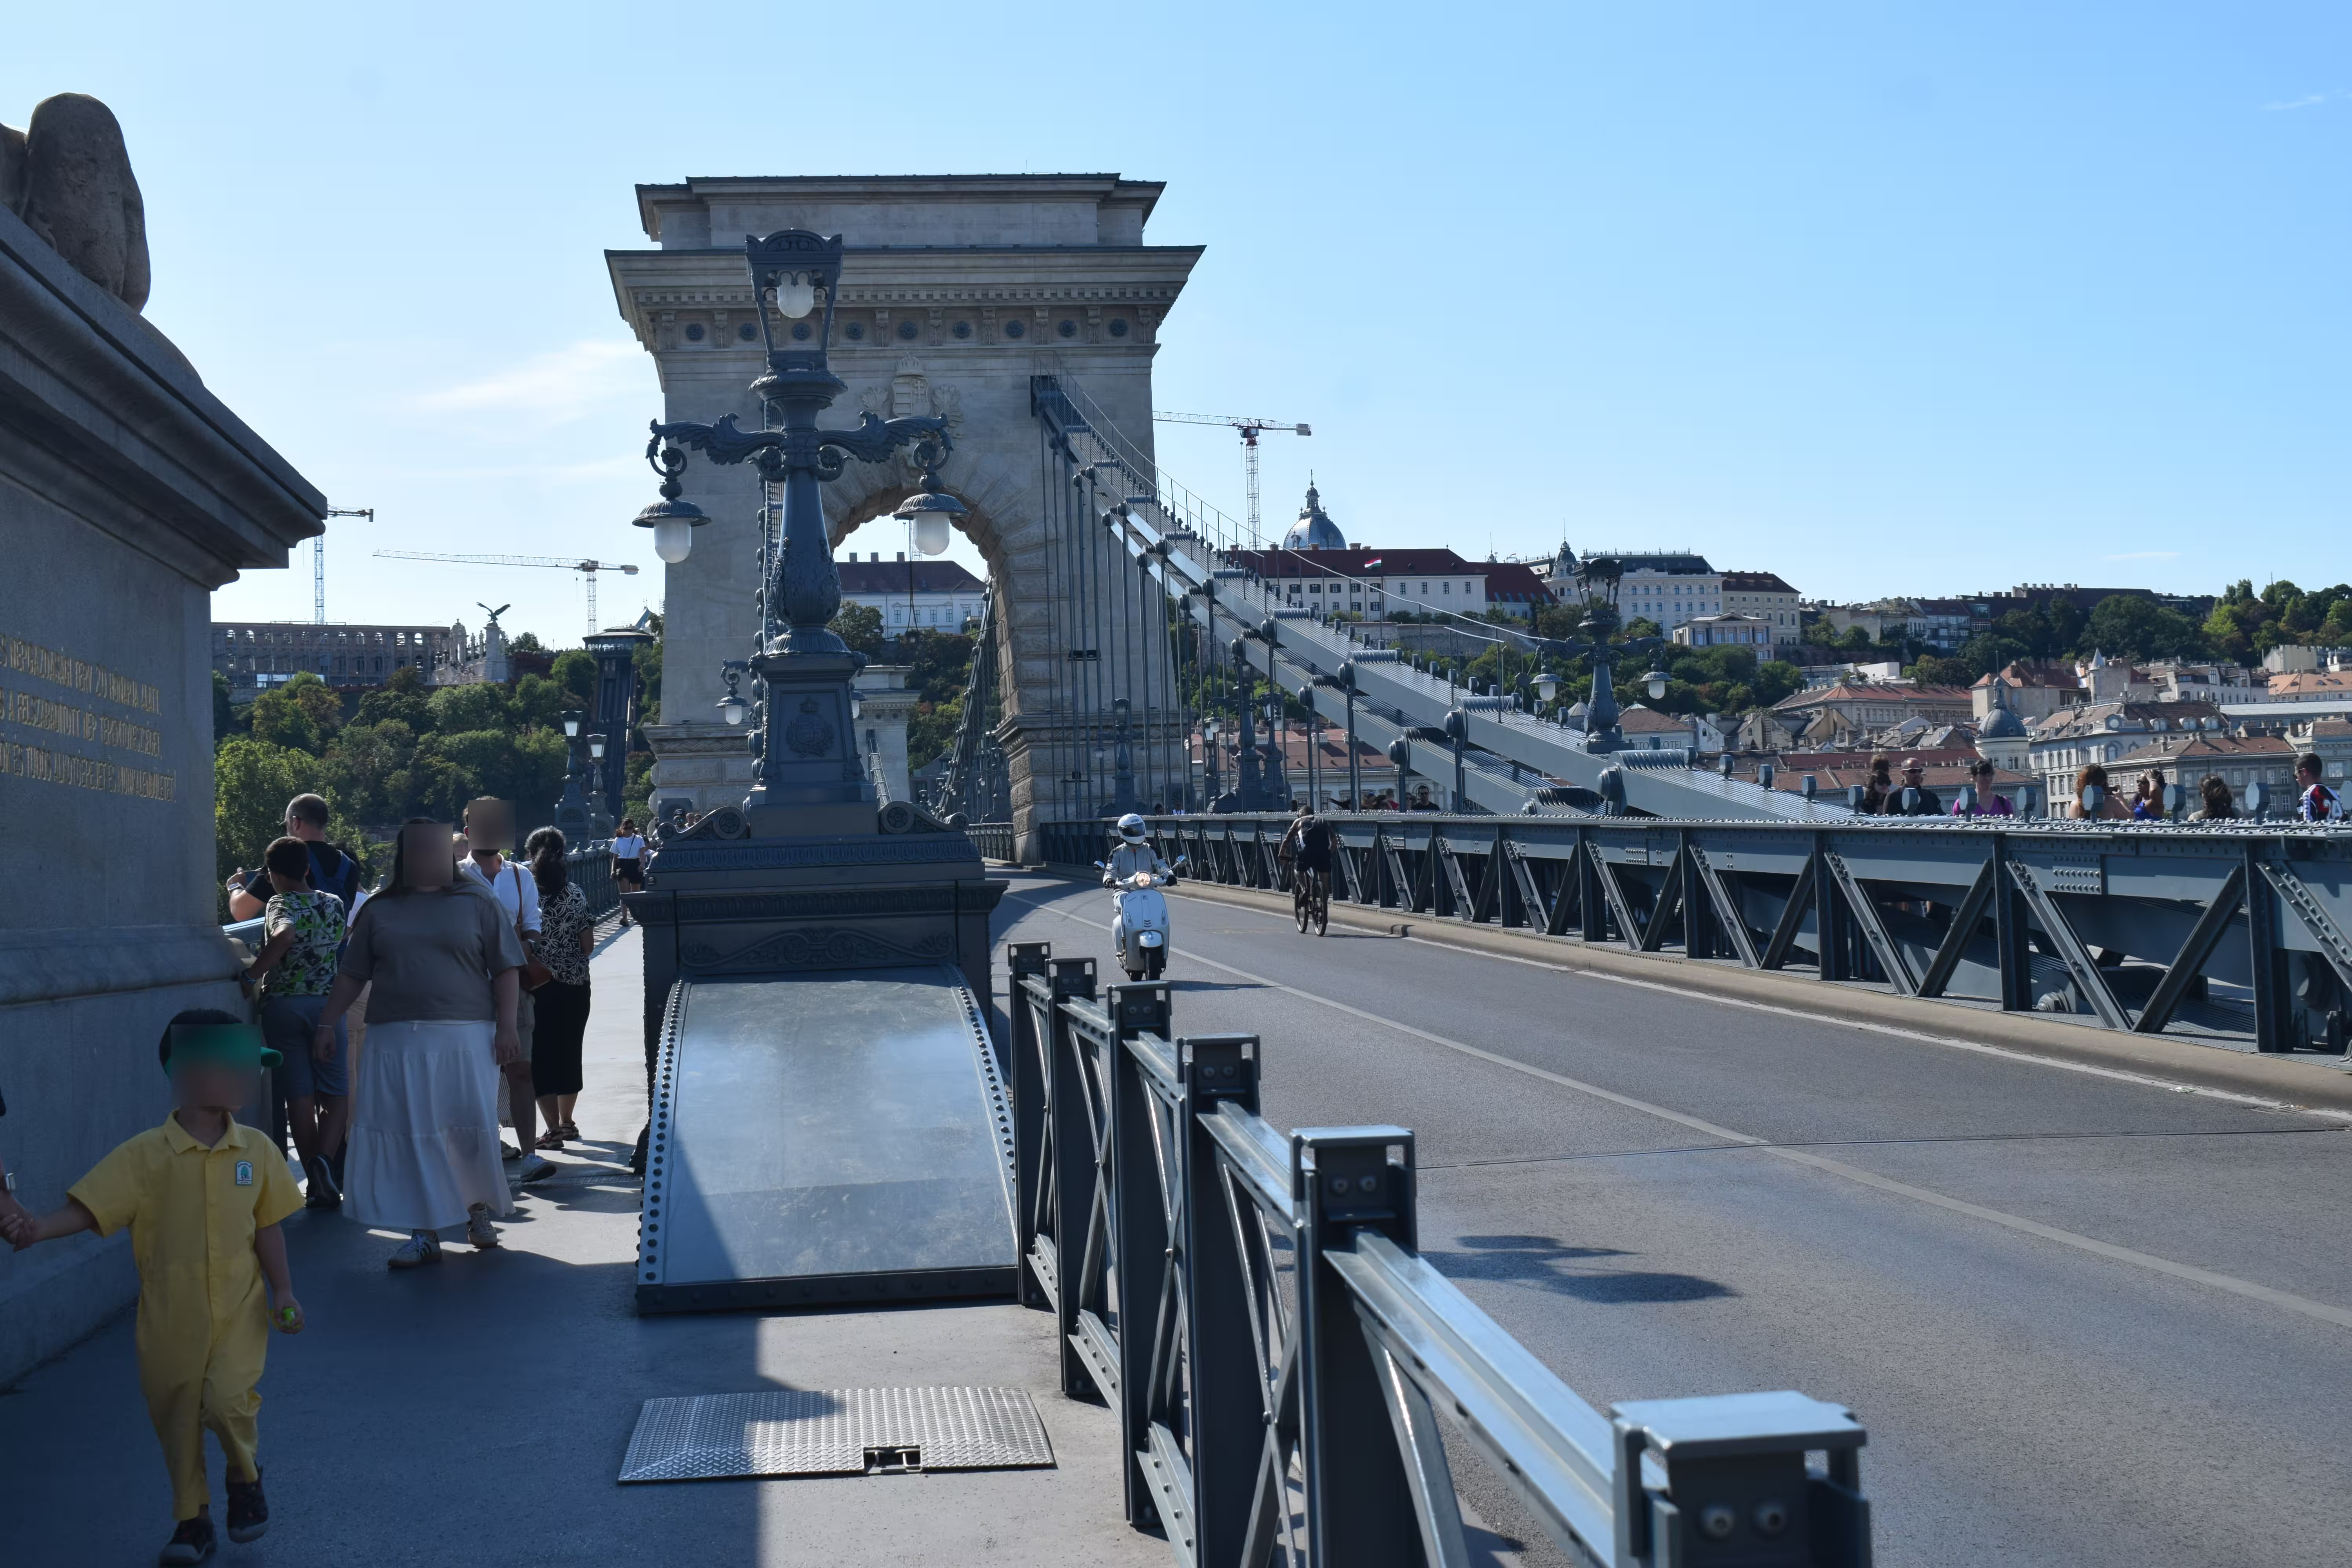 A shot of Chain Bridge.
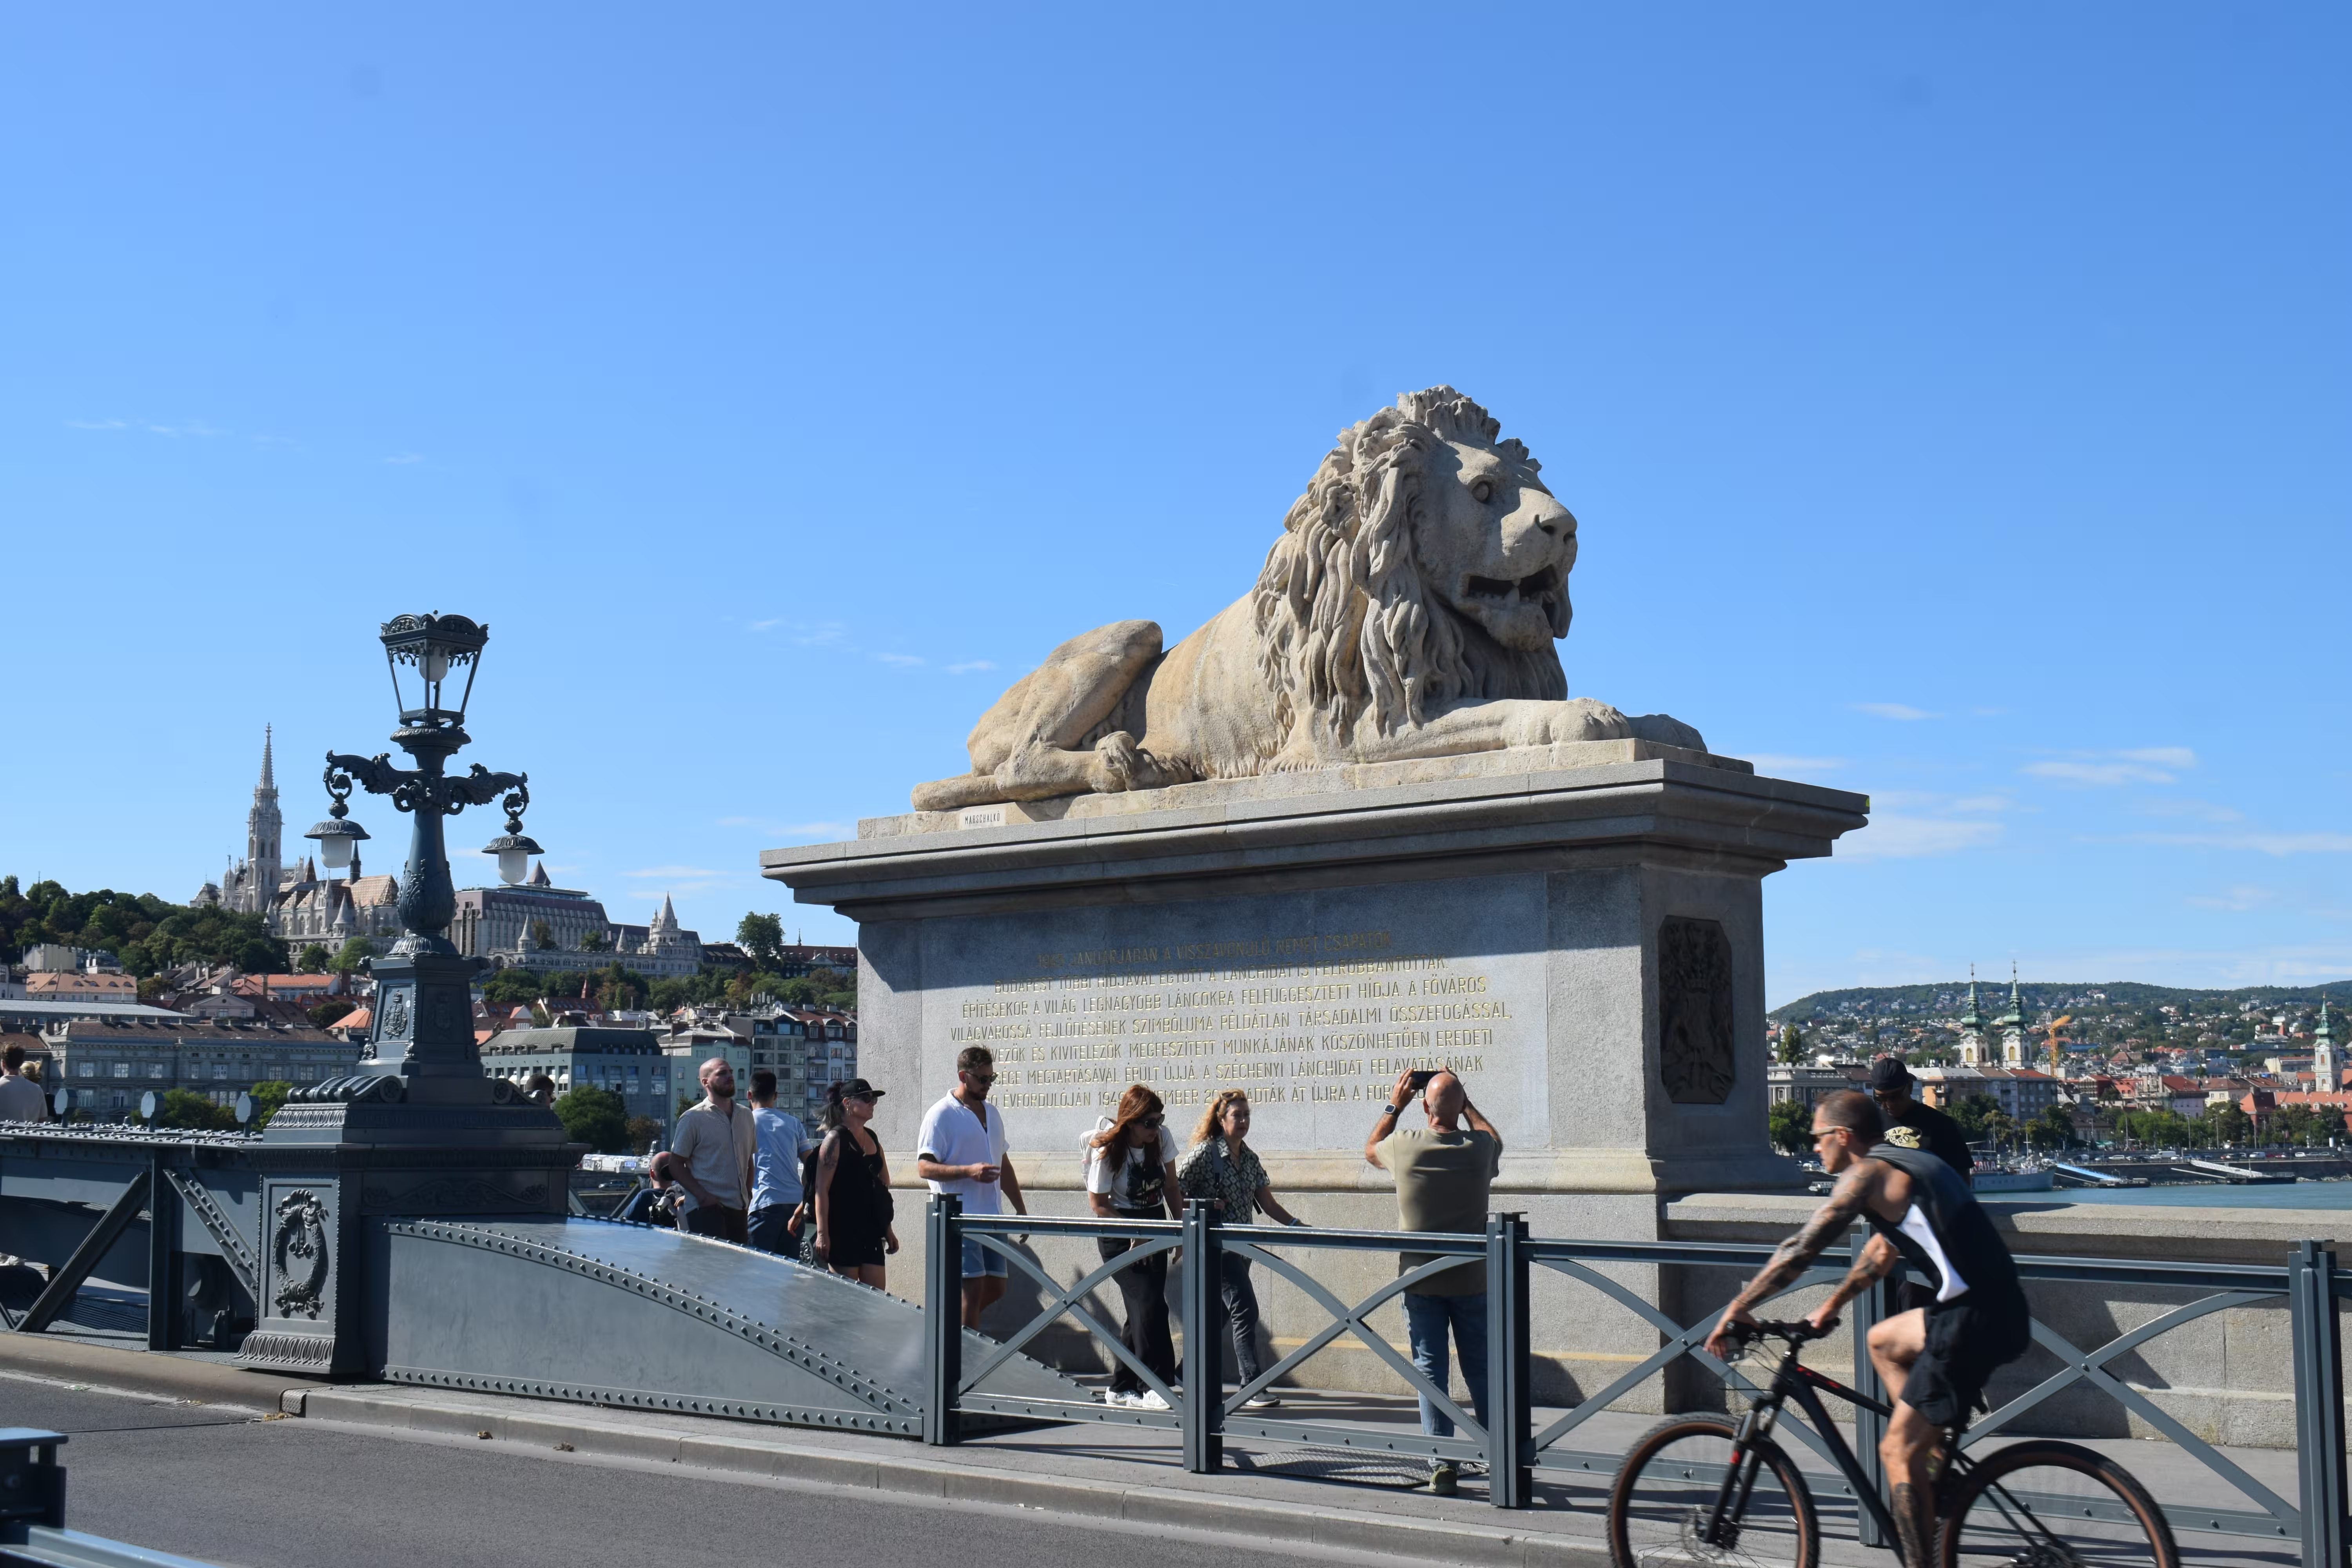 The lion statue on the Chain Bridge.
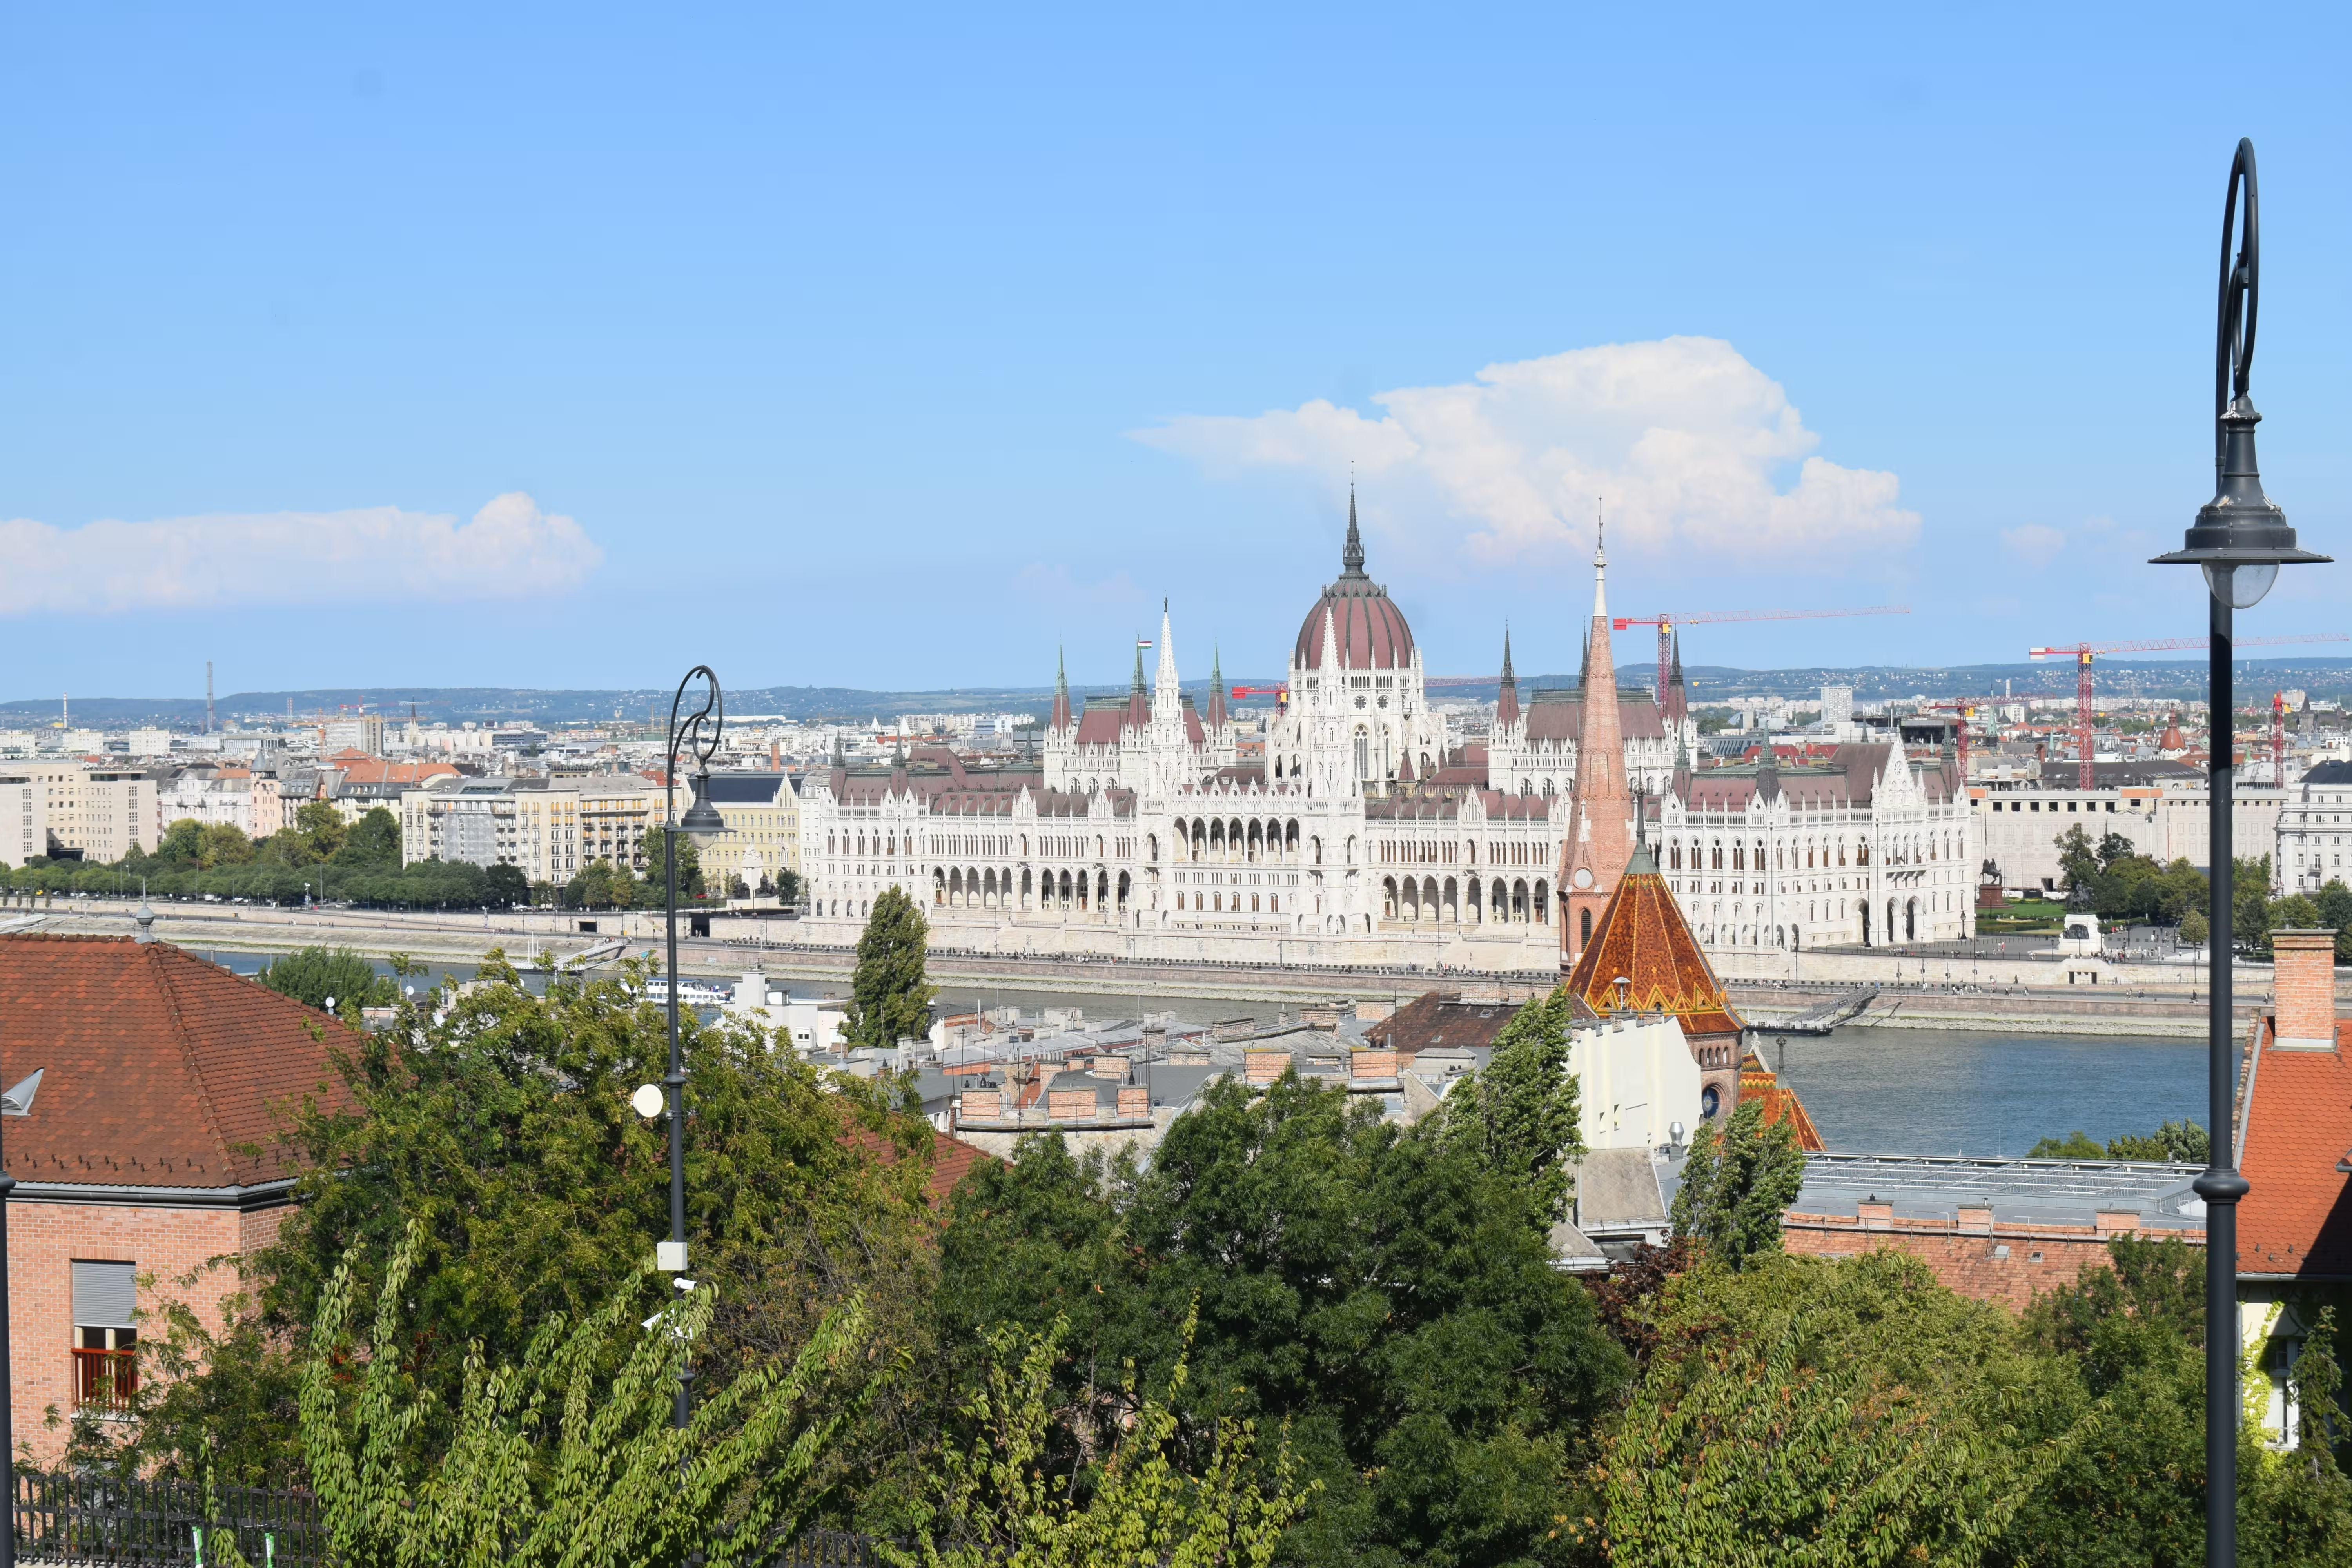 A view of Hungarian parliament from Fisherman s bastion.
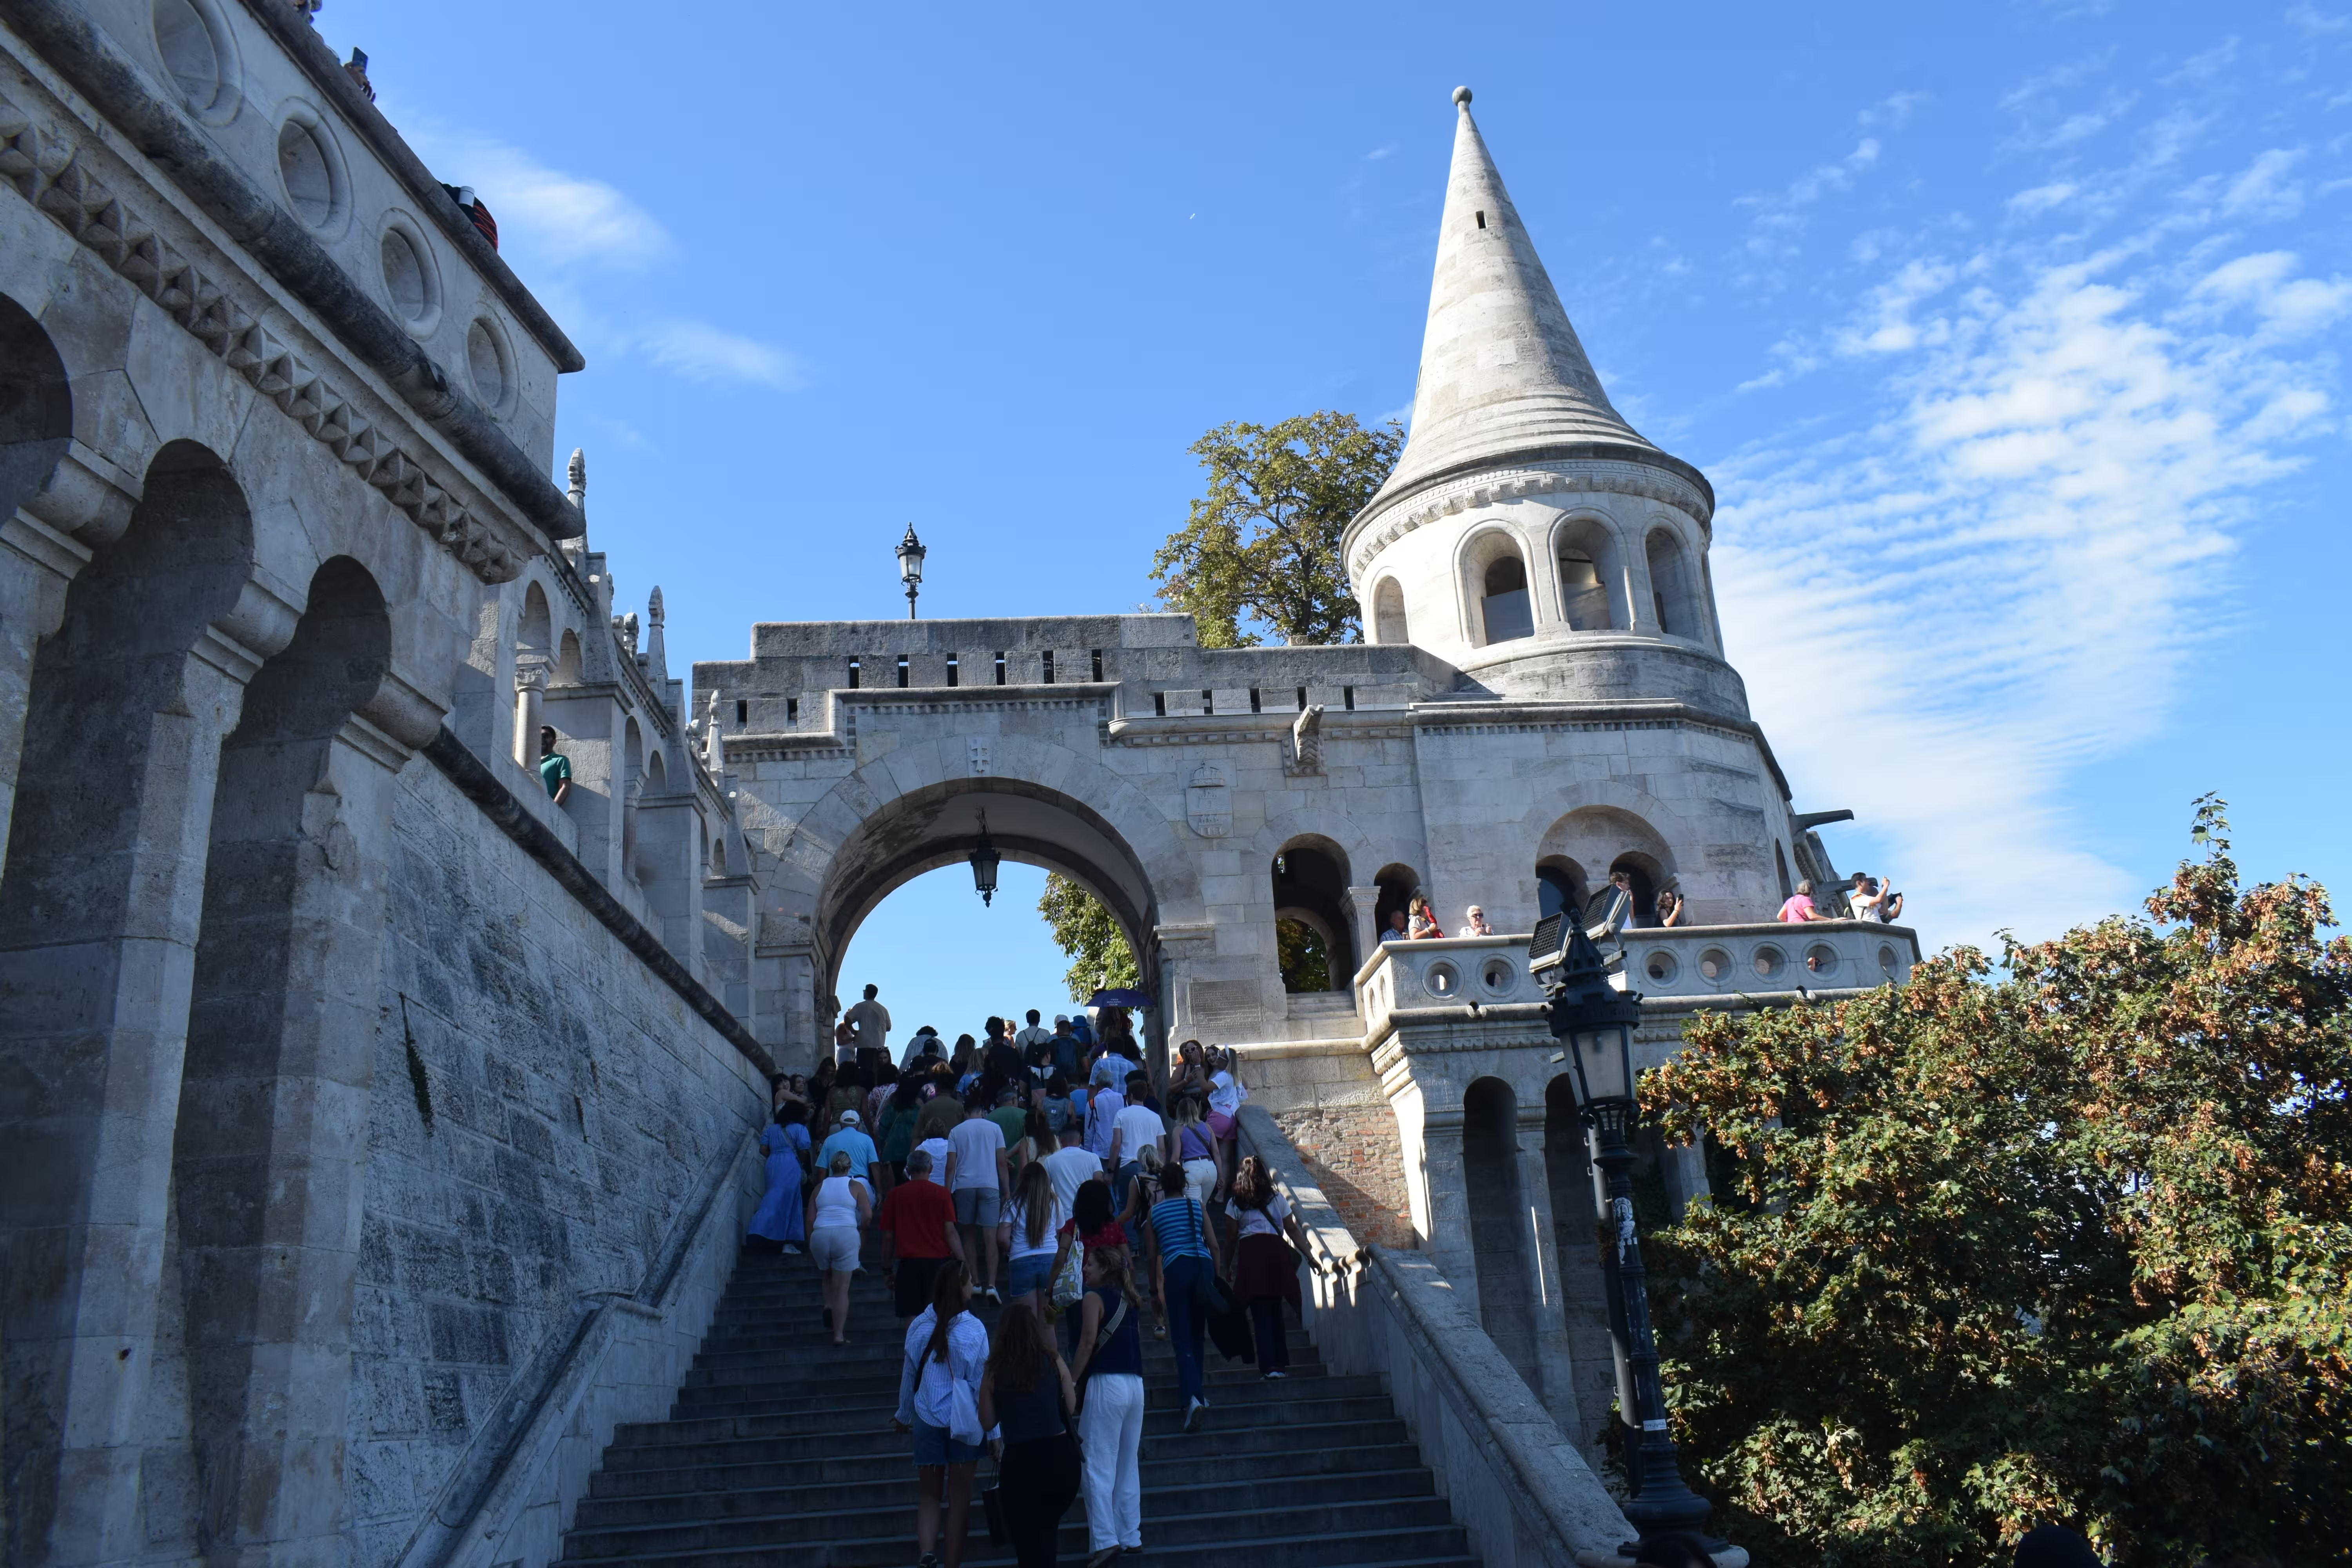 Fisherman s Bastion.
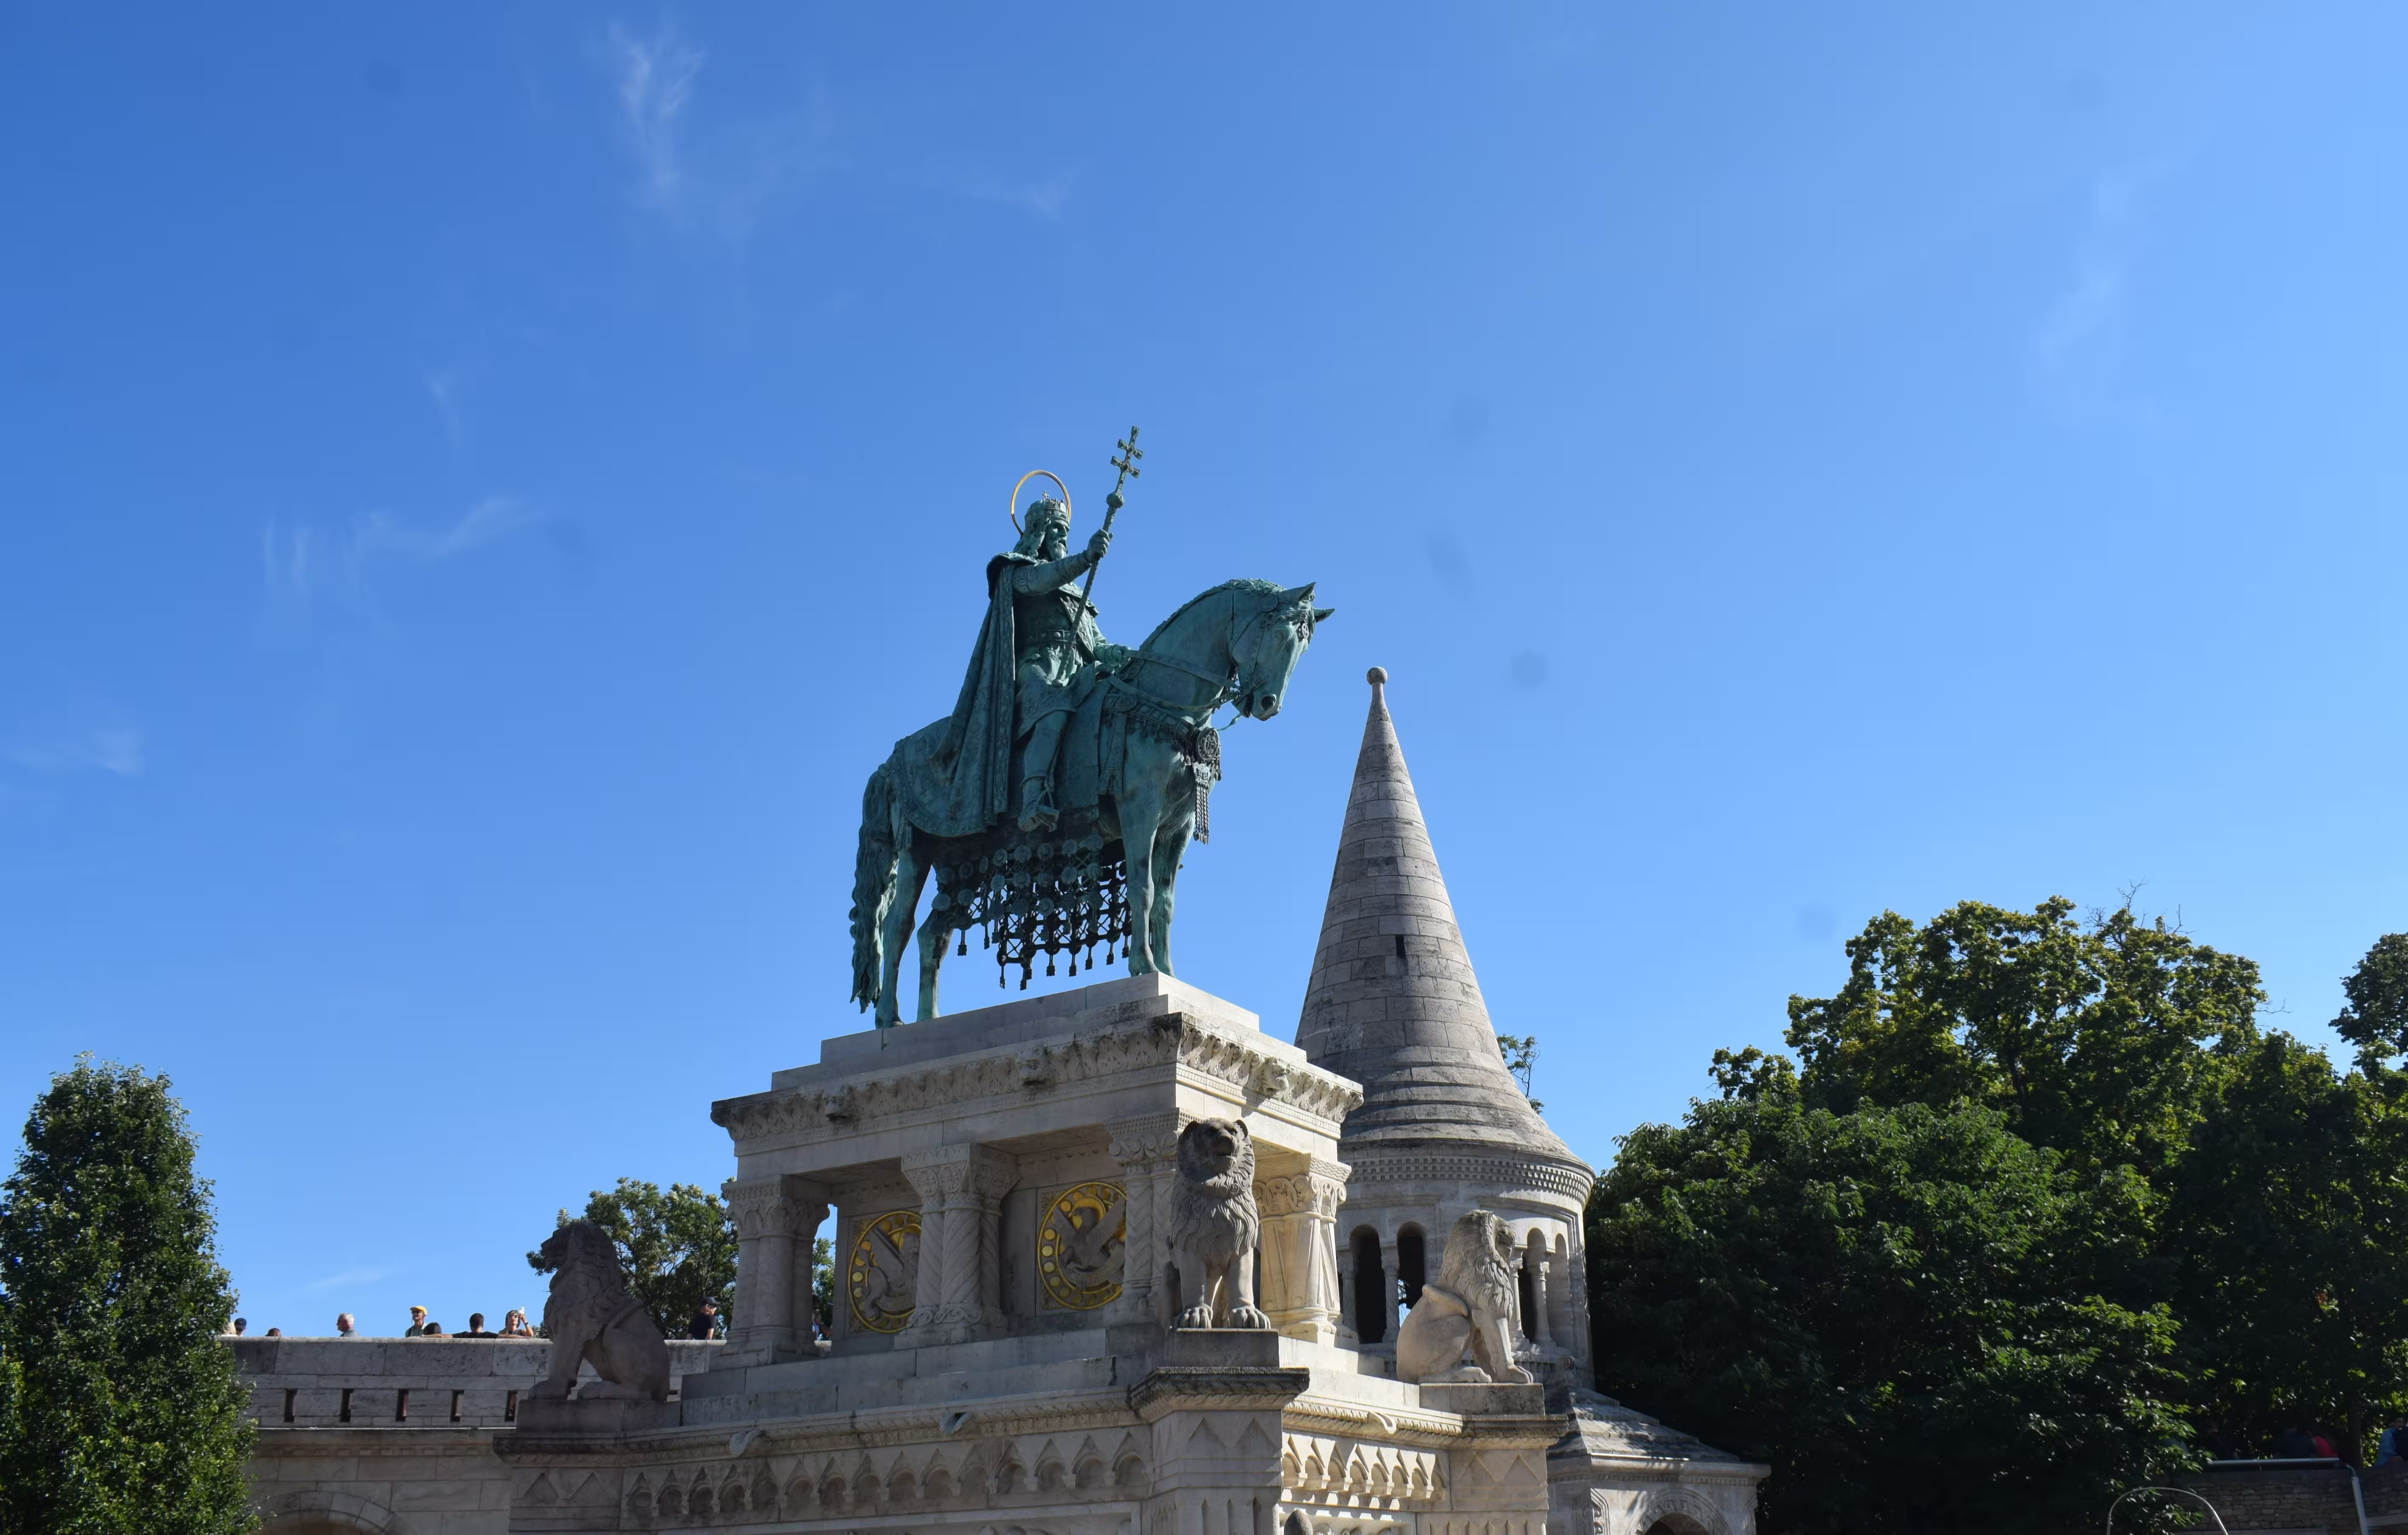 Statue of Stephen I of Hungary at Fisherman s Bastion.
 Batthy ny t r metro station.
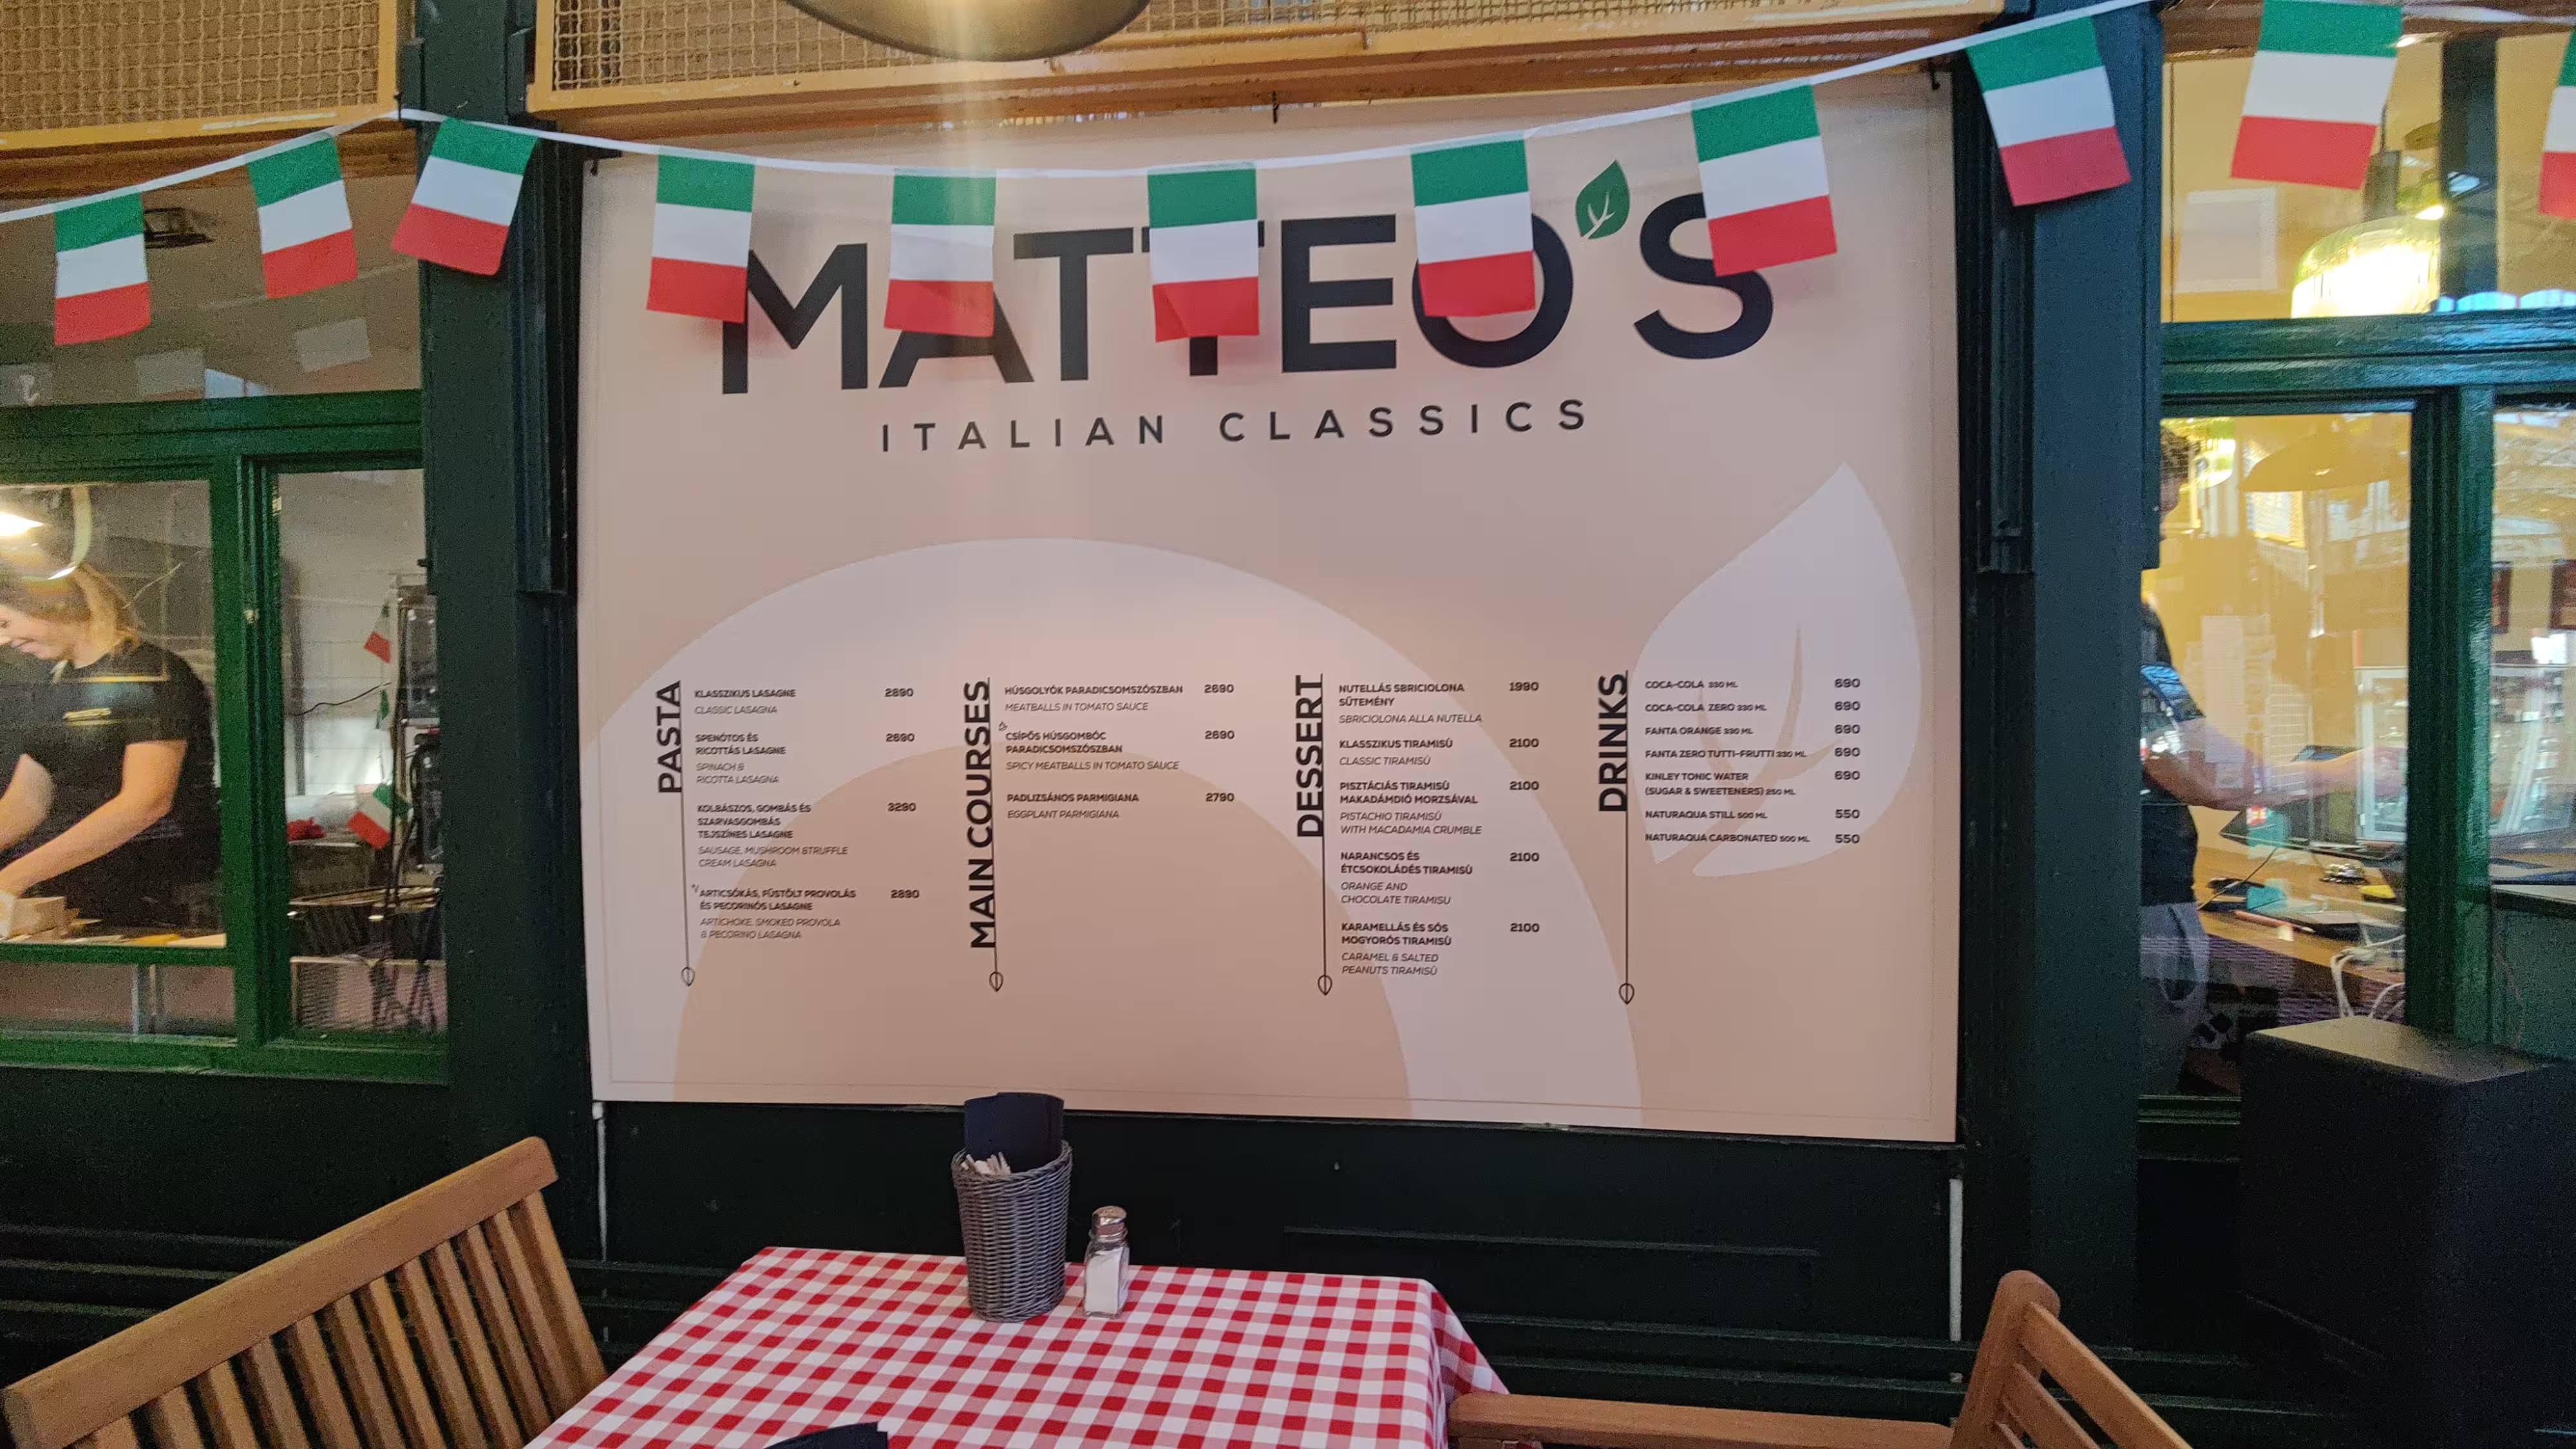 A picture of Matteos, where we had our lunch.
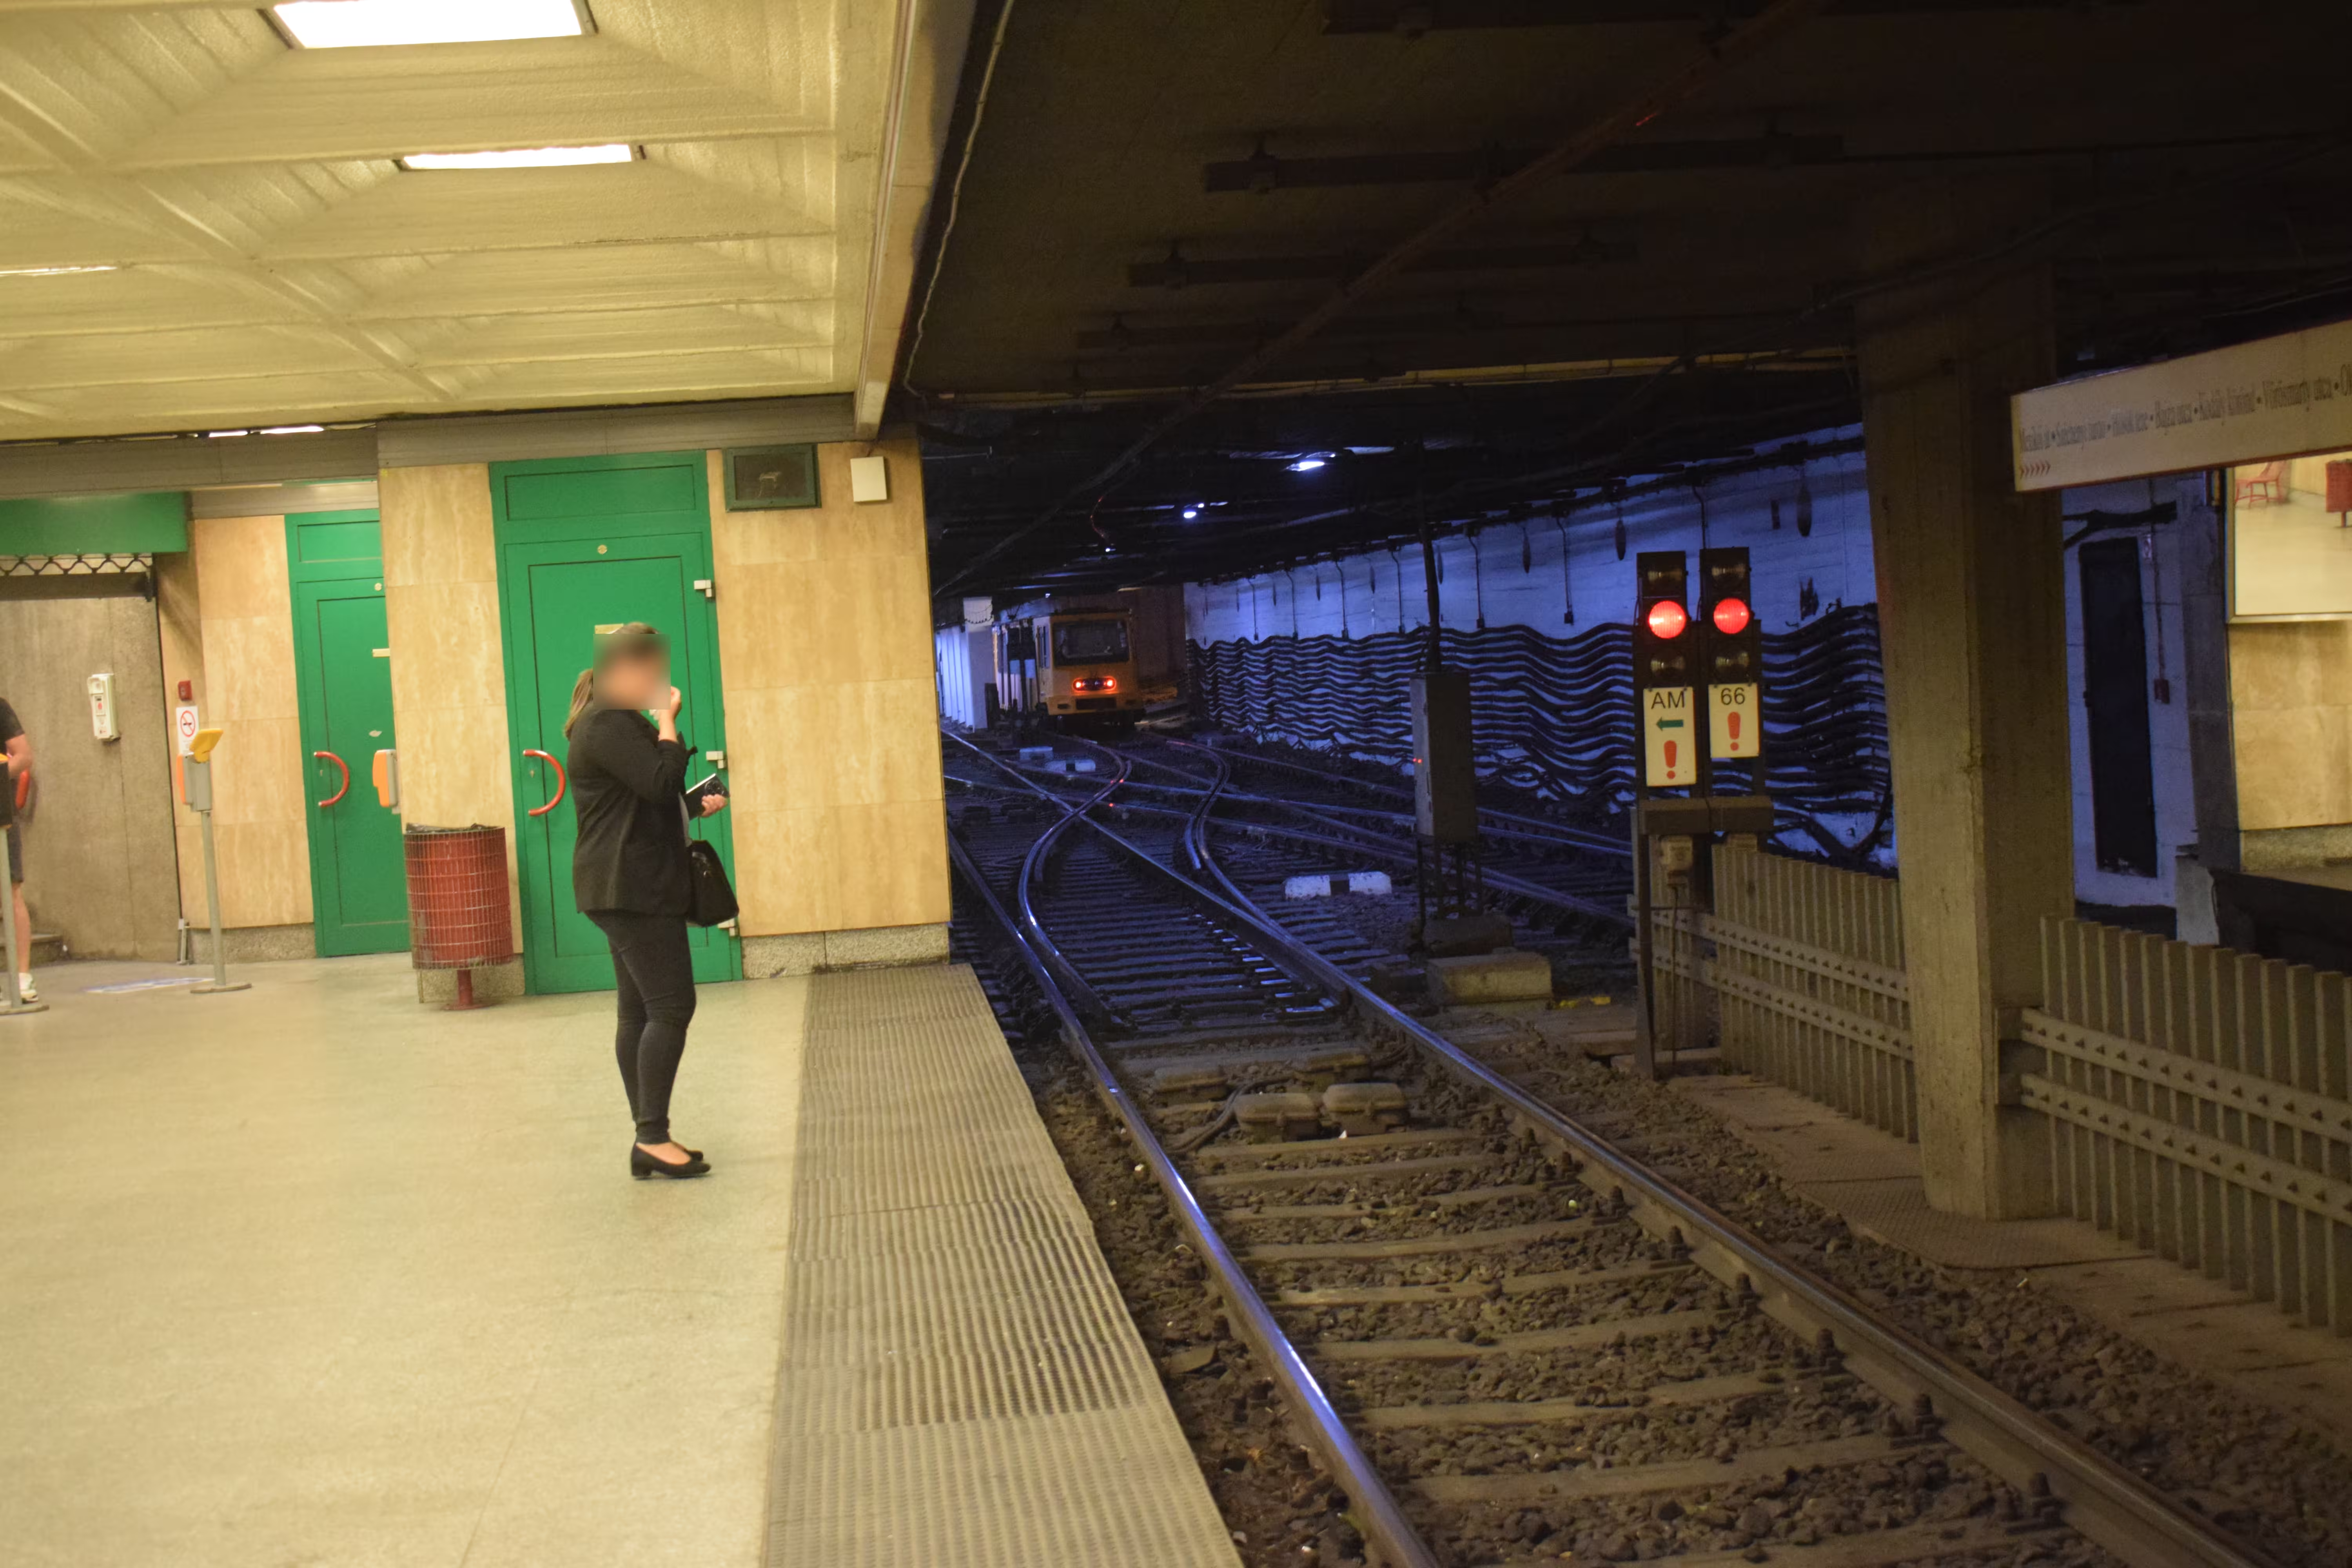 M1 line station and tracks. It is the oldest metro transit of Budapest and one of the oldest in the world. It started operations in 1896.
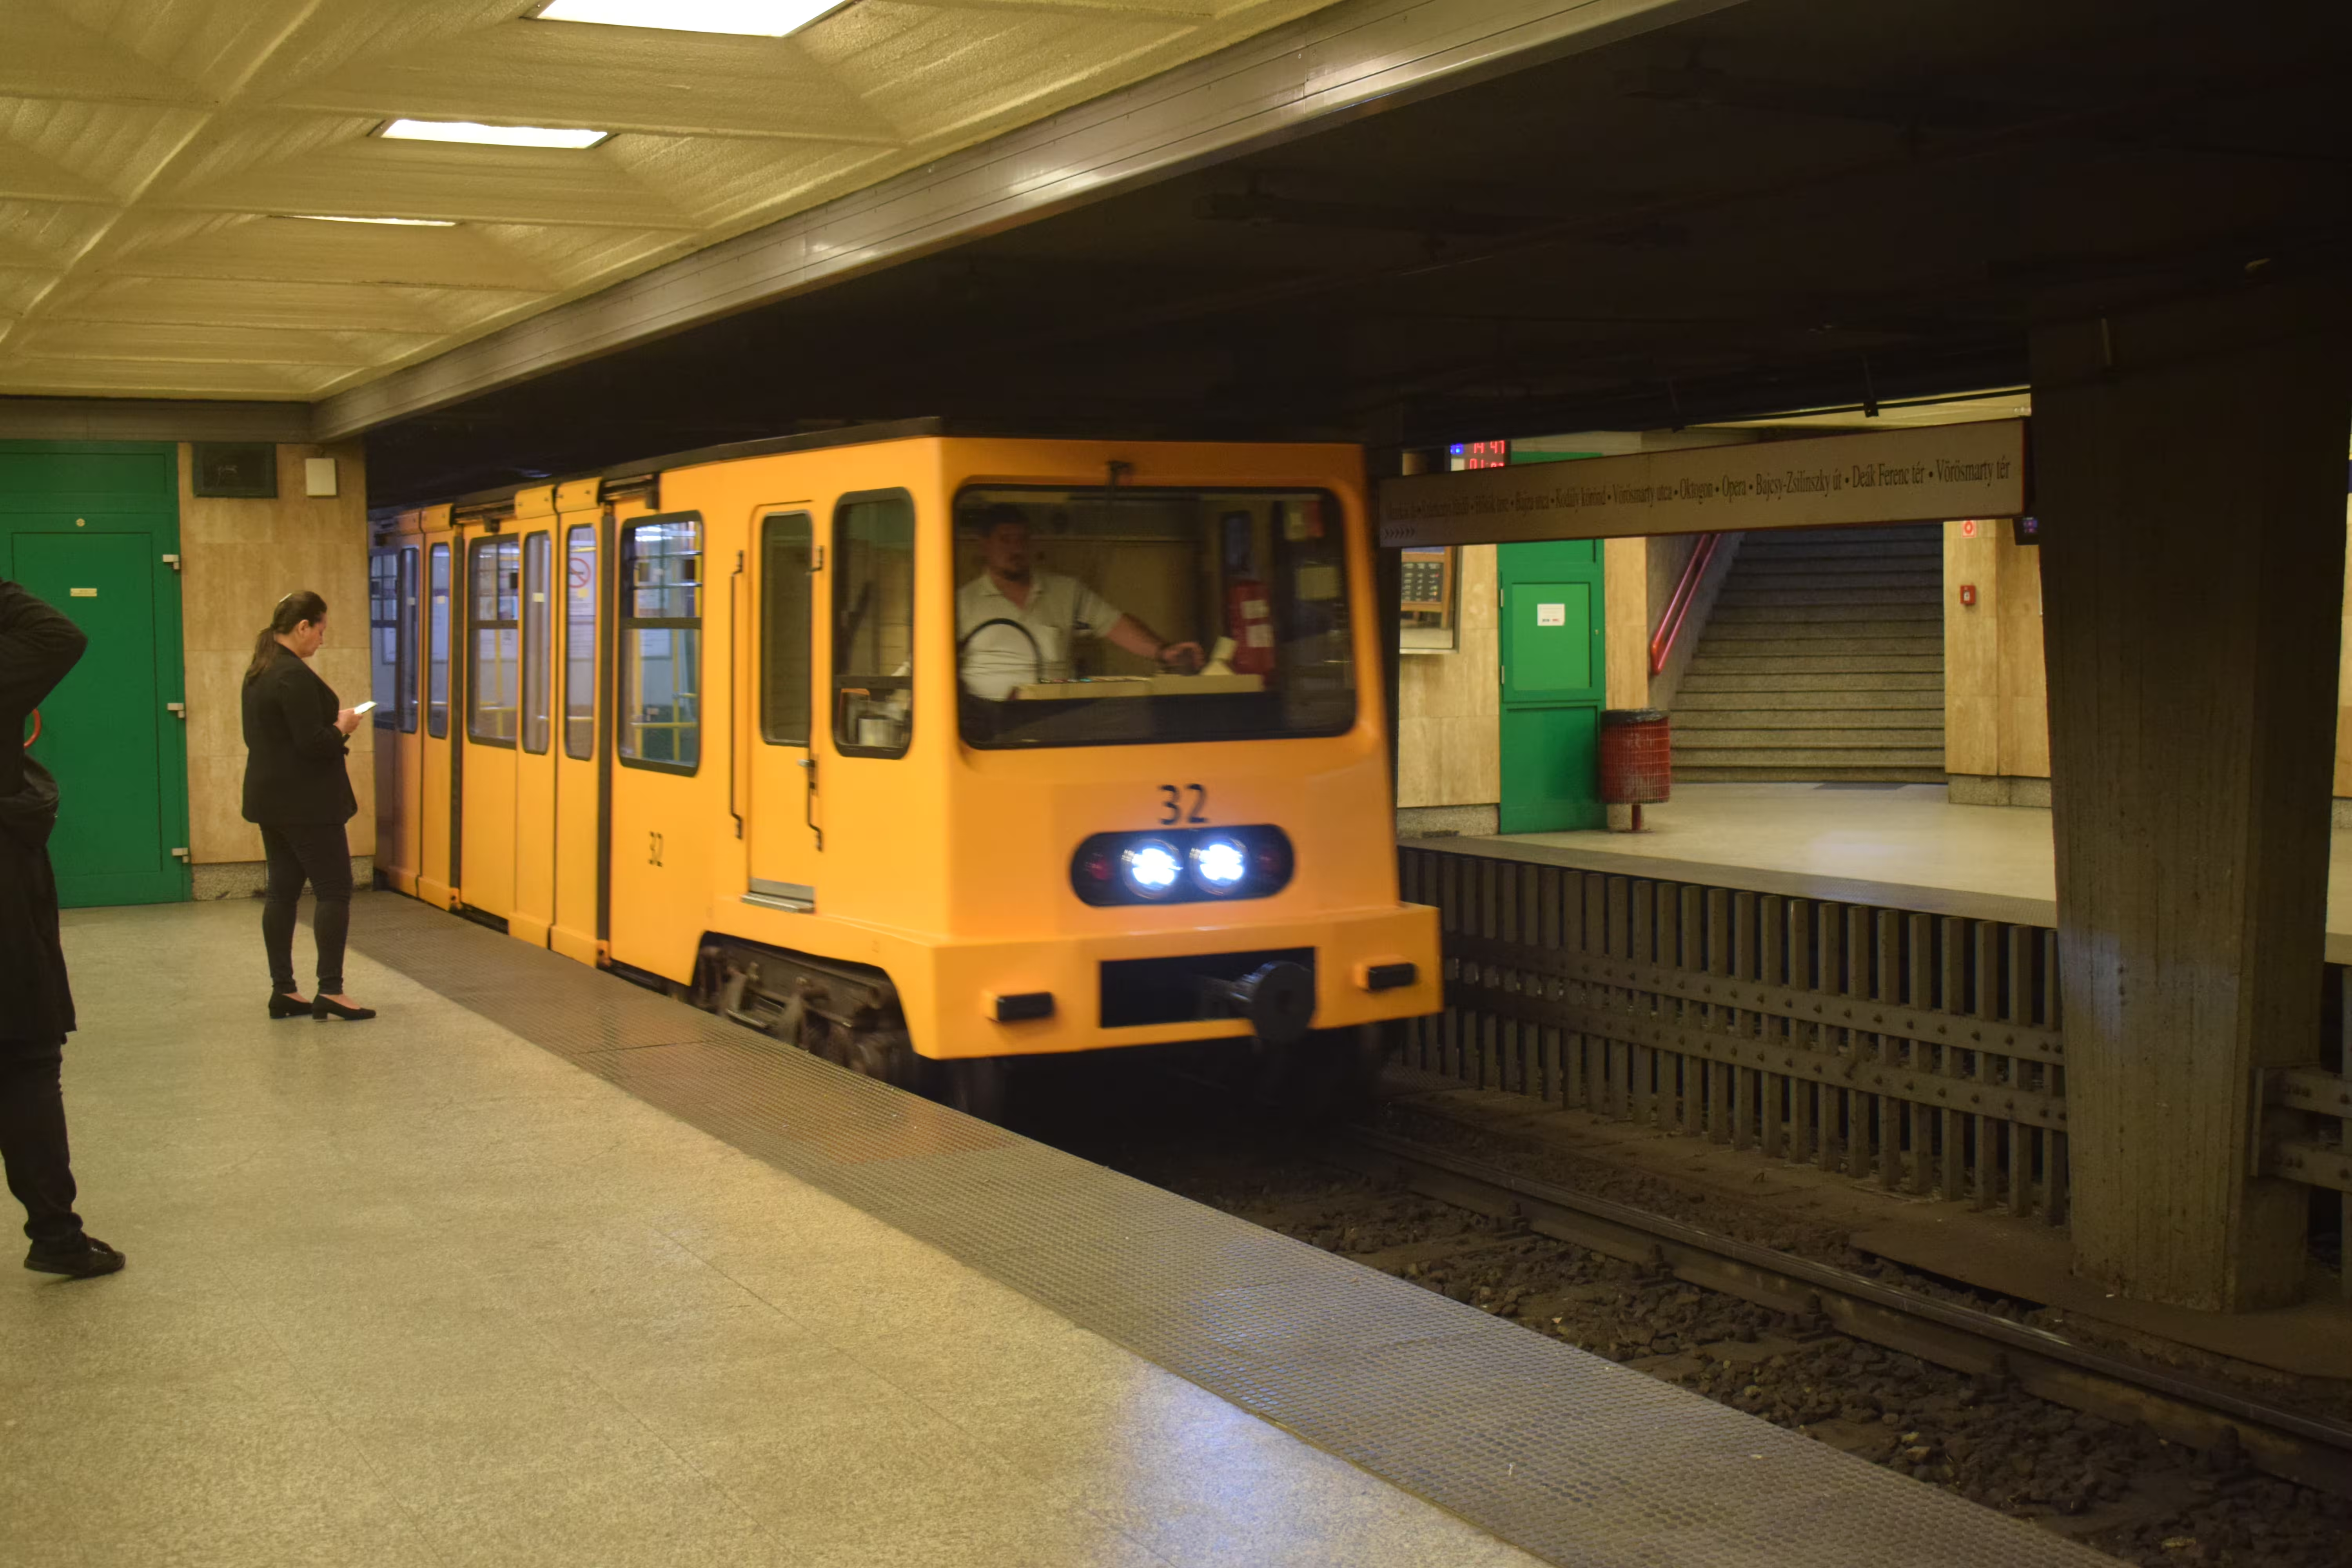 An M1 line metro train entering the station.
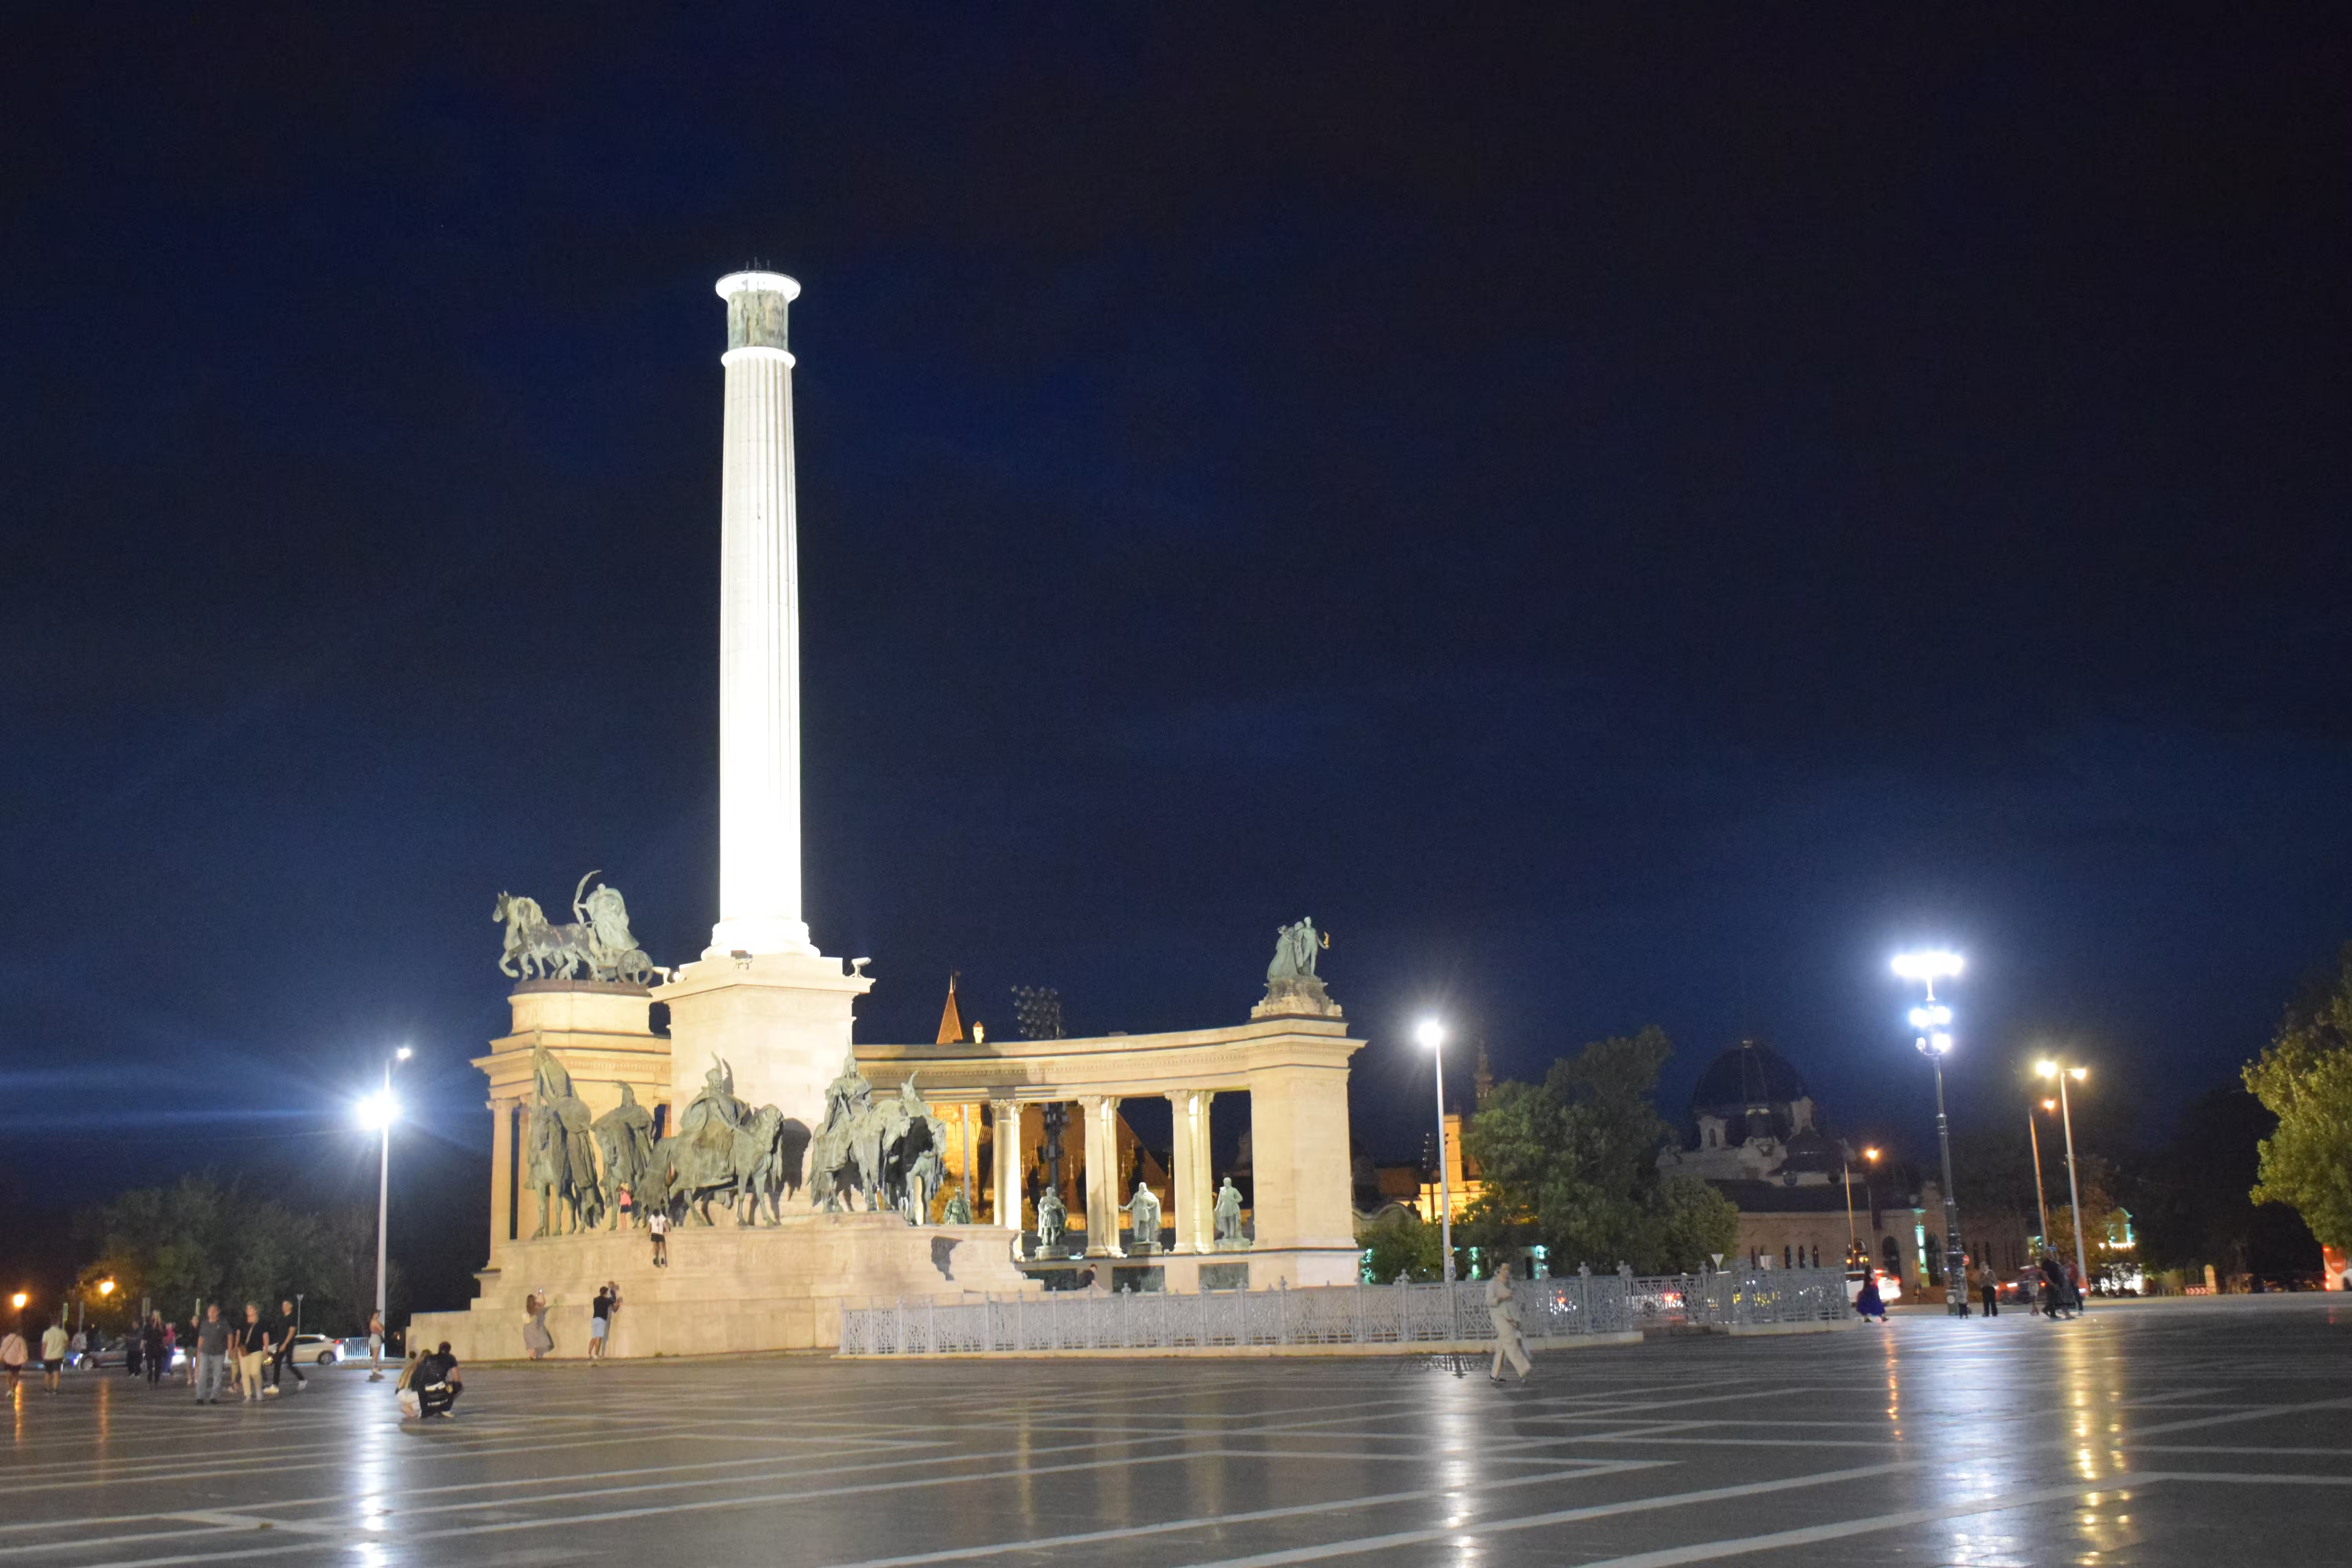 Heroes Square.
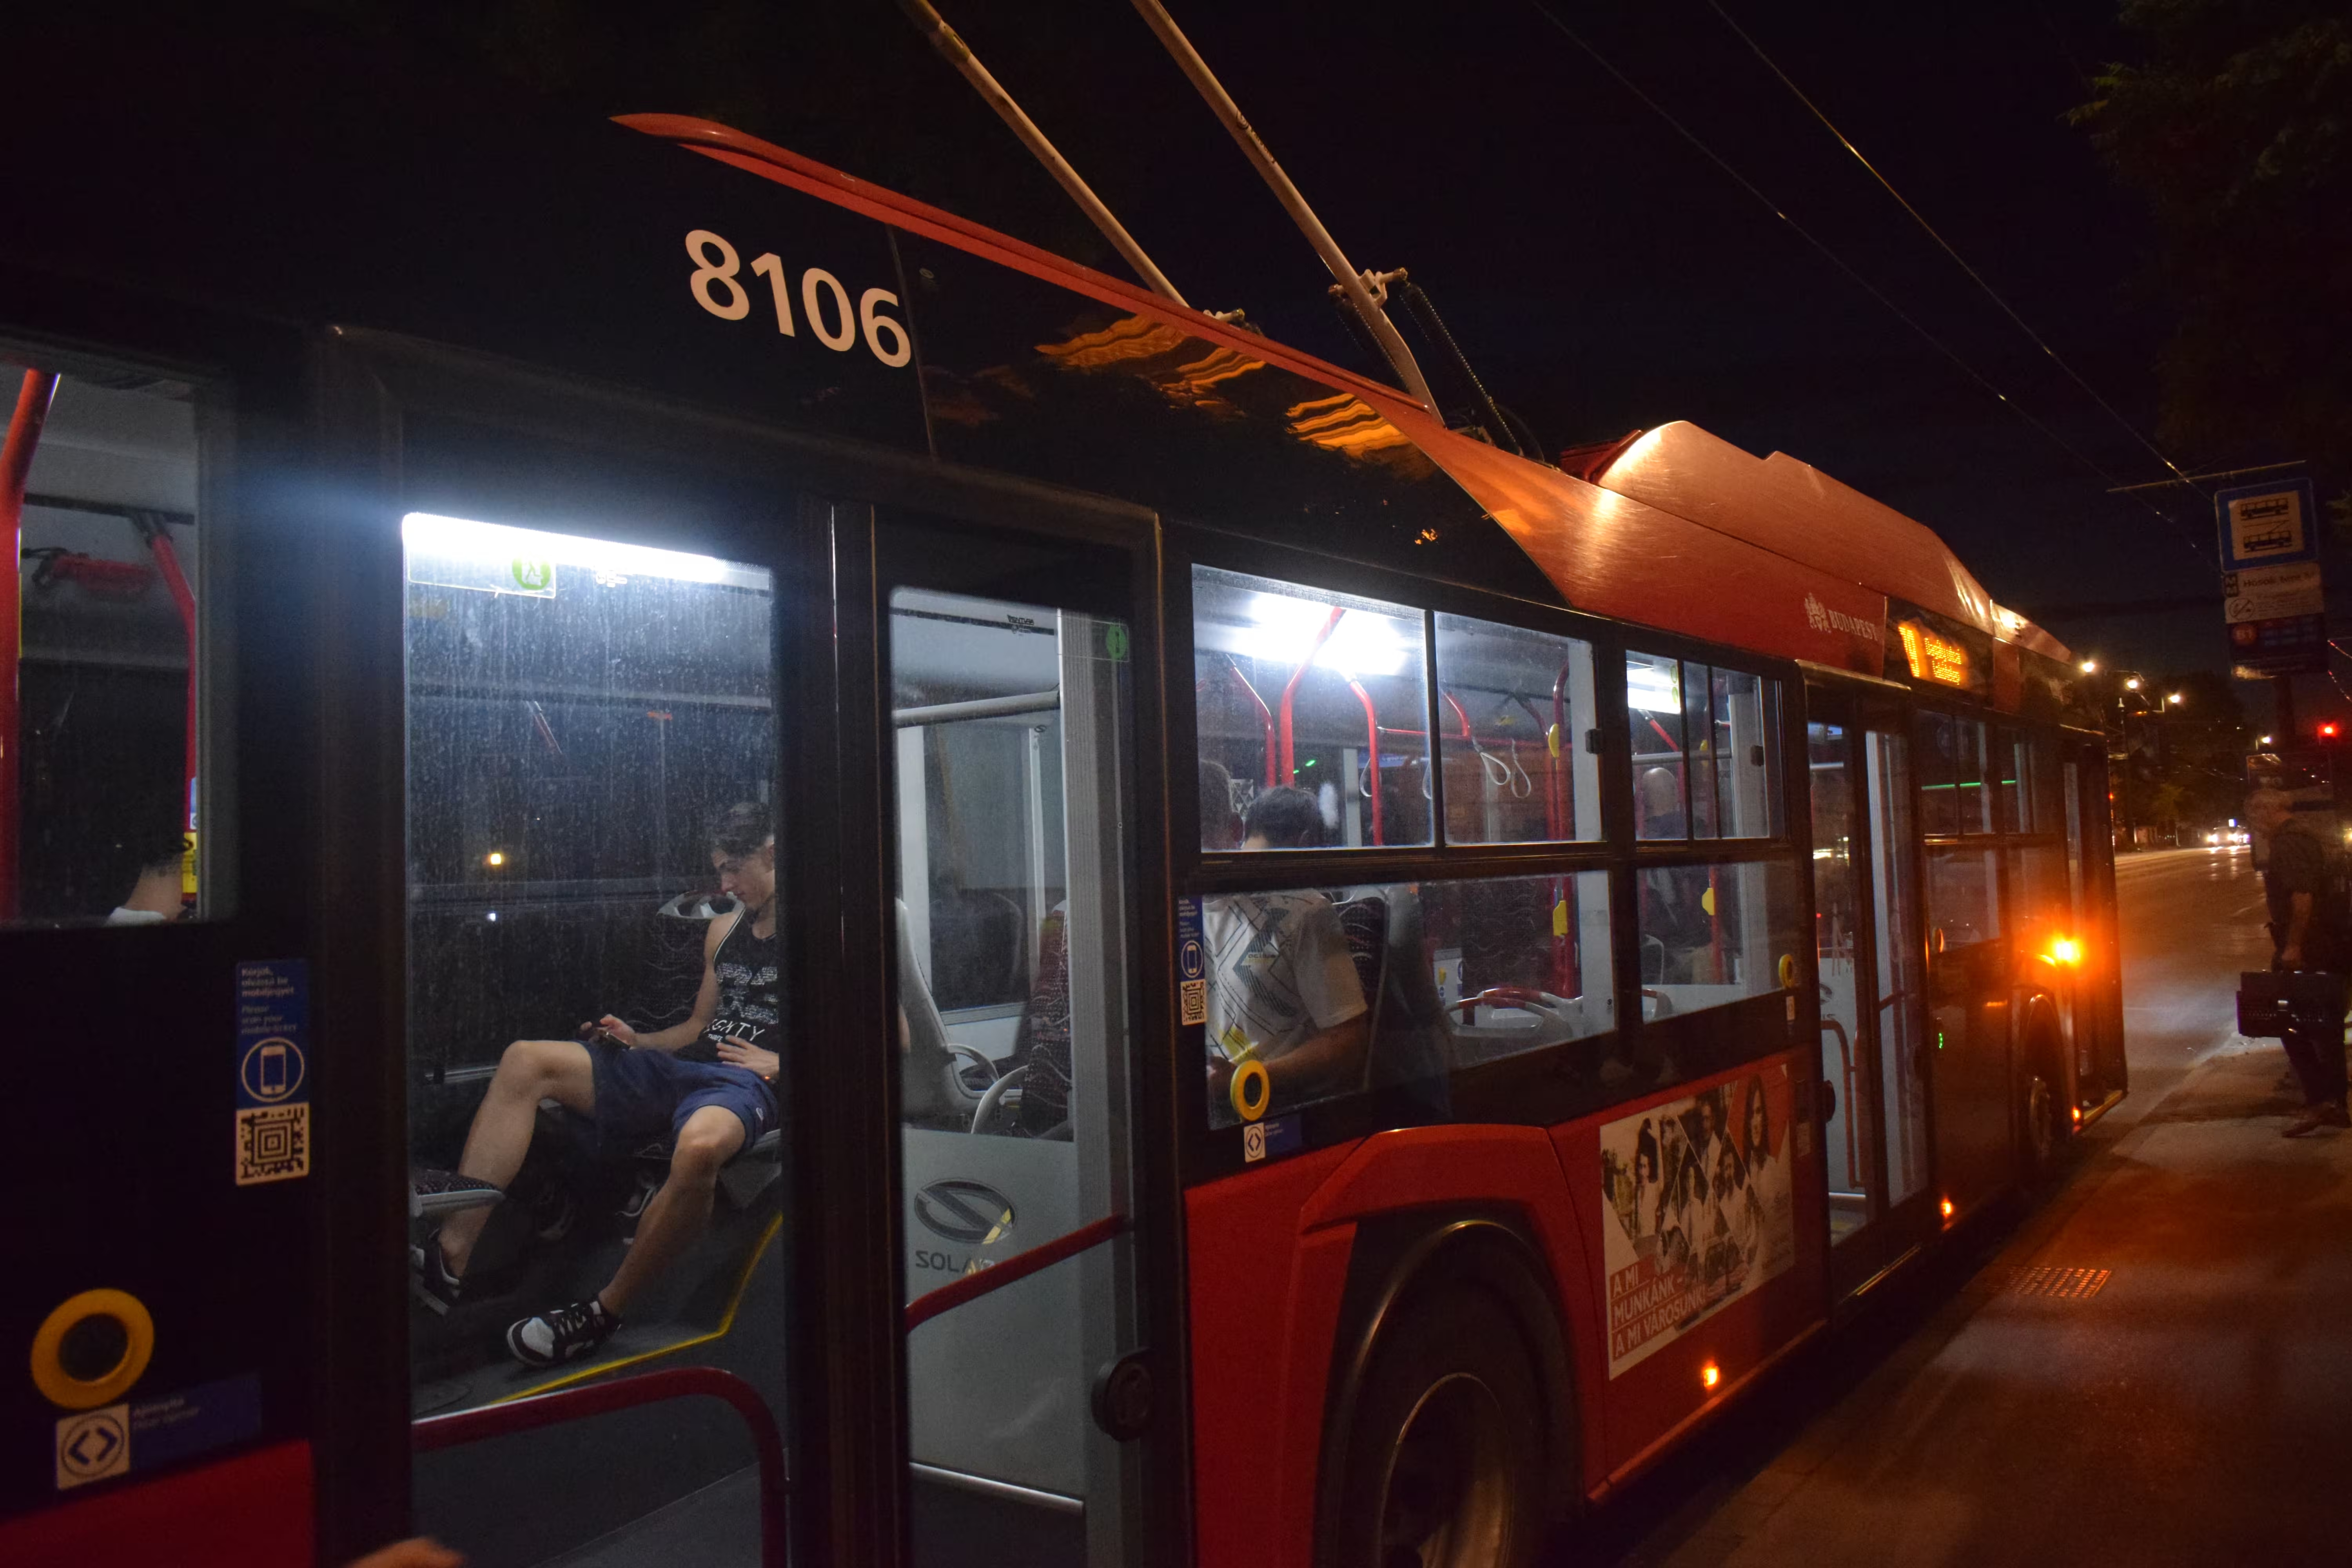 This is the trolleybus we took in Budapest.
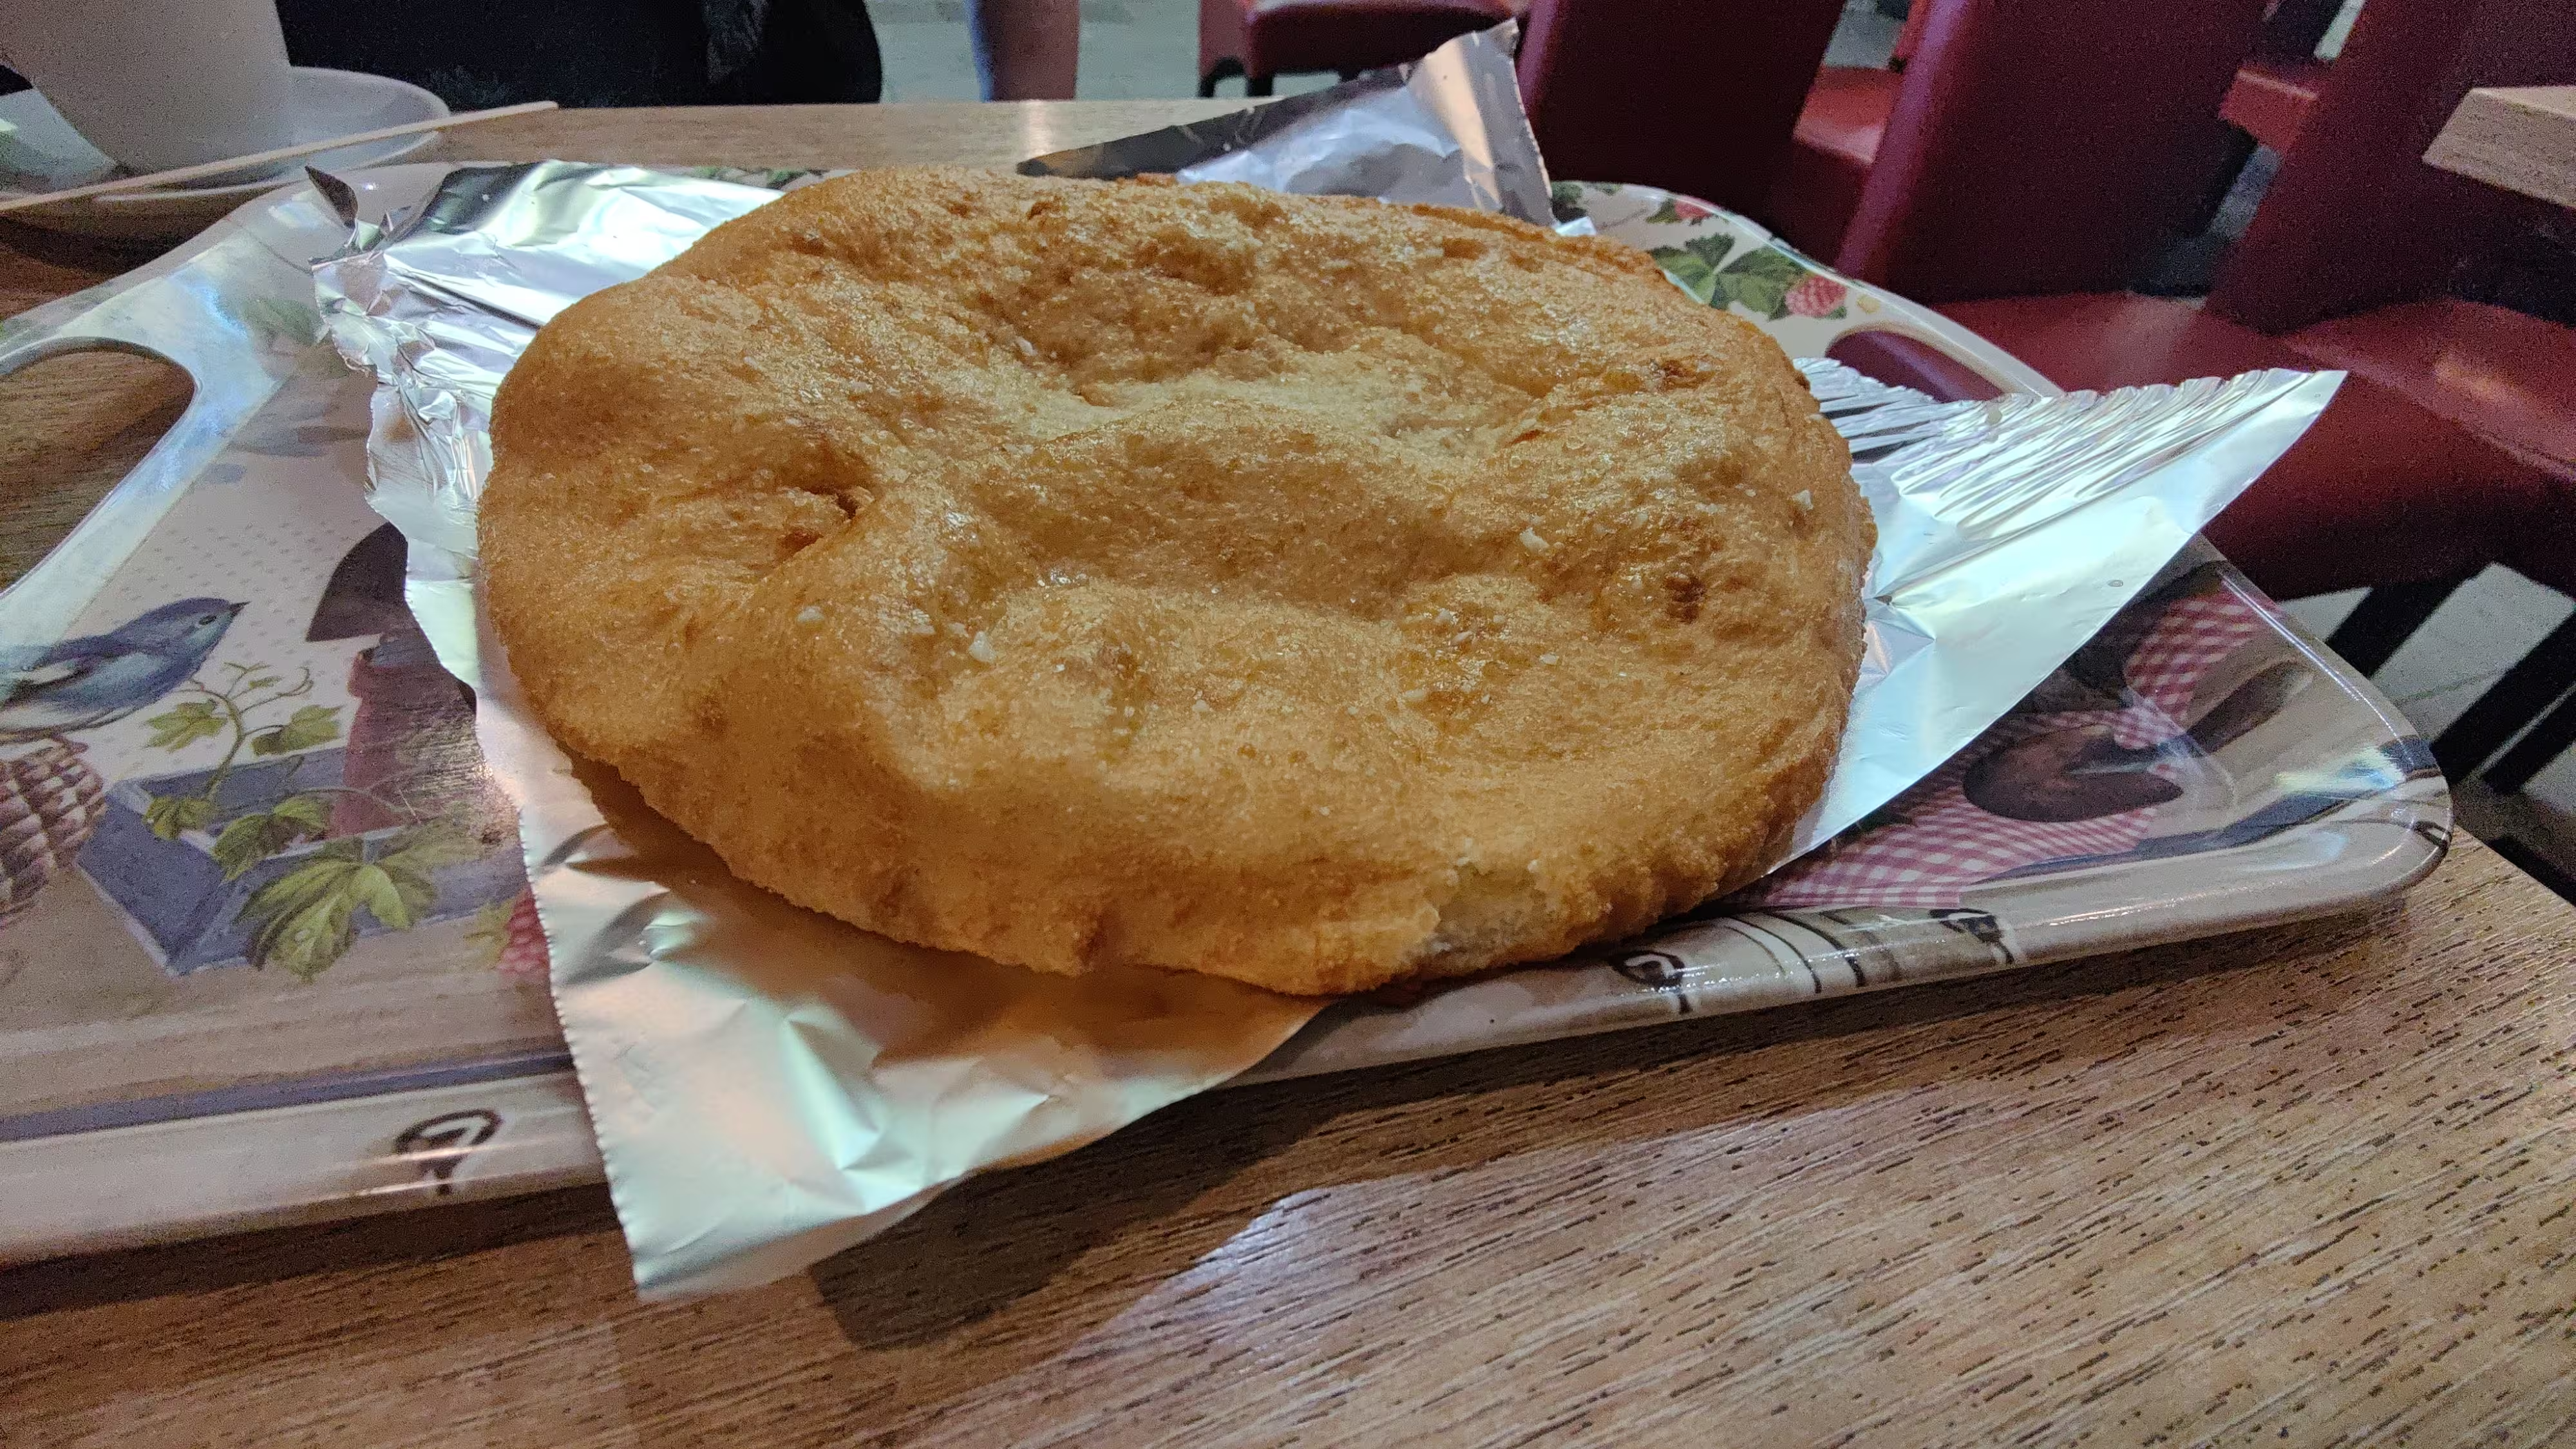 L ngos a dish which looks like the Indian flatbread bhatura.



 I am a teacher. Since January 2013, I have been teaching the Operating
Systems course at the
 Fishy, it really smells. Because the only code file Xxxx and Yyyyy wrote is

 Background
I'm a member of the EFI team in Debian, and I've done much of the
work for Debian to support UEFI Secure Boot (SB) in recent years. We
have included that support for a number of releases now, starting back
with Debian 10 (aka Buster).
I'm also a long-time accredited member of
the
 Another very minor update, now at 0.3.15, for our
 I was getting <XF86AudioPlay> is undefined in the status bar of Emacs displayed every 2-3 seconds. Nowhere else I noticed any misbehavior or problems, and also couldn t find any related log entries. It didn t stop, though didn t want to reboot my system to see whether that would fix the problem, but it was driving me nuts.
Now, as a starting point I adjusted my sway configuration, to react to the XF86AudioPlay key press event: