Search Results: "spa"

12 April 2026

Colin Watson: Free software activity in March 2026

My Debian contributions this month were all sponsored by Freexian. You can also support my work directly via Liberapay or GitHub Sponsors. OpenSSH I fixed CVE-2026-3497 in unstable, thanks to a fix in Ubuntu by Marc Deslauriers. Relatedly, I applied an Ubuntu patch by Athos Ribeiro to not default to weak GSS-API exchange algorithms. I m looking forward to being able to split out GSS-API key exchange support in OpenSSH once Ubuntu 26.04 LTS has been released! This stuff will still be my problem, but at least it won t be in packages that nearly everyone has installed. Python packaging New upstream versions: I packaged pybind11-stubgen, needed for new upstream versions of pytango. Tests of reproducible builds revealed that it didn t generate imports in a stable order; I contributed a fix for that upstream. I worked with the security team to release DSA-6161-1 in multipart, fixing CVE-2026-28356 (upstream discussion). (Most of the work for this was in February, but the vulnerability was still embargoed when I published my last monthly update.) In trixie-backports, I updated pytest-django to 4.12.0. I fixed a number of packages to support building with pyo3 0.28: Other build/test failures: Rust packaging New upstream versions: Other bits and pieces I upgraded tango to 10.1.2, and yubihsm-shell to 2.7.2. Code reviews

Vasudev Kamath: Hardening the Unpacakgeable: A systemd-run Sandbox for Third-Party Binaries

The Shift in Software Consumption Historically, I have been a "distribution-first" user. Sticking to tools packaged within the Debian archives provides a layer of trust; maintainers validate licenses, audit code, and ensure the entire dependency chain is verified. However, the rapid pace of development in the Generative AI space specifically with new tools like Gemini-CLI has made this traditional approach difficult to sustain. Many modern CLI tools are built within the npm or Python ecosystems. For a distribution packager, these are a nightmare; packaging a single tool often requires packaging a massive, shifting dependency chain. Consequently, I found myself forced to use third-party binaries, bypassing the safety of the Debian archive.
The Supply Chain Risk Recent supply chain attacks affecting widely used packages like axios and LiteLLM have made it clear: running unvetted binaries on a personal system is a significant risk. These scripts often have full access to your $HOME directory, SSH keys, and the system D-Bus. After discussing these concerns with a colleague, I was inspired by his approach using a Flatpak-style sandbox for even basic applications like Google Chrome. I decided to build a generalized version of this using OpenCode and Qwen 3.6 Fast (which was available for free use at the time) to create a robust, transient sandbox utility.
The Solution: safe-run-binary My script, safe-run-binary, leverages systemd-run to execute binaries within an isolated scope. It implements strict filesystem masking and resource control to ensure that even if a dependency is compromised, the "blast radius" is contained.
Key Technical Features
1. Virtualized Home Directory (tmpfs)
Instead of exposing my real home directory, the script mounts a tmpfs over $HOME. It then selectively creates and bind-mounts only the necessary subdirectories (like .cache or .config) into a virtual structure. This prevents the application from ever "seeing" sensitive files like ~/.ssh or ~/.gnupg.
2. D-Bus Isolation via xdg-dbus-proxy
For GUI applications, providing raw access to the D-Bus is a security hole. The script uses xdg-dbus-proxy to sit between the application and the system bus. By using the --filter and --talk=org.freedesktop.portal.* flags, the app can only communicate with necessary portals (like the file picker) rather than sniffing the entire bus.
3. Linux Namespace Restrictions

The sandbox utilizes several systemd execution properties to harden the process:

  • RestrictNamespaces=yes: For CLI tools, this prevents the app from creating its own nested namespaces.
  • PrivateTmp=yes: Ensures a private /tmp space that isn't shared with the host.
  • NoNewPrivileges=yes: Prevents the binary from gaining elevated permissions through SUID/SGID bits.
4. GPU and Audio Passthrough
The script intelligently detects and binds Wayland, PipeWire, and NVIDIA/DRI device nodes. This allows browsers like Firefox to run with full hardware acceleration and audio support while remaining locked out of the rest of the filesystem.
Usage To run a CLI tool like Gemini-CLI with access only to a specific directory:
safe-run-binary -b ~/.gemini-config -- npx @google/gemini-cli
For a GUI application like Firefox:
safe-run-binary --gui -b ~/.mozilla -b ~/.cache/mozilla -b ~/Downloads -- firefox
Conclusion While it is not always possible to escape the need for third-party software, it is possible to control the environment in which it operates. By leveraging native Linux primitives like systemd and namespaces, high-grade isolation is achievable. PS: If you spot any issues or have suggestions for improving the script, feel free to raise a PR on the repo.

10 April 2026

Reproducible Builds: Reproducible Builds in March 2026

Welcome to the March 2026 report from the Reproducible Builds project! These reports outline what we ve been up to over the past month, highlighting items of news from elsewhere in the increasingly-important area of software supply-chain security. As ever, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website.

  1. Linux kernel hash-based integrity checking proposed
  2. Distribution work
  3. Tool development
  4. Upstream patches
  5. Documentation updates
  6. Two new academic papers
  7. Misc news

Linux kernel hash-based integrity checking proposed Eric Biggers posted to the Linux Kernel Mailing List in response to a patch series posted by Thomas Wei schuh to introduce a calculated hash-based system of integrity checking to complement the existing signature-based approach. Thomas original post mentions:
The current signature-based module integrity checking has some drawbacks in combination with reproducible builds. Either the module signing key is generated at build time, which makes the build unreproducible, or a static signing key is used, which precludes rebuilds by third parties and makes the whole build and packaging process much more complicated.
However, Eric s followup message goes further:
I think this actually undersells the feature. It s also much simpler than the signature-based module authentication. The latter relies on PKCS#7, X.509, ASN.1, OID registry, crypto_sig API, etc in addition to the implementations of the actual signature algorithm (RSA / ECDSA / ML-DSA) and at least one hash algorithm.

Distribution work In Debian this month,
  • Lucas Nussbaum announced Debaudit, a new service to verify the reproducibility of Debian source packages :
    debaudit complements the work of the Reproducible Builds project. While reproduce.debian.net focuses on ensuring that binary packages can be bit-for-bit reproduced from their source packages, debaudit focuses on the preceding step: ensuring that the source package itself is a faithful and reproducible representation of its upstream source or Vcs-Git repository.
  • kpcyrd filed a bug against the librust-const-random-dev package reporting that the compile-time-rng feature of the ahash crate uses the const-random crate in turn, which uses a macro to read/generate a random number generator during the build. This issue was also filed upstream.
  • 60 reviews of Debian packages were added, 4 were updated and 16 were removed this month adding to our knowledge about identified issues. One new issue types was added, pkgjs_lock_json_file_issue.
Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their work there.

Tool development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions, 314 and 315 to Debian.
  • Chris Lamb:
    • Don t run test_code_is_black_clean test in the autopkgtests. (#1130402). [ ]
    • Add some debugging info for PyPI debugging. [ ]
  • Jelle van der Waa:
    • Fix compatibility with LLVM version 22. [ ]
    • Adjust the PGP file detection regular expression. [ ]
  • Michael R. Crusoe:
    • Reformat the source code using Black version 26.1.0 [ ][ ]
In addition, Vagrant Cascadian updated diffoscope in GNU Guix to version 315.
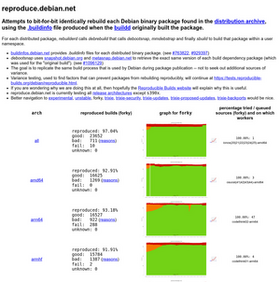
rebuilderd, our server designed monitor the official package repositories of Linux distributions and attempt to reproduce the observed results there; it powers, amongst other things, reproduce.debian.net. A new version, 0.26.0, was released this month, with the following improvements:
  • Much smoother onboarding/installation.
  • Complete database redesign with many improvements.
  • New REST HTTP API.
  • It s now possible to artificially delay the first reproduce attempt. This gives archive infrastructure more time to catch up.
  • And many, many other changes.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Documentation updates Once again, there were a number of improvements made to our website this month including:
  • kpcyrd:
    • Add a new page about Rust specifics. [ ][ ][ ]
  • Robin Candau:
    • Add link to the diffoci Arch Linux package on the Tools page. [ ]
  • Timo Pohl:

Two new academic papers Marc Ohm, Timo Pohl, Ben Swierzy and Michael Meier published a paper on the threat of cache poisoning in the Python ecosystem: Attacks on software supply chains are on the rise, and attackers are becoming increasingly creative in how they inject malicious code into software components. This paper is the first to investigate Python cache poisoning, which manipulates bytecode cache files to execute malicious code without altering the human-readable source code. We demonstrate a proof of concept, showing that an attacker can inject malicious bytecode into a cache file without failing the Python interpreter s integrity checks. In a large-scale analysis of the Python Package Index, we find that about 12,500 packages are distributed with cache files. Through manual investigation of cache files that cannot be reproduced automatically from the corresponding source files, we identify classes of reasons for irreproducibility to locate malicious cache files. While we did not identify any malware leveraging this attack vector, we demonstrate that several widespread package managers are vulnerable to such attacks. A PDF of the paper is available online.
Mario Lins of the University of Linz, Austria, has published their PhD doctoral thesis on the topic of Software supply chain transparency: We begin by examining threats to the software distribution stage the point at which artifacts (e.g., mobile apps) are delivered to end users with an emphasis on mobile ecosystems [and] we next focus on the operating system on mobile devices, with an emphasis on mitigating bootloader-targeted attacks. We demonstrate how to compensate lost security guarantees on devices with an unlocked bootloader. This allows users to flash custom operating systems on devices that no longer receive security updates from the original manufacturer without compromising security. We then move to the source code stage. [Also,] we introduce a new architecture to ensure strong source-to-binary correspondence by leveraging the security guarantees of Confidential Computing technology. Finally, we present The Supply Chain Game, an organizational security approach that enhances standard risk-management methods. We demonstrate how game-theoretic techniques, combined with common risk management practices, can derive new criteria to better support decision makers. A PDF of the paper is available online.

Misc news On our mailing list this month:
  • Holger Levsen announced that this year s Reproducible Builds summit will almost certainly be held in Gothenburg, Sweden, from September 22 until 24, followed by two days of hacking. However, these dates are preliminary and not 100% final an official announcement is forthcoming.
  • Mark Wielaard posted to our list asking a question on the difference between debugedit and relative debug paths based on a comment on the Build path page: Have people tried more modern versions of debugedit to get deterministic (absolute) DWARF paths and found issues with it?


Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

4 April 2026

Isoken Ibizugbe: Post Outreachy Activities

It s been about a month since I wrapped up my Outreachy internship, but my journey with Debian is far from over. I planned to keep contributing and exploring the community, and these past few weeks have been busy

Testing Locales and Solving Bug #1111214

For the openQA project, we decided to explore how accurate local language installations are and see if we can improve the translations. While exploring this, I started working on automating a test for a specific bug report: Debian Bug #1111214

This is a test I had started by writing a detailed description of the installation process to confirm that selecting the Spanish_panama locale works accurately. I spent time studying previous language installation tests, and I learned that I needed to add a specific tag (LANGUAGE-) to the needles (visual test markers).

Since the installation wasn t in English anymore, taking the correct screenshots and defining the areas took quite some time. I used the following command on the CLI to run the test:

openqa-cli api -X POST isos ISO=debian-live-testing-amd64-gnome.iso DISTRI=debian-live VERSION=forky FLAVOR=gnome LANGUAGE=spanish_panama ARCH=x86_64 BUILD=1311 CHECKSUM=unknown

While working on this, I got stuck at the complete_installation step. Because the keyboard layout had changed to Spanish, the commands required to confirm a successful install weren t working as expected. Specifically, we had an issue typing the greater than sign (>).

My mentor, Roland Clobus, worked on a clever maneuver for the keys (AltGr-Shift-X), which was actually submitted upstream to openSUSE.

In this step, I also had to confirm that the locale was correctly set to LANG= es_PA.UTF-8 . I had to dig into the scripts and Linux commands to make this work. It was a bit intimidating at first, but it turned out to be a great learning experience. You can follow my progress on this Merge Request here. I m currently debugging a small issue where the home key seems to click twice in the final step, and after that, the test would be complete  .

Community & Connections

Beyond the code, I ve been getting more involved in the social side of Debian:

  • Debian Women: I attended the monthly meeting and met Sruthi Chandran. I ve always seen her name as an Outreachy organizer, so it was great to meet her! She is currently running for Debian Project Leader (DPL). We also discussed starting technical sessions to introduce members to packaging, which I am very excited to learn.
  • DebConf Preparation: I am officially preparing for my first DebConf! My mentors, Tassia and Roland, along with my fellow intern Hellen, have been incredibly supportive in guiding me through the application and presentation process.

Dima Kogan: Simple gpx export from ridewithgps

The Tour de Los Padres is coming! The race organizer post the route on ridewithgps. This works, but has convoluted interfaces for people not wanting to use their service. I just wrote a simple script to export their data into a plain .gpx file, including all the waypoints; their exporter omits those. I've seen two flavors of their data, so here're two flavors of the gpx-from-ridewithgps.py script:
#!/usr/bin/python3
import sys
import json
def quote_xml(s):
    return s.replace("&", "&amp;").replace("<", "&lt;").replace(">", "&gt;")
print("Reading stdin", file=sys.stderr)
data = json.load(sys.stdin)
print(r"""<?xml version="1.0" encoding="UTF-8"?>
<gpx version="1.1" creator="gpx-from-ridewithgps.py" xmlns="http://www.topografix.com/GPX/1/1">""")
for item in data["extras"]:
    if item["type"] != "point_of_interest":
        continue
    poi = item["point_of_interest"]
    print(f'  <wpt lat=" poi["lat"] " lon=" poi["lng"] ">')
    print(f'    <name> quote_xml(poi["name"]) </name>')
    desc = poi.get("description","")
    if len(desc):
        print(f'    <desc> quote_xml(desc) </desc>')
    print(f'  </wpt>')
print("  <trk><trkseg>")
for pt in data.get("route",  ).get("track_points", []):
    print(f'    <trkpt lat=" pt["y"] " lon=" pt["x"] "><ele> pt["e"] </ele></trkpt>')
print("  </trkseg></trk>")
print("</gpx>")
#!/usr/bin/python3
import sys
import json
def quote_xml(s):
    return s.replace("&", "&amp;").replace("<", "&lt;").replace(">", "&gt;")
print("Reading stdin", file=sys.stderr)
data = json.load(sys.stdin)
print(r"""<?xml version="1.0" encoding="UTF-8"?>
<gpx version="1.1" creator="gpx-from-ridewithgps.py" xmlns="http://www.topografix.com/GPX/1/1">""")
for poi in data["points_of_interest"]:
    print(f'  <wpt lat=" poi["lat"] " lon=" poi["lng"] ">')
    print(f'    <name> quote_xml(poi["name"]) </name>')
    desc = poi.get("description","")
    if len(desc):
        print(f'    <desc> quote_xml(desc) </desc>')
    print(f'  </wpt>')
for poi in data["course_points"]:
    print(f'  <wpt lat=" poi["y"] " lon=" poi["x"] ">')
    print(f'    <name> quote_xml(poi["n"]) </name>')
    print(f'  </wpt>')
print("  <trk><trkseg>")
for pt in data['track_points']:
    print(f'    <trkpt lat=" pt["y"] " lon=" pt["x"] "><ele> pt["e"] </ele></trkpt>')
print("  </trkseg></trk>")
print("</gpx>")
You invoke it by downloading the route and feeding it into the script:
curl -s https://ridewithgps.com/routes/54493422.json   ./ridewithgps-to-gpx.py > out.gpx
Note that the route number 54493422 is in the url above.

2 April 2026

Joerg Jaspert: Building a house - 1 year in

Haven t written here about it, but last March we finally started on our journey to get our own house build, so we can move out of the rented flat here. That will be a big step, both the actual building, but also the moving - I am living at this one single place for 36 years now. If you can read german there is a dedicated webpage where I sometimes write about the process. Will have much more details (and way more ramblings) than the following part. If you can t read german, a somewhat short summary follows. Yes, still a lot of text, but shortened, still.

What? Why now? Current flat has 83m - which simply isn t enough space. And the number of rooms also doesn t fit anymore. But it is hard to find a place that fits our requirements (which do include location). Moving to a different rented place would also mean changed amount of rent. And nowadays that would be huge increase (my current rent is still the price from about 30 years ago!). So if we go and pay more - we could adjust and pay for something we own instead. And both, my wife and I had changes in our jobs that made it possible for us now, so we started looking.

Market Brrrr, looking is good, actually finding something that fits - not so. We never found an offer that fit. Space wise, sure. But then location was off, or price was idiotically high. Location fit, but then size was a joke, and guess about the price Who needs 200 square meters with 3 rooms? Entirely stupid design choices there. Or how about 40 square meters of hallway - with 50m of tiny rooms around. What are they smoking? Oh, there, useful size, good rooms - but now you want more money than a kidney is worth, or something. Thanks, no.

New place In February 2025 we finally got lucky and found a (newly opened) area with a large number of places to build a house on. Had multiple talks with someone from on of the companies developing that area (there are two you can select from), then talked with banks and signed a contract in March 2025. We got promised that actual house construction would be first quarter of 2026, finished in second quarter.

House type There are basically 2 ways of building a new house (that matter here). First is called Massivhaus , second is called Fertighaus in german, roughly translating to solid and prefabricated. The latter commonly a wood based construction, though it doesn t need to be. The important part of it is the prefabrication, walls and stuff get assembled in a factory somewhere and then transported to your place, where they play big kid lego for a day and suddenly a house is there. A common thought is prefabricated is faster, but that is only a half true. Sure, the actual work on side is way shorter - usually one or two days and the house is done - while a massive construction usually takes weeks to build up. But that is only a tiny part of the time needed, the major part goes of into planning and waiting and in there it doesn t matter what material you end up with.

Money fun Last year already wasn t the best time to start a huge loan - but isn t it always a few years ago would have been better ? So we had multiple talks with different banks and specialised consultants until we found something that we thought is good for us. Thinking about it now - we should have put even more money on top as reserve , but who could have thought that 2026 turns into such a shitshow? Does not help at all, quite the contrary. And that damn lotto game always ends up with the wrong numbers, meh.

Plans and plans and more plans - and rules For whichever reason you can not just go and put something on your ground and be happy. At least not if you are part of the normal people and not enormously rich. There is a large set of rules to follow. Usually that is a good thing, even though some rules are sometimes hard to understand. In Germany, besides the usual laws, we have something that is called Bebauungsplan , which translates to development plan (don t know if that carries the right meaning, it s a plan on what and how may be build, which can have really detailed specifications in). It basically tells you every aspect on top of the normal law that you have to keep in mind. In our case we have the requirement of 2 full floors and CAN have a third smaller on top, it limits how high the house can be and also how high our ground floor may be compared to the street. It regulates where on the property we may build and how much ground we may cover with the house, it gives a set of colors we are allowed to use, it demands a flat roof that we must have as a green roof and has a number of things more that aren t important enough to list here. If you do want to see the full list, my german post on it has all the details that matter to us. With all that stuff in mind - off to plans. Wouldn t have believed how many details there are to take in. Room sizes are simple, but how to arrange them for ideal usage of the sun, useful ways inside the house, but also keeping in mind that water needs to flow through and out. Putting a bath room right atop a living room means a water pipe needs to go down there. Switch the bath room side in the house, and it suddenly is above the kitchen - means you can connect the pipes from it to the ones from kitchen, which is much preferred than going through the living room. And lots more such things. It took us until nearly end of October to finalize the plans! And we learned a whole load from it. We started with a lot of wishes. The planner tried to make them work. Then we changed our minds. Plans changed. Minds changed again. Comparing the end result with the first draft we changed most of the ground floor around, with only the stairs and the entrance door at the same position. Less changes for the upper floor, but still enough.

Side quests The whole year was riddled with something my son named side quests. We visited a construction exhibition near us, we went to the house builders factory and took a look on how they work. We went to many different other companies that do SOME type of work which we need soon, say inside floors, painters, kitchen and more stuff. Of course the most important side quest was a visit to the notary to finalize the contracts, especially for the plot of land (in Germany you must have a notary for that to get entered into the governments books). Creates lots of fees, of course, for the notary and also the government (both fees and taxes here).

Building permit We had been lucky and only needed a small change to the plans to get the building permit - and the second part, the wastewater permit (yes, you need a separate one for this) also got through without trouble.

Choices, so many of them So in January we finally had an appointment for something that s called Bemusterung which badly translates to Sampling . Basically two days at the house builders factory to select all of what s needed for the house that you don t do in the plans. Doors, inside and out and their type and color and handles. Same things for the windows and the blinds and the protection level you want the windows to have. Decide about stairs, design for the sanitary installations - and also the height of the toilet! - and the tiles to put into the bathrooms. Decisions on all the tech needed (heating system, ventilation and whatnot. Two days, busy ones - and you can easily spend a lot of extra money here if you aren t careful. We managed to get out of it with only about 4000 extra, so pretty good.

Electro and automation Now, here I am special. Back when I was young the job I learned is electrician. So here I have very detailed wishes. I am also running lots of automatism in my current flat - obviously the new house should be better than that. So I have a lot of ideas and thoughts on it, so this is entirely extra and certainly out of the ordinary the house builder usually see. Which means I do all of that on my own. Well, the planning and some of the work, I must have a company at hand for certain tasks, it is required by some rules. But they will do what I planned, as long as I don t violate regulations. Which means the whole electrical installation is different. Entirely planned for automatisms and using KNX for it. I am so happy to ditch Homeassistant and the load of Homematic, Zigbee and ZWave based wireless things. Ok, Homeassistant is a nice thing - it can do a lot. And it can bridge between about any system you can find. But it is a central single point of failure. And it is a system that needs constant maintenance. Not touched for a while? Plan for a few hours playing update whack-a-mole. And often enough a component here or there breaks with an update. Can be fixed, but takes another hour or two. So I change. Away from wireless based stuff. To wires. To a system thats a standard for decades already. And works entirely without a SPOF. (Yes, you can add one here too). And, most important, should I ever die - can easily be maintained by anyone out there dealing with KNX, which is a large number of people and companies. Without digging through dozens of specialised integrations and whatnot. I may even end up with Homeassistant again - but that will entirely be as a client. It won t drive automations. It won t be the central point to do anything for the house. It will be a logging and data collecting thing that enables me to put up easy visualizations. It may be an easy interface for smartphones or tablets to control parts of the house, for those parts where one wants this to happen. Not the usual day-to-day stuff, extras on top.

Actual work happening Since march there finally is action visible. The base of the house is getting build. Wednesday the 1st April we finally got the base slab poured on the construction site and in another 10 days the house is getting delivered and build up. A 40ton mobile crane will be there.

Samuel Henrique: Bringing HTTP/3 to curl on Amazon Linux

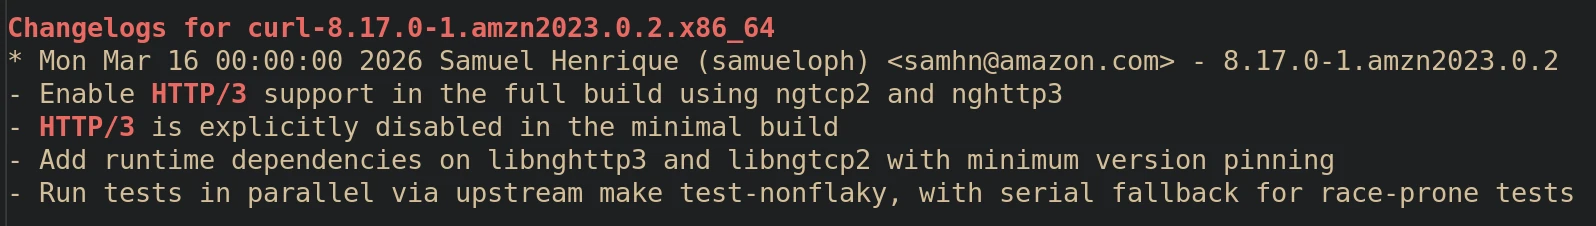
Screenshot of the top entry of the curl package's changelog, showing the following: Changelogs for curl-8.17.0-1.amzn2023.0.2.x86_64 * Mon Mar 16 00:00:00 2026 Samuel Henrique (samueloph) <samhn@amazon.com> - 8.17.0-1.amzn2023.0.2 - Enable HTTP/3 support in the full build using ngtcp2 and nghttp3 - HTTP/3 is explicitly disabled in the minimal build - Add runtime dependencies on libnghttp3 and libngtcp2 with minimum version pinning - Run tests in parallel via upstream make test-nonflaky, with serial fallback for race-prone tests

tl;dr Starting with curl 8.17.0-1.amzn2023.0.2 in Amazon Linux 2023, you can now use HTTP/3.
dnf swap -y libcurl-minimal libcurl-full
dnf swap -y curl-minimal curl-full
curl --http3-only https://example.com
(HTTP/3 is only enabled in the curl -full builds) Or, if you would like to try it out in a container:
podman run amazonlinux:2023 /bin/sh -c 'dnf upgrade -y --releasever=latest && dnf swap -y libcurl-minimal libcurl-full && dnf swap -y curl-minimal curl-full && curl --http3-only https://example.com'
For a list of test endpoints, you can refer to https://bagder.github.io/HTTP3-test/

The Upgrade I Didn't Have to Make My teammate Steve Zarkos, who previously worked on upgrading OpenSSL in Amazon Linux from 3.0 to 3.2, spent the last few months on the complex task of bumping OpenSSL again, this time to 3.5. A bump like this only happens after extensive code analysis and testing, something that I didn't foresee happening when AL2023 was released but that was a notable request from users. Having enabled HTTP/3 on Debian, I was always keeping an eye on when I would get to do the same for Amazon Linux (mind you, I work at AWS, in the Amazon Linux org). The bump to OpenSSL 3.5 was the perfect opportunity to do that, for the first time Amazon Linux is shipping an OpenSSL version that is supported by ngtcp2 for HTTP/3 support.

Non-Intrusive Change In order to avoid any intrusive changes to existing users of AL2023, I've only enabled HTTP/3 in the full build of curl, not in the minimal one, this means there is no change for the minimal images. The way curl handles HTTP/3 today also does not lead to any behavior changes for those who have the full variants of curl installed, this is due to the fact that HTTP/3 is only used if the user explicitly asks for it with the flags --http3 or --http3-only.

Side Quests Supporting HTTP/3 on curl also requires building it with ngtcp2 and nghttp3, two packages which were not shipped in Amazon Linux, besides, my team doesn't even own the curl package, we are a security team so our packages are the security related stuff such as OpenSSL and GnuTLS. Our main focus is the services behind Amazon Linux's vulnerability handling, not package maintenance. I worked with the owners of the curl package and got approvals on a plan to introduce the two new dependencies under their ownership and to enable the feature on curl, I appreciate their responsiveness. Amazon Linux 2023 is forked from Fedora, so while introducing ngtcp2, I also sent a couple of Pull Requests upstream to keep things in sync: [ngtcp2] package latest release 1.21.0 [ngtcp2] do not skip tests While building the curl package in Amazon Linux, I've noticed the build was taking 1 hour from start to end, and the culprit was something well known to me; tests. The curl test suite is quite extensive, with more than 1600 tests, all of that running without parallelization, running two times for each build of the package; once for the minimal build and again for the full build. I had previously enabled parallel tests in Debian back in 2024 but never got around to submit the same improvements to Amazon Linux or Fedora, this is now fixed. The build times for Amazon Linux came down to 10 minutes under the same host (previously 1 hour), and Fedora promptly merged my PR to do the same there: [curl] run tests in parallel All of this uncovered a test which is timing-dependent, meaning it's not supposed to be run with high levels of parallelism, so there goes another PR, this time to curl: Flag test 766 as timing-dependent#21155 What started as enabling a single feature turned into improvements that landed in curl, Fedora, and Amazon Linux alike. I did this in a mix of work and volunteer time, mostly during work hours (work email address used when this was the case), but I'm glad I put in the extra time for the sake of improving curl for everyone.

Release Notes Amazon Linux 2023 release notes for 2023.10.20260330

1 April 2026

Matthew Garrett: Self hosting as much of my online presence as practical

Because I am bad at giving up on things, I ve been running my own email server for over 20 years. Some of that time it s been a PC at the end of a DSL line, some of that time it s been a Mac Mini in a data centre, and some of that time it s been a hosted VM. Last year I decided to bring it in house, and since then I ve been gradually consolidating as much of the rest of my online presence as possible on it. I mentioned this on Mastodon and a couple of people asked for more details, so here we are. First: my ISP doesn t guarantee a static IPv4 unless I m on a business plan and that seems like it d cost a bunch more, so I m doing what I described here: running a Wireguard link between a box that sits in a cupboard in my living room and the smallest OVH instance I can, with an additional IP address allocated to the VM and NATted over the VPN link. The practical outcome of this is that my home IP address is irrelevant and can change as much as it wants - my DNS points at the OVH IP, and traffic to that all ends up hitting my server. The server itself is pretty uninteresting. It s a refurbished HP EliteDesk which idles at 10W or so, along 2TB of NVMe and 32GB of RAM that I found under a pile of laptops in my office. We re not talking rackmount Xeon levels of performance, but it s entirely adequate for everything I m doing here. So. Let s talk about the services I m hosting.

Web This one s trivial. I m not really hosting much of a website right now, but what there is is served via Apache with a Let s Encrypt certificate. Nothing interesting at all here, other than the proxying that s going to be relevant later.

Email Inbound email is easy enough. I m running Postfix with a pretty stock configuration, and my MX records point at me. The same Let s Encrypt certificate is there for TLS delivery. I m using Dovecot as an IMAP server (again with the same cert). You can find plenty of guides on setting this up. Outbound email? That s harder. I m on a residential IP address, so if I send email directly nobody s going to deliver it. Going via my OVH address isn t going to be a lot better. I have a Google Workspace, so in the end I just made use of Google s SMTP relay service. There s various commerical alternatives available, I just chose this one because it didn t cost me anything more than I m already paying.

Blog My blog is largely static content generated by Hugo. Comments are Remark42 running in a Docker container. If you don t want to handle even that level of dynamic content you can use a third party comment provider like Disqus.

Mastodon I m deploying Mastodon pretty much along the lines of the upstream compose file. Apache is proxying /api/v1/streaming to the websocket provided by the streaming container and / to the actual Mastodon service. The only thing I tripped over for a while was the need to set the X-Forwarded-Proto header since otherwise you get stuck in a redirect loop of Mastodon receiving a request over http (because TLS termination is being done by the Apache proxy) and redirecting to https, except that s where we just came from. Mastodon is easily the heaviest part of all of this, using around 5GB of RAM and 60GB of disk for an instance with 3 users. This is more a point of principle than an especially good idea.

Bluesky I m arguably cheating here. Bluesky s federation model is quite different to Mastodon - while running a Mastodon service implies running the webview and other infrastructure associated with it, Bluesky has split that into multiple parts. User data is stored on Personal Data Servers, then aggregated from those by Relays, and then displayed on Appviews. Third parties can run any of these, but a user s actual posts are stored on a PDS. There are various reasons to run the others, for instance to implement alternative moderation policies, but if all you want is to ensure that you have control over your data, running a PDS is sufficient. I followed these instructions, other than using Apache as the frontend proxy rather than nginx, and it s all been working fine since then. In terms of ensuring that my data remains under my control, it s sufficient.

Backups I m using borgmatic, backing up to a local Synology NAS and also to my parents home (where I have another HP EliteDesk set up with an equivalent OVH IPv4 fronting setup). At some point I ll check that I m actually able to restore them.

Conclusion Most of what I post is now stored on a system that s happily living under a TV, but is available to the rest of the world just as visibly as if I used a hosted provider. Is this necessary? No. Does it improve my life? In no practical way. Does it generate additional complexity? Absolutely. Should you do it? Oh good heavens no. But you can, and once it s working it largely just keeps working, and there s a certain sense of comfort in knowing that my online presence is carefully contained in a small box making a gentle whirring noise.

31 March 2026

C.J. Collier: Finding: Promoting SeaBIOS Cloud Images to UEFI Secure Boot (Proxmox)

Discovery Legacy cloud templates often lack the partitioning and bootloader
binaries required for UEFI Secure Boot. Attempting to switch such a VM
to OVMF in Proxmox results in not a bootable disk. We discovered that
a surgical promotion is possible by manipulating the block device and
EFI variables from the hypervisor.

The Problem
  1. Protective MBR Flags: Legacy installers often set
    the pmbr_boot flag on the GPT s protective MBR. Strict UEFI
    implementations (OVMF) will ignore the GPT if this flag is present.
  2. Missing ESP: Cloud images often lack a FAT32 EFI
    System Partition (ESP).
  3. Variable Store: A fresh Proxmox
    efidisk0 is empty and lacks both the trust certificates
    (PK/KEK/db) and the BootOrder entries required for an automated
    boot.

The Promotion Rule To upgrade a SeaBIOS VM to Secure Boot without a full OS reinstall:
1. Surgical Partitioning: Map the disk on the host and
add a FAT32 partition (Type EF00). Clear the
pmbr_boot flag from the MBR. 2. Binary
Preparation: Boot the VM in SeaBIOS mode to install
shim and grub-efi packages. Use
grub2-mkconfig to populate the new ESP. 3. Trust
Injection: Use the virt-fw-vars utility on the
hypervisor to programmatically enroll the Red Hat/Microsoft CA keys and
any custom certificates (e.g., FreeIPA CA) into the VM s
efidisk. 4. Boot Pinning: Explicitly set
the UEFI BootOrder to point to the shimx64.efi
path via virt-fw-vars --append-boot-filepath.

Solution (Example Command
Sequence) On the Proxmox Host (root):
# Map and Clean MBR
DEV=$(rbd map pool/disk)
parted -s $DEV disk_set pmbr_boot off

# Inject Trust and Boot Path (VM must be stopped)
virt-fw-vars --inplace /dev/rbd/mapped_efidisk \
  --enroll-redhat \
  --add-db <GUID> /path/to/ipa-ca.crt \
  --append-boot-filepath '\EFI\centos\shimx64.efi' \
  --sb
This workflow enables high-integrity Secure Boot environments using
existing SeaBIOS infrastructure templates.

Russ Allbery: Review: Code Blue Emergency

Review: Code Blue Emergency, by James White
Series: Sector General #7
Publisher: Orb
Copyright: 1987
Printing: May 2003
ISBN: 0-7653-0663-8
Format: Trade paperback
Pages: 252
Code Blue Emergency (annoying em-dash in original title) is the seventh book of James White's Sector General science fiction series about a vast multi-species hospital station. While there are some references to (and spoilers for) earlier books in the series, you don't have to remember the previous books to read this one. I had no trouble despite a nine-year gap. I read this as part of the Orb General Practice omnibus, which collects this novel and The Genocidal Healer. Cha Thrat is a Sommaradvan warrior-surgeon, member of a newly-discovered species that is beginning the process of contact with the Federation. She saved a Monitor corps human after an accident on her world, performing some some highly competent surgery on a species she had never seen before. That plus her somewhat outcast status on her own world due to her very traditional attitude towards medical ethics led Sector General to extend an offer of medical internship, and led her to leap into the unknown by accepting. This may have been a mistake; there is a great deal that Sector General does not understand about Sommaradvan medical ethics. This series entry is another proper (if somewhat episodic) novel and the first book of the series that doesn't primarily focus on Conway. He makes an appearance in his new role as Diagnostician, but only as a supporting character. Code Blue Emergency is told in the tight third-person perspective of Cha Thrat, an alien who finds many things about Sector General baffling, confusing, and ethically troubling (and who therefore provides a good reader surrogate for reintroducing the basics of how the hospital works). Using an alien viewpoint is a more sophisticated narrative technique than White has used previously. I'm glad he tried it, and it mostly works, although I have some complaints. Cha Thrat comes from the middle caste of a strictly hierarchical society of three castes, but is also immensely stubborn and used to a medical system in which doctors take sole responsibility for their patients. This creates a lot of cultural conflicts, and I do enjoy science fiction where the human attitudes are portrayed as the strange ones, but the cultural analysis offered by this novel is not very deep. The pattern of this book is for Cha Thrat to stumble into a successful approach to a problem while being either oblivious to or hostile to the normal hierarchical structure expected of medical trainees. This is believable as far as it goes. She is a skilled and intelligent doctor with some good instincts and a strong commitment to patient care, but is also culturally inclined to not ask for help. It makes sense for that to be a serious problem in a hospital. Unfortunately, no one says this directly. Sector General staff get quite upset in ways that seem more territorial than oriented towards patient safety, no one directly explains to Cha Thrat why following a process is important or shows examples of what could go wrong, and plot armor means that her mistakes usually have positive outcomes. One can extrapolate the reasons why she is not a good medical student, but the reader is forced to do the extrapolation. This is the sort of book where the narration makes clear there are unresolved cultural clashes that are going to cause problems but hides the details. To Cha Thrat, her perspective is so obvious she never bothers to explain it to the reader, so the specifics come as a surprise. As with the alien perspective, I've seen this technique used with more subtlety and sophistication in other books, but White's version mostly works. Cha Thrat is a sympathetic protagonist because she is truly trying to take the most ethical and empathetic action in every situation and is clearly competent. Most of my frustration as a reader, ironically, lands on the other Sector General doctors who seem to make little to no effort to understand her perspective when she fails to conform to their expectations. This is believable in the abstract, but the whole point of Sector General is that they're supposed to be wiser about interspecies difference than this. Also, sometimes their reactions just seem petty. Cha Thrat has a very hierarchical concept of medicine that matches the social classes of her culture. For her, the highest tier of doctor are wizards who treat rulers, because the work of rulers is mostly mental and intellectual and therefore the diseases of rulers are treated with magic spells performed with words to reshape their thinking rather than surgery on their bodies. O'Mara and the other Sector General psychologists take great offense at this, muttering about being called witch doctors, which I found completely absurd. This is a comprehensible, if odd, description of psychology from a wholly alien species. Surely one's first reaction should be that words like "wizard" or "magic" are translation errors. Don't get offended; look to see if the underlying substance matches, which it clearly does. Apart from cultural and psychological clashes, Code Blue Emergency has the standard episodic Sector General structure of interesting medical mysteries that require lateral thinking. I find this sort of puzzle story satisfying, particularly given the firm belief of every character in an essentially pacifist and empathetic approach to even the most alien of creatures. This determined non-violence is one of the more interesting things about this series, and it continues here. White does tend towards both biological and gender essentialism for everyone other than the protagonist and main supporting characters, but he seemed to be walking back some of the more outrageous limitations on women that appeared in previous books. There is still some nonsense in here about how females of any species can't be Diagnosticians, but then Cha Thrat, who is female, seems to violate the justification for that rule over the course of this novel (sadly without comment). Perhaps he's setting up for proving Sector General wrong about this prejudice. I picked this up after reading Elizabeth Bear's Machine, which is essentially a (better written) Sector General novel that got me in the mood for reading more. I wouldn't give Code Blue Emergency any awards, but it delivered exactly what I was looking for. This series is not as deep or well-written as some more recent SF, but it is reliably itself and reliably entertaining. There are worse things in a series. Recommended if you're in the mood for alien ER in space. The omnibus edition that I read has an introduction to both novels by John Clute. It does add some interesting insights, but (as is somewhat typical for Clute) it also spoils parts of both books. You may want to read it after you read the novels. Followed by The Genocidal Healer. Rating: 7 out of 10

30 March 2026

Jamie McClelland: Mailman3 has 2 databases. Whoops.

At May First we have been carefully planning our migration of about 1200 lists from mailman2 to mailman3 for almost six months now. We did a lot of user communications, had several months of beta testing with a handful of lists ported over, and everything was looking good. So we kicked off the migration! But, about 15% of the way through I started seeing sqlite lock errors. Wait, what? I carefully re-configured mailman3 to use postgres, not sqlite. Well, yes, but apparently that was for the database managing the email list configuration, not the database powering the django web app, which, incidentally, also includes hundresds of gigabytes of archives. In other words, the one we really need in postgres, not sqlite.

Moving from sqlite to postgres Well that sucks. We immediately stopped the migration to deal with this. I noticed that the web is full of useful django instructions on how to migrate your database from one database to antoher. However, if you read the fine print, those convenient looking dumpdata loaddata workflows are designed to move the table definitions and a small amount of data. In our case, even after just 15% of our lists moved, our sqlite database was about 30GB. I considered some of the hacks to manage memory and try to run this via django, but eventually decided that pgloader was a more robust option. This option also allowed me to more easily test things out on a copy of our sqlite database (made while mailman was turned off). This way I could migrate and re-migrate the sqlite database over and over without impacting our live installation until I was satisfied it was all working. My first decision was to opt out of pgloader s schema creation. I used django s schema creation tool by:
  • Turning off mailman3 and mailman3-web and changing the mailman web configuration to use the new postgresql database.
  • Running mailman-web migrate
  • Changing the mailman web configuration back to sqlite and starting everything again.
Note: I tried just adding new database settings in the mailman web configuration indexed to new - django has the ability to define different databases by name, then you can run mailman-web migrate --database new. But, during the migration, I caught django querying the sqlite database for some migrations that required referencing existing fields (specifically hyperkitty s 0003_thread_starting_email). I didn t want any of these steps to touch the live database so I opted for the cleaner approach. Once I had a clean postgres schema, I dumped it so I could easily return to this spot. Next I started working on our pgloader load file. After a lot of trial and error, I ended with:
LOAD DATABASE
    FROM sqlite:///var/lib/mailman3/sqlite-postgres-migration/mailman3web.clean.backup.db
    INTO postgresql://mailmanweb:xxxxxxxxxxx@localhost:5432/mailmanweb

WITH data only,
    reset sequences,
    include no drop,
    disable triggers,
    create no tables,
    batch size = 5MB,
    batch rows = 500,
    prefetch rows = 50,
    workers = 2,
    concurrency = 1

SET work_mem to '64MB',
    maintenance_work_mem to '512MB'

CAST type datetime to timestamptz drop default drop not null,
    type date to date drop default drop not null,
    type int when (= precision 1) to boolean using tinyint-to-boolean,
    type text to varchar using remove-null-characters;
The batch, prefetch, workers and concurreny settings are all there to ensure memory doesn t blow up. I also discovered that I had to make some changes to the schema before loading data. Mostly truncating tables that the django migrate command populated to avoid duplicate key errors:
TRUNCATE TABLE django_migrations CASCADE;
TRUNCATE TABLE django_content_type CASCADE;
TRUNCATE TABLE auth_permission CASCADE;
TRUNCATE TABLE django_site CASCADE;
And also, I had to change a column type. Apparently the mailman import process allowed an attachment file name that exceeds the limit for postgres, but was allowed into sqlite:
ALTER TABLE hyperkitty_attachment ALTER COLUMN name TYPE text
When pgloader runs, we still get a lot of warnings from pgloader, which wants to cast columns differently than django does. These are harmless (I was able to import the data without a problem). And there are still a lot of warnings along the lines of:
2026-03-30T14:08:01.691990Z WARNING PostgreSQL warning: constraint hyperkitty_vote_email_id_73a50f4d_fk_hyperkitty_email_id of relation hyperkitty_vote does not exist, skipping
These are harmless as well. They appear because disable triggers disables foreign key constraints. Without it, we wouldn t be able to load tables that require values in tables that have not yet been populated. After all the tweaking, the import of our 30GB sqlite database took about 40 minutes.

Final Steps I think the reset sequences from pgloader should take care of this, but just in case:
mailman-web sqlsequencereset hyperkitty mailman_django auth   mailman-web dbshell
And, just to ensure postgres is optimized, run this in the psql shell:
ANALYZE VERBOSE;

Last thoughts I understand very well all the decisions the mailman3 devs made in designing the next version of mailman, and if I was in the same place I may have made them the same ones. For example, separating the code running the mailing list from the code managing the archives and the web interface makes perfectly good sense - many people might want to run just the mailing list part without a web interface. And building the web interface in django makes a lot of sense as well - why re-invent the wheel? I m sure a lot of time and effort was saved by simply using the built in features you get for free with django. But the unfortunate consequence of these decisions is that sys admins have a much harder time. Almost everyone wants the email lists along with the web interface and the archives. But nobody wants two different configuration files with different syntaxes and logic, not to mention two different command lines to use for maintenance and configuration with completely different APIs. Trying to understand how to change a default template or set list defaults requires a lot of research and usually you have to write a python script to do it. I have finally come to the conclusion that mailman2 is designed for sys admins, while mailman3 is designed for developers. Despite these short comings, I am impressed with the community and their quick and friendly responses to the questions of a confused sys admin. That might be more valuable than anything else.

29 March 2026

Samuel Henrique: Latest NVIDIA Drivers for Debian (Packaged with AI)

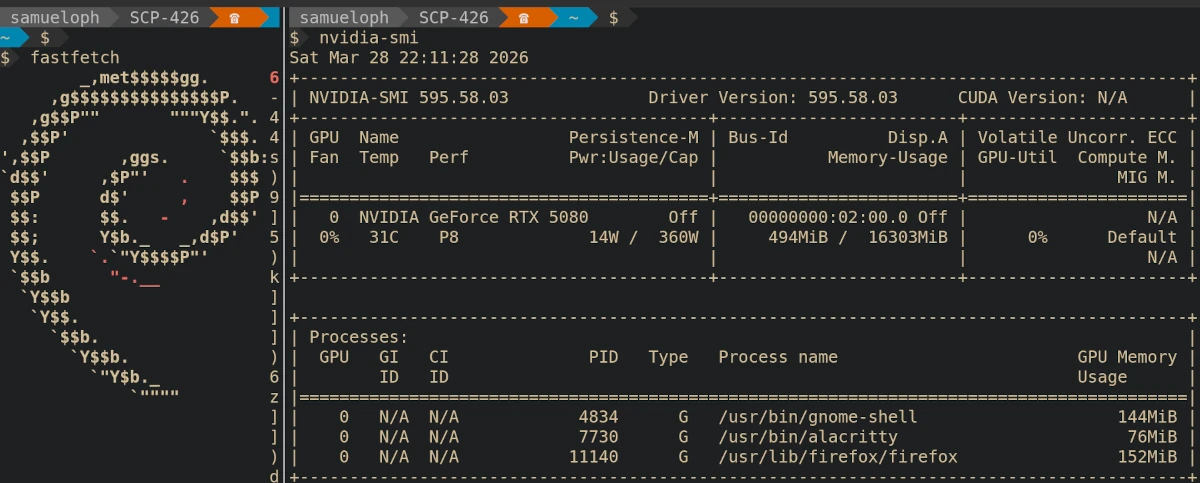
Two terminal windows side-by-side, on the left there's the Debian logo in ASCII art, and on the right it's the output of nvidia-smi, showing the driver version 595.58.03 running on a machine that has an NVIDIA RTS 5080

tl;dr This is not an official package, it's good enough for me and it might be good enough for you, confirmed as working in Debian Testing but I don't have a Stable machine to test there. You can use my custom repo to install the latest NVIDIA drivers on Debian Stable, Testing or Unstable (install from Sid repository): https://deb.debusine.debian.net/debian/r-samueloph-nvidia-ai/ The page above contains the APT sources you need, just add the one for your release to /etc/apt/sources.list.d/r-samueloph-nvidia-ai.sources, run sudo apt update and install the packages, you might need to disable Secure Boot.

This is not about AI Discussions about AI are quite divisive in the Free Software communities, and there's so much to be said about it that I'm not willing to go into in this blog post. This is rather just me telling people that if they need up-to-date NVIDIA packages for Debian, they could check if my custom repository gets the job done. The AI part is a means to an end, I've been careful to note in the repository names that the packages were produced with AI to respect people who do not want to run it for any reason.

RTX 5000 series support Back in May 2025 I opened a bug report asking for the NVIDIA drivers on Debian to be updated to support the RTX 5000 series. The Nouveau drivers might be good enough for some people, but I need the NVIDIA drivers because I want to play games and do experiments with open weight models. Opening a bug report doesn't guarantee anything, at the end of the day Debian Developers are volunteers, so if I really wanted the newer drivers, I would have to do something about it, ideally submitting a merge request. I briefly looked into the NVIDIA packaging, which involves 3 source packages (and one extra git repo for tarballs), unfortunately this was going to take more time and effort than what I was willing to spend.

What I Did After a few weeks of lamenting that I wasn't running the NVIDIA drivers, I figured I was willing to put in more effort than I originally thought, just enough to instruct the Claude Code agent to package the latest releases. I'm skilled enough with agentic tools that I knew how to use it to save time; providing a clear instruction on how to build the package and explaining the packaging layout, then letting the agent iterate until it gets a working build. The agent was running inside a VM that didn't have any of my credentials. After a little bit of back and forth, where I was reviewing the changes guiding the agent into how to fix certain issues, I ended up with a working set of packages. Once I installed it on my machine and confirmed they worked, I set up a debusine repository to make it easier to install future updates, and let others test it out. Debusine is analogous to Ubuntu's famous PPA, or Fedora's EPEL, it's a relatively new project but it has been working fine for this. Matheus Polkorny helped me test the packages and did spot a few issues which are fixed now. The Debusine developers were also always quick to respond to my questions and bug reports.

How Good Is It? Short answer: good enough for daily use, but not a substitute for an official Debian package. The whole point of doing this is because I don't have enough free time to maintain the package myself. All of this work was done as a volunteer, on my personal time. This means I'm trusting the agent to some degree; I review its commits but I don't go too deep into it, the quality will be dictated by the fact that I'm a Debian Developer and so by how easily I can spot issues without double checking everything. I only have a single machine with an NVIDIA GPU, this machine runs Debian Testing and so I don't have a way to test the Stable packages. I can do my best to address problems but at this point there is a risk that new updates break something. Installing NVIDIA drivers has always been a bit risky regardless, if you're comfortable with reverting updates and handling a system without a graphical interface (in case you end up in a tty), you will be fine. You will likely need to disable Secure Boot in order to use them, or set up your BIOS so that a MOK can be used to sign the DKMS modules. When choosing the version strings for the packages, I was careful enough to pick something that would sort lower than an official Debian package, meaning that whenever that same version is packaged in Debian, your system will see it as an upgrade. If you have any other methods of installing the NVIDIA drivers on your Debian system that is working for you, you should likely stick to that. I have a strong preference for installing them through .deb packages, making the package sort out configuration changes and dependency updates, besides handling the DKMS modules. Ultimately I'm not happy with the amount of difficulty that Debian users have in installing up-to-date NVIDIA drivers, and I hope this makes it easier for some.

How To Install Head over to the Debusine page that contains both repos for Trixie (Debian Stable) and Sid (for Debian Testing and Unstable): https://deb.debusine.debian.net/debian/r-samueloph-nvidia-ai/ If you are running Debian Testing, then pick the Sid repository. That page contains the contents of the apt .sources file you need, create the file /etc/apt/sources.list.d/r-samueloph-nvidia-ai.sources with the sources for your release. Run sudo apt update and install the packages you need, if you already have a previous version installed, sudo apt upgrade --update would update them. If there are no upgrades, meaning you don't have a previous version installed, then you need to explicitly install them.
sudo apt install nvidia-open-kernel-dkms nvidia-driver
If you run into issues in Debian Stable, consider using the Linux kernel package from the backports repository, if you need an up-to-date NVIDIA driver, you likely should also be running the backports kernel package (if you can't upgrade to Debian Testing).

Future Plans I currently have no means of measuring how many people are using the debusine repositories, so if you do end up using it feel free to let me know somehow. I don't know for how long I will keep managing this repository, and how much effort I will spend, but my machine needs it and for now I will keep it up-to-date with the latest production-grade NVIDIA drivers.

Sources The sources of the packages are available under a namespace in Salsa (Debian's GitLab instance): https://salsa.debian.org/samueloph-forks-team/nvidia-drivers-forks-with-ai You can also get the exact sources used in the repositories from debusine: https://debusine.debian.net/debian/r-samueloph-nvidia-ai/collection/debian:suite/sid-nvidia-ai/search/?category=debian:source-package https://debusine.debian.net/debian/r-samueloph-nvidia-ai/collection/debian:suite/trixie-nvidia-ai/search/?category=debian:source-package

28 March 2026

Evgeni Golov: Converting Dovecot password schemes on the fly without (too much) cursing

I finally upgraded my mail server to Debian 13 and, as expected, the Dovecot part was quite a ride. The configuration syntax changed between Dovecot 2.3 (Debian 12) and Dovecot 2.4 (Debian 13), so I started first with diffing my configuration against a vanilla Debian 12 one (this setup is slightly old) and then applied the same (logical) changes to a vanilla Debian 13 one. This mostly went well. Mostly because my user database is stored in SQL and while the Dovecot Configuration Upgrader says it can convert old dovecot-auth-sql.conf.ext files to the new syntax, it only does so for the structure, not the SQL queries themselves. While I don't expect it to be able to parse the queries and adopt them correctly, at least a hint that the field names in userdb changed and might require adjustment would've been cool. Once I got that all sorted, Dovecot would still refuse to let me in:
Error: sql: Invalid password in passdb: Weak password scheme 'MD5-CRYPT' used and refused
Yeah, right. Did I mention that this setup is old? The quick cure against this is a auth_allow_weak_schemes = yes in /etc/dovecot/conf.d/10-auth.conf, but long term I really should upgrade the password hashes in the database to something more modern. And this is what this post is about. My database only contains hashed (and salted) passwords, so I can't just update them without changing the password. And while there are only 9 users in total, I wanted to play nice and professional. (LOL) There is a Converting Password Schemes howto in the Dovecot documentation, but it uses a rather odd looking PHP script, wrapped in a shell script which leaks the plaintext password to the process list, and I really didn't want to remember how to write PHP to complete this task. Luckily, I know Python. The general idea is: To make the plaintext password available to the post-login script, we add '% password ' as userdb_plain_pass to the SELECT statement of our passdb query. The original howto also says to add a prefetch userdb, which we do. The sql userdb remains, as otherwise Postfix can't use Dovecot to deliver mail. Now comes the interesting part. We need to write a script that is executed by Dovecot's script-login and that will update the database for us. Thanks to Python's passlib and mysqlclient, the database and hashing parts are relatively straight forward:
#!/usr/bin/env python3
import os
import MySQLdb
import passlib.hash
DB_SETTINGS =  "host": "127.0.0.1", "user": "user", "password": "password", "database": "mail" 
SELECT_QUERY = "SELECT password_enc FROM mail_users WHERE username=%(username)s"
UPDATE_QUERY = "UPDATE mail_users SET password_enc=%(pwhash)s WHERE username=%(username)s"
SCHEME = "bcrypt"
EXPECTED_PREFIX = "$2b$"
def main():
    # https://doc.dovecot.org/2.4.3/core/config/post_login_scripting.html
    # https://doc.dovecot.org/2.4.3/howto/convert_password_schemes.html
    user = os.environ.get("USER")
    plain_pass = os.environ.get("PLAIN_PASS")
    if plain_pass is not None:
        db = MySQLdb.connect(**DB_SETTINGS)
        cursor = db.cursor()
        cursor.execute(SELECT_QUERY,  "username": user )
        result = cursor.fetchone()
        current_pwhash = result[0]
        if not current_pwhash.startswith(EXPECTED_PREFIX):
            hash_module = getattr(passlib.hash, SCHEME)
            pwhash = hash_module.hash(plain_pass)
            data =  "pwhash": pwhash, "username": user 
            cursor.execute(UPDATE_QUERY, data)
        cursor.close()
        db.close()
if __name__ == "__main__":
    main()
But if we add that as executable = script-login /etc/dovecot/dpsu.py to our imap-postlogin service, as the howto suggests, the users won't be able to login anymore:
Error: Post-login script denied access to user
WAT? Remember that shell script I wanted to avoid? It ends with exec "$@". Turns out the script-login "API" is rather interesting. It's not "pass in a list of scripts to call and I'll call all of them". It's "pass a list of scripts, I'll execv the first item and pass the rest as args, and every item is expected to execv the next one again". With that (cursed) knowledge, the script becomes:
#!/usr/bin/env python3
import os
import sys
import MySQLdb
import passlib.hash
DB_SETTINGS =  "host": "127.0.0.1", "user": "user", "password": "password", "database": "mail" 
SELECT_QUERY = "SELECT password_enc FROM mail_users WHERE username=%(username)s"
UPDATE_QUERY = "UPDATE mail_users SET password_enc=%(pwhash)s WHERE username=%(username)s"
SCHEME = "bcrypt"
EXPECTED_PREFIX = "$2b$"
def main():
    # https://doc.dovecot.org/2.4.3/core/config/post_login_scripting.html
    # https://doc.dovecot.org/2.4.3/howto/convert_password_schemes.html
    user = os.environ.get("USER")
    plain_pass = os.environ.get("PLAIN_PASS")
    if plain_pass is not None:
        db = MySQLdb.connect(**DB_SETTINGS)
        cursor = db.cursor()
        cursor.execute(SELECT_QUERY,  "username": user )
        result = cursor.fetchone()
        current_pwhash = result[0]
        if not current_pwhash.startswith(EXPECTED_PREFIX):
            hash_module = getattr(passlib.hash, SCHEME)
            pwhash = hash_module.hash(plain_pass)
            data =  "pwhash": pwhash, "username": user 
            cursor.execute(UPDATE_QUERY, data)
        cursor.close()
        db.close()
    os.execv(sys.argv[1], sys.argv[1:])
if __name__ == "__main__":
    main()
And the passwords are getting gradually updated as the users log in. Once all are updated, we can remove the post-login script and drop the auth_allow_weak_schemes = yes.

Russell Coker: Communication and Hostile AIs

We seem to be entering an AI apocalypse of sorts, they aren t going to kill us or even take our jobs. What they are doing is destroying the Internet commons by filling it with rubbish. This isn t even real AI, just pattern matching and prediction systems, mostly LLMs. The Problem Scott Shambaugh s saga of being attacked and defamed by an OpenClaw AI bot is interesting and raises some disturbing possibilities for future online discussion [1]. Imagine what it would be like if everyone who was in any way notable for free software work had 100 such bots going after them. Dania Dumas wrote an insightful blog post about why OpenClaw is impossible to secure and why it won t go away [2]. Bruce Schneier and Nathan E. Sanders wrote an insightful article about the AI generated text arms race [3] primarily concentrating on situations in which text that was assumed to be written by humans but was actually written in bulk by bots was performing a DOS attack on people who were reviewing it. There are many situations such as book publishing and publishing letters to the editor of newspapers where getting new material from unknown people is an important part of the job but where there are also people making low quality submissions that are almost a DOS attack at the best of times. Currently the email spam problem continues to get worse and when LLM use increases it will get significantly worse. Email encryption isn t viable [4]. The PGP web of trust never really worked well as it s too difficult for most users. The amount of AI generated content that s being recommended to users on platforms like YouTube and Facebook is steadily increasing and the amount of LLM generated commentary that purports to be from real people on Twitter and Facebook is also increasing. Here s an informative blog post by Erich Schubert about this [5]. Potential Solutions Surrender? One option and possibly the default option is to surrender to this and just let everything we built on the Internet over decades get destroyed. Whether to surrender is a decision that can be made on a per-service basis. Twitter is pretty much useless anyway, I quit Twitter because Elon deliberately made it suck [6]. In my opinion this is not surrendering to what s being done there, I m just stopping wasting time on it and using better options. I used to have about 300 followers on Twitter and I don t think that many of them would ever choose to stop following me, so I presume that about 1/3 of the people following me have decided to totally quit Twitter and delete their accounts. I also presume that some of the remainder have done the same as me and just kept a mostly inactive account. If Elon suddenly stopped being a stupid asshole it probably wouldn t change anything as the value of the system was connections to others. Some people will consider my abandonment of Twitter as surrender and I accept that it s not an unreasonable opinion. I think that the possibly 100 Twitter followers of mine who deleted their accounts surrendered. Facebook has been becoming a worse service, it s business model is becoming increasingly exploitative and it s interface is designed to be addictive. It s probably best avoided unless you really need it. The only good thing about Facebook at the moment is that Facebook Marketplace doesn t take a cut on sales and there are some really good deals on computers if you know what to look for. Unfortunately Facebook has a large number of users who are from marginalised communities and have no other alternatives for communication. It would be good to get them migrated to other platforms. We could just give up on a lot of general communications services and have everyone accept that good content is drowned out by rubbish and have the Internet become divided between people who accept the rubbish and those who cease using large portions of the Internet environment to avoid it. Using Non Commercial Services Lemmy is a good FOSS federated alternative to Reddit which also covers some of the uses of Facebook. It needs more users to get critical mass but is still quite usable. A post that might get a dozen comments on Reddit may get 1 comment on Lemmy but that one comment will be a good one. Reddit doesn t appear to be attacked much by LLM generated content at least not yet. Even if the Reddit model proves to be resilient to LLM attack the Lemmy software can be used to replace some things that are done on Facebook, Mastodon is a good FOSS federated replacement for Twitter, it has a decent user-base including some VIPs. While it is aimed at the Twitter use case it can also cover a significant part of the Facebook use case. There are some other FOSS social media programs which could take over other parts of the commercial social media environment. Generally commercially run Internet services will have a financial incentive to allow the problems to get worse so we need to rely on FOSS software, non-commercial implementations, and government services. Web Search For a long time Google has had a monopoly on web search, but now they default to including an AI Overview at the start of the results which is sometimes useful but also sometimes very wrong. You can use the search URL https://www.google.com/search?q=%s&udm=web to get google results without rubbish. But I presume that they will break that if it gets too popular. Searxng is a AGPL licensed metasearch engine that aggregates results from other engines, here s the Searxng source [7] and here s a list of Searxng instances if you want to try one [8]. Even using meta search engines like Searxng won t help if the original data is overloaded with spam, but alleviating the problem is a good temporary measure. Web of Trust for the Web? I ve idly considered the possibility of having some sort of rating system for web pages that uses a web of trust so that you can securely use trust ratings of friends of friends etc. But given all the difficulties in using a web of trust for signing GPG key for software developers (the demographic that is most skilled at doing such things) it doesn t seem viable. Should we surrender the idea of having a usable public web? In the early days of the web (before Google) it was standard practice to rely on recommendations from other people or from trusted sites to find other sites, that could be considered to be an informal web of trust. We could go back to that sort of usage pattern if Google and many of the big sites get overwhelmed by LLM generated spam. Wikipedia I believe that Wikipedia will be at the front lines of this battle. It s model has always included anonymous contributions. Benjamin Mako Hill wrote an interesting blog post about research he did with Kaylea Champion into Wikipedia pages on taboo topics which have a larger portion of contributors choosing to be anonymous than non-taboo pages [9]. Wikipedia also has a long history of being abused for various reasons, one that I witnessed was someone putting false content into Wikipedia pages to immediately cite them in support of their facebook arguments. That sort of thing can be dealt with at human scale but a large scale attack by bots is a different problem to solve. Also with the recent developments in AI developing multiple web sites entirely populated for the purpose of supporting one fake entry in Wikipedia is plausible. The upside of these attacks that I predict is that they will attract the attention of all the people who have skills related to developing counter-measures. While LLM bots are filling the inboxes of publishers with rubbish and messing up the stackoverflow comments section not a lot of people are bothered, but once the attacks on Wikipedia get serious everyone will take notice. National AI Bruce Schneier and Nathan E. Sanders wrote an interesting blog post about nationalised public AI [10]. While that won t directly address this issue it will get the right technology in the hands of people who can use it in the right way. Conclusion This is going to be a difficult problem to solve, more difficult than the email spam problem we have been unable to solve after 30 years of working on it. This is also a very important problem, we are currently in an age where we have access to information that most people couldn t even dream of 30 years ago. We also have disinformation that combines some of the worst aspects of authoritarian regimes throughout history combined with the worst aspects of cult brainwashing. If we lose access to the information but the disinformation remains (or get worse) then the result will be terrible. I don t have great ideas for solving this. I have outlined some small ideas to mitigate things and I hope that others can expand on them. Please write comments with any good ideas you have, or even ideas that don t totally suck. A problem this difficult is not going to be solved in a blog comment, but a blog comment might point in the right direction.

27 March 2026

Paul Tagliamonte: librtlsdr.so for fun and profit

Interested in future updates? Follow me on mastodon at @paul@soylent.green. Posts about hz.tools will be tagged #hztools.
It s well known and universally agreed that radios are cool. Among the contested field of coolest radios, Software Defined Radios (SDRs) are definitely the most interesting to me. Out of all of my (entirely too many) SDRs I own, the rtlsdr is still my #1. It s just good. It s a great price, extremely capable, reliable, well-supported, and compact. Why bother with anything else? Sure, it can t transmit, uses a (fairly weird) 8 bit unsigned integer IQ representation, limited sampling rate, limited frequency range but even with all that, it s still the radio I will pack first. Don t get me wrong, I love my Ettus radios, PlutoSDRs, HackRFs, my AirspyHF+ - they re great! I just always find myself falling back to an rtl-sdr, every time. Perhaps the best reason to use an rtlsdr is the absolutely mind-boggling amount of cool stuff people have written for it. The rtlsdr API is super easy to use, widely supported if you re building on top of existing radio processing frameworks it s still a shock to me when something omits rtlsdr support.

sparky Over the last 7 years, I ve been learning about radios I got my ham radio license (de K3XEC), hacked on some cool stuff where I ve learned how radios work by doing , and even was lucky enough to give my first rf-centric talk at districtcon. Embarrassingly, I still haven t gotten around to learning how the fancy stuff like GNU Radio works. I m sure I m going to love it when I do. As part of this, I ve also cooked up some very unprofessional formats and protocols I use for convenience. Locally, all my on-disk captures are stored in rfcap or more recently arf, while direct SDR access at my house is almost entirely a mix of the widely used rtl-tcp protocol, and my riq protocol (post on this coming soon). Both rtl-tcp and riq operate over the network, so I don t have to bother with plugging things into USB ports, and I can share my radios with my friends. All of that work sits in my current generation of radio processing code, sparky (a reference to spark-gap transmitters), which is a heap of Rust, supporting everything from no_std for embedded experiments, conditional support for interfacing with all the radios I own, and tokio-based async support in addition to blocking i/o for highly concurrent daemons. This quickly advanced beyond my old Go-based code (hz.tools/go-sdr), which I archived so I can focus on learning. I still think Go is a great language to write RF code in but I can t focus on that tech tree anymore. Of course, this now poses a new problem no one supports my format(s) or radio protocol(s), since, well, I m the only one using them. I ve committed a fair amount of my hardware to this setup, and yanking it from the rack to try something out does pose a bit of a pickle. This isn t a huge deal for learning, but it does make it tedious to try out something from the internets.

librtlsdr.so Thankfully, Rust has robust support for wrap[ping itself] in a grotesque simulacra of C s skin and mak[ing its] flesh undulate, which is an attractive nuisance if i ve ever seen one. Naturally, my ability to restrain myself from engaging in ill-advised rf adventures is basically zero, so it s time to do the thing any similarly situated person would do reimplement the API and ABI of librtlsdr.so, backed with sparky instead. Since enumeration of devices is going to be annoying (specifically, they re over the network), I decided early-on to rely on an explicit list of devices via a configuration file. I d rather only load that once so programs don t get confused, so I opted to use a CTOR to run a stub when the ELF is linked at runtime.
// lightly edited for clarity

#[used]
#[expect(unused)]
#[unsafe(link_section = ".init_array")]
pub static INITIALIZE: extern "C" fn() = sparky_rtlsdr_ctor;

#[unsafe(no_mangle)]
pub extern "C" fn sparky_rtlsdr_ctor()  
 let config: Config =  
 if let Ok(config_bytes) = std::fs::read("/etc/sparky-rtlsdr.toml")  
 toml::from_slice(&config_bytes).unwrap()
   else  
 Config   device: vec![]  
  
  ;
 CONFIG.set(config);
 
Next, it s time to start with the basics. Opening and closing a handle using rtlsdr_open and rtlsdr_close. Given we don t control the runtime, and the rtl-sdr device handle is opaque (for good reason!), I opted to smuggle a rust Box<Device> non-FFI safe heap-allocated struct through the device handle pointer, and let C take ownership of the Box. No one should be looking in there anyway.
// lightly edited for clarity

#[unsafe(no_mangle)]
pub unsafe extern "C" fn rtlsdr_open(dev: *mut *mut Handle, index: u32) -> int  
 let config = &CONFIG.device[index as usize];
 let sdr = match config.load()  
 Ok(v) => v,
 Err(err) =>  
 return -1;
  
  ;
 let handle = Box::new(Handle   config, sdr  );
 unsafe   *dev = Box::into_raw(handle)  ;
 0
 

#[unsafe(no_mangle)]
pub unsafe extern "C" fn rtlsdr_close(dev: *mut Handle) -> int  
 let dev = unsafe   Box::from_raw(dev)  ;
 drop(dev);
 0
 
With that in place, we can chip away at the API surface, translating calls as best as we can. I won t bother listing it all, since it s not very interesting but here s an example implementation of rtlsdr_set_sample_rate and rtlsdr_get_sample_rate. These calls are translating from an rtl-sdr frequency (which is a u32 containing the value as Hz) into a sparky Frequency type, and invoking get_sample_rate or set_sample_rate on the device s rust handle. Since each device implements the sparky Sdr trait, the actual underlying device doesn t matter much here.
#[unsafe(no_mangle)]
pub unsafe extern "C" fn rtlsdr_set_sample_rate(dev: *mut Handle, rate: u32) -> int  
 let dev = unsafe   &mut *dev  ;
 let rate = Frequency::from_hz(rate as i64);
 if let Err(err) = dev.sdr.set_sample_rate(dev.channel, rate)  
 return -1;
  
 0
 

#[unsafe(no_mangle)]
pub unsafe extern "C" fn rtlsdr_get_sample_rate(dev: *mut Handle) -> u32  
 let dev = unsafe   &mut *dev  ;
 let freq = match dev.sdr.get_sample_rate(dev.channel)  
 Ok(freq) => freq,
 Err(err) =>  
 return 0;
  
  ;
 freq.as_hz() as u32
 
After repeating this process for the rest of the stubs I could (and otherwise setting error conditions if the functionality is not supported), I was ready to try it out. Within sparky, I patched my MockSDR (basically a Sdr traited Mock type) to implement the same testmode IQ protocol that the RTL-SDR has, and decided to see if rtl_test from apt without any changes could be fooled.
$ rtl_test
No supported devices found.
Great, cool. No devices plugged in. Looks great. Let s try it with my librtlsdr.so LD_PRELOAD-ed into the binary first:
$ LD_PRELOAD=target/release/librtlsdr.so rtl_test
Found 1 device(s):
 0: hz.tools, mock sdr, SN: totally legit no tricks

Using device 0: sparky mock sdr
Supported gain values (0):
Sampling at 2048000 S/s.

Info: This tool will continuously read from the device, and report if
samples get lost. If you observe no further output, everything is fine.

Reading samples in async mode...
^CSignal caught, exiting!

User cancel, exiting...
Samples per million lost (minimum): 0
$
Outstanding. Even more outstandingly, if I change my testmode implementation to skip samples, rtl_test correctly reports the errors I think it s showing promise! On to try the real endgame here let s have our new librtlsdr.so connect to an rtl-tcp endpoint and see if rtl_fm works:
LD_PRELOAD=target/release/librtlsdr.so \
 rtl_fm -d 1 -s 120k -E deemp -M fm -f 90.9M   \
 ffplay -f s16le -ar 120k -i -
Found 2 device(s):
 0: hz.tools, mock sdr, SN: totally legit no tricks
 1: hz.tools, rtl-tcp, SN: node2.rf.lan:1202

Using device 1: sparky rtltcp node2
Tuner gain set to automatic.
Tuned to 91170000 Hz.
Oversampling input by: 9x.
Oversampling output by: 1x.
Buffer size: 7.59ms
Sampling at 1080000 S/s.
Output at 120000 Hz.
And there it was! Not the best audio quality (mostly due to my inability to correctly read the rtl_fm manpage to tune the filter and downsample/oversampling rates to audio), but it s definitely passable. I figured I d try something that was a bit more interesting next gqrx, since it s super handy, I use it a ton, and will definitely amuse me to no end. To my surprise and delight, LD_PRELOAD=target/release/librtlsdr.so gqrx wound up running, and I saw my devices pop right up in the setting menu: Huge. Huge. Amazing. It did crash as soon as I tried to actually use the radio, but after fixing a few dangling bugs in the API surface (and some assumptions I think some underlying gnuradio driver may be making that I need to double check in the code), I was able to get a super solid stream of broadcast fm radio, with gqrx being none the wiser. It thought it was just talking to the device it knows as rtl=1. Nice. I can t wait to try this with the rest of the rtl-sdr based tools I like having around using my riq protocol next. I don t think that ll be worth a post, but hopefully I ll get around to publishing details on that stack next.
epilogue Well. That s it. End of story. A bit anti-climatic, sure. While this new shim will provide me endless minutes of mild amusement, I could see using this to expose my sparky testing utilities via librtlsdr.so my mock sdr driver allows for replaying captures off disk, which could be interesting to make sure that signals are still properly decoded after changes, or instrument performance changes (via SNR, BER, packets observed, etc) on reference samples I have on my NAS. Maybe that ll come in handy one day! Truth be told, I m not sure I actually want to encourage anyone to do this for real (although I think I ll definitely be using it on my LAN to see what happens). I also don t have a repo to share I don t particularly feel with dealing with the secondary effects of publishing sparky (and sparky-rtlsdr) yet, since i m still getting my feet under me on the radio aspect of all this. I ll be sure to post updates if anything changes with this here (tagged sparky) and at @paul@soylent.green. I can t wait to post more about some of the odd sidequests (like this one!) i ve completed over the last few years I ve been waiting to feel confident that my work has matured and was withstood the new problems i ve thrown at it, and it largely has. It s my hope that these projects (and this project in particular) has provided a glimpse into the world of software defined radio for my systems friends, and a bit about systems for my radio friends. It s not all magic, and I hope someone out there feels inclined to have some fun with radios themselves!

Samuel Henrique: I use curl with ECH btw (in Debian)

tl;dr This is an experimental feature that, for the first time, brings full ECH support to curl on Debian using OpenSSL. Starting with curl 8.19.0-3+exp2 (Debian Experimental), you can now use ECH, with HTTPS-RR and DoH for maximum privacy. curl 8.19.0-3+exp2 is quite fresh at the time of writing, bear in mind that your repository might not have synced the package yet, all mirrors should have it by March 27th 14:00 UTC.
# defo.ie is a test server that confirms whether ECH was successfully used
curl -v --ech hard https://defo.ie/ech-check.php
# For Encrypted Client Hello (ECH) + DNS over HTTPS (DoH)
curl -v --ech hard --doh-url https://1.1.1.1/dns-query https://defo.ie/ech-check.php
"--ech hard" tells curl to refuse the connection entirely if ECH cannot be negotiated. Or, if you would like to try it out in a container:
podman run debian:experimental /bin/bash -c 'apt install --update -t experimental -y curl && curl -v --ech hard --doh-url https://1.1.1.1/dns-query https://defo.ie/ech-check.php'
(in case you haven't noticed, apt now has the --update option for the upgrade and install commands)

For Privacy CloudFlare calls it "the last puzzle piece to privacy" in their must-read announcement: https://blog.cloudflare.com/announcing-encrypted-client-hello/. Encrypted Client Hello (rfc9849) encrypts the "which website are you connecting to?" part of the TLS handshake that was previously visible in plaintext. HTTPS-RR (rfc9460) is a DNS record type that publishes connection parameters for a service, including the public key clients need to perform ECH. DNS Over HTTPS (rfc8484) encrypts DNS queries by tunneling them over HTTPS, hiding what domains you're looking up from network observers. When all three operate together over a CDN with shared IP space, the target domain name is hidden from passive observers; the HTTPS-RR record is queried over DoH in order to retrieve the ECH key (rfc9848) for the TLS handshake. Seems like quite an important feature, and in fact the major browsers have it enabled for some time now, the trick is that they do not use OpenSSL (Chrome uses BoringSSL and Firefox uses NSS). For everyone else, the only option is to patch OpenSSL or wait until 4.0.0 is released, and so part of the reason Debian is the first distro to enable it (curl + OpenSSL + ECH) is that the OpenSSL maintainer (Sebastian Andrzej Siewior) packaged the alpha release just 3 days after it was published. Do not forget that ECH support is experimental and currently relies on the alpha release of OpenSSL.

wcurl Gets It Too Considering wcurl is just a wrapper on curl, it gets the feature for free:
wcurl --curl-options="--ech hard --doh-url https://1.1.1.1/dns-query" $URL
If you're using wcurl, you don't want to have to set parameters, this is just to show that the feature is there and if you have a .curlrc file, it can enable the feature seamlessly.

Other Debian Releases Given the ECH feature requires OpenSSL >= 4, it will not make it to Debian 13, having a small chance of going to Debian 13 Backports (emphasis on small). It should get to Debian Unstable and Debian Testing within the next couple of months as the OpenSSL GA release happens and gets packaged, but you should be able to install the package from Experimental in your Unstable and Testing systems without issues. It will also be in Debian 14 once it becomes the new Stable.

Shoulders of Giants Stephen Farrell's presentation from OpenSSL Conference 2025 has a lot of background on the work involved: Encrypted Client Hello Lessons learned from trying to do something that was probably too complicated They have been working on implementing ECH in open-source projects for years, something as big as this doesn't happen without lots of people dedicating both their paid and free times over it. I ended up being the person who enabled it on Debian, which was pretty much the least amount of work between everyone involved, but hey it's fun flipping the switch and telling you about it.

Background Since 2025, the curl developers started organizing an yearly meeting with all maintainers of curl in Operating Systems. The 2026 edition happened in March 26th: https://github.com/curl/curl/wiki/curl-distro-discussion-2026. Attendance was really good, and as you can imagine one of the topics of discussion was ECH, in which it was pointed out that having OpenSSL 4 was the main requirement but besides it nothing unusual was needed. In Debian Experimental, we have been enabling HTTPS-RR since March 2025, and OpenSSL 4.0.0 alpha was packaged just recently (2026-03-13) by Sebastian Andrzej Siewior, it's time for the next step. The curl distro meeting was just the motivation I needed to go ahead and enable it in Debian Experimental, so as part of our Debian Brasil Weekly Meetings I've prepared and uploaded the changes, while Carlos Henrique Lima Melara worked on addressing a recent test regression for Debian Unstable. Unfortunately sergiodj couldn't join and I'm sure he's jealous of the hacking session now.

Appendix While writing this, I've noticed one of the authors of the CloudFlare blogpost is the previous curl maintainer on Debian; Alessandro Ghedini let me take over the maintenance back in 2021 and today curl is maintained by a team of 4 people, it's nice to see Alessandro's involvement.

26 March 2026

Petter Reinholdtsen: The 2026 LinuxCNC Norwegian Developer Gathering

The LinuxCNC project continues to thrive. I believe this great software system for numerical control of machines such as milling machines, lathes, plasma cutters, routers, cutting machines, robots, and hexapods would benefit even more from in-person developer gatherings. Therefore, we plan to organise another gathering this summer as well. We invite you to a small LinuxCNC and free software fabrication workshop/gathering in Norway this summer, over the weekend starting June 26th, 2026. As last year, we maintain a slightly broader scope and welcome people outside the LinuxCNC community. As before, we suggest to organise it as an unconference, where participants create the program upon arrival. The location is a metal workshop 15 minutes' drive from Gardermoen airport (OSL), with plenty of space and a hotel just 5 minutes away by car. We plan to fire up the barbecue in the evenings. Please let us know if you would like to join. We track the list of participants on a simple pad. Please add yourself there if you are interested in joining. Our friends over at the TS Robotics team at the University of Oslo have offered to handle any money involved with this gathering, that is, holding sponsor funds and paying the bills. We hope to secure enough sponsors to cover food, lodging, and travel. So far, Debian has offered to sponsor part of the expenses, which should cover food and a bit more. Please get in touch if you would like to help sponsor the gathering. As usual, if you use Bitcoin and wish to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

24 March 2026

Russ Allbery: Review: A Shadow in Summer

Review: A Shadow in Summer, by Daniel Abraham
Series: Long Price Quartet #1
Publisher: Tor
Copyright: March 2006
ISBN: 0-7653-1340-5
Format: Hardcover
Pages: 331
A Shadow in Summer is a high fantasy novel, the first of (as the name implies) a completed four-book series. Daniel Abraham is perhaps better known as half of the writing pair behind James S.A. Corey, author of the Expanse series. This was his first novel. Otah was the sixth son of a Khai, sent like many of the unwanted later children of the powerful to learn the secrets of the andat and be trained as a poet. He learned his lessons well enough to reject the school and its teachings and walk away. Amat Kyaan has worked her way up from nothing to become the senior overseer of the foreign Galtic House Wilsin in the sun-drenched port city of Saraykeht. Liat is her apprentice, distracted by young love. Maati is a new apprentice poet, having endured his training and sent to learn from Heshai how to eventually hold the andat Removing-The-Part-That-Continues, better known as Seedless. None of them know they will find themselves entangled in a plot to destroy the poet of Saraykeht and, through him, the city's most potent economic tool. A poet in this world is not what we would think of a poet. They are, in essence, magical slave-drivers who capture the essence of an andat, a spirit embodying an idea that is coerced into the prison of volition and obedience by the poet. The andat Seedless, the embodiment of the concept of removing the spark of life, is central to the economic wealth of Saraykeht in a way that is startling in its simplicity: Seedless can remove the seeds from a warehouse full of cotton at a thought. This gives Saraykeht a massive productivity advantage in the cotton trade. Seedless is also a powerful potential weapon. What he can do to cotton, he could as easily do to any other crop, or to people. The Galts are not fond of the independence and power of Saraykeht, but as long as the city controls a powerful andat, they do not dare to attack it directly. Indirectly, though... that's another matter. This is one of those fantasy novels with meticulous and thoughtful world-building, careful and evocative prose, and a complex ensemble cast of interesting characters that the novel then attempts to make utterly miserable and complicit in their own misery. There should be a name for this style of writing. It's not tragedy because the ending is not tragic, precisely. It's not magic realism; the andats are openly magical, which makes this clearly high fantasy. But Abraham approaches the story from the type of realist frame that considers the pain and desperation of the characters to be more interesting than their ability to overcome challenges. Amat starts the story as an admirable, sharp-witted expert manager, so her life is destroyed and she's subjected to sexual violence. Heshai loathes himself and veers between a tragic figure and a wastrel as the story systematically undermines opportunities for redemption. Maati is young and idealistic, so of course every character in the book sets out to crush his idealism under the weight of unforeseen consequences. There is a sad and depressing love triangle, because this is exactly the sort of book that has a sad and depressing love triangle. At the end of the novel, everyone who survives is older and wiser in the sense that some stories seem to think wisdom comes from the accumulation of trauma. I find books like this so immensely frustrating because their merits are so clear. The world-building is careful and detailed in a way that includes economic systems, unlike so much fantasy. It is full of small, intriguing touches, such as the use of posture and gesture to communicate the emotional valence of one's words. Abraham understands the moral implications of poets and andats and the story tackles them head-on. The writing flows beautifully and gave me a strong sense of the city. I wanted to like this book for the obvious skill that went into it, and sometimes I even managed. And yet, it's taken me three months to finish A Shadow in Summer because I simply do not want to spend this much time around miserable people. I would get through one or two chapters in a night and then wanted to read something happy or defiant or heroic, rather than watching slow-motion train wrecks intermixed with desperate attempts to navigate stifling layers of immoral systems. It's not that the story lacks a moral compass. The characters are sincerely trying to make the world a better place, with some success. It even delivers a happy ending of sorts. But so much of the journey was watching the lives of the characters fall apart. I am completely unsurprised that some people loved this book. I'm still intrigued enough by the world-building that I'm half-tempted to try to read the sequel even after having to drag myself through this one. I had a similar reaction to Abraham's The Dragon's Path, though, so I think Abraham is just not for me. I may get back to the Expanse at some point, but having to drag myself through both of his solo novels I've tried, in two different series, probably indicates an incompatibility between author and reader. That's a shame, given the quality of the writing. Followed by A Betrayal in Winter. Content notes: Sexual and reproductive violence as significant plot elements. Rating: 6 out of 10

23 March 2026

Russ Allbery: Review: Dark Class

Review: Dark Class, by Michelle Diener
Series: Class 5 #5
Publisher: Eclipse
Copyright: 2022
ISBN: 0-6454658-2-8
Format: Kindle
Pages: 349
Dark Class is the fifth novel (not counting the skippable novella) in Michelle Diener's Class 5 romantic science fiction series. As with the previous novels, this follows romance series conventions: There are new protagonists, but characters from the previous books make an appearance. It's helpful but not that necessary to remember the details of the previous books; the necessary background is explained enough to follow the story. By now, series readers know the formula. Yet another Earth woman was secretly abducted by the Tecran, encounters a Class 5 ship, and finds a way to be surprisingly dangerous and politically destabilizing. This time, Ellie has been mostly unconscious since her abduction and awakes in a secret Tecran base after the Tecran have all been murdered. There is a Class 5 AI involved, but not a full ship; instead, Dark Class picks up (or, arguably, manufactures) a loose end from Dark Minds. Other than that break from the formula, you know what to expected by now: a hunky Grih, a tricky political standoff, a protective Class 5, a slow-burn romance, and a surprisingly capable protagonist who upends politics through plucky grit and refusal to tolerate poor treatment. Oh, and a new selection of salvaged clothing and weapons to make Ellie beautiful and surprisingly dangerous. If you are this far into the series, you probably like the formula. That's my position. I don't care about the romance, but something about the prisoner to threat evolution of the kidnapped protagonists and the growing friendship with an AI makes me happy. This is not great literature, but it is reliably entertaining with a guaranteed victorious protagonist and happy ending, making it a comfortable break from more difficult books with emotionally wrenching scenes. Dark Class is one of the better executions of the formula because it has long stretches of my favorite parts of these books: exploration of mostly-abandoned surroundings for neat gadgets while the AI and the protagonist slowly build a relationship of mutual respect. This book has bonus drones with minds of their own and an enigmatic alien spaceship that provides a fun mid-novel twist. The Tecran and the Grih repeatedly underestimate Ellie and are caught by surprise at dramatically satisfying moments. It's just fun to read, and I save this series for when I need that type of book. As with the other books of the series, Diener's writing is serviceable but not great. She repeats herself, uses way too many paragraph breaks for emphasis, and is not going to win any literary awards for prose quality. The series is in the upper half of self-published works, and I've certainly read worse, but either the formula will click with you or it won't. If it doesn't, the prose is not going to salvage the book. There is some development of the series plot, but it's mostly predictable fallout from Dark Matters. This book is mostly tactical and smaller in scale. I am a little curious where Diener is going with political developments, since the accumulated Earth women and Class 5 ships are in some danger of becoming a sort of shadow government through sheer military power, but I'm dubious this series will have enough political sophistication to dig into the implications. It's best enjoyed as small-scale episodic wish fulfillment for female protagonists, and that's good enough for me. If you've read this far in the series, recommended; this is one of the stronger entries. Followed by Collision Course, which breaks the title convention for the series. Rating: 7 out of 10

22 March 2026

Vincent Bernat: Calculate 1/(40rods/hogshead) to L/100km from your Zsh prompt

I often need a quick calculation or a unit conversion. Rather than reaching for a separate tool, a few lines of Zsh configuration turn = into a calculator. Typing = 660km / (2/3)c * 2 -> ms gives me 6.60457 ms1 without leaving my terminal, thanks to the Zsh line editor.

The equal alias The main idea looks simple: define = as an alias to a calculator command. I prefer Numbat, a scientific calculator that supports unit conversions. Qalculate is a close second.2 If neither is available, we fall back to Zsh s built-in zcalc module. As the alias built-in uses = as a separator for name and value, we need to alter the aliases associative array:
if (( $+commands[numbat] )); then
  aliases[=]='numbat -e'
elif (( $+commands[qalc] )); then
  aliases[=]='qalc'
else
  autoload -Uz zcalc
  aliases[=]='zcalc -f -e'
fi
With this in place, = 847/11 becomes numbat -e 847/11.

The quoting problem The first problem surfaces quickly. Typing = 5 * 3 fails: Zsh expands the * character as a glob pattern before passing it to the calculator. The same issue applies to other characters that Zsh treats specially, such as > or . You must quote the expression:
$ = '5 * 3'
15
We fix this by hooking into the Zsh line editor to quote the expression before executing it.

Automatic quoting with ZLE Zsh calls the line-finish widget before submitting a command. We hook a function that detects the = prefix and quotes the expression:
_vbe_calc_quote()  
  case $BUFFER in
    "="*)
      typeset -g _vbe_calc_expr=$BUFFER # not used yet
      BUFFER="= $ (q-)$ $ BUFFER#= #  "
      ;;
  esac
 
add-zle-hook-widget line-finish _vbe_calc_quote
When you type = 5 * 3 and press , _vbe_calc_quote strips the = prefix, quotes the remainder with the (q-) parameter expansion flag, and rewrites the buffer to = '5 * 3' before Zsh submits the command. As a bonus, you can save a few keystrokes with =5*3! You can now compute math expressions and convert units directly from your shell. Zsh automatically quotes your expressions:
$ = '1 + 2'
3
$ = 'pi/3 + pi  > cos'
-0.5
$ = '17 USD -> EUR'
14.7122  
$ = '180*500mg -> g'
90 g
$ = '5 gigabytes / (2 minutes + 17 seconds) -> megabits/s'
291.971 Mbit/s
$ = 'now() -> tz("Asia/Tokyo")'
2026-03-22 22:00:03 JST (UTC +09), Asia/Tokyo
$ = '1 / (40 rods / hogshead) -> L / 100km'
118548   0.01 l/km
 That's the way I like it!  says Grampa Simpson
The metric system is the tool of the devil! My car gets forty rods to the hogshead, and that's the way I like it! Grampa Simpson, A Star Is Burns

Storing unquoted history As is, Zsh records the quoted expression in history. You must unquote it before submitting it again. Otherwise, the ZLE widget quotes it a second time. Bart Schaefer provided a solution to store the original version:
_vbe_calc_history()  
  return $ +_vbe_calc_expr 
 
add-zsh-hook zshaddhistory _vbe_calc_history
_vbe_calc_preexec()  
  (( $ +_vbe_calc_expr  )) && print -s $_vbe_calc_expr
  unset _vbe_calc_expr
  return 0
 
add-zsh-hook preexec _vbe_calc_preexec
The zshaddhistory hook returns 1 if we are evaluating an expression, telling Zsh not to record the command. The preexec hook then adds the original, unquoted command with print -s.
The complete code is available in my zshrc. A common alternative is the noglob precommand modifier. If you stick with to instead of -> for unit conversion, it covers 90% of use cases. For a related Zsh line editor trick, see how I use auto-expanding aliases to fix common typos.

  1. This is the fastest a packet can travel back and forth between Paris and Marseille over optical fiber.
  2. Qalculate is less understanding with units. For example, it parses Mbps as megabarn per picosecond:
    $ numbat -e '5 MB/s -> Mbps'
    40 Mbps
    $ qalc 5 MB/s to Mbps
    5 megabytes/second = 0.000005 B/ps
    

Next.

Previous.