Search Results: "reg"

16 March 2026

Russ Allbery: Review: The Martian Contingency

Review: The Martian Contingency, by Mary Robinette Kowal
Series: Lady Astronaut #4
Publisher: Tor
Copyright: 2025
ISBN: 1-250-23703-3
Format: Kindle
Pages: 390
The Martian Contingency is the fourth book of the mostly-realistic science fiction alternate history series that began with the novelette "The Lady Astronaut of Mars" and the novel The Calculating Stars. It returns to Elma York as the main character, covering her second trip to Mars after the events of The Fated Sky. It's helpful to remember the events of the previous two books to follow some of the plot. Elma is back on Mars, this time as second in command. The immediate goal of the second Mars mission is to open more domes and land additional crew currently in orbit, creating the first permanent human settlement on Mars. The long-term goal is to set up Mars as a refuge in case the greenhouse effect caused by the meteor strike in The Calculating Stars continues to spiral out of control. Elma is anxious and not looking forward to being partly in charge, particularly since her position is partly due to her fame with the public (and connection with the American president). She'd rather just be a pilot. But she'll do what the mission needs from her, and at least this time her husband is with her on Mars. As one might expect from earlier installments of this series, The Martian Contingency starts with the details and rhythms of life in a dangerous, highly technical, and mission-driven scientific environment: hard science fiction of the type most closely modeled on NASA and real space missions. Given that this is aimed at permanent Mars colonies that would theoretically have to be independent of Earth, it requires a huge amount of suspension of disbelief for the premise, but Kowal at least tries for verisimilitude in the small details. I am not an expert in early space program technology (Kowal's alternate history diverges into a greatly accelerated space program in the 1950s and, for example, uses female mathematicians for most calculations), so I don't know how successful this is, but it feels crunchy and believable. As with the previous books, though, this is not just a day in the life of an astronaut. There's something wrong, something that happened during the first Mars expedition while Elma was in orbit and left odd physical clues, and no one is willing to talk about it. Elma is just starting to poke around before the politics at home go off the rails (again), exacerbated by a cringe-worthy social error by Elma herself, and she once again has to navigate egregious sexism and political meddling in a highly dangerous environment a long way from home. It is a little surprising that I like this series as much as I do. I don't particularly care for pseudo-realistic science fiction, although I admit there is something deeply satisfying about reading about people following checklists properly. The idea of permanent Mars colonies as an escape from a doomed Earth is unbelievable and deeply silly, but Kowal locked herself into that alternate future with "The Lady Astronaut of Mars," which is still set in the future of all of the books so far. A primary conflict in each of the books comes from the egregious sexism and racism of a culture based on 1950s American attitudes towards both, and the amount of progress Elma can make against either is limited, contingent, and constantly compromised. And yet. At its best, this series is excellent competence porn, both in the spirit of the Apollo 13 movie and for the navigation of social and political obstacles and idiocy. Elma is highly competent in a believable and sympathetic way, with strengths, weaknesses, and an ongoing struggle with anxiety. There is something rewarding in watching people solve problems and eventually triumph by being professional, careful, principled, and creative. It's enough to make a good book, even if I am not that interested in the setting and technology. As with the rest of the series, this will not be for everyone. You have to be up for reading about a lot of truly awful sexism and racism without the payoff of a complete triumph. This is a system that Elma navigates, not overthrows, and that's not going to be enough for some readers. You also have to accept the premise of a Mars colony, which in an otherwise hard science fiction novel is a bit much despite Kowal's attempts to acknowledge some of the difficulties. But if you don't mind that drawbacks, this series continues to be an opportunity to read about people being quietly and professionally competent. This is not my favorite entry, mostly because Elma makes a rather humiliating mistake that's central to the plot and has a lot of after-effects (and therefore a lot of time in the spotlight), and because there is rather a lot of discussion of sexuality that felt childish to me. The intent was to try to capture the way people in the 1950s talked about sex, and perhaps Kowal was successful in that, but I didn't enjoy the experience. But I still found myself pulled into the plot and happily rooting for the characters, even though a reader of "The Lady Astronaut of Mars" has a pretty good idea of how everything will turn out. If you liked the series so far, recommended, although I doubt it will be the favorite entry for most readers. If you did not like the earlier books of the series, this one will not change your mind. Content notes: Way, way too much detailed discussion of an injury to a fingernail than I wanted to read, as well as some other rather explicit description of physical injury. Reproductive health care through the lens of the 1950s, so, uh, yeah. A whole lot of sexism, racism, and other forms of discrimination that is mostly worked around rather than confronted. Rating: 7 out of 10

Freexian Collaborators: Monthly report about Debian Long Term Support, February 2026 (by Thorsten Alteholz)

The Debian LTS Team, funded by [Freexian s Debian LTS offering] (https://www.freexian.com/lts/debian/), is pleased to report its activities for February.

Activity summary During the month of February, 20 contributors have been paid to work on Debian LTS (links to individual contributor reports are located below). The team released 35 DLAs fixing 527 CVEs. We also welcomed Arnaud Rebillout to the team and had to say farewell to Roberto, who left the team after more than nine years as part of it. The team continued preparing security updates in its usual rhythm. Beyond the updates targeting Debian 11 ( bullseye ), which is the current release under LTS, the team also proposed updates for more recent releases (Debian 12 ( bookworm ) and Debian 13 ( trixie )), including Debian unstable. Notable security updates:
  • Guilhem Moulin prepared DLA 4492-1 for gnutls28 to fix vulnerabilities which may lead to Denial of Service.
  • Utkarsh Gupta prepared DLA 4464-1 for xrdp, to fix a a vulnerability that could allow remote attackers to execute arbitrary code on the target system.
  • Emilio Pozuelo Monfort prepared DLA-4465-1 to replace ClamAV 1.0 with ClamAV 1.4. This latter is the current LTS version supported by upstream.
  • Markus Koschany prepared DLA 4468-1 for tomcat9, to fix a vulnerability that can be used to bypass security constraints.
  • Santiago Ruano Rinc n prepared DLA 4471-1 to update package debian-security-support, the Debian security coverage checker.
  • Bastien Roucari s prepared DLA 4473-1 for zabbix, to fix a potential remote code execution vulnerability.
  • Paride Legovini prepared DLA 4478-1 for tcpflow, to fix a vulnerability that might result in DoS and potentially code execution.
  • Thorsten Alteholz prepared DLA 4477-1 for munge, to fix a vulnerability which may allow local users to leak the MUNGE cryptographic key and forge arbitrary credentials.
  • Ben Hutchings prepared DLA 4475-1 and DLA 4476-1 for Linux kernel updates.
  • Chris Lamb prepared DLA 4482-1 for ceph, to fix SSL certificate checking in the Python bindings.
  • Andreas Henriksson prepared DLA 4491-1 to fix vulnerabilities in glib2.0, which could result in denial of service, memory corruption or potentially arbitrary code execution.
Contributions from outside the LTS Team:
  • The update of nova was prepared by the maintainer, Thomas Goirand. The corresponding DLA 4486-1 was published by Carlos Henrique Lima Melara.
  • The updates of thunderbird were prepared by the maintainer Christoph Goehre. The corresponding DLA 4466-1 and DLA 4495-1 was published by Emilio Pozuelo Monfort.
The LTS Team has also contributed with updates to the latest Debian releases:
  • Jochen prepared a point update of wireshark for bookworm (#1127945).
  • Jochen prepared point updates of erlang for trixie (#1127606) and bookworm (#1127607).
  • Bastien helped preparing DSA 6160-1 for netty and uploaded a fixed package to unstable.
  • Bastien prepared a point update of zabbix for trixie (#1127437).
  • Tobias prepared a point update of modsecurity-crs for bookworm (#1128655).
  • Tobias prepared a point update of busybox for bookworm (#1129503).
  • Tobias helped preparing DSA 6138-1 for libpng1.6.
  • Daniel prepared point updates of python-authlib for trixie (#1129477) and bookworm (#1129246).
  • Ben uploaded several Linux kernel packages to trixie-backports and bookworm-backports.
  • Ben prepared point updates of wireless-regdb for trixie and bookworm.
Other than the work related to updates, Sylvain made several improvements to the documentation and tooling used by the team. Some milestones in the lifecycle of two Debian releases are just around the corner. The support of Debian 12 will be handed over to the LTS team on June 11th 2026. After August 31st, support for Debian 11 will move from Debian LTS to ELTS managed by Freexian.

Individual Debian LTS contributor reports

Thanks to our sponsors Sponsors that joined recently are in bold.

Freexian Collaborators: Regression Tracking in Debusine (by Stefano Rivera)

Regression Tracking Debusine is a tool designed for Debian developers and Operating System developers in general. Debusine can run QA pipelines to check that Debian packages are ready to upload. This blog post describes the regression tracking mechanism that s recently become available in Debusine QA pipelines. The debian_pipeline workflow in Debusine can build, test, and upload a package to the Debian archive (or any other repository, such as a native Debusine APT repository). The QA tests involve running the standard Debian QA utilities (lintian, autopkgtest, piuparts, blhc) on the built artifacts. In addition we can run the autopkgtests of every other package in the archive that depends on the built package, like britney does for testing migration in Debian. Some of these other packages may have currently-failing autopkgtests that have nothing to do with the changes in the upload under test. For example: A Pipeline Figuring out which of these failures are new (and thus worth investigating) has been a manual process in Debusine until now. We have just completed the basic functionality of the regression_tracking=true feature, and have enabled it in the upload-to-* workflows on debusine.debian.net. With this enabled, you ll get a new QA tab on your debian_pipeline workflows that shows the trend of each test: QA Results This is determined by looking at recent task history for each task in the debian:qa-results collection. If there is no recent result for a given <package, version, architecture>, then tasks are queued under the reference tests qa workflow tree on the pipeline. These reference tests are run by using the same tasks as the main qa workflow, but without the addition of the package under test. In fact, it uses the same qa workflow that we use to check the package, but with a few different parameters to populate the regression tracking results collection. The debian:qa-results collection used for analyzing regressions is specified to the debian_pipeline with the regression_tracking_qa_results lookup parameter. On debusine.debian.net we have configured a debian:qa-results collection for sid that can be referenced and added to by tasks in any workspace. Regressions can be more subtle than a simple Success Failure. If the number of autopkgtests that fail increases, or the number of lintian tags emitted increases, those are also considered a regressions.

Using regression tracking now It s enabled by default on most of the upload-to-* workflows on debusine.debian.net. To disable, pass -O debusine_workflow_data.enable_regression_tracking=false when you dput an upload to debusine. To use the regression-tracking in your own workflows, use a debian_pipeline workflow that is configured with enable_regression_tracking=true. This will require a qa_suite to be specified, pointing to the baseline suite. We hope this will make it easier to check QA results for packages tested on debusine.debian.net.

15 March 2026

Russell Coker: The Difference Between Email and Instant Messaging

Introduction With various forms of IM becoming so prevalent and a lot of communication that used to be via email happening via IM I ve been thinking about the differences between Email and IM. I think it s worth comparing them not for the purpose of convincing people to use one or the other (most people will use whatever is necessary to communicate with the people who are important to them) but for the purpose of considering ways to improve them and use them more effectively. Also I don t think that users of various electronic communications systems have had a free choice in what to use for at least 25 years and possibly much longer depending on how you define a free choice. What you use is determined by who you want to communicate with and by what systems are available in your region. So there s no possibility of an analysis of this issue giving a result of let s all change what we use as almost everyone lacks the ability to make a choice. What the Difference is Not The name Instant Messaging implies that it is fast, and probably faster than other options. This isn t necessarily the case, when using a federated IM system such as Matrix or Jabber there can be delays while the servers communicate with each other. Email used to be a slow communication method, in the times of UUCP and Fidonet email there could be multiple days of delay in sending email. In recent times it s expected that email is quite fast, many web sites have options for authenticating an email address which have to be done within 5 minutes so the common expectation seems to be that all email is delivered to the end user in less than 5 minutes. When an organisation has a mail server on site (which is a common configuration choice for a small company) the mail delivery can be faster than common IM implementations. The Wikipedia page about Instant Messaging [1] links to the Wikipedia page about Real Time Computing [2] which is incorrect. Most IM systems are obviously designed for minimum average delays at best. For most software it s not a bad thing to design for the highest performance on average and just let users exercise patience when they get an unusual corner case that takes much longer than expected. If an IM message takes a few minutes to arrive then that s life on the Internet which was the catchphrase of an Australian Internet entrepreneur in the 90s that infuriated some of his customers. Protocol and Data Format Differences Data Formats Email data contains the sender, one or more recipients, some other metadata (time, subject, etc), and the message body. The recipients are typically an arbitrary list of addresses which can only be validated by the destination mail servers. The sender addresses weren t validated in any way and are now only minimally validated as part of anti-spam measures. IM data is sent through predefined connections called rooms or channels. When an IM message is sent to a room it can tag one or more members of the room to indicate that they may receive a special notification of the message. In many implementations it s possible to tag a user who isn t in the room which may result in them being invited to the room. But in IM there is no possibility to add a user to the CC list for part of a discussion and then just stop CCing messages to them later on in the discussion. Protocols Internet email is a well established system with an extensive user base. Adding new mandatory features to the protocols isn t viable because many old systems won t be updated any time soon. So while it is possible to send mail that s SSL encrypted and has a variety of authentication mechanisms that isn t something that can be mandatory for all email. Most mail servers are configured to use the SSL option if it s available but send in cleartext otherwise, so a hostile party could launch a Man In the Middle (MITM) attack and pretend to be the mail server in question but without SSL support. Modern IM protocols tend to be based on encryption, even XMPP (Jabber) which is quite an old IM protocol can easily be configured to only support encrypted messaging and it s reasonable to expect that all other servers that will talk to you will at least support SSL. Even for an IM system that is run by a single company the fact that communication with the servers is encrypted by SSL makes it safer than most email. A security model of this can only be read by you, me, and the staff at an American corporation isn t the worst type of Internet security. The Internet mail infrastructure makes no attempt to send mail in order and the design of the Simple Mail Transfer Protocol (SMTP) means that a network problem after a message has been sent but before the recipient has confirmed receipt will mean that the message is duplicated and this is not considered to be a problem. The IM protocols are designed to support reliable ordered transfer of messages and Matrix (the most recently designed IM protocol) has cryptographic connections between users. Forgery For most email systems there is no common implementation that prevents forging email. For Internet email transferred via SMTP it s possible to use technologies like SPF and DKIM/DMARC to make recipients aware of attempts at forgery, but many recipient systems will still allow email that fails such checks to be delivered. The default configuration tends to be permitting everything and all of the measures to prevent forgery require extra configuration work and often trade-offs as some users desire features that go against security. The default configuration of most mail servers doesn t even prevent trivial forgeries of email from the domain(s) owned by that server. For evidence check the SPF records of some domains that you communicate with and see if they end with -all (to block email from bad sources), ~all (to allow email from bad sources through after possibly logging an error), ?all (to be neutral on mail from unknown sources, or just lack a SPF record entirely. The below shows that of the the top four mail servers in the world only outlook.com has a policy to reject mail from bad sources.
# dig -t txt _spf.google.com grep spf1
_spf.google.com.	300	IN	TXT	"v=spf1 ip4:74.125.0.0/16 ip4:209.85.128.0/17 ip6:2001:4860:4864::/56 ip6:2404:6800:4864::/56 ip6:2607:f8b0:4000::/36 ip6:2800:3f0:4000::/36 ip6:2a00:1450:4000::/36 ip6:2c0f:fb50:4000::/36 ~all"
# dig -t txt outlook.com grep spf1
outlook.com.		126	IN	TXT	"v=spf1 include:spf2.outlook.com -all"
# dig -t txt _spf.mail.yahoo.com grep spf1
_spf.mail.yahoo.com.	1800	IN	TXT	"v=spf1 ptr:yahoo.com ptr:yahoo.net ip4:34.2.71.64/26 ip4:34.2.75.0/26 ip4:34.2.84.64/26 ip4:34.2.85.64/26 ip4:34.2.64.0/22 ip4:34.2.68.0/23 ip4:34.2.70.0/23 ip4:34.2.72.0/22 ip4:34.2.78.0/23 ip4:34.2.80.0/23 ip4:34.2.82.0/23 ip4:34.2.84.0/24 ip4:34.2.86.0" "/23 ip4:34.2.88.0/23 ip4:34.2.90.0/23 ip4:34.2.92.0/23 ip4:34.2.85.0/24 ip4:34.2.94.0/23 ?all"
# dig -t txt icloud.com grep spf1
icloud.com.		3586	IN	TXT	"v=spf1 ip4:17.41.0.0/16 ip4:17.58.0.0/16 ip4:17.142.0.0/15 ip4:17.57.155.0/24 ip4:17.57.156.0/24 ip4:144.178.36.0/24 ip4:144.178.38.0/24 ip4:112.19.199.64/29 ip4:112.19.242.64/29 ip4:222.73.195.64/29 ip4:157.255.1.64/29" " ip4:106.39.212.64/29 ip4:123.126.78.64/29 ip4:183.240.219.64/29 ip4:39.156.163.64/29 ip4:57.103.64.0/18" " ip6:2a01:b747:3000:200::/56 ip6:2a01:b747:3001:200::/56 ip6:2a01:b747:3002:200::/56 ip6:2a01:b747:3003:200::/56 ip6:2a01:b747:3004:200::/56 ip6:2a01:b747:3005:200::/56 ip6:2a01:b747:3006:200::/56 ~all"
In most IM systems there is a strong connection between people who communicate. If I send you two direct messages they will appear in the same room, and if someone else tries forging messages from me (EG by replacing the c and e letters in my address with Cyrillic letters that look like them or by mis-spelling my name) a separate room will be created and it will be obvious that something unexpected is happening. Protecting against the same attacks in email requires the user carefully reading the message, given that it s not uncommon for someone to start a message to me with Hi Russel (being unable to correctly copy my name from the To: field of the message they are writing) it s obvious that any security measure relying on such careful reading will fail. The IM protections against casual forgery also apply to rooms with multiple users, a new user can join a room for the purpose of spamming but they can t send a casual message impersonating a member of the room. A user can join a Matrix room I m in with the name Russell from another server but the potential for confusion will be minimised by a message notifying everyone that another Russell has joined the room and the list of users will show two Russells. For email the protections against forgery when sending to a list server are no different than those when sending to an individual directly which means very weak protections. Authenticating the conversation context once as done with IM is easier and more reliable than authenticating each message independently. Is Email Sucking the Main Technical Difference? It seems that the problems with forgery, spam, and general confusion when using email are a large part of the difference between email and IM. But in terms of technical issues the fact that email has significantly more users (if only because you need an email account to sign up for an IM system) is a major difference. Internet email is currently a universal system (apart from when it breaks from spam) and it has historically been used to gateway to other email systems like Fidonet, Uucp, and others. The lack of tight connection between parties that exchange messages in email makes it easier to bridge between protocols but harder to authenticate communication. Most of the problems with Internet email are not problems for everyone at all times, they are technical trade-offs that work well for some situations and for some times. Unfortunately many of those trade-offs are for things that worked well 25+ years ago. The GUI From a user perspective there doesn t have to be a great difference between email and IM. Email is usually delivered quickly enough to be in the same range as IM. The differences in layout between IM client software and email client software is cosmetic, someone could write an email client that organises messages in the same way as Slack or another popular IM system such that the less technical users wouldn t necessarily know the difference. The significant difference in the GUI for email and IM software was a design choice. Conversation Organisation The most significant difference in the operation of email and IM at the transport level is the establishment of connections in IM. Another difference is the fact that there are no standards implemented for the common IM implementations to interoperate which is an issue of big corporations creating IM systems and deliberately making them incompatible. The methods for managing email need to be improved. Having an inbox that s an unsorted mess of mail isn t useful if you want to track one discussion, breaking it out into different sub folders for common senders (similar to IM folders for DMs) as a standard feature without having to setup rules for each sender would be nice. Someone could design an email program with multiple layouts, one being the traditional form (which seems to be copied from Eudora [3]) and one with the inbox (or other folders) split up into conversations. There are email clients that support managing email threads which can be handy in some situations but often isn t the best option for quickly responding to messages that arrived recently. Archiving Most IM systems have no method for selectively archiving messages, there s a request open for a bookmark function in Matrix and there s nothing stopping a user from manually copying a message. But there s nothing like the convenient ability to move email to an archive folder in most IM systems. Without good archiving IM is a transient medium. This is OK for conversations but not good for determining the solutions to technical problems unless there is a Wiki or other result which can be used without relying on archives. Composing Messages In a modern email client when sending a message it prompts you for things that it considers complete, so if you don t enter a Subject or have the word attached in the message body but no file is attached to the message then it will prompt you to confirm that you aren t making a mistake. In an IM client the default is usually that pressing ENTER sends the message so every paragraph is a new message. IM clients are programmed to encourage lots of short messages while email clients are programmed to encourage more complete messages. Social Issues Quality The way people think about IM and email is very different, as one example there was never a need for a site like nohello.net for email. The idea that it s acceptable to use even lower quality writing in IM than people tend to use in email seems to be a major difference between the communication systems. It can be a good thing to have a chatty environment with messages that are regarded as transient for socialising, but that doesn t seem ideal for business use. Ownership Email is generally regarded as being comparable to physical letters. It is illegal and widely considered to be socially wrong to steal a letter from someone s letterbox if you regret sending it. In email the only unsend function I m aware of is that in Microsoft software which is documented to only work within the same organisation, and that only works if the recipient hasn t read the message. The message is considered to be owned by the recipient. But for IM it s a widely supported and socially acceptable function to delete or edit messages that have been sent. The message is regarded as permanently the property of the sender. What Should We Do? Community Creators When creating a community (and I use this in the broadest sense including companies) you should consider what types of communication will work well. When I started the Flounder group [4] I made a deliberate decision that non-free communication systems go against the aim of the group, I started it with a mailing list and then created a Matrix room which became very popular. Now the list hardly gets any use. It seems that most of the communication in the group is fairly informal and works better with IM. Does it make sense to use both? Should IM systems be supplemented with other systems that facilitate more detail such as a Wiki or a Lemmy room/instance [5] to cover the lack of long form communication? I have created a Lemmy room for Flounder but it hasn t got much interest so far. It seems that almost no-one makes a strategic decision about such issues. Software Developers It would be good to have the same options for archiving IM as there are for email. Also some options to encourage quality in IM communication similar to the way email clients want confirmation before sending messages without a subject or that might be missing an attachment. It would also be good to have better options for managing conversations in email. The Inbox as currently used is good for some things but a button to switch between that and a conversation view would be good. There are email clients that allow selecting message sort order and aggregation (kmail has a good selection of options) but they are designed for choosing a single setup that you like not between multiple views based on the task you are doing. It would be good to have links between different communication systems, if users had the option of putting their email address in their IM profile it would make things much easier. Having entirely separate systems for email and IM isn t good for users. Users The overall communications infrastructure could be improved if more people made tactical decisions about where and how to communicate. Keep the long messages to email and the chatty things to IM. Also for IM just do the communication not start with hello . To discourage wasting time I generally don t reply to messages that just say hello unless it s the first ever IM from someone. Conclusion A large part of the inefficiencies in electronic communication are due to platforms and usage patterns evolving with little strategic thought. The only apparent strategic thought is coming from corporations that provide IM services and have customer lock in at the core of their strategies. Free software developers have done great work in developing software to solve tactical problems but the strategies of large scale communications aren t being addressed. Email is loosely coupled and universal while IM is tightly coupled, authenticated, and often siloed. This makes email a good option for initial contact but a risk for ongoing discussions. There is no great solution to these issues as they are largely a problem due to the installed user base. But I think we can mitigate things with some GUI design changes and strategic planning of communication.

Vasudev Kamath: Using Gemini CLI to Configure the Hyprland Window Manager

What led to this experiment? Well, for one, Well, for one, there was a thought shared by Andrej Karpathy regarding the shift towards "Agentic" workflows.
"The future of software is not just 'tools', but 'agents' that can navigate complex tasks on your behalf."

Andrej Karpathy

Recently, I spoke with Ritesh, who mentioned his success using the Gemini CLI to debug an idle power drain issue on his laptop. I wanted to experiment with this myself, and I had the perfect use case: configuring the Hyprland Window Manager on my aging laptop. The machine is nearly eight years old with 12GB of RAM (upgraded from the original 4GB). I found that GNOME and KDE were becoming overkill, often leading to system freezes when running multiple AI-powered IDEs like Antigravity and VS Code with Co-pilot. Coincidentally, I noticed my Jio number had a "Google One 2TB" and "Google AI Premium" plan available to claim. I claimed it, and now here I am, experimenting with the Gemini CLI.
Getting Started First, you need to install geminicli. It is an open-source project, and currently, the easiest way to install it is via the Node Package Manager (npm):
npm install -g @google/gemini-cli
Next, we need to create a context for Gemini a set of instructions for it to follow throughout the project. This is managed via a GEMINI.md file. I went to Google Gemini, explained my requirements, and asked it to generate one for me. My requirements were:
  1. A minimalist but fully functional session, comparable to my existing GNOME setup.
  2. Basic functionalities including wallpaper, screen locks, and a status bar with system icons.
  3. Swapping Control and Caps Lock (a must for Emacs users).
  4. Mandatory permission prompts for privileged operations; otherwise, it can work freely within a specified directory.
  5. Persistent memory/artifacts for the session.
  6. Permission to inspect my current session to understand the existing hardware and software configuration.
The goal was to reduce bloat and reclaim memory for heavy applications like Antigravity and VS Code. Gemini provided the following GEMINI.md file:
# Role: Hyprland Configuration Specialist (Minimalist & High-Performance)
You are a Linux Systems Engineer specializing in migrating users from heavy
Desktop Environments to minimalist, tiling-based Wayland sessions on Debian.
Your goal is to maximize available RAM for heavy applications while maintaining
essential desktop features.
## 1. Environment & Persona
- **Target OS:** Debian (Linux)
- **Target WM:** Hyprland
- **Hardware:** ThinkPad E470 (i5-7th Gen, 12GB RAM)
- **User Profile:** Emacs user, prioritizes "anti-gravity" (zero bloat).
- **Tone:** Technical, concise, and security-conscious.
## 2. Core Functional Requirements
- **Status Bar:**  waybar  (with CPU, RAM, Network, and Battery icons).
- **Wallpaper:**  swww  or  hyprpaper .
- **Screen Lock:**  hyprlock  +  hypridle .
- **Input Mapping:** Swap Control and Caps Lock ( kb_options = ctrl:nocaps ).
## 3. Operational Constraints
- **Permission First:** Ask before using  sudo  or writing outside the work directory.
- **Inspection:** Use  hyprctl ,  lsmod , or  gsettings  for compatibility checks.
- **Artifact Management:** Update  MEMORY.md  after every major step.
Gemini also recommended creating a MEMORY.md file to track progress. Interestingly, Gemini remembered that I had previously shared dmidecode output, so it already knew my exact laptop specs. (Though it did include a note about me being a "daily rice eater" I assume it meant Linux 'ricing,' though I actually use Debian Unstable, not Stable!). The AI suggested starting with this prompt:
Read MEMORY.md and GEMINI.md. Based on my hardware, give me a shell script to inspect my current GNOME environment so we can start replicating the session basics.
How Did It Go? I initialized a git repository for these files and instructed the Gemini CLI to update GEMINI.md and commit changes after every major step so I could track the progress. The workflow looked like this:
  1. Inspection: It created a script to extract my GNOME settings.
  2. Configuration: Once I provided the output, it began configuring Hyprland.
  3. Utilities: It generated an installation script for all required Wayland utilities.
  4. Validation: All changes were staged in a hypr-config-draft folder. I had Gemini verify them using hyprland --verify-config before moving them to ~/.config/hypr.
Most things worked immediately, but I hit a snag with the wallpaper. Even after generating the config, hyprpaper failed to display anything. The AI got stuck in a loop trying to debug it. I eventually spawned a second Gemini CLI instance to review the code and logs. The debug log showed: 'DEBUG ]: Monitor eDP-1 has no target: no wp will be created'. It turns out the configuration format was outdated. By feeding the Hyprpaper Wiki into the AI, it finally corrected the config, and the wallpaper appeared. After that, it successfully fixed an ssh-agent issue and configured a clipboard manager with custom keybindings.
Learnings I have used window managers for a long time because my hardware was rarely top-of-the-line. However, I had moved back to KDE/GNOME with the arrival of Wayland because most of my preferred WMs were X11-based. Manually configuring a window manager is a painful, time-consuming process involving endless wiki-trawling and trial-and-error. What usually takes weeks took only a few hours with the Gemini CLI. AI isn't perfect I still had to step in and guide it when it hit a wall but the efficiency gain is undeniable. If you're interested in the configuration or the history of the session, you can find the repository here. I still have a few pending items in MEMORY.md, but I'll tackle those next time!

13 March 2026

Dirk Eddelbuettel: RcppCNPy 0.2.15 on CRAN: Maintenance

Another maintenance release of the RcppCNPy package arrived on CRAN today, and has already been built as an r2u binary. RcppCNPy provides R with read and write access to NumPy files thanks to the cnpy library by Carl Rogers along with Rcpp for the glue to R. The changes are minor and similar to other recent changes. We aid Rcpp in the transition away from calling Rf_error() by relying in Rcpp::stop() which has better behaviour and unwinding when errors or exceptions are encountered. So once again no user-facing changes. Full details are below.

Changes in version 0.2.15 (2026-03-13)
  • Replaced Rf_error with Rcpp::stop in three files
  • Maintenance updates to continuous integration

CRANberries also provides a diffstat report for the latest release. As always, feedback is welcome and the best place to start a discussion may be the GitHub issue tickets page. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Hellen Chemtai: One week later after the Outreachy internship: Managing Work-Life Balance

Hello world. I have been doing a lot after my internship with Outreachy. We are still working on some tasks :

  1. I am working on running locales for my native language in live images.
  2. I am also working on points to add to talk proposals for a Debian conference.

As I am moving around constantly, there are problems I had encountered when changing my networks. I had to connect my virtual machine to different networks and the network would not reflect within the machine. From terminal I edited the virtual machine XML settings:

su -
// input password
sudo virsh edit <machine_name> #its openqa for me
// Look for the interface within devices and replace this:
<interface type=&aposnetwork&apos>
<source network=&aposdefault&apos/>
#some other code in here
</interface>
// With just this then restart your machine:
<interface type=&aposuser&apos>
<model type=&aposvirtio&apos/>
</interface>

Hopefully the above will help someone out there. I am still working on a lot of tasks regarding the conference, so much to do and so little time. I am hoping I won t get any burnout during this period. I won t be updating much further till the conference. Have a nice time

12 March 2026

Reproducible Builds: Reproducible Builds in February 2026

Welcome to the February 2026 report from the Reproducible Builds project! These reports outline what we ve been up to over the past month, highlighting items of news from elsewhere in the increasingly-important area of software supply-chain security. As ever, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website.

  1. reproduce.debian.net
  2. Tool development
  3. Distribution work
  4. Miscellaneous news
  5. Upstream patches
  6. Documentation updates
  7. Four new academic papers

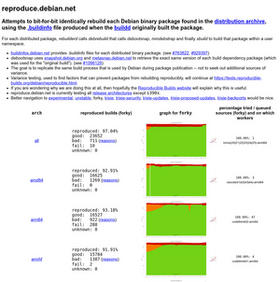
reproduce.debian.net The last year has seen the introduction, development and deployment of reproduce.debian.net. In technical terms, this is an instance of rebuilderd, our server designed monitor the official package repositories of Linux distributions and attempt to reproduce the observed results there. This month, however, Holger Levsen added suite-based navigation (eg. Debian trixie vs forky) to the service (in addition to the already existing architecture based navigation) which can be observed on, for instance, the Debian trixie-backports or trixie-security pages.

Tool development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions, 312 and 313 to Debian. In particular, Chris updated the post-release deployment pipeline to ensure that the pipeline does not fail if the automatic deployment to PyPI fails [ ]. In addition, Vagrant Cascadian updated an external reference for the 7z tool for GNU Guix. [ ]. Vagrant Cascadian also updated diffoscope in GNU Guix to version 312 and 313.

Distribution work In Debian this month:
  • 26 reviews of Debian packages were added, 5 were updated and 19 were removed this month adding to our extensive knowledge about identified issues.
  • A new debsbom package was uploaded to unstable. According to the package description, this package generates SBOMs (Software Bill of Materials) for distributions based on Debian in the two standard formats, SPDX and CycloneDX. The generated SBOM includes all installed binary packages and also contains Debian Source packages.
  • In addition, a sbom-toolkit package was uploaded, which provides a collection of scripts for generating SBOM. This is the tooling used in Apertis to generate the Licenses SBOM and the Build Dependency SBOM. It also includes dh-setup-copyright, a Debhelper addon to generate SBOMs from DWARF debug information, which are extracted from DWARF debug information by running dwarf2sources on every ELF binaries in the package and saving the output.
Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their work there.

Miscellaneous news

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Documentation updates Once again, there were a number of improvements made to our website this month including:

Four new academic papers Julien Malka and Arnout Engelen published a paper titled Lila: Decentralized Build Reproducibility Monitoring for the Functional Package Management Model:
[While] recent studies have shown that high reproducibility rates are achievable at scale demonstrated by the Nix ecosystem achieving over 90% reproducibility on more than 80,000 packages the problem of effective reproducibility monitoring remains largely unsolved. In this work, we address the reproducibility monitoring challenge by introducing Lila, a decentralized system for reproducibility assessment tailored to the functional package management model. Lila enables distributed reporting of build results and aggregation into a reproducibility database [ ].
A PDF of their paper is available online.
Javier Ron and Martin Monperrus of KTH Royal Institute of Technology, Sweden, also published a paper, titled Verifiable Provenance of Software Artifacts with Zero-Knowledge Compilation:
Verifying that a compiled binary originates from its claimed source code is a fundamental security requirement, called source code provenance. Achieving verifiable source code provenance in practice remains challenging. The most popular technique, called reproducible builds, requires difficult matching and reexecution of build toolchains and environments. We propose a novel approach to verifiable provenance based on compiling software with zero-knowledge virtual machines (zkVMs). By executing a compiler within a zkVM, our system produces both the compiled output and a cryptographic proof attesting that the compilation was performed on the claimed source code with the claimed compiler. [ ]
A PDF of the paper is available online.
Oreofe Solarin of Department of Computer and Data Sciences, Case Western Reserve University, Cleveland, Ohio, USA, published It s Not Just Timestamps: A Study on Docker Reproducibility:
Reproducible container builds promise a simple integrity check for software supply chains: rebuild an image from its Dockerfile and compare hashes. We built a Docker measurement pipeline and apply it to a stratified sample of 2,000 GitHub repositories that contained a Dockerfile. We found that only 56% produce any buildable image, and just 2.7% of those are bitwise reproducible without any infrastructure configurations. After modifying infrastructure configurations, we raise bitwise reproducibility by 18.6%, but 78.7% of buildable Dockerfiles remain non-reproducible.
A PDF of Oreofe s paper is available online.
Lastly, Jens Dietrich and Behnaz Hassanshahi published On the Variability of Source Code in Maven Package Rebuilds:
[In] this paper we test the assumption that the same source code is being used [by] alternative builds. To study this, we compare the sources released with packages on Maven Central, with the sources associated with independently built packages from Google s Assured Open Source and Oracle s Build-from-Source projects. [ ]
A PDF of their paper is available online.

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Mike Gabriel: Debian Lomiri Tablets 2025-2027 - Project Report (Q4/2025)

On 25th Oct 2025, I announced via my personal blog and on Mastodon that Fre(i)e Software GmbH was hiring. The hiring process was a mix of asking developers I know and waiting for new people to apply. At the beginning of November 2025 / in mid November 2025, we started with 13 developers (all part-time) to work on various topics around Lomiri (upstream and downstream). Note that the below achievements don't document the overall activity in the Lomiri project, but that part that our team at Fre(i)e Software GmbH contributed to. Organizational Achievements Maintenance Development Qt6 Porting Feature Development Research [1] https://gitlab.com/groups/ubports/development/-/boards/9895029?label_name%5B%5D=Topic%3A%20Qt%206
[2] https://gitlab.com/groups/ubports/development/-/boards/10037876?label_name[]=Topic%3A%20salsa2ubports%20DEB%20syncing

11 March 2026

Dirk Eddelbuettel: RcppDE 0.1.9 on CRAN: Maintenance

Another maintenance release of our RcppDE package arrived at CRAN, and has been built for r2u. RcppDE is a port of DEoptim, a package for derivative-free optimisation using differential evolution, from plain C to C++. By using RcppArmadillo the code became a lot shorter and more legible. Our other main contribution is to leverage some of the excellence we get for free from using Rcpp, in particular the ability to optimise user-supplied compiled objective functions which can make things a lot faster than repeatedly evaluating interpreted objective functions as DEoptim does (and which, in fairness, most other optimisers do too). The gains can be quite substantial. This release is again maintenance. We aid Rcpp in the transition away from calling Rf_error() by relying in Rcpp::stop() which has better behaviour and unwinding when errors or exceptions are encountered. We also overhauled the references in the vignette, added an Armadillo version getter and made the regular updates to continuous integration. Courtesy of my CRANberries, there is also a diffstat report. More detailed information is on the RcppDE page, or the repository.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

10 March 2026

Freexian Collaborators: Debian Contributions: Opening DebConf 26 Registration, Debian CI improvements and more! (by Anupa Ann Joseph)

Debian Contributions: 2026-02 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

DebConf 26 Registration, by Stefano Rivera, Antonio Terceiro, and Santiago Ruano Rinc n DebConf 26, to be held in Santa Fe Argentina in July, has opened for registration and event proposals. Stefano, Antonio, and Santiago all contributed to making this happen. As always, some changes needed to be made to the registration system. Bigger changes were planned, but we ran out of time to implement them for DebConf 26. All 3 of us have had experience in hosting local DebConf events in the past and have been advising the DebConf 26 local team.

Debian CI improvements, by Antonio Terceiro Debian CI is the platform responsible for automated testing of packages from the Debian archive, and its results are used by the Debian Release team automation as Quality Assurance to control the migration of packages from Debian unstable into testing, the base for the next Debian release. Antonio started developing an incus backend, and that prompted two rounds of improvements to the platform, including but not limited to allowing user to select a job execution backend (lxc, qemu) during the job submission, reducing the part of testbed image creation that requires superuser privileges and other refactorings and bug fixes. The platform API was also improved to reduce disruption when reporting results to the Release Team automation after service downtimes. Last, but not least, the platform now has support for testing packages against variants of autopkgtest, which will allow the Debian CI team to test new versions of autopkgtest before making releases to avoid widespread regressions.

Miscellaneous contributions
  • Carles improved po-debconf-manager while users requested features / found bugs. Improvements done - add packages from unstable instead of just salsa.debian.org, upgrade and merge templates of upgraded packages, finished adding typing annotations, improved deleting packages: support multiple line texts, add debug to see subprocess.run commands, etc.
  • Carles, using po-debconf-manager, reviewed 7 Catalan translations and sent bug reports or MRs for 11 packages. Also reviewed the translations of fortunes-debian-hints and submitted possible changes in the hints.
  • Carles submitted MRs for reportbug (reportbug --ui gtk detecting the wrong dependencies), devscript (delete unused code from debrebuild and add recommended dependency), wcurl (format help for 80 columns). Carles submitted a bug report for apt not showing the long descriptions of packages.
  • Carles resumed effort for checking relations (e.g. Recommends / Suggests) between Debian packages. A new codebase (still in early stages) was started with a new approach in order to detect, report and track the broken relations.
  • Emilio drove several transitions, most notably the haskell transition and the glibc/gcc-15/zlib transition for the s390 31-bit removal. This last one included reviewing and requeueing lots of autopkgtests due to britney losing a lot of results.
  • Emilio reviewed and uploaded poppler updates to experimental for a new transition.
  • Emilio reviewed, merged and deployed some performance improvements proposed for the security-tracker.
  • Stefano prepared routine updates for pycparser, python-confuse, python-cffi, python-mitogen, python-pip, wheel, platformdirs, python-authlib, and python-virtualenv.
  • Stefano updated Python 3.13 and 3.14 to the latest point releases, including security updates, and did some preliminary work for Python 3.15.
  • Stefano reviewed changes to dh-python and merged MRs.
  • Stefano did some debian.social sysadmin work, bridging additional IRC channels to Matrix.
  • Stefano and Antonio, as DebConf Committee Members, reviewed the DebConf 27 bids and took part in selecting the Japanese bid to host DebConf 27.
  • Helmut sent patches for 29 cross build failures.
  • Helmut continued to maintain rebootstrap addressing issues relating to specific architectures (such as musl-linux-any, hurd-any or s390x) or specific packages (such as binutils, brotli or fontconfig).
  • Helmut worked on diagnosing bugs such as rocblas #1126608, python-memray #1126944 upstream and greetd #1129070 with varying success.
  • Antonio provided support for multiple MiniDebConfs whose websites run wafer + wafer-debconf (the same stack as DebConf itself).
  • Antonio fixed the salsa tagpending webhook.
  • Antonio sent specinfra upstream a patch to fix detection of Debian systems in some situations.
  • Santiago reviewed some Merge Requests for the Salsa CI pipeline, including !703 and !704, that aim to improve how the build source job is handled by Salsa CI. Thanks a lot to Jochen for his work on this.
  • In collaboration with Emmanuel Arias, Santiago proposed a couple of projects for the Google Summer of Code (GSoC) 2026 round. Santiago has been reviewing applications and giving feedback to candidates.
  • Thorsten uploaded new upstream versions of ipp-usb, brlaser and gutenprint.
  • Rapha l updated publican to fix an old bug that became release critical and that happened only when building with the nocheck profile. Publican is a build dependency of the Debian s Administrator Handbook and with that fix, the package is back into testing.
  • Rapha l implemented a small feature in Debusine that makes it possible to refer to a collection in a parent workspace even if a collection with the same name is present in the current workspace.
  • Lucas updated the current status of ruby packages affecting the Ruby 3.4 transition after a bunch of updates made by team members. He will follow up on this next month.
  • Lucas joined the Debian orga team for GSoC this year and tried to reach out to potential mentors.
  • Lucas did some content work for MiniDebConf Campinas - Brazil.
  • Colin published minor security updates to bookworm and trixie for CVE-2025-61984 and CVE-2025-61985 in OpenSSH, both of which allowed code execution via ProxyCommand in some cases. The trixie update also included a fix for mishandling of PerSourceMaxStartups.
  • Colin spotted and fixed a typo in the bug tracking system s spam-handling rules, which in combination with a devscripts regression caused bts forwarded commands to be discarded.
  • Colin ported 12 more Python packages away from using the deprecated (and now removed upstream) pkg_resources module.
  • Anupa is co-organizing MiniDebConf Kanpur with Debian India team. Anupa was responsible for preparing the schedule, publishing it on the website, co-ordination with the fiscal host in addition to attending meetings.
  • Anupa attended the Debian Publicity team online sprint which was a skill sharing session.

9 March 2026

Isoken Ibizugbe: Starting Out in Outreachy

So you want to join Outreachy but you don t understand it, you re scared, or you don t know what open source is about.

What is FOSS anyway?

Free and Open Source Software (FOSS) refers to software that anyone can use, modify, and share freely. Think of it as a community garden; instead of one company owning the food, people from all over the world contribute, improve, and maintain it so everyone can benefit for free. You can read more here on what it means to contribute to open source.

Outreachy provides paid internships to anyone from any background who faces underrepresentation, systemic bias, or discrimination in the technical industry where they live. Their goal is to increase diversity in open source. Read their website for more. I spent a good amount of time reading all the guides listed, including the applicant guide and the how-to-apply guide.

The Secret to Applying (Spoiler: It s not a secret)

I know newcomers are scared or unsure and would prefer answers from previous participants, but the Outreachy website is actually a goldmine, almost every question you have is already answered there if you look closely. I used to hate reading documentation, but I ve learned to love it. Documentation is the Source of Truth.

  • My Advice: Read every single guide on their site. The applicant guide is your roadmap. Embracing documentation now will make you a much better contributor later.

The AI Trap: Be Yourself

Now for the part most newcomers have asked about is the initial essay. I know it s tempting to use AI, but I really encourage you to skip it for this. Your own story is much more powerful than a generated one. Outreachy and its mentoring organizations value your unique story. They are strongly against fabricated or AI-exaggerated essays.

For example, when I contributed to Debian using openQA, the information wasn t well established on the web. When I tried to use AI, it suggested imaginary ideas. The project maintainers had a particular style of contributing, so I had to follow the instructions carefully, observe the codebase, and read the provided documentation. With that information, I always wrote a solution first before consulting AI, and mine was always better. AI can only be intelligent in the context of what you give it; if it doesn t have your answer, it will look for the most similar solution (hallucinate). We do not want to increase the burden on reviewers their time is important because they are volunteers, too. This is crucial when you qualify for the contribution phase.

The Application Process

There are two main stages:

  • The initial application: Here you fill in basic details, time availability, and essay questions (you can find these on the Outreachy website).
  • The contribution phase: This is where you show you have the skills to work on the projects. Every project will list the skills needed and the level of proficiency.

When you qualify for the contribution phase:
  • A lot of people will try to create buzz or even panic; you just have to focus. Once you ve gotten the hang of the project, remember to help others along the way.
  • You can start contributions with spelling corrections, move to medium tasks (do multiple of these), then a hard task if possible. You don t need to be a guru on day one.
  • It s all about community building. Do your part to help others understand the project too; this is also a form of contribution.
  • Lastly, every project mentor has a way of evaluating candidates. My summary is: be confident, demonstrate your skills, and learn where you are lacking. Start small and work your way up, you don t have to prove yourself as a guru.

Tips
  • Watch this: This step-by-step video is a great walkthrough of the initial application process.
  • Sign up for the email list to get updates: https://lists.outreachy.org/cgi-bin/mailman/listinfo/announce
  • Be fast: Complete your initial application in the first 3 days, as there are a lot of applicants.
  • Back it up: In your essay about systemic bias, include some statistics to back it up.
  • Learn Git: Even if you don t have programming skills, contributions are pushed to GitHub or GitLab. Practice some commands and contribute to a first open issue to understand the flow: https://github.com/firstcontributions/first-contributions

The most important tip? Apply anyway. Even if you feel underqualified, the process itself is a massive learning experience.

Colin Watson: Free software activity in February 2026

My Debian contributions this month were all sponsored by Freexian. You can also support my work directly via Liberapay or GitHub Sponsors. OpenSSH I released bookworm and trixie fixes for CVE-2025-61984 and CVE-2025-61985, both allowing code execution via ProxyCommand in some cases. The trixie update also included a fix for openssh-server: refuses further connections after having handled PerSourceMaxStartups connections. bugs.debian.org administration Gioele Barabucci reported that some messages to the bug tracking system generated by the bts command were being discarded. While the regression here was on the client side, I found and fixed a typo in our SpamAssassin configuration that was failing to apply a bonus specifically to forwarded commands, mitigating the problem. Python packaging New upstream versions: Porting away from the deprecated (and now removed from upstream setuptools) pkg_resources: Other build/test failures: Other bugs: I added a manual page symlink to make the documentation for Testsuite: autopkgtest-pkg-pybuild easier to find. I backported python-pytest-unmagic, a more recent version of pytest-django, and a more recent version of django-cte to trixie for use in Debusine. Rust packaging I also packaged rust-garde and rust-garde-derive, which are part of the pile of work needed to get the ruff packaging back in shape (which is a project I haven t decided if I m going to take on for real, but I thought I d at least chip away at a bit of it). Other bits and pieces Code reviews

6 March 2026

Russell Coker: Links March 2026

Krebs has an interesting article about the Kimwolf botnet which uses residential proxy relay services [1]. cory Doctorow wrote an insightful blog post about code being a liability not an asset [2]. Aigars Mahinovs wrote an interesting review of the BMW i4 M50 xDrive and the BMW i5 eDrive40 which seem like very impressive vehicles [3]. I was wondering what BMW would do now that all the features they had in the 90s have been copied by cheaper brands but they have managed to do new and exciting things. Arstechnica has an interesting article about the recently declassified JUMPSEAT surveillance satellites that ran from 1971 to 1987 [4]. Cory Doctorow wrote an interesting blog post about OgApp which briefly allowed viewing Instagram without ads and the issues of US corporations misusing EU copyright law [5]. ZDNet has an interesting article about new planned developments for the web of trust for Linux kernel coders (and others) [6]. Last month India had a 300 million person strike, we need more large scale strikes against governments that support predatory corporations [7]. Techdirt has an insightful article on the ways the fascism is bad for innovation and a market based economy [8]. The Acknowledgements section from the Scheme Shell (scsh) reference is epic [9]. Vice has an insightful article on research about do your own research and how simple Google searches tend to reinforce conspiracy theories [10]. A problem with Google is that it s most effective if you already know the answer. Issendai has an interesting and insightful series of blog posts about estranged parents forums which seems a lot like Incel forums in the way they promote abuse [11]. Caitlin Johnstone wrote an interesting article about how the empire caused the rebirth of a real counterculture by their attempts to coerce support for Israeli atrocities [12]. Radley Balko wrote an interesting article about the courage to be decent concerning the Trump regime s attempts to scare lawyers into cooperating with them [13]. Terry Tan wrote a useful resource on the API for Google search, this could be good for shell scripts and for 3rd party programs that launch a search [14]. The Proof has an interesting article about eating oysters and mussels as a vegan [15]. All Things Linguistic has an interesting and amusing post about Yoda s syntax in non-English languages [16].

5 March 2026

Ian Jackson: Adopting tag2upload and modernising your Debian packaging

Introduction tag2upload allows authorised Debian contributors to upload to Debian simply by pushing a signed git tag to Debian s gitlab instance, Salsa. We have recently announced that tag2upload is, in our opinion, now very stable, and ready for general use by all Debian uploaders. tag2upload, as part of Debian s git transition programme, is very flexible - it needs to support a large variety of maintainer practices. And it s relatively unopinionated, wherever that s possible. But, during the open beta, various contributors emailed us asking for Debian packaging git workflow advice and recommendations. This post is an attempt to give some more opinionated answers, and guide you through modernising your workflow. (This article is aimed squarely at Debian contributors. Much of it will make little sense to Debian outsiders.) Why Ease of development git offers a far superior development experience to patches and tarballs. Moving tasks from a tarballs and patches representation to a normal, git-first, representation, makes everything simpler. dgit and tag2upload do automatically many things that have to be done manually, or with separate commands, in dput-based upload workflows. They will also save you from a variety of common mistakes. For example, you cannot accidentally overwrite an NMU, with tag2upload or dgit. These many safety catches mean that our software sometimes complains about things, or needs confirmation, when more primitive tooling just goes ahead. We think this is the right tradeoff: it s part of the great care we take to avoid our software making messes. Software that has your back is very liberating for the user. tag2upload makes it possible to upload with very small amounts of data transfer, which is great in slow or unreliable network environments. The other week I did a git-debpush over mobile data while on a train in Switzerland; it completed in seconds. See the Day-to-day work section below to see how simple your life could be. Don t fear a learning burden; instead, start forgetting all that nonsense Most Debian contributors have spent months or years learning how to work with Debian s tooling. You may reasonably fear that our software is yet more bizarre, janky, and mistake-prone stuff to learn. We promise (and our users tell us) that s not how it is. We have spent a lot of effort on providing a good user experience. Our new git-first tooling, especially dgit and tag2upload, is much simpler to use than source-package-based tooling, despite being more capable. The idiosyncrasies and bugs of source packages, and of the legacy archive, have been relentlessly worked around and papered over by our thousands of lines of thoroughly-tested defensive code. You too can forget all those confusing details, like our users have! After using our systems for a while you won t look back. And, you shouldn t fear trying it out. dgit and tag2upload are unlikely to make a mess. If something is wrong (or even doubtful), they will typically detect it, and stop. This does mean that starting to use tag2upload or dgit can involve resolving anomalies that previous tooling ignored, or passing additional options to reassure the system about your intentions. So admittedly it isn t always trivial to get your first push to succeed. Properly publishing the source code One of Debian s foundational principles is that we publish the source code. Nowadays, the vast majority of us, and of our upstreams, are using git. We are doing this because git makes our life so much easier. But, without tag2upload or dgit, we aren t properly publishing our work! Yes, we typically put our git branch on Salsa, and point Vcs-Git at it. However:
  • The format of git branches on Salsa is not standardised. They might be patches-unapplied, patches-applied, bare debian/, or something even stranger.
  • There is no guarantee that the DEP-14 debian/1.2.3-7 tag on salsa corresponds precisely to what was actually uploaded. dput-based tooling (such as gbp buildpackage) doesn t cross-check the .dsc against git.
  • There is no guarantee that the presence of a DEP-14 tag even means that that version of package is in the archive.
This means that the git repositories on Salsa cannot be used by anyone who needs things that are systematic and always correct. They are OK for expert humans, but they are awkward (even hazardous) for Debian novices, and you cannot use them in automation. The real test is: could you use Vcs-Git and Salsa to build a Debian derivative? You could not. tag2upload and dgit do solve this problem. When you upload, they:
  1. Make a canonical-form (patches-applied) derivative of your git branch;
  2. Ensure that there is a well-defined correspondence between the git tree and the source package;
  3. Publish both the DEP-14 tag and a canonical-form archive/debian/1.2.3-7 tag to a single central git depository, *.dgit.debian.org;
  4. Record the git information in the Dgit field in .dsc so that clients can tell (using the ftpmaster API) that this was a git-based upload, what the corresponding git objects are, and where to find them.
This dependably conveys your git history to users and downstreams, in a standard, systematic and discoverable way. tag2upload and dgit are the only system which achieves this. (The client is dgit clone, as advertised in e.g. dgit-user(7). For dput-based uploads, it falls back to importing the source package.) Adopting tag2upload - the minimal change tag2upload is a substantial incremental improvement to many existing workflows. git-debpush is a drop-in replacement for building, signing, and uploading the source package. So, you can just adopt it without completely overhauling your packaging practices. You and your co-maintainers can even mix-and-match tag2upload, dgit, and traditional approaches, for the same package. Start with the wiki page and git-debpush(1) (ideally from forky aka testing). You don t need to do any of the other things recommended in this article. Overhauling your workflow, using advanced git-first tooling The rest of this article is a guide to adopting the best and most advanced git-based tooling for Debian packaging. Assumptions
  • Your current approach uses the patches-unapplied git branch format used with gbp pq and/or quilt, and often used with git-buildpackage. You previously used gbp import-orig.
  • You are fluent with git, and know how to use Merge Requests on gitlab (Salsa). You have your origin remote set to Salsa.
  • Your main Debian branch name on Salsa is master. Personally I think we should use main but changing your main branch name is outside the scope of this article.
  • You have enough familiarity with Debian packaging including concepts like source and binary packages, and NEW review.
  • Your co-maintainers are also adopting the new approach.
tag2upload and dgit (and git-debrebase) are flexible tools and can help with many other scenarios too, and you can often mix-and-match different approaches. But, explaining every possibility would make this post far too confusing. Topics and tooling This article will guide you in adopting:
  • tag2upload
  • Patches-applied git branch for your packaging
  • Either plain git merge or git-debrebase
  • dgit when a with-binaries uploaded is needed (NEW)
  • git-based sponsorship
  • Salsa (gitlab), including Debian Salsa CI
Choosing the git branch format In Debian we need to be able to modify the upstream-provided source code. Those modifications are the Debian delta. We need to somehow represent it in git. We recommend storing the delta as git commits to those upstream files, by picking one of the following two approaches.
rationale Much traditional Debian tooling like quilt and gbp pq uses the patches-unapplied branch format, which stores the delta as patch files in debian/patches/, in a git tree full of unmodified upstream files. This is clumsy to work with, and can even be an alarming beartrap for Debian outsiders.
git merge Option 1: simply use git, directly, including git merge. Just make changes directly to upstream files on your Debian branch, when necessary. Use plain git merge when merging from upstream. This is appropriate if your package has no or very few upstream changes. It is a good approach if the Debian maintainers and upstream maintainers work very closely, so that any needed changes for Debian are upstreamed quickly, and any desired behavioural differences can be arranged by configuration controlled from within debian/. This is the approach documented more fully in our workflow tutorial dgit-maint-merge(7).
git-debrebase Option 2: Adopt git-debrebase. git-debrebase helps maintain your delta as linear series of commits (very like a topic branch in git terminology). The delta can be reorganised, edited, and rebased. git-debrebase is designed to help you carry a significant and complicated delta series. The older versions of the Debian delta are preserved in the history. git-debrebase makes extra merges to make a fast-forwarding history out of the successive versions of the delta queue branch. This is the approach documented more fully in our workflow tutorial dgit-maint-debrebase(7). Examples of complex packages using this approach include src:xen and src:sbcl.
Determine upstream git and stop using upstream tarballs We recommend using upstream git, only and directly. You should ignore upstream tarballs completely.
rationale Many maintainers have been importing upstream tarballs into git, for example by using gbp import-orig. But in reality the upstream tarball is an intermediate build product, not (just) source code. Using tarballs rather than git exposes us to additional supply chain attacks; indeed, the key activation part of the xz backdoor attack was hidden only in the tarball! git offers better traceability than so-called pristine upstream tarballs. (The word pristine is even a joke by the author of pristine-tar!)
First, establish which upstream git tag corresponds to the version currently in Debian. From the sake of readability, I m going to pretend that upstream version is 1.2.3, and that upstream tagged it v1.2.3. Edit debian/watch to contain something like this:
version=4
opts="mode=git" https://codeberg.org/team/package refs/tags/v(\d\S*)
You may need to adjust the regexp, depending on your upstream s tag name convention. If debian/watch had a files-excluded, you ll need to make a filtered version of upstream git.
git-debrebase From now on we ll generate our own .orig tarballs directly from git.
rationale We need some upstream tarball for the 3.0 (quilt) source format to work with. It needs to correspond to the git commit we re using as our upstream. We don t need or want to use a tarball from upstream for this. The .orig is just needed so a nice legacy Debian source package (.dsc) can be generated.
Probably, the current .orig in the Debian archive, is an upstream tarball, which may be different to the output of git-archive and possibly even have different contents to what s in git. The legacy archive has trouble with differing .origs for the same upstream version . So we must until the next upstream release change our idea of the upstream version number. We re going to add +git to Debian s idea of the upstream version. Manually make a tag with that name:
git tag -m "Compatibility tag for orig transition" v1.2.3+git v1.2.3~0
git push origin v1.2.3+git
If you are doing the packaging overhaul at the same time as a new upstream version, you can skip this part.
Convert the git branch
git merge Prepare a new branch on top of upstream git, containing what we want:
git branch -f old-master         # make a note of the old git representation
git reset --hard v1.2.3          # go back to the real upstream git tag
git checkout old-master :debian  # take debian/* from old-master
git commit -m "Re-import Debian packaging on top of upstream git"
git merge --allow-unrelated-histories -s ours -m "Make fast forward from tarball-based history" old-master
git branch -d old-master         # it's incorporated in our history now
If there are any patches, manually apply them to your main branch with git am, and delete the patch files (git rm -r debian/patches, and commit). (If you ve chosen this workflow, there should be hardly any patches,)
rationale These are some pretty nasty git runes, indeed. They re needed because we want to restart our Debian packaging on top of a possibly quite different notion of what the upstream is.
git-debrebase Convert the branch to git-debrebase format and rebase onto the upstream git:
git-debrebase -fdiverged convert-from-gbp upstream/1.2.3
git-debrebase -fdiverged -fupstream-not-ff new-upstream 1.2.3+git
If you had patches which patched generated files which are present only in the upstream tarball, and not in upstream git, you will encounter rebase conflicts. You can drop hunks editing those files, since those files are no longer going to be part of your view of the upstream source code at all.
rationale The force option -fupstream-not-ff will be needed this one time because your existing Debian packaging history is (probably) not based directly on the upstream history. -fdiverged may be needed because git-debrebase might spot that your branch is not based on dgit-ish git history.
Manually make your history fast forward from the git import of your previous upload.
dgit fetch
git show dgit/dgit/sid:debian/changelog
# check that you have the same version number
git merge -s ours --allow-unrelated-histories -m 'Declare fast forward from pre-git-based history' dgit/dgit/sid
Change the source format Delete any existing debian/source/options and/or debian/source/local-options.
git merge Change debian/source/format to 1.0. Add debian/source/options containing -sn.
rationale We are using the 1.0 native source format. This is the simplest possible source format - just a tarball. We would prefer 3.0 (native) , which has some advantages, but dpkg-source between 2013 (wheezy) and 2025 (trixie) inclusive unjustifiably rejects this configuration. You may receive bug reports from over-zealous folks complaining about the use of the 1.0 source format. You should close such reports, with a reference to this article and to #1106402.
git-debrebase Ensure that debian/source/format contains 3.0 (quilt).
Now you are ready to do a local test build. Sort out the documentation and metadata Edit README.source to at least mention dgit-maint-merge(7) or dgit-maint-debrebase(7), and to tell people not to try to edit or create anything in debian/patches/. Consider saying that uploads should be done via dgit or tag2upload. Check that your Vcs-Git is correct in debian/control. Consider deleting or pruning debian/gbp.conf, since it isn t used by dgit, tag2upload, or git-debrebase.
git merge Add a note to debian/changelog about the git packaging change.
git-debrebase git-debrebase new-upstream will have added a new upstream version stanza to debian/changelog. Edit that so that it instead describes the packaging change. (Don t remove the +git from the upstream version number there!)
Configure Salsa Merge Requests
git-debrebase In Settings / Merge requests , change Squash commits when merging to Do not allow .
rationale Squashing could destroy your carefully-curated delta queue. It would also disrupt git-debrebase s git branch structure.
Set up Salsa CI, and use it to block merges of bad changes Caveat - the tradeoff gitlab is a giant pile of enterprise crap. It is full of startling bugs, many of which reveal a fundamentally broken design. It is only barely Free Software in practice for Debian (in the sense that we are very reluctant to try to modify it). The constant-churn development approach and open-core business model are serious problems. It s very slow (and resource-intensive). It can be depressingly unreliable. That Salsa works as well as it does is a testament to the dedication of the Debian Salsa team (and those who support them, including DSA). However, I have found that despite these problems, Salsa CI is well worth the trouble. Yes, there are frustrating days when work is blocked because gitlab CI is broken and/or one has to keep mashing Retry . But, the upside is no longer having to remember to run tests, track which of my multiple dev branches tests have passed on, and so on. Automatic tests on Merge Requests are a great way of reducing maintainer review burden for external contributions, and helping uphold quality norms within a team. They re a great boon for the lazy solo programmer. The bottom line is that I absolutely love it when the computer thoroughly checks my work. This is tremendously freeing, precisely at the point when one most needs it deep in the code. If the price is to occasionally be blocked by a confused (or broken) computer, so be it. Setup procedure Create debian/salsa-ci.yml containing
include:
  - https://salsa.debian.org/salsa-ci-team/pipeline/raw/master/recipes/debian.yml
In your Salsa repository, under Settings / CI/CD , expand General Pipelines and set CI/CD configuration file to debian/salsa-ci.yml.
rationale Your project may have an upstream CI config in .gitlab-ci.yml. But you probably want to run the Debian Salsa CI jobs. You can add various extra configuration to debian/salsa-ci.yml to customise it. Consult the Salsa CI docs.
git-debrebase Add to debian/salsa-ci.yml:
.git-debrebase-prepare: &git-debrebase-prepare
  # install the tools we'll need
  - apt-get update
  - apt-get --yes install git-debrebase git-debpush
  # git-debrebase needs git user setup
  - git config user.email "salsa-ci@invalid.invalid"
  - git config user.name "salsa-ci"
  # run git-debrebase make-patches
  # https://salsa.debian.org/salsa-ci-team/pipeline/-/issues/371
  - git-debrebase --force
  - git-debrebase --noop-ok make-patches
  # make an orig tarball using the upstream tag, not a gbp upstream/ tag
  # https://salsa.debian.org/salsa-ci-team/pipeline/-/issues/541
  - git-deborig
.build-definition: &build-definition
  extends: .build-definition-common
  before_script: *git-debrebase-prepare
build source:
  extends: .build-source-only
  before_script: *git-debrebase-prepare
variables:
  # disable shallow cloning of git repository. This is needed for git-debrebase
  GIT_DEPTH: 0
rationale Unfortunately the Salsa CI pipeline currently lacks proper support for git-debrebase (salsa-ci#371) and has trouble directly using upstream git for orig tarballs (#salsa-ci#541). These runes were based on those in the Xen package. You should subscribe to the tickets #371 and #541 so that you can replace the clone-and-hack when proper support is merged.
Push this to salsa and make the CI pass. If you configured the pipeline filename after your last push, you will need to explicitly start the first CI run. That s in Pipelines : press New pipeline in the top right. The defaults will very probably be correct. Block untested pushes, preventing regressions In your project on Salsa, go into Settings / Repository . In the section Branch rules , use Add branch rule . Select the branch master. Set Allowed to merge to Maintainers . Set Allowed to push and merge to No one . Leave Allow force push disabled. This means that the only way to land anything on your mainline is via a Merge Request. When you make a Merge Request, gitlab will offer Set to auto-merge . Use that. gitlab won t normally merge an MR unless CI passes, although you can override this on a per-MR basis if you need to. (Sometimes, immediately after creating a merge request in gitlab, you will see a plain Merge button. This is a bug. Don t press that. Reload the page so that Set to auto-merge appears.) autopkgtests Ideally, your package would have meaningful autopkgtests (DEP-8 tests) This makes Salsa CI more useful for you, and also helps detect and defend you against regressions in your dependencies. The Debian CI docs are a good starting point. In-depth discussion of writing autopkgtests is beyond the scope of this article. Day-to-day work With this capable tooling, most tasks are much easier. Making changes to the package Make all changes via a Salsa Merge Request. So start by making a branch that will become the MR branch. On your MR branch you can freely edit every file. This includes upstream files, and files in debian/. For example, you can:
  • Make changes with your editor and commit them.
  • git cherry-pick an upstream commit.
  • git am a patch from a mailing list or from the Debian Bug System.
  • git revert an earlier commit, even an upstream one.
When you have a working state of things, tidy up your git branch:
git merge Use git-rebase to squash/edit/combine/reorder commits.
git-debrebase Use git-debrebase -i to squash/edit/combine/reorder commits. When you are happy, run git-debrebase conclude. Do not edit debian/patches/. With git-debrebase, this is purely an output. Edit the upstream files directly instead. To reorganise/maintain the patch queue, use git-debrebase -i to edit the actual commits.
Push the MR branch (topic branch) to Salsa and make a Merge Request. Set the MR to auto-merge when all checks pass . (Or, depending on your team policy, you could ask for an MR Review of course.) If CI fails, fix up the MR branch, squash/tidy it again, force push the MR branch, and once again set it to auto-merge. Test build An informal test build can be done like this:
apt-get build-dep .
dpkg-buildpackage -uc -b
Ideally this will leave git status clean, with no modified or un-ignored untracked files. If it shows untracked files, add them to .gitignore or debian/.gitignore as applicable. If it dirties the tree, consider trying to make it stop doing that. The easiest way is probably to build out-of-tree, if supported upstream. If this is too difficult, you can leave the messy build arrangements as they are, but you ll need to be disciplined about always committing, using git clean and git reset, and so on. For formal binaries builds, including for testing, use dgit sbuild as described below for uploading to NEW. Uploading to Debian Start an MR branch for the administrative changes for the release. Document all the changes you re going to release, in the debian/changelog.
git merge gbp dch can help write the changelog for you:
dgit fetch sid
gbp dch --ignore-branch --since=dgit/dgit/sid --git-log=^upstream/main
rationale --ignore-branch is needed because gbp dch wrongly thinks you ought to be running this on master, but of course you re running it on your MR branch. The --git-log=^upstream/main excludes all upstream commits from the listing used to generate the changelog. (I m assuming you have an upstream remote and that you re basing your work on their main branch.) If there was a new upstream version, you ll usually want to write a single line about that, and perhaps summarise anything really important.
(For the first upload after switching to using tag2upload or dgit you need --since=debian/1.2.3-1, where 1.2.3-1 is your previous DEP-14 tag, because dgit/dgit/sid will be a dsc import, not your actual history.)
Change UNRELEASED to the target suite, and finalise the changelog. (Note that dch will insist that you at least save the file in your editor.)
dch -r
git commit -m 'Finalise for upload' debian/changelog
Make an MR of these administrative changes, and merge it. (Either set it to auto-merge and wait for CI, or if you re in a hurry double-check that it really is just a changelog update so that you can be confident about telling Salsa to Merge unverified changes .) Now you can perform the actual upload:
git checkout master
git pull --ff-only # bring the gitlab-made MR merge commit into your local tree
git merge
git-debpush
git-debrebase
git-debpush --quilt=linear
--quilt=linear is needed only the first time, but it is very important that first time, to tell the system the correct git branch layout.
Uploading a NEW package to Debian If your package is NEW (completely new source, or has new binary packages) you can t do a source-only upload. You have to build the source and binary packages locally, and upload those build artifacts. Happily, given the same git branch you d tag for tag2upload, and assuming you have sbuild installed and a suitable chroot, dgit can help take care of the build and upload for you: Prepare the changelog update and merge it, as above. Then:
git-debrebase Create the orig tarball and launder the git-derebase branch:
git-deborig
git-debrebase quick
rationale Source package format 3.0 (quilt), which is what I m recommending here for use with git-debrebase, needs an orig tarball; it would also be needed for 1.0-with-diff.
Build the source and binary packages, locally:
dgit sbuild
dgit push-built
rationale You don t have to use dgit sbuild, but it is usually convenient to do so, because unlike sbuild, dgit understands git. Also it works around a gitignore-related defect in dpkg-source.
New upstream version Find the new upstream version number and corresponding tag. (Let s suppose it s 1.2.4.) Check the provenance:
git verify-tag v1.2.4
rationale Not all upstreams sign their git tags, sadly. Sometimes encouraging them to do so can help. You may need to use some other method(s) to check that you have the right git commit for the release.
git merge Simply merge the new upstream version and update the changelog:
git merge v1.2.4
dch -v1.2.4-1 'New upstream release.'
git-debrebase Rebase your delta queue onto the new upstream version:
git debrebase mew-upstream 1.2.4
If there are conflicts between your Debian delta for 1.2.3, and the upstream changes in 1.2.4, this is when you need to resolve them, as part of git merge or git (deb)rebase. After you ve completed the merge, test your package and make any further needed changes. When you have it working in a local branch, make a Merge Request, as above. Sponsorship git-based sponsorship is super easy! The sponsee can maintain their git branch on Salsa, and do all normal maintenance via gitlab operations. When the time comes to upload, the sponsee notifies the sponsor that it s time. The sponsor fetches and checks out the git branch from Salsa, does their checks, as they judge appropriate, and when satisfied runs git-debpush. As part of the sponsor s checks, they might want to see all changes since the last upload to Debian:
dgit fetch sid
git diff dgit/dgit/sid..HEAD
Or to see the Debian delta of the proposed upload:
git verify-tag v1.2.3
git diff v1.2.3..HEAD ':!debian'
git-debrebase Or to show all the delta as a series of commits:
git log -p v1.2.3..HEAD ':!debian'
Don t look at debian/patches/. It can be absent or out of date.
Incorporating an NMU Fetch the NMU into your local git, and see what it contains:
dgit fetch sid
git diff master...dgit/dgit/sid
If the NMUer used dgit, then git log dgit/dgit/sid will show you the commits they made. Normally the best thing to do is to simply merge the NMU, and then do any reverts or rework in followup commits:
git merge dgit/dgit/sid
git-debrebase You should git-debrebase quick at this stage, to check that the merge went OK and the package still has a lineariseable delta queue.
Then make any followup changes that seem appropriate. Supposing your previous maintainer upload was 1.2.3-7, you can go back and see the NMU diff again with:
git diff debian/1.2.3-7...dgit/dgit/sid
git-debrebase The actual changes made to upstream files will always show up as diff hunks to those files. diff commands will often also show you changes to debian/patches/. Normally it s best to filter them out with git diff ... ':!debian/patches' If you d prefer to read the changes to the delta queue as an interdiff (diff of diffs), you can do something like
git checkout debian/1.2.3-7
git-debrebase --force make-patches
git diff HEAD...dgit/dgit/sid -- :debian/patches
to diff against a version with debian/patches/ up to date. (The NMU, in dgit/dgit/sid, will necessarily have the patches already up to date.)
DFSG filtering (handling non-free files) Some upstreams ship non-free files of one kind of another. Often these are just in the tarballs, in which case basing your work on upstream git avoids the problem. But if the files are in upstream s git trees, you need to filter them out. This advice is not for (legally or otherwise) dangerous files. If your package contains files that may be illegal, or hazardous, you need much more serious measures. In this case, even pushing the upstream git history to any Debian service, including Salsa, must be avoided. If you suspect this situation you should seek advice, privately and as soon as possible, from dgit-owner@d.o and/or the DFSG team. Thankfully, legally dangerous files are very rare in upstream git repositories, for obvious reasons. Our approach is to make a filtered git branch, based on the upstream history, with the troublesome files removed. We then treat that as the upstream for all of the rest of our work.
rationale Yes, this will end up including the non-free files in the git history, on official Debian servers. That s OK. What s forbidden is non-free material in the Debianised git tree, or in the source packages.
Initial filtering
git checkout -b upstream-dfsg v1.2.3
git rm nonfree.exe
git commit -m "upstream version 1.2.3 DFSG-cleaned"
git tag -s -m "upstream version 1.2.3 DFSG-cleaned" v1.2.3+ds1
git push origin upstream-dfsg
And now, use 1.2.3+ds1, and the filtered branch upstream-dfsg, as the upstream version, instead of 1.2.3 and upstream/main. Follow the steps for Convert the git branch or New upstream version, as applicable, adding +ds1 into debian/changelog. If you missed something and need to filter out more a nonfree files, re-use the same upstream-dfsg branch and bump the ds version, eg v1.2.3+ds2. Subsequent upstream releases
git checkout upstream-dfsg
git merge v1.2.4
git rm additional-nonfree.exe # if any
git commit -m "upstream version 1.2.4 DFSG-cleaned"
git tag -s -m "upstream version 1.2.4 DFSG-cleaned" v1.2.4+ds1
git push origin upstream-dfsg
Removing files by pattern If the files you need to remove keep changing, you could automate things with a small shell script debian/rm-nonfree containing appropriate git rm commands. If you use git rm -f it will succeed even if the git merge from real upstream has conflicts due to changes to non-free files.
rationale Ideally uscan, which has a way of representing DFSG filtering patterns in debian/watch, would be able to do this, but sadly the relevant functionality is entangled with uscan s tarball generation.
Common issues
  • Tarball contents: If you are switching from upstream tarballs to upstream git, you may find that the git tree is significantly different. It may be missing files that your current build system relies on. If so, you definitely want to be using git, not the tarball. Those extra files in the tarball are intermediate built products, but in Debian we should be building from the real source! Fixing this may involve some work, though.
  • gitattributes: For Reasons the dgit and tag2upload system disregards and disables the use of .gitattributes to modify files as they are checked out. Normally this doesn t cause a problem so long as any orig tarballs are generated the same way (as they will be by tag2upload or git-deborig). But if the package or build system relies on them, you may need to institute some workarounds, or, replicate the effect of the gitattributes as commits in git.
  • git submodules: git submodules are terrible and should never ever be used. But not everyone has got the message, so your upstream may be using them. If you re lucky, the code in the submodule isn t used in which case you can git rm the submodule.
Further reading I ve tried to cover the most common situations. But software is complicated and there are many exceptions that this article can t cover without becoming much harder to read. You may want to look at:
  • dgit workflow manpages: As part of the git transition project, we have written workflow manpages, which are more comprehensive than this article. They re centered around use of dgit, but also discuss tag2upload where applicable. These cover a much wider range of possibilities, including (for example) choosing different source package formats, how to handle upstreams that publish only tarballs, etc. They are correspondingly much less opinionated. Look in dgit-maint-merge(7) and dgit-maint-debrebase(7). There is also dgit-maint-gbp(7) for those who want to keep using gbp pq and/or quilt with a patches-unapplied branch.
  • NMUs are very easy with dgit. (tag2upload is usually less suitable than dgit, for an NMU.) You can work with any package, in git, in a completely uniform way, regardless of maintainer git workflow, See dgit-nmu-simple(7).
  • Native packages (meaning packages maintained wholly within Debian) are much simpler. See dgit-maint-native(7).
  • tag2upload documentation: The tag2upload wiki page is a good starting point. There s the git-debpush(1) manpage of course.
  • dgit reference documentation: There is a comprehensive command-line manual in dgit(1). Description of the dgit data model and Principles of Operation is in dgit(7); including coverage of out-of-course situations. dgit is a complex and powerful program so this reference material can be overwhelming. So, we recommend starting with a guide like this one, or the dgit- (7) workflow tutorials.
  • Design and implementation documentation for tag2upload is linked to from the wiki.
  • Debian s git transition blog post from December. tag2upload and dgit are part of the git transition project, and aim to support a very wide variety of git workflows. tag2upload and dgit work well with existing git tooling, including git-buildpackage-based approaches. git-debrebase is conceptually separate from, and functionally independent of, tag2upload and dgit. It s a git workflow and delta management tool, competing with gbp pq, manual use of quilt, git-dpm and so on.
git-debrebase
  • git-debrebase reference documentation: Of course there s a comprehensive command-line manual in git-debrebase(1). git-debrebase is quick and easy to use, but it has a complex data model and sophisticated algorithms. This is documented in git-debrebase(5).


Edited 2026-03-05 18:48 UTC to add a missing --noop-ok to the Salsa CI runes. Thanks to Charlemagne Lasse for the report. Apologies if this causes Debian Planet to re-post this article as if it were new.


comment count unavailable comments

Dirk Eddelbuettel: RcppGSL 0.3.14 on CRAN: Maintenance

A new release 0.3.14 of RcppGSL is now on CRAN. The RcppGSL package provides an interface from R to the GNU GSL by relying on the Rcpp package. It has already been uploaded to Debian, and is also already available as a binary via r2u. This release, the first in over three years, contains mostly maintenance changes. We polished the fastLm example implementation a little more, updated continunous integration as one does over such a long period, adopted the Authors@R convention, switched the (pre-made) pdf vignette to a new driver now provided by Rcpp, updated vignette references and URLs, and updated one call to Rf_error to aid in a Rcpp transition towards using only Rcpp::stop which unwinds error conditions better. (Technically this was a false positive on Rf_error but on the margin worth tickling this release after all this time.) The NEWS entry follows:

Changes in version 0.3.14 (2026-03-05)
  • Updated some internals of fastLm example, and regenerated RcppExports.* files
  • Several updates for continuous integration
  • Switched to using Authors@R
  • Replace ::Rf_error with (Rf_error) in old example to aid Rcpp transition to Rcpp::stop (or this pass-through)
  • Vignette now uses the Rcpp::asis builder for pre-made pdfs
  • Vignette references have been updated, URLs prefer https and DOIs

Thanks to my CRANberries, there is also a diffstat report for this release. More information is on the RcppGSL page. Questions, comments etc should go to the issue tickets at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

Vincent Bernat: Automatic Prometheus metrics discovery with Docker labels

Akvorado, a network flow collector, relies on Traefik, a reverse HTTP proxy, to expose HTTP endpoints for its Docker Compose services. Docker labels attached to each service define the routing rules. Traefik picks them up automatically when a container starts. Instead of maintaining a static configuration file to collect Prometheus metrics, we apply the same approach with Grafana Alloy.

Traefik & Docker Traefik listens for events on the Docker socket. Each service advertises its configuration through labels. For example, here is the Loki service in Akvorado:
services:
  loki:
    #  
    expose:
      - 3100/tcp
    labels:
      - traefik.enable=true
      - traefik.http.routers.loki.rule=PathPrefix( /loki )
Once the container is healthy, Traefik creates a router forwarding requests matching /loki to its first exposed port. Colocating Traefik configuration with the service definition is attractive. How do we achieve the same for Prometheus metrics?

Metrics discovery with Alloy Grafana Alloy, a metrics collector that scrapes Prometheus endpoints, includes a discovery.docker component. Just like Traefik, it connects to the Docker socket.1 With a few relabeling rules, we teach it to use Docker labels to locate and scrape metrics. We define three labels on each service:
  • metrics.enable set to true enables metrics collection,
  • metrics.port specifies the port exposing the Prometheus endpoint, and
  • metrics.path specifies the path to the metrics endpoint.
If a service exposes more than one port, metrics.port is mandatory. Otherwise, it defaults to the only exposed port. The default value for metrics.path is /metrics. The Loki service from earlier becomes:
services:
  loki:
    #  
    expose:
      - 3100/tcp
    labels:
      - traefik.enable=true
      - traefik.http.routers.loki.rule=PathPrefix( /loki )
      - metrics.enable=true
      - metrics.path=/loki/metrics
Alloy s configuration is split into four parts:
  1. discover containers through the Docker socket,
  2. filter and relabel targets using Docker labels,
  3. scrape the matching endpoints, and
  4. forward the metrics to Prometheus.

Discovering Docker containers The first building block discovers running containers:
discovery.docker "docker"  
  host             = "unix:///var/run/docker.sock"
  refresh_interval = "30s"
  filter  
    name   = "label"
    values = ["com.docker.compose.project=akvorado"]
   
 
This connects to the Docker socket and lists containers every 30 seconds.2 The filter block restricts discovery to containers belonging to the akvorado project, avoiding interference with unrelated containers on the same host. For each discovered container, Alloy produces a target with labels such as __meta_docker_container_label_metrics_port for the metrics.port Docker label.

Relabeling targets The relabeling step filters and transforms raw targets from Docker discovery into scrape targets. The first stage keeps only targets with metrics.enable set to true:
discovery.relabel "prometheus"  
  targets = discovery.docker.docker.targets
  // Keep only targets with metrics.enable=true
  rule  
    source_labels = ["__meta_docker_container_label_metrics_enable"]
    regex         =  true 
    action        = "keep"
   
  //  
 
The second stage overrides the discovered port when the service defines metrics.port:
// When metrics.port is set, override __address__.
rule  
  source_labels = ["__address__", "__meta_docker_container_label_metrics_port"]
  regex         =  (.+):\d+;(.+) 
  target_label  = "__address__"
  replacement   = "$1:$2"
 
Next, we handle containers in host network mode. When __meta_docker_network_name equals host, Alloy rewrites the address to host.docker.internal instead of localhost:3
// When host networking, override __address__ to host.docker.internal.
rule  
  source_labels = ["__meta_docker_container_label_metrics_port", "__meta_docker_network_name"]
  regex         =  (.+);host 
  target_label  = "__address__"
  replacement   = "host.docker.internal:$1"
 
The next stage derives the job name from the service name, stripping any numbered suffix. The instance label is the address without the port:
rule  
  source_labels = ["__meta_docker_container_label_com_docker_compose_service"]
  regex         =  (.+)(?:-\d+)? 
  target_label  = "job"
 
rule  
  source_labels = ["__address__"]
  regex         =  (.+):\d+ 
  target_label  = "instance"
 
If a container defines metrics.path, Alloy uses it. Otherwise, it defaults to /metrics:
rule  
  source_labels = ["__meta_docker_container_label_metrics_path"]
  regex         =  (.+) 
  target_label  = "__metrics_path__"
 
rule  
  source_labels = ["__metrics_path__"]
  regex         = ""
  target_label  = "__metrics_path__"
  replacement   = "/metrics"
 

Scraping and forwarding With the targets properly relabeled, scraping and forwarding are straightforward:
prometheus.scrape "docker"  
  targets         = discovery.relabel.prometheus.output
  forward_to      = [prometheus.remote_write.default.receiver]
  scrape_interval = "30s"
 
prometheus.remote_write "default"  
  endpoint  
    url = "http://prometheus:9090/api/v1/write"
   
 
prometheus.scrape periodically fetches metrics from the discovered targets. prometheus.remote_write sends them to Prometheus.

Built-in exporters Some services do not expose a Prometheus endpoint. Redis and Kafka are common examples. Alloy ships built-in Prometheus exporters that query these services and expose metrics on their behalf.
prometheus.exporter.redis "docker"  
  redis_addr = "redis:6379"
 
discovery.relabel "redis"  
  targets = prometheus.exporter.redis.docker.targets
  rule  
    target_label = "job"
    replacement  = "redis"
   
 
prometheus.scrape "redis"  
  targets         = discovery.relabel.redis.output
  forward_to      = [prometheus.remote_write.default.receiver]
  scrape_interval = "30s"
 
The same pattern applies to Kafka:
prometheus.exporter.kafka "docker"  
  kafka_uris = ["kafka:9092"]
 
discovery.relabel "kafka"  
  targets = prometheus.exporter.kafka.docker.targets
  rule  
    target_label = "job"
    replacement  = "kafka"
   
 
prometheus.scrape "kafka"  
  targets         = discovery.relabel.kafka.output
  forward_to      = [prometheus.remote_write.default.receiver]
  scrape_interval = "30s"
 
Each exporter is a separate component with its own relabeling and scrape configuration. We set the job label explicitly since no Docker metadata can provide it.
With this setup, adding metrics to a new service with a Prometheus endpoint requires only a few labels in docker-compose.yml, just like adding a Traefik route. Alloy picks it up automatically. You can apply the same pattern with another discovery method, like discovery.kubernetes, discovery.scaleway, or discovery.http.

  1. Both Traefik and Alloy require access to the Docker socket, which grants root-level access to the host. A Docker socket proxy mitigates this by exposing only the read-only API endpoints needed for discovery.
  2. Unlike Traefik, which watches for events, Grafana Alloy polls the container list at regular intervals a behavior inherited from Prometheus.
  3. The Alloy service needs extra_hosts: ["host.docker.internal:host-gateway"] in its definition.

3 March 2026

Michael Ablassmeier: pbsindex - file backup index

If you take backups using the proxmox-backup-client and you wondered what backup may include a specific file, the only way to find out is to mount the backup and search for the files. For regular file backups, the Proxmox Backup Server frontend provides a pcat1 file for download, whose binary format is somewhat undocumented but actually includes a listing of the files backed up. A Proxmox backup server datastore includes the same pcat1 file as blob index (.pcat1.didx). So to actually beeing able to tell which backup contains which files, one needs to: 1) Open the .pcat1.didx file and find out required blobs, see format documentation 2) Reconstruct the .pcat1 file from the blobs 3) Parse the pcat1 file and output the directory listing. I ve implemented this in pbsindex which lets you create a central file index for your backups by scanning a complete PBS datastore. Lets say you want to have a file listing for a specific backup, use:
 pbsindex --chunk-dir /backup/.chunks/ /backup/host/vm178/2026-03-02T10:47:57Z/catalog.pcat1.didx
 didx uuid=7e4086a9-4432-4184-a21f-0aeec2b2de93 ctime=2026-03-02T10:47:57Z chunks=2 total_size=1037386
 chunk[0] start=0 end=344652 size=344652 digest=af3851419f5e74fbb4d7ca6ac3bc7c5cbbdb7c03d3cb489d57742ea717972224
 chunk[1] start=344652 end=1037386 size=692734 digest=e400b13522df02641c2d9934c3880ae78ebb397c66f9b4cf3b931d309da1a7cc
 d ./usr.pxar.didx
 d ./usr.pxar.didx/bin
 l ./usr.pxar.didx/bin/Mail
 f ./usr.pxar.didx/bin/[ size=55720 mtime=2025-06-04T15:14:05Z
 f ./usr.pxar.didx/bin/aa-enabled size=18672 mtime=2025-04-10T15:06:25Z
 f ./usr.pxar.didx/bin/aa-exec size=18672 mtime=2025-04-10T15:06:25Z
 f ./usr.pxar.didx/bin/aa-features-abi size=18664 mtime=2025-04-10T15:06:25Z
 l ./usr.pxar.didx/bin/apropos
It also lets you scan a complete datastore for all existing .pcat1.didx files and store the directory listings in a SQLite database for easier searching.

2 March 2026

Ben Hutchings: FOSS activity in February 2026

Valhalla's Things: A Pen Case (or a Few)

Posted on March 2, 2026
Tags: madeof:atoms, FreeSoftWear, craft:sewing
A pen case made of two pieces of a relatively stiff black material with a flat base and three separate channels on top, plus a flap covering everything and a band to keep the flap closed; there is visible light blue stitching all around the channels. For my birthday, I ve bought myself a fancy new expensive1 fountain pen. A two slot pen case in the same material as above, but brown: the flap is too short to cover the pens, and there isn't a band to keep it closed. Such a fancy pen, of course requires a suitable case: I couldn t use the failed prototype of a case I ve been keeping my Preppys in, so I had to get out the nice vegetable tanned leather Yeah, nope, I don t have that (yet). I got out the latex and cardboard material that is sold as a (cheaper) leather substitute, doesn t look like leather at all, but is quite nice (and easy) to work with. The project is not vegan anyway, because I used waxed linen thread, waxing it myself with a lot of very nicely smelling beeswax. a case similar to the one above, but this one only has two slots, and there is a a Faber Castell pen nested on top of the case between the two slots. Here the stitches are white, and in a coarser thread. I got the measurements2 from the less failed prototype where I keep my desktop pens, and this time I made a proper pattern I could share online, under the usual Free Culture license. A case like the one above, except that the stitches are in black, and not as regular. This one has also been scrunched up a bit for a different look, and now the band is a bit too wide. From the width of the material I could conveniently cut two cases, so that s what I did, started sewing the first one, realized that I got the order of stitching wrong, and also that if I used light blue thread instead of the black one it would look nice, and be easier to see in the pictures for the published pattern, started sewing the second one, and kept alternating between the two, depending on the availability of light for taking pictures. The open pen case, showing two pens, a blue Preppy and a gunmetal Plaisir cosily nested in the two outer slots, while the middle slot is ominously empty. One of the two took the place of my desktop one, where I had one more pen than slots, and one of the old prototypes was moved to keep my bedside pen, and the other new case was used for the new pen in my handbag, together with a Preppy, and now I have a free slot and you can see how this is going to go wrong, right? :D
  1. 16 . plus a 9 converter, and another 6 pen to get the EF nib from, since it wasn t available for the expensive pen.
  2. I have them written down somewhere. I couldn t find them. So I measured the real thing, with some approximation.

Next.

Previous.