Search Results: "ed"

6 July 2012

Marco Silva: C-d on UNIX

[...] read also says how many bytes of the file were returned, so end of file is assumed when a read says "zero bytes are being returned." [...] When a program reads from your terminal, each input line is given to the program by the kernel only when you type its newline (i.e, press RETURN). [...] [...] Now try something different: type some characters and then a *ctl*-d rather than a RETURN: $ cat -u
123
ctl-d123 cat prints the characters out immediately. *ctl*-d says, "immediately send the characters I have typed to the program that is reading from my terminal." The *ctl*-d itself is not sent to the program, unlike a newline. Now type a second ctl-d, with no other chracters: $ cat -u
123
ctl-d123ctl-d$ The shell responds with a prompt, because cat read no characters, decided that meant end of file, and stopped. ctl-d sends whatever you have typed to the program that is reading from the terminal. If you haven't typed anything, the program will therefore read no characters, and that looks like the end of the file. That is why *ctl*-d logs you out --- the shell sees no more input. Of course, *ctl*-d is usually used to signal an end-of-file but it is interesting that is has a more general function.
Brian W. Kernighan, Rob Pike. The UNIX Programming Environment. Prentice-Haskell Software Series, 1984, section 2.1, pages 44-45.

Matthew Garrett: DMI checks are a last resort

Most x86 devices export various bits of system information via SMBIOS, including the system manufacturer, model and firmware version. This makes it possible for the kernel to alter its behaviour depending on the machine it's running on, usually referred to as "DMI quirking". This is a very attractive approach to handling machine-specific bugs - unfortunately it also means that we often end up working around symptoms with no understanding of the underlying issue.

Almost all x86 hardware is tested with Windows. For the most part vendors don't ship devices that don't work - if you install a stock copy of Windows on a system, you expect it to boot successfully and reboot properly. Basic ACPI functionality should be present and correct, including processor power-saving states. Time should pass at something approximating the real rate. And since stock Windows isn't updated with large numbers of DMI quirk entries, the hardware needs to do this with an operating system that's already shipped.

Which means that if Linux doesn't provide the same level of functionality, it means we're doing something different to Windows. Sometimes this is because we're doing something fundamentally different with the hardware - the HP NX6125, for example, resets its thermal trip points if the timer is set up in a different way to Windows. In this case we've decided that the additional functionality of doing things the Linux way is worth it, and we'll just blacklist the small set of machines that are broken by it.

But other times there's no need for the difference. For years we were triggering system reboots in a different way to Windows and then adding DMI workarounds for any systems that didn't work. The problem with this approach is that it's basically impossible to guarantee that you've found the full set of broken hardware. It's very easy to add another DMI quirk, but it doesn't solve the problem for anyone who bought a machine, tried Linux and gave up when they found reboot didn't work. More recently we've added a pile of quirks for Dells - turns out that in all cases we're working around a bug in their firmware that hangs if we're using VT-d.

We typically don't merge code that fixes a specific example of a problem without at least considering whether there's a wider class of similar problems that could all be solved at once. We should take the same attitude to DMI quirks. Sometimes they're the least harmful way of handling an issue, but most of the time they're just fixing one person's itch and leaving a larger number of people to continue cursing at Linux. There should at least be a demonstration of an attempt to understand the underlying problem before just adding another quirk, and every patch that permits the removal of some DMI checks should be greeted with great cheer.

comment count unavailable comments

John Goerzen: How to listen to music?

This seems like a simple question: how do you listen to music? But in a way, I think I ve fallen behind the times. I ve enjoyed listening to digital music for years, since well before MP3 even existed (MIDI files could be comfortably downloaded over dialup; some of you may even remember MOD files). Anyhow, a few years ago, I digitized my entire CD collection, ripping it to FLAC and encoding to high-bitrate MP3 for storage on my 160GB iPod. Since, I ve purchased some music from DRM-free MP3 retailers, and even FLAC files from Magnatune, but at this point I basically say that I have enough music. I have only rarely bought anything new in the last couple of years. I have used Musicbrainz Picard to enforce consistent tagging across almost my entire collection. I am usually in front of a Linux machine. I run mt-daapd on my fileserver, so I can stream music from it to any other machine in the house. However, this has a lot of drawbacks. It is generally impossible to create or modify persistent playlists with this protocol. I can t modify metadata. I can t assign ratings. Though perhaps I don t need to. There are a lot of online services I could think of: Pandora, Spotify, Rdio, Slacker. Plus, of course, the upload your music to the cloud services such as Google and Amazon. Have people tried these? I m hesitant to use a service where I pay a monthly fee, unless I wind up owning the music in a DRM-free fashion. And I m a little nervous about the privacy implications of uploading a vast amount of music to the cloud. There are some items in my collection that I am certain are not available on any of those others, but for the most part I m willing to take what is out there if it meets my tastes. My tastes, by the way, typically run to classical and opera but also can go towards middle eastern or certain new age music (though I m very picky about that, since I don t care for most new age stuff I hear.) But these are huge categories; sometimes I d like to hear some load and noisy classical (say, Beethoven s Ninth conclusion, some Wagner, Verdi arias, etc.) And other times, something more contemplative (a Mozert concerto) or even quiet (a nice sonata) meet my mood. I have playlists for these on my iPod Classic a bit of a problem, since I don t use that device much anymore except in the car, and it takes a LOT of time to categorize things into these playlists. (An opera or a symphony could have parts in various styles and various levels of energy, for instance.) I keep a small manually-managed subset on my Android phone, which works fine. A recommendation engine for things like this could be useful, if it works well. My requirements, basically: I want something that will play the same music on my Linux machines. I want to be able to have playlists kept in sync across my machines. And I don t want a monthly fee. Ideally, the software will work on Android as well, and provide similar features there. Anything that requires Windows is a non-starter. I ve considered NFS mounts, but that s a bit annoying when the laptop disconnects from the network or when it s not at home. What are your thoughts? Ideas?

Lucas Nussbaum: Debian Maintainer Dashboard update

I ve spent some more time on Debian Maintainer Dashboard (DMD), a maintainer/team-centric dashboard relying on Ultimate Debian Database. Done:
- added tabs (jquery really rocks) see example
- added a hacking.html file that describes how to setup a development environment
- created a pad (http://debian.titanpad.com/DMD) to store ideas. TODO:
- recruit contributors ;)

Stefano Zacchiroli: DebConf BoF HOWTO - redux - redux

If you're organizing a DebConf12, and especially if you're new to it, please have a look at the DebConf BoF HOWTO. One of its main take away messages is: don't be exclusive, think of the kittens. Since last year, and to the might powers of DSA (and their kittens), we now have a more stable place for the gobby server: gobby.debian.org. I've just amended the howto to point to that, and updated the info about which gobby package to use (nowadays clarified, thanks to Phil). Enjoy your BoF-s!

Christian Perrier: Debcamp work

It's still good to be at Debcamp before DebConf and I'm not running all day long, contrary to what you might think by reading my posts. Of course, I'm always busy with "social-like" activities such as doing my best for us to have a good Cheese and Wine Party as, now that I'm trapped into it, people expect it to be better and better each year. Or to revive the traditional Assassins game. But Debian is not only about killing cheese with socks and I try to also achieve a few things while being here. As of now, I can already count a few things: The only thing I nearly haven't worked on yet is....the talk I have on Sunday and that is supposed to explain newcomers how to join the crowd of localization fanatics. Oh, and I'm still jetlagged and go to bed daily at 10pm...:-)

Paul Tagliamonte: Thinkpad t520i Palmrest

Hello, Internets! After a bit of a disappointment with Lenovo, they ve come through with flying colors, My 520i s palmrest fractured in a couple of really gnarly ways. The machine was still usable, but the fractures were really bad, looked really gnarly and creaked a bit when I put any pressure around it. After having fancyhands call them a few times, each time returning a different part number, I complained on twitter only tagging @lenovo as an afterthought which (to my surprise) got a fast response and helpful email service. Here I am, 3 days later with a replaced palmrest. Nice ending, but I hope it won t happen again :)

5 July 2012

Steve McIntyre: DebCamp

Yay, got to Nicaragua OK last night. It's the first time I've managed to get to DebCamp in quite a while, and I'm making the most of it. I've got slides ready for two of my BoF sessions next week (both ARM-related), and I'm preparing for the other four now. Why did I sign up to run six sessions? Maybe because I'm a bit silly, or maybe because they needed doing and other people hadn't registered them. Maybe both. :-) BTW: these are all BoF (Birds of a Feather) sessions, not lectures. While I have an interest in each topic, I'm neither wanting nor expecting to just talk at a room full of people - I'm wanting to provoke discussions in each case. If you're interested, please join in those discussions, either physically in Managua or virtually using the live video streaming and IRC back-channels: See you there...!

Joey Hess: git-annex-assistant milestone

I reached a nice milestone on my git-annex assistant in my first day's work at DebCamp in Nicaragua. Here's a screencast demoing it. <video controls="controls" src="http://joeyh.name/screencasts/git-annex-assistant.ogg"></video> git-annex-assistant.ogg (12 MB) By the way, the weather, food, and people here are all excellent.

Don Armstrong: Wikipedia Deletion Reviews

Many community driven projects have a problem with overgrown bureaucratic processes reducing the desire and ability of casual contributors to contribute. Debian has struggled with this problem, with efforts like Debian Maintainers and sponsorship to address it, but it's insidious and difficult to completely overcome. I recently ran into this problem again with Wikipedia, where I'm a casual contributor (I probably average an edit a month). Sometime in 2006, I uploaded an image of a Boojum tree I took in 2004 to Wikipedia to provide an image for the Boojum tree article. It wasn't a particularly awe inspiring image, as I took it while I was teaching second quarter freshmen biology on campus, and showing the students the awesome Botanical Gardens at UCR. In 2011, a Wikipedia user asked for deletion of the image because of some confusion about the copyright on the image, as Apache::Gallery's default template footer contains Apache::Gallery's copyright. I didn't notice that during the 7 day deletion review period because I rarely log into Wikipedia. A few days ago, I noticed the deletion and asked for a Deletion Review. I assumed that my explanation that the copyright notice was for Apache::Gallery would be understood (or at least believed), and that at least the original reason for the deletion would be seen to be invalid. Instead, during the process I was questioned as to whether I actually took the picture, why I used GPLv2+ for the pictures, whether I was claiming other people's images, and whether the image was actually good enough to be in Wikipedia in the first place. Hundreds of lines of text, an edit to the template in A::G, hours wasted, people still unsatisfied, and the potential contributor (myself) feeling so annoyed with the entire process that I bothered to write this blog entry. While I'm not sure what to do about Wikipedia, I've been forcibly reminded of how important enabling easy contributions are, and how alienated one can feel when one is stymied by them to the point that your (admittedly insignificant) contribution to a project no longer seems worth the effort.

Christian Perrier: DebConf running: take 3

The Grand Plan today was reaching the end of the road I already explored on Tuesday. Named "Camino Las Viudas", it's climbing in the southern hills up to a place named "Intermzeeo del Bosque", apparently a very fancy (and expensive) restaurant. The road climbs in the apparently "rich" neighbourhood of Managua, with very fancy villas as guarded by private security, as well as private condominiums, guarded as well. What's funny to see is that, at the bottom of the road, when it crosses a large avenue (Pista Suburbana Espana), you can find several auto-rickshaws, just like those you find everywhere in India. Those autos apparently drive people who happen to work in these villas (like maids, gardeners, security guards, etc.) up to the place they work. We even met two cows wandering on the road and I hesitated waiting for a rickshaw to show up and take a pic of the road (with holes), the auto and the cows, then pretending that I'm no longer in Nicaragua but back in Karnataka. I did the run along with No l K the, who I was very happy to find again, restoring our now famous Debconf Runners Duet. We even found the German Embassy! Though climb, even if we took care to start at 6 a.m. to avoid the heat (and also the traffic and noise). No l unfortunately had to give up at 1km from the top of the road, when a 15% climb suddenly "killed" his legs. I need to train him more for ups and downs..:-) I could continue the road and finally reached the restaurant....which was guarded by private security (as apparently everything in this country) who unfortunately didn't let me in despite my desperate attempts to convince him, in broken Spanish, that I just wanted to take a few pictures and not place a bomb or rob someone... So, I gota little bit disappointed and the only option was then....to run down for another 8.5 kilometers, accelerating all the way, to finish nearly at 14 km/h on Managua's sidewalks...Fun. Great run (nearly 400m positive slope in less than 17km). Next challenge : find another such nice run in the neighbourhood! Maybe Volcan Masaya tomorrow. GPS trace is here.

Michal &#268;iha&#345;: Roadmap for Weblate 1.2

As Weblate 1.1 is out, it's time to schedule next release. This release will bring some small improvements to the workflow, especially it will allow to tune it to different use cases than I originally had in mind. I've already started tagging bugs and feature requests to be fixed in 1.2 in [issue tracker][4]. Basically no big features on the list, just smaller things like notifications and locking. And of course dozen of bugfixes as the bugs will appear :-). As you can see there as well, 1.2 should be ready about month from now. This will be possible only thanks to Hackweek VIII (the wiki is still showing last one), which will happen from July 23rd to July 27th. The rest is time for testing the features and polishing the features. Anyway I might have time for some other features as well, so 1.2 might bring more things than I currently plan. But that depends on how fast I will be in implementing planned stuff.

Filed under: English Suse Weblate 0 comments Flattr this!

4 July 2012

Christian Perrier: DebConf running: take 2

Second day in managua, second day running. Today, after breakfast, so at about 7h45, I went out running with Gaudenz Steinlin. The goal was to go to laguna de Tiscapa, a lagoon of volcanic origin, in the middle of the city of Managua. The laguna is not really far away from the place we're staying at (about 2.5km). However, as usual here, the only way to get there is along the streets. Noisy streets. Often smelly streets. But that's the only way. For instance, it took Gaudenz several minutes before he could manage to cross the "Pista Beljamin Zelodon", a quite busy highway. The lagoon per se is really nice, particularly the view from the Sandino monument where you can see the Peninsula de Chiltepe. However, apart from that, it was sometimes a quite boring run because of the traffic, noise, etc. But I enjoyed again having a good run with Gaudenz. We'll do this again, but in another place..:-) GPS trace for that run is here.

Johannes Schauer: enumerating elementary circuits of a directed_graph

For my GSoC project this year I need to be able to enumerate all elementary circuits of a directed graph. My code is written in Ocaml but neither the ocamlgraph library nor graph libraries for other languages seem to implement a well tested algorithm for this task. In lack of such a well tested solution to the problem, I decided to implement a couple of different algorithms. Since it is unlikely that different algorithms yield the same wrong result, I can be certain enough that each individual algorithm is working correctly in case they all agree on a single solution. As a result I wrote a testsuite, containing an unholy mixture of Python, Ocaml, D and Java code which implements algorithms by D. B. Johnson, R. Tarjan, K. A. Hawick and H. A. James.

Algorithm by R. Tarjan The earliest algorithm that I included was published by R. Tarjan in 1973.
Enumeration of the elementary circuits of a directed graph
R. Tarjan, SIAM Journal on Computing, 2 (1973), pp. 211-216
http://dx.doi.org/10.1137/0202017
I implemented the pseudocode given in the paper using Python. The git repository can be found here: https://github.com/josch/cycles_tarjan

Algorithm by D. B. Johnson The algorithm by D. B. Johnson from 1975 improves on Tarjan's algorithm by its complexity.
Finding all the elementary circuits of a directed graph.
D. B. Johnson, SIAM Journal on Computing 4, no. 1, 77-84, 1975.
http://dx.doi.org/10.1137/0204007
In the worst case, Tarjan's algorithm has a time complexity of O(n e(c+1)) whereas Johnson's algorithm supposedly manages to stay in O((n+e)(c+1)) where n is the number of vertices, e is the number of edges and c is the number of cycles in the graph. I found two implementations of Johnson's algorithm. One was done by Frank Meyer and can be downloaded as a zip archive. The other was done by Pietro Abate and the code can be found in a blog entry which also points to a git repository. The implementation by Frank Meyer seemed to work flawlessly. I only had to add code so that a graph could be given via commandline. The git repository of my additions can be found here: https://github.com/josch/cycles_johnson_meyer Pietro Abate implemented an iterative and a functional version of Johnson's algorithm. It turned out that both yielded incorrect results as some cycles were missing from the output. A fixed version can be found in this git repository: https://github.com/josch/cycles_johnson_abate

Algorithm by K. A. Hawick and H. A. James The algorithm by K. A. Hawick and H. A. James from 2008 improves further on Johnson's algorithm and does away with its limitations.
Enumerating Circuits and Loops in Graphs with Self-Arcs and Multiple-Arcs.
Hawick and H.A. James, In Proceedings of FCS. 2008, 14-20
www.massey.ac.nz/~kahawick/cstn/013/cstn-013.pdf
In contrast to Johnson's algorithm, the algorithm by K. A. Hawick and H. A. James is able to handle graphs containing edges that start and end at the same vertex as well as multiple edges connecting the same two vertices. I do not need this functionality but add the code as additional verification. The paper posts extensive code snippets written in the D programming language. A full, working version with all pieces connected together can be found here: https://github.com/josch/cycles_hawick_james The algorithm was verified using example output given in the paper. The project README states how to reproduce it.

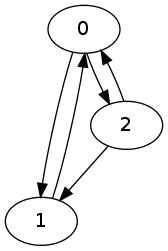
Input format All four codebases have been modified to produce executables that take the same commandline arguments which describes the graphs to investigate. The first argument is the number of vertices of the graph. Subsequent arguments are ordered pairs of comma separated vertices that make up the directed edges of the graph. Lets look at the following graph as an example: cycle example The DOT source for this graph is:
digraph G  
  0;
  1;
  2;
  0 -> 1;
  0 -> 2;
  1 -> 0;
  2 -> 0;
  2 -> 1;
   
To generate the list of elementary circuits using Tarjan's algorithm for the graph above, use:
$ python cycles.py 3 0,1 0,2 1,0 2,0 2,1
0 1
0 2
0 2 1
The commandline arguments are the exact same for the other three methods and yield the same result in the same order. If the DOT graph is in a format as simple as above, the following sed construct can be used to generate the commandline argument that represents the graph:
$ echo  sed -n -e '/^\s*[0-9]\+;$/p' graph.dot   wc -l   sed -n -e 's/^\s*\([0-9]\) -> \([0-9]\);$/\1,\2/p' graph.dot 

Testsuite As all four codebases take the same input format and have the same output format, it is now trivial to write a testsuite that compares the individual output of each algorithm for the same input and checks for differences. The code of the testsuite is available via this git repository: https://github.com/josch/cycle_test The other four repositories exist as submodules of the testsuite repository.
$ git clone git://github.com/josch/cycle_test.git
$ cd cycle_test
$ git submodule update --init
A testrun is done via calling:
$ ./test.sh 11
The argument to the shell script is an integer denoting the maximum number N of vertices for which graphs will be generated. The script will compile the Ocaml, Java and D sourcecode of the submodules as well as an ocaml script called rand_graph.ml which generates random graphs from v = 1..N vertices where N is given as a commandline argument. For each number of vertices n, e = 1..M number of edges are chosen where M is maximum number of edges given the number of vertices. For every combination of number of vertices v and number of edges e, a graph is randomly generated using Pack.Digraph.Rand.graph from the ocamlgraph library. Each of those generated graphs is checked for cycles and written to a file graph-v-e.dot if the graph contains a cycle. test.sh then loops over all generated dot files. It uses the above sed expression to convert each dot file to a commandline argument for each of the algorithms. The outputs of each algorithm are then compared with each other and only if they do not differ, does the loop continue. Otherwise the script returns with an exit code. The tested algorithms are the Python implementation of Tarjan's algorithm, the iterative and functional Ocaml implementation as well as the Java implementation of Johnson's algorithm and the D implementation of the algorithm by Hawick and James.

Future developments Running the testsuite with a maximum of 12 vertices takes about 33 minutes on a 2.53GHz Core2Duo and produces graphs with as much as 1.1 million cycles. It seems that all five implementations agree on the output for all 504 generated graphs that were used as input. If there should be another implementation of an algorithm that enumerates all elementary circuits of a directed graph, I would like to add it. There are some more papers that I would like to read but I lack access to epubs.siam.org and ieeexplore.ieee.org and would have to buy them. Benchmarks seem a bit pointless as not only the algorithms are very different from each other (and there are many ways to tweak each of them) but also the programming languages differ. Though for the curious kind, it follows the time each algorithm takes to enumerate all cycles for all generated graphs up to 11 vertices.
algorithmtime (s)
Johnson, Abate, Ocaml, iterative137
Johnson, Abate, Ocaml, functional139
Tarjan, Python153
Hawick, D175
Johnson, Meyer, Java357
The iterative Ocaml code performs as well as the functional one. In practice, the iterative code should probably be preferred as the functional code is not tail recursive. On the other hand it is also unlikely that cycles ever grow big enough to make a difference in the used stack space. The Python implementation executes surprisingly fast, given that Tarjan's algorithm is supposedly inferior to Johnson's and given that Python is interpreted but the Python implementation is also the most simple one with the least amount of required datastructures. The D code potentially suffers from the bigger datastructures and other bookkeeping that is required to support multi and self arcs. The java code implements a whole graph library which might explain some of its slowness.

Michael Banck: 4 Jul 2012

Update on computational chemistry packages in Debian

For many years, me and the Debichem team maintained two computational chemistry packages, first MPQC and later PSI3. In recent years however, two respected quantum chemistry codes have been open sourced and are now available in Debian: ACESIII and NWChem. Make no mistake, those are not recently started codes or some Ph.D.'s pet-project but state-of-the-art projects targeted at massively parallel supercomputers and developed at the University of Florida's Quantum Chemistry Project (QTP) in the case of ACESIII and at Pacific Northwest National Laboratory (PNNL) for NWChem.

While ACESIII has a somewhat narrow focus on Coupled-Cluster (unfortunately, the current version does not yet implement analytic gradients for the "golden standard" CCSD(T) method) and Multi-Body Perturbation Theory methods, NWChem is a very versatile package supporting a variety of molecular quantum chemistry methods (including Density Functional Theory (DFT)), as well as periodic plane-wave electronic structure and (ab-initio and classical) molecular dynamics. At this point, NWChem probably covers 90% of all use cases for routine computational chemistry compared to the popular non-free codes Gaussian and GAMESS, while likely exhibiting superior parallel scaling at least compared to Gaussian.

Over the last year, I have packaged and integrated NWChem and ACESIII for Debian, and they are now both in testing. Furthermore, I have recently overhauled the packaging of MPQC and enabled parallel execution via MPI. Further, both MPQC and PSI will see updated versions (MPQC3 and PSI4) in the near future with significant increased functionality, including some unique (at least among open source codes) features like Symmetry-Adapted Perturbation Theory (SAPT) for PSI4 and general explicitly correlated corrections ([2]f12) for MPQC3. Unfortunately, they both did not get released in time for the wheezy freeze.

On the periodic/plane-wave front, I have also packaged and uploaded Quantum ESPRESSO (formerly PwSCF), a set of plane-wave programs, and I have been working with lafur Jens Sigur sson to get the latest Abinit release packaged. The nanoscale-physics team is also targeting further periodic ab-initio packages like BigDFT and Octopus, but those as well did not land in time for the freeze.

Finally, I also packaged and uploaded CP2K, a well-engineered and versatile periodic plane-wave/pseudo-potential code which focuses on state-of-the-art ab-initio Molecular Dynamics (AIMD) using Density Functional Theory. Some of the authors have recently published a paper reporting linear scaling benchmark calculations on a system with a million atoms using almost 50,000 CPU cores.

All of the above mentioned packages are included either in the molecular ab-initio or the periodic ab-initio Debichem tasks.

Michal &#268;iha&#345;: Weblate 1.1

Pretty much on schedule, Weblate 1.1 has been released today. It comes with translation updates, bug fixes, improvements in working with Git repositories and brings support for offloading indexing. Full list of changes for 1.1: You can find more information about Weblate on it's website, the code is hosted on Github. If you are curious how it looks, you can try it out on demo server. You can login there with demo account using demo password or register your own user. Ready to run appliances can be found in SUSE Studio Gallery. Weblate is also being used https://l10n.cihar.com/ as official translating service for phpMyAdmin, Gammu, Weblate itself and others. If you are free software project which would like to use Weblate, I'm happy to help you with set up or even host Weblate for you (this will be decided case by case as my hosting space is limited). Update: Weblate appliace has now also been updated to 1.1.

Filed under: English Phpmyadmin Suse Weblate 0 comments Flattr this!

Stefano Zacchiroli: bits from the DPL for June 2012

Monthly DPL bits, fresh from the oven^W^W^W hot from DebConf12, and just posted to d-d-a.
Howdy from DebConf12. It's hot, but it's also time to bother you again with a (not so) brief DPL activity report, this time for June 2012. Time-based freeze: DONE, short freeze: TODO Two highlights for this month. First, you've probably noticed Wheezy is now frozen, YAY. This is huge achievement for the release, but also for the project. It's the first time we do a time-based freeze, and it took some quite heated discussion at the beginning of the release cycle to decide to do this. And we did it properly: respecting the planned month and narrowing down the period later. This exercise has hopefully helped both DDs in their package planning and our upstreams in targeting Wheezy with stable releases of their software. Kudos to the release team for their coordination work! Now we've the second part still TODO: releasing Wheezy, without RC bugs, with a freeze period as short as possible. See the beginning of my last "bits from the DPL" mail for my usual song and dance :-P on how to deliver that, together. DebConf12 A lot of us will attend DebConf12. Enjoy it! ... and take the chance to both have fun and make great plans for Debian's future. But remember that "if it didn't happen on a mailing list, it didn't happen". Not all of us will be lucky enough to attend DebConf (in person or remotely). Make sure that those who don't can take part in your team decisions and get informed of what is going to happen here. Politics Zack's spring tour I spent a significant part of June doing Debian talks ins some sort of "spring tour" between Italy and France. In particular: Many thanks to the organizers of these events for inviting and sponsoring me (as well as other Debian people, in the ESRF case) and for their interest in Debian. Sprints Assets Discussions Some relevant discussions for project evolution has been going on in June and I took part into them. You might want to have a look at them: Misc Cheers.
PS the boring day-to-day activity log for June is available at master:/srv/leader/news/bits-from-the-DPL.txt.201206

Dirk Eddelbuettel: RcppBDT 0.2.0

A new release of the RcppBDT package appeared on CRAN earlier today. RcppBDT uses Rcpp, and in particular the nifty Rcpp modules feature of wrapping C++ code for R just by declaring the (class or function) interfaces. It uses this to bring in some useful functions from Boost Date.Time to R so that one can do things like
R> library(RcppBDT)
R> sapply(2012:2016, function(year)
+         format(getNthDayOfWeek(first, Mon, Sep, year)))
[1] "2012-09-03" "2013-09-02" "2014-09-01" "2015-09-07" "2016-09-05"
R> 
to compute the next five Labor Day dates in the US, given the year and the first Monday of September requirement. More examples are e.g. on the earlier blog post announcing version 0.1.0. Changes are mostly internal. R 2.15.1 brough a better / easier way to load such 'modules' into R, and Rcpp 0.9.13 allows us to use this. So RcppBDT continues to be useful as an example package for Rcpp modules. I also streamlines the interface a little: identifiers are now directly accessible in the package's NAMESPACE rather than just via the an instantiated object. I also added a NEWS file, using the .Rd format so that we can import the marked-up text:
News for Package RcppBDT Changes in version 0.2.0 (2012-07-02)
  • The core module, which wraps what in C++ is boost::gregorian::date, is now exposed as an Rcpp module bdtDate. As all example and demos operated off a (package-global) variable 'bdt', no user visible change was needed outside of the code instantiating at package load.
  • Updated package instantiation to the new facilities offered by the current versions R 2.15.1 and Rcpp 0.9.13 which make Rcpp module initialization easier and more streamlined.
Changes in version 0.1.0 (2011-01-17)
  • First CRAN upload (and see ChangeLog for more granular details) bug fix in svm cross validation
Courtesy of CRANberries, there is also a diffstat report for 0.2.0 relative to 0.1.0. As always, feedback is welcome and the rcpp-devel mailing list off the R-Forge page for Rcpp is the best place to start a discussion.

3 July 2012

C.J. Adams-Collier: Currency platform superior to US Federal Reserve Bank

Should I recommend that Software in the Public Interest implement a monetary stack with the stated purpose of replacing the federal reserve system? We would have to publish the source code, of course, and the transaction db would need to be de-centralized so as to avoid private interests using it for their own benefit at the expense of their fellow humans. Not that that would ever happen, mittens. We d probably experience a period of instability due to scaling issues during the learning state, say the first two to five years. The IRS would need to be convinced that it would be a good idea, though. And I think they only listen to voters. And I don t want to be the one responsible for convincing them. I m not so good at exchanging paperwork with them, and they would likely get confused. Anyway, the idea would be that after the learning state, sessions would be migrated from the Fed db at a sustainable rate. After moving the sessions off of the Fed s current, compromised stack, the increase in tax revenues caused by removal of the current implementation s filters should be more than enough to fund the maintenance of the implementation undergoing strict peer review. http://www.wapublicbankproject.org/

Miriam Ruiz: Scratch in Debian

Scratch has finally reached Debian repositories. Scratch is a programming learning environment created by the Lifelong Kindergarten Group at the MIT Media Lab designed to be accessible by young learners (over 8 years old). Scratch makes it easy to create your own interactive stories, animations, games, music, and art through a visual interface based on blocks. Thus, beginners can get results without having to learn to write syntactically correct code first. It is powerful enough to have even been adopted as an entry-level computer language in computer science programs at different universities. Scratch makes use of pieces of code embedded in different blocks that are shaped like puzzle pieces. That way, programming consists on putting different blocks together, which gives immediate visual feedback to the programmer about the correctness of the syntax: If the pieces fit together, then the expression is valid. Scratch programming system is so nice and easy that has been the inspiration of other systems such as MIT App Inventor or Google Blocky.

Scratch animations consist of sprites that are animated by dragging the corresponent blocks into the Scripts area of the Scratch interface. Multiple sprites can be created and interact with one another. Each of the sprites can have different looks (called costumes in Scratch). You can use built-in sprites, load them from files, or draw your own using a drawing tool integrated in the environment. Scratch itself is coded in Squeak, a Smalltalk implementation derived from Smalltalk-80. The Scratch 1.4 source went GPLv2 on March, but there were some incompatibilites with the Squeak Virtual Machine currently in Wheezy that had to be resolved first. Luckily we were able to solve them, with the help of the Scratch and the Squeak guys, so I m happy to say that Scrach is finally available from Debian repositories. Note: If any Scratch derivatives (such as BYOB or Panther) also need to be ported to the current version of Squeak, they should have a look at the comments in the Scratch ITP, and especially to the script uploaded by Bert Freudenberg, that replaces 90 indexed primitive declarations (removed in later versions of Squeak VM) with their named counterpart. Note 2: This wouldn t have been possible without all the great work and effort made by Amos Blanton and many others. Lots of thanks!

Next.

Previous.