Search Results: "nate"

27 September 2020

Dirk Eddelbuettel: pkgKitten 0.2.0: Now with tinytest and new docs

kitten A new release 0.2.0 of pkgKitten just hit on CRAN today, or about eleven months after the previous release. This release brings support for tinytest by having pkgKitten::kitten() automagically call tinytest::puppy() if the latter package is installed (and the user did not opt out of calling it). So your newly created minimal package now also uses a wonderful yet tiny testing framework. We also added a new documentation site using the previously tweeted-about wrapper for Material for MkDocs I really dig. And last but not least we switched to BSPM-based Continued Integration (which I wrote about yesterday in R4 #30) and fixed one bug regarding the default NAMESPACE file.

Changes in version 0.2.0 (2020-09-27)
  • Continuous Integration uses the updated BSPM-based script on Travis and with GitHub Actions (Dirk in #11 plus earlier commits).
  • A new default NAMESPACE file is now installed (Dirk in #12).
  • A package documentation website was added (Dirk in #13).
  • Call tinytest::puppy if installed and not opted out (Dirk in #14).

More details about the package are at the pkgKitten webpage, the (new) pkgKitten docs site, and the pkgKitten GitHub repo. Courtesy of my CRANberries site, there is also a diffstat report for this release. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

26 September 2020

Fran ois Marier: Repairing a corrupt ext4 root partition

I ran into filesystem corruption (ext4) on the root partition of my backup server which caused it to go into read-only mode. Since it's the root partition, it's not possible to unmount it and repair it while it's running. Normally I would boot from an Ubuntu live CD / USB stick, but in this case the machine is using the mipsel architecture and so that's not an option.

Repair using a USB enclosure I had to pull the shutdown the server and then pull the SSD drive out. I then moved it to an external USB enclosure and connected it to my laptop. I started with an automatic filesystem repair:
fsck.ext4 -pf /dev/sde2
which failed for some reason and so I moved to an interactive repair:
fsck.ext4 -f /dev/sde2
Once all of the errors were fixed, I ran a full surface scan to update the list of bad blocks:
fsck.ext4 -c /dev/sde2
Finally, I forced another check to make sure that everything was fixed at the filesystem level:
fsck.ext4 -f /dev/sde2

Fix invalid alternate GPT The other thing I noticed is this messge in my dmesg log:
scsi 8:0:0:0: Direct-Access     KINGSTON  SA400S37120     SBFK PQ: 0 ANSI: 6
sd 8:0:0:0: Attached scsi generic sg4 type 0
sd 8:0:0:0: [sde] 234441644 512-byte logical blocks: (120 GB/112 GiB)
sd 8:0:0:0: [sde] Write Protect is off
sd 8:0:0:0: [sde] Mode Sense: 31 00 00 00
sd 8:0:0:0: [sde] Write cache: enabled, read cache: enabled, doesn't support DPO or FUA
sd 8:0:0:0: [sde] Optimal transfer size 33553920 bytes
Alternate GPT is invalid, using primary GPT.
 sde: sde1 sde2
I therefore checked to see if the partition table looked fine and got the following:
$ fdisk -l /dev/sde
GPT PMBR size mismatch (234441643 != 234441647) will be corrected by write.
The backup GPT table is not on the end of the device. This problem will be corrected by write.
Disk /dev/sde: 111.8 GiB, 120034123776 bytes, 234441648 sectors
Disk model: KINGSTON SA400S3
Units: sectors of 1 * 512 = 512 bytes
Sector size (logical/physical): 512 bytes / 512 bytes
I/O size (minimum/optimal): 512 bytes / 512 bytes
Disklabel type: gpt
Disk identifier: 799CD830-526B-42CE-8EE7-8C94EF098D46
Device       Start       End   Sectors   Size Type
/dev/sde1     2048   8390655   8388608     4G Linux swap
/dev/sde2  8390656 234441614 226050959 107.8G Linux filesystem
It turns out that all I had to do, since only the backup / alternate GPT partition table was corrupt and the primary one was fine, was to re-write the partition table:
$ fdisk /dev/sde
Welcome to fdisk (util-linux 2.33.1).
Changes will remain in memory only, until you decide to write them.
Be careful before using the write command.
GPT PMBR size mismatch (234441643 != 234441647) will be corrected by write.
The backup GPT table is not on the end of the device. This problem will be corrected by write.
Command (m for help): w
The partition table has been altered.
Syncing disks.

Run SMART checks Since I still didn't know what caused the filesystem corruption in the first place, I decided to do one last check: SMART errors. I couldn't do this via the USB enclosure since the SMART commands aren't forwarded to the drive and so I popped the drive back into the backup server and booted it up. First, I checked whether any SMART errors had been reported using smartmontools:
smartctl -a /dev/sda
That didn't show any errors and so I kicked off an extended test:
smartctl -t long /dev/sda
which ran for 30 minutes and then passed without any errors. The mystery remains unsolved.

Dirk Eddelbuettel: #30: Easy, Reliable, Fast and Portable Linux and macOS Continuous Integration

Welcome to the 30th post in the rarified R recommendation resources series or R4 for short. The last post introduced BSPM. In the four weeks since, we have worked some more on BSPM to bring it to the point where it is ready for use with continuous integration. Building on this, it is now used inside the run.sh script that driven our CI use for many years (via the r-travis repo). Which we actually use right now on three different platforms: All three use the exact same script facilitating this, and run a matrix over Linux and macOS. You read this right: one CI setup that is portable and which you can take to your CI provider of choice. No lock-in or tie-in. Use what works, change at will. Or run on all three if you like burning extra cycles. This is already used by handful of my repos as well as by at least two repos of friends also deploying r-travis. How does it work? In a nutshell we are There are several customizations that are possible via environment variables We find this setup compelling. The scheme is simple: there really is just one shell script behind it which can also be downloaded and altered. The scheme is also portable as we can (as shown) rotate between CI provides. The scheme is also more flexible: in case of debugging needs one can simply run the script on a local Docker or VM instance. Lastly, the scheme moves away from single points of failure or breakage. Currently the script uses only BSPM as I had the hunch that it would a) work and b) be compelling. Adding support for RSPM would be equally easy, but I have no immediate need to do so. Adding BioConductor installation may be next. That is easy when BioConductor uses r-release; it may be little more challenging under r-devel to but it should work too. Stay tuned. In the meantime, if the above sounds compelling, give run.sh from r-travis a go! If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

25 September 2020

Colin Watson: Porting Launchpad to Python 3: progress report

Launchpad still requires Python 2, which in 2020 is a bit of a problem. Unlike a lot of the rest of 2020, though, there s good reason to be optimistic about progress. I ve been porting Python 2 code to Python 3 on and off for a long time, from back when I was on the Ubuntu Foundations team and maintaining things like the Ubiquity installer. When I moved to Launchpad in 2015 it was certainly on my mind that this was a large body of code still stuck on Python 2. One option would have been to just accept that and leave it as it is, maybe doing more backporting work over time as support for Python 2 fades away. I ve long been of the opinion that this would doom Launchpad to being unmaintainable in the long run, and since I genuinely love working on Launchpad - I find it an incredibly rewarding project - this wasn t something I was willing to accept. We re already seeing some of our important dependencies dropping support for Python 2, which is perfectly reasonable on their terms but which is starting to become a genuine obstacle to delivering important features when we need new features from newer versions of those dependencies. It also looks as though it may be difficult for us to run on Ubuntu 20.04 LTS (we re currently on 16.04, with an upgrade to 18.04 in progress) as long as we still require Python 2, since we have some system dependencies that 20.04 no longer provides. And then there are exciting new features like type hints and async/await that we d like to be able to use. However, until last year there were so many blockers that even considering a port was barely conceivable. What changed in 2019 was sorting out a trifecta of core dependencies. We ported our database layer, Storm. We upgraded to modern versions of our Zope Toolkit dependencies (after contributing various fixes upstream, including some substantial changes to Zope s test runner that we d carried as local patches for some years). And we ported our Bazaar code hosting infrastructure to Breezy. With all that in place, a port seemed more of a realistic possibility. Still, even with this, it was never going to be a matter of just following some standard porting advice and calling it good. Launchpad has almost a million lines of Python code in its main git tree, and around 250 dependencies of which a number are quite Launchpad-specific. In a project that size, not only is following standard porting advice an extremely time-consuming task in its own right, but just about every strange corner case is going to show up somewhere. (Did you know that StringIO.StringIO(None) and io.StringIO(None) do different things even after you account for the native string vs. Unicode text difference? How about the behaviour of .union() on a subclass of frozenset?) Launchpad s test suite is fortunately extremely thorough, but even just starting up the test suite involves importing most of the data model code, so before you can start taking advantage of it you have to make a large fraction of the codebase be at least syntactically-correct Python 3 code and use only modules that exist in Python 3 while still working in Python 2; in a project this size that turns out to be a large effort on its own, and can be quite risky in places. Canonical s product engineering teams work on a six-month cycle, but it just isn t possible to cram this sort of thing into six months unless you do literally nothing else, and please can we put all feature development on hold while we run to stand still is a pretty tough sell to even the most understanding management. Fortunately, we ve been able to grow the Launchpad team in the last year or so, and so it s been possible to put Python 3 on our roadmap on the understanding that we aren t going to get all the way there in one cycle, while still being able to do other substantial feature development work as well. So, with all that preamble, what have we done this cycle? We ve taken a two-pronged approach. From one end, we identified 147 classes that needed to be ported away from some compatibility code in our database layer that was substantially less friendly to Python 3: we ve ported 38 of those, so there s clearly a fair bit more to do, but we were able to distribute this work out among the team quite effectively. From the other end, it was clear that it would be very inefficient to do general porting work when any attempt to even run the test suite would run straight into the same crashes in the same order, so I set myself a target of getting the test suite to start up, and started hacking on an enormous git branch that I never expected to try to land directly: instead, I felt free to commit just about anything that looked reasonable and moved things forward even if it was very rough, and every so often went back to tidy things up and cherry-pick individual commits into a form that included some kind of explanation and passed existing tests so that I could propose them for review. This strategy has been dramatically more successful than anything I ve tried before at this scale. So far this cycle, considering only Launchpad s main git tree, we ve landed 137 Python-3-relevant merge proposals for a total of 39552 lines of git diff output, keeping our existing tests passing along the way and deploying incrementally to production. We have about 27000 more lines of patch at varying degrees of quality to tidy up and merge. Our main development branch is only perhaps 10 or 20 more patches away from the test suite being able to start up, at which point we ll be able to get a buildbot running so that multiple developers can work on this much more easily and see the effect of their work. With the full unlanded patch stack, about 75% of the test suite passes on Python 3! This still leaves a long tail of several thousand tests to figure out and fix, but it s a much more incrementally-tractable kind of problem than where we started. Finally: the funniest (to me) bug I ve encountered in this effort was the one I encountered in the test runner and fixed in zopefoundation/zope.testrunner#106: IDs of failing tests were written to a pipe, so if you have a test suite that s large enough and broken enough then eventually that pipe would reach its capacity and your test runner would just give up and hang. Pretty annoying when it meant an overnight test run didn t give useful results, but also eloquent commentary of sorts.

22 September 2020

Russ Allbery: Review: Unconquerable Sun

Review: Unconquerable Sun, by Kate Elliott
Series: Sun Chronicles #1
Publisher: Tor
Copyright: 2020
ISBN: 1-250-19725-2
Format: Kindle
Pages: 526
Sun is the daughter and heir of the mercurial Queen-Marshal Eirene, ruler of the Republic of Chaonia. Chaonia, thanks to Eirene and her ancestors, has carved out a fiercely independent position between the Yele League and the Phene Empire. Sun's father, Prince Jo o, is one of Eirene's three consorts, all chosen for political alliances to shore up that fragile position. Jo o is Gatoi, a civilization of feared fighters and supposed barbarians from outside Chaonia who normally ally with the Phene, which complicates Sun's position as heir. Sun attempts to compensate for that by winning battles for the Republic, following in the martial footsteps of her mother. The publisher's summary of this book is not great (I'm a huge fan of Princess Leia, but that is... not the analogy that comes to mind), so let me try to help. This is gender-swapped Alexander the Great in space. However, it is gender-swapped Alexander the Great in space with her Companions, which means the DNA of this novel is half space opera and half heist story (without, to be clear, an actual heist, although there are some heist-like maneuvers). It's also worth mentioning that Sun, like Alexander, is not heterosexual. The other critical thing to know before reading, mostly because it will get you through the rather painful start, is that the most interesting viewpoint character in this book is not Sun, the Alexander analogue. It's Persephone, who isn't introduced until chapter seven. Significant disclaimer up front: I got a reasonably typical US grade school history of Alexander the Great, which means I was taught that he succeeded his father, conquered a whole swath of the middle of the Eurasian land mass at a very young age, and then died and left his empire to his four generals who promptly divided it into four uninteresting empires that no one's ever heard of, and that's why Rome is more important than Greece. (I put in that last bit to troll one specific person.) I am therefore not the person to judge the parallels between this story and known history, or to notice any damage done to Greek pride, or to pick up on elements that might cause someone with a better grasp of that history to break out in hives. I did enough research to know that one scene in this book is lifted directly out of Alexander's life, but I'm not sure how closely the other parallels track. Yele is probably southern Greece and Phene is probably Persia, but I'm not certain even of that, and some of the details don't line up. If I had to hazard a guess, I'd say that Elliott has probably mangled history sufficiently to make it clear that this isn't intended to be a retelling, but if the historical parallels are likely to bother you, you may want to do more research before reading. What I can say is that the space opera setup, while a bit stock, has all the necessary elements to make me happy. Unconquerable Sun is firmly in the "lost Earth" tradition: The Argosy fleet fled the now-mythical Celestial Empire and founded a new starfaring civilization without any contact with their original home. Eventually, they invented (or discovered; the characters don't know) the beacons, which allow for instantaneous travel between specific systems without the long (but still faster-than-light) journeys of the knnu drive. More recently, the beacon network has partly collapsed, cutting off the characters' known world from the civilization that was responsible for the beacons and guarded their secrets. It's a fun space opera history with lots of lost knowledge to reference and possibly discover, and with plot-enabling military choke points at the surviving beacons that link multiple worlds. This is all background to the story, which is the ongoing war between Chaonia and the Phene Empire mixed with cutthroat political maneuvering between the great houses of the Chaonian Republic. This is where the heist aspects come in. Each house sends one representative to join the household of the Queen-Marshal and (more to the point for this story) another to join her heir. Sun has encouraged the individual and divergent talents of her Companions and their cee-cees (an unfortunate term that I suspect is short for Companion's Companion) and forged them into a good working team. A team that's about to be disrupted by the maneuverings of a rival house and the introduction of a new team member whom no one wants. A problem with writing tactical geniuses is that they often aren't good viewpoint characters. Sun's tight third-person chapters, which is a little less than half the book, advance the plot and provide analysis of the interpersonal dynamics of the characters, but aren't the strength of the story. That lies with the interwoven first-person sections that follow Persephone, an altogether more interesting character. Persephone is the scion of the house that is Sun's chief rival, but she has no interest in being part of that house or its maneuverings. When the story opens, she's a cadet in a military academy for recruits from the commoners, having run away from home, hidden her identity, and won a position through the open entrance exams. She of course doesn't stay there; her past catches up with her and she gets assigned to Sun, to a great deal of mutual suspicion. She also is assigned an impeccably dressed and stunningly beautiful cee-cee, Tiana, who has her own secrets and who was my favorite character in the book. Somewhat unusually for the space opera tradition, this is a book that knows that common people exist and have interesting lives. It's primarily focused on the ruling houses, but that focus is not exclusive and the rulers do not have a monopoly on competence. Elliott also avoids narrowing the political field too far; the Gatoi are separate from the three rival powers, and there are other groups with traditions older than the Chaonian Republic and their own agendas. Sun and her Companions are following a couple of political threads, but there is clearly more going on in this world than that single plot. This is exactly the kind of story I think of when I think space opera. It's not doing anything that original or groundbreaking, and it's not going to make any of my lists of great literature, but it's a fun romp with satisfyingly layered bits of lore, a large-scale setting with lots of plot potential, and (once we get through the confusing and somewhat tedious process of introducing rather too many characters in short succession) some great interpersonal dynamics. It's the kind of book in which the characters are in the middle of decisive military action in an interstellar war and are also near-teenagers competing for ratings in an ad hoc reality TV show, primarily as an excuse to create tactical distractions for Sun's latest scheme. The writing is okay but not great, and the first few chapters have some serious infodumping problems, but I thoroughly enjoyed the whole book and will pre-order the sequel. One Amazon review complained that Unconquerable Sun is not a space opera like Hyperion or Use of Weapons. That is entirely true, but if that's your standard for space opera, the world may be a disappointing place. This is a solid entry in a subgenre I love, with some great characters, sarcasm, competence porn, plenty of pages to keep turning, a few twists, and the promise of more to come. Recommended. Followed by the not-yet-published Furious Heaven. Rating: 7 out of 10

20 September 2020

Dirk Eddelbuettel: RcppSpdlog 0.0.2: New upstream, awesome new stopwatch

Following up on the initial RcppSpdlog 0.0.1 release earlier this week, we are pumped to announce release 0.0.2. It contains upstream version 1.8.0 for spdlog which utilizes (among other things) a new feature in the embedded fmt library, namely completely automated formatting of high resolution time stamps which allows for gems like this (taken from this file in the package and edited down for brevity):
    spdlog::stopwatch sw;                                   // instantiate a stop watch

    // some other code

    sp->info("Elapsed time:  ", sw);
What we see is all there is: One instantiates a stopwatch object, and simply references it. The rest, as they say, is magic. And we get tic / toc alike behaviour in modern C++ at essentially no cost us (as code authors). So nice. Output from the (included in the package) function exampleRsink() (again edited down just a little):
R> RcppSpdlog::exampleRsink()
[13:03:23.845114] [fromR] [I] [thread 793264] Welcome to spdlog!
[...]
[13:03:23.845205] [fromR] [I] [thread 793264] Elapsed time: 0.000103611
[...]
[13:03:23.845281] [fromR] [I] [thread 793264] Elapsed time: 0.00018203
R> 
We see that the two simple logging instances come 10 and 18 microseconds into the call. RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovic. The NEWS entry for this release follows.

Changes in RcppSpdlog version 0.0.2 (2020-09-17)
  • Upgraded to upstream release 1.8.0
  • Switched Travis CI to using BSPM, also test on macOS
  • Added 'stopwatch' use to main R sink example

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppSpdlog page. The only sour grapes, again, are once more over the CRAN processing. And just how 0.0.1 was delayed for no good reason for three weeks, 0.0.2 was delayed by three days just because well that is how CRAN rules sometimes. I d be even more mad if I had an alternative but I don t. We remain grateful for all they do but they really could have let this one through even at one-day update delta. Ah well, now we re three days wiser and of course nothing changed in the package. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

19 September 2020

Vincent Bernat: Syncing NetBox with a custom Ansible module

The netbox.netbox collection from Ansible Galaxy provides several modules to update NetBox objects:
- name: create a device in NetBox
  netbox_device:
    netbox_url: http://netbox.local
    netbox_token: s3cret
    data:
      name: to3-p14.sfo1.example.com
      device_type: QFX5110-48S
      device_role: Compute Switch
      site: SFO1
However, if NetBox is not your source of truth, you may want to ensure it stays in sync with your configuration management database1 by removing outdated devices or IP addresses. While it should be possible to glue together a playbook with a query, a loop and some filtering to delete unwanted elements, it feels clunky, inefficient and an abuse of YAML as a programming language. A specific Ansible module solves this issue and is likely more flexible.

Notice I recommend that you read Writing a custom Ansible module as an introduction, as well as Syncing MySQL tables for a first simpler example.

Code The module has the following signature and it syncs NetBox with the content of the provided YAML file:
netbox_sync:
  source: netbox.yaml
  api: https://netbox.example.com
  token: s3cret
The synchronized objects are:
  • sites,
  • manufacturers,
  • device types,
  • device roles,
  • devices, and
  • IP addresses.
In our environment, the YAML file is generated from our configuration management database and contains a set of devices and a list of IP addresses:
devices:
  ad2-p6.sfo1.example.com:
     datacenter: sfo1
     manufacturer: Cisco
     model: Catalyst 2960G-48TC-L
     role: net_tor_oob_switch
  to1-p6.sfo1.example.com:
     datacenter: sfo1
     manufacturer: Juniper
     model: QFX5110-48S
     role: net_tor_gpu_switch
# [ ]
ips:
  - device: ad2-p6.example.com
    ip: 172.31.115.18/21
    interface: oob
  - device: to1-p6.example.com
    ip: 172.31.115.33/21
    interface: oob
  - device: to1-p6.example.com
    ip: 172.31.254.33/32
    interface: lo0.0
# [ ]
The network team is not the sole tenant in NetBox. While adding new objects or modifying existing ones should be relatively safe, deleting unwanted objects can be risky. The module only deletes objects it did create or modify. To identify them, it marks them with a specific tag, cmdb. Most objects in NetBox accept tags.

Module definition Starting from the skeleton described in the previous article, we define the module:
module_args = dict(
    source=dict(type='path', required=True),
    api=dict(type='str', required=True),
    token=dict(type='str', required=True, no_log=True),
    max_workers=dict(type='int', required=False, default=10)
)
result = dict(
    changed=False
)
module = AnsibleModule(
    argument_spec=module_args,
    supports_check_mode=True
)
It contains an additional optional arguments defining the number of workers to talk to NetBox and query the existing objects in parallel to speedup the execution.

Abstracting synchronization We need to synchronize different object types, but once we have a list of objects we want in NetBox, the grunt work is always the same:
  • check if the objects already exist,
  • retrieve them and put them in a form suitable for comparison,
  • retrieve the extra objects we don t want anymore,
  • compare the two sets, and
  • add missing objects, update existing ones, delete extra ones.
We code these behaviours into a Synchronizer abstract class. For each kind of object, a concrete class is built with the appropriate class attributes to tune its behaviour and a wanted() method to provide the objects we want. I am not explaining the abstract class code here. Have a look at the source if you want.

Synchronizing tags and tenants As a starter, here is how we define the class synchronizing the tags:
class SyncTags(Synchronizer):
    app = "extras"
    table = "tags"
    key = "name"
    def wanted(self):
        return  "cmdb": dict(
            slug="cmdb",
            color="8bc34a",
            description="synced by network CMDB") 
The app and table attributes defines the NetBox objects we want to manipulate. The key attribute is used to determine how to lookup for existing objects. In this example, we want to lookup tags using their names. The wanted() method is expected to return a dictionary mapping object keys to the list of wanted attributes. Here, the keys are tag names and we create only one tag, cmdb, with the provided slug, color and description. This is the tag we will use to mark the objects we create or modify. If the tag does not exist, it is created. If it exists, the provided attributes are updated. Other attributes are left untouched. We also want to create a specific tenant for objects accepting such an attribute (devices and IP addresses):
class SyncTenants(Synchronizer):
    app = "tenancy"
    table = "tenants"
    key = "name"
    def wanted(self):
        return  "Network": dict(slug="network",
                                description="Network team") 

Synchronizing sites We also need to synchronize the list of sites. This time, the wanted() method uses the information provided in the YAML file: it walks the devices and builds a set of datacenter names.
class SyncSites(Synchronizer):
    app = "dcim"
    table = "sites"
    key = "name"
    only_on_create = ("status", "slug")
    def wanted(self):
        result = set(details["datacenter"]
                     for details in self.source['devices'].values()
                     if "datacenter" in details)
        return  k: dict(slug=k,
                        status="planned")
                for k in result 
Thanks to the use of the only_on_create attribute, the specified attributes are not updated if they are different. The goal of this synchronizer is mostly to collect the references to the different sites for other objects.
>>> pprint(SyncSites(**sync_args).wanted())
 'sfo1':  'slug': 'sfo1', 'status': 'planned' ,
 'chi1':  'slug': 'chi1', 'status': 'planned' ,
 'nyc1':  'slug': 'nyc1', 'status': 'planned' 

Synchronizing manufacturers, device types and device roles The synchronization of manufacturers is pretty similar, except we do not use the only_on_create attribute:
class SyncManufacturers(Synchronizer):
    app = "dcim"
    table = "manufacturers"
    key = "name"
    def wanted(self):
        result = set(details["manufacturer"]
                     for details in self.source['devices'].values()
                     if "manufacturer" in details)
        return  k:  "slug": slugify(k) 
                for k in result 
Regarding the device types, we use the foreign attribute linking a NetBox attribute to the synchronizer handling it.
class SyncDeviceTypes(Synchronizer):
    app = "dcim"
    table = "device_types"
    key = "model"
    foreign =  "manufacturer": SyncManufacturers 
    def wanted(self):
        result = set((details["manufacturer"], details["model"])
                     for details in self.source['devices'].values()
                     if "model" in details)
        return  k[1]: dict(manufacturer=k[0],
                           slug=slugify(k[1]))
                for k in result 
The wanted() method refers to the manufacturer using its key attribute. In this case, this is the manufacturer name.
>>> pprint(SyncManufacturers(**sync_args).wanted())
 'Cisco':  'slug': 'cisco' ,
 'Dell':  'slug': 'dell' ,
 'Juniper':  'slug': 'juniper' 
>>> pprint(SyncDeviceTypes(**sync_args).wanted())
 'ASR 9001':  'manufacturer': 'Cisco', 'slug': 'asr-9001' ,
 'Catalyst 2960G-48TC-L':  'manufacturer': 'Cisco',
                           'slug': 'catalyst-2960g-48tc-l' ,
 'MX10003':  'manufacturer': 'Juniper', 'slug': 'mx10003' ,
 'QFX10002-36Q':  'manufacturer': 'Juniper', 'slug': 'qfx10002-36q' ,
 'QFX10002-72Q':  'manufacturer': 'Juniper', 'slug': 'qfx10002-72q' ,
 'QFX5110-32Q':  'manufacturer': 'Juniper', 'slug': 'qfx5110-32q' ,
 'QFX5110-48S':  'manufacturer': 'Juniper', 'slug': 'qfx5110-48s' ,
 'QFX5200-32C':  'manufacturer': 'Juniper', 'slug': 'qfx5200-32c' ,
 'S4048-ON':  'manufacturer': 'Dell', 'slug': 's4048-on' ,
 'S6010-ON':  'manufacturer': 'Dell', 'slug': 's6010-on' 
The device roles are defined like this:
class SyncDeviceRoles(Synchronizer):
    app = "dcim"
    table = "device_roles"
    key = "name"
    def wanted(self):
        result = set(details["role"]
                     for details in self.source['devices'].values()
                     if "role" in details)
        return  k: dict(slug=slugify(k),
                        color="8bc34a")
                for k in result 

Synchronizing devices A device is mostly a name with references to a role, a model, a datacenter and a tenant. These references are declared as foreign keys using the synchronizers defined previously.
class SyncDevices(Synchronizer):
    app = "dcim"
    table = "devices"
    key = "name"
    foreign =  "device_role": SyncDeviceRoles,
               "device_type": SyncDeviceTypes,
               "site": SyncSites,
               "tenant": SyncTenants 
    remove_unused = 10
    def wanted(self):
        return  name: dict(device_role=details["role"],
                           device_type=details["model"],
                           site=details["datacenter"],
                           tenant="Network")
                for name, details in self.source['devices'].items()
                if  "datacenter", "model", "role"  <= set(details.keys()) 
The remove_unused attribute is a safety implemented to fail if we have to delete more than 10 devices: this may be the indication there is a bug somewhere, unless one of your datacenter suddenly caught fire.
>>> pprint(SyncDevices(**sync_args).wanted())
 'ad2-p6.sfo1.example.com':  'device_role': 'net_tor_oob_switch',
                             'device_type': 'Catalyst 2960G-48TC-L',
                             'site': 'sfo1',
                             'tenant': 'Network' ,
 'to1-p6.sfo1.example.com':  'device_role': 'net_tor_gpu_switch',
                             'device_type': 'QFX5110-48S',
                             'site': 'sfo1',
                             'tenant': 'Network' ,
[ ]

Synchronizing IP addresses The last step is to synchronize IP addresses. We do not attach them to a device.2 Instead, we specify the device names in the description of the IP address:
class SyncIPs(Synchronizer):
    app = "ipam"
    table = "ip-addresses"
    key = "address"
    foreign =  "tenant": SyncTenants 
    remove_unused = 1000
    def wanted(self):
        wanted =  
        for details in self.source['ips']:
            if details['ip'] in wanted:
                wanted[details['ip']]['description'] = \
                    f" details['device']  (and others)"
            else:
                wanted[details['ip']] = dict(
                    tenant="Network",
                    status="active",
                    dns_name="",        # information is present in DNS
                    description=f" details['device'] :  details['interface'] ",
                    role=None,
                    vrf=None)
        return wanted
There is a slight difficulty: NetBox allows duplicate IP addresses, so a simple lookup is not enough. In case of multiple matches, we choose the best by preferring those tagged with cmdb, then those already attached to an interface:
def get(self, key):
    """Grab IP address from NetBox."""
    # There may be duplicate. We need to grab the "best".
    results = super(Synchronizer, self).get(key)
    if len(results) == 0:
        return None
    if len(results) == 1:
        return results[0]
    scores = [0]*len(results)
    for idx, result in enumerate(results):
        if "cmdb" in result.tags:
            scores[idx] += 10
        if result.interface is not None:
            scores[idx] += 5
    return sorted(zip(scores, results),
                  reverse=True, key=lambda k: k[0])[0][1]

Getting the current and wanted states Each synchronizer is initialized with a reference to the Ansible module, a reference to a pynetbox s API object, the data contained in the provided YAML file and two empty dictionaries for the current and expected states:
source = yaml.safe_load(open(module.params['source']))
netbox = pynetbox.api(module.params['api'],
                      token=module.params['token'])
sync_args = dict(
    module=module,
    netbox=netbox,
    source=source,
    before= ,
    after= 
)
synchronizers = [synchronizer(**sync_args) for synchronizer in [
    SyncTags,
    SyncTenants,
    SyncSites,
    SyncManufacturers,
    SyncDeviceTypes,
    SyncDeviceRoles,
    SyncDevices,
    SyncIPs
]]
Each synchronizer has a prepare() method whose goal is to compute the current and wanted states. It returns True in case of a difference:
# Check what needs to be synchronized
try:
    for synchronizer in synchronizers:
        result['changed']  = synchronizer.prepare()
except AnsibleError as e:
    result['msg'] = e.message
    module.fail_json(**result)

Applying changes Back to the skeleton described in the previous article, the last step is to apply the changes if there is a difference between these states. Each synchronizer registers the current and wanted states in sync_args["before"][table] and sync_args["after"][table] where table is the name of the table for a given NetBox object type. The diff object is a bit elaborate as it is built table by table. This enables Ansible to display the name of each table before the diff representation:
# Compute the diff
if module._diff and result['changed']:
    result['diff'] = [
        dict(
            before_header=table,
            after_header=table,
            before=yaml.safe_dump(sync_args["before"][table]),
            after=yaml.safe_dump(sync_args["after"][table]))
        for table in sync_args["after"]
        if sync_args["before"][table] != sync_args["after"][table]
    ]
# Stop here if check mode is enabled or if no change
if module.check_mode or not result['changed']:
    module.exit_json(**result)
Each synchronizer also exposes a synchronize() method to apply changes and a cleanup() method to delete unwanted objects. Order is important due to the relation between the objects.
# Synchronize
for synchronizer in synchronizers:
    synchronizer.synchronize()
for synchronizer in synchronizers[::-1]:
    synchronizer.cleanup()
module.exit_json(**result)

The complete code is available on GitHub. Compared to using netbox.netbox collection, the logic is written in Python instead of trying to glue Ansible tasks together. I believe this is both more flexible and easier to read, notably when trying to delete outdated objects. While I did not test it, it should also be faster. An alternative would have been to reuse code from the netbox.netbox collection, as it contains similar primitives. Unfortunately, I didn t think of it until now.

  1. In my opinion, a good option for a source of truth is to use YAML files in a Git repository. You get versioning for free and people can get started with a text editor.
  2. This limitation is mostly due to laziness: we do not really care about this information. Our main motivation for putting IP addresses in NetBox is to keep track of the used IP addresses. However, if an IP address is already attached to an interface, we leave this association untouched.

18 September 2020

Daniel Lange: Getting rid of the Google cookie consent popup

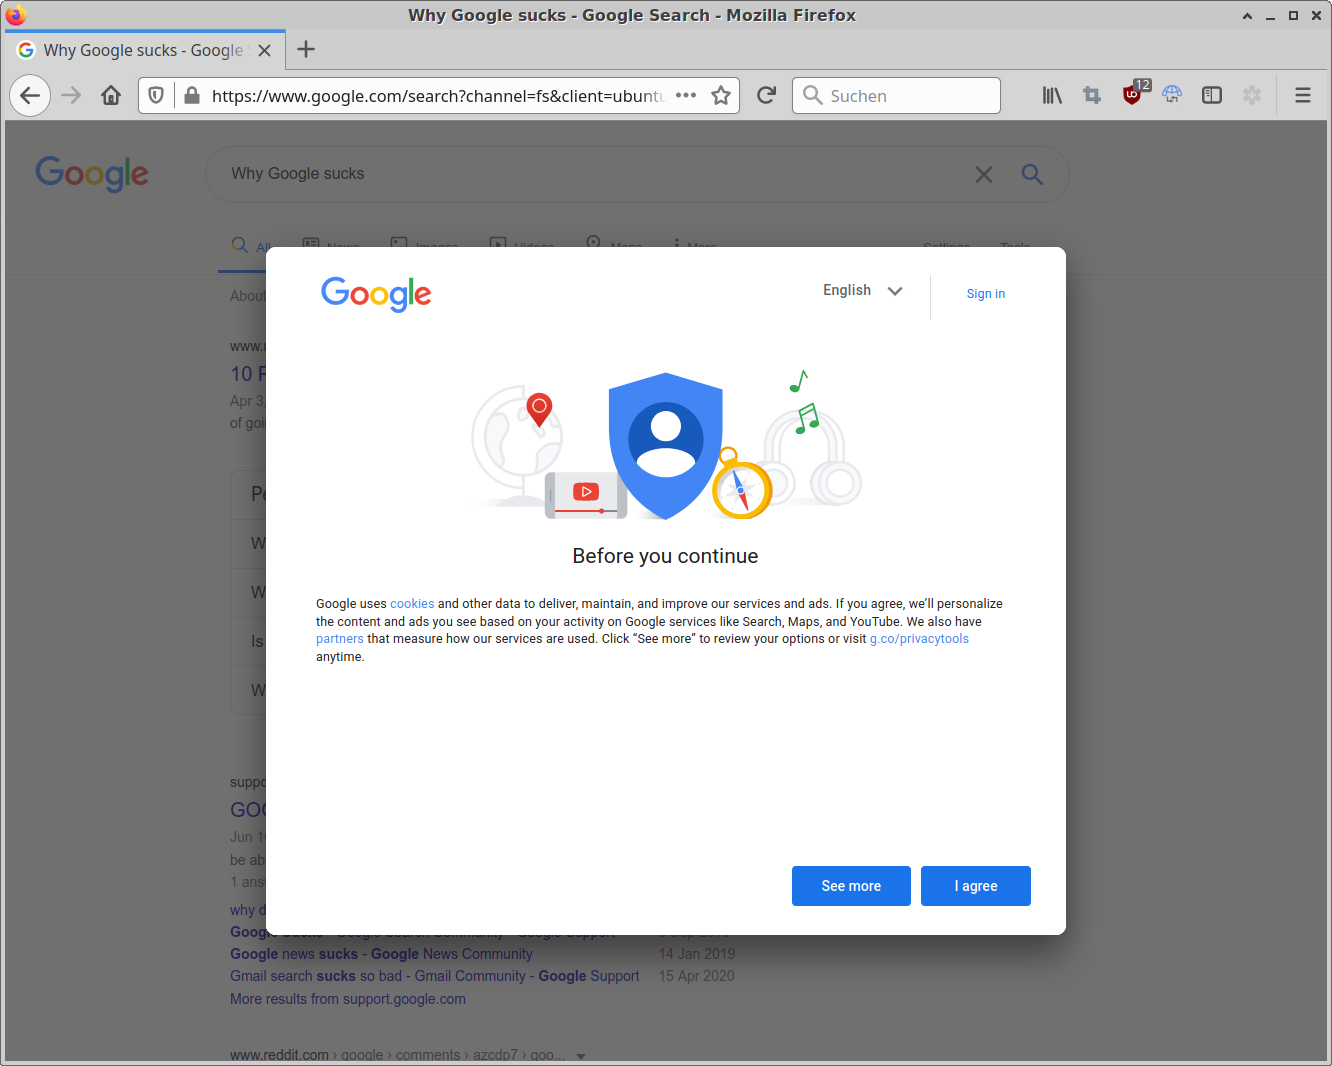
If you clear your browser cookies regularly (as you should do), Google will annoy you with a full screen cookie consent overlay these days. And - of course - there is no "no tracking consent, technically required cookies only" button. You may log in to Google to set your preference. Yeah, I'm sure this is totally following the intent of the EU Directive 2009/136/EC (the "cookie law"). Google cookie consent pop-up Unfortunately none of the big "anti-annoyances" filter lists seem to have picked that one up yet but the friendly folks from the Computerbase Forum [German] to the rescue. User "Sepp Depp" has created the following filter set that WFM: Add this to your uBlock Origin "My filters" tab:
! Google - remove cookie-consent-popup and restore scroll functionality
google.*##.wwYr3.aID8W.bErdLd
google.*##.aID8W.m114nf.t7xA6
google.*##div[jsname][jsaction^="dg_close"]
google.*##html:style(overflow: visible !important;)
google.*##.widget-consent-fullscreen.widget-consent

17 September 2020

Dirk Eddelbuettel: RcppSpdlog 0.0.1: New and Exciting Logging Package

Very thrilled to announce a new package RcppSpdlog which is now on CRAN in its first release 0.0.1. We had tweeted once about the earliest version which had already caught the eyes of Gabi upstream. RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovic. I had meant to package this for a few years now but didn t find an (easy, elegant) way to completely lift stdout / stderr and related uses which R wants us to remove for smoother operations from R itself including synchronized input/output. It was only a few weeks ago that I realized I should subclass a logger (or, more concretely, a sink for a logger) which could then use R input/output. With the right idea the implementaton was easy, and [Gabi]((https://github.com/gabime) was most helpful in making sure R CMD check would not see one or two remaining C++ i/o operations (which we currently do by not activating a default logger, and substituing REprintf() in one call). So this is now clean and sween and a simple use is included in an example in the package we can show here too (in slightly shorter form minus the documentation header):
// this portmanteau include also defines the r_sink we use below, and which
// diverts all logging to R via the Rcpp::Rcout replacement for std::cout
#include <RcppSpdlog>

// [[Rcpp::export]]
void exampleRsink()  

    std::string logname = "fromR";                          // fix a name for this logger
    auto sp = spdlog::get(logname);                         // retrieve existing one
    if (sp == nullptr) sp = spdlog::r_sink_mt(logname);     // or create new one if needed

    // change log pattern (changed from [%H:%M:%S %z] [%n] [%^---%L---%$] )
    sp->set_pattern("[%H:%M:%S.%f] [%n] [%^%L%$] [thread %t] %v");

    sp->info("Welcome to spdlog!");
    sp->error("Some error message with arg:  ", 1);

    sp->warn("Easy padding in numbers like  :08d ", 12);
    sp->critical("Support for int:  0:d ;  hex:  0:x ;  oct:  0:o ; bin:  0:b ", 42);
    sp->info("Support for floats  :03.2f ", 1.23456);
    sp->info("Positional args are  1   0 ..", "too", "supported");
    sp->info(" :<30 ", "left aligned");

 
The NEWS entry for the first release follows.

Changes in RcppSpdlog version 0.0.1 (2020-09-08)
  • Initial release with added R/Rcpp logging sink example

The only sour grapes, if any, are over the CRAN processing. This was originally uploaded three weeks ago. As a new package, it got extra attention and some truly idiosyncratic attention to two details that were already supplied in the first uploaded version. Yet it needed two rounds of going back and forth for really no great net gain, yet wasting a week each time. I am not all that impressed by this, and not particularly pleased either, but I presume is the tax we all pay in order to enjoy the unsurpassed richness of the CRAN repository system which continues to work just flawlessly. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

16 September 2020

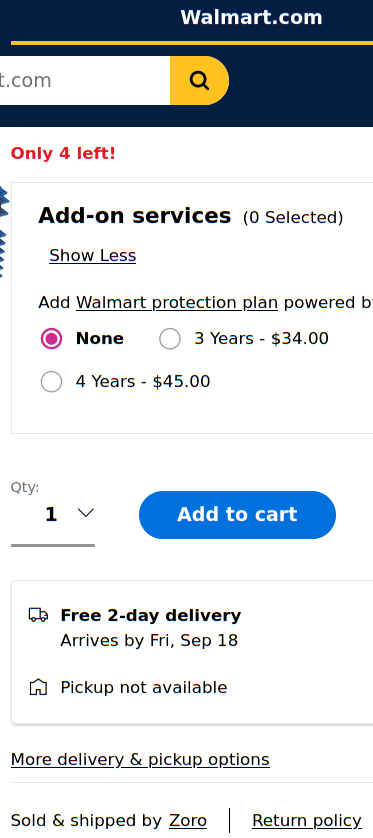
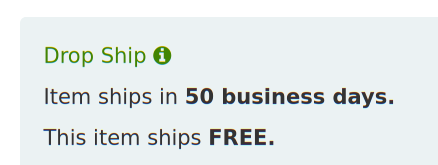
Joey Hess: comically bad shipping estimates and middlemen

My inverter has unfortunately died, and I wanted to replace it with the same model. Ideally before I lose the contents of the fridge. It's a 24v inverter, which is not at all as easy to find a replacement for as a 12v inverter would be. Somehow Walmart was the only retailer that had it available with a delivery estimate: Just 2 days. It's the second day now, with no indication they've shipped it. I noticed the "sold and shipped by Zoro", so went and found it on that website. So, the reality is it ships direct from China via container ship. As does every product from Zoro, which all show as 2 day delivery on Walmart's website. I don't think this is a pandemic thing. I think it's a trying to compete with Amazon and failing thing.
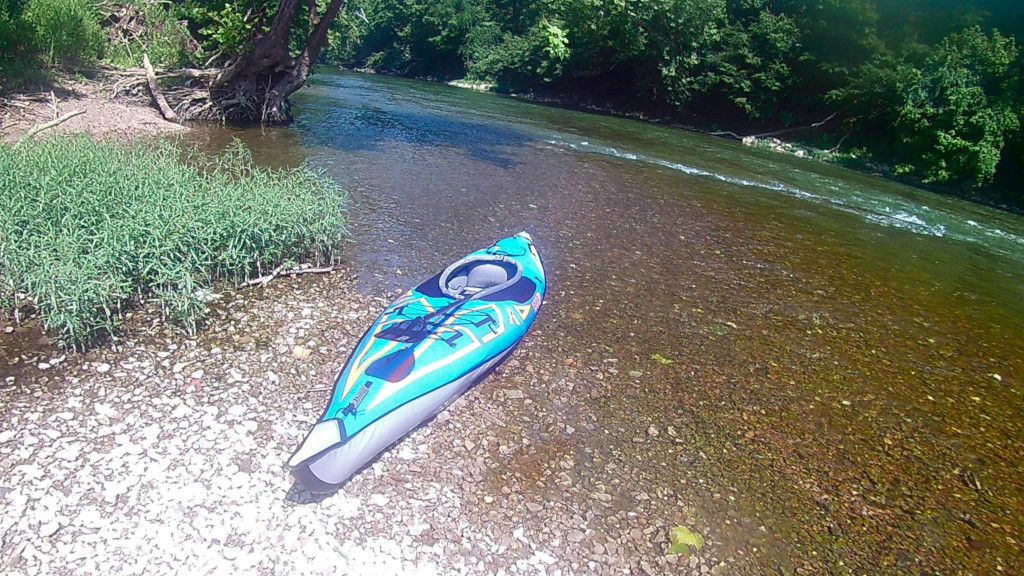
My other comically bad shipping estimate this pandemic was from Amazon though. There was a run this summer on Kayaks, because social distancing is great on the water. I found a high quality inflatable kayak. Amazon said "only 2 left in stock" and promised delivery in 1 week. One week later, it had not shipped, and they updated the delivery estimate forward 1 week. A week after that, ditto. Eventually I bought a new model from the same manufacturer, Advanced Elements. Unfortunately, that kayak exploded the second time I inflated it, due to a manufacturing defect. So I got in touch with Advanced Elements and they offered a replacement. I asked if, instead, they maybe still had any of the older model of kayak I had tried to order. They checked their warehouse, and found "the last one" in a corner somewhere. No shipping estimate was provided. It arrived in 3 days.

15 September 2020

Molly de Blanc: Actions, Inactions, and Consequences: Doctrine of Doing and Allowing W. Quinn

There are a lot of interesting and valid things to say about the philosophy and actual arguments of the Actions, Inactions, and Consequences: Doctrine of Doing and Allowing by Warren Quinn. Unfortunately for me, none of them are things I feel particularly inspired by. I m much more attracted to the many things implied in this paper. Among them are the role of social responsibility in making moral decisions. At various points in the text, Quinn makes brief comments about how we have roles that we need to fulfill for the sake of society. These roles carry with them responsibilities that may supersede our regular moral responsibilities. Examples Quinn makes include being a private life guard (and being responsible for the life of one particular person) and being a trolley driver (and your responsibility is to make sure the train doesn t kill anyone). This is part of what has led to me brushing Quinn off as another classist. Still, I am interested in the question of whether social responsibilities are more important than moral ones or whether there are times when this might occur. One of the things I maintain is that we cannot be the best versions of ourselves because we are not living in societies that value our best selves. We survive capitalism. We negotiate climate change. We make decisions to trade the ideal for the functional. For me, this frequently means I click through terms of service, agree to surveillance, and partake in the use and proliferation of oppressive technology. I also buy an iced coffee that comes in a single use plastic cup; I shop at the store with questionable labor practices; I use Facebook. But also, I don t give money to panhandlers. I see suffering and I let it pass. I do not get involved or take action in many situations because I have a pass to not. These things make society work as it is, and it makes me work within society. This is a self-perpetuating, mutually-abusive, co-dependent relationship. I must tell myself stories about how it is okay that I am preferring the status quo, that I am buying into the system, because I need to do it to survive within it and that people are relying on the system as it stands to survive, because that is how they know to survive. Among other things, I am worried about the psychic damage this causes us. When we view ourselves as social actors rather than moral actors, we tell ourselves it is okay to take non-moral actions (or in-actions); however, we carry within ourselves intuitions and feelings about what is right, just, and moral. We ignore these in order to act in our social roles. From the perspective of the individual, we re hurting ourselves and suffering for the sake of benefiting and perpetuating an caustic society. From the perspective of society, we are perpetuating something that is not just less than ideal, but actually not good because it is based on allowing suffering.[1] [1] This is for the sake of this text. I don t know if I actually feel that this is correct. My goal was to make this only 500 words, so I am going to stop here.

Russell Coker: More About the PowerEdge R710

I ve got the R710 (mentioned in my previous post [1]) online. When testing the R710 at home I noticed that sometimes the VGA monitor I was using would start flickering when in some parts of the BIOS setup, it seemed that the horizonal sync wasn t working properly. It didn t seem to be a big deal at the time. When I deployed it the KVM display that I had planned to use with it mostly didn t display anything. When the display was working the KVM keyboard wouldn t work (and would prevent a regular USB keyboard from working if they were both connected at the same time). The VGA output of the R710 also wouldn t work with my VGA->HDMI device so I couldn t get it working with my portable monitor. Fortunately the Dell front panel has a display and tiny buttons that allow configuring the IDRAC IP address, so I was able to get IDRAC going. One thing Dell really should do is allow the down button to change 0 to 9 when entering numbers, that would make it easier to enter 8.8.8.8 for the DNS server. Another thing Dell should do is make the default gateway have a default value according to the IP address and netmask of the server. When I got IDRAC going it was easy to setup a serial console, boot from a rescue USB device, create a new initrd with the driver for the MegaRAID controller, and then reboot into the server image. When I transferred the SSDs from the old server to the newer Dell server the problem I had was that the Dell drive caddies had no holes in suitable places for attaching SSDs. I ended up just pushing the SSDs in so they are hanging in mid air attached only by the SATA/SAS connectors. Plugging them in took the space from the above drive, so instead of having 2*3.5 disks I have 1*2.5 SSD and need the extra space to get my hand in. The R710 is designed for 6*3.5 disks and I m going to have trouble if I ever want to have more than 3*2.5 SSDs. Fortunately I don t think I ll need more SSDs. After booting the system I started getting alerts about a fault in one SSD, with no detail on what the fault might be. My guess is that the SSD in question is M.2 and it s in a M.2 to regular SATA adaptor which might have some problems. The data seems fine though, a BTRFS scrub found no checksum errors. I guess I ll have to buy a replacement SSD soon. I configured the system to use the nosmt kernel command line option to disable hyper-threading (which won t provide much performance benefit but which makes certain types of security attacks much easier). I ve configured BOINC to run on 6/8 CPU cores and surprisingly that didn t cause the fans to be louder than when the system was idle. It seems that a system that is designed for 6 SAS disks doesn t need a lot of cooling when run with SSDs. Update: It s a R710 not a T710. I mostly deal with Dell Tower servers and typed the wrong letter out of habit.

14 September 2020

Emmanuel Kasper: Using Debian and RHEL troubleshootings containers on Kubernetes & OpenShift

You can connect to a running pod with oc/kubectl rsh pod_name, or start a copy of a running pod with oc debug pod_name, but as best practises recommend unprivileged, slim container images, where do you get sosreport, kdump, dig and nmap for troubleshooting ? Fortunately you can start either a transient Debian troubleshooting container with:oc run troubleshooting-pod --stdin --tty --rm --image=docker.io/library/debian:busteror a Red Hat Entreprise Linux:
oc run troubleshooting-pod --stdin --tty --rm --image=registry.access.redhat.com/rhel7/rhel-tools

Russ Allbery: Review: Who Do You Serve, Who Do You Protect?

Review: Who Do You Serve, Who Do You Protect?, edited by Maya Schenwar, et al.
Editor: Maya Schenwar
Editor: Joe Macar
Editor: Alana Yu-lan Price
Publisher: Haymarket Books
Copyright: June 2016
ISBN: 1-60846-684-1
Format: Kindle
Pages: 250
Who Do You Serve, Who Do You Protect? is an anthology of essays about policing in the United States. It's divided into two sections: one that enumerates ways that police are failing to serve or protect communities, and one that describes how communities are building resistance and alternatives. Haymarket Books (a progressive press in Chicago) has made it available for free in the aftermath of the George Floyd killing and resulting protests in the United States. I'm going to be a bit unfair to this book, so let me start by admitting that the mismatch between it and the book I was looking for is not entirely its fault. My primary goal was to orient myself in the discussion on the left about alternatives to policing. I also wanted to sample something from Haymarket Books; a free book was a good way to do that. I was hoping for a collection of short introductions to current lines of thinking that I could selectively follow in longer writing, and an essay collection seemed ideal for that. What I had not realized (which was my fault for not doing simple research) is that this is a compilation of articles previously published by Truthout, a non-profit progressive journalism site, in 2014 and 2015. The essays are a mix of reporting and opinion but lean towards reporting. The earliest pieces in this book date from shortly after the police killing of Michael Brown, when racist police violence was (again) reaching national white attention. The first half of the book is therefore devoted to providing evidence of police abuse and violence. This is important to do, but it's sadly no longer as revelatory in 2020, when most of us have seen similar things on video, as it was to white America in 2014. If you live in the United States today, while you may not be aware of the specific events described here, you're unlikely to be surprised that Detroit police paid off jailhouse informants to provide false testimony ("Ring of Snitches" by Aaron Miguel Cant ), or that Chicago police routinely use excessive deadly force with no consequences ("Amid Shootings, Chicago Police Department Upholds Culture of Impunity" by Sarah Macaraeg and Alison Flowers), or that there is a long history of police abuse and degradation of pregnant women ("Your Pregnancy May Subject You to Even More Law Enforcement Violence" by Victoria Law). There are about eight essays along those lines. Unfortunately, the people who excuse or disbelieve these stories are rarely willing to seek out new evidence, let alone read a book like this. That raises the question of intended audience for the catalog of horrors part of this book. The answer to that question may also be the publication date; in 2014, the base of evidence and example for discussion had not been fully constructed. This sort of reporting is also obviously relevant in the original publication context of web-based journalism, where people may encounter these accounts individually through social media or other news coverage. In 2020, they offer reinforcement and rhetorical evidence, but I'm dubious that the people who would benefit from this knowledge will ever see it in this form. Those of us who will are already sickened, angry, and depressed. My primary interest was therefore in the second half of the book: the section on how communities are building resistance and alternatives. This is where I'm going to be somewhat unfair because the state of that conversation may have been different in 2015 than it is now in 2020. But these essays were lacking the depth of analysis that I was looking for. There is a human tendency, when one becomes aware of an obvious wrong, to simply publicize the horrible thing that is happening and expect someone to do something about it. It's obviously and egregiously wrong, so if more people knew about it, certainly it would be stopped! That has happened repeatedly with racial violence in the United States. It's also part of the common (and school-taught) understanding of the Civil Rights movement in the 1960s: activists succeeded in getting the violence on the cover of newspapers and on television, people were shocked and appalled, and the backlash against the violence created political change. Putting aside the fact that this is too simplistic of a picture of the Civil Rights era, it's abundantly clear at this point in 2020 that publicizing racist and violent policing isn't going to stop it. We're going to have to do something more than draw attention to the problem. Deciding what to do requires political and social analysis, not just of the better world that we want to see but of how our current world can become that world. There is very little in that direction in this book. Who Do You Serve, Who Do You Protect? does not answer the question of its title beyond "not us" and "white supremacy." While those answers are not exactly wrong, they're also not pushing the analysis in the direction that I wanted to read. For example (and this is a long-standing pet peeve of mine in US political writing), it would be hard to tell from most of the essays in this book that any country besides the United States exists. One essay ("Killing Africa" by William C. Anderson) talks about colonialism and draws comparisons between police violence in the United States and international treatment of African and other majority-Black countries. One essay talks about US military behavior oversees ("Beyond Homan Square" by Adam Hudson). That's about it for international perspective. Notably, there is no analysis here of what other countries might be doing better. Police violence against out-groups is not unique to the United States. No one has entirely solved this problem, but versions of this problem have been handled with far more success than here. The US has a comparatively appalling record; many countries in the world, particularly among comparable liberal democracies in Europe, are doing far better on metrics of racial oppression by agents of the government and of law enforcement violence. And yet it's common to approach these problems as if we have to develop a solution de novo, rather than ask what other countries are doing differently and if we could do some of those things. The US has some unique challenges, both historical and with the nature of endemic violence in the country, so perhaps such an analysis would turn up too many US-specific factors to copy other people's solutions. But we need to do the analysis, not give up before we start. Novel solutions can lead to novel new problems; other countries have tested, working improvements that could provide a starting framework and some map of potential pitfalls. More fundamentally, only the last two essays of this book propose solutions more complex than "stop." The authors are very clear about what the police are doing, seem less interested in why, and are nearly silent on how to change it. I suspect I am largely in political agreement with most of the authors, but obviously a substantial portion of the country (let alone its power structures) is not, and therefore nothing is changing. Part of the project of ending police violence is understanding why the violence exists, picking apart the motives and potential fracture lines in the political forces supporting the status quo, and building a strategy to change the politics. That isn't even attempted here. For example, the "who do you serve?" question of the book's title is more interesting than the essays give it credit. Police are not a monolith. Why do Black people become police officers? What are their experiences? Are there police forces in the United States that are doing better than others? What makes them different? Why do police act with violence in the moment? What set of cultural expectations, training experiences, anxieties, and fears lead to that outcome? How do we change those factors? Or, to take another tack, why are police not held accountable even when there is substantial public outrage? What political coalition supports that immunity from consequences, what are its fault lines and internal frictions, and what portions of that coalition could be broken off, pealed away, or removed from power? To whom, institutionally, are police forces accountable? What public offices can aspiring candidates run for that would give them oversight capability? This varies wildly throughout the United States; political approaches that work in large cities may not work in small towns, or with county sheriffs, or with the FBI, or with prison guards. To treat these organizations as a monolith and their motives as uniform is bad political tactics. It gives up points of leverage. I thought the best essays of this collection were the last two. "Community Groups Work to Provide Emergency Medical Alternatives, Separate from Police," by Candice Bernd, is a profile of several local emergency response systems that divert emergency calls from the police to paramedics, mental health experts, or social workers. This is an idea that's now relatively mainstream, and it seems to be finding modest success where it has been tried. It's more of a harm mitigation strategy than an attempt to deal with the root problem, but we're going to need both. The last essay, "Building Community Safety" by Ejeris Dixon, is the only essay in this book that is pushing in the direction that I was hoping to read. Dixon describes building an alternative system that can intervene in violent situations without using the police. This is fascinating and I'm glad that I read it. It's also frustrating in context because Dixon's essay should be part of a discussion. Dixon describes spending years learning de-escalation techniques, doing hard work of community discussion and collective decision-making, and making deep investment in the skills required to handle violence without calling in a dangerous outside force. I greatly admire this approach (also common in parts of the anarchist community) and the people who are willing to commit to it. But it's an immense amount of work, and as Dixon points out, that work often falls on the people who are least able to afford it. Marginalized communities, for whom the police are often dangerous, are also likely to lack both time and energy to invest in this type of skill training. And many people simply will not do this work even if they do have the resources to do it. More fundamentally, this approach conflicts somewhat with division of labor. De-escalation and social work are both professional skills that require significant time and practice to hone, and as much as I too would love to live in a world where everyone knows how to do some amount of this work, I find it hard to imagine scaling this approach without trained professionals. The point of paying someone to do this work as their job is that the money frees up their time to focus on learning those skills at a level that is difficult to do in one's free time. But once you have an organized group of professionals who do this work, you have to find a way to keep them from falling prey to the problems that plague the police, which requires understanding the origins of those problems. And that's putting aside the question of how large the residual of dangerous crime that cannot be addressed through any form of de-escalation might be, and what organization we should use to address it. Dixon's essay is great; I wouldn't change anything about it. But I wanted to see the next essay engaging with Dixon's perspective and looking for weaknesses and scaling concerns, and then the next essay that attempts to shore up those weaknesses, and yet another essay that grapples with the challenging philosophical question of a government monopoly on force and how that can and should come into play in violent crime. And then essays on grass-roots organizing in the context of police reform or abolition, and on restorative justice, and on the experience of attempting police reform from the inside, and on how to support public defenders, and on the merits and weaknesses of focusing on electing reform-minded district attorneys. Unfortunately, none of those are here. Overall, Who Do You Serve, Who Do You Protect? was a disappointment. It was free, so I suppose I got what I paid for, and I may have had a different reaction if I read it in 2015. But if you're looking for a deep discussion on the trade-offs and challenges of stopping police violence in 2020, I don't think this is the place to start. Rating: 3 out of 10

13 September 2020

Jonathan Carter: Wootbook / Tongfang laptop

Old laptop I ve been meaning to get a new laptop for a while now. My ThinkPad X250 is now 5 years old and even though it s still adequate in many ways, I tend to run out of memory especially when running a few virtual machines. It only has one memory slot, which I maxed out at 16GB shortly after I got it. Memory has been a problem in considering a new machine. Most new laptops have soldered RAM and local configurations tend to ship with 8GB RAM. Getting a new machine with only a slightly better CPU and even just the same amount of RAM as what I have in the X250 seems a bit wasteful. I was eyeing the Lenovo X13 because it s a super portable that can take up to 32GB of RAM, and it ships with an AMD Ryzen 4000 series chip which has great performance. With Lenovo s discount for Debian Developers it became even more attractive. Unfortunately that s in North America only (at least for now) so that didn t work out this time.

Enter Tongfang I ve been reading a bunch of positive reviews about the Tuxedo Pulse 14 and KDE Slimbook 14. Both look like great AMD laptops, supports up to 64GB of RAM and clearly runs Linux well. I also noticed that they look quite similar, and after some quick searches it turns out that these are made by Tongfang and that its model number is PF4NU1F. I also learned that a local retailer (Wootware) sells them as the Wootbook. I ve seen one of these before although it was an Intel-based one, but it looked like a nice machine and I was already curious about it back then. After struggling for a while to find a local laptop with a Ryzen CPU and that s nice and compact and that breaks the 16GB memory barrier, finding this one that jumped all the way to 64GB sealed the deal for me. This is the specs for the configuration I got:

This configuration cost R18 796 ( 947 / $1122). That s significantly cheaper than anything else I can get that even starts to approach these specs. So this is a cheap laptop, but you wouldn t think so by using it.
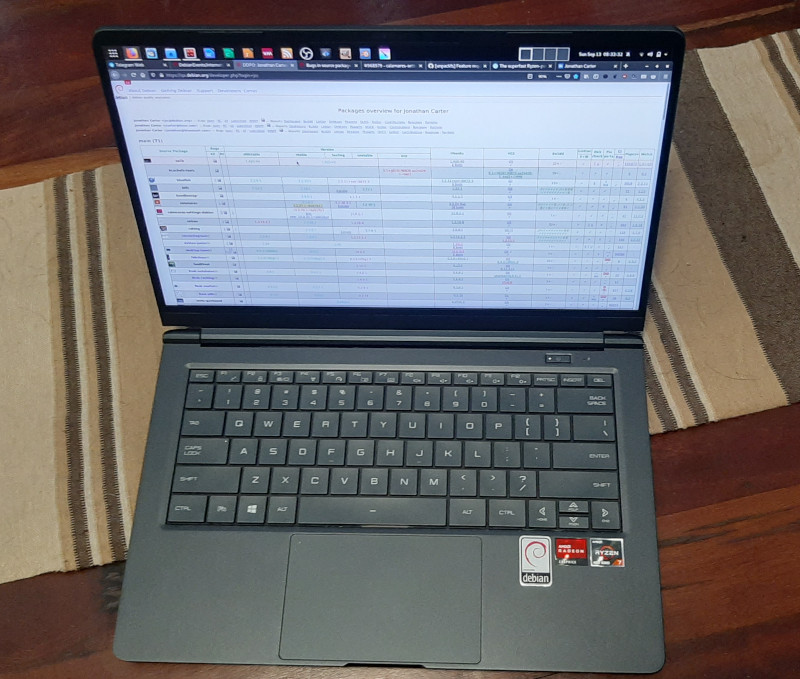
I used the Debian netinstall image to install, and installation was just another uneventful and boring Debian installation (yay!). Unfortunately it needs the firmware-iwlwifi and firmare-amd-graphics packages for the binary blobs that drives the wifi card and GPU. At least it works flawlessly and you don t need an additional non-free display driver (as is the case with NVidia GPUs). I haven t tested the graphics extensively yet, but desktop graphics performance is very snappy. This GPU also does fancy stuff like VP8/VP9 encoding/decoding, so I m curious to see how well it does next time I have to encode some videos. The wifi upgrade was nice for copying files over. My old laptop maxed out at 300Mbps, this one connects to my home network between 800-1000Mbps. At this speed I don t bother connecting via cable at home. I read on Twitter that Tuxedo Computers thinks that it s possible to bring Coreboot to this device. That would be yet another plus for this machine. I ll try to answer some of my own questions about this device that I had before, that other people in the Debian community might also have if they re interested in this device. Since many of us are familiar with the ThinkPad X200 series of laptops, I ll compare it a bit to my X250, and also a little to the X13 that I was considering before. Initially, I was a bit hesitant about the 14 form factor, since I really like the portability of the 12.5 ThinkPad. But because the screen bezel is a lot smaller, the Wootbook (that just rolls off the tongue a lot better than the PF4NU1F ) is just slightly wider than the X250. It weighs in at 1.1KG instead of the 1.38KG of the X250. It s also thinner, so even though it has a larger display, it actually feels a lot more portable. Here s a picture of my X250 on top of the Wootbook, you can see a few mm of Wootbook sticking out to the right.
Card Reader One thing that I overlooked when ordering this laptop was that it doesn t have an SD card reader. I see that some variations have them, like on this Slimbook review. It s not a deal-breaker for me, I have a USB card reader that s very light and that I ll just keep in my backpack. But if you re ordering one of these machines and have some choice, it might be something to look out for if it s something you care about. Keyboard/Touchpad On to the keyboard. This keyboard isn t quite as nice to type on as on the ThinkPad, but, it s not bad at all. I type on many different laptop keyboards and I would rank this keyboard very comfortably in the above average range. I ve been typing on it a lot over the last 3 days (including this blog post) and it started feeling natural very quickly and I m not distracted by it as much as I thought I would be transitioning from the ThinkPad or my mechanical desktop keyboard. In terms of layout, it s nice having an actual Insert button again. This is things normal users don t care about, but since I use mc (where insert selects files) this is a welcome return :). I also like that it doesn t have a Print Screen button at the bottom of my keyboard between alt and ctrl like the ThinkPad has. Unfortunately, it doesn t have dedicated pgup/pgdn buttons. I use those a lot in apps to switch between tabs. At leas the Fn button and the ctrl buttons are next to each other, so pressing those together with up and down to switch tabs isn t that horrible, but if I don t get used to it in another day or two I might do some remapping. The touchpad has en extra sensor-button on the top left corner that s used on Windows to temporarily disable the touchpad. I captured it s keyscan codes and it presses left control + keyscan code 93. The airplane mode, volume and brightness buttons work fine. I do miss the ThinkPad trackpoint. It s great especially in confined spaces, your hands don t have to move far from the keyboard for quick pointer operations and it s nice for doing something quick and accurate. I painted a bit in Krita last night, and agree with other reviewers that the touchpad could do with just a bit more resolution. I was initially disturbed when I noticed that my physical touchpad buttons were gone, but you get right-click by tapping with two fingers, and middle click with tapping 3 fingers. Not quite as efficient as having the real buttons, but it actually works ok. For the most part, this keyboard and touchpad is completely adequate. Only time will tell whether the keyboard still works fine in a few years from now, but I really have no serious complaints about it. Display The X250 had a brightness of 172 nits. That s not very bright, I think the X250 has about the dimmest display in the ThinkPad X200 range. This hasn t been a problem for me until recently, my eyes are very photo-sensitive so most of the time I use it at reduced brightness anyway, but since I ve been working from home a lot recently, it s nice to sometimes sit outside and work, especially now that it s spring time and we have some nice days. At full brightness, I can t see much on my X250 outside. The Wootbook is significantly brighter even (even at less than 50% brightness), although I couldn t find the exact specification for its brightness online. Ports The Wootbook has 3x USB type A ports and 1x USB type C port. That s already quite luxurious for a compact laptop. As I mentioned in the specs above, it also has a full-sized ethernet socket. On the new X13 (the new ThinkPad machine I was considering), you only get 2x USB type A ports and if you want ethernet, you have to buy an additional adapter that s quite expensive especially considering that it s just a cable adapter (I don t think it contains any electronics). It has one hdmi port. Initially I was a bit concerned at lack of displayport (which my X250 has), but with an adapter it s possible to convert the USB-C port to displayport and it seems like it s possible to connect up to 3 external displays without using something weird like display over usual USB3.

Overall remarks When maxing out the CPU, the fan is louder than on a ThinkPad, I definitely noticed it while compiling the zfs-dkms module. On the plus side, that happened incredibly fast. Comparing the Wootbook to my X250, the biggest downfall it has is really it s pointing device. It doesn t have a trackpad and the touchpad is ok and completely usable, but not great. I use my laptop on a desk most of the time so using an external mouse will mostly solve that. If money were no object, I would definitely choose a maxed out ThinkPad for its superior keyboard/mouse, but the X13 configured with 32GB of RAM and 128GB of SSD retails for just about double of what I paid for this machine. It doesn t seem like you can really buy the perfect laptop no matter how much money you want to spend, there s some compromise no matter what you end up choosing, but this machine packs quite a punch, especially for its price, and so far I m very happy with my purchase and the incredible performance it provides. I m also very glad that Wootware went with the gray/black colours, I prefer that by far to the white and silver variants. It s also the first laptop I ve had since 2006 that didn t come with Windows on it. The Wootbook is also comfortable/sturdy enough to carry with one hand while open. The ThinkPads are great like this and with many other brands this just feels unsafe. I don t feel as confident carrying it by it s display because it s very thin (I know, I shouldn t be doing that with the ThinkPads either, but I ve been doing that for years without a problem :) ). There s also a post on Reddit that tracks where you can buy these machines from various vendors all over the world.

Russell Coker: Setting Up a Dell T710 Server with DRAC6

I ve just got a Dell T710 server for LUV and I ve been playing with the configuration options. Here s a list of what I ve done and recommendations on how to do things. I decided not to try to write a step by step guide to doing stuff as the situation doesn t work for that. I think that a list of how things are broken and what to avoid is more useful. BIOS Firstly with a Dell server you can upgrade the BIOS from a Linux root shell. Generally when a server is deployed you won t want to upgrade the BIOS (why risk breaking something when it s working), so before deployment you probably should install the latest version. Dell provides a shell script with encoded binaries in it that you can just download and run, it s ugly but it works. The process of loading the firmware takes a long time (a few minutes) with no progress reports, so best to plug both PSUs in and leave it alone. At the end of loading the firmware a hard reboot will be performed, so upgrading your distribution while doing the install is a bad idea (Debian is designed to not lose data in this situation so it s not too bad). IDRAC IDRAC is the Integrated Dell Remote Access Controller. By default it will listen on all Ethernet ports, get an IP address via DHCP (using a different Ethernet hardware address to the interface the OS sees), and allow connections. Configuring it to be restrictive as to which ports it listens on may be a good idea (the T710 had 4 ports built in so having one reserved for management is usually OK). You need to configure a username and password for IDRAC that has administrative access in the BIOS configuration. Web Interface By default IDRAC will run a web server on the IP address it gets from DHCP, you can connect to that from any web browser that allows ignoring invalid SSL keys. Then you can use the username and password configured in the BIOS to login. IDRAC 6 on the PowerEdge T710 recommends IE 6. To get a ssl cert that matches the name you want to use (and doesn t give browser errors) you have to generate a CSR (Certificate Signing Request) on the DRAC, the only field that matters is the CN (Common Name), the rest have to be something that Letsencrypt will accept. Certbot has the option --config-dir /etc/letsencrypt-drac to specify an alternate config directory, the SSL key for DRAC should be entirely separate from the SSL key for other stuff. Then use the --csr option to specify the path of the CSR file. When you run letsencrypt the file name of the output file you want will be in the format *_chain.pem . You then have to upload that to IDRAC to have it used. This is a major pain for the lifetime of letsencrypt certificates. Hopefully a more recent version of IDRAC has Certbot built in. When you access RAC via ssh (see below) you can run the command racadm sslcsrgen to generate a CSR that can be used by certbot. So it s probably possible to write expect scripts to get that CSR, run certbot, and then put the ssl certificate back. I don t expect to use IDRAC often enough to make it worth the effort (I can tell my browser to ignore an outdated certificate), but if I had dozens of Dells I d script it. SSH The web interface allows configuring ssh access which I strongly recommend doing. You can configure ssh access via password or via ssh public key. For ssh access set TERM=vt100 on the host to enable backspace as ^H. Something like TERM=vt100 ssh root@drac . Note that changing certain other settings in IDRAC such as enabling Smartcard support will disable ssh access. There is a limit to the number of open sessions for managing IDRAC, when you ssh to the IDRAC you can run racadm getssninfo to get a list of sessions and racadm closessn -i NUM to close a session. The closessn command takes a -a option to close all sessions but that just gives an error saying that you can t close your own session because of programmer stupidity. The IDRAC web interface also has an option to close sessions. If you get to the limits of both ssh and web sessions due to network issues then you presumably have a problem. I couldn t find any documentation on how the ssh host key is generated. I Googled for the key fingerprint and didn t get a match so there s a reasonable chance that it s unique to the server (please comment if you know more about this). Don t Use Graphical Console The T710 is an older server and runs IDRAC6 (IDRAC9 is the current version). The Java based graphical console access doesn t work with recent versions of Java. The Debian package icedtea-netx has has the javaws command for running the .jnlp command for the console, by default the web browser won t run this, you download the .jnlp file and pass that as the first parameter to the javaws program which then downloads a bunch of Java classes from the IDRAC to run. One error I got with Java 11 was Exception in thread Timer-0 java.util.ServiceConfigurationError: java.nio.charset.spi.CharsetProvider: Provider sun.nio.cs.ext.ExtendedCharsets could not be instantiated , Google didn t turn up any solutions to this. Java 8 didn t have that problem but had a connection failed error that some people reported as being related to the SSL key, but replacing the SSL key for the web server didn t help. The suggestion of running a VM with an old web browser to access IDRAC didn t appeal. So I gave up on this. Presumably a Windows VM running IE6 would work OK for this. Serial Console Fortunately IDRAC supports a serial console. Here s a page summarising Serial console setup for DRAC [1]. Once you have done that put console=tty0 console=ttyS1,115200n8 on the kernel command line and Linux will send the console output to the virtual serial port. To access the serial console from remote you can ssh in and run the RAC command console com2 (there is no option for using a different com port). The serial port seems to be unavailable through the web interface. If I was supporting many Dell systems I d probably setup a ssh to JavaScript gateway to provide a web based console access. It s disappointing that Dell didn t include this. If you disconnect from an active ssh serial console then the RAC might keep the port locked, then any future attempts to connect to it will give the following error:
/admin1-> console com2
console: Serial Device 2 is currently in use
So far the only way I ve discovered to get console access again after that is the command racadm racreset . If anyone knows of a better way please let me know. As an aside having racreset being so close to racresetcfg (which resets the configuration to default and requires a hard reboot to configure it again) seems like a really bad idea. Host Based Management
deb http://linux.dell.com/repo/community/ubuntu xenial openmanage
The above apt sources.list line allows installing Dell management utilities (Xenial is old but they work on Debian/Buster). Probably the packages srvadmin-storageservices-cli and srvadmin-omacore will drag in enough dependencies to get it going. Here are some useful commands:
# show hardware event log
omreport system esmlog
# show hardware alert log
omreport system alertlog
# give summary of system information
omreport system summary
# show versions of firmware that can be updated
omreport system version
# get chassis temp
omreport chassis temps
# show physical disk details on controller 0
omreport storage pdisk controller=0
RAID Control The RAID controller is known as PERC (PowerEdge Raid Controller), the Dell web site has an rpm package of the perccli tool to manage the RAID from Linux. This is statically linked and appears to have different versions of libraries used to make it. The command perccli show gives an overview of the configuration, but the command perccli /c0 show to give detailed information on controller 0 SEGVs and the kernel logs a vsyscall attempted with vsyscall=none message. Here s an overview of the vsyscall enmulation issue [2]. Basically I could add vsyscall=emulate to the kernel command line and slightly reduce security for the system to allow system calls from perccli that are called from old libc code to work, or I could run code from a dubious source as root. Some versions of IDRAC have a racadm raid command that can be run from a ssh session to perform RAID administration remotely, mine doesn t have that. As an aside the help for the RAC system doesn t list all commands and the Dell documentation is difficult to find so blog posts from other sysadmins is the best source of information. I have configured IDRAC to have all of the BIOS output go to the virtual serial console over ssh so I can see the BIOS prompt me for PERC administration but it didn t accept my key presses when I tried to do so. In any case this requires downtime and I d like to be able to change hard drives without rebooting. I found vsyscall_trace on Github [3], it uses the ptrace interface to emulate vsyscall on a per process basis. You just run vsyscall_trace perccli and it works! Thanks Geoffrey Thomas for writing this! Here are some perccli commands:
# show overview
perccli show
# help on adding a vd (RAID)
perccli /c0 add help
# show controller 0 details
perccli /c0 show
# add a vd (RAID) of level RAID0 (r0) with the drive 32:0 (enclosure:slot from above command)
perccli /c0 add vd r0 drives=32:0
When a disk is added to a PERC controller about 525MB of space is used at the end for RAID metadata. So when you create a RAID-0 with a single device as in the above example all disk data is preserved by default except for the last 525MB. I have tested this by running a BTRFS scrub on a disk from another system after making it into a RAID-0 on the PERC.

12 September 2020

Ryan Kavanagh: Configuring OpenIKED VPNs for Road Warriors

A few weeks ago I configured a road warrior VPN setup. The remote end is on a VPS running OpenBSD and OpenIKED, the VPN is an IKEv2 VPN using x509 authentication, and the local end is StrongSwan. I also configured an IKEv2 VPN between my VPSs. Here are the notes for how to do so. In all cases, to use x509 authentication, you will need to generate a bunch of certificates and keys: Fortunately, OpenIKED provides the ikectl utility to help you do so. Before going any further, you might find it useful to edit /etc/ssl/ikeca.cnf to set some reasonable defaults for your certificates. Begin by creating and installing a CA certificate:
# ikectl ca vpn create
# ikectl ca vpn install
For simplicity, I am going to assume that the you are managing your CA on the same host as one of the hosts that you want to configure for the VPN. If not, see the bit about exporting certificates at the beginning of the section on persistent host-host VPNs. Create and install a key/certificate pair for your server. Suppose for example your first server is called server1.example.org:
# ikectl ca vpn certificate server1.example.org create
# ikectl ca vpn certificate server1.example.org install

Persistent host-host VPNs For each other server that you want to use, you need to also create a key/certificate pair on the same host as the CA certificate, and then copy them over to the other server. Assuming the other server is called server2.example.org:
# ikectl ca vpn certificate server2.example.org create
# ikectl ca vpn certificate server2.example.org export
This last command will produce a tarball server2.example.org.tgz. Copy it over to server2.example.org and install it:
# tar -C /etc/iked -xzpvf server2.example.org.tgz
Next, it is time to configure iked. To do so, you will need to find some information about the certificates you just generated. On the host with the CA, run
$ cat /etc/ssl/vpn/index.txt
V       210825142056Z           01      unknown /C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org
V       210825142208Z           02      unknown /C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org
Pick one of the two hosts to play the active role (in this case, server1.example.org). Using the information you gleaned from index.txt, add the following to /etc/iked.conf, filling in the srcid and dstid fields appropriately.
ikev2 'server1_server2_active' active esp from server1.example.org to server2.example.org \
	local server1.example.org peer server2.example.org \
	srcid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org' \
	dstid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org'
On the other host, add the following to /etc/iked.conf
ikev2 'server2_server1_passive' passive esp from server2.example.org to server1.example.org \
	local server2.example.org peer server1.example.org \
	srcid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org' \
	dstid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org'
Note that the names 'server1_server2_active' and 'server2_server1_passive' in the two stanzas do not matter and can be omitted. Reload iked on both hosts:
# ikectl reload
If everything worked out, you should see the negotiated security associations (SAs) in the output of
# ikectl show sa
On OpenBSD, you should also see some output on success or errors in the file /var/log/daemon.

For a road warrior Add the following to /etc/iked.conf on the remote end:
ikev2 'responder_x509' passive esp \
	from 0.0.0.0/0 to 10.0.1.0/24 \
	local server1.example.org peer any \
	srcid server1.example.org \
	config address 10.0.1.0/24 \
	config name-server 10.0.1.1 \
	tag "ROADW"
Configure or omit the address range and the name-server configurations to suit your needs. See iked.conf(5) for details. Reload iked:
# ikectl reload
If you are on OpenBSD and want the remote end to have an IP address, add the following to /etc/hostname.vether0, again configuring the address to suit your needs:
inet 10.0.1.1 255.255.255.0
Put the interface up:
# ifconfig vether0 up
Now create a client certificate for authentication. In my case, my road-warrior client was client.example.org:
# ikectl ca vpn certificate client.example.org create
# ikectl ca vpn certificate client.example.org export
Copy client.example.org.tgz to client and run
# tar -C /etc/ipsec.d/ -xzf client.example.org.tgz -- \
	./private/client.example.org.key \
	./certs/client.example.org.crt ./ca/ca.crt
Install StrongSwan and add the following to /etc/ipsec.conf, configuring appropriately:
ca example.org
  cacert=ca.crt
  auto=add
conn server1
  keyexchange=ikev2
  right=server1.example.org
  rightid=%server1.example.org
  rightsubnet=0.0.0.0/0
  rightauth=pubkey
  leftsourceip=%config
  leftauth=pubkey
  leftcert=client.example.org.crt
  auto=route
Add the following to /etc/ipsec.secrets:
# space is important
server1.example.org : RSA client.example.org.key
Restart StrongSwan, put the connection up, and check its status:
# ipsec restart
# ipsec up server1
# ipsec status
That should be it. Sources:

Ryan Kavanagh: Configuring OpenIKED VPNs for StrongSwan Clients

A few weeks ago I configured a road warrior VPN setup. The remote end is on a VPS running OpenBSD and OpenIKED, the VPN is an IKEv2 VPN using x509 authentication, and the local end is StrongSwan. I also configured an IKEv2 VPN between my VPSs. Here are the notes for how to do so. In all cases, to use x509 authentication, you will need to generate a bunch of certificates and keys: Fortunately, OpenIKED provides the ikectl utility to help you do so. Before going any further, you might find it useful to edit /etc/ssl/ikeca.cnf to set some reasonable defaults for your certificates. Begin by creating and installing a CA certificate:
# ikectl ca vpn create
# ikectl ca vpn install
For simplicity, I am going to assume that the you are managing your CA on the same host as one of the hosts that you want to configure for the VPN. If not, see the bit about exporting certificates at the beginning of the section on persistent host-host VPNs. Create and install a key/certificate pair for your server. Suppose for example your first server is called server1.example.org:
# ikectl ca vpn certificate server1.example.org create
# ikectl ca vpn certificate server1.example.org install

Persistent host-host VPNs For each other server that you want to use, you need to also create a key/certificate pair on the same host as the CA certificate, and then copy them over to the other server. Assuming the other server is called server2.example.org:
# ikectl ca vpn certificate server2.example.org create
# ikectl ca vpn certificate server2.example.org export
This last command will produce a tarball server2.example.org.tgz. Copy it over to server2.example.org and install it:
# tar -C /etc/iked -xzpvf server2.example.org.tgz
Next, it is time to configure iked. To do so, you will need to find some information about the certificates you just generated. On the host with the CA, run
$ cat /etc/ssl/vpn/index.txt
V       210825142056Z           01      unknown /C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org
V       210825142208Z           02      unknown /C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org
Pick one of the two hosts to play the active role (in this case, server1.example.org). Using the information you gleaned from index.txt, add the following to /etc/iked.conf, filling in the srcid and dstid fields appropriately.
ikev2 'server1_server2_active' active esp from server1.example.org to server2.example.org \
	local server1.example.org peer server2.example.org \
	srcid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org' \
	dstid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org'
On the other host, add the following to /etc/iked.conf
ikev2 'server2_server1_passive' passive esp from server2.example.org to server1.example.org \
	local server2.example.org peer server1.example.org \
	srcid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org' \
	dstid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org'
Note that the names 'server1_server2_active' and 'server2_server1_passive' in the two stanzas do not matter and can be omitted. Reload iked on both hosts:
# ikectl reload
If everything worked out, you should see the negotiated security associations (SAs) in the output of
# ikectl show sa
On OpenBSD, you should also see some output on success or errors in the file /var/log/daemon.

For a road warrior Add the following to /etc/iked.conf on the remote end:
ikev2 'responder_x509' passive esp \
	from 0.0.0.0/0 to 10.0.1.0/24 \
	local server1.example.org peer any \
	srcid server1.example.org \
	config address 10.0.1.0/24 \
	config name-server 10.0.1.1 \
	tag "ROADW"
Configure or omit the address range and the name-server configurations to suit your needs. See iked.conf(5) for details. Reload iked:
# ikectl reload
If you are on OpenBSD and want the remote end to have an IP address, add the following to /etc/hostname.vether0, again configuring the address to suit your needs:
inet 10.0.1.1 255.255.255.0
Put the interface up:
# ifconfig vether0 up
Now create a client certificate for authentication. In my case, my road-warrior client was client.example.org:
# ikectl ca vpn certificate client.example.org create
# ikectl ca vpn certificate client.example.org export
Copy client.example.org.tgz to client and run
# tar -C /etc/ipsec.d/ -xzf client.example.org.tgz -- \
	./private/client.example.org.key \
	./certs/client.example.org.crt ./ca/ca.crt
Install StrongSwan and add the following to /etc/ipsec.conf, configuring appropriately:
ca example.org
  cacert=ca.crt
  auto=add
conn server1
  keyexchange=ikev2
  right=server1.example.org
  rightid=%server1.example.org
  rightsubnet=0.0.0.0/0
  rightauth=pubkey
  leftsourceip=%config
  leftauth=pubkey
  leftcert=client.example.org.crt
  auto=route
Add the following to /etc/ipsec.secrets:
# space is important
server1.example.org : RSA client.example.org.key
Restart StrongSwan, put the connection up, and check its status:
# ipsec restart
# ipsec up server1
# ipsec status
That should be it. Sources:

11 September 2020

Louis-Philippe V ronneau: Hire me!

I'm happy to announce I handed out my Master's Thesis last Monday. I'm not publishing the final copy just yet1, as it still needs to go through the approval committee. If everything goes well, I should have my Master of Economics diploma before Christmas! It sure hasn't been easy, and although I regret nothing, I'm also happy to be done with university. Looking for a job What an odd time to be looking for a job, right? Turns out for the first time in 12 years, I don't have an employer. It's oddly freeing, but also a little scary. I'm certainly not bitter about it though and it's nice to have some time on my hands to work on various projects and read things other than academic papers. Look out for my next blog posts on using the NeTV2 as an OSHW HDMI capture card, on hacking at security tokens and much more! I'm not looking for anything long term (I'm hoping to teach Economics again next Winter), but for the next few months, my calendar is wide open. For the last 6 years, I worked as Linux system administrator, mostly using a LAMP stack in conjunction with Puppet, Shell and Python. Although I'm most comfortable with Puppet, I also have decent experience with Ansible, thanks to my work in the DebConf Videoteam. I'm not the most seasoned Debian Developer, but I have some experience packaging Python applications and libraries. Although I'm no expert at it, lately I've also been working on Clojure packages, as I'm trying to get Puppet 6 in Debian in time for the Bullseye freeze. At the rate it's going though, I doubt we're going to make it... If your company depends on Puppet and cares about having a version in Debian 11 that is maintained (Puppet 5 is EOL in November 2020), I'm your guy! Oh, and I guess I'm a soon-to-be Master of Economics specialising in Free and Open Source Software business models and incentives theory. Not sure I'll ever get paid putting that in application, but hey, who knows. If any of that resonates with you, contact me and let's have a chat! I promise I don't bite :)

  1. The title of the thesis is What are the incentive structures of Free Software? An economic analysis of Free Software's specific development model. Once the final copy is approved, I'll be sure to write a longer blog post about my findings here.

9 September 2020

Reproducible Builds: Reproducible Builds in August 2020

Welcome to the August 2020 report from the Reproducible Builds project. In our monthly reports, we summarise the things that we have been up to over the past month. The motivation behind the Reproducible Builds effort is to ensure no flaws have been introduced from the original free software source code to the pre-compiled binaries we install on our systems. If you re interested in contributing to the project, please visit our main website.


This month, Jennifer Helsby launched a new reproduciblewheels.com website to address the lack of reproducibility of Python wheels. To quote Jennifer s accompanying explanatory blog post:
One hiccup we ve encountered in SecureDrop development is that not all Python wheels can be built reproducibly. We ship multiple (Python) projects in Debian packages, with Python dependencies included in those packages as wheels. In order for our Debian packages to be reproducible, we need that wheel build process to also be reproducible
Parallel to this, transparencylog.com was also launched, a service that verifies the contents of URLs against a publicly recorded cryptographic log. It keeps an append-only log of the cryptographic digests of all URLs it has seen. (GitHub repo) On 18th September, Bernhard M. Wiedemann will give a presentation in German, titled Wie reproducible builds Software sicherer machen ( How reproducible builds make software more secure ) at the Internet Security Digital Days 2020 conference.

Reproducible builds at DebConf20 There were a number of talks at the recent online-only DebConf20 conference on the topic of reproducible builds. Holger gave a talk titled Reproducing Bullseye in practice , focusing on independently verifying that the binaries distributed from ftp.debian.org are made from their claimed sources. It also served as a general update on the status of reproducible builds within Debian. The video (145 MB) and slides are available. There were also a number of other talks that involved Reproducible Builds too. For example, the Malayalam language mini-conference had a talk titled , ? ( I want to join Debian, what should I do? ) presented by Praveen Arimbrathodiyil, the Clojure Packaging Team BoF session led by Elana Hashman, as well as Where is Salsa CI right now? that was on the topic of Salsa, the collaborative development server that Debian uses to provide the necessary tools for package maintainers, packaging teams and so on. Jonathan Bustillos (Jathan) also gave a talk in Spanish titled Un camino verificable desde el origen hasta el binario ( A verifiable path from source to binary ). (Video, 88MB)

Development work After many years of development work, the compiler for the Rust programming language now generates reproducible binary code. This generated some general discussion on Reddit on the topic of reproducibility in general. Paul Spooren posted a request for comments to OpenWrt s openwrt-devel mailing list asking for clarification on when to raise the PKG_RELEASE identifier of a package. This is needed in order to successfully perform rebuilds in a reproducible builds context. In openSUSE, Bernhard M. Wiedemann published his monthly Reproducible Builds status update. Chris Lamb provided some comments and pointers on an upstream issue regarding the reproducibility of a Snap / SquashFS archive file. [ ]

Debian Holger Levsen identified that a large number of Debian .buildinfo build certificates have been tainted on the official Debian build servers, as these environments have files underneath the /usr/local/sbin directory [ ]. He also filed against bug for debrebuild after spotting that it can fail to download packages from snapshot.debian.org [ ]. This month, several issues were uncovered (or assisted) due to the efforts of reproducible builds. For instance, Debian bug #968710 was filed by Simon McVittie, which describes a problem with detached debug symbol files (required to generate a traceback) that is unlikely to have been discovered without reproducible builds. In addition, Jelmer Vernooij called attention that the new Debian Janitor tool is using the property of reproducibility (as well as diffoscope when applying archive-wide changes to Debian:
New merge proposals also include a link to the diffoscope diff between a vanilla build and the build with changes. Unfortunately these can be a bit noisy for packages that are not reproducible yet, due to the difference in build environment between the two builds. [ ]
56 reviews of Debian packages were added, 38 were updated and 24 were removed this month adding to our knowledge about identified issues. Specifically, Chris Lamb added and categorised the nondeterministic_version_generated_by_python_param and the lessc_nondeterministic_keys toolchain issues. [ ][ ] Holger Levsen sponsored Lukas Puehringer s upload of the python-securesystemslib pacage, which is a dependency of in-toto, a framework to secure the integrity of software supply chains. [ ] Lastly, Chris Lamb further refined his merge request against the debian-installer component to allow all arguments from sources.list files (such as [check-valid-until=no]) in order that we can test the reproducibility of the installer images on the Reproducible Builds own testing infrastructure and sent a ping to the team that maintains that code.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of these patches, including:

diffoscope diffoscope is our in-depth and content-aware diff utility that can not only locate and diagnose reproducibility issues, it provides human-readable diffs of all kinds. In August, Chris Lamb made the following changes to diffoscope, including preparing and uploading versions 155, 156, 157 and 158 to Debian:
  • New features:
    • Support extracting data of PGP signed data. (#214)
    • Try files named .pgp against pgpdump(1) to determine whether they are Pretty Good Privacy (PGP) files. (#211)
    • Support multiple options for all file extension matching. [ ]
  • Bug fixes:
    • Don t raise an exception when we encounter XML files with <!ENTITY> declarations inside the Document Type Definition (DTD), or when a DTD or entity references an external resource. (#212)
    • pgpdump(1) can successfully parse some binary files, so check that the parsed output contains something sensible before accepting it. [ ]
    • Temporarily drop gnumeric from the Debian build-dependencies as it has been removed from the testing distribution. (#968742)
    • Correctly use fallback_recognises to prevent matching .xsb binary XML files.
    • Correct identify signed PGP files as file(1) returns data . (#211)
  • Logging improvements:
    • Emit a message when ppudump version does not match our file header. [ ]
    • Don t use Python s repr(object) output in Calling external command messages. [ ]
    • Include the filename in the not identified by any comparator message. [ ]
  • Codebase improvements:
    • Bump Python requirement from 3.6 to 3.7. Most distributions are either shipping with Python 3.5 or 3.7, so supporting 3.6 is not only somewhat unnecessary but also cumbersome to test locally. [ ]
    • Drop some unused imports [ ], drop an unnecessary dictionary comprehensions [ ] and some unnecessary control flow [ ].
    • Correct typo of output in a comment. [ ]
  • Release process:
    • Move generation of debian/tests/control to an external script. [ ]
    • Add some URLs for the site that will appear on PyPI.org. [ ]
    • Update author and author email in setup.py for PyPI.org and similar. [ ]
  • Testsuite improvements:
    • Update PPU tests for compatibility with Free Pascal versions 3.2.0 or greater. (#968124)
    • Mark that our identification test for .ppu files requires ppudump version 3.2.0 or higher. [ ]
    • Add an assert_diff helper that loads and compares a fixture output. [ ][ ][ ][ ]
  • Misc:
In addition, Mattia Rizzolo documented in setup.py that diffoscope works with Python version 3.8 [ ] and Frazer Clews applied some Pylint suggestions [ ] and removed some deprecated methods [ ].

Website This month, Chris Lamb updated the main Reproducible Builds website and documentation to:
  • Clarify & fix a few entries on the who page [ ][ ] and ensure that images do not get to large on some viewports [ ].
  • Clarify use of a pronoun re. Conservancy. [ ]
  • Use View all our monthly reports over View all monthly reports . [ ]
  • Move a is a suffix out of the link target on the SOURCE_DATE_EPOCH age. [ ]
In addition, Javier Jard n added the freedesktop-sdk project [ ] and Kushal Das added SecureDrop project [ ] to our projects page. Lastly, Michael P hn added internationalisation and translation support with help from Hans-Christoph Steiner [ ].

Testing framework The Reproducible Builds project operate a Jenkins-based testing framework to power tests.reproducible-builds.org. This month, Holger Levsen made the following changes:
  • System health checks:
    • Improve explanation how the status and scores are calculated. [ ][ ]
    • Update and condense view of detected issues. [ ][ ]
    • Query the canonical configuration file to determine whether a job is disabled instead of duplicating/hardcoding this. [ ]
    • Detect several problems when updating the status of reporting-oriented metapackage sets. [ ]
    • Detect when diffoscope is not installable [ ] and failures in DNS resolution [ ].
  • Debian:
    • Update the URL to the Debian security team bug tracker s Git repository. [ ]
    • Reschedule the unstable and bullseye distributions often for the arm64 architecture. [ ]
    • Schedule buster less often for armhf. [ ][ ][ ]
    • Force the build of certain packages in the work-in-progress package rebuilder. [ ][ ]
    • Only update the stretch and buster base build images when necessary. [ ]
  • Other distributions:
    • For F-Droid, trigger jobs by commits, not by a timer. [ ]
    • Disable the Archlinux HTML page generation job as it has never worked. [ ]
    • Disable the alternative OpenWrt rebuilder jobs. [ ]
  • Misc;
Many other changes were made too, including:
  • Chris Lamb:
    • Use <pre> HTML tags when dumping fixed-width debugging data in the self-serve package scheduler. [ ]
  • Mattia Rizzolo:
  • Vagrant Cascadian:
    • Mark that the u-boot Universal Boot Loader should not build architecture independent packages on the arm64 architecture anymore. [ ]
Finally, build node maintenance was performed by Holger Levsen [ ], Mattia Rizzolo [ ][ ] and Vagrant Cascadian [ ][ ][ ][ ]

Mailing list On our mailing list this month, Leo Wandersleb sent a message to the list after he was wondering how to expand his WalletScrutiny.com project (which aims to improve the security of Bitcoin wallets) from Android wallets to also monitor Linux wallets as well:
If you think you know how to spread the word about reproducibility in the context of Bitcoin wallets through WalletScrutiny, your contributions are highly welcome on this PR [ ]
Julien Lepiller posted to the list linking to a blog post by Tavis Ormandy titled You don t need reproducible builds. Morten Linderud (foxboron) responded with a clear rebuttal that Tavis was only considering the narrow use-case of proprietary vendors and closed-source software. He additionally noted that the criticism that reproducible builds cannot prevent against backdoors being deliberately introduced into the upstream source ( bugdoors ) are decidedly (and deliberately) outside the scope of reproducible builds to begin with. Chris Lamb included the Reproducible Builds mailing list in a wider discussion regarding a tentative proposal to include .buildinfo files in .deb packages, adding his remarks regarding requiring a custom tool in order to determine whether generated build artifacts are identical in a reproducible context. [ ] Jonathan Bustillos (Jathan) posted a quick email to the list requesting whether there was a list of To do tasks in Reproducible Builds. Lastly, Chris Lamb responded at length to a query regarding the status of reproducible builds for Debian ISO or installation images. He noted that most of the technical work has been performed but there are at least four issues until they can be generally advertised as such . He pointed that the privacy-oriented Tails operation system, which is based directly on Debian, has had reproducible builds for a number of years now. [ ]

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Next.

Previous.