Search Results: "ron"

23 May 2022

Arturo Borrero Gonz lez: Toolforge Jobs Framework

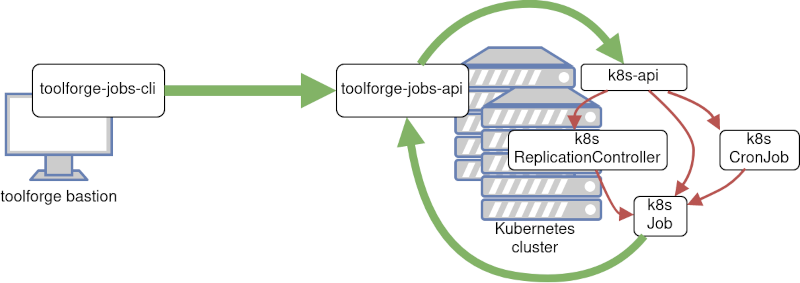
Toolforge jobs framework diagram This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez. This post continues the discussion of Toolforge updates as described in a previous post. Every non-trivial task performed in Toolforge (like executing a script or running a bot) should be dispatched to a job scheduling backend, which ensures that the job is run in a suitable place with sufficient resources. Jobs can be scheduled synchronously or asynchronously, continuously, or simply executed once. The basic principle of running jobs is fairly straightforward: So far, if a tool developer wanted to work with jobs, the Toolforge Grid Engine backend was the only suitable choice. This is despite the fact that Kubernetes supports this kind of workload natively. The truth is that we never prepared our Kubernetes environment to work with jobs. Luckily that has changed.

We no longer want to run Grid Engine In a previous blog post we shared information about our desired future for Grid Engine in Toolforge. Our intention is to discontinue our usage of this technology.

Convenient way of running jobs on Toolforge Kubernetes Some advanced Toolforge users really wanted to use Kubernetes. They were aware of the lack of abstractions or helpers, so they were forced to use the raw Kubernetes API. Eventually, they figured everything out and managed to succeed. The result of this move was in the form of [docs on Wikitech][raws] and a few dozen jobs running on Kubernetes for the first time. We were aware of this, and this initiative was much in sync with our ultimate goal: to promote Kubernetes over Grid Engine. We rolled up our sleeves and started thinking of a way to abstract and make it easy to run jobs without having to deal with lots of YAML and the raw Kubernetes API. There is a precedent: the webservice command does exactly that. It hides all the details behind a simple command line interface to start/stop a web app running on Kubernetes. However, we wanted to go even further, be more flexible and prepare ourselves for more situations in the future: we decided to create a complete new REST API to wrap the jobs functionality in Toolforge Kubernetes. The Toolforge Jobs Framework was born.

Toolforge Jobs Framework components The new framework is a small collection of components. As of this writing, we have three:
  • The REST API responsible for creating/deleting/listing jobs on the Kubernetes system.
  • A command line interface to interact with the REST API above.
  • An emailer to notify users about their jobs activity in the Kubernetes system.
Toolforge jobs framework diagram There were a couple of challenges that weren t trivial to solve. The authentication and authorization against the Kubernetes API was one of them. The other was deciding on the semantics of the new REST API itself. If you are curious, we invite you to take a look at the documentation we have in wikitech.

Open beta phase Once we gained some confidence with the new framework, in July 2021 we decided to start a beta phase. We suggested some advanced Toolforge users try out the new framework. We tracked this phase in Phabricator, where our collaborators quickly started reporting some early bugs, helping each other, and creating new feature requests. Moreover, when we launched the Grid Engine migration from Debian 9 Stretch to Debian 10 Buster we took a step forward and started promoting the new jobs framework as a viable replacement for the grid. Some official documentation pages were created on wikitech as well. As of this writing the framework continues in beta phase. We have solved basically all of the most important bugs, and we already started thinking on how to address the few feature requests that are missing. We haven t yet established yet the criteria for leaving the beta phase, but it would be good to have:
  • Critical bugs fixed and most feature requests addressed (or at least somehow planned).
  • Proper automated test coverage. We can do better on testing the different software components to ensure they are as bug free as possible. This also would make sure that contributing changes is easy.
  • REST API swagger integration.
  • Deployment automation. Deploying the REST API and the emailer is tedious. This is tracked in Phabricator.
  • Documentation, documentation, documentation.

Limitations One of the limitations we bear in mind since early on in the development process of this framework was the support for mixing different programming languages or runtime environments in the same job. Solving this limitation is currently one of the WMCS team priorities, because this is one of the key workflows that was available on Grid Engine. The moment we address it, the framework adoption will grow, and it will pretty much enable the same workflows as in the grid, if not more advanced and featureful. Stay tuned for more upcoming blog posts with additional information about Toolforge. This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez.

22 May 2022

Sergio Talens-Oliag: New Blog

Welcome to my new Blog for Technical Stuff. For a long time I was planning to start publishing technical articles again but to do it I wanted to replace my old blog based on ikiwiki by something more modern. I ve used Jekyll with GitLab Pages to build the Intranet of the ITI and to generate internal documentation sites on Agile Content, but, as happened with ikiwiki, I felt that things were kind of slow and not as easy to maintain as I would like. So on Kyso (the Company I work for right now) I switched to Hugo as the Static Site Generator (I still use GitLab Pages to automate the deployment, though), but the contents are written using the Markdown format, while my personal preference is the Asciidoc format. One thing I liked about Jekyll was that it was possible to use Asciidoctor to generate the HTML simply by using the Jekyll Asciidoc plugin (I even configured my site to generate PDF documents from .adoc files using the Asciidoctor PDF converter) and, luckily for me, that is also possible with Hugo, so that is what I plan to use on this blog, in fact this post is written in .adoc. My plan is to start publishing articles about things I m working on to keep them documented for myself and maybe be useful to someone else. The general intention is to write about Container Orchestration (mainly Kubernetes), CI/CD tools (currently I m using GitLab CE for that), System Administration (with Debian GNU/Linux as my preferred OS) and that sort of things. My next post will be about how I build, publish and update the Blog, but probably I will not finish it until next week, once the site is fully operational and the publishing system is tested.
Spoiler Alert: This is a personal site, so I m using Gitea to host the code instead of GitLab. To handle the deployment I ve configured json2file-go to save the data sent by the hook calls and process it asynchronously using inotify-tools. When a new file is detected a script parses the JSON file using jq and builds and updates the site if appropriate.

Ulrike Uhlig: How do kids conceive the internet? - part 3

I received some feedback on the first part of interviews about the internet with children that I d like to share publicly here. Thank you! Your thoughts and experiences are important to me! In the first interview round there was this French girl.
Asked what she would change if she could, the 9 year old girl advocated for a global usage limit of the internet in order to protect the human brain. Also, she said, her parents spend way too much time on their phones and people should rather spend more time with their children.
To this bit, one person reacted saying that they first laughed when reading her proposal, but then felt extremely touched by it. Another person reacted to the same bit of text:
That s just brilliant. We spend so much time worrying about how the internet will affect children while overlooking how it has already affected us as parents. It actively harms our relationship with our children (keeping us distracted from their amazing life) and sets a bad example for them. Too often, when we worry about children, we should look at our own behavior first. Until about that age (9-10+) at least, they are such a direct reflection of us that it s frightening
Yet another person reacted to the fact that many of the interviewees in the first round seemed to believe that the internet is immaterial, located somewhere in the air, while being at the same time omnipresent:
It reminds me of one time about a dozen years ago, when i was still working closely with one of the city high schools where i d just had a terrible series of days, dealing with hardware failure, crappy service followthrough by the school s ISP, and overheating in the server closet, and had basically stayed overnight at the school and just managed to get things back to mostly-functional before kids and teachers started showing up again. That afternoon, i d been asked by the teacher of a dystopian fiction class to join them for a discussion of Feed, which they d just finished reading. i had read it the week before, and came to class prepared for their questions. (the book is about a near-future where kids have cybernetic implants and their society is basically on a runaway communications overload; not a bad Y[oung]A[dult] novel, really!) The kids all knew me from around the school, but the teacher introduced my appearance in class as one of the most Internet-connected people and they wanted to ask me about whether i really thought the internet would do this kind of thing to our culture, which i think was the frame that the teacher had prepped them with. I asked them whether they thought the book was really about the Internet, or whether it was about mobile phones. Totally threw off the teacher s lesson plans, i think, but we had a good discussion. At one point, one of the kids asked me if there was some kind of crazy disaster and all the humans died out, would the internet just keep running? what would happen on it if we were all gone? all of my labor even that grueling week was invisible to him! The internet was an immaterial thing, or if not immaterial, a force of nature, a thing that you accounted for the way you accounted for the weather, or traffic jams. It didn t occur to him, even having just read a book that asked questions about what hyperconnectivity does to a culture (including grappling with issues of disparate access, effective discrimination based on who has the latest hardware, etc), it didn t occur to him that this shit all works to the extent that it does because people make it go. I felt lost trying to explain it to him, because where i wanted to get to with the class discussion was about how we might decide collectively to make it go somewhere else that our contributions to it, and our labor to perpetuate it (or not) might actually help shape the future that the network helps us slide into. but he didn t even see that human decisions or labor played a role it in at all, let alone a potentially directive role. We were really starting at square zero, which wasn t his fault. Or the fault of his classmates that matter but maybe a little bit of fault on the teacher, who i thought should have been emphasizing this more but even the teacher clearly thought of the internet as a thing being done to us not as something we might actually drive one way or another. And she s not even wrong most people don t have much control, just like most people can t control the weather, even as our weather changes based on aggregate human activity.
I was quite impressed by seeing the internet perceived as a force of nature, so we continued this discussion a bit:
that whole story happened before we started talking about the cloud , but the cloud really reinforces this idea, i think. not that anyone actually thinks that the cloud is a literal cloud, but language shapes minds in subtle ways.
(Bold emphasis in the texts are mine.) Thanks :) I m happy and touched that these interviews prompted your wonderful reactions, and I hope that there ll be more to come on this topic. I m working on it!

21 May 2022

Dirk Eddelbuettel: #37: Introducing r2u with 2 x 19k CRAN binaries for Ubuntu 22.04 and 20.04

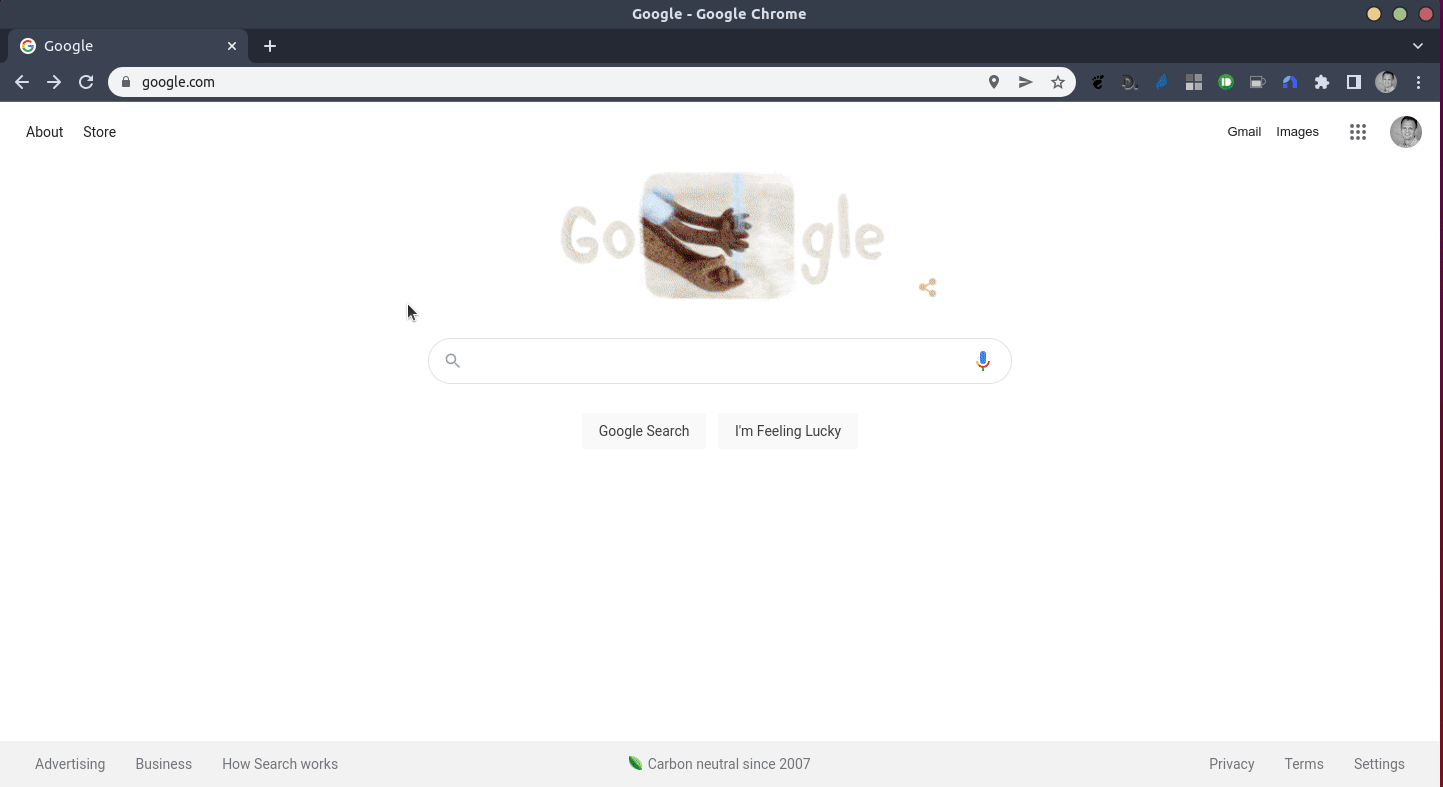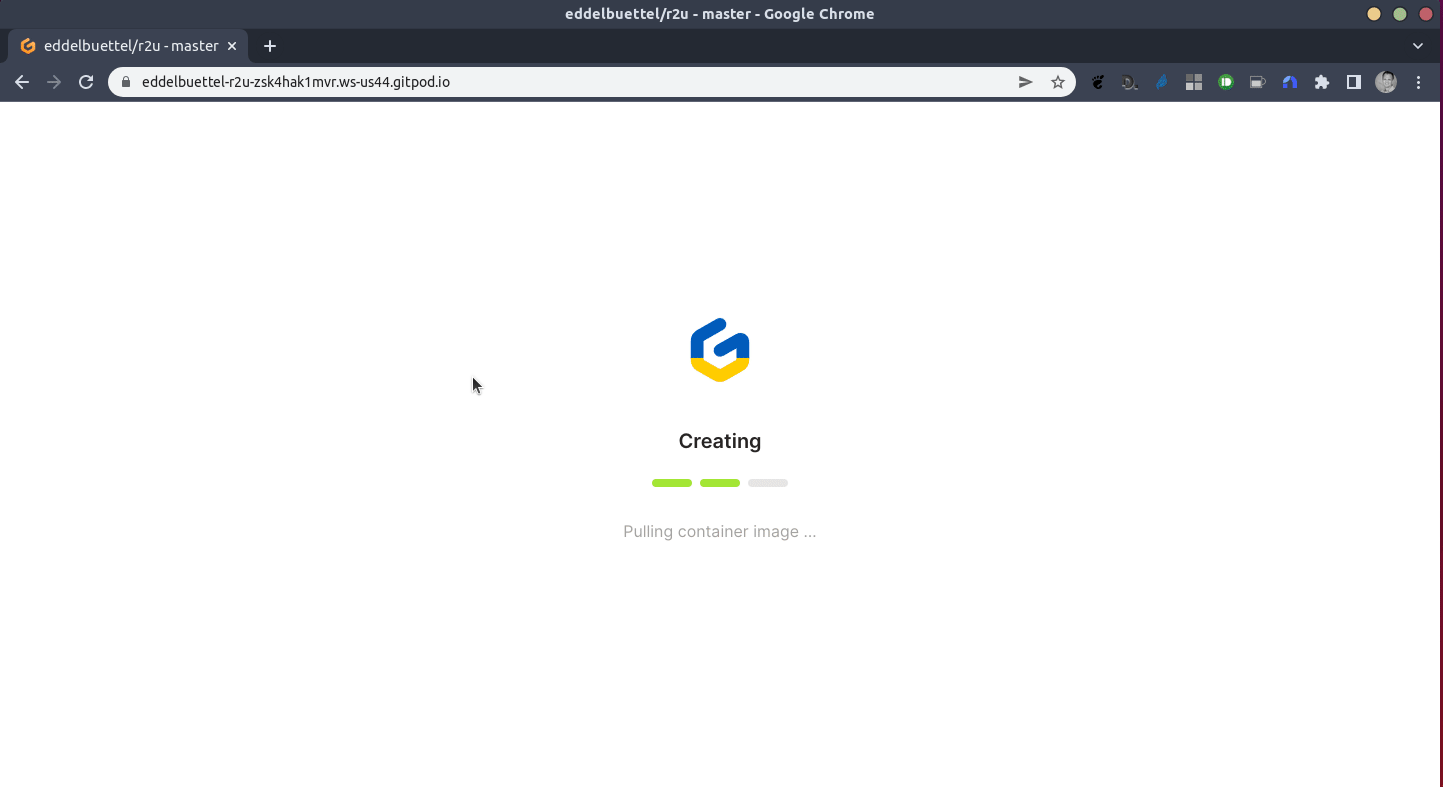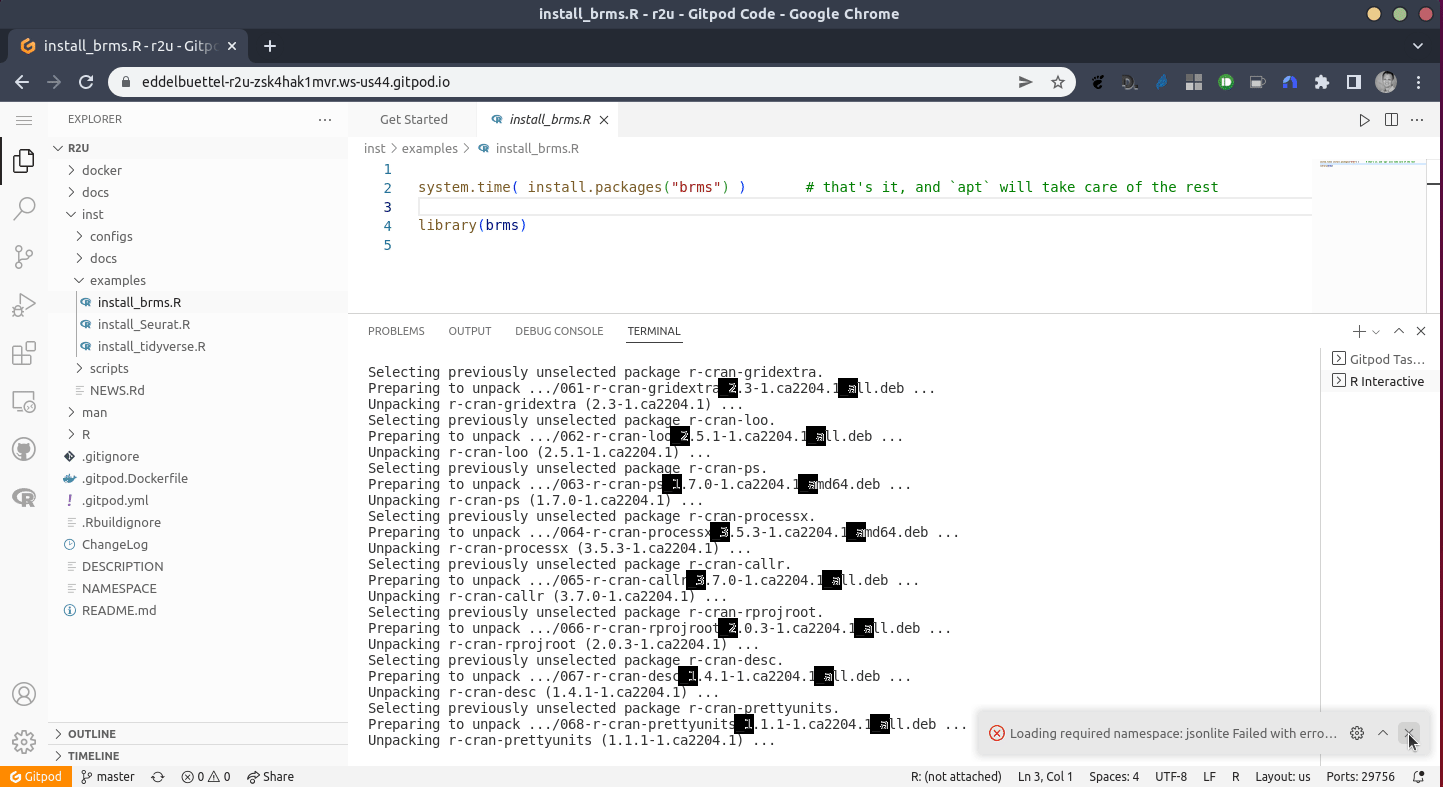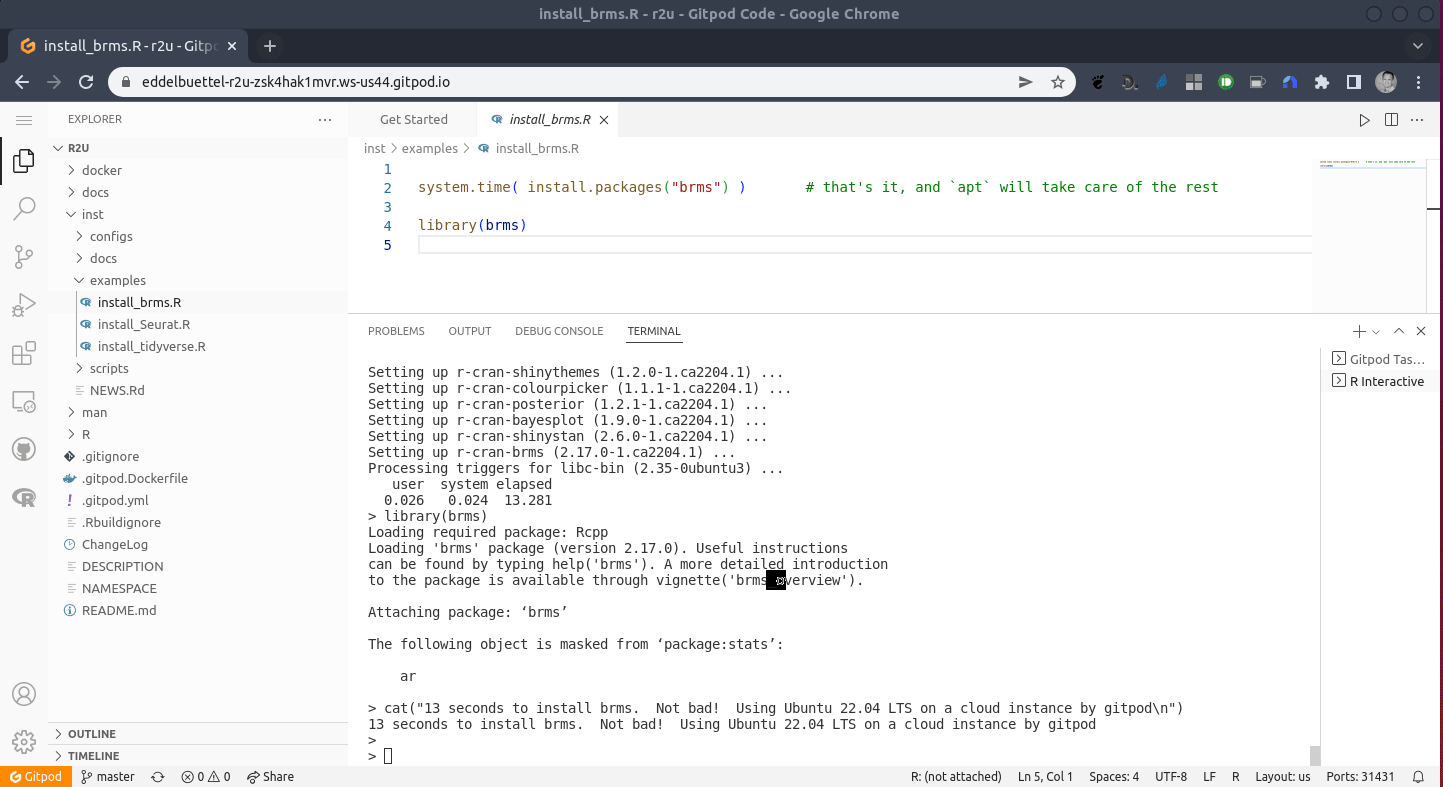
One month ago I started work on a new side project which is now up and running, and deserving on an introductory blog post: r2u. It was announced in two earlier tweets (first, second) which contained the two (wicked) demos below also found at the documentation site. So what is this about? It brings full and complete CRAN installability to Ubuntu LTS, both the focal release 20.04 and the recent jammy release 22.04. It is unique in resolving all R and CRAN packages with the system package manager. So whenever you install something it is guaranteed to run as its dependencies are resolved and co-installed as needed. Equally important, no shared library will be updated or removed by the system as the possible dependency of the R package is known and declared. No other package management system for R does that as only apt on Debian or Ubuntu can and this project integrates all CRAN packages (plus 200+ BioConductor packages). It will work with any Ubuntu installation on laptop, desktop, server, cloud, container, or in WSL2 (but is limited to Intel/AMD chips, sorry Raspberry Pi or M1 laptop). It covers all of CRAN (or nearly 19k packages), all the BioConductor packages depended-upon (currently over 200), and only excludes less than a handful of CRAN packages that cannot be built.

Usage Setup instructions approaches described concisely in the repo README.md and documentation site. It consists of just five (or fewer) simple steps, and scripts are provided too for focal (20.04) and jammy (22.04).

Demos Check out these two demos (also at the r2u site):

Installing the full tidyverse in one command and 18 seconds

Installing brms and its depends in one command and 13 seconds (and show gitpod.io)

Integration via bspm The r2u setup can be used directly with apt (or dpkg or any other frontend to the package management system). Once installed apt update; apt upgrade will take care of new packages. For this to work, all CRAN packages (and all BioConductor packages depended upon) are mapped to names like r-cran-rcpp and r-bioc-s4vectors: an r prefix, the repo, and the package name, all lower-cased. That works but thanks to the wonderful bspm package by I aki car we can do much better. It connects R s own install.packages() and update.packages() to apt. So we can just say (as the demos above show) install.packages("tidyverse") or install.packages("brms") and binaries are installed via apt which is fantastic and it connects R to the system package manager. The setup is really only two lines and described at the r2u site as part of the setup.

History and Motivation Turning CRAN packages into .deb binaries is not a new idea. Albrecht Gebhardt was the first to realize this about twenty years ago (!!) and implemented it with a single Perl script. Next, Albrecht, Stefan Moeller, David Vernazobres and I built on top of this which is described in this useR! 2007 paper. A most excellent generalization and rewrite was provided by Charles Blundell in an superb Google Summer of Code contribution in 2008 which I mentored. Charles and I described it in this talk at useR! 2009. I ran that setup for a while afterwards, but it died via an internal database corruption in 2010 right when I tried to demo it at CRAN headquarters in Vienna. This peaked at, if memory serves, about 5k packages: all of CRAN at the time. Don Armstrong took it one step further in a full reimplemenation which, if I recall correctly, coverd all of CRAN and BioConductor for what may have been 8k or 9k packages. Don had a stronger system (with full RAID-5) but it also died in a crash and was never rebuilt even though he and I could have relied on Debian resources (as all these approaches focused on Debian). During that time, Michael Rutter created a variant that cleverly used an Ubuntu-only setup utilizing Launchpad. This repo is still going strong, used and relied-upon by many, and about 5k packages (per distribution) strong. At one point, a group consisting of Don, Michael, G bor Cs rdi and myself (as lead/PI) had financial support from the RConsortium ISC for a more general re-implementation , but that support was withdrawn when we did not have time to deliver. We should also note other long-standing approaches. Detlef Steuer has been using the openSUSE Build Service to provide nearly all of CRAN for openSUSE for many years. I aki car built a similar system for Fedora described in this blog post. I aki and I also have a arXiv paper describing all this.

Details Please see the the r2u site for all details on using r2u.

Acknowledgements The help of everybody who has worked on this is greatly appreciated. So a huge Thank you! to Albrecht, David, Stefan, Charles, Don, Michael, Detlef, G bor, I aki and whoever I may have omitted. Similarly, thanks to everybody working on R, CRAN, Debian, or Ubuntu it all makes for a superb system. And another big Thank you! goes to my GitHub sponsors whose continued support is greatly appreciated.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

20 May 2022

Louis-Philippe V ronneau: Introducing metalfinder

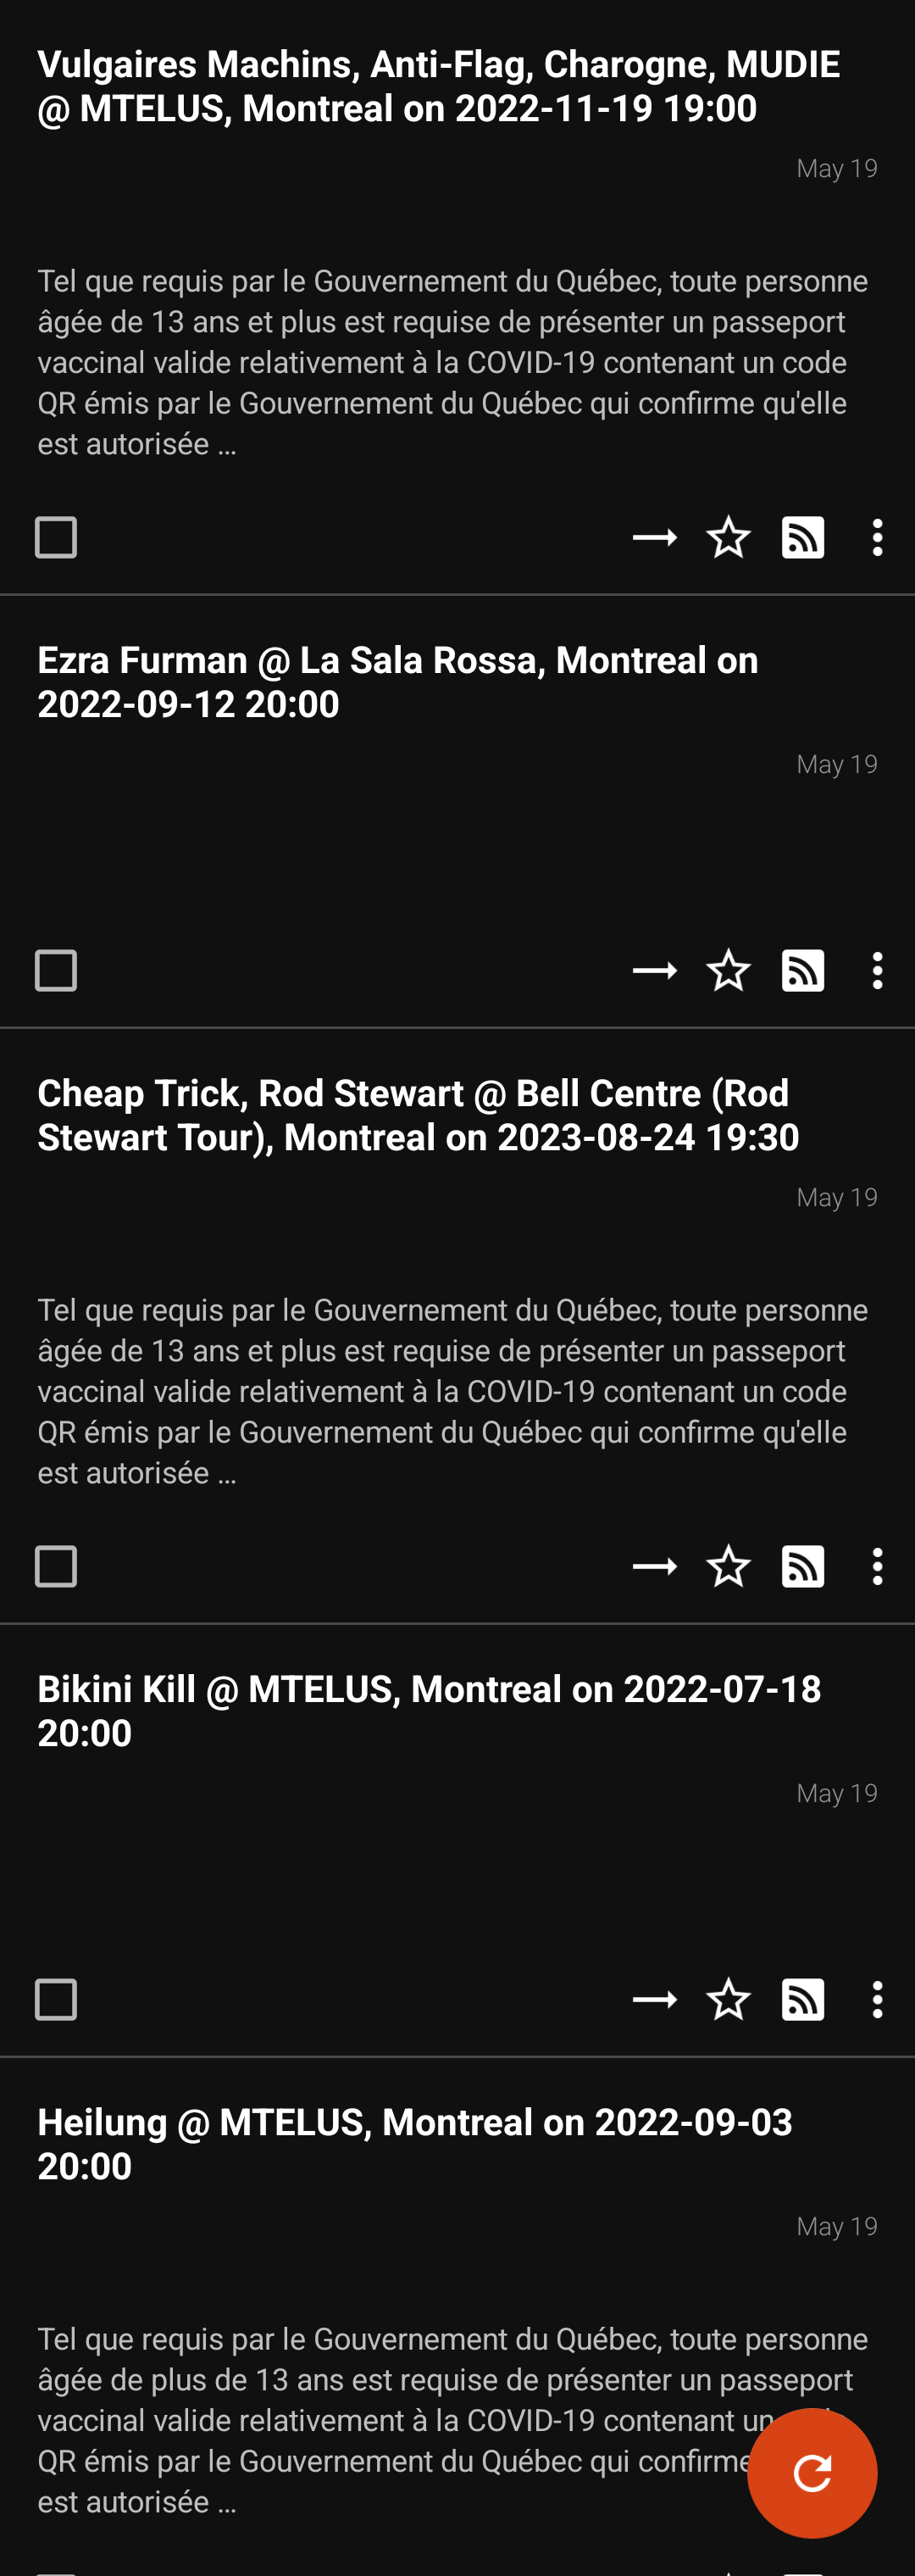
After going to an incredible Arch Enemy / Behemoth / Napalm Death / Unto Others concert a few weeks ago, I decided I wanted to go to more concerts. I like music, and I really enjoy concerts. Sadly, I often miss great performances because no one told me about it, or my local newspaper didn't cover the event enough in advance for me to get tickets. Some online services lets you sync your Spotify account to notify you when a new concert is announced, but I don't use Spotify. As a music geek, I have a local music collection and if I need to stream it, I have a supysonic server. Introducing metalfinder, a cli tool to find concerts using your local music collection! At the moment, it scans your music collection, creates a list of artists and queries Bandsintown for concerts in your town. Multiple output formats are supported, but I mainly use the ATOM one, as I'm a heavy feed reader user. Screenshot of the ATOM output in my feed reader The current metalfinder version (1.1.1) is a MVP: it works well enough, but I still have a lot of work to do... If you want to give it a try, the easiest way is to download it from PyPi. metalfinder is also currently in NEW and I'm planning to have something feature complete in time for the Bookworm freeze.

19 May 2022

Joerg Jaspert: Rust? Munin? munin-plugin

My first Rust crate: munin-plugin Sooo, some time ago I had to rewrite a munin plugin from Shell to Rust, due to the shell version going crazy after some runtime and using up a CPU all for its own. Sure, it only did that on Systems with Oracle Database installed, so that monster seems to be bad (who would have guessed?), but somehow I had to fixup this plugin and wasn t allowed to drop that wannabe-database. A while later I wrote a plugin to graph Fibre Channel Host data, and then Network interface statistics, all with a one-second resolution for the graphs, to allow one to zoom in and see every spike. Not have RRD round of the interesting parts. As one can imagine, that turns out to be a lot of very similar code - after all, most of the difference is in the graph config statements and actual data gathering, but the rest of code is just the same. As I already know there are more plugins (hello rsyslog statistics) I have to (sometimes re-)write in Rust, I took some time and wrote me a Rust library to make writing munin-plugins in Rust easier. Yay, my first crate on crates.io (and wrote lots of docs for it). By now I made my 1 second resolution CPU load plugin and the 1 second resolution Network interface plugin use this lib already. To test less complicated plugins with the lib, I took the munin default plugin load (Linux variant) and made a Rust version from it, but mostly to see that something as simple as that is also easy to implement: Munin load I got some idea on how to provide a useful default implementation of the fetch function, so one can write even less code, when using this library. It is my first library in Rust, so if you see something bad or missing in there, feel free to open issues or pull requests. Now, having done this, one thing missing: Someone to (re)write munin itself in something that is actually fast Not munin-node, but munin. Or maybe the RRD usage, but with a few hundred nodes in it, with loads of graphs, we had to adjust munin code and change some timeout or it would commit suicide regularly. And some other code change for not always checking for a rename, or something like it. And only run parts of the default cronjob once an hour, not on every update run. And switch to fetching data over ssh (and munin-async on the nodes). And rrdcached with loads of caching for the trillions of files (currently amounts to ~800G of data).. And it still needs way more CPU than it should. Soo, lots of possible optimizations hidden in there. Though I bet a non-scripting language rewrite might gain the most. (Except, of course, someone needs to do it :) )

18 May 2022

Reproducible Builds: Supporter spotlight: Jan Nieuwenhuizen on Bootstrappable Builds, GNU Mes and GNU Guix

The Reproducible Builds project relies on several projects, supporters and sponsors for financial support, but they are also valued as ambassadors who spread the word about our project and the work that we do. This is the fourth instalment in a series featuring the projects, companies and individuals who support the Reproducible Builds project. We started this series by featuring the Civil Infrastructure Platform project and followed this up with a post about the Ford Foundation as well as a recent ones about ARDC and the Google Open Source Security Team (GOSST). Today, however, we will be talking with Jan Nieuwenhuizen about Bootstrappable Builds, GNU Mes and GNU Guix.
Chris Lamb: Hi Jan, thanks for taking the time to talk with us today. First, could you briefly tell me about yourself? Jan: Thanks for the chat; it s been a while! Well, I ve always been trying to find something new and interesting that is just asking to be created but is mostly being overlooked. That s how I came to work on GNU Guix and create GNU Mes to address the bootstrapping problem that we have in free software. It s also why I have been working on releasing Dezyne, a programming language and set of tools to specify and formally verify concurrent software systems as free software. Briefly summarised, compilers are often written in the language they are compiling. This creates a chicken-and-egg problem which leads users and distributors to rely on opaque, pre-built binaries of those compilers that they use to build newer versions of the compiler. To gain trust in our computing platforms, we need to be able to tell how each part was produced from source, and opaque binaries are a threat to user security and user freedom since they are not auditable. The goal of bootstrappability (and the bootstrappable.org project in particular) is to minimise the amount of these bootstrap binaries. Anyway, after studying Physics at Eindhoven University of Technology (TU/e), I worked for digicash.com, a startup trying to create a digital and anonymous payment system sadly, however, a traditional account-based system won. Separate to this, as there was no software (either free or proprietary) to automatically create beautiful music notation, together with Han-Wen Nienhuys, I created GNU LilyPond. Ten years ago, I took the initiative to co-found a democratic school in Eindhoven based on the principles of sociocracy. And last Christmas I finally went vegan, after being mostly vegetarian for about 20 years!
Chris: For those who have not heard of it before, what is GNU Guix? What are the key differences between Guix and other Linux distributions? Jan: GNU Guix is both a package manager and a full-fledged GNU/Linux distribution. In both forms, it provides state-of-the-art package management features such as transactional upgrades and package roll-backs, hermetical-sealed build environments, unprivileged package management as well as per-user profiles. One obvious difference is that Guix forgoes the usual Filesystem Hierarchy Standard (ie. /usr, /lib, etc.), but there are other significant differences too, such as Guix being scriptable using Guile/Scheme, as well as Guix s dedication and focus on free software.
Chris: How does GNU Guix relate to GNU Mes? Or, rather, what problem is Mes attempting to solve? Jan: GNU Mes was created to address the security concerns that arise from bootstrapping an operating system such as Guix. Even if this process entirely involves free software (i.e. the source code is, at least, available), this commonly uses large and unauditable binary blobs. Mes is a Scheme interpreter written in a simple subset of C and a C compiler written in Scheme, and it comes with a small, bootstrappable C library. Twice, the Mes bootstrap has halved the size of opaque binaries that were needed to bootstrap GNU Guix. These reductions were achieved by first replacing GNU Binutils, GNU GCC and the GNU C Library with Mes, and then replacing Unix utilities such as awk, bash, coreutils, grep sed, etc., by Gash and Gash-Utils. The final goal of Mes is to help create a full-source bootstrap for any interested UNIX-like operating system.
Chris: What is the current status of Mes? Jan: Mes supports all that is needed from R5RS and GNU Guile to run MesCC with Nyacc, the C parser written for Guile, for 32-bit x86 and ARM. The next step for Mes would be more compatible with Guile, e.g., have guile-module support and support running Gash and Gash Utils. In working to create a full-source bootstrap, I have disregarded the kernel and Guix build system for now, but otherwise, all packages should be built from source, and obviously, no binary blobs should go in. We still need a Guile binary to execute some scripts, and it will take at least another one to two years to remove that binary. I m using the 80/20 approach, cutting corners initially to get something working and useful early. Another metric would be how many architectures we have. We are quite a way with ARM, tinycc now works, but there are still problems with GCC and Glibc. RISC-V is coming, too, which could be another metric. Someone has looked into picking up NixOS this summer. How many distros do anything about reproducibility or bootstrappability? The bootstrappability community is so small that we don t need metrics, sadly. The number of bytes of binary seed is a nice metric, but running the whole thing on a full-fledged Linux system is tough to put into a metric. Also, it is worth noting that I m developing on a modern Intel machine (ie. a platform with a management engine), that s another key component that doesn t have metrics.
Chris: From your perspective as a Mes/Guix user and developer, what does reproducibility mean to you? Are there any related projects? Jan: From my perspective, I m more into the problem of bootstrapping, and reproducibility is a prerequisite for bootstrappability. Reproducibility clearly takes a lot of effort to achieve, however. It s relatively easy to install some Linux distribution and be happy, but if you look at communities that really care about security, they are investing in reproducibility and other ways of improving the security of their supply chain. Projects I believe are complementary to Guix and Mes include NixOS, Debian and on the hardware side the RISC-V platform shares many of our core principles and goals.
Chris: Well, what are these principles and goals? Jan: Reproducibility and bootstrappability often feel like the next step in the frontier of free software. If you have all the sources and you can t reproduce a binary, that just doesn t feel right anymore. We should start to desire (and demand) transparent, elegant and auditable software stacks. To a certain extent, that s always been a low-level intent since the beginning of free software, but something clearly got lost along the way. On the other hand, if you look at the NPM or Rust ecosystems, we see a world where people directly install binaries. As they are not as supportive of copyleft as the rest of the free software community, you can see that movement and people in our area are doing more as a response to that so that what we have continues to remain free, and to prevent us from falling asleep and waking up in a couple of years and see, for example, Rust in the Linux kernel and (more importantly) we require big binary blobs to use our systems. It s an excellent time to advance right now, so we should get a foothold in and ensure we don t lose any more.
Chris: What would be your ultimate reproducibility goal? And what would the key steps or milestones be to reach that? Jan: The ultimate goal would be to have a system built with open hardware, with all software on it fully bootstrapped from its source. This bootstrap path should be easy to replicate and straightforward to inspect and audit. All fully reproducible, of course! In essence, we would have solved the supply chain security problem. Our biggest challenge is ignorance. There is much unawareness about the importance of what we are doing. As it is rather technical and doesn t really affect everyday computer use, that is not surprising. This unawareness can be a great force driving us in the opposite direction. Think of Rust being allowed in the Linux kernel, or Python being required to build a recent GNU C library (glibc). Also, the fact that companies like Google/Apple still want to play us vs them , not willing to to support GPL software. Not ready yet to truly support user freedom. Take the infamous log4j bug everyone is using open source these days, but nobody wants to take responsibility and help develop or nurture the community. Not ecosystem , as that s how it s being approached right now: live and let live/die: see what happens without taking any responsibility. We are growing and we are strong and we can do a lot but if we have to work against those powers, it can become problematic. So, let s spread our great message and get more people involved!
Chris: What has been your biggest win? Jan: From a technical point of view, the full-source bootstrap has have been our biggest win. A talk by Carl Dong at the 2019 Breaking Bitcoin conference stated that connecting Jeremiah Orian s Stage0 project to Mes would be the holy grail of bootstrapping, and we recently managed to achieve just that: in other words, starting from hex0, 357-byte binary, we can now build the entire Guix system. This past year we have not made significant visible progress, however, as our funding was unfortunately not there. The Stage0 project has advanced in RISC-V. A month ago, though, I secured NLnet funding for another year, and thanks to NLnet, Ekaitz Zarraga and Timothy Sample will work on GNU Mes and the Guix bootstrap as well. Separate to this, the bootstrappable community has grown a lot from two people it was six years ago: there are now currently over 100 people in the #bootstrappable IRC channel, for example. The enlarged community is possibly an even more important win going forward.
Chris: How realistic is a 100% bootstrappable toolchain? And from someone who has been working in this area for a while, is solving Trusting Trust) actually feasible in reality? Jan: Two answers: Yes and no, it really depends on your definition. One great thing is that the whole Stage0 project can also run on the Knight virtual machine, a hardware platform that was designed, I think, in the 1970s. I believe we can and must do better than we are doing today, and that there s a lot of value in it. The core issue is not the trust; we can probably all trust each other. On the other hand, we don t want to trust each other or even ourselves. I am not, personally, going to inspect my RISC-V laptop, and other people create the hardware and do probably not want to inspect the software. The answer comes back to being conscientious and doing what is right. Inserting GCC as a binary blob is not right. I think we can do better, and that s what I d like to do. The security angle is interesting, but I don t like the paranoid part of that; I like the beauty of what we are creating together and stepwise improving on that.
Chris: Thanks for taking the time to talk to us today. If someone wanted to get in touch or learn more about GNU Guix or Mes, where might someone go? Jan: Sure! First, check out: I m also on Twitter (@janneke_gnu) and on octodon.social (@janneke@octodon.social).
Chris: Thanks for taking the time to talk to us today. Jan: No problem. :)


For more information about the Reproducible Builds project, please see our website at reproducible-builds.org. If you are interested in ensuring the ongoing security of the software that underpins our civilisation and wish to sponsor the Reproducible Builds project, please reach out to the project by emailing contact@reproducible-builds.org.
Louis-Philippe V ronneau: Clojure Team 2022 Sprint Report

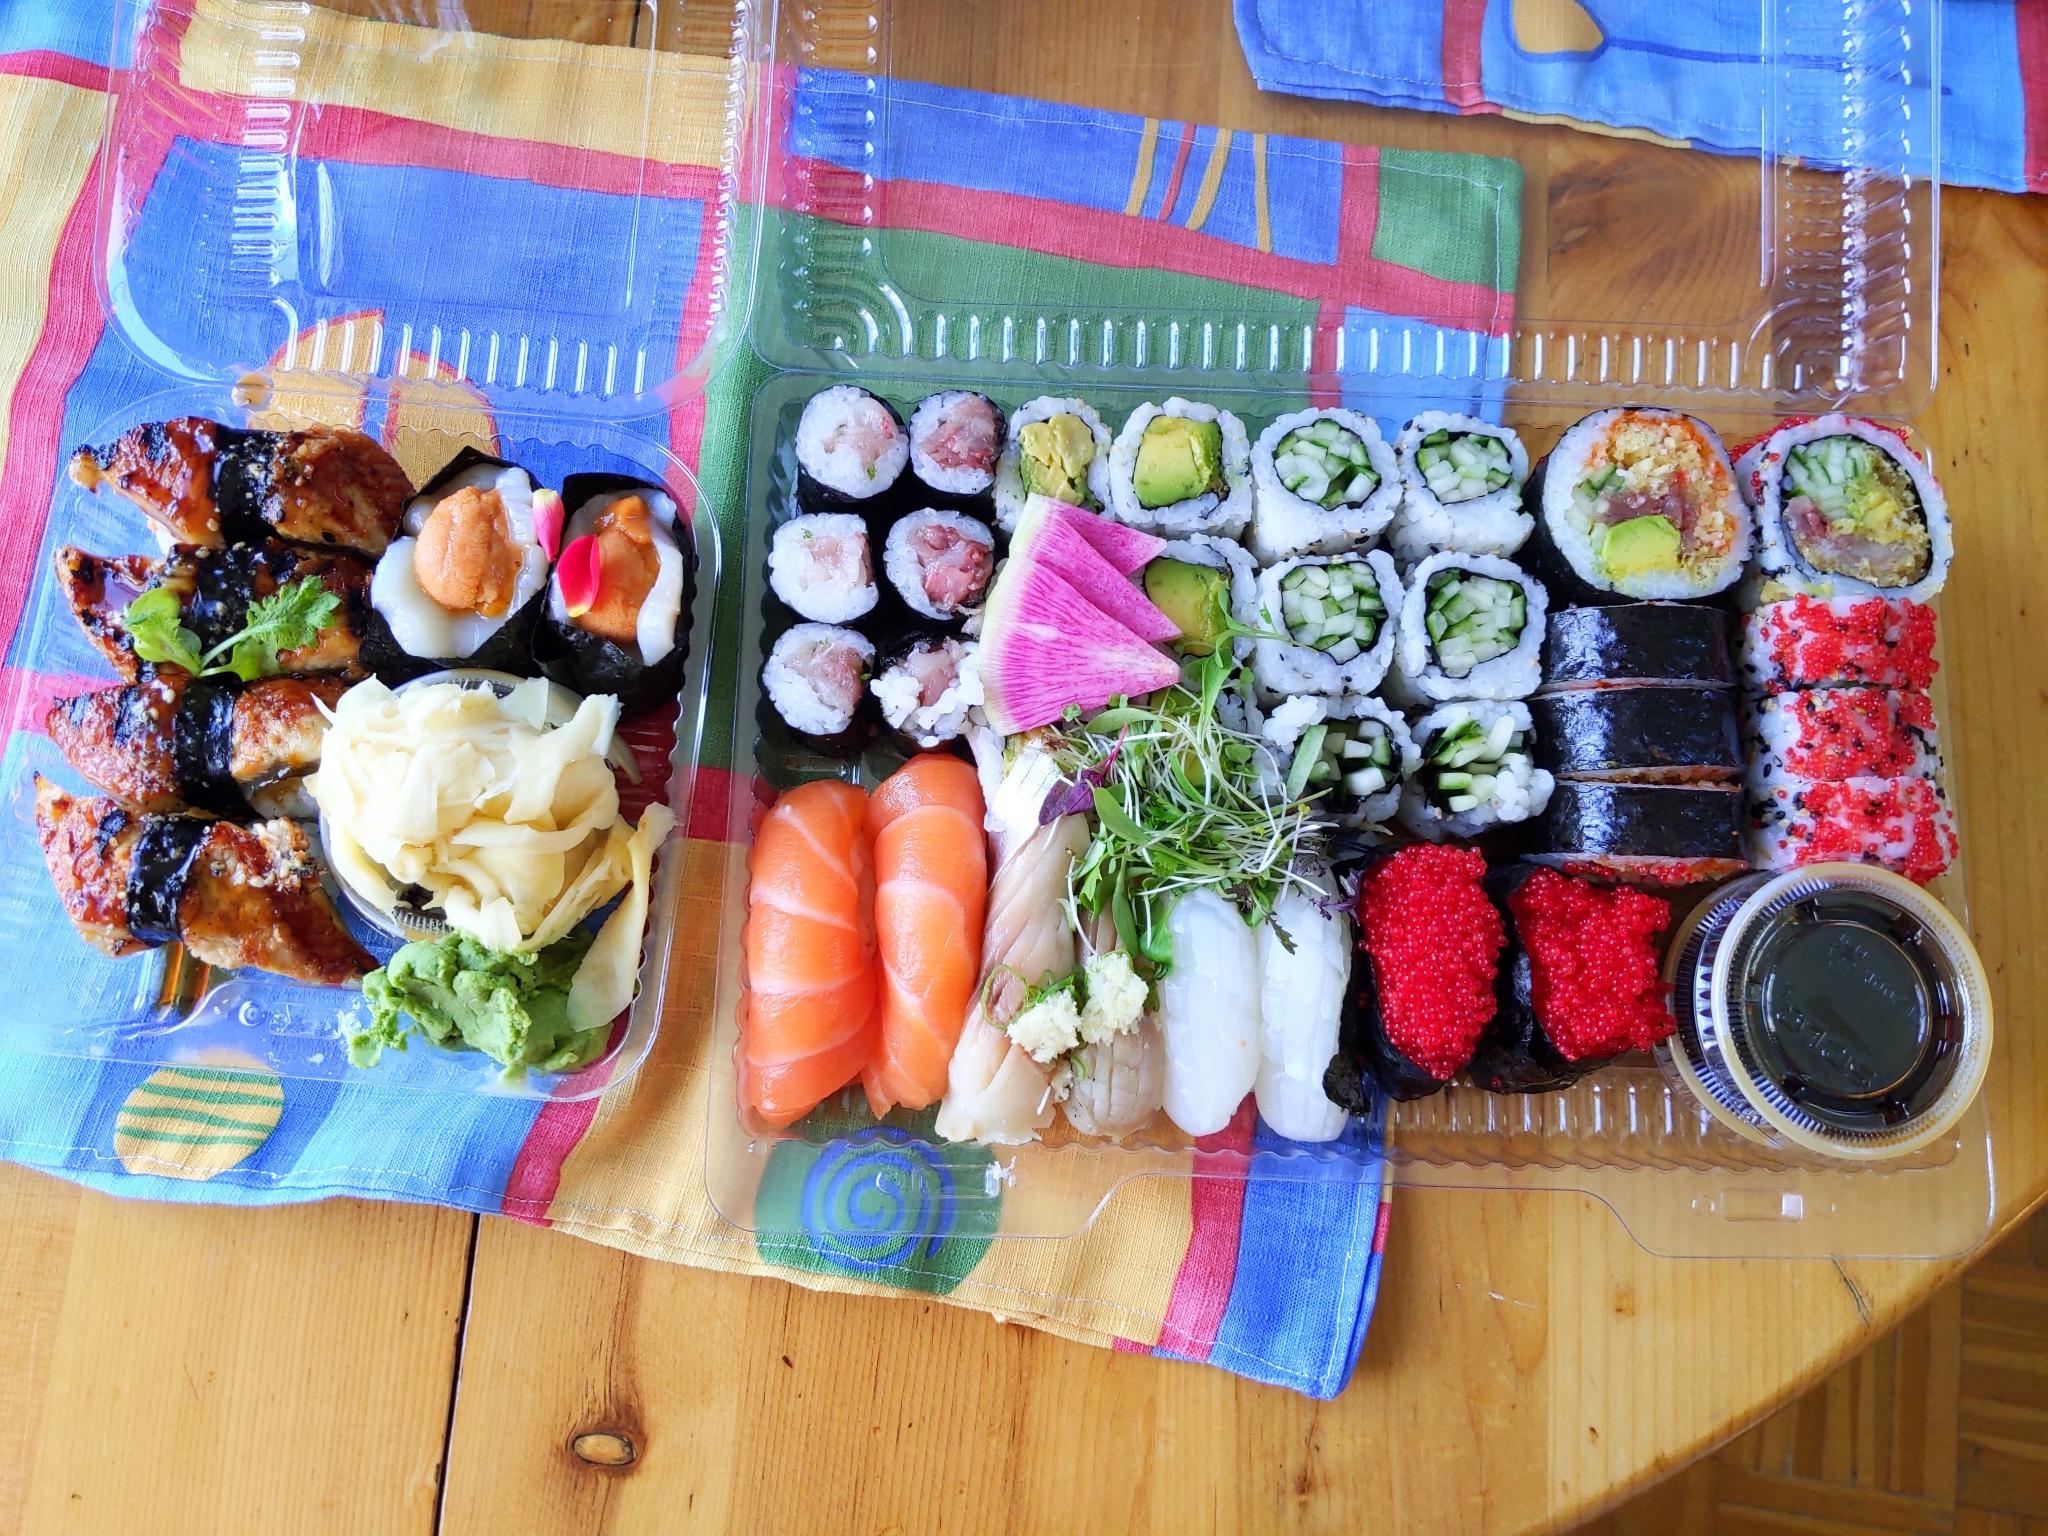
This is the report for the Debian Clojure Team remote sprint that took place on May 13-14th. Looking at my previous blog entries, this was my first Debian sprint since July 2020! Crazy how fast time flies... Many thanks to those who participated, namely: Sadly, Utkarsh Gupta although having planned on participating ended up not being able to and worked on DebConf Bursary paperwork instead. rlb Rob mostly worked on creating a dh-clojure tool to help make packaging Clojure libraries easier. At the moment, most of the packaging is done manually, by invoking build tools by hand. Having a tool to automate many of the steps required to build Clojure packages would go a long way in making them more uniform. His work (although still very much a WIP) can be found here: https://salsa.debian.org/rlb/dh-clojure/ ehashman Elana: lavamind It was J r me's first time working on Clojure packages, and things went great! During the sprint, he: allentiak Leandro joined us on Saturday, since he couldn't get off work on Friday. He mostly continued working on replacing our in-house scripts for /usr/bin/clojure by upstream's, a task he had already started during GSoC 2021. Sadly, none of us were familiar with Debian's mechanism for alternatives. If you (yes you, dear reader) are familiar with it, I'm sure he would warmly welcome feedback on his development branch. pollo As for me, I: Overall, it was quite a productive sprint! Thanks to Debian for sponsoring our food during the sprint. It was nice to be able to concentrate on fixing things instead of making food :) Here's a bonus picture of the nice sushi platter I ended up getting for dinner on Saturday night: Picture of a sushi platter

16 May 2022

Matthew Garrett: Can we fix bearer tokens?

Last month I wrote about how bearer tokens are just awful, and a week later Github announced that someone had managed to exfiltrate bearer tokens from Heroku that gave them access to, well, a lot of Github repositories. This has inevitably resulted in a whole bunch of discussion about a number of things, but people seem to be largely ignoring the fundamental issue that maybe we just shouldn't have magical blobs that grant you access to basically everything even if you've copied them from a legitimate holder to Honest John's Totally Legitimate API Consumer.

To make it clearer what the problem is here, let's use an analogy. You have a safety deposit box. To gain access to it, you simply need to be able to open it with a key you were given. Anyone who turns up with the key can open the box and do whatever they want with the contents. Unfortunately, the key is extremely easy to copy - anyone who is able to get hold of your keyring for a moment is in a position to duplicate it, and then they have access to the box. Wouldn't it be better if something could be done to ensure that whoever showed up with a working key was someone who was actually authorised to have that key?

To achieve that we need some way to verify the identity of the person holding the key. In the physical world we have a range of ways to achieve this, from simply checking whether someone has a piece of ID that associates them with the safety deposit box all the way up to invasive biometric measurements that supposedly verify that they're definitely the same person. But computers don't have passports or fingerprints, so we need another way to identify them.

When you open a browser and try to connect to your bank, the bank's website provides a TLS certificate that lets your browser know that you're talking to your bank instead of someone pretending to be your bank. The spec allows this to be a bi-directional transaction - you can also prove your identity to the remote website. This is referred to as "mutual TLS", or mTLS, and a successful mTLS transaction ends up with both ends knowing who they're talking to, as long as they have a reason to trust the certificate they were presented with.

That's actually a pretty big constraint! We have a reasonable model for the server - it's something that's issued by a trusted third party and it's tied to the DNS name for the server in question. Clients don't tend to have stable DNS identity, and that makes the entire thing sort of awkward. But, thankfully, maybe we don't need to? We don't need the client to be able to prove its identity to arbitrary third party sites here - we just need the client to be able to prove it's a legitimate holder of whichever bearer token it's presenting to that site. And that's a much easier problem.

Here's the simple solution - clients generate a TLS cert. This can be self-signed, because all we want to do here is be able to verify whether the machine talking to us is the same one that had a token issued to it. The client contacts a service that's going to give it a bearer token. The service requests mTLS auth without being picky about the certificate that's presented. The service embeds a hash of that certificate in the token before handing it back to the client. Whenever the client presents that token to any other service, the service ensures that the mTLS cert the client presented matches the hash in the bearer token. Copy the token without copying the mTLS certificate and the token gets rejected. Hurrah hurrah hats for everyone.

Well except for the obvious problem that if you're in a position to exfiltrate the bearer tokens you can probably just steal the client certificates and keys as well, and now you can pretend to be the original client and this is not adding much additional security. Fortunately pretty much everything we care about has the ability to store the private half of an asymmetric key in hardware (TPMs on Linux and Windows systems, the Secure Enclave on Macs and iPhones, either a piece of magical hardware or Trustzone on Android) in a way that avoids anyone being able to just steal the key.

How do we know that the key is actually in hardware? Here's the fun bit - it doesn't matter. If you're issuing a bearer token to a system then you're already asserting that the system is trusted. If the system is lying to you about whether or not the key it's presenting is hardware-backed then you've already lost. If it lied and the system is later compromised then sure all your apes get stolen, but maybe don't run systems that lie and avoid that situation as a result?

Anyway. This is covered in RFC 8705 so why aren't we all doing this already? From the client side, the largest generic issue is that TPMs are astonishingly slow in comparison to doing a TLS handshake on the CPU. RSA signing operations on TPMs can take around half a second, which doesn't sound too bad, except your browser is probably establishing multiple TLS connections to subdomains on the site it's connecting to and performance is going to tank. Fixing this involves doing whatever's necessary to convince the browser to pipe everything over a single TLS connection, and that's just not really where the web is right at the moment. Using EC keys instead helps a lot (~0.1 seconds per signature on modern TPMs), but it's still going to be a bottleneck.

The other problem, of course, is that ecosystem support for hardware-backed certificates is just awful. Windows lets you stick them into the standard platform certificate store, but the docs for this are hidden in a random PDF in a Github repo. Macs require you to do some weird bridging between the Secure Enclave API and the keychain API. Linux? Well, the standard answer is to do PKCS#11, and I have literally never met anybody who likes PKCS#11 and I have spent a bunch of time in standards meetings with the sort of people you might expect to like PKCS#11 and even they don't like it. It turns out that loading a bunch of random C bullshit that has strong feelings about function pointers into your security critical process is not necessarily something that is going to improve your quality of life, so instead you should use something like this and just have enough C to bridge to a language that isn't secretly plotting to kill your pets the moment you turn your back.

And, uh, obviously none of this matters at all unless people actually support it. Github has no support at all for validating the identity of whoever holds a bearer token. Most issuers of bearer tokens have no support for embedding holder identity into the token. This is not good! As of last week, all three of the big cloud providers support virtualised TPMs in their VMs - we should be running CI on systems that can do that, and tying any issued tokens to the VMs that are supposed to be making use of them.

So sure this isn't trivial. But it's also not impossible, and making this stuff work would improve the security of, well, everything. We literally have the technology to prevent attacks like Github suffered. What do we have to do to get people to actually start working on implementing that?

comment count unavailable comments

15 May 2022

Dirk Eddelbuettel: RcppArmadillo 0.11.1.1.0 on CRAN: Updates

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has syntax deliberately close to Matlab and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 978 other packages on CRAN, downloaded over 24 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 469 times according to Google Scholar. This release brings a first new upstream fix in the new release series 11.*. In particular, treatment of ill-conditioned matrices is further strengthened. We once again tested this very rigorously via three different RC releases each of which got a full reverse-dependencies run (for which results are always logged here). A minor issue with old g++ compilers was found once 11.1.0 was tagged to this upstream release is now 11.1.1. Also fixed is an OpenMP setup issue where Justin Silverman noticed that we did not propagate the -fopenmp setting correctly. The full set of changes (since the last CRAN release 0.11.0.0.0) follows.

Changes in RcppArmadillo version 0.11.1.1.0 (2022-05-15)
  • Upgraded to Armadillo release 11.1.1 (Angry Kitchen Appliance)
    • added inv_opts::no_ugly option to inv() and inv_sympd() to disallow inverses of poorly conditioned matrices
    • more efficient handling of rank-deficient matrices via inv_opts::allow_approx option in inv() and inv_sympd()
    • better detection of rank deficient matrices by solve()
    • faster handling of symmetric and diagonal matrices by cond()
  • The configure script again propagates the'found' case again, thanks to Justin Silverman for the heads-up and suggested fix (Dirk and Justin in #376 and #377 fixing #375).

Changes in RcppArmadillo version 0.11.0.1.0 (2022-04-14)
  • Upgraded to Armadillo release 11.0.1 (Creme Brulee)
    • fix miscompilation of inv() and inv_sympd() functions when using inv_opts::allow_approx and inv_opts::tiny options

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

13 May 2022

Antoine Beaupr : BTRFS notes

I'm not a fan of BTRFS. This page serves as a reminder of why, but also a cheat sheet to figure out basic tasks in a BTRFS environment because those are not obvious to me, even after repeatedly having to deal with them. Content warning: there might be mentions of ZFS.

Stability concerns I'm worried about BTRFS stability, which has been historically ... changing. RAID-5 and RAID-6 are still marked unstable, for example. It's kind of a lucky guess whether your current kernel will behave properly with your planned workload. For example, in Linux 4.9, RAID-1 and RAID-10 were marked as "mostly OK" with a note that says:
Needs to be able to create two copies always. Can get stuck in irreversible read-only mode if only one copy can be made.
Even as of now, RAID-1 and RAID-10 has this note:
The simple redundancy RAID levels utilize different mirrors in a way that does not achieve the maximum performance. The logic can be improved so the reads will spread over the mirrors evenly or based on device congestion.
Granted, that's not a stability concern anymore, just performance. A reviewer of a draft of this article actually claimed that BTRFS only reads from one of the drives, which hopefully is inaccurate, but goes to show how confusing all this is. There are other warnings in the Debian wiki that are quite scary. Even the legendary Arch wiki has a warning on top of their BTRFS page, still. Even if those issues are now fixed, it can be hard to tell when they were fixed. There is a changelog by feature but it explicitly warns that it doesn't know "which kernel version it is considered mature enough for production use", so it's also useless for this. It would have been much better if BTRFS was released into the world only when those bugs were being completely fixed. Or that, at least, features were announced when they were stable, not just "we merged to mainline, good luck". Even now, we get mixed messages even in the official BTRFS documentation which says "The Btrfs code base is stable" (main page) while at the same time clearly stating unstable parts in the status page (currently RAID56). There are much harsher BTRFS critics than me out there so I will stop here, but let's just say that I feel a little uncomfortable trusting server data with full RAID arrays to BTRFS. But surely, for a workstation, things should just work smoothly... Right? Well, let's see the snags I hit.

My BTRFS test setup Before I go any further, I should probably clarify how I am testing BTRFS in the first place. The reason I tried BTRFS is that I was ... let's just say "strongly encouraged" by the LWN editors to install Fedora for the terminal emulators series. That, in turn, meant the setup was done with BTRFS, because that was somewhat the default in Fedora 27 (or did I want to experiment? I don't remember, it's been too long already). So Fedora was setup on my 1TB HDD and, with encryption, the partition table looks like this:
NAME                   MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINT
sda                      8:0    0 931,5G  0 disk  
 sda1                   8:1    0   200M  0 part  /boot/efi
 sda2                   8:2    0     1G  0 part  /boot
 sda3                   8:3    0   7,8G  0 part  
   fedora_swap        253:5    0   7.8G  0 crypt [SWAP]
 sda4                   8:4    0 922,5G  0 part  
   fedora_crypt       253:4    0 922,5G  0 crypt /
(This might not entirely be accurate: I rebuilt this from the Debian side of things.) This is pretty straightforward, except for the swap partition: normally, I just treat swap like any other logical volume and create it in a logical volume. This is now just speculation, but I bet it was setup this way because "swap" support was only added in BTRFS 5.0. I fully expect BTRFS experts to yell at me now because this is an old setup and BTRFS is so much better now, but that's exactly the point here. That setup is not that old (2018? old? really?), and migrating to a new partition scheme isn't exactly practical right now. But let's move on to more practical considerations.

No builtin encryption BTRFS aims at replacing the entire mdadm, LVM, and ext4 stack with a single entity, and adding new features like deduplication, checksums and so on. Yet there is one feature it is critically missing: encryption. See, my typical stack is actually mdadm, LUKS, and then LVM and ext4. This is convenient because I have only a single volume to decrypt. If I were to use BTRFS on servers, I'd need to have one LUKS volume per-disk. For a simple RAID-1 array, that's not too bad: one extra key. But for large RAID-10 arrays, this gets really unwieldy. The obvious BTRFS alternative, ZFS, supports encryption out of the box and mixes it above the disks so you only have one passphrase to enter. The main downside of ZFS encryption is that it happens above the "pool" level so you can typically see filesystem names (and possibly snapshots, depending on how it is built), which is not the case with a more traditional stack.

Subvolumes, filesystems, and devices I find BTRFS's architecture to be utterly confusing. In the traditional LVM stack (which is itself kind of confusing if you're new to that stuff), you have those layers:
  • disks: let's say /dev/nvme0n1 and nvme1n1
  • RAID arrays with mdadm: let's say the above disks are joined in a RAID-1 array in /dev/md1
  • volume groups or VG with LVM: the above RAID device (technically a "physical volume" or PV) is assigned into a VG, let's call it vg_tbbuild05 (multiple PVs can be added to a single VG which is why there is that abstraction)
  • LVM logical volumes: out of that volume group actually "virtual partitions" or "logical volumes" are created, that is where your filesystem lives
  • filesystem, typically with ext4: that's your normal filesystem, which treats the logical volume as just another block device
A typical server setup would look like this:
NAME                      MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINT
nvme0n1                   259:0    0   1.7T  0 disk  
 nvme0n1p1               259:1    0     8M  0 part  
 nvme0n1p2               259:2    0   512M  0 part  
   md0                     9:0    0   511M  0 raid1 /boot
 nvme0n1p3               259:3    0   1.7T  0 part  
   md1                     9:1    0   1.7T  0 raid1 
     crypt_dev_md1       253:0    0   1.7T  0 crypt 
       vg_tbbuild05-root 253:1    0    30G  0 lvm   /
       vg_tbbuild05-swap 253:2    0 125.7G  0 lvm   [SWAP]
       vg_tbbuild05-srv  253:3    0   1.5T  0 lvm   /srv
 nvme0n1p4               259:4    0     1M  0 part
I stripped the other nvme1n1 disk because it's basically the same. Now, if we look at my BTRFS-enabled workstation, which doesn't even have RAID, we have the following:
  • disk: /dev/sda with, again, /dev/sda4 being where BTRFS lives
  • filesystem: fedora_crypt, which is, confusingly, kind of like a volume group. it's where everything lives. i think.
  • subvolumes: home, root, /, etc. those are actually the things that get mounted. you'd think you'd mount a filesystem, but no, you mount a subvolume. that is backwards.
It looks something like this to lsblk:
NAME                   MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINT
sda                      8:0    0 931,5G  0 disk  
 sda1                   8:1    0   200M  0 part  /boot/efi
 sda2                   8:2    0     1G  0 part  /boot
 sda3                   8:3    0   7,8G  0 part  [SWAP]
 sda4                   8:4    0 922,5G  0 part  
   fedora_crypt       253:4    0 922,5G  0 crypt /srv
Notice how we don't see all the BTRFS volumes here? Maybe it's because I'm mounting this from the Debian side, but lsblk definitely gets confused here. I frankly don't quite understand what's going on, even after repeatedly looking around the rather dismal documentation. But that's what I gather from the following commands:
root@curie:/home/anarcat# btrfs filesystem show
Label: 'fedora'  uuid: 5abb9def-c725-44ef-a45e-d72657803f37
    Total devices 1 FS bytes used 883.29GiB
    devid    1 size 922.47GiB used 916.47GiB path /dev/mapper/fedora_crypt
root@curie:/home/anarcat# btrfs subvolume list /srv
ID 257 gen 108092 top level 5 path home
ID 258 gen 108094 top level 5 path root
ID 263 gen 108020 top level 258 path root/var/lib/machines
I only got to that point through trial and error. Notice how I use an existing mountpoint to list the related subvolumes. If I try to use the filesystem path, the one that's listed in filesystem show, I fail:
root@curie:/home/anarcat# btrfs subvolume list /dev/mapper/fedora_crypt 
ERROR: not a btrfs filesystem: /dev/mapper/fedora_crypt
ERROR: can't access '/dev/mapper/fedora_crypt'
Maybe I just need to use the label? Nope:
root@curie:/home/anarcat# btrfs subvolume list fedora
ERROR: cannot access 'fedora': No such file or directory
ERROR: can't access 'fedora'
This is really confusing. I don't even know if I understand this right, and I've been staring at this all afternoon. Hopefully, the lazyweb will correct me eventually. (As an aside, why are they called "subvolumes"? If something is a "sub" of "something else", that "something else" must exist right? But no, BTRFS doesn't have "volumes", it only has "subvolumes". Go figure. Presumably the filesystem still holds "files" though, at least empirically it doesn't seem like it lost anything so far. In any case, at least I can refer to this section in the future, the next time I fumble around the btrfs commandline, as I surely will. I will possibly even update this section as I get better at it, or based on my reader's judicious feedback.

Mounting BTRFS subvolumes So how did I even get to that point? I have this in my /etc/fstab, on the Debian side of things:
UUID=5abb9def-c725-44ef-a45e-d72657803f37   /srv    btrfs  defaults 0   2
This thankfully ignores all the subvolume nonsense because it relies on the UUID. mount tells me that's actually the "root" (? /?) subvolume:
root@curie:/home/anarcat# mount   grep /srv
/dev/mapper/fedora_crypt on /srv type btrfs (rw,relatime,space_cache,subvolid=5,subvol=/)
Let's see if I can mount the other volumes I have on there. Remember that subvolume list showed I had home, root, and var/lib/machines. Let's try root:
mount -o subvol=root /dev/mapper/fedora_crypt /mnt
Interestingly, root is not the same as /, it's a different subvolume! It seems to be the Fedora root (/, really) filesystem. No idea what is happening here. I also have a home subvolume, let's mount it too, for good measure:
mount -o subvol=home /dev/mapper/fedora_crypt /mnt/home
Note that lsblk doesn't notice those two new mountpoints, and that's normal: it only lists block devices and subvolumes (rather inconveniently, I'd say) do not show up as devices:
root@curie:/home/anarcat# lsblk 
NAME                   MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINT
sda                      8:0    0 931,5G  0 disk  
 sda1                   8:1    0   200M  0 part  
 sda2                   8:2    0     1G  0 part  
 sda3                   8:3    0   7,8G  0 part  
 sda4                   8:4    0 922,5G  0 part  
   fedora_crypt       253:4    0 922,5G  0 crypt /srv
This is really, really confusing. Maybe I did something wrong in the setup. Maybe it's because I'm mounting it from outside Fedora. Either way, it just doesn't feel right.

No disk usage per volume If you want to see what's taking up space in one of those subvolumes, tough luck:
root@curie:/home/anarcat# df -h  /srv /mnt /mnt/home
Filesystem                Size  Used Avail Use% Mounted on
/dev/mapper/fedora_crypt  923G  886G   31G  97% /srv
/dev/mapper/fedora_crypt  923G  886G   31G  97% /mnt
/dev/mapper/fedora_crypt  923G  886G   31G  97% /mnt/home
(Notice, in passing, that it looks like the same filesystem is mounted in different places. In that sense, you'd expect /srv and /mnt (and /mnt/home?!) to be exactly the same, but no: they are entirely different directory structures, which I will not call "filesystems" here because everyone's head will explode in sparks of confusion.) Yes, disk space is shared (that's the Size and Avail columns, makes sense). But nope, no cookie for you: they all have the same Used columns, so you need to actually walk the entire filesystem to figure out what each disk takes. (For future reference, that's basically:
root@curie:/home/anarcat# time du -schx /mnt/home /mnt /srv
124M    /mnt/home
7.5G    /mnt
875G    /srv
883G    total
real    2m49.080s
user    0m3.664s
sys 0m19.013s
And yes, that was painfully slow.) ZFS actually has some oddities in that regard, but at least it tells me how much disk each volume (and snapshot) takes:
root@tubman:~# time df -t zfs -h
Filesystem         Size  Used Avail Use% Mounted on
rpool/ROOT/debian  3.5T  1.4G  3.5T   1% /
rpool/var/tmp      3.5T  384K  3.5T   1% /var/tmp
rpool/var/spool    3.5T  256K  3.5T   1% /var/spool
rpool/var/log      3.5T  2.0G  3.5T   1% /var/log
rpool/home/root    3.5T  2.2G  3.5T   1% /root
rpool/home         3.5T  256K  3.5T   1% /home
rpool/srv          3.5T   80G  3.5T   3% /srv
rpool/var/cache    3.5T  114M  3.5T   1% /var/cache
bpool/BOOT/debian  571M   90M  481M  16% /boot
real    0m0.003s
user    0m0.002s
sys 0m0.000s
That's 56360 times faster, by the way. But yes, that's not fair: those in the know will know there's a different command to do what df does with BTRFS filesystems, the btrfs filesystem usage command:
root@curie:/home/anarcat# time btrfs filesystem usage /srv
Overall:
    Device size:         922.47GiB
    Device allocated:        916.47GiB
    Device unallocated:        6.00GiB
    Device missing:          0.00B
    Used:            884.97GiB
    Free (estimated):         30.84GiB  (min: 27.84GiB)
    Free (statfs, df):        30.84GiB
    Data ratio:               1.00
    Metadata ratio:           2.00
    Global reserve:      512.00MiB  (used: 0.00B)
    Multiple profiles:              no
Data,single: Size:906.45GiB, Used:881.61GiB (97.26%)
   /dev/mapper/fedora_crypt  906.45GiB
Metadata,DUP: Size:5.00GiB, Used:1.68GiB (33.58%)
   /dev/mapper/fedora_crypt   10.00GiB
System,DUP: Size:8.00MiB, Used:128.00KiB (1.56%)
   /dev/mapper/fedora_crypt   16.00MiB
Unallocated:
   /dev/mapper/fedora_crypt    6.00GiB
real    0m0,004s
user    0m0,000s
sys 0m0,004s
Almost as fast as ZFS's df! Good job. But wait. That doesn't actually tell me usage per subvolume. Notice it's filesystem usage, not subvolume usage, which unhelpfully refuses to exist. That command only shows that one "filesystem" internal statistics that are pretty opaque.. You can also appreciate that it's wasting 6GB of "unallocated" disk space there: I probably did something Very Wrong and should be punished by Hacker News. I also wonder why it has 1.68GB of "metadata" used... At this point, I just really want to throw that thing out of the window and restart from scratch. I don't really feel like learning the BTRFS internals, as they seem oblique and completely bizarre to me. It feels a little like the state of PHP now: it's actually pretty solid, but built upon so many layers of cruft that I still feel it corrupts my brain every time I have to deal with it (needle or haystack first? anyone?)...

Conclusion I find BTRFS utterly confusing and I'm worried about its reliability. I think a lot of work is needed on usability and coherence before I even consider running this anywhere else than a lab, and that's really too bad, because there are really nice features in BTRFS that would greatly help my workflow. (I want to use filesystem snapshots as high-performance, high frequency backups.) So now I'm experimenting with OpenZFS. It's so much simpler, just works, and it's rock solid. After this 8 minute read, I had a good understanding of how ZFS worked. Here's the 30 seconds overview:
  • vdev: a RAID array
  • vpool: a volume group of vdevs
  • datasets: normal filesystems (or block device, if you want to use another filesystem on top of ZFS)
There's also other special volumes like caches and logs that you can (really easily, compared to LVM caching) use to tweak your setup. You might also want to look at recordsize or ashift to tweak the filesystem to fit better your workload (or deal with drives lying about their sector size, I'm looking at you Samsung), but that's it. Running ZFS on Linux currently involves building kernel modules from scratch on every host, which I think is pretty bad. But I was able to setup a ZFS-only server using this excellent documentation without too much problem. I'm hoping some day the copyright issues are resolved and we can at least ship binary packages, but the politics (e.g. convincing Debian that is the right thing to do) and the logistics (e.g. DKMS auto-builders? is that even a thing? how about signed DKMS packages? fun-fun-fun!) seem really impractical. Who knows, maybe hell will freeze over (again) and Oracle will fix the CDDL. I personally think that we should just completely ignore this problem (which wasn't even supposed to be a problem) and ship binary packages directly, but I'm a pragmatic and do not always fit well with the free software fundamentalists. All of this to say that, short term, we don't have a reliable, advanced filesystem/logical disk manager in Linux. And that's really too bad.

Arturo Borrero Gonz lez: Toolforge GridEngine Debian 10 Buster migration

Toolforge logo, a circle with an anvil in the middle This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez. In accordance with our operating system upgrade policy, we should migrate our servers to Debian Buster. As discussed in the previous post, one of the most important and successful services provided by the Wikimedia Cloud Services team at the Wikimedia Foundation is Toolforge. Toolforge is a platform that allows users and developers to run and use a variety of applications with the ultimate goal of helping the Wikimedia mission from the technical side. As you may know already, all Wikimedia Foundation servers are powered by Debian, and this includes Toolforge and Cloud VPS. The Debian Project mostly follows a two year cadence for releases, and Toolforge has been using Debian Stretch for some years now, which nowadays is considered old-old-stable . In accordance with our operating system upgrade policy, we should migrate our servers to Debian Buster. Toolforge s two different backend engines, Kubernetes and Grid Engine, are impacted by this upgrade policy. Grid Engine is notably tied to the underlying Debian release, and the execution environment offered to tools running in the grid is limited to what the Debian archive contains for a given release. This is unlike in Kubernetes, where tool developers can leverage container images and decouple the runtime environment selection from the base operating system. Since the Toolforge grid original conception, we have been doing the same operation over and over again: We ve done this type of migration several times before. The last few ones were Ubuntu Precise to Ubuntu Trusty and Ubuntu Trusty to Debian Stretch. But this time around we had some special angles to consider.
So, you are upgrading the Debian release
  • You are migrating to Debian 11 Bullseye, no?
  • No, we re migrating to Debian 10 Buster
  • Wait, but Debian 11 Bullseye exists!
  • Yes, we know! Let me explain
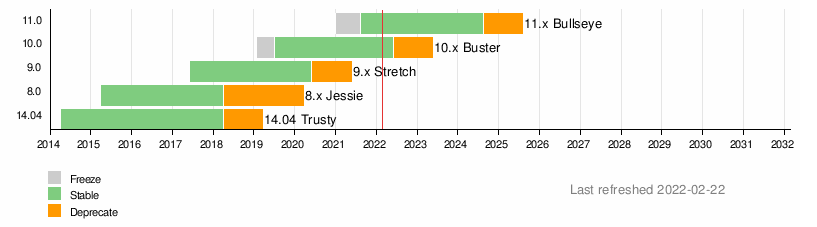
We re migrating the grid from Debian 9 Stretch to Debian 10 Buster, but perhaps we should be migrating from Debian 9 Stretch to Debian 11 Bullseye directly. This is a legitimate concern, and we discussed it in September 2021. A timeline showing Debian versions since 2014 Back then, our reasoning was that skipping to Debian 11 Bullseye would be more difficult for our users, especially because greater jump in version numbers for the underlying runtimes. Additionally, all the migration work started before Debian 11 Bullseye was released. Our original intention was for the migration to be completed before the release. For a couple of reasons the project was delayed, and when it was time to restart the project we decided to continue with the original idea. We had some work done to get Debian 10 Buster working correctly with the grid, and supporting Debian 11 Bullseye would require an additional effort. We didn t even check if Grid Engine could be installed in the latest Debian release. For the grid, in general, the engineering effort to do a N+1 upgrade is lower than doing a N+2 upgrade. If we had tried a N+2 upgrade directly, things would have been much slower and difficult for us, and for our users. In that sense, our conclusion was to not skip Debian 10 Buster.

We no longer want to run Grid Engine In a previous blog post we shared information about our desired future for Grid Engine in Toolforge. Our intention is to discontinue our usage of this technology.

No grid? What about my tools? Toolforge logo, a circle with an anvil in the middle Traditionally there have been two main workflows or use cases that were supported in the grid, but not in our Kubernetes backend:
  • Running jobs, long-running bots and other scheduled tasks.
  • Mixing runtime environments (for example, a nodejs app that runs some python code).
The good news is that work to handle the continuity of such use cases has already started. This takes the form of two main efforts:
  • The Toolforge buildpacks project to support arbitrary runtime environments.
  • The Toolforge Jobs Framework to support jobs, scheduled tasks, etc.
In particular, the Toolforge Jobs Framework has been available for a while in an open beta phase. We did some initial design and implementation, then deployed it in Toolforge for some users to try it and report bugs, report missing features, etc. These are complex, and feature-rich projects, and they deserve a dedicated blog post. More information on each will be shared in the future. For now, it is worth noting that both initiatives have some degree of development already. The conclusion Knowing all the moving parts, we were faced with a few hard questions when deciding how to approach the Debian 9 Stretch deprecation:
  • Should we not upgrade the grid, and focus on Kubernetes instead? Let Debian 9 Stretch be the last supported version on the grid?
  • What is the impact of these decisions on the technical community? What is best for our users?
The choices we made are already known in the community. A couple of weeks ago we announced the Debian 9 Stretch Grid Engine deprecation. In parallel to this migration, we decided to promote the new Toolforge Jobs Framework, even if it s still in beta phase. This new option should help users to future-proof their tool, and reduce maintenance effort. An early migration to Kubernetes now will avoid any more future grid problems. We truly hope that Debian 10 Buster is the last version we have for the grid, but as they say, hope is not a good strategy when it comes to engineering. What we will do is to work really hard in bringing Toolforge to the service level we want, and that means to keep developing and enabling more Kubernetes-based functionalities. Stay tuned for more upcoming blog posts with additional information about Toolforge. This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez.

11 May 2022

Raphaël Hertzog: Debian 9 soon out of (free) security support

Organizations that are still running Debian 9 servers should be aware that the security support of the Debian LTS team will end on June 30th 2022. If upgrading to a newer Debian release is not an option for them, then they should consider subscribing to Freexian s Extended LTS to get security support for the packages that they are using on their servers.
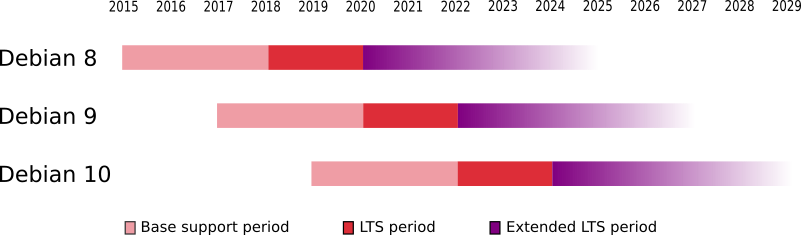
It s worth pointing out that we made some important changes to Freexian s Extended LTS offering : This means that we have again extended the life of Debian 8 Jessie, this time until June 30th 2025. And that Debian 9 Stretch that will start its extended life on July 1st 2022 can be maintained up to June 30th 2027. Organizations using Debian 10 should consider sponsoring the Debian LTS team since security support for that Debian release will soon transition from the regular security team to the LTS team.

10 May 2022

Melissa Wen: Multiple syncobjs support for V3D(V) (Part 2)

In the previous post, I described how we enable multiple syncobjs capabilities in the V3D kernel driver. Now I will tell you what was changed on the userspace side, where we reworked the V3DV sync mechanisms to use Vulkan multiple wait and signal semaphores directly. This change represents greater adherence to the Vulkan submission framework. I was not used to Vulkan concepts and the V3DV driver. Fortunately, I counted on the guidance of the Igalia s Graphics team, mainly Iago Toral (thanks!), to understand the Vulkan Graphics Pipeline, sync scopes, and submission order. Therefore, we changed the original V3DV implementation for vkQueueSubmit and all related functions to allow direct mapping of multiple semaphores from V3DV to the V3D-kernel interface. Disclaimer: Here s a brief and probably inaccurate background, which we ll go into more detail later on. In Vulkan, GPU work submissions are described as command buffers. These command buffers, with GPU jobs, are grouped in a command buffer submission batch, specified by vkSubmitInfo, and submitted to a queue for execution. vkQueueSubmit is the command called to submit command buffers to a queue. Besides command buffers, vkSubmitInfo also specifies semaphores to wait before starting the batch execution and semaphores to signal when all command buffers in the batch are complete. Moreover, a fence in vkQueueSubmit can be signaled when all command buffer batches have completed execution. From this sequence, we can see some implicit ordering guarantees. Submission order defines the start order of execution between command buffers, in other words, it is determined by the order in which pSubmits appear in VkQueueSubmit and pCommandBuffers appear in VkSubmitInfo. However, we don t have any completion guarantees for jobs submitted to different GPU queue, which means they may overlap and complete out of order. Of course, jobs submitted to the same GPU engine follow start and finish order. A fence is ordered after all semaphores signal operations for signal operation order. In addition to implicit sync, we also have some explicit sync resources, such as semaphores, fences, and events. Considering these implicit and explicit sync mechanisms, we rework the V3DV implementation of queue submissions to better use multiple syncobjs capabilities from the kernel. In this merge request, you can find this work: v3dv: add support to multiple wait and signal semaphores. In this blog post, we run through each scope of change of this merge request for a V3D driver-guided description of the multisync support implementation.

Groundwork and basic code clean-up: As the original V3D-kernel interface allowed only one semaphore, V3DV resorted to booleans to translate multiple semaphores into one. Consequently, if a command buffer batch had at least one semaphore, it needed to wait on all jobs submitted complete before starting its execution. So, instead of just boolean, we created and changed structs that store semaphores information to accept the actual list of wait semaphores.

Expose multisync kernel interface to the driver: In the two commits below, we basically updated the DRM V3D interface from that one defined in the kernel and verified if the multisync capability is available for use.

Handle multiple semaphores for all GPU job types: At this point, we were only changing the submission design to consider multiple wait semaphores. Before supporting multisync, V3DV was waiting for the last job submitted to be signaled when at least one wait semaphore was defined, even when serialization wasn t required. V3DV handle GPU jobs according to the GPU queue in which they are submitted:
  • Control List (CL) for binning and rendering
  • Texture Formatting Unit (TFU)
  • Compute Shader Dispatch (CSD)
Therefore, we changed their submission setup to do jobs submitted to any GPU queues able to handle more than one wait semaphores. These commits created all mechanisms to set arrays of wait and signal semaphores for GPU job submissions:
  • Checking the conditions to define the wait_stage.
  • Wrapping them in a multisync extension.
  • According to the kernel interface (described in the previous blog post), configure the generic extension as a multisync extension.
Finally, we extended the ability of GPU jobs to handle multiple signal semaphores, but at this point, no GPU job is actually in charge of signaling them. With this in place, we could rework part of the code that tracks CPU and GPU job completions by verifying the GPU status and threads spawned by Event jobs.

Rework the QueueWaitIdle mechanism to track the syncobj of the last job submitted in each queue: As we had only single in/out syncobj interfaces for semaphores, we used a single last_job_sync to synchronize job dependencies of the previous submission. Although the DRM scheduler guarantees the order of starting to execute a job in the same queue in the kernel space, the order of completion isn t predictable. On the other hand, we still needed to use syncobjs to follow job completion since we have event threads on the CPU side. Therefore, a more accurate implementation requires last_job syncobjs to track when each engine (CL, TFU, and CSD) is idle. We also needed to keep the driver working on previous versions of v3d kernel-driver with single semaphores, then we kept tracking ANY last_job_sync to preserve the previous implementation.

Rework synchronization and submission design to let the jobs handle wait and signal semaphores: With multiple semaphores support, the conditions for waiting and signaling semaphores changed accordingly to the particularities of each GPU job (CL, CSD, TFU) and CPU job restrictions (Events, CSD indirect, etc.). In this sense, we redesigned V3DV semaphores handling and job submissions for command buffer batches in vkQueueSubmit. We scrutinized possible scenarios for submitting command buffer batches to change the original implementation carefully. It resulted in three commits more: We keep track of whether we have submitted a job to each GPU queue (CSD, TFU, CL) and a CPU job for each command buffer. We use syncobjs to track the last job submitted to each GPU queue and a flag that indicates if this represents the beginning of a command buffer. The first GPU job submitted to a GPU queue in a command buffer should wait on wait semaphores. The first CPU job submitted in a command buffer should call v3dv_QueueWaitIdle() to do the waiting and ignore semaphores (because it is waiting for everything). If the job is not the first but has the serialize flag set, it should wait on the completion of all last job submitted to any GPU queue before running. In practice, it means using syncobjs to track the last job submitted by queue and add these syncobjs as job dependencies of this serialized job. If this job is the last job of a command buffer batch, it may be used to signal semaphores if this command buffer batch has only one type of GPU job (because we have guarantees of execution ordering). Otherwise, we emit a no-op job just to signal semaphores. It waits on the completion of all last jobs submitted to any GPU queue and then signal semaphores. Note: We changed this approach to correctly deal with ordering changes caused by event threads at some point. Whenever we have an event job in the command buffer, we cannot use the last job in the last command buffer assumption. We have to wait all event threads complete to signal After submitting all command buffers, we emit a no-op job to wait on all last jobs by queue completion and signal fence. Note: at some point, we changed this approach to correct deal with ordering changes caused by event threads, as mentioned before.

Final considerations With many changes and many rounds of reviews, the patchset was merged. After more validations and code review, we polished and fixed the implementation together with external contributions: Also, multisync capabilities enabled us to add new features to V3DV and switch the driver to the common synchronization and submission framework:
  • v3dv: expose support for semaphore imports
    This was waiting for multisync support in the v3d kernel, which is already available. Exposing this feature however enabled a few more CTS tests that exposed pre-existing bugs in the user-space driver so we fix those here before exposing the feature.
  • v3dv: Switch to the common submit framework
    This should give you emulated timeline semaphores for free and kernel-assisted sharable timeline semaphores for cheap once you have the kernel interface wired in.
We used a set of games to ensure no performance regression in the new implementation. For this, we used GFXReconstruct to capture Vulkan API calls when playing those games. Then, we compared results with and without multisync caps in the kernelspace and also enabling multisync on v3dv. We didn t observe any compromise in performance, but improvements when replaying scenes of vkQuake game.

Melissa Wen: Multiple syncobjs support for V3D(V) (Part 1)

As you may already know, we at Igalia have been working on several improvements to the 3D rendering drivers of Broadcom Videocore GPU, found in Raspberry Pi 4 devices. One of our recent works focused on improving V3D(V) drivers adherence to Vulkan submission and synchronization framework. We had to cross various layers from the Linux Graphics stack to add support for multiple syncobjs to V3D(V), from the Linux/DRM kernel to the Vulkan driver. We have delivered bug fixes, a generic gate to extend job submission interfaces, and a more direct sync mapping of the Vulkan framework. These changes did not impact the performance of the tested games and brought greater precision to the synchronization mechanisms. Ultimately, support for multiple syncobjs opened the door to new features and other improvements to the V3DV submission framework.

DRM Syncobjs But, first, what are DRM sync objs?
* DRM synchronization objects (syncobj, see struct &drm_syncobj) provide a
* container for a synchronization primitive which can be used by userspace
* to explicitly synchronize GPU commands, can be shared between userspace
* processes, and can be shared between different DRM drivers.
* Their primary use-case is to implement Vulkan fences and semaphores.
[...]
* At it's core, a syncobj is simply a wrapper around a pointer to a struct
* &dma_fence which may be NULL.
And Jason Ekstrand well-summarized dma_fence features in a talk at the Linux Plumbers Conference 2021:
A struct that represents a (potentially future) event:
  • Has a boolean signaled state
  • Has a bunch of useful utility helpers/concepts, such as refcount, callback wait mechanisms, etc.
Provides two guarantees:
  • One-shot: once signaled, it will be signaled forever
  • Finite-time: once exposed, is guaranteed signal in a reasonable amount of time

What does multiple semaphores support mean for Raspberry Pi 4 GPU drivers? For our main purpose, the multiple syncobjs support means that V3DV can submit jobs with more than one wait and signal semaphore. In the kernel space, wait semaphores become explicit job dependencies to wait on before executing the job. Signal semaphores (or post dependencies), in turn, work as fences to be signaled when the job completes its execution, unlocking following jobs that depend on its completion. The multisync support development comprised of many decision-making points and steps summarized as follow:
  • added to the v3d kernel-driver capabilities to handle multiple syncobj;
  • exposed multisync capabilities to the userspace through a generic extension; and
  • reworked synchronization mechanisms of the V3DV driver to benefit from this feature
  • enabled simulator to work with multiple semaphores
  • tested on Vulkan games to verify the correctness and possible performance enhancements.
We decided to refactor parts of the V3D(V) submission design in kernel-space and userspace during this development. We improved job scheduling on V3D-kernel and the V3DV job submission design. We also delivered more accurate synchronizing mechanisms and further updates in the Broadcom Vulkan driver running on Raspberry Pi 4. Therefore, we summarize here changes in the kernel space, describing the previous state of the driver, taking decisions, side improvements, and fixes.

From single to multiple binary in/out syncobjs: Initially, V3D was very limited in the numbers of syncobjs per job submission. V3D job interfaces (CL, CSD, and TFU) only supported one syncobj (in_sync) to be added as an execution dependency and one syncobj (out_sync) to be signaled when a submission completes. Except for CL submission, which accepts two in_syncs: one for binner and another for render job, it didn t change the limited options. Meanwhile in the userspace, the V3DV driver followed alternative paths to meet Vulkan s synchronization and submission framework. It needed to handle multiple wait and signal semaphores, but the V3D kernel-driver interface only accepts one in_sync and one out_sync. In short, V3DV had to fit multiple semaphores into one when submitting every GPU job.

Generic ioctl extension The first decision was how to extend the V3D interface to accept multiple in and out syncobjs. We could extend each ioctl with two entries of syncobj arrays and two entries for their counters. We could create new ioctls with multiple in/out syncobj. But after examining other drivers solutions to extend their submission s interface, we decided to extend V3D ioctls (v3d_cl_submit_ioctl, v3d_csd_submit_ioctl, v3d_tfu_submit_ioctl) by a generic ioctl extension. I found a curious commit message when I was examining how other developers handled the issue in the past:
Author: Chris Wilson <chris@chris-wilson.co.uk>
Date:   Fri Mar 22 09:23:22 2019 +0000
    drm/i915: Introduce the i915_user_extension_method
    
    An idea for extending uABI inspired by Vulkan's extension chains.
    Instead of expanding the data struct for each ioctl every time we need
    to add a new feature, define an extension chain instead. As we add
    optional interfaces to control the ioctl, we define a new extension
    struct that can be linked into the ioctl data only when required by the
    user. The key advantage being able to ignore large control structs for
    optional interfaces/extensions, while being able to process them in a
    consistent manner.
    
    In comparison to other extensible ioctls, the key difference is the
    use of a linked chain of extension structs vs an array of tagged
    pointers. For example,
    
    struct drm_amdgpu_cs_chunk  
    	__u32		chunk_id;
        __u32		length_dw;
        __u64		chunk_data;
     ;
[...]
So, inspired by amdgpu_cs_chunk and i915_user_extension, we opted to extend the V3D interface through a generic interface. After applying some suggestions from Iago Toral (Igalia) and Daniel Vetter, we reached the following struct:
struct drm_v3d_extension  
	__u64 next;
	__u32 id;
#define DRM_V3D_EXT_ID_MULTI_SYNC		0x01
	__u32 flags; /* mbz */
 ;
This generic extension has an id to identify the feature/extension we are adding to an ioctl (that maps the related struct type), a pointer to the next extension, and flags (if needed). Whenever we need to extend the V3D interface again for another specific feature, we subclass this generic extension into the specific one instead of extending ioctls indefinitely.

Multisync extension For the multiple syncobjs extension, we define a multi_sync extension struct that subclasses the generic extension struct. It has arrays of in and out syncobjs, the respective number of elements in each of them, and a wait_stage value used in CL submissions to determine which job needs to wait for syncobjs before running.
struct drm_v3d_multi_sync  
	struct drm_v3d_extension base;
	/* Array of wait and signal semaphores */
	__u64 in_syncs;
	__u64 out_syncs;
	/* Number of entries */
	__u32 in_sync_count;
	__u32 out_sync_count;
	/* set the stage (v3d_queue) to sync */
	__u32 wait_stage;
	__u32 pad; /* mbz */
 ;
And if a multisync extension is defined, the V3D driver ignores the previous interface of single in/out syncobjs. Once we had the interface to support multiple in/out syncobjs, v3d kernel-driver needed to handle it. As V3D uses the DRM scheduler for job executions, changing from single syncobj to multiples is quite straightforward. V3D copies from userspace the in syncobjs and uses drm_syncobj_find_fence()+ drm_sched_job_add_dependency() to add all in_syncs (wait semaphores) as job dependencies, i.e. syncobjs to be checked by the scheduler before running the job. On CL submissions, we have the bin and render jobs, so V3D follows the value of wait_stage to determine which job depends on those in_syncs to start its execution. When V3D defines the last job in a submission, it replaces dma_fence of out_syncs with the done_fence from this last job. It uses drm_syncobj_find() + drm_syncobj_replace_fence() to do that. Therefore, when a job completes its execution and signals done_fence, all out_syncs are signaled too.

Other improvements to v3d kernel driver This work also made possible some improvements in the original implementation. Following Iago s suggestions, we refactored the job s initialization code to allocate memory and initialize a job in one go. With this, we started to clean up resources more cohesively, clearly distinguishing cleanups in case of failure from job completion. We also fixed the resource cleanup when a job is aborted before the DRM scheduler arms it - at that point, drm_sched_job_arm() had recently been introduced to job initialization. Finally, we prepared the semaphore interface to implement timeline syncobjs in the future.

Going Up The patchset that adds multiple syncobjs support and improvements to V3D is available here and comprises four patches:
  • drm/v3d: decouple adding job dependencies steps from job init
  • drm/v3d: alloc and init job in one shot
  • drm/v3d: add generic ioctl extension
  • drm/v3d: add multiple syncobjs support
After extending the V3D kernel interface to accept multiple syncobjs, we worked on V3DV to benefit from V3D multisync capabilities. In the next post, I will describe a little of this work.

9 May 2022

Russ Allbery: C TAP Harness 4.8

C TAP Harness is my C implementation of the Perl "Test Anything Protocol" test suite framework. It includes test runner and libraries for both C and shell. This is mostly a cleanup release to resync with other utility libraries. It does fix an installation problem by managing symlinks correctly, and adds support for GCC 11's new deallocation warnings. The latter is a rather interesting new GCC feature. There is a Red Hat blog post about the implementation with more details, but the short version is that the __malloc__ attribute can now take an argument that specifies the function that should be used to deallocate the allocated object. GCC 11 and later can use that information to catch some deallocation bugs, such as deallocating things with the wrong function. You can get the latest version from the C TAP Harness distribution page.

8 May 2022

Thorsten Alteholz: My Debian Activities in April 2022

FTP master This month I accepted 186 and rejected 26 packages. The overall number of packages that got accepted was 188. Debian LTS This was my ninety-fourth month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload has been 40h. During that time I did LTS and normal security uploads of: Further I worked on libvirt, the dependency problems in unstable have been resolved and fixing in other releases can continue. I also continued to work on security support for golang packages. Last but not least I did some days of frontdesk duties. Debian ELTS This month was the forty-siyth ELTS month. During my allocated time I uploaded: Last but not least I did some days of frontdesk duties. Debian Printing This month I uploaded new upstream versions or improved packaging of: As I already became the maintainer of usb-modeswitch I also adopted usb-modeswitch-data Debian Astro Unfortunately I didn t do anything for this group, but in May I will upload a new version of openvlbi and several indi-3rdparty packages. Other stuff Last but not least I uploaded several new upstream version of golang packages but not before checking with ratt that all dependencies still work.

6 May 2022

Antoine Beaupr : Wallabako 1.4.0 released

I don't particularly like it when people announce their personal projects on their blog, but I'm making an exception for this one, because it's a little special for me. You see, I have just released Wallabako 1.4.0 (and a quick, mostly irrelevant 1.4.1 hotfix) today. It's the first release of that project in almost 3 years (the previous was 1.3.1, before the pandemic). The other reason I figured I would mention it is that I have almost never talked about Wallabako on this blog at all, so many of my readers probably don't even know I sometimes meddle with in Golang which surprises even me sometimes.

What's Wallabako Wallabako is a weird little program I designed to read articles on my E-book reader. I use it to spend less time on the computer: I save articles in a read-it-later app named Wallabag (hosted by a generous friend), and then Wallabako connects to that app, downloads an EPUB version of the book, and then I can read it on the device directly. When I'm done reading the book, Wallabako notices and sets the article as read in Wallabag. I also set it to delete the book locally, but you can actually configure to keep those books around forever if you feel like it. Wallabako supports syncing read status with the built-in Kobo interface (called "Nickel"), Koreader and Plato. I happen to use Koreader for everything nowadays, but it should work equally well on the others. Wallabako is actually setup to be started by udev when there's a connection change detected by the kernel, which is kind of a gross hack. It's clunky, but actually works and I thought for a while about switching to something else, but it's really the easiest way to go, and that requires the less interaction by the user.

Why I'm (still) using it I wrote Wallabako because I read a lot of articles on the internet. It's actually most of my readings. I read about 10 books a year (which I don't think is much), but I probably read more in terms of time and pages in Wallabag. I haven't actually made the math, but I estimate I spend at least double the time reading articles than I spend reading books. If I wouldn't have Wallabag, I would have hundreds of tabs open in my web browser all the time. So at least that problem is easily solved: throw everything in Wallabag, sort and read later. If I wouldn't have Wallabako however, I would be either spend that time reading on the computer -- which I prefer to spend working on free software or work -- or on my phone -- which is kind of better, but really cramped. I had stopped (and developing) Wallabako for a while, actually, Around 2019, I got tired of always read those technical articles (basically work stuff!) at home. I realized I was just not "reading" (as in books! fiction! fun stuff!) anymore, at least not as much as I wanted. So I tried to make this separation: the ebook reader is for cool book stuff. The rest is work. But because I had the Wallabag Android app on my phone and tablet, I could still read those articles there, which I thought was pretty neat. But that meant that I was constantly looking at my phone, which is something I'm generally trying to avoid, as it sets a bad example for the kids (small and big) around me. Then I realized there was one stray ebook reader lying around at home. I had recently bought a Kobo Aura HD to read books, and I like that device. And it's going to stay locked down to reading books. But there's still that old battered Kobo Glo HD reader lying around, and I figured I could just borrow it to read Wallabag articles.

What is this new release But oh boy that was a lot of work. Wallabako was kind of a mess: it was using the deprecated go dep tool, which lost the battle with go mod. Cross-compilation was broken for older devices, and I had to implement support for Koreader.

go mod So I had to learn go mod. I'm still not sure I got that part right: LSP is yelling at me because it can't find the imports, and I'm generally just "YOLO everythihng" every time I get anywhere close to it. That's not the way to do Go, in general, and not how I like to do it either. But I guess that, given time, I'll figure it out and make it work for me. It certainly works now. I think.

Cross compilation The hard part was different. You see, Nickel uses SQLite to store metadata about books, so Wallabako actually needs to tap into that SQLite database to propagate read status. Originally, I just linked against some sqlite3 library I found lying around. It's basically a wrapper around the C-based SQLite and generally works fine. But that means you actually link your Golang program against a C library. And that's when things get a little nutty. If you would just build Wallabag naively, it would fail when deployed on the Kobo Glo HD. That's because the device runs a really old kernel: the prehistoric Linux kobo 2.6.35.3-850-gbc67621+ #2049 PREEMPT Mon Jan 9 13:33:11 CST 2017 armv7l GNU/Linux. That was built in 2017, but the kernel was actually released in 2010, a whole 5 years before the Glo HD was released, in 2015 which is kind of outrageous. and yes, that is with the latest firmware release. My bet is they just don't upgrade the kernel on those things, as the Glo was probably bought around 2017... In any case, the problem is we are cross-compiling here. And Golang is pretty good about cross-compiling, but because we have C in there, we're actually cross-compiling with "CGO" which is really just Golang with a GCC backend. And that's much, much harder to figure out because you need to pass down flags into GCC and so on. It was a nightmare. That's until I found this outrageous "little" project called modernc.org/sqlite. What that thing does (with a hefty does of dependencies that would make any Debian developer recoil in horror) is to transpile the SQLite C source code to Golang. You read that right: it rewrites SQLite in Go. On the fly. It's nuts. But it works. And you end up with a "pure go" program, and that thing compiles much faster and runs fine on older kernel. I still wasn't sure I wanted to just stick with that forever, so I kept the old sqlite3 code around, behind a compile-time tag. At the top of the nickel_modernc.go file, there's this magic string:
//+build !sqlite3
And at the top of nickel_sqlite3.go file, there's this magic string:
//+build sqlite3
So now, by default, the modernc file gets included, but if I pass --tags sqlite3 to the Go compiler (to go install or whatever), it will actually switch to the other implementation. Pretty neat stuff.

Koreader port The last part was something I was hesitant in doing for a long time, but that turned out to be pretty easy. I have basically switch to using Koreader to read everything. Books, PDF, everything goes through it. I really like that it stores its metadata in sidecar files: I synchronize all my books with Syncthing which means I can carry my read status, annotations and all that stuff without having to think about it. (And yes, I installed Syncthing on my Kobo.) The koreader.go port was less than 80 lines, and I could even make a nice little test suite so that I don't have to redeploy that thing to the ebook reader at every code iteration. I had originally thought I should add some sort of graphical interface in Koreader for Wallabako as well, and had requested that feature upstream. Unfortunately (or fortunately?), they took my idea and just ran with it. Some courageous soul actually wrote a full Wallabag plugin for koreader, in Lua of course. Compared to the Wallabako implementation however, the koreader plugin is much slower, probably because it downloads articles serially instead of concurrently. It is, however, much more usable as the user is given a visible feedback of the various steps. I still had to enable full debugging to diagnose a problem (which was that I shouldn't have a trailing slash, and that some special characters don't work in passwords). It's also better to write the config file with a normal text editor, over SSH or with the Kobo mounted to your computer instead of typing those really long strings over the kobo. There's no sample config file which makes that harder but a workaround is to save the configuration with dummy values and fix them up after. Finally I also found the default setting ("Remotely delete finished articles") really dangerous as it can basically lead to data loss (Wallabag article being deleted!) for an unsuspecting user... So basically, I started working on Wallabag again because the koreader implementation of their Wallabag client was not up to spec for me. It might be good enough for you, but I guess if you like Wallabako, you should thank the koreader folks for their sloppy implementation, as I'm now working again on Wallabako.

Actual release notes Those are the actual release notes for 1.4.0.
Ship a lot of fixes that have accumulated in the 3 years since the last release. Features:
  • add timestamp and git version to build artifacts
  • cleanup and improve debugging output
  • switch to pure go sqlite implementation, which helps
  • update all module dependencies
  • port to wallabago v6
  • support Plato library changes from 0.8.5+
  • support reading koreader progress/read status
  • Allow containerized builds, use gomod and avoid GOPATH hell
  • overhaul Dockerfile
  • switch to go mod
Documentation changes:
  • remove instability warning: this works well enough
  • README: replace branch name master by main in links
  • tweak mention of libreoffice to clarify concern
  • replace "kobo" references by "nickel" where appropriate
  • make a section about related projects
  • mention NickelMenu
  • quick review of the koreader implementation
Bugfixes:
  • handle errors in http request creation
  • Use OutputDir configuration instead of hardcoded wallabako paths
  • do not noisily fail if there's no entry for book in plato
  • regression: properly detect read status again after koreader (or plato?) support was added

How do I use this?
This is amazing. I can't believe someone did something that awesome. I want to cover you with gold and Tesla cars and fresh water.
You're weird please stop. But if you want to use Wallabako, head over to the README file which has installation instructions. It basically uses a hack in Kobo e-readers that will happily overwrite their root filesystem as soon as you drop this file named KoboRoot.tgz in the .kobo directory of your e-reader. Note that there is no uninstall procedure and it messes with the reader's udev configuration (to trigger runs on wifi connect). You'll also need to create a JSON configuration file and configure a client in Wallabag. And if you're looking for Wallabag hosting, Wallabag.it offers a 14-day free trial. You can also, obviously, host it yourself. Which is not the case for Pocket, even years after Mozilla bought the company. All this wouldn't actually be necessary if Pocket was open-source because Nickel actually ships with a Pocket client. Shame on you, Mozilla. But you still make an awesome browser, so keep doing that.

Dirk Eddelbuettel: RQuantLib 0.4.16 on CRAN: Small Updates

A new release 0.4.16 of RQuantLib arrived at CRAN earlier today, and has been uploaded to Debian as well. QuantLib is a very comprehensice free/open-source library for quantitative finance; RQuantLib connects it to the R environment and language. The release of RQuantLib comes agaain about four months after the previous release, and brings a a few small updates for daycounters, all thanks to Kai Lin, plus a small parameter change to avoid an error in an example, and small updates to the Docker files.

Changes in RQuantLib version 0.4.16 (2022-05-05)
  • Documentationn for daycounters was updated and extended (Kai Lin)
  • Deprecated daycounters were approtiately updated (Kai Lin)
  • One example parameterization was changed to avoid error (Dirk)
  • The Docker files were updated

Courtesy of my CRANberries, there is also a diffstat report for the this release. As always, more detailed information is on the RQuantLib page. Questions, comments etc should go to the new rquantlib-devel mailing list. Issue tickets can be filed at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

5 May 2022

Reproducible Builds: Reproducible Builds in April 2022

Welcome to the April 2022 report from the Reproducible Builds project! In these reports, we try to summarise the most important things that we have been up to over the past month. If you are interested in contributing to the project, please take a few moments to visit our Contribute page on our website.

News Cory Doctorow published an interesting article this month about the possibility of Undetectable backdoors for machine learning models. Given that machine learning models can provide unpredictably incorrect results, Doctorow recounts that there exists another category of adversarial examples that comprise a gimmicked machine-learning input that, to the human eye, seems totally normal but which causes the ML system to misfire dramatically that permit the possibility of planting undetectable back doors into any machine learning system at training time .
Chris Lamb published two supporter spotlights on our blog: the first about Amateur Radio Digital Communications (ARDC) and the second about the Google Open Source Security Team (GOSST).
Piergiorgio Ladisa, Henrik Plate, Matias Martinez and Olivier Barais published a new academic paper titled A Taxonomy of Attacks on Open-Source Software Supply Chains (PDF):
This work proposes a general taxonomy for attacks on open-source supply chains, independent of specific programming languages or ecosystems, and covering all supply chain stages from code contributions to package distribution. Taking the form of an attack tree, it covers 107 unique vectors, linked to 94 real-world incidents, and mapped to 33 mitigating safeguards.

Elsewhere in academia, Ly Vu Duc published his PhD thesis. Titled Towards Understanding and Securing the OSS Supply Chain (PDF), Duc s abstract reads as follows:
This dissertation starts from the first link in the software supply chain, developers . Since many developers do not update their vulnerable software libraries, thus exposing the user of their code to security risks. To understand how they choose, manage and update the libraries, packages, and other Open-Source Software (OSS) that become the building blocks of companies completed products consumed by end-users, twenty-five semi-structured interviews were conducted with developers of both large and small-medium enterprises in nine countries. All interviews were transcribed, coded, and analyzed according to applied thematic analysis

Upstream news Filippo Valsorda published an informative blog post recently called How Go Mitigates Supply Chain Attacks outlining the high-level features of the Go ecosystem that helps prevent various supply-chain attacks.
There was new/further activity on a pull request filed against openssl by Sebastian Andrzej Siewior in order to prevent saved CFLAGS (which may contain the -fdebug-prefix-map=<PATH> flag that is used to strip an arbitrary the build path from the debug info if this information remains recorded then the binary is no longer reproducible if the build directory changes.

Events The Linux Foundation s SupplyChainSecurityCon, will take place June 21st 24th 2022, both virtually and in Austin, Texas. Long-time Reproducible Builds and openSUSE contributor Bernhard M. Wiedemann learned that he had his talk accepted, and will speak on Reproducible Builds: Unexpected Benefits and Problems on June 21st.
There will be an in-person Debian Reunion in Hamburg, Germany later this year, taking place from 23 30 May. Although this is a Debian event, there will be some folks from the broader Reproducible Builds community and, of course, everyone is welcome. Please see the event page on the Debian wiki for more information. 41 people have registered so far, and there s approx 10 on-site beds still left.
The minutes and logs from our April 2022 IRC meeting have been published. In case you missed this one, our next IRC meeting will take place on May 31st at 15:00 UTC on #reproducible-builds on the OFTC network.

Debian Roland Clobus wrote another in-depth status update about the status of live Debian images, summarising the current situation that all major desktops build reproducibly with bullseye, bookworm and sid, including the Cinnamon desktop on bookworm and sid, but at a small functionality cost: 14 words will be incorrectly abbreviated . This work incorporated:
  • Reporting an issue about unnecessarily modified timestamps in the daily Debian installer images. [ ]
  • Reporting a bug against the debian-installer: in order to use a suitable kernel version. (#1006800)
  • Reporting a bug in: texlive-binaries regarding the unreproducible content of .fmt files. (#1009196)
  • Adding hacks to make the Cinnamon desktop image reproducible in bookworm and sid. [ ]
  • Added a script to rebuild a live-build ISO image from a given timestamp. [
  • etc.
On our mailing list, Venkata Pyla started a thread on the Debian debconf cache is non-reproducible issue while creating system images and Vagrant Cascadian posted an excellent summary of the reproducibility status of core package sets in Debian and solicited for similar information from other distributions.
Lastly, 122 reviews of Debian packages were added, 44 were updated and 193 were removed this month adding to our extensive knowledge about identified issues. A number of issue types have been updated as well, including timestamps_generated_by_hevea, randomness_in_ocaml_preprocessed_files, build_path_captured_in_emacs_el_file, golang_compiler_captures_build_path_in_binary and build_path_captured_in_assembly_objects,

Other distributions Happy birthday to GNU Guix, which recently turned 10 years old! People have been sharing their stories, in which reproducible builds and bootstrappable builds are a recurring theme as a feature important to its users and developers. The experiences are available on the GNU Guix blog as well as a post on fossandcrafts.org
In openSUSE, Bernhard M. Wiedemann posted his usual monthly reproducible builds status report.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb prepared and uploaded versions 210 and 211 to Debian unstable, as well as noticed that some Python .pyc files are reported as data, so we should support .pyc as a fallback filename extension [ ]. In addition, Mattia Rizzolo disabled the Gnumeric tests in Debian as the package is not currently available [ ] and dropped mplayer from Build-Depends too [ ]. In addition, Mattia fixed an issue to ensure that the PATH environment variable is properly modified for all actions, not just when running the comparator. [ ]

Testing framework The Reproducible Builds project runs a significant testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
  • Daniel Golle:
    • Prefer a different solution to avoid building all OpenWrt packages; skip packages from optional community feeds. [ ]
  • Holger Levsen:
    • Detect Python deprecation warnings in the node health check. [ ]
    • Detect failure to build the Debian Installer. [ ]
  • Mattia Rizzolo:
    • Install disorderfs for building OpenWrt packages. [ ]
  • Paul Spooren (OpenWrt-related changes):
    • Don t build all packages whilst the core packages are not yet reproducible. [ ]
    • Add a missing RUN directive to node_cleanup. [ ]
    • Be less verbose during a toolchain build. [ ]
    • Use disorderfs for rebuilds and update the documentation to match. [ ][ ][ ]
  • Roland Clobus:
    • Publish the last reproducible Debian ISO image. [ ]
    • Use the rebuild.sh script from the live-build package. [ ]
Lastly, node maintenance was also performed by Holger Levsen [ ][ ].
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Next.

Previous.