Search Results: "reg"

21 August 2021

Dirk Eddelbuettel: RcppFastFloat 0.0.3: Maintenance

The third release of RcppFastFloat arrived on CRAN. The package wraps fastfloat, another nice library by Daniel Lemire. For details, see the recent arXiv paper showing that one can convert character representations of numbers into floating point at rates at or exceeding one gigabyte per second. This release deals with a header include on everybody s favourite CRAN platform bringing the result status to a clean suite of all OKs.

Changes in version 0.0.3 (2021-08-21)
  • Account for SunOS with an additional #define
  • Minor update to DESCRIPTION

Courtesy of my CRANberries, there is also a diffstat report for this release. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

19 August 2021

Jonathan Dowland: Budgeting tools

YNAB On the advice of many friends, I tried to use You Need A Budget. I gave it a seriously long, proper evaluation: over a year. But I just couldn't get it to work for me. I don't want to try and explain why. To be honest, those same friends who advocated for it fairly strongly, also gave me a pretty hard time for giving up on it! Despite it not clicking for me, there are a few concepts from YNAB that I quite like: GNUCash Jimmy Kaplowitz suggested back in 2012 that I should take a look at GNUCash. It took me a few more years before I did. The eventual trigger point for me was organising an event where I paid for a load of things on behalf of others and needed to track who had paid me back. It excelled for that. I've continued to use GNUCash to manage my personal money that is, my "play money" and anything I've accumulated but I haven't committed to it for my family finances. Practically speaking that would lock my wife out of them, which wouldn't be fair. But also because GNUCash's shortcomings (and despite its strengths, it certainly has some) mean that I don't expect I will be using it into the indefinite future, even for my personal stuff. The most significant drawback, in my opinion, is GNUCash's support for scripting. Sometimes, there's a laborious but easily-mechanisable (in theory) task I need to perform that would be ideal to script. GNUCash has built-in scripting support using Guile the GNU lisp/scheme dialect but this is limited to Reports only, I don't think it can be used for a task such as "match a series of transactions using one or more filters or regular expressions, and apply a transformation to them, such as change the account to which they are posted", etc. It also has a C library and auto-generated bindings for other languages. This has a horrible API, which is carried over into the language bindings. Documentation for the whole lot is basically non-existent too. Plain-text accounting For that reason I set out to find some better tools. There's a lot of interest and activity in plain-text accounting (PTA), including tools such as beancount, ledger or the Haskell re-implementation hledger. In a future post I'll write about PTA and hledger.

17 August 2021

Russ Allbery: Review: Black Sun

Review: Black Sun, by Rebecca Roanhorse
Series: Between Earth and Sky #1
Publisher: Saga Press
Copyright: October 2020
ISBN: 1-5344-3769-X
Format: Kindle
Pages: 454
Serapio has been crafted and trained to be the vessel for a god. He grew up in Obregi land, far from his ancestral home, but he will return to Tova at the appropriate time and carry the hopes of the Carrion Crow clan with him. Xiala is a ship captain, a woman, and a Teek. That means she's a target. Teek have magic, which makes them uncanny and dangerous. They're also said to carry that magic in their bones, which makes them valuable in ways that are not pleasant for the Teek. Running afoul of the moral codes of Cuecola is therefore even more dangerous to her than it would be to others, which is why she accepts a bargain to run errands for a local lord for twelve years, paid at the end of that time with ownership of a ship and crew. The first task: ferry a strange man to the city of Tova. Meanwhile, in Tova, the priestess Naranpa has clawed her way to the top of the Sky Made hierarchy from an inauspicious beginning in the poor district of Coyote's Maw. She's ruthlessly separated herself from her despised beginnings and focused her attention on calming Tova in advance of the convergence, a rare astronomical alignment at the same time as the winter solstice. But Carrion Crow holds a deep-seated grudge at their slaughter by the priesthood during the Night of Knives, and Naranpa's position atop the religious order that partly rules Tova's fractious politics is more precarious than she thinks. I am delighted that more fantasy is drawing on mythologies and histories other than the genre default of western European. It's long overdue for numerous reasons and a trend to be rewarded. But do authors writing fantasy in English who reach for Mesoamerican cultures have to gleefully embrace the excuse to add more torture? I'm developing an aversion to this setting (which I do not want to do!) because every book seems to feature human sacrifice, dismemberment, or some other horror show. Roanhorse at least does not fill the book with that (there's lingering child abuse but nothing as sickening as the first chapter), but that makes the authorial choice to make the torture one's first impression of this book even odder. Our introduction to Serapio is a scene that I would have preferred to have never read, and I don't think it even adds much to the plot. Huge warnings for people who don't want to read about a mother torturing her son, or about eyes in that context. Once past that introduction, Black Sun settles into a two-thread fantasy, one following Xiala and Serapio's sea voyage and the other following Naranpa and the political machinations in Tova. Both the magic systems and the political systems are different enough to be refreshing, and there are a few bits of world-building I enjoyed (a city built on top of rocks separated by deep canyons and connected with bridges, giant intelligent riding crows, everything about the Teek). My problem was that I didn't care what happened to any of the characters. Naranpa spends most of the book dithering and whining despite a backstory that should have promised more dynamic and decisive responses. The other character from Tova introduced somewhat later in the book is clearly "character whose story will appear in the next volume"; here, he's just station-keeping and representing the status quo. And while it's realistic given the plot that Serapio is an abused sociopath, that didn't mean I enjoyed reading his viewpoint or his childhood abuse. Xiala is the best character in the book by far and I was warming to the careful work she has to do to win over an unknown crew, but apparently Roanhorse was not interested in that. Instead, the focus of Xiala's characterization turns to a bad-boy romance that did absolutely nothing for me. This will be a matter of personal taste; I know this is a plot feature for many readers. But it had me rolling my eyes and turning the pages to get to something more interesting (which, sadly, was not forthcoming). It also plays heavily on magical disabled person cliches, like the blind man being the best fighter anyone has met. I did not enjoy this book very much, but there were some neat bits of world-building and I could see why other people might disagree. What pushed me into actively recommending against it (at least for now) is the publishing structure. This is the first book of a trilogy, so one can expect the major plot to not be resolved by the end of the book. But part of the contract with the reader when publishing a book series is that each volume should reach some sense of closure and catharsis. There will be cliffhangers and unanswered questions, but there should also be enough plot lines that are satisfactorily resolved to warrant publishing a book as a separate novel. There is none of that here. This is the first half (or third) of a novel. It introduces a bunch of plot lines, pulls them together, describes an intermediate crisis, and then simply stops. Not a single plot line is resolved. This is made worse by the fact this series (presumably, as I have only seen the first book) has a U-shaped plot: everything gets worse and worse until some point of crisis, and then presumably the protagonists will get their shit together and things will start to improve. I have soured on U-shaped plots since the first half of the story often feels like a tedious grind (eat your vegetables and then you can have dessert), but it's made much worse by cutting the book off at the bottom of the U. You get a volume, like Black Sun, that's all setup and horror and collapse, with no payoff or optimism. After two tries, I have concluded that Roanhorse is not for me. This is clearly a me problem rather than a Roanhorse problem, given how many other people love both Black Sun and her Sixth World series, but this is the second book of hers where I mildly enjoyed the world building but didn't care about any of the characters. Ah well, tastes will differ. Even if you get along with Roanhorse, though, I recommend against starting this book until the second half of it is published (currently scheduled for 2022). As it stands, it's a wholly unsatisfying reading experience. Followed by the not-yet-published Fevered Star. Rating: 4 out of 10

15 August 2021

Dirk Eddelbuettel: RcppBDT 0.2.4 on CRAN: Updates

After a seven-year break (!!), the RcppBDT packages has been updated on CRAN. The RcppBDT package is an early adopter of Rcpp and was one of the first packages utilizing Boost and its Date_Time library. The now more widely-used package anytime is a direct descentant of RcppBDT. In fact, the last time RcppBDT was released, anytime did not yet exist. And some of the changes now finally released here in this version are some of the first steps made towards what became anytime. RcppBDT is broader in scope and provides a wider range of functionality but in a somewhat rougher form as we never sat down writing higher-end wrappers in R for all the potential use cases. When we wrote the first RcppBDT versions, many other popular date/time packages were all in R code and not compiled, and this package showed how things could be done at the compiled level. Now other packages, including anytime have filled the void so fully polishing RcppBDT may never happen. In any event, this release refreshes the package and brings it to full R CMD check --as-cran compliance. The NEWS entry follows:

Changes in version 0.2.4 (2021-08-15)
  • New utility function toPOSIXct which can take multitple input format (integer, floating point or character) vectors and can convert by relying on a wide variety of standard formats. This predates what has long been split off into a new package anytime which is more functional and feaureful.
  • New demo 'toPOSIXct' illustrating the feature.
  • New demo 'toPOSIXctTiming' benchmarking it.
  • Documentation for new functions was added as well.
  • CI now uses run.sh from r-ci.
  • Functions getLastDayOfWeekInMonth and getFirstDayOfWeekInMonth now use dow argument.
  • The shared library is now registered when loaded from NAMESPACE.
  • C level entry points are now registered as R now recommends.
  • Several badges were added to the README.md file.
  • Several fields were added to the DESCRIPTION file, and/or updated.
  • Documentation URLs where both updated as needed and converted to https.

Courtesy of my CRANberries, there is also a diffstat report for this release. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

14 August 2021

Andy Simpkins: Debian Bullseye Released

Wow. It is 21:49 in the evening here (I am with isy and sledge in Cambridge) and image testing has completed! The images are being signed, and sledge is running through the final steps to push them out to our servers, and from there out onto the mirror and torrent networks to be available for public download.

We have had help testing installation images from the regular team; amacater and schweer. With schweer, as ever, covering the edu images. Thank you. This release we were joined by bitin who kindly ran through a couple of tests of the default netinst image with both UEFI and BIOS based VMs, before joining a release party. Moving onto the live images, linux-fan once again spent time testing i386 images on vintage hardware. Getting a desktop environment to work on a Pentium (4?) machine with 1GiB RAM from a live-image sees the number of desktops that will run in this environment get fewer all the time. Again highvoltage was around to run tests on some of the images.

liz, contributed for the first time indeed raised her first bug report as well. I hope that you had fun thanks for joining us today. smcv, also joined in the testing fun a long time DD is this the first time you have run through image smoke tests on release day? thanks! Many thanks to everyone taking time to test installation and live images. Of cause building and testing images doesn t happen in isolation. There is a huge team that puts together and releases the project that is Debin .
On a release day there are many teams working flat out: dsa, ftp, publicity, release, web, and ourselves as the cd/images team.
But that is just activity on a release day
There are all the other teams that are needed to produce the distribution, who work tirelessly day in, day out. Curating the 1,152,960,944 lines of code in Debian bullseye are over more than 6,208 people!!
Some of the contributors are shown in https://contributors.debian.org/contributors/flat
THANK YOU In the 15 minutes it has taken me to compile this post (many thanks to cnote and jmw for facts and figures they published on debian micronews), the last of the image release process has completed by sledge and that s it. Installation images for Debian 11 Bullseye are out in the big wide world, joining the official archives that became available at 10:35 this morning.

Dirk Eddelbuettel: RApiDatetime 0.0.5 (and 0.0.6): Updated (Twice)

After nearly two years, the RApiDatetime package on CRAN has received an update, followed-up a quick bug fix. RApiDatetime provides a number of entry points for C-level functions of the R API for Date and Datetime calculations. The functions asPOSIXlt and asPOSIXct convert between long and compact datetime representation, formatPOSIXlt and Rstrptime convert to and from character strings, and POSIXlt2D and D2POSIXlt convert between Date and POSIXlt datetime. Lastly, asDatePOSIXct converts to a date type. All these functions are rather useful, but were not previously exported by R for C-level use by other packages. Which this package aims to change. This pair of releases updates the code to the current R-devel standard, and refreshes a few standard packaging aspects starting from making builds on the Windows UCRT platform possible. And while making an accomodation for one beloved architecture (in release 0.0.5), we introduced another issue on another almost equally beloved platform which 0.0.6 clears up. It should be ready and stable now.

Changes in RApiDatetime version 0.0.6 (2021-08-13)
  • Correctly account for SunOS to have it avoid GMTOFF use
  • A new test file was added to ensure NEWS.Rd is always at the current release version.

Changes in RApiDatetime version 0.0.5 (2021-08-05)
  • Add a few #nocov tags
  • Update continuous integration to use r-ci, reenable coverage
  • Update DESCRIPTION with URL and BugReports fields
  • Add new CI and LastCommitted badges to README.md
  • Add compiler flag for Windows UCRT build
  • Synchronized datetime function with upstream r-devel code

Courtesy of my CRANberries, there is are comparisons to the previous release 0.0.5, and 0.0.4, respectively. More information is on the rapidatetime page. For questions or comments please use the issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Gunnar Wolf: Bullseye arrives. Private ARM64 install fest!

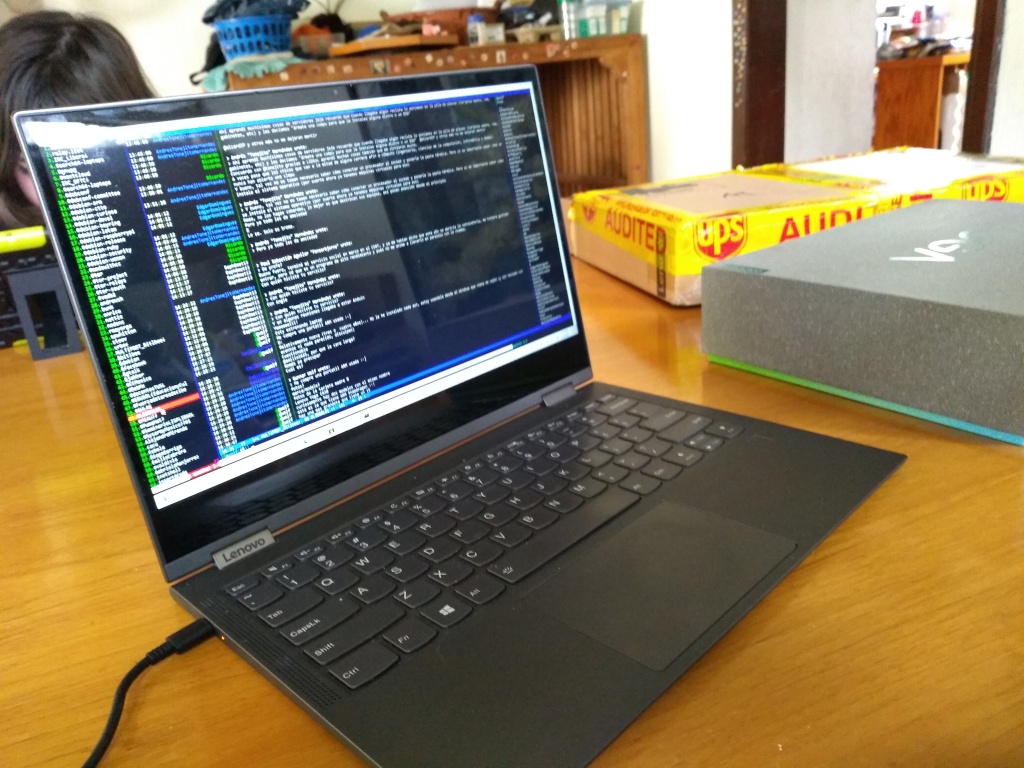
So today is the day when a new Debian release comes out! Congratulations to everybody, and thanks a lot mainly to the Release Team. Lots of very hard work was put into making Debian 11 Bullseye a reality! My very personal way to celebrate this was to do a somewhat different Debian install at home. Why different? Well, I have quite a bit of old, older and frankly elderly laptops at home. And as many of you know, I have done more than my fair share of Raspberry Pi installs I have played and worked with assorted ARM machines at least since 2013, and I cannot consider myself a newbie with them by any means. But this is the first time I installed Debian on a mass-market, decently-specced ARM64-based laptop. Yes, I know the Pinebook has been there like for ages, but it really does feel like a computer to show off and not to use seriously (and I ve seen probably too many people fiddling with it, unable to get $foo to work). So I got myself a used Lenovo Yoga C630. Yes, a discontinued product it seems Lenovo was not able to properly market this machine, and it had a pretty short shelf life the machine was available for samples in late 2018 and for general sale in 2019! The specs are quite decent: Installing it via an almost-standard debian-installer is almost straightforward does require the installer to know what he is doing but is not too different from a regular Debian install. The AArch64 laptops project has done quite a feat in getting a d-i image ready to be inserted as a USB drive, and comprehensive instructions to help through the process. The shipped scripts even reap the Windows partition for the firmware images! I have reduced Windows to 25GB, but having only a 128GB drive, it still is a little bit too much.. I guess I ll blow it away sooner rather than later. The installer image has a regular GNOME install, which works beautifully, but I promptly replaced it with i3, as it s fundamental for me to work happily. Of course, the computer has quirks, more than I d expect from a regular x86 system, but well within what I expected to achieve during my first day with it. The issues I have most noted are: Of course, more quirks will surely appear with use. And I ll start trying to address some of them. So Happy Bullseye! Happy Debian 11! Enjoy a great release! \o/

12 August 2021

Dirk Eddelbuettel: x13binary 1.1.57-2 on CRAN: Packaging Updates

Release 1.1.57-2 of the x13binary package providing the X-13ARIMA-SEATS program by the US Census Bureau is now on CRAN. This release comes a mere week after the previous release 1.1.57-1 and cleans up two packaging aspects. It corrects a (non-bash) shell script snippet for SunOS, and turns off the prohibition of staged install (which was needed a while back for macOS). No other changes were made; please see last week s release post for more about x13binary and the 1.1.57 release. Courtesy of my CRANberries, there is also a diffstat report for this release showing changes to the previous release. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

11 August 2021

Bits from Debian: Debian User Forums changes and updates.

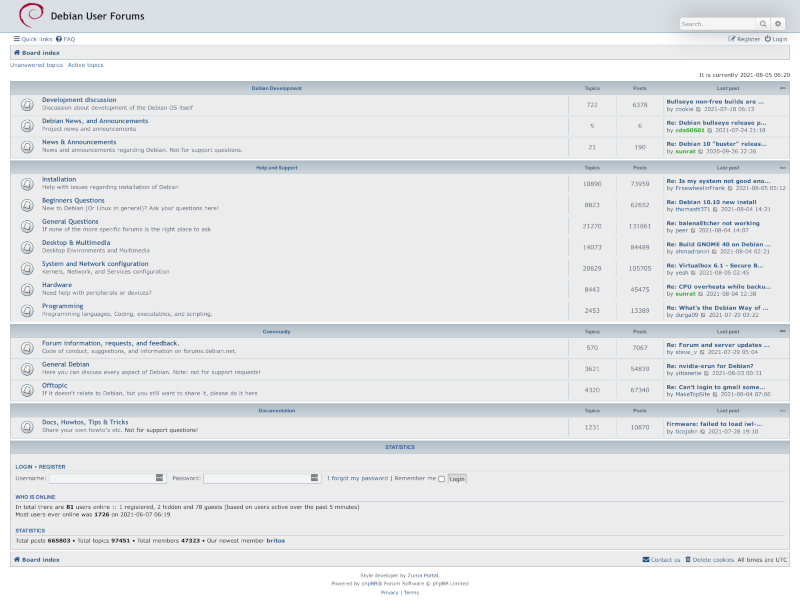
DebianUserForums Several issues were brought before the Debian Community team regarding responsiveness, tone, and needed software updates to forums.debian.net. The question was asked, who s in charge? Over the course of the discussion several Debian Developers volunteered to help by providing a presence on the forums from Debian and to assist with the necessary changes to keep the service up and running. We are happy to announce the following changes to the (NEW!) forums.debian.net, which have and should address most of the prior concerns with accountability, tone, use, and reliability: Debian Developers: Paulo Henrique de Lima Santana (phls), Felix Lechner (lechner), and Donald Norwood (donald) have been added to the forum's Server and Administration teams. The server instance is now running directly within Debian's infrastructure. The forum software and back-end have been updated to the most recent versions where applicable. DNS resolves for both IPv4 and IPv6. SSL/HTTPS are enabled. (It s 2021!) New Captcha and Anti-spam systems are in place to thwart spammers, bots, and to make it easier for humans to register. New Administrators and Moderation staff were added to provide additional coverage across the hours and to combine years of experience with forum operation and Debian usage. New viewing styles are available for users to choose from, some of which are ideal for mobile/tablet viewing. We inadvertently fixed the time issue that the prior forum had of running 11 minutes fast. :) We have clarified staff roles and staff visibility. Responsiveness to users on the forums has increased. Email addresses for mods/admins have been updated and checked for validity, it has seen direct use and response. The guidelines for forum use by users and staff have been updated. The Debian COC has been made into a Global Announcement as an accompanyist to the newly updated guidelines to give the moderators/administrators an additional rule-set for unruly or unbecoming behavior. Some of the discussion areas have been renamed and refocused, along with the movement of multiple threads to make indexing and searching of the forums easier. Many (New!) features and extensions have been added to the forum for ease of use and modernization, such as a user thanks system and thread hover previews. There are some server administrative tasks that were upgraded as well which don't belong on a public list, but we are backing up regularly and secure. :) We have a few minor details here and there to attend to and the work is ongoing. Many Thanks and Appreciation to the Debian System Administrators (DSA) and Ganneff who took the time to coordinate and assist with the instance, DNS, and network and server administration minutiae, our helpful DPL Jonathan Carter, many thanks to the current and prior forum moderators and administrators: Mez, sunrat, 4D696B65, arochester, and cds60601 for helping with the modifications and transition, and to the forum users who participated in lots of the tweaking. All in all this was a large community task and everyone did a significant part. Thank you!

10 August 2021

Shirish Agarwal: BBI, IP report, State Borders and Civil Aviation I

If I have seen further, it is by standing on the shoulders of Giants Issac Newton, 1675. Although it should be credited to 12th century Bernard of Chartres. You will know why I have shared this, probably at the beginning of Civil Aviation history itself.

Comments on the BBI court case which happened in Kenya, then and the subsequent appeal. I am not going to share much about the coverage of the BBI appeal as Gautam Bhatia has shared quite eloquently his observations, both on the initial case and the subsequent appeal which lasted 5 days in Kenya and was shown all around the world thanks to YouTube. One of the interesting points which stuck with me was that in Kenya, sign language is one of the official languages. And in fact, I was able to read quite a bit about the various sign languages which are there in Kenya. It just boggles the mind that there are countries that also give importance to such even though they are not as rich or as developed as we call developed economies. I probably might give more space and give more depth as it does carry some important judicial jurisprudence which is and which will be felt around the world. How does India react or doesn t is probably another matter altogether  But yes, it needs it own space, maybe after some more time. Report on Standing Committee on IP Regulation in India and the false promises. Again, I do not want to take much time in sharing details about what the report contains, as the report can be found here. I have uploaded it on WordPress, in case of an issue. An observation on the same subject can be found here. At least, to me and probably those who have been following the IP space as either using/working on free software or even IP would be aware that the issues shared have been known since 1994. And it does benefit the industry rather than the country. This way, the rent-seekers, and monopolists win. There is ample literature that shared how rich countries had weak regulation for decades and even centuries till it was advantageous for them to have strong IP. One can look at the history of Europe and the United States for it. We can also look at the history of our neighbor China, which for the last 5 decades has used some provision of IP and disregarded many others. But these words are of no use, as the policies done and shared are by the rich for the rich.

Fighting between two State Borders Ironically or because of it, two BJP ruled states Assam and Mizoram fought between themselves. In which 6 policemen died. While the history of the two states is complicated it becomes a bit more complicated when one goes back into Assam and ULFA history and comes to know that ULFA could not have become that powerful until and unless, the Marwaris, people of my clan had not given generous donations to them. They thought it was a good investment, which later would turn out to be untrue. Those who think ULFA has declined, or whatever, still don t have answers to this or this. Interestingly, both the Chief Ministers approached the Home Minister (Mr. Amit Shah) of BJP. Mr. Shah was supposed to be the Chanakya but in many instances, including this one, he decided to stay away. His statement was on the lines of you guys figure it out yourself. There is a poem that was shared by the late poet Rahat Indori. I am sharing the same below as an image and will attempt to put a rough translation.
kisi ke baap ka hindustan todi hain Rahat Indori
Poets, whether in India or elsewhere, are known to speak truth to power and are a bit of a rebel. This poem by Rahat Indori is provocatively titled Kisi ke baap ka Hindustan todi hai , It challenges the majoritarian idea that Hindustan/India only belongs to the majoritarian religion. He also challenges as well as asserts at the same time that every Indian citizen, regardless of whatever his or her religion might be, is an Indian and can assert India as his home. While the whole poem is compelling in itself, for me what hits home is in the second stanza

:Lagegi Aag to aayege ghat kayi zad me, Yaha pe sirf hamara makan todi hai The meaning is simple yet subtle, he uses Aag or Fire as a symbol of hate sharing that if hate spreads, it won t be his home alone that will be torched. If one wants to literally understand what he meant, I present to you the cult Russian movie No Escapes or Ogon as it is known in Russian. If one were to decipher why the Russian film doesn t talk about climate change, one has to view it from the prism of what their leader Vladimir Putin has said and done over the years. As can be seen even in there, the situation is far more complex than one imagines. Although, it is interesting to note that he decried Climate change as man-made till as late as last year and was on the side of Trump throughout his presidency. This was in 2017 as well as perhaps this. Interestingly, there was a change in tenor and note just a couple of weeks back, but that could be only politicking or much more. Statements that are not backed by legislation and application are usually just a whitewash. We would have to wait to see what concrete steps are taken by Putin, Kremlin, and their Duma before saying either way.

Civil Aviation and the broad structure Civil Aviation is a large topic and I would not be able to do justice to it all in one article/blog post. So, for e.g. I will not be getting into Aircraft (Boeing, Airbus, Comac etc., etc.) or the new electric aircraft as that will just make the blog post long. I will not be also talking about cargo or Visa or many such topics, as all of them actually would and do need their own space. So this would be much more limited to Airports and to some extent airlines, as one cannot survive without the other. The primary reason for doing this is there is and has been a lot of myth-making in India about Civil Aviation in general, whether it has to do with Civil Aviation history or whatever passes as of policy in India.

A little early history Man has always looked at the stars and envisaged himself or herself as a bird, flying with gay abandon. In fact, there have been many paintings, sculptors who imagined how we would fly. The Steam Engine itself was invented in 82 BCE. But the attempt to fly was done by a certain Monk called Brother Elmer of Malmesbury who attempted the same in 1010., shortly after the birth of the rudimentary steam engine The most famous of all would be Leonardo da Vinci for his amazing sketches of flying machines in 1493. There were a couple of books by Cyrano de Bergerac, apparently wrote two books, both sadly published after his death. Interestingly, you can find both the book and the gentleman in the Project Gutenberg archives. How much of M/s Cyrano s exploits were his own and how much embellished by M/S Curtis, maybe a friend, a lover who knows, but it does give the air of the swashbuckling adventurer of the time which many men aspired to in that time. So, why not an author???

L Autre Monde: ou les tats et Empires de la Lune (Comical History of the States and Empires of the Moon) and Les tats et Empires du Soleil (The States and Empires of the Sun). These two French books apparently had a lot of references to flying machines. Both of them were authored by Cyrano de Bergerac. Both of these were sadly published after his death, one apparently in 1656 and the other one a couple of years later. By the 17th century, while it had become easy to know and measure the latitude, measuring longitude was a problem. In fact, it can be argued and probably successfully that India wouldn t have been under British rule or UK wouldn t have been a naval superpower if it hadn t solved the longitudinal problem. Over the years, the British Royal Navy suffered many blows, one of the most famous or infamous among them might be the Scilly naval disaster of 1707 which led to the death of 2000 odd British Royal naval personnel and led to Queen Anne, who was ruling over England at that time via Parliament and called it the Longitude Act which basically was an open competition for anybody to fix the problem and carried the prize money of 20,000. While nobody could claim the whole prize, many did get smaller amounts depending upon the achievements. The best and the nearest who came was John Harrison who made the first sea-watch and with modifications, over the years it became miniaturized to a pocket-sized Marine chronometer although, I doubt the ones used today look anything in those days. But if that had not been invented, we surely would have been freed long ago. The assumption being that the East India Company would have dashed onto rocks so many times, that the whole exercise would have been futile. The downside of it is that maritime trade routes that are being used today and the commerce would not have been. Neither would have aircraft or space for that matter, or at the very least delayed by how many years or decades, nobody knows. If one wants to read about the Longitudinal problem, one can get the famous book Longitude .

In many mythologies, including Indian and Arabian tales, in which we had the flying carpet which would let its passengers go from one place to the next. Then there is also mention of Pushpak Vimana in ancient texts, but those secrets remain secrets. Think how much foreign exchange India could make by both using it and exporting the same worldwide. And I m being serious. There are many who believe in it, but sadly, the ones who know the secret don t seem to want India s progress. Just think of the carbon credits that India could have, which itself would make India a superpower. And I m being serious.

Western Ideas and Implementation. Even in the late and early 18th century, there were many machines that were designed to have controlled flight, but it was only the Wright Flyer that was able to demonstrate a controlled flight in 1903. The ones who came pretty close to what the Wrights achieved were the people by the name of Cayley and Langley. They actually studied what the pioneers had done. They looked at what Otto Lilienthal had done, as he had done a lot of hang-gliding and put a lot of literature in the public domain then.

Furthermore, they also consulted Octave Chanute. The whole system and history of the same are a bit complicated, but it does give a window to what happened then. So, it won t be wrong to say that whatever the Wright Brothers accomplished would probably not have been possible or would have taken years or maybe even decades if that literature and experiments, drawings, etc. in the commons were not available. So, while they did experimentation, they also looked at what other people were doing and had done which was in public domain/commons.

They also did a lot of testing, which gave them new insights. Even the propulsion system they used in the 1903 flight was a design by Nicolaus Otto. In fact, the Aircraft would not have been born if the Chinese had not invented kites in the early sixth century A.D. One also has to credit Issac Newton because of the three laws of motion, again without which none of the above could have happened. What is credited to the Wilbur brothers is not just they made the Kitty Hawk, they also made it commercial as they sold it and variations of the design to the American Air Force and also made a pilot school where pilots were trained for warfighting. 119 odd pilots came out of that school. The Wrights thought that air supremacy would end the war early, but this turned out to be a false hope.

Competition and Those Magnificent Men and their flying machines One of the first competitions to unlock creativity was the English Channel crossing offer made by Daily Mail. This was successfully done by the Frenchman Louis Bl riot. You can read his account here. There were quite a few competitions before World War 1 broke out. There is a beautiful, humorous movie that does dedicate itself to imagining how things would have gone in that time. In fact, there have been two movies, this one and an earlier movie called Sky Riders made many a youth dream. The other movie sadly is not yet in the public domain, and when it will be nobody knows, but if you see it or even read it, it gives you goosebumps.

World War 1 and Improvements to Aircraft World War 1 is remembered as the Great War or the War to end all wars in an attempt at irony. It did a lot of destruction of both people and property, and in fact, laid the foundation of World War 2. At the same time, if World War 1 hadn t happened then Airpower, Plane technology would have taken decades. Even medicine and medical techniques became revolutionary due to World War 1. In order to be brief, I am not sharing much about World War 1 otherwise that itself would become its own blog post. And while it had its heroes and villains who, when, why could be tackled perhaps another time.

The Guggenheim Family and the birth of Civil Aviation If one has to credit one family for the birth of the Civil Aviation, it has to be the Guggenheim family. Again, I would not like to dwell much as much of their contribution has already been noted here. There are quite a few things still that need to be said and pointed out. First and foremost is the fact that they made lessons about flying from grade school to college and afterward till college and beyond which were in the syllabus, whereas in the Indian schooling system, there is nothing like that to date. Here, in India, even in Engineering courses, you don t have much info. Unless until you go for professional Aviation or Aeronautical courses and most of these courses cost a bomb so either the very rich or the very determined (with loans) only go for that, at least that s what my friends have shared. And there is no guarantee you will get a job after that, especially in today s climate. Even their fund, grants, and prizes which were given to people for various people so that improvements could be made to the United States Civil Aviation. This, as shared in the report/blog post shared, was in response to what the younger child/brother saw as Europe having a large advantage both in Military and Civil Aviation. They also made several grants in several Universities which would not only do notable work during their lifetime but carry on the legacy researching on different aspects of Aircraft. One point that should be noted is that Europe was far ahead even then of the U.S. which prompted the younger son. There had already been talks of civil/civilian flights on European routes, although much different from what either of us can imagine today. Even with everything that the U.S. had going for her and still has, Europe is the one which has better airports, better facilities, better everything than the U.S. has even today. If you look at the lists of the Airports for better value of money or facilities, you would find many Airports from Europe, some from Asia, and only a few from the U.S. even though they are some of the most frequent users of the service. But that debate and arguments I would have to leave for perhaps the next blog post as there is still a lot to be covered between the 1930s, 1950s, and today. The Guggenheims archives does a fantastic job of sharing part of the story till the 1950s, but there is also quite a bit which it doesn t. I will probably start from that in the next blog post and then carry on ahead. Lastly, before I wind up, I have to share why I felt the need to write, capture and share this part of Aviation history. The plain and simple reason being, many of the people I meet either on the web, on Twitter or even in real life, many of them are just unaware of how this whole thing came about. The unawareness in my fellow brothers and sisters is just shocking, overwhelming. At least, by sharing these articles, I at least would be able to guide them or at least let them know how it all came to be and where things are going and not just be so clueless. Till later.

9 August 2021

Dirk Eddelbuettel: nanotime 0.3.3 on CRAN: Some Updates

Leonardo and I are pleased to share that a new nanotime version 0.3.3 was released today, and arrived on CRAN. This release brings a new (plotting) demo, an updated documentation site, additional nanoduration and nanoperiod functionality, and enhanced testing. nanotime relies on the RcppCCTZ package for (efficient) high(er) resolution time parsing and formatting up to nanosecond resolution, and the bit64 package for the actual integer64 arithmetic. Initially implemented using the S3 system, it has benefitted greatly from work by co-author Leonardo who not only rejigged nanotime internals in S4 but also added new S4 types for periods, intervals and durations. The NEWS snippet adds full details.

Changes in version 0.3.3 (2021-08-09)
  • New demo ggplot2Example.R (Leonardo and Dirk).
  • New documentation website using mkdocs-material (Dirk).
  • Updated unit test to account for r-devel POSIXct changes, and re-enable full testing under r-devel (Dirk).
  • Additional nanoduration and character ops plus tests (Colin Umansky in #88 addressing #87).
  • New plus and minus functions for periods (Leonardo in #91).

Thanks to CRANberries there is also a diff to the previous version. More details and examples are at the nanotime page; code, issue tickets etc at the GitHub repository. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

4 August 2021

Dirk Eddelbuettel: x13binary 1.1.57-1 on CRAN: New Upstream, New M1 Binary

Christoph and I are please to share that a new release 1.1.57-1 of x13binary, of the X-13ARIMA-SEATS program by the US Census Bureau (with updated upstream release 1.1.57) is now on CRAN. The x13binary package takes the pain out of installing X-13ARIMA-SEATS by making it a fully resolved CRAN dependency. For example, when installing the excellent seasonal package by Christoph, then X-13ARIMA-SEATS will get pulled in via the x13binary package and things just work. Just depend on x13binary and on all major OSs supported by R you should have an X-13ARIMA-SEATS binary installed which will be called seamlessly by the higher-level packages such as seasonal or gunsales. With this the full power of the what is likely the world s most sophisticated deseasonalization and forecasting package is now at your fingertips and the R prompt, just like any other of the 17960+ CRAN packages. You can read more about this (and the seasonal package) in the Journal of Statistical Software paper by Christoph and myself. This release brings a new upstream release as well as binaries. We continue to support two Linux flavours (theh standard x86_64 as well as armv7l), windows and for a first time two macOS flavour. In addition to the existing Intel binary we now have a native built using the arm64 M1 chip (with thanks to Kirill for the assist). We still lack a genuine binary for Solaris so if any of the esteemed readers of this post happens to have access to R on Solaris along with a basic Fortran compiler, we would love to hear from you. Building X-13ARIMA-SEATS from source on Solaris should be straightforward as it is on the other OSs. Or is someone with a bit of time wants to help following Gabor s tutorial we would greatly appreciate it. Courtesy of my CRANberries, there is also a diffstat report for this release showing changes to the previous release. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Petter Reinholdtsen: Mechanic's words in five languages, English, Norwegian and Northern S mi editions

Almost thirty years ago, some forward looking teachers at Samisk videreg ende skole og reindriftsskole teaching metal work and Northern S mi, decided to create a list of words used in Northern S mi metal work. After almost ten years this resulted in a dictionary database, published as the book "Mekanihkk rs nit : Mekanikerord = Mekaanisen alan sanasto = Mechanic's words" in 1999. The story of this work is available from the pen of Svein Lund, one of the leading actors behind this effort. They even got the dictionary approved by the S mi Language Council as the recommended metal work words to use. Fast forward twenty years, I came across this work when I recently became interested in metal work, and started watching educational and funny videos on the topic, like the ones from mrpete222 and This Old Tony. But they all talk English, but I wanted to know what the tools and techniques they used were called in Norwegian. Trying to track down a good dictionary from English to Norwegian, after much searching, I came across the database of words created almost thirty years ago, with translations into English, Norwegian, Northern S mi, Swedish and Finnish. This gave me a lot of the Norwegian phrases I had been looking for. To make it easier for the next person trying to track down a good Norwegian dictionary for the metal worker, and because I knew the person behind the database from my Skolelinux / Debian Edu days, I decided to ask if the database could be released to the public without any usage limitations, in other words as a Creative Commons licensed data set. And happily, after consulting with the S mi Parliament of Norway, the database is now available with the Creative Commons Attribution 4.0 International license from my gitlab repository. The dictionary entries look slightly different, depending on the language in focus. This is the same entry in the different editions. English
lathe
dreiebenk (nb) v rve, v rvenbea ka, jorahanbea ka, v tnanbea ka (se) svarv (sv) sorvi (fi)
Norwegian
dreiebenk
lathe (en) v rve, v rvenbea ka, jorahanbea ka, v tnanbea ka (se) svarv (sv) sorvi (fi)
(nb): sponskj rande bearbeidingsmaskin der ein med skj reverkt y lausgj r spon fr eit roterande arbetsstykke
Northern S mi
v rve, v rvenbea ka, jorahanbea ka, v tnanbea ka
dreiebenk (nb) lathe (en) svarv (sv) sorvi (fi)
(se): ma iidna mainna uohpp vuolahasaid jorri bargo vdnasis
(nb): sponskj rande bearbeidingsmaskin der ein med skj reverkt y lausgj r spon fr eit roterande arbetsstykke
The database included term description in both Norwegian and Northern S mi, but not English. Because of this, the Northern S mi edition include both descriptions, the Norwegian edition include the Norwegian description and the English edition lack a descripiton. Once the database was available without any usage restrictions, and armed with my experience in publishing books, I decided to publish a Norwegian/English dictionary as a book using the database, to make the data set available also on paper and as an ebook. Further into the project, it occurred to me that I could just as easily make an English dictionary, and talking to Svein and concluding that it was within reach, I decided to make a Northern S mi dictionary too. Thus I suddenly find myself publishing a Northern S mi dictionary, even though I do not understand the language myself. I hope it will be well received, and can help revive the impressive work done almost thirty years ago to document the vocabulary of metal workers. If I get some help, I might even extend it with some of the words I find missing, like collet, rotary broach, carbide, knurler, arbor press and others. But the first edition build from a lightly edited version of the original database, with no new entries added. If you would like to check it out, visit my list of published books and consider buying a paper or ebook copy from lulu.com. The paper edition is only available in hardcover to increase its durability in the workshop. I am very happy to report that in the process, and thanks to help from both Svein Lund and B rre Gaup who understand the language, the docbook tools I use to create books, dblatex and docbook-xsl, now include support for Northern S mi. Before I started, these lacked the needed locale settings for this language, but now the patches are included upstream. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

2 August 2021

Dirk Eddelbuettel: RcppFarmHash 0.0.2: Maintenance

A minor maintenance release of the new package RcppFarmHash, first released in version 0.0.1 a week ago, is now on CRAN in an version 0.0.2. RcppFarmHash wraps the Google FarmHash family of hash functions (written by Geoff Pike and contributors) that are used for example by Google BigQuery for the FARM_FINGERPRINT digest. This releases adds a #define which was needed on everybody s favourite CRAN platform to not attempt to include a missing header endian.h. With this added #define all is well as we can already tell from looking at the CRAN status where the three machines maintained by you-may-know-who have already built the package. The others will follow over the next few days. I also tweeted about the upload with a screenshot demonstrating an eight minute passage from upload to acceptance with the added #ThankYouCRAN tag to say thanks for very smooth and fully automated processing at their end. The very brief NEWS entry follows:

Changes in version 0.0.2 (2021-08-02)
  • On SunOS, set endianness to not error on #include endian.h
  • Add badges and installation notes to README as package is on CRAN

If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Colin Watson: Launchpad now runs on Python 3!

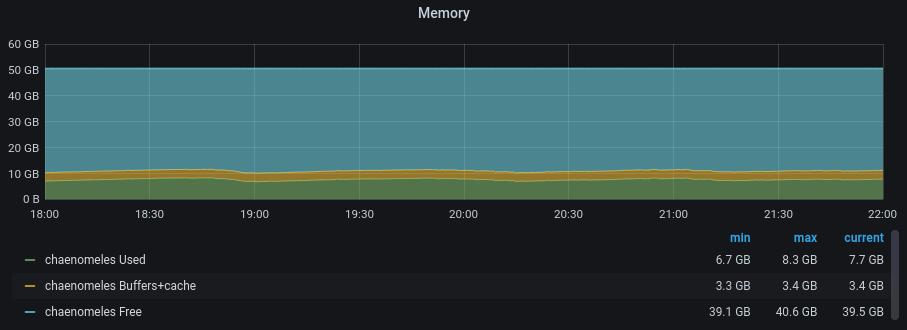
After a very long porting journey, Launchpad is finally running on Python 3 across all of our systems. I wanted to take a bit of time to reflect on why my emotional responses to this port differ so much from those of some others who ve done large ports, such as the Mercurial maintainers. It s hard to deny that we ve had to burn a lot of time on this, which I m sure has had an opportunity cost, and from one point of view it s essentially running to stand still: there is no single compelling feature that we get solely by porting to Python 3, although it s clearly a prerequisite for tidying up old compatibility code and being able to use modern language facilities in the future. And yet, on the whole, I found this a rewarding project and enjoyed doing it. Some of this may be because by inclination I m a maintenance programmer and actually enjoy this sort of thing. My default view tends to be that software version upgrades may be a pain but it s much better to get that pain over with as soon as you can rather than trying to hold back the tide; you can certainly get involved and try to shape where things end up, but rightly or wrongly I can t think of many cases when a righteously indignant user base managed to arrange for the old version to be maintained in perpetuity so that they never had to deal with the new thing (OK, maybe Perl 5 counts here). I think a more compelling difference between Launchpad and Mercurial, though, may be that very few other people really had a vested interest in what Python version Launchpad happened to be running, because it s all server-side code (aside from some client libraries such as launchpadlib, which were ported years ago). As such, we weren t trying to do this with the internet having Strong Opinions at us. We were doing this because it was obviously the only long-term-maintainable path forward, and in more recent times because some of our library dependencies were starting to drop support for Python 2 and so it was obviously going to become a practical problem for us sooner or later; but if we d just stayed on Python 2 forever then fundamentally hardly anyone else would really have cared directly, only maybe about some indirect consequences of that. I don t follow Mercurial development so I may be entirely off-base, but if other people were yelling at me about how late my project was to finish its port, that in itself would make me feel more negatively about the project even if I thought it was a good idea. Having most of the pressure come from ourselves rather than from outside meant that wasn t an issue for us. I m somewhat inclined to think of the process as an extreme version of paying down technical debt. Moving from Python 2.7 to 3.5, as we just did, means skipping over multiple language versions in one go, and if similar changes had been made more gradually it would probably have felt a lot more like the typical dependency update treadmill. I appreciate why not everyone might want to think of it this way: maybe this is just my own rationalization. Reflections on porting to Python 3 I m not going to defend the Python 3 migration process; it was pretty rough in a lot of ways. Nor am I going to spend much effort relitigating it here, as it s already been done to death elsewhere, and as I understand it the core Python developers have got the message loud and clear by now. At a bare minimum, a lot of valuable time was lost early in Python 3 s lifetime hanging on to flag-day-type porting strategies that were impractical for large projects, when it should have been providing for bilingual strategies (code that runs in both Python 2 and 3 for a transitional period) which is where most libraries and most large migrations ended up in practice. For instance, the early advice to library maintainers to maintain two parallel versions or perhaps translate dynamically with 2to3 was entirely impractical in most non-trivial cases and wasn t what most people ended up doing, and yet the idea that 2to3 is all you need still floats around Stack Overflow and the like as a result. (These days, I would probably point people towards something more like Eevee s porting FAQ as somewhere to start.) There are various fairly straightforward things that people often suggest could have been done to smooth the path, and I largely agree: not removing the u'' string prefix only to put it back in 3.3, fewer gratuitous compatibility breaks in the name of tidiness, and so on. But if I had a time machine, the number one thing I would ask to have been done differently would be introducing type annotations in Python 2 before Python 3 branched off. It s true that it s technically possible to do type annotations in Python 2, but the fact that it s a different syntax that would have to be fixed later is offputting, and in practice it wasn t widely used in Python 2 code. To make a significant difference to the ease of porting, annotations would need to have been introduced early enough that lots of Python 2 library code used them so that porting code didn t have to be quite so much of an exercise of manually figuring out the exact nature of string types from context. Launchpad is a complex piece of software that interacts with multiple domains: for example, it deals with a database, HTTP, web page rendering, Debian-format archive publishing, and multiple revision control systems, and there s often overlap between domains. Each of these tends to imply different kinds of string handling. Web page rendering is normally done mainly in Unicode, converting to bytes as late as possible; revision control systems normally want to spend most of their time working with bytes, although the exact details vary; HTTP is of course bytes on the wire, but Python s WSGI interface has some string type subtleties. In practice I found myself thinking about at least four string-like types (that is, things that in a language with a stricter type system I might well want to define as distinct types and restrict conversion between them): bytes, text, ordinary native strings (str in either language, encoded to UTF-8 in Python 2), and native strings with WSGI s encoding rules. Some of these are emergent properties of writing in the intersection of Python 2 and 3, which is effectively a specialized language of its own without coherent official documentation whose users must intuit its behaviour by comparing multiple sources of information, or by referring to unofficial porting guides: not a very satisfactory situation. Fortunately much of the complexity collapses once it becomes possible to write solely in Python 3. Some of the difficulties we ran into are not ones that are typically thought of as Python 2-to-3 porting issues, because they were changed later in Python 3 s development process. For instance, the email module was substantially improved in around the 3.2/3.3 timeframe to handle Python 3 s bytes/text model more correctly, and since Launchpad sends quite a few different kinds of email messages and has some quite picky tests for exactly what it emits, this entailed a lot of work in our email sending code and in our test suite to account for that. (It took me a while to work out whether we should be treating raw email messages as bytes or as text; bytes turned out to work best.) 3.4 made some tweaks to the implementation of quoted-printable encoding that broke a number of our tests in ways that took some effort to fix, because the tests needed to work on both 2.7 and 3.5. The list goes on. I got quite proficient at digging through Python s git history to figure out when and why some particular bit of behaviour had changed. One of the thorniest problems was parsing HTTP form data. We mainly rely on zope.publisher for this, which in turn relied on cgi.FieldStorage; but cgi.FieldStorage is badly broken in some situations on Python 3. Even if that bug were fixed in a more recent version of Python, we can t easily use anything newer than 3.5 for the first stage of our port due to the version of the base OS we re currently running, so it wouldn t help much. In the end I fixed some minor issues in the multipart module (and was kindly given co-maintenance of it) and converted zope.publisher to use it. Although this took a while to sort out, it seems to have gone very well. A couple of other interesting late-arriving issues were around pickle. For most things we normally prefer safer formats such as JSON, but there are a few cases where we use pickle, particularly for our session databases. One of my colleagues pointed out that I needed to remember to tell pickle to stick to protocol 2, so that we d be able to switch back and forward between Python 2 and 3 for a while; quite right, and we later ran into a similar problem with marshal too. A more surprising problem was that datetime.datetime objects pickled on Python 2 require special care when unpickling on Python 3; rather than the approach that ended up being implemented and documented for Python 3.6, though, I preferred a custom unpickler, both so that things would work on Python 3.5 and so that I wouldn t have to risk affecting the decoding of other pickled strings in the session database. General lessons Writing this over a year after Python 2 s end-of-life date, and certainly nowhere near the leading edge of Python 3 porting work, it s perhaps more useful to look at this in terms of the lessons it has for other large technical debt projects. I mentioned in my previous article that I used the approach of an enormous and frequently-rebased git branch as a working area for the port, committing often and sometimes combining and extracting commits for review once they seemed to be ready. A port of this scale would have been entirely intractable without a tool of similar power to git rebase, so I m very glad that we finished migrating to git in 2019. I relied on this right up to the end of the port, and it also allowed for quick assessments of how much more there was to land. git worktree was also helpful, in that I could easily maintain working trees built for each of Python 2 and 3 for comparison. As is usual for most multi-developer projects, all changes to Launchpad need to go through code review, although we sometimes make exceptions for very simple and obvious changes that can be self-reviewed. Since I knew from the outset that this was going to generate a lot of changes for review, I therefore structured my work from the outset to try to make it as easy as possible for my colleagues to review it. This generally involved keeping most changes to a somewhat manageable size of 800 lines or less (although this wasn t always possible), and arranging commits mainly according to the kind of change they made rather than their location. For example, when I needed to fix issues with / in Python 3 being true division rather than floor division, I did so in one commit across the various places where it mattered and took care not to mix it with other unrelated changes. This is good practice for nearly any kind of development, but it was especially important here since it allowed reviewers to consider a clear explanation of what I was doing in the commit message and then skim-read the rest of it much more quickly. It was vital to keep the codebase in a working state at all times, and deploy to production reasonably often: this way if something went wrong the amount of code we had to debug to figure out what had happened was always tractable. (Although I can t seem to find it now to link to it, I saw an account a while back of a company that had taken a flag-day approach instead with a large codebase. It seemed to work for them, but I m certain we couldn t have made it work for Launchpad.) I can t speak too highly of Launchpad s test suite, much of which originated before my time. Without a great deal of extensive coverage of all sorts of interesting edge cases at both the unit and functional level, and a corresponding culture of maintaining that test suite well when making new changes, it would have been impossible to be anything like as confident of the port as we were. As part of the porting work, we split out a couple of substantial chunks of the Launchpad codebase that could easily be decoupled from the core: its Mailman integration and its code import worker. Both of these had substantial dependencies with complex requirements for porting to Python 3, and arranging to be able to do these separately on their own schedule was absolutely worth it. Like disentangling balls of wool, any opportunity you can take to make things less tightly-coupled is probably going to make it easier to disentangle the rest. (I can see a tractable way forward to porting the code import worker, so we may well get that done soon. Our Mailman integration will need to be rewritten, though, since it currently depends on the Python-2-only Mailman 2, and Mailman 3 has a different architecture.) Python lessons Our database layer was already in pretty good shape for a port, since at least the modern bits of its table modelling interface were already strict about using Unicode for text columns. If you have any kind of pervasive low-level framework like this, then making it be pedantic at you in advance of a Python 3 port will probably incur much less swearing in the long run, as you won t be trying to deal with quite so many bytes/text issues at the same time as everything else. Early in our port, we established a standard set of __future__ imports and started incrementally converting files over to them, mainly because we weren t yet sure what else to do and it seemed likely to be helpful. absolute_import was definitely reasonable (and not often a problem in our code), and print_function was annoying but necessary. In hindsight I m not sure about unicode_literals, though. For files that only deal with bytes and text it was reasonable enough, but as I mentioned above there were also a number of cases where we needed literals of the language s native str type, i.e. bytes in Python 2 and text in Python 3: this was particularly noticeable in WSGI contexts, but also cropped up in some other surprising places. We generally either omitted unicode_literals or used six.ensure_str in such cases, but it was definitely a bit awkward and maybe I should have listened more to people telling me it might be a bad idea. A lot of Launchpad s early tests used doctest, mainly in the style where you have text files that interleave narrative commentary with examples. The development team later reached consensus that this was best avoided in most cases, but by then there were far too many doctests to conveniently rewrite in some other form. Porting doctests to Python 3 is really annoying. You run into all the little changes in how objects are represented as text (particularly u'...' versus '...', but plenty of other cases as well); you have next to no tools to do anything useful like skipping individual bits of a doctest that don t apply; using __future__ imports requires the rather obscure approach of adding the relevant names to the doctest s globals in the relevant DocFileSuite or DocTestSuite; dealing with many exception tracebacks requires something like zope.testing.renormalizing; and whatever code refactoring tools you re using probably don t work properly. Basically, don t have done that. It did all turn out to be tractable for us in the end, and I managed to avoid using much in the way of fragile doctest extensions aside from the aforementioned zope.testing.renormalizing, but it was not an enjoyable experience. Regressions I know of nine regressions that reached Launchpad s production systems as a result of this porting work; of course there were various other regressions caught by CI or in manual testing. (Considering the size of this project, I count it as a resounding success that there were only nine production issues, and that for the most part we were able to fix them quickly.) Equality testing of removed database objects One of the things we had to do while porting to Python 3 was to implement the __eq__, __ne__, and __hash__ special methods for all our database objects. This was quite conceptually fiddly, because doing this requires knowing each object s primary key, and that may not yet be available if we ve created an object in Python but not yet flushed the actual INSERT statement to the database (most of our primary keys are auto-incrementing sequences). We thus had to take care to flush pending SQL statements in such cases in order to ensure that we know the primary keys. However, it s possible to have a problem at the other end of the object lifecycle: that is, a Python object might still be reachable in memory even though the underlying row has been DELETEd from the database. In most cases we don t keep removed objects around for obvious reasons, but it can happen in caching code, and buildd-manager crashed as a result (in fact while it was still running on Python 2). We had to take extra care to avoid this problem. Debian imports crashed on non-UTF-8 filenames Python 2 has some unfortunate behaviour around passing bytes or Unicode strings (depending on the platform) to shutil.rmtree, and the combination of some porting work and a particular source package in Debian that contained a non-UTF-8 file name caused us to run into this. The fix was to ensure that the argument passed to shutil.rmtree is a str regardless of Python version. We d actually run into something similar before: it s a subtle porting gotcha, since it s quite easy to end up passing Unicode strings to shutil.rmtree if you re in the process of porting your code to Python 3, and you might easily not notice if the file names in your tests are all encoded using UTF-8. lazr.restful ETags We eventually got far enough along that we could switch one of our four appserver machines (we have quite a number of other machines too, but the appservers handle web and API requests) to Python 3 and see what happened. By this point our extensive test suite had shaken out the vast majority of the things that could go wrong, but there was always going to be room for some interesting edge cases. One of the Ubuntu kernel team reported that they were seeing an increase in 412 Precondition Failed errors in some of their scripts that use our webservice API. These can happen when you re trying to modify an existing resource: the underlying protocol involves sending an If-Match header with the ETag that the client thinks the resource has, and if this doesn t match the ETag that the server calculates for the resource then the client has to refresh its copy of the resource and try again. We initially thought that this might be legitimate since it can happen in normal operation if you collide with another client making changes to the same resource, but it soon became clear that something stranger was going on: we were getting inconsistent ETags for the same object even when it was unchanged. Since we d recently switched a quarter of our appservers to Python 3, that was a natural suspect. Our lazr.restful package provides the framework for our webservice API, and roughly speaking it generates ETags by serializing objects into some kind of canonical form and hashing the result. Unfortunately the serialization was dependent on the Python version in a few ways, and in particular it serialized lists of strings such as lists of bug tags differently: Python 2 used [u'foo', u'bar', u'baz'] where Python 3 used ['foo', 'bar', 'baz']. In lazr.restful 1.0.3 we switched to using JSON for this, removing the Python version dependency and ensuring consistent behaviour between appservers. Memory leaks This problem took the longest to solve. We noticed fairly quickly from our graphs that the appserver machine we d switched to Python 3 had a serious memory leak. Our appservers had always been a bit leaky, but now it wasn t so much a small hole that we can bail occasionally as the boat is sinking rapidly : A serious memory leak (Yes, this got in the way of working out what was going on with ETags for a while.) I spent ages messing around with various attempts to fix this. Since only a quarter of our appservers were affected, and we could get by on 75% capacity for a while, it wasn t urgent but it was definitely annoying. After spending some quality time with objgraph, for some time I thought traceback reference cycles might be at fault, and I sent a number of fixes to various upstream projects for those (e.g. zope.pagetemplate). Those didn t help the leaks much though, and after a while it became clear to me that this couldn t be the sole problem: Python has a cyclic garbage collector that will eventually collect reference cycles as long as there are no strong references to any objects in them, although it might not happen very quickly. Something else must be going on. Debugging reference leaks in any non-trivial and long-running Python program is extremely arduous, especially with ORMs that naturally tend to end up with lots of cycles and caches. After a while I formed a hypothesis that zope.server might be keeping a strong reference to something, although I never managed to nail it down more firmly than that. This was an attractive theory as we were already in the process of migrating to Gunicorn for other reasons anyway, and Gunicorn also has a convenient max_requests setting that s good at mitigating memory leaks. Getting this all in place took some time, but once we did we found that everything was much more stable: A rather flat memory graph This isn t completely satisfying as we never quite got to the bottom of the leak itself, and it s entirely possible that we ve only papered over it using max_requests: I expect we ll gradually back off on how frequently we restart workers over time to try to track this down. However, pragmatically, it s no longer an operational concern. Mirror prober HTTPS proxy handling After we switched our script servers to Python 3, we had several reports of mirror probing failures. (Launchpad keeps lists of Ubuntu archive and image mirrors, and probes them every so often to check that they re reasonably complete and up to date.) This only affected HTTPS mirrors when probed via a proxy server, support for which is a relatively recent feature in Launchpad and involved some code that we never managed to unit-test properly: of course this is exactly the code that went wrong. Sadly I wasn t able to sort out that gap, but at least the fix was simple. Non-MIME-encoded email headers As I mentioned above, there were substantial changes in the email package between Python 2 and 3, and indeed between minor versions of Python 3. Our test coverage here is pretty good, but it s an area where it s very easy to have gaps. We noticed that a script that processes incoming email was crashing on messages with headers that were non-ASCII but not MIME-encoded (and indeed then crashing again when it tried to send a notification of the crash!). The only examples of these I looked at were spam, but we still didn t want to crash on them. The fix involved being somewhat more careful about both the handling of headers returned by Python s email parser and the building of outgoing email notifications. This seems to be working well so far, although I wouldn t be surprised to find the odd other incorrect detail in this sort of area. Failure to handle non-ISO-8859-1 URL-encoded form input Remember how I said that parsing HTTP form data was thorny? After we finished upgrading all our appservers to Python 3, people started reporting that they couldn t post Unicode comments to bugs, which turned out to be only if the attempt was made using JavaScript, and was because I hadn t quite managed to get URL-encoded form data working properly with zope.publisher and multipart. The current standard describes the URL-encoded format for form data as in many ways an aberrant monstrosity , so this was no great surprise. Part of the problem was some very strange choices in zope.publisher dating back to 2004 or earlier, which I attempted to clean up and simplify. The rest was that Python 2 s urlparse.parse_qs unconditionally decodes percent-encoded sequences as ISO-8859-1 if they re passed in as part of a Unicode string, so multipart needs to work around this on Python 2. I m still not completely confident that this is correct in all situations, but at least now that we re on Python 3 everywhere the matrix of cases we need to care about is smaller. Inconsistent marshalling of Loggerhead s disk cache We use Loggerhead for providing web browsing of Bazaar branches. When we upgraded one of its two servers to Python 3, we immediately noticed that the one still on Python 2 was failing to read back its revision information cache, which it stores in a database on disk. (We noticed this because it caused a deployment to fail: when we tried to roll out new code to the instance still on Python 2, Nagios checks had already caused an incompatible cache to be written for one branch from the Python 3 instance.) This turned out to be a similar problem to the pickle issue mentioned above, except this one was with marshal, which I didn t think to look for because it s a relatively obscure module mostly used for internal purposes by Python itself; I m not sure that Loggerhead should really be using it in the first place. The fix was relatively straightforward, complicated mainly by now needing to cope with throwing away unreadable cache data. Ironically, if we d just gone ahead and taken the nominally riskier path of upgrading both servers at the same time, we might never have had a problem here. Intermittent bzr failures Finally, after we upgraded one of our two Bazaar codehosting servers to Python 3, we had a report of intermittent bzr branch hangs. After some digging I found this in our logs:
Traceback (most recent call last):
  ...
  File "/srv/bazaar.launchpad.net/production/codehosting1-rev-20124175fa98fcb4b43973265a1561174418f4bd/env/lib/python3.5/site-packages/twisted/conch/ssh/channel.py", line 136, in addWindowBytes
    self.startWriting()
  File "/srv/bazaar.launchpad.net/production/codehosting1-rev-20124175fa98fcb4b43973265a1561174418f4bd/env/lib/python3.5/site-packages/lazr/sshserver/session.py", line 88, in startWriting
    resumeProducing()
  File "/srv/bazaar.launchpad.net/production/codehosting1-rev-20124175fa98fcb4b43973265a1561174418f4bd/env/lib/python3.5/site-packages/twisted/internet/process.py", line 894, in resumeProducing
    for p in self.pipes.itervalues():
builtins.AttributeError: 'dict' object has no attribute 'itervalues'
I d seen this before in our git hosting service: it was a bug in Twisted s Python 3 port, fixed after 20.3.0 but unfortunately after the last release that supported Python 2, so we had to backport that patch. Using the same backport dealt with this. Onwards!

Russ Allbery: Review: Piranesi

Review: Piranesi, by Susanna Clarke
Publisher: Bloomsbury Publishing
Copyright: 2020
ISBN: 1-63557-564-8
Format: Kindle
Pages: 245
Piranesi is a story told in first-person journal entries by someone who lives in a three-floored world of endless halls full of statues. The writing style is one of the most distinctive things about this book (and something you'll have to get along with to enjoy it), so it's worth quoting a longer passage from the introductory description of the world:
I am determined to explore as much of the World as I can in my lifetime. To this end I have travelled as far as the Nine-Hundred-and-Sixtieth Hall to the West, the Eight-Hundred-and-Ninetieth Hall to to the North and the Seven-Hundred-and-Sixty-Eighth Hall to the South. I have climbed up to the Upper Halls where Clouds move in slow procession and Statues appear suddenly out of the Mists. I have explored the Drowned Halls where the Dark Waters are carpeted with white water lilies. I have seen the Derelict Halls of the East where Ceilings, Floors sometimes even Walls! have collapsed and the dimness is split by shafts of grey Light. In all these places I have stood in Doorways and looked ahead. I have never seen any indication that the World was coming to an End, but only the regular progression of Halls and Passageways into the Far Distance. No Hall, no Vestibule, no Staircase, no Passage is without its Statues. In most Halls they cover all the available space, though here and there you will find an Empty Plinth, Niche or Apse, or even a blank space on a Wall otherwise encrusted with Statues. These Absences are as mysterious in their way as the Statues themselves.
So far as the protagonist knows, the world contains only one other living person, the Other, and thirteen dead ones who exist only as bones. The Other is a scientist searching for Great and Secret Knowledge, and calls the protagonist Piranesi, which is odd because that is not the protagonist's name. Be warned that I'm skating around spoilers for the rest of this review. I don't think I'm giving away anything that would ruin the book, but the nature of the story takes some sharp turns. If knowing anything about that would spoil the book for you and you want to read this without that knowledge, you may want to stop reading here. I also want to disclose early in this review that I wanted this to be a different book than it is, and that had a significant impact on how much I enjoyed it. Someone who came to it with different expectations may have a different and more enjoyable experience. I was engrossed by the strange world, the atmosphere, and the mystery of the halls full of statues. The protagonist is also interested in the same things, and the early part of the book is full of discussion of exploration, scientific investigation, and attempts to understand the nature of the world. That led me to hope for the sort of fantasy novel in which the setting is a character and where understanding the setting is a significant part of the plot. Piranesi is not that book. The story that Clarke wants to tell is centered on psychology rather than setting. The setting does not become a character, nor do we learn much about it by the end of the book. While we do learn how the protagonist came to be in this world, my first thought when that revelation starts halfway through the book was "this is going to be disappointing." And, indeed, it was. I say all of this because I think Piranesi looks, from both its synopsis and from the first few chapters, like it's going to be a world building and exploration fantasy. I think it runs a high risk of disappointing readers in the way that it disappointed me, and that can lead to disliking a book one may have enjoyed if one had read it in a different mood and with a different set of expectations. Piranesi is, instead, about how the protagonist constructs the world, about the effect of trauma on that construction, and about the complexities hidden behind the idea of recovery. And there is a lot to like here: The ending is complex and subtle and does not arrive at easy answers (although I also found it very sad), and although Clarke, by the end of the book, is using the setting primarily as metaphor, the descriptions remain vivid and immersive. I still want the book that I thought I was reading, but I want that book in large part because the fragments of that book that are in this one are so compelling and engrossing. What did not work for me was every character in the book except for the protagonist and one supporting character. The relationship between the protagonist and the Other early in the book is a lovely bit of unsettling complexity. It's obvious that the Other has a far different outlook on the world than the protagonist, but the protagonist seems unaware of it. It's also obvious that the Other is a bit of a jerk, but I was hoping for a twist that showed additional complexity in his character. Sadly, when we get the twist, it's not in the direction of more complexity. Instead, it leads to a highly irritating plot that is unnecessarily prolonged through the protagonist being gullible and child-like in the face of blatantly obvious gaslighting. This is a pattern for the rest of the book: Once villains appear on stage, they're one-note narcissists with essentially no depth. There is one character in Piranesi that I liked as well or better than the protagonist, but they only show up late in the story and get very little character development. Clarke sketches the outline of a character I wanted to learn much more about, but never gives us the details on the page. That leads to what I thought was too much telling rather than showing in the protagonist's relationships at the end of the book, which is part of why I thought the ending was so sad. What the protagonist loses is obvious to me (and lines up with the loss I felt when the book didn't turn out to be what I was hoping it would be); what the protagonist gains is less obvious, is working more on the metaphorical level of the story than the literal level, and is more narrated than shown. In other words, this is psychological fantasy with literary sensibilities told in a frame that looks like exploration fantasy. Parts of it, particularly the descriptions and the sense of place, are quite skillful, but the plot, once revealed, is superficial, obvious, and disappointing. I think it's possible this shift in the reader's sense of what type of book they're reading is intentional on Clarke's part, since it works with the metaphorical topic of the book. But it's not the existence of a shift itself that is my primary objection. I like psychological fantasy as well as exploration fantasy. It's that I thought the book after the shift was shallower, less interesting, and more predictable than the book before the shift. The one thing that is excellent throughout Piranesi, though, is the mood. It takes a bit to get used to the protagonist's writing style (and I continue to dislike the Affectation of capitalizing Nouns when writing in English), but it's open-hearted, curious, thoughtful, observant, and capable in a way I found delightful. Some of the events in this book are quite dark, but it never felt horrifying or oppressive because the protagonist remains so determinedly optimistic and upbeat, even when yanked around by the world's most obvious and blatant gaslighting. That persistent hopefulness and lightness is a good feature in a book published in 2020 and is what carried me through the parts of the story I didn't care for. I wish this had been a different book than it was, or failing that, a book with more complex and interesting supporting characters and plot to fit its complex and interesting psychological arc. I also wish that Clarke had done something more interesting with gender in this novel; it felt like she was setting that up for much of the book, and then it never happened. Ah well. As is, I can't recommend Piranesi, but I can say the protagonist, atmosphere, and sense of place are very well done and I think it will work for some other readers better than it did for me. Rating: 6 out of 10

31 July 2021

Chris Lamb: Free software activities in July 2021

Here is my monthly update covering what I have been doing in the free software world during July 2021 (previous month): As part of my role of being the assistant Secretary of the Open Source Initiative and a board director of Software in the Public Interest I attended their respective monthly meetings. As outlined in last months posts, however, my term on the OSI board has been slightly extended due to the discovery of a vulnerability in OSI's recent election as a result, the 2021 election is currently being re-run. Reproducible Builds One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. However, whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third parties to compromise systems by injecting malicious code into ostensibly secure software during the various compilation and distribution processes. The motivation behind the Reproducible Builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. This month, I: I also made the following changes to diffoscope, including preparing and uploading versions 178 and 179 to PyPI and Debian: Debian Bugs filed Uploads Debian LTS This month I have worked 18 hours on Debian Long Term Support (LTS) and 12 hours on its sister Extended LTS project. You can find out more about the project via the following video:

Dirk Eddelbuettel: RcppAnnoy 0.0.19 on CRAN: Maintenance

annoy image A minor maintenance release, now at version 0.0.19, of RcppAnnoy is now on CRAN. RcppAnnoy is the Rcpp-based R integration of the nifty Annoy library by Erik Bernhardsson. Annoy is a small and lightweight C++ template header library for very fast approximate nearest neighbours originally developed to drive the famous Spotify music discovery algorithm. This release only contains internal packaging changes. Nothing changes upstream, or in package functionality. Detailed changes follow.

Changes in version 0.0.19 (2021-07-30)
  • Minor tweaks to default CI setup and DESCRIPTION file

Courtesy of my CRANberries, there is also a diffstat report for this release. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

27 July 2021

Dirk Eddelbuettel: RcppFarmHash 0.0.1: New CRAN Package

A new package RcppFarmHash is now on CRAN in an inaugural version 0.0.1. RcppFarmHash wraps the Google FarmHash family of hash functions (written by Geoff Pike and contributors) that are used for example by Google BigQuery for the FARM_FINGERPRINT. The package was prepared and uploaded yesterday afternoon, and to my surprise already on CRAN this (early) morning when I got up. So here is another #ThankYouCRAN for very smoothing operations. The very brief NEWS entry follows:

Changes in version 0.0.1 (2021-07-25)
  • Initial version and CRAN upload

If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

24 July 2021

Dirk Eddelbuettel: littler 0.3.13: Moar Goodies

max-heap image The fourteenth release of littler as a CRAN package just landed, following in the now fifteen year history (!!) as a package started by Jeff in 2006, and joined by me a few weeks later. littler is the first command-line interface for R as it predates Rscript. It allows for piping as well for shebang scripting via #!, uses command-line arguments more consistently and still starts faster. It also always loaded the methods package which Rscript only started to do in recent years. littler lives on Linux and Unix, has its difficulties on macOS due to yet-another-braindeadedness there (who ever thought case-insensitive filesystems as a default were a good idea?) and simply does not exist on Windows (yet the build system could be extended see RInside for an existence proof, and volunteers are welcome!). See the FAQ vignette on how to add it to your PATH. A few examples are highlighted at the Github repo, as well as in the examples vignette. This release brings two new example scripts and command wrappers (compiledDeps.r, silenceTwitterAccount.r), along with extensions, corrections, or polish for a number a of other examples as detailed in the NEWS file entry below.

Changes in littler version 0.3.13 (2021-07-24)
  • Changes in examples
    • New script compiledDeps.r to show which dependencies are compiled
    • New script silenceTwitterAccount.r wrapping rtweet
    • The -c or --code option for installRSPM.r was corrected
    • The kitten.r script now passes options bunny and puppy on to the pkgKitten::kitten() call; new options to call the Arma and Eigen variants were added
    • The getRStudioDesktop.r and getRStudioServer.r scripts were updated for a change in rvest
    • Two typos in the tt.r help message were correct (Aaron Wolen in #86)
    • The message in cranIncoming.r was corrected.
  • Changes in package
    • Added Continuous Integration runner via run.sh from r-ci.
    • Two vignettes got two extra vignette attributes.
    • The mkdocs-material documentation input was moved.
    • The basic unit tests were slightly refactored and updated.

My CRANberries provides a comparison to the previous release. Full details for the littler release are provided as usual at the ChangeLog page, and now also on the new package docs website. The code is available via the GitHub repo, from tarballs and now of course also from its CRAN page and via install.packages("littler"). Binary packages are available directly in Debian as well as soon via Ubuntu binaries at CRAN thanks to the tireless Michael Rutter. Comments and suggestions are welcome at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Next.

Previous.