Search Results: "cts"

30 April 2021

Bastian Venthur: Getting the Function keys of a Keychron working on Linux

Having destroyed the third Cherry Stream keyboard in 4 years, I wanted to try a more substantial keyboard for a change. After some research I decided that I want a mechanical, wired, tenkeyless keyboard without any fancy LEDs. At the end I settled for a Keychron C1 with red switches. It meets all requirements, looks very nice and the price is reasonable. Surprise! After the keyboard was delivered, I connected it to my Debian machine and was unpleasantly surprised to notice that the Function-keys did not work at all. The keyboard shares the Multimedia keys with the F-keys and you have an fn key that supposedly switches between the two modes, like you re used to on a laptop. On Linux, however you cannot access the F-keys at all: pressing fn + F1 or F1 makes no difference, you ll always get the Multimedia key. Switching the keyboard between Windows and Mac mode makes no difference either, in both modes the F-keys are not accessible. Apparently Keychron is aware of the problem, because the quick start manual tells you:
We have a Linux user group on facebook. Please search Keychron Linux Group on facebook. So you can better experience with our keyboard.
Customer support at its finest! So at this point you should probably just send the keyboard back, get the refund and buy a proper one with functioning F-keys. The fix Test if this command fixes the issue and enables the Fn + F-key-combos:
# as root:
echo 2 > /sys/module/hid_apple/parameters/fnmode
Depending on the mode the keyboard is in, you should now be able to use the F-keys by simply pressing them, and the Multimedia keys by pressing fn + F-key (or the other way round). To switch the default mode of the F-keys to Function- or Multimedia-mode, press and hold fn + X + L for 4 seconds. If everything works as expected, you can make the change permanent by creating the file /etc/modprobe.d/hid_apple.conf and adding the line:
options hid_apple fnmode=2
This works regardless if the keyboard is in Windows- or Mac-mode, and that might hint at the problem: in both cases the Linux thinks you re connecting a Mac keyboard. The rant Although the fix was not very hard to find and apply, this experience still leaves a foul taste. I naively assumed the problem of having a properly functioning keyboard that simply works when you plug it in, has been thoroughly solved by 2021. To make it worse, I assume Keychron must be aware of the problem because the other Keychron models have the same issue! But instead of fixing it on their end, they forward you to a facebook community and expect you to somehow fix it yourself. So dear Keychron, you do make really beautiful keyboards! But before you release your next model with the same bug, maybe invest a bit on fixing the basics? I see that your keyboards support firmware updates for Windows and Mac maybe you can talk to the folks over at the Linux Vendor Firmware Service and support Linux as well? Maybe you can even fix this annoying bug for the keyboards you ve already sold? I found it really cute that you sent different keycaps for Windows and Mac setups a few disappointed Linux users might accept an apology in form of a Linux cap

Raphaël Hertzog: Freexian s report about Debian Long Term Support, March 2021

A Debian LTS logo
Like each month, have a look at the work funded by Freexian s Debian LTS offering. Debian project funding In March, we put aside 3225 EUR to fund Debian projects but sadly nobody picked up anything, so this one of the many reasons Raphael posted as series of blog posts titled Challenging times for Freexian , posted in 4 parts on the last two days of March and the first two of April. [Part one, two, three and four] So we re still looking forward to receive more projects from various Debian teams! Learn more about the rationale behind this initiative in this article! Debian LTS contributors In March, 11 contributors have been paid to work on Debian LTS, their reports are available: Evolution of the situation In March we released 28 DLAs and held our second LTS team meeting for 2021 on IRC, with the next public IRC meeting coming up at the end of May. At that meeting Holger announced that after 2.5 years he wanted to step back from his role helping Rapha l in coordinating/managing the LTS team. We would like to thank Holger for his continuous work on Debian LTS (which goes back to 2014) and are happy to report that we already found a successor which we will introduce in the upcoming April report from Freexian. Finally, we would like to remark once again that we are constantly looking for new contributors. For a last time, please contact Holger if you are interested! The security tracker currently lists 42 packages with a known CVE and the dla-needed.txt file has 28 packages needing an update. We are also pleased to report that we got 4 new sponsors over the last 2 months : thanks to sipgate GmbH, OVH US LLC, Tilburg University and Observatoire des Sciences de l Univers de Grenoble ! Thanks to our sponsors Sponsors that joined recently are in bold.

29 April 2021

Junichi Uekawa: Surrounding a region with Emacs lisp.

Surrounding a region with Emacs lisp. I wanted to surround a region with HTML tags and here's what I learnt today. Specifying "r" in interactive gives two numbers, begin and end. When I want to obtain multiple kinds of values in interactive, I can use newlines to delimit. set-marker is an api to keep a marker at relative position even after edits, API needs making make-marker to create an empty marker first, and seems like the number of markers affects editing speed so the API is made to allow reuse of markers. After I got these going I could now write.

28 April 2021

Martin Michlmayr: Research on FOSS foundations

I worked on research on FOSS foundations and published two reports: Growing Open Source Projects with a Stable Foundation This primer covers non-technical aspects that the majority of projects will have to consider at some point. It also explains how FOSS foundations can help projects grow and succeed. This primer explains: You can download Growing Open Source Projects with a Stable Foundation. Research report The research report describes the findings of the research and aims to help understand the operations and challenges FOSS foundations face. This report covers topics such as: You can download the research report. Acknowledgments This research was sponsored by Ford Foundation and Alfred P. Sloan Foundation. The research was part of their Critical Digital Infrastructure Research initiative, which investigates the role of open source in digital infrastructure.

Russell Coker: Links April 2021

Dr Justin Lehmiller s blog post comparing his official (academic style) and real biographies is interesting [1]. Also the rest of his blog is interesting too, he works at the Kinsey Institute so you know he s good. Media Matters has an interesting article on the spread of vaccine misinformation on Instagram [2]. John Goerzen wrote a long post summarising some of the many ways of having a decentralised Internet [3]. One problem he didn t address is how to choose between them, I could spend months of work to setup a fraction of those services. Erasmo Acosta wrote an interesting medium article Could Something as Pedestrian as the Mitochondria Unlock the Mystery of the Great Silence? [4]. I don t know enough about biology to determine how plausible this is. But it is a worry, I hope that humans will meet extra-terrestrial intelligences at some future time. Meredith Haggerty wrote an insightful Medium article about the love vs money aspects of romantic comedies [5]. Changes in viewer demographics would be one factor that makes lead actors in romantic movies significantly less wealthy in recent times. Informative article about ZIP compression and the history of compression in general [6]. Vice has an insightful article about one way of taking over SMS access of phones without affecting voice call or data access [7]. With this method the victom won t notice that they are having their sservice interfered with until it s way too late. They also explain the chain of problems in the US telecommunications industry that led to this. I wonder what s happening in this regard in other parts of the world. The clown code of ethics (8 Commandments) is interesting [8]. Sam Hartman wrote an insightful blog post about the problems with RMS and how to deal with him [9]. Also Sam Whitton has an interesting take on this [10]. Another insightful post is by Selam G about RMS long history of bad behavior and the way universities are run [11]. Cory Doctorow wrote an insightful article for Locus about free markets with a focus on DRM on audio books [12]. We need legislative changes to fix this!

Russ Allbery: Review: Beyond Shame

Review: Beyond Shame, by Kit Rocha
Series: Beyond #1
Publisher: Kit Rocha
Copyright: December 2013
ASIN: B00GIA4GN8
Format: Kindle
Pages: 270
I read this book as part of the Beyond Series Bundle (Books 1-3), which is what the sidebar information is for. Noelle is a child of Eden, the rich and technologically powerful city of a post-apocalyptic world. As the daughter of a councilman, she had everything she wanted except the opportunity to feel. Eden's religious elite embrace a doctrine of strict Puritanism: Even hugging one's children was frowned upon, let alone anything related to sex. Noelle was too rebellious to settle for that, which is why this book opens with her banished from Eden, ejected into Sector Four. The sectors are the city slums, full of gangs and degenerates and violence, only a slight step up from the horrific farming communes. Luckily for her, she literally stumbles into one of the lieutenants of the O'Kane gang, who are just as violent as their reputations but who have surprising sympathy for a helpless city girl. My shorthand distinction between romance and erotica is that romance mixes some sex into the plot and erotica mixes some plot into the sex. Beyond Shame is erotica, specifically BDSM erotica. The forbidden sensations that Noelle got kicked out of Eden for pursuing run strongly towards humiliation, which is tangled up in the shame she was taught to feel about anything sexual. There is a bit of a plot surrounding the O'Kanes who take her in, their leader, some political skulduggery that eventually involves people she knows, and some inter-sector gang warfare, but it's quite forgettable (and indeed I've already forgotten most of it). The point of the story is Noelle navigating a relationship with Jasper (among others) that involves a lot of very graphic sex. I was of two minds about reviewing this. Erotica is tricky to review, since to an extent it's not trying to do what most books are doing. The point is less to tell a coherent story (although that can be a bonus) than it is to turn the reader on, and what turns the reader on is absurdly personal and unpredictable. Erotica is arguably more usefully marked with story codes (which in this case would be something like MF, MMFF, FF, Mdom, Fdom, bd, ds, rom, cons, exhib, humil, tattoos) so that the reader has an idea whether the scenarios in the story are the sort of thing they find hot. This is particularly true of BDSM erotica, since the point is arousal from situations that wouldn't work or might be downright horrifying in a different sort of book. Often the forbidden or taboo nature of the scene is why it's erotic. For example, in another genre I would complain about the exaggerated and quite sexist gender roles, where all the men are hulking cage fighters who want to control the women, but in male-dominant BDSM erotica that's literally the point. As you can tell, I wrote a review anyway, primarily because of how I came to read this book. Kit Rocha (which is a pseudonym for the writing team of Donna Herren and Bree Bridges) recently published Deal with the Devil, a book about mercenary librarians in a post-apocalyptic future. Like every right-thinking person, I immediately wanted to read a book about mercenary librarians, but discovered that it was set in an existing universe. I hate not starting at the beginning of things, so even though there was probably no need to read the earlier books first, I figured out Beyond Shame was the first in this universe and the bundle of the first three books was only $2. If any of you are immediately hooked by mercenary librarians but are back-story completionists, now you know what you'll be getting into. That said, there are a few notable things about this book other than it has a lot of sex. The pivot of the romantic relationship was more interesting and subtle than most erotica. Noelle desperately wants a man to do all sorts of forbidden things to her, but she starts the book unable to explain or analyze why she wants what she wants, and both Jasper and the story are uncomfortable with that and unwilling to leave it alone. Noelle builds up a more coherent theory of herself over the course of the book, and while it's one that's obviously designed to enable lots of erotic scenes, it's not a bad bit of character development. Even better is Lex, the partner (sort of) of the leader of the O'Kane gang and by far the best character in the book. She takes Noelle under her wing from the start, and while that relationship is sexualized like nearly everything in this book, it also turns into an interesting female friendship that I would have also enjoyed in a different genre. I liked Lex a lot, and the fact she's the protagonist of the next book might keep me reading. Beyond Shame also has a lot more female gaze descriptions of the men than is often the case in male-dominant BDSM. The eye candy is fairly evenly distributed, although the gender roles are very much not. It even passes the Bechdel test, although it is still erotica and nearly all the conversations end up being about sex partners or sex eventually. I was less fond of the fact that the men are all dangerous and violent and the O'Kane leader frequently acts like a controlling, abusive psychopath. A lot of that was probably the BDSM setup, but it was not my thing. Be warned that this is the sort of book in which one of the (arguably) good guys tortures someone to death (albeit off camera). Recommendations are next to impossible for erotica, so I won't try to give one. If you want to read the mercenary librarian novel and are dubious about this one, it sounds like (although I can't confirm) that it's a bit more on the romance end of things and involves a lot fewer group orgies. Having read this book, I suspect it was entirely unnecessary to have done so for back-story. If you are looking for male-dominant BDSM, Beyond Shame is competently written, has a more thoughtful story than most, and has a female friendship that I fully enjoyed, which may raise it above the pack. Rating: 6 out of 10

25 April 2021

Antoine Beaupr : Lost article ideas

I wrote for LWN for about two years. During that time, I wrote (what seems to me an impressive) 34 articles, but I always had a pile of ideas in the back of my mind. Those are ideas, notes, and scribbles lying around. Some were just completely abandoned because they didn't seem a good fit for LWN. Concretely, I stored those in branches in a git repository, and used the branch name (and, naively, the last commit log) as indicators of the topic. This was the state of affairs when I left:
remotes/private/attic/novena                    822ca2bb add letter i sent to novena, never published
remotes/private/attic/secureboot                de09d82b quick review, add note and graph
remotes/private/attic/wireguard                 5c5340d1 wireguard review, tutorial and comparison with alternatives
remotes/private/backlog/dat                     914c5edf Merge branch 'master' into backlog/dat
remotes/private/backlog/packet                  9b2c6d1a ham radio packet innovations and primer
remotes/private/backlog/performance-tweaks      dcf02676 config notes for http2
remotes/private/backlog/serverless              9fce6484 postponed until kubecon europe
remotes/private/fin/cost-of-hosting             00d8e499 cost-of-hosting article online
remotes/private/fin/kubecon                     f4fd7df2 remove published or spun off articles
remotes/private/fin/kubecon-overview            21fae984 publish kubecon overview article
remotes/private/fin/kubecon2018                 1edc5ec8 add series
remotes/private/fin/netconf                     3f4b7ece publish the netconf articles
remotes/private/fin/netdev                      6ee66559 publish articles from netdev 2.2
remotes/private/fin/pgp-offline                 f841deed pgp offline branch ready for publication
remotes/private/fin/primes                      c7e5b912 publish the ROCA paper
remotes/private/fin/runtimes                    4bee1d70 prepare publication of runtimes articles
remotes/private/fin/token-benchmarks            5a363992 regenerate timestamp automatically
remotes/private/ideas/astropy                   95d53152 astropy or python in astronomy
remotes/private/ideas/avaneya                   20a6d149 crowdfunded blade-runner-themed GPLv3 simcity-like simulator
remotes/private/ideas/backups-benchmarks        fe2f1f13 review of backup software through performance and features
remotes/private/ideas/cumin                     7bed3945 review of the cumin automation tool from WM foundation
remotes/private/ideas/future-of-distros         d086ca0d modern packaging problems and complex apps
remotes/private/ideas/on-dying                  a92ad23f another dying thing
remotes/private/ideas/openpgp-discovery         8f2782f0 openpgp discovery mechanisms (WKD, etc), thanks to jonas meurer
remotes/private/ideas/password-bench            451602c0 bruteforce estimates for various password patterns compared with RSA key sizes
remotes/private/ideas/prometheus-openmetrics    2568dbd6 openmetrics standardizing prom metrics enpoints
remotes/private/ideas/telling-time              f3c24a53 another way of telling time
remotes/private/ideas/wallabako                 4f44c5da talk about wallabako, read-it-later + kobo hacking
remotes/private/stalled/bench-bench-bench       8cef0504 benchmarking http benchmarking tools
remotes/private/stalled/debian-survey-democracy 909bdc98 free software surveys and debian democracy, volunteer vs paid work
Wow, what a mess! Let's see if I can make sense of this:

Attic Those are articles that I thought about, then finally rejected, either because it didn't seem worth it, or my editors rejected it, or I just moved on:
  • novena: the project is ooold now, didn't seem to fit a LWN article. it was basically "how can i build my novena now" and "you guys rock!" it seems like the MNT Reform is the brain child of the Novena now, and I dare say it's even cooler!
  • secureboot: my LWN editors were critical of my approach, and probably rightly so - it's a really complex subject and I was probably out of my depth... it's also out of date now, we did manage secureboot in Debian
  • wireguard: LWN ended up writing extensive coverage, and I was biased against Donenfeld because of conflicts in a previous project

Backlog Those were articles I was planning to write about next.
  • dat: I already had written Sharing and archiving data sets with Dat, but it seems I had more to say... mostly performance issues, beaker, no streaming, limited adoption... to be investigated, I guess?
  • packet: a primer on data communications over ham radio, and the cool new tech that has emerged in the free software world. those are mainly notes about Pat, Direwolf, APRS and so on... just never got around to making sense of it or really using the tech...
  • performance-tweaks: "optimizing websites at the age of http2", the unwritten story of the optimization of this website with HTTP/2 and friends
  • serverless: god. one of the leftover topics at Kubecon, my notes on this were thin, and the actual subject, possibly even thinner... the only lie worse than the cloud is that there's no server at all! concretely, that's a pile of notes about Kubecon which I wanted to sort through. Probably belongs in the attic now.

Fin Those are finished articles, they were published on my website and LWN, but the branches were kept because previous drafts had private notes that should not be published.

Ideas A lot of those branches were actually just an empty commit, with the commitlog being the "pitch", more or less. I'd send that list to my editors, sometimes with a few more links (basically the above), and they would nudge me one way or the other. Sometimes they would actively discourage me to write about something, and I would do it anyways, send them a draft, and they would patiently make me rewrite it until it was a decent article. This was especially hard with the terminal emulator series, which took forever to write and even got my editors upset when they realized I had never installed Fedora (I ended up installing it, and I was proven wrong!)

Stalled Oh, and then there's those: those are either "ideas" or "backlog" that got so far behind that I just moved them out of the way because I was tired of seeing them in my list.
  • stalled/bench-bench-bench benchmarking http benchmarking tools, a horrible mess of links, copy-paste from terminals, and ideas about benchmarking... some of this trickled out into this benchmarking guide at Tor, but not much more than the list of tools
  • stalled/debian-survey-democracy: "free software surveys and Debian democracy, volunteer vs paid work"... A long standing concern of mine is that all Debian work is supposed to be volunteer, and paying explicitly for work inside Debian has traditionally been frowned upon, even leading to serious drama and dissent (remember Dunc-Tank)? back when I was writing for LWN, I was also doing paid work for Debian LTS. I also learned that a lot (most?) Debian Developers were actually being paid by their job to work on Debian. So I was confused by this apparent contradiction, especially given how the LTS project has been mostly accepted, while Dunc-Tank was not... See also this talk at Debconf 16. I had hopes that this study would show the "hunch" people have offered (that most DDs are paid to work on Debian) but it seems to show the reverse (only 36% of DDs, and 18% of all respondents paid). So I am still confused and worried about the sustainability of Debian.

What do you think? So that's all I got. As people might have noticed here, I have much less time to write these days, but if there's any subject in there I should pick, what is the one that you would find most interesting? Oh! and I should mention that you can write to LWN! If you think people should know more about some Linux thing, you can get paid to write for it! Pitch it to the editors, they won't bite. The worst that can happen is that they say "yes" and there goes two years of your life learning to write. Because no, you don't know how to write, no one does. You need an editor to write. That's why this article looks like crap and has a smiley. :)

24 April 2021

Gunnar Wolf: FLISOL Talking about Jitsi

Every year since 2005 there is a very good, big and interesting Latin American gathering of free-software-minded people. Of course, Latin America is a big, big, big place, and it s not like we are the most economically buoyant region to meet in something equiparable to FOSDEM. What we have is a distributed free software conference originally, a distributed Linux install-fest (which I never liked, I am against install-fests), but gradually it morphed into a proper conference: Festival Latinoamericano de Instalaci n de Software Libre (Latin American Free Software Installation Festival) This FLISOL was hosted by the always great and always interesting Rancho Electr nico, our favorite local hacklab, and has many other interesting talks. I like talking about projects where I am involved as a developer but this time I decided to do otherwise: I presented a talk on the Jitsi videoconferencing server. Why? Because of the relevance videoconferences have had over the last year. So, without further ado Here is a video I recorded locally from the talk I gave (MKV), as well as the slides (PDF).

23 April 2021

Thomas Goirand: Puppet and OS detection

As you may know, Puppet uses facter to get facts about the machine it is about to configure. That s fine, and a nice concept. One can later use variables in a puppet manifest to do different things depending on what facter tells. For example, the operating system name oh no! This thing is really stupid Here s the code one has to do to be compatible with puppet from version 3 up to 5: if $::lsbdistcodename == undef
# This works around differences between facter versions
if $facts['os']['lsb'] != undef
$distro_codename = $facts['os']['lsb']['distcodename']
else
$distro_codename = $facts['os']['distro']['codename']

else
$distro_codename = downcase($::lsbdistcodename)
Indeed, the global variable $::lsbdistcodename still existed up to Stretch (and is gone in Buster). The global $::facts wasn t an array before (but a hash), so in Jessie, it breaks with the error message facts is not a hash or array when accessing it with os . So, one need the full code above to make this work. It s ok to improve things. It is NOT OK to break os detection. To me it is a very bad practice from upstream Puppet authors. I m publishing this in the hope to avoid others to fall in the same trap as I did.

Matthew Garrett: An accidental bootsplash

Back in 2005 we had Debconf in Helsinki. Earlier in the year I'd ended up invited to Canonical's Ubuntu Down Under event in Sydney, and one of the things we'd tried to design was a reasonable graphical boot environment that could also display status messages. The design constraints were awkward - we wanted it to be entirely in userland (so we didn't need to carry kernel patches), and we didn't want to rely on vesafb[1] (because at the time we needed to reinitialise graphics hardware from userland on suspend/resume[2], and vesa was not super compatible with that). Nothing currently met our requirements, but by the time we'd got to Helsinki there was a general understanding that Paul Sladen was going to implement this.

The Helsinki Debconf ended being an extremely strange event, involving me having to explain to Mark Shuttleworth what the physics of a bomb exploding on a bus were, many people being traumatised by the whole sauna situation, and the whole unfortunate water balloon incident, but it also involved Sladen spending a bunch of time trying to produce an SVG of a London bus as a D-Bus logo and not really writing our hypothetical userland bootsplash program, so on the last night, fueled by Koff that we'd bought by just collecting all the discarded empty bottles and returning them for the deposits, I started writing one.

I knew that Debian was already using graphics mode for installation despite having a textual installer, because they needed to deal with more complex fonts than VGA could manage. Digging into the code, I found that it used BOGL - a graphics library that made use of the VGA framebuffer to draw things. VGA had a pre-allocated memory range for the framebuffer[3], which meant the firmware probably wouldn't map anything else there any hitting those addresses probably wouldn't break anything. This seemed safe.

A few hours later, I had some code that could use BOGL to print status messages to the screen of a machine booted with vga16fb. I woke up some time later, somehow found myself in an airport, and while sitting at the departure gate[4] I spent a while staring at VGA documentation and worked out which magical calls I needed to make to have it behave roughly like a linear framebuffer. Shortly before I got on my flight back to the UK, I had something that could also draw a graphical picture.

Usplash shipped shortly afterwards. We hit various issues - vga16fb produced a 640x480 mode, and some laptops were not inclined to do that without a BIOS call first. 640x400 worked basically everywhere, but meant we had to redraw the art because circles don't work the same way if you change the resolution. My brief "UBUNTU BETA" artwork that was me literally writing "UBUNTU BETA" on an HP TC1100 shortly after I'd got the Wacom screen working did not go down well, and thankfully we had better artwork before release.

But 16 colours is somewhat limiting. SVGALib offered a way to get more colours and better resolution in userland, retaining our prerequisites. Unfortunately it relied on VM86, which doesn't exist in 64-bit mode on Intel systems. I ended up hacking the X.org x86emu into a thunk library that exposed the same API as LRMI, so we could run it without needing VM86. Shockingly, it worked - we had support for 256 colour bootsplashes in any supported resolution on 64 bit systems as well as 32 bit ones.

But by now it was obvious that the future was having the kernel manage graphics support, both in terms of native programming and in supporting suspend/resume. Plymouth is much more fully featured than Usplash ever was, but relies on functionality that simply didn't exist when we started this adventure. There's certainly an argument that we'd have been better off making reasonable kernel modesetting support happen faster, but at this point I had literally no idea how to write decent kernel code and everyone should be happy I kept this to userland.

Anyway. The moral of all of this is that sometimes history works out such that you write some software that a huge number of people run without any idea of who you are, and also that this can happen without you having any fucking idea what you're doing.

Write code. Do crimes.

[1] vesafb relied on either the bootloader or the early stage kernel performing a VBE call to set a mode, and then just drawing directly into that framebuffer. When we were doing GPU reinitialisation in userland we couldn't guarantee that we'd run before the kernel tried to draw stuff into that framebuffer, and there was a risk that that was mapped to something dangerous if the GPU hadn't been reprogrammed into the same state. It turns out that having GPU modesetting in the kernel is a Good Thing.

[2] ACPI didn't guarantee that the firmware would reinitialise the graphics hardware, and as a result most machines didn't. At this point Linux didn't have native support for initialising most graphics hardware, so we fell back to doing it from userland. VBEtool was a terrible hack I wrote to try to re-execute the system's graphics hardware through a range of mechanisms, and it worked in a surprising number of cases.

[3] As long as you were willing to deal with 640x480 in 16 colours

[4] Helsinki-Vantaan had astonishingly comfortable seating for time

comment count unavailable comments

22 April 2021

Shirish Agarwal: The Great Train Robbery

I had a twitter fight few days back with a gentleman and the article is a result of that fight. Sadly, I do not know the name of the gentleman as he goes via a psuedo name and then again I ve not taken permission from him to quote him in either way. So I will just state the observations I was able to make from the conversations we had. As people who read this blog regularly would know, I am and have been against Railway Privatization which is happening in India. And will be sharing some of the case studies from other countries as to how it panned out for them.

UK Railways
How Privatization Fails : Railways
The Above video is by a gentleman called Shaun who basically shared that privatization as far as UK is concerned is nothing but monopolies and while there are complex reasons for the same, the design of the Railways is such that it will always be a monopoly structure. At the most what you can do is have several monopolies but that is all that can happen. The idea of competition just cannot happen. Even the idea that subsidies will be less or/and trains will run on time is far from fact. Both of these facts have been checked and found to be truthful by fullfact.org. It is and argued that UK is small and perhaps it doesn t have the right conditions. It is probably true but still we do deserve to have a glance at the UK railway map.
UK railway map with operatorsUK railway map with operators
The above map is copyrighted to Map Marketing where you could see it today . As can be seen above most companies had their own specified areas. Now if you had looked at the facts then you would have seen that UK fares have been higher. In fact, an oldish article from Metro (a UK publication) shares the same. In fact, UK nationalized its railways effectively as many large rail operators were running in red. Even Scotland is set to nationalised back in March 2022. Remember this is a country which hasn t seen inflation go upwards of 5% in nearly a decade. The only outlier was 2011 where they indeed breached the 5% mark. So from this, what we see is Private Gains and Private Gains Public Losses perhaps seem fit. But then maybe we didn t use the right example. Perhaps Japan would be better. They have bullet trains while UK is still thinking about it. (HS2).

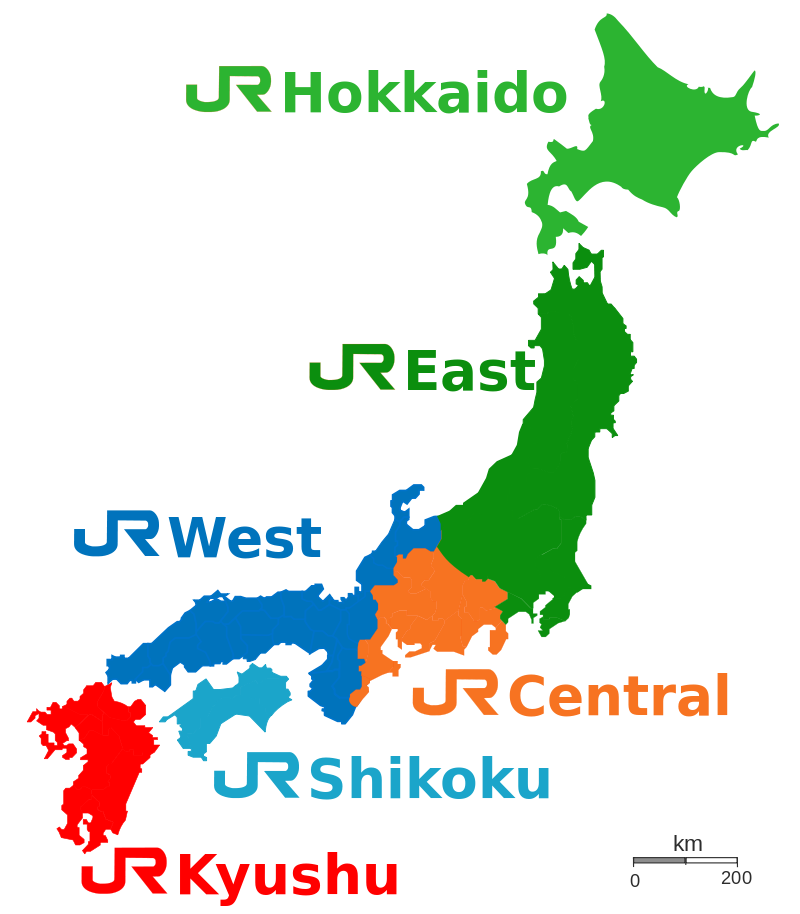
Japanese Railway Below is the map of Japanese Railway
Railway map of Japan with private ownership courtesy Wikimedia commons
Japan started privatizing its railway in 1987 and to date it has not been fully privatized. And on top of it, amount as much as 24 trillion of the long-term JNR debt was shouldered by the government at the expense of taxpayers of Japan while also reducing almost 1/4th of it employees. To add to it, while some parts of Japanese Railways did make profits, many of them made profits by doing large-scale non-railway business mostly real estate of land adjacent to railway stations. In many cases, it seems this went all the way up to 60% of the revenue. The most profitable has been the Shinkansen though. And while it has been profitable, it has not been without safety scandals over the years, the biggest in recent years was the 2005 Amagasaki derailment. What was interesting to me was the Aftermath, while the Wikipedia page doesn t share much, I had read at the time and probably could be found how a lot of ordinary people stood up to the companies in a country where it is a known fact that most companies are owned by the Yakuza. And this is a country where people are loyal to their corporation or company no matter what. It is a strange culture to west and also here in India where people change jobs on drop of hat, although nowadays we have record unemployment. So perhaps Japan too does not meet our standard as it doesn t do competition with each other but each is a set monopoly in those regions. Also how much subsidy is there or not is not really transparent.

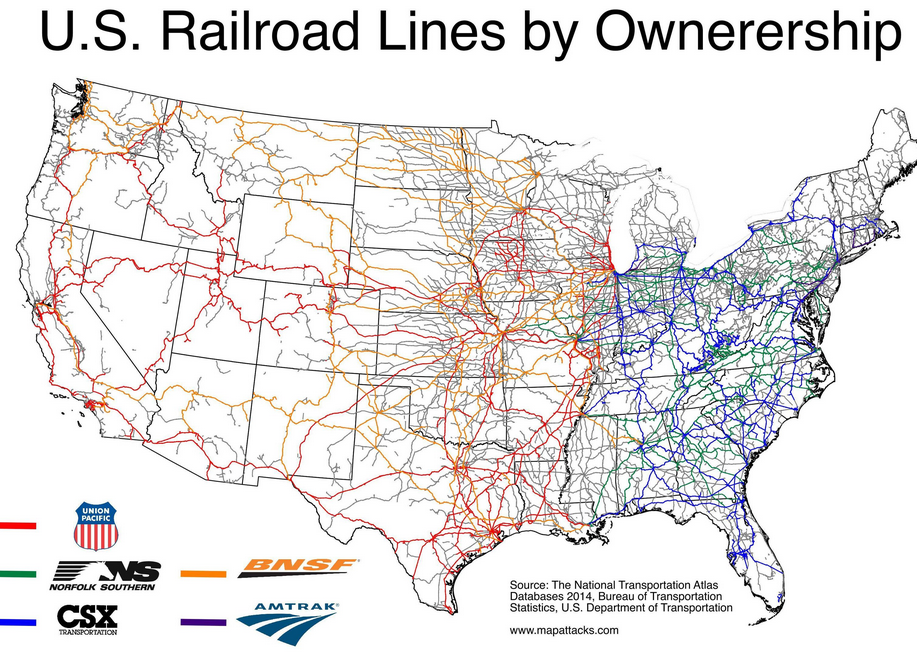
U.S. Railways Last, but not the least I share the U.S. Railway map. This is provided by A Mr. Tom Alison on reddit on channel maporn. As the thread itself is archived and I do not know the gentleman concerned, nor have taken permission for the map, hence sharing the compressed version


U.S. Railway lines with the different owners
Now the U.S. Railways is and has always been peculiar as unlike the above two the U.S. has always been more of a freight network. Probably, much of it has to do that in the 1960 s when oil was cheap, the U.S. made zillions of roadways and romanticized the road trip and has been doing it ever since. Also the creation of low-cost airlines definitely didn t help the railways to have more passenger services, in fact the opposite. There are and have been smaller services and attempts of privatization in both New Zealand and Australia and both have been failures. Please see papers in that regard. My simple point is this, as can be seen above, there have been various attempts at privatization of railways and most of them have been a mixed bag. The only one which comes close to what we think as good is Japanese but that also used a lot of public debt which we don t know what will happen on next. Also for higher-speed train services like a bullet train or whatever, you need to direct, no hair pen bends. In fact, a good talk on the topic is the TBD podcast which while it talks about hyperloop, the same questions is and would be asked if were to do in India. Another thing to be kept in mind is that the Japanese have been exceptional builders and this is because they have been forced to. They live in a seismically active zone which made Fukushima disaster a reality but at the same time, their buildings are earthquake-resistant. Standard Disclaimer The above is a simplified version of things. I could have added in financial accounts but that again has no set pattern. For e.g. some Railways use accrual, some use cash and some use hybrid. I could have also shared in either the guage or electrification but all have slightly different standards, although uniguage is something that all Railways aspire for and electrification is again something that all Railways want although in many cases it just isn t economically feasible.

Indian Railways Indian Railways itself recently made the move from Cash to Accrual couple of years back. In-between for a couple of years, it was hybrid. The sad part is and was you can now never measure against past performance in the old way because it is so different. Hence, whether the Railways will be making a loss or a profit, we would come to know only much later. Also, most accountants don t know the new system well, so it is gonna take more time, how much unknown. Sadly, what GOI did a few years back is merge the Railway budget into the Union Budget. Of course, the excuse they gave is too many pressures of new trains, while the truth is, by doing this, they decreased transparency about the whole thing. For e.g. for the last few years, the only state which had significant work being done is in U.P. (Uttar Pradesh) and a bit in Goa, although that is has been protested time and again. I being from the neighborly state of Maharashtra , and have been there several times. Now it does feels all like a dream, going to Goa :(.

Covid news Now before I jump on the news, I should share the movie Virus (2019) which was made by the talented Aashiq Abu. Even though, am not a Malayalee, I still have enjoyed many of his movies simply because he is a terrific director and Malayalam movies, at least most of them have English subtitles and lot of original content.. Interestingly, unlike the first couple of times when I saw it a couple of years back. The first time I saw it, I couldn t sleep a wink for a week. Even the next time, it was heavy. I had shared the movie with mum, and even she couldn t see it in one go. It is and was that powerful Now maybe because we are headlong in the pandemic, and the madness is all around us. There are two terms that helped me though understand a great deal of what is happening in the movie, the first term was altered sensorium which has been defined here. The other is saturation or to be more precise oxygen saturation . This term has also entered the Indian twitter lexicon quite a bit as India has started running out of oxygen. Just today Delhi High Court did an emergency hearing on the subject late at night. Although there is much to share about the mismanagement of the center, the best piece on the subject has been by Miss Priya Ramani. Yup, the same lady who has won against M.J. Akbar and this is when Mr. Akbar had 100 lawyers for this specific case. It would be interesting to see what happens ahead. There are however few things even she forgot in her piece, For e.g. reverse migration i.e. from urban to rural migration started again. Two articles from different entities sharing a similar outlook.Sadly, the right have no empathy or feeling for either the poor or the sick. Even the labor minister Santosh Gangwar s statement that around 1.04 crores were the only people who walked back home. While there is not much data, however some work/research has been done on migration to cites that the number could be easily 10 times as much. And this was in the lockdown of last year. This year, again the same issue has re-surfaced and migrants learning lessons started leaving cities. And I m ashamed to say I think they are doing the right thing. Most State Governments have not learned lessons nor have they done any work to earn the trust of migrants. This is true of almost all state Governments. Last year, just before the lockdown was announced, me and my friend spent almost 30k getting a cab all the way from Chennai to Pune, how much we paid for the cab, how much we bribed the various people just so we could cross the state borders to return home to our anxious families. Thankfully, unlike the migrants, we were better off although we did make a loss. I probably wouldn t be alive if I were in their situation as many didn t. That number is still in the air undocumented deaths  Vaccine issues Currently, though the issue has been the Vaccine and the pricing of the same. A good article to get a summation of the issues outlined has been shared on Economist. Another article that goes to the heart of the issue is at scroll. To buttress the argument, the SII chairman had shared this few weeks back
Adar Poonawala talking to Vishnu Som on Left, right center, 7th April 2021.
So, a licensee manufacturer wants to make super-profits during the pandemic. And now, as shared above they can very easily do it. Even the quotes given to nearby countries is smaller than the quotes given to Indian states

Prices of AstraZeneca among various states and countries.
The situation around beds, vaccines, oxygen, anything is so dire that people could go to any lengths to save their loved ones. Even if they know if a certain medicine doesn t work. For e.g. Remdesivir, 5 WHO trials have concluded that it doesn t increase mortality. Heck, even AIIMS chief said the same. But both doctors and relatives desperation to cling on hope has made Remdesivir as a black market drug with unoffical prices hovering anywhere between INR 14k/- to INR30k/- per vial. One of the executives of a top firm was also arrested in Gujarat. In Maharashtra, the opposition M.P. came to the rescue of the officials of Bruick pharms in Mumbai. Sadly, this strange affliction to the party in the center is also there in my extended family. At one end, they will heap praise on Mr. Modi, at the same time they can t get wait to get fast out of India. Many of them have settled in horrors of horror Dubai, as it is the best place to do business, get international schools for the young ones at decent prices, cheaper or maybe a tad more than what they paid in Delhi or elsewhere. Being an Agarwal or a Gupta makes it easier to compartmentalize both things. Ease of doing business, 5 days flat to get a business registered, up and running. And the paranoia is still there. They won t talk on the phone about him because they are afraid they may say something which comes back to bite them. As far as their decision to migrate, can t really blame them. If I were 20-25 yeas younger and my mum were in a better shape than she is, we probably would have migrated as well, although would have preferred Europe than anywhere else.

Internet Freedom and Aarogya Setu App.


Internet Freedom had shared the chilling effects of the Aarogya Setu App. This had also been shared by FSCI in the past, and recently had their handle being banned on Twitter. This was also apparent in a legal bail order which the high court judge gave. While I won t go into the merits and demerits of the bail order, it is astounding for the judge to say that the accused, even though he would be on bail install an app. so he can be surveilled. And this is a high court judge, such a sad state of affairs. We seem to be putting up new lows every day when it comes to judicial jurisprudence. One interesting aspect of the whole case was shared by Aishwarya Iyer. She shared a story that she and her team worked on quint which raises questions on the quality of the work done by Delhi Police. This is of course, up to Delhi Police to ascertain the truth of the matter because unless and until they are able to tie in the PMO s office in for a leak or POTUS s office it hardly seems possible. For e.g. the dates when two heads of state can meet each other would be decided by the secretaries of the two. Once the date is known, it would be shared with the press while at the same time some sort of security apparatus would kick in place. It is incumbent, especially on the host to take as much care as he can of the guest. We all remember that World War 1 (the war to end all wars) started due to the murder of Archduke Ferdinand.

As nobody wants that, the best way is to make sure that a political murder doesn t happen on your watch. Now while I won t comment on what it would be, it would be safe to assume that it would be z+ security along with higher readiness. Especially if it as somebody as important as POTUS. Now, it would be quite a reach for Delhi Police to connect the two dates. They either will have to get creative with the dates or some other way. Otherwise, with practically no knowledge in the public domain, they can t work in limbo. In either case, I do hope the case comes up for hearing soon and we see what the Delhi Police says and contends in the High Court about the same. At the very least, it would be irritating for them to talk of the dates unless they can contend some mass conspiracy which involves the PMO (and would bring into question the constant vetting done by the Intelligence dept. of all those who work in PMO). And this whole case is to kind of shelter to the Delhi riots which happened in which majorly the Muslims died but their deaths lay unaccounted till date

Conclusion In Conclusion, I would like to share a bit of humor because right now the atmosphere is humorless, both with authoritarian tendencies of the Central Govt. and the mass mismanagement of public health which they now have left to the state to do as they fit. The peice I am sharing is from arre, one of my goto sites whenever I feel low.

19 April 2021

Ritesh Raj Sarraf: Catching Up Your Sources

I ve mostly had the preference of controlling my data rather than depend on someone else. That s one reason why I still believe email to be my most reliable medium for data storage, one that is not plagued/locked by a single entity. If I had the resources, I d prefer all digital data to be broken down to its simplest form for storage, like email format, and empower the user with it i.e. their data. Yes, there are free services that are indirectly forced upon common users, and many of us get attracted to it. Many of us do not think that the information, which is shared for the free service in return, is of much importance. Which may be fair, depending on the individual, given that they get certain services without paying any direct dime.

New age communication So first, we had email and usenet. As I mentioned above, email was designed with fine intentions. Intentions that make it stand even today, independently. But not everything, back then, was that great either. For example, instant messaging was very closed and centralised then too. Things like: ICQ, MSN, Yahoo Messenger; all were centralized. I wonder if people still have access to their ICQ logs. Not much has chagned in the current day either. We now have domination by: Facebook Messenger, Google Whatever the new marketing term they introdcue, WhatsApp, Telegram, Signal etc. To my knowledge, they are all centralized. Over all this time, I m yet to see a product come up with good (business) intentions, to really empower the end user. In this information age, the most invaluable data is user activity. That s one data everyone is after. If you decline to share that bit of free data in exchange for the free services, mind you, that that free service like Facebook, Google, Instagram, WhatsApp, Truecaller, Twitter; none of it would come to you at all. Try it out. So the reality is that while you may not be valuating the data you offer in exchange correctly, there s a lot that is reaped from it. But still, I think each user has (and should have) the freedom to opt in for these tech giants and give them their personal bit, for free services in return. That is a decent barter deal. And it is a choice that one if free to choose

Retaining my data I m fond of keeping an archive folder in my mailbox. A folder that holds significant events in the form of an email usually, if documented. Over the years, I chose to resort to the email format because I felt it was more reliable in the longer term than any other formats. The next best would be plain text. In my lifetime, I have learnt a lot from the internet; so it is natural that my preference has been with it. Mailing Lists, IRCs, HOWTOs, Guides, Blog posts; all have helped. And over the years, I ve come across hundreds of such content that I d always like to preserve. Now there are multiple ways to preserving data. Like, for example, big tech giants. In most usual cases, your data for your lifetime, should be fine with a tech giant. In some odd scenarios, you may be unlucky if you relied on a service provider that went bankrupt. But seriously, I think users should be fine if they host their data with Microsoft, Google etc; as long as they abide by their policies. There s also the catch of alignment. As the user, you should ensure to align (and transition) with the product offerings of your service provider. Otherwise, what may look constant and always reliable, will vanish in the blink of an eye. I guess Google Plus would be a good example. There was some Google Feed service too. Maybe Google Photos in the near decade future, just like Google Picasa in the previous (or current) decade.

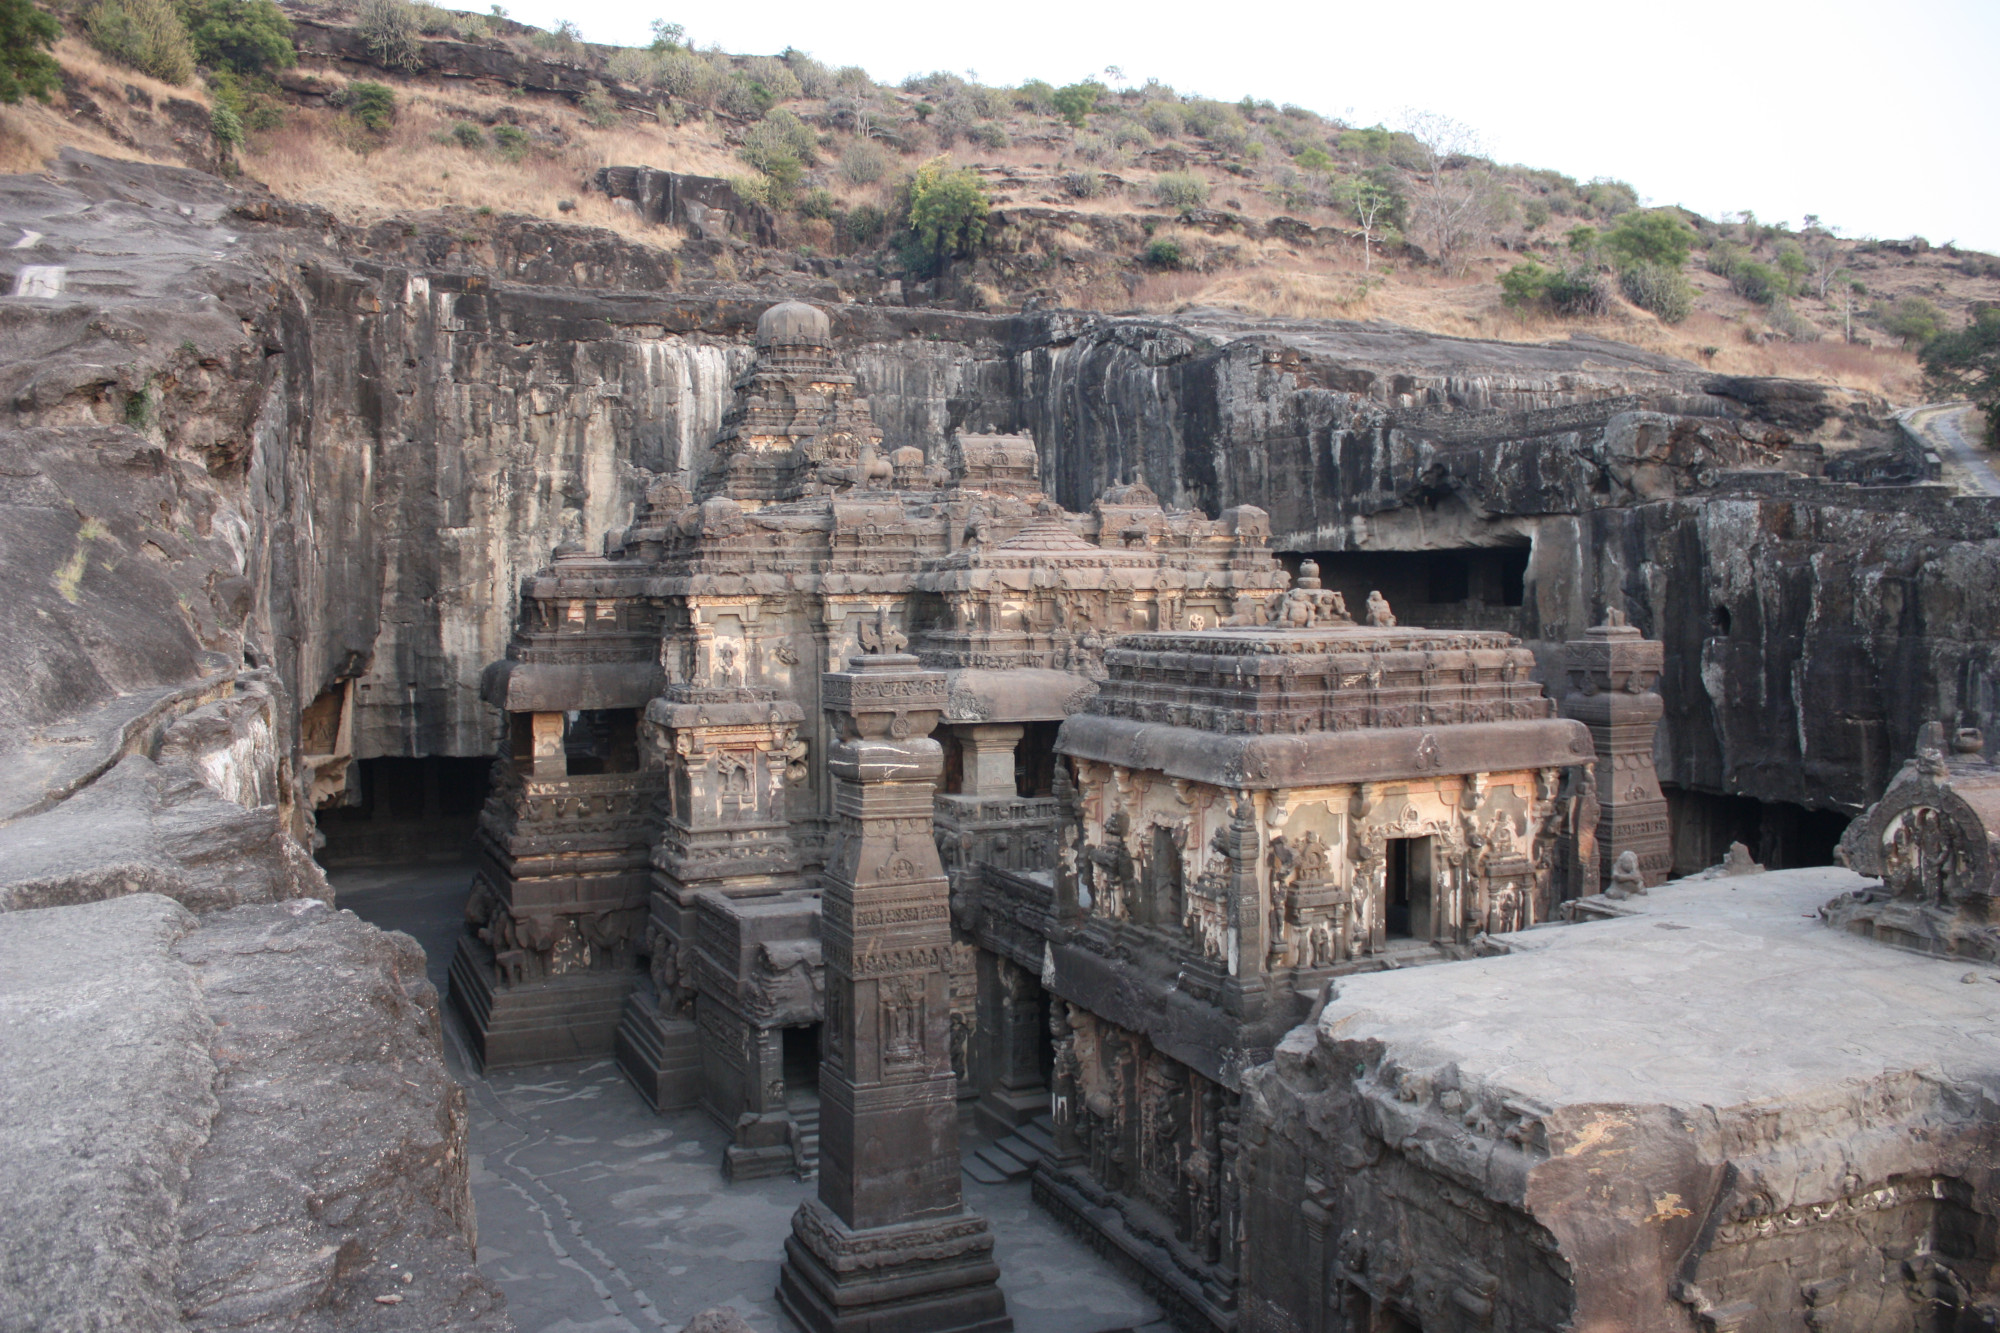
History what is On the topic of retaining information, lets take a small drift. I still admire our ancestors. I don t know what went in their mind when they were documenting events in the form of scriptures, carvings, temples, churches, mosques etc; but one things for sure, they were able to leave a fine means of communication. They are all gone but a large number of those events are evident through the creations that they left. Some of those events have been strong enough that further rulers/invaders have had tough times trying to wipe it out from history. Remember, history is usually not the truth, but the statement to be believed by the teller. And the teller is usually the survivor, or the winner you may call. But still, the information retention techniques were better. I haven t visited, but admire whosoever built the Kailasa Temple, Ellora, without which, we d be made to believe what not by all invaders and rulers of the region. But the majestic standing of the temple, is a fine example of the history and the events that have occured in the past.
Ellora Temple -  The majectic carving believed to be carved out of a single stone
Ellora Temple - The majectic carving believed to be carved out of a single stone
Dominance has the power to rewrite history and unfortunately that s true and it has done its part. It is just that in a mere human s defined lifetime, it is not possible to witness the transtion from current to history, and say that I was there then and I m here now, and this is not the reality. And if not dominance, there s always the other bit, hearsay. With it, you can always put anything up for dispute. Because there s no way one can go back in time and produce a fine evidence. There s also a part about religion. Religion can be highly sentimental. And religion can be a solid way to get an agenda going. For example, in India - a country which today consitutionally is a secular country, there have been multiple attempts to discard the belief, that never ever did the thing called Ramayana exist. That the Rama Setu, nicely reworded as Adam s Bridge by who so ever, is a mere result of science. Now Rama, or Hanumana, or Ravana, or Valmiki, aren t going to come over and prove that that is true or false. So such subjects serve as a solid base to get an agenda going. And probably we ve even succeeded in proving and believing that there was never an event like Ramayana or the Mahabharata. Nor was there ever any empire other than the Moghul or the British Empire. But yes, whosoever made the Ellora Temple or the many many more of such creations, did a fine job of making a dent for the future, to know of what the history possibly could also be.

Enough of the drift So, in my opinion, having events documented is important. It d be nice to have skills documented too so that it can be passed over generations but that s a debatable topic. But events, I believe should be documented. And documented in the best possible ways so that its existence is not diminished. A documentation in the form of certain carvings on a rock is far more better than links and posts shared on Facebook, Twitter, Reddit etc. For one, these are all corporate entities with vested interests and can pretext excuse in the name of compliance and conformance. So, for the helpless state and generation I am in, I felt email was the best possible independent form of data retention in today s age. If I really had the resources, I d not rely on digital age. This age has no guarantee of retaining and recording information in any reliable manner. Instead, it is just mostly junk, which is manipulative and changeable, conditionally.

Email and RSS So for my communication, I like to prefer emails over any other means. That doesn t mean I don t use the current trends. I do. But this blog is mostly about penning my desires. And desire be to have communication over email format. Such is the case that for information useful over the internet, I crave to have it formatted in email for archival. RSS feeds is my most common mode of keeping track of information I care about. Not all that I care for is available in RSS feeds but hey such is life. And adaptability is okay. But my preference is still RSS. So I use RSS feeds through a fine software called feed2imap. A software that fits my bill fairly well. feed2imap is:
  • An rss feed news aggregator
  • Pulls and extracts news feeds in the form of an email
  • Can push the converted email over pop/imap
  • Can convert all image content to email mime attachment
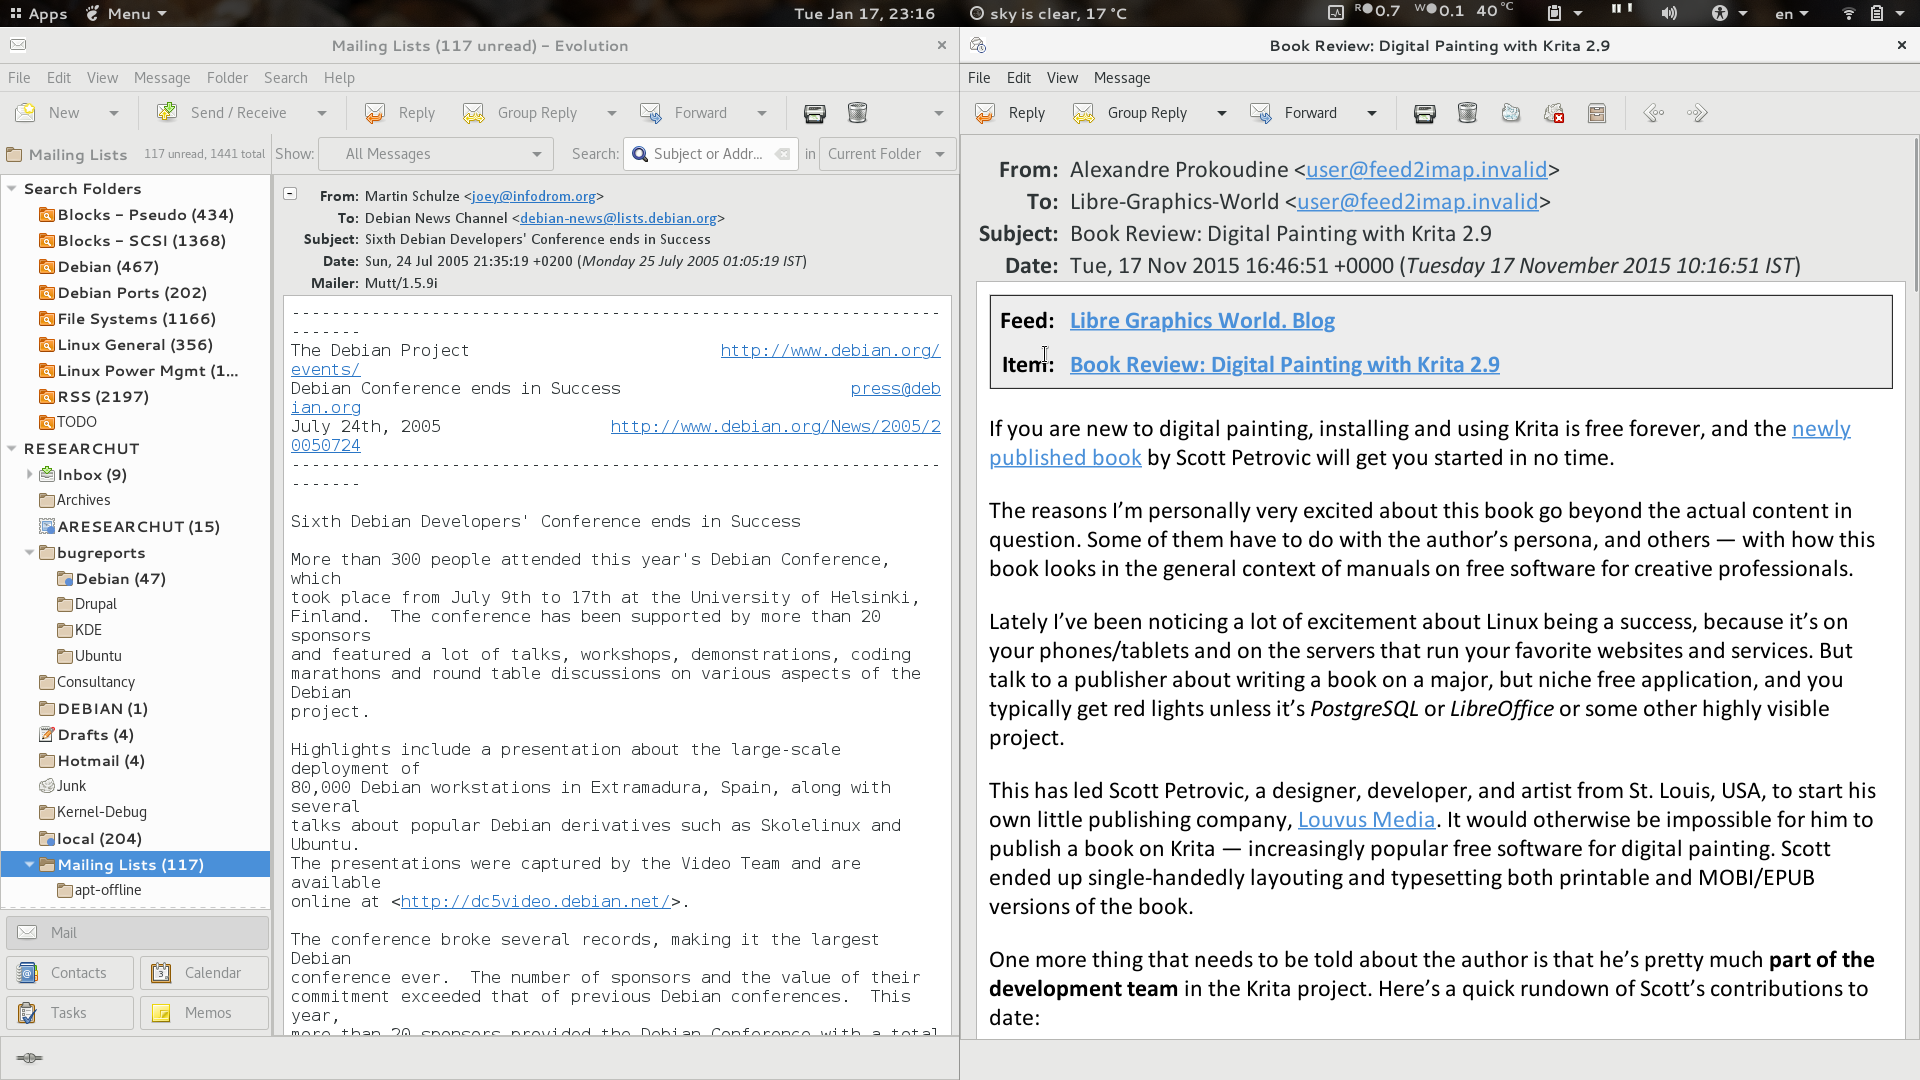
In a gist, it makes the online content available to me offline in the most admired email format In my mail box, in today s day, my preferred email client is Evolution. It does a good job of dealing with such emails (rss feed items). An image example of accessing the rrs feed item through it is below
RSS News Item through Evolution
The good part is that my actual data is always independent of such MUAs. Tomorrow, as technology - trends - economics evolve, something new would come as a replacement but my data would still be mine.

14 April 2021

Dirk Eddelbuettel: RcppArmadillo 0.10.4.0.0 on CRAN: New Upstream Plus

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 852 other packages on CRAN. This new release brings us the just release Armadillo 10.4.0. Upstream moves at a speed that is a little faster than the cadence CRAN likes. We release RcppArmadillo 0.10.2.2.0 on March 9; and upstream 10.3.0 came out shortly thereafter. We aim to accomodate CRAN with (roughly) monthly (or less frequent) releases) so by the time we were ready 10.4.0 had just come out. As it turns, the full testing had a benefit. Among the (currently) 852 CRAN packages using RcppArmadillo, two were failing tests. This is due to a subtle, but important point. Early on we realized that it would be beneficial if the standard R control over random-number creation and seeding affected Armadillo too, which Conrad accomodated kindly with an optional RNG interface which RcppArmadillo supplies. With recent changes he made, the R side saw normally-distributed draws (via the Armadillo interface) changed, which lead to the two changes. All hail unit tests. So I mentioned this to Conrad, and with the usual Chicago-Brisbane time difference late my evening a fix was in my inbox. The CRAN upload was then halted as I had missed that due to other changes he had made random draws from a Gamma would now call std::rand() which CRAN flags. Another email to Brisbane, another late (one-line) fix back and all was good. We still encountered one package with an error but flagged this as internal to that package s setup, so Uwe let RcppArmadillo onto CRAN, I contacted that package s maintainer who was very receptive and a change should be forthcoming. So with all that we have 0.10.4.0.0 on CRAN giving us Armadillo 10.4.0. The full set of changes follows. As Armadillo 10.3.0 was not uploaded to CRAN, its changes are included too.

Changes in RcppArmadillo version 0.10.4.0.0 (2021-04-12)
  • Upgraded to Armadillo release 10.4.0 (Pressure Cooker)
    • faster handling of triangular matrices by log_det()
    • added log_det_sympd() for log determinant of symmetric positive matrices
    • added ARMA_WARN_LEVEL configuration option, to control the degree of emitted warning messages
    • reduced the default degree of warning messages, so that failed decompositions, failed saving/loading, etc, no longer emit warnings
  • Apply one upstream corrections for arma::randn draws when using alternative (here R) generator, and arma::randg.

Changes in RcppArmadillo version 0.10.3.0.0 (2021-03-10)
  • Upgraded to Armadillo release 10.3 (Sunrise Chaos)
    • faster handling of symmetric positive definite matrices by pinv()
    • expanded .save() / .load() for dense matrices to handle coord_ascii format
    • for out of bounds access, element accessors now throw the more nuanced std::out_of_range exception, instead of only std::logic_error
    • improved quality of random numbers

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

12 April 2021

Russell Coker: Yama

I ve just setup the Yama LSM module on some of my Linux systems. Yama controls ptrace which is the debugging and tracing API for Unix systems. The aim is to prevent a compromised process from using ptrace to compromise other processes and cause more damage. In most cases a process which can ptrace another process which usually means having capability SYS_PTRACE (IE being root) or having the same UID as the target process can interfere with that process in other ways such as modifying it s configuration and data files. But even so I think it has the potential for making things more difficult for attackers without making the system more difficult to use. If you put kernel.yama.ptrace_scope = 1 in sysctl.conf (or write 1 to /proc/sys/kernel/yama/ptrace_scope) then a user process can only trace it s child processes. This means that strace -p and gdb -p will fail when run as non-root but apart from that everything else will work. Generally strace -p (tracing the system calls of another process) is of most use to the sysadmin who can do it as root. The command gdb -p and variants of it are commonly used by developers so yama wouldn t be a good thing on a system that is primarily used for software development. Another option is kernel.yama.ptrace_scope = 3 which means no-one can trace and it can t be disabled without a reboot. This could be a good option for production servers that have no need for software development. It wouldn t work well for a small server where the sysadmin needs to debug everything, but when dozens or hundreds of servers have their configuration rolled out via a provisioning tool this would be a good setting to include. See Documentation/admin-guide/LSM/Yama.rst in the kernel source for the details. When running with capability SYS_PTRACE (IE root shell) you can ptrace anything else and if necessary disable Yama by writing 0 to /proc/sys/kernel/yama/ptrace_scope . I am enabling mode 1 on all my systems because I think it will make things harder for attackers while not making things more difficult for me. Also note that SE Linux restricts SYS_PTRACE and also restricts cross-domain ptrace access, so the combination with Yama makes things extra difficult for an attacker. Yama is enabled in the Debian kernels by default so it s very easy to setup for Debian users, just edit /etc/sysctl.d/whatever.conf and it will be enabled on boot.

Russell Coker: Riverdale

I ve been watching the show Riverdale on Netflix recently. It s an interesting modern take on the Archie comics. Having watched Josie and the Pussycats in Outer Space when I was younger I was anticipating something aimed towards a similar audience. As solving mysteries and crimes was apparently a major theme of the show I anticipated something along similar lines to Scooby Doo, some suspense and some spooky things, but then a happy ending where criminals get arrested and no-one gets hurt or killed while the vast majority of people are nice. Instead the first episode has a teen being murdered and Ms Grundy being obsessed with 15yo boys and sleeping with Archie (who s supposed to be 15 but played by a 20yo actor). Everyone in the show has some dark secret. The filming has a dark theme, the sky is usually overcast and it s generally gloomy. This is a significant contrast to Veronica Mars which has some similarities in having a young cast, a sassy female sleuth, and some similar plot elements. Veronica Mars has a bright theme and a significant comedy element in spite of dealing with some dark issues (murder, rape, child sex abuse, and more). But Riverdale is just dark. Anyone who watches this with their kids expecting something like Scooby Doo is in for a big surprise. There are lots of interesting stylistic elements in the show. Lots of clothing and uniform designs that seem to date from the 1940 s. It seems like some alternate universe where kids have smartphones and laptops while dressing in the style of the 1940s. One thing that annoyed me was construction workers using tools like sledge-hammers instead of excavators. A society that has smart phones but no earth-moving equipment isn t plausible. On the upside there is a racial mix in the show that more accurately reflects American society than the original Archie comics and homophobia is much less common than in most parts of our society. For both race issues and gay/lesbian issues the show treats them in an accurate way (portraying some bigotry) while the main characters aren t racist or homophobic. I think it s generally an OK show and recommend it to people who want a dark show. It s a good show to watch while doing something on a laptop so you can check Wikipedia for the references to 1940s stuff (like when Bikinis were invented). I m half way through season 3 which isn t as good as the first 2, I don t know if it will get better later in the season or whether I should have stopped after season 2. I don t usually review fiction, but the interesting aesthetics of the show made it deserve a review.

Russell Coker: Storage Trends 2021

The Viability of Small Disks Less than a year ago I wrote a blog post about storage trends [1]. My main point in that post was that disks smaller than 2TB weren t viable then and 2TB disks wouldn t be economically viable in the near future. Now MSY has 2TB disks for $72 and 2TB SSD for $245, saving $173 if you get a hard drive (compared to saving $240 10 months ago). Given the difference in performance and noise 2TB hard drives won t be worth using for most applications nowadays. NVMe vs SSD Last year NVMe prices were very comparable for SSD prices, I was hoping that trend would continue and SSDs would go away. Now for sizes 1TB and smaller NVMe and SSD prices are very similar, but for 2TB the NVMe prices are twice that of SSD presumably partly due to poor demand for 2TB NVMe. There are also no NVMe devices larger than 2TB on sale at MSY (a store which caters to home stuff not special server equipment) but SSDs go up to 8TB. It seems that NVMe is only really suitable for workstation storage and for cache etc on a server. So SATA SSDs will be around for a while. Small Servers There are a range of low end servers which support a limited number of disks. Dell has 2 disk servers and 4 disk servers. If one of those had 8TB SSDs you could have 8TB of RAID-1 or 24TB of RAID-Z storage in a low end server. That covers the vast majority of servers (small business or workgroup servers tend to have less than 8TB of storage). Larger Servers Anandtech has an article on Seagates roadmap to 120TB disks [2]. They currently sell 20TB disks using HAMR technology Currently the biggest disks that MSY sells are 10TB for $395, which was also the biggest disk they were selling last year. Last year MSY only sold SSDs up to 2TB in size (larger ones were available from other companies at much higher prices), now they sell 8TB SSDs for $949 (4* capacity increase in less than a year). Seagate is planning 30TB disks for 2023, if SSDs continue to increase in capacity by 4* per year we could have 128TB SSDs in 2023. If you needed a server with 100TB of storage then having 2 or 3 SSDs in a RAID array would be much easier to manage and faster than 4*30TB disks in an array. When you have a server with many disks you can expect to have more disk failures due to vibration. One time I built a server with 18 disks and took disks from 2 smaller servers that had 4 and 5 disks. The 9 disks which had been working reliably for years started having problems within weeks of running in the bigger server. This is one of the many reasons for paying extra for SSD storage. Seagate is apparently planning 50TB disks for 2026 and 100TB disks for 2030. If that s the best they can do then SSD vendors should be able to sell larger products sooner at prices that are competitive. Matching hard drive prices is not required, getting to less than 4* the price should be enough for most customers. The Anandtech article is worth reading, it mentions some interesting features that Seagate are developing such as having 2 actuators (which they call Mach.2) so the drive can access 2 different tracks at the same time. That can double the performance of a disk, but that doesn t change things much when SSDs are more than 100* faster. Presumably the Mach.2 disks will be SAS and incredibly expensive while providing significantly less performance than affordable SATA SSDs. Computer Cases In my last post I speculated on the appearance of smaller cases designed to not have DVD drives or 3.5 hard drives. Such cases still haven t appeared apart from special purpose machines like the NUC that were available last year. It would be nice if we could get a new industry standard for smaller power supplies. Currently power supplies are expected to be almost 5 inches wide (due to the expectation of a 5.25 DVD drive mounted horizontally). We need some industry standards for smaller PCs that aren t like the NUC, the NUC is very nice, but most people who build their own PC need more space than that. I still think that planning on USB DVD drives is the right way to go. I ve got 4PCs in my home that are regularly used and CDs and DVDs are used so rarely that sharing a single DVD drive among all 4 wouldn t be a problem. Conclusion I m tempted to get a couple of 4TB SSDs for my home server which cost $487 each, it currently has 2*500G SSDs and 3*4TB disks. I would have to remove some unused files but that s probably not too hard to do as I have lots of old backups etc on there. Another possibility is to use 2*4TB SSDs for most stuff and 2*4TB disks for backups. I m recommending that all my clients only use SSDs for their storage. I only have one client with enough storage that disks are the only option (100TB of storage) but they moved all the functions of that server to AWS and use S3 for the storage. Now I don t have any clients doing anything with storage that can t be done in a better way on SSD for a price difference that s easy for them to afford. Affordable SSD also makes RAID-1 in workstations more viable. 2 disks in a PC is noisy if you have an office full of them and produces enough waste heat to be a reliability issue (most people don t cool their offices adequately on weekends). 2 SSDs in a PC is no problem at all. As 500G SSDs are available for $73 it s not a significant cost to install 2 of them in every PC in the office (more cost for my time than hardware). I generally won t recommend that hard drives be replaced with SSDs in systems that are working well. But if a machine runs out of space then replacing it with SSDs in a RAID-1 is a good choice. Moore s law might cover SSDs, but it definitely doesn t cover hard drives. Hard drives have fallen way behind developments of most other parts of computers over the last 30 years, hopefully they will go away soon.

11 April 2021

Jelmer Vernooij: The upstream ontologist

The Debian Janitor is an automated system that commits fixes for (minor) issues in Debian packages that can be fixed by software. It gradually started proposing merges in early December. The first set of changes sent out ran lintian-brush on sid packages maintained in Git. This post is part of a series about the progress of the Janitor. The upstream ontologist is a project that extracts metadata about upstream projects in a consistent format. It does this with a combination of heuristics and reading ecosystem-specific metadata files, such as Python s setup.py, rust s Cargo.toml as well as e.g. scanning README files.

Supported Data Sources It will extract information from a wide variety of sources, including:
Supported Fields Fields that it currently provides include:
  • Homepage: homepage URL
  • Name: name of the upstream project
  • Contact: contact address of some sort of the upstream (e-mail, mailing list URL)
  • Repository: VCS URL
  • Repository-Browse: Web URL for viewing the VCS
  • Bug-Database: Bug database URL (for web viewing, generally)
  • Bug-Submit: URL to use to submit new bugs (either on the web or an e-mail address)
  • Screenshots: List of URLs with screenshots
  • Archive: Archive used - e.g. SourceForge
  • Security-Contact: e-mail or URL with instructions for reporting security issues
  • Documentation: Link to documentation on the web:
  • Wiki: Wiki URL
  • Summary: one-line description of the project
  • Description: longer description of the project
  • License: Single line license description (e.g. GPL 2.0 ) as declared in the metadata[1]
  • Copyright: List of copyright holders
  • Version: Current upstream version
  • Security-MD: URL to markdown file with security policy
All data fields have a certainty associated with them ( certain , confident , likely or possible ), which gets set depending on how the data was derived or where it was found. If multiple possible values were found for a specific field, then the value with the highest certainty is taken.
Interface The ontologist provides a high-level Python API as well as two command-line tools that can write output in two different formats: For example, running guess-upstream-metadata on dulwich:
 % guess-upstream-metadata
 <string>:2: (INFO/1) Duplicate implicit target name: "contributing".
 Name: dulwich
 Repository: https://www.dulwich.io/code/
 X-Security-MD: https://github.com/dulwich/dulwich/tree/HEAD/SECURITY.md
 X-Version: 0.20.21
 Bug-Database: https://github.com/dulwich/dulwich/issues
 X-Summary: Python Git Library
 X-Description:  
   This is the Dulwich project.
   It aims to provide an interface to git repos (both local and remote) that
   doesn't call out to git directly but instead uses pure Python.
 X-License: Apache License, version 2 or GNU General Public License, version 2 or later.
 Bug-Submit: https://github.com/dulwich/dulwich/issues/new
Lintian-Brush lintian-brush can update DEP-12-style debian/upstream/metadata files that hold information about the upstream project that is packaged as well as the Homepage in the debian/control file based on information provided by the upstream ontologist. By default, it only imports data with the highest certainty - you can override this by specifying the uncertain command-line flag.
[1]Obviously this won t be able to describe the full licensing situation for many projects. Projects like scancode-toolkit are more appropriate for that.

Vishal Gupta: Sikkim 101 for Backpackers

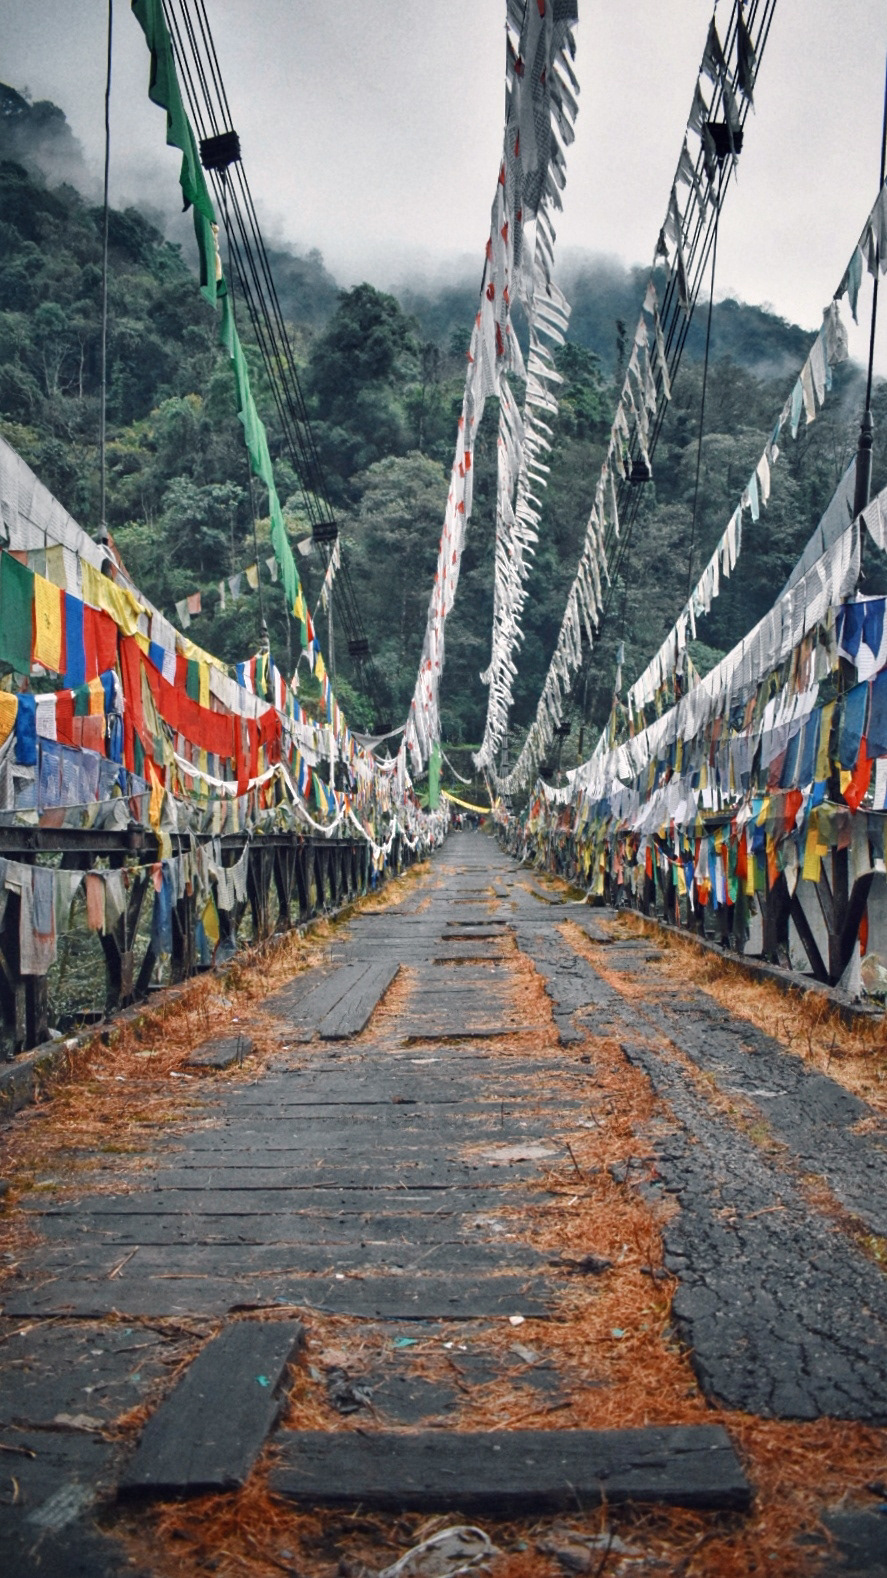
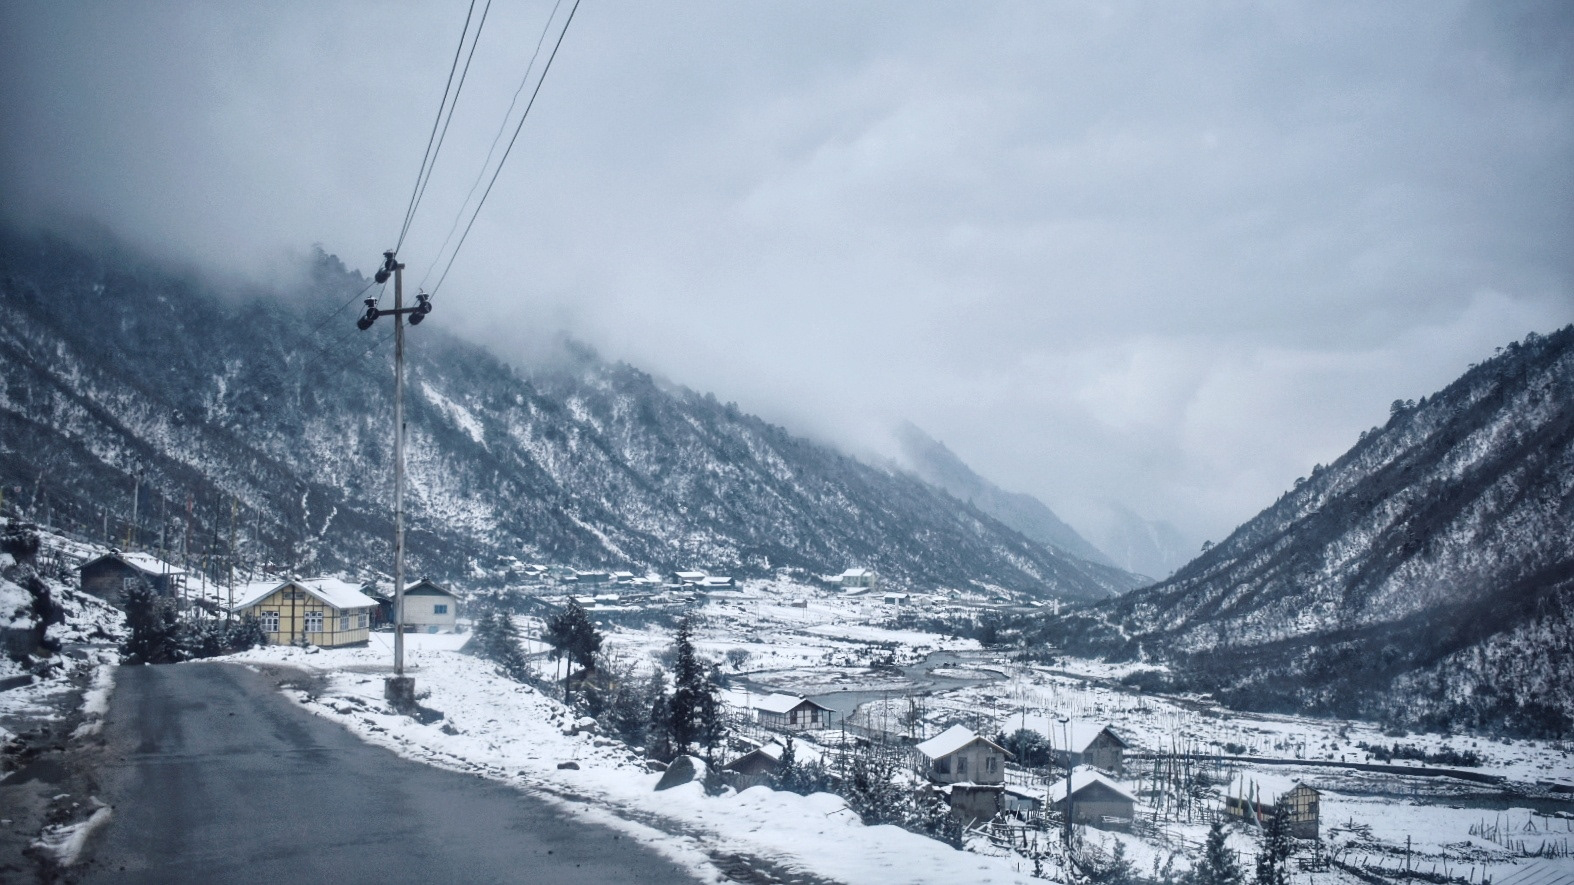
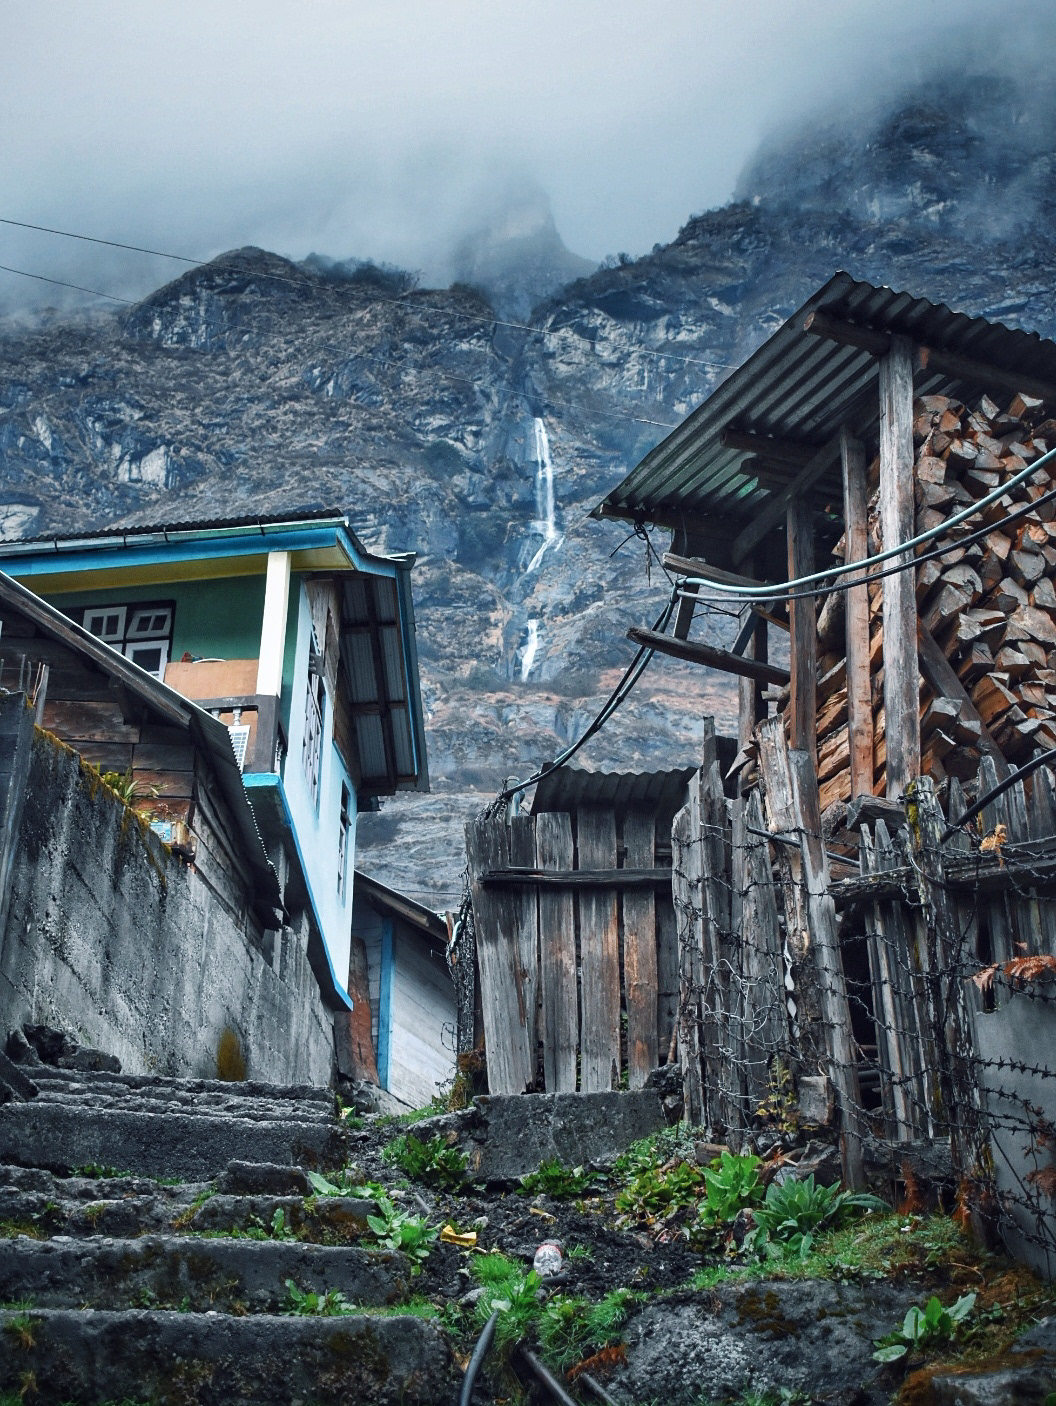
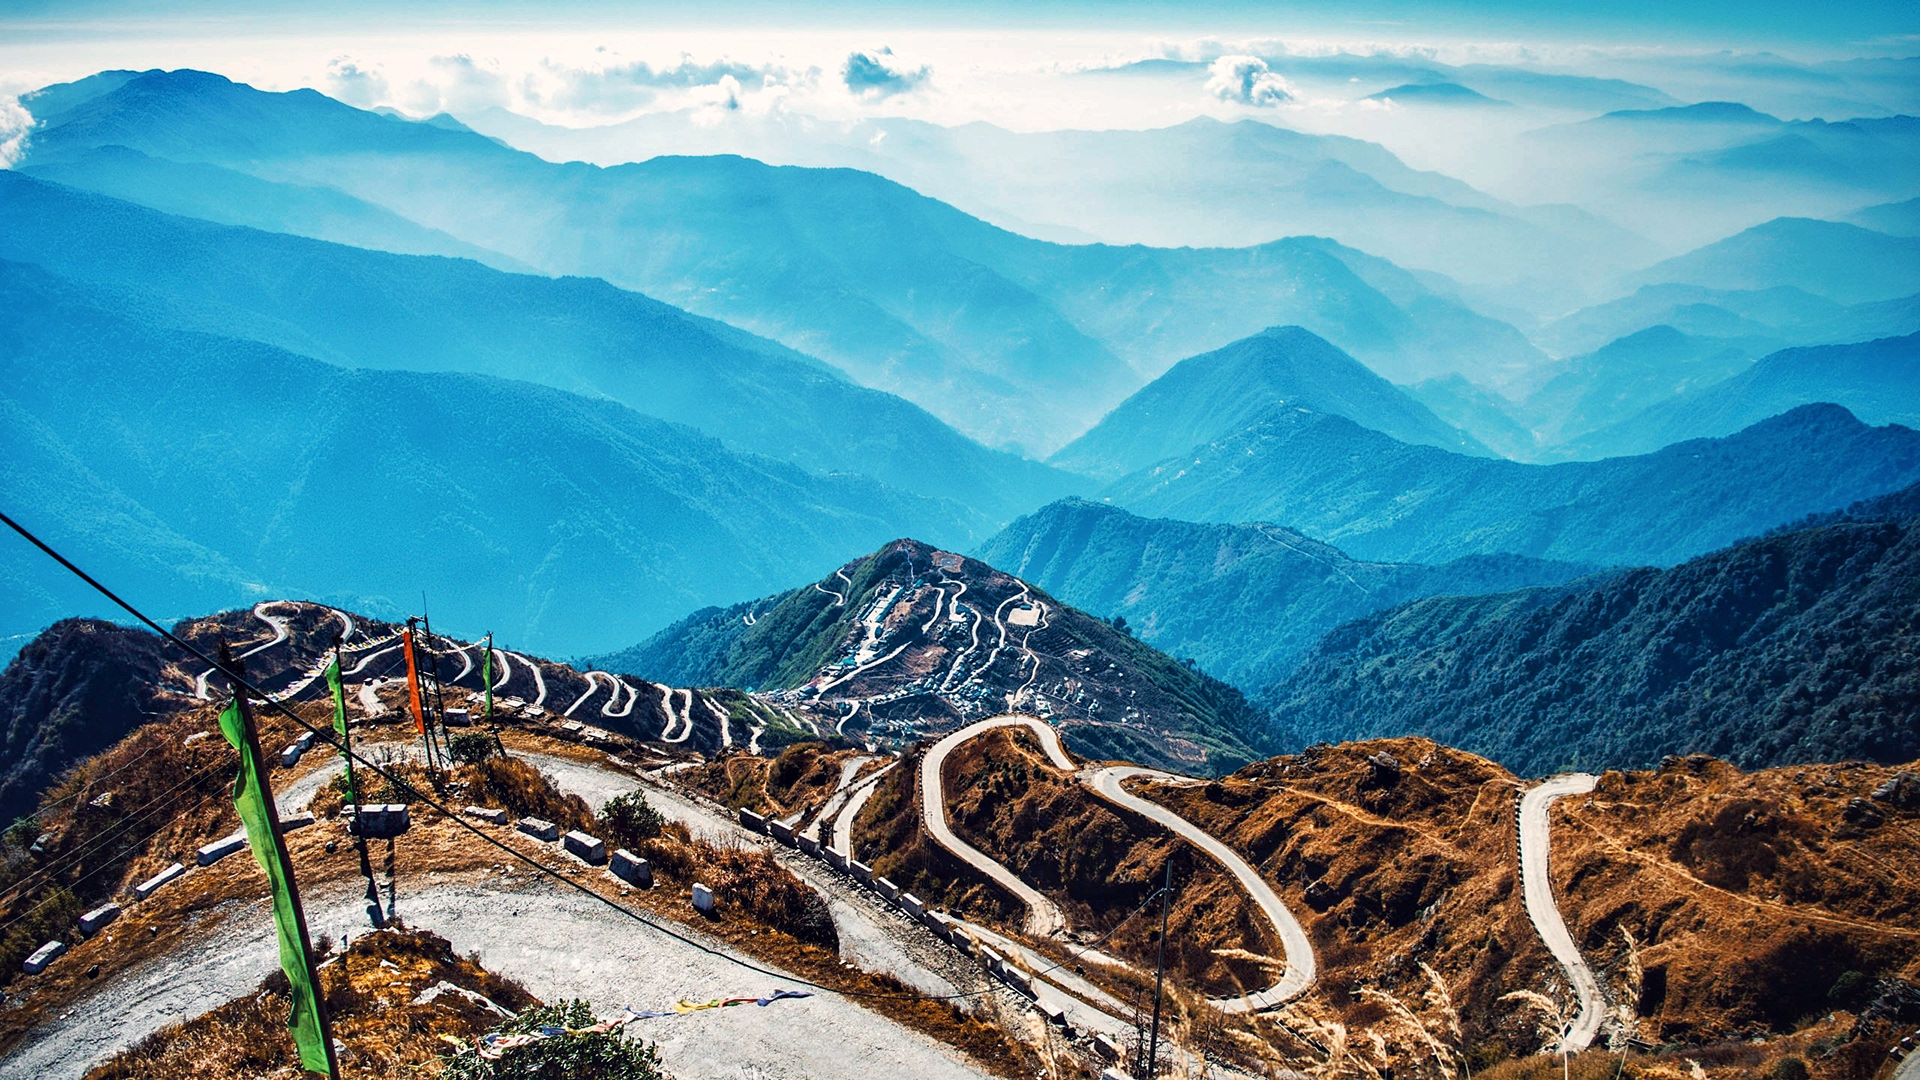
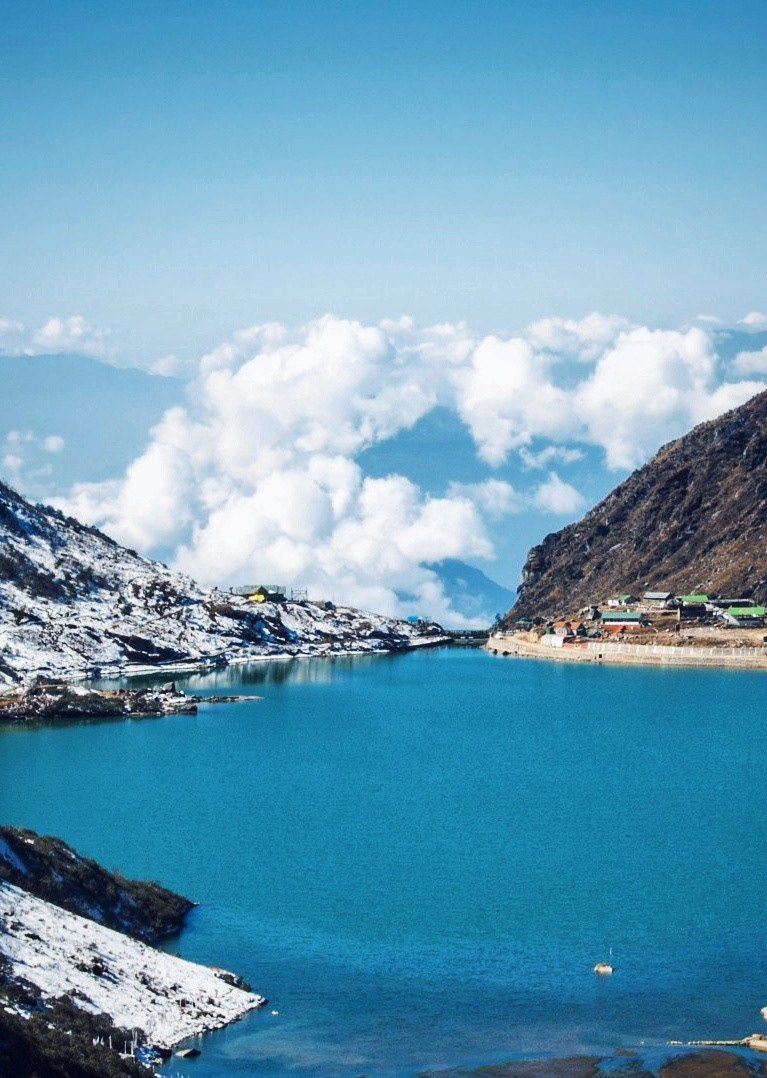
Host to Kanchenjunga, the world s third-highest mountain peak and the endangered Red Panda, Sikkim is a state in northeastern India. Nestled between Nepal, Tibet (China), Bhutan and West Bengal (India), the state offers a smorgasbord of cultures and cuisines. That said, it s hardly surprising that the old spice route meanders through western Sikkim, connecting Lhasa with the ports of Bengal. Although the latter could also be attributed to cardamom (kali elaichi), a perennial herb native to Sikkim, which the state is the second-largest producer of, globally. Lastly, having been to and lived in India, all my life, I can confidently say Sikkim is one of the cleanest & safest regions in India, making it ideal for first-time backpackers.

Brief History
  • 17th century: The Kingdom of Sikkim is founded by the Namgyal dynasty and ruled by Buddhist priest-kings known as the Chogyal.
  • 1890: Sikkim becomes a princely state of British India.
  • 1947: Sikkim continues its protectorate status with the Union of India, post-Indian-independence.
  • 1973: Anti-royalist riots take place in front of the Chogyal's palace, by Nepalis seeking greater representation.
  • 1975: Referendum leads to the deposition of the monarchy and Sikkim joins India as its 22nd state.
Languages
  • Official: English, Nepali, Sikkimese/Bhotia and Lepcha
  • Though Hindi and Nepali share the same script (Devanagari), they are not mutually intelligible. Yet, most people in Sikkim can understand and speak Hindi.
Ethnicity
  • Nepalis: Migrated in large numbers (from Nepal) and soon became the dominant community
  • Bhutias: People of Tibetan origin. Major inhabitants in Northern Sikkim.
  • Lepchas: Original inhabitants of Sikkim

Food
  • Tibetan/Nepali dishes (mostly consumed during winter)
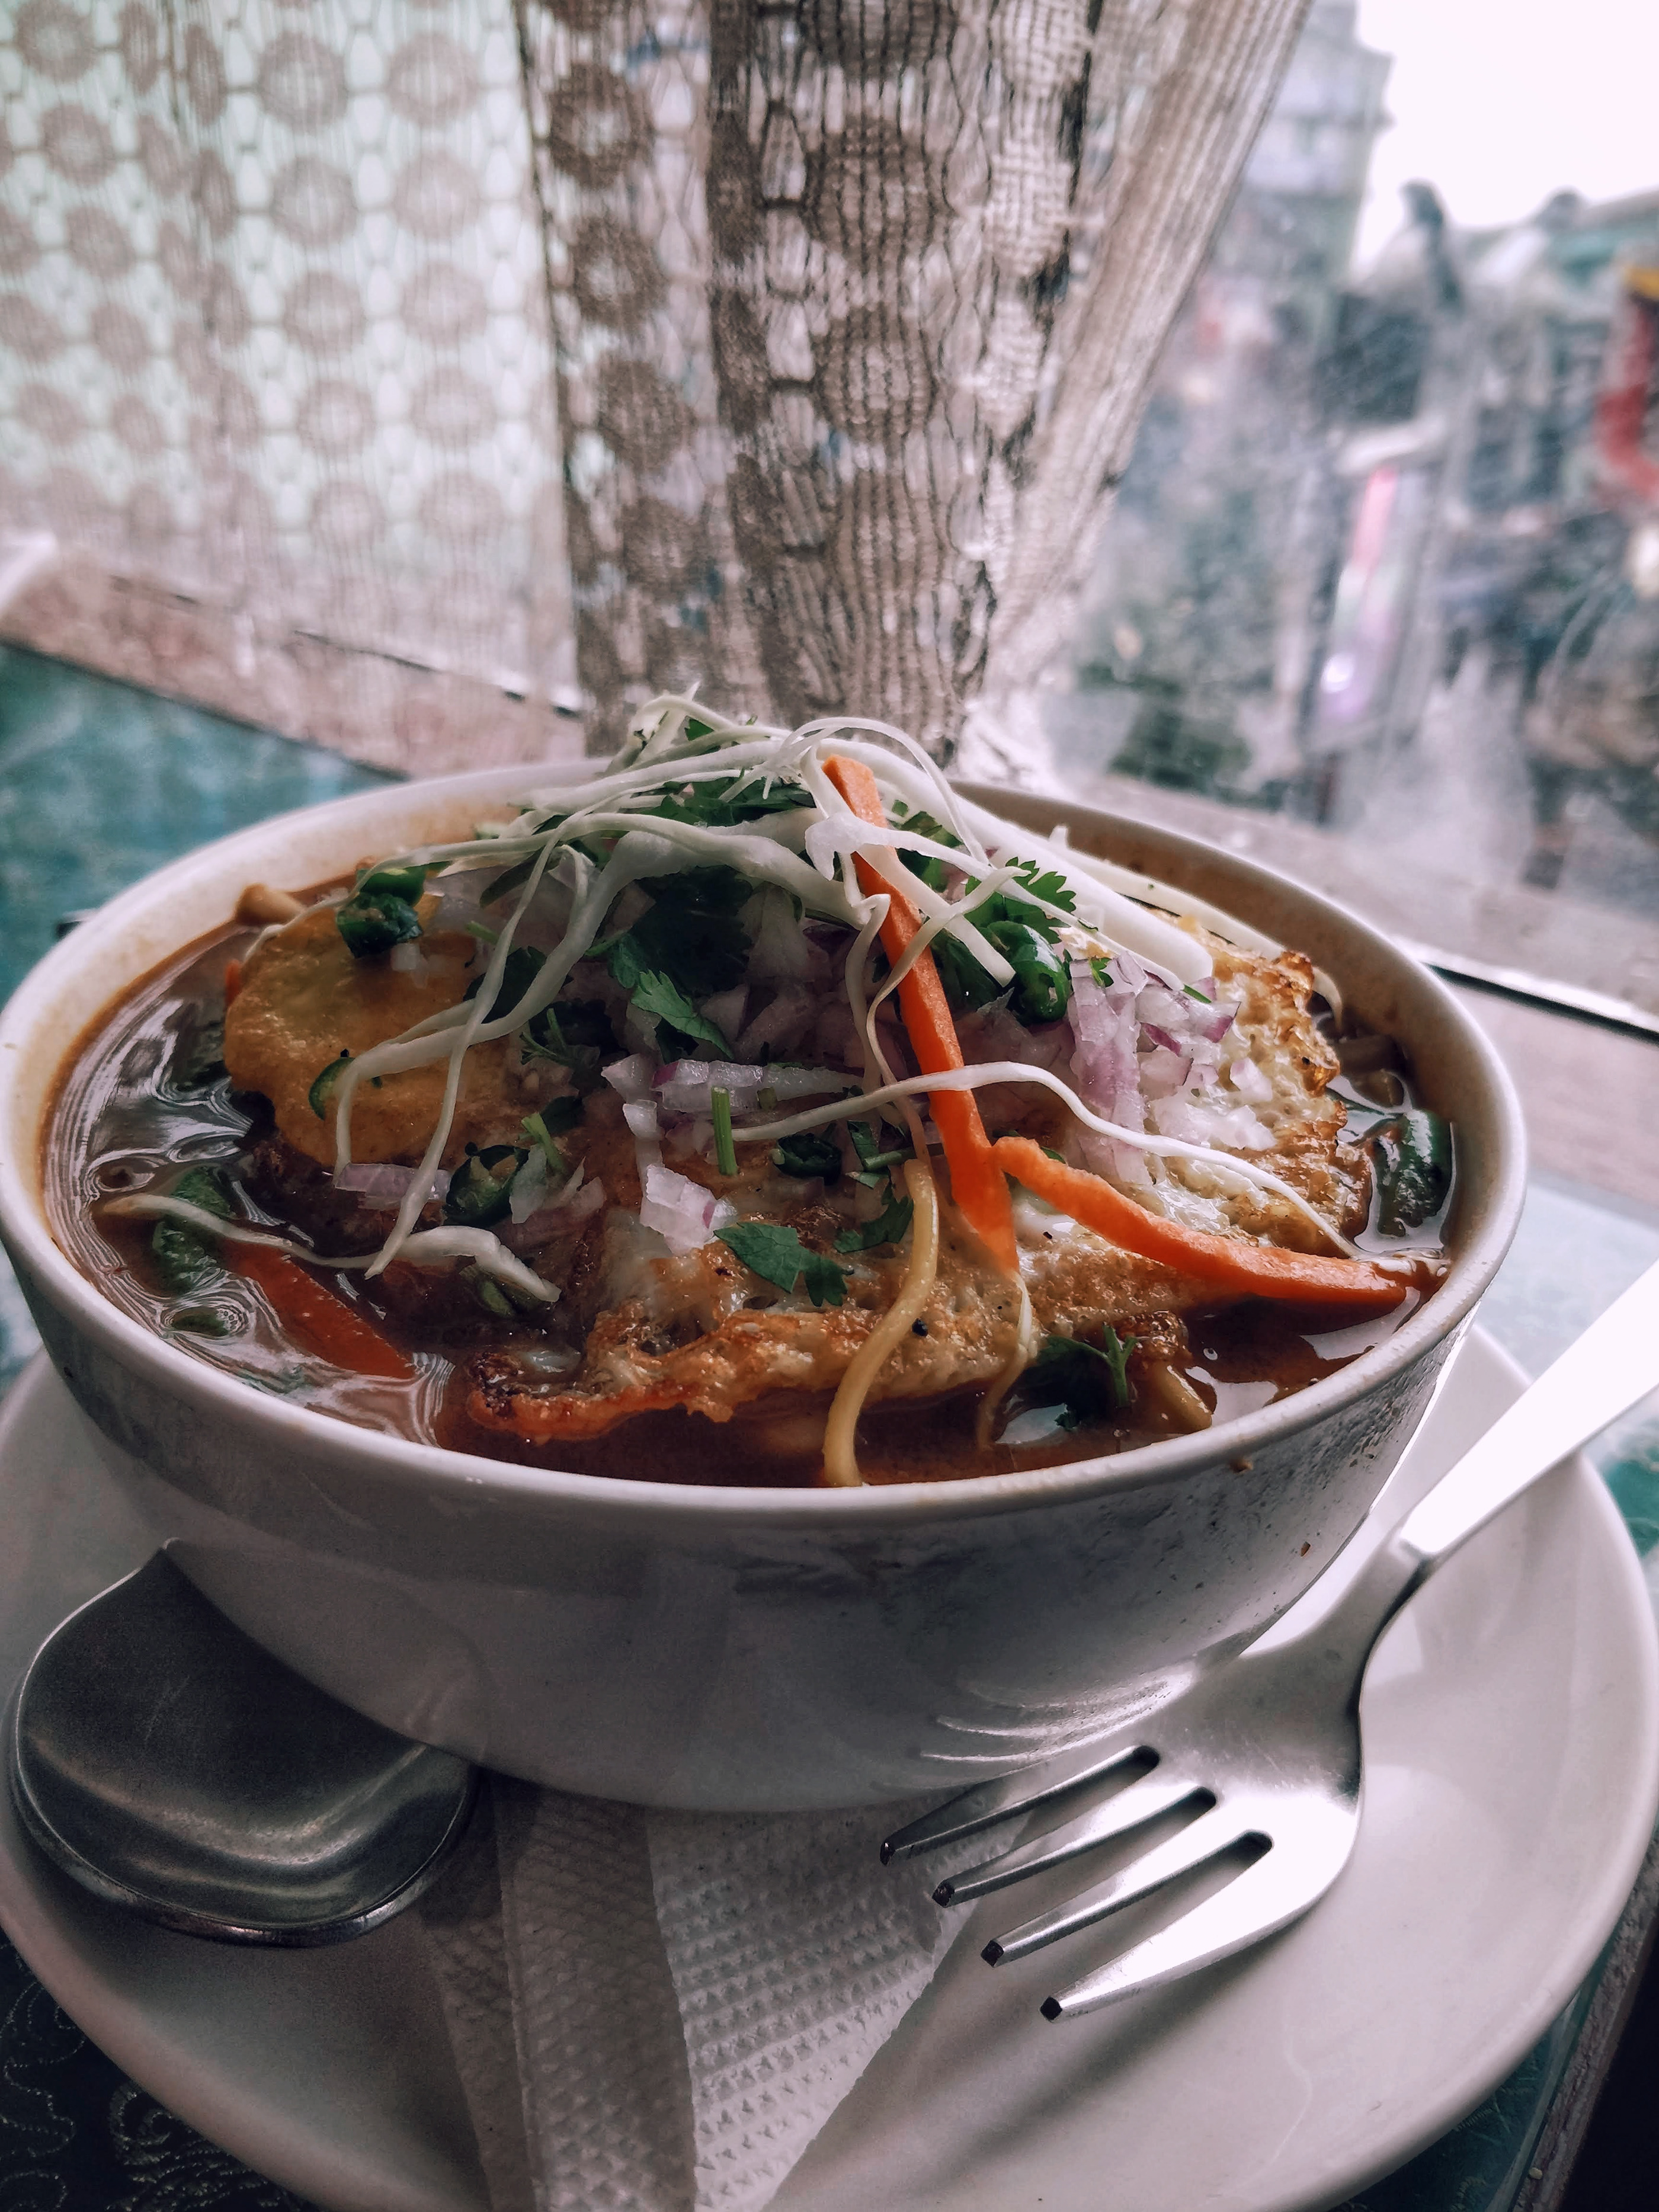
    • Thukpa: Noodle soup, rich in spices and vegetables. Usually contains some form of meat. Common variations: Thenthuk and Gyathuk
    • Momos: Steamed or fried dumplings, usually with a meat filling.
    • Saadheko: Spicy marinated chicken salad.
    • Gundruk Soup: A soup made from Gundruk, a fermented leafy green vegetable.
    • Sinki : A fermented radish tap-root product, traditionally consumed as a base for soup and as a pickle. Eerily similar to Kimchi.
  • While pork and beef are pretty common, finding vegetarian dishes is equally easy.
  • Staple: Dal-Bhat with Subzi. Rice is a lot more common than wheat (rice) possibly due to greater carb content and proximity to West Bengal, India s largest producer of Rice.
  • Good places to eat in Gangtok
    • Hamro Bhansa Ghar, Nimtho (Nepali)
    • Taste of Tibet
    • Dragon Wok (Chinese & Japanese)

Buddhism in Sikkim
  • Bayul Demojong (Sikkim), is the most sacred Land in the Himalayas as per the belief of the Northern Buddhists and various religious texts.
  • Sikkim was blessed by Guru Padmasambhava, the great Buddhist saint who visited Sikkim in the 8th century and consecrated the land.
  • However, Buddhism is said to have reached Sikkim only in the 17th century with the arrival of three Tibetan monks viz. Rigdzin Goedki Demthruchen, Mon Kathok Sonam Gyaltshen & Rigdzin Legden Je at Yuksom. Together, they established a Buddhist monastery.
  • In 1642 they crowned Phuntsog Namgyal as the first monarch of Sikkim and gave him the title of Chogyal, or Dharma Raja.
  • The faith became popular through its royal patronage and soon many villages had their own monastery.
  • Today Sikkim has over 200 monasteries.

Major monasteries
  • Rumtek Monastery, 20Km from Gangtok
  • Lingdum/Ranka Monastery, 17Km from Gangtok
  • Phodong Monastery, 28Km from Gangtok
  • Ralang Monastery, 10Km from Ravangla
  • Tsuklakhang Monastery, Royal Palace, Gangtok
  • Enchey Monastery, Gangtok
  • Tashiding Monastery, 35Km from Ravangla


Reaching Sikkim
  • Gangtok, being the capital, is easiest to reach amongst other regions, by public transport and shared cabs.
  • By Air:
    • Pakyong (PYG) :
      • Nearest airport from Gangtok (about 1 hour away)
      • Tabletop airport
      • Reserved cabs cost around INR 1200.
      • As of Apr 2021, the only flights to PYG are from IGI (Delhi) and CCU (Kolkata).
    • Bagdogra (IXB) :
      • About 20 minutes from Siliguri and 4 hours from Gangtok.
      • Larger airport with flights to most major Indian cities.
      • Reserved cabs cost about INR 3000. Shared cabs cost about INR 350.
  • By Train:
    • New Jalpaiguri (NJP) :
      • About 20 minutes from Siliguri and 4 hours from Gangtok.
      • Reserved cabs cost about INR 3000. Shared cabs from INR 350.
  • By Road:
    • NH10 connects Siliguri to Gangtok
    • If you can t find buses plying to Gangtok directly, reach Siliguri and then take a cab to Gangtok.
  • Sikkim Nationalised Transport Div. also runs hourly buses between Siliguri and Gangtok and daily buses on other common routes. They re cheaper than shared cabs.
  • Wizzride also operates shared cabs between Siliguri/Bagdogra/NJP, Gangtok and Darjeeling. They cost about the same as shared cabs but pack in half as many people in luxury cars (Innova, Xylo, etc.) and are hence more comfortable.

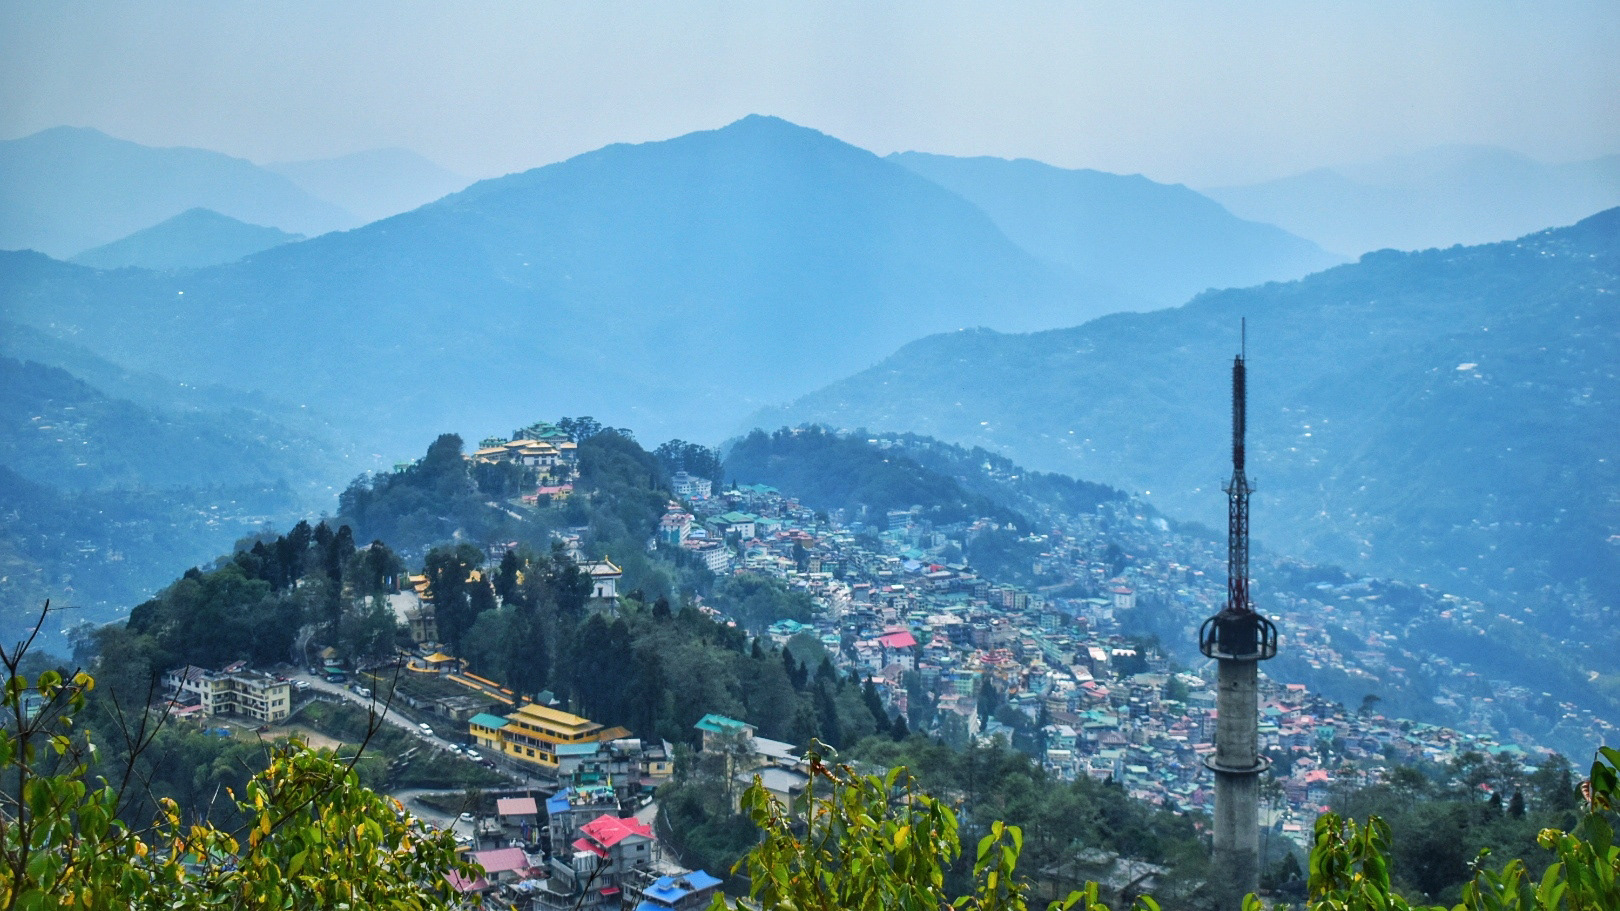
Gangtok
  • Time needed: 1D/1N
  • Places to visit:
    • Hanuman Tok
    • Ganesh Tok
    • Tashi View Point [6,800ft]
    • MG Marg
    • Sikkim Zoo
    • Gangtok Ropeway
    • Enchey Monastery
    • Tsuklakhang Palace & Monastery
  • Hostels: Tagalong Backpackers (would strongly recommend), Zostel Gangtok
  • Places to chill: Travel Cafe, Caf Live & Loud and Gangtok Groove
  • Places to shop: Lal Market and MG Marg

Getting Around
  • Taxis operate on a reserved or shared basis. In case of the latter, you can pool with other commuters your taxis will pick up and drop en-route.
  • Naturally shared taxis only operate on popular routes. The easiest way to get around Gangtok is to catch a shared cab from MG Marg.
  • Reserved taxis for Gangtok sightseeing cost around INR 1000-1500, depending upon the spots you d like to see
  • Key taxi/bus stands :
    • Deorali stand: For Darjeeling, Siliguri, Kalimpong
    • Vajra stand: For North & East Sikkim (Tsomgo Lake & Nathula)
    • Rumtek taxi: For Ravangla, Pelling, Namchi, Geyzing, Jorethang and Singtam.
Exploring Gangtok on an MTB

North Sikkim
  • The easiest & most economical way to explore North Sikkim is the 3D/2N package offered by shared-cab drivers.
  • This includes food, permits, cab rides and accommodation (1N in Lachen and 1N in Lachung)
  • The accommodation on both nights are at homestays with bare necessities, so keep your hopes low.
  • In the spirit of sustainable tourism, you ll be asked to discard single-use plastic bottles, so please carry a bottle that you can refill along the way.
  • Zero Point and Gurdongmer Lake are snow-capped throughout the year
3D/2N Shared-cab Package Itinerary
  • Day 1
    • Gangtok (10am) - Chungthang - Lachung (stay)
  • Day 2
    • Pre-lunch : Lachung (6am) - Yumthang Valley [12,139ft] - Zero Point - Lachung [15,300ft]
    • Post-lunch : Lachung - Chungthang - Lachen (stay)
  • Day 3
    • Pre-lunch : Lachen (5am) - Kala Patthar - Gurdongmer Lake [16,910ft] - Lachen
    • Post-lunch : Lachen - Chungthang - Gangtok (7pm)
  • This itinerary is idealistic and depends on the level of snowfall.
  • Some drivers might switch up Day 2 and 3 itineraries by visiting Lachen and then Lachung, depending upon the weather.
  • Areas beyond Lachen & Lachung are heavily militarized since the Indo-China border is only a few miles away.

East Sikkim

Zuluk and Silk Route
  • Time needed: 2D/1N
  • Zuluk [9,400ft] is a small hamlet with an excellent view of the eastern Himalayan range including the Kanchenjunga.
  • Was once a transit point to the historic Silk Route from Tibet (Lhasa) to India (West Bengal).
  • The drive from Gangtok to Zuluk takes at least four hours. Hence, it makes sense to spend the night at a homestay and space out your trip to Zuluk

Tsomgo Lake and Nathula
  • Time Needed : 1D
  • A Protected Area Permit is required to visit these places, due to their proximity to the Chinese border
  • Tsomgo/Chhangu Lake [12,313ft]
    • Glacial lake, 40 km from Gangtok.
    • Remains frozen during the winter season.
    • You can also ride on the back of a Yak for INR 300
  • Baba Mandir
    • An old temple dedicated to Baba Harbhajan Singh, a Sepoy in the 23rd Regiment, who died in 1962 near the Nathu La during Indo China war.
  • Nathula Pass [14,450ft]
    • Located on the Indo-Tibetan border crossing of the Old Silk Route, it is one of the three open trading posts between India and China.
    • Plays a key role in the Sino-Indian Trade and also serves as an official Border Personnel Meeting(BPM) Point.
    • May get cordoned off by the Indian Army in event of heavy snowfall or for other security reasons.


West Sikkim
  • Time needed: 3N/1N
  • Hostels at Pelling : Mochilerro Ostillo

Itinerary

Day 1: Gangtok - Ravangla - Pelling
  • Leave Gangtok early, for Ravangla through the Temi Tea Estate route.
  • Spend some time at the tea garden and then visit Buddha Park at Ravangla
  • Head to Pelling from Ravangla

Day 2: Pelling sightseeing
  • Hire a cab and visit Skywalk, Pemayangtse Monastery, Rabdentse Ruins, Kecheopalri Lake, Kanchenjunga Falls.

Day 3: Pelling - Gangtok/Siliguri
  • Wake up early to catch a glimpse of Kanchenjunga at the Pelling Helipad around sunrise
  • Head back to Gangtok on a shared-cab
  • You could take a bus/taxi back to Siliguri if Pelling is your last stop.

Darjeeling
  • In my opinion, Darjeeling is lovely for a two-day detour on your way back to Bagdogra/Siliguri and not any longer (unless you re a Bengali couple on a honeymoon)
  • Once a part of Sikkim, Darjeeling was ceded to the East India Company after a series of wars, with Sikkim briefly receiving a grant from EIC for gifting Darjeeling to the latter
  • Post-independence, Darjeeling was merged with the state of West Bengal.

Itinerary

Day 1 :
  • Take a cab from Gangtok to Darjeeling (shared-cabs cost INR 300 per seat)
  • Reach Darjeeling by noon and check in to your Hostel. I stayed at Hideout.
  • Spend the evening visiting either a monastery (or the Batasia Loop), Nehru Road and Mall Road.
  • Grab dinner at Glenary whilst listening to live music.

Day 2:
  • Wake up early to catch the sunrise and a glimpse of Kanchenjunga at Tiger Hill. Since Tiger Hill is 10km from Darjeeling and requires a permit, book your taxi in advance.
  • Alternatively, if you don t want to get up at 4am or shell out INR1500 on the cab to Tiger Hill, walk to the Kanchenjunga View Point down Mall Road
  • Next, queue up outside Keventers for breakfast with a view in a century-old cafe
  • Get a cab at Gandhi Road and visit a tea garden (Happy Valley is the closest) and the Ropeway. I was lucky to meet 6 other backpackers at my hostel and we ended up pooling the cab at INR 200 per person, with INR 1400 being on the expensive side, but you could bargain.
  • Get lunch, buy some tea at Golden Tips, pack your bags and hop on a shared-cab back to Siliguri. It took us about 4hrs to reach Siliguri, with an hour to spare before my train.
  • If you ve still got time on your hands, then check out the Peace Pagoda and the Darjeeling Himalayan Railway (Toy Train). At INR 1500, I found the latter to be too expensive and skipped it.


Tips and hacks
  • Download offline maps, especially when you re exploring Northern Sikkim.
  • Food and booze are the cheapest in Gangtok. Stash up before heading to other regions.
  • Keep your Aadhar/Passport handy since you need permits to travel to North & East Sikkim.
  • In rural areas and some cafes, you may get to try Rhododendron Wine, made from Rhododendron arboreum a.k.a Gurans. Its production is a little hush-hush since the flower is considered holy and is also the National Flower of Nepal.
  • If you don t want to invest in a new jacket, boots or a pair of gloves, you can always rent them at nominal rates from your hotel or little stores around tourist sites.
  • Check the weather of a region before heading there. Low visibility and precipitation can quite literally dampen your experience.
  • Keep your itinerary flexible to accommodate for rest and impromptu plans.
  • Shops and restaurants close by 8pm in Sikkim and Darjeeling. Plan for the same.

Carry
  • a couple of extra pairs of socks (woollen, if possible)
  • a pair of slippers to wear indoors
  • a reusable water bottle
  • an umbrella
  • a power bank
  • a couple of tablets of Diamox. Helps deal with altitude sickness
  • extra clothes and wet bags since you may not get a chance to wash/dry your clothes
  • a few passport size photographs

Shared-cab hacks
  • Intercity rides can be exhausting. If you can afford it, pay for an additional seat.
  • Call shotgun on the drives beyond Lachen and Lachung. The views are breathtaking.
  • Return cabs tend to be cheaper (WB cabs travelling from SK and vice-versa)

Cost
  • My median daily expenditure (back when I went to Sikkim in early March 2021) was INR 1350.
  • This includes stay (bunk bed), food, wine and transit (shared cabs)
  • In my defence, I splurged on food, wine and extra seats in shared cabs, but if you re on a budget, you could easily get by on INR 1 - 1.2k per day.
  • For a 9-day trip, I ended up shelling out nearly INR 15k, including 2AC trains to & from Kolkata
  • Note : Summer (March to May) and Autumn (October to December) are peak seasons, and thereby more expensive to travel around.

Souvenirs and things you should buy

Buddhist souvenirs :
  • Colourful Prayer Flags (great for tying on bikes or behind car windshields)
  • Miniature Prayer/Mani Wheels
  • Lucky Charms, Pendants and Key Chains
  • Cham Dance masks and robes
  • Singing Bowls
  • Common symbols: Om mani padme hum, Ashtamangala, Zodiac signs

Handicrafts & Handlooms
  • Tibetan Yak Wool shawls, scarfs and carpets
  • Sikkimese Ceramic cups
  • Thangka Paintings

Edibles
  • Darjeeling Tea (usually brewed and not boiled)
  • Wine (Arucha Peach & Rhododendron)
  • Dalle Khursani (Chilli) Paste and Pickle

Header Icon made by Freepik from www.flaticon.com is licensed by CC 3.0 BY

9 April 2021

Michael Prokop: A Ceph war story

It all started with the big bang! We nearly lost 33 of 36 disks on a Proxmox/Ceph Cluster; this is the story of how we recovered them. At the end of 2020, we eventually had a long outstanding maintenance window for taking care of system upgrades at a customer. During this maintenance window, which involved reboots of server systems, the involved Ceph cluster unexpectedly went into a critical state. What was planned to be a few hours of checklist work in the early evening turned out to be an emergency case; let s call it a nightmare (not only because it included a big part of the night). Since we have learned a few things from our post mortem and RCA, it s worth sharing those with others. But first things first, let s step back and clarify what we had to deal with. The system and its upgrade One part of the upgrade included 3 Debian servers (we re calling them server1, server2 and server3 here), running on Proxmox v5 + Debian/stretch with 12 Ceph OSDs each (65.45TB in total), a so-called Proxmox Hyper-Converged Ceph Cluster. First, we went for upgrading the Proxmox v5/stretch system to Proxmox v6/buster, before updating Ceph Luminous v12.2.13 to the latest v14.2 release, supported by Proxmox v6/buster. The Proxmox upgrade included updating corosync from v2 to v3. As part of this upgrade, we had to apply some configuration changes, like adjust ring0 + ring1 address settings and add a mon_host configuration to the Ceph configuration. During the first two servers reboots, we noticed configuration glitches. After fixing those, we went for a reboot of the third server as well. Then we noticed that several Ceph OSDs were unexpectedly down. The NTP service wasn t working as expected after the upgrade. The underlying issue is a race condition of ntp with systemd-timesyncd (see #889290). As a result, we had clock skew problems with Ceph, indicating that the Ceph monitors clocks aren t running in sync (which is essential for proper Ceph operation). We initially assumed that our Ceph OSD failure derived from this clock skew problem, so we took care of it. After yet another round of reboots, to ensure the systems are running all with identical and sane configurations and services, we noticed lots of failing OSDs. This time all but three OSDs (19, 21 and 22) were down:
% sudo ceph osd tree
ID CLASS WEIGHT   TYPE NAME      STATUS REWEIGHT PRI-AFF
-1       65.44138 root default
-2       21.81310     host server1
 0   hdd  1.08989         osd.0    down  1.00000 1.00000
 1   hdd  1.08989         osd.1    down  1.00000 1.00000
 2   hdd  1.63539         osd.2    down  1.00000 1.00000
 3   hdd  1.63539         osd.3    down  1.00000 1.00000
 4   hdd  1.63539         osd.4    down  1.00000 1.00000
 5   hdd  1.63539         osd.5    down  1.00000 1.00000
18   hdd  2.18279         osd.18   down  1.00000 1.00000
20   hdd  2.18179         osd.20   down  1.00000 1.00000
28   hdd  2.18179         osd.28   down  1.00000 1.00000
29   hdd  2.18179         osd.29   down  1.00000 1.00000
30   hdd  2.18179         osd.30   down  1.00000 1.00000
31   hdd  2.18179         osd.31   down  1.00000 1.00000
-4       21.81409     host server2
 6   hdd  1.08989         osd.6    down  1.00000 1.00000
 7   hdd  1.08989         osd.7    down  1.00000 1.00000
 8   hdd  1.63539         osd.8    down  1.00000 1.00000
 9   hdd  1.63539         osd.9    down  1.00000 1.00000
10   hdd  1.63539         osd.10   down  1.00000 1.00000
11   hdd  1.63539         osd.11   down  1.00000 1.00000
19   hdd  2.18179         osd.19     up  1.00000 1.00000
21   hdd  2.18279         osd.21     up  1.00000 1.00000
22   hdd  2.18279         osd.22     up  1.00000 1.00000
32   hdd  2.18179         osd.32   down  1.00000 1.00000
33   hdd  2.18179         osd.33   down  1.00000 1.00000
34   hdd  2.18179         osd.34   down  1.00000 1.00000
-3       21.81419     host server3
12   hdd  1.08989         osd.12   down  1.00000 1.00000
13   hdd  1.08989         osd.13   down  1.00000 1.00000
14   hdd  1.63539         osd.14   down  1.00000 1.00000
15   hdd  1.63539         osd.15   down  1.00000 1.00000
16   hdd  1.63539         osd.16   down  1.00000 1.00000
17   hdd  1.63539         osd.17   down  1.00000 1.00000
23   hdd  2.18190         osd.23   down  1.00000 1.00000
24   hdd  2.18279         osd.24   down  1.00000 1.00000
25   hdd  2.18279         osd.25   down  1.00000 1.00000
35   hdd  2.18179         osd.35   down  1.00000 1.00000
36   hdd  2.18179         osd.36   down  1.00000 1.00000
37   hdd  2.18179         osd.37   down  1.00000 1.00000
Our blood pressure increased slightly! Did we just lose all of our cluster? What happened, and how can we get all the other OSDs back? We stumbled upon this beauty in our logs:
kernel: [   73.697957] XFS (sdl1): SB stripe unit sanity check failed
kernel: [   73.698002] XFS (sdl1): Metadata corruption detected at xfs_sb_read_verify+0x10e/0x180 [xfs], xfs_sb block 0xffffffffffffffff
kernel: [   73.698799] XFS (sdl1): Unmount and run xfs_repair
kernel: [   73.699199] XFS (sdl1): First 128 bytes of corrupted metadata buffer:
kernel: [   73.699677] 00000000: 58 46 53 42 00 00 10 00 00 00 00 00 00 00 62 00  XFSB..........b.
kernel: [   73.700205] 00000010: 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00  ................
kernel: [   73.700836] 00000020: 62 44 2b c0 e6 22 40 d7 84 3d e1 cc 65 88 e9 d8  bD+.."@..=..e...
kernel: [   73.701347] 00000030: 00 00 00 00 00 00 40 08 00 00 00 00 00 00 01 00  ......@.........
kernel: [   73.701770] 00000040: 00 00 00 00 00 00 01 01 00 00 00 00 00 00 01 02  ................
ceph-disk[4240]: mount: /var/lib/ceph/tmp/mnt.jw367Y: mount(2) system call failed: Structure needs cleaning.
ceph-disk[4240]: ceph-disk: Mounting filesystem failed: Command '['/bin/mount', '-t', u'xfs', '-o', 'noatime,inode64', '--', '/dev/disk/by-parttypeuuid/4fbd7e29-9d25-41b8-afd0-062c0ceff05d.cdda39ed-5
ceph/tmp/mnt.jw367Y']' returned non-zero exit status 32
kernel: [   73.702162] 00000050: 00 00 00 01 00 00 18 80 00 00 00 04 00 00 00 00  ................
kernel: [   73.702550] 00000060: 00 00 06 48 bd a5 10 00 08 00 00 02 00 00 00 00  ...H............
kernel: [   73.702975] 00000070: 00 00 00 00 00 00 00 00 0c 0c 0b 01 0d 00 00 19  ................
kernel: [   73.703373] XFS (sdl1): SB validate failed with error -117.
The same issue was present for the other failing OSDs. We hoped, that the data itself was still there, and only the mounting of the XFS partitions failed. The Ceph cluster was initially installed in 2017 with Ceph jewel/10.2 with the OSDs on filestore (nowadays being a legacy approach to storing objects in Ceph). However, we migrated the disks to bluestore since then (with ceph-disk and not yet via ceph-volume what s being used nowadays). Using ceph-disk introduces these 100MB XFS partitions containing basic metadata for the OSD. Given that we had three working OSDs left, we decided to investigate how to rebuild the failing ones. Some folks on #ceph (thanks T1, ormandj + peetaur!) were kind enough to share how working XFS partitions looked like for them. After creating a backup (via dd), we tried to re-create such an XFS partition on server1. We noticed that even mounting a freshly created XFS partition failed:
synpromika@server1 ~ % sudo mkfs.xfs -f -i size=2048 -m uuid="4568c300-ad83-4288-963e-badcd99bf54f" /dev/sdc1
meta-data=/dev/sdc1              isize=2048   agcount=4, agsize=6272 blks
         =                       sectsz=4096  attr=2, projid32bit=1
         =                       crc=1        finobt=1, sparse=1, rmapbt=0
         =                       reflink=0
data     =                       bsize=4096   blocks=25088, imaxpct=25
         =                       sunit=128    swidth=64 blks
naming   =version 2              bsize=4096   ascii-ci=0, ftype=1
log      =internal log           bsize=4096   blocks=1608, version=2
         =                       sectsz=4096  sunit=1 blks, lazy-count=1
realtime =none                   extsz=4096   blocks=0, rtextents=0
synpromika@server1 ~ % sudo mount /dev/sdc1 /mnt/ceph-recovery
SB stripe unit sanity check failed
Metadata corruption detected at 0x433840, xfs_sb block 0x0/0x1000
libxfs_writebufr: write verifer failed on xfs_sb bno 0x0/0x1000
cache_node_purge: refcount was 1, not zero (node=0x1d3c400)
SB stripe unit sanity check failed
Metadata corruption detected at 0x433840, xfs_sb block 0x18800/0x1000
libxfs_writebufr: write verifer failed on xfs_sb bno 0x18800/0x1000
SB stripe unit sanity check failed
Metadata corruption detected at 0x433840, xfs_sb block 0x0/0x1000
libxfs_writebufr: write verifer failed on xfs_sb bno 0x0/0x1000
SB stripe unit sanity check failed
Metadata corruption detected at 0x433840, xfs_sb block 0x24c00/0x1000
libxfs_writebufr: write verifer failed on xfs_sb bno 0x24c00/0x1000
SB stripe unit sanity check failed
Metadata corruption detected at 0x433840, xfs_sb block 0xc400/0x1000
libxfs_writebufr: write verifer failed on xfs_sb bno 0xc400/0x1000
releasing dirty buffer (bulk) to free list!releasing dirty buffer (bulk) to free list!releasing dirty buffer (bulk) to free list!releasing dirty buffer (bulk) to free list!found dirty buffer (bulk) on free list!bad magic number
bad magic number
Metadata corruption detected at 0x433840, xfs_sb block 0x0/0x1000
libxfs_writebufr: write verifer failed on xfs_sb bno 0x0/0x1000
releasing dirty buffer (bulk) to free list!mount: /mnt/ceph-recovery: wrong fs type, bad option, bad superblock on /dev/sdc1, missing codepage or helper program, or other error.
Ouch. This very much looked related to the actual issue we re seeing. So we tried to execute mkfs.xfs with a bunch of different sunit/swidth settings. Using -d sunit=512 -d swidth=512 at least worked then, so we decided to force its usage in the creation of our OSD XFS partition. This brought us a working XFS partition. Please note, sunit must not be larger than swidth (more on that later!). Then we reconstructed how to restore all the metadata for the OSD (activate.monmap, active, block_uuid, bluefs, ceph_fsid, fsid, keyring, kv_backend, magic, mkfs_done, ready, require_osd_release, systemd, type, whoami). To identify the UUID, we can read the data from ceph --format json osd dump , like this for all our OSDs (Zsh syntax ftw!):
synpromika@server1 ~ % for f in  0..37  ; printf "osd-$f: %s\n" "$(sudo ceph --format json osd dump   jq -r ".osds[]   select(.osd==$f)   .uuid")"
osd-0: 4568c300-ad83-4288-963e-badcd99bf54f
osd-1: e573a17a-ccde-4719-bdf8-eef66903ca4f
osd-2: 0e1b2626-f248-4e7d-9950-f1a46644754e
osd-3: 1ac6a0a2-20ee-4ed8-9f76-d24e900c800c
[...]
Identifying the corresponding raw device for each OSD UUID is possible via:
synpromika@server1 ~ % UUID="4568c300-ad83-4288-963e-badcd99bf54f"
synpromika@server1 ~ % readlink -f /dev/disk/by-partuuid/"$ UUID "
/dev/sdc1
The OSD s key ID can be retrieved via:
synpromika@server1 ~ % OSD_ID=0
synpromika@server1 ~ % sudo ceph auth get osd."$ OSD_ID " -f json 2>/dev/null   jq -r '.[]   .key'
AQCKFpZdm0We[...]
Now we also need to identify the underlying block device:
synpromika@server1 ~ % OSD_ID=0
synpromika@server1 ~ % sudo ceph osd metadata osd."$ OSD_ID " -f json   jq -r '.bluestore_bdev_partition_path'    
/dev/sdc2
With all of this, we reconstructed the keyring, fsid, whoami, block + block_uuid files. All the other files inside the XFS metadata partition are identical on each OSD. So after placing and adjusting the corresponding metadata on the XFS partition for Ceph usage, we got a working OSD hurray! Since we had to fix yet another 32 OSDs, we decided to automate this XFS partitioning and metadata recovery procedure. We had a network share available on /srv/backup for storing backups of existing partition data. On each server, we tested the procedure with one single OSD before iterating over the list of remaining failing OSDs. We started with a shell script on server1, then adjusted the script for server2 and server3. This is the script, as we executed it on the 3rd server. Thanks to this, we managed to get the Ceph cluster up and running again. We didn t want to continue with the Ceph upgrade itself during the night though, as we wanted to know exactly what was going on and why the system behaved like that. Time for RCA! Root Cause Analysis So all but three OSDs on server2 failed, and the problem seems to be related to XFS. Therefore, our starting point for the RCA was, to identify what was different on server2, as compared to server1 + server3. My initial assumption was that this was related to some firmware issues with the involved controller (and as it turned out later, I was right!). The disks were attached as JBOD devices to a ServeRAID M5210 controller (with a stripe size of 512). Firmware state:
synpromika@server1 ~ % sudo storcli64 /c0 show all   grep '^Firmware'
Firmware Package Build = 24.16.0-0092
Firmware Version = 4.660.00-8156
synpromika@server2 ~ % sudo storcli64 /c0 show all   grep '^Firmware'
Firmware Package Build = 24.21.0-0112
Firmware Version = 4.680.00-8489
synpromika@server3 ~ % sudo storcli64 /c0 show all   grep '^Firmware'
Firmware Package Build = 24.16.0-0092
Firmware Version = 4.660.00-8156
This looked very promising, as server2 indeed runs with a different firmware version on the controller. But how so? Well, the motherboard of server2 got replaced by a Lenovo/IBM technician in January 2020, as we had a failing memory slot during a memory upgrade. As part of this procedure, the Lenovo/IBM technician installed the latest firmware versions. According to our documentation, some OSDs were rebuilt (due to the filestore->bluestore migration) in March and April 2020. It turned out that precisely those OSDs were the ones that survived the upgrade. So the surviving drives were created with a different firmware version running on the involved controller. All the other OSDs were created with an older controller firmware. But what difference does this make? Now let s check firmware changelogs. For the 24.21.0-0097 release we found this:
- Cannot create or mount xfs filesystem using xfsprogs 4.19.x kernel 4.20(SCGCQ02027889)
- xfs_info command run on an XFS file system created on a VD of strip size 1M shows sunit and swidth as 0(SCGCQ02056038)
Our XFS problem certainly was related to the controller s firmware. We also recalled that our monitoring system reported different sunit settings for the OSDs that were rebuilt in March and April. For example, OSD 21 was recreated and got different sunit settings:
WARN  server2.example.org  Mount options of /var/lib/ceph/osd/ceph-21      WARN - Missing: sunit=1024, Exceeding: sunit=512
We compared the new OSD 21 with an existing one (OSD 25 on server3):
synpromika@server2 ~ % systemctl show var-lib-ceph-osd-ceph\\x2d21.mount   grep sunit
Options=rw,noatime,attr2,inode64,sunit=512,swidth=512,noquota
synpromika@server3 ~ % systemctl show var-lib-ceph-osd-ceph\\x2d25.mount   grep sunit
Options=rw,noatime,attr2,inode64,sunit=1024,swidth=512,noquota
Thanks to our documentation, we could compare execution logs of their creation:
% diff -u ceph-disk-osd-25.log ceph-disk-osd-21.log
-synpromika@server2 ~ % sudo ceph-disk -v prepare --bluestore /dev/sdj --osd-id 25
+synpromika@server3 ~ % sudo ceph-disk -v prepare --bluestore /dev/sdi --osd-id 21
[...]
-command_check_call: Running command: /sbin/mkfs -t xfs -f -i size=2048 -- /dev/sdj1
-meta-data=/dev/sdj1              isize=2048   agcount=4, agsize=6272 blks
[...]
+command_check_call: Running command: /sbin/mkfs -t xfs -f -i size=2048 -- /dev/sdi1
+meta-data=/dev/sdi1              isize=2048   agcount=4, agsize=6336 blks
          =                       sectsz=4096  attr=2, projid32bit=1
          =                       crc=1        finobt=1, sparse=0, rmapbt=0, reflink=0
-data     =                       bsize=4096   blocks=25088, imaxpct=25
-         =                       sunit=128    swidth=64 blks
+data     =                       bsize=4096   blocks=25344, imaxpct=25
+         =                       sunit=64     swidth=64 blks
 naming   =version 2              bsize=4096   ascii-ci=0 ftype=1
 log      =internal log           bsize=4096   blocks=1608, version=2
          =                       sectsz=4096  sunit=1 blks, lazy-count=1
 realtime =none                   extsz=4096   blocks=0, rtextents=0
[...]
So back then, we even tried to track this down but couldn t make sense of it yet. But now this sounds very much like it is related to the problem we saw with this Ceph/XFS failure. We follow Occam s razor, assuming the simplest explanation is usually the right one, so let s check the disk properties and see what differs:
synpromika@server1 ~ % sudo blockdev --getsz --getsize64 --getss --getpbsz --getiomin --getioopt /dev/sdk
4685545472
2398999281664
512
4096
524288
262144
synpromika@server2 ~ % sudo blockdev --getsz --getsize64 --getss --getpbsz --getiomin --getioopt /dev/sdk
4685545472
2398999281664
512
4096
262144
262144
See the difference between server1 and server2 for identical disks? The getiomin option now reports something different for them:
synpromika@server1 ~ % sudo blockdev --getiomin /dev/sdk            
524288
synpromika@server1 ~ % cat /sys/block/sdk/queue/minimum_io_size
524288
synpromika@server2 ~ % sudo blockdev --getiomin /dev/sdk 
262144
synpromika@server2 ~ % cat /sys/block/sdk/queue/minimum_io_size
262144
It doesn t make sense that the minimum I/O size (iomin, AKA BLKIOMIN) is bigger than the optimal I/O size (ioopt, AKA BLKIOOPT). This leads us to Bug 202127 cannot mount or create xfs on a 597T device, which matches our findings here. But why did this XFS partition work in the past and fails now with the newer kernel version? The XFS behaviour change Now given that we have backups of all the XFS partition, we wanted to track down, a) when this XFS behaviour was introduced, and b) whether, and if so how it would be possible to reuse the XFS partition without having to rebuild it from scratch (e.g. if you would have no working Ceph OSD or backups left). Let s look at such a failing XFS partition with the Grml live system:
root@grml ~ # grml-version
grml64-full 2020.06 Release Codename Ausgehfuahangl [2020-06-24]
root@grml ~ # uname -a
Linux grml 5.6.0-2-amd64 #1 SMP Debian 5.6.14-2 (2020-06-09) x86_64 GNU/Linux
root@grml ~ # grml-hostname grml-2020-06
Setting hostname to grml-2020-06: done
root@grml ~ # exec zsh
root@grml-2020-06 ~ # dpkg -l xfsprogs util-linux
Desired=Unknown/Install/Remove/Purge/Hold
  Status=Not/Inst/Conf-files/Unpacked/halF-conf/Half-inst/trig-aWait/Trig-pend
 / Err?=(none)/Reinst-required (Status,Err: uppercase=bad)
 / Name           Version      Architecture Description
+++-==============-============-============-=========================================
ii  util-linux     2.35.2-4     amd64        miscellaneous system utilities
ii  xfsprogs       5.6.0-1+b2   amd64        Utilities for managing the XFS filesystem
There it s failing, no matter which mount option we try:
root@grml-2020-06 ~ # mount ./sdd1.dd /mnt
mount: /mnt: mount(2) system call failed: Structure needs cleaning.
root@grml-2020-06 ~ # dmesg   tail -30
[...]
[   64.788640] XFS (loop1): SB stripe unit sanity check failed
[   64.788671] XFS (loop1): Metadata corruption detected at xfs_sb_read_verify+0x102/0x170 [xfs], xfs_sb block 0xffffffffffffffff
[   64.788671] XFS (loop1): Unmount and run xfs_repair
[   64.788672] XFS (loop1): First 128 bytes of corrupted metadata buffer:
[   64.788673] 00000000: 58 46 53 42 00 00 10 00 00 00 00 00 00 00 62 00  XFSB..........b.
[   64.788674] 00000010: 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00  ................
[   64.788675] 00000020: 32 b6 dc 35 53 b7 44 96 9d 63 30 ab b3 2b 68 36  2..5S.D..c0..+h6
[   64.788675] 00000030: 00 00 00 00 00 00 40 08 00 00 00 00 00 00 01 00  ......@.........
[   64.788675] 00000040: 00 00 00 00 00 00 01 01 00 00 00 00 00 00 01 02  ................
[   64.788676] 00000050: 00 00 00 01 00 00 18 80 00 00 00 04 00 00 00 00  ................
[   64.788677] 00000060: 00 00 06 48 bd a5 10 00 08 00 00 02 00 00 00 00  ...H............
[   64.788677] 00000070: 00 00 00 00 00 00 00 00 0c 0c 0b 01 0d 00 00 19  ................
[   64.788679] XFS (loop1): SB validate failed with error -117.
root@grml-2020-06 ~ # mount -t xfs -o rw,relatime,attr2,inode64,sunit=1024,swidth=512,noquota ./sdd1.dd /mnt/
mount: /mnt: wrong fs type, bad option, bad superblock on /dev/loop1, missing codepage or helper program, or other error.
32 root@grml-2020-06 ~ # dmesg   tail -1
[   66.342976] XFS (loop1): stripe width (512) must be a multiple of the stripe unit (1024)
root@grml-2020-06 ~ # mount -t xfs -o rw,relatime,attr2,inode64,sunit=512,swidth=512,noquota ./sdd1.dd /mnt/
mount: /mnt: mount(2) system call failed: Structure needs cleaning.
32 root@grml-2020-06 ~ # dmesg   tail -14
[   66.342976] XFS (loop1): stripe width (512) must be a multiple of the stripe unit (1024)
[   80.751277] XFS (loop1): SB stripe unit sanity check failed
[   80.751323] XFS (loop1): Metadata corruption detected at xfs_sb_read_verify+0x102/0x170 [xfs], xfs_sb block 0xffffffffffffffff 
[   80.751324] XFS (loop1): Unmount and run xfs_repair
[   80.751325] XFS (loop1): First 128 bytes of corrupted metadata buffer:
[   80.751327] 00000000: 58 46 53 42 00 00 10 00 00 00 00 00 00 00 62 00  XFSB..........b.
[   80.751328] 00000010: 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00  ................
[   80.751330] 00000020: 32 b6 dc 35 53 b7 44 96 9d 63 30 ab b3 2b 68 36  2..5S.D..c0..+h6
[   80.751331] 00000030: 00 00 00 00 00 00 40 08 00 00 00 00 00 00 01 00  ......@.........
[   80.751331] 00000040: 00 00 00 00 00 00 01 01 00 00 00 00 00 00 01 02  ................
[   80.751332] 00000050: 00 00 00 01 00 00 18 80 00 00 00 04 00 00 00 00  ................
[   80.751333] 00000060: 00 00 06 48 bd a5 10 00 08 00 00 02 00 00 00 00  ...H............
[   80.751334] 00000070: 00 00 00 00 00 00 00 00 0c 0c 0b 01 0d 00 00 19  ................
[   80.751338] XFS (loop1): SB validate failed with error -117.
Also xfs_repair doesn t help either:
root@grml-2020-06 ~ # xfs_info ./sdd1.dd
meta-data=./sdd1.dd              isize=2048   agcount=4, agsize=6272 blks
         =                       sectsz=4096  attr=2, projid32bit=1
         =                       crc=1        finobt=1, sparse=0, rmapbt=0
         =                       reflink=0
data     =                       bsize=4096   blocks=25088, imaxpct=25
         =                       sunit=128    swidth=64 blks
naming   =version 2              bsize=4096   ascii-ci=0, ftype=1
log      =internal log           bsize=4096   blocks=1608, version=2
         =                       sectsz=4096  sunit=1 blks, lazy-count=1
realtime =none                   extsz=4096   blocks=0, rtextents=0
root@grml-2020-06 ~ # xfs_repair ./sdd1.dd
Phase 1 - find and verify superblock...
bad primary superblock - bad stripe width in superblock !!!
attempting to find secondary superblock...
..............................................................................................Sorry, could not find valid secondary superblock
Exiting now.
With the SB stripe unit sanity check failed message, we could easily track this down to the following commit fa4ca9c:
% git show fa4ca9c5574605d1e48b7e617705230a0640b6da   cat
commit fa4ca9c5574605d1e48b7e617705230a0640b6da
Author: Dave Chinner <dchinner@redhat.com>
Date:   Tue Jun 5 10:06:16 2018 -0700
    
    xfs: catch bad stripe alignment configurations
    
    When stripe alignments are invalid, data alignment algorithms in the
    allocator may not work correctly. Ensure we catch superblocks with
    invalid stripe alignment setups at mount time. These data alignment
    mismatches are now detected at mount time like this:
    
    XFS (loop0): SB stripe unit sanity check failed
    XFS (loop0): Metadata corruption detected at xfs_sb_read_verify+0xab/0x110, xfs_sb block 0xffffffffffffffff
    XFS (loop0): Unmount and run xfs_repair
    XFS (loop0): First 128 bytes of corrupted metadata buffer:
    0000000091c2de02: 58 46 53 42 00 00 10 00 00 00 00 00 00 00 10 00  XFSB............
    0000000023bff869: 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00  ................
    00000000cdd8c893: 17 32 37 15 ff ca 46 3d 9a 17 d3 33 04 b5 f1 a2  .27...F=...3....
    000000009fd2844f: 00 00 00 00 00 00 00 04 00 00 00 00 00 00 06 d0  ................
    0000000088e9b0bb: 00 00 00 00 00 00 06 d1 00 00 00 00 00 00 06 d2  ................
    00000000ff233a20: 00 00 00 01 00 00 10 00 00 00 00 01 00 00 00 00  ................
    000000009db0ac8b: 00 00 03 60 e1 34 02 00 08 00 00 02 00 00 00 00  ... .4..........
    00000000f7022460: 00 00 00 00 00 00 00 00 0c 09 0b 01 0c 00 00 19  ................
    XFS (loop0): SB validate failed with error -117.
    
    And the mount fails.
    
    Signed-off-by: Dave Chinner <dchinner@redhat.com>
    Reviewed-by: Carlos Maiolino <cmaiolino@redhat.com>
    Reviewed-by: Darrick J. Wong <darrick.wong@oracle.com>
    Signed-off-by: Darrick J. Wong <darrick.wong@oracle.com>
diff --git fs/xfs/libxfs/xfs_sb.c fs/xfs/libxfs/xfs_sb.c
index b5dca3c8c84d..c06b6fc92966 100644
--- fs/xfs/libxfs/xfs_sb.c
+++ fs/xfs/libxfs/xfs_sb.c
@@ -278,6 +278,22 @@ xfs_mount_validate_sb(
                return -EFSCORRUPTED;
         
        
+       if (sbp->sb_unit)  
+               if (!xfs_sb_version_hasdalign(sbp)  
+                   sbp->sb_unit > sbp->sb_width  
+                   (sbp->sb_width % sbp->sb_unit) != 0)  
+                       xfs_notice(mp, "SB stripe unit sanity check failed");
+                       return -EFSCORRUPTED;
+                 
+         else if (xfs_sb_version_hasdalign(sbp))   
+               xfs_notice(mp, "SB stripe alignment sanity check failed");
+               return -EFSCORRUPTED;
+         else if (sbp->sb_width)  
+               xfs_notice(mp, "SB stripe width sanity check failed");
+               return -EFSCORRUPTED;
+        
+
+       
        if (xfs_sb_version_hascrc(&mp->m_sb) &&
            sbp->sb_blocksize < XFS_MIN_CRC_BLOCKSIZE)  
                xfs_notice(mp, "v5 SB sanity check failed");
This change is included in kernel versions 4.18-rc1 and newer:
% git describe --contains fa4ca9c5574605d1e48
v4.18-rc1~37^2~14
Now let s try with an older kernel version (4.9.0), using old Grml 2017.05 release:
root@grml ~ # grml-version
grml64-small 2017.05 Release Codename Freedatensuppe [2017-05-31]
root@grml ~ # uname -a
Linux grml 4.9.0-1-grml-amd64 #1 SMP Debian 4.9.29-1+grml.1 (2017-05-24) x86_64 GNU/Linux
root@grml ~ # lsb_release -a
No LSB modules are available.
Distributor ID: Debian
Description:    Debian GNU/Linux 9.0 (stretch)
Release:        9.0
Codename:       stretch
root@grml ~ # grml-hostname grml-2017-05
Setting hostname to grml-2017-05: done
root@grml ~ # exec zsh
root@grml-2017-05 ~ #
root@grml-2017-05 ~ # xfs_info ./sdd1.dd
xfs_info: ./sdd1.dd is not a mounted XFS filesystem
1 root@grml-2017-05 ~ # xfs_repair ./sdd1.dd
Phase 1 - find and verify superblock...
bad primary superblock - bad stripe width in superblock !!!
attempting to find secondary superblock...
..............................................................................................Sorry, could not find valid secondary superblock
Exiting now.
1 root@grml-2017-05 ~ # mount ./sdd1.dd /mnt
root@grml-2017-05 ~ # mount -t xfs
/root/sdd1.dd on /mnt type xfs (rw,relatime,attr2,inode64,sunit=1024,swidth=512,noquota)
root@grml-2017-05 ~ # ls /mnt
activate.monmap  active  block  block_uuid  bluefs  ceph_fsid  fsid  keyring  kv_backend  magic  mkfs_done  ready  require_osd_release  systemd  type  whoami
root@grml-2017-05 ~ # xfs_info /mnt
meta-data=/dev/loop1             isize=2048   agcount=4, agsize=6272 blks
         =                       sectsz=4096  attr=2, projid32bit=1
         =                       crc=1        finobt=1 spinodes=0 rmapbt=0
         =                       reflink=0
data     =                       bsize=4096   blocks=25088, imaxpct=25
         =                       sunit=128    swidth=64 blks
naming   =version 2              bsize=4096   ascii-ci=0 ftype=1
log      =internal               bsize=4096   blocks=1608, version=2
         =                       sectsz=4096  sunit=1 blks, lazy-count=1
realtime =none                   extsz=4096   blocks=0, rtextents=0
Mounting there indeed works! Now, if we mount the filesystem with new and proper sunit/swidth settings using the older kernel, it should rewrite them on disk:
root@grml-2017-05 ~ # mount -t xfs -o sunit=512,swidth=512 ./sdd1.dd /mnt/
root@grml-2017-05 ~ # umount /mnt/
And indeed, mounting this rewritten filesystem then also works with newer kernels:
root@grml-2020-06 ~ # mount ./sdd1.rewritten /mnt/
root@grml-2020-06 ~ # xfs_info /root/sdd1.rewritten
meta-data=/dev/loop1             isize=2048   agcount=4, agsize=6272 blks
         =                       sectsz=4096  attr=2, projid32bit=1
         =                       crc=1        finobt=1, sparse=0, rmapbt=0
         =                       reflink=0
data     =                       bsize=4096   blocks=25088, imaxpct=25
         =                       sunit=64    swidth=64 blks
naming   =version 2              bsize=4096   ascii-ci=0, ftype=1
log      =internal log           bsize=4096   blocks=1608, version=2
         =                       sectsz=4096  sunit=1 blks, lazy-count=1
realtime =none                   extsz=4096   blocks=0, rtextents=0
root@grml-2020-06 ~ # mount -t xfs                
/root/sdd1.rewritten on /mnt type xfs (rw,relatime,attr2,inode64,logbufs=8,logbsize=32k,sunit=512,swidth=512,noquota)
FTR: The sunit=512,swidth=512 from the xfs mount option is identical to xfs_info s output sunit=64,swidth=64 (because mount.xfs s sunit value is given in 512-byte block units, see man 5 xfs, and the xfs_info output reported here is in blocks with a block size (bsize) of 4096, so sunit = 512*512 := 64*4096 ). mkfs uses minimum and optimal sizes for stripe unit and stripe width; you can check this e.g. via (note that server2 with fixed firmware version reports proper values, whereas server3 with broken controller firmware reports non-sense):
synpromika@server2 ~ % for i in /sys/block/sd*/queue/ ; do printf "%s: %s %s\n" "$i" "$(cat "$i"/minimum_io_size)" "$(cat "$i"/optimal_io_size)" ; done
[...]
/sys/block/sdc/queue/: 262144 262144
/sys/block/sdd/queue/: 262144 262144
/sys/block/sde/queue/: 262144 262144
/sys/block/sdf/queue/: 262144 262144
/sys/block/sdg/queue/: 262144 262144
/sys/block/sdh/queue/: 262144 262144
/sys/block/sdi/queue/: 262144 262144
/sys/block/sdj/queue/: 262144 262144
/sys/block/sdk/queue/: 262144 262144
/sys/block/sdl/queue/: 262144 262144
/sys/block/sdm/queue/: 262144 262144
/sys/block/sdn/queue/: 262144 262144
[...]
synpromika@server3 ~ % for i in /sys/block/sd*/queue/ ; do printf "%s: %s %s\n" "$i" "$(cat "$i"/minimum_io_size)" "$(cat "$i"/optimal_io_size)" ; done
[...]
/sys/block/sdc/queue/: 524288 262144
/sys/block/sdd/queue/: 524288 262144
/sys/block/sde/queue/: 524288 262144
/sys/block/sdf/queue/: 524288 262144
/sys/block/sdg/queue/: 524288 262144
/sys/block/sdh/queue/: 524288 262144
/sys/block/sdi/queue/: 524288 262144
/sys/block/sdj/queue/: 524288 262144
/sys/block/sdk/queue/: 524288 262144
/sys/block/sdl/queue/: 524288 262144
/sys/block/sdm/queue/: 524288 262144
/sys/block/sdn/queue/: 524288 262144
[...]
This is the underlying reason why the initially created XFS partitions were created with incorrect sunit/swidth settings. The broken firmware of server1 and server3 was the cause of the incorrect settings they were ignored by old(er) xfs/kernel versions, but treated as an error by new ones. Make sure to also read the XFS FAQ regarding How to calculate the correct sunit,swidth values for optimal performance . We also stumbled upon two interesting reads in RedHat s knowledge base: 5075561 + 2150101 (requires an active subscription, though) and #1835947. Am I affected? How to work around it? To check whether your XFS mount points are affected by this issue, the following command line should be useful:
awk '$3 == "xfs" print $2 ' /proc/self/mounts   while read mount ; do echo -n "$mount " ; xfs_info $mount   awk '$0 ~ "swidth" gsub(/.*=/,"",$2); gsub(/.*=/,"",$3); print $2,$3 '   awk '  if ($1 > $2) print "impacted"; else print "OK" ' ; done
If you run into the above situation, the only known solution to get your original XFS partition working again, is to boot into an older kernel version again (4.17 or older), mount the XFS partition with correct sunit/swidth settings and then boot back into your new system (kernel version wise). Lessons learned Thanks: Darshaka Pathirana, Chris Hofstaedtler and Michael Hanscho. Looking for help with your IT infrastructure? Let us know!

8 April 2021

Sean Whitton: consfigurator-live-build

One of my goals for Consfigurator is to make it capable of installing Debian to my laptop, so that I can stop booting to GRML and manually partitioning and debootstrapping a basic system, only to then turn to configuration management to set everything else up. My configuration management should be able to handle the partitioning and debootstrapping, too. The first stage was to make Consfigurator capable of debootstrapping a basic system, chrooting into it, and applying other arbitrary configuration, such as installing packages. That s been in place for some weeks now. It s sophisticated enough to avoid starting up newly installed services, but I still need to add some bind mounting. Another significant piece is teaching Consfigurator how to partition block devices. That s quite tricky to do in a sufficiently general way I want to cleanly support various combinations of LUKS, LVM and regular partitions, including populating /etc/crypttab and /etc/fstab. I have some ideas about how to do it, but it ll probably take a few tries to get the abstractions right. Let s imagine that code is all in place, such that Consfigurator can be pointed at a block device and it will install a bootable Debian system to it. Then to install Debian to my laptop I d just need to take my laptop s disk drive out and plug it into another system, and run Consfigurator on that system, as root, pointed at the block device representing my laptop s disk drive. For virtual machines, it would be easy to write code which loop-mounts an empty disk image, and then Consfigurator could be pointed at the loop-mounted block device, thereby making the disk image file bootable. This is adequate for virtual machines, or small single-board computers with tiny storage devices (not that I actually use any of those, but I want Consfigurator to be able to make disk images for them!). But it s not much good for my laptop. I casually referred to taking out my laptop s disk drive and connecting it to another computer, but this would void my laptop s warranty. And Consfigurator would not be able to update my laptop s NVRAM, as is needed on UEFI systems. What s wanted here is a live system which can run Consfigurator directly on the laptop, pointed at the block device representing its physical disk drive. Ideally this live system comes with a chroot with the root filesystem for the new Debian install already built, so that network access is not required, and all Consfigurator has to do is partition the drive and copy in the contents of the chroot. The live system could be set up to automatically start doing that upon boot, but another option is to just make Consfigurator itself available to be used interactively. The user boots the live system, starts up Emacs, starts up Lisp, and executes a Consfigurator deployment, supplying the block device representing the laptop s disk drive as an argument to the deployment. Consfigurator goes off and partitions that drive, copies in the contents of the chroot, and executes grub-install to make the laptop bootable. This is also much easier to debug than a live system which tries to start partitioning upon boot. It would look something like this:
    ;; melete.silentflame.com is a Consfigurator host object representing the
    ;; laptop, including information about the partitions it should have
    (deploy-these :local ...
      (chroot:partitioned-and-installed
        melete.silentflame.com "/srv/chroot/melete" "/dev/nvme0n1"))
Now, building live systems is a fair bit more involved than installing Debian to a disk drive and making it bootable, it turns out. While I want Consfigurator to be able to completely replace the Debian Installer, I decided that it is not worth trying to reimplement the relevant parts of the Debian Live tool suite, because I do not need to make arbitrary customisations to any live systems. I just need to have some packages installed and some files in place. Nevertheless, it is worth teaching Consfigurator how to invoke Debian Live, so that the customisation of the chroot which isn t just a matter of passing options to lb_config(1) can be done with Consfigurator. This is what I ve ended up with in Consfigurator s source code:
(defpropspec image-built :lisp (config dir properties)
  "Build an image under DIR using live-build(7), where the resulting live
system has PROPERTIES, which should contain, at a minimum, a property from
CONSFIGURATOR.PROPERTY.OS setting the Debian suite and architecture.  CONFIG
is a list of arguments to pass to lb_config(1), not including the '-a' and
'-d' options, which Consfigurator will supply based on PROPERTIES.
This property runs the lb_config(1), lb_bootstrap(1), lb_chroot(1) and
lb_binary(1) commands to build or rebuild the image.  Rebuilding occurs only
when changes to CONFIG or PROPERTIES mean that the image is potentially
out-of-date; e.g. if you just add some new items to PROPERTIES then in most
cases only lb_chroot(1) and lb_binary(1) will be re-run.
Note that lb_chroot(1) and lb_binary(1) both run after applying PROPERTIES,
and might undo some of their effects.  For example, to configure
/etc/apt/sources.list, you will need to use CONFIG not PROPERTIES."
  (:desc (declare (ignore config properties))
         #?"Debian Live image built in $ dir ")
  (let* (...)
    ;; ...
     (eseqprops
      ;; ...
      (on-change
          (eseqprops
           (on-change
               (file:has-content ,auto/config ,(auto/config config) :mode #o755)
             (file:does-not-exist ,@clean)
             (%lbconfig ,dir)
             (%lbbootstrap t ,dir))
           (%lbbootstrap nil ,dir)
           (deploys ((:chroot :into ,chroot)) ,host))
        (%lbchroot ,dir)
        (%lbbinary ,dir)))))
Here, %lbconfig is a property running lb_config(1), %lbbootstrap one which runs lb_bootstrap(1), etc. Those properties all just change directory to the right place and run the command, essentially, with a little extra code to handle failed debootstraps and the like. The ON-CHANGE and ESEQPROPS combinators work together to sequence the interaction of the Debian Live suite and Consfigurator. This way, we only rebuild the chroot if the configuration changed, and we only rebuild the image if the chroot changed. Now over in my personal consfig:
(try-register-data-source
 :git-snapshot :name "consfig" :repo #P"src/cl/consfig/" ...)
(defproplist hybrid-live-iso-built :lisp ()
  "Build a Debian Live system in /srv/live/spw.
Typically this property is not applied in a DEFHOST form, but rather run as
needed at the REPL.  The reason for this is that otherwise the whole image will
get rebuilt each time a commit is made to my dotfiles repo or to my consfig."
  (:desc "Sean's Debian Live system image built")
  (live-build:image-built.
      '("--archive-areas" "main contrib non-free" ...)
      "/srv/live/spw"
    (os:debian-stable "buster" :amd64)
    (basic-props)
    (apt:installed "whatever" "you" "want")
    (git:snapshot-extracted "/etc/skel/src" "dotfiles")
    (file:is-copy-of "/etc/skel/.bashrc" "/etc/skel/src/dotfiles/.bashrc")
    (git:snapshot-extracted "/root/src/cl" "consfig")))
The first argument to LIVE-BUILD:IMAGE-BUILT. is additional arguments to lb_config(1). The third argument onwards are the properties for the live system. The cool thing is GIT:SNAPSHOT-EXTRACTED the calls to this ensure that a copy of my Emacs configuration and my consfig end up in the live image, ready to be used interactively to install Debian, as described above. I ll need to add something like (chroot:host-chroot-bootstrapped melete.silentflame.com "/srv/chroot/melete") too. As with everything Consfigurator-related, Joey Hess s Propellor is the giant upon whose shoulders I m standing.

Next.

Previous.