Search Results: "ed"

2 September 2012

Lars Wirzenius: Debian discussion culture: what doesn't work

I claim that the way we conduct discussions on debian-devel has gone quickly downhill this year. The discussions around the default init implementation are particularly sad examples of how Debian debates technical topics. I've whined about this before, and people have suggested various things. Here's a list of things that I think we can conclude do not work: Things that can work: Things that might be worthwhile to try: The current situation, where a few hard-nosed, uncompromising people can prevent any rational discussion about init systems cannot be allowed to continue.

Emanuele Rocca: Story of a bug in Ubuntu

Some months ago I have run into a pretty interesting bug while working on a Ubuntu-based remote desktop system. The whole OS was installed on a server somewhere and users could access their desktop remotely. Some call this stuff Desktop-as-a-Service. The operating system we chose was Ubuntu Oneiric (11.10) and the remote access part was implemented with x2go, which uses nxagent to provide NX transport of X sessions. Users could access their Ubuntu machines remotely, with sound, video, youtube, and all you would expect from a desktop machine. The whole thing was working quite well. Now, as I said that was in May. Ubuntu 12.04 LTS was available, and the choice of upgrading to it sounded pretty much obvious. So we upgraded our test system to Precise and everything seemed to work smoothly. Till we tried to open a PDF document, actually. It took evince about 50 seconds to display a relatively small document. Same story with images opened with the default image viewer, eog. The fix delivered to our users was simple: we have set shotwell-viewer as the default image viewer, and epdfview as the default PDF viewer. Everybody happy. In the meantime, obviously, I was interested in this issue so I ve tried to run run evince from a terminal, getting the following output:
(evince:15833): GRIP-WARNING **: Failed to initialize gesture manager.
Funny. On another test system running Debian Sid (unstable) everything was working smoothly. The diff between Ubuntu s version of evince and Debian s is a 6MB monster. Among other changes, I noticed that Ubuntu s version build-depends on libgrip-dev, which depends on libutouch-geis. Multitouch stuff. Why should multitouch support break my remote session? So on May the 10th I filed a bug on launchpad. How this issue got handled is in my opinion one of the many fine examples of the inherent superiority of free software, coupled with a we won t hide problems mindset. For an example of how bad is the proprietary approach, just check a random bug in Adobe s bug tracking system. But let s go back to the evince bug. Other users reported that their VNC sessions were also affected by the same problem. After a few days it was clear that the culprit was utouch-geis, and a patch appeared. Unfortunately it did not actually address the issue. Somebody else reported that RDP sessions were broken too. At the beginning of June Precise was still affected. Finally, on August the 6th a working patch was submitted by Bradley M. Froehle and included by Chase Douglas (thank you guys). End of August, fixed version of geis accepted into precise-updates, case closed. Now for some considerations. The problem was clearly of a certain importance. A Long Term Support, stable version of Ubuntu shipped with broken PDF and image viewing functionalities. It got fixed properly, even though 3 good months are quite a long time for such a bug to get solved. However, the issue only affected a pretty limited number of users, also certainly not Ubuntu s main target audience. This bug never affected Debian, simply because utouch-geis has not made its way into the archive yet. It takes longer to make changes like this in Debian, but for some categories of users stability is more important than new, cool features. Choice is a good thing.

Erich Schubert: ELKI call for contributions

ELKI is a data mining software project that I have been working on for the last years as part of my PhD research. It is open source (AGPL-3 licensed) and avilable as both a Debian package and Ubuntu package in the official repositories. So a simple aptitude install elki should get you going and give you a menu entry for ELKI. These packages come with the scripts elki to launch the MiniGUI and elki-cli to run from command line. The key feature that sets ELKI apart from existing open source tools used in data mining (e.g. Weka and R) is that it has support for index structures to speed up algorithms, and a very modular architecture that allows various combinations of data types, distance functions, index structures and algorithms. When looking for performance regressions and optimization potential in ELKI, I recently ran some benchmarks on a data set with 110250 images described by 8 dimensional color histograms. This is a decently sized dataset: it takes long enough (usually in the range of 1-10 minutes) to measure true hotspots. When including Weka and R in the comarison I was quite surprised: our k-means implementation runs at the same speed as Rs implementation in C (and around twice that of the more flexible "flexclus" version). For some of the key agorithms (DBSCAN, OPTICS, LOF) we are an order of magnitude faster than Weka and R, and adding index support speeds up the computation by another factor of 5-10x. In the most extreme case - DBSCAN in Weka vs. DBSCAN with R-tree in ELKI - the speedup was a factor of 330x, or 2 minutes (ELKI) as opposed to 11 hours (Weka).
The reason why I was suprised is that I expected ELKI to perform much worse. It is written in Java (as opposed to R's kmeans, which is in C), uses a very flexible architecture which for example does not assume distances to be of type double and just has a lot of glue code inbetween. However, obviously, the Java Hotspot compiler actually lives up to its expectations and manages to inline the whole distance computations into k-means, and then compiles it at a level comparable to C. R executes vectorized operations quite fast, but on non-native code as in the LOF example it can become quite slow, too. (I would not take Weka as reference, in particular with DBSCAN and OPTICS there seems to be something seriously broken. Judging from a quick look at it, the OPTICS implementation actually is not even complete, and both implementations actually copy all data out of Weka into a custom linear database, process it there, then feed back the result into Weka. They should just drop that "extension" altogether. The much newer and Weka-like LOF module is much more comparable.) Note that we also have a different focus than Weka. Weka is really popular for machine learning, in particular for classification. In ELKI, we do not have a single classification algorithm because there is Weka for that. Instead, ELKI focuses on cluster analysis and outlier detection. And ELKI has a lot of algorithms in this domain, I dare to say the largest collection. In particular, they are all in the same framework, so they can be easily compared. R does of course have an impressive collection in CRAN, but in the end they do not really fit together. Anyway, ELKI is a cool research project. It keeps on growing, we have a number of students writing extensions as part of their thesis. It has been extremely helpful for me in my own research, as I could quickly prototype some algorithms, then try different combinations and use my existing evaluation and benchmarking. You need some time to get started (largely because of the modular architecture, Java generics and such hurdles), but then it is a very powerful research tool. But there are just many more algorithms, published sometime, somewhere, but barely with source code available. We'd love to get all these published algorithms into ELKI, so researchers can try them out. And enhance them. And use them for their actual data. So far, ELKI was mostly used for algorithmic research, but it's starting to move out into the "real" world. More and more people that are not computer scientists start using ELKI to analyze their data. Because it has algorithms that no other tools have. I tried to get ELKI into the "Google Summer of Code", but it was not accepted. But I'd really like to see it gain more traction outside the university world. There are a number of cool projects associated with ELKI that I will not be able to do myself the next years, unfortunately. If you are a researcher in cluster analysis or outlier detection, consider contributing your algorithms to ELKI. Spend some time optimizing them, adding some documentation. Because, if ELKI keeps on growing and gaining popularity, it will be the future benchmark platform. And this can give you citations, which are somewhat the currency of science these days. Algorithms available in the major toolkits just do get cited more, because people compare to them. See this list for an overview of work cited by ELKI - scientific work that we reimplemented at least to some extend for ELKI. It is one of the services that we provide with ELKI for researchers: not only the algorithm, but also the appropriate citation.

1 September 2012

Lars Wirzenius: Dabbling in diplomacy

For about the past three months I've been conducting a small experiment. When I've seen people misbehave on the Debian development mailing list, I've sent a private e-mail to them suggesting they should avoid some specific behavior, in the hope of getting them to stop. My success has been varied. A few have thanked me, and changed their behavior. A couple have taken offense. Some have ignored me. I've noticed a correlation between how much effort I put into the letter and how successful it. Broadly speaking, if I send anything earlier than the sixth version, it fails. Getting the message exactly right is not easy, for me, and takes quite some effort and time. I'm happy about my successes, but on the whole, I fear my experiment is a failure. It's too much effort to do this in the long term, and it's too chancy. Someone else might be able to do it better, but this is not something I can keep on doing. I think we need some better solution to keep discussions in Debian on track and not have them blow up. We have a systemic problem where contentious issues, such as choice of init system, is quite hard for us to deal with. We're also not very good at dealing with situations where a few individuals are dominating the discussion by being loud, insistent, and unwilling to budge or to give any credence to opposing views. I don't know what to do about that, but we clearly need social and possibly technical tools for this.

Martin-Éric Racine: PulseAudio: system mode broken

Ever since version 1.1 of PulseAudio was released, remote audio stopped working for me. Basically, the tunnel created by enabling "Detect native remote PulseAudio sinks" in paprefs on the client side immediately crashes the PulseAudio server on the remote host. I reported the issue at Free Desktop bug #49681. The issue still exists in version 2.0, which is what Debian's next stable release is supposed to ship (and in 2.1, available via the experimental repository). This essentially means that I cannot upgrade my hosts to Wheezy without losing my remote speakers. Would anybody knowledgable enough with PulseAudio internals be able to help me track down the cause of this bug?

Martin-Éric Racine: Bounty: PulseAudio: implement compression into the RTP modules

I'm looking for someone preferably based within the IBAN zone to implement compression support into PulseAudio's RTP modules. Please contact me via my Ubuntu address for details.

Tanguy Ortolo: XMPPloit explained

XMPPloit is an exploit tool for a so-called flaw in the XMPP protocol. It has been published recently under the GPLv3 license, and has received much comment. However, it does not seem anybody took the time to study this attack and explain it. Goals XMPPloit is designed to serve as a transparent man-in-the-middle between an XMPP client and its XMPP server, in order to force the client not to encrypt its communications, so that it is possible to read them and modify them on-the-fly. That allows to force the client to use a clear text authentication mechanism, to display its login and password, and to modify any message it sends or receives.
XMPP logo
Mode of operation If you were expecting a tricky, undetectable attack against the XMPP protocol itself, you will be disappointed. This attack could not be simpler:
  1. In XMPP, the clients opens a connection to the server as plain text. In this case, with the attacker between them.
  2. The server offers the STARTTLS extension. The attacker blocks it, that is, does not transmit this offer to the client, so the connection stays in plain text.
  3. The client authenticate over the plain text connection.
Comments In fact, this is only an exploit against design flaws of some XMPP clients that would not warn the user that they are about to send their credentials on a clear text channel. Actually, the protocol most vulnerable to this type of attack is HTTP. Many websites that identify their users are made available over clear text HTTP, with an automatic redirection to HTTPS. Unless they use HSTS, this redirection can be blocked by an attacker without being noticed by most users. And, contrary to XMPP, not warn the user of an insecure login is not the fact of some broken clients, but of all the available browsers. I repeat: not a single browser will currently tell the user: Hey, you are about to transmit a password in clear, it could be intercepted! . Yes, there are browser that warn their users this way the first time: Hey, you are about to transmit your answers to a form in clear! Do you wish to do that, and do you want me to warn you next time? but this not quite the same, and it is just badly designed and in practice neither useful nor usable so everybody disables that.

31 August 2012

Roland Mas: Integrating FWbuilder with fail2ban and port-knocking

This article documents how I'm currently building my firewalls. It builds on netfilter-based-port-knocking, and tries to integrate several components of a firewall as gracefully as possible. For some context: I'm getting involved with servers where the firewall policy goes beyond a handful of SSH from my home and my other servers rules. There are many different network streams that need to be policed, some of them are common across several (potentially many) servers, and so on. So I'm gradually giving up on my hand-made scripts, and trying out higher-level tools. I settled on FWbuilder, which seems nice. However, it only allows static policies, and I still want to keep dynamic policies such as what fail2ban provides, as well as my own port-knocking system. The problem I had was that fail2ban isn't really made to play nice as part of a complex firewalling setup, my port-knocking system was too tightly integrated within my firewall script, and FWbuilder wasn't too flexible when it came to delegating part of the firewall policy to something external. Fortunately, this was only a perceived problem (or a real problem in my understanding), because it is actually possible to have all three blocks playing nicely together. More context: as usual, I'm focusing on Debian-like systems. More precisely, on those with a Linux kernel; it may be that FreeBSD's firewalling subsystem has a feature comparable to Linux's recent module, but I don't know. Let's start with FWbuilder. This is not the place for a manual, the official documentation is rather complete. I'll assume you have defined most relevant blocks in there: firewall, hosts, IP addresses, services, and so on. You define your static policy with the standard rules. From then on, we want to integrate the external tools for dynamic rules. Step 1: Integrating fail2ban We want fail2ban to have its own playground, so that it doesn't overwrite anything in the standard policy. The trick is to define a new policy rule set named fail2ban. Leave it empty in FWbuilder. So far so good, but fail2ban (the daemon) still operates on the INPUT chain in the firewall, and could therefore still mangle the static rules. Fortunately, starting with fail2ban 0.8.5 (available from Debian Wheezy, or in the backports for Squeeze), you can define what chain to operate on: with a configuration item such as chain = fail2ban, fail2ban (the daemon) will now only add its rules to fail2ban (the firewall chain), and won't be able do damage the other chains. The missing part is to send some of the traffic to it using the standard policy: i defined a rule sending the incoming SSH connections to the fail2ban policy ( branching in FWbuilder jargon). Voil : the static policy delegates part of the decision-making to a sub-policy controlled by the fail2ban daemon. Step 2: Integrating port-knocking This is a bit trickier, but we'll use a similar method. First, the traffic used for port-knocking needs to be directed to the chain that does the listening. Define a policy rule set named portknocking, and leave it empty in FWbuilder. It'll be used by the dynamic rules to track progression of source IP addresses through the port-knocking sequence, so you'll need to send ( branch ) incoming traffic there, probably after the rules allowing incoming connections from known hosts. The dynamic part of this will only concern the refreshing of this listening chain , which we assume will do its work and mark IP addresses with PK_ESTABLISHED once the sequence is completed. What we do with these marked IP addresses will still be defined within the FWbuilder policy. We're going to need some complex rules since we want to filter according to this PK_ESTABLISHED bit and according to destination port, for instance; unfortunately FWbuilder doesn't allow combining filter criteria with and, so we define a new policy rule set called accept_if_pk_ok. This ruleset has two rules: the second is an ACCEPT and should be easy to understand. The first rule needs to ensure the ACCEPT is only reached for connections coming from PK_ESTABLISHED addresses, so it's going to be a bit tricky. (Explanation: the first rule matches packets coming from IP addresses not marked as PK_ESTABLISHED, and returns them to the calling policy. Packets remaining after this rule are those coming from the appropriate addresses, and they go on to the ACCEPT. We could have had the first rule match on IP addresses that are marked, and branch to yet another ruleset with the ACCEPT part, but that would make it harder to read, I feel.) Now let's get back to the main policy and add rules concerning what kind of traffic we want to allow once the port-knocking sequence completed. For instance, we define a rule matching on the SSH service , where the action is to branch to accept_if_pk_ok. When an incoming packet tries to establish a connection to the SSH port, it's passed to the accept_if_pk_ok ruleset. If it comes from the same IP as a recent port-knocking sequence, it goes on to be ACCEPTed. If not, it returns to the main policy. Maybe static rules further on will allow it to go through. Step 3: tying it all together Now that we have all the pieces, the rest is plumbing. With this setup, at boot time, the $hostname.fw script creates the static policy and the extra playgrounds; then the port-knocking script implements the listening for the magic sequence; then fail2ban inserts its own rules. And there we are: three different parts for the firewall policy, all integrating nicely. Mission accomplished! Note: (Mostly copy-and-pasted from the previous article) This article is deliberately short on details and ready-to-run scripts. Firstly because firewall scripts vary wildly so any script would have to be adapted anyway, but mostly because security is best handled with one's brain switched on. Fiddling with a firewall can easily open gaping holes or lock everyone out. So please make sure you understand what goes on before blindly pasting stuff into your own setup. Some bits are left as an exercise to the reader.

Russell Coker: Links August 2012

Google are providing some really good employee benefits including benefits to a life partner of a deceased employee [1]. It s not known if all those benefits are available outside the US, in any case the US is the first world country with the least social security so they need it most there. A recent Australian legal case had a father petitioning the court to have his kids take his family name [2]. According to the news report no good reason was given for renaming the kids, merely tradition. The mother won. GlassDoor.com is a site for reviewing companies [3]. It also has job adverts, it seems that they get people in to read the reviews and then advertise jobs. Sarah Resnick interviewed Jacob Appelbaum (of Tor fame) about privacy issues and published the article as Leave Your Cellphone at Home [4]. It s very interesting and references some resources such as riseup.net that I have to try using. Systemd in Fedora 17 has multi-seat support [5]. They support plugging USB terminals in at run-time to dynamically add new consoles for GNOME sessions. The Coding Horror blog has an amusing and informative post about why people shouldn t learn to code [6]. Related posts:
  1. Links June 2012 This Youtube video is an amusing satire of EULAs and...
  2. Links January 2012 Cops in Tennessee routinely steal cash from citizens [1]. They...
  3. Links August 2008 Michael Janke is writing a series of posts about estimating...

Paul Tagliamonte: A bit more on DPU

DPU, as I ve mentioned casually, is a testing framework for Debian tools. I ll expand a bit more about what DPU does, what it s going to be used for, and how it can help you (yes, you!) create tools to work with Debian packages. Firstly, DPU is a test framework. It s sole purpose is only to run tests, and give each test a pass / fail grade. The test syntax will be as declarative and simple as one can keep such things, and tries to do the right thing(tm). It s not currently stable, but it s getting there. DPU aims to replace Lintian s test suite, and clean up the tests to make them a bit more declarative, and less hackish. At it s core, DPU uses a templating system (using Jinja2) to render out a policy-perfect Debian source directory, including (if needed) any number of fake Upstream files, such as Hello World! in Shell (for arch:all), in C (for arch:any), and so forth. DPU tests mangle (slightly) the files before a run simple stuff like removing a manpage, or adding a file where it shouldn t be. After the builder builds the package (with any of the global or test-local builders), any number of checkers (again, global or local) are run, and output compared. This is the part that s currently undergoing work, but the basics are alive, and an example test directory is on my github. Everything s in Python, and new contributors are welcome!

30 August 2012

Bastian Venthur: Awesome Firefox Campaign

Gil writes about the awesome Firefox ad campaign running currently in Berlin Alexanderplatz. Good stuff!

Erich Schubert: Finding packages for deinstallation

On my netbook, I try to keep the amount of installed software limited. Aptitudes "automatically installed" markers are very helpful here, since they allow you to differentiate between packages that were deliberately installed and packages that were manually marked for installation. I quite often browse through the list of installed packages and recheck those that are not marked as "A".
However, packages that are "suggested" by some other package (but not "required") will be kept even when marked as automatically. This is quite sensible: when you deinstall the package that "suggested" them, they will be removed. So this is nice for having optional software also automatically removed.
However sometimes you need the core package but not this optional functionality. Aptitude can help you there, too. Here's an aptitude filter I used to find some packages for removal:
!?reverse-depends(~i) ~M !?essential
It will display only packages with no direct dependency from another installed package and that are marked as automatically installed (so they must be kept installed because of a weaker dependency.
Some examples of "suggested but not required" packages:
  • Accessibility extensions of Gnome
  • Spelling dictionaries
  • Optional functionality / extensions
Depending on your requirements, you might want to keep some of these and remove others.

Here is also a filter to find packages that you can put on "automatically installed":
~i !~M ?reverse-depends(~i) !?essential
This will catch "installed but not automatically installed packages, that another installed package depends on". Note that you should not blindly put all of these to "automatic" mode. For example "logrotate" depends on "cron anacron fcron". If you have both cron and anacron installed, aptitude will consider anacron to be unnecessary (it is - on a system with 24h uptime). So review this list, and see what happens when you set packages to "A", and reconsider your intentions. If it is a software you want for sure, leave it on manual.

Paul Wise: Ponds as time travel devices

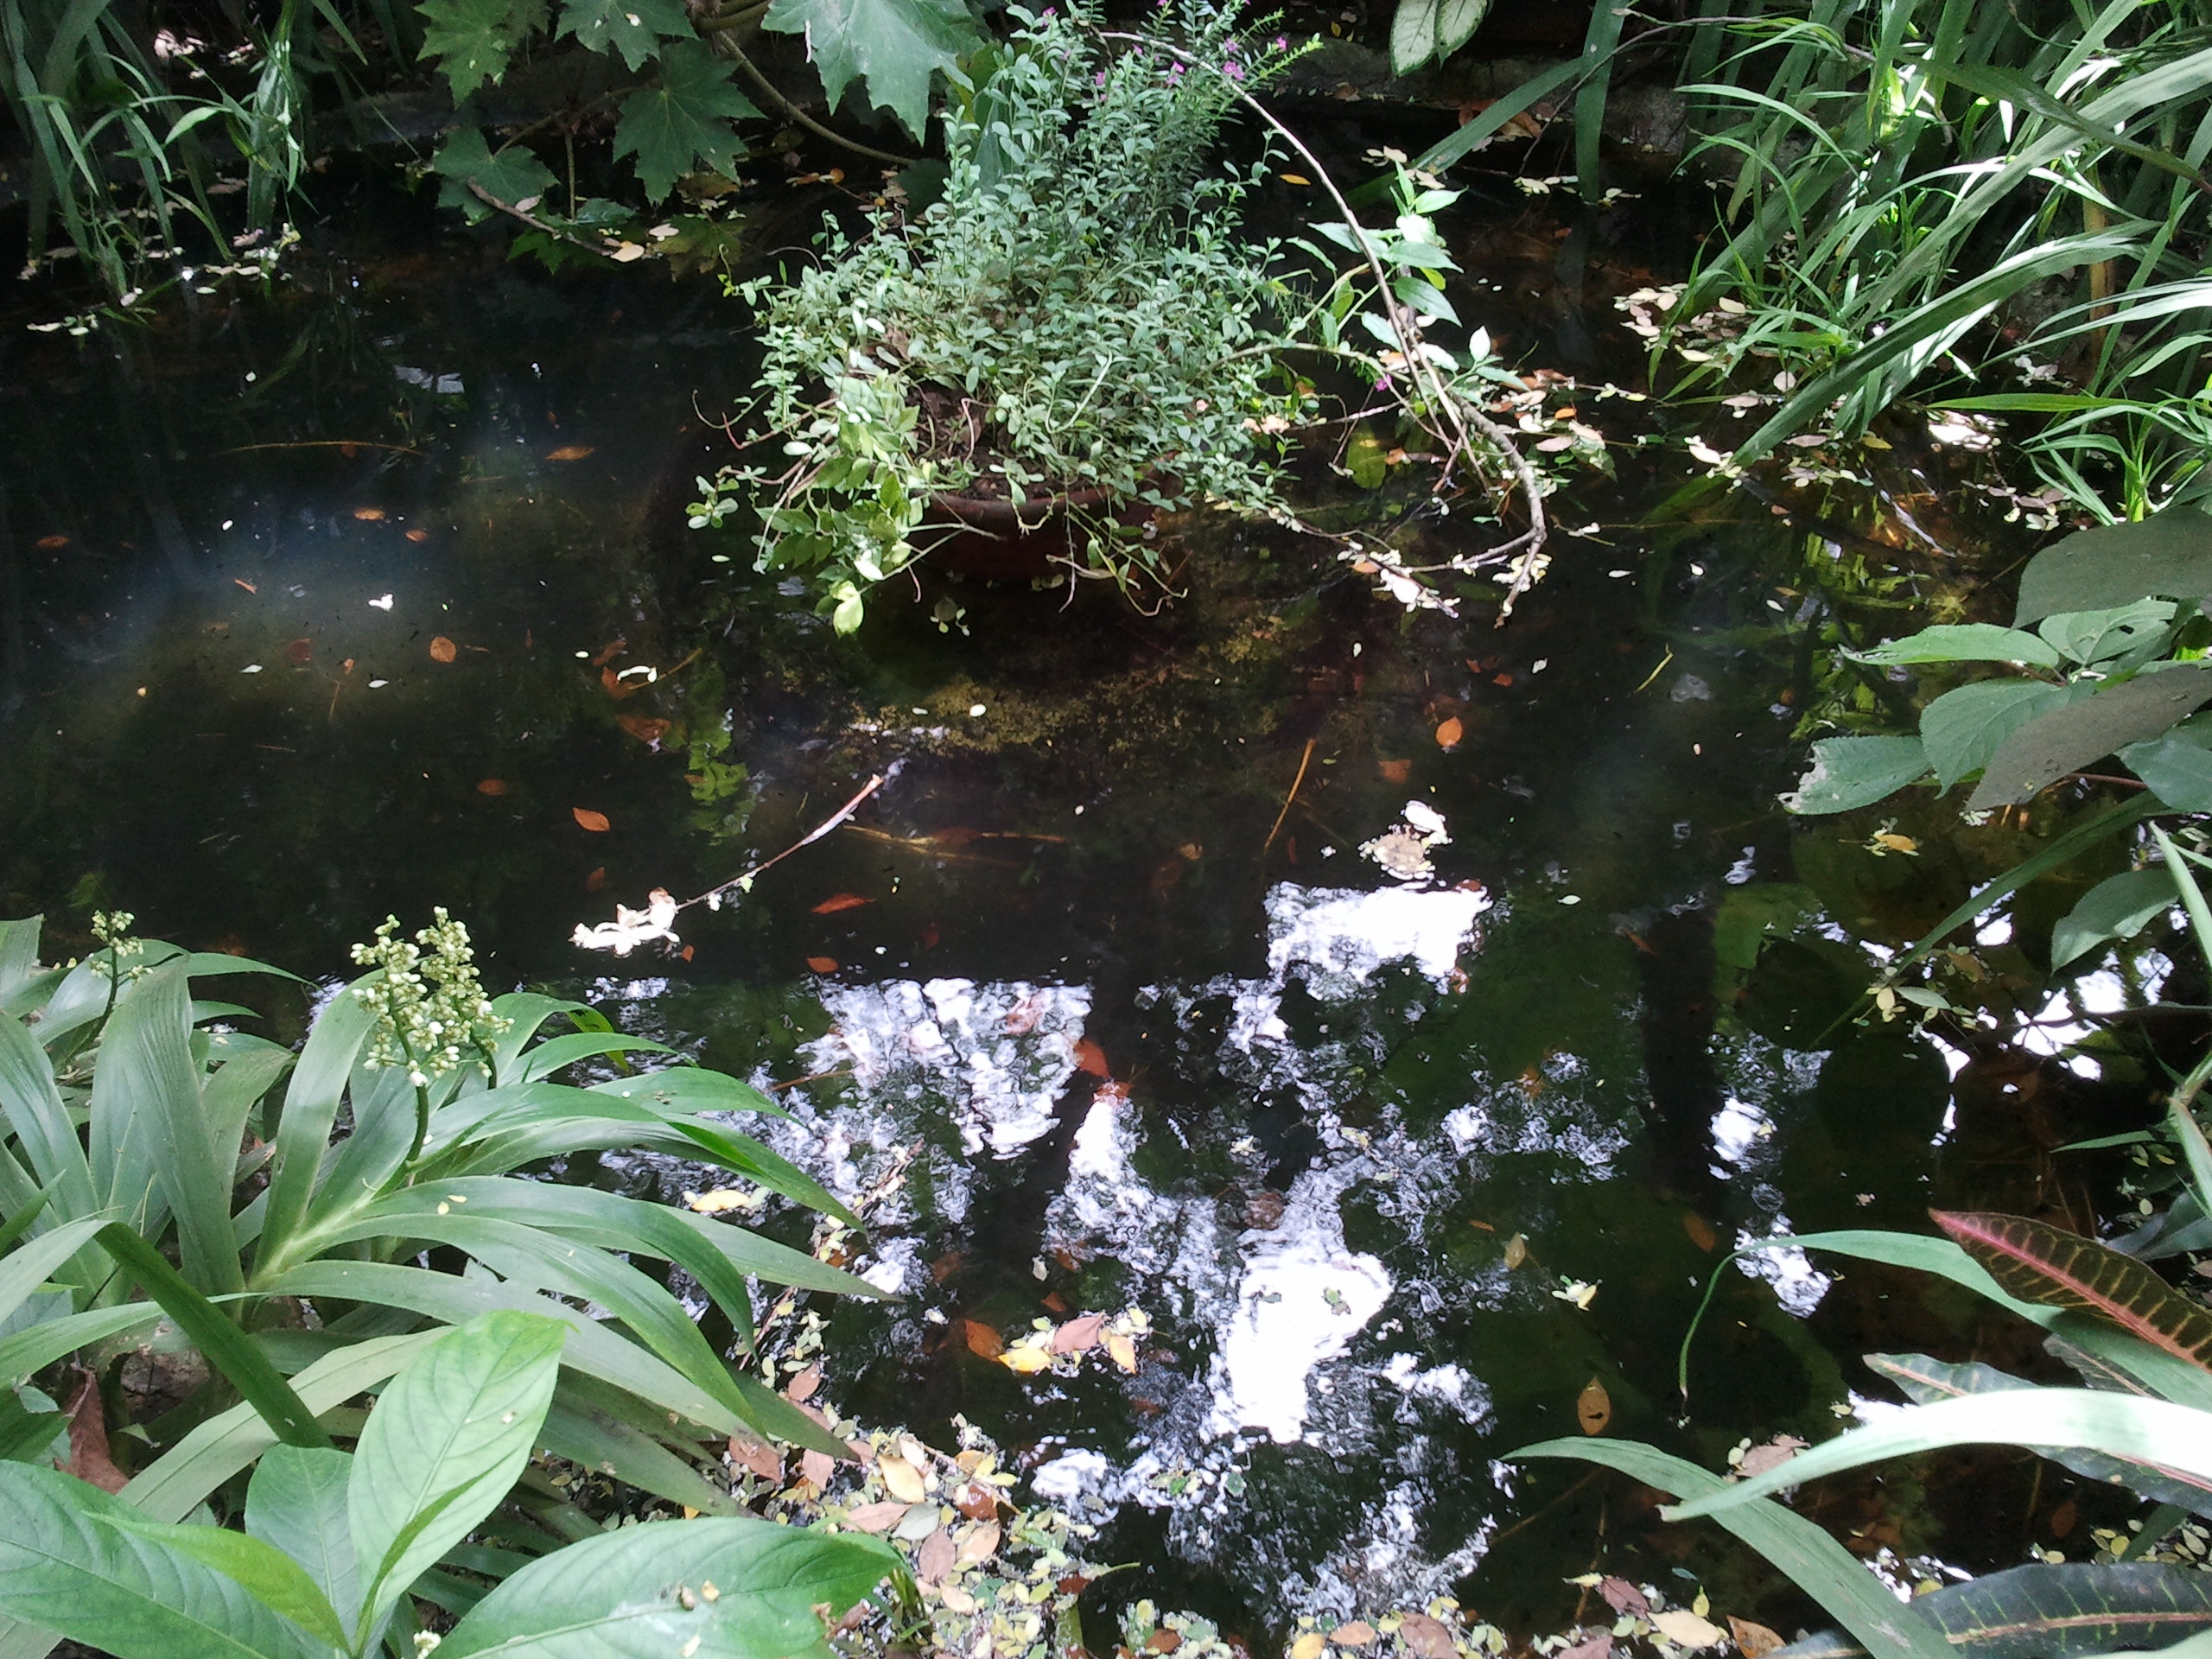
I firmly believe that this pond is a time travel device: Space invader pond The proof is in this recording I made1. At minimum, clearly there is some sort of quantum entanglement with computer games from the 70s going on. 1. Folks may want to use this recording in free software. To the extent possible under law, I have waived all copyright and related or neighboring rights to this work. The frogs have too. An email or a link to this page would be appreciated though.

Axel Beckert: deepgrep: grep nested archives with one command

Several months ago, I wrote about grep everything and listed grep-like tools which can grep through compressed files or specific data formats. The blog posting sparked several magazine articles and talks by Frank Hofmann and me. Frank recently noticed that we though missed one more or less mighty tool so far. We missed it, because it s mostly unknown, undocumented and hidden behind a package name which doesn t suggest a real recursive grep everything : deepgrep deepgrep is part of the Debian package strigi-utils, a package which contains utilities related to the KDE desktop search Strigi. deepgrep especially eases the searching through tar balls, even nested ones, but can also search through zip files and OpenOffice.org/LibreOffice documents (which are actually zip files). deepgrep seems to support at least the following archive and compression formats: A search in an archive which is deeply nested looks like this:
$ deepgrep bar foo.ar
foo.ar/foo.tar/foo.tar.gz/foo.zip/foo.tar.bz2/foo.txt.gz/foo.txt:foobar
foo.ar/foo.tar/foo.tar.gz/foo.zip/foo.tar.bz2/foo.txt.gz/foo.txt:bar
deepgrep though neither seems to support any LZMA based compression (lzma, xz, lzip, 7z), nor does it support lzop, rzip, compress (.Z suffix), cab, cpio, xar, or rar. Further current drawbacks of deepgrep: deepfind If you just need the file names of the files in nested archives, the package also contains the tool deepfind which does nothing else than to list all files and directories in a given set of archives or directories:
$ deepfind foo.ar
foo.ar
foo.ar/foo.tar
foo.ar/foo.tar/foo.tar.gz
foo.ar/foo.tar/foo.tar.gz/foo.zip
foo.ar/foo.tar/foo.tar.gz/foo.zip/foo.tar.bz2
foo.ar/foo.tar/foo.tar.gz/foo.zip/foo.tar.bz2/foo.txt.gz
foo.ar/foo.tar/foo.tar.gz/foo.zip/foo.tar.bz2/foo.txt.gz/foo.txt
As with deepgrep, deepfind does not implement any common options of it s normal sister tool find. Dependencies The package strigi-utils doesn t pull in the complete Strigi framework (i.e. no daemon), just a few libraries (libstreams, libstreamanalyzer, and libclucene). On Wheezy it also pulls in some audio/video decoding libraries which may make some server administrators less happy. Conclusion Both tools are quite limited to some basic use cases, but can be worth a fortune if you have to work with nested archives. Nevertheless the claim in the Debian package description of strigi-utils that they re enhanced versions of their well known counterparts is IMHO disproportionate. Most of the missing features and documentation can be explained by the primary purpose of these tools: Being backend for desktop searches. I guess, there wasn t much need for proper commandline usage yet. Until now. ;-) 42.zip And yes, I was curious enough to let deepfind have a look at 42.zip (the one from SecurityFocus, unzip seems not able to unpack 42.zip from unforgettable.dk due a missing version compatibility) and since it just traverses the archive sequentially, it has no problem with that, needing just about 5 MB of RAM and a lot of time:
[ ]
42.zip/lib f.zip/book f.zip/chapter f.zip/doc f.zip/page e.zip
42.zip/lib f.zip/book f.zip/chapter f.zip/doc f.zip/page e.zip/0.dll
42.zip/lib f.zip/book f.zip/chapter f.zip/doc f.zip/page f.zip
42.zip/lib f.zip/book f.zip/chapter f.zip/doc f.zip/page f.zip/0.dll
deepfind 42.zip  11644.12s user 303.89s system 97% cpu 3:24:02.46 total
I though won t try deepgrep on 42.zip. ;-)

29 August 2012

Julien Danjou: Gnus notifications

Today, I've merged my Gnus notifications module inside Gnus git repository. This way, it will be available for everybody in Emacs 24.2. gnus-notifications example This module allows you to be notified via notifications-notify (the Emacs implementation of the Freedesktop desktop notifications) on new messages received in Gnus. It can also retrieves contacts photo via gravatar.el and google-contacts.el to include them in the notification. To enable it in Emacs > 24.1, you just have to add the following line to your Gnus configuration file:
(add-hook 'gnus-after-getting-new-news-hook 'gnus-notifications)
If you want to download it and use it stand-alone for a previous Emacs version, you can fetch the latest file revision and load it before adding the previously given line.

Olivier Berger: Debian Package Tracking System now produces RDF description of source packages

Here s a second post on the subject of RDF descriptions for Debian source packages (see the previous post for some context). From now on, the Debian Package Tracking System (PTS) will produce, alongside HTML pages meant for humans, RDF pages meant for Linked Data / Semantic Web aware applications. Every Debian source package, which used to have an HTML page like http://packages.qa.debian.org/packagename now has a corresponding RDF/XML document available provided that the application/rdf+xml content-type is required (the HTTP client being redirected to the proper HTML or RDF document).

The main objective is to try and produce (closest as possible from the source, at debian.org) an authoritative description of Debian s packages in an interoperable format (RDF using the ADMS.SW 1.0 ontology). Thus, each package in Debian can be identified on the Semantic Web with a unique URI like http://packages.qa.debian.org/apache2, which is dereferenceable as RDF. Here s a graph representing the resources included in http://packages.qa.debian.org/apache2 (click on the image to load it) :
You can see an example of such an RDF representation for the apache2 source package in trying (with the raptor2-utils package installed):

$ rapper -o turtle http://packages.qa.debian.org/apache2
If you prefer more visual/navigatable versions, use one of the Linked Data browsers referenced in wikipedia or see the output of the W3C RDF validator. For more details about the underlying format see a raw RDF/XML dump :

$ curl -L -v -H 'Accept: application/rdf+xml' http://packages.qa.debian.org/apache2
Any Semantic Web application can then reference that resource, which becomes part of the Linked Open Data cloud. There are probably lots of uses that could emerge from this, but the immediate I can think of is the matching of Debian packages with other packages/projects (upstream, downstream, other dists) in an interoperable way (see other projects like distromatch, etc.). At the moment, the doap:homepage of the upstream SoftwareProject resources generated by the PTS can be such a simple matching key (it s actually much more complex than that, but will be the topic of further efforts). AFAICT, this is the first large deployment of an ADMS.SW 1.0 implementation. On my machine, I ve counted almost 1.5 million triples generated. Stay tuned for more installments on similar topics.

John Goerzen: Kindergarten Computer Class and Password Security

Jacob started Kindergarten last week. More on that in another post. He s been loving it, until yesterday. At least part of his disgruntlement was because it was his first visit to computer class. Putting together a few conversations, we learned this:
Jacob: Something was different about Kindergarten today. Us: Oh? What was it? Jacob: I had computer class today. Us: What did you do? Jacob, super frustrated: Nothing. NOTHING, NOTHING, NOOOO THIIING. Nothing. Us: You didn t get to use a computer? Jacob: All we did was log on and log off the whole time. Log on and log off. My username is Jacob and my password is Jacob. (annoyed and confused voice) Why are they the same??
I guess his teachers weren t used to children that had been logging on to computers for two years before Kindergarten. And probably also weren t expecting any of them to take some sort of offense at their password poicy. He probably couldn t appreciate how reasonable it was to tech Kindergarteners how to log in to a computer on the first day of computer class

Russell Coker: Woolworths Maths Fail

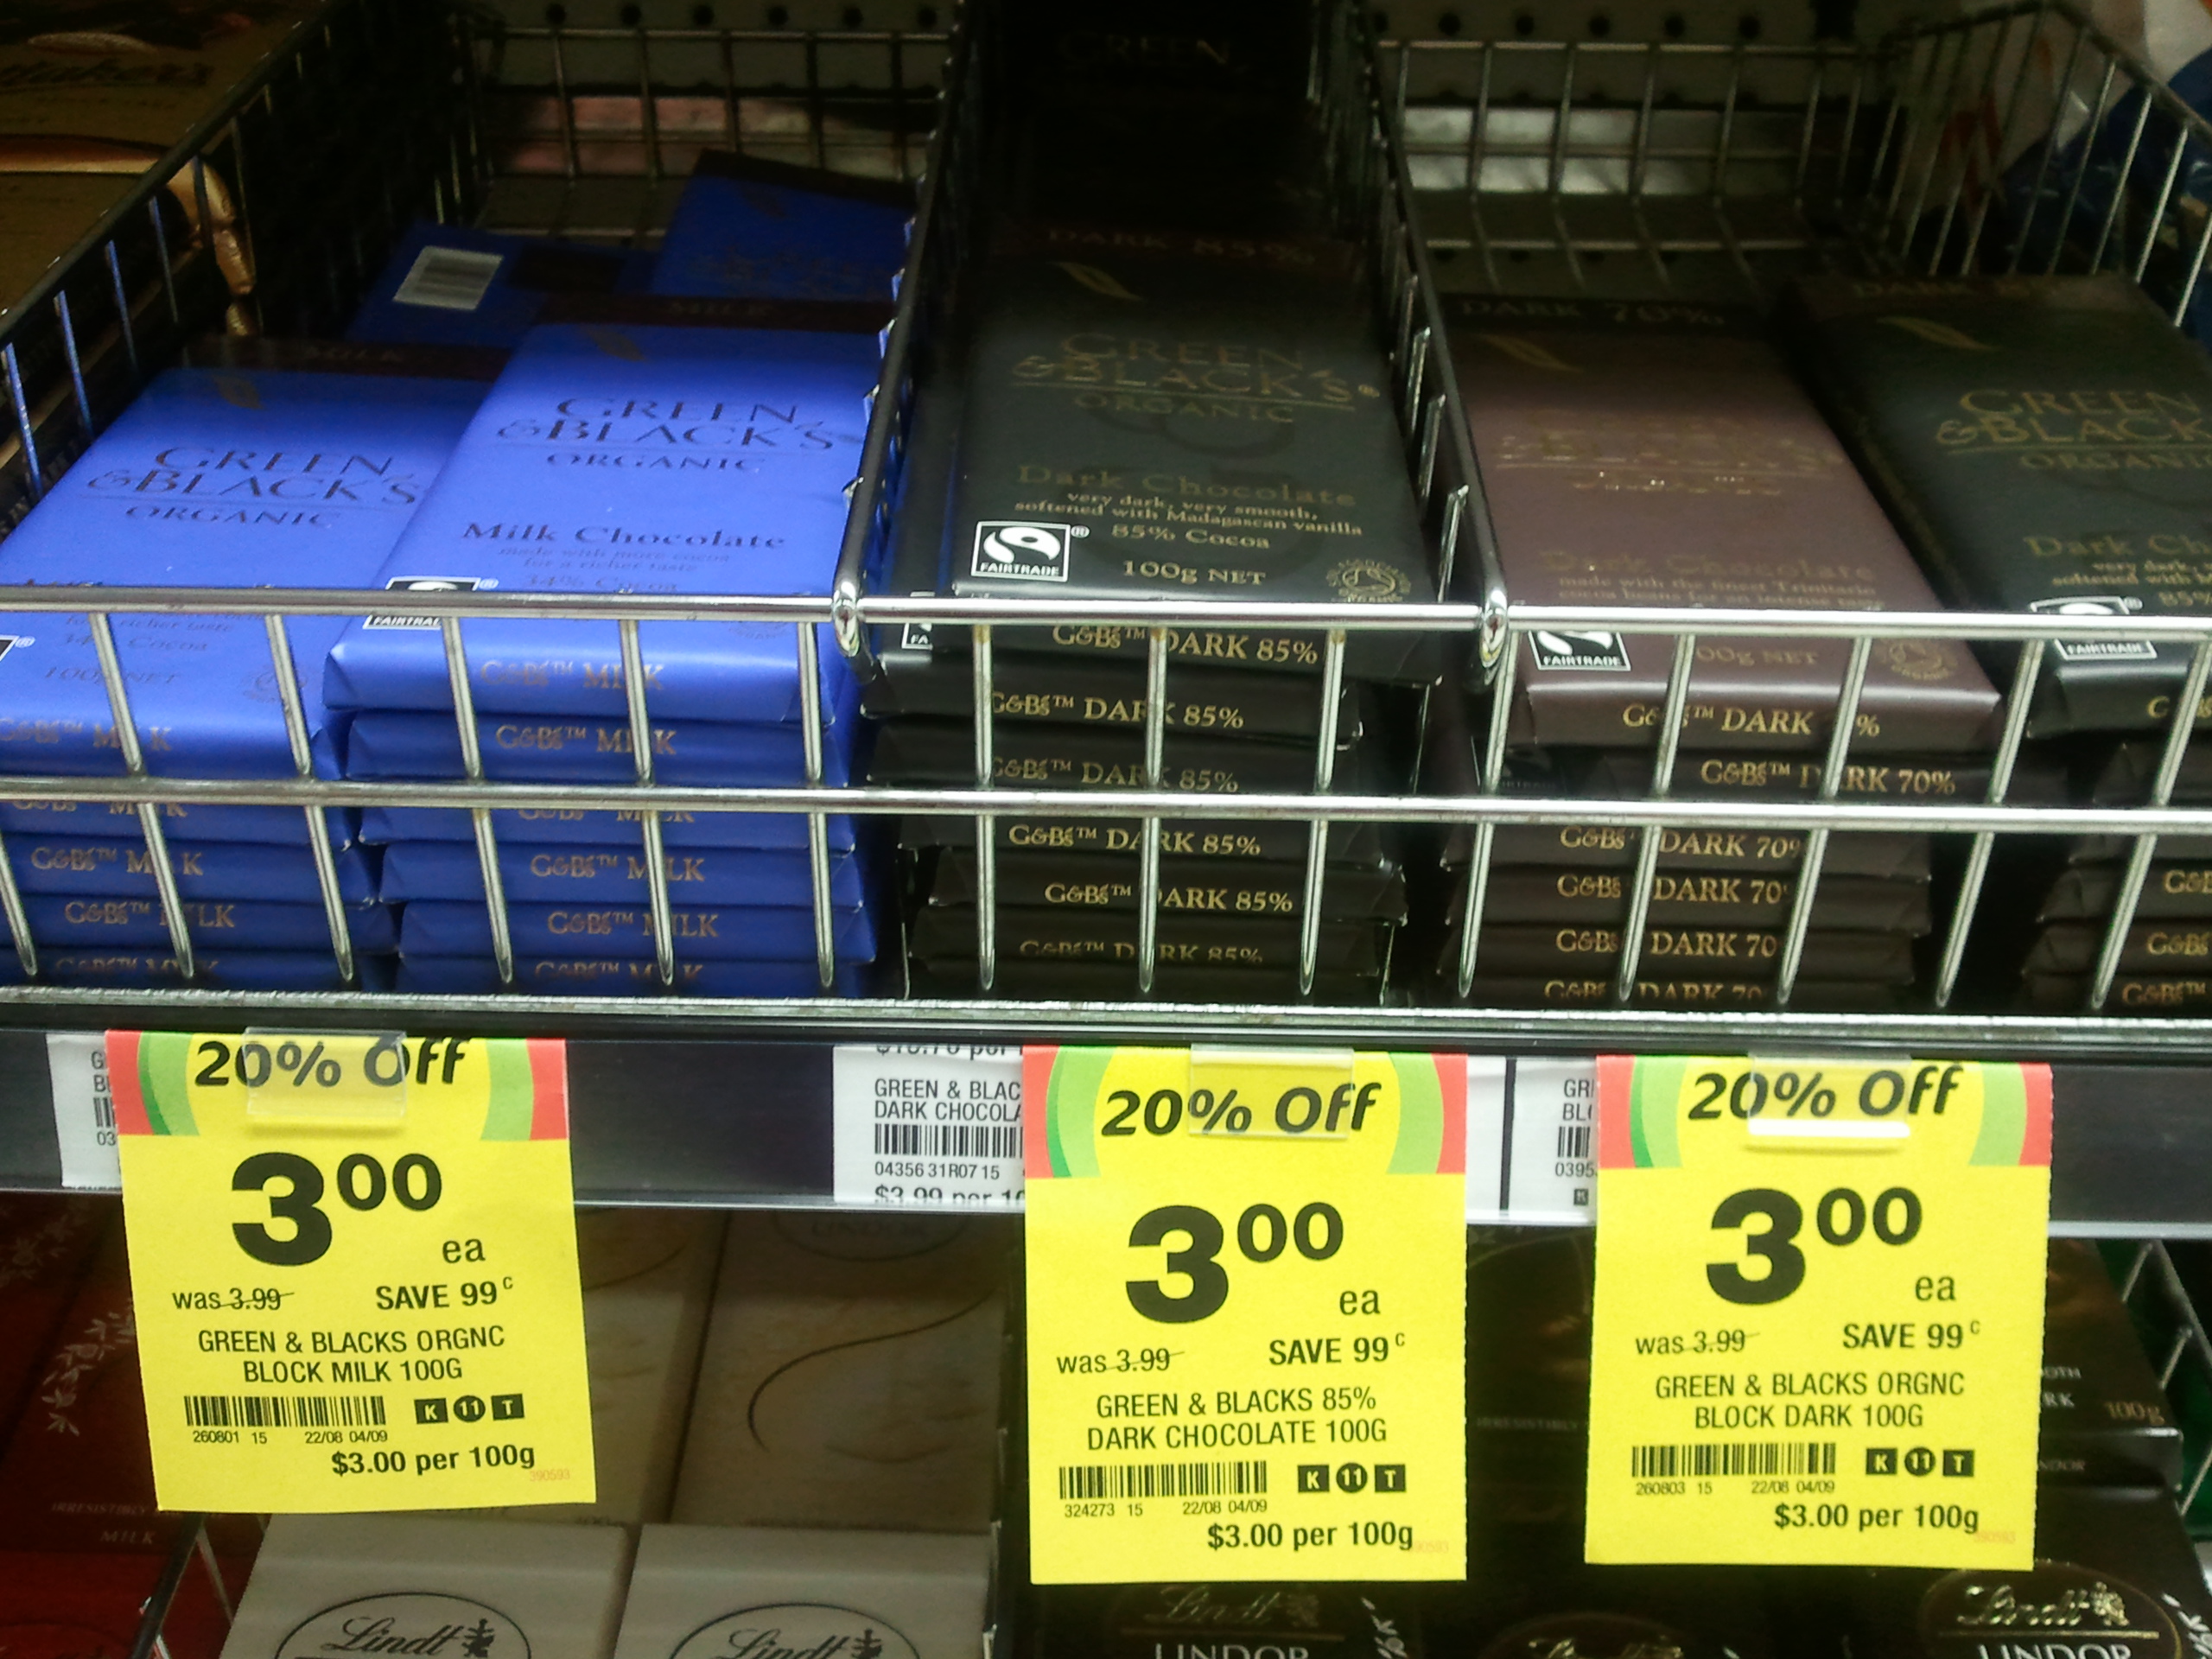
picture of discount from $3.99 to $3.00 advertised as 20% off The above is a picture of the chocolate display at Woolworths, an Australian supermarket that was formerly known as Safeway it had the same logo as the US Safeway so there s probably a connection. This is actually a 24.81% discount. It s possible that some people might consider it a legal issue to advertise something as a 25% discount when it s 1 cent short of that (even though we haven t had a coin smaller than 5 cents in Australia since 1991). But then if they wanted to advertise a discount percentage that s a multiple of 5% they could have made the discount price $2.99, presumably whatever factors made them make the original price $3.99 instead of $4.00 would also apply when choosing a discount price. So the question is, do Woolworths have a strict policy of rounding down discount rates to the nearest 5% or do they just employ people who failed maths in high school? Sometimes when discussing education people ask rhetorical questions such as when would someone use calculus in real life , I think that the best answer is people who have studied calculus probably won t write such stupid signs . Sure the claimed discount is technically correct as they don t say no more than 20% off and not misleading in a legal sense (it s OK to claim less than you provide), but it s annoyingly wrong. Well educated people don t do that sort of thing. As an aside, the chocolate in question is Green and Black, that s a premium chocolate line that is Fair Trade, Organic, and very tasty. If you are in Australia then I recommend buying some because $3.00 is a good price. Related posts:
  1. fair trade is the Linux way I have recently purchased a large quantity of fair trade...
  2. LUG Meetings etc Recently I was talking to an employee at Safeway (an...
  3. The Sad State of Shopping in Australia Paul Wayper has written a blog post criticising the main...

28 August 2012

David Welton: Small Town Google Pollution

There are so many sites trying to vie for Google results for any and every town in existance in the United States that they are crowding out useful information. They get their list of towns from census data or similar sources, and generate pages for every single entry they find, no matter how small. During the weekend, I was poking around, looking for information on a not-quite-ghost town called Lonerock, in Oregon:
http://en.wikipedia.org/wiki/Lonerock,_Oregon

I love to visit out of the way places like that when I'm back in Oregon, which we hope to do next summer. So I was curious about it - it appears quite isolated, but seems like it might be worth a look. According to the Wikipedia article it is a very small town, with a population of 24 people. And yet, if you look at the Google results for it, you find a few good links at first, and then: And so on and so forth. Scattered in the middle, you can even find a few articles and photo pages by people who actually had something to say or show about the place, but finding them amidst all the crud is not an easy task. To me this seems surprising - it doesn't seem like it'd be that hard to make sites that just happen to have entries for every town in the entire nation rank a bit lower than things written by human beings. Google - have a look at Lonerock, and see if you can use it as a way to seperate the wheat from the chaff!

Russell Coker: SSD for a Workstation

SSDs have been dropping in price recently so I just bought four Intel 120G devices for $115 each. I installed the first one for my mother in law who had been complaining about system performance. Her system boot time went from 90 seconds to 20 seconds and a KDE login went from about 35 seconds to about 10 seconds. The real problem that she had reported was occasional excessive application delay, while it wasn t possible to diagnose that properly I think it was a combination of her MUA doing synchronous writes while other programs such as Chromium were doing things. To avoid the possibility of a CPU performance problem I replaced her 1.8GHz E4300 system with a 2.66GHz E7300 that I got from a junk pile (it s amazing what s discarded nowadays). I also installed a SSD in my own workstation (a 2.4GHz E4600). The boot time went down from 45s on Ext4 without an encrypted root to 27s with root on BTRFS including the time taken to enter the encryption password (maybe about 23s excluding my typing time). The improvement wasn t as great, but that s because my workstation does some things on bootup that aren t dependent on disk IO such as enabling a bridge with STP (making every workstation a bridge is quieter than using switches). KDE login went from about 27s to about 12s and the time taken to start Chromium and have it be usable (rather than blocking on disk IO) went from 30 seconds to an almost instant response (maybe a few seconds)! Tests on another system indicates that Chromium startup could be improved a lot by purging history, but I don t want to do that. It s unfortunate that Chromium only supports deleting recent history (to remove incriminating entries) but doesn t support deleting ancient history that just isn t useful. I didn t try to seriously benchmark the SSD (changing from Ext4 to BTRFS on my system would significantly reduce the accuracy of the results), I have plans for doing that on more important workloads in the near future. For the moment the most casual tests have shown a significant performance benefit so it s clear that an SSD is the correct storage option for any new workstation which doesn t need more than 120G of storage space. $115 for SSD vs $35 for HDD is a fairly easy choice for a new system. For larger storage the price of hard drives increases more slowly than that of SSD. In spite of the performance benefits I doubt that I will gain a real benefit from this in the next year. The time taken to install the SSD equates to dozens of boot cycles which given a typical workstation uptime in excess of a month is unlikely to happen soon. One minor benefit is that deleting messages in Kmail is an instant operation which saves a little annoyance and there will be other occasional benefits. One significant extra benefit is that an SSD is quiet and dissipates less heat which might allow the system cooling fans to run more slowly. As noisy computers annoy me an SSD is a luxury feature. Also it s good to test new technologies that my clients may need. The next thing on my todo list is to do some tests of ZFS with SSD for L2ARC and ZIL. Related posts:
  1. How I Partition Disks Having had a number of hard drives fail over the...
  2. Xen and Swap The way Xen works is that the RAM used by...
  3. big and cheap USB flash devices It s often the case with technology that serious changes occur...

Next.

Previous.