Search Results: "xam"

24 March 2020

Dirk Eddelbuettel: New package RcppDate 0.0.1 now on CRAN!

A new small package with a new C++ header library is now on CRAN. It brings the date library by Howard Hinnant to R. This library has been in pretty wide-spread use for a while now, and adds to C++11/C++14/C++17 what will be (with minor modifications) the date library in C++20. I had been aware of it for a while, but not needed thanks to CCTZ library out of Google and our RcppCCTZ package. And like CCTZ, it builds upon std::chron adding a whole lot of functionality and useability enhancement. But a some upcoming (and quite exciting!) changes in nanotime required it, I had a reason to set about packaging it as RcppDate. And after a few days of gestation and review it is now available via CRAN. Two simple example files are included and can be accessed by Rcpp::sourceCpp(). Some brief excerpts follow. The first example shows three date constructors. Note how the month (and the leading digits) are literals. No quotes for strings anywhere. And no format (just like our anytime package for R).
  constexpr auto x1 = 2015_y/March/22;
  constexpr auto x2 = March/22/2015;
  constexpr auto x3 = 22_d/March/2015;
Note that these are constexpr that resolve at compile-time, and that the resulting year_month_day type is inferred via auto. A second example constructs the last day of the months similarly:
  constexpr auto x1 = 2015_y/February/last;
  constexpr auto x2 = February/last/2015;
  constexpr auto x3 = last/February/2015;
For more, see the copious date.h documentation. The (very bland first) NEWS entry (from a since-added NEWS file) for the initial upload follows.

Changes in version 0.0.1 (2020-01-17)
  • Initial CRAN upload of first version

If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Christoph Berg: Announcing apt-archive.postgresql.org

Users had often asked where they could find older versions of packages from apt.postgresql.org. I had been collecting these since about April 2013, and in July 2016, I made the packages available via an ad-hoc URL on the repository master host, called "the morgue". There was little repository structure, all files belonging to a source package were stuffed into a single directory, no matter what distribution they belonged to. Besides this not being particularly accessible for users, the main problem was the ever-increasing need for more disk space on the repository host. We are now at 175 GB for the archive, of which 152 GB is for the morgue. Our friends from yum.postgresql.org have had a proper archive host (yum-archive.postgresql.org) for some time already, so it was about time to follow suit and implement a proper archive for apt.postgresql.org as well, usable from apt. So here it is: apt-archive.postgresql.org The archive covers all past and current Debian and Ubuntu distributions. The apt sources.lists entries are similar to the main repository, just with "-archive" appended to the host name and the distribution:
deb https://apt-archive.postgresql.org/pub/repos/apt DIST-pgdg-archive main
deb-src https://apt-archive.postgresql.org/pub/repos/apt DIST-pgdg-archive main
The oldest PostgreSQL server versions covered there are 8.2.23, 8.3.23, 8.4.17, 9.0.13, 9.1.9, 9.2.4, 9.3beta1, and everything newer. Some example:
$ apt-cache policy postgresql-12
postgresql-12:
  Installed: 12.2-2.pgdg+1+b1
  Candidate: 12.2-2.pgdg+1+b1
  Version table:
 *** 12.2-2.pgdg+1+b1 900
        500 http://apt.postgresql.org/pub/repos/apt sid-pgdg/main amd64 Packages
        500 https://apt-archive.postgresql.org/pub/repos/apt sid-pgdg-archive/main amd64 Packages
        100 /var/lib/dpkg/status
     12.2-2.pgdg+1 500
        500 https://apt-archive.postgresql.org/pub/repos/apt sid-pgdg-archive/main amd64 Packages
     12.2-1.pgdg+1 500
        500 https://apt-archive.postgresql.org/pub/repos/apt sid-pgdg-archive/main amd64 Packages
     12.1-2.pgdg+1 500
        500 https://apt-archive.postgresql.org/pub/repos/apt sid-pgdg-archive/main amd64 Packages
     12.1-1.pgdg+1 500
        500 https://apt-archive.postgresql.org/pub/repos/apt sid-pgdg-archive/main amd64 Packages
     12.0-2.pgdg+1 500
        500 https://apt-archive.postgresql.org/pub/repos/apt sid-pgdg-archive/main amd64 Packages
     12.0-1.pgdg+1 500
        500 https://apt-archive.postgresql.org/pub/repos/apt sid-pgdg-archive/main amd64 Packages
     12~rc1-1.pgdg+1 500
        500 https://apt-archive.postgresql.org/pub/repos/apt sid-pgdg-archive/main amd64 Packages
     12~beta4-1.pgdg+1 500
        500 https://apt-archive.postgresql.org/pub/repos/apt sid-pgdg-archive/main amd64 Packages
     12~beta3-1.pgdg+1 500
        500 https://apt-archive.postgresql.org/pub/repos/apt sid-pgdg-archive/main amd64 Packages
     12~beta2-1.pgdg+1 500
        500 https://apt-archive.postgresql.org/pub/repos/apt sid-pgdg-archive/main amd64 Packages
     12~beta1-1.pgdg+1 500
        500 https://apt-archive.postgresql.org/pub/repos/apt sid-pgdg-archive/main amd64 Packages
Because this is hosted on S3, browsing directories is only supported indirectly by static index.html files, so if you want to look at some specific URL, append "/index.html" to see it. The archive is powered by a PostgreSQL database and a bunch of python/shell scripts, from which the apt index files are built. Archiving old distributions I'm also using the opportunity to remove some long-retired distributions from the main repository host. The following distributions have been moved over: They are available as "DIST-pgdg" from the archive, e.g. squeeze:
deb https://apt-archive.postgresql.org/pub/repos/apt squeeze-pgdg main
deb-src https://apt-archive.postgresql.org/pub/repos/apt squeeze-pgdg main

Anisa Kuci: Outreachy post 5 - Final report

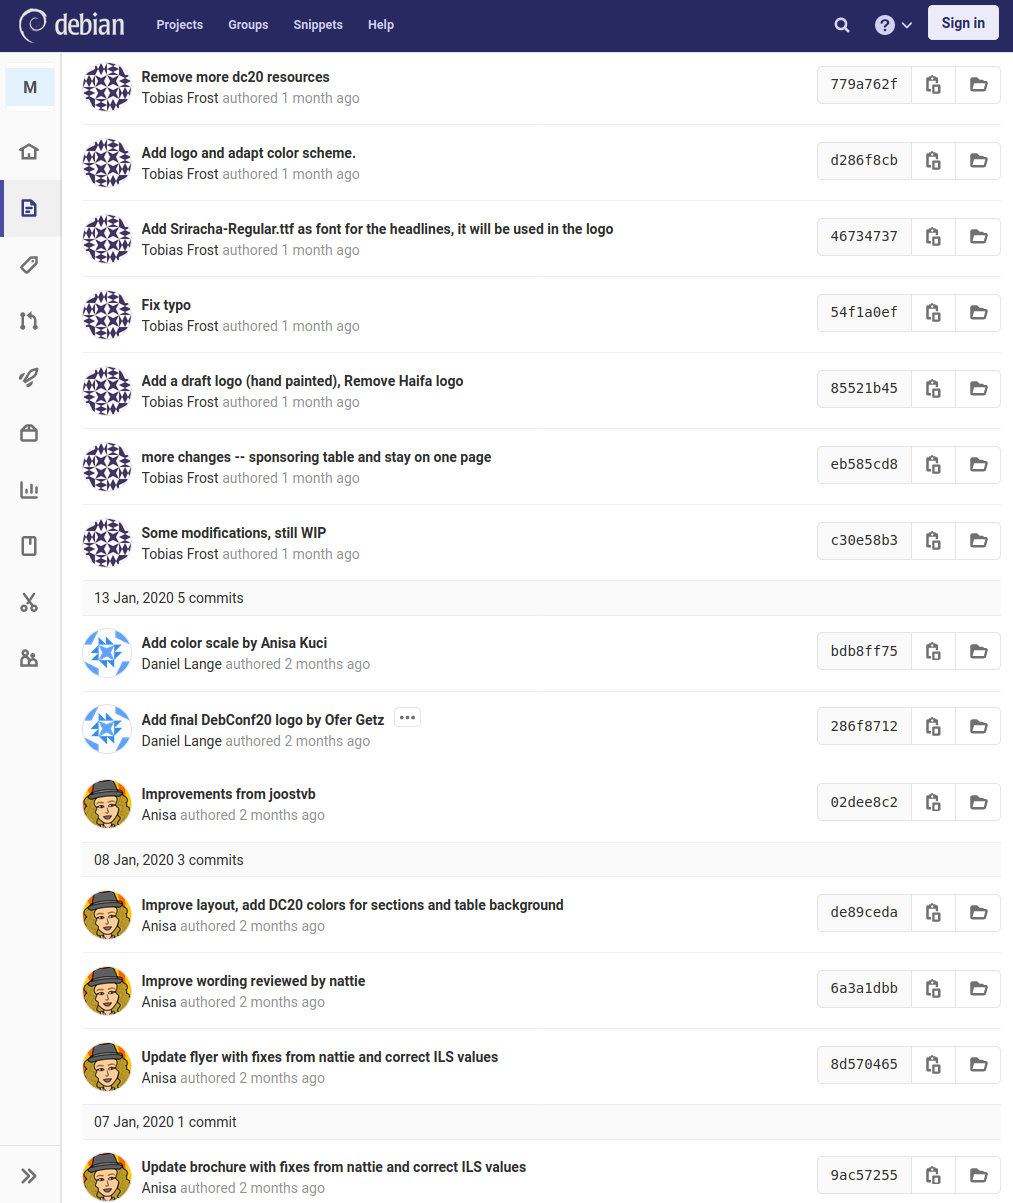
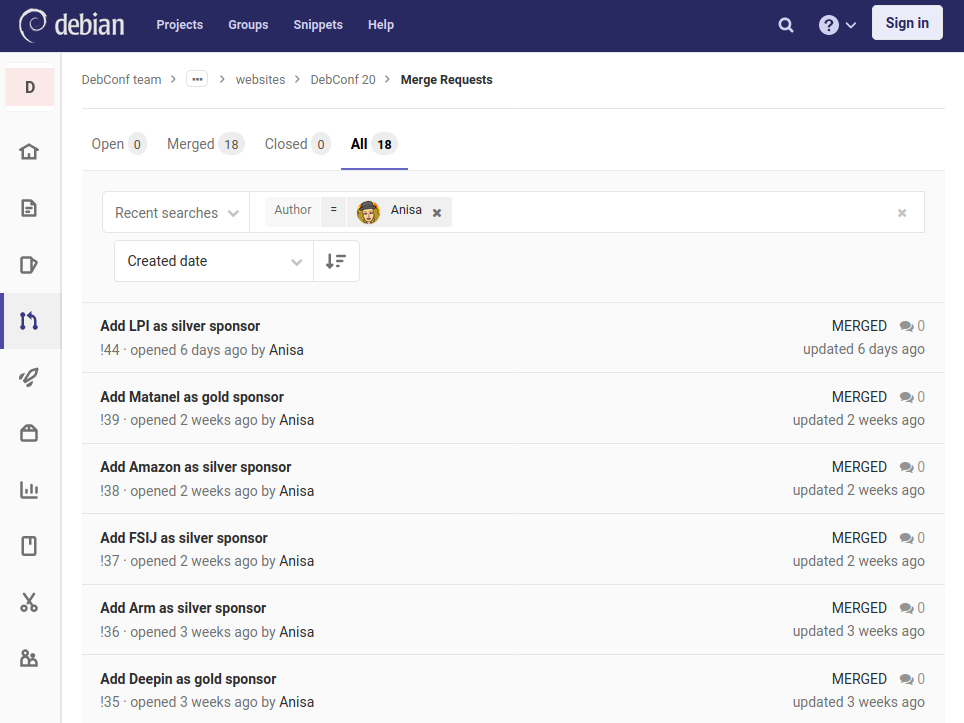
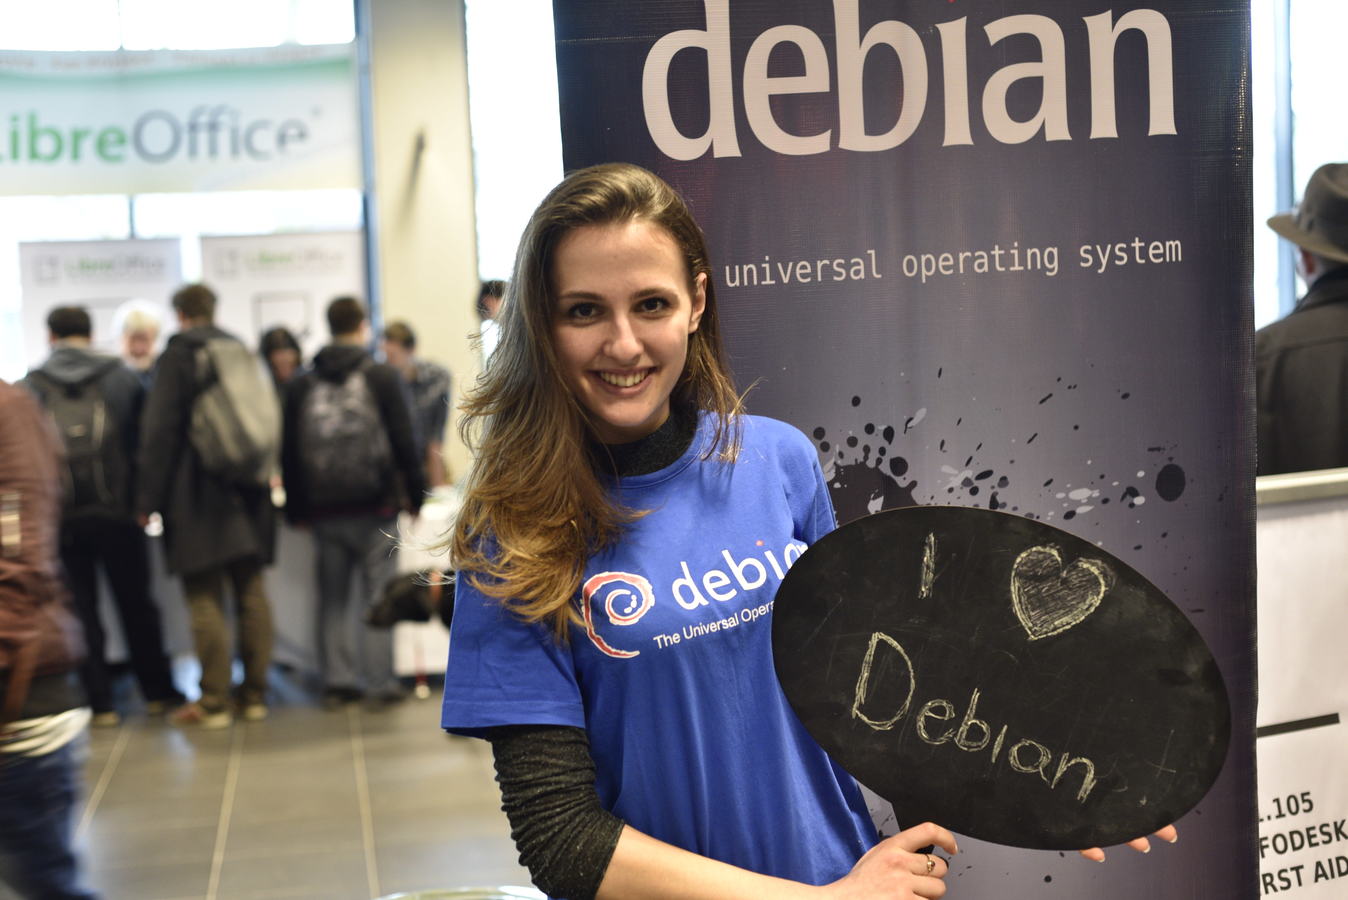
This is my last Outreachy blogpost, as my internship unfortunately has come to an end. It was a blast! Through the Outreachy internship I gained a lot of valuable knowledge and even though I dont know what the future will bring, I am more confident about myself, my skills in fundraising and my technical abilities now. During the contribution phase I did quite a lot of research so I could come up with relevant information to add on the Debian wiki as part of the contribution phase tasks. This was helpful for me to build a more deep understanding of the Debian project, the DebConf conferences and the general style of working within Debian. During this phase I completed most of the tasks given and got onto the mailing lists and IRC channels which are public. This was quite an intense experience by itself as it was like digging into a new job but in a competitive situation as other applicants, of course, were also putting in their best to get one of the 50 Outreachy internships (two in Debian) that were available. When I got selected I also got access to the sponsors@debconf.org email address and the private git repos as they would be needed for me to work on fundraising. I was also provided with an @debconf.org email address that is the one I use for sponsors communication. I learned what makes communication look professional and how to think of the recipient when formulating emails, sending replies or creating marketing messages. As the internship continued I started to learn how the DebConf organizing structure works, with a particular attention on the fundraising team. I have also quickly been given the responsibility to reach out to 100 potential sponsors and combine learning and working experience very nicely. I was given responsibility of working on the fundraising material (flyer and brochure) for DebConf20, so using LaTeX I updated the files in order to remove the translation system, I added the Israeli currency and the visual design chosen from a public logo proposal contest that is held for each DebConf. My creative side could also be put to good use as the team trusted me with selecting the images for the brochure and making sure that the usage rights granted and attribution are all compliant to Free Software/Creative Commons licences. I have continuously maintained those materials and was very happy that long term team members even asked me to approve changes they proposed on the fundraising material. The MiniDebConf team for Regensburg have taken the files I created and made them into their fundraising material (brochure, flyer) which is great to see. MiniDebConf Regensburg commits I have profited so much from other people s work, so I am very happy if community members can build on mine. Afterall sharing is caring! Through the Outreachy travel stipend I was able to attend FOSDEM 2020 and besides meeting many friends from the community and having a fundraising meeting with a sponsor, I was able to also support distributing the DebConf20 fundraising material both in electronic form and as printed versions. During the Outreachy internship I did two communication waves to potential sponsors and maintained the daily communication with them. I followed the documentation that was already available in the Debian wiki guiding me through the process of invoicing sponsors through the organizations that Debian collaborates with. As I have been in frequent contact with the sponsors, I have continuously updated the DebConf20 website with sponsor logos and links through git files, improving web pages on the wafer system and doing 18 merge requests in total. DebConf20 website merge requests I completed six email templates for the DebConf sponsor communication campaigns. While two of them have already been very useful, I hope my other proposals will be the ones used for the next waves of sponsors contacting. I committed them to the sponsors git repo so they can be easily accessible and well documented for other DebConf teams or can be recycled for smaller Debian events. Unfortunately, due to the insecurity about travel around the Corona virus pandemic, the third wave of communication, originally scheduled for the end of my internship in March, has been held. I have committed to the team to do this once the travel restrictions have been lifted and we know that DebConf20 can proceed as planned for August 2020. So yeah, I am definitely going to stay around and continue to help with DebConf fundraising! DebConf has been held for two decades and it also has a generic website, so I also updated the static sponsors page on the main website as it is the first landing page for everyone especially for people who are not necessarily insiders in Debian or DebConf. I have completed a Python tutorial, got the general understanding of the programming language and made some smaller contributions to improve existing tools in the fundraising team based on the learning. The internship was also focused on documentation, so during the whole internship I have kept notes in order to be able to improve existing documentation and I have also written new material, especially on the tasks that I have been working on more closely: Every DebConf has a new team every year, in a new country, so I hope this documentation I have worked on will be useful as a jump-starter for them to organize and finance their events. I would like to take a moment to thank again my mentors Daniel and Karina for all their support, it has been great working with them. Having them as an example, I have learned a lot. Also warm thanks to the DebConf global and local teams which have been very welcoming and always supportive during my internship. So, as you might already know, if you have read my other Outreachy blog posts, this has been a great experience for me! Outreachy provides an awesome opportunity that would not be available if it was not for the generous sponsors and volunteers making such a program for people from underrepresented groups in the FLOSS community. I really encourage people from these groups to find the confidence within themselves and apply for Outreachy! I love Debian

22 March 2020

Sylvestre Ledru: Some clang rebuild results (8.0.1, 9.0.1 & 10rc2)

As part of the LLVM release cycle, I am continuing rebuilding the Debian archive with clang instead of gcc to evaluate potential regressions. Processed results are available on the website: https://clang.debian.net/status.php - Now includes some fancy graphs to show the evolution
Raw logs are published on github: https://github.com/opencollab/clang.debian.net/tree/master/logs Since my last blog post on the subject (August 2017), Clang is more and more present in the tech ecosystem. It is now the compiler used to build Firefox and Chrome upstream binaries on all the supported architectures/operating systems. More architectures are supported, it has a new linker (lld), a new hybrid IR (MLIR), a lot of checkers in clang-tidy, cross-language linking with Rust, etc.

Results
Now, about Debian results, we rebuilt using 8.0.1, 9.0.1 and 10.0rc2. Results are pretty similar to what we had with previous versions: between 4 to 5% of packages are failing when gcc is replaced by clang.
Some clang rebuild results (8.0.1, 9.0.1 & 10rc2)

Even if most of the software are still using gcc as compiler, we can see that clang has a positive effect on code quality. With many different kinds of errors and warnings found clang over the years, we noticed a steady decline of the number of errors. For example, the number of incorrect C/C++ main declarations has been decreasing years after years:
Some clang rebuild results (8.0.1, 9.0.1 & 10rc2)

Errors found
The biggest offender is still the qmake changes which doesn't allow the used workaround (replacing /usr/bin/gcc by /usr/bin/clang) - about 250 errors. Most of these packages would probably compile fine with clang. More on the Qt bug tracker. The workaround proposed in the bug isn't applicable for us as we use the dropped-in replacement of the
The second error is still some differences in symbol generation. Unlike gcc, it seems that clang doesn't generate some symbols (or adds some). As a bunch of Debian packages are checking the list of symbols in the library (for ABI management), the build fails on purpose. For example, with libcec, the symbol _ZN10P8PLATFORM14CConditionImplD1Ev@Base 3.1.0 isn't generated anymore. I am not expecting this to be a big deal: the generated libraries probably works most of the time. More on C++ symbol management in Debian.

Current status
As previously said in a blog post, I don't think there is a strong intensive to go away from gcc for most of the Linux distributions. The big reason for BSD was the license (even if the move to the Apache 2 license wasn't received positively by some of them).
While the LLVM/clang ecosystem clearly won the tooling battle, as a C/C++ compiler, gcc is still an excellent compiler which supports more architecture and more languages.
In term of new warnings and checks, as the clang community moved the efforts in clang-tidy (which requires more complex tooling), out of the box, gcc provides a better experience (as example, see the Firefox meta bug to build with -Werror with the default warnings using gcc 9, gcc 10 and clang trunk for example).

Next steps
I see some potential next steps to decrease the number of failure:
  • Workaround the Qt/Qmake issue
  • Fix the objective-c header include issues (echo "#include <objc/objc.h>" > foo.m && clang -c foo.m is currently failing)
  • Identify why clang generates more/less symbols that gcc in the library and try to fix that
  • Rebuild the archive with clang-7 - Seems that I have some data problem

Many thanks to Lucas Nussbaum for the rebuilds.

Sylvestre Ledru: Some clang rebuild results (8.0.1, 9.0.1 & 10rc2)

As part of the LLVM release cycle, I am continuing rebuilding the Debian archive with clang instead of gcc to evaluate potential regressions. Processed results are available on the website: https://clang.debian.net/status.php - Now includes some fancy graphs to show the evolution
Raw logs are published on github: https://github.com/opencollab/clang.debian.net/tree/master/logs Since my last blog post on the subject (August 2017), Clang is more and more present in the tech ecosystem. It is now the compiler used to build Firefox and Chrome upstream binaries on all the supported architectures/operating systems. More architectures are supported, it has a new linker (lld), a new hybrid IR (MLIR), a lot of checkers in clang-tidy, cross-language linking with Rust, etc.

Results
Now, about Debian results, we rebuilt using 8.0.1, 9.0.1 and 10.0rc2. Results are pretty similar to what we had with previous versions: between 4 to 5% of packages are failing when gcc is replaced by clang.
Some clang rebuild results (8.0.1, 9.0.1 &amp; 10rc2)

Even if most of the software are still using gcc as compiler, we can see that clang has a positive effect on code quality. With many different kinds of errors and warnings found clang over the years, we noticed a steady decline of the number of errors. For example, the number of incorrect C/C++ main declarations has been decreasing years after years:
Some clang rebuild results (8.0.1, 9.0.1 &amp; 10rc2)

Errors found
The biggest offender is still the qmake changes which doesn't allow the used workaround (replacing /usr/bin/gcc by /usr/bin/clang) - about 250 errors. Most of these packages would probably compile fine with clang. More on the Qt bug tracker. The workaround proposed in the bug isn't applicable for us as we use the dropped-in replacement of the compiler.
The second error is still some differences in symbol generation. Unlike gcc, it seems that clang doesn't generate some symbols (or adds some). As a bunch of Debian packages are checking the list of symbols in the library (for ABI management), the build fails on purpose. For example, with libcec, the symbol _ZN10P8PLATFORM14CConditionImplD1Ev@Base 3.1.0 isn't generated anymore. I am not expecting this to be a big deal: the generated libraries probably works most of the time. More on C++ symbol management in Debian.
I reported this bug upstream a while back: https://bugs.llvm.org/show_bug.cgi?id=30441

Current status
As previously said in a blog post, I don't think there is a strong intensive to go away from gcc for most of the Linux distributions. The big reason for BSD was the license (even if the move to the Apache 2 license wasn't received positively by some of them).
While the LLVM/clang ecosystem clearly won the tooling battle, as a C/C++ compiler, gcc is still an excellent compiler which supports more architecture and more languages.
In term of new warnings and checks, as the clang community moved the efforts in clang-tidy (which requires more complex tooling), out of the box, gcc provides a better experience (as example, see the Firefox meta bug to build with -Werror with the default warnings using gcc 9, gcc 10 and clang trunk for example).

Next steps
I see some potential next steps to decrease the number of failure:
  • Workaround the Qt/Qmake issue
  • Fix the objective-c header include issues (echo "#include <objc/objc.h>" > foo.m && clang -c foo.m is currently failing)
  • Identify why clang generates more/less symbols that gcc in the library and try to fix that
  • Rebuild the archive with clang-7 - Seems that I have some data problem

Many thanks to Lucas Nussbaum for the rebuilds.

18 March 2020

Dirk Eddelbuettel: RcppCCTZ 0.2.7

A new release 0.2.7 of RcppCCTZ is now at CRAN. RcppCCTZ uses Rcpp to bring CCTZ to R. CCTZ is a C++ library for translating between absolute and civil times using the rules of a time zone. In fact, it is two libraries. One for dealing with civil time: human-readable dates and times, and one for converting between between absolute and civil times via time zones. And while CCTZ is made by Google(rs), it is not an official Google product. The RcppCCTZ page has a few usage examples and details. This package was the first CRAN package to use CCTZ; by now at least three others do using copies in their packages which remains less than ideal. This version adds internal extensions, contributed by Leonardo, which support upcoming changes to the nanotime package we are working on.

Changes in version 0.2.7 (2020-03-18)
  • Added functions _RcppCCTZ_convertToCivilSecond that converts a time point to the number of seconds since epoch, and _RcppCCTZ_convertToTimePoint that converts a number of seconds since epoch into a time point; these functions are only callable from C level (Leonardo in #34 and #35).
  • Added function _RcppCCTZ_getOffset that returns the offset at a speficied time-point for a specified timezone; this function is only callable from C level (Leonardo in #32).

We also have a diff to the previous version thanks to CRANberries. More details are at the RcppCCTZ page; code, issue tickets etc at the GitHub repository. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Antoine Beaupr : How can I trust this git repository?

Join me in the rabbit hole of git repository verification, and how we could improve it.

Problem statement As part of my work on automating install procedures at Tor, I ended up doing things like:
git clone REPO
./REPO/bootstrap.sh
... something eerily similar to the infamous curl pipe bash method which I often decry. As a short-term workaround, I relied on the SHA-1 checksum of the repository to make sure I have the right code, by running this both on a "trusted" (ie. "local") repository and the remote, then visually comparing the output:
$ git show-ref master
9f9a9d70dd1f1e84dec69a12ebc536c1f05aed1c refs/heads/master
One problem with this approach is that SHA-1 is now considered as flawed as MD5 so it can't be used as an authentication mechanism anymore. It's also fundamentally difficult to compare hashes for humans. The other flaw with comparing local and remote checksums is that we assume we trust the local repository. But how can I trust that repository? I can either:
  1. audit all the code present and all the changes done to it after
  2. or trust someone else to do so
The first option here is not practical in most cases. In this specific use case, I have audited the source code -- I'm the author, even -- what I need is to transfer that code over to another server. (Note that I am replacing those procedures with Fabric, which makes this use case moot for now as the trust path narrows to "trust the SSH server" which I already had anyways. But it's still important for my fellow Tor developers who worry about trusting the git server, especially now that we're moving to GitLab.) But anyways, in most cases, I do need to trust some other fellow developer I collaborate with. To do this, I would need to trust the entire chain between me and them:
  1. the git client
  2. the operating system
  3. the hardware
  4. the network (HTTPS and the CA cartel, specifically)
  5. then the hosting provider (and that hardware/software stack)
  6. and then backwards all the way back to that other person's computer
I want to shorten that chain as much as possible, make it "peer to peer", so to speak. Concretely, it would eliminate the hosting provider and the network, as attackers.

OpenPGP verification My first reaction is (perhaps perversely) to "use OpenPGP" for this. I figured that if I sign every commit, then I can just check the latest commit and see if the signature is good. The first problem here is that this is surprisingly hard. Let's pick some arbitrary commit I did recently:
commit b3c538898b0ed4e31da27fc9ca22cb55e1de0000
Author: Antoine Beaupr  <anarcat@debian.org>
Date:   Mon Mar 16 14:37:28 2020 -0400
    fix test autoloading
    pytest only looks for file names matching  test  by default. We inline
    tests inside the source code directly, so hijack that.
diff --git a/fabric_tpa/pytest.ini b/fabric_tpa/pytest.ini
new file mode 100644
index 0000000..71004ea
--- /dev/null
+++ b/fabric_tpa/pytest.ini
@@ -0,0 +1,3 @@
+[pytest]
+# we inline tests directly in the source code
+python_files = *.py
That's the output of git log -p in my local repository. I signed that commit, yet git log is not telling me anything special. To check the signature, I need something special: --show-signature, which looks like this:
commit b3c538898b0ed4e31da27fc9ca22cb55e1de0000
gpg: Signature faite le lun 16 mar 2020 14:37:53 EDT
gpg:                avec la clef RSA 7B164204D096723B019635AB3EA1DDDDB261D97B
gpg: Bonne signature de  Antoine Beaupr  <anarcat@orangeseeds.org>  [ultime]
gpg:                 alias  Antoine Beaupr  <anarcat@torproject.org>  [ultime]
gpg:                 alias  Antoine Beaupr  <anarcat@anarc.at>  [ultime]
gpg:                 alias  Antoine Beaupr  <anarcat@koumbit.org>  [ultime]
gpg:                 alias  Antoine Beaupr  <anarcat@debian.org>  [ultime]
Author: Antoine Beaupr  <anarcat@debian.org>
Date:   Mon Mar 16 14:37:28 2020 -0400
    fix test autoloading
    pytest only looks for file names matching  test  by default. We inline
    tests inside the source code directly, so hijack that.
Can you tell if this is a valid signature? If you speak a little french, maybe you can! But even if you would, you are unlikely to see that output on your own computer. What you would see instead is:
commit b3c538898b0ed4e31da27fc9ca22cb55e1de0000
gpg: Signature made Mon Mar 16 14:37:53 2020 EDT
gpg:                using RSA key 7B164204D096723B019635AB3EA1DDDDB261D97B
gpg: Can't check signature: No public key
Author: Antoine Beaupr  <anarcat@debian.org>
Date:   Mon Mar 16 14:37:28 2020 -0400
    fix test autoloading
    pytest only looks for file names matching  test  by default. We inline
    tests inside the source code directly, so hijack that.
Important part: Can't check signature: No public key. No public key. Because of course you would see that. Why would you have my key lying around, unless you're me. Or, to put it another way, why would that server I'm installing from scratch have a copy of my OpenPGP certificate? Because I'm a Debian developer, my key is actually part of the 800 keys in the debian-keyring package, signed by the APT repositories. So I have a trust path. But that won't work for someone who is not a Debian developer. It will also stop working when my key expires in that repository, as it already has on Debian buster (current stable). So I can't assume I have a trust path there either. One could work with a trusted keyring like we do in the Tor and Debian project, and only work inside that project, that said. But I still feel uncomfortable with those commands. Both git log and git show will happily succeed (return code 0 in the shell) even though the signature verification failed on the commits. Same with git pull and git merge, which will happily push your branch ahead even if the remote has unsigned or badly signed commits. To actually verify commits (or tags), you need the git verify-commit (or git verify-tag) command, which seems to do the right thing:
$ LANG=C.UTF-8 git verify-commit b3c538898b0ed4e31da27fc9ca22cb55e1de0000
gpg: Signature made Mon Mar 16 14:37:53 2020 EDT
gpg:                using RSA key 7B164204D096723B019635AB3EA1DDDDB261D97B
gpg: Can't check signature: No public key
[1]$
At least it fails with some error code (1, above). But it's not flexible: I can't use it to verify that a "trusted" developer (say one that is in a trusted keyring) signed a given commit. Also, it is not clear what a failure means. Is a signature by an expired certificate okay? What if the key is signed by some random key in my personal keyring? Why should that be trusted?

Worrying about git and GnuPG In general, I'm worried about git's implementation of OpenPGP signatures. There has been numerous cases of interoperability problems with GnuPG specifically that led to security, like EFAIL or SigSpoof. It would be surprising if such a vulnerability did not exist in git. Even if git did everything "just right" (which I have myself found impossible to do when writing code that talks with GnuPG), what does it actually verify? The commit's SHA-1 checksum? The tree's checksum? The entire archive as a zip file? I would bet it signs the commit's SHA-1 sum, but I just don't know, on the top of my head, and neither do git-commit or git-verify-commit say exactly what is happening. I had an interesting conversation with a fellow Debian developer (dkg) about this and we had to admit those limitations:
<anarcat> i'd like to integrate pgp signing into tor's coding practices more, but so far, my approach has been "sign commits" and the verify step was "TBD" <dkg> that's the main reason i've been reluctant to sign git commits. i haven't heard anyone offer a better subsequent step. if torproject could outline something useful, then i'd be less averse to the practice. i'm also pretty sad that git remains stuck on sha1, esp. given the recent demonstrations. all the fancy strong signatures you can make in git won't matter if the underlying git repo gets changed out from under the signature due to sha1's weakness
In other words, even if git implements the arcane GnuPG dialect just so, and would allow us to setup the trust chain just right, and would give us meaningful and workable error messages, it still would fail because it's still stuck in SHA-1. There is work underway to fix that, but in February 2020, Jonathan Corbet described that work as being in a "relatively unstable state", which is hardly something I would like to trust to verify code. Also, when you clone a fresh new repository, you might get an entirely different repository, with a different root and set of commits. The concept of "validity" of a commit, in itself, is hard to establish in this case, because an hostile server could put you backwards in time, on a different branch, or even on an entirely different repository. Git will warn you about a different repository root with warning: no common commits but that's easy to miss. And complete branch switches, rebases and resets from upstream are hardly more noticeable: only a tiny plus sign (+) instead of a star (*) will tell you that a reset happened, along with a warning (forced update) on the same line. Miss those and your git history can be compromised.

Possible ways forward I don't consider the current implementation of OpenPGP signatures in git to be sufficient. Maybe, eventually, it will mature away from SHA-1 and the interface will be more reasonable, but I don't see that happening in the short term. So what do we do?

git evtag The git-evtag extension is a replacement for git tag -s. It's not designed to sign commits (it only verifies tags) but at least it uses a stronger algorithm (SHA-512) to checksum the tree, and will include everything in that tree, including blobs. If that sounds expensive to you, don't worry too much: it takes about 5 seconds to tag the Linux kernel, according to the author. Unfortunately, that checksum is then signed with GnuPG, in a manner similar to git itself, in that it exposes GnuPG output (which can be confusing) and is likely similarly vulnerable to mis-implementation of the GnuPG dialect as git itself. It also does not allow you to specify a keyring to verify against, so you need to trust GnuPG to make sense of the garbage that lives in your personal keyring (and, trust me, it doesn't). And besides, git-evtag is fundamentally the same as signed git tags: checksum everything and sign with GnuPG. The difference is it uses SHA-512 instead of SHA-1, but that's something git will eventually fix itself anyways.

kernel patch attestations The kernel also faces this problem. Linus Torvalds signs the releases with GnuPG, but patches fly all over mailing list without any form of verification apart from clear-text email. So Konstantin Ryabitsev has proposed a new protocol to sign git patches which uses SHA256 to checksum the patch metadata, commit message and the patch itself, and then sign that with GnuPG. It's unclear to me what this solves, if anything, at all. As dkg argues, it would seem better to add OpenPGP support to git-send-email and teach git tools to recognize that (e.g. git-am) at least if you're going to keep using OpenPGP anyways. And furthermore, it doesn't resolve the problems associated with verifying a full archive either, as it only attests "patches".

jcat Unhappy with the current state of affairs, the author of fwupd (Richard Hughes) wrote his own protocol as well, called jcat, which provides signed "catalog files" similar to the ones provided in Microsoft windows. It consists of a "gzip-compressed JSON catalog files, which can be used to store GPG, PKCS-7 and SHA-256 checksums for each file". So yes, it is yet again another wrapper to GnuPG, probably with all the flaws detailed above, on top of being a niche implementation, disconnected from git.

The Update Framework One more thing dkg correctly identified is:
<dkg> anarcat: even if you could do exactly what you describe, there are still some interesting wrinkles that i think would be problems for you. the big one: "git repo's latest commits" is a loophole big enough to drive a truck through. if your adversary controls that repo, then they get to decide which commits to include in the repo. (since every git repo is a view into the same git repo, just some have more commits than others)
In other words, unless you have a repository that has frequent commits (either because of activity or by a bot generating fake commits), you have to rely on the central server to decide what "the latest version" is. This is the kind of problems that binary package distribution systems like APT and TUF solve correctly. Unfortunately, those don't apply to source code distribution, at least not in git form: TUF only deals with "repositories" and binary packages, and APT only deals with binary packages and source tarballs. That said, there's actually no reason why git could not support the TUF specification. Maybe TUF could be the solution to ensure end-to-end cryptographic integrity of the source code itself. OpenPGP-signed tarballs are nice, and signed git tags can be useful, but from my experience, a lot of OpenPGP (or, more accurately, GnuPG) derived tools are brittle and do not offer clear guarantees, and definitely not to the level that TUF tries to address. This would require changes on the git servers and clients, but I think it would be worth it.

Other Projects

OpenBSD There are other tools trying to do parts of what GnuPG is doing, for example minisign and OpenBSD's signify. But they do not integrate with git at all right now. Although I did find a hack] to use signify with git, it's kind of gross...

Golang Unsurprisingly, this is a problem everyone is trying to solve. Golang is planning on hosting a notary which would leverage a "certificate-transparency-style tamper-proof log" which would be ran by Google (see the spec for details). But that doesn't resolve the "evil server" attack, if we treat Google as an adversary (and we should).

Python Python had OpenPGP going for a while on PyPI, but it's unclear if it ever did anything at all. Now the plan seems to be to use TUF but my hunch is that the complexity of the specification is keeping that from moving ahead.

Docker Docker and the container ecosystem has, in theory, moved to TUF in the form of Notary, "a project that allows anyone to have trust over arbitrary collections of data". In practice however, in my somewhat limited experience, setting up TUF and image verification in Docker is far from trivial.

Android and iOS Even in what is possibly one of the strongest models (at least in terms of user friendliness), mobile phones are surprisingly unclear about those kind of questions. I had to ask if Android had end-to-end authentication and I am still not clear on the answer. I have no idea of what iOS does.

Conclusion One of the core problems with everything here is the common usability aspect of cryptography, and specifically the usability of verification procedures. We have become pretty good at encryption. The harder part (and a requirement for proper encryption) is verification. It seems that problem still remains unsolved, in terms of usability. Even Signal, widely considered to be a success in terms of adoption and usability, doesn't properly solve that problem, as users regularly ignore "The security number has changed" warnings... So, even though they deserve a lot of credit in other areas, it seems unlikely that hardcore C hackers (e.g. git and kernel developers) will be able to resolve that problem without at least a little bit of help. And TUF seems like the state of the art specification around here, it would seem wise to start adopting it in the git community as well. Update: git 2.26 introduced a new gpg.minTrustLevel to "tell various signature verification codepaths the required minimum trust level", presumably to control how Git will treat keys in your keyrings, assuming the "trust database" is valid and up to date. For an interesting narrative of how "normal" (without PGP) git verification can fail, see also A Git Horror Story: Repository Integrity With Signed Commits.

16 March 2020

Matthias Klumpp: Maintain release info easily in MetaInfo/Appdata files

This article isn t about anything new , like the previous ones on AppStream it rather exists to shine the spotlight on a feature I feel is underutilized. From conversations it appears that the reason simply is that people don t know that it exists, and of course that s a pretty bad reason not to make your life easier  Mini-Disclaimer: I ll be talking about appstreamcli, part of AppStream, in this blogpost exclusively. The appstream-util tool from the appstream-glib project has a similar functionality check out its help text and look for appdata-to-news if you are interested in using it instead. What is this about? AppStream permits software to add release information to their MetaInfo files to describe current and upcoming releases. This feature has the following advantages: The disadvantage of all this, is that humans have to maintain the release information. Also, people need to write XML for this. Of course, once humans are involved with any technology, things get a lot more complicated. That doesn t mean we can t make things easier for people to use though. Did you know that you don t actually have to edit the XML in order to update your release information? To make creating and maintaining release information as easy as possible, the appstreamcli utility has a few helpers built in. And the best thing is that appstreamcli, being part of AppStream, is available pretty ubiquitously on Linux distributions. Update release information from NEWS data The NEWS file is a not very well defined textfile that lists user-visible changes worth mentioning per each version. This maps pretty well to what AppStream release information should contain, so let s generate that from a NEWS file! Since the news format is not defined, but we need to parse this somehow, the amount of things appstreamcli can parse is very limited. We support a format in this style:
Version 0.2.0
~~~~~~~~~~~~~~
Released: 2020-03-14
Notes:
 * Important thing 1
 * Important thing 2
Features:
 * New/changed feature 1
 * New/changed feature 2 (Author Name)
 * ...
Bugfixes:
 * Bugfix 1
 * Bugfix 2
 * ...
Version 0.1.0
~~~~~~~~~~~~~~
Released: 2020-01-10
Features:
 * ...
When parsing a file like this, appstreamcli will allow a lot of errors/ imperfections and account for quite a few style and string variations. You will need to check whether this format works for you. You can see it in use in appstream itself and libxmlb for a slightly different style. So, how do you convert this? We first create our NEWS file, e.g. with this content:
Version 0.2.0
~~~~~~~~~~~~~~
Released: 2020-03-14
Bugfixes:
 * The CPU no longer overheats when you hold down spacebar
Version 0.1.0
~~~~~~~~~~~~~~
Released: 2020-01-10
Features:
 * Now plays a "zap" sound on every character input
For the MetaInfo file, we of course generate one using the MetaInfo Creator. Then we can run the following command to get a preview of the generated file: appstreamcli news-to-metainfo ./NEWS ./org.example.myapp.metainfo.xml - Note the single dash at the end this is the explicit way of telling appstreamcli to print something to stdout. This is how the result looks like:
<?xml version="1.0" encoding="utf-8"?>
<component type="desktop-application">
  [...]
  <releases>
    <release type="stable" version="0.2.0" date="2020-03-14T00:00:00Z">
      <description>
        <p>This release fixes the following bug:</p>
        <ul>
          <li>The CPU no longer overheats when you hold down spacebar</li>
        </ul>
      </description>
    </release>
    <release type="stable" version="0.1.0" date="2020-01-10T00:00:00Z">
      <description>
        <p>This release adds the following features:</p>
        <ul>
          <li>Now plays a "zap" sound on every character input</li>
        </ul>
      </description>
    </release>
  </releases>
</component>
Neat! If we want to save this to a file instead, we just exchange the dash with a filename. And maybe we don t want to add all releases of the past decade to the final XML? No problem too, just pass the --limit flag as well: appstreamcli news-to-metainfo --limit=6 ./NEWS ./org.example.myapp.metainfo.tmpl.xml ./result/org.example.myapp.metainfo.xml That s nice on its own, but we really don t want to do this by hand The best way to ensure the MetaInfo file is updated, is to simply run this command at build time to generate the final MetaInfo file. For the Meson build system you can achieve this with a code snippet like below (but for CMake this shouldn t be an issue either you could even make a nice macro for it there):
ascli_exe = find_program('appstreamcli')
metainfo_with_relinfo = custom_target('gen-metainfo-rel',
    input : ['./NEWS', 'org.example.myapp.metainfo.xml'],
    output : ['org.example.myapp.metainfo.xml'],
    command : [ascli_exe, 'news-to-metainfo', '--limit=6', '@INPUT0@', '@INPUT1@', '@OUTPUT@']
)
In order to also translate releases, you will need to add this to your .pot file generation workflow, so (x)gettext can run on the MetaInfo file with translations merged in. Release information from YAML files Since parsing a no structure, somewhat human-readable file is hard without baking an AI into appstreamcli, there is also a second option available: Generate the XML from a YAML file. YAML is easy to write for humans, but can also be parsed by machines.The YAML structure used here is specific to AppStream, but somewhat maps to the NEWS file contents as well as MetaInfo file data. That makes it more versatile, but in order to use it, you will need to opt into using YAML for writing news entries. If that s okay for you to consider, read on! A YAML release file has this structure:
---
Version: 0.2.0
Date: 2020-03-14
Type: development
Description:
- The CPU no longer overheats when you hold down spacebar
- Fixed bugs ABC and DEF
---
Version: 0.1.0
Date: 2020-01-10
Description:  -
  This is our first release!
  Now plays a "zap" sound on every character input
As you can see, the release date has to be an ISO 8601 string, just like it is assumed for NEWS files. Unlike in NEWS files, releases can be defined as either stable or development depending on whether they are a stable or development release, by specifying a Type field. If no Type field is present, stable is implicitly assumed. Each release has a description, which can either be a free-form multi-paragraph text, or a list of entries. Converting the YAML example from above is as easy as using the exact same command that was used before for plain NEWS files: appstreamcli news-to-metainfo --limit=6 ./NEWS.yml ./org.example.myapp.metainfo.tmpl.xml ./result/org.example.myapp.metainfo.xml If appstreamcli fails to autodetect the format, you can help it by specifying it explicitly via the --format=yaml flag. This command would produce the following result:
<?xml version="1.0" encoding="utf-8"?>
<component type="console-application">
  [...]
  <releases>
    <release type="development" version="0.2.0" date="2020-03-14T00:00:00Z">
      <description>
        <ul>
          <li>The CPU no longer overheats when you hold down spacebar</li>
          <li>Fixed bugs ABC and DEF</li>
        </ul>
      </description>
    </release>
    <release type="stable" version="0.1.0" date="2020-01-10T00:00:00Z">
      <description>
        <p>This is our first release!</p>
        <p>Now plays a "zap" sound on every character input</p>
      </description>
    </release>
  </releases>
</component>
Note that the 0.2.0 release is now marked as development release, a thing which was not possible in the plain text NEWS file before. Going the other way Maybe you like writing XML, or have some other tool that generates the MetaInfo XML, or you have received your release information from some other source and want to convert it into text. AppStream also has a tool for that! Using appstreamcli metainfo-to-news <metainfo-file> <news-file> you can convert a MetaInfo file that has release entries into a text representation. If you don t want appstreamcli to autodetect the right format, you can specify it via the --format=<text yaml> switch. Future considerations The release handling is still not something I am entirely happy with. For example, the release information has to be written and translated at release time of the application. For some projects, this workflow isn t practical. That s why issue #240 exists in AppStream which basically requests an option to have release notes split out to a separate, remote location (and also translations, but that s unlikely to happen). Having remote release information is something that will highly likely happen in some way, but implementing this will be a quite disruptive, if not breaking change. That is why I am holding this change back for the AppStream 1.0 release. In the meanwhile, besides improving the XML form of release information, I also hope to support a few more NEWS text styles if they can be autodetected. The format of the systemd project may be a good candidate. The YAML release-notes format variant will also receive a few enhancements, e.g. for specifying a release URL. For all of these things, I very much welcome pull requests or issue reports. I can implement and maintain the things I use myself best, so if I don t use something or don t know about a feature many people want I won t suddenly implement it or start to add features at random because they may be useful . That would be a recipe for disaster. This is why for these features in particular contributions from people who are using them in their own projects or want their new usecase represented are very welcome.

Ulrike Uhlig: Deconstructing the term control freak

Control freaks. You may have called people like this. Or you may have been called one yourself. Maybe you got angry. Or, on the contrary, you felt like being a control freak is a feature, because who would notice all these little details that are not exactly perfect if not you? This post is an attempt to deconstruct the term. Etymological considerations Control - from latin contra- rotulus - refers to the copy of an account register as a means of verification of the original register. So control is about keeping track, not making mistakes, i.e. it's about doing a perfect calculation. The meaning of control in our society is linked to authority, or to policing like in crowd control. What English calls an inspector, is a Kontrolleur in German or contr leur in French. The word is also linked to manufacturing, as in quality control. We also talk about being in control, which is linked to the desire of being autonomous, to be able to act on one's own account. Being in control can also designate a need to preserve one's own integrity: if I have integrity (in the sense of feeling whole), I can self-determine, which is the most fundamental requirement for having one's own identity. Freak - refers to someone who does not fit the norm. Calling someone a freak is per se problematic, because it blames a person for being atypical, abnormal. Freak is a word that, while pointing a finger at difference, at the same time denies people the right to be different and diverse. People can reappropriate such words to make it clear that not fitting the norm is a wanted expression of their diversity we can see that if we follow the history of the word queer for an example. Types of control freaking To me, being a control freak is mostly a feature, if it's about controlling my own life and my own effectiveness. Control freaking becomes troublesome when it's about controlling other people's effectiveness. And it becomes highly problematic when it's about controlling other people's lives. Controlling one's own life Having control over one's own life is a basic human need. In particular people who are part of minorities, people who face discrimination and oppression every day have an increased need for self-determination, and the need to see their existence and their identity acknowledged and accepted by the rest of the world. Too often do we experience that other people (generally the ones with privilege, or not facing the same oppression) try to own the narrative over our lives (1)(2). Calling this control freakish is missing the point, and is probably a sign of looking at it from a perspective of privilege. Controlling one's own effectiveness People produce things. People write code, make ceramics, or write texts, for example. People have a need to control their own effectiveness: they set up routines, product tests, documentation. This type of control is a feature, and can help to release better software, better texts, or perfectly burnt clay pots ultimately controlling one's own effectiveness helps to learn from one's mistakes and to improve routines over time. The grey zone The grey zone describes the zone in between wanting to control one's own effectiveness and wanting to control other people's effectiveness. Here we could situate the type of control freak who does not delegate tasks to others for fear of seeing them done differently then they had expected them to be done. This can be harmful particularly to the person who does not delegate: they can get overworked or burnt out. This type of control freakism might be linked to perfectionism. Controlling other people's effectiveness When we work with other people, our own effectiveness might get in the way of other people's effectiveness, or vice versa. Indeed, it happens - not only in work contexts - that people find themselves in setups in which mutual responsibilities and autonomies conflict with one another because one person is dependent on the other for making decisions or moving things forward as they see fit. (There is generally a relation of dependency between two conflicting parties that is worth looking at (3).) Add to this the fact that, when delegating a task, some people have a hard time also delegating the responsibility and autonomy needed to resolve the task. They lack trust that another person can also do the work, or want that person to do the work exactly in the same way they would do it. (In some cases this can be related to Founder's Syndrome and can result in organizations staying stuck with one or a small group of founders holding knowledge and power, and preventing the organization from growing. Page 11 in the booklet "Working with conflict in our groups" describes how such an informal hierarchy can come into being in grassroot groups.) The (perfectly valid) need behind this type of control freaking could be to make sure that a group of people builds a successful product, releases a fact-checked documentary, or creates a publication without mistakes. But controlling other people's effectiveness as a strategy to satisfy this need can create a non-cooperative climate in which people do not meet each other on eye level, but are dependent on each other, experience a lack autonomy, a break of boundaries, or sometimes feel authority to be overexerted. Acknowledging the need to build a good product, it is possible to create the appropriate strategies to guarantee that the involved people can meet each other on eye level: for example by clearly defining and documenting role-responsibility-accountability along with appropriate decision making processes, or by distributing leadership ( you should totally click on that link!), by looking at inclusive leadership models, by learning from past mistakes, by instating feedback cycles, by making boundaries between the direction of an organization and the day-to-day work clear. An organization I work with has the rule that people can make decisions for themselves if the decision only affects their work, while decisions that affect a team should be made with the team, and decisions that affect the organization as a whole need to be made at the organizational level. They call that a no-brainer, but in organizations with traditional hierarchies, or in grown grassroot environments that have never clearly defined and assigned responsibilities and accountabilities (aka "functional roles") this is not so obvious at all. Controlling someone else's life This type of control freak does not only desire to control their own life but for a reason or another wants to know and control what other people do, think (especially about the control freak), decide, or how they live. In some cases, this type of control freak might even want to force upon others things they should do as a way to be accepted by the control freak. It's what we call narcissism, harassment, abuse. It is unacceptable. Conclusion In summary, the distinctions I came up with in this post describe the boundaries along which control freakism takes hold of someone else's effectiveness or life and ultimately prevents them from self-determining. In German we have the word bergriffig which describes that someone is infringing someone else's boundaries they are over - grabbing, seizing, grasping, taking hold of. Which type of control freak are you, if any?

(1) Like when a West-Berliner in a round of 15 East Germans arrogantly talks about the time when the wall came down and tells the story that he could not go shopping between Thursdays and Sundays because the East Germans bought too many products in the supermarkets while this event marked an unimaginable rift in the biographies of 17 million East Germans, 15 of whom are sitting right in front of him. Thirty years after 1989, many of us are finally starting to question this publicly ( links in German language).

(2) Women experience it similary regularly, see Men Explain Things to me, a book by Rebecca Solnit.

(3) By the way, rather than having "recruited the wrong person" conflict may intrinsically arise as part of certain work relationships, simply due to the inter-dependencies of roles or workers, like in a delivery chain.

15 March 2020

Enrico Zini: News and politics links

Theresa Kachindamoto - Wikipedia
empowerment people politics archive.org
Theresa Kachindamoto is the paramount chief, or Inkosi, of the Dedza District in the central region of Malawi. She has informal authority over more than 900,000 people. She is known for her forceful action in dissolving child marriages and insisting on education for both girls and boys.
Daryl Davis is no ordinary musician. He s played with President Clinton and tours the country playing burnin boogie woogie piano and sharing musical stylings inspired by greats like Fats Domino, Chuck Berry and Jerry Lee Lewis. He s a highly respected and electrifying performer who is currently an integral member of The Legendary Blues Band (formerly
An undercover tracking program is revealing the toll of the e-waste trade.
The .io country code top-level domain is pretty popular right now, particularly among tech startups that want to take advantage of the snappy input/output reference and the relative availability of names Fusion.io, Wise.io and Import.io are just a few examples. But who benefits from the sale of .io domains? Sadly, not the people who ultimately should.
FDA ban brings an end to decades-long battle against use of aversive therapy at the Judge Rotenberg Center in Massachusetts

Dima Kogan: numpysane and broadcasting in C

Since the beginning, the numpysane library provided a broadcast_define() function to decorate existing Python routines to give them broadcasting awareness. This was very useful, but slow. I just did lots of typing, and now I have a flavor of this in C (the numpysane_pywrap module; new in numpysane 0.22). As expected, you get fast C loops! And similar to the rest of this library, this is a port of something in PDL: PDL::PP. Full documentation lives here: https://github.com/dkogan/numpysane/blob/master/README-pywrap.org After writing this I realized that there was something similar available in numpy this whole time: https://docs.scipy.org/doc/numpy/reference/c-api.generalized-ufuncs.html I haven't looked too deeply into this yet, but 2 things are clear: There's a design difference: the numpy implementation uses function callbacks, while I generate C code. Code generation is what PDL::PP does, and when I thought about it earlier, it seemed like doing this with function pointers would be too painful. I guess it's doable, though. And at least in one case, the gufuncs aren't doing the right broadcasting thing:
>>> a = np.arange(5).reshape(5,1)
>>> b = np.arange(3)
>>> np.matmul(a,b)
ValueError: matmul: Input operand 1 has a mismatch in
   its core dimension 0, with gufunc signature
   (n?,k),(k,m?)->(n?,m?) (size 3 is different from 1)
This should work. And if you do this with numpysane.broadcast_define() or with numpysane_pywrap, it does work. I'll look at it later to figure out what it's doing.

14 March 2020

John Goerzen: It Doesn t Take Much to Make Someone s Day

In times like these, it is natural to fear. Viruses, incompetent leadership, economic hardship, even death. But remember this:
When I was a boy and I would see scary things in the news, my mother would say to me, Look for the helpers. You will always find people who are helping. To this day, especially in times of disaster, I remember my mother s words, and I am always comforted by realizing that there are still so many helpers so many caring people in this world. Fred Rogers
This is so true. The examples are everywhere. Here in the United States, our federal government has been weak responding to COVID-19 but others have stepped up. Institutions big and small across the country are following the science and closing or taking other steps to slow the spread of coronavirus, even in areas it hasn t yet been detected, because this is the right thing to do. People are helping their neighbors, or giving up their favorite activities to do their part to slow the spread of COVID-19. I work for a company that s publicly-traded on the NYSE, and it shut down all its offices globally. And kept paying the janitors and other office staff. Some people are in a vulnerable place today. To them: remember the helpers. There are doctors and nurses, officials, neighbors the care, everywhere. To those that are able: be a helper. It doesn t take much to brighten someone s day. Maybe a phone call or video call. Maybe delivering groceries to a neighbor that s quarantined. Maybe acts of grace and understanding to the stressed people around you, trying their best to get by in the face of a lack of information and certainty. Maybe giving up some activities you enjoy, in order to help slow the spread of COVID-19, even if you personally aren t especially vulnerable. I am reminded of this quote, part of a story about a dying cancer patient: Don t forget that it doesn t take much to make someone s day.

Dirk Eddelbuettel: RcppAPT 0.0.6

A new version of RcppAPT our interface from R to the C++ library behind the awesome apt, apt-get, apt-cache, commands and their cache powering Debian, Ubuntu and the like is now on CRAN. RcppAPT allows you to query the (Debian or Ubuntu) package dependency graph at will, with build-dependencies (if you have deb-src entries), reverse dependencies, and all other goodies. See the vignette and examples for illustrations. This new version corrects builds failures under the new and shiny Apt 2.0 release (and the pre-releases like the 1.9.* series in Ubuntu) as some header files moved around. My thanks to Kurt Hornik for the heads-up. I accomodated the change in the (very simple and shell-based) configure script by a) asking pkg-config about the version of pkg-apt and then using that to b) compare to a threshold value of 1.9.0 and c) setting another compiler #define if needed so that d) these headers could get included if defined. The neat part is that a) and b) are done in an R one-liner, and the whole script is still in shell. Now, CRAN being CRAN, I now split the script into two: one almost empty one not using bash that passes the omg but bash is not portable test, and which calls a second bash script doing the work. Fun and games The full set of changes follows.

Changes in version 0.0.6 (2020-03-14)
  • Accomodate Apt 2.0 code changes by including more header files
  • Change is backwards compatible and conditional
  • Added configure call using pkg-config and package version comparison (using R) to determine if the define is needed
  • Softened unit tests as we cannot assume optional source deb information to be present, so demo code runs but zero results tolerated

Courtesy of CRANberries, there is also a diffstat report for this release. A bit more information about the package is available here as well as as the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

12 March 2020

Dirk Eddelbuettel: RInside 0.2.16

A new release 0.2.16 of RInside arrived on CRAN and in Debian today. This comes almost exactly one year after the previous release 0.2.15. RInside provides a set of convenience classes which facilitate embedding of R inside of C++ applications and programs, using the classes and functions provided by Rcpp. This release brings one new feature, contributed by Lance Bachmeier (with some additional post-processing by me). It adds the ability to embed and call R from C programs and applications. The interface is more limited as we do not get Rcpp for automagic conversion. But this offers the door to a number of applications supporting plain C interface, and the new examples directory for example shows one for ruby. We may add others. The short list of changes since the last release were:

Changes in RInside version 0.2.16 (2020-03-12)
  • RInside is now embeddable (with a reduced interface) from C applications thanks to Lance Bachmeier (who is now co-author) plus some polish by Dirk in #43)
  • Added R_SESSION_INIIALIZED to list of excluded variables.
  • Added simple diagnostics function to have a registered function.

CRANberries also provides a short report with changes from the previous release. More information is on the RInside page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page, or to issues tickets at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Julien Danjou: One year of Mergify

One year of MergifyIt has been close to a year now that I've incorporated my new company, Mergify. I've been busy, and I barely wrote anything about it so far. Now is an excellent time to take a break and reflect a bit on what happened during those last 12 months.
One year of Mergify

What problem does Mergify solve?Mergify is a powerful automation engine for GitHub pull requests. It allows you to automate everything and especially merging. You write rules, and it handles the rest.
One year of MergifyExample of rule matching returned in GitHub checks
For example, let's say you want your pull request to be merged, e.g., once your CI passes and the pull request has been approved. You just write such a rule, and our engine merges the pull request as soon as it's ready.We also deal with more advanced use cases. For instance, we provide a merge queue so your pull requests are merged serially and tested by your CI one after another avoiding any regression in your code.Our goal is to make pull request management and automation easy. You can use your bot to trigger a rebase of your pull requests, or a backport to a different branch, just with a single comment.
One year of MergifySome people like to make bots talk to each other.
A New AdventureMergify is the first company that I ever started. I did run some personal businesses before, created non-profit organizations, built FOSS projects but I never created a company from scratch, even less with an associate.Indeed, I've chosen to build the company with my old friend Mehdi. We've known each others for 7 years now, and have worked together all that time on different open-source projects. Having worked with each other for so long has probably been a critical factor in the success of our venture so far.I had little experience sharing the founding seats with someone, and tons of reading seemed to indicate that it would be a tough ride. Picking the right business partner(s) can be a hard task. Luckily, after working so much time together, Mehdi and I both know our strengths and weaknesses well enough to be able to circumvent them. On the other hand, we both have similar backgrounds as software engineers. That does not help to cover all the hats you need to wear when building a company. Over time, we found arrangements to cover most of those equally between us.We don't have any magical advice to give on this. As in every relationship, communication is the key, and the #1 factor of success.

Getting UsersI don't know if we got lucky, but we got users and customers pretty early. We used a few cooperative projects as guinea pigs first, and they were brave enough to try our service and give us feedback. No repository has been harmed during this first phase!Then, as soon as we managed to get our application on the GitHub Marketplace, we saw a steady number of users coming to us.This has been fantastic as it allowed us to get feedback rapidly. We set up a form asking users for feedback after they used Mergify for a couple of weeks. What we hear is that users were happy, that the documentation was confusing and that some features were buggy or missing. We planned all of those ideas as our future work in our roadmap, using the principles we described a few months ago.
How we handle our roadmap for Mergify
Whatever you re building a company, a product, or a house a time comes where you need planning. Pushing random buttons to move forward does not work anymore. You need to take a step back to
One year of Mergify
If you're curious, you can read this article.
We tried various strategies to get new users, but so far, organic growth has been our #1 way of onboarding new users. Like many small startups out there, we're not that good at marketing and executing strategies.We provide our service for free for open-source projects We are now powering many organizations, such as Mozilla, Amazon Web Services, Ceph and Fedora.

Working with GitHubWorking with GitHub has been complicated. When you build an application for a marketplace, your business is entirely dependent on the platform you develop for both in terms of features and quality of service.In our case, we hit quite many bugs with GitHub. Their support has mostly been fast to answer, but some significant issues are still opened months later. The truth is that the GitHub API could deserve more love and care from GitHub. For example, their GraphQL API is a work in progress for years and miss out many essential features.
One year of MergifyGitHub service status is not always green.
We dealt and still deal with all those issues. It obviously impacts our operations and decreases our overall velocity. We regularly have to find new ways to sidestep GitHub limitations.You have no idea how we wished for GitHub to be open-source. The idea of not having access to their code and understand how it works is so frustrating that we publish our engine as an open-source project. That allows all of our users to see how it works and even propose enhancements.
One year of Mergify

Automate all the wayWe're a tiny startup, and we decided to bootstrap our company. We never took any funding. From the beginning, it has been clear to us that we had to think and act like we had no resources. We're built around a scarcity mindset. Every decision we make is based on the assumption that we basically are very limited in terms of money and time.We basically act like any wrong choice we do could (virtually) kill the company. We only do what is essential, we ship fast, and we automate everything.For example, we have built our whole operation about CI/CD systems, and pushing any new fix or feature in production is done in a matter of minutes. It's not uncommon for us to push a fix from our phone, just by reviewing some code or editing a file.

GrowthWe're extremely happy with our steady growth and more users using our service. We now manage close to 30k repositories and merge 15k pull requests per month for our users.That's a lot of mouse clicks saved!If you want to try Mergify yourself, it's a single click log-in using your GitHub account. Check it out!

11 March 2020

Steve Kemp: Goodbye twitter

I was slow to start using twitter, but found it a lot of fun. Often it would be useful at times when websites were slow; I'd hop to the website and search "edinburgh network", "github down", or "helsinki outage" and find live updates as people disclosed problems before the appropriate companies updated their status pages. I've found a lot of useful information, in near real-time, over the past few years. For example I remember hearing a loud explosion a few years back and had no idea what it was. Turns out it was an electrical substation catching fire nearby. Anyway recently I've been getting a lot of fake notifications, things that aren't real: You can't disable these notifications, the only thing you can do is click "see less often". For a couple of days I did that every time I saw them, to no avail. So I'm done. I've removed references to my account anywhere I could spot them, and I've signed out for good. (I read twitter on my desktop 99% of the time, though I did use my mobile phone to make posts, especially when images/pictures were involved.) I've not deleted my account, but I'd uninstalled the application and deleted the entry from my password-store. No doubt in a few years they'll delete my account, though they seem to have recently backtracked on their attempts to nuke inactive accounts.

Antoine Beaupr : Font changes

I have worked a bit on the fonts I use recently. From the main font I use every day in my text editor and terminals to this very website, I did a major and (hopefully) thoughtful overhaul of my typography, in the hope of making things easier to use and, to be honest, just prettier.

Editor and Terminal: Fira mono This all started when I found out about the Jetbrains Mono font. I found the idea of ligatures fascinating: the result is truly beautiful. So I do what I often do (sometimes to the despair of some fellow Debian members) and filed a RFP to document my research. As it turns out, Jetbrains Mono is not free enough to be packaged in Debian, because it requires proprietary tools to build. I nevertheless figured I could try another font so I looked at other monospace alternatives. I found the following packages in debian: Those are also "programmer fonts" that caught my interest but somehow didn't land in Debian yet: Because Fira code had ligatures, i ended up giving it a shot. I really like the originality of the font. See, for example, how the @ sign looks when compared to my previous font, Liberation Mono:
A dark terminal window showing the prompt '[SIGPIPE]anarcat@angela:~(master)$' in the Liberation Mono font Liberation Mono
A dark terminal window showing the prompt '[SIGPIPE]anarcat@angela:~(master)$' in the Fira mono font Fira Mono
Interestingly, a colleague (thanks ahf!) pointed me to the Practical Typography post "Ligatures in programming fonts: hell no", which makes the very convincing argument that ligatures are downright dangerous to programming environment. In my experiences with the fonts, it was also not always giving the result I would expect. I also remembered that the Emacs Haskell mode would have this tendency of inserting crazy syntactic sugar like this in source code without being asked, which I found extremely frustrating. Besides, Emacs doesn't support ligatures, unless you count such horrendous hacks which hack at the display time. That's because Emacs' display layer is not based on a modern rendering library like Pango but some scary legacy code that very few people understand. On top of the complexity of the codebase, there is also resistance in including a modern font. So I ended up using Fira mono everywhere I use fixed-width fonts, even though it's not packaged in Debian. That involves the following configuration in my .Xresources (no, I haven't switched to Wayland):
! font settings
Emacs*font: Fira mono
rofi*font: Fira mono 12
! Symbola is to get emojis to display correctly, apt install fonts-symbola
!URxvt*font: xft:Monospace,xft:Symbola
URxvt*font: xft:Fira mono,xft:Symbola
I also dropped this script in ~/.local/share/fonts/download.sh, for lack of a better way, to download all the fonts I'm interested in:
#!/bin/sh
set -e
set -u
wget --no-clobber --continue https://practicaltypography.com/fonts/charter.zip
unzip -u charter.zip
wget --no-clobber --continue https://github.com/adobe-fonts/source-serif-pro/releases/download/3.001R/source-serif-pro-3.001R.zip
unzip -u source-serif-pro-3.001R.zip
wget --no-clobber --continue https://github.com/adobe-fonts/source-sans-pro/releases/download/3.006R/source-sans-pro-3.006R.zip
unzip -u source-sans-pro-3.006R.zip
wget --no-clobber --continue https://github.com/adobe-fonts/source-code-pro/releases/download/2.030R-ro%2F1.050R-it/source-code-pro-2.030R-ro-1.050R-it.zip
unzip -u source-code-pro-2.030R-ro-1.050R-it.zip
wget --no-clobber --continue -O Fira-4.202.zip https://github.com/mozilla/Fira/archive/4.202.zip   true
unzip -u Fira-4.202.zip
Update: I forgot to mention one motivation behind this was to work around a change in the freetype interpreter, discussed in bug 866685 and my upgrades documentation.

Website: Charter That "hell no" article got me interested in the Practical Typography web book, which I read over the weekend. It was an eye opener and I realized I had already some of those concepts implanted; in fact it's probably after reading the Typography in ten minutes guide that I ended up trying Fira sans a few years ago. I have removed that font since then, however, after realising it was taking up an order of magnitude more bandwidth space than the actual page content. I really loved the book, so much that I actually bought it. I liked the concept of it, the look, and the fact that it's a living document. There's a lot of typography work I would need to do on this site to catchup with the recommendations from Matthew Butterick. Switching fonts is only one part of this, but it's something I was excited to work on. So I sat down and reviewed the free fonts Butterick recommends and tried out a few. I ended up settling on Charter, a relatively old (in terms of computing) font designed by Matthew Carter (of Verdana fame) in 1987. Charter really looks great and is surprisingly small. While a single version of Fira varies between 96KiB (Fira Sans Condensed) and 308KiB (Fira Sans Medium Italic), Charter is only 28KiB! While it's still about as large as most of my articles, I found it was a better compromise and decided to make the jump. This site is now in Serif, which is a huge change for me. The change was done with the following CSS:
h1, h2, h3, h4, h5, body  
    /* 
     * Charter: Butterick's favorite, freely available, found on https://practicaltypography.com/free-fonts.html
     * Palatino: Mac OS
     * Palatino Linotype: Windows
     * Noto serif: Android, packaged in Debian
     * Liberation serif: Linux fallback
     * Serif: fallback
     */
    font-family: Charter, Palatino, "Palatino Linotype", "Noto serif", "Liberation serif", serif;
    /* Charter is available from https://practicaltypography.com/charter.html under the liberal Bitstream license */
 
I have also decided to outline headings by making them slanted, using the beautiful italic version of Charter:
h1, h2, h3, h4, h5  
    font-style: italic;
 
I also made the point size larger, if the display is large enough:
/* enlarge body point size for charter for larger displays */
@media (min-device-width: 750px)  
    body  
        font-size: 20px;
        line-height: 1.3; /* default in FF is ~1.48 */
     
 
Modern display (including fonts) have a much higher resolution and the point size on my website was really getting too small to be readable. This, in turn, required a change to the max-width:
#content  
    /* about 2.5 alphabets with charter */
    max-width: 35em;
 
I have kept the footers and "UI" elements in sans-serif though, and kept those aligned on operating system defaults or "system fonts":
/* some hacking at typefaces to get some fresh zest in here
 * fallbacks from:
 * https://en.wikipedia.org/wiki/List_of_typefaces_included_with_Microsoft_Windows
 * https://en.wikipedia.org/wiki/List_of_typefaces_included_with_macOS
 */
.navbar, .footer  
    /*
     * Avenir: Mac, quite different but should still be pretty
     * Gill sans: Mac, Windows, somewhat similar to Avenir (indulge me)
     * Noto sans: Android, packaged in Debian
     * Open sans: Texlive extras AKA Linux, packaged in Debian
     * Fira sans: Mozilla's Firefox OS
     * Liberation sans: Linux fallback
     * Helvetica: general fallback
     * Sans-serif: fallback
     */
    font-family: Avenir, "Gill sans", "Noto sans", "Open sans", "Fira sans", "Liberation sans", Helvetica, sans-serif;
    /* Fira is available from https://github.com/mozilla/Fira/ under the SIL Open Font License */
    /* alternatively, just use system fonts for "controls" instead:
    font-family: -apple-system, BlinkMacSystemFont, "Segoe UI", "Roboto", "Oxygen", "Ubuntu", "Cantarell", "Fira Sans", "Droid Sans", "Helvetica Neue", sans-serif;
    gitlab uses: -apple-system, BlinkMacSystemFont, "Segoe UI", Roboto, "Noto Sans", Ubuntu, Cantarell, "Helvetica Neue", sans-serif, "Apple Color Emoji", "Segoe UI Emoji", "Segoe UI Symbol", "Noto Color Emoji"
    */
 
I've only done some preliminary testing of how this will look like. Although I tested on a few devices (my phone, e-book tablet, an iPad, and of course my laptop), I fully expect things to break on your device. Do let me know if things look better or worse. For future comparison, my site is well indexed in the Internet Wayback Machine and can be used to look at the site before the change. For example, compare the previous article here with its earlier style. The changes to the theme are of course available in my custom ikiwiki bootstrap theme (see in particular commits 0bca0fb7 and d1901fb8), as usual. Enjoy, and let me know what you think! PS: I considered just setting the Charter font in CSS and not adding it as a @font-face. I'm still considering that option and might do so if the performance cost is too big. The Fira mono font is actually set like this for the preformatted sections of the site, but because it's more common (and it's too big) I haven't added it as a font-face. You might want to download the font locally to benefit from the full experience as well. PPS: As it turns out, an earlier version of this post featured exactly that: a non-webfont version of Charter, which works fine if you have a good Charter font available. But it looks absolutely terrible if, like many Linux users, you have the nasty bitmap font shipped with xfonts-100dpi and xfonts-75dpi. So I fixed the webfont and it's unlikely this site will be able to load reasonably well in Linux until those packages are removed or bitmap font rendering is disabled.

9 March 2020

Sam Hartman: Forged Email

Last night, a series of forged emails was sent to a number of places around the Debian, Ubuntu and Free Software communities. The meat of the mail was a fake message from me to debian-private with the subject "DebConf19 Diversity Girls." I didn't write such a message.
I view this message as the latest installment in a campaign of attacks on Debian that attempt to undermine the project and take up the time of our members.
I was expecting something like this: yesterday, I banned Daniel Pocock from the project.There's been a pattern of related events over the past year and a half:

8 March 2020

Ulrike Uhlig: Implementing feedback into our work culture

Everywhere I worked in the past, the only feedback that was asked of employees was during a yearly evaluation meeting. These meetings always felt to me like talking to Santa Claus and his Knecht Ruprecht. I was asked: Were you a good employee last year? If yes, we might give you a raise. If no, admit all your mistakes now, even if we already know everything, ho ho ho. And don't you talk about your feelings, or your well-being, or say anything about the organization's (invisible) hierarchies, otherwise we will put you on the "naughty list", and that's it with candy. The yearly evaluation set aside, there was no other place to give feedback (except by escalating a matter by involving the Labour Court, if you happen to work in France, or going on strike, also mostly part of French culture). Feedback allows to reflect on work processes, to situate oneself, and to get closure. How surprised was I when, some years ago, I received an email from a collaborator asking me: kindly for just few paragraphs (doesn t have to be anything long) to hear from you about the process, your work, challenges you had, or anything else you want to mention there.. Wow!
This simple email allowed me to reflect about: How do we get to a feedback culture? How do we get from German Christmas folklore, protestant work ethics, and the deeply rooted principles of disciplining and punishing to a feedback culture on eye level? It sounds a bit like going from the dark ages to a really cool science fiction utopia with universal peace, telepathy, and magic between all sentient beings on all inhabited planets in the cosmos at least that's how I imagined it as a child, just like some of my heroes did: the cosmonaut girl who saves Earth, the boy who talks to space flowers that give him the capacity to fly, and the little onion who fights for justice (the Italian author was so popular on our side of the iron curtain that a soviet astronomer named a minor planet after him. His wife meanwhile immortalized Karl Marx.) and some romantic part of me hangs on to these ideas. Feedback is not always easy to hear and to give. I-Statements Giving and receiving feedback is hard in a culture where people learnt that when they made a mistake they won't get candy. Or that they have to constantly please other people because they are not worthy by themselves. This can lead to people putting mistakes on one another. Every sentence that starts with You are has the potential of creating a lot of hurt, and anger. Have you heard of I-Statements? They have very powerfully changed my world view, as they shift from accusation to ownership of feelings. So instead of telling someone Your writing style is impossible! You really need to change the way you write., with an I-Statement one could say I have a hard time understanding that part of the text. I-Statements make cooperation possible. Listening actively Feedback is not about being right or wrong, it's first of all about being able to see how another person has experienced a situation. Active listening is a tool that helps with understanding. It might seem easy, but needs quite some practice and a safe space. One part of active listening is to restate what you hear the other person say (by mirroring, or paraphrasing), to make sure you understood, and make sure they know you understood what they were trying to say. You can practise this: in a circle of three people, have one person tell how they experienced a (possibly conflictual) situation, have one person do the active listening, and the third person observing in order to give feedback to the active listener about how they did. Then switch roles, for example clockwise, until everyone has had every role. Encouraging continuous feedback A working feedback culture does not take place only once a year. It needs to be a continuous process and therefore implemented in meetings, teams, eventually on the level of a project. Making clear: Who can I talk to if I experience an issue? is not different than telling developers and users where and how they can report a bug, or request a feature. A safe space to express feedback is key. Encouraging multiple feedback channels Some people might feel less empowered or more vulnerable over a channel than others. Make sure to have different channels for receiving feedback such as email, a point on each meeting agenda, a one-to-one meeting, or a poll. Giving and receiving feedback on eye level In a workplace that does not have a working feedback culture, feedback is easily perceived as policing. If your feedback process consists of asking people to upload a form to a cloud server every 3 months, and you notice that some people don't do it, you could ask yourself if there is an issue with how your colleagues perceive giving feedback in your organization. Do you meet your colleagues on eye level when it comes to feedback? Do you take feedback seriously and act on it? How do you deal with unpleasant feedback? How do you react when colleagues don't meet your expectations? Can people participate in the feedback process within their paid work time? Did everybody understand what the feedback process is about? Don't jump to conclusions Humans are problem solving animals. When someone comes to us with a problem, the first thing we want to do is to solve it, to help them. But sometimes this is uncalled for, it can be disempowering, or prevent people from acquiring competences themselves, and it can even break people's boundaries. So instead of asking What can I do for you?, try asking What do you need right now? People will often reply something that you did not expect at all. Acting on feedback Make sure you have a process to collect feedback (possibly anonymized) and to regularly evaluate if the organization needs to implement changes to thrive. Conclusion I stumbled upon Hans-Christian Dany's critique of feedback again recently, therefore I need to make it clear: I'm not interested in improving capitalist work culture by using cybernetic principles of self-regulation through feedback. Instead, I am interested in improving cooperation between people who work either individually or in organizations on eye level. In this framework, I see feedback processes as profoundly anti-capitalist methods to improve cooperation while working towards common good. Implementing these ideas should be doable: there are organizations who provide feedback training for example. This document, initially aiming at people in cooperatives, gives many insights on communication skills and feedback, the agile and UX worlds do feedback "retrospectives". and otherwise I'll have to go and write science fiction stories for children myself.

7 March 2020

Fran ois Marier: Fixing MariaDB InnoDB errors after upgrading to MythTV 30

After upgrading to MythTV 30 and MariaDB 10.3.18 on Debian buster, I noticed the following errors in my logs:
Jan 14 02:00:05 hostname mysqld[846]: 2020-01-14  2:00:05 62 [Warning] InnoDB: Cannot add field  rating  in table  mythconverg . internetcontentarticles  because after adding it, the row size is 8617 which is greater than maximum allowed size (8126) for a record on index leaf page.
Jan 14 02:00:05 hostname mysqld[846]: 2020-01-14  2:00:05 62 [Warning] InnoDB: Cannot add field  playcommand  in table  mythconverg . videometadata  because after adding it, the row size is 8243 which is greater than maximum allowed size (8126) for a record on index leaf page.
The root cause is that the database is using an InnoDB row format that cannot handle the new table sizes. To fix it, I put the following in alter_tables.sql:
ALTER TABLE archiveitems ROW_FORMAT=DYNAMIC;
ALTER TABLE bdbookmark ROW_FORMAT=DYNAMIC;
ALTER TABLE callsignnetworkmap ROW_FORMAT=DYNAMIC;
ALTER TABLE capturecard ROW_FORMAT=DYNAMIC;
ALTER TABLE cardinput ROW_FORMAT=DYNAMIC;
ALTER TABLE channel ROW_FORMAT=DYNAMIC;
ALTER TABLE channelgroup ROW_FORMAT=DYNAMIC;
ALTER TABLE channelgroupnames ROW_FORMAT=DYNAMIC;
ALTER TABLE channelscan ROW_FORMAT=DYNAMIC;
ALTER TABLE channelscan_channel ROW_FORMAT=DYNAMIC;
ALTER TABLE channelscan_dtv_multiplex ROW_FORMAT=DYNAMIC;
ALTER TABLE codecparams ROW_FORMAT=DYNAMIC;
ALTER TABLE credits ROW_FORMAT=DYNAMIC;
ALTER TABLE customexample ROW_FORMAT=DYNAMIC;
ALTER TABLE diseqc_config ROW_FORMAT=DYNAMIC;
ALTER TABLE diseqc_tree ROW_FORMAT=DYNAMIC;
ALTER TABLE displayprofilegroups ROW_FORMAT=DYNAMIC;
ALTER TABLE displayprofiles ROW_FORMAT=DYNAMIC;
ALTER TABLE dtv_multiplex ROW_FORMAT=DYNAMIC;
ALTER TABLE dtv_privatetypes ROW_FORMAT=DYNAMIC;
ALTER TABLE dvdbookmark ROW_FORMAT=DYNAMIC;
ALTER TABLE dvdinput ROW_FORMAT=DYNAMIC;
ALTER TABLE dvdtranscode ROW_FORMAT=DYNAMIC;
ALTER TABLE eit_cache ROW_FORMAT=DYNAMIC;
ALTER TABLE filemarkup ROW_FORMAT=DYNAMIC;
ALTER TABLE gallery_directories ROW_FORMAT=DYNAMIC;
ALTER TABLE gallery_files ROW_FORMAT=DYNAMIC;
ALTER TABLE gallerymetadata ROW_FORMAT=DYNAMIC;
ALTER TABLE housekeeping ROW_FORMAT=DYNAMIC;
ALTER TABLE inputgroup ROW_FORMAT=DYNAMIC;
ALTER TABLE internetcontent ROW_FORMAT=DYNAMIC;
ALTER TABLE internetcontentarticles ROW_FORMAT=DYNAMIC;
ALTER TABLE inuseprograms ROW_FORMAT=DYNAMIC;
ALTER TABLE iptv_channel ROW_FORMAT=DYNAMIC;
ALTER TABLE jobqueue ROW_FORMAT=DYNAMIC;
ALTER TABLE jumppoints ROW_FORMAT=DYNAMIC;
ALTER TABLE keybindings ROW_FORMAT=DYNAMIC;
ALTER TABLE keyword ROW_FORMAT=DYNAMIC;
ALTER TABLE livestream ROW_FORMAT=DYNAMIC;
ALTER TABLE logging ROW_FORMAT=DYNAMIC;
ALTER TABLE music_albumart ROW_FORMAT=DYNAMIC;
ALTER TABLE music_albums ROW_FORMAT=DYNAMIC;
ALTER TABLE music_artists ROW_FORMAT=DYNAMIC;
ALTER TABLE music_directories ROW_FORMAT=DYNAMIC;
ALTER TABLE music_genres ROW_FORMAT=DYNAMIC;
ALTER TABLE music_playlists ROW_FORMAT=DYNAMIC;
ALTER TABLE music_radios ROW_FORMAT=DYNAMIC;
ALTER TABLE music_smartplaylist_categories ROW_FORMAT=DYNAMIC;
ALTER TABLE music_smartplaylist_items ROW_FORMAT=DYNAMIC;
ALTER TABLE music_smartplaylists ROW_FORMAT=DYNAMIC;
ALTER TABLE music_songs ROW_FORMAT=DYNAMIC;
ALTER TABLE music_stats ROW_FORMAT=DYNAMIC;
ALTER TABLE music_streams ROW_FORMAT=DYNAMIC;
ALTER TABLE mythlog ROW_FORMAT=DYNAMIC;
ALTER TABLE mythweb_sessions ROW_FORMAT=DYNAMIC;
ALTER TABLE networkiconmap ROW_FORMAT=DYNAMIC;
ALTER TABLE oldfind ROW_FORMAT=DYNAMIC;
ALTER TABLE oldprogram ROW_FORMAT=DYNAMIC;
ALTER TABLE oldrecorded ROW_FORMAT=DYNAMIC;
ALTER TABLE people ROW_FORMAT=DYNAMIC;
ALTER TABLE phonecallhistory ROW_FORMAT=DYNAMIC;
ALTER TABLE phonedirectory ROW_FORMAT=DYNAMIC;
ALTER TABLE pidcache ROW_FORMAT=DYNAMIC;
ALTER TABLE playgroup ROW_FORMAT=DYNAMIC;
ALTER TABLE powerpriority ROW_FORMAT=DYNAMIC;
ALTER TABLE profilegroups ROW_FORMAT=DYNAMIC;
ALTER TABLE program ROW_FORMAT=DYNAMIC;
ALTER TABLE programgenres ROW_FORMAT=DYNAMIC;
ALTER TABLE programrating ROW_FORMAT=DYNAMIC;
ALTER TABLE recgrouppassword ROW_FORMAT=DYNAMIC;
ALTER TABLE recgroups ROW_FORMAT=DYNAMIC;
ALTER TABLE record ROW_FORMAT=DYNAMIC;
ALTER TABLE record_tmp ROW_FORMAT=DYNAMIC;
ALTER TABLE recorded ROW_FORMAT=DYNAMIC;
ALTER TABLE recordedartwork ROW_FORMAT=DYNAMIC;
ALTER TABLE recordedcredits ROW_FORMAT=DYNAMIC;
ALTER TABLE recordedfile ROW_FORMAT=DYNAMIC;
ALTER TABLE recordedmarkup ROW_FORMAT=DYNAMIC;
ALTER TABLE recordedprogram ROW_FORMAT=DYNAMIC;
ALTER TABLE recordedrating ROW_FORMAT=DYNAMIC;
ALTER TABLE recordedseek ROW_FORMAT=DYNAMIC;
ALTER TABLE recordfilter ROW_FORMAT=DYNAMIC;
ALTER TABLE recordingprofiles ROW_FORMAT=DYNAMIC;
ALTER TABLE recordmatch ROW_FORMAT=DYNAMIC;
ALTER TABLE scannerfile ROW_FORMAT=DYNAMIC;
ALTER TABLE scannerpath ROW_FORMAT=DYNAMIC;
ALTER TABLE schemalock ROW_FORMAT=DYNAMIC;
ALTER TABLE settings ROW_FORMAT=DYNAMIC;
ALTER TABLE storagegroup ROW_FORMAT=DYNAMIC;
ALTER TABLE tvchain ROW_FORMAT=DYNAMIC;
ALTER TABLE tvosdmenu ROW_FORMAT=DYNAMIC;
ALTER TABLE upnpmedia ROW_FORMAT=DYNAMIC;
ALTER TABLE user_permissions ROW_FORMAT=DYNAMIC;
ALTER TABLE user_sessions ROW_FORMAT=DYNAMIC;
ALTER TABLE users ROW_FORMAT=DYNAMIC;
ALTER TABLE videocast ROW_FORMAT=DYNAMIC;
ALTER TABLE videocategory ROW_FORMAT=DYNAMIC;
ALTER TABLE videocollection ROW_FORMAT=DYNAMIC;
ALTER TABLE videocountry ROW_FORMAT=DYNAMIC;
ALTER TABLE videogenre ROW_FORMAT=DYNAMIC;
ALTER TABLE videometadata ROW_FORMAT=DYNAMIC;
ALTER TABLE videometadatacast ROW_FORMAT=DYNAMIC;
ALTER TABLE videometadatacountry ROW_FORMAT=DYNAMIC;
ALTER TABLE videometadatagenre ROW_FORMAT=DYNAMIC;
ALTER TABLE videopart ROW_FORMAT=DYNAMIC;
ALTER TABLE videopathinfo ROW_FORMAT=DYNAMIC;
ALTER TABLE videosource ROW_FORMAT=DYNAMIC;
ALTER TABLE videotypes ROW_FORMAT=DYNAMIC;
ALTER TABLE weatherdatalayout ROW_FORMAT=DYNAMIC;
ALTER TABLE weatherscreens ROW_FORMAT=DYNAMIC;
ALTER TABLE weathersourcesettings ROW_FORMAT=DYNAMIC;
and then ran it like this:
mysql -umythtv -pPassword1 mythconverg < alter_tables.sql

Next.

Previous.