Search Results: "spa"

1 February 2022

Dirk Eddelbuettel: #35: apt install rstudio quarto

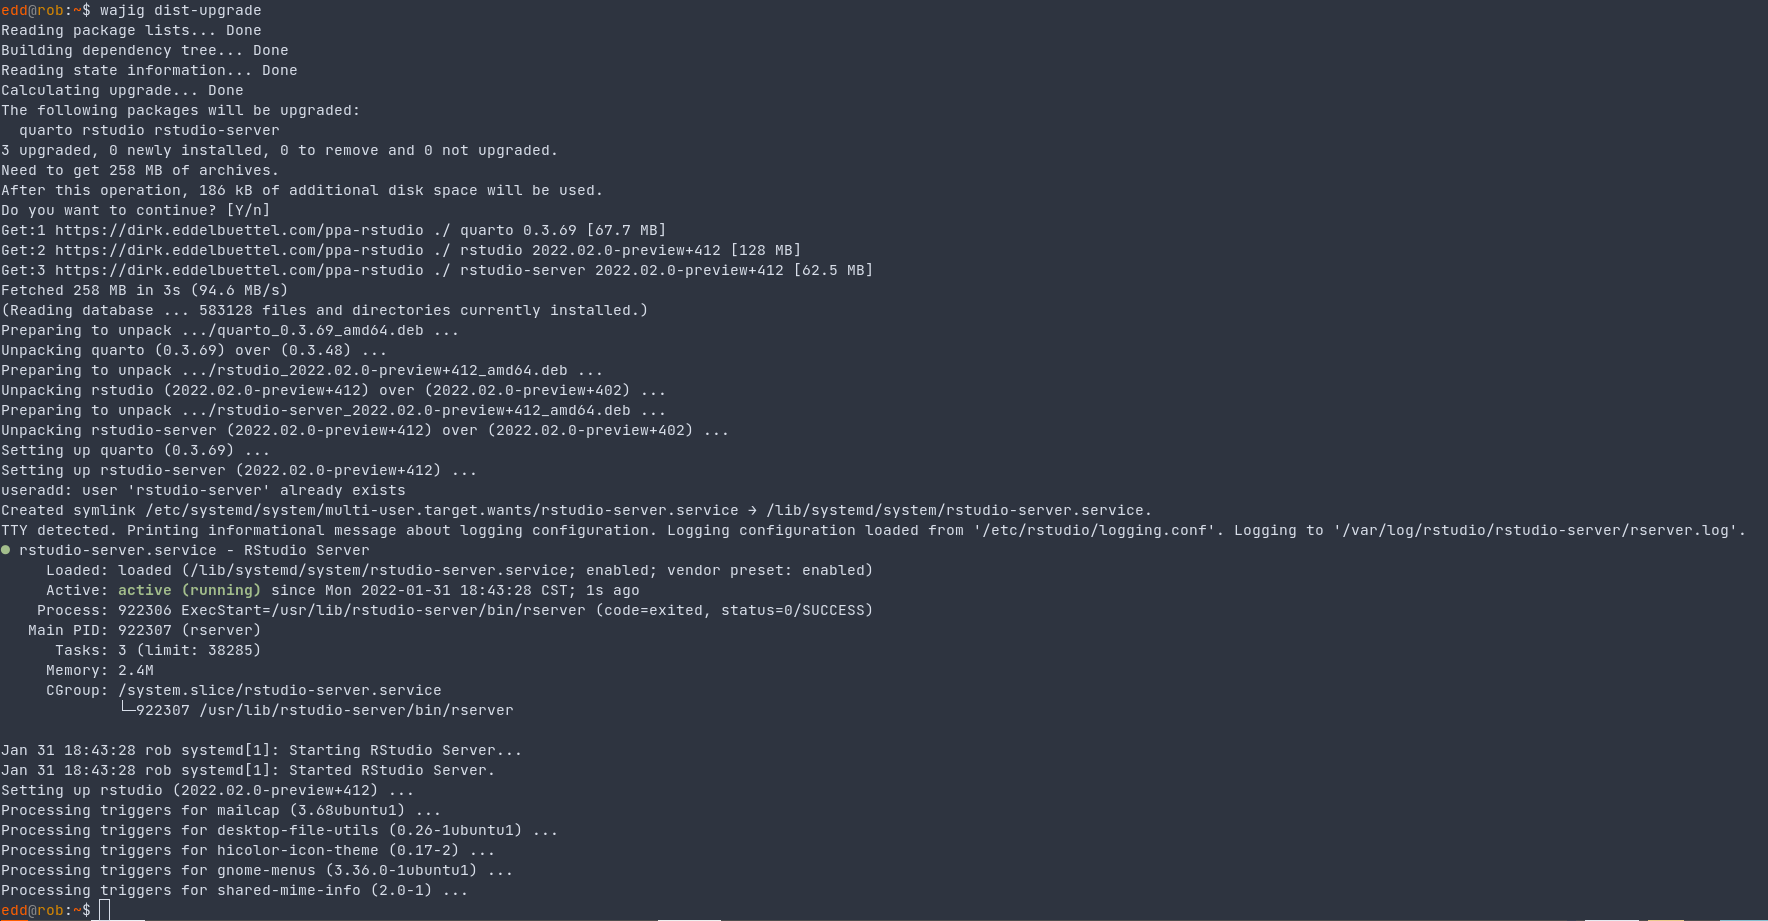
Welcome to the 35th post in the ravishingly rabiant R recommendations, or R4. Today s post is about apt and R tools. Many of us have been running RStudio off our local machines for as long as binaries have been provided. Which is by now probably a bit over a decade. Time flies. And as nice it is to have matching binaries, in my case in the .deb format used on Debian or Ubuntu, it is wee bit a painful to manually download a file and then install it. Twice the pain if you are lucky enough to be on a system where you can also run RStudio Server. And now three times as painful as you may need a matching quarto-cli binary for the nice quarto service. So wouldn t it be nice to have an apt-getable repo? And to autoMAGICall get updated versions when they are available? Oh yes. And I had been bugging JJ from day one. And JJ would almost listen intendly, nod briefly and firmly, and issue an assured we will look into it. Well, they are still looking Luckily, years ago, Carl wrote a helper script for our use in Rocker. I promptly adopted these and kept them in the littler examples directory as a pair of script getRStudioDesktop.r and getRStudioServer.r, later complemented by getQuartoCli.r. And I used these for years, somewhere between weekly and monthly. But it is still very manual: three script calls, one sudo dpkg -i call. And as our good friends at RStudio don t seem to be coming forward with a repo, I created one at GitHub thinking I could serve the files via GitHub Pages. Which of course I cannot as the .deb file for rstudio is well above the 100mb limit. So that seemed to be a bit of a setback. But after a bit of pondering, and recognizing that I am now in the fortunate position to have symmetric broadband access at home, I reckoned that until the bandwidth use gets excessive I will serve this as truly personal package archive (or tPPA) from here. Note that this is calibrated for my use so Ubuntu amd64 it is. Nothing else. And that it installs dailies . Which may cause issues for some people. You have warned. Reading tis paragraphs signifies agreement with the terms and limitations. Just kidding. A quick screenshot from an update earlier is here. Note that I use the fabulous wajig wrapper by Graham Williams here as my frontend to apt, dpkg and more as I have for even longer than I have use RStudio. Its use is tangential here; sudo apt upgrade would have done the same (and is essentially being called). And it demonstrates the main benefit: we are now automated as the cron scheduler launches an update of the PPA at which ever frequency you chose (currently twice a week for me) and after that it becomes part of the normal apt updates we do anyway (and which I do about daily). So that s main gist: automated apt upgrades of rstudio, rstudio-server, and quarto-cli. And you can find the underlying code in the GitHub repo ppa-rstudio which I put together a good week ago. I am currently updating the tPPA twice a week from crontab and have had two full upgrades already. And who knows, maybe with a bid of prodding RStudio may come around. One can always hope. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Paul Wise: FLOSS Activities January 2022

Focus This month I didn't have any particular focus. I just worked on issues in my info bubble.

Changes

Issues

Review

Administration
  • Debian BTS: unarchive/reopen/triage bugs for reintroduced packages
  • Debian servers: ping folks about mail forwarding issues
  • Debian wiki: unblock IP addresses, approve accounts

Communication
  • Respond to queries from Debian users and contributors on the mailing lists and IRC

Sponsors The oci-cli, oci-python-sdk, circuitbreaker, autoconf-archive, libpst, purple-discord, sptag work was sponsored. All other work was done on a volunteer basis.

31 January 2022

Russ Allbery: Review: The Story of the Treasure Seekers

Review: The Story of the Treasure Seekers, by E. Nesbit
Publisher: Amazon
Copyright: 1899
Printing: May 2012
ASIN: B0082ZBXSI
Format: Kindle
Pages: 136
The Story of the Treasure Seekers was originally published in 1899 and is no longer covered by copyright. I read the free Amazon Kindle version because it was convenient. My guess is that Amazon is republishing the Project Gutenberg version, but they only credit "a community of volunteers." There are six Bastable children: Dora, Oswald, Dicky, the twins Alice and Noel, and Horace Octavius (H.O.), the youngest. Their mother is dead and the family's finances have suffered in the wake of her death (or, as the first-person narrator puts it, "the fortunes of the ancient House of Bastable were really fallen"), which means that their father works long hours and is very absorbed with his business. That leaves the six kids largely to fend for themselves, since they can't afford school. Clearly the solution is to find treasure. This is a fix-up novel constructed from short stories that were originally published in various periodicals, reordered and occasionally rewritten for the collected publication. To be honest, calling it a fix-up novel is generous; there are some references to previous events, but the first fourteen chapters can mostly stand alone. The last two chapters are closely related and provide an ending. More on that in a moment. What grabs the reader's attention from the first paragraph is the writing style:
This is the story of the different ways we looked for treasure, and I think when you have read it you will see that we were not lazy about the looking. There are some things I must tell before I begin to tell about the treasure-seeking, because I have read books myself, and I know how beastly it is when a story begins, "Alas!" said Hildegarde with a deep sigh, "we must look our last on this ancestral home" and then some one else says something and you don't know for pages and pages where the home is, or who Hildegarde is, or anything about it.
The first-person narrator of The Story of the Treasure Seekers is one of the six kids.
It is one of us that tells this story but I shall not tell you which: only at the very end perhaps I will.
The narrator then goes on to elaborately praise one of the kids, occasionally accidentally uses "I" instead of their name, and then remembers and tries to hide who is telling the story again. It's beautifully done and had me snickering throughout the book. It's not much of a mystery (you will figure out who is telling the story very quickly), but Nesbit captures the writing style of a kid astonishingly well without making the story poorly written. Descriptions of events have a headlong style that captures a child's sense of adventure and heedless immortality mixed with quiet observations that remind the reader that kids don't miss as much as people think they do. I think the most skillful part of this book is the way Nesbit captures a kid's disregard of literary convention. The narrator in a book written by an adult tends to fit into a standard choice of story-telling style and follow it consistently. Even first-person narrators who break some of those rules feel like intentionally constructed characters. The Story of the Treasure Seekers is instead half "kid telling a story" and half "kid trying to emulate the way stories are told in books" and tends to veer wildly between the two when the narrator gets excited, as if they're vaguely aware of the conventions they're supposed to be following but are murky on the specifics. It feels exactly like the sort of book a smart and well-read kid would write (with extensive help from an editor). The other thing that Nesbit handles exceptionally well is the dynamic between the six kids. This is a collection of fairly short stories, so there isn't a lot of room for characterization. The kids are mostly sketched out with one or two memorable quirks. But Nesbit puts a lot of effort into the dynamics that arise between the children in a tight-knit family, properly making the group of kids as a whole and in various combinations a sort of character in their own right. Never for a moment does either the reader or the kids forget that they have siblings. Most adventures involve some process of sorting out who is going to come along and who is going to do other things, and there's a constant but unobtrusive background rhythm of bickering, making up, supporting each other, being frustrated by each other, and getting exasperated at each other's quirks. It's one of the better-written sibling dynamics that I've read. I somehow managed to miss Nesbit entirely as a kid, probably because she didn't write long series and child me was strongly biased towards books that were part of long series. (One book was at most a pleasant few hours; there needed to be a whole series attached to get any reasonable amount of reading out of the world.) This was nonetheless a fun bit of nostalgia because it was so much like the books I did read: kids finding adventures and making things up, getting into various trouble but getting out of it by being honest and kind, and only occasional and spotty adult supervision. Reading as an adult, I can see the touches of melancholy of loss that Nesbit embeds into this quest for riches, but part of the appeal of the stories is that the kids determinedly refuse to talk about it except as a problem to be solved. Nesbit was a rather famous progressive, but this is still a book of its time, which means there's one instance of the n-word and the kids have grown up playing the very racist version of cowboys and indians. The narrator also does a lot of stereotyping of boys and girls, although Nesbit undermines that a bit by making Alice a tomboy. I found all of this easier to ignore because the story is narrated by one of the kids who doesn't know any better, but your mileage may vary. I am always entertained by how anyone worth writing about in a British children's novel of this era has servants. You know the Bastables have fallen upon hard times because they only have one servant. The kids don't have much respect for Eliza, which I found a bit off-putting, and I wondered what this world looks like from her perspective. She clearly did a lot of the work of raising these motherless kids, but the kids view her as the hired help or an obstacle to be avoided, and there's not a lot of gratitude present. As the stories unfold, it becomes more and more clear that there's a quiet conspiracy of surrounding adults to watch out for these kids, which the kids never notice. This says good things about society, but it does undermine the adventures a little, and by the end of the book the sameness of the stories was wearing a bit thin. The high point of the book is probably chapter eight, in which the kids make their own newspaper, the entirety of which is reproduced in the book and is a note-perfect recreation of what an enterprising group of kids would come up with. In the last two stories, Nesbit tacks on an ending that was probably obligatory, but which I thought undermined some of the emotional subtext of the rest of the book. I'm not sure how else one could have put an ending on this book, but the ending she chose emphasized the degree to which the adventures really were just play, and the kids are rewarded in these stories for their ethics and their circumstances rather than for anything they concretely do. It's a bit unsatisfying. This is mostly a nostalgia read, but I'm glad I read it. If this book was not part of your childhood, it's worth reading if only for how well Nesbit captures a child's narrative voice. Rating: 7 out of 10

30 January 2022

Russell Coker: Links Jan 2022

Washington Post has an interesting article on how gender neutral language is developing in different countries [1]. pimaker has an interesting blog post about how they wrote a RISCV CPU emulator to boot a Linux kernel in a pixel shader in the VR Chat platform [2]. ZD has an interesting article about the new Solo Bumblebee platform for writing EBPF programs to run inside the Linux kernel [3]. EBPF is an interesting platform and it s good to have new tools to help people develop for it. Big Think has an interesting article about augmented reality suggesting that it could be worse than social media for driving disputes [4]. Some people would want tags of racial status on all people they see. Vice has an insightful article making the case for 8 hours of work per week [5]. The Guardian has an insightful article about how our attention is being stolen by modern technology [6]. Interesting article about the Ilobleed rootkit that targets the HP ILO server management system [7], it s apparently designed for persistent attacks as it bypasses the firmware upgrade process and updates only the version number so anyone who thinks that a firmware update will fix it is horribly mislead. Nick Bostrom wrote an insightful and disturbing article for Aeon titles None of Our Technologies has Managed to Destroy Humanity Yet [8] about the existential risk of new technologies and how they might be mitigated, much of which involves authoritarian governments unlike any we have seen before. As a counterpoint the novel A Deepness in the Sky claims that universal surveillance would be as damaging to the future of a society as planet-buster bombs. Euronews has an informative article about eco-fascism [9]. The idea that the solution to ecological problems is to have less people in the world and particularly less non-white people is a gateway from green politics to fascism. The developer of the colors and faker npm libraries (for NodeJS) recently uploaded corrupted versions of those libraries as a protest against companies that use them without paying him [10]. This is the wrong way to approach the issue, but it does demonstrate a serious problem with systems like NPM that allow automatic updates. It gives a better result to just use software packaged by a distribution which has QA checks applied including on security updates. VentureBeat has an interesting article on the way that AI is taking over jobs [11]. Lots of white collar jobs can be replaced by machine learning systems, we need to plan for the ways this will change the economy. The Atlantic has an interesting article about tapeworms that infect some ants [12]. The tapeworms make the ants live longer and produce pheromones to make the other ants serve them. This increases the chance that the ants will be eaten by birds which is the next stage in the tapeworm lifecycle.

29 January 2022

Sylvestre Ledru: An update on rust/coreutils

TLDR: we are making progress on the Rust implementation of the GNU coreutils. Well, it is an understatement to say my previous blog post interested many people. Many articles, blog posts and some podcasts talked about it! As we pushed coreutils 0.0.12 a few days ago and getting closer to the 10 000 stars on github, it is now time to give an update! This has brought a lot of new contributors to this project. Instead of 30 to 60 patches per month, we jumped to 400 to 472 patches every month. Similarly, we saw an increase in the number of contributors (20 to 50 per month from 3 to 8). Two new maintainers (Michael Debertol & Terts Diepraam) stepped in and have been doing a much better job than myself as reviewers now! As a silly metric, according to github, we had 5 561 clones of the repository over the last 2 weeks! The new contributors focused on: Closing the gap with GNU As far as I know, we are only missing stty (change and print terminal line settings) as a program. Thanks to some heroes, basenc, pr, chcon and runcon have been implemented. For example, for the two last programs, Koutheir Attouchi wrote new crates to manage SELinux properly. This crate has been used for some other utilities like cp, ls or id. Leveraging the GNU testsuite to test this implementation Because the GNU testsuite is excellent, we now have a proper CI using it to run the tests. It is pretty long on the Github action CI (almost two hours to run it) but it is an amazing improvement to the way we work. It was a joint work from a bunch of folks (James Robson, Roy Ivy III, etc). To achieve this, we also made it easier to run the GNU testsuite locally with the Rust implementation but also to ignore some tests or adjust some error messages (see build-gnu.sh and run-gnu-test.sh). Following a suggestion of Brian G, a colleague at Mozilla (he did the same for some Firefox major change), we are now collecting the history of fail/pass/error into a separate repository and generating a daily graph showing the evolution of regression. Evolution over time At this date, we have, with GNU/Coreutils 9.0:
Total 611 tests
Pass 214
Skip 84
Fail 298
Error 15
We are now automatically identifying new passing tests and regressions in the CI. For example:
Warning: Congrats! The gnu test tests/chmod/c-option is now passing!
<br />Warning: Congrats! The gnu test tests/chmod/silent is now passing!
<br />Warning: Congrats! The gnu test tests/chmod/umask-x is now passing!
<br />Error: GNU test failed: tests/du/long-from-unreadable. tests/du/long-from-unreadable is passing on 'master'. Maybe you have to rebase?
[...]
<br />Warning: Changes from master: PASS +4 / FAIL +0 / ERROR -4 / SKIP +0
This is also beneficial to GNU as, by implementing some options, Michael Debertol noticed some incorrect behaviors (with sort and cat) or an uninitialized variable (with chmod). Documentations Every day, we are generating the user documentation and of the internal coreutils. User documentation: https://uutils.github.io/coreutils-docs/user/ Example: ls or cp The internal documentation can be seen on: https://uutils.github.io/coreutils-docs/dev/uucore/
For example, the backup style is documented here: https://uutils.github.io/coreutils-docs/dev/uucore/backup_control/index.html More? Besides my work on Debian/Ubuntu, I have also noticed that more and more operating systems are starting to look at this: In parallel, https://github.com/uutils/findutils/, a rust dropped-in replacement for find, is getting more attention lately! Here, the graph showing the evolution of the program using the BFS testsuite (much better than GNU's). Evolution over time - BFS testsuite What is next?
  1. stty needs to be implemented
  2. Improve the GNU compatibility on key programs and reduce the gap
  3. Investigate how to reduce the size of the binaries
  4. Allow Debian and Ubuntu to switch by default without tricky manipulation
How to help? I have been maintaining a list of good first bugs for new comers in the repo! Don't hesitate to contribute, it is much easier than it seems and a terrific way to learn Rust!

28 January 2022

Reproducible Builds (diffoscope): diffoscope 202 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 202. This version includes the following changes:
[ Chris Lamb ]
* Don't fail if comparing a nonexistent file with a .pyc file (and add test).
  (Closes: #1004312)
* Drop a reference in the manual page which claims the ability to compare
  non-existent files on the command-line. This has not been possible since
  version 32 which was released in September 2015. (Closes: #1004182)
* Add experimental support for incremental output support with a timeout.
  Passing, for example, --timeout=60 will mean that diffoscope will not
  recurse into any sub-archives after 60 seconds total execution time has
  elapsed and mark the diff as being incomplete. (Note that this is not a
  fixed/strict timeout due to implementation issues.)
  (Closes: reproducible-builds/diffoscope#301)
* Don't return with an exit code of 0 if we encounter device file such as
  /dev/stdin with human-readable metadata that matches literal, non-device,
  file contents. (Closes: #1004198)
* Correct a "recompile" typo.
[ Sergei Trofimovich ]
* Fix/update whitespace for Black 21.12.
You find out more by visiting the project homepage.

27 January 2022

Russ Allbery: Review: I Didn't Do the Thing Today

Review: I Didn't Do the Thing Today, by Madeleine Dore
Publisher: Avery
Copyright: 2022
ISBN: 0-593-41914-6
Format: Kindle
Pages: 291
At least from my narrow view of it, the world of productivity self-help literature is a fascinating place right now. The pandemic overturned normal work patterns and exacerbated schedule inequality, creating vastly different experiences for the people whose work continued to be in-person and the people whose work could become mostly or entirely remote. Self-help literature, which is primarily aimed at the more affluent white-collar class, primarily tracked the latter disruption: newly-remote work, endless Zoom meetings, the impossibility of child care, the breakdown of boundaries between work and home, and the dawning realization that much of the mechanics of day-to-day office work are neither productive nor defensible. My primary exposure these days to the more traditional self-help productivity literature is via Cal Newport. The stereotype of the productivity self-help book is a collection of life hacks and list-making techniques that will help you become a more efficient capitalist cog, but Newport has been moving away from that dead end for as long as I've been reading him, and his recent work focuses more on structural issues with the organization of knowledge work. He also shares with the newer productivity writers a willingness to tell people to use the free time they recover via improved efficiency on some life goal other than improved job productivity. But he's still prickly and defensive about the importance of personal productivity and accomplishing things. He gives lip service on his podcast to the value of the critique of productivity, but then usually reverts to characterizing anti-productivity arguments as saying that productivity is a capitalist invention to control workers. (Someone has doubtless said this on Twitter, but I've never seen a serious critique of productivity make this simplistic of an argument.) On the anti-productivity side, as it's commonly called, I've seen a lot of new writing in the past couple of years that tries to break the connection between productivity and human worth so endemic to US society. This is not a new analysis; disabled writers have been making this point for decades, it's present in both Keynes and in Galbraith's The Affluent Society, and Kathi Weeks's The Problem with Work traces some of its history in Marxist thought. But what does feel new to me is its widespread mainstream appearance in newspaper articles, viral blog posts, and books such as Jenny Odell's How to Do Nothing and Devon Price's Laziness Does Not Exist. The pushback against defining life around productivity is having a moment. Entering this discussion is Madeleine Dore's I Didn't Do the Thing Today. Dore is the author of the Extraordinary Routines blog and host of the Routines and Ruts podcast. Extraordinary Routines began as a survey of how various people organize their daily lives. I Didn't Do the Thing Today is, according to the preface, a summary of the thoughts Dore has had about her own life and routines as a result of those interviews. As you might guess from the subtitle (Letting Go of Productivity Guilt), Dore's book is superficially on the anti-productivity side. Its chapters are organized around gentle critiques of productivity concepts, with titles like "The Hopeless Search for the Ideal Routine," "The Myth of Balance," or "The Harsh Rules of Discipline." But I think anti-productivity is a poor name for this critique; its writers are not opposed to being productive, only to its position as an all-consuming focus and guilt-generating measure of personal worth. Dore structures most chapters by naming an aspect, goal, or concern of a life defined by productivity, such as wasted time, ambition, busyness, distraction, comparison, or indecision. Each chapter sketches the impact of that idea and then attempts to gently dismantle the grip that it may have on the reader's life. All of these discussions are nuanced; it's rare for Dore to say that one of these aspects has no value, and she anticipates numerous objections. But her overarching goal is to help the reader be more comfortable with imperfection, more willing to live in the moment, and less frustrated with the limitations of life and the human brain. If striving for productivity is like lifting weights, Dore's diagnosis is that we've tried too hard for too long, and have overworked that muscle until it is cramping. This book is a gentle massage to induce the muscle to relax and let go. Whether this will work is, as with all self-help books, individual. I found it was best read in small quantities, perhaps a chapter per day, since it otherwise began feeling too much the same. I'm also not the ideal audience; Dore is a creative freelancer and primarily interviewed other creative people, which I think has a different sort of productivity rhythm than the work that I do. She's also not a planner to the degree that I am; more on that below. And yet, I found this book worked on me anyway. I can't say that I was captivated all the way through, but I found myself mentally relaxing while I was reading it, and I may re-read some chapters from time to time. How does this relate to the genre of productivity self-help? With less conflict than I think productivity writers believe, although there seems to be one foundational difference of perspective. Dore is not opposed to accomplishing things, or even to systems that help people accomplish things. She is more attuned than the typical productivity writer to the guilt and frustration that can accumulate when one has a day in which one does not do the thing, but her goal is not to talk you out of attempting things. It is, instead, to convince you to hold those attempts and goals more lightly, to allow them to move and shift and change, and to not treat a failure to do the thing today as a reason for guilt. This is wholly compatible with standard productivity advice. It's adding nuance at one level of abstraction higher: how tightly to cling to productivity goals, and what to do when they don't work out. Cramping muscles are not strong muscles capable of lifting heavy things. If one can massage out the cramp, one's productivity by even the strict economic definition may improve. Where I do see a conflict is that most productivity writers are planners, and Dore is not. This is, I think, a significant blind spot in productivity self-help writing. Cal Newport, for example, advocates time-block planning, where every hour of the working day has a job. David Allen advocates a complex set of comprehensive lists and well-defined next actions. Mark Forster builds a flurry of small systems for working through lists. The standard in productivity writing is to to add structure to your day and cultivate the self-discipline required to stick to that structure. For many people, including me, this largely works. I'm mostly a planner, and when my life gets chaotic, adding more structure and focusing on that structure helps me. But the productivity writers I've read are quite insistent that their style of structure will work for everyone, and on that point I am dubious. Newport, for example, advocates time-block planning for everyone without exception, insisting that it is the best way to structure a day. Dore, in contrast, describes spending years trying to perfect a routine before realizing that elastic possibilities work better for her than routines. For those who are more like Dore than Newport, I Didn't Do the Thing Today is more likely to be helpful than Newport's instructions. This doesn't make Newport's ideas wrong; it simply makes them not universal, something that the productivity self-help genre seems to have trouble acknowledging. Even for readers like myself who prefer structure, I Didn't Do the Thing Today is a valuable corrective to the emphasis on every-better systems. For those who never got along with too much structure, I think it may strike a chord. The standard self-help caveat still applies: Dore has the most to say to people who are in a similar social class and line of work as her. I'm not sure this book will be of much help to someone who has to juggle two jobs with shift work and child care, where the problem is more sharp external constraints than internalized productivity guilt. But for its target audience, I think it's a valuable, calming message. Dore doesn't have a recipe to sort out your life, but may help you feel better about the merits of life unsorted. Rating: 7 out of 10

Michael Ablassmeier: Qemu backup on Debian Bullseye

In my last article i showed how to use the new features included in Debian Bullseye to easily create backups of your libvirt managed domains. A few years ago as this topic came to my interest, i also implemented a rather small utility (POC) to create full and incremental backups from standalone qemu processes: qmpbackup The workflow for this is a little bit different from the approach i have taken with virtnbdbackup. While with libvirt managed virtual machines, the libvirt API provides all necessary API calls to create backups, a running qemu process only provides the QMP protocol socket to get things going. Using the QMP protocol its possible to create bitmaps for the attached disks and make Qemu push the contents of the bitmaps to a specified target directory. As the bitmaps keep track of the changes on the attached block devices, you can create incremental backups too. The nice thing here is that the Qemu process actually does this all by itself and you dont have to care about which blocks are dirty, like you would have to do with the Pull based approach. So how does it work? The utility requires to start your qemu process with an active QMP socket attached, like so:
 qemu-system-<arch> <options> -qmp unix:/tmp/socket,server,nowait
Now you can easily make qemu push the latest data for a created bitmap to a given target directory:
# qmpbackup --socket /tmp/socket backup --level full --target /tmp/backup/
[2022-01-27 19:41:33,819]    INFO  Version: 0.10
[2022-01-27 19:41:33,819]    INFO  Qemu version: [5.0.2] [Debian 1:5.2+dfsg-11+deb11u1]
[2022-01-27 19:41:33,825]    INFO  Guest Agent socket connected
[2022-01-27 19:41:33,825]    INFO  Trying to ping guest agent
[2022-01-27 19:41:38,827] WARNING  Unable to reach Guest Agent: cant freeze file systems.
[2022-01-27 19:41:38,828]    INFO  Backup target directory: /tmp/backup/
[2022-01-27 19:41:38,828]    INFO  FULL Backup operation: "/tmp/backup//ide0-hd0/FULL-1643308898"
[2022-01-27 19:41:38,836]    INFO  Wrote Offset: 0% (0 of 2147483648)
[2022-01-27 19:41:39,838]    INFO  Wrote Offset: 25% (541065216 of 2147483648)
[2022-01-27 19:41:40,840]    INFO  Wrote Offset: 33% (701890560 of 2147483648)
[2022-01-27 19:41:41,841]    INFO  Wrote Offset: 40% (867041280 of 2147483648)
[2022-01-27 19:41:42,844]    INFO  Wrote Offset: 50% (1073741824 of 2147483648)
[2022-01-27 19:41:43,846]    INFO  Wrote Offset: 59% (1269760000 of 2147483648)
[2022-01-27 19:41:44,847]    INFO  Wrote Offset: 75% (1610612736 of 2147483648)
[2022-01-27 19:41:45,848]    INFO  Saved disk: [ide0-hd0]
The resulting directory now contains a full backup image of the disk attached. From this point on, its possible to create further incremental backups:
# qmpbackup  --socket /tmp/socket backup --level inc --target /tmp/backup/
[2022-01-27 19:42:03,930]    INFO  Version: 0.10
[2022-01-27 19:42:03,931]    INFO  Qemu version: [5.0.2] [Debian 1:5.2+dfsg-11+deb11u1]
[2022-01-27 19:42:03,933]    INFO  Guest Agent socket connected
[2022-01-27 19:42:03,933]    INFO  Trying to ping guest agent
[2022-01-27 19:42:08,938] WARNING  Unable to reach Guest Agent: cant freeze file systems.
[2022-01-27 19:42:08,939]    INFO  Backup target directory: /tmp/backup/
[2022-01-27 19:42:08,939]    INFO  INC Backup operation: "/tmp/backup//ide0-hd0/INC-1643308928"
[2022-01-27 19:42:08,953]    INFO  Wrote Offset: 0% (0 of 1835008)
[2022-01-27 19:42:09,957]    INFO  Saved disk: [ide0-hd0]
The target directory will now have multiple data backups:
/tmp/backup/ide0-hd0/
  FULL-1643308898
  INC-1643308928
Restoring the image Using the qmprebase utility you can now rebase the images to the latest state. The --dry-run option gives an good impression which command sequences are required, if one wants only rebase to a specific incremental backup, thats possible using the --until option.
# qmprebase rebase --dir /tmp/backup/ide0-hd0/ --dry-run
[2022-01-27 17:18:08,790]    INFO  Version: 0.10
[2022-01-27 17:18:08,790]    INFO  Dry run activated, not applying any changes
[2022-01-27 17:18:08,790]    INFO  qemu-img check /tmp/backup/ide0-hd0/INC-1643308928
[2022-01-27 17:18:08,791]    INFO  qemu-img rebase -b "/tmp/backup/ide0-hd0/FULL-1643308898" "/tmp/backup/ide0-hd0/INC-1643308928" -u
[2022-01-27 17:18:08,791]    INFO  qemu-img commit "/tmp/backup/ide0-hd0/INC-1643308928"
[2022-01-27 17:18:08,791]    INFO  Rollback of latest [FULL]<-[INC] chain complete, ignoring older chains
[2022-01-27 17:18:08,791]    INFO  Image files rollback successful.
Filesystem consistency The backup utility also supports to freeze and thaw the virtual machines file system in case qemu is started with a guest agent socket and the guest agent is reachable during backup operation. Check out the README for the full feature set.

26 January 2022

Gunnar Wolf: Progvis Now in Debian proper! (unstable)

Progvis finally made it into Debian! What is it, you ask? It is a great tool to teach about memory management and concurrency. I first saw progvis in the poster presentation his author, Filip Str mb ck, did last year at the 52nd ACM Technical Sympossium on Computer Science Education (SIGCSE), immediately recognizing it as a tool I wanted to use at my classes, and being it free software, make it available for all interested Debian users. Quoting from Progvis Web page:
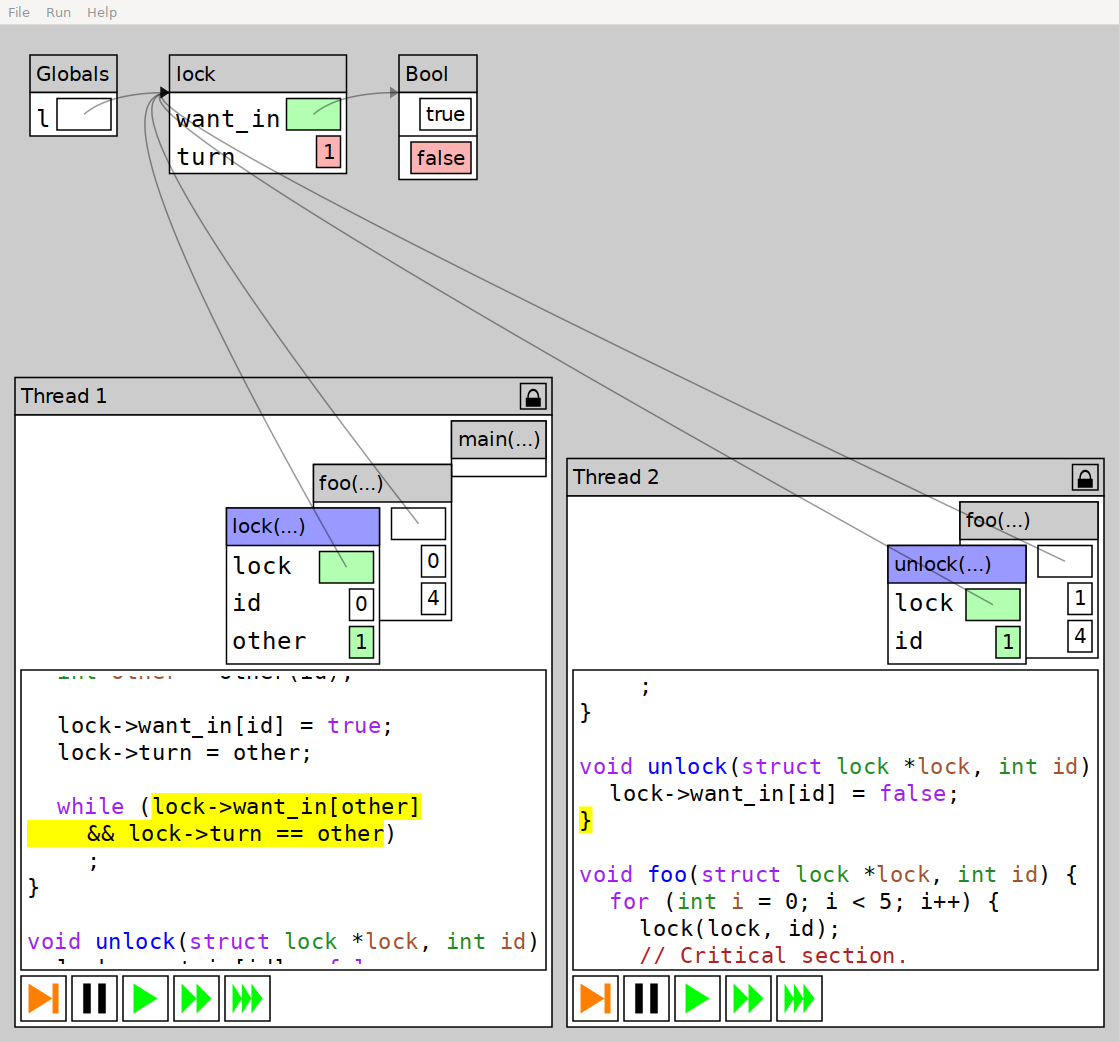
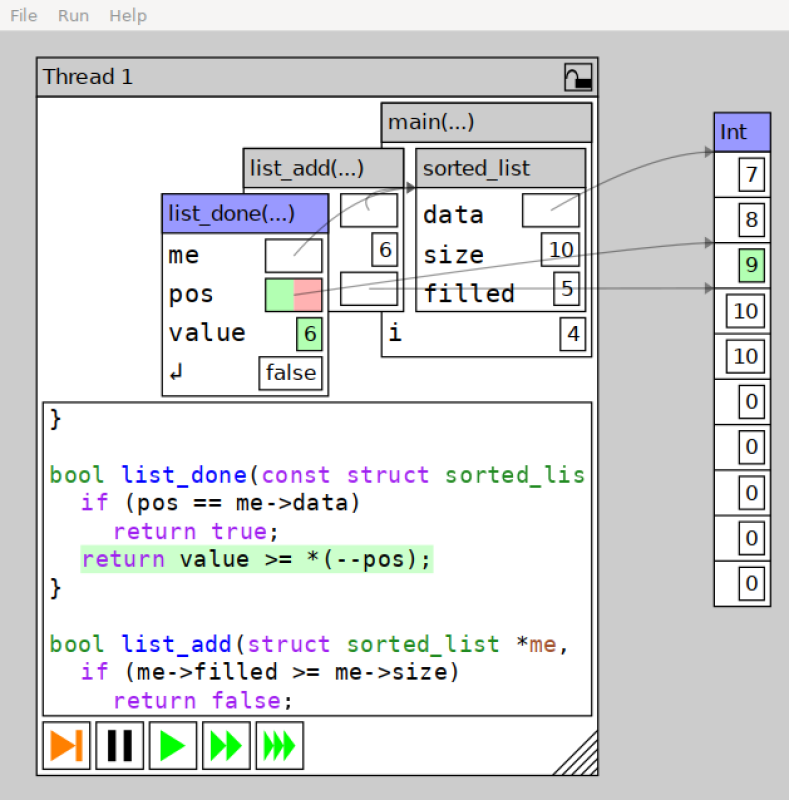
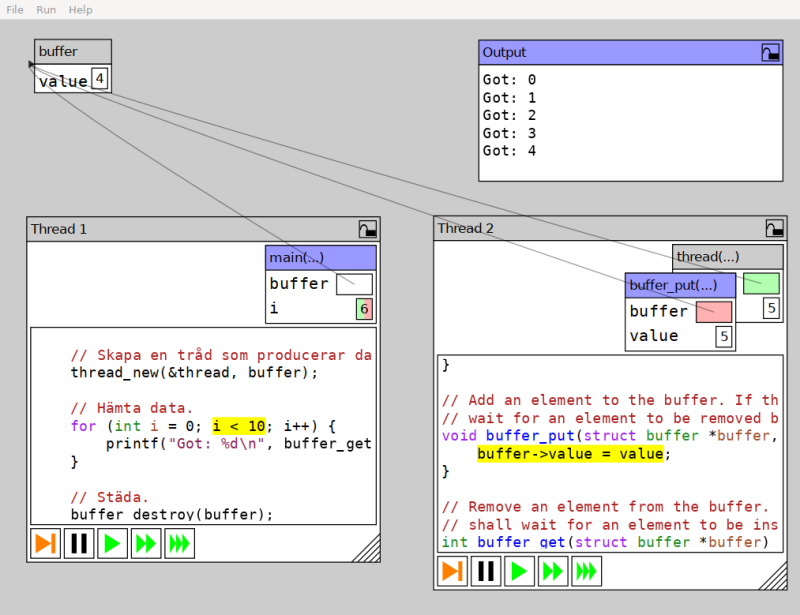
This is a program visualization tool aimed at concurrent programs and related issues. The tool itself is mostly language agnostic, and relies on Storm to compile the provided code and provide basic debug information. The generated code is then inspected and instrumented to provide an experience similar to a basic debugger. The tool emphasizes a visual representation of the object hierarchy that is manipulated by the executed program to make it easy to understand how it looks. In particular, a visual representation is beneficial over a text representation since it makes it easier to find shared data that might need to be synchronized in a concurrent program. As mentioned, the tool is aimed at concurrent programs. Therefore, it allows spawning multiple threads running the same program to see if that affects the program s execution (this is mostly interesting if global variables are used). Furthermore, any spawned threads also appear in the tool, and the user may control them independently to explore possible race conditions or other synchronization errors. If enabled from the menu bar, the tool keeps track of reads and writes to the data structure in order to highlight basic race conditions in addition to deadlocks.
So, what is this Storm thing? Filip promptly informed me that Progvis is not just a pedagogical tool Or rather, that it is part of something bigger. Progvis is a program built using the Storm programming language platform is more than a compiler; it presents as a framework for creating languages, designed to make easy to implement languages that can be extended with new syntax and semantics. Storm is much more than what I have explored, and can be used as an interactive compiler, a language server used as a service for highlighting and completing in IDEs. But I won t dig much more into Storm (which is, of course, now also available in Debian as well as the libraries built from the same source). Back to progvis: It implements a very-close-to-C++ language, with some details to better suit its purpose (i.e. instead of using the usual pthread implementation, an own thread model is used; i.e. thread creation is handled via int thread_id = thread_name(funcname, &params) instead of the more complex pthread_create() function (including details such as the thread object being passed as by reference as a parameter) All in all, while I have not yet taken full advantage of this tool in my teaching, it has helped me show somewhat hard to grasp concepts such as: All in all, a great tool. I hope you find it useful and enjoyable as well! PS- I suggest you to install the progvis-examples package to get started. You will find some dozens of sample programs in /usr/share/doc/progvis-examples/examples; playing with them will help you better understand the tool and be able to better write your own programs.

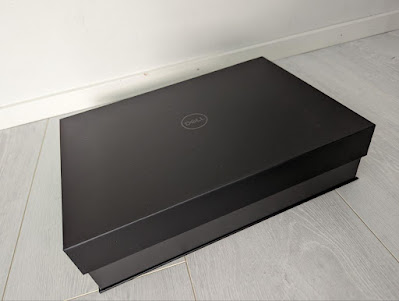
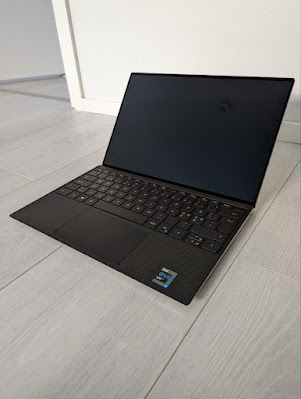
Timo Jyrinki: Unboxing Dell XPS 13 - openSUSE Tumbleweed alongside preinstalled Ubuntu

A look at the 2021 model of Dell XPS 13 - available with Linux pre-installed
I received a new laptop for work - a Dell XPS 13. Dell has been long famous for offering certain models with pre-installed Linux as a supported option, and opting for those is nice for moving some euros/dollars from certain PC desktop OS monopoly towards Linux desktop engineering costs. Notably Lenovo also offers Ubuntu and Fedora options on many models these days (like Carbon X1 and P15 Gen 2).
black box

opened box

accessories and a leaflet about Linux support

laptop lifted from the box, closed

laptop with lid open

Ubuntu running

openSUSE runnin
Obviously a smooth, ready-to-rock Ubuntu installation is nice for most people already, but I need openSUSE, so after checking everything is fine with Ubuntu, I continued to install openSUSE Tumbleweed as a dual boot option. As I m a funny little tinkerer, I obviously went with some special things. I wanted:
  • Ubuntu to remain as the reference supported OS on a small(ish) partition, useful to compare to if trying out new development versions of software on openSUSE and finding oddities.
  • openSUSE as the OS consuming most of the space.
  • LUKS encryption for openSUSE without LVM.
  • ext4 s new fancy fast_commit feature in use during filesystem creation.
  • As a result of all that, I ended up juggling back and forth installation screens a couple of times (even more than shown below, and also because I forgot I wanted to use encryption the first time around).
First boots to pre-installed Ubuntu and installation of openSUSE Tumbleweed as the dual-boot option:
(if the embedded video is not shown, use a direct link)
Some notes from the openSUSE installation:
  • openSUSE installer s partition editor apparently does not support resizing or automatically installing side-by-side another Linux distribution, so I did part of the setup completely on my own.
  • Installation package download hanged a couple of times, only passed when I entered a mirror manually. On my TW I ve also noticed download problems recently, there might be a problem with some mirror I need to escalate.
  • The installer doesn t very clearly show encryption status of the target installation - it took me a couple of attempts before I even noticed the small encrypted column and icon (well, very small, see below), which also did not spell out the device mapper name but only the main partition name. In the end it was going to do the right thing right away and use my pre-created encrypted target partition as I wanted, but it could be a better UX. Then again I was doing my very own tweaks anyway.
  • Let s not go to the details why I m so old-fashioned and use ext4 :)
  • openSUSE s installer does not work fine with HiDPI screen. Funnily the tty consoles seem to be fine and with a big font.
  • At the end of the video I install the two GNOME extensions I can t live without, Dash to Dock and Sound Input & Output Device Chooser.

23 January 2022

Matthieu Caneill: Debsources, python3, and funky file names

Rumors are running that python2 is not a thing anymore. Well, I'm certainly late to the party, but I'm happy to report that sources.debian.org is now running python3. Wait, it wasn't? Back when development started, python3 was very much a real language, but it was hard to adopt because it was not supported by many libraries. So python2 was chosen, meaning print-based debugging was used in lieu of print()-based debugging, and str were bytes, not unicode. And things were working just fine. One day python2 EOL was announced, with a date far in the future. Far enough to procrastinate for a long time. Combine this with a codebase that is stable enough to not see many commits, and the fact that Debsources is a volunteer-based project that happens at best on week-ends, and you end up with a dormant software and a missed deadline. But, as dormant as the codebase is, the instance hosted at sources.debian.org is very popular and gets 200k to 500k hits per day. Largely enough to be worth a proper maintenance and a transition to python3. Funky file names While transitioning to python3 and juggling left and right with str, bytes and unicode for internal objects, files, database entries and HTTP content, I stumbled upon a bug that has been there since day 1. Quick recap if you're unfamiliar with this tool: Debsources displays the content of the source packages in the Debian archive. In other words, it's a bit like GitHub, but for the Debian source code. And some pieces of software out there, that ended up in Debian packages, happen to contain files whose names can't be decoded to UTF-8. Interestingly enough, there's no such thing as a standard for file names: with a few exceptions that vary by operating system, any sequence of bytes can be a legit file name. And some sequences of bytes are not valid UTF-8. Of course those files are rare, and using ASCII characters to name a file is a much more common practice than using bytes in a non-UTF-8 character encoding. But when you deal with almost 100 million files on which you have no control (those files come from free software projects, and make their way into Debian without any renaming), it happens. Now back to the bug: when trying to display such a file through the web interface, it would crash because it can't convert the file name to UTF-8, which is needed for the HTML representation of the page. Bugfix An often valid approach when trying to represent invalid UTF-8 content is to ignore errors, and replace them with ? or . This is what Debsources actually does to display non-UTF-8 file content. Unfortunately, this best-effort approach is not suitable for file names, as file names are also identifiers in Debsources: among other places, they are part of URLs. If an URL were to use placeholder characters to replace those bytes, there would be no deterministic way to match it with a file on disk anymore. The representation of binary data into text is a known problem. Multiple lossless solutions exist, such as base64 and its variants, but URLs looking like https://sources.debian.org/src/Y293c2F5LzMuMDMtOS4yL2Nvd3NheS8= are not readable at all compared to https://sources.debian.org/src/cowsay/3.03-9.2/cowsay/. Plus, not backwards-compatible with all existing links. The solution I chose is to use double-percent encoding: this allows the representation of any byte in an URL, while keeping allowed characters unchanged - and preventing CGI gateways from trying to decode non-UTF-8 bytes. This is the best of both worlds: regular file names get to appear normally and are human-readable, and funky file names only have percent signs and hex numbers where needed. Here is an example of such an URL: https://sources.debian.org/src/aspell-is/0.51-0-4/%25EDslenska.alias/. Notice the %25ED to represent the percentage symbol itself (%25) followed by an invalid UTF-8 byte (%ED). Transitioning to this was quite a challenge, as those file names don't only appear in URLs, but also in web pages themselves, log files, database tables, etc. And everything was done with str: made sense in python2 when str were bytes, but not much in python3. What are those files? What's their network? I was wondering too. Let's list them!
import os
with open('non-utf-8-paths.bin', 'wb') as f:
    for root, folders, files in os.walk(b'/srv/sources.debian.org/sources/'):
        for path in folders + files:
            try:
                path.decode('utf-8')
            except UnicodeDecodeError:
                f.write(root + b'/' + path + b'\n')
Running this on the Debsources main instance, which hosts pretty much all Debian packages that were part of a Debian release, I could find 307 files (among a total of almost 100 million files). Without looking deep into them, they seem to fall into 2 categories: That last point hits home, as it was clearly lacking in Debsources. A funky file name is now part of its test suite. ;)

20 January 2022

Dirk Eddelbuettel: RQuantLib 0.4.15: Regular Update

A new release 0.4.15 of RQuantLib arrived at CRAN earlier today, and has been uploaded to Debian as well. QuantLib is a very comprehensice free/open-source library for quantitative finance; RQuantLib connects it to the R environment and language. The release of RQuantLib comes four months after the previous release, and brings a momitor update for the just-released QuantLib 1.2.5 version along with a few small cleanups to calendars and daycounters.

Changes in RQuantLib version 0.4.15 (2022-01-19)
  • Changes in RQuantLib code:
    • Calendar support has been updated and completed to current QuantLib standards (Dirk in #161)
    • More daycounters have been added (Kai Lin in #163 fixing #162, #164)
    • The bonds pricers were update to changes in QuantLib 1.25 (Dirk)
  • Changes in RQuantLib package and setup:
    • Some package metadata was removed from the README.md (Dirk)

Courtesy of my CRANberries, there is also a diffstat report for the this release. As always, more detailed information is on the RQuantLib page. Questions, comments etc should go to the new rquantlib-devel mailing list. Issue tickets can be filed at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

19 January 2022

Joerg Jaspert: Funny CPU usage

Munin plugin and it s CPU usage (shell fixup) So at work we do have a munin server running, and one of the graphs we do for every system is a network statistics one with a resolution of 1 second. That s a simple enough script to have, and it is working nicely - on 98% of our machines. You just don t notice the data gatherer at all, so that we also have some other graphs done with a 1 second resolution. For some, this really helps.

Basics The basic code for this is simple. There is a bunch of stuff to start the background gathering, some to print out the config, and some to hand out the data when munin wants it. Plenty standard. The interesting bit that goes wrong and uses too much CPU on one Linux Distribution is this:
run_acquire()  
   echo "$$" > $ pidfile 
   while :; do
     TSTAMP=$(date +%s)
     echo $ IFACE _tx.value $ TSTAMP :$(cat /sys/class/net/$ IFACE /statistics/tx_bytes ) >> $ cache 
     echo $ IFACE _rx.value $ TSTAMP :$(cat /sys/class/net/$ IFACE /statistics/rx_bytes ) >> $ cache 
     # Sleep for the rest of the second
     sleep 0.$(printf '%04d' $((10000 - 10#$(date +%4N))))
   done
 
That code works, and none of Debian wheezy, stretch and buster as well as RedHat 6 or 7 shows anything, it just works, no noticable load generated. Now, Oracle Linux 7 thinks differently. The above code run there generates between 8 and 15% CPU usage (on fairly recent Intel CPUs, but that shouldn t matter). (CPU usage measured with the highly accurate use of top and looking what it tells ) Whyever.

Fixing Ok, well, the code above isn t all the nicest shell, actually. There is room for improvement. But beware, the older the bash, the less one can fix it.
  • So, first of, there are two useless uses of cat. Bash can do that for us, just use the $(< /PATH/TO/FILE ) way.
  • Oh, Bash5 knows the epoch directly, we can replace the date call for the timestamp and use $ EPOCHSECONDS
  • Too bad Bash4 can t do that. But hey, it s builtin printf can help out, a nice TSTAMP=$(printf %(%s)T\n -1) works.
  • Unfortunately, Bash4.2 and later, not 4.1, and meh, we have a 4.1 system, so that has to stay with the date call there.
Taking that, we end up with 3 different possible versions, depending on the Bash on the system.
obtain5()  
  ## Purest bash version, Bash can tell us epochs directly
  echo $ IFACE _tx.value $ EPOCHSECONDS :$(</sys/class/net/$ IFACE /statistics/tx_bytes) >> $ cache 
  echo $ IFACE _rx.value $ EPOCHSECONDS :$(</sys/class/net/$ IFACE /statistics/rx_bytes) >> $ cache 
  # Sleep for the rest of the second
  sleep 0.$(printf '%04d' $((10000 - 10#$(date +%4N))))
 
obtain42()  
  ## Bash cant tell us epochs directly, but the builtin printf can
  TSTAMP=$(printf '%(%s)T\n' -1)
  echo $ IFACE _tx.value $ TSTAMP :$(</sys/class/net/$ IFACE /statistics/tx_bytes) >> $ cache 
  echo $ IFACE _rx.value $ TSTAMP :$(</sys/class/net/$ IFACE /statistics/rx_bytes) >> $ cache 
  # Sleep for the rest of the second
  sleep 0.$(printf '%04d' $((10000 - 10#$(date +%4N))))
 
obtain41()  
  ## Bash needs help from a tool to get epoch, means one exec() all the time
  TSTAMP=$(date +%s)
  echo $ IFACE _tx.value $ TSTAMP :$(</sys/class/net/$ IFACE /statistics/tx_bytes) >> $ cache 
  echo $ IFACE _rx.value $ TSTAMP :$(</sys/class/net/$ IFACE /statistics/rx_bytes) >> $ cache 
  # Sleep for the rest of the second
  sleep 0.$(printf '%04d' $((10000 - 10#$(date +%4N))))
 
run_acquire()  
   echo "$$" > $ pidfile 
   case $ BASH_VERSINFO[0]  in
     5) while :; do
          obtain5
        done
        ;;
     4) if [[ $ BASHVERSION[1]  -ge 2 ]]; then
          while :; do
            obtain42
          done
        else
          while :; do
            obtain41
          done
        fi
        ;;
   esac
 

Does it help? Oh yes, it does. Oracle Linux 7 appears to use Bash 4.2, so uses obtain42 and hey, removing one date and two cat calls, and it has a sane CPU usage of 0 (again, highly accurate number generated from top ). Appears OL7 is doing heck-what-do-i-know extra, when calling other tools, for whatever gains, removing that does help (who would have thought). (None of RedHat or Oracle Linux has SELinux turned on, so that one shouldn t bite. But it is clear OL7 doing something extra for everything that bash spawns.)

16 January 2022

Russell Coker: SSD Endurance

I previously wrote about the issue of swap potentially breaking SSD [1]. My conclusion was that swap wouldn t be a problem as no normally operating systems that I run had swap using any significant fraction of total disk writes. In that post the most writes I could see was 128GB written per day on a 120G Intel SSD (writing the entire device once a day). My post about swap and SSD was based on the assumption that you could get many thousands of writes to the entire device which was incorrect. Here s a background on the terminology from WD [2]. So in the case of the 120G Intel SSD I was doing over 1 DWPD (Drive Writes Per Day) which is in the middle of the range of SSD capability, Intel doesn t specify the DWPD or TBW (Tera Bytes Written) for that device. The most expensive and high end NVMe device sold by my local computer store is the Samsung 980 Pro which has a warranty of 150TBW for the 250G device and 600TBW for the 1TB device [3]. That means that the system which used to have an Intel SSD would have exceeded the warranty in 3 years if it had a 250G device. My current workstation has been up for just over 7 days and has averaged 110GB written per day. It has some light VM use and the occasional kernel compile, a fairly typical developer workstation. It s storage is 2*Crucial 1TB NVMe devices in a BTRFS RAID-1, the NVMe devices are the old series of Crucial ones and are rated for 200TBW which means that they can be expected to last for 5 years under the current load. This isn t a real problem for me as the performance of those devices is lower than I hoped for so I will buy faster ones before they are 5yo anyway. My home server (and my wife s workstation) is averaging 325GB per day on the SSDs used for the RAID-1 BTRFS filesystem for root and for most data that is written much (including VMs). The SSDs are 500G Samsung 850 EVOs [4] which are rated at 150TBW which means just over a year of expected lifetime. The SSDs are much more than a year old, I think Samsung stopped selling them more than a year ago. Between the 2 SSDs SMART reports 18 uncorrectable errors and btrfs device stats reports 55 errors on one of them. I m not about to immediately replace them, but it appears that they are well past their prime. The server which runs my blog (among many other things) is averaging over 1TB written per day. It currently has a RAID-1 of hard drives for all storage but it s previous incarnation (which probably had about the same amount of writes) had a RAID-1 of enterprise SSDs for the most written data. After a few years of running like that (and some time running with someone else s load before it) the SSDs became extremely slow (sustained writes of 15MB/s) and started getting errors. So that s a pair of SSDs that were burned out. Conclusion The amounts of data being written are steadily increasing. Recent machines with more RAM can decrease storage usage in some situations but that doesn t compare to the increased use of checksummed and logged filesystems, VMs, databases for local storage, and other things that multiply writes. The amount of writes allowed under warranty isn t increasing much and there are new technologies for larger SSD storage that decrease the DWPD rating of the underlying hardware. For the systems I own it seems that they are all going to exceed the rated TBW for the SSDs before I have other reasons to replace them, and they aren t particularly high usage systems. A mail server for a large number of users would hit it much earlier. RAID of SSDs is a really good thing. Replacement of SSDs is something that should be planned for and a way of swapping SSDs to less important uses is also good (my parents have some SSDs that are too small for my current use but which work well for them). Another thing to consider is that if you have a server with spare drive bays you could put some extra SSDs in to spread the wear among a larger RAID-10 array. Instead of having a 2*SSD BTRFS RAID-1 for a server you could have 6*SSD to get a 3* longer lifetime than a regular RAID-1 before the SSDs wear out (BTRFS supports this sort of thing). Based on these calculations and the small number of errors I ve seen on my home server I ll add a 480G SSD I have lying around to the array to spread the load and keep it running for a while longer.

11 January 2022

Ritesh Raj Sarraf: ThinkPad AMD Debian

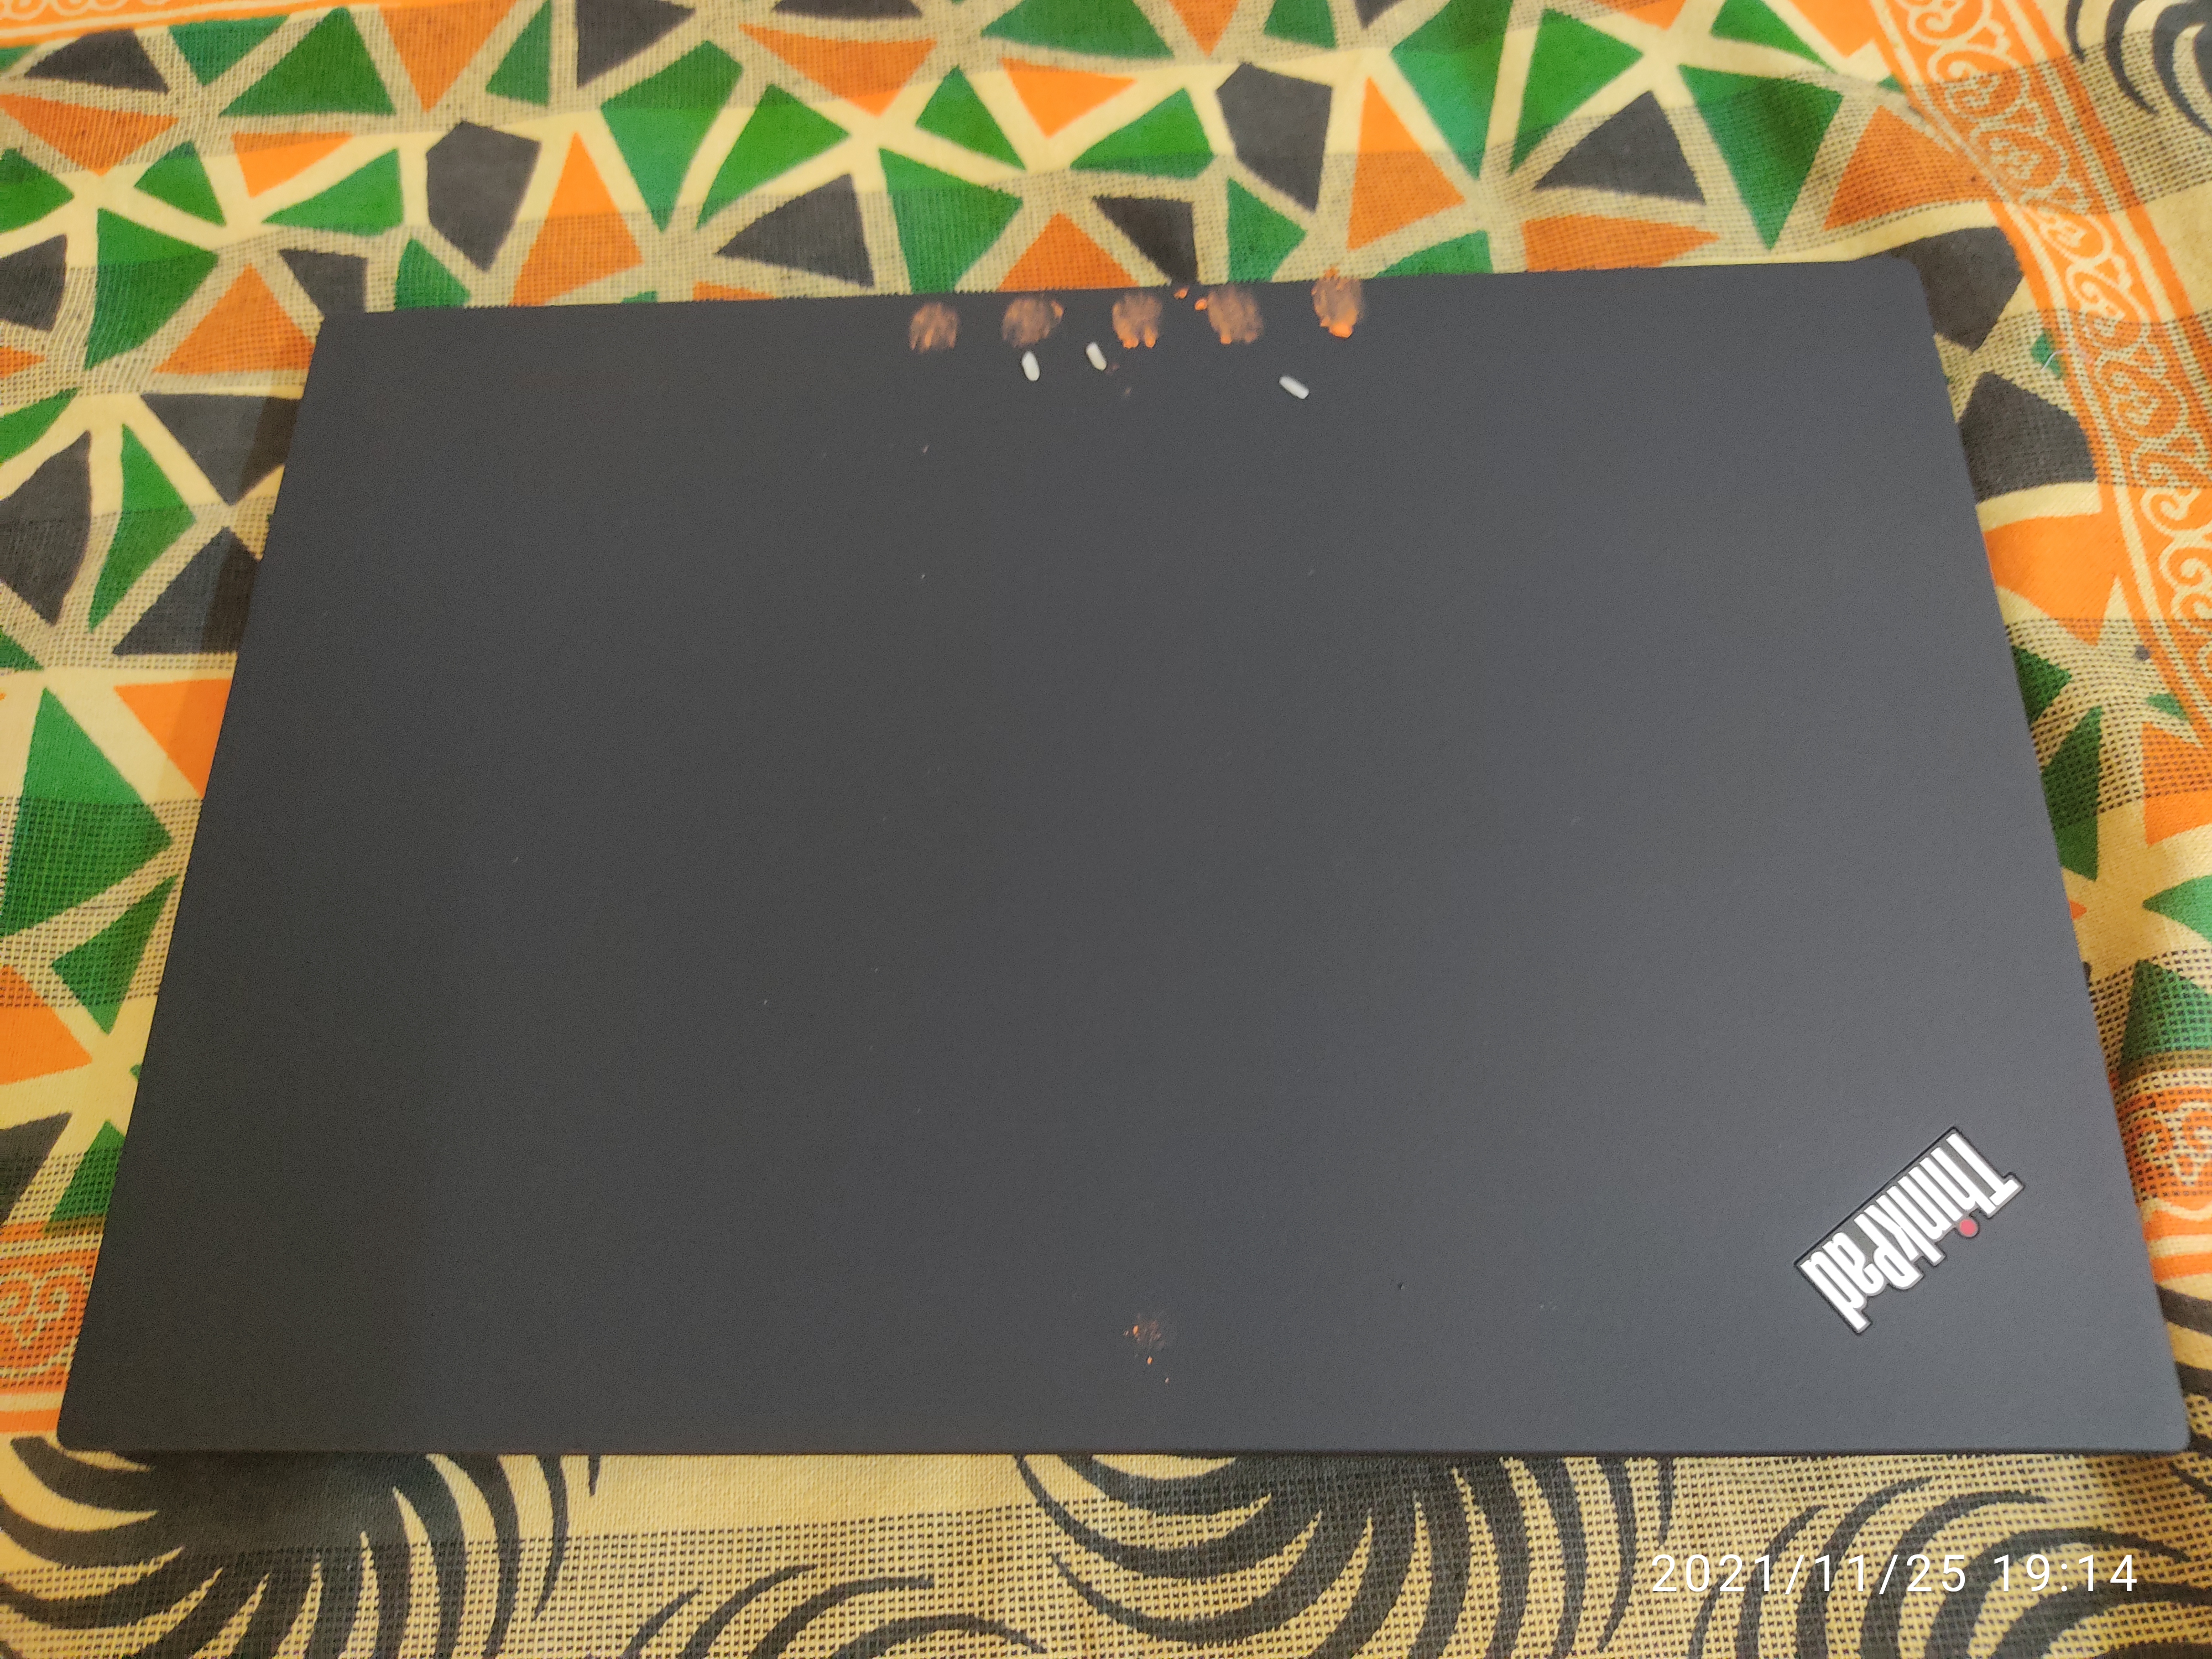
After a hiatus of 6 years, it was nice to be back with the ThinkPad. This blog post briefly touches upon my impressions with the current generation ThinkPad T14 Gen2 AMD variant.
ThinkPad T14 Gen2 AMD

Lenovo It took 8 weeks to get my hands on the machine. Given the pandemic, restrictions and uncertainities, not sure if I should call it an ontime delivery. This was a CTO - Customise-to-order; so was nice to get rid of things I really didn t care/use much. On the other side, it also meant I could save on some power. It also came comparatively cheaper overall.
  • No fingerprint reader
  • No Touch screen
There s still parts where Lenovo could improve. Or less frustate a customer. I don t understand why a company would provide a full customization option on their portal, while at the same time, not provide an explicit option to choose the make/model of the hardware one wants. Lenovo deliberately chooses to not show/specify which WiFi adapter one could choose. So, as I suspected, I ended up with a MEDIATEK Corp. Device 7961 wifi adapter.

AMD For the first time in my computing life, I m now using AMD at the core. I was pretty frustrated with annoying Intel Graphics bugs, so decided to take the plunge and give AMD/ATI a shot, knowing that the radeon driver does have decent support. So far, on the graphics side of things, I m glad that things look bright. The stock in-kernel radeon driver has been working perfect for my needs and I haven t had to tinker even once so far, in my 30 days of use. On the overall system performance, I have not done any benchmarks nor do I want to do. But wholly, the system performance is smooth.

Power/Thermal This is where things need more improvement on the AMD side. This AMD laptop terribly draws a lot of power in suspend mode. And it isn t just this machine, but also the previous T14 Gen1 which has similar problems. I m not sure if this is a generic ThinkPad problem, or an AMD specific problem. But coming from the Dell XPS 13 9370 Intel, this does draw a lot lot more power. So much, that I chose to use hibernation instead. Similarly, on the thermal side, this machine doesn t cool down well as compared the the Dell XPS Intel one. On an idle machine, its temperature are comparatively higher. Looking at powertop reports, it does show to consume an average of 10 watts power even while idle. I m hoping these are Linux ingeration issues and that Lenovo/AMD will improve things in the coming months. But given the user feedback on the ThinkPad T14 Gen1 thread, it may just be wishful thinking.

Linux The overall hardware support has been surprisingly decent. The MediaTek WiFi driver had some glitches but with Linux 5.15+, things have considerably improved. And I hope the trend will continue with forthcoming Linux releases. My previous device driver experience with MediaTek wasn t good but I took the plunge, considering that in the worst scenario I d have the option to swap the card. There s a lot of marketing about Linux + Intel. But I took a jibe with Linux + AMD. There are glitches but nothing so far that has been a dealbreaker. If anything, I wish Lenovo/AMD would seriously work on the power/thermal issues.

Migration Other than what s mentioned above, I haven t had any serious issues. I may have had some rare occassional hangs but they ve been so infrequent that I haven t spent time to investigate those. Upon receiving the machine, my biggest requirement was how to switch my current workstation from Dell XPS to Lenovo ThinkPad. I ve been using btrfs for some time now. And over the years, built my own practise on how to structure it. Things like, provisioning [sub]volumes, based on use cases is one thing I see. Like keeping separate subvols for: cache/temporary data, copy-on-write data , swap etc. I wish these things could be simplified; either on the btrfs tooling side or some different tool on top of it. Below is filtered list of subvols created over years, that were worthy of moving to the new machine.
rrs@priyasi:~$ cat btrfs-volume-layout 
ID 550 gen 19166 top level 5 path home/foo/.cache
ID 552 gen 1522688 top level 5 path home/rrs
ID 553 gen 1522688 top level 552 path home/rrs/.cache
ID 555 gen 1426323 top level 552 path home/rrs/rrs-home/Libvirt-Images
ID 618 gen 1522672 top level 5 path var/spool/news
ID 634 gen 1522670 top level 5 path var/tmp
ID 635 gen 1522688 top level 5 path var/log
ID 639 gen 1522226 top level 5 path var/cache
ID 992 gen 1522670 top level 5 path disk-tmp
ID 1018 gen 1522688 top level 552 path home/rrs/NoBackup
ID 1196 gen 1522671 top level 5 path etc
ID 23721 gen 775692 top level 5 path swap
18:54                      

btrfs send/receive This did come in handy but I sorely missed some feature. Maybe they aren t there, or are there and I didn t look close enough. Over the years, different attributes were set to different subvols. Over time I forget what feature was added where. But from a migration point of view, it d be nice to say, Take this volume and take it with all its attributes . I didn t find that functionality in send/receive. There s get/set-property which I noticed later but by then it was late. So some sort of tooling, ideally something like btrfs migrate or somesuch would be nicer. In the file system world, we already have nice tools to take care of similar scenarios. Like with rsync, I can request it to carry all file attributes. Also, iirc, send/receive works only on ro volumes. So there s more work one needs to do in:
  1. create ro vol
  2. send
  3. receive
  4. don t forget to set rw property
  5. And then somehow find out other properties set on each individual subvols and [re]apply the same on the destination
I wish this all be condensed into a sub-command. For my own sake, for this migration, the steps used were:
user@debian:~$ for volume in  sudo btrfs sub list /media/user/TOSHIBA/Migrate/   cut -d ' ' -f9   grep -v ROOTVOL   grep -v etc   grep -v btrbk ; do echo $volume; sud
o btrfs send /media/user/TOSHIBA/$volume   sudo btrfs receive /media/user/BTRFSROOT/ ; done            
Migrate/snapshot_disk-tmp
At subvol /media/user/TOSHIBA/Migrate/snapshot_disk-tmp
At subvol snapshot_disk-tmp
Migrate/snapshot-home_foo_.cache
At subvol /media/user/TOSHIBA/Migrate/snapshot-home_foo_.cache
At subvol snapshot-home_foo_.cache
Migrate/snapshot-home_rrs
At subvol /media/user/TOSHIBA/Migrate/snapshot-home_rrs
At subvol snapshot-home_rrs
Migrate/snapshot-home_rrs_.cache
At subvol /media/user/TOSHIBA/Migrate/snapshot-home_rrs_.cache
At subvol snapshot-home_rrs_.cache
ERROR: crc32 mismatch in command
Migrate/snapshot-home_rrs_rrs-home_Libvirt-Images
At subvol /media/user/TOSHIBA/Migrate/snapshot-home_rrs_rrs-home_Libvirt-Images
At subvol snapshot-home_rrs_rrs-home_Libvirt-Images
ERROR: crc32 mismatch in command
Migrate/snapshot-var_spool_news
At subvol /media/user/TOSHIBA/Migrate/snapshot-var_spool_news
At subvol snapshot-var_spool_news
Migrate/snapshot-var_lib_machines
At subvol /media/user/TOSHIBA/Migrate/snapshot-var_lib_machines
At subvol snapshot-var_lib_machines
Migrate/snapshot-var_lib_machines_DebianSidTemplate
..... snipped .....
And then, follow-up with:
user@debian:~$ for volume in  sudo btrfs sub list /media/user/BTRFSROOT/   cut -d ' ' -f9 ; do echo $volume; sudo btrfs property set -ts /media/user/BTRFSROOT/$volume ro false; done
ROOTVOL
ERROR: Could not open: No such file or directory
etc
snapshot_disk-tmp
snapshot-home_foo_.cache
snapshot-home_rrs
snapshot-var_spool_news
snapshot-var_lib_machines
snapshot-var_lib_machines_DebianSidTemplate
snapshot-var_lib_machines_DebSidArmhf
snapshot-var_lib_machines_DebianJessieTemplate
snapshot-var_tmp
snapshot-var_log
snapshot-var_cache
snapshot-disk-tmp
And then finally, renaming everything to match proper:
user@debian:/media/user/BTRFSROOT$ for x in snapshot*; do vol=$(echo $x   cut -d '-' -f2   sed -e "s _ / g"); echo $x $vol; sudo mv $x $vol; done
snapshot-var_lib_machines var/lib/machines
snapshot-var_lib_machines_Apertisv2020ospackTargetARMHF var/lib/machines/Apertisv2020ospackTargetARMHF
snapshot-var_lib_machines_Apertisv2021ospackTargetARM64 var/lib/machines/Apertisv2021ospackTargetARM64
snapshot-var_lib_machines_Apertisv2022dev3ospackTargetARMHF var/lib/machines/Apertisv2022dev3ospackTargetARMHF
snapshot-var_lib_machines_BusterArm64 var/lib/machines/BusterArm64
snapshot-var_lib_machines_DebianBusterTemplate var/lib/machines/DebianBusterTemplate
snapshot-var_lib_machines_DebianJessieTemplate var/lib/machines/DebianJessieTemplate
snapshot-var_lib_machines_DebianSidTemplate var/lib/machines/DebianSidTemplate
snapshot-var_lib_machines_DebianSidTemplate_var_lib_portables var/lib/machines/DebianSidTemplate/var/lib/portables
snapshot-var_lib_machines_DebSidArm64 var/lib/machines/DebSidArm64
snapshot-var_lib_machines_DebSidArmhf var/lib/machines/DebSidArmhf
snapshot-var_lib_machines_DebSidMips var/lib/machines/DebSidMips
snapshot-var_lib_machines_JenkinsApertis var/lib/machines/JenkinsApertis
snapshot-var_lib_machines_v2019 var/lib/machines/v2019
snapshot-var_lib_machines_v2019LinuxSupport var/lib/machines/v2019LinuxSupport
snapshot-var_lib_machines_v2020 var/lib/machines/v2020
snapshot-var_lib_machines_v2021dev3Slim var/lib/machines/v2021dev3Slim
snapshot-var_lib_machines_v2021dev3SlimTarget var/lib/machines/v2021dev3SlimTarget
snapshot-var_lib_machines_v2022dev2OspackMinimal var/lib/machines/v2022dev2OspackMinimal
snapshot-var_lib_portables var/lib/portables
snapshot-var_log var/log
snapshot-var_spool_news var/spool/news
snapshot-var_tmp var/tmp

snapper Entirely independent of this, but indirectly related. I use snapper as my snapshotting tool. It worked perfect on my previous machine. While everything got migrated, the only thing that fell apart was snapper. It just wouldn t start/run proper. Funny thing is that I just removed the snapper configs and reinitialized with the exact same config again, and voila snapper was happy.

Conclusion That was pretty much it. With the above and then also migrating /boot and then just chroot to install the boot loader. At some time, I d like to explore other boot options but given that that is such a non-essential task, it is low on the list. The good part was that I booted into my new machine with my exact workstation setup as it was. All the way to the user cache and the desktop session. So it was nice on that part. But I surely think there s room for a better migration experience here. If not directly as btrfs migrate, then maybe as an independent tool. The problem is that such a tool is going to be used once in years, so I didn t find the motivation to write one. But this surely would be a good use case for the distribution vendors.

Russ Allbery: Review: Hench

Review: Hench, by Natalie Zina Walschots
Publisher: William Morrow
Copyright: September 2020
ISBN: 0-06-297859-4
Format: Kindle
Pages: 403
Anna Tromedlov is a hench, which means she does boring things for terrible people for money. Supervillains need a lot of labor to keep their bases and criminal organizations running, and they get that labor the same way everyone else does: through temporary agencies. Anna does spreadsheets, preferably from home on her couch. On-site work was terrifying and she tried to avoid it, but the lure of a long-term contract was too strong. The Electric Eel, despite being a creepy sleazeball, seemed to be a manageable problem. He needed some support at a press conference, which turns out to be code for being a diversity token in front of the camera, but all she should have to do is stand there. That's how Anna ends up holding the mind control device to the head of the mayor's kid when the superheroes attack, followed shortly by being thrown across the room by Supercollider. Left with a complex fracture of her leg that will take months to heal, a layoff notice and a fruit basket from Electric Eel's company, and a vaguely menacing hospital conversation with the police (including Supercollider in a transparent disguise) in which it's made clear to her that she is mistaken about Supercollider's hand-print on her thigh, Anna starts wondering just how much damage superheroes have done. The answer, when analyzed using the framework for natural disasters, is astonishingly high. Anna's resulting obsession with adding up the numbers leads to her starting a blog, the Injury Report, with a growing cult following. That, in turn, leads to a new job and a sponsor: the mysterious supervillain Leviathan. To review this book properly, I need to talk about Watchmen. One of the things that makes superheroes interesting culturally is the straightforwardness of their foundational appeal. The archetypal superhero story is an id story: an almost pure power fantasy aimed at teenage boys. Like other pulp mass media, they reflect the prevailing cultural myths of the era in which they're told. World War II superheroes are mostly all-American boy scouts who punch Nazis. 1960s superheroes are a more complex mix of outsider misfits with a moral code and sarcastic but earnestly ethical do-gooders. The superhero genre is vast, with numerous reinterpretations, deconstructions, and alternate perspectives, but its ur-story is a good versus evil struggle of individual action, in which exceptional people use their powers for good to defeat nefarious villains. Watchmen was not the first internal critique of the genre, but it was the one that everyone read in the 1980s and 1990s. It takes direct aim at that moral binary. The superheroes in Watchmen are not paragons of virtue (some of them are truly horrible people), and they have just as much messy entanglement with the world as the rest of us. It was superheroes re-imagined for the post-Vietnam, post-Watergate era, for the end of the Cold War when we were realizing how many lies about morality we had been told. But it still put superheroes and their struggles with morality at the center of the story. Hench is a superhero story for the modern neoliberal world of reality TV and power inequality in the way that Watchmen was a superhero story for the Iran-Contra era and the end of the Cold War. Whether our heroes have feet of clay is no longer a question. Today, a better question is whether the official heroes, the ones that are celebrated as triumphs of individual achievement, are anything but clay. Hench doesn't bother asking whether superheroes have fallen short of their ideal; that answer is obvious. What Hench asks instead is a question familiar to those living in a world full of televangelists, climate denialism, manipulative advertising, and Facebook: are superheroes anything more than a self-perpetuating scam? Has the good superheroes supposedly do ever outweighed the collateral damage? Do they care in the slightest about the people they're supposedly protecting? Or is the whole system of superheroes and supervillains a performance for an audience, one that chews up bystanders and spits them out mangled while delivering simplistic and unquestioned official morality? This sounds like a deeply cynical premise, but Hench is not a cynical book. It is cynical about superheroes, which is not the same thing. The brilliance of Walschots's approach is that Anna has a foot in both worlds. She works for a supervillain and, over the course of the book, gains access to real power within the world of superheroic battles. But she's also an ordinary person with ordinary problems: not enough money, rocky friendships, deep anger at the injustices of the world and the way people like her are discarded, and now a disability and PTSD. Walschots perfectly balances the tension between those worlds and maintains that tension straight to the end of the book. From the supervillain world, Anna draws support, resources, and a mission, but all of the hope, true morality, and heart of this book comes from the ordinary side. If you had the infrastructure of a supervillain at your disposal, what would you do with it? Anna's answer is to treat superheroes as a destructive force like climate change, and to do whatever she can to drive them out of the business and thus reduce their impact on the world. The tool she uses for that is psychological warfare: make them so miserable that they'll snap and do something too catastrophic to be covered up. And the raw material for that psychological warfare is data. That's the foot in the supervillain world. In descriptions of this book, her skills with data are often called her superpower. That's not exactly wrong, but the reason why she gains power and respect is only partly because of her data skills. Anna lives by the morality of the ordinary people world: you look out for your friends, you treat your co-workers with respect as long as they're not assholes, and you try to make life a bit better for the people around you. When Leviathan gives her the opportunity to put together a team, she finds people with skills she admires, funnels work to people who are good at it, and worries about the team dynamics. She treats the other ordinary employees of a supervillain as people, with lives and personalities and emotions and worth. She wins their respect. Then she uses their combined skills to destroy superhero lives. I was fascinated by the moral complexity in this book. Anna and her team do villainous things by the morality of the superheroic world (and, honestly, by the morality of most readers), including some things that result in people's deaths. By the end of the book, one could argue that Anna has been driven by revenge into becoming an unusual sort of supervillain. And yet, she treats the people around her so much better than either the heroes or the villains do. Anna is fiercely moral in all the ordinary person ways, and that leads directly to her becoming a villain in the superhero frame. Hench doesn't resolve that conflict; it just leaves it on the page for the reader to ponder. The best part about this book is that it's absurdly grabby, unpredictable, and full of narrative momentum. Walschots's pacing kept me up past midnight a couple of times and derailed other weekend plans so that I could keep reading. I had no idea where the plot was going even at the 80% mark. The ending is ambiguous and a bit uncomfortable, just like the morality throughout the book, but I liked it the more I thought about it. One caveat, unfortunately: Hench has some very graphic descriptions of violence and medical procedures, and there's an extended torture sequence with some incredibly gruesome body horror that I thought went on far too long and was unnecessary to the plot. If you're a bit squeamish like I am, there are some places where you'll want to skim, including one sequence that's annoyingly intermixed with important story developments. Otherwise, though, this is a truly excellent book. It has a memorable protagonist with a great first-person voice, an epic character arc of empowerment and revenge, a timely take on the superhero genre that uses it for sharp critique of neoliberal governance and reality TV morality, a fascinatingly ambiguous and unsettled moral stance, a gripping and unpredictable plot, and some thoroughly enjoyable competence porn. I had put off reading it because I was worried that it would be too cynical or dark, but apart from the unnecessary torture scene, it's not at all. Highly recommended. Rating: 9 out of 10

9 January 2022

Russ Allbery: Review: Redemptor

Review: Redemptor, by Jordan Ifueko
Series: Raybearer #2
Publisher: Amulet Books
Copyright: 2021
ISBN: 1-68335-720-5
Format: Kindle
Pages: 328
Redemptor is the second half of a duology that started with Raybearer. You could read the first book without the second, but reading the second without the first will not make much sense. I'm going to be a bit elliptical in my plot description since there's a lot of potential for spoilers for the first book. Tarisai has reached a point of stability and power, but she's also committed herself to a goal, one that will right a great historical and ongoing injustice. She's also now in a position to both notice and potentially correct numerous other injustices in the structure of her society, and plans to start by defending those closest to her. But in the midst of her opening gambit to save someone she believes is unjustly imprisoned, the first murderous undead child appears, attacking both Tarisai's fragile sense of security and her self-esteem and self-worth. Before long, she's drowning in feelings of inadequacy and isolation, and her grand plans for reordering the world have turned into an anxiety loop of self-flagellating burnout. I so much wanted to like this book. Argh. I think I see what Ifueko was aiming for, and it's a worthy topic for a novel. In Raybearer, Tarisai got the sort of life that she previously could only imagine, but she's also the sort of person who shoulders massive obligations. Imposter syndrome, anxiety, overwork, and burnout are realistic risks, and are also important topics to write about. There are some nicely subtle touches buried in this story, such as the desire of her chosen family to have her present and happy without entirely understanding why she isn't, and without seeing the urgency that she sees in the world's injustice. The balancing act of being effective without overwhelming oneself is nearly impossible, and Tarisai has very little preparation or knowledgeable support. But this story is told with the subtlety of a sledgehammer, and in a way that felt forced rather than arising naturally from the characters. If the point of emphasis had been a disagreement with her closest circle over when and how much the world should be changed, I think this would be a better book. In the places where this drives the plot, it is a better book. But Ifueko instead externalizes anxiety and depression in the form of obviously manipulative demonic undead children who (mostly) only Tarisai can see, and it's just way too much. Her reactions are manipulated and sometimes externally imposed in a way that turns what should have been a character vs. self plot into a character vs. character plot in which the protagonist is very obviously making bad decisions and the antagonist is an uninteresting cliche. The largest problem I had with this book is that I found it thuddingly obvious, in part because the plot felt like it was on narrowly constrained rails to ensure it hit all of the required stops. When the characters didn't want the plot to go somewhere, they're sidelined, written out of the story, or otherwise forcibly overridden. Tarisai has to feel isolated, so all the people who, according to the events of the previous book and the established world-building rules, would not let her be isolated are pushed out of her life. When this breaks the rules of magic in this world, those rules are off-handedly altered. Characters that could have had their own growth arcs after Raybearer become static and less interesting, since there's no room for them in the plot. Instead, we get all new characters, which gives Redemptor a bit of a cast size problem. Underneath this, there is an occasional flash of great writing. Ifueko chooses to introduce a dozen mostly-new characters to an already large cast and I was still able to mostly keep them straight, which shows real authorial skill. She is very good with short bursts of characterization to make new characters feel fresh and interesting. Even the most irritating of the new characters (Crocodile, whose surprise twist I thought was obvious and predictable) is an interesting archetype to explore in a book about activism and activist burnout. I can see some pieces of a better book here. But I desperately wanted something to surprise me, for Tarisai or one of the other characters to take the plot in some totally unexpected direction the way that Raybearer did. It never happened. That leads directly to another complaint: I liked Raybearer in part because of the freshness of a different mythological system and a different storytelling tradition than what we typically get in fantasy novels. I was hoping for more of the same in Redemptor, which meant I was disappointed when I got a mix of Christianity and Greek mythology. As advertised by Raybearer, the central mythological crisis of Redemptor concerns the Underworld. This doesn't happen until about 80% into the book (which is also a bit of a problem; the ending felt rushed given how central it was to the plot), so I can't talk about it in detail without spoiling it. But what I think I can say is that unfortunately the religious connotations of the title are not an accident. Rather than something novel that builds on the excellent idea of the emi-ehran spirit animal, there is a lot of Christ symbolism mixed with an underworld that could have come from an Orpheus retelling. There's nothing inherently wrong with this (although the Christian bits landed poorly for me), but it wasn't what I was hoping for from the mythology of this world. I rarely talk much about the authors in fiction reviews. I prefer to let books stand on their own without trying too hard to divine the author's original intentions. But here, I think it's worth acknowledging Ifueko's afterword in which she says that writing Redemptor in the middle of a pandemic, major depression, and the George Floyd protests was the most difficult thing she'd ever done. I've seen authors write similar things in afterwords when the effect on the book was minimal or invisible, but I don't think that was the case here. Redemptor is furious, anxious, depressed, and at points despairing, and while it's okay for novels to be all of those things when it's under the author's control, here they felt like emotions that were imposed on the story from outside. Raybearer was an adventure story about found family and ethics that happened to involve a lot of politics. Redemptor is a story about political activism and governance, but written in a universe whose bones are set up for an adventure story. The mismatch bothered me throughout; not only did these not feel like the right characters to tell this story with, but the politics were too simple, too morally clear-cut, and too amenable to easy solutions for a good political fantasy. Raybearer focused its political attention on colonialism. That's a deep enough topic by itself to support a duology (or more), but Redemptor adds in property rights, land reform, economic and social disparity, unfair magical systems, and a grab bag of other issues, and it overwhelms the plot. There isn't space and time to support solutions with sufficient complexity to satisfyingly address the problems. Ifueko falls back on benevolent dictator solutions, and I understand why, but that's not the path to a satisfying resolution in an overtly political fantasy. This is the sort of sequel that leaves me wondering if I can recommend reading the first book and not the second, and that makes me sad. Redemptor is not without its occasional flashes of brilliance, but I did not have fun reading this book and I can't recommend the experience. That said, I think this is a book problem, not an author problem; I will happily read Ifueko's next novel, and I suspect it will be much better. Rating: 5 out of 10

6 January 2022

Jacob Adams: Linux Hibernation Documentation

Recently I ve been curious about how hibernation works on Linux, as it s an interesting interaction between hardware and software. There are some notes in the Arch wiki and the kernel documentation (as well as some kernel documentation on debugging hibernation and on sleep states more generally), and of course the ACPI Specification

The Formal Definition ACPI (Advanced Configuration and Power Interface) is, according to the spec, an architecture-independent power management and configuration framework that forms a subsystem within the host OS which defines a hardware register set to define power states. ACPI defines four global system states G0, working/on, G1, sleeping, G2, soft off, and G3, mechanical off1. Within G1 there are 4 sleep states, numbered S1 through S4. There are also S0 and S5, which are equivalent to G0 and G2 respectively2.

Sleep According to the spec, the ACPI S1-S4 states all do the same thing from the operating system s perspective, but each saves progressively more power, so the operating system is expected to pick the deepest of these states when entering sleep. However, most operating systems3 distinguish between S1-S3, which are typically referred to as sleep or suspend, and S4, which is typically referred to as hibernation.

S1: CPU Stop and Cache Wipe The CPU caches are wiped and then the CPU is stopped, which the spec notes is equivalent to the WBINVD instruction followed by the STPCLK signal on x86. However, nothing is powered off.

S2: Processor Power off The system stops the processor and most system clocks (except the real time clock), then powers off the processor. Upon waking, the processor will not continue what it was doing before, but instead use its reset vector4.

S3: Suspend/Sleep (Suspend-to-RAM) Mostly equivalent to S2, but hardware ensures that only memory and whatever other hardware memory requires are powered.

S4: Hibernate (Suspend-to-Disk) In this state, all hardware is completely powered off and an image of the system is written to disk, to be restored from upon reapplying power. Writing the system image to disk can be handled by the operating system if supported, or by the firmware.

Linux Sleep States Linux has its own set of sleep states which mostly correspond with ACPI states.

Suspend-to-Idle This is a software only sleep that puts all hardware into the lowest power state it can, suspends timekeeping, and freezes userspace processes. All userspace and some kernel threads5, except those tagged with PF_NOFREEZE, are frozen before the system enters a sleep state. Frozen tasks are sent to the __refrigerator(), where they set TASK_UNINTERRUPTIBLE and PF_FROZEN and infinitely loop until PF_FROZEN is unset6. This prevents these tasks from doing anything during the imaging process. Any userspace process running on a different CPU while the kernel is trying to create a memory image would cause havoc. This is also done because any filesystem changes made during this would be lost and could cause the filesystem and its related in-memory structures to become inconsistent. Also, creating a hibernation image requires about 50% of memory free, so no tasks should be allocating memory, which freezing also prevents.

Standby This is equivalent to ACPI S1.

Suspend-to-RAM This is equivalent to ACPI S3.

Hibernation Hibernation is mostly equivalent to ACPI S4 but does not require S4, only requiring low-level code for resuming the system to be present for the underlying CPU architecture according to the Linux sleep state docs. To hibernate, everything is stopped and the kernel takes a snapshot of memory. Then, the system writes out the memory image to disk. Finally, the system either enters S4 or turns off completely. When the system restores power it boots a new kernel, which looks for a hibernation image and loads it into memory. It then overwrites itself with the hibernation image and jumps to a resume area of the original kernel7. The resumed kernel restores the system to its previous state and resumes all processes.

Hybrid Suspend Hybrid suspend does not correspond to an official ACPI state, but instead is effectively a combination of S3 and S4. The system writes out a hibernation image, but then enters suspend-to-RAM. If the system wakes up from suspend it will discard the hibernation image, but if the system loses power it can safely restore from the hibernation image.
  1. The difference between soft and mechanical off is that mechanical off is entered and left by a mechanical means (for example, turning off the system s power through the movement of a large red switch)
  2. It s unclear to me why G and S states overlap like this. I assume this is a relic of an older spec that only had S states, but I have not as yet found any evidence of this. If someone has any information on this, please let me know and I ll update this footnote.
  3. Of the operating systems I know of that support ACPI sleep states (I checked Windows, Mac, Linux, and the three BSDs8), only MacOS does not allow the user to deliberately enable hibernation, instead supporting a hybrid suspend it calls safe sleep
  4. The reset vector of a processor is the default location where, upon a reset, the processor will go to find the first instruction to execute. In other words, the reset vector is a pointer or address where the processor should always begin its execution. This first instruction typically branches to the system initialization code. Xiaocong Fan, Real-Time Embedded Systems, 2015
  5. All kernel threads are tagged with PF_NOFREEZE by default, so they must specifically opt-in to task freezing.
  6. This is not from the docs, but from kernel/freezer.c which also notes Refrigerator is place where frozen processes are stored :-).
  7. This is the operation that requires special architecture-specific low-level code .
  8. Interestingly NetBSD has a setting to enable hibernation, but does not actually support hibernation

5 January 2022

Reproducible Builds: Reproducible Builds in December 2021

Welcome to the December 2021 report from the Reproducible Builds project! In these reports, we try and summarise what we have been up to over the past month, as well as what else has been occurring in the world of software supply-chain security. As a quick recap of what reproducible builds is trying to address, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. As always, if you would like to contribute to the project, please get in touch with us directly or visit the Contribute page on our website.
Early in December, Julien Voisin blogged about setting up a rebuilderd instance in order to reproduce Tails images. Working on previous work from 2018, Julien has now set up a public-facing instance which is providing build attestations. As Julien dryly notes in his post, Currently, this isn t really super-useful to anyone, except maybe some Tails developers who want to check that the release manager didn t backdoor the released image. Naturally, we would contend sincerely that this is indeed useful.
The secure/anonymous Tor browser now supports reproducible source releases. According to the project s changelog, version 0.4.7.3-alpha of Tor can now build reproducible tarballs via the make dist-reprod command. This issue was tracked via Tor issue #26299.
Fabian Keil posted a question to our mailing list this month asking how they might analyse differences in images produced with the FreeBSD and ElectroBSD s mkimg and makefs commands:
After rebasing ElectroBSD from FreeBSD stable/11 to stable/12
I recently noticed that the "memstick" images are unfortunately
still not 100% reproducible.
Fabian s original post generated a short back-and-forth with Chris Lamb regarding how diffoscope might be able to support the particular format of images generated by this command set.

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb prepared and uploading versions 195, 196, 197 and 198 to Debian, as well as made the following changes:
  • Support showing Ordering differences only within .dsc field values. [ ]
  • Add support for XMLb files. [ ]
  • Also add, for example, /usr/lib/x86_64-linux-gnu to our local binary search path. [ ]
  • Support OCaml versions 4.11, 4.12 and 4.13. [ ]
  • Drop some unnecessary has_same_content_as logging calls. [ ]
  • Replace token variable with an anonymously-named variable instead to remove extra lines. [ ]
  • Don t use the runtime platform s native endianness when unpacking .pyc files. This fixes test failures on big-endian machines. [ ]
Mattia Rizzolo also made a number of changes to diffoscope this month as well, such as:
  • Also recognize GnuCash files as XML. [ ]
  • Support the pgpdump PGP packet visualiser version 0.34. [ ]
  • Ignore the new Lintian tag binary-with-bad-dynamic-table. [ ]
  • Fix the Enhances field in debian/control. [ ]
Finally, Brent Spillner fixed the version detection for Black uncompromising code formatter [ ], Jelle van der Waa added an external tool reference for Arch Linux [ ] and Roland Clobus added support for reporting when the GNU_BUILD_ID field has been modified [ ]. Thank you for your contributions!

Distribution work In Debian this month, 70 reviews of packages were added, 27 were updated and 41 were removed, adding to our database of knowledge about specific issues. A number of issue types were created as well, including: strip-nondeterminism version 1.13.0-1 was uploaded to Debian unstable by Holger Levsen. It included contributions already covered in previous months as well as new ones from Mattia Rizzolo, particularly that the dh_strip_nondeterminism Debian integration interface uses the new get_non_binnmu_date_epoch() utility when available: this is important to ensure that strip-nondeterminism does not break some kinds of binNMUs.
In the world of openSUSE, however, Bernhard M. Wiedemann posted his monthly reproducible builds status report.
In NixOS, work towards the longer-term goal of making the graphical installation image reproducible is ongoing. For example, Artturin made the gnome-desktop package reproducible.

Upstream patches The Reproducible Builds project attempts to fix as many currently-unreproducible packages as possible. In December, we wrote a large number of such patches, including:

Testing framework The Reproducible Builds project runs a significant testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
  • Holger Levsen:
    • Run the Debian scheduler less often. [ ]
    • Fix the name of the Debian testing suite name. [ ]
    • Detect builds that are rescheduling due to problems with the diffoscope container. [ ]
    • No longer special-case particular machines having a different /boot partition size. [ ]
    • Automatically fix failed apt-daily and apt-daily-upgrade services [ ], failed e2scrub_all.service & user@ systemd units [ ][ ] as well as generic build failures [ ].
    • Simplify a script to powercycle arm64 architecture nodes hosted at/by codethink.co.uk. [ ]
    • Detect if the udd-mirror.debian.net service is down. [ ]
    • Various miscellaneous node maintenance. [ ][ ]
  • Roland Clobus (Debian live image generation):
    • If the latest snapshot is not complete yet, try to use the previous snapshot instead. [ ]
    • Minor: whitespace correction + comment correction. [ ]
    • Use unique folders and reports for each Debian version. [ ]
    • Turn off debugging. [ ]
    • Add a better error description for incorrect/missing arguments. [ ]
    • Report non-reproducible issues in Debian sid images. [ ]
Lastly, Mattia Rizzolo updated the automatic logfile parsing rules in a number of ways (eg. to ignore a warning about the Python setuptools deprecation) [ ][ ] and Vagrant Cascadian adjusted the config for the Squid caching proxy on a node. [ ]

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

4 January 2022

Jelmer Vernooij: Personal Streaming Audio Server

For a while now, I ve been looking for a good way to stream music from my home music collection on my phone. There are quite a few options for music servers that support streaming. However, Android apps that can stream music from one of those servers tend to be unmaintained, clunky or slow (or more than one of those). It is possible to use something that runs in a web server, but that means no offline caching - which can be quite convenient in spots without connectivity, such as the Underground or other random bits of London with poor cell coverage.
Server Most music servers today support some form of the subsonic API. I ve tried a couple, with mixed results:
  • supysonic; Python. Slow. Ran into some issues with subsonic clients. No real web UI.
  • gonic; Go. Works well & fast enough. Minimal web UI, i.e. no ability to play music from a browser.
  • airsonic; Java. Last in a chain of (abandoned) forks. More effort to get to work, and resource intensive.
Eventually, I ve settled on Navidrome. It s got a couple of things going for it:
  • Good subsonic implementation that worked with all the Android apps I used it with.
  • Great Web UI for use in a browser
I run Navidrome in Kubernetes. It s surprisingly easy to get going. Here s the deployment I m using:
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
apiVersion: apps/v1
kind: Deployment
metadata:
 name: navidrome
spec:
 replicas: 1
 selector:
   matchLabels:
     app: navidrome
 template:
   metadata:
     labels:
       app: navidrome
   spec:
     containers:
       - name: navidrome
         image: deluan/navidrome:latest
         imagePullPolicy: Always
         resources:
           limits:
             cpu: ".5"
             memory: "2Gi"
           requests:
             cpu: "0.1"
             memory: "10M"
         ports:
           - containerPort: 4533
         volumeMounts:
           - name: navidrome-data-volume
             mountPath: /data
           - name: navidrome-music-volume
             mountPath: /music
         env:
           - name: ND_SCANSCHEDULE
             value: 1h
           - name: ND_LOGLEVEL
             value: info
           - name: ND_SESSIONTIMEOUT
             value: 24h
           - name: ND_BASEURL
             value: /navidrome
         livenessProbe:
            httpGet:
              path: /navidrome/app
              port: 4533
            initialDelaySeconds: 30
            periodSeconds: 3
            timeoutSeconds: 90
     volumes:
        - name: navidrome-data-volume
          hostPath:
           path: /srv/navidrome
           type: Directory
        - name: navidrome-music-volume
          hostPath:
            path: /srv/media/music
            type: Directory
---
apiVersion: v1
kind: Service
metadata:
  name: navidrome
spec:
  ports:
    - port: 4533
      name: web
  selector:
    app: navidrome
  type: ClusterIP
At the moment, this deployment is still tied to the machine with my music on it since it relies on hostPath volumes, but I m planning to move that to ceph in the future. I then expose this service on /navidrome on my private domain (here replaced with example.com) using an Ingress:
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
apiVersion: networking.k8s.io/v1
kind: Ingress
metadata:
  name: navidrome
spec:
  ingressClassName: nginx
  rules:
  - host: example.com
    http:
      paths:
      - backend:
          service:
            name: navidrome
            port:
              name: web
        path: /navidrome(/ $)(.*)
        pathType: Prefix
Client On the desktop, I usually just use navidrome s web interface. Clementine s support for subsonic is also okay. sublime-music is meant to be a music player specifically for Subsonic, but I ve not really found it stable enough for day-to-day usage. There are various Android clients for Subsonic, but I ve only really considered the Open Source ones that are hosted on F-Droid. Most of those are abandoned, but D-Sub works pretty well - as does my preferred option, Subtracks.

Next.

Previous.