Search Results: "nate"

17 November 2020

Dirk Eddelbuettel: RcppAnnoy 0.0.17

annoy image A new release 0.0.17 of RcppAnnoy is now on CRAN. RcppAnnoy is the Rcpp-based R integration of the nifty Annoy library by Erik Bernhardsson. Annoy is a small and lightweight C++ template header library for very fast approximate nearest neighbours originally developed to drive the famous Spotify music discovery algorithm. This release brings a new upstream version 1.17, released a few weeks ago, which adds multithreaded index building. This changes the API by adding a new threading policy parameter requiring code using the main Annoy header to update. For this reason we waited a little for the dust to settle on the BioConductor 3.12 release before bringing the changes to BiocNeighbors via this commit and to uwot via this simple PR. Aaron and James updated their packages accordingly so by the time I uploaded RcppAnnoy it made for very smooth sailing as we all had done our homework with proper conditional builds, and the package had no other issue preventing automated processing at CRAN. Yay. I also added a (somewhat overdue one may argue) header file RcppAnnoy.h regrouping defines and includes which should help going forward. Detailed changes follow below.

Changes in version 0.0.17 (2020-11-15)
  • Upgrade to Annoy 1.17, but default to serial use.
  • Add new header file to regroup includes and defines.
  • Upgrade CI script to use R with bspm on focal.

Courtesy of my CRANberries, there is also a diffstat report for this release. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

12 November 2020

Dirk Eddelbuettel: tidyCpp 0.0.2: More documentation and features

A first update of the still fairly new package tidyCpp is now on CRAN. The packages offers a C++ layer on top of the C API for R which aims to make its use a little easier and more consistent. The vignette has been extended with a new examples, a new section and some general editing. A few new defines have been added mostly from the Rinternals.h header. We also replaced the Shield class with a simpler yet updated version class Protect. The name better represent the core functionality of offering a simpler alternative to the PROTECT and UNPROTECT macro pairing. We also added a short discussion to the vignette of a gotcha one has to be mindful of, and that we fell for ourselves in version 0.0.1. We also added a typedef so that code using Shield can still be used. The NEWS entry follows.

Changes in tidyCpp version 0.0.2 (2020-11-12)
  • Expanded definitions in internals.h to support new example.
  • The vignette has been extended with an example based on package uchardet.
  • Class Shield has been replaced by an new class Protect; a compatibility typdef has been added.
  • The examples and vignette have been clarified with respect to proper ownership of protected objects; a new vignette section was added.

Thanks to my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

11 November 2020

Reproducible Builds: Reproducible Builds in October 2020

Welcome to the October 2020 report from the Reproducible Builds project. In our monthly reports, we outline the major things that we have been up to over the past month. As a brief reminder, the motivation behind the Reproducible Builds effort is to ensure flaws have not been introduced in the binaries we install on our systems. If you are interested in contributing to the project, please visit our main website.

General On Saturday 10th October, Morten Linderud gave a talk at Arch Conf Online 2020 on The State of Reproducible Builds in Arch. The video should be available later this month, but as a teaser:
The previous year has seen great progress in Arch Linux to get reproducible builds in the hands of the users and developers. In this talk we will explore the current tooling that allows users to reproduce packages, the rebuilder software that has been written to check packages and the current issues in this space.
During the Reproducible Builds summit in Marrakesh in 2019, developers from the GNU Guix, NixOS and Debian distributions were able to produce a bit-for-bit identical GNU Mes binary despite using three different versions of GCC. Since this summit, additional work resulted in a bit-for-bit identical Mes binary using tcc, and last month a fuller update was posted to this effect by the individuals involved. This month, however, David Wheeler updated his extensive page on Fully Countering Trusting Trust through Diverse Double-Compiling, remarking that:
GNU Mes rebuild is definitely an application of [Diverse Double-Compiling]. [..] This is an awesome application of DDC, and I believe it s the first publicly acknowledged use of DDC on a binary
There was a small, followup discussion on our mailing list. In openSUSE, Bernhard M. Wiedemann published his monthly Reproducible Builds status update. This month, the Reproducible Builds project restarted our IRC meetings, managing to convene twice: the first time on October 12th (summary & logs), and later on the 26th (logs). As mentioned in previous reports, due to the unprecedented events throughout 2020, there will be no in-person summit event this year. On our mailing list this month El as Alejandro posted a request for help with a local configuration

Software development This month, we tried to fix a large number of currently-unreproducible packages, including: Bernhard M. Wiedemann also reported three issues against bison, ibus and postgresql12.

Tools diffoscope is our in-depth and content-aware diff utility. Not only could you locate and diagnose reproducibility issues, it provides human-readable diffs of all kinds too. This month, Chris Lamb uploaded version 161 to Debian (later backported by Mattia Rizzolo), as well as made the following changes:
  • Move test_ocaml to the assert_diff helper. [ ]
  • Update tests to support OCaml version 4.11.1. Thanks to Sebastian Ramacher for the report. (#972518)
  • Bump minimum version of the Black source code formatter to 20.8b1. (#972518)
In addition, Jean-Romain Garnier temporarily updated the dependency on radare2 to ensure our test pipelines continue to work [ ], and for the GNU Guix distribution Vagrant Cascadian diffoscope to version 161 [ ]. In related development, trydiffoscope is the web-based version of diffoscope. This month, Chris Lamb made the following changes:
  • Mark a --help-only test as being a superficial test. (#971506)
  • Add a real, albeit flaky, test that interacts with the try.diffoscope.org service. [ ]
  • Bump debhelper compatibility level to 13 [ ] and bump Standards-Version to 4.5.0 [ ].
Lastly, disorderfs version 0.5.10-2 was uploaded to Debian unstable by Holger Levsen, which enabled security hardening via DEB_BUILD_MAINT_OPTIONS [ ] and dropped debian/disorderfs.lintian-overrides [ ].

Website and documentation This month, a number of updates to the main Reproducible Builds website and related documentation were made by Chris Lamb:
  • Add a citation link to the academic article regarding dettrace [ ], and added yet another supply-chain security attack publication [ ].
  • Reformatted the Jekyll s Liquid templating language and CSS formatting to be consistent [ ] as well as expand a number of tab characters [ ].
  • Used relative_url to fix missing translation icon on various pages. [ ]
  • Published two announcement blog posts regarding the restarting of our IRC meetings. [ ][ ]
  • Added an explicit note regarding the lack of an in-person summit in 2020 to our events page. [ ]

Testing framework The Reproducible Builds project operates a Jenkins-based testing framework that powers tests.reproducible-builds.org. This month, Holger Levsen made the following changes:
  • Debian-related changes:
    • Refactor and improve the Debian dashboard. [ ][ ][ ]
    • Track bugs which are usertagged as filesystem , fixfilepath , etc.. [ ][ ][ ]
    • Make a number of changes to package index pages. [ ][ ][ ]
  • System health checks:
    • Relax disk space warning levels. [ ]
    • Specifically detect build failures reported by dpkg-buildpackage. [ ]
    • Fix a regular expression to detect outdated package sets. [ ]
    • Detect Lintian issues in diffoscope. [ ]
  • Misc:
    • Make a number of updates to reflect that our sponsor Profitbricks has renamed itself to IONOS. [ ][ ][ ][ ]
    • Run a F-Droid maintenance routine twice a month to utilise its cleanup features. [ ]
    • Fix the target name in OpenWrt builds to ath79 from ath97. [ ]
    • Add a missing Postfix configuration for a node. [ ]
    • Temporarily disable Arch Linux builds until a core node is back. [ ]
    • Make a number of changes to our thanks page. [ ][ ][ ]
Build node maintenance was performed by both Holger Levsen [ ][ ] and Vagrant Cascadian [ ][ ][ ], Vagrant Cascadian also updated the page listing the variations made when testing to reflect changes for in build paths [ ] and Hans-Christoph Steiner made a number of changes for F-Droid, the free software app repository for Android devices, including:
  • Do not fail reproducibility jobs when their cleanup tasks fail. [ ]
  • Skip libvirt-related sudo command if we are not actually running libvirt. [ ]
  • Use direct URLs in order to eliminate a useless HTTP redirect. [ ]

If you are interested in contributing to the Reproducible Builds project, please visit the Contribute page on our website. However, you can also get in touch with us via:

10 November 2020

Thorsten Alteholz: My Debian Activities in October 2020

FTP master This month I accepted 208 packages and rejected 29. The overall number of packages that got accepted was 563, so yeah, I was not alone this month :-). Anyway, this month marked another milestone in my NEW package handling. My overall number of ACCEPTed package exceeded the magic number of 20000 packages. This is almost 30% of all packages accepted in Debian. I am a bit proud of this achievement. Debian LTS This was my seventy-sixth month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload has been 20.75h. During that time I did LTS uploads of: I also started to work on golang-1.7 and golang-1.8 Last but not least I did some days of frontdesk duties. Debian ELTS This month was the twenty eighth ELTS month. During my allocated time I uploaded: The first upload of python3.4, last month, did not build on armel, so I had to reupload an improved package this month. For amd64 and i386 the ELTS packages are built in native mode, whereas the packages on armel are cross-built. There is some magic in debian/rules of python to detect in which mode the package is built. This is important as some tests of the testsuite are not really working in cross-build-mode. Unfortunately I had to learn this the hard way The upload of libsndfile now aligns the number of fixed CVEs in all releases. Last but not least I did some days of frontdesk duties. Other stuff Despite my NEW-handling and LTS/ELTS stuff I hadn t much fun with Debian packages this month. Given the approaching freeze, I hope this will change again in November.

9 November 2020

Joachim Breitner: Distributing Haskell programs in a multi-platform zip file

My maybe most impactful piece of code is tttool and the surrounding project, which allows you to create your own content for the Ravensburger Tiptoi platform. The program itself is a command line tool, and in this blog post I want to show how I go about building that program for Linux (both normal and static builds), Windows (cross-compiled from Linux), OSX (only on CI), all combined into and released as a single zip file. Maybe some of it is useful or inspiring to my readers, or can even serve as a template. This being a blob post, though, note that it may become obsolete or outdated.

Ingredients I am building on the these components: Without the nix build system and package manger I probably woudn t even attempt to pull of complex tasks that may, say, require a patched ghc. For many years I resisted learning about nix, but when I eventually had to, I didn t want to go back. This project provides an alternative Haskell build infrastructure for nix. While this is not crucial for tttool, it helps that they tend to have some cross-compilation-related patches more than the official nixpkgs. I also like that it more closely follows the cabal build work-flow, where cabal calculates a build plan based on your projects dependencies. It even has decent documentation (which is a new thing compared to two years ago). Niv is a neat little tool to keep track of your dependencies. You can quickly update them with, say niv update nixpkgs. But what s really great is to temporarily replace one of your dependencies with a local checkout, e.g. via NIV_OVERRIDE_haskellNix=$HOME/build/haskell/haskell.nix nix-instantiate -A osx-exe-bundle There is a Github action that will keep your niv-managed dependencies up-to-date. This service (proprietary, but free to public stuff up to 10GB) gives your project its own nix cache. This means that build artifacts can be cached between CI builds or even build steps, and your contributors. A cache like this is a must if you want to use nix in more interesting ways where you may end up using, say, a changed GHC compiler. Comes with GitHub actions integration.
  • CI via Github actions
Until recently, I was using Travis, but Github actions are just a tad easier to set up and, maybe more important here, the job times are high enough that you can rebuild GHC if you have to, and even if your build gets canceled or times out, cleanup CI steps still happen, so that any new nix build products will still reach your nix cache.

The repository setup All files discussed in the following are reflected at https://github.com/entropia/tip-toi-reveng/tree/7020cde7da103a5c33f1918f3bf59835cbc25b0c. We are starting with a fairly normal Haskell project, with a single .cabal file (but multi-package projects should work just fine). To make things more interesting, I also have a cabal.project which configures one dependency to be fetched via git from a specific fork. To start building the nix infrastructure, we can initialize niv and configure it to use the haskell.nix repo:
niv init
niv add input-output-hk/haskell.nix -n haskellNix
This creates nix/sources.json (which you can also edit by hand) and nix/sources.nix (which you can treat like a black box). Now we can start writing the all-important default.nix file, which defines almost everything of interest here. I will just go through it line by line, and explain what I am doing here.
  checkMaterialization ? false  :
This defines a flag that we can later set when using nix-build, by passing --arg checkMaterialization true, and which is off by default. I ll get to that flag later.
let
  sources = import nix/sources.nix;
  haskellNix = import sources.haskellNix  ;
This imports the sources as defined niv/sources.json, and loads the pinned revision of the haskell.nix repository.
  # windows crossbuilding with ghc-8.10 needs at least 20.09.
  # A peek at https://github.com/input-output-hk/haskell.nix/blob/master/ci.nix can help
  nixpkgsSrc = haskellNix.sources.nixpkgs-2009;
  nixpkgsArgs = haskellNix.nixpkgsArgs;
  pkgs = import nixpkgsSrc nixpkgsArgs;
Now we can define pkgs, which is our version of the nixpkgs package set, extended with the haskell.nix machinery. We rely on haskell.nix to pin of a suitable revision of the nixpkgs set (see how we are using their niv setup). Here we could our own configuration, overlays, etc to nixpkgsArgs. In fact, we do in
  pkgs-osx = import nixpkgsSrc (nixpkgsArgs //   system = "x86_64-darwin";  );
to get the nixpkgs package set of an OSX machine.
  # a nicer filterSource
  sourceByRegex =
    src: regexes: builtins.filterSource (path: type:
      let relPath = pkgs.lib.removePrefix (toString src + "/") (toString path); in
      let match = builtins.match (pkgs.lib.strings.concatStringsSep " " regexes); in
      ( type == "directory"  && match (relPath + "/") != null
        match relPath != null)) src;
Next I define a little helper that I have been copying between projects, and which allows me to define the input to a nix derivation (i.e. a nix build job) with a set of regexes. I ll use that soon.
  tttool-exe = pkgs: sha256:
    (pkgs.haskell-nix.cabalProject  
The cabalProject function takes a cabal project and turns it into a nix project, running cabal v2-configure under the hood to let cabal figure out a suitable build plan. Since we want to have multiple variants of the tttool, this is so far just a function of two arguments pkgs and sha256, which will be explained in a bit.
      src = sourceByRegex ./. [
          "cabal.project"
          "src/"
          "src/.*/"
          "src/.*.hs"
          ".*.cabal"
          "LICENSE"
        ];
The cabalProject function wants to know the source of the Haskell projects. There are different ways of specifying this; in this case I went for a simple whitelist approach. Note that cabal.project.freze (which exists in the directory) is not included.
      # Pinning the input to the constraint solver
      compiler-nix-name = "ghc8102";
The cabal solver doesn t find out which version of ghc to use, that is still my choice. I am using GHC-8.10.2 here. It may require a bit of experimentation to see which version works for your project, especially when cross-compiling to odd targets.
      index-state = "2020-11-08T00:00:00Z";
I want the build to be deterministic, and not let cabal suddenly pick different package versions just because something got uploaded. Therefore I specify which snapshot of the Hackage package index it should consider.
      plan-sha256 = sha256;
      inherit checkMaterialization;
Here we use the second parameter, but I ll defer the explanation for a bit.
      modules = [ 
        # smaller files
        packages.tttool.dontStrip = false;
       ] ++
These modules are essentially configuration data that is merged in a structural way. Here we say that we want the tttool binary to be stripped (saves a few megabyte).
      pkgs.lib.optional pkgs.hostPlatform.isMusl  
        packages.tttool.configureFlags = [ "--ghc-option=-static" ];
Also, when we are building on the musl platform, that s when we want to produce a static build, so let s pass -static to GHC. This seems to be enough in terms of flags to produce static binaries. It helps that my project is using mostly pure Haskell libraries; if you link against C libraries you might have to jump through additional hoops to get static linking going. The haskell.nix documentation has a section on static building with some flags to cargo-cult.
        # terminfo is disabled on musl by haskell.nix, but still the flag
        # is set in the package plan, so override this
        packages.haskeline.flags.terminfo = false;
       ;
This (again only used when the platform is musl) seems to be necessary to workaround what might be a big in haskell.nix.
     ).tttool.components.exes.tttool;
The cabalProject function returns a data structure with all Haskell packages of the project, and for each package the different components (libraries, tests, benchmarks and of course executables). We only care about the tttool executable, so let s project that out.
  osx-bundler = pkgs: tttool:
   pkgs.stdenv.mkDerivation  
      name = "tttool-bundle";
      buildInputs = [ pkgs.macdylibbundler ];
      builder = pkgs.writeScript "tttool-osx-bundler.sh" ''
        source $ pkgs.stdenv /setup
        mkdir -p $out/bin/osx
        cp $ tttool /bin/tttool $out/bin/osx
        chmod u+w $out/bin/osx/tttool
        dylibbundler \
          -b \
          -x $out/bin/osx/tttool \
          -d $out/bin/osx \
          -p '@executable_path' \
          -i /usr/lib/system \
          -i $ pkgs.darwin.Libsystem /lib
      '';
     ;
This function, only to be used on OSX, takes a fully build tttool, finds all the system libraries it is linking against, and copies them next to the executable, using the nice macdylibbundler. This way we can get a self-contained executable. A nix expert will notice that this probably should be written with pkgs.runCommandNoCC, but then dylibbundler fails because it lacks otool. This should work eventually, though.
in rec  
  linux-exe      = tttool-exe pkgs
     "0rnn4q0gx670nzb5zp7xpj7kmgqjmxcj2zjl9jqqz8czzlbgzmkh";
  windows-exe    = tttool-exe pkgs.pkgsCross.mingwW64
     "01js5rp6y29m7aif6bsb0qplkh2az0l15nkrrb6m3rz7jrrbcckh";
  static-exe     = tttool-exe pkgs.pkgsCross.musl64
     "0gbkyg8max4mhzzsm9yihsp8n73zw86m3pwvlw8170c75p3vbadv";
  osx-exe        = tttool-exe pkgs-osx
     "0rnn4q0gx670nzb5zp7xpj7kmgqjmxcj2zjl9jqqz8czzlbgzmkh";
Time to create the four versions of tttool. In each case we use the tttool-exe function from above, passing the package set (pkgs, ) and a SHA256 hash. The package set is either the normal one, or it is one of those configured for cross compilation, building either for Windows or for Linux using musl, or it is the OSX package set that we instantiated earlier. The SHA256 hash describes the result of the cabal plan calculation that happens as part of cabalProject. By noting down the expected result, nix can skip that calculation, or fetch it from the nix cache etc. How do we know what number to put there, and when to change it? That s when the --arg checkMaterialization true flag comes into play: When that is set, cabalProject will not blindly trust these hashes, but rather re-calculate them, and tell you when they need to be updated. We ll make sure that CI checks them.
  osx-exe-bundle = osx-bundler pkgs-osx osx-exe;
For OSX, I then run the output through osx-bundler defined above, to make it independent of any library paths in /nix/store. This is already good enough to build the tool for the various systems! The rest of the the file is related to packaging up the binaries, to tests, and various other things, but nothing too essentially. So if you got bored, you can more or less stop now.
  static-files = sourceByRegex ./. [
    "README.md"
    "Changelog.md"
    "oid-decoder.html"
    "example/.*"
    "Debug.yaml"
    "templates/"
    "templates/.*\.md"
    "templates/.*\.yaml"
    "Audio/"
    "Audio/digits/"
    "Audio/digits/.*\.ogg"
  ];
  contrib = ./contrib;
The final zip file that I want to serve to my users contains a bunch of files from throughout my repository; I collect them here.
  book =  ;
The project comes with documentation in the form of a Sphinx project, which we build here. I ll omit the details, because they are not relevant for this post (but of course you can peek if you are curious).
  os-switch = pkgs.writeScript "tttool-os-switch.sh" ''
    #!/usr/bin/env bash
    case "$OSTYPE" in
      linux*)   exec "$(dirname "''$ BASH_SOURCE[0] ")/linux/tttool" "$@" ;;
      darwin*)  exec "$(dirname "''$ BASH_SOURCE[0] ")/osx/tttool" "$@" ;;
      msys*)    exec "$(dirname "''$ BASH_SOURCE[0] ")/tttool.exe" "$@" ;;
      cygwin*)  exec "$(dirname "''$ BASH_SOURCE[0] ")/tttool.exe" "$@" ;;
      *)        echo "unsupported operating system $OSTYPE" ;;
    esac
  '';
The zipfile should provide a tttool command that works on all systems. To that end, I implement a simple platform switch using bash. I use pks.writeScript so that I can include that file directly in default.nix, but it would have been equally reasonable to just save it into nix/tttool-os-switch.sh and include it from there.
  release = pkgs.runCommandNoCC "tttool-release"  
    buildInputs = [ pkgs.perl ];
    ''
    # check version
    version=$($ static-exe /bin/tttool --help perl -ne 'print $1 if /tttool-(.*) -- The swiss army knife/')
    doc_version=$(perl -ne "print \$1 if /VERSION: '(.*)'/" $ book /book.html/_static/documentation_options.js)
    if [ "$version" != "$doc_version" ]
    then
      echo "Mismatch between tttool version \"$version\" and book version \"$doc_version\""
      exit 1
    fi
Now the derivation that builds the content of the release zip file. First I double check that the version number in the code and in the documentation matches. Note how $ static-exe refers to a path with the built static Linux build, and $ book the output of the book building process.
    mkdir -p $out/
    cp -vsr $ static-files /* $out
    mkdir $out/linux
    cp -vs $ static-exe /bin/tttool $out/linux
    cp -vs $ windows-exe /bin/* $out/
    mkdir $out/osx
    cp -vsr $ osx-exe-bundle /bin/osx/* $out/osx
    cp -vs $ os-switch  $out/tttool
    mkdir $out/contrib
    cp -vsr $ contrib /* $out/contrib/
    cp -vsr $ book /* $out
  '';
The rest of the release script just copies files from various build outputs that we have defined so far. Note that this is using both static-exe (built on Linux) and osx-exe-bundle (built on Mac)! This means you can only build the release if you either have setup a remote osx builder (a pretty nifty feature of nix, which I unfortunately can t use, since I don't have access to a Mac), or the build product must be available in a nix cache (which it is in my case, as I will explain later). The output of this derivation is a directory with all the files I want to put in the release.
  release-zip = pkgs.runCommandNoCC "tttool-release.zip"  
    buildInputs = with pkgs; [ perl zip ];
    ''
    version=$(bash $ release /tttool --help perl -ne 'print $1 if /tttool-(.*) -- The swiss army knife/')
    base="tttool-$version"
    echo "Zipping tttool version $version"
    mkdir -p $out/$base
    cd $out
    cp -r $ release /* $base/
    chmod u+w -R $base
    zip -r $base.zip $base
    rm -rf $base
  '';
And now these files are zipped up. Note that this automatically determines the right directory name and basename for the zipfile. This concludes the step necessary for a release.
  gme-downloads =  ;
  tests =  ;
These two definitions in default.nix are related to some simple testing, and again not relevant for this post.
  cabal-freeze = pkgs.stdenv.mkDerivation  
    name = "cabal-freeze";
    src = linux-exe.src;
    buildInputs = [ pkgs.cabal-install linux-exe.env ];
    buildPhase = ''
      mkdir .cabal
      touch .cabal/config
      rm cabal.project # so that cabal new-freeze does not try to use HPDF via git
      HOME=$PWD cabal new-freeze --offline --enable-tests   true
    '';
    installPhase = ''
      mkdir -p $out
      echo "-- Run nix-shell -A check-cabal-freeze to update this file" > $out/cabal.project.freeze
      cat cabal.project.freeze >> $out/cabal.project.freeze
    '';
   ;
Above I mentioned that I still would like to be able to just run cabal, and ideally it should take the same library versions that the nix-based build does. But pinning the version of ghc in cabal.project is not sufficient, I also need to pin the precise versions of the dependencies. This is best done with a cabal.project.freeze file. The above derivation runs cabal new-freeze in the environment set up by haskell.nix and grabs the resulting cabal.project.freeze. With this I can run nix-build -A cabal-freeze and fetch the file from result/cabal.project.freeze and add it to the repository.
  check-cabal-freeze = pkgs.runCommandNoCC "check-cabal-freeze"  
      nativeBuildInputs = [ pkgs.diffutils ];
      expected = cabal-freeze + /cabal.project.freeze;
      actual = ./cabal.project.freeze;
      cmd = "nix-shell -A check-cabal-freeze";
      shellHook = ''
        dest=$ toString ./cabal.project.freeze 
        rm -f $dest
        cp -v $expected $dest
        chmod u-w $dest
        exit 0
      '';
      ''
      diff -r -U 3 $actual $expected  
          echo "To update, please run"; echo "nix-shell -A check-cabal-freeze"; exit 1;  
      touch $out
    '';
But generated files in repositories are bad, so if that cannot be avoided, at least I want a CI job that checks if they are up to date. This job does that. What s more, it is set up so that if I run nix-shell -A check-cabal-freeze it will update the file in the repository automatically, which is much more convenient than manually copying. Lately, I have been using this pattern regularly when adding generated files to a repository: * Create one nix derivation that creates the files * Create a second derivation that compares the output of that derivation against the file in the repo * Create a derivation that, when run in nix-shell, updates that file. Sometimes that derivation is its own file (so that I can just run nix-shell nix/generate.nix), or it is merged into one of the other two. This concludes the tour of default.nix.

The CI setup The next interesting bit is the file .github/workflows/build.yml, which tells Github Actions what to do:
name: "Build and package"
on:
  pull_request:
  push:
Standard prelude: Run the jobs in this file upon all pushes to the repository, and also on all pull requests. Annoying downside: If you open a PR within your repository, everything gets built twice. Oh well.
jobs:
  build:
    strategy:
      fail-fast: false
      matrix:
        include:
        - target: linux-exe
          os: ubuntu-latest
        - target: windows-exe
          os: ubuntu-latest
        - target: static-exe
          os: ubuntu-latest
        - target: osx-exe-bundle
          os: macos-latest
    runs-on: $  matrix.os  
The build job is a matrix job, i.e. there are four variants, one for each of the different tttool builds, together with an indication of what kind of machine to run this on.
    - uses: actions/checkout@v2
    - uses: cachix/install-nix-action@v12
We begin by checking out the code and installing nix via the install-nix-action.
    - name: "Cachix: tttool"
      uses: cachix/cachix-action@v7
      with:
        name: tttool
        signingKey: '$  secrets.CACHIX_SIGNING_KEY  '
Then we configure our Cachix cache. This means that this job will use build products from the cache if possible, and it will also push new builds to the cache. This requires a secret key, which you get when setting up your Cachix cache. See the nix and Cachix tutorial for good instructions.
    - run: nix-build --arg checkMaterialization true -A $  matrix.target  
Now we can actually run the build. We set checkMaterialization to true so that CI will tell us if we need to update these hashes.
    # work around https://github.com/actions/upload-artifact/issues/92
    - run: cp -RvL result upload
    - uses: actions/upload-artifact@v2
      with:
        name: tttool ($  matrix.target  )
        path: upload/
For convenient access to build products, e.g. from pull requests, we store them as Github artifacts. They can then be downloaded from Github s CI status page.
  test:
    runs-on: ubuntu-latest
    needs: build
    steps:
    - uses: actions/checkout@v2
    - uses: cachix/install-nix-action@v12
    - name: "Cachix: tttool"
      uses: cachix/cachix-action@v7
      with:
        name: tttool
        signingKey: '$  secrets.CACHIX_SIGNING_KEY  '
    - run: nix-build -A tests
The next job repeats the setup, but now runs the tests. Because of needs: build it will not start before the builds job has completed. This also means that it should get the actual tttool executable to test from our nix cache.
  check-cabal-freeze:
    runs-on: ubuntu-latest
    steps:
    - uses: actions/checkout@v2
    - uses: cachix/install-nix-action@v12
    - name: "Cachix: tttool"
      uses: cachix/cachix-action@v7
      with:
        name: tttool
        signingKey: '$  secrets.CACHIX_SIGNING_KEY  '
    - run: nix-build -A check-cabal-freeze
The same, but now running the check-cabal-freeze test mentioned above. Quite annoying to repeat the setup instructions for each job
  package:
    runs-on: ubuntu-latest
    needs: build
    steps:
    - uses: actions/checkout@v2
    - uses: cachix/install-nix-action@v12
    - name: "Cachix: tttool"
      uses: cachix/cachix-action@v7
      with:
        name: tttool
        signingKey: '$  secrets.CACHIX_SIGNING_KEY  '
    - run: nix-build -A release-zip
    - run: unzip -d upload ./result/*.zip
    - uses: actions/upload-artifact@v2
      with:
        name: Release zip file
        path: upload
Finally, with the same setup, but slightly different artifact upload, we build the release zip file. Again, we wait for build to finish so that the built programs are in the nix cache. This is especially important since this runs on linux, so it cannot build the OSX binary and has to rely on the cache. Note that we don t need to checkMaterialization again. Annoyingly, the upload-artifact action insists on zipping the files you hand to it. A zip file that contains just a zipfile is kinda annoying, so I unpack the zipfile here before uploading the contents.

Conclusion With this setup, when I do a release of tttool, I just bump the version numbers, wait for CI to finish building, run nix-build -A release-zip and upload result/tttool-n.m.zip. A single file that works on all target platforms. I have not yet automated making the actual release, but with one release per year this is fine. Also, when trying out a new feature, I can easily create a branch or PR for that and grab the build products from Github s CI, or ask people to try them out (e.g. to see if they fixed their bugs). Note, though, that you have to sign into Github before being able to download these artifacts. One might think that this is a fairly hairy setup finding the right combinations of various repertories so that cross-compilation works as intended. But thanks to nix s value propositions, this does work! The setup presented here was a remake of a setup I did two years ago, with a much less mature haskell.nix. Back then, I committed a fair number of generated files to git, and juggled more complex files but once it worked, it kept working for two years. I was indeed insulated from upstream changes. I expect that this setup will also continue to work reliably, until I choose to upgrade it again. Hopefully, then things are even more simple, and require less work-around or manual intervention.

6 November 2020

Louis-Philippe V ronneau: Book Review: Working in Public by Nadia Eghbal

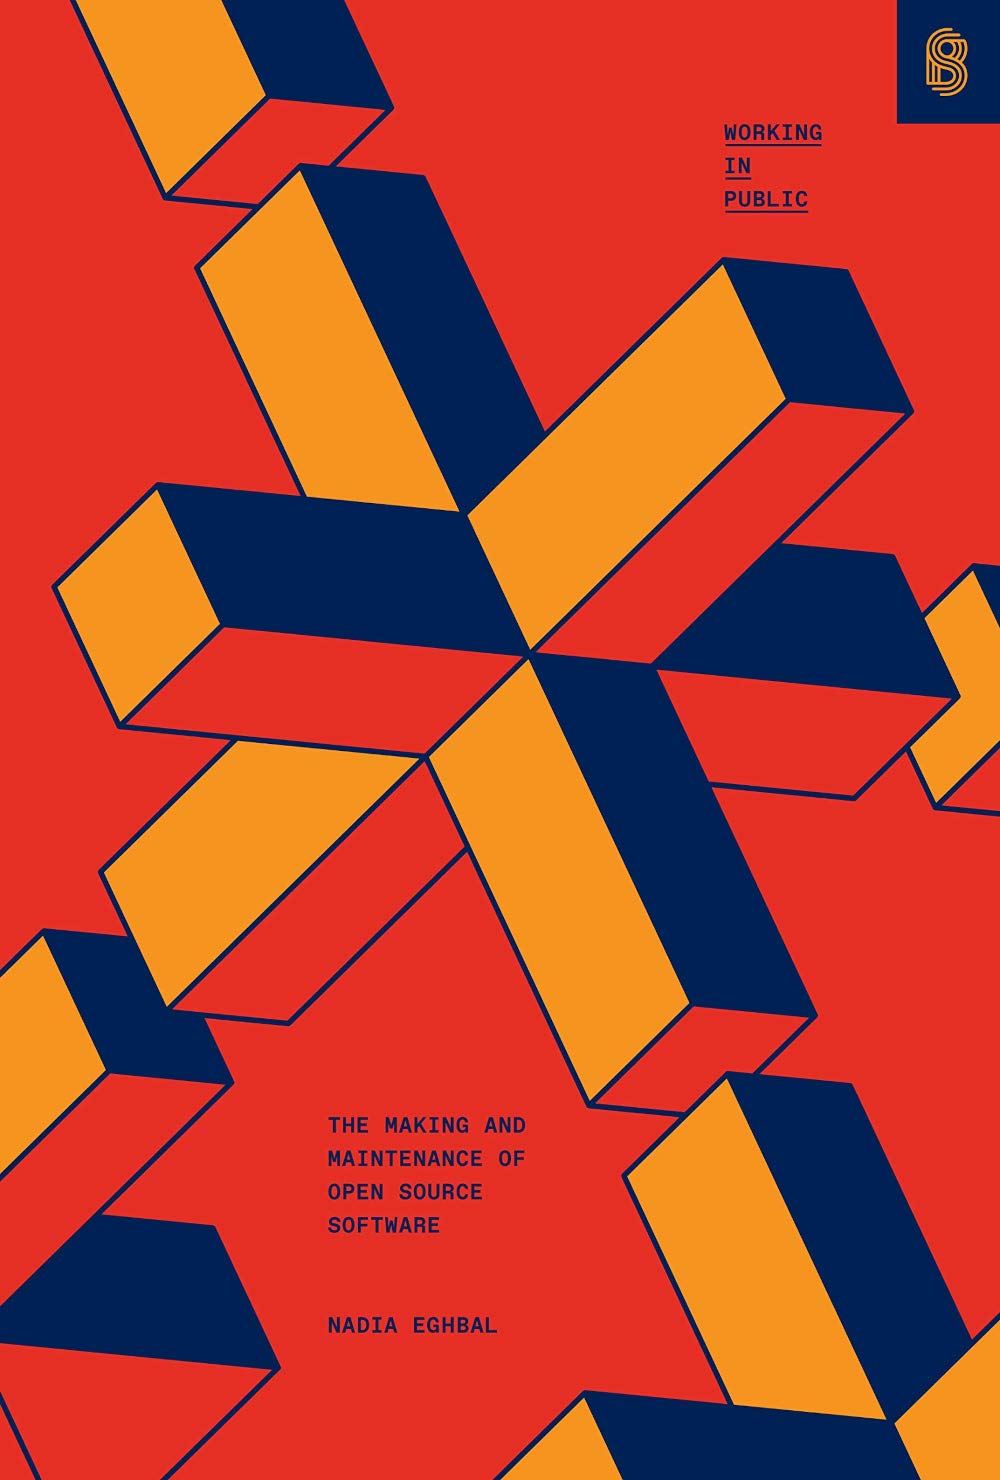
I have a lot of respect for Nadia Eghbal, partly because I can't help to be jealous of her work on the economics of Free Software1. If you are not already familiar with Eghbal, she is the author of Roads and Bridges: The Unseen Labor Behind Our Digital Infrastructure, a great technical report published for the Ford Foundation in 2016. You may also have caught her excellent keynote at LCA 2017, entitled Consider the Maintainer. Her latest book, Working in Public: The Making and Maintenance of Open Source Software, published by Stripe Press a few months ago, is a great read and if this topic interests you, I highly recommend it. The book itself is simply gorgeous; bright orange, textured hardcover binding, thick paper, wonderful typesetting it has everything to please. Well, nearly everything. Sadly, it is only available on Amazon, exclusively in the United States. A real let down for a book on Free and Open Source Software. The book is divided in five chapters, namely:
  1. Github as a Platform
  2. The Structure of an Open Source Project
  3. Roles, Incentives and Relationships
  4. The Work Required by Software
  5. Managing the Costs of Production
A picture of the book cover Contrary to what I was expecting, the book feels more like an extension of the LCA keynote I previously mentioned than Roads and Bridges. Indeed, as made apparent by the following quote, Eghbal doesn't believe funding to be the primary problem of FOSS anymore:
We still don't have a common understanding about who's doing the work, why they do it, and what work needs to be done. Only when we understand the underlying behavioral dynamics of open source today, and how it differs from its early origins, can we figure out where money fits in. Otherwise, we're just flinging wet paper towels at a brick wall, hoping that something sticks. p.184
That is to say, the behavior of maintainers and the challenges they face not the eternal money problem is the real topic of this book. And it feels refreshing. When was the last time you read something on the economics of Free Software without it being mostly about what licences projects should pick and how business models can be tacked on them? I certainly can't. To be clear, I'm not sure I agree with Eghbal on this. Her having worked at Github for a few years and having interviewed mostly people in the Ruby on Rails and Javascript communities certainly shows in the form of a strong selection bias. As she herself admits, this is a book on how software on Github is produced. As much as this choice irks me (the Free Software community certainly cannot be reduced to Github), this exercise had the merit of forcing me to look at my own selection biases. As such, reading Working in Public did to me something I wasn't expecting it to do: it broke my Free Software echo chamber. Although I consider myself very familiar with the world of Free and Open Source Software, I now understand my somewhat ill-advised contempt for certain programming languages mostly JS skewed my understanding of what FOSS in 2020 really is. My Free Software world very much revolves around Debian, a project with a strong and opinionated view of Free Software, rooted in a historical and political understanding of the term. This, Eghbal argues, is not the case for a large swat of developers anymore. They are The Github Generation, people attached to Github as a platform first and foremost, and who feel "Open Source" is just a convenient way to make things. Although I could intellectualise this, before reading the book, I didn't really grok how communities akin to npm have been reshaping the modern FOSS ecosystem and how different they are from Debian itself. To be honest, I am not sure I like this tangent and it is certainly part of the reason why I had a tendency to dismiss it as a fringe movement I could safely ignore. Thanks to Nadia Eghbal, I come out of this reading more humble and certainly reminded that FOSS' heterogeneity is real and should not be idly dismissed. This book is rich in content and although I could go on (my personal notes clock-in at around 2000 words and I certainly disagree with a number of things), I'll stop here for now. Go and grab a copy already!

  1. She insists on using the term open source, but I won't :)

2 November 2020

Vincent Bernat: My collection of vintage PC cards

Recently, I have been gathering some old hardware at my parents house, notably PC extension cards, as they don t take much room and can be converted to a nice display item. Unfortunately, I was not very concerned about keeping stuff around. Compared to all the hardware I have acquired over the years, only a few pieces remain.

Tseng Labs ET4000AX (1989) This SVGA graphics card was installed into a PC powered by a 386SX CPU running at 16 MHz. This was a good card at the time as it was pretty fast. It didn t feature 2D acceleration, unlike the later ET4000/W32. This version only features 512 KB of RAM. It can display 1024 768 images with 16 colors or 800 600 with 256 colors. It was also compatible with CGA, EGA, VGA, MDA, and Hercules modes. No contemporary games were using the SVGA modes but the higher resolutions were useful with Windows 3. This card was manufactured directly by Tseng Labs.
Carte Tseng Labs ET4000AX ISA au-dessus de la bo te "Plan te Aventure"
Tseng Labs ET4000 AX ISA card

AdLib clone (1992) My first sound card was an AdLib. My parents bought it in Canada during the summer holidays in 1992. It uses a Yamaha OPL2 chip to produce sound via FM synthesis. The first game I have tried is Indiana Jones and the Last Crusade. I think I gave this AdLib to a friend once I upgraded my PC with a Sound Blaster Pro 2. Recently, I needed one for a side project, but they are rare and expensive on eBay. Someone mentioned a cheap clone on Vogons, so I bought it. It was sold by Sun Moon Star in 1992 and shipped with a CD-ROM of Doom shareware.
AdLib clone on top of "Alone in the Dark" box
AdLib clone ISA card by Sun Moon Star
On this topic, take a look at OPL2LPT: an AdLib sound card for the parallel port and OPL2 Audio Board: an AdLib sound card for Arduino .

Sound Blaster Pro 2 (1992) Later, I switched the AdLib sound card with a Sound Blaster Pro 2. It features an OPL3 chip and was also able to output digital samples. At the time, this was a welcome addition, but not as important as the FM synthesis introduced earlier by the AdLib.
Sound Blaster Pro 2 on top of "Day of the Tentacle" box
Sound Blaster Pro 2 ISA card

Promise EIDE 2300 Plus (1995) I bought this card mostly for the serial port. I was using a 486DX2 running at 66 MHz with a Creatix LC 288 FC external modem. The serial port was driven by an 8250 UART with no buffer. Thanks to Terminate, I was able to connect to BBSes with DOS, but this was not possible with Windows 3 or OS/2. I needed one of these fancy new cards with a 16550 UART, featuring a 16-byte buffer. At the time, this was quite difficult to find in France. During a holiday trip, I convinced my parent to make a short detour from Los Angeles to San Diego to buy this Promise EIDE 2300 Plus controller card at a shop I located through an advertisement in a local magazine! The card also features an EIDE controller with multi-word DMA mode 2 support. In contrast with the older PIO modes, the CPU didn t have to copy data from disk to memory.
Promise EIDE 2300 Plus next to an OS/2 Warp CD
Promise EIDE 2300 Plus VLB card

3dfx Voodoo2 Magic 3D II (1998) The 3dfx Voodoo2 was one of the first add-in graphics cards implementing hardware acceleration of 3D graphics. I bought it from a friend along with his Pentium II box in 1999. It was a big evolutionary step in PC gaming, as games became more beautiful and fluid. A traditional video controller was still required for 2D. A pass-through VGA cable daisy-chained the video controller to the Voodoo, which was itself connected to the monitor.
3dfx Voodoo 2 Magic 3D II on top of "Jedi Knight: Dark Forces II" box
3dfx Voodoo2 Magic 3D II PCI card

3Com 3C905C-TX-M Tornado (1999) In the early 2000s, in college, the Internet connection on the campus was provided by a student association through a 100 Mbps Ethernet cable. If you wanted to reach the maximum speed, the 3Com 3C905C-TX-M PCI network adapter, nicknamed Tornado , was the card you needed. We would buy it second-hand by the dozen and sell them to other students for around 30 .
3COM 3C905C-TX-M on top of "Red Alert" box
3Com 3C905C-TX-M PCI card

Dirk Eddelbuettel: RcppSimdJson 0.1.2: New Upstream, New Utilities

A new RcppSimdJson release arrived on CRAN late yesterday bringing along the one recently updated simdjson release 0.6.0. RcppSimdJson wraps the fantastic and genuinely impressive simdjson library by Daniel Lemire and collaborators. Via very clever algorithmic engineering to obtain largely branch-free code, coupled with modern C++ and newer compiler instructions, it results in parsing gigabytes of JSON parsed per second which is quite mindboggling. The best-case performance is faster than CPU speed as use of parallel SIMD instructions and careful branch avoidance can lead to less than one cpu cycle per byte parsed; see the video of the talk by Daniel Lemire at QCon (also voted best talk). Other than the upstream update, Brendan added some new utilities to check for valid utf-8 or json format, and to minify json plus a small workaround for a clang-9 bug we encountered. We can confirm Daniel s statement on ridiculously fast utf-8 validattion. It is so cool to work with amazing tools. The NEWS entry follows.

Changes in version 0.1.3 (2020-11-01)
  • Added URLs to DESCRIPTION (Dirk closing #50).
  • Upgraded to simdjson 0.6.0 (Dirk in #52).
  • New policy option to always convert integers to int64_t (Brendan in #55 closing #54).
  • Added workaround for odd clang-9 bug (Brendan in #57).
  • New utility functions is_valid_utf8(), is_valid_json() and fminify() (Brendan in #58).

Courtesy of my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Sandro Knau : Bugzilla integration for KDE Project API

The KDE Bugzilla handles a lot of projects and they often match with the repo name, but not always. For instance we have ancient products and components at Bugzilla, as projects have a lifecycle from playground into Release Service, or Frameworks, sometimes with a change of name. So you may end up searching Bugzilla quite awhile for the correct product and component to be able to confirm or create bug reports against an application. Let's have a look at KPeople, and see why the situation is complicated. You find two products in KDE Bugzilla: kpeople (the repository's name) and on the other hand Frameworks have the scheme of a "frameworks-" prefix: frameworks-kpeople. From the data displayed even I as a developer am unable to tell which is the correct product to add new bug reports. Both have bug reports this year that got fixed and the number of bug reports is too low to get a clear picture of which to choose. This is not only a problem of KDE; it is a general problem in different communities that it is hard for newcomers to find the correct place to search and add new bug reports. That's why Debian added the bug report information for every package. This should help users to search the upstream bug reports or create new ones (Bug-Submit and Bug-Database): https://wiki.debian.org/UpstreamMetadata#Fields While I was collecting this information for Frameworks and KDE PIM, I wondered why KDE does not have links between each project and Bugzilla. After some searching and discussions it became obvious, that KDE does not have this information that can be processed. Okay let's fix this. The obvious place to reach this information is the Project API available under https://projects.kde.org/api/. To reach this goal I began adding Bugzilla information to the data source of the Project API named Git Repo Metadata. Then a merge request later the Project API is able to generate the links to Bugzilla invent:sysadmin/projects-api!2. Where you should search for bugs in kontact? Go to https://projects.kde.org/api/v1/identifier/kontact: After implementing the needed bits I found out that Nicolas Alvarez had the same idea, to store Bugzilla information in Git Repo Metadata invent:sysadmin/repo-metadata@085d878ea. Fortunately I can say that since June the information are used by Project API. So now, back to my task to add upstream metadata to Debian packages. After I filled the needed information to Repo Metadata I created a script to update the links in Debian salsa:qt-kde-team/pkg-kde-dev-scripts/function_collection/functions_plasma.py:addMissingBugMetadatafields. This should hopefully help to always point to the correct Bugzilla links in future. A random list came to my mind of places that may benefit from the Bugzilla information in Git Metadata Repository: The truth is, that Nicolas is right that adding the Bugzilla links are a manual task. But on the other hand, let's add this information once at one place and than we can use it at several places. Please help adding this information; it is simple a yaml file. If you see the data missing example commit and create a merge request. Or you can also give me the data and I'll add it.

1 November 2020

Vincent Bernat: Running Isso on NixOS in a Docker container

This short article documents how I run Isso, the commenting system used by this blog, inside a Docker container on NixOS, a Linux distribution built on top of Nix. Nix is a declarative package manager for Linux and other Unix systems.
While NixOS 20.09 includes a derivation for Isso, it is unfortunately broken and relies on Python 2. As I am also using a fork of Isso, I have built my own derivation, heavily inspired by the one in master:1
issoPackage = with pkgs.python3Packages; buildPythonPackage rec  
  pname = "isso";
  version = "custom";
  src = pkgs.fetchFromGitHub  
    # Use my fork
    owner = "vincentbernat";
    repo = pname;
    rev = "vbe/master";
    sha256 = "0vkkvjcvcjcdzdj73qig32hqgjly8n3ln2djzmhshc04i6g9z07j";
   ;
  propagatedBuildInputs = [
    itsdangerous
    jinja2
    misaka
    html5lib
    werkzeug
    bleach
    flask-caching
  ];
  buildInputs = [
    cffi
  ];
  checkInputs = [ nose ];
  checkPhase = ''
    $ python.interpreter  setup.py nosetests
  '';
 ;
I want to run Isso through Gunicorn. To this effect, I build a Python environment combining Isso and Gunicorn. Then, I can invoke the latter with "$ issoEnv /bin/gunicorn", like with a virtual environment.
issoEnv = pkgs.python3.buildEnv.override  
    extraLibs = [
      issoPackage
      pkgs.python3Packages.gunicorn
      pkgs.python3Packages.gevent
    ];
 ;
Before building a Docker image, I also need to specify the Isso configuration file for Isso:
issoConfig = pkgs.writeText "isso.conf" ''
  [general]
  dbpath = /db/comments.db
  host =
    https://vincent.bernat.ch
    http://localhost:8080
  notify = smtp
  [ ]
'';
NixOS comes with a convenient tool to build a Docker image without a Dockerfile:
issoDockerImage = pkgs.dockerTools.buildImage  
  name = "isso";
  tag = "latest";
  extraCommands = ''
    mkdir -p db
  '';
  config =  
    Cmd = [ "$ issoEnv /bin/gunicorn"
            "--name" "isso"
            "--bind" "0.0.0.0:$ port "
            "--worker-class" "gevent"
            "--workers" "2"
            "--worker-tmp-dir" "/dev/shm"
            "--preload"
            "isso.run"
          ];
    Env = [
      "ISSO_SETTINGS=$ issoConfig "
      "SSL_CERT_FILE=$ pkgs.cacert /etc/ssl/certs/ca-bundle.crt"
    ];
   ;
 ;
Because we refer to the issoEnv derivation in config.Cmd, the whole derivation, including Isso and Gunicorn, is copied inside the Docker image. The same applies for issoConfig, the configuration file we created earlier, and pkgs.cacert, the derivation containing trusted root certificates. The resulting image is 171 MB once installed, which is comparable to the Debian Buster image generated by the official Dockerfile. NixOS features an abstraction to run Docker containers. It is not currently documented in NixOS manual but you can look at the source code of the module for the available options. I choose to use Podman instead of Docker as the backend because it does not require running an additional daemon.
virtualisation.oci-containers =  
  backend = "podman";
  containers =  
    isso =  
      image = "isso";
      imageFile = issoDockerImage;
      ports = ["127.0.0.1:$ port :$ port "];
      volumes = [
        "/var/db/isso:/db"
      ];
     ;
   ;
 ;
A systemd unit file is automatically created to run and supervise the container:
$ systemctl status podman-isso.service
  podman-isso.service
     Loaded: loaded (/nix/store/a66gzqqwcdzbh99sz8zz5l5xl8r8ag7w-unit->
     Active: active (running) since Sun 2020-11-01 16:04:16 UTC; 4min 44s ago
    Process: 14564 ExecStartPre=/nix/store/95zfn4vg4867gzxz1gw7nxayqcl>
   Main PID: 14697 (podman)
         IP: 0B in, 0B out
      Tasks: 10 (limit: 2313)
     Memory: 221.3M
        CPU: 10.058s
     CGroup: /system.slice/podman-isso.service
              14697 /nix/store/pn52xgn1wb2vr2kirq3xj8ij0rys35mf-podma>
              14802 /nix/store/7vsba54k6ag4cfsfp95rvjzqf6rab865-conmo>
nov. 01 16:04:17 web03 podman[14697]: container init (image=localhost/isso:latest)
nov. 01 16:04:17 web03 podman[14697]: container start (image=localhost/isso:latest)
nov. 01 16:04:17 web03 podman[14697]: container attach (image=localhost/isso:latest)
nov. 01 16:04:19 web03 conmon[14802]: INFO: connected to SMTP server
nov. 01 16:04:19 web03 conmon[14802]: INFO: connected to https://vincent.bernat.ch
nov. 01 16:04:19 web03 conmon[14802]: [INFO] Starting gunicorn 20.0.4
nov. 01 16:04:19 web03 conmon[14802]: [INFO] Listening at: http://0.0.0.0:8080 (1)
nov. 01 16:04:19 web03 conmon[14802]: [INFO] Using worker: gevent
nov. 01 16:04:19 web03 conmon[14802]: [INFO] Booting worker with pid: 8
nov. 01 16:04:19 web03 conmon[14802]: [INFO] Booting worker with pid: 9
As the last step, we configure Nginx to forward requests for comments.luffy.cx to the container. NixOS provides a simple integration to grab a Let s Encrypt certificate.
services.nginx.virtualHosts."comments.luffy.cx" =  
  root = "/data/webserver/comments.luffy.cx";
  enableACME = true;
  forceSSL = true;
  extraConfig = ''
    access_log /var/log/nginx/comments.luffy.cx.log anonymous;
  '';
  locations."/" =  
    proxyPass = "http://127.0.0.1:$ port ";
    extraConfig = ''
      proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
      proxy_set_header Host $host;
      proxy_set_header X-Forwarded-Proto $scheme;
      proxy_hide_header Set-Cookie;
      proxy_hide_header X-Set-Cookie;
      proxy_ignore_headers Set-Cookie;
    '';
   ;
 ;
security.acme.certs."comments.luffy.cx" =  
  email = lib.concatStringsSep "@" [ "letsencrypt" "vincent.bernat.ch" ];
 ;

While I still struggle with Nix and NixOS, I am convinced this is how declarative infrastructure should be done. I like how in one single file, I can define the derivation to build Isso, the configuration, the Docker image, the container definition, and the Nginx configuration. The Nix language is used both for building packages and for managing configurations. Moreover, the Docker image is updated automatically like a regular NixOS host. This solves an issue plaguing the Docker ecosystem: no more stale images! My next step would be to combine this approach with Nomad, a simple orchestrator to deploy and manage containers.

  1. There is a subtle difference: I am using buildPythonPackage instead of buildPythonApplication. This is important for the next step. I didn t investigate if an application can be converted to a package easily.

Steve Kemp: Archiving Debian-Administration.org, for real

Back in 2017 I announced that the https://Debian-Administration.org website was being made read-only, and archived. At the time I wrote a quick update to save each requested page as a flat-file, hashed beneath /tmp, with the expectation that after a few months I'd have a complete HTML-only archive of the site which I could serve as a static-website, instead of keeping the database and pile of CGI scripts running. Unfortunately I never got round to archiving the pages in a git-repository, or some other store, and I usually only remembered this local tree of content was available a few minutes after I'd rebooted the server and lost the stuff - as the reboot would reap the contents of /tmp! Thinking about it today I figured I probably didn't even need to do that, instead I just need to redirect to the wayback machine. Working on the assumption that the site has been around for "a while" it should have all the pages mirrored by now I've made a "final update" to Apache:
 RewriteEngine on
 RewriteRule   ^/(.*)  "http://web.archive.org/web/https://debian-administration.org/$1"  [R,L]
Assuming nobody reports a problem in the next month I'll retire the server and make a simple docker container to handle the appropriate TLS certificate renewal, and hardwire the redirection(s) for the sites involved.

29 October 2020

Norbert Preining: Deleting many files from an S3 bucket

So we found ourselves in the need to delete a considerable amount of files (around 500000, amounting to 1.6T) from an S3 bucket. With the list of files in hand my first shot was calling
aws s3 rm s3://BUCKET/FILE
for each file. That wasn t the best idea I have to say, since first of all, it makes 500000 requests, and then it takes a looong time. And this command does not allow to pass in multiple files. Fortunately there is aws s3api delete-objects which takes a json input and can delete multiple files:
aws 3api delete-objects --bucket BUCKET --delete ' "Objects": [   "Key" : "FILE1"  ,   "Key" : "FILE2"  ... ] '
That did help, and with a bit of magic from bash (mapfile which can read in lines from stdin in batches) and jq, at the end it was a business of some 20min or so:
cat files-to-be-deleted    while mapfile -t -n 500 ary && (($ #ary[@] )); do
        objdef=$(printf '%s\n' "$ ary[@] "   jq -nR ' Objects: (reduce inputs as $line ([]; . + [ "Key":$line ])) ')
        aws s3api --no-cli-pager  delete-objects --bucket BUCKET --delete "$objdef"
done
This reads 500 files a time, and reformats it using jq into the proper json format: reduce inputs is a jq filter that iterates over the input lines and does a map/reduce step. In this case we use an empty array as start and add new key/filename pairs on the go. Finally, the whole bunch is send to AWS with the above API call. Puuuh, 500000 files and 1.6T less, in 20min.

28 October 2020

Daniel Lange: Git shared hosting quirk

Show https://github.com/torvalds/linux/blob/b4061a10fc29010a610ff2b5b20160d7335e69bf/drivers/hid/hid-samsung.c#L113-L118 to a friend. Oops 'eh? Yep, Linux has been backdoored. Well, or not. Konstantin Ryabitsev explains it nicely in a cgit mailing list email:
It is common for git hosting environments to configure all forks of the same repo to use an "object storage" repository. For example, this is what allows git.kernel.org's 600+ forks of linux.git to take up only 10GB on disk as opposed to 800GB. One of the side-effects of this setup is that any object in the shared repository can be accessed from any of the forks, which periodically confuses people into believing that something terrible has happened.
The hack was discussed on Github in Dec 2018 when it was discovered. I forgot about it again but Konstantin's mail brought the memory back and I think it deserves more attention. I'm sure putting some illegal content into a fork and sending a made up "blob" URL to law enforcement would go quite far. Good luck explaining the issue. "Yes this is my repo" but "no, no that's not my data" ... "yes, it is my repo but not my data" ... "no we don't want that data either, really" ... "but, but there is nothing we can do, we host on github...1". Update 05.11.20 Nate Friedman (CEO of Github) promises
[..] we are going to make it much more obvious when you're viewing an orphaned commit.
For context: The source code of Github (the product) had been leaked as a commit to Github's own DMCA repository. The repository has turned into a playground since Github took down the hosting for youtube-dl as the result of a DMCA complaint. 14.11.20 Seems Github now adds a warning to commits that are not in a reachable branch Github commit warning message

  1. Actually there is something you can do. Making a repo private takes it out of the shared "object storage". You can make it public again afterwards. Seems to work at least for now.

24 October 2020

Dirk Eddelbuettel: digest 0.6.27: Build fix

Exactly one week after the previous release 0.6.26 of digest, a minor cleanup release 0.6.27 just arrived on CRAN and will go to Debian shortly. digest creates hash digests of arbitrary R objects (using the md5, sha-1, sha-256, sha-512, crc32, xxhash32, xxhash64, murmur32, spookyhash, and blake3 algorithms) permitting easy comparison of R language objects. It is a fairly widely-used package (currently listed at one million monthly downloads, 282 direct reverse dependencies and 8068 indirect reverse dependencies, or just under half of CRAN) as many tasks may involve caching of objects for which it provides convenient general-purpose hash key generation. Release 0.6.26 brought support for the (nice, even cryptographic) blake3 hash algorithm. In the interest of broader buildability we had already (with a sad face) disabled a few very hardware-specific implementation aspects using intrinsic ops. But to our chagrin, we left one #error define that raised its head on everybody s favourite CRAN build platform. Darn. So 0.6.27 cleans that up and also removes the check and #error as all the actual code was already commented out. If you read this and tears start running down your cheeks, then by all means come and help us bring blake3 to its full (hardware-accelerated) potential. This (probably) only needs a little bit of patient work with the build options and configurations. You know where to find us My CRANberries provides the usual summary of changes to the previous version. For questions or comments use the issue tracker off the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

23 October 2020

Dirk Eddelbuettel: RcppSpdlog 0.0.3: New features and much more docs

A good month after the initial two releases, we are thrilled to announce relase 0.0.3 of RcppSpdlog. This brings us release 1.8.1 of spdlog as well as a few local changes (more below). RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovic. This version of RcppSpdlog brings a new top-level function setLogLevel to control what events get logged, updates the main example to show this and to also make the R-aware logger the default logger, and adds both an extended vignette showing several key features and a new (external) package documentation site. The NEWS entry for this release follows.

Changes in RcppSpdlog version 0.0.3 (2020-10-23)
  • New function setLogLevel with R accessor in exampleRsink example
  • Updated exampleRsink to use default logger instance
  • Upgraded to upstream release 1.8.1 which contains finalised upstream use to switch to REprintf() if R compilation detected
  • Added new vignette with extensive usage examples, added compile-time logging switch example
  • A package documentation website was added

Courtesy of my CRANberries, there is also a diffstat report. More detailed information is on the RcppSpdlog page. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

21 October 2020

Dirk Eddelbuettel: RcppZiggurat 0.1.6

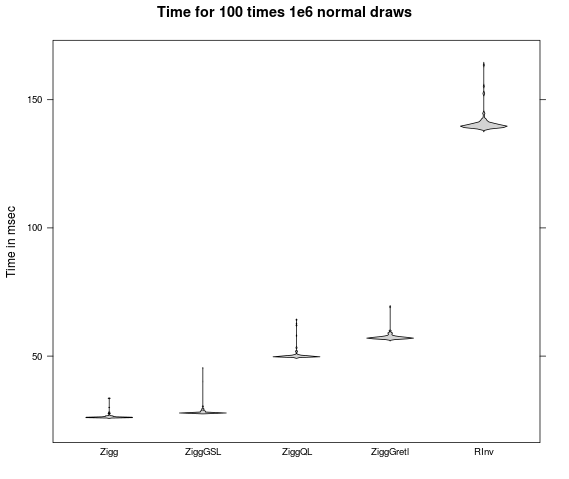
ziggurats A new release, now at version 0.1.6, of RcppZiggurat is now on the CRAN network for R. The RcppZiggurat package updates the code for the Ziggurat generator by Marsaglia and other which provides very fast draws from a Normal distribution. The package provides a simple C++ wrapper class for the generator improving on the very basic macros, and permits comparison among several existing Ziggurat implementations. This can be seen in the figure where Ziggurat from this package dominates accessing the implementations from the GSL, QuantLib and Gretl all of which are still way faster than the default Normal generator in R (which is of course of higher code complexity). This release brings a corrected seed setter and getter which now correctly take care of all four state variables, and not just one. It also corrects a few typos in the vignette. Both were fixed quite a while back, but we somehow managed to not ship this to CRAN for two years. The NEWS file entry below lists all changes.

Changes in version 0.1.6 (2020-10-18)
  • Several typos were corrected in the vignette (Blagoje Ivanovic in #9).
  • New getters and setters for internal state were added to resume simulations (Dirk in #11 fixing #10).
  • Minor updates to cleanup script and Travis CI setup (Dirk).

Courtesy of my CRANberries, there is a diffstat report for this release. More information is on the RcppZiggurat page. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

20 October 2020

Dirk Eddelbuettel: RcppArmadillo 0.10.1.0.0

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 786 other packages on CRAN. A little while ago, Conrad released version 10.1.0 of Armadillo, a a new major release. As before, given his initial heads-up we ran two full reverse-depends checks, and as a consequence contacted four packages authors (two by email, two via PR) about a miniscule required change (as Armadillo now defaults to C++11, an old existing setting of avoiding C++11 lead to an error). Our thanks to those who promptly update their packages truly appreciated. As it turns out, Conrad also softened the error by the time the release ran around. But despite our best efforts, the release was delayed considerably by CRAN. We had made several Windows test builds but luck had it that on the uploaded package CRAN got itself a (completely spurious segfault which can happen on a busy machine building machine things at once). Sadly it took three or four days for CRAN to reply our email. After which it took another number of days for them to ponder the behaviour of a few new deprecated messaged tickled by at the most ten or so (out of 786) packages. Oh well. So here we are, eleven days after I emailed the rcpp-devel list about the new package being on CRAN but possibly delayed (due to that seg.fault). But during all that time the package was of course available via the Rcpp drat. The changes in this release are summarized below as usual and are mostly upstream along with an improved Travis CI setup due to the aforementioned use of the bspm package for binaries at Travis.

Changes in RcppArmadillo version 0.10.1.0.0 (2020-10-09)
  • Upgraded to Armadillo release 10.1.0 (Orchid Ambush)
    • C++11 is now the minimum required C++ standard
    • faster handling of compound expressions by trimatu() and trimatl()
    • faster sparse matrix addition, subtraction and element-wise multiplication
    • expanded sparse submatrix views to handle the non-contiguous form of X.cols(vector_of_column_indices)
    • expanded eigs_sym() and eigs_gen() with optional fine-grained parameters (subspace dimension, number of iterations, eigenvalues closest to specified value)
    • deprecated form of reshape() removed from Cube and SpMat classes
    • ignore and warn on use of the ARMA_DONT_USE_CXX11 macro
  • Switch Travis CI testing to focal and BSPM

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Steve Kemp: Offsite-monitoring, from my desktop.

For the past few years I've had a bunch of virtual machines hosting websites, services, and servers. Of course I want them to be available - especially since I charge people money to access at some of them (for example my dns-hosting service) - and that means I want to know when they're not. The way I've gone about this is to have a bunch of machines running stuff, and then dedicate an entirely separate machine solely for monitoring and alerting. Sure you can run local monitoring, testing that services are available, the root-disk isn't full, and that kind of thing. But only by testing externally can you see if the machine is actually available to end-users, customers, or friends.
A local-agent might decide "I'm fine", but if the hosting-company goes dark due to a fibre cut you're screwed.
I've been hosting my services with Hetzner (cloud) recently, and their service is generally pretty good. Unfortunately I've started to see an increasing number of false-alarms. I'd have a server in Germany, with the monitoring machine in Helsinki (coincidentally where I live!). For the past month I've started to get pinged with a failure every three/four days on average, "service down - dns failed", or "service down - timeout". When the notice would wake me up I'd go check and it would be fine, it was a very transient failure. To be honest the reason for this is my monitoring is just too damn aggressive, I like to be alerted immediately in case something is wrong. That means if a single test fails I get an alert, as rather than only if a test failed for something more reasonable like three+ consecutive failures. I'm experimenting with monitoring in a less aggressive fashion, from my home desktop. Since my monitoring tool is a single self-contained golang binary, and it is already packaged as a docker-based container deployment was trivial. I did a little work writing an agent to receive failure-notices, and ping me via telegram - instead of the previous approach where I had an online status-page which I could view via my mobile, and alerts via pushover. So far it looks good. I've tweaked the monitoring to setup a timeout of 15 seconds, instead of 5, and I've configured it to only alert me if there is an outage which lasts for >= 2 consecutive failures. I guess the TLDR is I now do offsite monitoring .. from my house, rather than from a different region. The only real reason to write this post was mostly to say that the process of writing a trivial "notify me" gateway to interface with telegram was nice and straightforward, and to remind myself that transient failures are way more common than we expect. I'll leave things alone for a moment, but it was a fun experiment. I'll keep the two systems in parallel for a while, but I guess I can already predict the outcome:

19 October 2020

Antoine Beaupr : SSH 2FA with Google Authenticator and Yubikey

About a lifetime ago (5 years), I wrote a tutorial on how to configure my Yubikey for OpenPGP signing, SSH authentication and SSH 2FA. In there, I used the libpam-oath PAM plugin for authentication, but it turns out that had too many problems: users couldn't edit their own 2FA tokens and I had to patch it to avoid forcing 2FA on all users. The latter was merged in the Debian package, but never upstream, and the former was never fixed at all. So I started looking at alternatives and found the Google Authenticator libpam plugin. A priori, it's designed to work with phones and the Google Authenticator app, but there's no reason why it shouldn't work with hardware tokens like the Yubikey. Both use the standard HOTP protocol so it should "just work". After some fiddling, it turns out I was right and you can authenticate with a Yubikey over SSH. Here's that procedure so you don't have to second-guess it yourself.

Installation On Debian, the PAM module is shipped in the google-authenticator source package:
apt install libpam-google-authenticator
Then you need to add the module in your PAM stack somewhere. Since I only use it for SSH, I added this line on top of /etc/pam.d/sshd:
auth required pam_google_authenticator.so nullok
I also used no_increment_hotp debug while debugging to avoid having to renew the token all the time and have more information about failures in the logs. Then reload ssh (not sure that's actually necessary):
service ssh reload

Creating or replacing tokens To create a new key, run this command on the server:
google-authenticator -c
This will prompt you for a bunch of questions. To get them all right, I prefer to just call the right ones on the commandline directly:
google-authenticator --counter-based --qr-mode=NONE --rate-limit=1 --rate-time=30 --emergency-codes=1 --window-size=3
Those are actually the defaults, if my memory serves me right, except for the --qr-mode and --emergency-codes (which can't be disabled so I only print one). I disable the QR code display because I won't be using the codes on my phone, but you would obviously keep it if you want to use the app.

Converting to a Yubikey-compatible secret Unfortunately, the encoding (base32) produced by the google-authenticator command is not compatible with the token expected by the ykpersonalize command used to configure the Yubikey (base16 AKA "hexadecimal", with a fixed 20 bytes length). So you need a way to convert between the two. I wrote a program called oath-convert which basically does this:
read base32
add padding
convert to hex
print
Or, in Python:
def convert_b32_b16(data_b32):
    remainder = len(data_b32) % 8
    if remainder > 0:
        # XXX: assume 6 chars are missing, the actual padding may vary:
        # https://tools.ietf.org/html/rfc3548#section-5
        data_b32 += "======"
    data_b16 = base64.b32decode(data_b32)
    if len(data_b16) < 20:
        # pad to 20 bytes
        data_b16 += b"\x00" * (20 - len(data_b16))
    return binascii.hexlify(data_b16).decode("ascii")
Note that the code assumes a certain token length and will not work correctly for other sizes. To use the program, simply call it with:
head -1 .google_authenticator   oath-convert
Then you paste the output in the prompt:
$ ykpersonalize -1 -o oath-hotp -o append-cr -a
Firmware version 3.4.3 Touch level 1541 Program sequence 2
 HMAC key, 20 bytes (40 characters hex) : [SECRET GOES HERE]
Configuration data to be written to key configuration 1:
fixed: m:
uid: n/a
key: h:[SECRET REDACTED]
acc_code: h:000000000000
OATH IMF: h:0
ticket_flags: APPEND_CR OATH_HOTP
config_flags: 
extended_flags: 
Commit? (y/n) [n]: y
Note that you must NOT pass the -o oath-hotp8 parameter to the ykpersonalize commandline, which we used to do in the Yubikey howto. That is because Google Authenticator tokens are shorter: it's less secure, but it's an acceptable tradeoff considering the plugin is actually maintained. There's actually a feature request to support 8-digit codes so that limitation might eventually be fixed as well. Thanks to the Google Authenticator people and Yubikey people for their support in establishing this procedure.

18 October 2020

Antoine Beaupr : CDPATH replacements

after reading this post I figured I might as well bite the bullet and improve on my CDPATH-related setup, especially because it does not work with Emacs. so i looked around for autojump-related alternatives that do.

What I use now I currently have this in my .shenv (sourced by .bashrc):
export CDPATH=".:~:~/src:~/dist:~/wikis:~/go/src:~/src/tor"
This allows me to quickly jump into projects from my home dir, or the "source code" (~/src), "work" (src/tor), or wiki checkouts (~/wikis) directories. It works well from the shell, but unfortunately it's very static: if I want a new directory, I need to edit my config file, restart shells, etc. It also doesn't work from my text editor.

Shell jumpers Those are commandline tools that can be used from a shell, generally with built-in shell integration so that a shell alias will find the right directory magically, usually by keeping track of the directories visited with cd. Some of those may or may not have integration in Emacs.

autojump

fasd

z

fzf

Emacs plugins not integrated with the shell Those projects can be used to track files inside a project or find files around directories, but do not offer the equivalent functionality in the shell.

projectile

elpy
  • home page
  • elpy has a notion of projects, so, by default, will find files in the current "project" with C-c C-f which is useful

bookmarks.el
  • built-in
  • home page
  • "Bookmarks record locations so you can return to them later"

recentf
  • built-in
  • home page
  • "builds a list of recently opened files. This list is is automatically saved across sessions on exiting Emacs - you can then access this list through a command or the menu"

references https://www.emacswiki.org/emacs/LocateFilesAnywhere

Next.

Previous.