Search Results: "will"

2 December 2007

Brandon Holtsclaw: ugh

fabbione why oh why did you upload openssl097 UNPATCHED when there were known security issues with this version, with the fix even linked to in the bug? This software was removed from Gutsy for a reason, if its going to be added back it should ATLEASTE be patched, as it stands right now anyone who installs vmware-server via Canonical’s Partner Repository is remote exploitable and it was known prior to the upload, is this a case of $$ from VMware means more than security? I’m sorry but this is simply not acceptable from Canonical as far as I’m concerned. It isnt a case where VMware is distributing it, its us, or atleaste Canonical distributing it to STABLE releases. At this point a patch to fix the issue will simply not be enough, I want to know why this happened. And whats going to be done to ensure the Distribution I spend many hours for volunteering isnt going to allow this to happen again. I Love Ubuntu and hate to see things like this happen, lets ensure they dont. /* annoyed */

Brandon Holtsclaw: Brandon s Holiday Computer Fund

I’m a developer, and my primary tool is my computer. Unfortunately, about 3 months ago, my computer died an untimely death, and I have resorted to using a pentium 200MHz machine with 256MB Ram, which lets me keep up with regular communications, but significantly slows the pace of development. As a computer is a big purchase, and represents most of what I want to receive for the holidays, I’ve set up a fundraiser so that people who wanted to help towards this gift could do so without needing to purchase the entire thing (and to avoid the all too common problem of receiving 8 video cards and no RAM). www.fundable.com allows me to accept pledges via paypal but NOT collect any unless the goal is met, so if you feel giving and pledge something, it will only be charged if the goal is met ( this is set at $250, which seems to be the minimum for a decent system, if more is collected, I can look at something better). You can read more about how fundable works from www.fundable.com/faq, and I’m more than happy to answer any questions via email, IRC, Jabber, etc.

Thomas Girard: Fun with templates

At work we had to use two C libraries defining structures with different size but same name. Function names were different though, so we believed no symbol clash would occur. We thought if we used the headers from each library in a different compilation unit we'd be safe. But we were wrong. The code compiled fine but crashed at runtime. Why? Because we used templates within these compilation units, and this generated weak symbols with the very same name. The linker then discarded duplicate symbols, and since structure size was different we got a crash. Let's reproduce this on a small example:
/* A.h */
#ifndef A_H
#define A_H
struct Data   int an_int;  ;
#endif
/* B.h */
#ifndef B_H
#define B_H
struct Data   char a_buffer[65];  ;
#endif
/* UsingA.cpp */
#inlude "A.h"
#inlude <deque>
static std::deque<Data> a_datas;
std::size_t get_a_size()   return a_datas.size();  
/* UsingB.cpp */
#inlude "B.h"
#inlude <deque>
static std::deque<Data> b_datas;
std::size_t get_b_size()   return b_datas.size();  
/* Main.cpp */
int main(int argc, char* argv[])    return 0;  
We compile these files:
$ g++ -c -I . UsingA.cpp UsingB.cpp Main.cpp
$ g++ -o Main UsingA.o UsingB.o Main.o
and inspect what got generated in UsingA.o, choosing the call to size() to reduce the output:
$ nm -C UsingA.o   grep '::size()'
0000000000000000 W std::deque<Data, std::allocator<Data> >::size() const
Likewise in UsingB.o:
$ nm -C UsingB.o   grep '::size()'
0000000000000000 W std::deque<Data, std::allocator<Data> >::size() const
g++ has generated code for the deque we're using. That's how templates work: they get "expanded" in the compilation unit using them. So far so good. Now if we look in Main:
$ nm -C Main   grep '::size()'
0000000000400a64 W std::deque<Data, std::allocator<Data> >::size() const
we see there's only a single symbol in the resulting binary. Because the symbols are weak (see the W in nm output), g++ silently discards one version, say the version in UsingB.o. (If they were not weak, link would fail because of duplicate symbols. And every C++ program would fail to link.) Therefore any call on b_datas is likely to fail: the deque code called will not use the right definition of Data. Lesson learned: avoid data structures with the same name.

1 December 2007

John Goerzen: Attention Junkmailers

We love to hear from you. I'm sure that's what you're thinking, anyway, as you prepare volumes of paper to send to our mailbox.

But just so you know, let me explain just how much we love the material you send us.

When we get one of your catalogs, it will get added to the junk mail pile. Every so often, I will go through this pile. I will contact the company behind each and every mailing, asking them to remove me from their list and not rent my name further. If I have extra time, I will probably also write that note on your postage-paid envelope and pop it in the mailbox. I will also add your name to my list of companies that send me junk mail, so I can avoid doing business with you in the future. If you have sent me junk mail in the past, rest assured that I will find some creatively enjoyable way of dealing with your refusal to honor my removal request.

After I have processed your piece of artfully-crafted handiwork, possibly trying to sell me pink laptops or a shirt with the word "femail" on it -- whatever that means -- I will deposit your catalog, along with dozens of other similar catalogs, on the kitchen floor.

This is when the real fun begins, because now it's Jacob's turn to process them.

He will usually start by ripping out every page from the catalog. He'll start slowly and carefully, ripping out pages one at a time, savoring the wonderful rrrrriiiiippppp noise as he goes. But then he'll get faster, going for two pages at a time, then more, until finally he just will lunge for paper by the handful to crush, tear, or otherwise mutilate.

After that, there are many things he might do to your fine piece of unsolicited advertising. Perhaps he will enjoy drooling on it -- a satisfying fate for your 4-color catalog, don't you think? Or perhaps he will grab some of your pages, carefully emblazoned with your logo, and tear them into as many tiny bits as he can. Or maybe he will simply gather your work together on the floor, then spin himself around on top of it, scattering the remnants as far and wide as possible, cackling all the while. He may also smear bits of food on them if he ate recently, or perhaps he will simply resume tearing pages apart.

But whatever he does, rest assured that he will treat your catalog with the care and attention it deserves. No catalog will survive intact, and as many pages as possible will be ripped apart and left in bits. He does, after all, have a great attention to detail.

After Jacob is done, we will gather up what remains and put it all in our recycling container.

Oh, and under no circumstances will we actually make a purchase from your catalog.

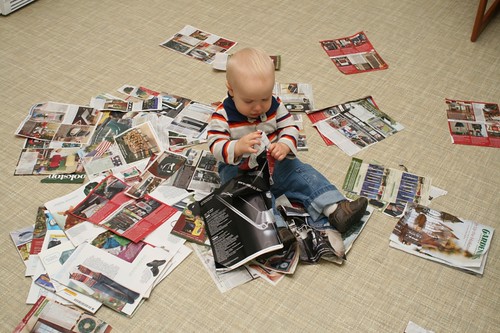
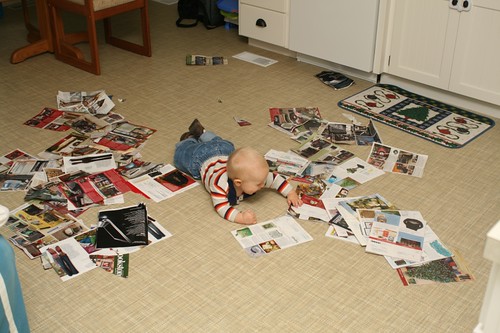
Here are two pictures of the scene.

img_4160.jpg

Notice the careful concentration in this photo. Obviously he knows that Dell has been ignoring my removal requests for some time, and is taking note to tear their pages into the smallest possible bits.

But it's not all hard work -- processing your catalogs is fun, too.

img_4163.jpg

Christian Perrier: Heading to FOSS.in

Tomorrow morning, I'll leave for Bangalore to attend FOSS.in, the major FLOSS event in India (for BLR people, my arrival time is 07:30 on Monday). That will be my first time in India, so probaly a lot to discover and learn. Also, of course, many online friends to meet in real life, which is always something one enjoys. I'll have two talks (in a row!) there. One is my first time talking about "Contrbuting to Debian". I hope I will make it interesting for attending people. The main goal is explaining that there are much much more ways to contribute to Debian than one would imagine, and roughly say that becoming a DD is far from being the only way to contribute. The other talk is my standard i18n talk, slightly more focused on localization for languages from India (yes, with the maps, of course). Sam Hocevar is also coming and giving talks. I cross fingers for people there to not be bored about our damn French accent. I'll be really delighted to share this with Sam who is someone I really appreciate (and, actually, even more since he is doing good job as DPL). Of course, I know that the most interesting will be BOFs and informal discussions as well as booths visits and the like. Everybody knows that India is the paradise for people working in i18n: so many languages to cope with! I already know it will be too short, I'm afraid, but see you in BLR !

Gunnar Wolf: Is it already December!? Oh, crap...

Last weekend, Nadezhda and me went to the the San Nicol s Totoloapan park, a beautiful area in the slopes of the Ajusco mountain. We cycled only for a short while, as we are not really used to slopes nor to non-paved roads - But all in all, it was very fun and a very nice time.But, only now I realize, thanks to the oh-so-always-nice Rodrigo, that, because of having fun while being at the Ajusco, we completely missed November's Ciclot n.Crap.Cycling over 30 Km in Mexico City is very fun. Nadezhda loved it when she did it in August, just the day I came back from Vienna. I loved it when I did it last month, when she was in Monterrey. But, being together, we insist on missing it. Bah. Anyway, this Sunday we will have the short (~15Km) ride in Coyoac n.

30 November 2007

Steve Kemp: We are the champions my friend

My tool to query apache logfiles via SQL seems suprisingly popular. Just as a recap the process goes like this: Now it is possible to save and load the SQLite database, so that you don't need to reparse the apache logs each time, that gives a nice speed increase for non-changing files. By tonight I'll have aliases working for queries so you can bookmark them:
alias refers SELECT distinct(referer) FROM logs
Then in the future the 'refers' command will be available and will run the named query. Neat. Now that I'm comfortable with SQL queries it just seems so natural, easy, and right to query logfiles this way. I guess that makes me strange.

Daniel Burrows: The Dreaded I-Word

A popular and recurrent topic of conversation on the Internet has the following form:
Is (X) innovative?
I occasionally find myself reading these discussions; they have the same sort of macabre fascination for me that's often ascribed to train wrecks, messy divorces, and Usenet. Of course, the outcome (or rather the lack of one) is always predetermined. The only variable is how many pixels will be mutilated and how many absurd postures will be struck before the dust settles. Why do I say the outcome is predetermined? Because in not one of these discussions does the person posing the question precisely define what innovation is. If the discussion concerned, say, whether an object was blue, or made of concrete, or 5 meters by 6 meters, this would not be a real problem: while any hair can be split, there are commonly accepted definitions of blue, concrete, and meter that are sufficient for an informal discussion. But innovation is not blue, concrete, or meter. Different people have subtly, even radically different views of what constitutes innovation and how to measure it. Hence, any discussion involving more than one person quickly devolves into chaos. One person will say, X is innovative because of such-and-such, and another will reply, X is not innovative because of such-and-such unrelated reason. Both writers are correct by their own definitions of innovation; they are answering different questions, and so they end up talking past one another. Although these discussions never go anywhere, I think it's entertaining and enlightening to catalogue some of the definitions of innovation that the participants use. I've listed some popular definitions below; feel free to email me with more suggestions and I'll update the list. Of course, since people rarely bother to define their terms, most of these meanings have been inferred from the statements people have made about what is and is not innovative. As a result, some of them are fairly absurd and may not accurately reflect the opinions of the speakers, had the speakers stopped to think about what they were saying. Caveat lector. Conventions: Below, personal pronouns such as I and me refer to the speaker. The words product, idea, and technique are used interchangeably and as appropriate to refer to the thing whose innovativeness is in dispute.
  • The idea advanced the state of human knowledge.
  • The idea was an improvement over existing ideas.
  • The idea improved the state of practice within its field.
  • The idea was previously unknown.
  • The idea was previously unknown to its creator.
  • The idea was previously unknown to me.
  • The technique solved a problem thought to be unsolvable.
  • The technique solved a problem with no known solution.
  • The technique solved a problem with no solution known to me.
  • The technique solved a problem with no solution known to its inventor.
  • The product was aesthetically pleasing to me.
  • The product is entirely unlike any other product with which I am familiar.
  • The product is exactly the same as some other product with which I am familiar.
  • The product solved a problem more effectively than existing tools.
  • The product made its creator the wealthiest living human.
  • The product made its creator wealthy.
  • The product made someone wealthy.
  • The product reaped a huge profit for the corporation selling it.
  • The product was bought by many people.
  • The product was used by many people.
  • The product was useful to many people.
  • The product was useful to someone.
  • I bought the product.
  • The product was useful to me.
  • The product was created by (some particular entity, such as Toyota or Apple).
  • The product was not created by (some particular entity).
  • The product is good. (NB: of course good is another ambiguous term with many definitions, one of which appears to be innovative; the fun never stops!)
A Contrarian View This post charitably assumes that the purpose of the discussions I described, and the goal of the participants, is to arrive at a commonly agreed-upon answer to the opening question. In reality, though, most discussions on the Internet, particularly when they involve many anonymous or pseudonymous parties, are just tribal wars. Individuals decide which side to affiliate themselves with, then search for arguments that will tend to support their side or undercut the opposition. Facts and logic are largely irrelevant, except as weapons with which to smack one's opponents, and a dismissive put-down is as good as or better than a reality-based analysis. Actually changing your mind based on the evidence presented shows weakness, and is to be avoided at all costs. If you have to assert that up is down, do it. In this environment, using vague terms appears to be a bonus, since it gives you more wiggle room and opportunities to play gotcha!. If someone responds to your post with facts that rebut you based on the definition you were using, you can pick any other definition and say ...but what about..? Which is why these discussions (in which no-one is actually discussing anything) are both a fascinating window into human nature and a depressing commentary on human nature, and why I keep finding myself reading them.
PS: This post is the first long post that I've used ikiwiki to write. An advantage of my new workflow, where I write posts on the bus and commit them into a local git repository, is that I have a nice block of time to write down random thoughts that have occurred to me on the way to or from work; sometimes I forget what I was going to write over the course of the day, and when I get home I usually get deluged in email and real life. It's always amazing to me how long it takes to write posts when I actually think about what I'm doing. This post has taken me at least an hour to compose, and I think probably more (especially counting the composition I did in my head while, e.g., walking from point A to point B). It's a lot harder -- which means, of course, that it's fun; if I don't get distracted by a coding project, I'll be trying to take advantage of my new workflow to post more often.
Felipe Augusto van de Wiel: 30 Nov 2007

It is about time...

qmail under Public Domain
Using qmail-ldap for quite some time (first because of my employer and then because I was used to it), the DJB license was a major pain, qmail-ldap patch is under BSD, but the original qmail was non-free. Yes, was. Yesterday DJB released qmail under Public Domain, and based on a GoogleVideo, he is going to change the license for all his existent software and for all his future works.

For some strange reason the URL direct to the video doesn't work, but if you do a search you are able to use the Watch video here option.


Not only that
Yes, I know. I'm not going to say sorry, I should post more, this last three months were not exactly the best ones, and I thought about writing something about what I was doing for Debian and other projects here but ended up being consumed by University, Work, Real Life and "Other Stuff (tm)".

One of the important things on the way is the Debian i18n Extremadura Meeting to be held on December, when we expect to work on i18n.debian.net, change from CVS to SVN, improve DDTP and ddtss and work with Pootle related stuff and infrastructure.

In the meantime, we are also changing our Primary Push Server for volatile.debian.org from durin to verdi (don't worry, a proper announcement will be made on an announcement list close to you). :-)

Thanks for everybody that had the patient to wait for my replies and/or my actions, and the ones that calmly understood my undergoing situation, giving me support and offering help. Thank you very much!

Russell Coker: Vista ReadyBoostReady - Good for Linux?

At the moment it seems that about half the USB flash devices on sale are listed as “Vista ReadyBoost Ready“. I recently bought an 8G USB device that I returned because it could only sustain 4MB/s writes (not much fun for backing up 4G+ of data). So I’ve been wondering whether I should get a ReadyBoostReady device. ReadyBoostReady only means that it is faster than other devices in some ways, it has no inherent feature difference. After some searching I found a FAQ about ReadyBoost [1] which explains what it requires. It seems that ReadyBoost needs “2.5MB/sec throughput for 4K random reads and 1.75MB/sec throughput for 512K random writes“, which isn’t really a lot. About 5-6 years ago I was running some machines with 4 disk RAID-5 arrays that could sustain 3MB/s writes for significantly smaller block sizes (maybe 12K), given that random access is something that disks are really bad at (physical movement of the heads is required) and something that flash is good at) it gives an indication of how low the performance bar is for ReadyBoost. I’m sure that a device which meets the minimum specs would do some good if you have a single disk that’s not overly fast. But if you have a decent RAID array for swap then I doubt that the minimum requirements for ReadyBoost would give a benefit. As for doing bulk transfers, it seems that while ReadyBoost Ready devices will have consistent good performance across all their storage (apparently some devices perform better for the first blocks so that people who use FAT based filesystems can get good performance from their FAT) they won’t necessarily have particularly good performance for bulk IO (1.75MB/s is pitiful when you want to copy DVD images). There are some USB flash devices that are marketted as having high performance and which are supposed to sustain >20MB/s, but I’m unlikely to find them going cheap at my local electronics store. I had hoped that ReadyBoost would be demanding enough that the ReadyBoostReady devices (which aren’t the cheapest flash devices on sale but often aren’t too expensive) would satisfy my requirements.

MJ Ray: Stupidity: PHP's Standard Sub-standard Approach to SQL

I'm just fixing another customer web site where the reported bug was something like
"when I put a customer password that includes an apostrophe into the web form, the site returns an error message"
and in the PHP source code I found something roughly similar to
"insert into customers values ($id,'$username','$password')"
(no, I didn't write the site - I'm doing ad-hoc support on it). Now, I realise that there are times when you want to send particular SQL instructions to the database and I know there are 1001 modules for tieing databases to variables, but it is still a problem that PHP's basic standard approach to SQL is to shove strings around and even today, with the dangers well-known, many PHP coders will interpolate unsafe user-submitted variables into them. It's enough to make a meltdown imminent. Surely no-one ever thought it was a feature?

David Welton: One reason to think Rails is &quot;all that&quot;

The economics of programming languages point to Rails being significantly better than what went before it. I got to thinking about this when reading a comment on a site I like to read, which said:
Rails in itself is, to me, not that impressive. It does a lot of things right, but it does probably just as many wrong. Not the least of which is scaling.
It seems that these sorts of "after the fact" "I know better" comments are a dime a dozen in the world of programming discussions. It's easy to come along after something's been built and puff yourself up by pointing to defects in existing systems and show that, therefore, by comparison, you're a clever fellow. That's not my point, though - what I wish to explain is that yes, Rails really was that much better than what was around before it came onto the scene: "Switching costs" between languages are high. Less so for really sharp programmers, but for the masses that use one or two languages, learning a new language, tools, deployment, etc... is a big step to take, with potentially high risks. Even most A-list programmers I know use a few languages at a time - it's simply easier if you're not tripping over your own feet by switching to a different system every day. "Flow" is easier to attain when you're ensconced in the thinking of one language. For companies, this effect is magnified, and switching to something new is not done lightly. Since companies are beginning to explore Rails, successfully, I might add, you have to conclude that the big step into the unknown was worth it for some reason. Especially considering that a number of other languages rushed to copy various nice aspects of Rails, lessening the need for users of those systems to consider taking the leap. Of course, that's not to say it's a perfect system, without reproach, or has no negative aspects, but in the spirit of honesty, and credit where credit is due, Rails really did move things a step forward, and the willingness of people to incur high switching costs to obtain its benefits is strong evidence of that.

Adrian von Bidder: Groupware suite

The topic of a groupware with SyncML support is still bothering me. What are people using, and with how many users? Please tell me (I'll update this article.) Looking around, it seems there aren't that many open source (or even commercial) projects if it should be usable on Linux (Clients, too) and be reasonable priced (which pretty much kills Lotus and similar big enterprise solutions AFAIK.). Oh, and a web frontend is an absolute necessity, too, but that's usually not a problem. There are some other groupware projects out there, and I might do them injustice, but on a first glance development seemed to either have stalled as a whole or at least regarding their SyncML support. I know of OpenGroupware.org (last news of SyncML support from 2005), Kolab (No production quality Web frontend, and I can't find much about SyncML either), Horde (Hmm. I didn't like the classical horde webmail very much, but "Horde Groupware" might be worth another look. The status of the SyncML part is not clear, judging from the website.) and phpGroupWare (egw's ancestor, when I last looked development seemed to stall, and the information I found about its SyncML support is somewhat scant.) The open direcory project lists some more, but I haven't looked at these.

Evan Prodromou: 8 Frimaire CCXVI

A few days ago I installed the Flock browser, version 1.0, on my notebook computer. I've been using it as my default browser for that time, and I have to say that I find it very slick and useful. I'd used the early beta versions of Flock and I thought it was a good idea, but I wasn't able to use most of the features. The blog posting tool, for example, doesn't work with my hacked-together WikiBlog system. Also, a lot of my must-have Firefox extensions, like SearchStatus, wouldn't install on Flock. But version 1.0 now installs all my Firefox extensions, and it also has lots of neat features that I find really useful. The feed reader, for example, is very slick, complete, and useful. The integration with social software sites like Facebook and Twitter is amazing, and the People View -- which tracks your friends on different systems -- is huge. The "My World" generated home page has replaced Netvibes for me. All good things. I'm a little disappointed with the narrow range of sites that are integrated into the browser, though. It'd be great to see more and better documentation on writing integration plugins on the Flock Developer site. I'd love to work on ways to make it easier to post to MediaWiki sites, upload files, get notifications, etc. I think getting site owners to make their own Flock plug-ins, or making it easy for users or third parties to do the plug-ins themselves, is going to be key to the success of these features. One other thing I found annoying was the indexer. This is a background task that indexes your browsing history so you can search for stuff you've recently seen ("Where did I read about that new version of JavaScript...?") Although this seems really useful, I found that the indexer was pegging the CPU on my Linux box -- possibly a threading problem? -- and I found the program increasingly unresponsive. Eventually I found the toggle in about:config to turn off the indexer ("flock.service.indexer.enabled"), and once I switched it off my browsing experience has been much less frustrating. I'd like to see Flock succeed -- it's a nice piece of work, and I think it's going down the right path. Getting more contributions from the world Web community will go a long way towards making it more useful for users. tags:

Yo Gamma Gamma Last night I dropped by the SAT for a great games event here in Montreal. Gamma 256 was a fun party, associated with the MIGS game summit. The event showcases submitted games based on a theme -- this year's theme was 256x256 pixel games (or smaller) -- thus the name. There were a ton of Montreal tech people there. The games were fun to play, especially the insanely violent Bloody Zombies, where your chainsaw-wielding alter ego slaughters the undead and then swims in their blood to reach the next level. Great fun, and a good example of Gamma's concentration on art in games. The music was good too -- lots of bleeps and boops and gamety fun. Congratulations to Heather Kelley and Damien DiFede and the rest of the Kokoromi Collective on their great job with this event. I'm already looking forward to next year. tags:

One-liners Some more things going on with me: tags:

29 November 2007

Stefano Zacchiroli: rss powered pts

The PTS has grown RSS feeds These days I'm taking part in the Extremadura Debian QA Metting. Today is the first day and I've mostly spent it doing some PTS hacks. The first visible tiny teeny outcome of that is the addition of RSS feeds for the "latest news" part of each package page. For example, in the PTS page of bash you can see a link to the corresponding RSS feed. (Other package pages will need a bit to be completely regenerated by the current PTS run ...) Thanks to KiBi and Luk the pages are now also listing links to the corresponding entry in svnbuildstat. Forthcoming additions are links to outcome of the piupart tests run by Liw and H01ger and 2 new markers: one for lowThresholdNmu-ability and the other for maintenance by Debian Maintainers. Stay tuned!

MJ Ray: Installing a web application with its CPAN dependencies

I fully expect to be told that this is Evil, Bad and Wrong, but what are the drawbacks of moving a MakeMaker tarball into the local cpan download tree and using CPAN::install on it like this? Other than the usual hackiness-problems with that early draft, I can't see a blocking problem with it. The CPAN shell handles the dependencies. (Don't worry, the eventual debian package will use dpkg to install the dependencies.) (2007-11-29: 1 comment)

Martin F. Krafft: Rewarding geek^W survey participants

Sooner or later, I will conduct a series of interviews as well as a community survey among Debian package maintainers as part of my research. The motivation for my research is to improve the workflows in the Debian project. How could I make you take part in such a survey? A key challenge and necessity of a survey is to ensure a high degree of participation, or else the responses cannot be read as descriptive of the entire group. Well-formulated questions and a smart way to present them are prerequisites. For instance, I'd consider it quite counter-productive (somewhat ironic even) to ask Debian package maintainers to hit radio buttons on a web form. Instead, participation should require the use of tools with which we are familiar. Another way to get people to respond is by showing how their time will help the project. This assumes that the research hypothesis is tangible and the whole endeavour plausible. And that people care. A third means of motivation is to reward participants. Commonly, this is done by way of a draw among all participants at the end of the survey, and a price given out to the (random) winner. Obviously, the individual's chances get slimmer with every additional participant, but if the price is right, it's still worth a try. I've been pondering for a few days on what a right price would be. Previously, Nokia Internet tablets have been hip, but would you dedicate your time to a survey where you could win one of those? Or a Neo1973 (thanks Lo-lan-do)? Or would a game console, such as the PS3 or the Wii be more exciting? Or is there something (in the same price range) out there you want and would, uh, fill for fill out the survey I mean Please take a moment and let me know which price you could not resist. Don't hesitate to provide me with a list I could just as well let the winner of the draw chose her/his favourite NP: The Pineapple Thief: 8 Days Later Update: Gaudenz Steinlin suggested a Thecus N2100.

Michal &#268;iha&#345;: Too lazy to manually upload to PPA

As I wrote before, I tried to use Ubuntu Personal Package Archive for distributing up to date Gammu, python-gammu and Wammu packages. For first time I failed because I expected it to behave more like OpenSUSE build service than like Debian archives, but I was wrong, so I have to upload different version to each Ubuntu suite. Well that sounds like a work which should be automated. So I hacked a little shell script, which takes current version from unstable, updates changelog and injects it into my PPA. The hacky script is called deb2ppa. It requires dput to be configured for ppa same way as I have it and maybe has some other tricky dependencies which I do not realize right now. Anyway you can now use current Wammu/Gammu versions even on older Ubuntu releases if you wish :-). (Well you have to wait till it is rebuild, but I hope it will not take much time.)

28 November 2007

Neil Williams: Next stages


emsource/emdebuild machine variants

Extending the customisation support in Emdebian so that the Emdebian package now becomes the source package for a machine specific variant build. Using the same principles as the machine variant handling in emsandbox, customised builds would apply patches over the Emdebian source to modify dependency chains, remove unwanted binaries etc.. emsource would use the existing Emdebian package (i.e. the package must have been cross built for Emdebian already) as the source, providing an unpacked package with the Emdebian patches already applied. emsource would use the ../machine/$machine/$variant directory instead of trunk/. Patches from the machine/$machine/$variant/f/foo/ subdirectory of your Emdebian work directory would then be applied. emdebuild would update those patches because the relevant $foo.old directory would contain the Emdebian source. The Debian source would always be available in trunk/ for comparison. Using the Emdebian package as source means that the variant build tree will not contain any .svn/ or CVS/ directories so machine/variant builds can use your preferred RCS. Expected in emdebian-tools >> 0.7.0.

langupdate and tdeb packages

The current Emdebian package search script will be adapted to handle the buildd.emdebian.org/locale repository and omit locale packages (tdebs) from the default search and package count. locale packages will be migrated into the locale repository with a cron task, removing them from the main repository at the same time. This way, uploads proceed as normal, no modifications are needed for the .changes file and the main repository apt cache is kept as small as possible. langupdate itself will use apt options to direct apt to the langupdate cache of locale packages. Unlike the main apt cache, this cache is removed after each langupdate run (actually it will probably be removed just before the packages are unpacked). langupdate will call apt to do the download and actual installation. Whilst this does mean that the installed tdebs will show up in the apt and dpkg cache data, it does prevent the other 90% of locale packages from also ending up in the main apt cache. Besides, the user should be able to see which tdeb packages are installed using the normal dpkg -l queries. tdeb packages are very small but hopefully apt-get autoclean will clean up the downloaded package files. langupdate will also automatically remove any tdebs and translation files for unsupported locales. Finally, langupdate will be run for the first time by the eventual Emdebian installer - as soon as the user has selected a timezone and set of supported locales. langupdate may well be extended in future to support handling the zoneinfo data from tzdata and the gconv data from glibc. langupdate currently uses libglib2.0-0 (because I like using it) but if anyone fancies developing it in plain C (or probably C++ to fit in better with apt), let me know. Code is in Emdebian SVN.


Russell Coker: Creepy Social Networking

Cory Doctorow wrote an interesting article about social networking [1]. One of his points is “Imagine how creepy it would be to wander into a co-worker’s cubicle and discover the wall covered with tiny photos of everyone in the office, ranked by “friend” and “foe,” with the top eight friends elevated to a small shrine decorated with Post-It roses and hearts“, another concerns the issue of forced “friends” where colleagues and casual acquaintances demand to be added to a friends list. He speculates that the reason for social networking systems to be a fad is that once too many people you don’t really like force themselves into your friends list then you will feel compelled to join a different service. I believe that the practice of ranking friends is simply a bad idea and wonder whether anyone who has completed high-school has ever used it seriously. If you publicly rank your friends then you will alienate other friends (particularly any who might have ranked you more highly than you ranked them). Everyone who has used social networking systems has discovered the pressure to avoid alienating people that you don’t actually like. It seems obvious that alienating people who you do like is even more of a problem. In my previous post about Better Social Networking [2] I suggested having multiple lists on your social networking server that are published to different people. That would allow segregating the lists as a way of dealing with some demands to be listed. People who are associated with work (colleagues, managers, and in an example Cory used students at a school where a teacher worked) would be on a work list. The work list would point to the work profiles of other people which would match whatever the standards are for the industry in question (which would still allow quite a range, the standards for sys-admins of ISPs differ significantly from those for primary school teachers). I’m sure that someone who worked for an ISP in Amsterdam would understand that a work-based friend request made to someone who teaches primary school in a part of the world that is religiously conservative would understand why that request would be declined (but the same person might add them to a personal friends list). Another way of alleviating such problems is to not require that listing be bi-directional. Current social networking systems involve one party making a friend request to another which is listed as pending in the GUI for both parties. The options are to either leave it in that state (which is an annoyance) or reject it (which may cause offence). With a uni-directional listing one party would add the other and hope for the best. If they aren’t obsessive about such things they may not even notice that the other party didn’t reciprocate. Also it would allow for famous people receiving links from many people to their public profile without any expectation of reciprocation. Of course a distributed social networking system such as I suggest would inherently have uni-directional links as there would be no central repository to force them to be all bi-directional.

Next.

Previous.