Search Results: "nate"

14 December 2020

Jonathan Dowland: git rebasing and lab books

For my PhD work, I've been working on preparing an experimental branch of StrIoT for merging down to the main branch. This has been a long-lived branch (a year!) within which I've been exploring some ideas. Some of the code I want to keep, and some I don't. The history of the experimental branch is consequently messy. Looking it over and considering what a reviewer needs to see, there's a lot of things that are irrelevant and potentially distracting. And so, I've been going through an iterative process of steadily whittling down the history to the stuff that matters: some strings of commits are dropped, others squashed together, and others re-ordered. The resulting branch is a historic fiction. This is common practice. Joey Hess ruminated about it 5 years ago in "our beautiful fake histories", pointing out that the real history is also useful, and perhaps worth preserving. After a recent conversation with my supervisor I realised the situation was analagous to writing a research paper (or a thesis): the process of getting to the conclusion which the thesis documents is messy, with false starts, wrong directions, and plenty of roads-not-travelled. The eventual write-up focusses on the path that lead to the conclusion, and a lot of the side-quest stuff disappears. The "true history" then, is captured elsewhere: in lab books, diaries and the like, and these have their own value. So do my messy exploratory branches, before they've been cleaned up for merging.

13 December 2020

Jan Wagner: Monitoring Plugins 2.3 released

While our last release has matured for quite a little time, there raised demands within our community for a new release. The development has settled this fall and @sni was already using master for a while in production, so we thought about to release. Anyway Debian Freeze is coming, let's cut a new upstream release! The last question was: Who should cut the release? The last releases was done by @JeremyHolger, but these days everybody is short on time. Fortunately Holger has documented the whole release process very well, so I jumped on the band wagon and slipped into the release wizard role.
Surprisingly it seems I was able to fix all faults I've done in the release process (beside using the 2.2 link in the release announcement mail) and kicked the release of monitoring-plugins 2.3 successfully. Grab the new Monitoring Plugins release while it's hot (and give the new check_curl a try)!
Hopefully monitoring-plugins 2.3 will hit Debian experimental soon.

11 December 2020

Dirk Eddelbuettel: RcppSpdlog 0.0.4: New upstream

Not quite two months after the last release, we are happy to announce version 0.0.4 of RcppSpdlog. It contains release 1.8.2 of spdlog made today, along with version 7.1.3 of fmt. RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovich. The NEWS entry for this release follows.

Changes in RcppSpdlog version 0.0.4 (2020-12-11)
  • Upgraded to upstream release spdlog 1.8.2
  • Added GitHub Actions CI using run.sh from r-ci

Courtesy of my CRANberries, there is also a diffstat report. More detailed information is on the RcppSpdlog page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

9 December 2020

Shirish Agarwal: Farm Laws and Too much Democracy

Issues with Farm Laws While I have written about the farm laws a bit sometime back. The issue is still in the nation s eye and that is due to the policies which have been done. I have been reading up on it quite a bit and also have been seeing what has been happening in here and now. The problems are with the three bills themselves which I have shared as below Click to access farmers-produce-trade-and-commerce-promotion-and-facilation-bill.pdf Click to access farmers-empowerment-and-protection-bill.pdf Click to access essential-commodities-bill-2020.pdf Biggest issue with the laws While there are many issues with the laws themselves but for me the biggest issue is that the fundamental right of the farmer to get justice via civil courts has been railroaded. From the laws itself. Standard disclaimer not a lawyer, please consult one for any issues per-se.

Farmers-produce-trade-and-commerce (promotion and facilitation-bill) 2020 Page 4 Chapter 3 Section 8 (1)8. (1) In case of any dispute arising out of a transaction between the farmer and a trader under section 4, the parties may seek a mutually acceptable solution through conciliation by filing an application to the Sub-Divisional Magistrate who shall refer such dispute to a Conciliation Board to be appointed by him for facilitating the binding settlement of the dispute. (2) Every Board of Conciliation appointed by the Sub-Divisional Magistrate under sub-section (1), shall consist of a chairperson and such members not less than two and not more than four, as the Sub-Divisional Magistrate may deem fit.10 (5) If the parties to the transaction under sub-section (1) are unable to resolve the dispute within thirty days in the manner set out under this section, they may approach the Sub-Divisional Magistrate concerned who shall be the Sub-Divisional Authority for settlement of such dispute. (8) Any party aggrieved by the order of the Sub-Divisional Authority may prefer an appeal before the Appellate Authority (Collector or Additional Collector nominated by the Collector) within thirty days of such order who shall dispose of the appeal within thirty days from the date of filing of such appeal. 10. (1) Any person aggrieved by an order under section 9 may, prefer an appeal within sixty days from the date of such order, to an officer not below the rank of Joint Secretary to the Government of India to be nominated by the Central Government for this purpose: Page 6 of the bill. 13. No suit, prosecution or other legal proceedings shall lie against the Central Government or the State Government, or any officer of the Central Government or the State Government or any other person in respect of anything which is in good faith done or intended to be done under this Act or of any rules or orders made thereunder. Page 7 of the bill, 15. No civil court shall have jurisdiction to entertain any suit or proceedings in respect of any matter, the cognizance of which can be taken and disposed of by any authority empowered by or under this Act or the rules made thereunder. Now the same laws have been reiterated for the farmers (Empowerment and Protection) Agreement on Price Assurance and Farm Services Bill, 2020. The problem is that too much power is being put into the hands of the executive. All the three, whether it is SDM (Sub-Divisional Magistrate) , the Appellate Authority or the Government Secretary directly are subservient to the whims and fancies of the Central Govt. They after all get their salaries from the Govt. itself. So there will be no independent oversight to any injustices done to the farmer. The third bill i.e. the Essential Commodities Bill, 2020 does away with stock limits on traders and big players like Adani and Ambani. This means that both these players can take and keep produce at their end thereby forcing consumers like you and me who at the retail end would have to pay higher prices for fruits and vegetables while from the producer they will take at the lowest price possible. While I have shared is just one of the points. That is the reason why even the Supreme Court bar association which almost never takes part in politics has been forced to take sides with the farmers. In many ways, one is forced to remember the Emergency  Update 11/12/20 Came across this article on the wire which tells how everybody s rights, not just the farmer s rights are being shod over. I think it depicts correctly the signs of time to come. While arguing on SM, also came to know about Article 300 (1), thanks to Sachin Kumar which shows multiple instances where Government was sued because somebody was working in official capacity and did mistakes, malafide or otherwise and it was the state who was made to pay. FWIW, today farmers from Maharashtra, my state arrived at Delhi border where they were also kept at bay. I did come across an infographic which shows how the various states have fared. Most tellingly, is the state of Bihar. It was in 2006 (one of the most backward states) where APMC was taken off. While others have tried to paint a flattering picture of Bihar, they have failed to share that in the interim 15 odd years, there hasn t been any sort of infrastructure created for farmers which is the reason it is still the lowest earner. These are the last available figures we have about the farmer s income. From 2014 to 2020 there hasn t been any update.
Situation Assessment Survey of Agricultural Household 2013 Copyright GOI,
This concludes just one portion of the bill. I will take other parts of the bill. I may dwell on some other parts as and when I have the time. A cartoon which depicts the current issue
I stand with farmers Copyright Sanitary Panels
Too much democracy Amitabh Kant Yesterday, the Niti Aayog chief Amitabh Kant remarked that we are too much of a democracy at an event called for Atmanirbhar Bharat which is basically a coinage for import substitution. Whether this is desirable or not I have argued and if needed will re-argue the same later as well. What is and was interesting were the gentleman s context, the media reactions and our overall Democracy Index which has been going downhill for quite some years. Now the gentleman who is the Niti Aayog chief and who is supposed to have the ear of the Prime Minister had opined it in an event organized by Swarajya Magazine (a far-right magazine) known to be Islamophobic and all things undemocratic. It has been a target of defundthehate campaign and with good reason. But that s a different story altogether. His full statement was as below

Tough reforms are very difficult in the Indian context, as we are too much of a democracy but the government has shown courage and determination in pushing such reforms across sectors, including mining, coal, labour and agriculture. Niti Aayog chief. The upper quotation remarks and the statement has been from the article in Indian Express which I have linked to. I have archived it as a pdf just in case the link goes dead. Yesterday, after the statement became viraled, tweets of media houses which shared the tweet suddenly become unavailable. Seems too much democracy, became too little democracy all of a sudden. I think Mr. Amitabh Kant didn t visualize as the opposition as well as most people who are on Twitter to share their opinion on the same. Few examples
Too much Democracy copyright Satish Acharya
Too much democracy Illustration and Copyright Alok
Sterlite protest 13 dead, 100 injured Copyright Business Standard too much democracy
Erosion of Democracy V-dem institute Copyright The Hindu Web Team
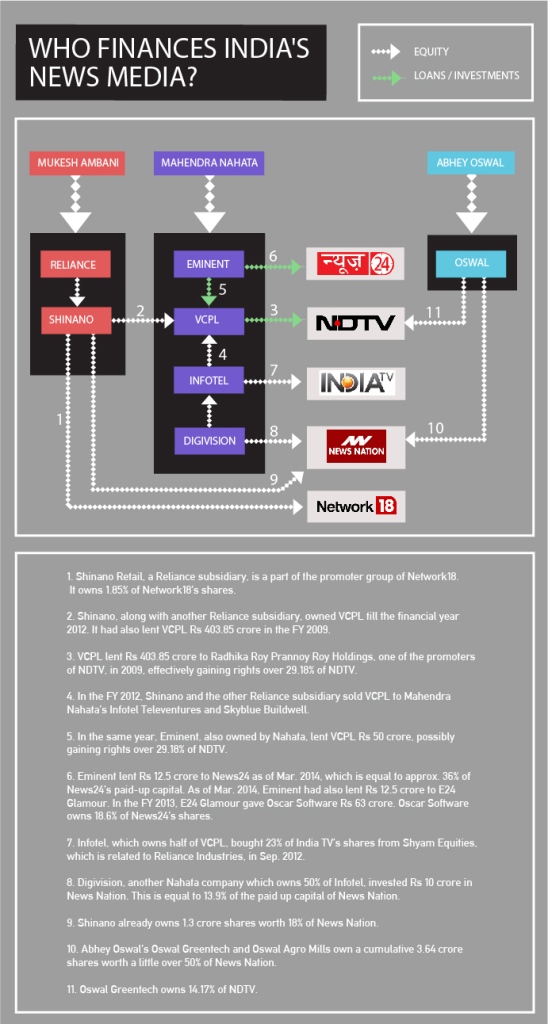
The last one requires a bit more information. This comes from V-Dem Institute which is an independent research institute based out of Department of Political Science, University of Gothenburg, Sweden. I am gonna leave the methods they use for another day as the blog post itself has become rather big/large. Apart from that is the Economists own Democracy Index -2019 Click to access democracy-index-2019.pdf Now for many people, both the V-Dem report and the Economist Index are some sort of attack against India. Doesn t matter that in V-Dem 200+ countries have been taken a variety of indicators and data or the Economist which has data from 150+- countries. Somehow India is supposed to be bigger than all these countries, they do think that other countries data specifically our neighbor China or any other neighbor, those are all accurate. How the dissonance is, has to be gauged from statements of various people. Update 11/12/20 Sadly, the newest V-Dem report marks India as getting into authoritarianism. Gag on Press and Media owners I had shared about the gag on the press especially with respect to western media or reports or anything. This news made its way to straitstimes which normally covers a wide-range of stories covering East Asia vis-a-vis India/South-East Asia. What has also been a big worry that most of the media has been in the hands of a few people. Caravan ran a story on the same in 2016, it has been four years, god only knows what the current situation might be. Any wonder that there is dearth of investigative journalism in India.
India media ownership 2016 Copyright Caravan
Incidentally, a reporter called Akarshan Uppal, who is a reporter on a channel called IBN24 had showecased just few days back how Adani has got land which was shot down for land change use in 2017 to 2020 around 100 acres. There seem to be very less details as to how the land was acquired, whose land it was etc. etc. The reporter was supposedly following a story on drugs on which he was attacked and is now lying in hospital.
Akarshan Uppal Reporter, IBN24 Copyright IBN24
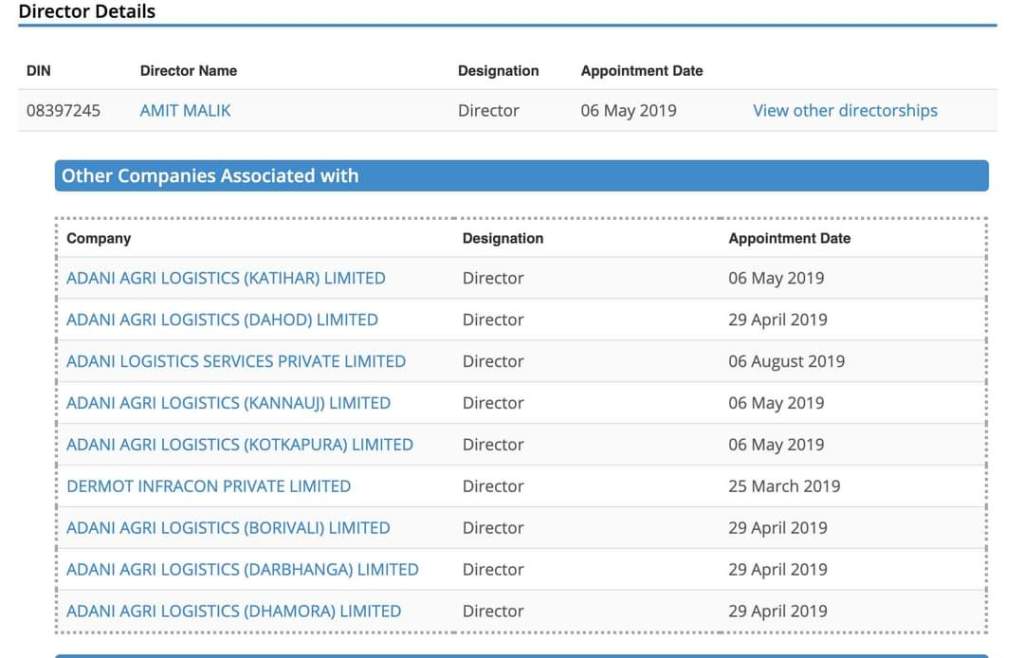
While it would take a whole article/blog post to talk about either Adani or Ambani, in the recent case, the land that has been taken over by Adani is 100 acres and there are private rail lines. And all of this was secret till few days back. The place where these massive godowns/silos have been made are Panipat s Jondhan Kalan and Naultha villages in Haryana. This is Adani AgiLogistics. Almost 7 odd companies have registered and come up in the last couple of years. As can be seen, almost all have come up within the last 2-3 years. Seems to be a lot of coincidence, isn t it?
Personal Anecdote on Data Collection and child marriages in India.

Around 1995 -96 when Internet had started to become a thing in India, there had been quite a few non-profits which were working on various issues. One of those which I initially came in contact with and which I found to be a bit absurd was non-profit which was working in the field of women against Violence. Now it is and was not the concept or the idea which was absurd to me, it was what these women were doing. Instead of the traditional ways in which you counsel women and try and figure out issues, these women were collecting data points from newspapers and magazines. This was way way before data science became a thing in India. They had their own structure where a story about violence against women which would be above the fold would be 5 points, the one below 2.5 points, in inner pages, it would be less and less. Patriarchy at that time was so strong, even today is but at that time it was such, that it felt a waste of time. I did consult them but never said that but did privately feel the above. In hindsight, they were doing the right thing and yet even today crimes against women goes unreported and is suppressed by both State and Central Governments as well as NCRB (National Crime Records Bureau). Interestingly, just few days back, the case against M.J. Akbar by Priya Ramani had taken a back seat and the defamation case by M.J. Akbar was taken forward. Even then, Priya Ramani s counsel s arguments were such that the court wound up in half an hour when they were expecting to do a whole day hearing. The next hearing would be happening today which I will look at in few hours from now. Why Priya Ramani was singled out rather than other tweets may probably be because she is an NRI and most NRI s usually do not want to be part of the bureaucratic Indian court system. This is also the reason that most companies from outside India especially those who are into startups prefer to change ownership, IPR etc. to their own or any country outside India which does make a loss to the exchequer. But this again is a story for another day. At the end, while I did not want to end on a negative note, it seems in many ways status-quo remains. For e.g. 2 years back, a BJP candidate (part of the ruling dispensation) had made a controversy saying that if they win the police won t interfere in child marriages. This is and was in Rajasthan where they have been trying to eradicate it forever. Till date, neither the NHRC (National Human Rights Commission) nor NCW (National Commission for Women) has taken cognizance of the statement. This is our state of democracy.

6 December 2020

Olivier Berger: Offsite backups to rsync.net from an Asustor NAS

I have an Asustor (Nimbuster 4 / AS5304T) NAS at home, which allows me to perform regular backups. Unfortunately, I couldn't manage to find a way to configure remote backups from the NAS to rsync.net using the "Remote Sync" option of the "Backup & Restore" app provided in the ADM OS of the Asustor NAS. I'm used to using rsync -e ssh commands and would have expected some such configuration to be possible... it may just be some UI issue, but I couldn't find how to add one for rsync.net. I've then used the following workaround : the NAS can run a "Linux VM" (LXC ?) with the provided "Linux Center" app. It allows me to run a regular Debian installation inside this Linux guest. On which I installed backupninja, which performs backups over rsync, from the NAS filesystem, to the rsync.net remote. Along the way I had to overcome a few issues, whose documentation may be useful to others :

5 December 2020

Thorsten Alteholz: My Debian Activities in November 2020

FTP master Unfortunately a day only has 24h. As the freeze is approaching, I had to concentrate a bit more on keeping my packages in shape. So this month I only accepted nine packages. The good news, I rejected no package. The overall number of packages that got accepted was 328. Debian LTS This was my seventy-seventh month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload has been 22.75h. During that time I did LTS uploads of: I also started to work on x11vnc and slirp. Last but not least I did some days of frontdesk duties. Debian ELTS This month was the twenty ninth ELTS month. During my allocated time I uploaded: Unfortunately I also had to give back some hours. Last but not least I did some days of frontdesk duties. Other stuff This month I uploaded new upstream versions of: I fixed one or two bugs in: I improved packaging of: and there have been even some new packages: As it is again this time of the year, I would also like to draw some attention to the Debian Med Advent Calendar. Like the past years, the Debian Med team starts a bug squashing event from the December 1st to 24th. Every bug that is closed will be registered in the calendar. So instead of taking something from the calendar, this special one will be filled and at Christmas hopefully every Debian Med related bug is closed. Don t hesitate, start to squash :-). The announcement on the mailing list can be found here.

Joachim Breitner: Named goals in Coq

TL;DR: Some mildly tricky tricks allow you to select subgoals by name, like in Isabelle. This leads to more readable proofs, and proofs that are more robust against changes.

The need for case names Consider the following Coq proof, right out of the respected Software Foundations book, Chapter Inductively Defined Propositions (and slightly simplified):
Lemma star_app: forall T (s1 s2 : list T) (re : reg_exp T),
  s1 =~ Star re ->
  s2 =~ Star re ->
  s1 ++ s2 =~ Star re.
Proof.
  intros T s1 s2 re H1.
  remember (Star re) as re'.
   generalize dependent s2.
  induction H1.
  - (* MEmpty *) discriminate.
  - (* MChar *) discriminate.
  - (* MApp *) discriminate.
  - (* MUnionL *) discriminate.
  - (* MUnionR *) discriminate.
  - (* MStar0 *)
    injection Heqre' as Heqre''. intros s H. apply H.
  - (* MStarApp *)
    injection Heqre' as Heqre''.
    intros s3 H1. rewrite <- app_assoc.
    apply MStarApp.
    + apply H1_.
    + apply IHexp_match2.
      * rewrite Heqre''. reflexivity.
      * apply H1.
Qed.
This is a very typical example for a proof by induction over an inductively defined relation (in this case, the relations s =~ re which indicates that the string s matches the regular expression re): After some preparation, the invocation of a tactic like induction (could also be inversion or others) creates a number of new goals, one of for each rule of the relation. Then the modern(!) Coq user uses proof bullets to focus the goals, one after another, in order, to solve them. We can see from this example that proof bullets (which were a big improvement) are not quite satisfactory, and the author of this proof felt the need to annotate each subproof with the case it corresponds to. But these are mere comments! This is unsatisfactory, as there is nothing keeping them correct as my proof changes. And anyone who came to Coq from Isabelle is just flabbergasted that the state of art in Coq is still at that level So, wouldn t it be great if
  • I could focus goals by their name (e.g. MEmpty)
  • Focus them in any order (so that refactoring of my data types do not break my proofs)
  • This even worked when simultaneously inducting over or inverting multiple relations?

Simulating named goals in Coq Well, with a few tricks we can! It just takes three simple steps:
  1. I load a small file full of hacks (explained below):
    Require Import NamedCases.
  2. This allows me to prefix the type of the constructors of the inductive relations (i.e. the rules of the relation) with case <name>, , as follows:
    Reserved Notation "s =~ re" (at level 80).
    Inductive exp_match  T  : list T -> reg_exp T -> Prop :=
        MEmpty:
        case empty,
        [] =~ EmptyStr
        MChar:
        case char,
        forall x,
        [x] =~ (Char x)
        MApp:
        case app,
        forall s1 re1 s2 re2
        (H1 : s1 =~ re1)
        (H2 : s2 =~ re2),
        (s1 ++ s2) =~ (App re1 re2)
        MUnionL:
        case union_l,
        forall s1 re1 re2
        (H1 : s1 =~ re1),
        s1 =~ (Union re1 re2)
        MUnionR:
        case union_r,
        forall re1 s2 re2
        (H2 : s2 =~ re2),
        s2 =~ (Union re1 re2)
        MStar0:
        case star0,
        forall re,
        [] =~ (Star re)
        MStarApp:
        case star_app,
        forall s1 s2 re
        (H1 : s1 =~ re)
        (H2 : s2 =~ (Star re)),
        (s1 ++ s2) =~ (Star re)
      where "s =~ re" := (exp_match s re).
    This is the definition from the Software Foundations book; only the case <name>, lines are added.
  3. Now I can change the proof: After the induction tactic I use ; name_cases to name the cases, and then I can use the relatively new named goal focusing feature ([name]: , which I suggested two years ago, and was implemented by Th o Zimmermann) to focus a specific case:
    Lemma star_app2: forall T (s1 s2 : list T) (re : reg_exp T),
      s1 =~ Star re ->
      s2 =~ Star re ->
      s1 ++ s2 =~ Star re.
    Proof.
      intros T s1 s2 re H1.
      remember (Star re) as re'.
       generalize dependent s2.
      induction H1; name_cases.
      [empty]:  
         discriminate.
       
      [char]:  
         discriminate.
       
      [app]:  
         discriminate.
       
      [unionL]:  
         discriminate.
       
      [unionR]:  
        discriminate.
       
      [star0]:  
        injection Heqre' as Heqre''. intros s H. apply H.
       
      [starApp]:  
        injection Heqre' as Heqre''.
        intros s3 H1. rewrite <- app_assoc.
        apply MStarApp; clear_names.
        + apply H1_.
        + apply IHexp_match2.
          * rewrite Heqre''. reflexivity.
          * apply H1.
        
    Qed.
    The comments have turned into actual names!
Goal focusing is now just much more reliable. For example, let me try to discharge the boring cases by using ; try discriminate after the induction. This means there are suddenly only two goals left. With bullets, the first bullet would now suddenly focus a different goal, and my proof script would likely fail somewhere. With named goals, I get a helpful error message No such goal: empty and I can t even enter the first subproof. So let me delete these goals and, just to show off, focus the remaining goals in the wrong order:
Lemma star_app: forall T (s1 s2 : list T) (re : reg_exp T),
  s1 =~ Star re ->
  s2 =~ Star re ->
  s1 ++ s2 =~ Star re.
Proof.
  intros T s1 s2 re H1.
  remember (Star re) as re'.
   generalize dependent s2.
  induction H1; name_cases; try discriminate.
  [starApp]:  
    injection Heqre' as Heqre''.
    intros s3 H1. rewrite <- app_assoc.
    apply MStarApp; clear_names.
    + apply H1_.
    + apply IHexp_match2.
      * rewrite Heqre''. reflexivity.
      * apply H1.
    
  [star0]:  
    injection Heqre' as Heqre''. intros s H. apply H.
   
Qed.
I did not explain the clear_names tactic yet that I had to use after apply MStarApp. What I am showing here is a hack, and it shows these case names are extra hypothesis (of a trivially true type CaseName), and this tactic gets rid of it.

Even better than Isabelle The above even works when there are multiple inductions/inversions involved. To give an example, let s introduce another inductive predicate, and begin proving a lemma that one can do by induction on one and inversion on the other predicate.
Inductive Palindrome  T  : list T -> Prop :=
  EmptyPalin:
  case emptyP,
  Palindrome []
  SingletonPalin:
  case singletonP,
  forall x,
  Palindrome [x]
  GrowPalin:
  case growP,
  forall l x,
  Palindrome l -> Palindrome ([x] ++ l ++ [x])
.
Lemma palindrome_star_of_two:
  forall T (s : list T) x y,
  Palindrome s -> s =~ Star (App (Char x) (Char y)) ->
  s = [] \/ x = y.
Proof.
  intros T s x y HPalin HRe.
  induction HPalin; inversion HRe; name_cases.
At this point we have four open goals. Can you tell why there are four, and which ones they are? Luckily, Show Existentials will tell us their names (and Coq 8.13 will just show them in the proof state window). These names not only help us focus the goal in a reliable way; they even assist us in understanding what goal we have to deal with. For example, the last goal arose from the GrowP rule and the StarApp rule. Neat!
  [emptyP_star0]:  
    left. reflexivity.
   
  [emptyP_starApp]:  
     left. reflexivity.
   
  [singletonP_starApp]:  
    inversion HRe; clear HRe.
    inversion H5; clear H5.
    inversion H10; clear H10.
    inversion H11; clear H11.
    subst.
    inversion H3.
   
 [growP_starApp]:  
    admit. (* I did not complete the proof *)
  

Under the hood (the hack) The above actually works, but it works with a hack, and I wish that Coq s induction tactic would just do the right thing here. I hope eventually this will be the case, and this section will just be curiosity but until, it may actually be helpful.
  1. The trick1 is to leave markers in the proof state. We use a dedicate type CaseName, and a hypothesis name : CaseName indicates that this goal arose from the that case.
    Inductive CaseName := CaseNameI.
    With this, we can write StarApp: forall (starApp : CaseName), to name this case.
  2. For a little bit of polish, we can introduce notation for that:
    Notation "'case' x , t" := (forall  x : CaseName , t) (at level 200).
    This allows us to use the syntax you saw above.
  3. To easily discharge these CaseName assumptions when using the introduction forms, I wrote these tactics:
    Ltac clear_names := try exact CaseNameI.
    Ltac named_constructor  := constructor; [ exact CaseNameI   idtac .. ].
    Ltac named_econstructor := econstructor; [ exact CaseNameI   idtac .. ].
  4. Finally I wrote the tactic name_cases. What it does is relatively simple:
    For each subgoal: Take all hypotheses of type CaseName, concatenate their names, change the name of the current goal to that, and clear these hypotheses
    Unfortunately, my grasp of Coq tactic programming is rather rudimentary, and the only way I manged to solve this is a horrible monster of Ltac2, including hand-rolled imperative implementations of string concatenation and a little nested Ltac1 tactic within. You have been warned:
    From Ltac2 Require Import Ltac2.
    From Ltac2 Require Option.
    Set Default Proof Mode "Classic".
    Ltac name_cases := ltac2:(
      (* Horribly manual string manipulations. Does this mean I should
         go to the Ocaml level?
      *)
      let strcpy s1 s2 o :=
        let rec go := fun n =>
          match Int.lt n (String.length s2) with
            true => String.set s1 (Int.add o n) (String.get s2 n); go (Int.add n 1)
            false => ()
          end
        in go 0
      in
      let concat := fun s1 s2 =>
        let l := Int.add (Int.add (String.length s1) (String.length s2)) 1 in
        let s := String.make l (Char.of_int 95) in
        strcpy s s1 0;
        strcpy s s2 (Int.add (String.length s1) 1);
        s
      in
      Control.enter (let rec go () :=
        lazy_match! goal with
          [ h1 : CaseName, h2 : CaseName  - _ ] =>
          (* Multiple case names? Combine them (and recurse) *)
          let h := concat (Ident.to_string h1) (Ident.to_string h2) in
          Std.clear [h1; h2];
          let h := Option.get (Ident.of_string h) in
          assert ($h := CaseNameI);
          go ()
          [ _ : CaseName  - _ ] =>
          (* A single case name? Set current goal name accordingly. *)
          ltac1:(
            (* How to do this in ltac2? *)
            lazymatch goal with
              [ H : CaseName  - _ ] => refine ?[H]; clear H
            end
          )
          [  - _ ] =>
          Control.backtrack_tactic_failure "Did not find any CaseName hypotheses"
        end
      in go)
    ).
    If someone feels like re-implementing this in a way that is more presentable, I ll be happy to update this code (and learn something along the way
That s all it takes!

Conclusion With some mild hackery, we can get named cases in Coq, which I find indispensable in managing larger, evolving proofs. I wonder why this style is not more common, and available out of the box, but maybe it is just not known well enough? Maybe this blog post can help a bit here.

  1. I have vague recollections of seeing at least parts of this trick on some blog some years ago, and I do not claim originality here.

4 December 2020

Jonathan Dowland: Toronto

selfie skating at night
Nathan Phillips Square rink at night
view over Nathan Phillips Square rink
skaters by day
This time a year ago, I visited Toronto, Canada for my first (and hopefully not last) time, for the Red Hat Java team's face-to-face meetings. The hotel we were staying in was right next to Nathan Phillip's Square, which is an open-air Ice Rink for the winter months. I love Ice Skating and rarely took opportunities to do it (even before Covid-19) so I decided to take full advantage of the locality. Skating was free, but boot rental was not, so I bought some new skates. That meant an interesting problem getting them home on the plane. I think I got out there about 5 times over 5 days. It was busy during the day and very quiet at other times. 8am worked pretty well. My local Ice Rink has been intermittently open over the year as and when the Lockdown rules have allowed it, but the combination of cold air, indoor circulation and strenuous activity seem to me to be very unsafe, so I won't risk it. In Newcastle, the Centre for Life usually puts an outdoor rink on around Christmas, which is very expensive to skate on. Unfortunately they've decided against it this year. Toronto was great for more than just Ice Skating! I had a fantastic time meeting my team members; good food, good drink (especially Ice Wine); The CN Tower; a funky music instrument shop, and the first Teenage Engineering OP-1 I've ever seen in the flesh; not much Maple syrup, which surprised me. Good coffee. A comfortable-feeling city. It'll probably be a long while before I travel for work (or anything else) quite like this again. I'm glad to have made the most of it, whilst I could!
me, covered in snow

Dirk Eddelbuettel: #31: Test your R package against bleeding-edge gcc

Welcome to the 31th post in the rapturously rampant R recommendations series, or R4 for short. This post will once again feature Docker for use with R. Earlier this week, I received a note from CRAN about how my RcppTOML package was no longer building with the (as of right now of course unreleased) version 11 of the GNU C++ compiler, i.e. g++-11. And very kindly even included a hint about the likely fix (which was of course correct). CRAN, and one of its maintainers in particular, is extremely forward-looking in terms of toolchain changes. A year ago we were asked to updated possible use of global variables in C code as gcc-10 tightened the rules. This changes is a C++ one, and a fairly simple one of simply being more explicit with include headers. Previous g++ release had done the same. The question now was about the least painful way to get g++-11 onto my machine, with the least amount of side-effects. Regular readers of this blog will know where this is headed, but even use of Docker requires binaries. A look at g++-11 within packages.debian.org comes up empty. No Debian means no Ubuntu. But there is a PPA for Ubuntu with toolchain builds we have used before. And voil there we have it: within the PPA for Ubuntu Toolchain repository is the volatile packages PPA with both g++-10 and g++-11. Here Ubuntu 20.10 works with g++-10, but g++-11 requires Ubuntu 21.04. Docker containers are there for either. So with the preliminaries sorted out, the key steps are fairly straightforward: And that is it! RcppTOML is fairly minimal and could be a member of the tinyverse so no other dependencies are needed if your package has any you could just use the standard steps to install from source, or binary (including using RSPM or bspm). You can see the resulting Dockerfile which contains a minimal amount of extra stuff to deal with some environment variables and related settings. Nothing critical, but it smoothes the experience somewhat. This container is now built (under label rocker/r-edge with tags latest and gcc-11), and you can download it from Docker Hub. With that the proof of the (now fixed and uploaded) package building becomes as easy as
edd@rob:~/git/rcpptoml(master)$ docker run --rm -ti -v $PWD:/mnt -w /mnt rocker/r-edge:gcc-11 g++ --version
g++ (Ubuntu 11-20201128-0ubuntu2) 11.0.0 20201128 (experimental) [master revision fb6b29c85c4:a331ca6194a:e87559d202d90e614315203f38f9aa2f5881d36e]
Copyright (C) 2020 Free Software Foundation, Inc.
This is free software; see the source for copying conditions.  There is NO
warranty; not even for MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.

edd@rob:~/git/rcpptoml(master)$ 
edd@rob:~/git/rcpptoml(master)$ docker run --rm -ti -v $PWD:/mnt -w /mnt rocker/r-edge:gcc-11 R CMD INSTALL RcppTOML_0.1.7.tar.gz
* installing to library  /usr/local/lib/R/site-library 
* installing *source* package  RcppTOML  ...
** using staged installation
** libs
g++ -std=gnu++11 -I"/usr/share/R/include" -DNDEBUG -I../inst/include/ -DCPPTOML_USE_MAP -I'/usr/lib/R/site-library/Rcpp/include'    -fpic  -g -O2 -fdebug-prefix-map=/build/r-base-Fuvi9C/r-base-4.0.3=. -fstack-protector-strong -Wformat -Werror=format-security -Wdate-time -D_FORTIFY_SOURCE=2 -g  -c RcppExports.cpp -o RcppExports.o
g++ -std=gnu++11 -I"/usr/share/R/include" -DNDEBUG -I../inst/include/ -DCPPTOML_USE_MAP -I'/usr/lib/R/site-library/Rcpp/include'    -fpic  -g -O2 -fdebug-prefix-map=/build/r-base-Fuvi9C/r-base-4.0.3=. -fstack-protector-strong -Wformat -Werror=format-security -Wdate-time -D_FORTIFY_SOURCE=2 -g  -c parse.cpp -o parse.o
g++ -std=gnu++11 -shared -L/usr/lib/R/lib -Wl,-Bsymbolic-functions -Wl,-z,relro -o RcppTOML.so RcppExports.o parse.o -L/usr/lib/R/lib -lR
installing to /usr/local/lib/R/site-library/00LOCK-RcppTOML/00new/RcppTOML/libs
** R
** inst
** byte-compile and prepare package for lazy loading
** help
*** installing help indices
** building package indices
** testing if installed package can be loaded from temporary location
** checking absolute paths in shared objects and dynamic libraries
** testing if installed package can be loaded from final location
** testing if installed package keeps a record of temporary installation path
* DONE (RcppTOML)
edd@rob:~/git/rcpptoml(master)$ 
I hope both the availability of such a base container with gcc-11 (and g++-11 and gfortran-11) as well as a recipe for building similar containers with newer clang version will help other developers. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

3 December 2020

Daniel Lange: No dog food today - the Linux Foundation annual report

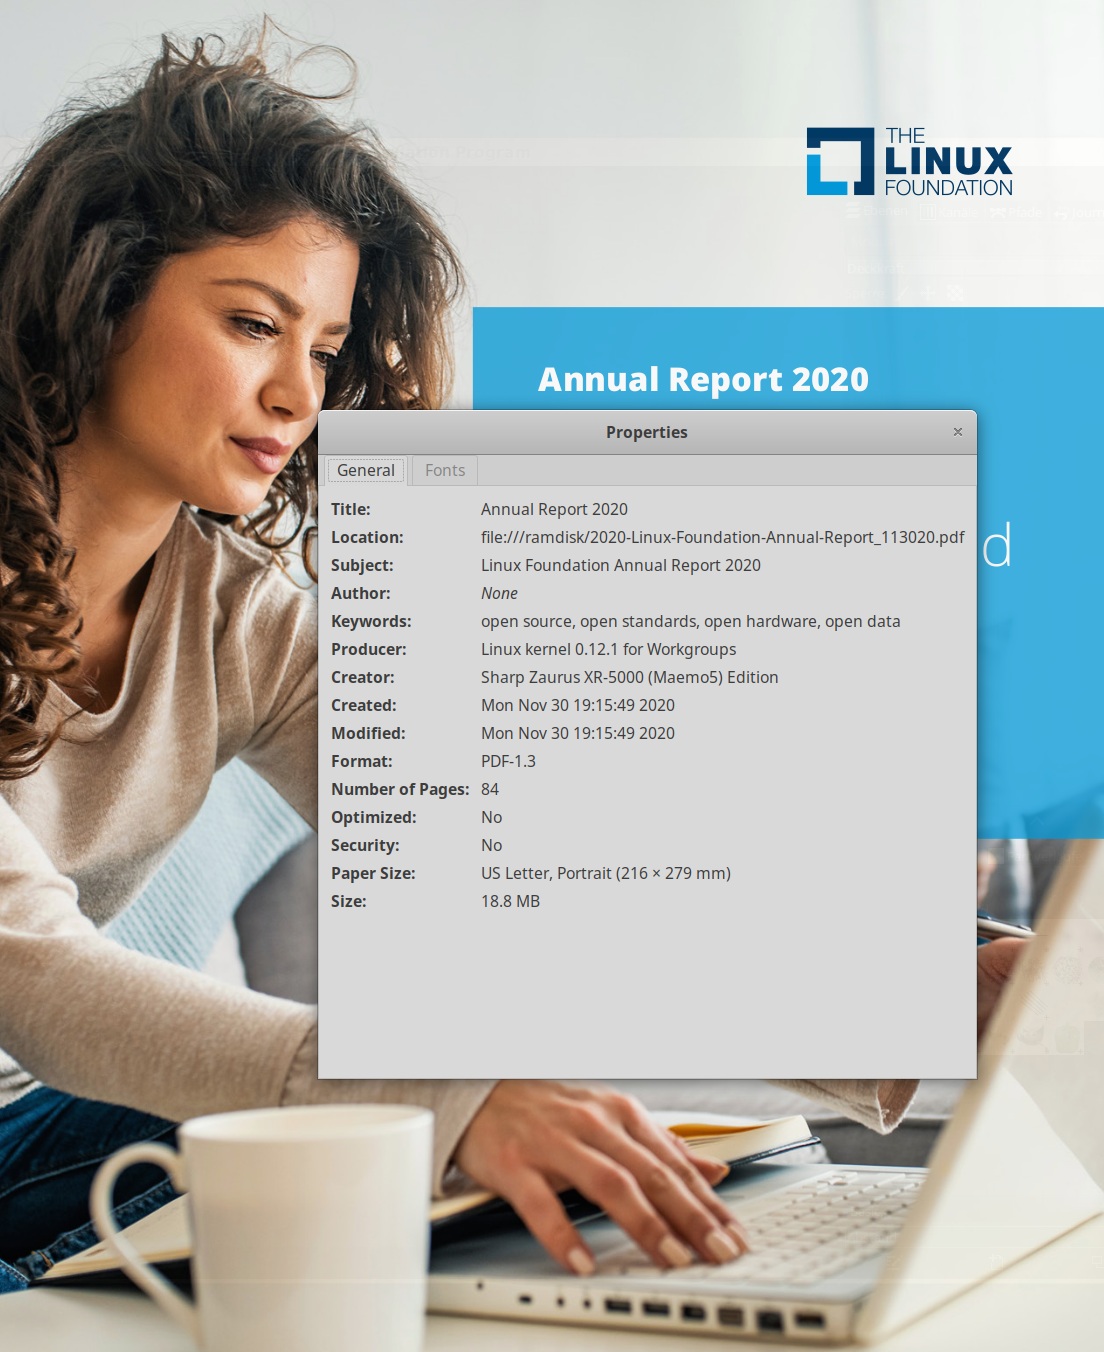
The Linux Foundation has published its annual report today. LWN calls it glossy and yeah, boy, it is shiny. So shiny that people that work in the publishing industry immediately see this has been produced with the Adobe toolchain which - unfortunately - is one of the big suites of software not yet available for Linux. Checking the PDF file metadata reveals the keywords "open source, open standards, open hardware, open data". That is what the Linux Foundation is about. Good stuff. Linux Foundation annual report 2020 cover The PDF producer meta data for the annual report PDF has been set to "Linux kernel 0.12.1 for Workgroups" and the PDF creator meta data element to "Sharp Zaurus XR-5000 (Maemo5) Edition". Somebody thought to better hide the real data and had some tongue-in-cheek ideas. Kudos. But nicer would have been to use Open Source software to produce the report, not? Running strings 2020-Linux-Foundation-Annual-Report_113020.pdf grep Adobe wc -l gives us 1229 lines and confirms the suspicion of the toolchain. A stale /Title (Annual Report 2020) /Producer (macOS Version 10.15.7 \(Build 19H15\) Quartz PDFContext) has been forgotten in the document to tell us about the platform. So, ladies and gentlemen, the Linux Foundation 2020 annual report has been produced on a Mac. Running Adobe Creative Cloud on MacOS Catalina 10.15.7. Which is proprietary software. Its kernel (and some userland pieces) are based on BSD. Not Linux.
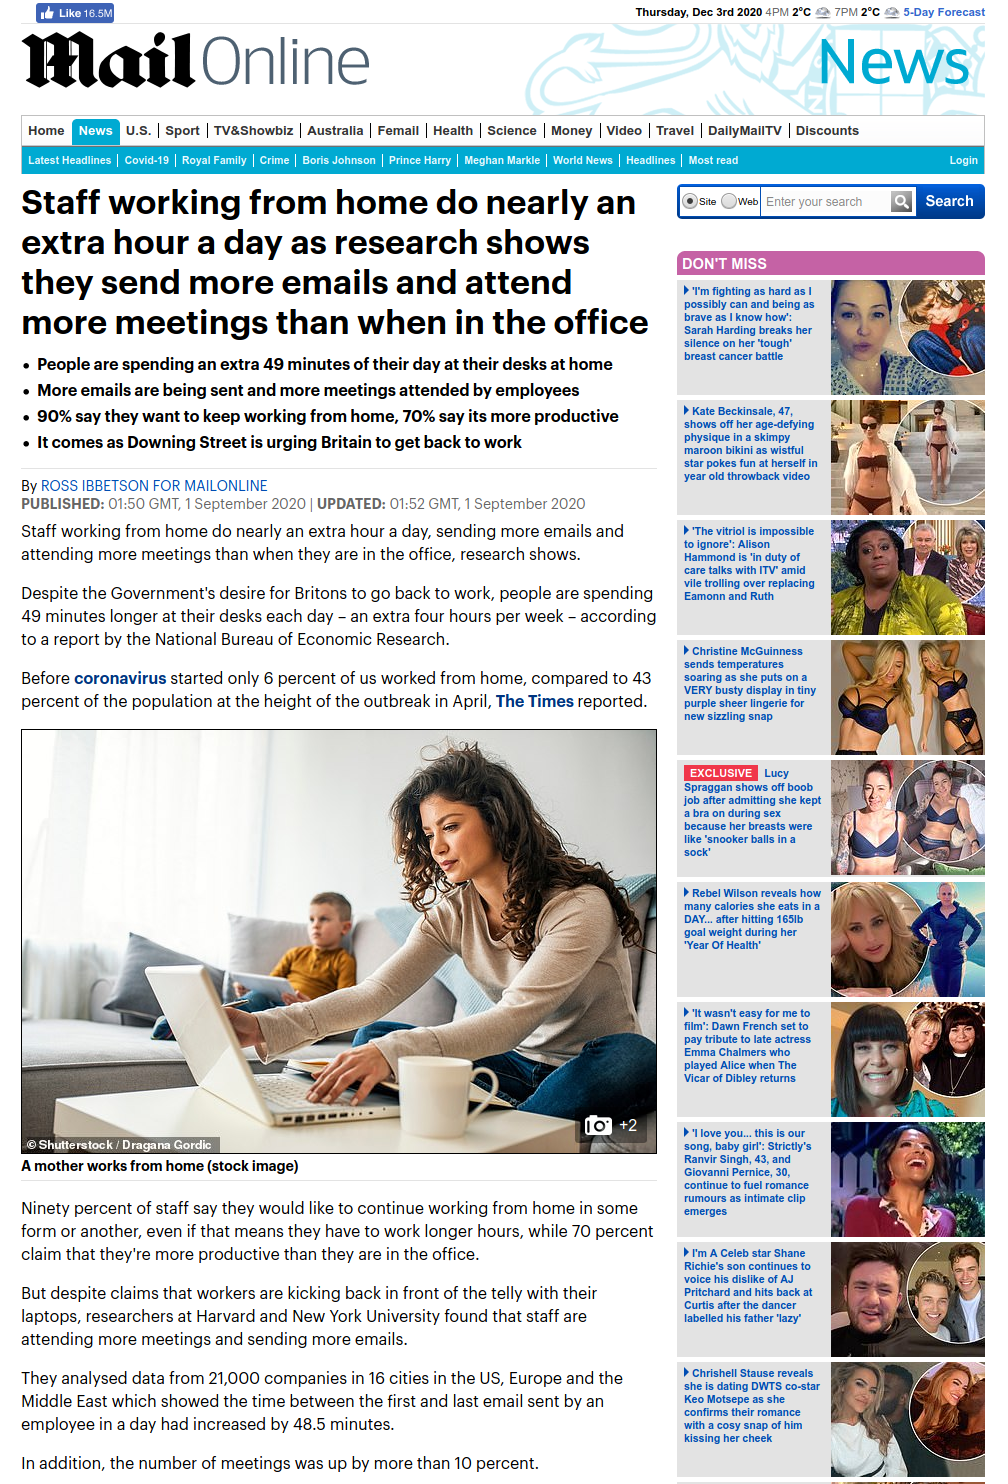
The image on the front page also struck me as a bit odd ... using a ballpoint pen on the laptop screen? Unbranded laptop. Unbranded cup in the foreground. Kid in the background not paying attention to his tablet. All of that cries stock image so loud it hurts. Google currently finds ~560 uses of the picture and any editorial use nicely tells us that it is Dragana Gordic / Shutterstock. The image is "Smiling mom working at home with her child on the sofa while writing an email. Young woman working from home, while in quarantine isolation during the Covid-19 health crisis". See the Daily Mail for a wonderful example of the working mum in context. I hope, if her laptop had been powered on, it would have run Linux. I mean, what else would still run on an old white MacBook with an Intel "Core 2 Duo" processor from 2008? Daily Mail screenshot of the same stock image used Continue reading "No dog food today - the Linux Foundation annual report"

Alberto Garc a: Subcluster allocation for qcow2 images

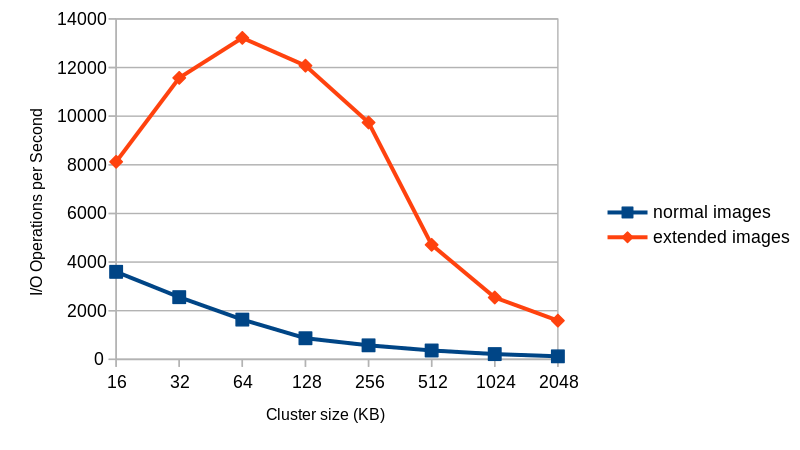
In previous blog posts I talked about QEMU s qcow2 file format and how to make it faster. This post gives an overview of how the data is structured inside the image and how that affects performance, and this presentation at KVM Forum 2017 goes further into the topic. This time I will talk about a new extension to the qcow2 format that seeks to improve its performance and reduce its memory requirements. Let s start by describing the problem. Limitations of qcow2 One of the most important parameters when creating a new qcow2 image is the cluster size. Much like a filesystem s block size, the qcow2 cluster size indicates the minimum unit of allocation. One difference however is that while filesystems tend to use small blocks (4 KB is a common size in ext4, ntfs or hfs+) the standard qcow2 cluster size is 64 KB. This adds some overhead because QEMU always needs to write complete clusters so it often ends up doing copy-on-write and writing to the qcow2 image more data than what the virtual machine requested. This gets worse if the image has a backing file because then QEMU needs to copy data from there, so a write request not only becomes larger but it also involves additional read requests from the backing file(s). Because of that qcow2 images with larger cluster sizes tend to: Unfortunately, reducing the cluster size is in general not an option because it also has an impact on the amount of metadata used internally by qcow2 (reference counts, guest-to-host cluster mapping). Decreasing the cluster size increases the number of clusters and the amount of necessary metadata. This has direct negative impact on I/O performance, which can be mitigated by caching it in RAM, therefore increasing the memory requirements (the aforementioned post covers this in more detail). Subcluster allocation The problems described in the previous section are well-known consequences of the design of the qcow2 format and they have been discussed over the years. I have been working on a way to improve the situation and the work is now finished and available in QEMU 5.2 as a new extension to the qcow2 format called extended L2 entries. The so-called L2 tables are used to map guest addresses to data clusters. With extended L2 entries we can store more information about the status of each data cluster, and this allows us to have allocation at the subcluster level. The basic idea is that data clusters are now divided into 32 subclusters of the same size, and each one of them can be allocated separately. This allows combining the benefits of larger cluster sizes (less metadata and RAM requirements) with the benefits of smaller units of allocation (less copy-on-write, smaller images). If the subcluster size matches the block size of the filesystem used inside the virtual machine then we can eliminate the need for copy-on-write entirely. So with subcluster allocation we get: This figure shows the average number of I/O operations per second that I get with 4KB random write requests to an empty 40GB image with a fully populated backing file.
I/O performance comparison between traditional and extended qcow2 images
Things to take into account: How to use this? Extended L2 entries are available starting from QEMU 5.2. Due to the nature of the changes it is unlikely that this feature will be backported to an earlier version of QEMU. In order to test this you simply need to create an image with extended_l2=on, and you also probably want to use a larger cluster size (the default is 64 KB, remember that every cluster has 32 subclusters). Here is an example:
$ qemu-img create -f qcow2 -o extended_l2=on,cluster_size=128k img.qcow2 1T
And that s all you need to do. Once the image is created all allocations will happen at the subcluster level. More information This work was presented at the 2020 edition of the KVM Forum. Here is the video recording of the presentation, where I cover all this in more detail: You can also find the slides here. Acknowledgments This work has been possible thanks to Outscale, who have been sponsoring Igalia and my work in QEMU.
Igalia and Outscale
And thanks of course to the rest of the QEMU development team for their feedback and help with this!

Dirk Eddelbuettel: RcppTOML 0.1.7: Support for g++-11, Minor Updates

A new RcppTOML release arrived on CRAN earlier today evening. RcppTOML brings TOML to R. TOML is a file format that is most suitable for configurations, as it is meant to be edited by humans but read by computers. It emphasizes strong readability for humans while at the same time supporting strong typing as well as immediate and clear error reports. On small typos you get parse errors, rather than silently corrupted garbage. Much preferable to any and all of XML, JSON or YAML though sadly these may be too ubiquitous now. TOML has been making inroads with projects such as the Hugo static blog compiler, or the Cargo system of Crates (aka packages ) for the Rust language. CRAN had sent us a note that the package no longer compiled under the [unreleased, of course, never change, BDR ;-) ] g++-11 compiler, but were kind enough to hint that it was only lacking an #include <limits>. These things happen: newer compilers are generally more strict, and that is generally a good things. (Last year this time we prepped code for the more stringent view on global variables under gcc-10. Earlier g++ version had similar demands to clarify include headers.) I set up a simple Docker contain with on Ubuntu 21.04 with g++-11, R, and Rcpp to build the package and make this change (which was of course also PR ed upstream at cpptoml), plus some other small ones that update the package since the last release roughly 18 months ago. We also switched CI use to the r-ci setup I should blog about a little more, removed a bashism and updated a few URLs. The bulleted list of changes in this version follows.

Changes in version 0.1.7 (2020-12-01)
  • Add #include <limits> to header file, also contributed upstream, to permit compilation under the (unreleased) g++-11.
  • Switch the simple cleanup script to sh.
  • Switch CI use to r-ci for focal and bspm.
  • Update several TOML URLs to https://toml.io/en/.

Courtesy of my CRANberries, there is a diffstat report for this release. More information is on the RcppTOML page page. Please use the GitHub issue tracker for issues and bugreports. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

1 December 2020

Shirish Agarwal: The Constitution of Knowledge

Truth, Untruths and Education in India. I read this somewhat disturbing and yet pretty raw truth from foreign affairs. It took me quite a few days to not only digest but also say yes and see the same situation playing out in India. I have been seeing the discourse on Twitter and while a part of it is the equivalent of road rage, a huge part is a disconnect to not acknowledge and be civil. We may come to different conclusions from the same data but being civil seems to be difficult for a lot of people. One part is of course ego, where nobody wants to lose, but more than that are the plain comprehension issues. Most of the literature, good literature is unfortunately based in English.

And while we can have differing opinions of what constitutes good literature, for me it s books like Battle of Belonging,The:On Nationalism, Patriotism, and What it Means Shashi Tharoor. From what little I have understood, the book makes the case of civic nationalism which is far more inclusive than the narrow confines of patriotism. Now this begs the question when you have such books and many books which do tell you about different aspects of social, political and knowledge, why are so many people prone to disinformation in India similar to U.S. and probably other countries as well. One of the biggest reasons per-se is lack of education and quality education. When the number of graduates is less than five percent how do you expect that population to be able to take decisions in their economic self-interest? So sadly the understanding is ingrained from WhatsApp and there is no need to check from alternate sources. And just like Mr. Trump followers, they believe those versions to be the unvarnished truth. I do understand that no truth is immutable except for life and death. All others are imperfect unless it is validated by some sort of scientific validation behind it. At the same time, these truths may themselves be invalidated if a stronger scientific evidence establishes itself. This is the reason why hypothesis and facts themselves are challenged again and again. Sharing couple of examples below.

Nationalization of Banking, RERA and RCEP Most of the people want freedom of the banks i.e. private banking don t really know that private banking existed at a time in free India before they were nationalized and these banks failed at surprisingly regular intervals. Now it isn t as if this fact is hidden but it is not as popular as maybe some other facts or ideas. Now the Government in the center obviously doesn t want to share these facts as they want corporates in banking. And if that fact is known by many people it will be a huge setback to their plans. RBI failures have been to many to count. Even recent legislations like RERA and others which were supposed to bring relief to millions of potential homeowners has become a pawn in the hands of builders and this has been known. One of the interesting points of RCEP which is not so much in public domain is that RCEP would have a mere 4.5% duty on most products which will go down to 1.5% over a 20 year period. Now with India staying out of it, we have done two things. We have said that we will not be competitive even after 20 years of this which is the more damning part. And we will not take part in the growth that other countries will have due to this. Contempt Proceedings against Comic Artist because she has an opinion on SC The fall in SC and constitutional values grows day by day. The AG today consented to have contempt proceedings against a comic artist saying she insulted the SC. Gone are the days when an artist made fun of the PM, and she gave him a Padam Shri (one of the highest civilian honors) for his contributions. Then, even dissent or being cynical was looked as being a contribution to the national effort rather than today. This is the reason why India has been continuously falling in the Global Freedom of Expression Index. I have seen censoring many a time here. I, myself has been locked out of Wikipedia many times. Can you imagine, being locked out of Wikipedia which is perhaps one of the more neutral sites on the web. And then there was this wikibio thing, such a sad thing to happen. Guessing this is the future of the Indian interweb.
Stick figure by Sanitary Panels on SC

Dirk Eddelbuettel: inline 0.3.17: Refactored and New Tests

A new release of the inline package arrived on CRAN this evening and has already been shipped to Debian as well. inline facilitates writing code in-line in simple string expressions or short files. The package was used quite extensively by Rcpp in the days before Rcpp Attributes arrived on the scene proving an even better alternative for its use cases. inline is still use by rstan and a number of other packages. One of those other packages is mkin, and its author Johannes Ranke overhauled the saving and re-loading of C functions part with a really well-done set of contributions. In the process we also added unit testing via the lovely tinytest, and changed to continuous integration setup to r-ci. See below for a detailed list of changes extracted from the NEWS file.

Changes in inline version 0.3.17 (2020-11-30)
  • Unit testing is now supported via tinytest (Johannes in #15 addressing #14).
  • CI was updated to use focal and run.sh from r-ci on Travis and GitHub Actions (Dirk)
  • The writing and reading of compiled code was refactored and extended (Johannes in #16 fixing #13).
  • Some minor problems related to CRAN checks and tests were corrected (Johannes and Dirk in #17, Johannes in #18, #19, #20).
  • Small stylistic updates have been applied to some R and Rd files (Dirk).

Courtesy of my CRANberries, there is a comparison to the previous release. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

30 November 2020

Chris Lamb: Free software activities in November 2020

Here is my monthly update covering what I have been doing in the free software world during November 2020 (previous month):

Reproducible Builds One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. However, whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into ostensibly secure software during the various compilation and distribution processes. The motivation behind the Reproducible Builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. The project is proud to be a member project of the Software Freedom Conservancy. Conservancy acts as a corporate umbrella allowing projects to operate as non-profit initiatives without managing their own corporate structure. If you like the work of the Conservancy or the Reproducible Builds project, please consider becoming an official supporter.
This month, I:
I also made the following changes to diffoscope:

Debian I performed the following uploads to the Debian Linux distribution this month: I also filed a release-critical bug against the minidlna package which could not be successfully purged from the system without reporting a cannot remove '/var/log/minidlna' error. (#975372)

Debian LTS This month I have worked 18 hours on Debian Long Term Support (LTS) and 12 hours on its sister Extended LTS project, including: You can find out more about the Debian LTS project via the following video:

28 November 2020

Russ Allbery: Review: Nine Goblins

Review: Nine Goblins, by T. Kingfisher
Publisher: Red Wombat Tea Company
Copyright: 2013
ASIN: B00G9GSEXO
Format: Kindle
Pages: 140
The goblins are at war, a messy multi-sided war also involving humans, elves, and orcs. The war was not exactly their idea, although the humans would claim otherwise. Goblins kept moving farther and farther into the wilderness to avoid human settlements, and then they ran out of wilderness, and it wasn't clear what else to do. For the Nineteenth Infantry, the war is a confusing business, full of boredom and screaming and being miserable and following inexplicable orders. And then they run into a wizard. Wizards in this world are not right in the head, and by not right I mean completely psychotic. That's the only way that you get magical powers. Wizards are therefore incredibly dangerous and scarily unpredictable, so when the Whinin' Nineteenth run into a human wizard who shoots blue out of his mouth, making him stop shooting blue out of his mouth becomes a high priority. Goblins have only one effective way of stopping things: charge at them and hit them with something until they stop. Wizards have things like emergency escape portals. And that's how the entire troop of nine goblins ended up far, far behind enemy lines. Sings-to-Trees's problems, in contrast, are rather more domestic. At the start of the book, they involve, well:
Sings-to-Trees had hair the color of sunlight and ashes, delicately pointed ears, and eyes the translucent green of new leaves. His shirt was off, he had the sort of tanned muscle acquired from years of healthy outdoor living, and you could have sharpened a sword on his cheekbones. He was saved from being a young maiden's fantasy unless she was a very peculiar young maiden by the fact that he was buried up to the shoulder in the unpleasant end of a heavily pregnant unicorn.
Sings-to-Trees is the sort of elf who lives by himself, has a healthy appreciation for what nursing wild animals involves, and does it anyway because he truly loves animals. Despite that, he was not entirely prepared to deal with a skeleton deer with a broken limb, or at least with the implications of injured skeleton deer who are attracted by magical disturbances showing up in his yard. As one might expect, Sings-to-Trees and the goblins run into each other while having to sort out some problems that are even more dangerous than the war the goblins were unexpectedly removed from. But the point of this novella is not a deep or complex plot. It pushes together a bunch of delightfully weird and occasionally grumpy characters, throws a challenge at them, and gives them space to act like fundamentally decent people working within their constraints and preconceptions. It is, in other words, an excellent vehicle for Ursula Vernon (writing as T. Kingfisher) to describe exasperated good-heartedness and stubbornly determined decency.
Sings-to-Trees gazed off in the middle distance with a vague, pleasant expression, the way that most people do when present at other people's minor domestic disputes, and after a moment, the stag had stopped rattling, and the doe had turned back and rested her chin trustingly on Sings-to-Trees' shoulder. This would have been a touching gesture, if her chin hadn't been made of painfully pointy blades of bone. It was like being snuggled by an affectionate plow.
It's not a book you read for the twists and revelations (the resolution is a bit of an anti-climax). It's strength is in the side moments of characterization, in the author's light-hearted style, and in descriptions like the above. Sings-to-Trees is among my favorite characters in all of Vernon's books, surpassed only by gnoles and a few characters in Digger. The Kingfisher books I've read recently have involved humans and magic and romance and more standard fantasy plots. This book is from seven years ago and reminds me more of Digger. There is less expected plot machinery, more random asides, more narrator presence, inhuman characters, no romance, and a lot more focus on characters deciding moment to moment how to tackle the problem directly in front of them. I wouldn't call it a children's book (all of the characters are adults), but it has a bit of that simplicity and descriptive focus. If you like Kingfisher in descriptive mode, or enjoy Vernon's descriptions of D&D campaigns on Twitter, you are probably going to like this. If you don't, you may not. I thought it was slight but perfect for my mood at the time. Rating: 7 out of 10

27 November 2020

Arturo Borrero Gonz lez: Netfilter virtual workshop 2020 summary

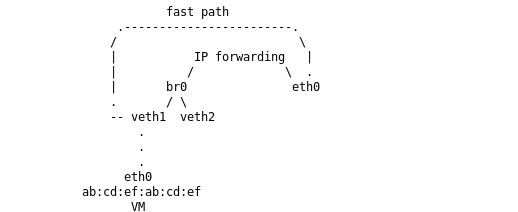
Netfilter logo Once a year folks interested in Netfilter technologies gather together to discuss past, ongoing and future works. The Netfilter Workshop is an opportunity to share and discuss new ideas, the state of the project, bring people together to work & hack and to put faces to people who otherwise are just email names. This is an event that has been happening since at least 2001, so we are talking about a genuine community thing here. It was decided there would be an online format, split in 3 short meetings, once per week on Fridays. I was unable to attend the first session on 2020-11-06 due to scheduling conflict, but I made it to the sessions on 2020-11-13 and 2020-11-20. I would say the sessions were joined by about 8 to 10 people, depending on the day. This post is a summary with some notes on what happened in this edition, with no special order. Pablo did the classical review of all the changes and updates that happened in all the Netfilter project software components since last workshop. I was unable to watch this presentation, so I have nothing special to comment. However, I ve been following the development of the project very closely, and there are several interesting things going on, some of them commented below. Florian Westphal brought to the table status on some open/pending work for mptcp option matching, systemd integration and finally interfacing from nft with cgroupv2. I was unable to participate in the talk for the first two items, so I cannot comment a lot more. On the cgroupv2 side, several options were evaluated to how to match them, identification methods, the hierarchical tree that cgroups present, etc. We will have to wait a bit more to see how the final implementation looks like. Also, Florian presented his concerns on conntrack hash collisions. There are no real-world known issues at the moment, but there is an old paper that suggests we should keep and eye on this and introduce improvements to prevent future DoS attack vectors. Florian mentioned these attacks are not practical at the moment, but who knows in a few years. He wants to explore introducing RB trees for conntrack. It will probably be a rbtree structure of hash tables in order to keep supporting parallel insertions. He was encouraged by others to go ahead and play/explore with this. Phil Sutter shared his past and future iptables development efforts. He highlighted fixed bugs and his short/midterm TODO list. I know Phil has been busy lately fixing iptables-legacy/iptables-nft incompatibilities. Basically addressing annoying bugs discovered by all ruleset managers out there (kubernetes, docker, openstack neutron, etc). Lots of work has been done to improve the situation; moreover I myself reported, or forwarded from the Debian bug tracker, several bugs. Anyway I was unable to attend this talk, only learnt a few bits in the following sessions, so I don t have a lot to comment here. But when I was fully present, I was asked by Phil about the status of netfilter components in Debian, and future plans. I shared my information. The idea for the next Debian stable release is to don t include iptables in the installer, and include nftables instead. Since Debian Buster, nftables is the default firewalling tool anyway. He shared the plans for the RedHat-related ecosystem, and we were able to confirm that we are basically in sync. Pablo commented on the latest Netfilter flowtable enhancements happening. Using the flowtable infrastructure, one can create kernel network bypasses to speed up packet throughput. The latest changes are aimed for bridge and VLAN enabled setups. The flowtable component will now know how to bypass in these 2 network architectures as well as the previously supported ingress hook. This is basically aimed for virtual machines and containers scenarios. There was some debate on use cases and supported setups. I commented that a bunch of virtual machines connected to a classic linux bridge and then doing NAT is basically what Openstack Neutron does, specifically in DVR setups. Same can be found in some container-based environments. Early/simple benchmarks done by Pablo suggest there could be huge performance improvements for those use cases. There was some inevitable comparison of this approach to what others, like DPDK/XDP can do. A point was raised about this being a more generic and operating system-integrated solution, which should make it more extensible and easier to use. flowtable for bridges Stefano Bravio commented on several open topics for nftables that he is interested on working on. One of them, issues related to concatenations + vmap issues. He also addressed concerns with people s expectations when migrating from ipset to nftables. There are several corner features in ipset that aren t currently supported in nftables, and we should document them. Stefano is also wondering about some tools to help in the migration. A translation layer like there is in place for iptables. Eric Gaver commented there are a couple of semantics that will not be suitable for translation, such as global sets, or sets of sets. But ipset is way simpler than iptables, so a translation mechanism should probably be created. In any case, there was agreement that anything that helps people migrate is more than welcome, even if it doesn t support 100% of the use cases. Stefano is planning to write documentation in the nftables wiki on how the pipapo algorithm works and the supported use cases. Other plans by Stefano include to work on some optimisations for faster matches. He mentioned using architecture specific instruction to speed up sets operations, like lookups. Finally, he commented that some folks working with eBPF have showed interest in reusing some parts of the nftables sets infrastructure (pipapo) because they have detected performance issues in their own data structures in some cases. It is not clear how to best achieve it, how to better bridge the two things together. Probably the ideal is to generalize the pipapo data structures and integrate it into the generic bitmap library or something which can be used by anyone. Anyway, he hopes to get some more time to focus on Netfilter stuff begining with the next year, in a couple of months. Moving a bit away from the pure software development topics, Pablo commented on the netfilter.org infrastructure. Right now the servers are running on gandi.net, on virtual machines that are being basically donated to us. He pointed that the plan is to simplify the infrastructure. For that reason, for example, FTP services has been shut down. Rsync services have been shut down as well, so basically we no longer have a mirrors infrastructure. The bugzilla and wikis we have need some attention, given they are old software pieces, and we need to migrate them to be more modern. Finally, the new logo that was created was presented. Later on, we spent a good chunk of the meeting discussing options on how to address the inevitable iptables deprecation situation. There are some open questions, and we discussed several approaches. From doing nothing at all, which means keeping the current status-quo, to setting a deadline date for the deprecation like the python community did with python2. I personally like this deadline idea, but it is perceived like a negative push by other. We all agree that the current do nothing approach is not sustainable either. Probably the way to go is basically to be more informative. We need to clearly communicate that choosing iptables for anything in 2020 is a bad idea. There are additional initiatives to help on this topic, without being too aggressive. A FAQ will probably be introduced. Eric Garver suggested we should bring nftables front and center. Given the website still mentions iptables everywhere, we will probably refresh the web content, introduce additional informative banners and similar things. There was an interesting talk on the topic of nft table ownership. The idea is to attach a table, and all the child objects, to a process. Then, we prevent any modifications to the table or the child objects by external entities. Basically, allocating and locking a table for a certain netlink socket. This is a nice way for ruleset managers, like firewalld, to ensure they have full control of what s happening to their ruleset, reducing the chances for ending with an inconsistent configuration. There is a proof-of-concept patch by Pablo to support this, and Eric mentioned he is pretty much interested in any improvements to support this use case. The final time block in the final session day was dedicated to talk about the next workshop. We are all very happy we could meet. Meeting virtually is way easier (and cheaper) than in person. Perhaps we can make it online every 3 or 6 months instead of, or in addition to, one big annual physical event. We will see what happens next year. That s all on my side!
21 November 2020

Michael Stapelberg: Winding down my Debian involvement

This post is hard to write, both in the emotional sense but also in the I would have written a shorter letter, but I didn t have the time sense. Hence, please assume the best of intentions when reading it it is not my intention to make anyone feel bad about their contributions, but rather to provide some insight into why my frustration level ultimately exceeded the threshold. Debian has been in my life for well over 10 years at this point. A few weeks ago, I have visited some old friends at the Z rich Debian meetup after a multi-year period of absence. On my bike ride home, it occurred to me that the topics of our discussions had remarkable overlap with my last visit. We had a discussion about the merits of systemd, which took a detour to respect in open source communities, returned to processes in Debian and eventually culminated in democracies and their theoretical/practical failings. Admittedly, that last one might be a Swiss thing. I say this not to knock on the Debian meetup, but because it prompted me to reflect on what feelings Debian is invoking lately and whether it s still a good fit for me. So I m finally making a decision that I should have made a long time ago: I am winding down my involvement in Debian to a minimum.

What does this mean? Over the coming weeks, I will:
  • transition packages to be team-maintained where it makes sense
  • remove myself from the Uploaders field on packages with other maintainers
  • orphan packages where I am the sole maintainer
I will try to keep up best-effort maintenance of the manpages.debian.org service and the codesearch.debian.net service, but any help would be much appreciated. For all intents and purposes, please treat me as permanently on vacation. I will try to be around for administrative issues (e.g. permission transfers) and questions addressed directly to me, permitted they are easy enough to answer.

Why? When I joined Debian, I was still studying, i.e. I had luxurious amounts of spare time. Now, over 5 years of full time work later, my day job taught me a lot, both about what works in large software engineering projects and how I personally like my computer systems. I am very conscious of how I spend the little spare time that I have these days. The following sections each deal with what I consider a major pain point, in no particular order. Some of them influence each other for example, if changes worked better, we could have a chance at transitioning packages to be more easily machine readable.

Change process in Debian The last few years, my current team at work conducted various smaller and larger refactorings across the entire code base (touching thousands of projects), so we have learnt a lot of valuable lessons about how to effectively do these changes. It irks me that Debian works almost the opposite way in every regard. I appreciate that every organization is different, but I think a lot of my points do actually apply to Debian. In Debian, packages are nudged in the right direction by a document called the Debian Policy, or its programmatic embodiment, lintian. While it is great to have a lint tool (for quick, local/offline feedback), it is even better to not require a lint tool at all. The team conducting the change (e.g. the C++ team introduces a new hardening flag for all packages) should be able to do their work transparent to me. Instead, currently, all packages become lint-unclean, all maintainers need to read up on what the new thing is, how it might break, whether/how it affects them, manually run some tests, and finally decide to opt in. This causes a lot of overhead and manually executed mechanical changes across packages. Notably, the cost of each change is distributed onto the package maintainers in the Debian model. At work, we have found that the opposite works better: if the team behind the change is put in power to do the change for as many users as possible, they can be significantly more efficient at it, which reduces the total cost and time a lot. Of course, exceptions (e.g. a large project abusing a language feature) should still be taken care of by the respective owners, but the important bit is that the default should be the other way around. Debian is lacking tooling for large changes: it is hard to programmatically deal with packages and repositories (see the section below). The closest to sending out a change for review is to open a bug report with an attached patch. I thought the workflow for accepting a change from a bug report was too complicated and started mergebot, but only Guido ever signaled interest in the project. Culturally, reviews and reactions are slow. There are no deadlines. I literally sometimes get emails notifying me that a patch I sent out a few years ago (!!) is now merged. This turns projects from a small number of weeks into many years, which is a huge demotivator for me. Interestingly enough, you can see artifacts of the slow online activity manifest itself in the offline culture as well: I don t want to be discussing systemd s merits 10 years after I first heard about it. Lastly, changes can easily be slowed down significantly by holdouts who refuse to collaborate. My canonical example for this is rsync, whose maintainer refused my patches to make the package use debhelper purely out of personal preference. Granting so much personal freedom to individual maintainers prevents us as a project from raising the abstraction level for building Debian packages, which in turn makes tooling harder. How would things look like in a better world?
  1. As a project, we should strive towards more unification. Uniformity still does not rule out experimentation, it just changes the trade-off from easier experimentation and harder automation to harder experimentation and easier automation.
  2. Our culture needs to shift from this package is my domain, how dare you touch it to a shared sense of ownership, where anyone in the project can easily contribute (reviewed) changes without necessarily even involving individual maintainers.
To learn more about how successful large changes can look like, I recommend my colleague Hyrum Wright s talk Large-Scale Changes at Google: Lessons Learned From 5 Yrs of Mass Migrations .

Fragmented workflow and infrastructure Debian generally seems to prefer decentralized approaches over centralized ones. For example, individual packages are maintained in separate repositories (as opposed to in one repository), each repository can use any SCM (git and svn are common ones) or no SCM at all, and each repository can be hosted on a different site. Of course, what you do in such a repository also varies subtly from team to team, and even within teams. In practice, non-standard hosting options are used rarely enough to not justify their cost, but frequently enough to be a huge pain when trying to automate changes to packages. Instead of using GitLab s API to create a merge request, you have to design an entirely different, more complex system, which deals with intermittently (or permanently!) unreachable repositories and abstracts away differences in patch delivery (bug reports, merge requests, pull requests, email, ). Wildly diverging workflows is not just a temporary problem either. I participated in long discussions about different git workflows during DebConf 13, and gather that there were similar discussions in the meantime. Personally, I cannot keep enough details of the different workflows in my head. Every time I touch a package that works differently than mine, it frustrates me immensely to re-learn aspects of my day-to-day. After noticing workflow fragmentation in the Go packaging team (which I started), I tried fixing this with the workflow changes proposal, but did not succeed in implementing it. The lack of effective automation and slow pace of changes in the surrounding tooling despite my willingness to contribute time and energy killed any motivation I had.

Old infrastructure: package uploads When you want to make a package available in Debian, you upload GPG-signed files via anonymous FTP. There are several batch jobs (the queue daemon, unchecked, dinstall, possibly others) which run on fixed schedules (e.g. dinstall runs at 01:52 UTC, 07:52 UTC, 13:52 UTC and 19:52 UTC). Depending on timing, I estimated that you might wait for over 7 hours (!!) before your package is actually installable. What s worse for me is that feedback to your upload is asynchronous. I like to do one thing, be done with it, move to the next thing. The current setup requires a many-minute wait and costly task switch for no good technical reason. You might think a few minutes aren t a big deal, but when all the time I can spend on Debian per day is measured in minutes, this makes a huge difference in perceived productivity and fun. The last communication I can find about speeding up this process is ganneff s post from 2008. How would things look like in a better world?
  1. Anonymous FTP would be replaced by a web service which ingests my package and returns an authoritative accept or reject decision in its response.
  2. For accepted packages, there would be a status page displaying the build status and when the package will be available via the mirror network.
  3. Packages should be available within a few minutes after the build completed.

Old infrastructure: bug tracker I dread interacting with the Debian bug tracker. debbugs is a piece of software (from 1994) which is only used by Debian and the GNU project these days. Debbugs processes emails, which is to say it is asynchronous and cumbersome to deal with. Despite running on the fastest machines we have available in Debian (or so I was told when the subject last came up), its web interface loads very slowly. Notably, the web interface at bugs.debian.org is read-only. Setting up a working email setup for reportbug(1) or manually dealing with attachments is a rather big hurdle. For reasons I don t understand, every interaction with debbugs results in many different email threads. Aside from the technical implementation, I also can never remember the different ways that Debian uses pseudo-packages for bugs and processes. I need them rarely enough to establish a mental model of how they are set up, or working memory of how they are used, but frequently enough to be annoyed by this. How would things look like in a better world?
  1. Debian would switch from a custom bug tracker to a (any) well-established one.
  2. Debian would offer automation around processes. It is great to have a paper-trail and artifacts of the process in the form of a bug report, but the primary interface should be more convenient (e.g. a web form).

Old infrastructure: mailing list archives It baffles me that in 2019, we still don t have a conveniently browsable threaded archive of mailing list discussions. Email and threading is more widely used in Debian than anywhere else, so this is somewhat ironic. Gmane used to paper over this issue, but Gmane s availability over the last few years has been spotty, to say the least (it is down as I write this). I tried to contribute a threaded list archive, but our listmasters didn t seem to care or want to support the project.

Debian is hard to machine-read While it is obviously possible to deal with Debian packages programmatically, the experience is far from pleasant. Everything seems slow and cumbersome. I have picked just 3 quick examples to illustrate my point. debiman needs help from piuparts in analyzing the alternatives mechanism of each package to display the manpages of e.g. psql(1). This is because maintainer scripts modify the alternatives database by calling shell scripts. Without actually installing a package, you cannot know which changes it does to the alternatives database. pk4 needs to maintain its own cache to look up package metadata based on the package name. Other tools parse the apt database from scratch on every invocation. A proper database format, or at least a binary interchange format, would go a long way. Debian Code Search wants to ingest new packages as quickly as possible. There used to be a fedmsg instance for Debian, but it no longer seems to exist. It is unclear where to get notifications from for new packages, and where best to fetch those packages.

Complicated build stack See my Debian package build tools post. It really bugs me that the sprawl of tools is not seen as a problem by others.

Developer experience pretty painful Most of the points discussed so far deal with the experience in developing Debian, but as I recently described in my post Debugging experience in Debian , the experience when developing using Debian leaves a lot to be desired, too.

I have more ideas At this point, the article is getting pretty long, and hopefully you got a rough idea of my motivation. While I described a number of specific shortcomings above, the final nail in the coffin is actually the lack of a positive outlook. I have more ideas that seem really compelling to me, but, based on how my previous projects have been going, I don t think I can make any of these ideas happen within the Debian project. I intend to publish a few more posts about specific ideas for improving operating systems here. Stay tuned. Lastly, I hope this post inspires someone, ideally a group of people, to improve the developer experience within Debian.

19 November 2020

Daniel Silverstone: Withdrawing Gitano from support

Unfortunately, in Debian in particular, libgit2 is undergoing a transition which is blocked by gall. Despite having had over a month to deal with this, I've not managed to summon the tuits to update Gall to the new libgit2 which means, nominally, I ought to withdraw it from testing and possibly even from unstable given that I'm not really prepared to look after Gitano and friends in Debian any longer. However, I'd love for Gitano to remain in Debian if it's useful to people. Gall isn't exactly a large piece of C code, and so probably won't be a huge job to do the port, I simply don't have the desire/energy to do it myself. If someone wanted to do the work and provide a patch / "pull request" to me, then I'd happily take on the change and upload a new package, or if someone wanted to NMU the gall package in Debian I'll take the change they make and import it into upstream. I just don't have the energy to reload all that context and do the change myself. If you want to do this, email me and let me know, so I can support you and take on the change when it's done. Otherwise I probably will go down the lines of requesting Gitano's removal from Debian in the next week or so.

17 November 2020

Dirk Eddelbuettel: RcppArmadillo 0.10.1.2.0

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 779 other packages on CRAN. This release ties up a few loose ends from the recent 0.10.1.0.0.

Changes in RcppArmadillo version 0.10.1.2.0 (2020-11-15)
  • Upgraded to Armadillo release 10.1.2 (Orchid Ambush)
  • Remove three unused int constants (#313)
  • Include main armadillo header using quotes instead of brackets
  • Rewrite version number use in old-school mode because gcc 4.8.5
  • Skipping parts of sparse conversion on Windows as win-builder fails

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Next.

Previous.