Search Results: "cas"

15 November 2021

Vincent Bernat: Git as a source of truth for network automation

The first step when automating a network is to build the source of truth. A source of truth is a repository of data that provides the intended state: the list of devices, the IP addresses, the network protocols settings, the time servers, etc. A popular choice is NetBox. Its documentation highlights its usage as a source of truth:
NetBox intends to represent the desired state of a network versus its operational state. As such, automated import of live network state is strongly discouraged. All data created in NetBox should first be vetted by a human to ensure its integrity. NetBox can then be used to populate monitoring and provisioning systems with a high degree of confidence.
When introducing Jerikan, a common feedback we got was: you should use NetBox for this. Indeed, Jerikan s source of truth is a bunch of YAML files versioned with Git.

Why Git? If we look at how things are done with servers and services, in a datacenter or in the cloud, we are likely to find users of Terraform, a tool turning declarative configuration files into infrastructure. Declarative configuration management tools like Salt, Puppet,1 or Ansible take care of server configuration. NixOS is an alternative: it combines package management and configuration management with a functional language to build virtual machines and containers. When using a Kubernetes cluster, people use Kustomize or Helm, two other declarative configuration management tools. Tapped together, these tools implement the infrastructure as code paradigm.
Infrastructure as code is an approach to infrastructure automation based on practices from software development. It emphasizes consistent, repeatable routines for provisioning and changing systems and their configuration. You make changes to code, then use automation to test and apply those changes to your systems. Kief Morris, Infrastructure as Code, O Reilly.
A version control system is a central tool for infrastructure as code. The usual candidate is Git with a source code management system like GitLab or GitHub. You get:
Traceability and visibility
Git keeps a log of all changes: what, who, why, and when. With a bit of discipline, each change is explained and self-contained. It becomes part of the infrastructure documentation. When the support team complains about a degraded experience for some customers over the last two months or so, you quickly discover this may be related to a change to an incoming policy in New York.
Rolling back
If a change is defective, it can be reverted quickly, safely, and without much effort, even if other changes happened in the meantime. The policy change at the origin of the problem spanned over three routers. Reverting this specific change and deploying the configuration let you solve the situation until you find a better fix.
Branching, reviewing, merging
When working on a new feature or refactoring some part of the infrastructure, a team member creates a branch and works on their change without interfering with the work of other members. Once the branch is ready, a pull request is created and the change is ready to be reviewed by the other team members before merging. You discover the issue was related to diverting traffic through an IX where one ISP was connected without enough capacity. You propose and discuss a fix that includes a change of the schema and the templates used to declare policies to be able to handle this case.
Continuous integration
For each change, automated tests are triggered. They can detect problems and give more details on the effect of a change. Branches can be deployed to a test infrastructure where regression tests are executed. The results can be synthesized as a comment in the pull request to help the review. You check your proposed change does not modify the other existing policies.

Why not NetBox? NetBox does not share these features. It is a database with a REST and a GraphQL API. Traceability is limited: changes are not grouped into a transaction and they are not documented. You cannot fork the database. Usually, there is one staging database to test modifications before applying them to the production database. It does not scale well and reviews are difficult. Applying the same change to the production database can be hazardous. Rolling back a change is non-trivial.

Update (2021-11) Nautobot, a fork of NetBox, will soon address this point by using Dolt, an SQL database engine allowing you to clone, branch, and merge, like a Git repository. Dolt is compatible with MySQL clients. See Nautobots, Roll Back! for a preview of this feature.

Moreover, NetBox is not usually the single source of truth. It contains your hardware inventory, the IP addresses, and some topology information. However, this is not the place you put authorized SSH keys, syslog servers, or the BGP configuration. If you also use Ansible, this information ends in its inventory. The source of truth is therefore fragmented between several tools with different workflows. Since NetBox 2.7, you can append additional data with configuration contexts. This mitigates this point. The data is arranged hierarchically but the hierarchy cannot be customized.2 Nautobot can manage configuration contexts in a Git repository, while still allowing to use of the API to fetch them. You get some additional perks, thanks to Git, but the remaining data is still in a database with a different lifecycle. Lastly, the schema used by NetBox may not fit your needs and you cannot tweak it. For example, you may have a rule to compute the IPv6 address from the IPv4 address for dual-stack interfaces. Such a relationship cannot be easily expressed and enforced in NetBox. When changing the IPv4 address, you may forget the IPv6 address. The source of truth should only contain the IPv4 address but you also want the IPv6 address in NetBox because this is your IPAM and you need it to update your DNS entries.

Why not Git? There are some limitations when putting your source of truth in Git:
  1. If you want to expose a web interface to allow an external team to request a change, it is more difficult to do it with Git than with a database. Out-of-the-box, NetBox provides a nice web interface and a permission system. You can also write your own web interface and interact with NetBox through its API.
  2. YAML files are more difficult to query in different ways. For example, looking for a free IP address is complex if they are scattered in multiple places.
In my opinion, in most cases, you are better off putting the source of truth in Git instead of NetBox. You get a lot of perks by doing that and you can still use NetBox as a read-only view, usable by other tools. We do that with an Ansible module. In the remaining cases, Git could still fit the bill. Read-only access control can be done through submodules. Pull requests can restrict write access: a bot can check the changes only modify allowed files before auto-merging. This still requires some Git knowledge, but many teams are now comfortable using Git, thanks to its ubiquity.

  1. Wikimedia manages its infrastructure with Puppet. They publish everything on GitHub. Creative Commons uses Salt. They also publish everything on GitHub. Thanks to them for doing that! I wish I could provide more real-life examples.
  2. Being able to customize the hierarchy is key to avoiding repetition in the data. For example, if switches are paired together, some data should be attached to them as a group and not duplicated on each of them. Tags can be used to partially work around this issue but you lose the hierarchical aspect.

14 November 2021

Russ Allbery: Review: The Last Graduate

Review: The Last Graduate, by Naomi Novik
Series: The Scholomance #2
Publisher: Del Rey
Copyright: 2021
ISBN: 0-593-12887-7
Format: Kindle
Pages: 388
This is a direct sequel to A Deadly Education, by which I mean it starts in the same minute at which A Deadly Education ends (and let me say how grateful I am for a sequel that doesn't drop days, months, or years between books). You do not want to read this series out of order. This book is also very difficult to review without spoiling either it or the previous book, so please bear with me if I'm elliptical in my ravings. Because The Last Graduate is so good. So good, not only as a piece of writing, but as a combination of two of my favorite tropes in fiction, one of which I can't talk about because of spoilers. I adored this book in a way that is not entirely rational. I will attempt a review below anyway, but if you liked the first book, just stop reading here and go read the second one. It's more of everything I loved in the first book except even better, it did some things I was expecting and some things I didn't expect at all, and it's just so ridiculously good. Just be aware that it has another final-line cliffhanger. The third book is coming in (hopefully) 2022. Novik handles the cliffhanger at the end of the previous book beautifully, which is worth noting because there were so many ways in which it could have gone poorly. One of the best things about this series is Novik's skill at writing El's relationship with her mother, even though her mother has not appeared in the series so far. El argues with her mother's voice in her head, tells stories about her, wonders what her mother would think of her classmates (or in some cases knows exactly what her mother would think of her classmates), and sometimes makes the explicit decision to not be her mother. The relationship has the sort of messy complexity, shared history, and underlying respect that many people experience in life but that I've rarely seen portrayed this well in a fantasy novel. Novik's presentation of that relationship works because El's voice is so strong. Within fifteen minutes of starting The Last Graduate, I was already muttering "I love this book" to myself, mostly because of how much I enjoy El's sarcastic, self-deprecating internal commentary. Novik strikes a balance between self-awareness, snark, humor, and real character growth that rivals Murderbot in its effectiveness of first-person perspective. It carries the story over a few weak points, such as a romance that didn't do much for me. Even when I didn't care about part of the plot, I cared about El's opinion of the plot and what it said about El's growing understanding of how to navigate the world. A Deadly Education was scene and character establishment. El insisted on being herself and following her own morals and social rules, and through that found some allies. The Last Graduate gives El enough breathing space to make more nuanced decisions. This is the part of growing up where one realizes the limitations of one's knee-jerk reactions and innate moral judgment. It's also when it becomes hard to trust success that is entirely outside of one's previous experience. El was not a kid who had friends, so she doesn't know what to do with them now that she has them. She's barely able to convince herself that they are friends. This is one of the two fictional tropes I mentioned, the one that I can talk about (at least briefly) without major spoilers. I have such a soft spot for stubborn, sarcastic, principled characters who refuse to play by the social rules that they think are required to make friends and who then find friends who like them for themselves. The moment when they start realizing this has happened and have no idea how to deal with it or how to be a person who has friends is one I will happily read over and over again. I enjoyed this book from the beginning, but there were two points when it grabbed my heart and I was all in. The first one is a huge spoiler that I can't talk about. The second was this paragraph:
[She] came round to me and put her arm around my waist and said under her breath, "Hey, she can be taught," with a tease in her voice that wobbled a little, and when I looked at her, her eyes were bright and wet, and I put my arm around her shoulders and hugged her.
You'll know it when you get there. The Last Graduate also gives the characters other than El and Orion more room, which is part of how it handles the chosen one trope. It's been obvious since early in the first book that Orion is a sort of chosen one, and it becomes obvious to the reader that El may be as well. But Novik doesn't let the plot focus only on them; instead, she uses that trope to look at how alliances and collective action happen, and how no one can carry the weight by themselves. As El learns more and gains power, she also becomes less central to the plot resolution and has to learn how to be less self-reliant. This is not a book where one character is trained to save the world. It's a book where she manages to enlist the support of a kick-ass project manager and becomes part of a team. Middle books of a trilogy are notoriously challenging. Often they're travel books: the first book sets up a problem, the second book moves the characters both physically and emotionally into a position to solve the problem, and the third book is the payoff. Travel books often sag. They can feel obligatory but somewhat boring, like a chore on the way to the third-book climax. The Last Graduate is not a travel book; it is, instead, a pivot book, which is my favorite form of trilogy. It's a book that rewrites the problem the first book set up, both resolving it and expanding the scope beyond what the reader had expected. This is immensely satisfying when done well, and Novik does it extremely well. This is not a flawless book. There are some pacing hiccups, there is a romance angle that didn't work for me (although it does arrive at some character insights that I thought were spot on), and although I think Novik is doing something interesting with the trope, there is a lot of chosen one power escalation happening here. It's not the sort of book that I can claim is perfectly written. Instead, it's the sort of book that uses some of my favorite plot elements and emotional beats in such an effective way and with such a memorable character that I do not have it in me to care about any of the flaws. Your mileage may therefore vary, but I would be happy to read books like this until the end of time. As mentioned above, The Last Graduate ends on another cliffhanger. This time I was worried that Novik might have ended the series there, since there's enough of an internal climax that I could imagine some literary fiction (which often seems allergic to endings) would have stopped here. Thankfully, Novik's web site says this is not the case. The next year is going to be a difficult wait. The third book of this series is going to be incredibly difficult to write, and I hope Novik is up to the challenge she's made for herself. But she handled the transition between the first and second book so well, and this book is so good that I have a lot of hope. If the third book is half as good as I'm hoping, this is going to be one of my favorite fantasy series of all time. Followed by an as-yet-untitled third book. Rating: 10 out of 10

Ruby Team: Ruby transition and packaging hints #2 - Gemfile.lock created by bundler/setup with Ruby 2.7 preventing successful test with Ruby 3.0

We currently face an issue in all packages requiring bunlder/setup and trying to run the tests for Ruby 2.7 and 3.0. The problem is that the first tests will create Gemfile.lock (or gemfile/gemfile-*.lock) using Ruby 2.7 and the next run for Ruby 3 will report e.g.:
Failure/Error: require 'bundler/setup' # Set up gems listed in the Gemfile.
Bundler::GemNotFound:
  Could not find racc-1.4.16 in any of the sources
or
/usr/share/rubygems-integration/all/gems/bundler-2.2.27/lib/bundler/definition.rb:496:in  materialize':
  Could not find rexml-3.2.3.1 in any of the sources (Bundler::GemNotFound)
Both bugs #996207 and #996302 are incarnations of this issue. The fix is as easy as making sure that the .lock files are removed before each run. This can be done in e.g. debian/ruby-tests.rake as very first task:
File.delete("Gemfile.lock") if File.exist?("Gemfile.lock")
In another case the .lock file is created by the tests in gemfiles/. While the first examples could actually be solved by gem2deb removing Gemfile.lock on its own, I m not quite sure how to handle the last case using packaging tools. The interesting part is that we will unlikely be confronted with this issue anytime soon again. It seems very specific to the Ruby 3.0 transition.

Update After talking to Antonio he added some code to gem2deb-test-runner to moving Gemfile.lock files out of the way. The tool already did this in an autopkgtest environment. In the upcoming 1.7 release it will do it in general and this will fix some more FTBFSes, e.g. #998497 and #996141 - originally reported against ruby-voight-kampff and ruby-bootsnap.

13 November 2021

Ruby Team: Ruby transition and packaging hints #1 - Adjusting Ruby version in commands

This is the first part of a series of short posts about issues that came up during the Ruby 3.0 transition and how to fix them. Hopefully more team members will join in and add their input. During the Ruby 3.0 transition there are essentially two different Ruby versions with two different binaries available, /usr/bin/ruby2.7 and /usr/bin/ruby3.0, while /usr/bin/ruby points to the current default version, which is Ruby 2.7. In some cases the tests shipped by the source packages will use shell commands to run scripts or Ruby code. It is imparative that in these cases the Ruby executable is not invoked by /usr/bin/ruby or ruby, because this will point to Ruby 2.7 only and fail if the tests are invoked with Ruby version 3. The fix is to rely on RbConfig.ruby which will point to the absolute pathname of the ruby command for the current Ruby environment, e.g.
cmd = "# RbConfig.ruby  ..."
This issue appeard for example in ruby-byebug and ruby-backports.

12 November 2021

Jonathan Dowland: Frictionless external backups with systemd

Here's a description of how my monthly external backups are managed at a technical level. I didn't realise I hadn't written this all down anywhere yet. What
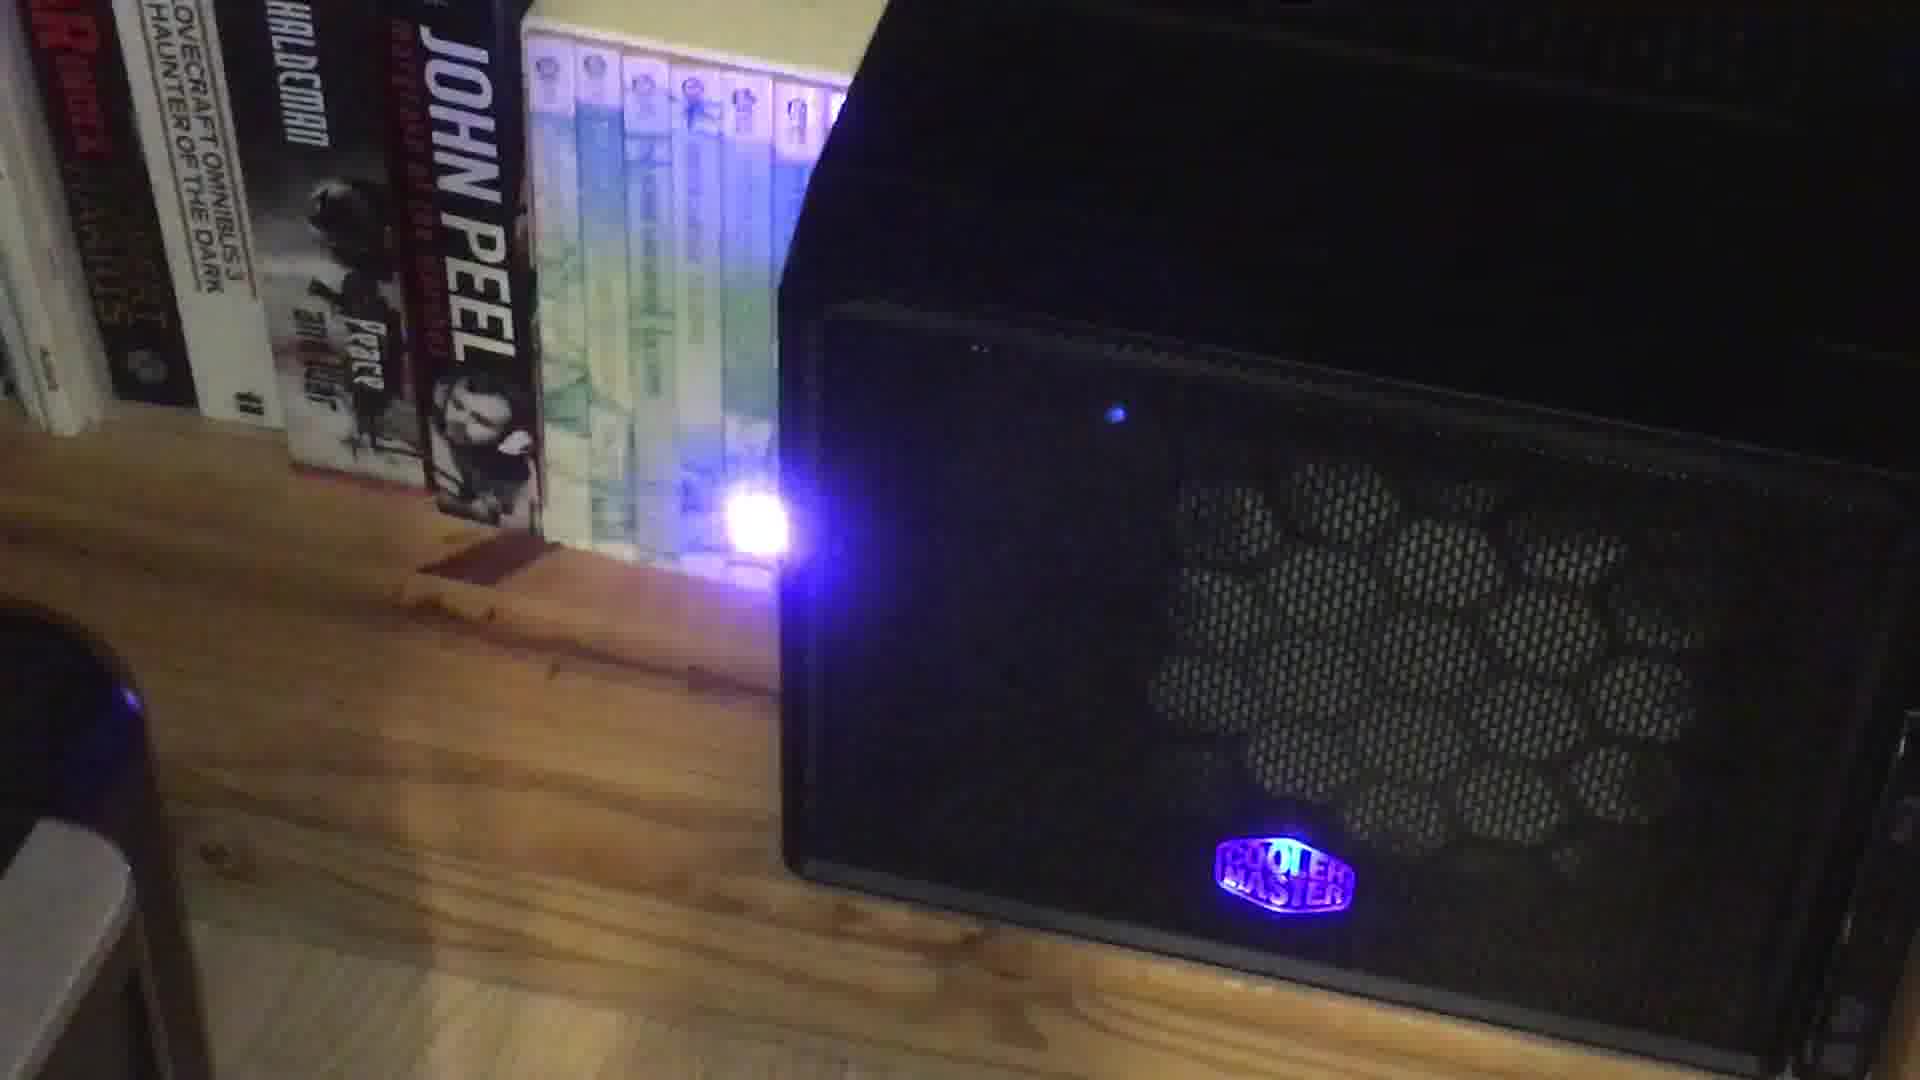
blinkenlights! blinkenlights!
I plug in one of two (prepared) external hard drives into my headless NAS. The NAS contains my primary data backup. A job automatically decrypts the encrypted filesystem on the drive, mounts it and synchronises the copy of my backup data on the drive from that on the NAS. Whilst this is going on, the blinkstick LED on the NAS switches to a colour to signal "in progress". When it's done, the light changes to green to signal "done" and I can remove it. If something goes wrong, it turns red and I get mail. Why I want a third-strand, off-site backup of my and my family's data in case of a disaster in our house. For it to be useful it has to be regular, so I needed to remove as much of the friction of performing the backup as possible. I use two drives alternately so that I don't have all my eggs in one basket in the window when I bring one of them home and perform the backup. How As much as possible I lean on systemd and its ability to trigger actions based on events.
  1. External drive is plugged in. systemd instantiates a corresponding device unit, named dev-disk-by\x2duuid-aaaaaaaa\x2daaaa\x2daaaa\x2daaaa\x2daaaaaaaaaaaa.device, where aaaa is the UUID of a partition on the device
  2. The backup job is a systemd service which has a WantedBy relationship on the device unit, so when the device appears, systemd starts the backup service.
  3. The backup service has Requires and After relationships on systemd-cryptsetup@extbackup.service, a service created by systemd's cryptsetup generator on start-up (but slightly customised, see below). The encrypted device is therefore unlocked.
  4. The backup service defines multiple start and stop commands with ExecStart and ExecStop. These are used to:
    1. set the blinkstick to the working colour (blue-ish)
    2. mount the now-decrypted filesystem
    3. get a lock on the backup repository (so nothing else writes to it) and synchronise the files
    4. unmount the filesystem
    5. set the blinkstick to the success colour (green)
  5. Finally, the systemd-cryptsetup@extbackup.service unit realises it is not required any more. It has been customised with StopWhenUnneeded=true1, so the encrypted filesystem is closed, ready for the drive to be removed.
  6. I notice the LED colour is green, remove the drive, and take it to its off-site home.
If anything goes wrong, all my custom systemd units have, as a matter of course,
OnFailure=status-email-user@%n.service blinkstick-fail.service
Preparing a new backup disk This is mostly just a standard dm-crypt/cryptsetup/LUKS encrypted device, on top of a standard partition on the underlying disk, with a normal filesystem sitting on top: Basically, the most common way to encrypt a drive in Linux. See places like the cryptsetup docs for how to set something like that up. The key things here are The backup service Here's the backup service unit definition in its entirety:
 [Unit]
 OnFailure=status-email-user@%n.service blinkstick-fail.service
 Requires=systemd-cryptsetup@extbackup.service backup.mount
 After=systemd-cryptsetup@extbackup.service backup.mount
 [Service]
 Type=oneshot
 ExecStart=/usr/local/bin/blinkstick --index 1 --limit 10 --set-color 33c280
 ExecStart=/bin/mount /extbackup
 ExecStart=/home/jon/bin/phobos-backup-monthly
 ExecStop=/bin/umount /extbackup
 ExecStop=/usr/local/bin/blinkstick --index 1 --limit 10 --set-color green
 [Install]
 WantedBy=dev-disk-by\x2duuid-aaaaaaaa\x2daaaa\x2daaaa\x2daaaa\x2daaaaaaaaaaaa.device
The dashes in the UUID in WantedBy= need to be encoded as \x2d and then the slashes from the path bit as dashes. Using dashes to encode slashes is possibly the single most frustrating systemd design decision. Issues Sadly (as detailed in Blinkenlights, part 2) there are 2 some frustrating limitations with trying to handle the mount (and unmount) of the filesystem in systemd-land, so instead, it's done using the traditional mount, umount and fstab. If you can point out any improvements to this approach, please let me know!

  1. I customized mine a while ago by copying the generated service file to a static file, but nowadays I think you could do systemd edit systemd-cryptsetup@extbackup.service to add the StopWhenUnneeded to an override file and not need the rest.
  2. or at least were. It's been a while since I revisited this part.

10 November 2021

Jonathan Dowland: LEGO Princess Castle-books

The set The set
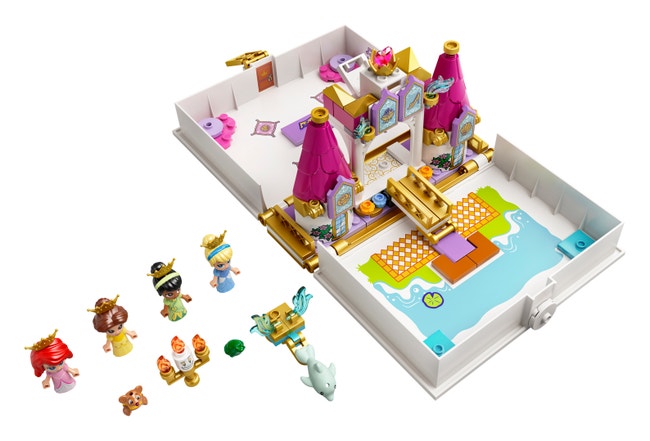
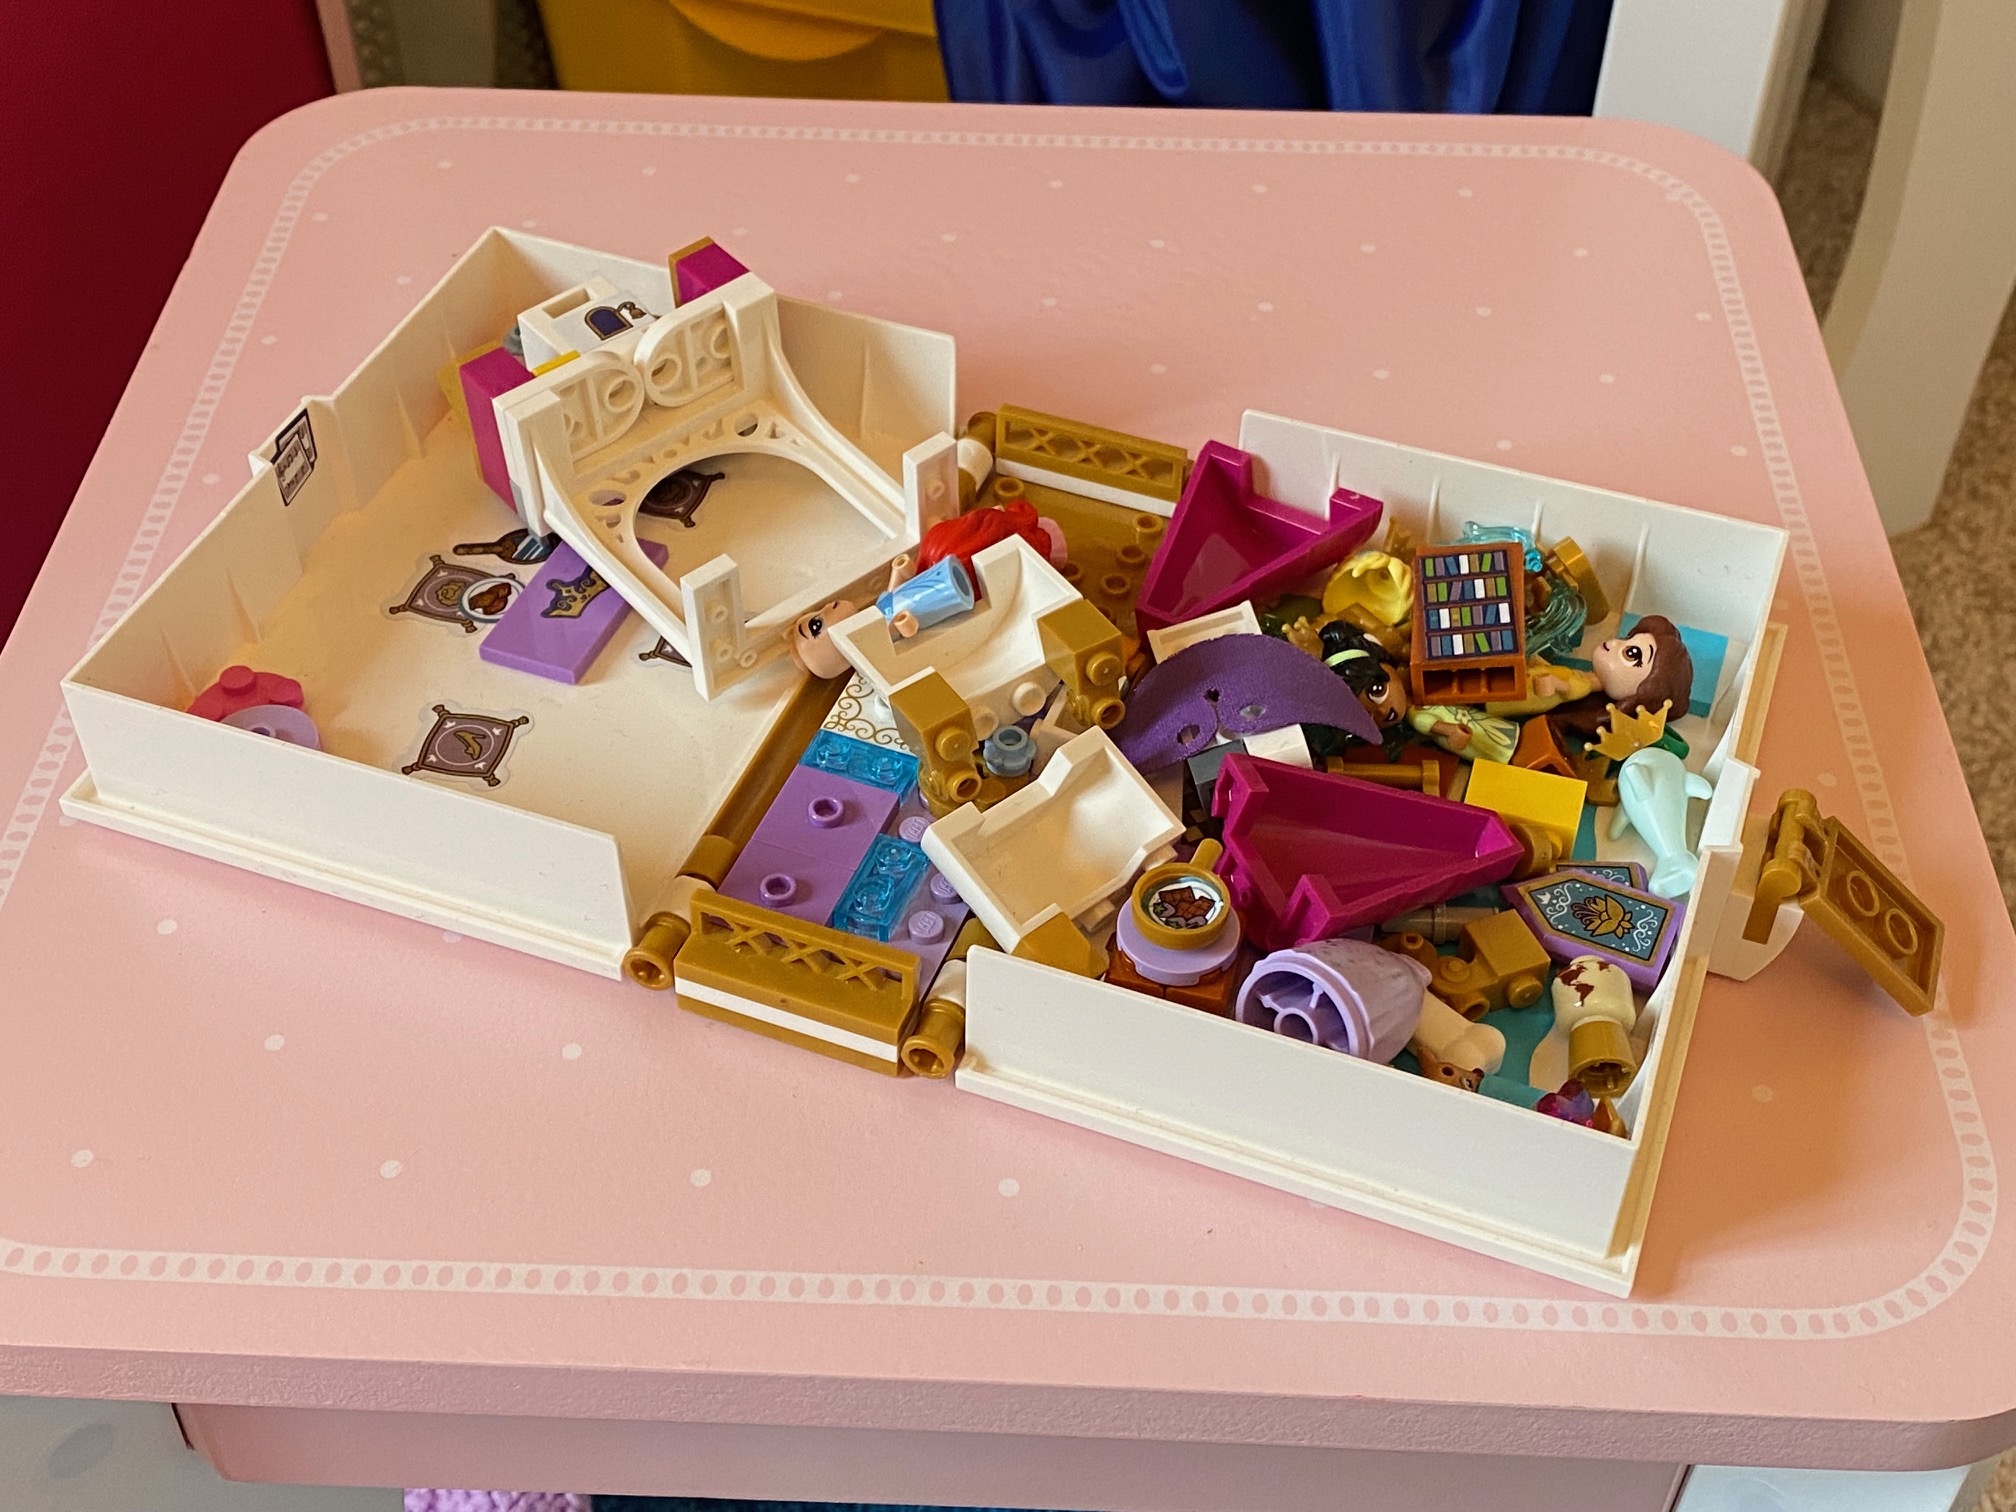
My eldest daughter and I visited a LEGO shop recently and I wanted to buy her a gift. The catch was that we were going to be flying on an airplane the next day, so I wanted to find something with the lowest risk of losing parts on the plane. We settled on Ariel, Belle, Cinderella and Tiana's Storybook Adventures which had a number of things going for it: It was reasonably priced at under 20, for the size of the set; it included four human minifigs (albeit in a sub-minifig size, some kind of munchkin size, but that did not seem to matter) and an assortment of animal accompaniments; but mostly, it folded up into a self-contained mock fairytail "book", and opened up into an enclosed "tray" play area, minimising the risk of losses on the flight.
The set in its resting state The set in its resting state
Lego have done a few of these styles of sets, all Disney princess themed, and it looks like they have a few more on their product roadmap. The newer ones incorporate a locking mechanism with a cute Lego key. I love the concept and think it should be extended to other themes/properties. I can imagine a Lego Star Wars-themed version with a little Death Star trench in the middle, or even an original IP like Classic Space, or Medieval.
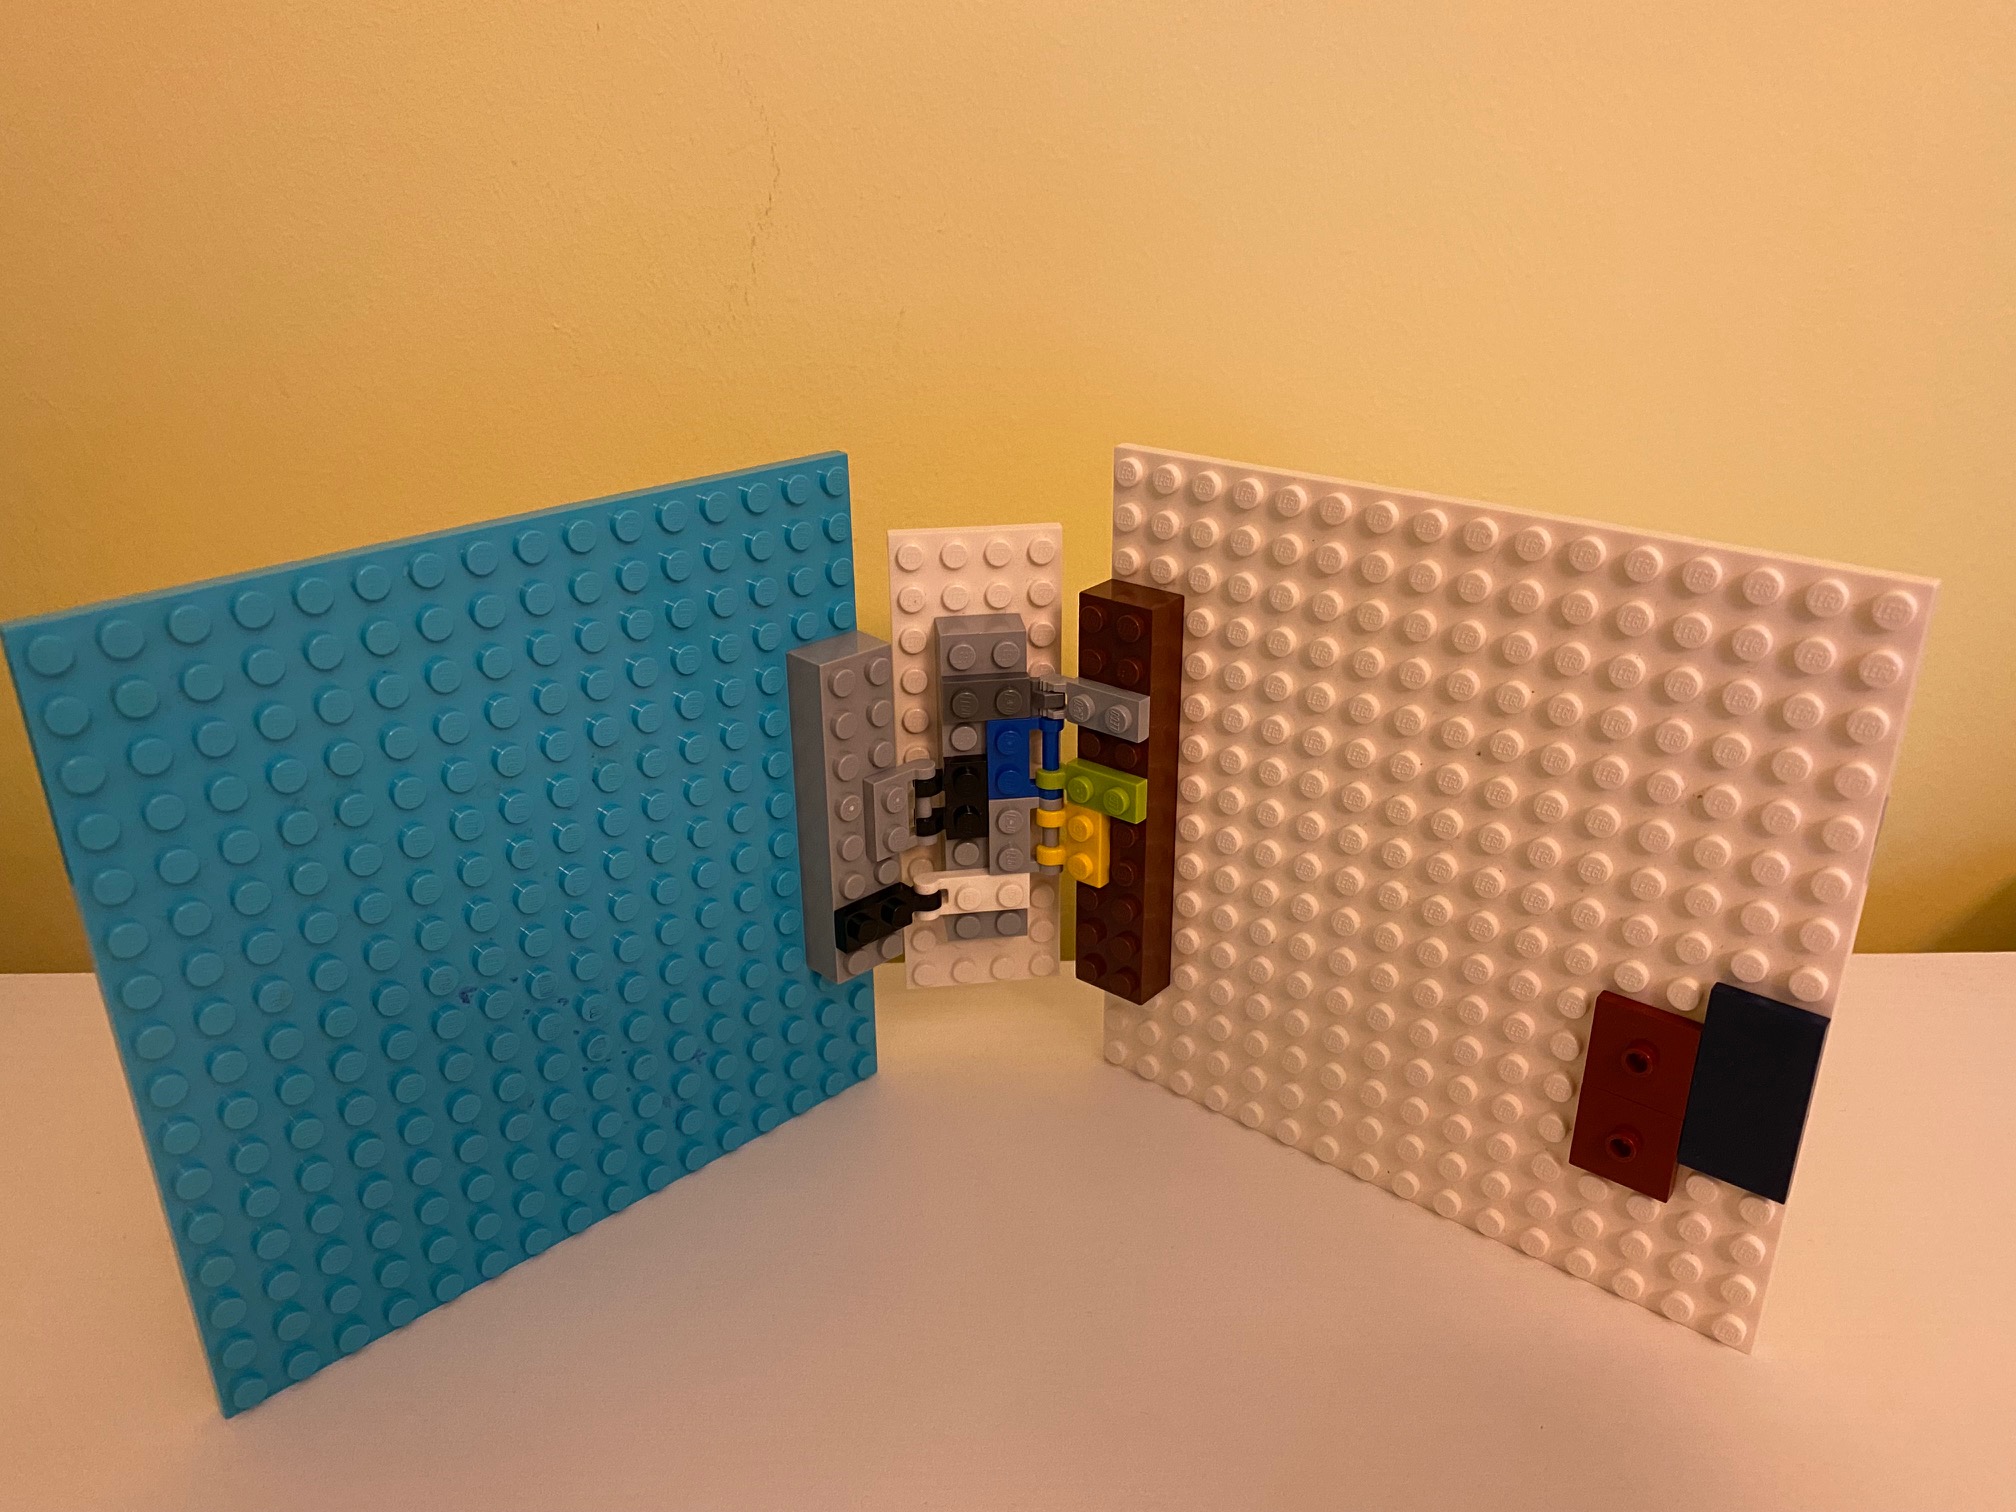
Exploring a DIY Lego book frame Exploring a DIY Lego book frame
I really liked the Book device which reminded me of hollow books as a child. The cover and spine pieces are bespoke Lego bricks made for purpose, but I thought you could create something similar with generic parts. Holly and I had a go at the concept with what bricks we had to hand. It's definitely viable (and you could do a lot better with a wider selection of bricks / more skilled builders) and it will be fun to pick something to try and build on the spine.

Craig Small: Changing Grafana Legends

I m not sure if I just can search Google properly, or this really is just not written down much, but I have had problems with Grafana Legends (I would call them the series labels). The issue is that Grafana queries Prometheus for a time series and you want to display multiple lines, but the time-series labels you get are just not quite right. A simple example is you might be using the black-box exporter to monitor an external TCP port and you would just like the port number separate to display. The default output would look like this:
probe_duration_seconds instance="example.net:5222",job="blackbox",module="xmpp_banner"  = 0.01
probe_duration_seconds instance="example.net:5269",job="blackbox",module="xmpp_banner"  = 0.01
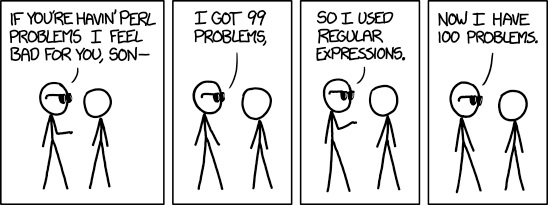
I can graph the number of seconds that it takes to probe the 5222 and 5269 TCP ports, but my graph legend is going to have the hostname, making it cluttered. I just want the legend to be the port numbers on Grafana. The answer is to use a Prometheus function called label_replace that takes an existing label, applies a regular expression, then puts the result into another label. That s right, regular expressions, and if you get them wrong then the label just doesn t appear.
Perl REGEX Problems courtesy of XKCD
The label_replace documentation is a bit terse, and in my opinion, the order of parameters is messed up, but after a few goes I had what I needed:
label_replace(probe_duration_seconds module="xmpp_banner" , "port", "$1", "instance", ".*:(.*)")
probe_duration_seconds instance="example.net:5222",job="blackbox",module="xmpp_banner",port="5222" 	0.001
probe_duration_seconds instance="example.net:5269",job="blackbox",module="xmpp_banner",port="5269" 	0.002
The response now has a new label (or field if you like) called port. So what is this function to our data coming from probe_duration_seconds? The function format is: label_replace(value, dst_label, replacement, src_label, regex) So the function does the following:
  1. Evaluate value, which is generally some sort of query such as probe_duration_seconds
  2. Find the required source label src_label, in this example is instance, in this case the values are example.net:5222 and example.net:5269
  3. Apply regular expression regex, for us its .*:(.*) That says skip everying before : then capture/store everything past : . The brackets mean copy what is after the colon and put it in match #1
  4. Make a new label specified in dst_label, for us this is port
  5. Whatever is in replacement goes into dst_label. For this example it is $1 which means match #1 in our regular expression in the label called port.
In short, the function captures everything after the colon in the instance label and puts that into a new label called port. It does this for each value that is returned into the first parameter. This means I can use the port in my Grafana graph Legend and it will show 5222 or 5269 respectively. I have made the Legend TCP port to give the below result, but I could have used port in Grafana Legend and made the result TCP $1 in the label_replace function to get the same result.
Grafana console showing the use of the label_replace function

9 November 2021

Joachim Breitner: How to audit an Internet Computer canister

I was recently called upon by Origyn to audit the source code of some of their Internet Computer canisters ( canisters are services or smart contracts on the Internet Computer), which were written in the Motoko programming language. Both the application model of the Internet Computer as well as Motoko bring with them their own particular pitfalls and possible sources for bugs. So given that I was involved in the creation of both, they reached out to me. In the course of that audit work I collected a list of things to watch out for, and general advice around them. Origyn generously allowed me to share that list here, in the hope that it will be helpful to the wider community.
Inter-canister calls The Internet Computer system provides inter-canister communication that follows the actor model: Inter-canister calls are implemented via two asynchronous messages, one to initiate the call, and one to return the response. Canisters process messages atomically (and roll back upon certain error conditions), but not complete calls. This makes programming with inter-canister calls error-prone. Possible common sources for bugs, vulnerabilities or simply unexpected behavior are:
  • Reading global state before issuing an inter-canister call, and assuming it to still hold when the call comes back.
  • Changing global state before issuing an inter-canister call, changing it again in the response handler, but assuming nothing else changes the state in between (reentrancy).
  • Changing global state before issuing an inter-canister call, and not handling failures correctly, e.g. when the code handling the callback rolls backs.
If you find such pattern in your code, you should analyze if a malicious party can trigger them, and assess the severity that effect These issues apply to all canisters, and are not Motoko-specific.

Rollbacks Even in the absence of inter-canister calls the behavior of rollbacks can be surprising. In particular, rejecting (i.e. throw) does not rollback state changes done before, while trapping (e.g. Debug.trap, assert , out of cycle conditions) does. Therefore, one should check all public update call entry points for unwanted state changes or unwanted rollbacks. In particular, look for methods (or rather, messages, i.e. the code between commit points) where a state change is followed by a throw. This issues apply to all canisters, and are not Motoko-specific, although other CDKs may not turn exceptions into rejects (which don t roll back).

Talking to malicious canisters Talking to untrustworthy canisters can be risky, for the following (likely incomplete) reasons:
  • The other canister can withhold a response. Although the bidirectional messaging paradigm of the Internet Computer was designed to guarantee a response eventually, the other party can busy-loop for as long as they are willing to pay for before responding. Worse, there are ways to deadlock a canister.
  • The other canister can respond with invalidly encoded Candid. This will cause a Motoko-implemented canister to trap in the reply handler, with no easy way to recover. Other CDKs may give you better ways to handle invalid Candid, but even then you will have to worry about Candid cycle bombs that will cause your reply handler to trap.
Many canisters do not even do inter-canister calls, or only call other trustwothy canisters. For the others, the impact of this needs to be carefully assessed.

Canister upgrade: overview For most services it is crucial that canisters can be upgraded reliably. This can be broken down into the following aspects:
  1. Can the canister be upgraded at all?
  2. Will the canister upgrade retain all data?
  3. Can the canister be upgraded promptly?
  4. Is three a recovery plan for when upgrading is not possible?

Canister upgradeability A canister that traps, for whatever reason, in its canister_preupgrade system method is no longer upgradeable. This is a major risk. The canister_preupgrade method of a Motoko canister consists of the developer-written code in any system func preupgrade() block, followed by the system-generated code that serializes the content of any stable var into a binary format, and then copies that to stable memory. Since the Motoko-internal serialization code will first serialize into a scratch space in the main heap, and then copy that to stable memory, canisters with more than 2GB of live data will likely be unupgradeable. But this is unlikely the first limit: The system imposes an instruction limit on upgrading a canister (spanning both canister_preupgrade and canister_postupgrade). This limit is a subnet configuration value, and sepearate (and likely higher) than the normal per-message limit, and not easily determined. If the canister s live data becomes too large to be serialized within this limit, the canister becomes non-upgradeable. This risk cannot be eliminated completely, as long as Motoko and Stable Variables are used. It can be mitigated by appropriate load testing: Install a canister, fill it up with live data, and exercise the upgrade. If this succeeds with a live data set exceeding the expected amount of data by a margin, this risk is probably acceptable. Bonus points for adding functionality that will prevent the canister s live data to increase above a certain size. If this testing is to be done on a local replica, extra care needs to be taken to make sure the local replica actually performs instruction counting and has the same resource limits as the production subnet. An alternative mitigation is to avoid canister_pre_upgrade as much as possible. This means no use of stable var (or restricted to small, fixed-size configuration data). All other data could be
  • mirrored off the canister (possibly off chain), and manually re-hydrated after an upgrade.
  • stored in stable memory manually, during each update call, using the ExperimentalStableMemory API. While this matches what high-assurance Rust canisters (e.g. the Internet Identity) do, This requires manual binary encoding of the data, and is marked experimental, so I cannot recommend this at the moment.
  • not put into a Motoko canister until Motoko has a scalable solution for stable variable (for example keeping them in stable memory permanently, with smart caching in main memory, and thus obliterating the need for pre-upgrade code.)

Data retention on upgrades Obviously, all live data ought to be retained during upgrades. Motoko automatically ensures this for stable var data. But often canisters want to work with their data in a different format (e.g. in objects that are not shared and thus cannot be put in stable vars, such as HashMap or Buffer objects), and thus may follow following idiom:
stable var fooStable =  ;
var foo = fooFromStable(fooStable);
system func preupgrade()   fooStable := fooToStable(foo);  )
system func postupgrade()   fooStable := (empty);  )
In this case, it is important to check that
  • All non-stable global vars, or global lets with mutable values, have a stable companion.
  • The assignments to foo and fooStable are not forgotten.
  • The fooToStable and fooFromStable form bijections.
An example would be HashMaps stored as arrays via Iter.toArray( .entries()) and HashMap.fromIter( .vals()). It is worth pointiong out that a code view will only look at a single version of the code, but cannot check whether code changes will preserve data on upgrade. This can easily go wrong if the names and types of stable variables are changed in incompatible way. The upgrade may fail loudly in this cases, but in bad cases, the upgrade may even succeed, losing data along the way. This risk needs to be mitigated by thorough testing, and possibly backups (see below).

Prompt upgrades Motoko and Rust canisters cannot be safely upgraded when they are still waiting for responses to inter-canister calls (the callback would eventually reach the new instance, and because of infelicities of the IC s System API, could possibly call arbitrary internal functions). Therefore, the canister needs to be stopped before upgrading, and started again. If the inter-canister calls take a long time, this mean that upgrading may take a long time, which may be undesirable. Again, this risk is reduced if all calls are made to trustworthy canisters, and elevated when possibly untrustworthy canisters are called, directly or indirectly.

Backup and recovery Because of the above risk around upgrades it is advisable to have a disaster recovery strategy. This could involve off-chain backups of all relevant data, so that it is possible to reinstall (not upgrade) the canister and re-upload all data. Note that reinstall has the same issue as upgrade described above in prompt upgrades : It ought to be stopped first to be safe. Note that the instruction limit for messages, as well as the message size limit, limit the amount of data returned. If the canister needs to hold more data than that, the backup query method might have to return chunks or deltas, with all the extra complexity that entails, e.g. state changes between downloading chunks. If large data load testing is performed (as Irecommend anyways to test upgradeability), one can test whether the backup query method works within the resource limits.

Time is not strictly monotonic The timestamps for current time that the Internet Computer provides to its canisters is guaranteed to be monotonic, but not strictly monotonic. It can return the same values, even in the same messages, as long as they are processed in the same block. It should therefore not be used to detect happens-before relations. Instead of using and comparing time stamps to check whether Y has been performed after X happened last, introduce an explicit var y_done : Bool state, which is set to False by X and then to True by Y. When things become more complex, it will be easier to model that state via an enumeration with speaking tag names, and update this state machine along the way. Another solution to this problem is to introduce a var v : Nat counter that you bump in every update method, and after each await. Now v is your canister s state counter, and can be used like a timestamp in many ways. While we are talking about time: The system time (typically) changes across an await. So if you do let now = Time.now() and then await, the value in now may no longer be what you want.

Wrapping arithmetic The Nat64 data type, and the other fixed-width numeric types provide opt-in wrapping arithmetic (e.g. +%, fromIntWrap). Unless explicitly required by the current application, this should be avoided, as usually a too large or negatie value is a serious, unrecoverable logic error, and trapping is the best one can do.

Cycle balance drain attacks Because of the IC s canister pays model, all canisters are prone to DoS attacks by draining their cycle balance, and this risk needs to be taken into account. The most elementary mitigation strategy is to monitor the cycle balance of canisters and keep it far from the (configurable) freezing threshold. On the raw IC-level, further mitigation strategies are possible:
  • If all update calls are authenticated, perform this authentication as quickly as possible, possibly before decoding the caller s argument. This way, a cycle drain attack by an unauthenticated attacker is less effective (but still possible).
  • Additionally, implementing the canister_inspect_message system method allows the above checks to be performed before the message even is accepted by the Internet Computer. But it does not defend against inter-canister messages and is therefore not a complete solution.
  • If an attack from an authenticated user (e.g. a stakeholder) is to be expected, the above methods are not effective, and an effective defense might require relatively involved additional program logic (e.g. per-caller statistics) to detect such an attack, and react (e.g. rate-limiting).
  • Such defenses are pointless if there is only a single method where they do not apply (e.g. an unauthenticated user registration method). If the application is inherently attackable this way, it is not worth the bother to raise defenses for other methods.
Related: A justification why the Internet Identity does not use canister_inspect_message) A motoko-implemented canister currently cannot perform most of these defenses: Argument decoding happens unconditionally before any user code that may reject a message based on the caller, and canister_inspect_message is not supported. Furthermore, Candid decoding is not very cycle defensive, and one should assume that it is possible to construct Candid messages that require many instructions to decode, even for simple argument type signatures. The conclusion for the audited canisters is to rely on monitoring to keep the cycle blance up, even during an attack, if the expense can be born, and maybe pray for IC-level DoS protections to kick in.

Large data attacks Another DoS attack vector exists if public methods allow untrustworthy users to send data of unlimited size that is persisted in the canister memory. Because of the translation of async-await code into multiple message handlers, this applies not only to data that is obviously stored in global state, but also local data that is live across an await point. The effectiveness of such attacks is limited by the Internet Computer s message size limit, which is in the order of a few megabytes, but many of those also add up. The problem becomes much worse if a method has an argument type that allows a Candid space bomb: It is possible to encode very large vectors with all values null in Candid, so if any method has an argument of type [Null] or [?t], a small message will expand to a large value in the Motoko heap. Other types to watch out:
  • Nat and Int: This is an unbounded natural number, and thus can be arbitrarily large. The Motoko representation will however not be much larger than the Candid encoding (so this does not qualify as a space bomb).
It is still advisable to check if the number is reasonable in size before storing it or doing an await. For example, when it denotes an index in an array, throw early if it exceeds the size of the array; if it denotes a token amount to transfer, check it against the available balance, if it denotes time, check it against reasonable bounds.
  • Principal: A Principal is effectively a Blob. The Interface specification says that principals are at most 29 bytes in length, but the Motoko Candid decoder does not check that currently (fixed in the next version of Motoko). Until then, a Principal passed as an argument can be large (the principal in msg.caller is system-provided and thus safe). If you cannot wait for the fix to reach you, manually check the size of the princial (via Principal.toBlob) before doing the await.

Shadowing of msg or caller Don t use the same name for the message context of the enclosing actor and the methods of the canister: It is dangerous to write shared(msg) actor, because now msg is in scope across all public methods. As long as these also use public shared(msg) func , and thus shadow the outer msg, it is correct, but it if one accidentially omits or mis-types the msg, no compiler error would occur, but suddenly msg.caller would now be the original controller, likely defeating an important authorization step. Instead, write shared(init_msg) actor or shared( caller = controller ) actor to avoid using msg.

Conclusion If you write a serious canister, whether in Motoko or not, it is worth to go through the code and watch out for these patterns. Or better, have someone else review your code, as it may be hard to spot issues in your own code. Unfortunately, such a list is never complete, and there are surely more ways to screw up your code in addition to all the non-IC-specific ways in which code can be wrong. Still, things get done out there, so best of luck!

8 November 2021

Enrico Zini: An educational debugging session

This morning we realised that a test case failed on Fedora 34 only (the link is in Italian) and we set to debugging. The initial analysis This is the initial reproducer:
$ PROJ_DEBUG=3 python setup.py test
test_recipe (tests.test_litota3.TestLITOTA3NordArkimetIFS) ... pj_open_lib(proj.db): call fopen(/lib64/../share/proj/proj.db) - succeeded
proj_create: Open of /lib64/../share/proj/proj.db failed
pj_open_lib(proj.db): call fopen(/lib64/../share/proj/proj.db) - succeeded
proj_create: no database context specified
Cannot instantiate source_crs
EXCEPTION in py_coast(): ProjP: cannot create crs to crs from [EPSG:4326] to [+proj=merc +lon_0=0 +k=1 +x_0=0 +y_0=0 +ellps=WGS84 +datum=WGS84 +over +units=m +no_defs]
ERROR
Note that opening /lib64/../share/proj/proj.db sometimes succeeds, sometimes fails. It's some kind of Schr dinger path, which works or not depending on how you observe it:
# ls -lad /lib64
lrwxrwxrwx 1 1000 1000 9 Jan 26  2021 /lib64 -> usr/lib64
$ ls -la /lib64/../share/proj/proj.db
-rw-r--r-- 1 root root 8925184 Jan 28  2021 /lib64/../share/proj/proj.db
$ cd /lib64/../share/proj/
$ cd /lib64
$ cd ..
$ cd share
-bash: cd: share: No such file or directory
And indeed, stat(2) finds it, and sqlite doesn't (the file is a sqlite database):
$ stat /lib64/../share/proj/proj.db
  File: /lib64/../share/proj/proj.db
  Size: 8925184     Blocks: 17432      IO Block: 4096   regular file
Device: 33h/51d Inode: 56907       Links: 1
Access: (0644/-rw-r--r--)  Uid: (    0/    root)   Gid: (    0/    root)
Access: 2021-11-08 14:09:12.334350779 +0100
Modify: 2021-01-28 05:38:11.000000000 +0100
Change: 2021-11-08 13:42:51.758874327 +0100
 Birth: 2021-11-08 13:42:51.710874051 +0100
$ sqlite3 /lib64/../share/proj/proj.db
Error: unable to open database "/lib64/../share/proj/proj.db": unable to open database file
A minimal reproducer Later on we started stripping layers of code towards a minimal reproducer: here it is. It works or doesn't work depending on whether proj is linked explicitly, or via MagPlus:
$ cat tc.cc
#include <magics/ProjP.h>
int main()  
    magics::ProjP p("EPSG:4326", "+proj=merc +lon_0=0 +k=1 +x_0=0 +y_0=0 +ellps=WGS84 +datum=WGS84 +over +units=m +no_defs");
    return 0;
 
$ g++ -o tc  tc.cc -I/usr/include/magics  -lMagPlus
$ ./tc
proj_create: Open of /lib64/../share/proj/proj.db failed
proj_create: no database context specified
terminate called after throwing an instance of 'magics::MagicsException'
  what():  ProjP: cannot create crs to crs from [EPSG:4326] to [+proj=merc +lon_0=0 +k=1 +x_0=0 +y_0=0 +ellps=WGS84 +datum=WGS84 +over +units=m +no_defs]
Aborted (core dumped)
$ g++ -o tc  tc.cc -I/usr/include/magics -lproj  -lMagPlus
$ ./tc
What is going on here? A difference between the two is the path used to link to libproj.so:
$ ldd ./tc   grep proj
    libproj.so.19 => /lib64/libproj.so.19 (0x00007fd4919fb000)
$ g++ -o tc  tc.cc -I/usr/include/magics   -lMagPlus
$ ldd ./tc   grep proj
    libproj.so.19 => /lib64/../lib64/libproj.so.19 (0x00007f6d1051b000)
Common sense screams that this should not matter, but we chased an intuition and found that one of the ways proj looks for its database is relative to its shared library. Indeed, gdb in hand, that dladdr call returns /lib64/../lib64/libproj.so.19. From /lib64/../lib64/libproj.so.19, proj strips two paths from the end, presumably to pass from something like /something/usr/lib/libproj.so to /something/usr. So, dladdr returns /lib64/../lib64/libproj.so.19, which becomes /lib64/../, which becomes /lib64/../share/proj/proj.db, which exists on the file system and is used as a path to the database. But depending how you look at it, that path might or might not be valid: it passes the stat(2) check that stops the lookup for candidate paths, but sqlite is unable to open it. Why does the other path work? By linking libproj.so in the other way, dladdr returns /lib64/libproj.so.19, which becomes /share/proj/proj.db, which doesn't exist, which triggers a fallback to a PROJ_LIB constant defined at compile time, which is a path that works no matter how you look at it. Why that weird path with libMagPlus? To complete the picture, we found that libMagPlus.so is packaged with a rpath set, which is known to cause trouble
# readelf -d /usr/lib64/libMagPlus.so grep rpath
 0x000000000000000f (RPATH)              Library rpath: [$ORIGIN/../lib64]
The workaround We found that one can set PROJ_LIB in the environment to override the normal proj database lookup. Building on that, we came up with a simple way to override it on Fedora 34 only:
    if distro is not None and distro.linux_distribution()[:2] == ("Fedora", "34") and "PROJ_LIB" not in os.environ:
         self.env_overrides["PROJ_LIB"] = "/usr/share/proj/"
This has been a most edifying and educational debugging session, with only the necessary modicum of curses and swearwords. Working in a team of excellent people really helps.

6 November 2021

Reproducible Builds: Reproducible Builds in October 2021

Welcome to the October 2021 report from the Reproducible Builds project!
This month Samanta Navarro posted to the oss-security security mailing on a novel category of exploit in the .tar archive format, where a single .tar file contains different contents depending on the tar utility being used. Naturally, this has consequences for reproducible builds as Samanta goes onto reply:

Arch Linux uses libarchive (bsdtar) in its build environment. The default tar program installed is GNU tar. It is possible to create a source distribution which leads to different files seen by the build environment than compared to a careful reviewer and other Linux distributions.
Samanta notes that addressing the tar utilities themselves will not be a sufficient fix:
I have submitted bug reports and patches to some projects but eventually I had to conclude that the problem itself cannot be fixed by these implementations alone. The best choice for these tools would be to only allow archives which are fully compatible to standards but this in turn would render a lot of archives broken.
Reproducible builds, with its twin ideas of reaching consensus on the build outputs as well as precisely recording and describing the build environment, would help address this problem at a higher level.
Codethink announced that they had achieved ISO-26262 ASIL D Tool Certification, a way of determining specific safety standards for software. Codethink used open source tooling to achieve this, but they also leverage:
Reproducibility, repeatability and traceability of builds, drawing heavily on best-practices championed by the Reproducible Builds project.

Elsewhere on the internet, according to a comment on Hacker News, Microsoft are now comparing NPM Javascript packages with their original source repositories:
I got a PR in my repository a few days ago leading back to a team trying to make it easier for packages to be reproducible from source.

Lastly, Martin Monperrus started an interesting thread on our mailing list about Github, specifically that their autogenerated release tarballs are not deterministic . The thread generated a significant number of replies that are worth reading.

Events and presentations

Community news On our mailing list this month:
There were quite a few changes to the Reproducible Builds website and documentation this month as well, including Feng Chai updating some links on our publications page [ ] and marco updated our project metadata around the Bitcoin Core building guide [ ].
Lastly, we ran another productive meeting on IRC during October. A full set of notes from the meeting is available to view.

Distribution work Qubes was heavily featured in the latest edition of Linux Weekly News, and a significant section was dedicated to discussing reproducibility. For example, it was mentioned that the Qubes project has been working on incorporating reproducible builds into its continuous integration (CI) infrastructure . But the LWN article goes on to describe that:
The current goal is to be able to build the Qubes OS Debian templates solely from packages that can be built reproducibly. Templates in Qubes OS are VM images that can be used to start an application qube quickly based on the template. The qube will have read-only access to the root filesystem of the template, so that the same root filesystem can be shared with multiple application qubes. There are official templates for several variants of both Fedora and Debian, as well as community maintained templates for several other distributions.
You can view the whole article on LWN, and Fr d ric also published a lengthy summary about their work on reproducible builds in Qubes as well for those wishing to learn more.
In Debian this month, 133 reviews of Debian packages were added, 81 were updated and 24 were removed this month, adding to Debian s ever-growing knowledge about identified issues. A number of issues were categorised and added by Chris Lamb and Vagrant Cascadian too [ ][ ][ ]. In addition, work on alternative snapshot service has made progress by Fr d ric Pierret and Holger Levsen this month, including moving from the existing host (snapshot.notset.fr) to snapshot.reproducible-builds.org (more info) thanks to OSUOSL for the machine and hosting and Debian for the disks.
Finally, Bernhard M. Wiedemann posted his monthly reproducible builds status report.

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb made the following changes, including preparing and uploading versions 186, 187, 188 and 189 to Debian
  • New features:
    • Add support for Python Sphinx inventory files (usually named objects.inv on-disk). [ ]
    • Add support for comparing .pyc files. Thanks to Sergei Trofimovich for the inspiration. [ ]
    • Try some alternative suffixes (e.g. .py) to support distributions that strip or retain them. [ ][ ]
  • Bug fixes:
    • Fix Python decompilation tests under Python 3.10+ [ ] and for Python 3.7 [ ].
    • Don t raise a traceback if we cannot unmarshal Python bytecode. This is in order to support Python 3.7 failing to load .pyc files generated with newer versions of Python. [ ]
    • Skip Python bytecode testing where we do not have an expected diff. [ ]
  • Codebase improvements:
    • Use our file_version_is_lt utility instead of accepting both versions of uImage expected diff. [ ]
    • Split out a custom call to assert_diff for a .startswith equivalent. [ ]
    • Use skipif instead of manual conditionals in some tests. [ ]
In addition, Jelle van der Waa added external tool references for Arch Linux for ocamlobjinfo, openssl and ffmpeg [ ][ ][ ] and added Arch Linux as a Continuous Integration (CI) test target. [ ] and Vagrant Cascadian updated the testsuite to skip Python bytecode comparisons when file(1) is older than 5.39. [ ] as well as added external tool references for the Guix distribution for dumppdf and ppudump. [ ][ ]. Vagrant Cascadian also updated the diffoscope package in GNU Guix [ ][ ]. Lastly, Guangyuan Yang updated the FreeBSD package name on the website [ ], Mattia Rizzolo made a change to override a new Lintian warning due to the new test files [ ], Roland Clobus added support to detect and log if the GNU_BUILD_ID field in an ELF binary been modified [ ], Sandro J ckel updated a number of helpful links on the website [ ] and Sergei Trofimovich made the uImage test output support file() version 5.41 [ ].

reprotest reprotest is the Reproducible Build s project end-user tool to build same source code twice in widely differing environments, checking the binaries produced by the builds for any differences. This month, reprotest version 0.7.18 was uploaded to Debian unstable by Holger Levsen, which also included a change by Holger to clarify that Python 3.9 is used nowadays [ ], but it also included two changes by Vasyl Gello to implement realistic CPU architecture shuffling [ ] and to log the selected variations when the verbosity is configured at a sufficiently high level [ ]. Finally, Vagrant Cascadian updated reprotest to version 0.7.18 in GNU Guix.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix unreproducible packages. We try to send all of our patches upstream where appropriate. We authored a large number of such patches this month, including:

Testing framework The Reproducible Builds project runs a testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
  • Holger Levsen:
    • Debian-related changes:
      • Incorporate a fix from bremner into builtin-pho related to binary-NMUs. [ ]
      • Keep bullseye environments around longer, in an attempt to fix a Jenkins issue. [ ]
      • Improve the documentation of buildinfos.debian.net. [ ]
      • Improve documentation for the builtin-pho setup. [ ][ ]
    • OpenWrt-related changes:
      • Also use -j1 for better debugging. [ ]
      • Document that that Python 3.x is now used. [ ]
      • Enable further debugging for the toolchain build. [ ]
    • New snapshot.reproducible-builds.org service:
      • Actually add new node. [ ][ ]
      • Install xfsprogs on snapshot.reproducible-builds.org. [ ]
      • Create account for fpierret on new node. [ ]
      • Run node_health_check job on new node too. [ ]
  • Mattia Rizzolo:
    • Debian-related changes:
      • Handle schroot errors when invoking diffoscope instead of masking them. [ ][ ]
      • Declare and define some variables separately to avoid masking the subshell return code. [ ]
      • Fix variable name. [ ]
      • Improve log reporting. [ ]
      • Execute apt-get update with the -q argument to get more decent logs. [ ]
      • Set the Debian HTTP mirror and proxy for snapshot.reproducible-builds.org. [ ]
      • Install the libarchive-tools package (instead of bsdtar) when updating Jenkins nodes. [ ]
    • Be stricter about errors when starting the node agent [ ] and don t overwrite NODE_NAME so that we can expect Jenkins to properly set for us [ ].
    • Explicitly warn if the NODE_NAME is not a fully-qualified domain name (FQDN). [ ]
    • Document whether a node runs in the future. [ ]
    • Disable postgresql_autodoc as it not available in bullseye. [ ]
    • Don t be so eager when deleting schroot internals, call to schroot -e to terminate the schroots instead. [ ]
    • Only consider schroot underlays for deletion that are over a month old. [ ][ ]
    • Only try to unmount /proc if it s actually mounted. [ ]
    • Move the db_backup task to its own Jenkins job. [ ]
Lastly, Vasyl Gello added usage information to the reproducible_build.sh script [ ].

Contributing If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

5 November 2021

Jonathan Dowland: 25 things I would like to 3D print

Last year I started collecting ideas of things I would like to 3D print one day, on Twitter. Twitter is fundamentally ephemeral, so I'll collect it here instead. I got up to 14 items on Twitter, and now I'm up to 25. I don't own a 3D printer, but I have access to one at the work office. Perhaps this list is my subconcious trying to convince me to buy one. What am I missing? What else should I be thinking of printing? Let me know!
  1. Some kind of 45 leaning prong to dry bottles and flasks on
  2. A tea tray and coasters
  3. a replacement prop arm/foot for my computer keyboard (something like this but for the Lenovo Ultranav)
  4. some attempted representation of Borges Library of Babel, a la @jwz The Library of Babel, again
  5. an exploration of the geometry of Susanna Clarke s Piranesi
  6. further iterations of my castle
  7. Small tins to keep loose-leaf tea in
  8. Who am I kidding, bound to be a map from DOOM. E1M1 perhaps, or something more regular (MAP07? E2M8?) See also this amazing print of Quake 3: Arena's "Camping Grounds"
  9. replacement bits for kids toy sets, e.g. a bolt with long shank from Early Learning Centre Build It Deluxe Set, without all 4 of which you can't build much of anything
  10. A stand for a decorative Christmas bauble (kid's hand print on it) A roll of cellotape works pretty well in the mean time
  11. DIY bits-and-bobs sorter/storage (nuts and bolts etc)
  12. A space ship from Elite/Frontier. Probably a Cobra mk3 or maybe a Viper mk2. In a glow-in-the-dark PLA which i d overpaint with gunmetal except for the fuselage
  13. A watch stand/holder/storage thing Except it would look nicer in wood (And I m more inclined to get rid of all but one watch instead)
  14. Little tabbed 7 dividers for vinyl records, with A-Z cut into the tabs 12 ones might be a stretch (something like this)
  15. A low-profile custom trackpoint cover like the ones by SaotoTech (e.g.)
  16. A vinyl record. (Not sure that any 3D printer I would have access to would have the necessary resolution. I haven't done any research yet.)
  17. A free-standing inclined vinyl record display stand (e.g.)
  18. A "Settlers of Catan" set. I've got the travel edition which is great but it would be nicer to have a larger-sized set. There are some things I really like about the travel set that the full-size set lacks; so designing and printing a larger set myself could incorporate them. Also I don't feel inclined to buy the full-size set for 50 or so to end up with essentially the same game I already bought. No doubt I'd spent at least that much in PLA.
  19. Little kids trinkets. Pacman ghosts, that sort-of thing. Whatever my daughters come up with next.
  20. Lego storage/sorters.
  21. Some kind of lenticular picture. Perhaps a gift or Christmas card combined in one.
  22. A bracket to install a Gotek drive in my Amiga 500 (e.g.). I've managed without but the fit isn't great.
  23. An attempt at using the 3D printer for 2D drawing. I would never get the same kind of quality results you can get from a proper plotter, but still Take a look at some proper plotter art!
  24. Garden decorations. I like the idea of porous geometric shapes that you can plant mosses or ferns into, but also things which might be taken over and "used" by nature in ways I hadn't thought of.
  25. Floor plans / 3D plans of my house (including variations if I remodelled)

Jonathan Dowland: Mastodon again

I've been an occasional Mastodon user for (apparently) four years. I experimented with running my own instance for a while before giving that up, then I shopped around for an interesting little instance and settled on one, which was lovely until the maintainer decided (quite reasonably) it wasn't worth the trouble any more and turned it off. So I'm in need of a new instance! The first account I had was @Jmtd@mastodon.cloud, but that instance was too busy for my liking. I'd like to find something with small but vibrant local traffic, ideally matching to my interests. In fact one of the problems with my last instance1 was it was too quiet, and the local timeline was mostly empty. So something between "empty" and "overwhelmingly busy" as mastodon.cloud is, or was. Recommendations welcome! I'd set @jmtd@mastodon.cloud to forward to my instance for most of the last four years. I've turned that off now, so I am (at least temporarily) back to that instance. That's got me thinking: perhaps it's less onerous to run a local instance that only forwards, and to use that as a sort-of "permalink", allowing me to migrate from real instance-to-instance when required, but giving me a Mastodon "perma-link". Something to look at. (It's also worth considering that you should back up the list of accounts you are following off whichever instance you are on. I'm starting again with almost a clean slate.)

  1. I'm deliberately omitting the name of my last instance to give the former maintainer a break.

Reproducible Builds (diffoscope): diffoscope 190 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 190. This version includes the following changes:
[ Chris Lamb ]
* Don't raise a traceback if we cannot de-marshal Python bytecode to support
  Python 3.7 loading newer .pyc files.
  (Closes: reproducible-builds/diffoscope#284)
* Fix Python tests under Python 3.7 with file 5.39+.
[ Vagrant Cascadian ]
* Skip Python bytecode testing when "file" is older than 5.39.
[ Roland Clobus ]
* Detect whether the GNU_BUILD_ID field has been modified.
You find out more by visiting the project homepage.

1 November 2021

Russell Coker: Talking to Criminals

I think most people and everyone who reads my blog is familiar with the phone support scams that are common nowadays. There s the we are Microsoft support and have found a problem with your PC , the we are from your ISP and want to warn you that your Internet access will be cut off , and the here s the bill for something expensive and we need you to confirm whether you want to pay . Most people hang up when scammers call them and don t call them back. But I like to talk to them. I review the quality of their criminal enterprise and tell them that I expect better quality criminals to call me. I ask them if they are proud to be criminals and if their parents would be proud of them. I ask them if they are paid well to be a criminal. Usually they just hang up and on one occasion the criminal told me to get lost before hanging up. Today I got a spam message telling me to phone +61-2-8006-7237 about an invoice for Norton Software Enhancer and Firewall Defender if I wanted to dispute it. It was interesting that they had an invoice number in the email which they asked me for when I called, at the time I didn t think to make up an invoice number with the same format to determine if they were actually looking it up, in retrospect I should have used a random 9 digit number to determine if they had a database for this. On the first call they just hung up on me. The second call they told me you won t save anyone before hanging up. The third call I got on to a friendly and talkative guy who told me that he was making good money being a criminal. I asked if he was in India or Australia (both guys had accents from the Indian subcontinent), he said he was in Pakistan. He said that he made good money by Pakistani standards as $1 Australian is over 100 Pakistani Rupees. He asked me if I d like to work for him, I said that I make good money doing legal things, he said that if I have so much money I could send him some. ;) He also offered to take me on a tour of Islamabad if I visited, this could have been a genuine offer to have a friendly meeting with someone from the opposite site of computer security or an attempt at kidnap for ransom. He didn t address my question about whether the local authorities would be interested in his work, presumably he thinks that a combination of local authorities not caring much and the difficulty of tracking international crime makes him safe. It was an interesting conversation, I encourage everyone to chat to such criminals. They are right that you won t save anyone. But you can have some fun and occasionally learn some interesting things.

Andreas R nnquist: Debian packages, version numbers and pre-release versions

Getting the latest version of a package into Debian involves checking when there are new versions available fortunately (and not surprisingly) Debian has tools to make this simpler. I have recently ran into the problem when an upstream beta version sorts higher than a newer non-beta version. Which is problematic, of course. This is due to Debian sorting something like 1.0b as later than a pure 1.0 version.
gusnan@debian-i7:~ > dpkg --compare-versions 1.0b lt 1.0 && echo true
gusnan@debian-i7:~ > dpkg --compare-versions 1.0b gt 1.0 && echo true
true
But there s a solution name the beta versions something like 1.0~beta. And you don t need to force upstream to make any changes either. You can use uscan and the watch file to make it interpret an upstream 1.0b version as 1.0~beta in Debian. This is done by using a line like
uversionmangle=s/(\d)[\_\.\-\+]?((RC rc pre dev beta alpha b a)\d*)$/$1~$2/;s/\~b/\~beta/;,\
in uversionmangle in your debian/watch file. In this case i have added on the end something to make the ending ~b into ~beta instead. Full version of the watch file available here.

31 October 2021

Joachim Breitner: A mostly allocation-free optional type

The Motoko programming language has a built-in data type for optional values, named ?t with values null and ?v (for v : t); this is the equivalent of Haskell s Maybe, Ocaml s option or Rust s Option. In this post, I explain how Motoko represents such optional values (almost) without allocation. I neither claim nor expect that any of this is novel; I just hope it s interesting.

Uniform representation The Motoko programming language, designed by Andreas Rossberg and implemented by a pretty cool team at DFINITY is a high-level language with strict semantics and a strong, structural, equi-recursive type system that compiles down to WebAssembly. Because the type system supports polymorphism, it represents all values uniformly. Simplified for the purpose of this blog post, they are always pointers into a heap object where the first word of the heap object, the heap tag, contains information about the value:
 
  tag    
 
The tag is something like array, int64, blob, variant, record, , and it has two purposes:
  • The garbage collector uses it to understand what kind of object it is looking at, so that it can move it around and follow pointers therein. Variable size objects such as arrays include the object size in a subsequent word of the heap object.
  • Some types have values that may have different shapes on the heap. For example, the ropes used in our text representation can either be a plain blob, or a concatenation node of two blobs. For these types, the tag of the heap object is inspected.

The optional type, naively The optional type (?t) is another example of such a type: Its values can either be null, or ?v for some value v of type t, and the primitive operations on this type are the two introduction forms, an analysis function, and a projection for non-null values:
null : () -> ?t
some : t -> ?t
is_some : ?t -> bool
project : ?t -> t     // must only be used if is_some holds
It is natural to use the heap tag to distinguish the two kind of values:
  • The null value is a simple one-word heap object with just a tag that says that this is null:
     
      null  
     
  • The other values are represented by a two-word object: The tag some, indicating that it is a ?v, and then the payload, which is the pointer that represents the value v:
     
      some   payload  
     
With this, the four operations can be implemented as follows:
def null():
  ptr <- alloc(1)
  ptr[0] = NULL_TAG
  return ptr
def some(v):
  ptr <- alloc(2)
  ptr[0] = SOME_TAG
  ptr[1] = v
  return ptr
def is_some(p):
  return p[0] == SOME_TAG
def project(p):
  return p[1]
The problem with this implementation is that null() and some(v) both allocate memory. This is bad if they are used very often, and very liberally, and this is the case in Motoko: For example the iterators used for the for (x in e) construct have type
type Iter<T> =   next : () -> ?T  
and would unavoidably allocate a few words on each iteration. Can we avoid this?

Static values It is quite simple to avoid this for for null: Just statically create a single null value and use it every time:
static_null = [NULL_TAG]
def null():
  return static_null
This way, at least null() doesn t allocate. But we gain more: Now every null value is represented by the same pointer, and since the pointer points to static memory, it does not change even with a moving garbage collector, so we can speed up is_some:
def is_some(p):
  return p != static_null
This is not a very surprising change so far, and most compilers out there can and will do at least the static allocation of such singleton constructors. For example, in Haskell, there is only a single empty list ([]) and a single Nothing value in your program, as you can see in my videos exploring the Haskell heap. But can we get rid of the allocation in some(v) too?

Unwrapped optional values If we don t want to allocate in some(v), what can we do? How about simply
def some(v):
  return v
That does not allocate! But it is also broken. At type ??Int, the values null, ?null and ??null are distinct values, but here this breaks. Or, more formally, the following laws should hold for our four primitive operations:
  1. is_some(null()) = false
  2. v. is_some(some(v)) = true
  3. p. project(some(p)) = p
But with the new definition of some, we d get is_some(some(null())) = false. Not good! But note that we only have a problem if we are wrapping a value that is null or some(v). So maybe take the shortcut only then, and write the following:
def some(v):
  if v == static_null   v[0] == SOME_TAG:
    ptr <- alloc(2)
    ptr[0] = SOME_TAG
    ptr[1] = v
    return ptr
  else:
    return v
The definition of is_some can stay as it is: It is still the case that all null values are represented by static_null. But the some values are now no longer all of the same shape, so we have to change project():
def project(p):
  if p[0] == SOME_TAG:
    return p[1]
  else:
    return p
Now things fall into place: A value ?v can, in many cases, be represented the same way as v, and no allocation is needed. Only when v is null or ?null or ??null or ???null etc. we need to use the some heap object, and thus have to allocate. In fact, it doesn t cost much to avoid allocation even for ?null:
static_some_null = [SOME_TAG, static_null]
def some(v):
  if v == static_null:
    return static_some_null
  else if v[0] == SOME_TAG:
    ptr <- alloc(2)
    ptr[0] = SOME_TAG
    ptr[1] = v
    return ptr
  else:
    return v
So unless one nests the ? type two levels deep, there is no allocation whatsoever, and the only cost is a bit more branching in some and project. That wasn t hard, but quite rewarding, as one can now use idioms like the iterator shown above with greater ease.

Examples The following tables shows the representation of various values before and after. Here [ ] is a pointed-to dynamically allocated heap object, a statically allocated heap object, N = NULL_TAG and S = SOME_TAG.
type value before after
Null null N N
?Int null N N
?Int ?23 [S,23] 23
??Int null N N
??Int ?null [S, N ] S, N
??Int ??23 [S,[S,23]] 23
???Int null N N
???Int ?null [S, N ] S, N
???Int ??null [S,[S, N ]] [S, S, N ]
???Int ???23 [S,[S,[S,23]]] 23

Concluding remarks
  • If you know what parametric polymorphism is, and wonder how this encoding can work in a language that has that, note that this representation is on the low-level of the untyped run-time value representation: We don t need to know the type of v in some(v), merely its heap representation.
  • The uniform representation in Motoko is a bit more involved: The pointers are tagged (by subtracting 1) and some scalar values are represented directly in place (shifted left by 1 bit). But this is luckily orthogonal to what I showed here.
  • Could Haskell do this for its Maybe type? Not so easily:
    • The Maybe type is not built-in, but rather a standard library-defined algebraic data type. But the compiler could feasible detect that this is option-like?
    • Haskell is lazy, so at runtime, the type Maybe could be Nothing, or Just v, or, and this is crucial, a yet to be evaluated expression, also called a thunk. And one definitely needs to distinguish between a thunk t :: Maybe a that may evaluate to Nothing, and a value Just t :: Maybe a that definitely is Just, but contains a value, which may be a thunk.
    Something like this may work for a strict Maybe type or unlifted sums like (# (# #) a #), but may clash with other ticks in GHC, such as pointer tagging.
  • As I said above, I don t expect this to be novel, and I am happy to add references to prior art here.
  • Given that a heap object with tag SOME_TAG now always encodes a tower ? null for n>0, one could try to optimize that even more by just storing the n:
     
      some    n   
     
    But that seems unadvisable: It is only a win if you have deep towers, which is probably rare. Worse, now the project function would have to return such a heap object with n decremented, so now projection might have to allocate, which goes against the cost model expected by the programmer.
  • If you rather want to see code than blog posts, feel free to check out Motoko PR #2115.
  • Does this kind of stuff excite you? Motoko is open source, so your contributions may be welcome!

Russ Allbery: Review: Shadow Scale

Review: Shadow Scale, by Rachel Hartman
Series: Seraphina #2
Publisher: Ember
Copyright: 2015
ISBN: 0-375-89659-7
Format: Kindle
Pages: 458
Shadow Scale, despite confusing publisher marketing that calls it a "companion" to Seraphina, is a direct sequel. It picks up shortly after Seraphina and resolves most of the loose ends of the previous book. This is a book for which my completionist tendencies did me no favors. The book I was intending to read, when I started on Hartman's work, is Tess of the Road, but I hate starting series in the middle and it was clear that Tess was set after Seraphina. (I have been repeatedly assured that this doesn't matter and that one can start with Tess. Such reassurances rarely work on me; do as I say, not as I do.) For Seraphina itself, this turned out fine; I'm mildly surprised by the book's Andre Norton award nomination, but it was enjoyable enough and I liked the first-person protagonist. Shadow Scale I approached with a bit more trepidation. I hadn't heard much about it and the few reviews I saw were lukewarm. Unfortunately, there's a reason for that. Seraphina left obvious room for a sequel, including a brewing war, significant unresolved interpersonal relationships, and Seraphina's own newfound understanding of the nature of her internal menagerie. Alas, the start of the book uses the war primarily as plot device (and introduces a brand-new bit of magic that I never found interesting), largely ignores the relationship, and focuses on that third plot element. And by focuses, I mean Seraphina is sent out of the country of Goredd on a journey of map exploration to collect plot coupons. The best description I have for the middle of this book is tedious and depressing. Like a lot of novels, it has a U-shaped plot: things get worse and worse until a crisis, and then start getting better. This plot can work, but the reader has to have a good reason to stick through the depressing bits. One of the better reasons is if the plot allows the main character some small triumphs, maintaining their agency throughout even if larger events are spiraling out of control. This is not one of those books. After some early successes tracking down some objects of her search, Seraphina encounters an antagonist from her own past (barely hinted at in the first book) who can systematically corrupt everything she is trying to do. She spends most of the book feeling like what she's doing is futile, or hoping for things the reader knows aren't going to happen. Given that this is happening during plodding map exploration fantasy through largely indistinguishable faux-medieval countries, or (later) somewhat more interesting but obviously irrelevant local politics in a remote trading city, it's hard to avoid sharing that sense of futility. The other structural problem with Shadow Scale is that the plot coupons are people, which means this book has an excessive cast size problem. Seraphina collects too many people for me to even keep straight, let alone care about. Critical developments (usually for the worst) in the lives of one of these characters were frequently met with reader mutterings like, "Now which one was Brasidas again, was he the plague doctor?" This tends to undermine the emotional impact. It didn't help that the plot was enough of a slog that I kept putting the book aside for a few days. This does get better, but not enough better to redeem the middle of the book, and one has to put up with a lot of helpless despair to get there. Shadow Scale is one of those stories where the protagonist has the innate power to resolve the plot, is told cryptically by various people that this is the case, but has absolutely no idea how to use it and her supposed mentors are essentially useless. The result is that she feels both hopeless and guilty, which was not the reading experience I wanted. I did enjoy the moment when she finally figures it out, and I thought Hartman's idea was reasonably clever, but it would have been better if that had happened faster. Like, 200 pages faster. At least. The major world-building in Seraphina was the dragons. The dragons also show up in this book (and feel less like autism spectrum archetypes, which I appreciated), and in theory are central to the plot, but I'm not entirely sure why? It was an odd reading experience. I think Hartman was attempting to set up dual villains posing different threats, but the dragon one is off-screen for nearly the entire book and never developed, so it feels perfunctory. Near the end of the book, Hartman abruptly picks up the dragons again, but that whole section felt oddly disconnected from the rest of the plot and is only barely relevant to the resolution. At least for me, the plot structure didn't cohere. Shadow Scale does go up a whole point in rating for me because of the romance plot and how Hartman resolves it, which I will not spoil but which I loved. The process of getting there is immensely frustrating because it feels like Hartman is forcing the characters into a corner where only stupid resolutions are possible, but in this case the U-shaped emotional structure worked on me. The ending is completely true to the characters in a way that I thought Hartman had made impossible (and which does a lovely bit of undermining of traditional roles), so full credit there. It helped that the relationship is put on ice for most of the book and only appears at the end (which is also the best part of the book), so it didn't drag on like the other parts of the plot. Overall, though, I tentatively agree with the general advice to skip this one, and suspect that advice will become less tentative once I read Tess of the Road. It's a largely unpleasant slog. There are some mildly interesting world-building revelations that fill in the background of Seraphina, the ending was reasonably good, and the relationships were much better than I was expecting through most of the book, but the amount of time and patience required to get there was not a good trade-off for me. Followed (in the sense that it's set in the same universe but is not a sequel and I suspect does not depend heavily on this plot) by Tess of the Road. Rating: 4 out of 10

30 October 2021

Dirk Eddelbuettel: RcppQuantuccia 0.1.0 on CRAN: Full QuantLib Business Calendar Support

Another new release of RcppQuantuccia arrived on CRAN today, just a week after the previous release which brought full calendaring support. RcppQuantuccia started from the Quantuccia header-only subset / variant of QuantLib which it brings it to R. As of this release, the QuantLib code is only minimally modified. In other words we no longer follow the Quantuccia route of header-izing the file but include both cpp and hpp directly. The minimal changes, documented in a diff file in the repo, consists chiefly of removing includes for headers we do not use (given the pure calendaring focus) and accomodating CRAN Policies (by eschewing #pragma directives). We do follow Quantuccia by not having any external linking requirement: the R package only depends on Rcpp (for the glue) and BH for the Boost headers (and system-level Boost headers can be used as drop-in). The our knowledge, this provides the only small and self-contained (apart from Boost headers) library with current (and regularly updated within QuantLib, which I intend to shadow here) calendaring code on a global scale. Every exchange that matters is likely included. The screenshot provides quick demo. The complete list changes for this release follows.

Changes in version 0.1.0 (2021-10-30)
  • Code reorganized to have minimal (documented) changes relative to upstream, essentially just removing unused headers, and pragma
  • Added example for full calendaring to README.md

Time permitting, I may look into other bindings from this sub-library; see a first email thread on this. Courtesy of CRANberries, there is also a diffstat report relative to the previous release. More information is on the RcppQuantuccia page. Issues and bugreports should go to the GitHub issue tracker. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

29 October 2021

Reproducible Builds (diffoscope): diffoscope 189 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 189. This version includes the following changes:
[ Chris Lamb ]
* Try some alternative suffixes (eg. ".py") to support distributions that
  strip or retain them. (Closes: reproducible-builds/diffoscope#283)
* Skip Python bytecode testing where we do not have an expected diff.
  (Closes: reproducible-builds/diffoscope#284)
* Refactor the find_executable utility into an explicit method.
* Split out a custom call to assert_diff to support a .startswith equivalent.
* Use skipif instead of manual conditionals in some tests.
[ Vagrant Cascadian ]
* Add an external tool reference for Guix to support ppudump and dumppdf.
[ Sergei Trofimovich ]
* Update uImage test output for file(1) version 5.41.
[ Jelle van der Waa ]
* Add Arch Linux as CI test target.
* Add external tools on Arch Linux for ffmpeg, openssl and ocalobjinfo.
You find out more by visiting the project homepage.

26 October 2021

Russell Coker: Links October 2021

Bloomburg has an insightful article about Juniper, the NSA, and the compromise of Netscreen [1]. It was worse than we previously thought and the Chinese government was involved. Haaretz has an amusing story about security issues at a credit card company based on a series of major WTFs [2]. They used WhatsApp for communicating with customers (despite the lack of support from Facebook for issues like account compromise), stored it on a phone (they should have used a desktop PC), didn t lock the phone down (should have been in a locked case and bolted down like any other financial security device), and allowed it to get stolen. Fortunately the thief was only after a free phone not the financial data stored on it. David Brin wrote an insightful blog post Should facts and successes matter in economics? Or politics? [3] which is part of his series about challenging conservatives to bet on their policies. Vice has an interesting article about a normal-looking USB-C to Lightning cable that intercepts data transfer and sends it out via an embedded Wifi AP [4]. Getting that into such a small space is an impressive engineering feat. The vendor already has a YSB-A to lightning cable with such features for $120 [5]. That s too expensive to just leave them lying around and hope that someone with interesting data finds them, but it s also quite cheap for a targeted attack. Interesting article about tracking people via Bluetooth MAC address or device name [6]. Most of the research is based on a man riding a bike around Norway and passively sniffing Bluetooth transmissions. You can buy commercial devices that can receive Bluetooth from 1Km away. A recent version of Bluetooth has random Mac addresses but that still allows tracking by device name which for many people is their own name. Cory Doctorow has a good summary of the ways that Facebook is rotten [7]. It s worse than you think. In 2019 almost all Facebook s top Christian pages were run by foreign troll farms [8]. This is partly due to Christians being gullible, but Facebook is also to blame for this. Cornell has an interesting article about using CRISPR to identify the gender of chicken eggs before they hatch [9]. This means that instead of killing roosters hatched from eggs for egg production they can just put those eggs for eating and save some money. Another option would be to genetically engineer more sexual dimorphism into chickens as the real problem is that hens for laying eggs are too thin to be good for eating so if you could have a breed of chicken with thin hens and fat cocks then all eggs could be hatched and the chickens used. The article claims that this is an ethical benefit of not killing baby roosters, but really it s about saving 50 cents per egg. Umair Haque wrote an insightful article about why everything will get more expensive as the externalities dating back to the industrial revolution have to be paid for [9]. Alexei Navalny (the jailed Russian opposition politician who Putin tried to murder) wrote an insightful article about why corruption is at the root of most world problems and how to solve it [10]. Cory Doctorow wrote an insightful article about breaking in to the writing industry which can apply to starting in most careers [11]. The main point is that people who have established careers have knowledge about starting a career that s at best outdated and at most totally irrelevant. Learning from people who are at most one step ahead of you is probably best. Peter Wehner wrote an insightful article for The Atlantic about the way churches in the US are breaking apart due to political issues [12]. Similar things appear to be happening in Australia for the same reason, conservative fear based politics which directly opposes everything in the Bible about Jesus is taking over churches. On the positive side this should destroy churches and the way churches are currently going they should be destroyed. The Guardian has an article about the incidence of reinfection with Covid19 [13]. The current expectation is that people who aren t vaccinated will probably get it about every 16 months if it becomes endemic (as it has in the US and will do in Australia if conservatives have their way). If the mortality rate is 2% each time then an unvaccinated person could expect a 15% chance of dying over the course of 10 years if there is no cumulative damage. However if damage to the heart and lungs accumulates over multiple courses of the disease then the probability of death over 10 years could be a lot higher. Psyche has an interesting article by Professor Jan-Willem van Prooijeni about the way that conspiracy theories bypass rationality [14]. The way that entertaining stories bypass rationality is particularly concerning given the way Facebook and other social media are driven by clickbait.

Next.

Previous.