Search Results: "ag"

20 February 2012

Tanguy Ortolo: Opportunistic SSH agent

To use an SSH agent, one usually has to:
  1. launch the agent;
  2. add his key to it.
The first step can be automated in the desktop or shell startup script (this is a typical use case for login shell-only startup scripts, by the way), but the second one cannot if your private key is protected by a passphrase.Opportunistic key loading GNOME Keyring includes an SSH agent which has an interesting feature I call opportunistic key loading : it asks for the passphrase to decrypt the private key the first time it is needed. This feature mimics the behaviour of PGP agents, and eliminates the second step I previously mentioned. Question Do you know if there exists another SSH agent able to do opportunistic key loading?

Richard Hartmann: Lenovo hardware quality

This is half rant, half warning to others. Relative merrits of the IBM ThinkPad X31 vs the Lenovo ThinkPad X220... Old IBM ThinkPad X31 which I abused for years: I upgraded the RAM, swapped the battery once and the HDD twice. If not for a loose power socket, I would still use it. Contrast my new Lenovo ThinkPad X220 after a few months of pampering: Google tells me there are several people with random issues with their X220, especially when the mini-PCI slot is being used in a machine with USB 3.0. Removing the UMTS/GPS module did help, but still, this means no SSD for me as that's the slot I would have to use. Recently, things have been degrading very quickly to the point where I refuse to do even simple things, like write and push blog posts, on this machine. I am not sure if I am simply unlucky and received a dud, if the X220 is a model with issues, or if this is indicative of a general trend within Lenovo, but it's time to contact Lenovo support. If I had known all of this in advance, I would simply have soldered the power socket back into my X31 and held out for the X221. Or something else, entirely.

Gunnar Wolf: Left Google Reader for rssLounge

Ben mentions he left Google Reader and went back to Liferea, but mentions a series of bugs that keep him from being happy. After pondering it a bit, a couple of months ago I also left Google Reader, but I turned to a free webapp: rssLounge aggregator. Although it does not fully cover Ben's wishlist (I'll get to it now), I am happy using it as it covers my main need: Being able to read my stuff from just about everywhere, without installing even a ssh client (that would make public Windows machines a liability for me, as they could sniff my keystrokes while authenticating to my ssh server). So, for me, a webapp is basically a must. Well, as for Ben's list:

  1. MAY be a desktop or web application.
    Check. Well, I don't know what would fail this :)
  2. If it's a web application, it MUST be reasonably secure, e.g. it must not be written in PHP.
    Fail. It's PHP. And that's my main reason for not uploading it to Debian I use and enjoy this app every day, but it has some bugs I don't really feel like looking into. And yes, maintaining PHP code is ugly.
  3. If it's a web application, it MUST allow for multiple independent users on the same server.
    Don't really remember, I set it up just for myself. But in any case, you could install a different instance per user?
  4. If it's a desktop application, it MUST embed a browser engine (presumably Gecko or WebKit) so I can follow links without having to switch windows.
    N/A
  5. MUST support organisation of feeds by folders or tags, including combined item lists.
    Pass.
  6. MUST keep track of which items have been read.
    Pass.
  7. MUST support a global 'unread items' list. SHOULD only remove items from this list when I refresh it, not as soon as I move away from an item.
    Pass. In fact, given that storage is cheap, I have set it to never expire old entries. I don't know if it will ever be useful, but as long as it does not hurt me...
  8. SHOULD support a three-pane (folder/list/item) view or something similar. Google Reader's list view with expanding items is perhaps even better, though it means links must be opened in a separate tab.
    It's more like Google Reader's
  9. SHOULD support folder and item navigation by keyboard.
    Pass.
  10. SHOULD have some way to flag/bookmark items for later attention.
    Pass.
  11. If it's a desktop application, it SHOULD have some sort of download manager to support podcasts.
    N/A
So, Ben, with only one (big) fail, it might be a good candidate for you. PS- And hard as it might seem, I am leading an almost-Google-free life now! :) But don't let them hear this, as we want them to keep sponsoring Summer of Code and DebConf.

Ben Hutchings: Feed reading

I switched from Google Reader to Liferea a while back. I was mostly happy with the functionality of Reader but I don't really want my reading history to be recorded or my feed list to be vulnerable to the whim of Google's inscrutable abuse department. I'm still using Liferea but unfortunately it has a lot of problems. Yes I do have bug numbers: So, I'm looking for an alternative again. My requirements are:
  1. MAY be a desktop or web application.
  2. If it's a web application, it MUST be reasonably secure, e.g. it must not be written in PHP.
  3. If it's a web application, it MUST allow for multiple independent users on the same server.
  4. If it's a desktop application, it MUST embed a browser engine (presumably Gecko or WebKit) so I can follow links without having to switch windows.
  5. MUST support organisation of feeds by folders or tags, including combined item lists.
  6. MUST keep track of which items have been read.
  7. MUST support a global 'unread items' list. SHOULD only remove items from this list when I refresh it, not as soon as I move away from an item.
  8. SHOULD support a three-pane (folder/list/item) view or something similar. Google Reader's list view with expanding items is perhaps even better, though it means links must be opened in a separate tab.
  9. SHOULD support folder and item navigation by keyboard.
  10. SHOULD have some way to flag/bookmark items for later attention.
  11. If it's a desktop application, it SHOULD have some sort of download manager to support podcasts.

Michal Čihař: Prague carnivals

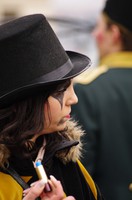
During these days, there are various carnivals in Prague. On Saturday I've visited Malostransk masopust, which is probably not the biggest one, but definitely the one in most attractive location, starting at Prague castle and going down to Kampa. This was actually my first visit of this carnival and I quite enjoyed it. Bellow you can find some photos taken during the event to catch the atmosphere:
Filed under: English Photography 0 comments Flattr this!

19 February 2012

Richard Hartmann: RAID sucks

Intro RAID sucks, and so do all other Free alternatives in the Linux world. Having been in exactly the same situation several times in the past, I have been following Russell Coker's posts regarding data integrity with interest. FWIW, the correct answer to "BTRFS (sic) and Xen" is: subvolumes. Now that Fedora has, once again, decided to postpone their switch to Btrfs as default file system, I decided to write up my own take on this topic. Any and all my considerations are made under the assumption that important data is backed up while semi-important data is at least living on two different machines. Beware, this is a long post, but I do like to think it's well worth reading. RAID Disk failures Let's recap the current situation for "traditional" file systems like xfs, ext 2..4 , etc. In case you need to freshen up on the technical details go here. Silent corruption All the RAID levels with redundancy are fine and dandy if you lose a whole disk and put in a new one. Of course, that does not help you the tiniest bit once you get read errors. Controllers which manage RAID 1 or 10 may or may not compare the data while it's being read and may or may not tell you about discrepancies. They can then toss a coin and give you either result. There is no way to determine which is correct. RAID 2, 3, 4, 5, and 6 could, in theory, verify the data as it's being read, but that would limit your read rate to that of a single disk so no one does that. We actually had a massive web presence fail over night, once. No one knew what the cause was as there hadn't been any kind of access logged. As that particular deployment is done directly from a VCS, we simply ran a diff and found one change. We traced the failure down to a syntax error; a one character change made everything fail. Looking at the ASCII table, it was clear that one single bit had flipped. This sucked. A lot. Mitigation So you end up scrubbing your RAID sets on a weekly basis, recovering from silent corruption with the help of your RAID 6's two parity stripes. And even though you schedule the scrubbings with the least priority, you still take a performance hit when randomly seeking a lot. ZFS Some smart people at Sun set out to fix these problems and more, and fix it they did. The "Z" in ZFS is meant to imply that this is the last file system you will ever need and if not for its license, this might have worked. Of course, "last" and "forever" mean "not now" and "10 years" respectively, in computer terms. The limits within ZFS have been chosen so that the entropy needed to create a disk able to max out a ZFS volume would, literally, require our oceans to boil. Let's just say that you won't encounter these limits any time soon. While that is a nice thing to know, it does not say anything about data integrity. There are several mechanisms ensuring data integrity built in ZFS, the most fundamental being extensive checksumming. Checksums are vastly superior to live comparisions which RAID would have to perform as it does not need to sacrifice any significant i/o reading checksum data. With HDD access, you are i/o-bound, and not CPU-bound, anyway, so performing the checksum calculations is laughably cheap when factoring in the added safety. Everything, be data, metadata, inodes, you name it, is checksummed. Every read operation must go through the checksumming functions, ensuring that all data which reaches your user space is correct. If ZFS can't verify the checksum, it will not deliver any data at all, ensuring noticeable, as opposed to silent, corruption. So how does ZFS recover when the checksum does not match the data? copies= 1..3 The easy way is to store several copies of your data within your volume. Mount a ZFS volume or subvolume with copies=2 or 3 and all data that is being written from then on will be copied twice or three times. Trivial in principle, but powerful when built into a file system. RAIDz 1..3 This is where things start to get interesting. RAIDz1, 2, and 3 will allow you to lose 1, 2, or 3 disks respectively while still retaining your data; at the obvious expense of the storage capacity of as many disks. Basically, RAIDz2 is ZFS' variant of RAID 6, but it's so much better than mere RAID 6. Moo! RAIDz will not assign fixed slices and fill them up like RAID does. It will look at the current write speeds and use appropriate slice sizes dynamically. As a direct result, data which has been written at roughly the same time will always be near other data written at the same time. This is very nice for functionality like snapshots, writeable subvolumes and other things and is called COW, ZFS' variant of super cow powers. This also enables ZFS to write data, read it back and verify the checksum and only then point to the new data. Atomic commits done right. Keep rollin' As ZFS has to keep track of what data is still in use in which volumes and subvolumes anyway, it knows which regions are free to be reclaimed. Instead of filling up random places, ZFS will roll over your disks, overwriting unused data on the fly. This bears repeating: Contrary to RAID 5 and 6, ZFS will never need to read old data in order to write new data. Write performance galore and anyone still stuck on RAID 10 can finally enjoy the increased data security. Btrfs To be completely honest, I do not know Btrfs as well as I know ZFS. If I get anything wrong, correct me. If I offend anyone with my outsider's interpretation, that is not my intention. Btrfs has been initiated by Oracle way before it ever even thought about buying Sun or history might have run a different course, for worse or a lot worse. The closing of Java, Solaris, ZFS, Hudson, OpenOffice (since then "gifted" aka thrown away), and others makes me think the latter. As there are few technological developments which caused me as much stress, overtime and pain as OCFS2, I am naturally wary of file systems sponsored by Oracle and their data focus integrity/availability. The fact that there's still no way to fsck a Btrfs volume could be birthing pain or yet another facet of Oracle's stance on this topic, I honestly don't know. Either way, it's a good idea to be wary for now. I can't say too much on Btrfs' technical underpinnings, but I know it uses COW and that it has its own variant of RAID. Toss in snapshots (writeable?), subvolumes and integrated block device management, and you have the building blocks of a decent file system. Still, Btrfs is not ready for prime time. Btrfs has been "one or two years in the future" for a few years now so I will not be holding my breath. And once the first distributions are starting to use Btrfs by default, people will lose data. A year or three after that, I will feel comfortable to use it myself and in production. Commercial solutions You can either hand a lot of money to proprietary vendors who will not tell you a thing about how things work internally (and no way to fix things directly) or you can buy solutions that employ ZFS in the back-end. I prefer my storage hardware to be relatively dumb while keeping the intelligent bits where I can see and poke them so this is not really part of these considerations. So what can you do? Test your disks before deploying them Easy, but vitally important:
disk=/dev/foo
smartctl -a $disk
smartctl -t long $disk
badblocks -swo $vendor_$model_$serial_$timestamp.badblocks.swo $disk
smartctl -a $disk

If you are lazy, get a copy of disktest, a tool I wrote to do exactly this. It should wait for the long self-test to finish, can not read out all vendor names, and does not have a way to document who ran the test, but it's a start. Patches and feedback are, obviously, welcome. And yes, I will package this soonish. Using your disks This list is surprisingly short. You can use And that's it. At work, I prefer small RAID 6 volume sets. It sucks, but there is nothing better. For personal use, I have a machine with a FUSE-based RAIDz2 mounted with copies=2. Three disks can fail and my data is still secure. While this setup is slow as molasses due to FUSE, speed is not a consideration for me here; data safety is. A migration to Debian/kFreeBSD in the medium term is still likely. If you have things to add or disagree with me, I would love to hear from you. Update: Jan Christian Kaessens pointed out that, contrary to my experience, zfsonlinux did not bring down his sytem in flames. As zfsonlinux is a kernel module, potential performance is a lot better. Also, it supports ZFS Pool Version 28 as opposed to FUSE-ZFS' 23. While the really nice features are in v 29 and 30 (which are closed thanks to Oracle) v 28 still has some nice changes.

Lars Wirzenius: Copyright as theft

Copyright maximalists, such as MPAA and RIAA, like to say that copyright violations are theft. I don't agree, but if they are, then logically, extending copyright in a way that makes things that were out of copyright to again be in copyright is also theft. And that's happened so much it's grand larceny.

Petter Reinholdtsen: First release candidate of Debian Edu / Skolelinux based on Squeeze

One week delayed due to DVD build problems, we managed today to wrap up and publish the first release candidate for Debian Edu / Skolelinux based on Squeeze. The full announcement is available on the project announcement list. Check it out if you need a software solution for your school.

Gregor Herrmann: RC bugs 2012/07

thanks to the Paris BSP & other activities we're seeing a nice decline in RC bugs. here are my recent contributions:

Russ Allbery: Debian, licenses, and license-count

A few people have been using the license-count tool that I wrote to analyze the breakdown of licenses in Debian and draw some conclusions. Unfortunately, some of those conclusions can't be drawn from the output of this specific tool (which doesn't make them wrong, just unproven). So here are a few cautions. license-count was written for a specific purpose: to see how many references there are to a particular license in Debian so that we had some facts behind our discussion of whether to include it in common-licenses. It was not written to classify packages into particular categories, only to find out how many copies of a license we could save by adding it to common-licenses. This means that using it to determine how much software in Debian is covered by a particular license fails in the following ways:
  1. license-count numbers cannot be added. Since the goal is to find every reference to a given license, each package is not classified as under one and only one license. If a package has material under the GPL, the LGPL, and the GFDL, it will add one to each of those counts. This means that you cannot determine, from its output, questions like "how many packages are covered under one of the GPL family of licenses?" You will double- or treble-count packages when you add the numbers together.
  2. license-count counts any reference, not just "important" ones. If the license is referenced in debian/copyright, that counts, since the goal is to see how many packages might benefit from being able to reference it in common-licenses. This may not be the license that the package is under, just some small portion of the package. For example, all of my packages that use Autotools add to the GPL count because I include all the source code licensing statements, including the statements for libtool and the Automake helper scripts, which say that the files can be released under either the GPL or the license of the including package. These packages are generally under a BSD-style license (or in some cases the Apache 2.0 license), not under the GPL, but since the reproduced license text has a reference to the GPL, license-count adds one to the GPL column for each of those binary packages. For most purposes for counting GPL-covered software, these are false positives. I don't know how many people are as complete in documenting license statements as I am, but just the binary packages that I maintain probably count for at least 50 false positives because of this alone.
  3. license-count numbers include dual-licensing. Whether this matters for your analysis or not depends on what question you're asking, of course. If you're asking whether the package is covered under a copyleft license, including the thousands of packages that are dual-licensed under the Artistic license and the GPL may be okay, since the Artistic license is a sort of copyleft (although it allows you to avoid the copyleft requirement by renaming executables, providing the originals, and documenting your changes). But, for example, one of my packages is dual-licensed under a BSD-style license and the GPL (for reasons that aren't worth getting into). This package is not covered by copyleft under any reasonable definition of the term, but license-count will count it as a package using the GPL.
In order to draw interesting conclusions like "how much software in Debian is protected by copyleft," I'm afraid that you'd have to write a much more sophisticated tool than license-count.

Bartosz Feński: Not able to install Debian

That s sad. Hardware that was supported sometime ago, it s now unsupported.
I have no idea how to install Debian on Sony Vaio laptop.
Tried all possibilities.

Lars Wirzenius: Obnam 0.25 released (backup software)

I've released version 0.25 of Obnam, my backup application. BUG FIXES:

18 February 2012

Asheesh Laroia: Help a BSD developer bike across the US, and give hope to cancer communities

<style type="text/css"> @import "/pub/special-css/venk.css"; </style>
'Cancer' is a cluster of diseases, a betrayal by the majesty and power of the development program that constructed and heals us.
Support Venkatesh's bike ride, and alleviate the toll of cancer.
My friend Venkatesh, pictured above, is going to bike four thousand miles, all the way across the continental US, from Baltimore to Portland. He's doing it to raise money for the Ulman Cancer Fund for Young Adults. I'm writing this because I want you to donate money to his cause. He's a DragonFly BSD developer, loves bikes, and your donation could make a big difference. I first met Venkatesh through the Johns Hopkins computer club, an ACM chapter. I was the head of the club, and he had just started his career at Hopkins. He was looking for advice on running Brickwiki, the LEGO encyclopedia. Quickly, I became his friend; in that time, I've learned the following things about him. In the years since I graduated from Hopkins, I've been impressed by Venkatesh's ongoing curiosity and contributions to open source projects like DragonFly. I'm honored to have this chance to help him bike across the country for a good cause. Here is a quick word about the 4K for cancer effort:
Since 2002, groups of college students have undertaken a 70 day, 4000+ mile summer bike ride across the United States with the goal of offering hope, inspiration and support to cancer communities along the way. This past summer was our 10th year of cycling across the country as 76 volunteers rode along three different routes: Baltimore to San Francisco, Baltimore to Portland, and Baltimore to Seattle. Our riders raised a combined $476,000 to support organizations and individuals in the fight against cancer.
His fundraising goal is $5,000. Anything from $5 to $500 is a donation to an organization that helps young adult cancer surviers and their families get access to information and support resources. Can you help?
Biella Coleman: Montreal, first impressions

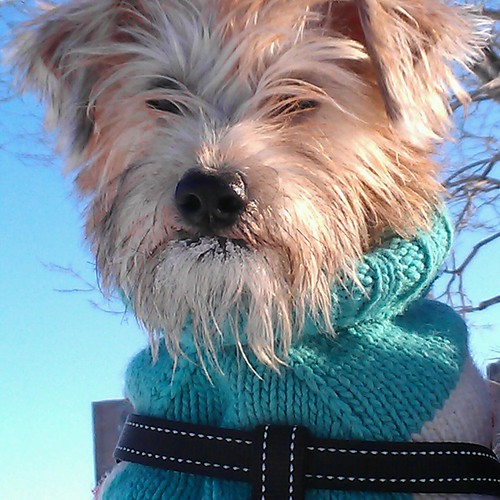
frozenlights When I told people of my plans to move to Montreal, it usually prompted one of two reactions: one was some version of joyful envy, many people exclaiming breathlessly Montreal is one of my favorite cities, one person once even clutching my arm and told me as he looked me straight in the eye: you are so lucky, there is no city quite like Montreal in North America. The second reaction came off as a thinly veiled mixture of disdain and disbelief usually peppered with many reallys: oh wow, really, really you would really leave NYC? I am pretty certain they really were thinking something along the lines of what a fool, how dare she leave a great job, a great university, a world class city (the only city to live) for some Canadian mid-sized city, which is like tundra for a good chunk of the year? The decision to move weighed heavily on me, if for no other reason I had a choice to stay or to go and I honestly have not had a choice, a decision to make about where to go since I got accepted to graduate school (and even then the choice was more obvious than this one). So over a month into my move what is my verdict? In a word, win. I don t miss NYC at all though I get why some people cannot leave the place and know that despite some oddities and difficulties of living in Montreal, it fits my tastes and needs much better than NYC which dwarfed me in so many ways. I never felt I could enjoy it, I grew tired of the cramped living quarters, the noise ate at my soul, and I simply felt more overwhelmed by the fact that I could not even get a handle on the neighborhoods in my vicinity, much less all the other hoods in the area. Instead of dogging NYC anymore, I think I will spend a little time on first impressions, as they will soon be lost to the familiarity borne with time and experience. In essence Montreal is chock full of life but rather intimate, a quirky city with lots of charm but some grit and lacking the way over designed and done feel of cities like Portland. Here are some of quirks: 1. The Hawt Metro: I fell in love with the Metro when I first rode it a few years ago. I just love the powder blue color of the cars and the super sweet 1960s aesthetic of many stations. Even better and unlike NYC, they are just clean and quiet. The downside? The temperatures approximates a sauna during the winter and while you would think this is a good thing, when you are layered with the clothing necessary to survive outside (re: long underwear along with Canada-coat, gloves, hat, and scarf), it is hooooooot down there and you feel like you need to pass out. 2. Spend money, get free stuff: In many establishments you get free stuff (like blueberries or some like sports bar) when you spend over a certain amount of money, like 70 bucks. Quirky local tradition. 3. The culture of negotiation and the kick ass standard lease: Housing is amazing here. There is plenty of it, there are many different styles, and it is rather fun exploring all the different hoods that make up the city. Problem is too that lots of apartments have weird problems and issues and I had to steer clear of anything that could even possibly have mold. I spent weeks day in day out looking for a place, desperate to move out of my corporate apartment very nicely provided by the university but still not my ideal living situation. Finally found a place that fit all my needs in the perfect location and I took it to only find out that places are priced to negotiate and I was faced with the decision to negotiate or not. Sort of did, was not thrilled about it (thinking that I might lose the place) but it sort of worked and I scored the place. If price is up to haggling, the lease on the other hand, is standard (you can buy one at your local bodega ). It is the law to use it and it is like a no nonsense, straightforward lease, which is very protective of renters. 4. Montreal is known for its exceptional food but you know Poutine is just plain gross: Food here is good and I can tell that I will get a handle of restaurants in a way that felt impossible in NYC. The gluten free religion seems to be spreading, thankfully. There are many little Fruiterias! to get your fruits veggies which I am still exploring and right around my house is a crazy supermarket that is so cheap, which is weird because consumer goods generally ain t cheap in Montreal like they are in the states but this place is a gem and everyone agrees (and almost impossible to notice from the street!). Now Poutine is disgusting. Ok it did not help that the first night I went out to eat it, I was still under the clutches of Noro virus, and I think it re-activated the nausea that had been zapped by some strong medicine and the hospital, the day before, which brings me to the next point, the health care system. 5. Healthcare, I had to use it way too early: So last week I came down with the Noro virus and you usually wait it out as it runs through you quickly but I was dehydrated before I even started to vomit to for 8 hours straight, at which point severely tired and so nauseous (I was yelling to make it stop), I went to the hospital. Now I had talked to lot of people about the healthcare system in Montreal as it seems good, really great but a bit over taxed, especially compared to where I had lived in Edmonton where it was like a magic fairy tale dream. I had heard of two things: the care is excellent but the facilities are shocking and the wait times unless dire can be atrociously long. So facilities, yea they are kinda shocking, somewhat shabby but who cares, so long as the care is good, no? Packaging is irrelevant so long as the goods are derived. Before going I was scared of the long wait times (and also the taxi took me by mistake to Montreal General Hospital was looked too much like a HUGE version of the creepy buildings in The Shining for me, and I was supposed to go to Jewish General so left for there). The wait time: nearly none, somewhat as shocking as the facilities first looked to me. I think it was a combination of the time I arrived, with the fact that my lounge was parched and yellowish-gross (sorry, it was gross), indicating I was dehydrated, oh and I was crying bit hysterically, for despite my high threshold for pain, nausea terrorizes me. I was covered by insurance and since I did not yet have my McGill health cards (it takes three months to qualify for the local stuff), I did pay and the price was laughably cheap compared to what I would pay in NYC for the same treatment. 6. Now for my favorite, snow so nice, ice oh Christ: Well this winter has been, by all accounts, weak and warm, the spirit of winter barely making its way from the underworld to the outerworld. But even though it is has been more idle than full throttle, I still got a pretty accurate taste of what winter is like, with a few days of 20- c temps, and having to walk a number of times on a layer of frozen ice that makes it feel like a very dangerous mini-ice age in the making. IMAG0028-1 I do rather love the quiet snow falling and just love love sprinting through the snow with my dog, Roscoe, who has taken a liking for prancing in the white stuff and looks awful cute with his winter man s ice beard. After a sizable snowfall, it is clear they city does not toy with the snow removal although the sidewalk snow plows do look somewhat like very large and dangerous but kinda cute toys. But let s be frank, winters are hard, so hard that I think I would go mad if I had to stay through the entire thing, being born and raised in the tropics So the fact that I am writing this from the southern hemisphere in the height of summer gives me the assurance I can handle the rest of the snow, ice, ice and snow upon my return.
Stefano Zacchiroli: GPL-d Debian software skew (?)

At FOSDEM, John Sullivan delivered an interesting talk titled Is copyleft being framed? to verify alleged claims on the decline of GPL-d software. (Slides are available.) The crux of the talk is the analysis he performed on the Debian archive to discover the amount of software we distribute that is covered by GPL, LGPL, or AGPL ("GPL-d" for short in the remainder). John's talk steps in an interesting and long running debate (a recent summary of which is available in this ITWire article). The most interesting part is the discrepancy among John's results and Blackduck's, which are often used to argue how the popularity of the GPL license is declining. That might be the case. Or not. The more analyses we do to find it out, the better. The underlying assumption on John's work is that Debian is a representative sample of the Free Software out there, which I think is a reasonable assumption. I find the analysis presented in the talk completely satisfactorily from a purely scientific point of view. The same cannot be said about Blackduck's result: both their methods and data are secret, making it impossible to reproduce their experiments. Highly unscientific. Still, John's results are surprising: as much as 87 percent of Lenny's packages and 93 percent of Squeeze's are GPL-d. That seems a lot. Puzzled about that, John discussed with me the issue before his talk, in search for pitfalls in his methods or data. Finding none, I pointed him to the almighty DktrKranz for some extra review; who found nothing either. To stay on the safe side, even during his talk John called for independent reviews of his results. What could be wrong? The tool used to gather the data is license-count from the debian-policy package. Input data are the debian/copyright files of all Debian source packages. If license-count is not bugged, our debian/copyright files might be. One thing that occurred to me only a few days ago is the habit of declaring a different license for Debian packaging (the files under debian/) than the software being packaged itself. That's a bad habit because it might cause unwanted license mixtures via patches that live under debian/ but I've seen several occurrences of it in the Debian archive. For name and (self-)shame: I've also been guilty of it in the past, when I was young . Is that reason enough to skew results and overestimate GPL-d software? I don't think so, I hope not, but ultimately I don't know. It'd be nice to rule out the possibility entirely. So if anyone is willing to do some sampling of affected debian/copyright files and propose patches for license-count to exclude those "false positives", please shout. (As a bonus point: that would also help to take more sound decision for the typical use case of license-count, i.e. deciding when a license should be added to /usr/share/common-licenses.) Other independent reviews of the results are equally welcome. Note: the above, as well as John's analysis, would be a trivial exercise if DEP-5 were already widely deployed in the Debian archive.
Update: add link to John's slides
Update 19/02/2012: Russ Allbery, author of license-count, posted a way more likely cause of data skew in John's analysis: double counting among the different types of copyleft licenses

Dirk Eddelbuettel: Using Rcout with Rcpp / RcppArmadillo to coordinate output with R

The new RcppArmadillo release 0.2.35 now supports the Rcpp::Rcout output stream device. Based on a contributed Rcpp patch by Jelper Ypma, the Rcpp::Rcout output stream gets redirected to R's buffered output. In other words, R's own output and that eminating from C++ code using Rcpp::Rcout are now both in sync. This avoids a stern warning from Section 5.6 in the Writing R Extensions manual:
Using C++ iostreams, as in this example, is best avoided. There is no guarantee that the output will appear in the R console, and indeed it will not on the R for Windows console. Use R code or the C entry points (*note Printing) for all I/O if at all possible.
and does in fact provide exactly what is recommended: the same entry points R itself uses. Below is a sample program, once again using the wonderful inline package to compile, load and link C++ code into R from a simple text variable submitted to the cxxfunction. What is shown in R code to load the package, the definition of the C++ code as assigned to a variable src and the creation of the dynamically-loadaded R function called fun which contains the code from we compiled, link and load via a single call to cxxfunction() given src.
library
library(inline)
src <- '
  Rcpp::Rcout << "Armadillo version: " << arma::arma_version::as_string() << std::endl;
  // directly specify the matrix size (elements are uninitialised)
  arma::mat A(2,3);
  // .n_rows = number of rows    (read only)
  // .n_cols = number of columns (read only)
  Rcpp::Rcout << "A.n_rows = " << A.n_rows << std::endl;
  Rcpp::Rcout << "A.n_cols = " << A.n_cols << std::endl;
  // directly access an element (indexing starts at 0)
  A(1,2) = 456.0;
  A.print("A:");
  // scalars are treated as a 1x1 matrix,
  // hence the code below will set A to have a size of 1x1
  A = 5.0;
  A.print("A:");
  // if you want a matrix with all elements set to a particular value
  // the .fill() member function can be used
  A.set_size(3,3);
  A.fill(5.0);
  A.print("A:");
  arma::mat B;
  // endr indicates "end of row"
  B << 0.555950 << 0.274690 << 0.540605 << 0.798938 << arma::endr
    << 0.108929 << 0.830123 << 0.891726 << 0.895283 << arma::endr
    << 0.948014 << 0.973234 << 0.216504 << 0.883152 << arma::endr
    << 0.023787 << 0.675382 << 0.231751 << 0.450332 << arma::endr;
  // print to the cout stream
  // with an optional string before the contents of the matrix
  B.print("B:");
  // the << operator can also be used to print the matrix
  // to an arbitrary stream (cout in this case)
  Rcpp::Rcout << "B:" << std::endl << B << std::endl;
  // save to disk
  B.save("B.txt", arma::raw_ascii);
  // load from disk
  arma::mat C;
  C.load("B.txt");
  C += 2.0 * B;
  C.print("C:");
  // submatrix types:
  //
  // .submat(first_row, first_column, last_row, last_column)
  // .row(row_number)
  // .col(column_number)
  // .cols(first_column, last_column)
  // .rows(first_row, last_row)
  Rcpp::Rcout << "C.submat(0,0,3,1) =" << std::endl;
  Rcpp::Rcout << C.submat(0,0,3,1) << std::endl;
  // generate the identity matrix
  arma::mat D = arma::eye<arma::mat>(4,4);
  D.submat(0,0,3,1) = C.cols(1,2);
  D.print("D:");
  // transpose
  Rcpp::Rcout << "trans(B) =" << std::endl;
  Rcpp::Rcout << trans(B) << std::endl;
  // maximum from each column (traverse along rows)
  Rcpp::Rcout << "max(B) =" << std::endl;
  Rcpp::Rcout << max(B) << std::endl;
  // maximum from each row (traverse along columns)
  Rcpp::Rcout << "max(B,1) =" << std::endl;
  Rcpp::Rcout << max(B,1) << std::endl;
  // maximum value in B
  Rcpp::Rcout << "max(max(B)) = " << max(max(B)) << std::endl;
  // sum of each column (traverse along rows)
  Rcpp::Rcout << "sum(B) =" << std::endl;
  Rcpp::Rcout << sum(B) << std::endl;
  // sum of each row (traverse along columns)
  Rcpp::Rcout << "sum(B,1) =" << std::endl;
  Rcpp::Rcout << sum(B,1) << std::endl;
  // sum of all elements
  Rcpp::Rcout << "sum(sum(B)) = " << sum(sum(B)) << std::endl;
  Rcpp::Rcout << "accu(B)     = " << accu(B) << std::endl;
  // trace = sum along diagonal
  Rcpp::Rcout << "trace(B)    = " << trace(B) << std::endl;
  Rcpp::Rcout << std::endl;
'
fun <- cxxfunction(signature(), body=src, plugin="RcppArmadillo")
setwd("/tmp")                           # adjust on other OSs
fun()                                   # output to stdout
sink("rcpparma.log.txt")                # start 'sink' to output to file
fun()                                   # no output to screen
sink()                                  # stop 'sink'
We then switch to a temporary directory (as the example code, taken from one of the two examples in Conrad's Armadillo sources, creates a temporary file) and run the new function. To demontrate how it does in fact now mesh perfectly with R, we create an output 'sink' (which catches all output) and re-run. This simple example demonstrated how we can use the new Rcout output stream from Rcpp to have dynamically-loaded C++ code cooperate more cleanly with the (buffered) R output. It also demontrated some of the nice features in Armadillo which we bring to R via RcppArmadillo.
Andrea Veri: Nagios XMPP Notifications for GTalk

While improving GNOME s servers Nagios Notifications, I ended up working on a nice way to notify the relevant folks through GTalk in case something could go wrong on any of the hosted services. Looking around on the web, I found Seth Vidal s script, modified it to suit my needs and made it working with GTalk, here s the result:
#!/usr/bin/python -tt
import warnings
warnings.simplefilter("ignore")
import xmpp
from xmpp.protocol import Message
from optparse import OptionParser
import ConfigParser
import sys
import os
parser = OptionParser()
opts, args = parser.parse_args()
if len(args) < 1:
    print "xmppsend message [to whom, multiple args]"
    sys.exit(1)
msg = args[0]
msg = msg.replace('\\n', '\n')
# Connect to the server
c  =  xmpp.Client('gmail.com')
c.connect( ( 'talk.google.com', 5223 ) )
# Authenticate to the server
jid  =  xmpp.protocol.JID( 'example@gmail.com' )
c.auth( jid.getNode( ), 'yourgmailpassword' )
if len(args) < 2:
    r = c.getRoster()
    for user in r.keys():
        if user == username:
            continue
        c.send(Message(user, '%s' % msg))
else:
    for user in args[1:]:
        c.send(Message(user, '%s' % msg))
I, then, added the command definitions on the relevant Nagios configuration file:
define command 
        command_name    host-notify-by-xmpp
        command_line    /home/user/bin/xmppsend "Host '$HOSTALIAS$' is $HOSTSTATE$ - Info : $HOSTOUTPUT$" $CONTACTPAGER$
         
define command 
        command_name    notify-by-xmpp
        command_line    /home/user/bin/xmppsend "$NOTIFICATIONTYPE$ $HOSTNAME$ $SERVICEDESC$ $SERVICESTATE$ $SERVICEOUTPUT$ $LONGDATETIME$" $CONTACTPAGER$
         
And in the end on contacts.cfg:
define contact  
        contact_name    admin
        use             generic-contact
        alias           Full Name
        email           example@gmail.com
        pager           example@gmail.com
        service_notification_commands   notify-by-xmpp
        host_notification_commands      host-notify-by-xmpp
 
When done just reload the configuration files with:
sudo /etc/init.d/nagios3 reload
Enjoy your new XMPP Nagios notifications! Update: if you don t want the script to store your username or password, you can use the following modified script together with a nice config file like this one:
[xmpp_nagios]
username=example@gmail.com
password=yourgmailpassword
Then you can invoke xmppsend this way:
xmppsend -a config.ini

Neil Williams: Introducing ladder

We needed a new package at work and once I'd written it, I realised that it could well be useful for others, so I did the ITP and the package is now in Debian unstable.

Ladder - Stepwise repository upgrade tool

Ladder creates a local repository of packages required
to upgrade a tarball of a chroot to a new milestone or
software release.
.
The repository can be signed and includes all specified
target packages and dependencies. The repository can then
be distributed and used to upgrade multiple devices in
sequence without needing network access.


The only dependencies are some simple perl modules, reprepro for the repository, apt and gnupg for the signing. None of those need to be particularly recent versions, so once ladder has had a little time in testing, I will be doing a backport to Squeeze. Lenny is a little less likely but eminently possible if someone specifically asks for it. Not that it particularly needs a backport mind, if you want to run ladder on some other Debian-based system, it's simply a case of installing the version in unstable. reprepro was in Lenny at a suitable version for what ladder requires, so any system remotely recent should be able to run ladder without changes.

Normally, whenever you need to upgrade a device, you need to get that device onto a network, get access over the serial port or some form of pre-configured network connection, run the commands and clean up afterwards. OK, now do that again... oh and here are another 40 or 100 devices which all need precisely the same thing done and they all have to be shipped to paying customers today. What does any geek do? Script it.

Ladder is part of that process. There would need to be some scripting / programming support on the devices concerned but ladder makes it easier to put that support in place at the design stage and then automate the actual update without the device needing to get onto a network and, potentially, allowing you to decide how to offer the upgrade (automatic, user involvement, engineers only etc.) Once that is implemented, the device is simply pointed at a locally mounted filesystem which contains the ladder step for the migration. Each step is a SecureApt signed repository which is available at a deterministic location which can be easily scripted and which contains only the packages necessary (with dependencies) to upgrade any device installed at Milestone A to Milestone B. Nice and small, only the stuff you need, whatever architecture you like and if you need to migrate from Milestone A to Milestone D, then you create a few steps on the ladder and automate the migration from A to B to C to D. All you need is enough space on whatever local media you need to use to plug into the devices. Then copy the media enough times, start the interface on each device and do something useful whilst the upgrade happens. Then, when the next lot need to be upgraded, you already have the media... Oh and ladder does not need to run on the same architecture as the devices - all package handling is entirely architecture-neutral. So create the ladder steps and media on your fast x86 machines and then let the slower SSD devices take their own sweet time via automation. Simple - maybe, hopefully.

I'm expressly talking about devices here because this is where the original requirement arose - embedded devices which don't have direct / automatic / accessible network ports or even a working network configuration preset. These aren't new images to flash onto the device either, these are apt repositories, so only the stuff which needs to be changed is changed which saves a lot of time writing to slow SSD storage.

If the mechanism sounds familiar, yes, it's using the same principles as xapt, multistrap and emdebian-grip but I thought it could be useful, so I generalised the interface (a bit) and uploaded.

Let me know via the BTS if you need tweaks to the support. Ladder isn't particularly about getting desktop machines from Debian Potato to Debian Wheezy because you need to identify a target package to be the top point of the dependency chain which gets into the step repository and all devices should start with the same packages at the same versions. Normally, the kind of devices I use at work have a single top level application which is the sole user interface and which directly or indirectly depends on all the other software required for that device. Whilst the target package value could take a few carefully selected packages instead of just one and there is support for an extra packages field, it's not intended / expected to be useful for desktops. This is for use with multiple devices which all have the same package selection, are at the same milestone at the start and which all need to migrate smoothly to whatever milestone is intended - one step at a time. Ladder could be used to migrate between Debian releases and I've included example config files to support that, but the principle usage is with internal / proprietary repositories based on a common Debian stable platform where the user interface software is managed via identifiable milestones and where users have no direct control over installing packages. It's a production / manufacturing support tool more than a user / admin support tool. If you want to manage servers and desktops which allow users to install (or request to be installed) arbitrary packages, there are plenty of tools which already support this and are used by DSA in Debian for exactly these tasks. Ladder is not puppet but Linp didn't sound like a good name...

Ladder step repositories only include the binary packages, not sources - so if the migration is not going to be done in-house and you're expecting to distribute these steps to users somehow, ensure that the original source repository is available online for the Debian / free software packages concerned. If you can't do that (because the source is proprietary), you possibly shouldn't be distributing the binaries as a user update mechanism in the first place because each step will include packages from the core Debian system which need to have the sources available when distributed.

Inevitably, the ladder source package already contains two POT files for translations of the runtime messages and the POD based manpage. I expect to need to expand / clarify the manpage in due course, so don't rush to translate it yet as it's likely to change.

Mike Hommey: Debian Mozilla news

Here are the few noteworthy news about Mozilla packages in Debian:

Mike Hommey: How to waste a lot of space without knowing

const char *foo = "foo";
This was recently mentioned on bugzilla, and the problem is usually underestimated, so I thought I would give some details about what is wrong with the code above. The first common mistake here is to believe foo is a constant. It is a pointer to a constant. In practical ELF terms, this means the pointer lives in the .data section, and the string constant in .rodata. The following code defines a constant pointer to a constant:
const char * const foo = "foo";
The above code will put both the pointer and the string constant in .rodata. But keeping a constant pointer to a constant string is pointless. In the above examples, the string itself is 4 bytes (3 characters and a zero termination). On 32-bits architectures, a pointer is 4 bytes, so storing the pointer and the string takes 8 bytes. A 100% overhead. On 64-bits architectures, a pointer is 8 bytes, putting the total weight at 12 bytes, a 200% overhead. The overhead is always the same size, though, so the longer the string, the smaller the overhead, relatively to the string size. But there is another, not well known, hidden overhead: relocations. When loading a library in memory, its base address varies depending on how many other libraries were loaded beforehand, or depending on the use of address space layout randomization (ASLR). This also applies to programs built as position independent executables (PIE). For pointers embedded in the library or program image to point to the appropriate place, they need to be adjusted to the base address where the program or library is loaded. This process is called relocation. The relocation process requires information which is stored in .rel.* or .rela.* ELF sections. Each pointer needs one relocation. The relocation overhead varies depending on the relocation type and the architecture. REL relocations use 2 words, and RELA relocations use 3 words, where a word is 4 bytes on 32-bits architectures and 8 bytes on 64-bits architectures. On x86 and ARM, to mention the most popular 32-bits architectures nowadays, REL relocations are used, which makes a relocation weigh 8 bytes. This puts the pointer overhead for our example string to 12 bytes, or 300% of the string size. On x86-64, RELA relocations are used, making a relocation weigh 24 bytes! This puts the pointer overhead for our example string to 32 bytes, or 800% of the string size! Another hidden cost of using a pointer to a constant is that every time it is used in the code, there will be pointer dereference. A function as simple as
int bar() return foo;
weighs one instruction more when foo is defined const char *. On x86, that instruction weighs 2 bytes. On x86-64, 3 bytes. On ARM, 4 bytes (or 2 in Thumb). That weight can vary depending on the additional instructions required, but you get the idea: using a pointer to a constant also adds overhead to the code, both in time and space. Also, if the string is defined as a constant instead of being used as a literal in the code, chances are it s used several times, multiplying the number of such instructions. Update: Note that in the case of const char * const, the compiler will optimize these instruction and avoid reading the pointer, since it s never going to change. The symbol for foo is also exported, making it available from other libraries or programs, which might not be required, but also adds its own overhead: an entry in the symbols table (5 words), an entry in the string table for the symbol name (strlen("foo") + 1) and an entry in the symbols hash chain table (4 bytes if only one type of hash table (sysv or GNU) is present, 8 if both are present), and possibly an entry in the symbols hash bucket table, depending on the other exported symbols (4 or 8 bytes, as chain table). It can also affect the size of the bloom filter table in the GNU symbol hash table. So here we are, with a seemingly tiny 3 character string possibly taking 64 bytes or more! Now imagine what happens when you have an array of such tiny strings. This also doesn t only apply to strings, it applies to any kind of global pointer to constants. In conclusion, using a definition like
const char *foo = "foo";
is almost never what you want. Instead, you want to use one of the following forms:

Next.

Previous.