Search Results: "spa"

22 March 2022

Norbert Preining: Packages for Debian: KDE/Plasma, RSSguard, et al

As mentioned in this post, most of my activity around Debian has come to a complete halt (Send your thanks to da-manager@debian.org!). Since I still have a few computers running Debian, I keep maintaining a few things which I heavily rely on, in particular KDE/Plasma and RSSguard. For KDE/Plasma, there are the well known OBS repos I maintain, please read the blog posts tagged KDE. For RSSguard, I just uploaded a package for the recently released RSSguard 4.2.0 to a new OBS project debian-various. To activate this repository, first of all, you need to add my OBS key say in /usr/local/share/keyrings/obs-npreining.asc and add a file /etc/apt/sources.list.d/obs-npreining-various.list, containing the following line, replacing the DISTRIBUTION part with one of Debian_11 (for Bullseye), Debian_Testing, or Debian_Unstable:
deb [signed-by=/usr/local/share/keyrings/obs-npreining.asc] https://download.opensuse.org/repositories/home:/npreining:/debian-various/DISTRIBUTION/ ./
With that in place you will get a fresh and new rssguard. I will add more packages over time, typical candidates are rspamd and all the other none-KDE/Plasma packages I maintained. Enjoy.

21 March 2022

Gunnar Wolf: Long, long, long live Emacs after 39 years

Reading Planet Debian (see, Sam, we are still having a conversation over there? ), I read Anarcat s 20+ years of Emacs. And.. Well, should I brag contribute to the discussion? Of course, why not? Emacs is the first computer program I can name that I ever learnt to use to do something minimally useful. 39 years ago.
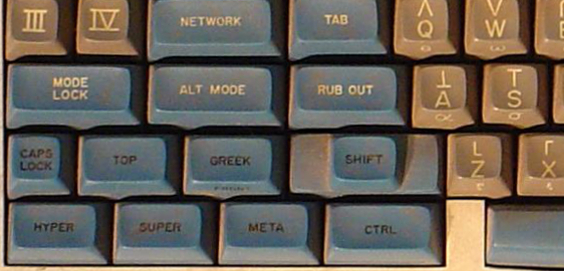
From the Space Cadet keyboard that (obviously ) influenced Emacs early design
The Emacs editor was born, according to Wikipedia, in 1976, same year as myself. I am clearly not among its first users. It was already a well-established citizen when I first learnt it; I am fortunate to be the son of a Physics researcher at UNAM, My father used to take me to his institute after he noticed how I was attracted to computers; we would usually spend some hours there between 7 and 11PM on Friday nights. His institute had a computer room where they had very sweet gear: Some 10 Heathkit terminals quite similar to this one: The terminals were connected (via individual switches) to both a PDP-11 and a Foonly F2 computers. The room also had a beautiful thermal printer, a beautiful Tektronix vectorial graphics output terminal, and some other stuff. The main user for my father was to typeset some books; he had recently (1979) published Integral Transforms in Science and Engineering (that must be my first mention in scientific literature), and I remember he was working on the proceedings of a conference he held in Oaxtepec (the account he used in the system was oax, not his usual kbw, which he lent me). He was also working on Manual de Lenguaje y Tipograf a Cient fica en Castellano, where you can see some examples of TeX; due to a hardware crash, the book has the rare privilege of being a direct copy of the output of the thermal printer: It was not possible to produce a higher resolution copy for several years But it is fun and interesting to see what we were able to produce with in-house tools back in 1985! So, what could he teach me so I could use the computers while he worked? TeX, of course. No, no LaTeX (that was published in 1984). LaTeX is a set of macros developed initially by Leslie Lamport, used to make TeX easier; TeX was developed by Donald Knuth, and if I have this information correct, it was Knuth himself who installed and demonstrated TeX in the Foonly computer, during a visit to UNAM. Now, after 39 years hammering at Emacs buffers Have I grown extra fingers? Nope. I cannot even write decent elisp code, and can barely read it. I do use org-mode (a lot!) and love it; I have written basically five books, many articles and lots of presentations and minor documents with it. But I don t read my mail or handle my git from Emacs. I could say, I m a relatively newbie after almost four decades. Four decades When we got a PC in 1986, my father got the people at the Institute to get him memacs (micro-emacs). There was probably a ten year period I barely used any emacs, but always recognized it. My fingers hve memorized a dozen or so movement commands, and a similar number of file management commands. And yes, Emacs and TeX are still the main tools I use day to day.

20 March 2022

Joerg Jaspert: Another shell script moved to rust

Shell? Rust! Not the first shell script I took and made a rust version of, but probably my largest yet. This time I took my little tm (tmux helper) tool which is (well, was) a bit more than 600 lines of shell, and converted it to Rust. I got most of the functionality done now, only one major part is missing.

What s tm? tm started as a tiny shell script to make handling tmux easier. The first commit in git was in July 2013, but I started writing and using it in 2011. It started out as a kind-of wrapper around ssh, opening tmux windows with an ssh session on some other hosts. It quickly gained support to open multiple ssh sessions in one window, telling tmux to synchronize input (send input to all targets at once), which is great when you have a set of machines that ought to get the same commands.

tm vs clusterssh / mussh In spirit it is similar to clusterssh or mussh, allowing to run the same command on many hosts at the same time. clusterssh sets out to open new terminals (xterm) per host and gives you an input line, that it sends everywhere. mussh appears to take your command and then send it to all the hosts. Both have disadvantages in my opinion: clusterssh opens lots of xterm windows, and you can not easily switch between multiple sessions, mussh just seems to send things over ssh and be done. tm instead just creates a tmux session, telling it to ssh to the targets, possibly setting the tmux option to send input to all panes. And leaves all the rest of the handling to tmux. So you can
  • detach a session and reattach later easily,
  • use tmux great builtin support for copy/paste,
  • see all output, modify things even for one machine only,
  • zoom in to one machine that needs just ONE bit different (cssh can do this too),
  • let colleagues also connect to your tmux session, when needed,
  • easily add more machines to the mix, if needed,
  • and all the other extra features tmux brings.

More tm tm also supports just attaching to existing sessions as well as killing sessions, mostly for lazyness (less to type than using tmux directly). At some point tm gained support for setting up sessions according to some session file . It knows two formats now, one is simple and mostly a list of hostnames to open synchronized sessions for. This may contain LIST commands, which let tm execute that command, expected output is list of hostnames (or more LIST commands) for the session. That, combined with the replacement part, lets us have one config file that opens a set of VMs based on tags our Ganeti runs, based on tags. It is simply a LIST command asking for VMs tagged with the replacement arg and up. Very handy. Or also all VMs on host X . The second format is basically free form tmux commands . Mostly commandline tmux call, just drop the tmux in front collection. Both of them supporting a crude variable replacement.

Conversion to Rust Some while ago I started playing with Rust and it somehow clicked , I do like it. My local git tells me, that I tried starting off with go in 2017, but that appearently did not work out. Fun, everywhere I can read says that Rust ought to be harder to learn. So by now I have most of the functionality implemented in the Rust version, even if I am sure that the code isn t a good Rust example. I m learning, after all, and already have adjusted big parts of it, multiple times, whenever I learn (and understand) something more - and am also sure that this will happen again

Compatibility with old tm It turns out that my goal of staying compatible with the behaviour of the old shell script does make some things rather complicated. For example, the LIST commands in session config files - in shell I just execute them commands, and shell deals with variable/parameter expansion, I just set IFS to newline only and read in what I get back. Simple. Because shell is doing a lot of things for me. Now, in Rust, it is a different thing at all:
  • Properly splitting the line into shell words, taking care of quoting (can t simply take whitespace) (there is shlex)
  • Expanding specials like ~ and $HOME (there is home_dir).
  • Supporting environment variables in general, tm has some that adjust behaviour of it. Which shell can use globally. Used lazy_static for a similar effect - they aren t going to change at runtime ever, anyways.
Properly supporting the commandline arguments also turned out to be a bit more work. Rust appearently has multiple crates supporting this, I settled on clap, but as tm supports getopts -style as well as free-form arguments (subcommands in clap), it takes a bit to get that interpreted right.

Speed Most of the time entirely unimportant in the tool that tm is (open a tmux with one to some ssh connections to some places is not exactly hard or time consuming), there are situations, where one can notice that it s calling out to tmux over and over again, for every single bit to do, and that just takes time: Configurations that open sessions to 20 and more hosts at the same time especially lag in setup time. (My largest setup goes to 443 panes in one window). The compiled Rust version is so much faster there, it s just great. Nice side effect, that is. And yes, in the end it is also only driving tmux, still, it takes less than half the time to do so.

Code, Fun parts As this is still me learning to write Rust, I am sure the code has lots to improve. Some of which I will sure find on my own, but if you have time, I love PRs (or just mails with hints).

Github Also the first time I used Github Actions to see how it goes. Letting it build, test, run clippy and also run a code coverage tool (Yay, more than 50% covered ) on it. Unsure my tests are good, I am not used to writing tests for code, but hey, coverage!

Up next I do have to implement the last missing feature, which is reading the other config file format. A little scared, as that means somehow translating those lines into correct calls within the tmux_interface I am using, not sure that is easy. I could be bad and just shell out to tmux on it all the time, but somehow I don t like the thought of doing that. Maybe (ab)using the control mode, but then, why would I use tmux_interface, so trying to handle it with that first. Afterwards I want to gain a new command, to save existing sessions and be able to recreate them easily. Shouldn t be too hard, tmux has a way to get at that info, somewhere.

18 March 2022

Enrico Zini: Context-dependent logger in Python

This is a common logging pattern in Python, to have loggers related to module names:
import logging
log = logging.getLogger(__name__)
class Bill:
    def load_bill(self, filename: str):
        log.info("%s: loading file", filename)
I often however find myself wanting to have loggers related to something context-dependent, like the kind of file that is being processed. For example, I'd like to log loading of bill loading when done by the expenses module, and not when done by the printing module. I came up with a little hack that keeps the same API as before, and allows to propagate a context dependent logger to the code called:
# Call this file log.py
from __future__ import annotations
import contextlib
import contextvars
import logging
_log: contextvars.ContextVar[logging.Logger] = contextvars.ContextVar('log', default=logging.getLogger())
@contextlib.contextmanager
def logger(name: str):
    """
    Set a default logger for the duration of this context manager
    """
    old = _log.set(logging.getLogger(name))
    try:
        yield
    finally:
        _log.reset(old)
def debug(*args, **kw):
    _log.get().debug(*args, **kw)
def info(*args, **kw):
    _log.get().info(*args, **kw)
def warning(*args, **kw):
    _log.get().warning(*args, **kw)
def error(*args, **kw):
    _log.get().error(*args, **kw)
And now I can do this:
from . import log
#  
    with log.logger("expenses"):
        bill = load_bill(filename)
# This code did not change!
class Bill:
    def load_bill(self, filename: str):
        log.info("%s: loading file", filename)

17 March 2022

Raphaël Hertzog: Freexian s report about Debian Long Term Support, February 2022

A Debian LTS logo
Every month we review the work funded by Freexian s Debian LTS offering. Please find the report for February below. Debian project funding Debian LTS contributors In February, 12 contributors were paid to work on Debian LTS, their reports are available below. If you re interested in participating in the LTS or ELTS teams, we welcome participation from the Debian community. Simply get in touch with Jeremiah or Rapha l if you are if you are interested in participating. Evolution of the situation In February we released 24 DLAs. The security tracker currently lists 61 packages with a known CVE and the dla-needed.txt file has 26 packages needing an update. You can find out more about the Debian LTS project via the following video:
Thanks to our sponsors Sponsors that joined recently are in bold.

16 March 2022

Michael Ablassmeier: python logging messages and exit codes

Everyone knows that an application exit code should change based on the success, error or maybe warnings that happened during execution. Lately i came along some python code that was structured the following way:
#!/usr/bin/python3
import sys
import logging
def warnme():
    # something bad happens
    logging.warning("warning")
    sys.exit(2)
def evil():
    # something evil happens
    logging.error("error")
    sys.exit(1)
def main():
    logging.basicConfig(
        level=logging.DEBUG,
    )   
    [..]
the situation was a little bit more complicated, some functions in other modules also exited the application, so sys.exit() calls were distributed in lots of modules an files. Exiting the application in some random function of another module is something i dont consider nice coding style, because it makes it hard to track down errors. I expect:

How to do better? As the application is using the logging module, we have a single point to collect warnings and errors that might happen accross all modules. This works by passing a custom handler to the logging module which tracks emitted messages. Heres an small example:
#!/usr/bin/python3
import sys
import logging
class logCount(logging.Handler):
    class LogType:
        def __init__(self):
            self.warnings = 0
            self.errors = 0
    def __init__(self):
        super().__init__()
        self.count = self.LogType()
    def emit(self, record):
        if record.levelname == "WARNING":
            self.count.warnings += 1
        if record.levelname == "ERROR":
            self.count.errors += 1
            
def infome():
    logging.info("hello world")
def warnme():
    logging.warning("help, an warning")
def evil():
    logging.error("yikes")
def main():
    EXIT_WARNING = 2
    EXIT_ERROR = 1
    counter = logCount()
    logging.basicConfig(
        level=logging.DEBUG,
        handlers=[counter, logging.StreamHandler(sys.stderr)],
    )
    infome()
    warnme()
    evil()
    if counter.count.errors != 0:
        raise SystemExit(EXIT_ERROR)
    if counter.count.warnings != 0:
        raise SystemExit(EXIT_WARNING)
if __name__ == "__main__":
    main()
python3 count.py ; echo $?
INFO:root:hello world
WARNING:root:help, an warning
ERROR:root:yikes
1
This also makes easy to define something like:
  • hey, got 2 warnings, change exit code to error?
  • got 3 warnings, but no strict passed, ingore those, exit with success!
  • etc..

15 March 2022

Russell Coker: Librem 5 First Impression

I just received the Purism Librem 5 that I paid for years ago (I think it was 2018). The process of getting the basic setup done was typical (choosing keyboard language, connecting to wifi, etc). Then I tried doing things. One thing I did was update to the latest PureOS release which gave me a list of the latest Debian packages installed which is nice. The first problem I found was the lack of notification when the phone is trying to do something. I d select to launch an app, nothing would happen, then a few seconds later it would appear. When I go to the PureOS app store and get a list of apps in a category nothing happens for ages (shows a blank list) then it might show actual apps, or it might not. I don t know what it s doing, maybe downloading a list of apps, if so it should display how many apps have had their summary data downloaded or how many KB of data have been downloaded so I know if it s doing something and how long it might take. Running any of the productivity applications requires a GNOME keyring, I selected a keyring password of a few characters and it gave a warning about having no password (does this mean it took 3 characters to be the same as 0 characters?). Then I couldn t unlock it later. I tried deleting the key file and creating a new one with a single character password and got the same result. I think that such keyring apps have little benefit, all processes in the session have the same UID and presumable can use ptrace to get data from each other s memory space. If the keyring program was SETGID and the directory used to store the keyring files was a system directory with execute access only for that group then it might provide some benefit (SETGID means that ptrace is denied). Ptrace is denied for the keyring but relying on a user space prompt for the passphrase to a file that the user can read seems of minimal benefit as a hostile process could read the file and prompt for the passphrase. This is probably more of a Debian issue, and I reproduced the keyring issue with my Debian workstation. The Librem 5 is a large phone (unusually thick by modern phone standards) and is rumoured to be energy hungry. When I tried charging it from the USB port on my PC (HP ML110 Gen9) the charge level went down. I used the same USB port and USB cable that I use to charge my Huawei Mate 10 Pro every day, so other phones can draw more power from that USB port and cable faster than they use it. The on-sceen keyboard for the Librem 5 is annoying, it doesn t have a TAB key and the cursor control keys are unreasonably small. The keyboard used by ConnectBot (the most popular SSH client for Android) is much better, it has it s own keys for CTRL, ESC, TAB, arrows, HOME, and END in addition to the regular on-screen keyboard. The Librem 5 comes with a terminal app by default which is much more difficult to use than it should be due to the lack of TAB filename completion etc. The phone has a specified temperature range of 0C to 35C, that s not great for Australia where even the cooler cities have summer temperatures higher than that. When charging on a fast charger (one that can provide energy faster than the phone uses it) the phone gets quite warm. It feels like more than 10C hotter than the ambient temperature, so I guess I can t charge it on Monday afternoon when the forecast is 31C! Maybe I should put a USB charger by my fridge with a long enough cable that I can charge a phone that s inside the fridge, seriously. Having switches to disable networking is a good security feature and designing the phone with separate components that can t interfere with each other is good too. There are reports that software fixes will reduce the electricity use which will alleviate the problems with charging and temperature. Most of my problems are clearly software related and therefore things that I can fix (in theory at least I don t have unlimited coding time). Overall this wasn t the experience I had hoped for after spending something like $700 and waiting about 4 years (so long that I can t easily find the records of how long and how much money). Getting It Working It seems that the PureOS app store app doesn t work properly. I can visit the app site and then select an app to install which then launches the app store app to do the install, which failed for every app I tried. Then I tried going to the terminal and running the following:
sudo bash
apt update
apt install openssh-server netcat
So I should be able to use APT to install everything I want and use the PureOS web site as a guide to what is expected to work on the phone. As an aside the PureOS apt repository appears to be a mirror or rebuild of the Debian/Bullseye arm64 archive without non-free components that they call Byzanteum. Then I could ssh to my phone via ssh purism@purism (after adding an entry to /etc/hosts with the name purism and a static entry in my DHCP configuration to match) and run sudo bash to get root. To be able to login to root directly I had to install a ssh key (root is setup to login without password) and run usermod --expiredate= root (empty string for expire date) to have direct root logins. I put the following in /etc/ssh/sshd_config.d/local.conf to restrict who can login (I added the users I want to the sshusers group). It also uses the ClientAlive checks because having sessions break due to IP address changes is really common with mobile devices and we don t want disconnected sessions taking up memory forever.
AllowGroups sshusers
PasswordAuthentication no
UseDNS no
ClientAliveInterval 60
ClientAliveCountMax 6
Notifications The GNOME notification system is used for notifications in the phone UI. So if you install the package libnotify-bin you get a utility notify-send that allows sending notifications from shell scripts. Final Result Now it basically works as a Debian workstation with a single-button mouse. So I just need to configure it as I would a Debian system and fix bugs along the way. Presumably any bug fixes I get into Debian will appear in PureOS shortly after the next Debian release.

Kunal Mehta: How to mirror the Russian Wikipedia with Debian and Kiwix

It has been reported that the Russian government has threatened to block access to Wikipedia for documenting narratives that do not agree with the official position of the Russian government. One of the anti-censorship strategies I've been working on is Kiwix, an offline Wikipedia reader (and plenty of other content too). Kiwix is free and open source software developed by a great community of people that I really enjoy working with. With threats of censorship, traffic to Kiwix has increased fifty-fold, with users from Russia accounting for 40% of new downloads! You can download copies of every language of Wikipedia for offline reading and distribution, as well as hosting your own read-only mirror, which I'm going to explain today. Disclaimer: depending on where you live it may be illegal or get you in trouble with the authorities to rehost Wikipedia content, please be aware of your digital and physical safety before proceeding. With that out of the way, let's get started. You'll need a Debian (or Ubuntu) server with at least 30GB of free disk space. You'll also want to have a webserver like Apache or nginx installed (I'll share the Apache config here). First, we need to download the latest copy of the Russian Wikipedia.
$ wget 'https://download.kiwix.org/zim/wikipedia/wikipedia_ru_all_maxi_2022-03.zim'
If the download is interrupted or fails, you can use wget -c $url to resume it. Next let's install kiwix-serve and try it out. If you're using Ubuntu, I strongly recommend enabling our Kiwix PPA first.
$ sudo apt update
$ sudo apt install kiwix-tools
$ kiwix-serve -p 3004 wikipedia_ru_all_maxi_2022-03.zim
At this point you should be able to visit http://yourserver.com:3004/ and see the Russian Wikipedia. Awesome! You can use any available port, I just picked 3004. Now let's use systemd to daemonize it so it runs in the background. Create /etc/systemd/system/kiwix-ru-wp.service with the following:
[Unit]
Description=Kiwix Russian Wikipedia
[Service]
Type=simple
User=www-data
ExecStart=/usr/bin/kiwix-serve -p 3004 /path/to/wikipedia_ru_all_maxi_2022-03.zim
Restart=always
[Install]
WantedBy=multi-user.target
Now let's start it and enable it at boot:
$ sudo systemctl start kiwix-ru-wp
$ sudo systemctl enable kiwix-ru-wp
Since we want to expose this on the public internet, we should put it behind a more established webserver and configure HTTPS. Here's the Apache httpd configuration I used:
<VirtualHost *:80>
        ServerName ru-wp.yourserver.com
        ServerAdmin webmaster@localhost
        DocumentRoot /var/www/html
        ErrorLog $ APACHE_LOG_DIR /error.log
        CustomLog $ APACHE_LOG_DIR /access.log combined
        <Proxy *>
                Require all granted
        </Proxy>
        ProxyPass / http://127.0.0.1:3004/
        ProxyPassReverse / http://127.0.0.1:3004/
</VirtualHost>
Put that in /etc/apache2/sites-available/kiwix-ru-wp.conf and run:
$ sudo a2ensite kiwix-ru-wp
$ sudo systemctl reload apache2
Finally, I used certbot to enable HTTPS on that subdomain and redirect all HTTP traffic over to HTTPS. This is an interactive process that is well documented so I'm not going to go into it in detail. You can see my mirror of the Russian Wikipedia, following these instructions, at https://ru-wp.legoktm.com/. Anyone is welcome to use it or distribute the link, though I am not committing to running it long-term. This is certainly not a perfect anti-censorship solution, the copy of Wikipedia that Kiwix provides became out of date the moment it was created, and the setup described here will require you to manually update the service when the new copy is available next month. Finally, if you have some extra bandwith, you can also help seed this as a torrent.

10 March 2022

Michael Ablassmeier: fscom switch shell

fs.com s5850 and s8050 series type switches have a secret mode which lets you enter a regular shell from the switch cli, like so:
hostname # start shell
Password:
The command and password are not documented by the manufacturer, i wondered wether if its possible to extract that password from the firmware. After all: its my device, and i want to have access to all the features! Download the latest firmware image for those switch types and let binwalk do its magic:
$ wget https://img-en.fs.com/file/user_manual/s5850-and-s8050-series-switches-fsos-v7-2-5r-software.zip
binwalk FSOS-S5850-v7.2.5.r.bin  -e
This will extract an regular cpio archive, including the switch root FS:
$ file 2344D4 
2344D4: ASCII cpio archive (SVR4 with no CRC)
$ cpio --no-absolute-filenames -idv < 2344D4
The extracted files include the passwd file with hashes:
cat etc/passwd
root:$1$ZrdxfwMZ$1xAj.S6emtA7gWD7iwmmm/:0:0:root:/root:/bin/sh
nms:$1$nUbsGtA7$5omXOHPNK.ZzNd5KeekUq/:0:0:root:/ftp:/bin/sh
Let john do its job:
$ wget https://github.com/brannondorsey/naive-hashcat/releases/download/data/rockyou.txt
$ sudo john etc/passwd  --wordlist=rockyou.txt
<the_password>   (nms)
<the_password>   (root)
2g 0:00:04:03 100% 0.008220g/s 58931p/s 58935c/s 58935C/s nancy..!*!hahaha!*!
Thats it (wont reveal the password here, but well: its an easy one ;)) Now have fun poking around on your switches firmware:
hostname # start shell
Password: <the_password>
[root@hostname /mnt/flash]$ ps axw
  PID TTY      STAT   TIME COMMAND
    1 ?        Ss     0:29 init
    2 ?        S      0:06 [kthreadd]
 [..]
[root@hostname /mnt/flash]$ uname -a
Linux hostname 2.6.35-svn37723 #1 Thu Aug 22 20:43:19 CST 2019 ppc unknow
even tho the good things wont work, but i guess its time to update the firmware anyways:
[root@hostname /mnt/flash]$ tcpdump -pni vlan250
tcpdump: can't get TPACKET_V3 header len on packet socket: Invalid argument

9 March 2022

Dirk Eddelbuettel: RcppRedis 0.2.0: Major Updates

A new major release of RcppRedis arrived on CRAN today. RcppRedis is one of several packages connecting R to the fabulous Redis in-memory datastructure store (and much more). RcppRedis does not pretend to be feature complete, but it may do some things faster than the other interfaces, and also offers an optional coupling with MessagePack binary (de)serialization via RcppMsgPack. The package has carried production loads for several years now. This release integrates support for pub/sub, a popular messaging pattern in which one or more clients can subscribe to one or more channels . Whenever a client instances publishes, the Redis server immediately updates all clients listening on the given channel. This pattern is fairly common to transmit data to listeners. A there is a bit more to explain about this, I also added a brand-new vignette describing pub/sub with RcppRedis, along with another introductory vignette about Redis itself. We blogged about this exciting new feature and its particular use for market monitoring in R4 #36 recently too. The pub/sub feature was available in package rredis by Bryan Lewis and has now been ported over by Bryan in a truly elegant yet compact implementation. We placed the code for the pub/sub examples, both for a single symbol (SP 500) as well as for a set of (futures) symbols, into a new examples/ subdirectory. Other changes in this release are the removal of the build-dependency on Boost (or, rather, my BH package), an update to the included hiredis library (used if no system-wide version is found), and an updated to the UCRT build for R. That last one is a bit of a sore spot and nobody at CRAN deemed it necessary to tell me they were waiting for me to make this change; communication with the CRAN team can still be challenging (and I am being generous here). Anyway, the package is now on CRAN so all is well now, at long last. The detailed changes list follows.

Changes in version 0.2.0 (2022-03-08)
  • Two simple C++11 features remove needs for BH and lexical_cast() (Dirk in #45 addressing #44).
  • Redis pub/sub is now supported (Dirk in #43, Bryan in #46).
  • Bryan Lewis is now a coauthor.
  • Added pub/sub examples for single and multiple Globex symbols.
  • The included hiredis sources have been updated to release 1.0.2.
  • Two vignettes have been added to introduce Redis and to described a live market-monitoring application included in directory pubsub/.
  • The UCRT build was updated per a suggestion by Tomas.

Courtesy of CRANberries, there is also a diffstat report for this release. More information is on the RcppRedis page. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Fran ois Marier: Using a Streamzap remote control with MythTV on Debian Bullseye

After upgrading my MythTV machine to Debian Bullseye and MythTV 31, my Streamzap remote control stopped working correctly: the up and down buttons were working, but the OK button wasn't. Here's the complete solution that made it work with the built-in kernel support (i.e. without LIRC).

Button re-mapping Since some of the buttons were working, but not others, I figured that the buttons were probably not mapped to the right keys. Inspired by these old v4l-utils-based instructions, I made my own custom keymap by by copying the original keymap:
cp /lib/udev/rc_keymaps/streamzap.toml /etc/rc_keymaps/
and then modifying it to adapt it to what MythTV needs. This is what I ended up with:
<span class="createlink"><a href="/blog.cgi?do=create&amp;from=posts%2Fusing-streamzap-remote-with-mythtv-debian-bullseye&amp;page=protocols" rel="nofollow">?</a>protocols</span>
name = "streamzap"
protocol = "rc-5-sz"
[protocols.scancodes]
0x28c0 = "KEY_0"
0x28c1 = "KEY_1"
0x28c2 = "KEY_2"
0x28c3 = "KEY_3"
0x28c4 = "KEY_4"
0x28c5 = "KEY_5"
0x28c6 = "KEY_6"
0x28c7 = "KEY_7"
0x28c8 = "KEY_8"
0x28c9 = "KEY_9"
0x28ca = "KEY_ESC"
0x28cb = "KEY_MUTE"
0x28cc = "KEY_UP"
0x28cd = "KEY_RIGHTBRACE"
0x28ce = "KEY_DOWN"
0x28cf = "KEY_LEFTBRACE"
0x28d0 = "KEY_UP"
0x28d1 = "KEY_LEFT"
0x28d2 = "KEY_ENTER"
0x28d3 = "KEY_RIGHT"
0x28d4 = "KEY_DOWN"
0x28d5 = "KEY_M"
0x28d6 = "KEY_ESC"
0x28d7 = "KEY_L"
0x28d8 = "KEY_P"
0x28d9 = "KEY_ESC"
0x28da = "KEY_BACK"
0x28db = "KEY_FORWARD"
0x28dc = "KEY_R"
0x28dd = "KEY_PAGEUP"
0x28de = "KEY_PAGEDOWN"
0x28e0 = "KEY_D"
0x28e1 = "KEY_I"
0x28e2 = "KEY_END"
0x28e3 = "KEY_A"
Note that the keycodes can be found in the kernel source code. With my own keymap in place at /etc/rc_keymaps/streamzap.toml, I changed /etc/rc_maps.cfg to have the kernel driver automatically use it:
--- a/rc_maps.cfg
+++ b/rc_maps.cfg
@@ -126,7 +126,7 @@
 *      rc-real-audio-220-32-keys real_audio_220_32_keys.toml
 *      rc-reddo                 reddo.toml
 *      rc-snapstream-firefly    snapstream_firefly.toml
-*      rc-streamzap             streamzap.toml
+*      rc-streamzap             /etc/rc_keymaps/streamzap.toml
 *      rc-su3000                su3000.toml
 *      rc-tango                 tango.toml
 *      rc-tanix-tx3mini         tanix_tx3mini.toml

Button repeat delay To adjust the delay before button presses are repeated, I followed these old out-of-date instructions on the MythTV wiki and put the following in /etc/udev/rules.d/streamzap.rules:
ACTION=="add", ATTRS idVendor =="0e9c", ATTRS idProduct =="0000", RUN+="/usr/bin/ir-keytable -s rc0 -D 1000 -P 250"
Note that the -d option has been replaced with -s in the latest version of ir-keytable. To check that the Streamzap is indeed detected as rc0 on your system, use this command:
$ ir-keytable 
Found /sys/class/rc/rc0/ with:
    Name: Streamzap PC Remote Infrared Receiver (0e9c:0000)
    Driver: streamzap
    Default keymap: rc-streamzap
...
Make sure you don't pass the -c to ir-keytable or else it will clear the keymap set via /etc/rc_maps.cfg, removing all of the button mappings.

7 March 2022

Ayoyimika Ajibade: Progress Report!! Modifying Expectations...

Wait! Just like yesterday when I was accepted as an Outreachy intern and the first half of the internship is finished . How time flies when you are having a good time As part of the requirements for the final application during the contribution period for the Outreachy internship, I needed to provide a timeline to achieve our goal on my outreachy task which is transitioning of dependencies in node16 and webpack5. Having consulted my mentors who implied that the packages depending on webpack and nodejs combined are so numerous that its impossible to finish all within a space of three months but we have steps to guide us through the entire process to achieve most of our goals which are As of this writing(though a little late ) we have successfully rebuilt all reverse dependencies of webpack5 and split them equally each for I and my co-intern for all Javascript modules as ruby packages also depend on webpack which is a total of 44 packages. Filed a bug report on Debian bug tracking system for failing packages, also the original maintainer or uploader of the package to the Debian archive mostly Debian developers also get a mail in references to the package bug report. Sometimes the uploader who also receives the bug report decides to help out to fix the package and forward the patch upstream if need be. We have also filed an issue to upstream repo mostly via github where some respond and create PR to solve those errors and others are plain aversive to the whole idea. PR from the upstream developer is cherry-picked and a patch is created by us to incorporate the code into our own working repository. some package upstream maintainer rejects such issues or doesn't respond, we take it upon ourselves to fix the package. The total number of packages that are successfully updated and ready to be merged is 10 packages while 12 packages remain on my own end to be updated. One of the most challenging packages to update so far was prop-type as its runs its large test suite using jest of a lower version 19.0.2 compared to that of Debian OS which is version 27.5.1 updating and migrating its API's and methods to use the Debian updated version is so challenging after several googling, testing out the solution from StackOverflow, trials, and errors, reading documentations we eventually made progress with the help of my mentor, co-intern and the whole community member. It's so crazy that when I got it working I said to myself. phew it's not rocket science why can I figure it out sooner than expected I initially proposed that I would be halfway done with the project by now, I guess the reason am not able to achieve some of our goals which are finishing up with the packages for webpack and moving to transition some of the nodejs packages at all is DEBUGGING. Yes DEBUGGING! where you never can predict what the solution is. is the problem coming from Debian? or dependencies of the package you are working on, upstream bug, or dependencies of dependencies of the package you are working on, so many questions to answer. You can't easily find a solution to a bug as it takes time to try out so many guesses more of an educated guess, or even try out all the solutions from stack overflow and still no viable progress. Obviously, you cannot really know about something to set up a plan for unless you get right into it. One way of doing this, if I have to start again is the truly understand how the javascript package work under the hood, how its handles different interaction between packages, some of its dos and don't of transpiling, bundling, testing, e.t.c I guess my unrealistic goals need to be modified because some drawback that was not envisaged popped up and I underestimated the complexity of the tasks, which will be reducing the number of packages to update in transitioning of nodejs from what I planned My major focus for the second half of the internship is to fix bugs and errors I discover, file bug reports for future bugs to seek help from co-maintainer or developers, file issues upstream and close those whose bugs are already resolved for the remaining 12 packages, and ultimately successfully uploading all reverse dependencies. Also diving into transitioning of nodejs16. Thanks for stopping by

5 March 2022

Reproducible Builds: Reproducible Builds in February 2022

Welcome to the February 2022 report from the Reproducible Builds project. In these reports, we try to round-up the important things we and others have been up to over the past month. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website.
Jiawen Xiong, Yong Shi, Boyuan Chen, Filipe R. Cogo and Zhen Ming Jiang have published a new paper titled Towards Build Verifiability for Java-based Systems (PDF). The abstract of the paper contains the following:
Various efforts towards build verifiability have been made to C/C++-based systems, yet the techniques for Java-based systems are not systematic and are often specific to a particular build tool (eg. Maven). In this study, we present a systematic approach towards build verifiability on Java-based systems.

GitBOM is a flexible scheme to track the source code used to generate build artifacts via Git-like unique identifiers. Although the project has been active for a while, the community around GitBOM has now started running weekly community meetings.
The paper Chris Lamb and Stefano Zacchiroli is now available in the March/April 2022 issue of IEEE Software. Titled Reproducible Builds: Increasing the Integrity of Software Supply Chains (PDF), the abstract of the paper contains the following:
We first define the problem, and then provide insight into the challenges of making real-world software build in a reproducible manner-this is, when every build generates bit-for-bit identical results. Through the experience of the Reproducible Builds project making the Debian Linux distribution reproducible, we also describe the affinity between reproducibility and quality assurance (QA).

In openSUSE, Bernhard M. Wiedemann posted his monthly reproducible builds status report.
On our mailing list this month, Thomas Schmitt started a thread around the SOURCE_DATE_EPOCH specification related to formats that cannot help embedding potentially timezone-specific timestamp. (Full thread index.)
The Yocto Project is pleased to report that it s core metadata (OpenEmbedded-Core) is now reproducible for all recipes (100% coverage) after issues with newer languages such as Golang were resolved. This was announced in their recent Year in Review publication. It is of particular interest for security updates so that systems can have specific components updated but reducing the risk of other unintended changes and making the sections of the system changing very clear for audit. The project is now also making heavy use of equivalence of build output to determine whether further items in builds need to be rebuilt or whether cached previously built items can be used. As mentioned in the article above, there are now public servers sharing this equivalence information. Reproducibility is key in making this possible and effective to reduce build times/costs/resource usage.

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb prepared and uploaded versions 203, 204, 205 and 206 to Debian unstable, as well as made the following changes to the code itself:
  • Bug fixes:
    • Fix a file(1)-related regression where Debian .changes files that contained non-ASCII text were not identified as such, therefore resulting in seemingly arbitrary packages not actually comparing the nested files themselves. The non-ASCII parts were typically in the Maintainer or in the changelog text. [ ][ ]
    • Fix a regression when comparing directories against non-directories. [ ][ ]
    • If we fail to scan using binwalk, return False from BinwalkFile.recognizes. [ ]
    • If we fail to import binwalk, don t report that we are missing the Python rpm module! [ ]
  • Testsuite improvements:
    • Add a test for recent file(1) issue regarding .changes files. [ ]
    • Use our assert_diff utility where we can within the test_directory.py set of tests. [ ]
    • Don t run our binwalk-related tests as root or fakeroot. The latest version of binwalk has some new security protection against this. [ ]
  • Codebase improvements:
    • Drop the _PATH suffix from module-level globals that are not paths. [ ]
    • Tidy some control flow in Difference._reverse_self. [ ]
    • Don t print a warning to the console regarding NT_GNU_BUILD_ID changes. [ ]
In addition, Mattia Rizzolo updated the Debian packaging to ensure that diffoscope and diffoscope-minimal packages have the same version. [ ]

Website updates There were quite a few changes to the Reproducible Builds website and documentation this month as well, including:
  • Chris Lamb:
    • Considerably rework the Who is involved? page. [ ][ ]
    • Move the contributors.sh Bash/shell script into a Python script. [ ][ ][ ]
  • Daniel Shahaf:
    • Try a different Markdown footnote content syntax to work around a rendering issue. [ ][ ][ ]
  • Holger Levsen:
    • Make a huge number of changes to the Who is involved? page, including pre-populating a large number of contributors who cannot be identified from the metadata of the website itself. [ ][ ][ ][ ][ ]
    • Improve linking to sponsors in sidebar navigation. [ ]
    • drop sponsors paragraph as the navigation is clearer now. [ ]
    • Add Mullvad VPN as a bronze-level sponsor . [ ][ ]
  • Vagrant Cascadian:

Upstream patches The Reproducible Builds project attempts to fix as many currently-unreproducible packages as possible. February s patches included the following:

Testing framework The Reproducible Builds project runs a significant testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
  • Daniel Golle:
    • Update the OpenWrt configuration to not depend on the host LLVM, adding lines to the .config seed to build LLVM for eBPF from source. [ ]
    • Preserve more OpenWrt-related build artifacts. [ ]
  • Holger Levsen:
  • Temporary use a different Git tree when building OpenWrt as our tests had been broken since September 2020. This was reverted after the patch in question was accepted by Paul Spooren into the canonical openwrt.git repository the next day.
    • Various improvements to debugging OpenWrt reproducibility. [ ][ ][ ][ ][ ]
    • Ignore useradd warnings when building packages. [ ]
    • Update the script to powercycle armhf architecture nodes to add a hint to where nodes named virt-*. [ ]
    • Update the node health check to also fix failed logrotate and man-db services. [ ]
  • Mattia Rizzolo:
    • Update the website job after contributors.sh script was rewritten in Python. [ ]
    • Make sure to set the DIFFOSCOPE environment variable when available. [ ]
  • Vagrant Cascadian:
    • Various updates to the diffoscope timeouts. [ ][ ][ ]
Node maintenance was also performed by Holger Levsen [ ] and Vagrant Cascadian [ ].

Finally If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

3 March 2022

Enrico Zini: Migrating from procmail to sieve

Anarcat's "procmail considered harmful" post convinced me to get my act together and finally migrate my venerable procmail based setup to sieve. My setup was nontrivial, so I migrated with an intermediate step in which sieve scripts would by default pipe everything to procmail, which allowed me to slowly move rules from procmailrc to sieve until nothing remained in procmailrc. Here's what I did. Literature review https://brokkr.net/2019/10/31/lets-do-dovecot-slowly-and-properly-part-3-lmtp/ has a guide quite aligned with current Debian, and could be a starting point to get an idea of the work to do. https://wiki.dovecot.org/HowTo/PostfixDovecotLMTP is way more terse, but more aligned with my intentions. Reading the former helped me in understanding the latter. https://datatracker.ietf.org/doc/html/rfc5228 has the full Sieve syntax. https://doc.dovecot.org/configuration_manual/sieve/pigeonhole_sieve_interpreter/ has the list of Sieve features supported by Dovecot. https://doc.dovecot.org/settings/pigeonhole/ has the reference on Dovecot's sieve implementation. https://raw.githubusercontent.com/dovecot/pigeonhole/master/doc/rfc/spec-bosch-sieve-extprograms.txt is the hard to find full reference for the functions introduced by the extprograms plugin. Debugging tools: Backup of all mails processed One thing I did with procmail was to generate a monthly mailbox with all incoming email, with something like this:
BACKUP="/srv/backupts/test- date +%Y-%m-d .mbox"
:0c
$BACKUP
I did not find an obvious way in sieve to create montly mailboxes, so I redesigned that system using Postfix's always_bcc feature, piping everything to an archive user. I'll then recreate the monthly archiving using a chewmail script that I can simply run via cron. Configure dovecot
apt install dovecot-sieve dovecot-lmtpd
I added this to the local dovecot configuration:
service lmtp  
  unix_listener /var/spool/postfix/private/dovecot-lmtp  
    user = postfix
    group = postfix
    mode = 0666
   
 
protocol lmtp  
  mail_plugins = $mail_plugins sieve
 
plugin  
  sieve = file:~/.sieve;active=~/.dovecot.sieve
 
This makes Dovecot ready to receive mail from Postfix via a lmtp unix socket created in Postfix's private chroot. It also activates the sieve plugin, and uses ~/.sieve as a sieve script. The script can be a file or a directory; if it is a directory, ~/.dovecot.sieve will be a symlink pointing to the .sieve file to run. This is a feature I'm not yet using, but if one day I want to try enabling UIs to edit sieve scripts, that part is ready. Delegate to procmail To make sieve scripts that delegate to procmail, I enabled the sieve_extprograms plugin:
 plugin  
   sieve = file:~/.sieve;active=~/.dovecot.sieve
+  sieve_plugins = sieve_extprograms
+  sieve_extensions +vnd.dovecot.pipe
+  sieve_pipe_bin_dir = /usr/local/lib/dovecot/sieve-pipe
+  sieve_trace_dir = ~/.sieve-trace
+  sieve_trace_level = matching
+  sieve_trace_debug = yes
  
and then created a script for it:
mkdir -p /usr/local/lib/dovecot/sieve-pipe/
(echo "#!/bin/sh'; echo "exec /usr/bin/procmail") > /usr/local/lib/dovecot/sieve-pipe/procmail
chmod 0755 /usr/local/lib/dovecot/sieve-pipe/procmail
And I can have a sieve script that delegates processing to procmail:
require "vnd.dovecot.pipe";
pipe "procmail";
Activate the postfix side These changes switched local delivery over to Dovecot:
--- a/roles/mailserver/templates/dovecot.conf
+++ b/roles/mailserver/templates/dovecot.conf
@@ -25,6 +25,8 @@
 
+auth_username_format = %Ln
+
 
diff --git a/roles/mailserver/templates/main.cf b/roles/mailserver/templates/main.cf
index d2c515a..d35537c 100644
--- a/roles/mailserver/templates/main.cf
+++ b/roles/mailserver/templates/main.cf
@@ -64,8 +64,7 @@ virtual_alias_domains =
 
-mailbox_command = procmail -a "$EXTENSION"
-mailbox_size_limit = 0
+mailbox_transport = lmtp:unix:private/dovecot-lmtp
 
Without auth_username_format = %Ln dovecot won't be able to understand usernames sent by postfix in my specific setup. Moving rules over to sieve This is mostly straightforward, with the luxury of being able to do it a bit at a time. The last tricky bit was how to call spamc from sieve, as in some situations I reduce system load by running the spamfilter only on a prefiltered selection of incoming emails. For this I enabled the filter directive in sieve:
 plugin  
   sieve = file:~/.sieve;active=~/.dovecot.sieve
   sieve_plugins = sieve_extprograms
-  sieve_extensions +vnd.dovecot.pipe
+  sieve_extensions +vnd.dovecot.pipe +vnd.dovecot.filter
   sieve_pipe_bin_dir = /usr/local/lib/dovecot/sieve-pipe
+  sieve_filter_bin_dir = /usr/local/lib/dovecot/sieve-filter
   sieve_trace_dir = ~/.sieve-trace
   sieve_trace_level = matching
   sieve_trace_debug = yes
  
Then I created a filter script:
mkdir -p /usr/local/lib/dovecot/sieve-filter/"
(echo "#!/bin/sh'; echo "exec /usr/bin/spamc") > /usr/local/lib/dovecot/sieve-filter/spamc
chmod 0755 /usr/local/lib/dovecot/sieve-filter/spamc
And now what was previously:
:0 fw
  /usr/bin/spamc
:0
* ^X-Spam-Status: Yes
.spam/
Can become:
require "vnd.dovecot.filter";
require "fileinto";
filter "spamc";
if header :contains "x-spam-level" "**************"  
    discard;
  elsif header :matches "X-Spam-Status" "Yes,*"  
    fileinto "spam";
 
Updates Ansgar mentioned that it's possible to replicate the monthly mailbox using the variables and date extensions, with a hacky trick from the extensions' RFC:
require "date"
require "variables"
if currentdate :matches "month" "*"   set "month" "$ 1 ";  
if currentdate :matches "year" "*"   set "year" "$ 1 ";  
fileinto :create "$ month -$ year ";

Ian Jackson: 3D printed hard case for Fairphone 4

About 4 years ago, I posted about making a 3D printed case for my then-new phone. The FP2 was already a few years old when I got one and by now, some spares are unavailable - which is a problem, because I'm terribly hard on hardware. Indeed, that's why I need a very sturdy case for my phone - a case which can be ablative when necessary. With the arrival of my new Fairphone 4, I've updated my case design. Sadly the FP4 doesn't have a notification LED - I guess we're supposed to be glued to the screen and leaving the phone ignored in a corner unless it lights up is forbidden. But that does at least make the printing simpler, as there's no need for a window for the LED. Source code: https://www.chiark.greenend.org.uk/ucgi/~ianmdlvl/git?p=reprap-play.git;a=blob;f=fairphone4-case.scad;h=1738612c2aafcd4ee4ea6b8d1d14feffeba3b392;hb=629359238b2938366dc6e526d30a2a7ddec5a1b0 And the diagrams (which are part of the source, although I didn't update them for the FP4 changes: https://www.chiark.greenend.org.uk/ucgi/~ianmdlvl/git?p=reprap-diagrams.git;a=tree;f=fairphone-case;h=65f423399cbcfd3cf24265ed3216e6b4c0b26c20;hb=07e1723c88a294d68637bb2ca3eac388d2a0b5d4 ( big pictures )

comment count unavailable comments

2 March 2022

Antoine Beaupr : procmail considered harmful

TL;DR: procmail is a security liability and has been abandoned upstream for the last two decades. If you are still using it, you should probably drop everything and at least remove its SUID flag. There are plenty of alternatives to chose from, and conversion is a one-time, acceptable trade-off.

Procmail is unmaintained procmail is unmaintained. The "Final release", according to Wikipedia, dates back to September 10, 2001 (3.22). That release was shipped in Debian since then, all the way back from Debian 3.0 "woody", twenty years ago. Debian also ships 25 uploads on top of this, with 3.22-21 shipping the "3.23pre" release that has been rumored since at least the November 2001, according to debian/changelog at least:
procmail (3.22-1) unstable; urgency=low
  * New upstream release, which uses the  standard' format for Maildir
    filenames and retries on name collision. It also contains some
    bug fixes from the 3.23pre snapshot dated 2001-09-13.
  * Removed  sendmail' from the Recommends field, since we already
    have  exim' (the default Debian MTA) and  mail-transport-agent'.
  * Removed suidmanager support. Conflicts: suidmanager (<< 0.50).
  * Added support for DEB_BUILD_OPTIONS in the source package.
  * README.Maildir: Do not use locking on the example recipe,
    since it's wrong to do so in this case.
 -- Santiago Vila <sanvila@debian.org>  Wed, 21 Nov 2001 09:40:20 +0100
All Debian suites from buster onwards ship the 3.22-26 release, although the maintainer just pushed a 3.22-27 release to fix a seven year old null pointer dereference, after this article was drafted. Procmail is also shipped in all major distributions: Fedora and its derivatives, Debian derivatives, Gentoo, Arch, FreeBSD, OpenBSD. We all seem to be ignoring this problem. The upstream website (http://procmail.org/) has been down since about 2015, according to Debian bug #805864, with no change since. In effect, every distribution is currently maintaining its fork of this dead program. Note that, after filing a bug to keep Debian from shipping procmail in a stable release again, I was told that the Debian maintainer is apparently in contact with the upstream. And, surprise! they still plan to release that fabled 3.23 release, which has been now in "pre-release" for all those twenty years. In fact, it turns out that 3.23 is considered released already, and that the procmail author actually pushed a 3.24 release, codenamed "Two decades of fixes". That amounts to 25 commits since 3.23pre some of which address serious security issues, but none of which address fundamental issues with the code base.

Procmail is insecure By default, procmail is installed SUID root:mail in Debian. There's no debconf or pre-seed setting that can change this. There has been two bug reports against the Debian to make this configurable (298058, 264011), but both were closed to say that, basically, you should use dpkg-statoverride to change the permissions on the binary. So if anything, you should immediately run this command on any host that you have procmail installed on:
dpkg-statoverride --update --add root root 0755 /usr/bin/procmail
Note that this might break email delivery. It might also not work at all, thanks to usrmerge. Not sure. Yes, everything is on fire. This is fine. In my opinion, even assuming we keep procmail in Debian, that default should be reversed. It should be up to people installing procmail to assign it those dangerous permissions, after careful consideration of the risk involved. The last maintainer of procmail explicitly advised us (in that null pointer dereference bug) and other projects (e.g. OpenBSD, in [2]) to stop shipping it, back in 2014. Quote:
Executive summary: delete the procmail port; the code is not safe and should not be used as a basis for any further work.
I just read some of the code again this morning, after the original author claimed that procmail was active again. It's still littered with bizarre macros like:
#define bit_set(name,which,value) \
  (value?(name[bit_index(which)] =bit_mask(which)):\
  (name[bit_index(which)]&=~bit_mask(which)))
... from regexp.c, line 66 (yes, that's a custom regex engine). Or this one:
#define jj  (aleps.au.sopc)
It uses insecure functions like strcpy extensively. malloc() is thrown around gotos like it's 1984 all over again. (To be fair, it has been feeling like 1984 a lot lately, but that's another matter entirely.) That null pointer deref bug? It's fixed upstream now, in this commit merged a few hours ago, which I presume might be in response to my request to remove procmail from Debian. So while that's nice, this is the just tip of the iceberg. I speculate that one could easily find an exploitable crash in procmail if only by running it through a fuzzer. But I don't need to speculate: procmail had, for years, serious security issues that could possibly lead to root privilege escalation, remotely exploitable if procmail is (as it's designed to do) exposed to the network. Maybe I'm overreacting. Maybe the procmail author will go through the code base and do a proper rewrite. But I don't think that's what is in the cards right now. What I expect will happen next is that people will start fuzzing procmail, throw an uncountable number of bug reports at it which will get fixed in a trickle while never fixing the underlying, serious design flaws behind procmail.

Procmail has better alternatives The reason this is so frustrating is that there are plenty of modern alternatives to procmail which do not suffer from those problems. Alternatives to procmail(1) itself are typically part of mail servers. For example, Dovecot has its own LDA which implements the standard Sieve language (RFC 5228). (Interestingly, Sieve was published as RFC 3028 in 2001, before procmail was formally abandoned.) Courier also has "maildrop" which has its own filtering mechanism, and there is fdm (2007) which is a fetchmail and procmail replacement. Update: there's also mailprocessing, which is not an LDA, but processing an existing folder. It was, however, specifically designed to replace complex Procmail rules. But procmail, of course, doesn't just ship procmail; that would just be too easy. It ships mailstat(1) which we could probably ignore because it only parses procmail log files. But more importantly, it also ships:
  • lockfile(1) - conditional semaphore-file creator
  • formail(1) - mail (re)formatter
lockfile(1) already has a somewhat acceptable replacement in the form of flock(1), part of util-linux (which is Essential, so installed on any normal Debian system). It might not be a direct drop-in replacement, but it should be close enough. formail(1) is similar: the courier maildrop package ships reformail(1) which is, presumably, a rewrite of formail. It's unclear if it's a drop-in replacement, but it should probably possible to port uses of formail to it easily.
Update: the maildrop package ships a SUID root binary (two, even). So if you want only reformail(1), you might want to disable that with:
dpkg-statoverride --update --add root root 0755 /usr/bin/lockmail.maildrop 
dpkg-statoverride --update --add root root 0755 /usr/bin/maildrop
It would be perhaps better to have reformail(1) as a separate package, see bug 1006903 for that discussion.
The real challenge is, of course, migrating those old .procmailrc recipes to Sieve (basically). I added a few examples in the appendix below. You might notice the Sieve examples are easier to read, which is a nice added bonus.

Conclusion There is really, absolutely, no reason to keep procmail in Debian, nor should it be used anywhere at this point. It's a great part of our computing history. May it be kept forever in our museums and historical archives, but not in Debian, and certainly not in actual release. It's just a bomb waiting to go off. It is irresponsible for distributions to keep shipping obsolete and insecure software like this for unsuspecting users. Note that I am grateful to the author, I really am: I used procmail for decades and it served me well. But now, it's time to move, not bring it back from the dead.

Appendix

Previous work It's really weird to have to write this blog post. Back in 2016, I rebuilt my mail setup at home and, to my horror, discovered that procmail had been abandoned for 15 years at that point, thanks to that LWN article from 2010. I would have thought that I was the only weirdo still running procmail after all those years and felt kind of embarrassed to only "now" switch to the more modern (and, honestly, awesome) Sieve language. But no. Since then, Debian shipped three major releases (stretch, buster, and bullseye), all with the same vulnerable procmail release. Then, in early 2022, I found that, at work, we actually had procmail installed everywhere, possibly because userdir-ldap was using it for lockfile until 2019. I sent a patch to fix that and scrambled to remove get rid of procmail everywhere. That took about a day. But many other sites are now in that situation, possibly not imagining they have this glaring security hole in their infrastructure.

Procmail to Sieve recipes I'll collect a few Sieve equivalents to procmail recipes here. If you have any additions, do contact me. All Sieve examples below assume you drop the file in ~/.dovecot.sieve.

deliver mail to "plus" extension folder Say you want to deliver user+foo@example.com to the folder foo. You might write something like this in procmail:
MAILDIR=$HOME/Maildir/
DEFAULT=$MAILDIR
LOGFILE=$HOME/.procmail.log
VERBOSE=off
EXTENSION=$1            # Need to rename it - ?? does not like $1 nor 1
:0
* EXTENSION ?? [a-zA-Z0-9]+
        .$EXTENSION/
That, in sieve language, would be:
require ["variables", "envelope", "fileinto", "subaddress"];
########################################################################
# wildcard +extension
# https://doc.dovecot.org/configuration_manual/sieve/examples/#plus-addressed-mail-filtering
if envelope :matches :detail "to" "*"  
  # Save name in $ name  in all lowercase
  set :lower "name" "$ 1 ";
  fileinto "$ name ";
  stop;
 

Subject into folder This would file all mails with a Subject: line having FreshPorts in it into the freshports folder, and mails from alternc.org mailing lists into the alternc folder:
:0
## mailing list freshports
* ^Subject.*FreshPorts.*
.freshports/
:0
## mailing list alternc
* ^List-Post.*mailto:.*@alternc.org.*
.alternc/
Equivalent Sieve:
if header :contains "subject" "FreshPorts"  
    fileinto "freshports";
  elsif header :contains "List-Id" "alternc.org"  
    fileinto "alternc";
 

Mail sent to root to a reports folder This double rule:
:0
* ^Subject: Cron
* ^From: .*root@
.rapports/
Would look something like this in Sieve:
if header :comparator "i;octet" :contains "Subject" "Cron"  
  if header :regex :comparator "i;octet"  "From" ".*root@"  
        fileinto "rapports";
   
 
Note that this is what the automated converted does (below). It's not very readable, but it works.

Bulk email I didn't have an equivalent of this in procmail, but that's something I did in Sieve:
if header :contains "Precedence" "bulk"  
    fileinto "bulk";
 

Any mailing list This is another rule I didn't have in procmail but I found handy and easy to do in Sieve:
if exists "List-Id"  
    fileinto "lists";
 

This or that I wouldn't remember how to do this in procmail either, but that's an easy one in Sieve:
if anyof (header :contains "from" "example.com",
           header :contains ["to", "cc"] "anarcat@example.com")  
    fileinto "example";
 
You can even pile up a bunch of options together to have one big rule with multiple patterns:
if anyof (exists "X-Cron-Env",
          header :contains ["subject"] ["security run output",
                                        "monthly run output",
                                        "daily run output",
                                        "weekly run output",
                                        "Debian Package Updates",
                                        "Debian package update",
                                        "daily mail stats",
                                        "Anacron job",
                                        "nagios",
                                        "changes report",
                                        "run output",
                                        "[Systraq]",
                                        "Undelivered mail",
                                        "Postfix SMTP server: errors from",
                                        "backupninja",
                                        "DenyHosts report",
                                        "Debian security status",
                                        "apt-listchanges"
                                        ],
           header :contains "Auto-Submitted" "auto-generated",
           envelope :contains "from" ["nagios@",
                                      "logcheck@",
                                      "root@"])
     
    fileinto "rapports";
 

Automated script There is a procmail2sieve.pl script floating around, and mentioned in the dovecot documentation. It didn't work very well for me: I could use it for small things, but I mostly wrote the sieve file from scratch.

Progressive migration Enrico Zini has progressively migrated his procmail setup to Sieve using a clever way: he hooked procmail inside sieve so that he could deliver to the Dovecot LDA and progressively migrate rules one by one, without having a "flag day". See this explanatory blog post for the details, which also shows how to configure Dovecot as an LMTP server with Postfix.

Other examples The Dovecot sieve examples are numerous and also quite useful. At the time of writing, they include virus scanning and spam filtering, vacation auto-replies, includes, archival, and flags.

Harmful considered harmful I am aware that the "considered harmful" title has a long and controversial history, being considered harmful in itself (by some people who are obviously not afraid of contradictions). I have nevertheless deliberately chosen that title, partly to make sure this article gets maximum visibility, but more specifically because I do not have doubts at this moment that procmail is, clearly, a bad idea at this moment in history.

Developing story I must also add that, incredibly, this story has changed while writing it. This article is derived from this bug I filed in Debian to, quite frankly, kick procmail out of Debian. But filing the bug had the interesting effect of pushing the upstream into action: as mentioned above, they have apparently made a new release and merged a bunch of patches in a new git repository. This doesn't change much of the above, at this moment. If anything significant comes out of this effort, I will try to update this article to reflect the situation. I am actually happy to retract the claims in this article if it turns out that procmail is a stellar example of defensive programming and survives fuzzing attacks. But at this moment, I'm pretty confident that will not happen, at least not in scope of the next Debian release cycle.

Petter Reinholdtsen: Run your industrial metal working machine using Debian?

After many months of hard work by the good people involved in LinuxCNC, the system was accepted Sunday into Debian. Once it was available from Debian, I was surprised to discover from its popularity-contest numbers that people have been reporting its use since 2012. Its project site might be a good place to check out, but sadly is not working when visiting via Tor. But what is LinuxCNC, you are probably wondering? Perhaps a Wikipedia quote is in place?
"LinuxCNC is a software system for numerical control of machines such as milling machines, lathes, plasma cutters, routers, cutting machines, robots and hexapods. It can control up to 9 axes or joints of a CNC machine using G-code (RS-274NGC) as input. It has several GUIs suited to specific kinds of usage (touch screen, interactive development)."
It can even control 3D printers. And even though the Wikipedia page indicate that it can only work with hard real time kernel features, it can also work with the user space soft real time features provided by the Debian kernel. The source code is available from Github. The last few months I've been involved in the translation setup for the program and documentation. Translators are most welcome to join the effort using Weblate. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Keith Packard: picolibc-testing

Testing Picolibc with the glibc tests Picolibc has a bunch of built-in tests, but more testing is always better, right? I decided to see how hard it would be to run some of the tests provided in the GNU C Library (glibc). Parallel meson build files Similar to how Picolibc uses meson build files to avoid modifying the newlib autotools infrastructure, I decided to take the glibc code and write meson build rules that would compile the tests against Picolibc header files and link against Picolibc libraries. I decided to select a single target for this project so I could focus on getting things building and not worry too much about making it portable. I wanted to pick something that had hardware floating point so that I would have rounding modes and exception support, so I picked the ARM Cortex M7 with hard float ABI:
$ arm-none-eabi-gcc -mcpu=cortex-m7 -mfloat-abi=hard
It should be fairly easy to extend this to other targets, but for now, that's what I've got working. There's a cross-cortex-m7.txt file containing all of the cross compilation details which is used when running meson setup. All of the Picolibc-specific files live in a new picolibc directory so they are isolated from the main glibc code. Pre-loading a pile of hacks Adapt Picolibc to support the Glibc test code required a bunch of random hacks, from providing _unlocked versions of the stdio macros to stubbing out various unsupportable syscalls (like sleep and chdir). Instead of modifying the Glibc code, I created a file called hacks.h which is full of this stuff and used the gcc -include parameter to read that into the compiler before starting compilation on all of the files. Supporting command line parameters The glibc tests all support a range of command line parameters, some of which turned out to be quite useful for this work. Picolibc had limited semihosting support for accessing the command line, but that required modifying applications to go fetch the command line using a special semihosting function. To make this easier, I added a new crt0 variant for picolibc called (oddly) semihost. This extends the existing hosted variant by adding a call to the semihosting library to fetch the current command line and splitting that into words at each space. It doesn't handle any quoting, but it's sufficient for the needs here. Avoiding glibc headers The glibc tests use some glibc-specific extensions to the standard POSIX C library, so I needed to include those in the test builds. Headers for those extensions are mixed in with the rest of the POSIX standard headers, which conflict with the Picolibc versions. To work around this, I stuck stub #include files in the picolibc directory which directly include the appropriate headers for the glibc API extensions. This includes things like argp.h and array_length.h. For other headers which weren't actually needed for picolibc, I created empty files. Adding more POSIX to Picolibc At this point, code was compiling but failing to find various standard POSIX functions which aren't available in Picolibc. That included some syscalls which could be emulated using semihosting, like gettimeofday and getpagesize. It also included some generally useful additions, like replacing ecvtbuf and fcvtbuf with ecvt_r and fcvt_r. The _r variants provide a target buffer size instead of assuming that it was large enough as the Picolibc buf variants did. Which tests are working? So far, I've got some of the tests in malloc, math, misc and stdio-common running. There are a lot of tests in the malloc directory which cover glibc API extensions or require POSIX syscalls not supported by semihosting. I think I've added all of the tests which should be supported. For the math tests, I'm testing the standard POSIX math APIs in both float and double forms, except for the Bessel and Gamma functions. Picolibc's versions of those are so bad that they violate some pretty basic assumptions about error bounds built into the glibc test code. Until Picolibc gets better versions of these functions, we'll have to skip testing them this way. In the misc directory, I've only added tests for ecvt, fcvt, gcvt, dirname and hsearch. I don't think there are any other tests there which should work. Finally, for stdio-common, almost all of the tests expect a fully functioning file system, which semihosting really can't support. As a result, we're only able to run the printf, scanf and some of the sprintf tests. All in all, we're running 78 of the glibc test programs, which is a small fraction of the total tests, but I think it's the bulk of the tests which cover APIs that don't depend too much on the underlying POSIX operating system. Bugs found and fixed in Picolibc This exercise has resulted in 17 fixes in Picolibc, which can be classified as:
  1. Math functions taking sNaN and not raising FE_INVALID and returning qNaN. Almost any operation on an sNaN value is supposed to signal an invalid operand and replace that with a qNaN so that further processing doesn't raise another exception. This was fairly easy to fix, just need to use return x + x; instead of return x;.
  2. Math functions failing to set errno. I'd recently restructured the math library to get rid of the separate IEEE version of the functions which didn't set errno and missed a couple of cases that needed to use the errno-setting helper functions.
  3. Corner cases in string/float conversion, including the need to perform round-to-even for '%a' conversions in printf and supporting negative decimal values for fcvt. This particular exercise led to replacing the ecvtbuf and fcvtbuf APIs with glibc's ecvt_r and fcvt_r versions as those pass explicit buffer lengths, making overflow prevention far more reliable.
  4. A bunch of malloc entry points were not handling failure correctly; allocation values close to the maximum possible size caused numerous numeric wrapping errors with the usual consequences (allocations "succeed", but return a far smaller buffer than requested). Also, realloc was failing to check the return value from malloc before copying the old data, which really isn't a good idea.
  5. Tinystdio's POSIX support code was returning an error instead of EOF at end of file.
  6. Error bounds for the Picolibc math library aren't great; I had to generate Picolibc-specific ulps files. Most functions are between 0 and 3 ulps, but for some reason, the float version of erfc (ercf) has errors as large as 64 ulps. That needs investigation.
Tests added to Picolibc With all of the fixes applied to Picolibc, I added some tests to verify them without relying on running the glibc tests, that includes sNaN vs qNaN tests for math functions, testing fopen and mktemp, checking the printf %a rounding support and adding a ecvt/fcvt tests. I also discovered that the github-based CI system was compiling but not testing when using clang with a riscv target, so that got added in. Where's the source code? The Picolibc changes are sitting on the glibc-testing branch. I'll merge them once the current CI pass finishes. The hacked-up Glibc bits are in a glibc mirror at github in the picolibc project on the picolibc-testing branch. It would be interesting to know what additional tests should be usable in this environment. And, perhaps, finding a way to use this for picolibc CI testing in the future. Concluding thoughts Overall, I'm pretty pleased with these results. The bugs in malloc are fairly serious and could easily result in trouble, but the remaining issues are mostly minor and shouldn't have a big impact on applications using Picolibc. I'll get the changes merged and start thinking about doing another Picolibc release.

1 March 2022

Paul Wise: FLOSS Activities February 2022

Focus This month I didn't have any particular focus. I just worked on issues in my info bubble.

Changes

Issues

Review

Administration
  • Debian BTS: fix usertags for some users, unarchive/reopen/triage bugs for reintroduced packages: horae dh-haskell shutter logging-tree openstreetmap-carto gnome-commander
  • Debian servers: restore wiki data from backup, restarted bacula director for TLS cert update
  • Debian wiki: restore wiki account from backup, approve accounts

Communication
  • Respond to queries from Debian users and contributors on the mailing lists and IRC

Sponsors The purple-discord, gensim, DiskANN, SPTAG, wsproto work was sponsored by my employer. All other work was done on a volunteer basis.

Next.

Previous.