Search Results: "reg"

5 November 2021

Jonathan Dowland: 25 things I would like to 3D print

Last year I started collecting ideas of things I would like to 3D print one day, on Twitter. Twitter is fundamentally ephemeral, so I'll collect it here instead. I got up to 14 items on Twitter, and now I'm up to 25. I don't own a 3D printer, but I have access to one at the work office. Perhaps this list is my subconcious trying to convince me to buy one. What am I missing? What else should I be thinking of printing? Let me know!
  1. Some kind of 45 leaning prong to dry bottles and flasks on
  2. A tea tray and coasters
  3. a replacement prop arm/foot for my computer keyboard (something like this but for the Lenovo Ultranav)
  4. some attempted representation of Borges Library of Babel, a la @jwz The Library of Babel, again
  5. an exploration of the geometry of Susanna Clarke s Piranesi
  6. further iterations of my castle
  7. Small tins to keep loose-leaf tea in
  8. Who am I kidding, bound to be a map from DOOM. E1M1 perhaps, or something more regular (MAP07? E2M8?) See also this amazing print of Quake 3: Arena's "Camping Grounds"
  9. replacement bits for kids toy sets, e.g. a bolt with long shank from Early Learning Centre Build It Deluxe Set, without all 4 of which you can't build much of anything
  10. A stand for a decorative Christmas bauble (kid's hand print on it) A roll of cellotape works pretty well in the mean time
  11. DIY bits-and-bobs sorter/storage (nuts and bolts etc)
  12. A space ship from Elite/Frontier. Probably a Cobra mk3 or maybe a Viper mk2. In a glow-in-the-dark PLA which i d overpaint with gunmetal except for the fuselage
  13. A watch stand/holder/storage thing Except it would look nicer in wood (And I m more inclined to get rid of all but one watch instead)
  14. Little tabbed 7 dividers for vinyl records, with A-Z cut into the tabs 12 ones might be a stretch (something like this)
  15. A low-profile custom trackpoint cover like the ones by SaotoTech (e.g.)
  16. A vinyl record. (Not sure that any 3D printer I would have access to would have the necessary resolution. I haven't done any research yet.)
  17. A free-standing inclined vinyl record display stand (e.g.)
  18. A "Settlers of Catan" set. I've got the travel edition which is great but it would be nicer to have a larger-sized set. There are some things I really like about the travel set that the full-size set lacks; so designing and printing a larger set myself could incorporate them. Also I don't feel inclined to buy the full-size set for 50 or so to end up with essentially the same game I already bought. No doubt I'd spent at least that much in PLA.
  19. Little kids trinkets. Pacman ghosts, that sort-of thing. Whatever my daughters come up with next.
  20. Lego storage/sorters.
  21. Some kind of lenticular picture. Perhaps a gift or Christmas card combined in one.
  22. A bracket to install a Gotek drive in my Amiga 500 (e.g.). I've managed without but the fit isn't great.
  23. An attempt at using the 3D printer for 2D drawing. I would never get the same kind of quality results you can get from a proper plotter, but still Take a look at some proper plotter art!
  24. Garden decorations. I like the idea of porous geometric shapes that you can plant mosses or ferns into, but also things which might be taken over and "used" by nature in ways I hadn't thought of.
  25. Floor plans / 3D plans of my house (including variations if I remodelled)

3 November 2021

Benjamin Mako Hill: Q&A about doing a PhD with my research group

Ever considered doing research about online communities, free culture/software, and peer production full time? It s PhD admission season and my research group the Community Data Science Collective is doing an open-to-anyone Q&A about PhD admissions this Friday November 5th. We ve got room in the session and its not too late to sign up to join us! The session will be a good opportunity to hear from and talk to faculty recruiting students to our various programs at the University of Washington, Purdue, and Northwestern and to talk with current and previous students in the group. I am hoping to admit at least one new PhD advisee to the Department of Communication at UW this year (maybe more) and am currently co-advising (and/or have previously co-advised) students in UW s Allen School of Computer Science & Engineering, Department of Human-Centered Design & Engineering, and Information School. One thing to keep in mind is that my primary/home department Communication has a deadline for PhD applications of November 15th this year. The registration deadline for the Q&A session is listed as today but we ll do what we can to sneak you in even if you register late. That said, please do register ASAP so we can get you the link to the session!

Dirk Eddelbuettel: RDieHarder 0.2.2 on CRAN: Simpler Build, Fixes

An updated version 0.2.2 of the random-number generator tester RDieHarder (based on the DieHarder suite developed / maintained by Robert Brown with contributions by David Bauer and myself) is now on CRAN. I should dub this the due to Brian Ripley release. He sent me a detailed five-point email a few days ago which detailed a change I could not have tested ( no access ), a change I would not have known ( somewhat obscure C language bit-level manipulation ), a change I had missed (how my build setup failed for M1mac), another advanced C level fix, and one more simple fix I actually knew. Speechless. The man (I presume) does not sleep and is just so generous with his time and expertise. So based on the input I rejigged the package over the weekend and made two more (substantial) changes. First, extending on what 0.2.0 brought, I will no longer attempt to use an external libdieharder library (or build one on the fly) that was issue one. Now we just declare all C files as dependents of the package shared library, and things are simpler and more consistent. Sadly, that also implies everything is in the package so I had to edit out a metric ton of stdout or exit() reference with the appropriate R C API hooks to appease the CRAN Policy deities. Win some, loose some. But the package is now simpler, and cleaner, and should be in good standing. (Or so one hopes. Earlier today, and within hours of it hitting CRAN, I got an issue ticket from a motivated user about yet another ( mostly harmless in the Douglas Adams sense) compiler warning Good now too.) Thanks to CRANberries, you can also look at the most recent diff. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

30 October 2021

Dirk Eddelbuettel: RcppQuantuccia 0.1.0 on CRAN: Full QuantLib Business Calendar Support

Another new release of RcppQuantuccia arrived on CRAN today, just a week after the previous release which brought full calendaring support. RcppQuantuccia started from the Quantuccia header-only subset / variant of QuantLib which it brings it to R. As of this release, the QuantLib code is only minimally modified. In other words we no longer follow the Quantuccia route of header-izing the file but include both cpp and hpp directly. The minimal changes, documented in a diff file in the repo, consists chiefly of removing includes for headers we do not use (given the pure calendaring focus) and accomodating CRAN Policies (by eschewing #pragma directives). We do follow Quantuccia by not having any external linking requirement: the R package only depends on Rcpp (for the glue) and BH for the Boost headers (and system-level Boost headers can be used as drop-in). The our knowledge, this provides the only small and self-contained (apart from Boost headers) library with current (and regularly updated within QuantLib, which I intend to shadow here) calendaring code on a global scale. Every exchange that matters is likely included. The screenshot provides quick demo. The complete list changes for this release follows.

Changes in version 0.1.0 (2021-10-30)
  • Code reorganized to have minimal (documented) changes relative to upstream, essentially just removing unused headers, and pragma
  • Added example for full calendaring to README.md

Time permitting, I may look into other bindings from this sub-library; see a first email thread on this. Courtesy of CRANberries, there is also a diffstat report relative to the previous release. More information is on the RcppQuantuccia page. Issues and bugreports should go to the GitHub issue tracker. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Dirk Eddelbuettel: dang 0.0.15: Small Correction

A bug-fix release of the dang package arrived at CRAN a little while ago. The dang package regroups a few functions of mine that had no other home as for example lsos() from a StackOverflow question from 2009 (!!), the overbought/oversold price band plotter from an older blog post, the market monitor from the last release as well the checkCRANStatus() function tweeted about by Tim Taylor. This release corrects a small mistake wrapping extern "C" ... around code that is not actually C but C++ which g++ kept silent about yet clang++ complains about, correctly. So CRAN asked me to correct this, which this version does. The NEWS entry follows.

Changes in version 0.0.15 (2021-10-26)
  • Corrected scope of 'extern "C"' declaration to the actually C-callable function (noticed by clang++, change requested by CRAN)

Courtesy of my CRANberries, there is a comparison to the previous release. For questions or comments use the issue tracker off the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

28 October 2021

Dirk Eddelbuettel: td 0.0.5 on CRAN: New Reference Accessors

The td package for accessing the twelvedata API for financial data has been updated on CRAN to version 0.0.5. This is version is mostly the work of Kenneth who suggested to add accessors for reference data, and then did just that. So if you already use td, good news as you now have nine or so more functions getting data for you! The NEWS entry follows.

Changes in version 0.0.5 (2021-10-28)
  • New functions to access twelvedata reference data (Kenneth in #4 addressing #3)

Courtesy of my CRANberries, there is a comparison to the previous release. For questions or comments use the issue tracker off the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

24 October 2021

Sean Whitton: Deploying containers with Consfigurator

For some months now I ve been working on some patches to Consfigurator to add support for Linux containers. My goal is to make Consfigurator capable of both performing the initial setup of a container and of entering the running container to apply configuration. For the case of unprivileged LXCs running as non-root, my work-in-progress branch can now do both of these things. As Consfigurator enters the container directly using system calls, it should be decently fast at configuring multiple containers on a host, and it will also be possible to have it do this in parallel. The initial setup for the container uses Consfigurator s existing support for building root filesystems, and it should be easy to extend that to support arbitrary GNU/Linux distributions by teaching Consfigurator how to invoke bootstrapping tools other than debootstrap(8). Here s an example:
(defhost lxc1.silentflame.com ()
  (os:debian-stable "bullseye" :amd64)
  (basic-props)
  (apt:installed "systemd" "netcat")
  (apache:https-vhost ...))
(defhost lxctest.laptop.silentflame.com ()
  (os:debian-stable "bullseye" :amd64)
  (apt:proxy "http://192.168.122.1:3142")
  (basic-props)
  (apt:installed "linux-image-amd64" "lxc")
  (lxc:usernet-usable-by "spwhitton" "lxcbr0")
  (lxc:user-containers-autostart "spwhitton")
  (lxc:user-container-for '(:additional-lines
                            ("lxc.net.0.type = veth"
                             "lxc.net.0.flags = up"
                             "lxc.net.0.link = lxcbr0"
                             ...))
                          "spwhitton"
                          lxc1.silentflame.com))
(defhost laptop.silentflame.com ()
  ...
  (libvirt:kvm-boots-chroot-for '(:always-deploys t)
                                lxctest.laptop.silentflame.com))
This code is a simplified definition of my testing setup for this work. It defines three hosts: a container lxc1, a container host lxctest, and my laptop. When Consfigurator is asked to deploy the laptop, it will set up the root filesystem for lxctest and then boot it as a KVM virtual machine. Preparing that root filesystem will include setting up the root filesystem for lxc1, too, including shifting the ownership and ACLs to match the user namespace LXC will use when booting the container. Thus, once the deployment of the laptop is finished, it will be possible to boot the lxctest VM, connect to it as the user spwhitton, and start lxc1. Consfigurator includes only minimal support for setting up container networking, as there are so many different ways in which you might want to do it. In my own consfig I ve been developing properties to connect containers directly to my tinc VPN. A single tinc daemon runs on the container host, and other tinc daemons route a whole subnet, containing the addresses for each of the containers, to the container host s tinc daemon. As the LXCs Consfigurator sets up run as non-root, some sort of setuid facility is required to configure this networking. Consfigurator s ability to dump executable Lisp images is helping here. I define a function which runs as root to set up the networking:
(defun route-athenet-container-veth (host)
  (let ((user (getenv "USERV_USER"))
        (peer (getenv "USERV_U_PEER"))
        (ip (car (uiop:command-line-arguments))))
    (unless (string-prefix-p (format nil "veth~D_" (getenv "USERV_UID")) peer)
      (error "~A does not belong to requester." peer))
    (unless (member (cons user ip) (get-hostattrs 'veth-ips host) :test #'equal)
      (error "~A does not have permission to route ~A." user ip))
    (flet ((r (&rest args)
             ;; Explicitly passing nil means UIOP will not invoke a shell.
             (run-program args :force-shell nil)))
      (eswitch ((getenv "USERV_U_HOOK_TYPE") :test #'string=)
        ("up"
         (apply #'r
                "sysctl" "-w"
                "net.ipv6.conf.all.forwarding=1"
                ...)
         (r "ip" "addr" "flush" "dev" peer "scope" "link")
         (r "ip" "-6" "addr" "add" "fe80::1/64" "dev" peer)
         (r "ip" "-6" "route" "add" (strcat ip "/128") "dev" peer)
         ...)
        ("down"
         ...
         (r "ip" "-6" "route" "del" (strcat ip "/128") "dev" peer))))))
and then apply the following property to lxctest to dump an image which will call this function and then exit:
(image-dumped
 "/usr/lib/userv/route-athenet-container-veth"
  (route-athenet-container-veth ,(intern (string-upcase (get-hostname)))))
I m using GNU userv to enable ordinary users to run this image as root, so there there s a small script which converts LXC s LXC_HOOK_* environment variables into appropriate command line arguments to userv(1) such that the function above is able to access that information from its environment (the USERV_U_* variables above). You could just as easily do this with sudo, by giving permission for the relevant LXC_HOOK_* environment variables to survive the switch to root. What s particularly nice about this is that there s no need to write any code to keep a config file updated, specifying which users are allowed to route which IPs to their containers. ROUTE-ATHENET-CONTAINER-VETH receives a HOST value for the container host and can just look at the metadata established by properties for particular containers. Each time this metadata is updated and lxctest is deployed, a fresh image is dumped containing the updated metadata. This work has provided opportunities to make various other improvements to Consfigurator, especially with regard to dumping and reinvoking images. Making SBCL capable of entering user namespaces required a change upstream, which made it into the recent SBCL 2.1.8 release. I m very grateful to the SBCL developers for their engagement with my project. I ve been able to add a workaround so that Consfigurator can still enter user namespaces when run on the version of SBCL included in Debian stable. I also discovered that deploying all of my laptop, lxctest and lxc1 at once generates enough output to fill up a pipe, thus revealing a deadlock in Consfigurator s IPC, which it was good to become aware of and fix. That involved writing my first multi-threaded Lisp, as there are two pipes that need to be kept from filling up, and to my surprise it worked first time. Take that Haskell :)

23 October 2021

Dirk Eddelbuettel: RcppQuantuccia 0.0.5 on CRAN: Updated and Calendar Focus

Another new release of RcppQuantuccia arrived on CRAN today, just a couple of days after the previous release. RcppQuantuccia started from the Quantuccia header-only subset / variant of QuantLib which it brings it to R. As of this release, it concentrates on calendaring functionality taking advantage of the extensive collection of country-specific holiday information in QuantLib. The release updates the included code to the most recent QuantLib release. We added one calendar (for Brazil) and one utility function (of exporting all business days in a given range, which is the simple complement to the existing holiday list getter). The complete list changes follows.

Changes in version 0.0.5 (2021-10-23)
  • Refocused on calendaring functionality only, removed daycounters/, math/, methods/, models/, plus other unused headers
  • Fully updated to (current) QuantLib release 0.2.4
  • Added getBusinessDays() to retrieve range of dates
  • Added Brazil calendar

Courtesy of CRANberries, there is also a diffstat report relative to the previous release. More information is on the RcppQuantuccia page. Issues and bugreports should go to the GitHub issue tracker. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Antoine Beaupr : The Neo-Colonial Internet

I grew up with the Internet and its ethics and politics have always been important in my life. But I have also been involved at other levels, against police brutality, for Food, Not Bombs, worker autonomy, software freedom, etc. For a long time, that all seemed coherent. But the more I look at the modern Internet -- and the mega-corporations that control it -- and the less confidence I have in my original political analysis of the liberating potential of technology. I have come to believe that most of our technological development is harmful to the large majority of the population of the planet, and of course the rest of the biosphere. And now I feel this is not a new problem. This is because the Internet is a neo-colonial device, and has been from the start. Let me explain.

What is Neo-Colonialism? The term "neo-colonialism" was coined by Kwame Nkrumah, first president of Ghana. In Neo-Colonialism, the Last Stage of Imperialism (1965), he wrote:
In place of colonialism, as the main instrument of imperialism, we have today neo-colonialism ... [which] like colonialism, is an attempt to export the social conflicts of the capitalist countries. ... The result of neo-colonialism is that foreign capital is used for the exploitation rather than for the development of the less developed parts of the world. Investment, under neo-colonialism, increases, rather than decreases, the gap between the rich and the poor countries of the world.
So basically, if colonialism is Europeans bringing genocide, war, and its religion to the Africa, Asia, and the Americas, neo-colonialism is the Americans (note the "n") bringing capitalism to the world. Before we see how this applies to the Internet, we must therefore make a detour into US history. This matters, because anyone would be hard-pressed to decouple neo-colonialism from the empire under which it evolves, and here we can only name the United States of America.

US Declaration of Independence Let's start with the United States declaration of independence (1776). Many Americans may roll their eyes at this, possibly because that declaration is not actually part of the US constitution and therefore may have questionable legal standing. Still, it was obviously a driving philosophical force in the founding of the nation. As its author, Thomas Jefferson, stated:
it was intended to be an expression of the American mind, and to give to that expression the proper tone and spirit called for by the occasion
In that aging document, we find the following pearl:
We hold these truths to be self-evident, that all men are created equal, that they are endowed by their Creator with certain unalienable Rights, that among these are Life, Liberty and the pursuit of Happiness.
As a founding document, the Declaration still has an impact in the sense that the above quote has been called an:
"immortal declaration", and "perhaps [the] single phrase" of the American Revolutionary period with the greatest "continuing importance." (Wikipedia)
Let's read that "immortal declaration" again: "all men are created equal". "Men", in that context, is limited to a certain number of people, namely "property-owning or tax-paying white males, or about 6% of the population". Back when this was written, women didn't have the right to vote, and slavery was legal. Jefferson himself owned hundreds of slaves. The declaration was aimed at the King and was a list of grievances. A concern of the colonists was that the King:
has excited domestic insurrections amongst us, and has endeavoured to bring on the inhabitants of our frontiers, the merciless Indian Savages whose known rule of warfare, is an undistinguished destruction of all ages, sexes and conditions.
This is a clear mark of the frontier myth which paved the way for the US to exterminate and colonize the territory some now call the United States of America. The declaration of independence is obviously a colonial document, having being written by colonists. None of this is particularly surprising, historically, but I figured it serves as a good reminder of where the Internet is coming from, since it was born in the US.

A Declaration of the Independence of Cyberspace Two hundred and twenty years later, in 1996, John Perry Barlow wrote a declaration of independence of cyberspace. At this point, (almost) everyone has a right to vote (including women), slavery was abolished (although some argue it still exists in the form of the prison system); the US has made tremendous progress. Surely this text will have aged better than the previous declaration it is obviously derived from. Let's see how it reads today and how it maps to how the Internet is actually built now.

Borders of Independence One of the key ideas that Barlow brings up is that "cyberspace does not lie within your borders". In that sense, cyberspace is the final frontier: having failed to colonize the moon, Americans turn inwards, deeper into technology, but still in the frontier ideology. And indeed, Barlow is one of the co-founder of the Electronic Frontier Foundation (the beloved EFF), founded six years prior. But there are other problems with this idea. As Wikipedia quotes:
The declaration has been criticized for internal inconsistencies.[9] The declaration's assertion that 'cyberspace' is a place removed from the physical world has also been challenged by people who point to the fact that the Internet is always linked to its underlying geography.[10]
And indeed, the Internet is definitely a physical object. First controlled and severely restricted by "telcos" like AT&T, it was somewhat "liberated" from that monopoly in 1982 when an anti-trust lawsuit broke up the monopoly, a key historical event that, one could argue, made the Internet possible. (From there on, "backbone" providers could start competing and emerge, and eventually coalesce into new monopolies: Google has a monopoly on search and advertisement, Facebook on communications for a few generations, Amazon on storage and computing, Microsoft on hardware, etc. Even AT&T is now pretty much as consolidated as it was before.) The point is: all those companies have gigantic data centers and intercontinental cables. And those are definitely prioritizing the western world, the heart of the empire. Take for example Google's latest 3,900 mile undersea cable: it does not connect Argentina to South Africa or New Zealand, it connects the US to UK and Spain. Hardly a revolutionary prospect.

Private Internet But back to the Declaration:
Do not think that you can build it, as though it were a public construction project. You cannot. It is an act of nature and it grows itself through our collective actions.
In Barlow's mind, the "public" is bad, and private is good, natural. Or, in other words, a "public construction project" is unnatural. And indeed, the modern "nature" of development is private: most of the Internet is now privately owned and operated. I must admit that, as an anarchist, I loved that sentence when I read it. I was rooting for "us", the underdogs, the revolutionaries. And, in a way, I still do: I am on the board of Koumbit and work for a non-profit that has pivoted towards censorship and surveillance evasion. Yet I cannot help but think that, as a whole, we have failed to establish that independence and put too much trust in private companies. It is obvious in retrospect, but it was not, 30 years ago. Now, the infrastructure of the Internet has zero accountability to traditional political entities supposedly representing the people, or even its users. The situation is actually worse than when the US was founded (e.g. "6% of the population can vote"), because the owners of the tech giants are only a handful of people who can override any decision. There's only one Amazon CEO, he's called Jeff Bezos, and he has total control. (Update: Bezos actually ceded the CEO role to Andy Jassy, AWS and Amazon music founder, while remaining executive chairman. I would argue that, as the founder and the richest man on earth, he still has strong control over Amazon.)

Social Contract Here's another claim of the Declaration:
We are forming our own Social Contract.
I remember the early days, back when "netiquette" was a word, it did feel we had some sort of a contract. Not written in standards of course -- or barely (see RFC1855) -- but as a tacit agreement. How wrong we were. One just needs to look at Facebook to see how problematic that idea is on a global network. Facebook is the quintessential "hacker" ideology put in practice. Mark Zuckerberg explicitly refused to be "arbiter of truth" which implicitly means he will let lies take over its platforms. He also sees Facebook as place where everyone is equal, something that echoes the Declaration:
We are creating a world that all may enter without privilege or prejudice accorded by race, economic power, military force, or station of birth.
(We note, in passing, the omission of gender in that list, also mirroring the infamous "All men are created equal" claim of the US declaration.) As the Wall Street Journal's (WSJ) Facebook files later shown, both of those "contracts" have serious limitations inside Facebook. There are VIPs who systematically bypass moderation systems including fascists and rapists. Drug cartels and human traffickers thrive on the platform. Even when Zuckerberg himself tried to tame the platform -- to get people vaccinated or to make it healthier -- he failed: "vaxxer" conspiracies multiplied and Facebook got angrier. This is because the "social contract" behind Facebook and those large companies is a lie: their concern is profit and that means advertising, "engagement" with the platform, which causes increased anxiety and depression in teens, for example. Facebook's response to this is that they are working really hard on moderation. But the truth is that even that system is severely skewed. The WSJ showed that Facebook has translators for only 50 languages. It's a surprisingly hard to count human languages but estimates range the number of distinct languages between 2500 and 7000. So while 50 languages seems big at first, it's actually a tiny fraction of the human population using Facebook. Taking the first 50 of the Wikipedia list of languages by native speakers we omit languages like Dutch (52), Greek (74), and Hungarian (78), and that's just a few random nations picks from Europe. As an example, Facebook has trouble moderating even a major language like Arabic. It censored content from legitimate Arab news sources when they mentioned the word al-Aqsa because Facebook associates it with the al-Aqsa Martyrs' Brigades when they were talking about the Al-Aqsa Mosque... This bias against Arabs also shows how Facebook reproduces the American colonizer politics. The WSJ also pointed out that Facebook spends only 13% of its moderation efforts outside of the US, even if that represents 90% of its users. Facebook spends three more times moderating on "brand safety", which shows its priority is not the safety of its users, but of the advertisers.

Military Internet Sergey Brin and Larry Page are the Lewis and Clark of our generation. Just like the latter were sent by Jefferson (the same) to declare sovereignty over the entire US west coast, Google declared sovereignty over all human knowledge, with its mission statement "to organize the world's information and make it universally accessible and useful". (It should be noted that Page somewhat questioned that mission but only because it was not ambitious enough, Google having "outgrown" it.) The Lewis and Clark expedition, just like Google, had a scientific pretext, because that is what you do to colonize a world, presumably. Yet both men were military and had to receive scientific training before they left. The Corps of Discovery was made up of a few dozen enlisted men and a dozen civilians, including York an African American slave owned by Clark and sold after the expedition, with his final fate lost in history. And just like Lewis and Clark, Google has a strong military component. For example, Google Earth was not originally built at Google but is the acquisition of a company called Keyhole which had ties with the CIA. Those ties were brought inside Google during the acquisition. Google's increasing investment inside the military-industrial complex eventually led Google to workers organizing a revolt although it is currently unclear to me how much Google is involved in the military apparatus. Other companies, obviously, do not have such reserve, with Microsoft, Amazon, and plenty of others happily bidding on military contracts all the time.

Spreading the Internet I am obviously not the first to identify colonial structures in the Internet. In an article titled The Internet as an Extension of Colonialism, Heather McDonald correctly identifies fundamental problems with the "development" of new "markets" of Internet "consumers", primarily arguing that it creates a digital divide which creates a "lack of agency and individual freedom":
Many African people have gained access to these technologies but not the freedom to develop content such as web pages or social media platforms in their own way. Digital natives have much more power and therefore use this to create their own space with their own norms, shaping their online world according to their own outlook.
But the digital divide is certainly not the worst problem we have to deal with on the Internet today. Going back to the Declaration, we originally believed we were creating an entirely new world:
This governance will arise according to the conditions of our world, not yours. Our world is different.
How I dearly wished that was true. Unfortunately, the Internet is not that different from the offline world. Or, to be more accurate, the values we have embedded in the Internet, particularly of free speech absolutism, sexism, corporatism, and exploitation, are now exploding outside of the Internet, into the "real" world. The Internet was built with free software which, fundamentally, was based on quasi-volunteer labour of an elite force of white men with obviously too much time on their hands (and also: no children). The mythical writing of GCC and Emacs by Richard Stallman is a good example of this, but the entirety of the Internet now seems to be running on random bits and pieces built by hit-and-run programmers working on their copious free time. Whenever any of those fails, it can compromise or bring down entire systems. (Heck, I wrote this article on my day off...) This model of what is fundamentally "cheap labour" is spreading out from the Internet. Delivery workers are being exploited to the bone by apps like Uber -- although it should be noted that workers organise and fight back. Amazon workers are similarly exploited beyond belief, forbidden to take breaks until they pee in bottles, with ambulances nearby to carry out the bodies. During peak of the pandemic, workers were being dangerously exposed to the virus in warehouses. All this while Amazon is basically taking over the entire economy. The Declaration culminates with this prophecy:
We will spread ourselves across the Planet so that no one can arrest our thoughts.
This prediction, which first felt revolutionary, is now chilling.

Colonial Internet The Internet is, if not neo-colonial, plain colonial. The US colonies had cotton fields and slaves, we have disposable cell phones and Foxconn workers. Canada has its cultural genocide, Facebook has his own genocides in Ethiopia, Myanmar, and mob violence in India. Apple is at least implicitly accepting the Uyghur genocide. And just like the slaves of the colony, those atrocities are what makes the empire run. The Declaration actually ends like this, a quote which I have in my fortune cookies file:
We will create a civilization of the Mind in Cyberspace. May it be more humane and fair than the world your governments have made before.
That is still inspiring to me. But if we want to make "cyberspace" more humane, we need to decolonize it. Work on cyberpeace instead of cyberwar. Establish clear code of conduct, discuss ethics, and question your own privileges, biases, and culture. For me the first step in decolonizing my own mind is writing this article. Breaking up tech monopolies might be an important step, but it won't be enough: we have to do a culture shift as well, and that's the hard part.

Appendix: an apology to Barlow I kind of feel bad going through Barlow's declaration like this, point by point. It is somewhat unfair, especially since Barlow passed away a few years ago and cannot mount a response (even humbly assuming that he might read this). But then again, he himself recognized he was a bit too "optimistic" in 2009, saying: "we all get older and smarter":
I'm an optimist. In order to be libertarian, you have to be an optimist. You have to have a benign view of human nature, to believe that human beings left to their own devices are basically good. But I'm not so sure about human institutions, and I think the real point of argument here is whether or not large corporations are human institutions or some other entity we need to be thinking about curtailing. Most libertarians are worried about government but not worried about business. I think we need to be worrying about business in exactly the same way we are worrying about government.
And, in a sense, it was a little naive to expect Barlow to not be a colonist. Barlow is, among many things, a cattle rancher who grew up on a colonial ranch in Wyoming. The ranch was founded in 1907 by his great uncle, 17 years after the state joined the Union, and only a generation or two after the Powder River War (1866-1868) and Black Hills War (1876-1877) during which the US took over lands occupied by Lakota, Cheyenne, Arapaho, and other native American nations, in some of the last major First Nations Wars.

Appendix: further reading There is another article that almost has the same title as this one: Facebook and the New Colonialism. (Interestingly, the <title> tag on the article is actually "Facebook the Colonial Empire" which I also find appropriate.) The article is worth reading in full, but I loved this quote so much that I couldn't resist reproducing it here:
Representations of colonialism have long been present in digital landscapes. ( Even Super Mario Brothers, the video game designer Steven Fox told me last year. You run through the landscape, stomp on everything, and raise your flag at the end. ) But web-based colonialism is not an abstraction. The online forces that shape a new kind of imperialism go beyond Facebook.
It goes on:
Consider, for example, digitization projects that focus primarily on English-language literature. If the web is meant to be humanity s new Library of Alexandria, a living repository for all of humanity s knowledge, this is a problem. So is the fact that the vast majority of Wikipedia pages are about a relatively tiny square of the planet. For instance, 14 percent of the world s population lives in Africa, but less than 3 percent of the world s geotagged Wikipedia articles originate there, according to a 2014 Oxford Internet Institute report.
And they introduce another definition of Neo-colonialism, while warning about abusing the word like I am sort of doing here:
I m loath to toss around words like colonialism but it s hard to ignore the family resemblances and recognizable DNA, to wit, said Deepika Bahri, an English professor at Emory University who focuses on postcolonial studies. In an email, Bahri summed up those similarities in list form:
  1. ride in like the savior
  2. bandy about words like equality, democracy, basic rights
  3. mask the long-term profit motive (see 2 above)
  4. justify the logic of partial dissemination as better than nothing
  5. partner with local elites and vested interests
  6. accuse the critics of ingratitude
In the end, she told me, if it isn t a duck, it shouldn t quack like a duck.
Another good read is the classic Code and other laws of cyberspace (1999, free PDF) which is also critical of Barlow's Declaration. In "Code is law", Lawrence Lessig argues that:
computer code (or "West Coast Code", referring to Silicon Valley) regulates conduct in much the same way that legal code (or "East Coast Code", referring to Washington, D.C.) does (Wikipedia)
And now it feels like the west coast has won over the east coast, or maybe it recolonized it. In any case, Internet now christens emperors.

20 October 2021

Arturo Borrero Gonz lez: Iterating on how we do NFS at Wikimedia Cloud Services

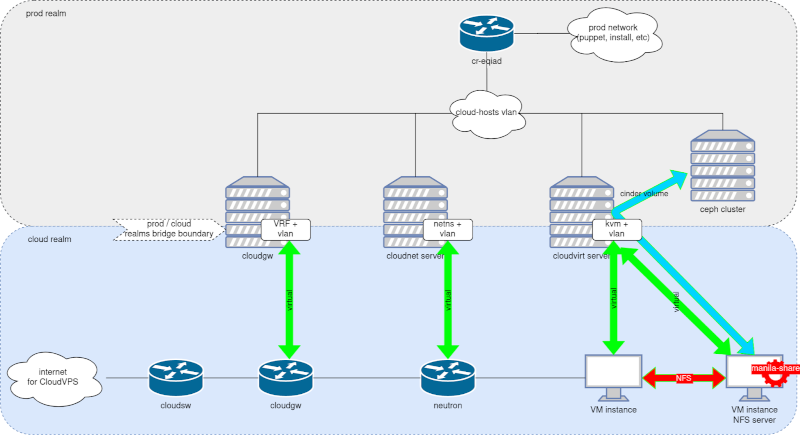
Logos This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez. NFS is a central piece of infrastructure that is essential to services like Toolforge. Recently, the Cloud Services team at Wikimedia had been reviewing how we do NFS. The current situation NFS is a central piece of technology for some of the services that the Wikimedia Cloud Services team offers to the community. We have several shares that power different use cases: Toolforge user home directories live on NFS, and Cloud VPS users can also access dumps using this protocol. The current setup involves several physical hardware servers, with about 20TB of storage, offering shares over 10G links to the cloud. For the system to be more fault-tolerant, we duplicate each share for redundancy using DRBD. Running NFS on dedicated hardware servers has traditionally offered us advantages: mostly on the performance and the capacity fields. As time has passed, we have been enumerating more and more reasons to review how we do NFS. For one, the current setup is in violation of some of our internal rules regarding realm separation. Additionally, we had been longing for additional flexibility managing our servers: we wanted to use virtual machines managed by Openstack Nova. The DRBD-based high-availability system required mostly a hand-crafted procedure for failover/failback. There s also some scalability concerns as NFS is easy to grow up, but not to grow horizontally, and of course, we have to be able to keep the tenancy setup while doing so, something that NFS does by using LDAP/Unix users and may get complicated too when growing. In general, the servers have become too big to fail , clearly technical debt, and it has taken us years to decide on taking on the task to rethink the architecture. It s worth mentioning that in an ideal world, we wouldn t depend on NFS, but the truth is that it will still be a central piece of infrastructure for years to come in services like Toolforge. Over a series of brainstorming meetings, the WMCS team evaluated the situation and sorted out the many moving parts. The team managed to boil down the potential service future to two competing options: Then we decided to research both options in parallel. For a number of reasons, the evaluation was timeboxed to three weeks. Both ideas had a couple of points in common: the NFS data would be stored on our Ceph farm via Cinder volumes, and we would rely on Ceph reliability to avoid using DRBD. Another open topic was how to back up data from Ceph, to store our important bits in more than one basket. We will get to the back up topic later. The manila experiment The Wikimedia Foundation was an early adopter of some Openstack components (Nova, Glance, Designate, Horizon), but Manila was never evaluated for usage until now. Our approach for this experiment was to closely follow the upstream guidelines. We read the documentation and tried to understand the different setups you can build with Manila. As we often feel with other Openstack components, the documentation doesn t perfectly describe how to introduce a given component in your particular local setup. Here we use an admin-controller flat-topology Neutron network. This network is shared by all tenants (or projects) in our Openstack deployment. Also, Manila can use many different driver backends, for things like NetApps or CephFS that we don t use , yet. After some research, the generic driver was the one that seemed to better fit our use case. The generic driver leverages Nova virtual machines instances plus Cinder volume to create and manage the shares. In general, Manila supports two operational modes, whether it should create/destroy the share servers (i.e, the virtual machine instances) or not. This option is called driver_handles_share_server (or DHSS) and takes a boolean value. We were interested in trying with DHSS=true, to really benefit from the potential of the setup. Manila diagram NFS idea 6, original image in Wikitech So, after sorting all these variables, we moved on with our initial testing. We built a PoC setup as depicted in the diagram above, with the manila-share component running in a virtual machine inside the cloud. The PoC led to us reporting several bugs upstream: In some cases we tried to address these bugs ourselves: It s worth mentioning that the upstream community was extra-welcoming to us, and we re thankful for that. However, at the end of our three-week period, our Manila setup still wasn t working as expected. Your experience may change with other drivers perhaps the ZFSonLinux or the CephFS ones. In general, we were having trouble making the setup work as expected, so we decided to abandon this approach in favor of the other option we were considering at the beginning. Simple virtual machine serving NFS The alternative was to create a Nova virtual machine instance by hand and to configure it using puppet. We have been investing in an automation framework lately, so the idea is to not actually create the server by hand. Anyway, the data would be decoupled from the instance into Cinder volumes, which led us to the question we left for later: How should we back up those terabytes of important information? Just to be clear, the backup problem was independent of the above options; with Manila we would still have had to solve the same challenge. We would like to see our data be backed up somewhere else other than in Ceph. And that s exactly where we are at right now. We ve been exploring different backup strategies and will finally use the Cinder backup API. Conclusion The iteration will end with the dedicated NFS hardware servers being stopped, and the shares being served from within the cloud. The migration will take some time to happen because we will check and double-check that everything works as expected (including from the performance point of view) before making definitive changes. We already have some plans to make sure our users experience as little service impact as possible. The most troublesome shares will be those related to Toolforge. At some point we will need to disallow writes to the NFS share, rsync the data out of the hardware servers into the Cinder volumes, point the NFS clients to the new virtual machines, and then enable writes again. The main Toolforge share has about 8TB of data, so this will take a while. We will have more updates in the future. Who knows, perhaps our next-next iteration, in a couple of years, will see us adopting Openstack Manila for good. Featured image credit: File:(from break water) Manila Skyline panoramio.jpg, ewol, CC BY-SA 3.0 This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez.

19 October 2021

Dirk Eddelbuettel: RVowpalWabbit 0.0.16: One More CRAN Request

Another maintenance RVowpalWabbit released brings us to version 0.0.16 on CRAN. This is last package for which configure.ac needed an update to current standards (see the updates of corels, RcppGSL, RQuantLib, and littler). The make matters more interesting we also had to address one UBSAN issue we could not reproduce locally (which, it turns out, was our fault because we had not rebuilt one package dependency under UBSAN). But Prof Ripley confirmed the issue as addressed so all is good for now. As noted before, there is a newer package rvw based on the excellent GSoC 2018 and beyond work by Ivan Pavlov (mentored by James and myself) so if you are into Vowpal Wabbit from R go check it out. CRANberries provides a summary of changes to the previous version. More information is on the RVowpalWabbit page. Issues and bugreports should go to the GitHub issue tracker. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

18 October 2021

Gunnar Wolf: raspi.debian.net now hosted on Debian infrastructure

So, since I registered the URL for serving the unofficial Debian images for the Raspberry computers, raspi.debian.net, in April 2020, I had been hosting it in my Dreamhost webspace. Over two years ago yes, before I finished setting it up in Dreamhost Steve McIntyre approached me and invited me to host the images under the Debian cdimages user group. I told him I d first just get the setup running, and later I would approach him for finalizing the setup. Then, I set up the build on my own server, hosted on my Dreamhost account and forgot about it for many months. Last month, there was a not particularly happy flamewar in debian-arm@lists.debian.org finished with me stating I would be moving the hosting to Debian infrastructure soon. Well It took me a bit over a month to get this sorted out, together with several days of half-broken links, but it is finally done: raspi.debian.net is a CNAME for ftp.acc.umu.se, which is the same system that hosts cdimage.debian.org. And, of course it is also reachable as https://cdimage.debian.org/cdimage/unofficial/raspi/ looks more official, but is less memorable Thanks a lot to Steve for the nudging, and to maswan to help finalizing the setup. What next? Well, the images are being built on my server. I d love to move the builder over to Debian machines as well. When? How? That s still in the air.

Dirk Eddelbuettel: dang 0.0.14: Several Updates

A new release of the dang package arrived at CRAN a couple of hours ago, exactly eight months after the previous release. The dang package regroups a few functions of mine that had no other home as for example lsos() from a StackOverflow question from 2009 (!!), the overbought/oversold price band plotter from an older blog post, the market monitor from the last release as well the checkCRANStatus() function recently tweeted about by Tim Taylor. This release regroups a few small edits to several functions, adds a sample function for character encoding reading and conversion using a library already used by R (hence look Ma, no new depends ), adds a weekday helper, and a sample usage (computing rolling min/max values) of a new simple vector class added to tidyCpp (and the function and class need to get another blog post or study ), and an experimental git sha1sum and date marker (as I am not the fan of autogenerated binaries from repos as opposed to marked released meaning: we may see different binary release with the same version number). The full NEWS entry follows.

Changes in version 0.0.14 (2021-10-17)
  • Updated continuous integration to run on Linux only.
  • Edited checkNonAscii.cpp for readability.
  • More robust title display in intradayMarketMonitor.R.
  • New C++-based function to read and convert encoding via the R-supplied iconv library, noted a potential variability.
  • New function wday returning day of the week as integer.
  • The signature to as.data.table was standardized.
  • A new function rollMinMax was added illustrating use of the NumVec class from tidyCpp.
  • The configure script can record the last commit date and sha1 to automate timestamping builds, but not activated in this release.
  • checkCRANStatus() now works correctly for single-package lookups (Jordan Mark Barbone in #4).

Courtesy of my CRANberries, there is a comparison to the previous release. For questions or comments use the issue tracker off the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

13 October 2021

Dirk Eddelbuettel: GitHub Streak: Round Eight

Seven years ago I referenced the Seinfeld Streak used in an earlier post of regular updates to to the Rcpp Gallery:
This is sometimes called Jerry Seinfeld s secret to productivity: Just keep at it. Don t break the streak.
and then showed the first chart of GitHub streaking 366 days:
github activity october 2013 to october 2014github activity october 2013 to october 2014
And six years ago a first follow-up appeared in this post about 731 days:
github activity october 2014 to october 2015github activity october 2014 to october 2015
And five years ago we had a followup at 1096 days
github activity october 2015 to october 2016github activity october 2015 to october 2016
And four years ago we had another one marking 1461 days
github activity october 2016 to october 2017github activity october 2016 to october 2017
And three years ago another one for 1826 days
github activity october 2017 to october 2018github activity october 2017 to october 2018
And two year another one bringing it to 2191 days
github activity october 2018 to october 2019github activity october 2018 to october 2019
And last year another one bringing it to 2257 days
github activity october 2019 to october 2020github activity october 2019 to october 2020
And as today is October 12, here is the newest one from 2020 to 2021 with a new total of 2922 days:
github activity october 2020 to october 2021github activity october 2020 to october 2021
Again, special thanks go to Alessandro Pezz for the Chrome add-on GithubOriginalStreak.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Dirk Eddelbuettel: RcppQuantuccia 0.0.4 on CRAN: Updated Calendar

A new release of RcppQuantuccia arrived on CRAN earlier today. RcppQuantuccia brings the Quantuccia header-only subset / variant of QuantLib to R. At the current stage, it mostly offers date and calendaring functions. This release is the first in two years and brings a few internal updates (such as a swift to continuous integration to the trusted r-ci setup) along with a first update of the United States calendar. Which, just like RQuantLib, now knows about two new calendars LiborUpdate and FederalReserve. So now we can for example look for holidays during June of next year under the Federal Reserve calendar and see
> library(RcppQuantuccia)
> setCalendar("UnitedStates/FederalReserve")
> getHolidays(as.Date("2022-06-01"), as.Date("2022-06-30"))
[1] "2022-06-20"
> 
that Juneteenth 2022 will be observed on (Monday) June 20th. We should note that Quantuccia itself was a bit of a trial balloon and is not actively maintained so we may concentrate on these calendaring functions to keep them in sync with QuantLib. Being a header-only subset is good, and the removal of the (very !!) expensive (in terms of compiled library size) Sobol sequence-based RNG in release 0.0.3 was the right call. So time permitting, a leaner, meaner RcppQuantuccia with a calendaring focus may emerge. The complete list changes follows.

Changes in version 0.0.4 (2021-10-12)
  • Allow for 'Null' calendar without weekends or holidays
  • Switch CI use to r-ci
  • Updated UnitedStates calendar to current QuantLib calendar
  • Small updates to DESCRIPTION and README.md

Courtesy of CRANberries, there is also a diffstat report relative to the previous release. More information is on the RcppQuantuccia page. Issues and bugreports should go to the GitHub issue tracker. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

12 October 2021

Antonio Terceiro: Triaging Debian build failure logs with collab-qa-tools

The Ruby team is working now on transitioning to ruby 3.0. Even though most packages will work just fine, there is substantial amount of packages that require some work to adapt. We have been doing test rebuilds for a while during transitions, but usually triaged the problems manually. This time I decided to try collab-qa-tools, a set of scripts Lucas Nussbaum uses when he does archive-wide rebuilds. I'm really glad that I did, because those tols save a lot of time when processing a large number of build failures. In this post, I will go through how to triage a set of build logs using collab-qa-tools. I have some some improvements to the code. Given my last merge request is very new and was not merged yet, a few of the things I mention here may apply only to my own ruby3.0 branch. collab-qa-tools also contains a few tools do perform the builds in the cloud, but since we already had the builds done, I will not be mentioning that part and will write exclusively about the triaging tools. Installing collab-qa-tools The first step is to clone the git repository. Make sure you have the dependencies from debian/control installed (a few Ruby libraries). One of the patches I sent, and was already accepted, is the ability to run it without the need to install:
source /path/to/collab-qa-tools/activate.sh
This will add the tools to your $PATH. Preparation The first think you need to do is getting all your build logs in a directory. The tools assume .log file extension, and they can be named $ PACKAGE _*.log or just $ PACKAGE .log. Creating a TODO file
cqa-scanlogs   grep -v OK > todo
todo will contain one line for each log with a summary of the failure, if it's able to find one. collab-qa-tools has a large set of regular expressions for finding errors in the build logs It's a good idea to split the TODO file in multiple ones. This can easily be done with split(1), and can be used to delimit triaging sessions, and/or to split the triaging between multiple people. For example this will create todo into todo00, todo01, ..., each containing 30 lines:
split --lines=30 --numeric-suffixes todo todo
Triaging You can now do the triaging. Let's say we split the TODO files, and will start with todo01. The first step is calling cqa-fetchbugs (it does what it says on the tin):
cqa-fetchbugs --TODO=todo01
Then, cqa-annotate will guide you through the logs and allow you to report bugs:
cqa-annotate --TODO=todo01
I wrote myself a process.sh wrapper script for cqa-fetchbugs and cqa-annotate that looks like this:
#!/bin/sh
set -eu
for todo in $@; do
  # force downloading bugs
  awk ' print(".bugs." $1) ' "$ todo "   xargs rm -f
  cqa-fetchbugs --TODO="$ todo "
  cqa-annotate \
    --template=template.txt.jinja2 \
    --TODO="$ todo "
done
The --template option is a recent contribution of mine. This is a template for the bug reports you will be sending. It uses Liquid templates, which is very similar to Jinja2 for Python. You will notice that I am even pretending it is Jinja2 to trick vim into doing syntax highlighting for me. The template I'm using looks like this:
From:   fullname   <  email  >
To: submit@bugs.debian.org
Subject:   package  : FTBFS with ruby3.0:   summary  
Source:   package  
Version:   version   split:'+rebuild'   first  
Severity: serious
Justification: FTBFS
Tags: bookworm sid ftbfs
User: debian-ruby@lists.debian.org
Usertags: ruby3.0
Hi,
We are about to enable building against ruby3.0 on unstable. During a test
rebuild,   package   was found to fail to build in that situation.
To reproduce this locally, you need to install ruby-all-dev from experimental
on an unstable system or build chroot.
Relevant part (hopefully):
 % for line in extract % >   line  
 % endfor % 
The full build log is available at
https://people.debian.org/~kanashiro/ruby3.0/round2/builds/3/  package  /  filename   replace:".log",".build.txt"  
The cqa-annotate loop cqa-annotate will parse each log file, display an extract of what it found as possibly being the relevant part, and wait for your input:
######## ruby-cocaine_0.5.8-1.1+rebuild1633376733_amd64.log ########
--------- Error:
     Failure/Error: undef_method :exitstatus
     FrozenError:
       can't modify frozen object: pid 2351759 exit 0
     # ./spec/support/unsetting_exitstatus.rb:4:in  undef_method'
     # ./spec/support/unsetting_exitstatus.rb:4:in  singleton class'
     # ./spec/support/unsetting_exitstatus.rb:3:in  assuming_no_processes_have_been_run'
     # ./spec/cocaine/errors_spec.rb:55:in  block (2 levels) in <top (required)>'
Deprecation Warnings:
Using  should  from rspec-expectations' old  :should  syntax without explicitly enabling the syntax is deprecated. Use the new  :expect  syntax or explicitly enable  :should  with  config.expect_with(:rspec)    c  c.syntax = :should   instead. Called from /<<PKGBUILDDIR>>/spec/cocaine/command_line/runners/backticks_runner_spec.rb:19:in  block (2 levels) in <top (required)>'.
If you need more of the backtrace for any of these deprecations to
identify where to make the necessary changes, you can configure
 config.raise_errors_for_deprecations! , and it will turn the
deprecation warnings into errors, giving you the full backtrace.
1 deprecation warning total
Finished in 6.87 seconds (files took 2.68 seconds to load)
67 examples, 1 failure
Failed examples:
rspec ./spec/cocaine/errors_spec.rb:54 # When an error happens does not blow up if running the command errored before execution
/usr/bin/ruby3.0 -I/usr/share/rubygems-integration/all/gems/rspec-support-3.9.3/lib:/usr/share/rubygems-integration/all/gems/rspec-core-3.9.2/lib /usr/share/rubygems-integration/all/gems/rspec-core-3.9.2/exe/rspec --pattern ./spec/\*\*/\*_spec.rb --format documentation failed
ERROR: Test "ruby3.0" failed:
----------------
ERROR: Test "ruby3.0" failed:      Failure/Error: undef_method :exitstatus
----------------
package: ruby-cocaine
lines: 30
------------------------------------------------------------------------
s: skip
i: ignore this package permanently
r: report new bug
f: view full log
------------------------------------------------------------------------
Action [s i r f]:
You can then choose one of the options: When there are existing bugs in the package, cqa-annotate will list them among the options. If you choose a bug number, the TODO file will be annotated with that bug number and new runs of cqa-annotate will not ask about that package anymore. For example after I reported a bug for ruby-cocaine for the issue listed above, I aborted with a ctrl-c, and when I run my process.sh script again I then get this prompt:
----------------
ERROR: Test "ruby3.0" failed:      Failure/Error: undef_method :exitstatus
----------------
package: ruby-cocaine
lines: 30
------------------------------------------------------------------------
s: skip
i: ignore this package permanently
1: 996206 serious ruby-cocaine: FTBFS with ruby3.0: ERROR: Test "ruby3.0" failed:      Failure/Error: undef_method :exitstatus  
r: report new bug
f: view full log
------------------------------------------------------------------------
Action [s i 1 r f]:
Chosing 1 will annotate the TODO file with the bug number, and I'm done with this package. Only a few other hundreds to go.

9 October 2021

Thorsten Alteholz: My Debian Activities in September 2021

FTP master This month I accepted 224 and rejected 47 packages. This is almost thrice the rejects of last month. Please, be more careful and check your package twice before uploading. The overall number of packages that got accepted was 233. Debian LTS This was my eighty-seventh month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload has been 24.75h. During that time I did LTS and normal security uploads of: I also started to work on exiv2 and faad2. Last but not least I did some days of frontdesk duties. Debian ELTS This month was the thirty-ninth ELTS month. Unfortunately during my allocated time I could not process any upload. I worked on openssl, curl and squashfs-tools but for one reason or another the prepared packages didn t pass all tests. In order to avoid regressions, I postponed the uploads (meanwhile an ELA for curl was published ). Last but not least I did some days of frontdesk duties. Other stuff On my neverending golang challenge I again uploaded some packages either for NEW or as source upload. As Odyx took a break from all Debian activities, I volunteered to take care of the printing packages. Please be merciful when somethings breaks after I did an upload. My first printing upload was hplip

Dirk Eddelbuettel: corels 0.0.3 on CRAN: Update

An updated version of the corels package is now on CRAN! The change is chiefly an updated configure.ac (just like RcppGSL yesterday, RQuantLib two days ago, and littler three days ago. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

8 October 2021

Dirk Eddelbuettel: RcppGSL 0.3.10: Small Update

A new release 0.3.10 of RcppGSL is now on CRAN. upload](https://dirk.eddelbuettel.com/blog/2020/06/21#rcppgsl_0.3.8). The RcppGSL package provides an interface from R to the GNU GSL by relying on the Rcpp package. This release brings a requested configure.ac update (just like RQuantLib yesterday and littler two days ago, along with the at-work tiledb update today). It also adds a small testing improvement. No user-visible changes, no new features. Details follow from the NEWS file.

Changes in version 0.3.10 (2021-10-07)
  • Tests of the client package now skip of no LIB_GSL is set
  • The configure files were updated to the standard of version 2.69 following a CRAN request

Courtesy of CRANberries, a summary of changes in the most recent release is also available. More information is on the RcppGSL page. Questions, comments etc should go to the issue tickets at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

7 October 2021

Dirk Eddelbuettel: RQuantLib 0.4.14: More Calendars plus Update

A new release 0.4.14 of RQuantLib was uploaded to CRAN earlier today, and has by now been uploaded to Debian as well. QuantLib is a very comprehensice free/open-source library for quantitative finance; RQuantLib connects it to the R environment and language. The release of RQuantLib comes just one months after the previous release, and brings three changes. First, we added both two more US-based calendars (including FederalReserve ) along with a bunch of not-yet-included other calendars which should complete the coverage in the R package relative to the upstream library. Should we have forgotten any, feel free to open an issue. Second, CRAN currently aims to have older autoconf conventions updated and notified maintainers of affected packages. I received a handful of these, and just like yesterday s update to littler refreshed this here. Third, we set up automated container builds on GitHub. No other changes were made, details follow.

Changes in RQuantLib version 0.4.14 (2021-10-06)
  • Changes in RQuantLib code:
    • Several new calendars were added (Dirk in #159 closing #155)
  • Changes in RQuantLib package and setup:
    • Docker containers are now updated on a monthly schedule via GitHub Actions
    • The configure files were updated to the standard of version 2.69 following a CRAN request

Courtesy of my CRANberries, there is also a diffstat report for the this release. As always, more detailed information is on the RQuantLib page. Questions, comments etc should go to the new rquantlib-devel mailing list. Issue tickets can be filed at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Next.

Previous.