Search Results: "tar"

25 August 2007

Gustavo R. Montesino: SoC Final Report

The Google Summer of Code coding period has ended earlier this week, so it seems to be a good time to stop and look what was done (and what wasn't). Let's start with an objective analysis, following the list of planned features:

Advanced query of bugs on the Debian BTS

In a 1-10 scale, I would give myself something like 6 or 7 here. bug-triage can query bugs by number, source package, package, maintainer and submitter. These parameters can be combined to make an query (reports must match all parameters) and more than one query may be added, subtracted and and'ed. A clearly missing feature is querying by usertag, support for it has been added on btsutils already and is just a question of adding a new input box on the query builder dialog (it should work if you enter the query manually in the bug-triage query line AFAICT).

Show all the information related to a bug report

bug-triage has a "goto" button which opens the bug in the user's preferred browser. Missing is the support to open the bug in a MUA, which I have promissed to Lo c.

Send additional information to a bug report

bug-triage has a "followup" button which opens the user's MUA with the right address. Maybe setting the subject would be nice...

Manipulate the tags of a bug report

I haven't had time to implement this at all. I've started it, the bugs have a context-sensitive menu which have each of the available tags as checkboxes on the right current status, but clicking on them does nothing currently.

Search for similar bugs in upstream developer BTS

This one would value something like 3 or 4 in a 1-10 scale. It searches upstream bugzillas by product and component, but doesn't do any cool trick like searching words in the bug subjects. The plus is that it does support KDE bugzilla, even though I haven't been brave enough to promisse it before SoC :P

Forward a bug report to the upstream developer BTS

There isn't really a good interface to report bugs programatically on GNOME bugzilla, which was disappointing. <rant>There is the bug-buddy xmlrpc(?) interface, but the developers say they will actively break anything using it, which I find very free-software-unlike.</rant>. The current bug-triage solution opens a browser with some of the fields filled. It would be nice to fill the full bug description, but its limited by the maximum size of an URL, so it fills only an introductory text (something like This bug was filled on Debian BTS #XXX) currently. Let's hope bugzilla 3 get on the GNOME world soon.

Conclusions

Unfortunately, this project hasn't evolved as much as I would like in the second half of the GSoC. As I said elsewhere, a lot of stuff has happened, some good, some bad, but on the end everything I hadn't been able to dedicate myself to anything I should. Even so, I think the project may be considered sucessful.

Maybe the more interesting product of this project, at least currently, is still on python-btsutils. As I said in the middle-term report, it'll be integrated in the debian_bundle soon, and might be powering important stuff like the devscripts in the future.

The bug-triage application has a lot to evolve yet, but is also an interesting tool IMHO. There are a lot of hurdles in the way to get different BTSes integrated, but the effort will for sure pay in the future. I plan to keep developing it (evon though keeping the GSoC pace is impossible) and am anxious to see the results ;)

Finally, as I said before, one of the main things on GSoC for me was the potential to learn cool stuff. The best choice I've made during all of this was to use Python. Even though it's still a new language for me, and i still have to search embarassingly simple things in the tutorial/reference, it was a lot more productive than if I was developing in C. Learning to use git was also a great. This goal was the more fulfilled one, I've really learnt a lot of things which will surely be useful in the future. BTOH, I still can't get used to glade :/

Lior Kaplan: Bug triaging on various packages

In the end of the my last post, I’ve offered to package maintainers who need help with bug triaging to contact me. While no mails arrived, I decided to take a more active approach. Baruch Even referred me to “Status of Maintainer’s packages, ports and bugs“, from which I could find quite easily the maintainers who have a lot of bugs. After a few manual processing and checks, an offer of help mail was sent to the maintainers of openssh, cvs, grub, cupsys, apt, dpkg, bind9, postfix, util-linux, file, xmms, wine, xorg, xorg-server, xterm, iceweasel, aptitude and emacs21. Although only a few answered the mail, I think I got enough “work” to do. I’ve agreed about the goals for a bug triage for aptitude and ice weasl,dove,ape with their maintainers. I’m pleased with the openoffice.org triage method I used, although I got some comments and suggestions from people which I’d like to apply. I’ll try to use some of Ana Guerrero’s scripts for this end. Wish my luck (:

Michal &#268;iha&#345;: First Japanese experiences

Thursday morning I arrived Chubu airport near Nagoya and at this time started my first visit to Japan. It will take quite long time (3-6 months), so I should have enough time to do as much sightseeing as I want. But there was not much time for sightseeing so far. Besides work and having rest after 24 hours of travelling, we only went today to see a bit of city. No real sightseeing, it was rather finding out some things. The most important was to find ATM accepting our credit cards. I didn't expect it will be that difficult, but it turned out that most ATMs accept only Japanese Visa and MasterCard cards and not ours. Fortunately post office has ATMs accepting foreign cards, so we finally have enough cache to survive next week ;-). The next step was to buy something we can start to learn Japanese a bit. It would be great to be able to read at least some signs and menu in restaurant. We bought few books, but later in restaurant it turned out to be almost useless. Fortunately the cook can a bit English, so we managed to order something we wanted. But this is the largest problem here - our poor Japanese knowledge as there was not time to prepare for this back at home...

Dave Noble: Vodafone-Induced Anger

Around three months ago, I received my IBM/Lenovo X60s laptop (that has been fantastically well supported under Sid). As I was going to be doing a lot of travel in the future, I decided to go for the model with the built in 3G/GPRS radio... However, what I did not realise was that it was hardware locked to work only with Vodafone sim cards.
Considering I am moving to Norway in about a month; where Vodafone does not exist, it is obviously a drawback only being able to use a Vodafone SIM; so following the gude at thinkwiki.org; I proceeded to phone [UK] IBM/Lenovo technical support. This is where the problems began.
After waiting about 10 minutes, I got through to one support tech that didn't know they were shipping laptops with 3G modems built in, who then put me through to another, and yet another. Finally, I got through to a competent tech; who contacted Lenovo for the unlock code, and called back as promised the next day. However, this code did not work; returning an incorrect code error; and being the start of Debconf, I have had no time to call back the support people until now.
It makes me angry to think that all this hassle could have been spared by Vodafone not being utter cretins and locking hardware to their network! There was no mention of this network lock on the laptop retailer's page; and had I known of this, and how much hassle it would be, I would probably have bought a different model!

Russell Coker: Designing Computers for Small Business

Dell just sent me a letter advertising their new Vostro line “especially for small business“. They say “we listened, then we listened some more” and explain that it’s based on feedback from people in small companies. The problem (which should be familiar to everyone who has ever done any consulting work) is that people don’t ask for what they need! Ask someone what they want in a computer system and the first thing that they will ask for is a fast CPU and a low price, the colour of the box will probably be higher on their priority list than the option of a backup. Dell have proved this by advertising their small business machines by advertising cheap desktop machines for small business use. Here is a list of the features that I consider essential in small business systems (based on my experience working for dozens of small companies):
Reliable operation. Using a relatively inexpensive machine as both a desktop machine and a server for the company network is very common in companies with less than 10 people. The Dell PowerEdge Tower systems are reasonably cheap (as little as $800AU - $100 more than a low-end Vostro in the base configuration, although the Vostro includes a bundled monitor). The PowerEdge machines have ECC RAM as a standard feature (avoids data loss due to memory errors) and can be delivered with hardware RAID support (SATA-2 or SAS) and a variety of backup options. A low-end tower PowerEdge server with 250G of hardware SATA RAID-1, a 160G removable disk for backup, and an extra gigabit-ethernet port costs $2015. Such a machine would do really well as a server for a small company while also being quite good as a desk-side workstation (the cooling fans would probably be louder than on most workstations but the money saved would be worth-while for most small businesses). If Dell was to promote PowerEdge tower machines (maybe under the label “Vostro Servers”) it would be good for customers and should be profitable for them. The next thing that Dell should consider is a laptop with ECC RAM. Many small businesses start out as a sole trader with a laptop. Data loss on such a machine would be catastrophic. At the design stage ECC RAM would not be difficult to add - if there was a company that produced such RAM (I expect that Dell could purchase enough volume to drive the creation of new memory modules). Another laptop issue is the reliability of mass storage. Laptops tend to get dropped and hard drives tend to break when dropped. Lenovo sells a “ThinkPad Serial ATA Hard Drive Bay Adapter” which allows two hard drives in a Thinkpad which could be used for RAID-1 (if you don’t want a built-in DVD drive). I chose to use regular backups instead of buying the extra hardware for RAID-1 but it would be good if other companies offered such options - especially when promoting their products to small businesses (who often don’t do regular backups). Even Lenovo could improve things in regard to their potential RAID-1 support in Thinkpads by promoting this feature (instead of just having the hardware listed as an optional extra with no mention of why you would want it) and offering a default install with RAID-1. Better still would be hot-swap RAID-1 in a laptop (which would be quite easy to do if the expansion bay was changed to use USB as it’s method of connection). Of course RAID-1 only covers you in the case where the drop is only enough to destroy one disk or if it causes partial damage to both disks but doesn’t destroy the same section of data on both disks. The next big thing for laptops will be flash storage. One of the major advantages of flash is that it’s almost impossible to destroy it by dropping it. I would rather have my important data on a flash storage than a hard drive (it also saves electricity and therefore makes the battery last longer). The option of having flash as the primary storage device and a hard drive for files that are larger and less important would be useful to most small businesses. Of course hardly any small business owners will ask for this, they will probably ask for a machine that has a fast CPU. Sometimes when developing a product you have to design something with the features that customers need and get the sales and marketting people to convince the customer of the benefits of the features. Even though the number of people who understand the technology and will jump at the opportunity to buy good things (such as me) is rather small, the number of people who can understand once it’s explained to them is quite significant. I’m sure that if Dell released a new line of computers with the slogan “reliable machines that don’t lose your data” instead of “good-looking new machines” then they would get some interest. After writing this post but before publication time I happened to be speaking to the owner of a small business on the topic of choice of computers for a company such as his. He seemed convinced of the benefits of a better machine to replace his current desktop PC that is running as a server (it’s yet to be seen whether he considers the benefit to be worth the cost). I wonder if Matt Domsch reads my blog…

24 August 2007

Simon Richter: componentization tutorial #1: understanding what we are trying to do

This is the first post of a series on componentization, starting with a brief explanation of the problem(s) we are trying to solve. I expect some familiarity with programming in general, but no specific knowledge of any particular system; the terms "DLL" and "shared library" are used interchangeably. When you are writing a DLL, you are essentially committing to support whatever interface you are exporting forever. So it better be good on the first try. DLL hell is what happens if it was not good, and you end up making an incompatible change. The obvious way an interface can be "not good" is when you need to touch the header files that define it in order to implement some new functionality. You can get away with a few things, like the addition of new functions, if you can somehow make sure that users will always have a recent enough version of your DLL around, but in general any change to the interface is going to be incompatible. The traditional Unix way of solving the issue has been renaming the library. When you link a program against a shared library on a system that uses the ELF format, the linker looks inside the library for the SONAME field, which tells it what name the library wants to be known under, and the program will then attempt to load this file at startup (which usually is a symlink to the latest compatible version). This "official" name of the library usually contains a number (sometimes more than one), and when there is an incompatible change, you simply change that number, and the new version of the library can be installed in parallel with the old. There are additional mechanisms, like symbol versioning support, that allow a single library to provide different "versions" of exported functions, and have the program specify the desired version for each symbol. To run a system like this, one generally needs to keep track of programs' dependencies; this generally happens in the package manager with more (Debian) or less (Red Hat) support from package build scripts. If you built your system from scratch, you end up doing this work yourself. That's why you had highly paid system administrators in the old days, and very short shell scripts to replace them (with various degrees of success) in the current age. In the Windows world, things have been a bit different, because except in large installations, you generally do not have a clueful, benevolent system administrator who will take care of these things; rather, you have users that expect your software to work without having an insight into the inner workings. In general, software developers have not been taking chances and simply shipped all the DLLs they needed along with the main program. When they installed these DLLs into the same directory as the program, things were fine, if they installed them into the WINDOWS directory, not so much, because when you had two conflicting versions of the same DLL, you had to decide which one to keep, and a program that would only work with the one that you threw away would simply fail in curious and interesting ways. This is the original definition of DLL hell — you cannot do it right. To make matters worse, this is not the only way an interface could change. When you define a platform, you write up an "Application Binary Interface" (ABI) document that details conventions that should be followed; for example, the ARM processor does not have a dedicated stack pointer register, so the ABI document for Linux on ARM says that R13 is to be used as a stack pointer, functions may thus expect it to point to memory that is readable and writeable, and memory with an address lower than the stack pointer is considered "free". When the function is done, it is supposed to jump to the address in R14, which happens to be the register the ARM's "Branch with Link" instruction sets to the address of the instruction following it. If the function takes arguments, the ABI says where to find them, and if it returns a value, it also tells where to place that. For everything not in the ABI document, the compiler author gets to choose. The ABI document usually attempts to be rather minimal, so it defines how C functions are to be called, and calls it a day. Anything not in the C standard is not guaranteed to work between different compilers (or even different versions of the same compiler). That includes C language extensions such as the "long double" data type, language features in C++ and Java such as namespaces, nested types and exceptions, and the data structures used by the C library's malloc() function. The latter makes life difficult even for pure C programmers, as it disallows releasing memory from a different module than the one it was allocated in, because the different modules may link to different C libraries. In essence, this means you are not supposed to export anything from a DLL that is not a C function, and even then, there are additional requirements. You could in theory export data objects, but that is discouraged, as it exposes an implementation detail. Now, we're in a bit of a dilemma here. There is lots of interesting code out there that is not necessarily written in C, we'd like to reuse it and we don't want stuff to break. The Linux approach so far has been "we simply pretend the problem does not exist", and this has been working to a large extent, simply because everyone uses gcc, and when the ABI extensions the gcc people had made changed, recompiling everything that uses these extensions makes the problem go away. This has several drawbacks. For one, it mandates that the tools used to rebuild everything and keep the installation consistent be written in C or handle the transition gracefully (for the curious who have a Debian system handy: look at libapt-pkg's SONAME), and it also requires that we have the full source code for everything not just available but buildable in an automated way. Within the context of a Linux distribution, both of these are true, so we have survived the last major ABI transitions without too many losses. So we need an extension of the ABI document that specifies how modules written by different people and compiled with different compilers can interact. These are commonly called component models, and, to quote Andrew Tanenbaum, "[t]he good thing about standards is that there are so many to choose from". Next: "componentization tutorial #2: CORBA and COM"

Miriam Ruiz: GoPlay!

Thumbnail of GoPlay! v0.1DebTags is a really nice system for clasifying programs, it allows you to select which packages you want by being able to select between many different kind of labels, that are used to categorize them. Anyway, there is sitll a long way to go if we want to make it easier for users to locate the programs they want, and that goes for games too. In DebConf7, in Edinburgh (Scotland), Enrico suggested me that we could do a GUI for searching the games available in Debian, using his DebTags as the backend. Starting there, using his libept library for accessing the data, FLTK (Fast Light Toolkit) as the toolkit engine, and C++ as the programming language, we’ve been slowly developing it. The version 0.1 of the program is ready, and hopefully will be in Debian soon. We’ve decided to create a standalone package with the thumbnails, that could also be shared with other programs, and the package for goplay itself. Both are now waiting in the NEW queue, and hopefully soon they will be in Debian. Of course, more snapshots of the games shall be taken, and there’s a lot of room for improvements, but at least it’s a starting point. For using it, you’ll need to install debtags and ept-cache in your system, and set them up properly, and possibly also the results from popcon, if you want to have that data in the GUI too: apt-get install debtags ept-cache
debtags update
mkdir /var/lib/popcon/
cd /var/lib/popcon
wget http://popcon.debian.org/all-popcon-results.txt.gz
ept-cache reindex

Gunnar Wolf: Have a very, <em>very</em> nice day!

And no, I don't mean Mao.
How was Thursday 23 for me?
6:30 Wake up, knowing it will be a long day. No, don't get those delicious extra 15 minutes of sleep.
8:00 Arrive to work, ~90min earlier than usual, to finish the Rails app you have to demo at 10:00
10:00 Meeting with the Institute's Director, Academic Secretary and Technic Secretary to show them the system for following the internal inter-tematic colloquium information workflow. Thankfully, they were happy with it.
11:20 (20 minutes after scheduled): As several academics have said they are interested in getting to know Linux, I'm giving a series of introductory sessions on Debian to them. So, I went with some of them through the Etch installation. Of course, mostly everything was fine. What was not? Resizing a Windows partition is still a step that requires several jumps through hoops (i.e. booting Debian LiveCDs, some console-based interactivity which I wanted to avoid...), and... Well, d-i does not time out if the selected mirror is not responding. Will file a bug, yes. Anyway...
14:30 Managed to leave the lab working, with no damages. Went to the bank to check some data and to have a quick lunch.
16:00 Get back to the institute. Jos Luis, from Difusi n y extensi n was already waiting for me to show a set of components for the Comas-based system we use for tracking attendance to the Institute's activities
16:45 The people from AMECIDER arrived so I could show them my proposal for their new website. Can you believe most of the websites I host are still completely static HTML, and, what's even worse, generated by the $ despiseful_adjective Dreamweaver? Yes, I am proposing them to move over to Drupal
17:30 I finally received another person, one of the people that's attending my Thursday lessons, wanting me to help with some Linux questions. What's Linux's killer app for my Institute's researchers? Believe it or not, a not-brain-dead PDF reader. They are amazed that, using Gnome's Evince, they can just copy-paste bits of PDFs into their documents (and the fact that pasting tabular data into OpenOffice's Calc allows for an easy import feature - Yesterday I spent ~1hr with this researcher importing data generated by the International Monetary Fund into his work), and they are even more amazed with the gnome-screenshot they can directly include graphics from such documents without redrawing them.
19:45 (45 minutes behind schedule): Went to the Astronomy Research Institute, to meet with Sergio, H ctor and Eric, to decide on bits of the implementation of the new gear we will be putting in nisamox, our dear and faithful ftp.mx.debian.org mirror. Thanks to everybody! We will soon tell you what we got and what we did with it, it's mostly settled by now.
20:30 Had the first of some... Four calls regarding yet another system I have been working with for the ICME conference, to be held in Mexico in 2008. Several pushing details that need my attention and work, bah :-/ Have to work on them...
21:00 Got home. Did a couple housekeeping activities (i.e. take out the trash, buy some food...). I was too burnt out to start making my bags for going to Vienna (I'm leaving tonight!), work on the pending systems I have to work on, or even stay awake.
Leaving work for a week to go a conference is always fun and great... But man, it's stressing!

Russell Coker: Water Prices and Scarcity

Due to climate change and population increases we are having increasing problems with the water supply in Australia. Peter Lieverdink suggests that we have more options for water supply including treated sewage similar to the Netherlands here he grew up. However I believe that in Australia we already do what he proposes (put treated sewage in rivers and then use the same rivers for the water supply). It’s just removing the middle step (of having the treated sewage in a river) that is controversial. I recently examined a water bill for my house. Among other things it said that my water use was slightly above the average for houses that use water efficiently and significantly below the average for typical water use. The funny thing was that most of the expenses on the bill were not actually related to the amount of water used. My bill for a quarter was $54 service charges for sewerage and water (of which $39 was sewerage), $30 for sewage disposal, $26 for water, and $14 for drainage. So the cost of disposing of sewage was greater than the cost of getting fresh water and the sewerage service charge was the largest single item on the bill. Australia supposedly has a capitalist economic system in place (except for the communist policies related to farming and the protection of some industries such as car manufacture and coal mining). Surely the right thing to do is to make water expensive enough that people have a financial incentive to conserve it! The first thing that should be done is to make the majority of the value of a water bill received by a typical household be determined by the amount of water used. This could be achieved by reducing the fixed components of the bill to something small (EG $20 per quarter instead of $98 for me) and then increasing the cost per kilo-litre (EG from $0.85 to $2.50). The end result would be that people who use average amounts of water would pay about the same amount as they do now and people who use less than the average amount would get smaller bills, while government revenue would remain the same. The next thing to do is to have different tarriffs for different quantities of water used. The first 50L per day could be free (water for drinking and cooking is a right), between 50 and 450L per day (451L per day being regarded as efficient water use for a house with four occupants and a medium garden) could be at slightly more than current prices, and usage greater than 450L per day could be significantly more expensive. The current situation is that everyone is going to pay through taxes for desalination plants and other expensive methods of producing new fresh water. Having people pay for what they use is the capitalist way.

Maximilian Attems: linux-2.6 bugs cleanup part 2

Random notes on effective bugs cleanup on a bigger scale:
  • Ignore the subject. In 90% of the cases it is badly formulated and provides no clue.
  • Be on a good mood or don't even start.
  • Use different overviews (bts, mbox, web, reportbug-ng, ..) to not miss the easy stuff right on start.
  • Read the last message first. A please close message on the tail or an upstream nack keeps you from reading the previous ones. Obviously as curious person i often violate that rule.
  • Have prepared standard answers on FAQ: Debian kernel patch acceptance guidelines, report issue to Linux upstream, debug initramfs.
  • Be bold: A big wontfix list won't help anyone. Close right away.
  • In the ping mail directly write To the submitter. A Cc to the bug report makes it more personal.
  • Tag any bug that is against an old version with moreinfo in the ping mail. Gives the submitter a clear indication that this bug needs an update.
  • Sometimes a close acts better as ping, reopen quickly and use the info.
  • 23 August 2007

    Joerg Jaspert: UMTS V2

    I got a few replies to my post about UMTS and finally ordered the flatrate from Moobicent as they use the Vodafone net. Vodafone got the best recommendations in the replys and is also the only one that has UMTS available in the area I want it… Basic summary of the comments is - Vodafone is the way to go as they (currently) have the best UMTS network. Even in Portugal, it seems, so if I plan a vacation that seems to be a good place to stay online during it. :) I also got the tip to always have a data transfer running in the background as it seems to make working with ssh way more comfortable. That should be simple to arrange. :) I already got the registration e-mail from Moobicent, my username and, in a seperate mail, my password to login to their service. I just need to wait for the hardware before I can start with that stuff. There was a big rant here first, about how “nice” it is to send you your username and your password in two unencrypted mails (sent at the exact same second, no difference in the header part beside subject and the SMTP id postfix puts in…………..). I decided to delete it, doesn’t help anyway. Instead I decided to play with Amazon wishlist a bit. Thats better for my blood pressure. :) Anyway, Im happy to have ordered the stuff and would love if the hardware would already be here (it will probably arrive on Friday/Saturday, I hope, having ordered on Wednesday). Oh my, lets play in NEW a bit, that usually kills lots of time… :)

    Benjamin Mako Hill: Sweet!

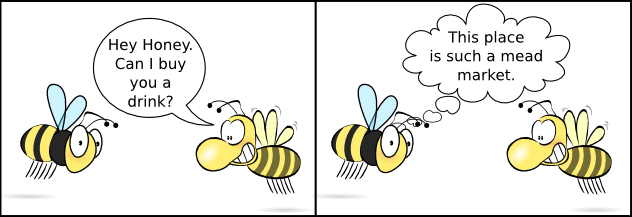
    With the help of open clipart, I made my first webcomic! /copyrighteous/images/mead_market.png On a related note, Mika and I will be holding something of a mead market this Saturday to celebrate moving into our new place and the grand opening of the Acetarium 2.0 (and its new Web 2.0 webpage). We'll also be celebrating my finishing up my degree at MIT and the end of Mika's first semester at HSPH. If you know us, are local to Boston/Camberville, and haven't been invited yet, it's probably an oversight. Contact me first and we'll work it out.

    Wouter Verhelst: Asterisk adventures, and the DECT gap.

    A customer called me a while back, requesting whether I could help him set up asterisk. Since I hadn't previously played with asterisk, we agreed that I'd try out stuff, and then do a demo setup, so that he could decide whether that is okay for his needs. So I bought me a Linksys SPA-3102 ATA (with one FXO and one FXS port) and a Linksys SPA-921 IP phone, and started experimenting. Didn't take me long to figure out that the SPA-921 works, but that if I want to use a company-wide directory (which was a requirement for that customer), I have to use a Linksys proprietary protocol, which Asterisk obviously doesn't support. Someone then told me that Snom's hardware phones have LDAP support in their hardware phones; so I bought me the Snom 300 as well, and played a bit with the system. After experimenting for about two weeks or so, alltogether, I've now got a demo setup that fulfills most of his requirements, and I can show why others can't easily be implemented. Which is cool. Afterwards, I'll be stuck with an ATA and two IP phones that I have no immediate use for at the office, so I was thinking of taking them home and using them there. We've got way too many phones at home anyway (one upstairs, one downstairs, a fax, and a DECT basestation with no less than four handsets), so adding the ability to call eachother might be useful. Except that I can't seem to find a DECT basestation that appeals to me. The one we have doesn't have VoIP, so that'll need replacement. Just connecting it to the ATA could work, but then transferring a call from a regular phone to one of the DECT handsets would be troublesome, at best; what I would prefer is the ability to give each of my DECT handsets a separate asterisk extension; in effect, a DECT - SIP bridge. What I've found so far in DECT basestations that allow me to somehow link the DECT phones to a computer, is appaling. So now basically I'm left to conclude that there is a gap in what's available in DECT basestation products; one that allows me to connect a low number of DECT handsets to a network through SIP, and has nothing more. It'd be cool if one existed...

    Russell Coker: The Start of My Computer Career

    When I was about 11 years old I decided that I wanted a career related to computers. My first computer was the TEC-1 single-board Z80 based kit computer from Talking Electronics magazine (see the photo below). I think that I built this when I was 10. tec-1.jpg The computer is 16cm high and 25cm wide. The six seven segment displays are the only built-in output device (there were optional kits for other output devices). The keypad has the hexadecimal number keys, an “ad” button for entering addresses, a “go” button for executing programs, and “+” and “-” keys for incrementing and decrementing the address. Below the reset button (labelled “R“) you will see the optional function key (of which I can’t remember the purpose). Programming this computer required entering the hexadecimal code on the keypad with the “+” and “-” keys being the main method of editing (the “ad” key was used to jump to a different section of RAM). In editing mode the first four seven-segment displays showed the address (the Z80 could only address 64K of RAM) and the other two showed the memory contents (the word size was one byte). In terms of user-friendlyness it was probably about equal to punched cards - apart from the lack of non-volatile storage (unless you built the optional NVRAM kit). My TEC-1 has 2K of RAM (the 83251R chip is equivalent to an Intel 16kilo-bit 6116 static RAM chip) and 2K of ROM (the chip with the orange sticker labeled Mon1 is a 2716 EPROM - 16kilo-bit). Not long after that my parents bought the first serious computer for the family, a Microbee Z80 based system with a tape drive that used a monochrome monitor of resolution approximately equal to CGA and which had either 16K or 32K of RAM (I can’t recall). The next family computer was a Microbee Premium series 128K which is probably the same model as the one depicted on the Microbee Wikipedia page (a serious omission of the Wikipedia page is that it has no picture of the box containing the PSU and the floppy drives for the Premium Series). My first published article in a computer magazine was when I was about 15 years old and I wrote a long email on a Fidonet echo (mailing list) reviewing a 3rd party update to the CP/M system for the Premium Series Microbee and was surprised by having it published in the Microbee club magazine (in those days we didn’t bother much about copyright so no-one asked for my permission before publishing). I wonder if starting with computers at such an age is typical for people who now contribute to free software development. I think it would be interesting to see some blog posts from other people in the community about how old they were when they started with computers and what type of computer they started with. I also wonder about the correlation between the age of starting with computers and career success in the computer industry. One significant benefit of starting early was that I could learn things that would be useful for my career in later decades while other children were wasting time studying what teachers told them to study. It also meant that in later years of high-school I could relax knowing that I could get straight B’s without effort which was more than was required to enter a CS degree program at that time. Until half-way through year 12 I tried to avoid ever doing home-work at home - home-time was computer time! Do you think that the age at which you chose your career significantly affected your success? If so in what way? If you were asked for advice by parents as to when their child should be given it’s first computer what age would you suggest? Unfortunately I usually get asked for advice about such things by people who have children aged 16+ (which is way too late IMHO).

    Brice Goglin: Debian X.org notes - ATI 6.7.191 with RandR-1.2 and TV-out support in experimental

    No, I am not confusing version numbers. Yes, xserver-xorg-video-ati 6.7.191 follows 6.6.193. Upstream thought it was useless to try fixing the dead-end 6.7 branch (where 6.6.193 came from) since they were already mostly working on the randr-1.2 branch. So 6.7 will probably never happen. The randr-1.2 support has been merged in master and will be released as driver 6.8. 6.7.191 is its first release candidate. With RandR-1.2 support, you get mode auto-detection and so, as in the Intel driver 2.x. So you may clean your xorg.conf as described here. If you don't get your desired resolution at startup, see here. However, the old dual-head support code (zaphod) is dead, so some people might have to get used to xrandr instead. Several people will also be happy that the GATOS TV-output support code has been merged and improved to support more cards. You will see a S-video output and you can enable it as usual with xrandr. Not sure how well tested it has been, but at least it seems to work fine on my rv370 (Mobility X300). Don't forget that this is a release candidate. I personally consider the code as highly experimental since I seem to get more GPU lockups when playing xmoto than in 6.6.193. The code is still under heavy development. Multiple ATI boards have strange behaviors that may not be supported yet (but it shouldn't be worse than in 6.6.193). Fortunately, upstream people are very responsive and doing a great job at fixing bugs, so feel free to ping them on IRC or report a bug directly on http://bugzilla.freedesktop.org. The package is in now in debian experimental. But the Xserver release candidate is there too. So you will need to upgrade xserver-xorg-core too. If you don't want to do so, just rebuild the driver against unstable, you should just need to downgrade xserver-xorg-dev build-depend to 1.3.0 or so.
    (Permanent link) 

    22 August 2007

    Mike Hommey: Problems and expectations

    What would you expect a software such as VMware ESX server, in its latest version, to do when it technically can’t do what you would like it to do ? Well, I, for one, would expect it, at least, to tell me… but it doesn’t. If you don’t have VT enabled on an Intel 64bits processor-based server, and want to run a 64bits OS in a VM configured to host a 64bits guest, it doesn’t tell you. All you have for your eyes to stare at is an error message from the guest OS saying that the processor doesn’t support 64bits instructions. You have to gather from this message that it only needs VT extensions to be enabled. Now, if you’re not very familiar with these technical details, what would be your first test on such a server ? I’d say, most probably, try to run the 64bits OS on the bare hardware… which would succeed, indeed, leaving the user in a big blur. Note that in the “processor” part of the configuration panel in the Virtual Infrastructure Client, while there is information about Hyperthreading being enabled or not, there is nothing about of VT.

    Evan Prodromou: 4 Fructidor CCXV

    It's been a while since I've posted here; I've had a busy two weeks, and posting on my blog hasn't been a priority. Something I should do more often. Of course, as time backs up it seems harder and harder to actually get around to posting. I wanted to bring the attention of my friends and colleagues, though, to a notice that Maj put on the Wikitravel shared logbook. As of 15 August 2007, Maj is no longer working on Wikitravel. In addition, my time has been curtailed quite a bit, and I'm concentrating only on community and content issues -- no more programming or sysadmin work. This is all coming about for several reasons. The main one is that Internet Brands, the company that now owns wikitravel.org, wanted to have their own staff do the programming and sysadmin work. The end of our service contract seemed like an ideal time to effect this change. On our side, it's been challenging for us to work with a large organization not specialized in Open Content and wiki sites. We've gotten along really well with the IB people, but we haven't always seen eye-to-eye on the best way to grow and develop the site. As the decision was made to remove us from our technical roles, Maj decided it was a good time to opt out entirely. I'm going to miss her tremendously. As most people reading this already know, we started the Wikitravel project together, and over the last 4 years it's been a constant important part of our family life. Maj's information-architecture skills and dedication to travel have been crucial to the development of the site. She's been a strategizer, a spokesperson, a content organizer and a content builder. Probably most important for the future of the project, she developed almost single-handedly the Wikitravel Extra personal experience component of the site. We've got a lot to keep us busy, though. We recently launched Keiki, a project to create an Open Content parenting guide. For myself, I've also started Vinismo, an Open Content wine guide (sensing a pattern here...?). And we'll be working with our partner Jani P. on Wikitravel Press, an independent project to publish printed travel guidebooks based on Wikitravel articles. Despite the shakeups, I anticipate that the future of Wikitravel will be good. We have an incredibly strong and smart community, dedicated to an important and noble purpose. I'll remain involved on a part-time basis. We've got a lot of traction in public opinion and great Web traffic. I don't think that IB is going to make any bad decisions about the site, but if they do there's a local and global community of people that take Wikitravel and Open Content travel guides extremely seriously. I think things are probably going to be OK. tags:

    On the subject of wiki The South by Southwest 2008 Panel Picker app is up for public review right now. SXSW Interactive, in Austin, is one of the best tech conferences of the year. I've got a panel proposal up, on Wiki 2.0 -- I really want to talk about some of the interesting new wiki apps, new wikis, and new wiki business models coming up. There are a couple of other wiki-related panels proposed -- including one on commercial wikis, which I presented about last year (Talks/SXSW07). Folks who are interested in wikis, or in SXSW, should take some time to give their feedback on the proposed panels and improved the level of discussion for 2008. tags:

    Jacobo Tarr&#237;o Barreiro: Ok everyone

    Now, who leaked debian-private to Randall Munroe?

    Guido Trotter: LISA, I m coming! :)

    It’s official: I will be representing my team at USENIX’s 21st Large Installation System Administration Conference (LISA) in Dallas (TX), speaking about the project we’re working on! My talk will be on Thursday 15th November! Check out the program: http://www.usenix.org/events/lisa07/tech/#thursday Wow, I’m so happy! :)

    Neil Williams: Moving away from gedit to geany

    gedit can be a real pain sometimes - mainly through what it still lacks: code folding, bookmarks and the ability to run two instances of gedit side by side (each with their own tabs) without having to start the second in a different workspace and then move it. Of these, code folding and bookmarks and the biggest problems with how I wanted to use gedit - for Perl source code.
    Anjuta is overkill for perl (and doesn't support perl particularly well) and bluefish perl syntax highlighting is plain broken - it gets the syntax wrong frequently (especially when using copy and paste and then requires you to edit the line at which the syntax failed before it will move on and fail a few lines later. Bah!
    So I've turned to geany - never used it before but it's great for Perl. It identifies all the objects in a Perl script or module and allows me to click on any object to go to that part of the file. It has code folding (and it works). It has bookmarks (although it would be nice to be able to click on a button to go from one mark to the next). It handles "projects" quite well too. It also makes no complaints about running in a second instance. This is really helpful because I can have apt-cross in one instance of geany - with all the relevant files in tabs - and dpkg-cross in another, with its files.
    There's a 'scribble' area in geany too which is neat - no need to have an "untitled document" tab that takes up more space on the tab bar than it deserves AND nags you when you eventually close gedit.
    I'll still use gedit for some things but I guess it's about time that I moved away from a simple but powerful text editor and used a proper IDE that can cope with Perl. For me, that is geany.

    Next.

    Previous.