Search Results: "ed"

6 January 2013

Steve Kemp: Debian-Administration.org almost migrated

The new version of the Debian Administration is almost ready now. I'm just waiting on some back-end changes to happen on the excellent BigV hosting product. I was hoping that the migration would be a fun "Christmas Project", but I had to wait for outside help once or twice and that pushed things back a little. Still it is hard to be anything other than grateful to folk who volunteer time, energy, and enthusiasm. Otherwise this week has largely consisted of sleeping, planting baby spider-plants, shuffling other plants around (Aloe Vera, Cacti, etc), and enjoying my new moving plant (video isn't my specific plant). I've spent too long reworking templer such that is now written in a modular fashion and supports plugins. The documentation is overhauled. The only feedback I received was that it should support inline perl - so I added that as a plugin this morning via a new formatter plugin:
Title: This is my page title
Format: perl
Name: Steve
----
This is my page.  It has inline perl:
   The sum of 1 + 5 is   1 + 5  
This page was written by   $name  
ObQuote: "She even attacked a mime. Just found out about it. Seems the mime had been reluctant to talk. " - Hexed

Russ Allbery: Pod::Thread 1.00 (and spin 1.80)

Well, this wasn't really what I intended to do with the tail end of my vacation, but I got started on it last night after fixing a different bug and failed to stop. Thread is the macro language (converted to HTML by a program called spin) that I use for maintaining all of my web pages, as mentioned in the previous release announcements from this week. Pod::Thread converts POD documentation into thread so that spin can convert it to HTML. This has multiple advantages over converting it directly to HTML for my web site, such as being able to use spin's methods for adding navigation links and not having to come up with separate style sheets. This release finally converts Pod::Thread to use Pod::Simple as the POD parser, which means I no longer have any modules using Pod::Parser. I find Pod::Simple a bit more fiddly to work with, but it's actively maintained and higher-quality. This conversion, for example, fixes a problem with being too aggressive about turning =item into a numeric list, something that I really couldn't fix with Pod::Parser. Also fixed in this release is the bug that got me started down this path: mishandling of URLs with anchor text. This is the second Perl module that I've converted to my new coding style and augmented test suite, and I'm getting a little bit faster at it, but it still took me a full day. (Although that included the Pod::Simple rewrite, which required touching most of the code.) I'm not entirely sure that should have been my top priority today, but oh well, I had to do it sometime. You can get the latest version from my web tools distribution page. I also uploaded a new Debian package to my personal repository. I also released spin 1.80, a follow-on from the previous release, that fixes a bug in the new code to determine last modification date from Git.

5 January 2013

Ian Wienand: Position Independent Code and x86-64 libraries

A comment pointed out that the original article from 2008 made a few simplifications that were a bit misleading, so I have taken some time to update this. Thanks for the feedback. If you've ever tried to link non-position independent code into a shared library on x86-64, you should have seen a fairly cryptic error about invalid relocations and missing symbols. Hopefully this will clear it up a little. Let's start with a small program to illustrate.
int global = 100;
int function(int i)  
    return i + global;
 
Firstly, inspect the disassembley of this function:
$gcc -c function.c
$objdump --disassemble function.o
0000000000000000 <function>:
   0:   55                      push   %rbp
   1:   48 89 e5                mov    %rsp,%rbp
   4:   89 7d fc                mov    %edi,-0x4(%rbp)
   7:   8b 05 00 00 00 00       mov    0x0(%rip),%eax        # d <function+0xd>
   d:   03 45 fc                add    -0x4(%rbp),%eax
  10:   c9                      leaveq
  11:   c3                      retq
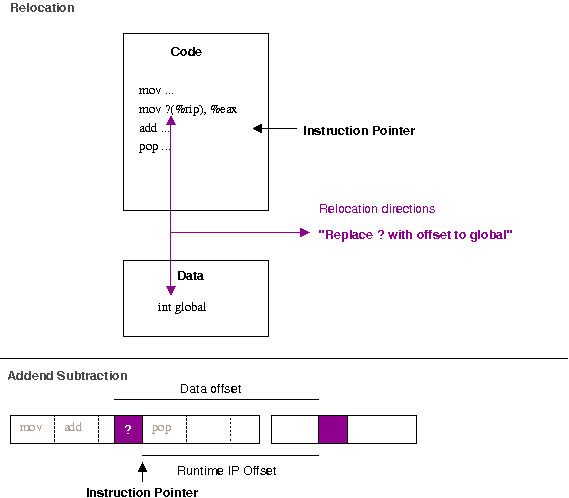
Lets just go through that for clarity: The IP relative move is really the trick here. We know from the code that it has to move the value of the global variable here. The zero value is simply a place holder - the compiler currently does not determine the required address (i.e. how far away from the instruction pointer the memory holding the global variable is). It leaves behind a relocation -- a note that says to the linker "you should determine the correct address of foo (global in our case), and then patch this bit of the code to point to that addresss". Relocations with addend The top portion of the image above gives some idea of how it works. We can examine relocations in binaries with the readelf tool.
$ readelf --relocs ./function.o
Relocation section '.rela.text' at offset 0x518 contains 1 entries:
  Offset          Info           Type           Sym. Value    Sym. Name + Addend
000000000009  000800000002 R_X86_64_PC32     0000000000000000 global + fffffffffffffffc
There are many different types of relocations for different situations; the exact rules for different relocation types are described in the ABI documentation for the architecture. The R_X86_64_PC32 relocation is defined as "the base of the section the symbol is within, plus the symbol value, plus the addend". The addend makes it look more tricky than it is; remember that when an instruction is executing the instruction pointer points to the next instruction to be executed. Therefore, to correctly find the data relative to the instruction pointer, we need to subtract the extra. This can be seen more clearly when layed out in a linear fashion (as in the bottom of the above diagram). If you try and build a shared object (dynamic library) with an object file with this type of relocation, you should get something like:
$ gcc -shared function.c
/usr/bin/ld: /tmp/ccQ2ttcT.o: relocation R_X86_64_32 against  a local symbol' can not be used when making a shared object; recompile with -fPIC
/tmp/ccQ2ttcT.o: could not read symbols: Bad value
collect2: ld returned 1 exit status
If you look back at the disassembly, we notice that the R_X86_64_32 relocation has left only 4-bytes (32-bits) of space left for the relocation entry (the zeros in 7: 8b 15 00 00 00 00). So why does this matter when you're creating a shared library? The first thing to remember is that in a shared library situation, we can not depend on the local value of global actually being the one we want. Consider the following example, where we override the value of global with a LD_PRELOAD library.
$ cat function.c
int global = 100;
int function(int i)  
    return i + global;
 
$ gcc -fPIC -shared -o libfunction.so function.c
$ cat preload.c
int global = 200;
$ gcc -shared preload.c -o libpreload.so
$ cat program.c
#include <stdio.h>
int function(int i);
int main(void)  
   printf("%d\n", function(10));
 
$ gcc -L. -lfunction program.c -o program
$ LD_LIBRARY_PATH=. ./program
110
$ LD_PRELOAD=libpreload.so LD_LIBRARY_PATH=. ./program
210
If the code in libfunction.so were to have a fixed offset into its own data section, it will not be able to be overridden at run-time by the value provided by libpreload.so. Additionally, there are only 4-bytes available to patch in for the address of global -- since a shared library could conceivably be loaded anywhere in the 64-bit (8-byte) address space we therefore need 8-bytes of space to cover ourselves for all possible addresses global might turn up at. The two basic possibilities for an object file are to be either linked into an executable or linked into a shared-library. In the executable case, the value of global will be in the exectuable's data section, which should definitely be reachable with a 32-bit offset of the current instruction-pointer. The instruction-pointer relative address can simply be patched in and the executable is finalised. But what about the shared-library case, where we know the value of global could essentially be anywhere within the 64-bit address space? It is possible to leave 8-bytes of space for the address of global, by telling gcc to use the large-code model. e.g.
$ gcc -c -mcmodel=large function.c
$ objdump --disassemble ./function.o
./function.o:     file format elf64-x86-64
Disassembly of section .text:
0000000000000000 <function>:
   0:  55                      push   %rbp
   1:  48 89 e5                mov    %rsp,%rbp
   4:  89 7d fc                mov    %edi,-0x4(%rbp)
   7:  48 b8 00 00 00 00 00    movabs $0x0,%rax
   e:  00 00 00
  11:  8b 10                   mov    (%rax),%edx
  13:  8b 45 fc                mov    -0x4(%rbp),%eax
  16:  01 d0                   add    %edx,%eax
  18:  5d                      pop    %rbp
  19:  c3                      retq
However, this creates a problem if you really want to share this code. By having to patch in an address of global directly, this means the run-time code above does not remain unchanged. Two separate processes therefore can't share this code -- they each need separate copies that are identical but for their own addresses of global patched into it. By enabling Position Independent Code (PIC, with the flag -fPIC) you can ensure the code remains share-able. PIC means that the output binary does not expect to be loaded at a particular base address, but is happy being put anywhere in memory (compare the output of readelf --segments on a binary such as /bin/ls to that of any shared library). This is obviously critical for implementing lazy-loading (i.e. only loaded when required) shared-libraries, where you may have many libraries loaded in essentially any order at any location. Of course, any problem in computer science can be solved with a layer of abstraction and that is essentially what is done when compiling with -fPIC. To examine this case, let's see what happens with PIC turned on.
$ gcc -fPIC -shared -c  function.c
$ objdump --disassemble ./function.o
./function.o:     file format elf64-x86-64
Disassembly of section .text:
0000000000000000 <function>:
   0:   55                      push   %rbp
   1:   48 89 e5                mov    %rsp,%rbp
   4:   89 7d fc                mov    %edi,-0x4(%rbp)
   7:   48 8b 05 00 00 00 00    mov    0x0(%rip),%rax        # e <function+0xe>
   e:   8b 00                   mov    (%rax),%eax
  10:   03 45 fc                add    -0x4(%rbp),%eax
  13:   c9                      leaveq
  14:   c3                      retq
It's almost the same! We setup the frame pointer with the first two instructions as before. We push the first argument into memory in the pre-allocated "red-zone" as before. Then, however, we do an IP relative load of an address into rax. Next we de-reference this into eax (e.g. eax = *rax in C) before adding the incoming argument to it and returning.
$ readelf --relocs ./function.o
Relocation section '.rela.text' at offset 0x550 contains 1 entries:
  Offset          Info           Type           Sym. Value    Sym. Name + Addend
00000000000a  000800000009 R_X86_64_GOTPCREL 0000000000000000 global + fffffffffffffffc
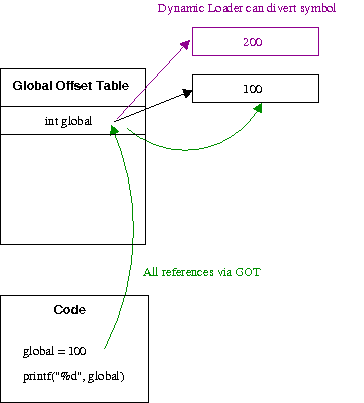
The magic here is again in the relocations. Notice this time we have a P_X86_64_GOTPCREL relocation. This says "replace the data at offset 0xa with the global offset table (GOT) entry of global. Global Offset Table operation with data variables As shown above, the GOT ensures the abstraction required so symbols can be diverted as expected. Each entry is essentially a pointer to the real data (hence the extra dereference in the code above). Since we can assume the GOT is at a fixed offset from the program code within plus or minus 2Gib, the code can use a 32-bit IP relative address to gain access to the table entries. So, taking a look a the final shared-library binary we see a final offset hard-coded
$ gcc -shared -fPIC -o libfunction.so function.c
$ objdump --disassemble ./libfunction.so
00000000000006b0 <function>:
 6b0:  55                      push   %rbp
 6b1:  48 89 e5                mov    %rsp,%rbp
 6b4:  89 7d fc                mov    %edi,-0x4(%rbp)
 6b7:  48 8b 05 8a 02 20 00    mov    0x20028a(%rip),%rax        # 200948 <_DYNAMIC+0x1d8>
 6be:  8b 10                   mov    (%rax),%edx
 6c0:  8b 45 fc                mov    -0x4(%rbp),%eax
 6c3:  01 d0                   add    %edx,%eax
 6c5:  5d                      pop    %rbp
 6c6:  c3                      retq
 6c7:  90                      nop
Every process who wants to share this code just needs to make sure they have their unique address of global at 0x20028a(%rip). Since each process has a separate address-space, this means they can all have different values for global but share the same code! Thus the default of the small-code model is sensible. It is exceedingly rare for an executable to need more than 4-byte offsets for a relative access to a variable in it's data region, so using a full 8-byte value would just be a waste of space. Although leaving 8-bytes would allow access to the variable anywhere in the 64-bit address space; when building a shared library, you really want to use -fPIC to ensure the library can actually be shared, which introduces a different relocation and access to data via the GOT. This should explain why gcc -shared function.c works on x86-32, but does not work on x86-64. Inspecting the code reveals why:
$ objdump --disassemble ./function.o
00000000 <function>:
   0:   55                      push   %ebp
   1:   89 e5                   mov    %esp,%ebp
   3:   a1 00 00 00 00          mov    0x0,%eax
   8:   03 45 08                add    0x8(%ebp),%eax
   b:   5d                      pop    %ebp
   c:   c3                      ret
$ readelf --relocs ./function.o
Relocation section '.rel.text' at offset 0x2ec contains 1 entries:
 Offset     Info    Type            Sym.Value  Sym. Name
00000004  00000701 R_386_32          00000000   global
We start out the same, with the first two instructions setting up the frame pointer. However, next we load a memory value into eax -- as we can see from the relocation information, the address of global. Next we add the incoming argument from the stack (0x8(%ebp)) to the value in this memory location; implicitly dereferencing it. But since we only have a 32-bit address-space, the 4-bytes allocated is enough to access any possible address. So while this can work, you're not creating position-independent code and hence not enabling code-sharing. The disadvantage of PIC code is that you require "bouncing" through the GOT, which requires more loads and reads to find an address than directly referencing it. However, if your program is at the point that this is becoming a performance issue you're probably not reading this blog! Hopefully, this helps clear up that possibly cryptic error message. Further searches around position-independent code, global-offset tables and code-sharing should also yield you more information if it remains unclear.

Jan Wagner: Brainfucked intellectual property rights

This issue is about a bit specific situation in Germany and it's (mainly tax-financed) public service broadcasting. If you think you are not interested, please skip this entry. :) Just beginning from scratch... In Germany we have (like most european countries) a public service broadcasting. Starting with 2013 the system collecting the funding of the public service broadcasting changed from GEZ to Beitragsservice.
To make it short (and a bit simplified) ... it changed from "most 'families' have to pay" to "every menage has to pay". This means, even if you don't have any device to use the service of the german public service broadcasting but are a menage, you have to pay for it. This sitiation is even more worse than pay-TV. Don't get me wrong ... I'm neither against public service broadcasting nor against paying for it in principle. In the rare cases I'm watching TV, this is most likely a channel of the public service broadcasting. Same counts for the rest of my small family. Mostly we are watching news and documentations ... also some movies are watched. The kids are watching KiKA, which we like cause it's Ads-free and it's not just some cartoons with hidden violence. So we most likely benefit from public service broadcasting. Anyways ... in common we are not using "TV" as most of the others may do. We still like some sort of the broadcast, but we are missing it cause various reasons. For our luck there is a service called 'Mediathek' provided by the most german public service broadcasting channels. If you missed a broadcast or are prevented for any reason, you may watch the broadcast there. Unfortunately the timeframe you can access the broadcast is very short, in most cases 7 days. This is manifested in the so called Rundfunkstaatsvertrag, more precisely in the 12. Rundfunk nderungsstaatsvertrag. The 'Tagesschau' has a good explanation about the issue. This means, in simple words, the tax payed broadcasts needs to be deleted after a (in my eyes) short time. WTF?!? Why do we wipe work we all payed for it? Guess what ... it was implemented by lobbying from commercial print media and private (e.g. ads-financed) TV-channels. A comment about a related problem, which I agree, can be found here. Another challenge ... How do you know there is a broadcasting your are interested in? How do you know when it is broadcasted? I remember, my parents was subscribed to a daily newspaper, which included an additional TV paper, my parents-in-law bought also one.
As we are neither subscribed to a daily newspaper nor buying a TV paper, we have to solve that differently (beside that a printed paper won't help us I think). When we use the opportunity to watch TV at the evening, I just use an electronical TV paper (-app). If we find something which fits, we are fine .. if not, we do other things. This sounds a bit like an old school behaviour and it is not, how I would like to use a media today. I like using a feedreader. You can subscribe differnt 'channels' of information feeds and it is a way I would love to use TV. In the past I used a tool called 'Mediathek', which is a tool for Mac OSX. With this tool it was easily possible to find broadcasts, you could subscribe to so called 'channels', which means broadcasts of a same series for example. You could also mark them as "unread" und "read" .. something like a feedreader.
On the other way, it was also possible to list recent broadcast per genres and popular broadcast of the recent and the last week. This was very comfortable as this was working for several mediathek sites for german public service broadcasting channels in one central place. For every broadcast you could just view it or download it to view it later. You could even download subscribed channels automatically. After using the Mediathek-App and being satisfied by the Mediathek sites of the german public service broadcasting channels for several years, this week the server(s) behind the App was shut down. What the f....?!? On Twitter the author stated that the shutdown was cause by problems with the copyright law. Das Erste, ZDF and WDR denied that they has anything todo with this recent issue. The question is ... what is the direct cause for shutting down such a good service. This smells a bit like the PirateBay issue, but in this case the content which is Mediathek providing access to isn't pirated, but legal hosted. So where is the real issue? In my mind, the german citizen has payed to produce this content and should have the right to access the content is an usable way. The Mediathek App did provide such a way and it is really pissing me off that this access isn't available anymore, at least for this reason. Actually I don't see any solution to access our payed content in a decent way. Footnote: I think it's obscenely, that publishing houses and commercial broadcaster trying to gain their turnover at the expense of the german citizen by forcing the german legislature to implement Depublication,.

Ian Campbell: Debugging Initramfs Issues With No Console

The QNAP TS-XXX NAS boxes are nice little systems but one thing I really miss is a console. Martin Michlmayr has some instructions (TS-119, TS-219, TS-41x) on his excellent Debian On QNAP pages on how to build a suitable adaptor but sadly even though I've managed to get all the parts I've been too lazy to actually solder the thing together (it doesn't help that I nearly always burn myself when I use a soldering iron!). This became more pressing when someone reported that Debian bug #693263 in qcontrol was not fixed in Wheezy since the issue appeared to be in the initramfs hook. Worse it seemed like something in my proposed fix was causing the system to not boot at all! Having finally found the hardware needed to reproduce the issue my first thought was to try netconsole. To do this I edited /etc/initramfs-tools/modules to add:
      mv643xx_eth
      netconsole netconsole=@<IP>/eth0,@<DST-IP>/<DST-MAC>
The option syntax is described in netconsole.txt but briefly: <IP> is the address of the TS-419P II I'm debugging on, and <DST-IP> and <DST-MAC> are the IP and MAC address of another machine on the network. Having done that, running update-initramfs -u and rebooting I can use netcat -u -l -p 6666 on the other machine to see all the kernel messages. So far so good but this doesn't get me any debugging from the userspace portions of the initramfs. To get those we have to get a bit hacky by editing /usr/share/initramfs-tools/init, first to change:

     # Parse command line options
    -for x in $(cat /proc/cmdline); do
    +for x in $(cat /proc/cmdline) debug; do
            case $x in
and secondly:

             debug)
                     debug=y
                     quiet=n
    -                exec >/run/initramfs/initramfs.debug 2>&1
    +                exec >/dev/kmsg 2>&1
                     set -x
                     ;;
The first of these simulates adding debug to the kernel command line (which can't otherwise easily be edited on these systems) and the second redirects the initramfs process's output to the kernel log. The overall effect is that the output of the initramfs processes appears over netcat.

Tanguy Ortolo: rlwrap: give readline super powers to any command line tool

Did you ever use a tool such as netcat, which has no history and does not allow you to edit the line you are typing?
% nc localhost smtp
220 cocorico.example.com ESMTP Postfix
HELO localhost
250 cocorico.example.com
MAIL FROM: <tanguy@localhost>
250 2.1.0 Ok
RCTP TO: <tanguy@localhost>
502 5.5.2 Error: command not recognized
^[[A Sh*t, line recall does not work!
502 5.5.2 Error: command not recognized
Here comes rlwrap: it is a small and useful tool that wraps any command line-oriented tool using readline to provide you a history allow you to edit each line before you send it:
% rlwrap nc localhost smtp
220 cocorico.example.com ESMTP Postfix
HELO localhost
250 cocorico.example.com
MAIL FROM: <tanguy@localhost>
250 2.1.0 Ok
RCTP TO: <tanguy@localhost>
502 5.5.2 Error: command not recognized
  RCTP TO: <tanguy@localhost>  
rlwrap's effect is hard to describe with a transcript, so here are two screencasts, with and without it. If you often use tools such as netcat, try it!
<video alt="SMTP session with netcat" controls="controls" src="http://tanguy.ortolo.eu/blog/data/images/screenshots/smtp-session.webm">Sorry your browser does not support videos, you may want to try another one.</video>

SMTP session without rlwrap

<video alt="SMTP session with netcat and rlwrap" controls="controls" src="http://tanguy.ortolo.eu/blog/data/images/screenshots/smtp-session-rlwrap.webm">Sorry your browser does not support videos, you may want to try another one.</video>

SMTP session with rlwrap

Olly Betts: Empty Strings in C++

Gaurav (one of Xapian's GSoC students this year) queried my advice that it's better not to explicitly initialise a std::string in C++ like this:
std::string s = "";
but instead to write:
std::string s;
It could be argued that the former makes it clearer that the string is initialised (since C++ does inherit C's behaviour of not implicitly initialising variables of fundamental types, such as int and double). But objects aren't left uninitialised - the default constructor gets called (or if there isn't one, the code won't compile). The downside is that you get quite a lot more code from the first version than the second. Perhaps compilers will grow smarter and in future both the above will compile to the same code, but that's not true today. Here's a simple bit of test code:
#include <string>
std::string f()  
#ifdef EXPLICIT_INIT
    std::string s = "";
#else
    std::string s;
#endif
    return s;
 
And I'll compile it with GCC (g++ (Debian 4.7.2-4) 4.7.2) on x86-64 to produce assembler output:
$ g++ -O2 -S s.cc -o s1.s
$ g++ -DEXPLICIT_INIT -O2 -S s.cc -o s2.s
$ diff s1.s s2.s
1a2,4
>   .section        .rodata.str1.1,"aMS",@progbits,1
> .LC0:
>   .string ""
9,10c12,25
<   movq    %rdi, %rax
<   movq    $_ZNSs4_Rep20_S_empty_rep_storageE+24, (%rdi)
---
>   pushq   %rbx
>   .cfi_def_cfa_offset 16
>   .cfi_offset 3, -16
>   movl    $.LC0, %esi
>   movq    %rdi, %rbx
>   subq    $16, %rsp
>   .cfi_def_cfa_offset 32
>   leaq    15(%rsp), %rdx
>   call    _ZNSsC1EPKcRKSaIcE
>   addq    $16, %rsp
>   .cfi_def_cfa_offset 16
>   movq    %rbx, %rax
>   popq    %rbx
>   .cfi_def_cfa_offset 8
(As an aside, I wouldn't recommend spending a lot of time digging into the assembler your compiler produces, but if there's more than one equivalent way to write code for a common case (as here) and you want to know which is most efficient, it can be informative to see what code is produced for each). You don't really need to know x86-64 assembler to grasp what's happening above, which is lucky, since I don't really know x86-64 assembler. In the first hunk, we get an empty literal string being added to the rodata (read-only data) section; and in the second, instead of two instructions which copy a standard empty string representation, we get much more elaborate code, including a function call to _ZNSsC1EPKcRKSaIcE - the C++ mangled name for the std::string from const char * constructor:
$ c++filt _ZNSsC1EPKcRKSaIcE
std::basic_string<char, std::char_traits<char>, std::allocator<char> >::basic_string(char const*, std::allocator<char> const&)
I also tested the example above with clang (Debian clang version 3.0-6 (tags/RELEASE_30/final) (based on LLVM 3.0)) and the resultant code is fairly similar for each case. The overhead for doing this once isn't going to matter, but if it happens every time you declare a std::string variable, the cumulative effects may be measurable. And as well as taking longer to execute, the larger code will cause greater CPU cache pressure.

Russ Allbery: Automated Perl testing

I started several coding projects today, but none of them reached an announcable conclusion, so this seems like a good day to write up my current discoveries in automated Perl testing modules. This post isn't about test frameworks like Test::More and friends, or even about helper modules (although I do recommend Test::Warn if you want to test warning code in your modules). It's not about writing functionality tests. Rather, it's about various CPAN modules that can be used almost identically in just about every Perl module distribution (and in some other places, like Perl scripts inside a larger package written in another language). You can drop a small driver script into your t directory and (mostly) run make test with no further customization. If you want to see the driver scripts for all of the below that I'm currently using, see the t directory of the Term::ANSIColor distribution. They'll slowly make their way into my other modules, and probably, despite the name of the package, rra-c-util, since that's my equivalent of gnulib and I have tools to synchronize shared code from that package. The driver script generally tests whether the module is installed, skips the test if not, and otherwise dispatches to the "test everything" routine in the module. Test::MinimumVersion: This tests that you're not accidentally using a newer Perl feature than you were expecting. It's very handy if you want to support backward compatibility to a particular version of Perl. It knows about features as far back as 5.004_05. It won't be able to catch everything, but it will catch some of the most obvious things. Test::Perl::Critic: This is sort of the thousand-pound gorilla. Test::Perl::Critic runs all of your code through perlcritic and reports any errors. You will probably need to combine this with a perlcriticrc file in your distribution that you configure it to use, since otherwise the person running the tests may have customized perlcritic. If you let it run perltidy to check for formatting problems, you'll also want a perltidyrc. See the driver script mentioned above for how I set that up. I usually configure this test to only run for me (by checking an environment variable) since the results vary a lot depending on what version of perlcritic is installed, and it's likely new versions will cause the test to start failing. If you use this, expect to need to add ## no critic annotations to your code. Test::Pod: Checks for syntax errors in your POD documentation so that you won't have those embarassing POD ERRORS sections. Note that the latest version of podlators turns syntax errors into fatal errors, so soon you won't have to worry as much about this. But if you'd been using this module all along, you wouldn't have to worry about the fact that pod2man may start faliing due to syntax errors you never fixed! Test::Pod::Coverage: Only of interest to module distributions, not ramdom scripts, this checks that every sub provided by your module has POD documentation. It understands various subs that don't need to be documented (such as the ones you provide to implement a tied class) and lets you mark some subs as not requiring documentation. Test::Pod::Spelling: Checks your POD documentation for spelling mistakes with a spell checker. (Note that perlcritic, and hence Test::Perl::Critic, can also do this, but I use this module separately since I think the output is more readable.) You will almost certainly want to make this test maintainer-only, since spell checkers and spelling dictionaries vary a lot. But it prevents a lot of embarassment when you read your documentation on search.cpan.org and find that obvious spelling error you never saw before. Test::Strict: Checks all Perl code to ensure that it compiles, checks whether it has use strict, and optionally checks whether it has use warnings. This is great; I use this even with packages that just have a few Perl utility scripts in a package otherwise written in C, since I previously kept releasing packages with helper scripts with obvious syntax errors since I didn't run them much. Another place it's useful is if you have internal Debian packages that wrap up Perl utility scripts; just create a small test suite with this module and run it from override_dh_auto_check and you won't ever release a package with scripts that won't run. You can also do test suite coverage testing with this module (and Devel::Cover), but that you'll want to mark maintainer-only since it takes a while. Test::Synopsis: Checks the code in the SYNOPSIS section of any POD documentation to ensure that it compiles. No more syntax errors in your example code in the documentation! All of these modules are, of course, packaged for Debian (thanks largely to the wonderful Perl packaging team!), and otherwise available on CPAN. There are a variety of others, of course; these are just the main ones that I've found personally useful. One final whine, however: all this wonderful Perl testing infrastructure desperately needs a common module and a common interface for providing a list of files to check. Every one of these modules reinvents that wheel, and most of them do it a slightly different way than all the others. Most of them check in either blib or lib (or sometimes both). Most of them also add t. Most of them don't include Makefile.PL, but some of them do. Almost none of them look in examples. Some have a simple way to add more files or directories; some don't. Some can be run from the t directory and still find things, but most of them can't. And of course the syntax is different in every case! Most of the work in my driver scripts is finding the right way to add a few additional directories to the scope of the testing, and in one annoying case (Test::Synopsis), I actually had to use Perl::Critic::Utils (for lack of a better module) to build a list of files to check instead of using the build-in file list, since the build-in file list required all module code be in lib. A module to abstract out all of this and provide a common interface would be easy to write. Most of the work would involve talking to all the authors of all these different modules and asking them to use it. If someone in the Perl community felt like doing that, it would make life so much easier for everyone.

Paul Tagliamonte: Updates to dput-ng since version 1.0

Big release notes since 1.0: We ve got a new list dput-ng-maint@lists.alioth.debian.org feel free to subscribe!
1.3:
  * Avoid failing on upload if a pre/post upload hook is missing from the
    Filesystem.
  * Fix "dcut raises FtpUploadException" by correctly initializing the uploader
    classes from dcut (Closes: #696467)
1.2:
  * Add bash completions for dput-ng (Closes: #695412).
  * Add in a script to set the default profile depending on the building
    distro (Ubuntu support)
  * Fix a bug where meta-class info won't be loaded if the config file has the
    same name.
  * Add an Ubuntu upload target.
  * Added .udeb detection to the check debs hook.
  * Catch the correct exception falling out of bin/dcut
  * Fix the dput manpages to use --uid rather then the old --dm flag.
  * Fix the CLI flag registration by setting required=True
    in cancel and upload.
  * Move make_delayed_upload above the logging call for sanity's sake.
  * Fix "connects to the host even with -s" (Closes: #695347)
Thanks to everone who s contributed!
     7  Bernhard R. Link
     4  Ansgar Burchardt
     3  Luca Falavigna
     2  Michael Gilbert
     2  Salvatore Bonaccorso
     1  Benjamin Drung
     1  Gergely Nagy
     1  Jakub Wilk
     1  Jimmy Kaplowitz
     1  Luke Faraone
     1  Sandro Tosi
This has been your every-once-in-a-while dput-ng update. We re looking for more code contributions (to make sure everyone s happy), doc updates (etc) or ideas.

4 January 2013

Richard Hartmann: Release Critical Bug report for Week 01

Another gaffe Sorry for pushing this on Saturday, couldn't manage to do it earlier. I'm just glad that other than running my script, updating UDD source (the stats below) and then copying that one line over to here, there's no coherent thought required to publish this. Another gist The UDD bugs interface currently knows about the following release critical bugs: How do we compare to the Squeeze release cycle?
Week Squeeze Wheezy Diff
43 284 (213+71) 468 (332+136) +184 (+119/+65)
44 261 (201+60) 408 (265+143) +147 (+64/+83)
45 261 (205+56) 425 (291+134) +164 (+86/+78)
46 271 (200+71) 401 (258+143) +130 (+58/+72)
47 283 (209+74) 366 (221+145) +83 (+12/+71)
48 256 (177+79) 378 (230+148) +122 (+53/+69)
49 256 (180+76) 360 (216+155) +104 (+36/+79)
50 204 (148+56) 339 (195+144) +135 (+47/+90)
51 178 (124+54) 323 (190+133) +145 (+66/+79)
52 115 (78+37) 289 (190+99) +174 (+112/+62)
1 93 (60+33) 287 (171+116) +194 (111/+83)
2 82 (46+36)
3 25 (15+10)
4 14 (8+6)
5 2 (0+2)
6 release!
Graphical overview of bug stats thanks to azhag:

David Welton: The Software Millionaire Next Door

I've been reading "The Millionaire Next Door" and have so far found it to be a pleasant book with a good message: don't waste your money on silly things and appearance (fancy suits, fancy cars, expensive boats, etc...), save what you do earn consistently and constantly, invest wisely, and so on. Wikipedia has a good summary:
http://en.wikipedia.org/wiki/The_Millionaire_Next_Door
One of the things I like about it is that it focuses on "ordinary" wealthy people, those with a million or more in the bank, but not the Warren Buffets or Bill Gates types that are extreme statistical outliers. There are plenty of people in the US who have done well by themselves by slowly but surely putting together enough money to be financially independent, without, however, being in the spotlight. As the book says, these are the kind of people who maybe own a local chain of businesses doing something fairly ordinary, but doing it well enough to succeed. They may very well not live in a fancy house, nor drive an expensive car, or otherwise outwardly draw much attention to themselves. The world of software does not revolve around "dressing for success" (you noticed?), but we do tend to focus on the "big winners". Gates, Jobs, Zuckerberg, Larry & Sergey, Larry Ellison, and so on are the stars of the show. Of course, the economics of software being what they are, instances of winner-take-all markets with one big fish and a lot of also-rans are not uncommon. However, that is not the only story, and I think it'd be interesting to know more about those in our industry who have accumulated significant wealth, yet are not the guys with more money than they could possibly ever spend on things that aren't, say, country-sized chunks of real-estate. I'm guessing they'd fall into these categories: It'd be very interesting to gather some actual data on this, although I'm not in a position to do so myself - I wouldn't even really know where to start. As I age, I think the third category has begun to seem appealing in many ways - I'm simply not cut out for the Big Company life, and I'm not interested in living in Silicon Valley and going "all in" on the latest startup - I already did that, and while it was fun and I don't regret it, it's not the kind of thing I'd want to do now that I'm married and have kids. Incidentally, this more relaxed, under the radar approach is exactly what is expoused in one of my favorite books of the past few years, Start Small, Stay Small. Edit : I finished reading the book and reviewed it here: http://davids-book-reviews.blogspot.com/

Jan Wagner: New blogging engine

You may have noticed that I recently started posting more updates again. The reason is, I switched over from Wordpress to Octopress as blogging engine. The idea was driven, cause my used theme K2 got stuck and with the upcoming release of Debian wheezy I'm forced to switch to a more recent Wordpress release, which is likely incompatible.
Another reason is, that I got bored by wordpress itself (and it's software dependencies). With octopress these dependencies are lowered to a webserver which can server static files and rsync on the server side. Maybe I will post some parts of the story, what I did when migrating the content and what components (plugins, theme ...) I'm using, later.

Thorsten Glaser: on the linguistic gender of hosts, with an xz reminder

Let s start a convention: bare-metal machines have the linguistic male gender ( der Computer , he needs to be rebooted), whereas VMs have the linguistic female gender ( die virtuelle Maschine , she runs better since the last upgrade of Linux-KVM), and neutral linguistic gender is used when you cannot or do not want or need to make such distinction.
This is, of course, entirely unrelated to human gender, but not unrelated to #debian-68k (on OFTC) discussions ;-) ObRant: DO NOT USE xz COMPRESSION LEVELS ABOVE 6! (For -7 we can make exceptions, for example in Debian *-dbg or *-source packages.) You may use -e if you absolutely need the better compression, but please think of the poor sods who have to create the archives. You must not use the highest compression levels -8 or -9 since they have absolutely insane memory requirements on compression and will still hinder machines with less RAM on decompression. (Using -e only affects CPU usage at compression time; decompression is exactly as fast and memory-consuming as without.) Furthermore, DO NOT CHOOSE A COMPRESSION LEVEL WITH A DICTIONARY SIZE MUCH LARGER THAN THE DATA TO COMPRESS, as that makes absolutely no sense and will rather worsen than improve compression. As a reminder, xz uses the following dictionary sizes: Decompression uses less than 1 MiB more than the dictionary size, but the dictionary must always be allocated wholly. (You re fine to use custom presets, but mind the RAM usage!) As a general rule, if you have something of up to 20 MiB to compress, -4 is fine, and -5 will only be better if you have similar data spread across the whole of the file instead of close to each other. When I make mksh distfiles, I instead put files close to each other that have related content, which improves compression much more nicely without penalising low-memory systems; for example, you could put documentation, Makefiles, scripts, m4(1) files, and C source code into groups before archiving, instead of doing it alphabetically. Another note on bzip2: its decompression is slow. I see no reason to use it any more, at all. Use gzip(1) if you care for compatibility or have an issue with xz not having a free copyright licence, and xz otherwise.

Stefano Zacchiroli: bits from the DPL for December 2012

Happy new year, Debian! To celebrate, here are some freshly posted, bits from the DPL for December 2012.
Dear Project Members, happy new year! Here goes another report of DPL activities, this time for December 2012. This issue of the DPL-monthly is skinnier than usual: during the past month I've been struck by the catastrophe also known as "family holiday season", enjoying a solid 10 day break from computer-related activities. Talks Assets DPL helpers Collaboration with the outer world That's all for last year, enjoy the new one, which will soon see a new Debian release out of the door. And to make it happen sooner, let's go back fix RC bugs! Cheers.
PS the day-to-day activity log for December 2012 is available at the usual place master:/srv/leader/news/bits-from-the-DPL.txt.201212

Hideki Yamane: As tech writer

Sometimes I write articles for Japanese Tech Magazine, the recent one is for Software Design 2013/01. It's "Overview for 2013", of course I wrote about Debian :-)


And luckyly, editor requested the series (yeah!), so I'll do it for a while. I'm happy to get a chance to provide Debian information to readers, thanks!

... and I hope they'll be a media sponsor for DebConf in Japan (in some day :)

Julien Danjou: Integrating cl-irc and cl-async

Recently, I've started programming in Common Lisp. My idea here is to use cl-irc, an IRC library into an event loop. This can be really useful, for example to trigger action based on time, using timers. Creating a connection The first step is to create a basic cl-irc:connection object on our own. This can be achieved easily with this:
(require :cl-irc)

(defun connect (server)
(cl-irc:make-connection :connection-type 'cl-irc:connection
:client-stream t
:network-stream ?
:server-name server))

This will return a cl-irc:connection object, logging to stdout (:client-stream t) and having the server name server. Note that the server name could be any string. You probably noticed the ? I used as :network-stream value. This is not a real and working value: this should be a stream established to the IRC server you want to chat with. This is where we'll need to use cl-async:tcp-connect to establish a TCP connection. As you can read in this function's documentation, all we need to pass is the server address, two callbacks for read and general events, and the :stream option to get a stream rather than a socket. So you would do something like:
(require :cl-irc)
(require :cl-async)

(defun connection-socket-read (socket stream)
(format t "We should read the IRC message from ~a ~%" stream))

(defun connection-socket-event (ev)
(format t "Socket event: ~a~%" ev))

(defun connect (server &optional (port 6667))
(cl-irc:make-connection :connection-type 'cl-irc:connection
:client-stream t
:network-stream (as:tcp-connect server port
#'connection-socket-read
#'connection-socket-event
:stream t)
:server-name server))

(as:start-event-loop (lambda () (connect "irc.oftc.net")))

If you run this program, it will connect to the OFTC IRC server, and then notice you each time the server is sending you a message. Therefore our problem here is how we you treat the message read from the stream in connection-socket-read and handle them in the name of our connection object you used? We can't link both together at this point. We can't build a closure, because as the time we use as:tcp-connect we don't have the cl-irc:connection instance. Also we can't change easily the read-cb parameter of our network-stream established by as:tcp-connect, simply because cl-async doesn't use to do allow that. Building a closure So one solution here is to hack cl-irc:make-connection so we can build an cl-irc:connection instance without providing in advance the network-stream, allowing us to build a closure including the cl-irc:connection to read event for. This is what we're going to do in the connect function.
(require :cl-irc)
(require :cl-async)
(require :flexi-streams)

(defun connection-socket-read (connection)
(loop for message = (cl-irc::read-irc-message connection)
while message
do (cl-irc:irc-message-event connection message)))

(defun connection-socket-event (ev)
(format t "Socket event: ~a~%" ev))

(defun connect (server port nickname
&key
(username nil)
(realname nil)
(password nil))
;; Build an instance of cl-irc:connection, without any network/output stream
(let* ((connection (make-instance 'cl-irc:connection
:user username
:password password
:server-name server
:server-port port
:client-stream t))
;; Use as:tcp-connect to build our network stream, and build a
;; closure calling connection-socket-read' with our connection'
;; as arguments
(network-stream (as:tcp-connect server port
(lambda (socket stream)
(declare (ignore socket stream))
(connection-socket-read connection))
#'connection-socket-event
:stream t)))
;; Set the network stream on the connection
(setf (cl-irc:network-stream connection) network-stream)
;; Set the output stream on the connection
(setf (cl-irc:output-stream connection)
;; This is grabbed from cl-irc:make-connection
(flexi-streams:make-flexi-stream
network-stream
:element-type 'character
:external-format '(:utf8 :eol-style :crlf)))

;; Now handle the IRC protocol authentication pass
(unless (null password)
(cl-irc:pass connection password))
(cl-irc:nick connection nickname)
(cl-irc:user- connection (or username nickname) 0 (or realname nickname))
connection))

(as:start-event-loop (lambda () (connect "irc.oftc.net" 6667 "jd-blog")))

And here we are! If we run this, we're now using an event loop to run cl-irc. Each time the socket has something to read, the function connection-socket-read will be called on the non-blocking mode socket. If there's no message to be read, then the function will exit and the loop will continue to run. Using timers You can now modify the last line with this:
(defun say-hello (connection)
(cl-irc:privmsg connection "#jd-blog" "Hey I read your blog!")
(as:delay (lambda () (say-hello connection)) :time 60))

(as:start-event-loop (lambda ()
(let ((connection (connect "irc.oftc.net" 6667 "jd-blog")))
(cl-irc:join connection "#jd-blog")
(say-hello connection))))

This will connect to the IRC server, join a channel and then say the same sentence every minute. Challenge accomplished! And I'd like to thank Andrew Lyon, the author of cl-async, who has been incredibly helpful with my recent experimentations in this area.

Russell Coker: Links January 2013

AreWomenHuman has an interesting article about ViolentAcrez and the wide support for trolling (including by media corporations) [1]. Chrys Stevenson wrote an important article for the ABC about the fundamentalist Christians who are trying to take over the Australian education system [2]. Tavi Gevinson gave an interesting TED talk titled A teen just trying to figure it out about her work starting Rookie magazine and her ideas about feminism [3]. Burt Rutan gave an interesting and inspiring TED talk about the future of space expploration [4]. One of his interesting points is that fun really is defendable in regard to tourism paying for the development of other space industries. Stephen Petranek gave an interesting TED talk about how to prepare for some disasters that could kill a significant portion of the world s population [5]. Some of these are risks of human extinction, we really need to spend some money on it. John Wilbanks gave an intresting TED talk about the way that current informed consent laws prevent large-scale medical research [6]. He says I live in a web world where when you share things beautiful stuff happens, not bad stuff . Joey Hess was interviewed for The Setup and the interview sparked a very interesting Hacker News discussion about workflow for software development [7]. Like most developers I prefer large screens with high resolution, I have an EeePC 701 which works reasonably well for an ultra-portable system but I largely don t use it now I have an Android phone (extremely portable and totally awful input usually beats moderately portable and mostly awful input for me). But Joey s methods are interesting and it seems that for some people different systems give the best result. Jeff Masters gave an insightful TED talk about the weather disasters that may seriously impact the US in the next 30 years [8]. Governments really need to start preparing for such things, some of them are really cheap to mitigate if work is started early. Bryan Stevenson gave an inspiring TED talk about the lack of justice in the US justice system [9]. Wouter Verhelst wrote an insightful article about some of the criticisms of Linux from Windows users [10]. He references a slightly satirical post he previously wrote about why Windows isn t ready for desktop use. Paul Carr wrote an interesting article comparing disruptive business practices of dot-com companies to the more extreme aspects of Ayn Rand s doctrine [11]. In reading some of the links from that article I discovered that Ayn Rand was even more of a sociopath than I had previously realised. Lindy West gave an amazing Back Fence PDX talk about dealing with nasty blog comments from the PUA/MRA communities [12]. After investigating them she just feels sorry for the trolls who s lives suck. Hang from the Vlogbrothers explains gender, sex, sexual orientation, etc [13]. Rick Falkvinge wrote an interesting article about recent political news from Brazil, they had a proposed law that was very positive for liberty on the Internet but it was sabotaged by the media and telcos [14]. We should try to avoid paying any money to the media industry so that they can go away sooner. Amy Cuddy gave an interesting TED talk about body language, power, and the imposter syndrome [15]. Caleb Chung gave an interesting TED talk about toy design which focussed on Pleo a robotic dinosaur with a SD card and USB socket to allow easy reprogramming by the user [16].

Ian Wienand: Tagging handbrake output for iTunes

If you rip your DVD's with a unix-y name like longish-show-name-season-01-01.m4v then the iPad and iPhone video player only shows the prefix of the file-name to it's string limit, so you only ever see longish-show-na and can never tell what episode is what in the overview list. You can edit the files in iTunes to add meta-data information, but that's annoying and non-unix-y. It is of course easy, but I went down several dead-ends with tools that didn't recognise file-extensions, corrupted files and plain didn't work. The package I had most success with is mp4v2-utils and the mp4tags utility. The help is fairly self-explanatory, but something like
mp4tags -show "Show Name" -season <season> -episode <episode> -type "tvshow"  file.m4v
will mean that when you import your file into iTunes it displays correctly as a TV show (and not a movie), is grouped correctly into series and has a name you can see. Unfortunately, it doesn't seem my Nexus 7 tablet picks up these tags. And both players interfaces remain terrible at indicating which episodes have been watched and which have not. But this has allowed me to re-visit my old box-set of Yes Minister which, despite a few odd references to Quango's still seems as relevant as ever!

Russ Allbery: cl2xhtml 1.10

cl2xhtml converts GNU ChangeLog files to XHTML for (hopefully) pretty web display. After making the most recent Term::ANSIColor release, I noticed that it didn't support the multi-author ChangeLog convention. This is not in the GNU standards, but it's become conventional to note changes by multiple authors with the syntax:
2013-01-03  Some Author <author@example.com>
            Another Person <person@example.com>
        * file.c: Some change.
cl2xhtml now understands that syntax, including with more than two authors, and turns it into a list of authors on the HTML page separated with commas and "and" as needed. You can get the latest version of cl2xhtml from my web tools page.

Russ Allbery: spin 1.79

spin is the program that I use to generate all of my web pages, including this journal, from a bespoke macro language. I've been slowly evolving it since 1999 and really do intend to turn it into a proper Perl module one of these days.... My web site was one of the few places left that I was still using Subversion, and I finally decided to do something about that during this vacation. The main reason why it wasn't trivial was that I was using Subversion Id strings to get a more accurate last change date for files rather than just using file timestamps. (Nit-picky, I know, but if I'm not allowed to be nit-picky on my own web site, where can I be?) This release recognizes when the source directory is a Git working tree and supports determining the last modification date from git log instead (by way of the Git::Repository Perl module). I also updated all my various (not released) helper scripts for maintaining the site to use Git rather than Subversion, which mostly involved changing svn to git and removing some fiddly bits that Git doesn't require. Of course, this means that I also removed the \id thread commands on all my pages, which in turn means that I just updated the last modification date of every file, making it somewhat hard to test since every thread-generated page on my site has now been modified today. *heh* You can get the latest release of spin from my web tools distribution page. I also released version 1.44 of my release utility, which I use to help automate some of the work of generating software releases. The change there is to use Git rather than Subversion to commit changes to the .versions file that drives some of the software-related parts of my web site. You can get the latest version of release from my scripts page.

Next.

Previous.
