On Linux, network interface device naming has been somewhat chaotic: depending
on a number of factors,
eth0 today might not be
eth0 tomorrow. For me, this
has never been a problem in practice. At work, our physical servers have a bank
of on-mainboard network ports, all managed by the same driver and so are
assigned names predictably. For our virtual machines, the same is true: 99% of
the time they have one network interface, but when they have more than one,
they are of the same type and so are assigned predictably. At home, even on
desktops and laptops with multiple network devices being added and removed at a
time, I've never actually hit a problem where one was mis-identified.
However, it must have been a problem for some people because it has been
solved three times
now.
Sadly, these incompatible solutions cause headaches in all of my use cases.
At work we have a puppet snippet that relies on knowing the interface name for
a host's "primary" interface. In our case, "primary" means something like "the
one the default route is over". We used to hardcode
eth0 into this recipe. I
don't feel too bad about that, as
the puppet folks do the exact same thing in
many of their scripts.
This breaks for newer physical hosts where one of the three schemes are in play
and the interfaces are named/numbered
em1 and counting. We worked around it
by parameterizing the interface name in our recipe and defining it in our
nodes.pp for the troublesome hosts, but that just moves the problem around.
My more permanent solution is to define a facter fact
primary_interface that
tells puppet what the correct interface should be. Here's my first attempt:
Facter.add("primary_interface") do
  setcode do
    ifs = Dir.new("/sys/class/net").each.to_a - \
      Dir.new("/sys/devices/virtual/net").each.to_a
      # filter out ones with no link
      ifs.reject! do  i
        begin
          File.read("/sys/class/net/# i /carrier") != "1\n"
        rescue Errno::EINVAL
          true
        end
      end
    ifs[0]
  end
end
Of course, there is plenty of room for improvement with this solution: if
ifs
has more than one element at the end, a lexographic sort may prove more
accurate; if there is an existing network default route up, that might be a
strong clue too. It's also very Linux specific. My question though is whether
this is a sensible approach in the first place?

Better debugging tools can help us understand what's going on with MIME messages. A python scrap i wrote a couple years ago named
printmimestructure has been very useful to me, so i thought i'd share it. It reads a message from stdin, and prints a visualisation of its structure, like this:
0 dkg@alice:~$ printmimestructure < 'Maildir/cur/1269025522.M338697P12023.monkey,S=6459,W=6963:2,Sa'
 multipart/signed 6546 bytes
  text/plain inline 895 bytes
  application/pgp-signature inline [signature.asc] 836 bytes
0 dkg@alice:~$
You can fetch it with git if you like:
git clone git://lair.fifthhorseman.net/~dkg/printmimestructure
It feels silly to treat this ~30 line script as its own project, but i don't know of another simple tool that does this. If you know of one, or of something similar, i'd love to hear about it in the comments (or by sending me e-mail if you prefer). If it's useful for others, I'd be happy to contribute
printmimestructure to a project of like-minded tools. Does such a project exist? Or if people think it would be handy to have in debian, i can also package it up, though that feels like it might be overkill. and oh yeah, as always: bug reports, suggestions, complaints, and patches are welcome :)Tags:
debugging,
mime,
python

Over the last couple of weeks, I have been working on getting
binary packages for [Varnish] modules built. In the current version,
you need to have a built, unpacked source tree to build a module
against. This is being fixed in the next version, but until then, I
needed to provide this in the build environment somehow.
RPMs were surprisingly easy, since our RPM build setup is much simpler
and doesn't use mock/mach or other chroot-based tools. Just make a
source RPM available and unpack + compile that.
Debian packages on the other hand, they were not easy to get going.
My first problem was to just get the Varnish source package into the
chroot. I ended up making a directory in
/var/lib/sbuild/build
which is exposed as
/build once
sbuild runs. The other hard part
was getting Varnish itself built.
sbuild exposes two hooks that
could work: a
pre-build hook and a
chroot-setup hook. Neither
worked: Pre-build is called before the chroot is set up, so we can't
build Varnish. Chroot-setup is run before the build-dependencies are
installed and it runs as the user invoking
sbuild, so it can't
install packages.
Sparc32 and similar architectures use the
linux32 tool to set the
personality before building packages. I ended up abusing this, so I
set HOME to a temporary directory where I create a
.sbuildrc which sets
$build_env_cmnd to a script which in turns unpacks the Varnish
source, builds it and then chains to
dpkg-buildpackage. Of course,
the build-dependencies for modules don't include all the
build-dependencies for Varnish itself, so I have to extract those from
the Varnish source package too.
No source available at this point, mostly because it's beyond ugly.
I'll see if I can get it cleaned up.

Finally,
phpMyAdmin packages for Debian and Ubuntu do not lag much behind upstream. Today, I've prepared packages for yesterday released bug fix release 3.5.6.
For Debian users, the package should be soon available in
experimental (sorry no uploads to unstable during freeze).
Ubuntu users, can use
my phpMyAdmin PPA. After
dozens of comments and no help offered, I've still decided to be nice to Ubuntu users and adjusted the package so that it should work on Lucid as well. The downside is that, unlike in Debian, the package includes bundled copy of many PHP and javascript libraries.
PS: As soon as Debian is not frozen or 4.0 is officially released, I will start uploading 4.0 to experimental. My current bet is that 4.0 release will come earlier.
Filed under:
Debian
English
Phpmyadmin
0 comments
Flattr this!
Indeed, two days was enough time to recover from an afternoon of social,
despite having an hour and a half of meetings today. But today was a day
of catching up, sorting issues in JIRA, doing lots of planning meetings,
and doing some debugging, so I don't have anything new code-wise to give
to the world. So have a photograph.
The product backlog is now all sorted out for the Account Services project
into the new phases that will define the work through pretty much the end
of the calendar year, I'm guessing. And everything is now a story, not a
bug or enhancement or something else without story points, and a few
things are shuffled into a more reasonable order.
I'm probably going to find a few hours this week to go play video games or
work on personal projects, given that I've been working well over 40 hours
a week since the start of the year.
Michael Biebl and I are giving a talk on
systemd in Debian at
FOSDEM on Sunday morning at 10. We'll be talking a bit about the
current state in Wheezy, what our plans for Jessie are and what Debian
packagers should be aware of. We would love to get input from people
about what systemd in Jessie should look like, so if you have any
ideas, opinions or insights, please come along. If you're just
curious, you are also of course welcome to join.
Well, today was another day of sleeping, zoning, and having no brain for
programming (and no willpower for that or exercise, which is even more
frustrating), so you all get more musing about missions and work.
Tomorrow, I will re-engage my normal schedule and turn the television off
again, because seriously, two days of recovery should be enough even for a
whole afternoon of meetings.
Perhaps the best concept in the scrum methodology for agile project
management is the concept of the product backlog and the product owner.
For those who aren't familiar, a scrum project has, as one of its inputs,
a prioritized list of stories that the team will implement. During each
planning session (generally between once a week and once a month), the
development team estimates and takes from the front of the product backlog
the top-priority stories that can be completed during that period of time.
The product owner is responsible for building the list of pending
development stories based on business needs and keeping them sorted in
priority order so that the work of the team follows the goals of the
larger organization. But the product owner does not get to say how
difficult the stories are; the development team estimates the stories, and
the product owner may change order based on those estimates (to do simpler
things earlier, for example).
We've been doing scrum to some extent or another for quite some time now,
and while there are a variety of things that I like about it, I think this
is the best part. And I think it has very useful concepts for management
in general.
The product backlog is effectively a problem stream of the sort that I
talked about in my last couple of posts. It's a set of problems that need
to be solved, that matter to other people. And, if the team is doing
scrum properly, the problems are presented in a form that describe a
complete unit of desired functionality with its requirements and
constraints, but without assuming any sort of implementation. The problem
is the domain of the product owner; the solution is the domain of the
development team.
I am increasingly convinced that my quality of life at work, and that of
many other people doing similar sorts of development and project work,
would be drastically improved if managers considered this role the core of
their jobs. (Ironically, at least in our initial experiences with scrum,
it was quite rare for regular managers to be product owners; instead,
individual line staff or project managers act as product owners. I think
this speaks to how confused a lot of managers are about their roles in a
technical development organization. This seems to be improving.) The
core of the sort of work that I do is a combination of ongoing maintenance
and solving new problems. Both of those can be viewed as a sequence of
(possibly recurring) stories; I know this because that's largely how I do
my own time management. Apart from HR and staffing, the core role of a
manager is almost exactly what scrum calls "backlog grooming":
communicating with everyone who has input into what their group is doing,
finding out what their problems are, translating that into a list of
things that the organization needs to have done, prioritizing them,
breaking them into manageable chunks, ensuring they are fully specified
and actionable (read: well-written stories), and communicating their
completion back to other stakeholders (and then possibly iterating).
This lept out at me when I started thinking about our larger strategic
vision. That strategic vision is a sort of product backlog: a set of
development stories (or, in this case, epics that would be broken down
into a large number of smaller stories). But most strategic plans have
glaring flaws if they're evaluated by the standards of scrum product
backlogs. They're normally written as marketing statements and aimed at
the clients or customers rather than at the staff. From the staff
perspective, they're often hopelessly vague, not concrete, actionable
epics. Often, they are almost entirely composed of grand, conceptual
epics that any scrum team would immediately reject as too large and
nebulous to even discuss. And often they're undefined but still
scheduled: statements that the organization will definitely complete some
underspecified thing within the next year or two.
Scrum rightfully rejects any form of scheduling for unspecified stories
and epics. Additional vagueness and sketchiness is tolerated the farther
the story is from the current iteration, so they can be put into the
future backlog, but scrum makes no guarantees about when they'll get done
until they've been sized and you can apply a reasonable velocity estimate.
If you want to put a date on something, you have to make it concrete.
This is exactly the problem that I have with long-range strategic plans.
We already know this about technology development: long-range strategic
plans are feel-good guesses, half-truths, and lies that we tell other
people because we're expected to do so, but which no one really believes.
The chance that we can predict anything about the shape of projects and
rate of delivery of those projects three years from now is laughable, and
certainly none of the work that would be required to make real estimates
has normally been done for those sorts of long-term strategic projects.
There are a lot of scrum advocates who would go farther than I in asking
for a complete revolution of how technical projects are planned. I'm not
sure how realistic that is, or how well the whole scrum process would work
when rolling up work across dozens, if not hundreds, of scrum-sized teams.
But in the specific area of the role of managers in a development
organization, I think we could learn a lot from this product backlog
concept. Right now, there is a constant tension between managers who feel
like they need to provide some sort of visionary leadership and guidance
(the cult of Steve Jobs) and line staff who feel like managers don't
understand enough about specific technology to lead or guide anything.
But if you ask a technical developer whether, instead, it would be useful
for managers to provide a well-structured, priority-ordered, and clean
problem stream from the larger organization so that the developer can
trust the problem stream (and not have to go talk to everyone themselves)
but have control over the choice of implementation within the described
constraints, I think you would find a great deal of enthusiasm.
As a further bonus, scrum has a lot of advice about what that problem
stream should look like. I think some of the story structuring is
overblown (for example, I can't stand the story phrasing structures, the
"AS A... I WANT TO... SO THAT..." shackles), but one thing it does
correctly emphasize is the difference between problem and solution. The
purpose of the story is to describe the outcome from the perspective of
the person who will use the resulting technology. Describing the
constraints on the solution, in terms of cost or integrations, is actively
encouraged. Describing the implementation is verboten; it's up to the
project team to choose the implementation that satisfies the constraints.
If managers in general would pick up even that simple distinction, I think
it would greatly improve the engagement, excitement, and joy that
developers could take in their work.
There's very little that's more frustrating than to be given an
interesting problem in the guise of a half-designed solution and be told
that one is not permitted to apply any of one's expertise in elegance,
robustness, or durability to replacing the half-baked partial solution.
Or even be allowed to know the actual motivating problem, instead of the
half-digested form that the manager is willing to pass on.

I'll be at
FOSDEM again this year, arriving in Brussels on Thursday 31st and leaving on Tuesday 5th.
I'll be speaking on Sunday in the
legal issues devroom at 10:00.
If you will be there and want to meet up,
let me know.
I may be trying to watch the Super Bowl from there, a plan that didn't quite work out last year but seems more likely this year.
State of the GNUnion
FSF licensing policy challenges in 2013
This talk will cover the main challenges facing the Free Software Foundation's Licensing and Compliance lab in 2013, and will invite discussion of the FSF's work and policies in this area. We'll explore:
- Copyright assignment: Some high-profile GNU maintainers have recently criticized the FSF's copyright assignment policy and system. What are these criticisms, what does the FSF intend to do about them, and what's the point of its assignment process to begin with?
- GPL adoption: Last year here, in "Is copyleft being framed?", I put numbers supposedly showing declining GPL adoption in perspective, showing problems with the data, questioning the conclusions drawn from the data, and presenting different data leading to the opposite conclusions. We'll look at the questions that were raised since then about my data, and at some new data that's been made available, and draw new conclusions.
- App Stores: When Apple's App Store launched, the FSF concluded that its terms were incompatible with the GPL -- and with any kind of strong copyleft. Since then, we have several new App Stores; most notably from Google and Microsoft. Are the Apple terms still incompatible with the GPL? Are the other stores any better? Are these stores undermining GPL adoption, and should copyleft relax its standards in order to get free software to this audience, or should it stand its ground?
 Jan
Wagner
writes about using ethtool to poll the link state on
network devices. While I'm pleased to see another happy ethtool
user, it's a bit heavyweight for reading one bit of information
and it's not ideal for scripting.
Much information about each network device is available under
the
/sys/class/net/name directory, including the
carrier and
speed attributes. (When the interface
is down, some of these attributes cannot be read.) It's also
possible to listen for link changes (rather than polling
periodically) using the rtnetlink API, but this is probably not
suitable for munin.
This morning I gave a status report on SE Linux. The talk initially didn t go too well, I wasn t in the right mental state for it and I moved through the material too fast. Fortunately Casey Schaufler asked some really good questions which helped me to get back on track. The end result seemed reasonably good. Here s a summary of the things I discussed:
Transaction hooks for RPM to support SE Linux operations. This supports signing packages to indicate their security status and preventing packages from overwriting other packages or executing scripts in the wrong context. There is also work to incorporate some of the features of that into dpkg for Debian.
Some changes to libraries to allow faster booting. Systems with sysvinit and a HDD won t be affected but with systemd and SSD it makes a real difference. Mostly Red Hat s work.
Filename transition rules to allow the initial context to be assigned based on file name were created in 2011 but are not starting to get used.
When systemd is used for starting/stopping daemons some hacks such as run_init can be avoided. Fedora is making the best progress in this regard due to only supporting systemd while the support for other init systems will limit what we can do for Debian. This improves security by stopping terminal buffer insertion attacks while also improving reliability by giving the daemon the same inherited settings each time it s executed.
Labelled NFS has been accepted as part of the NFSv4.2 specification. This is a big deal as labelled NFS work has been going for many years without hitting such a milestone in the past.
ZFS and BTRFS support but we still need to consider management issues for such snapshot based filesystems. Filesystem snapshots have the potential to interact badly with relabelling if we don t develop code and sysadmin practices to deal with it properly.
The most significant upstream focus of SE Linux development over the last year is SE Android. I hope that will result in more work on the X Access Controls for use on the desktop.
During question time I also gave a 3 minute lightning talk description of SE Linux.

My old X61 has 2G in RAM and 3G in Swap. It seems my using-habit for Google Chrome is heavy (more than 20 tabs open most of the time) so my swap is normally being used above the 1.8G-mark. That means, my disk is constantly being written and read, and since this is the original hard-drive scare comes to my mind:
will I blow-up my disk if I continue doing this? and the heat this disk-use's generating was absurd.
That's not good, at all, I prefer having cache used than swap; in Venezuela is not that easy to get a good sale on hard-drives (you know, is hard to get dollars here, since is illegal to buy them unless the govt gives you permission).
So the first thing that comes to my mind is
sysctl. If I wanted to cofigure swap it would be with a kernel parameter. So running
sysctl -a grep swap throws me
vm.swappiness = 60, and a little google search tells me more about it.
If the swappiness is close to 0 then it will use the swap only if it is really necessary, if it is close to 100 then it will use the swap aggressively. Mine was at 60, and it was really aggressive.
The next steps for me was doing
sudo echo 'vm.swappiness = 1' >> /etc/sysctl.conf && sudo sysctl -p.
Now my system is really smooth and using Chrome + Terminal + Tmux + Rhythmbox is acceptable.
The next point update for Debian 6.0 should include many fixes and
improvements to the Linux kernel. Version 2.6.32-47, currently
available in the 'squeeze-proposed-updates' suite, includes
updates to the following SAS drivers, adding support for new
hardware:
Note that the binary package names don't change; they are still
linux-image-2.6.32-5-
flavour.
If you are using any of the above SAS controllers, whether or not it
is already supported by Debian 6.0.6, please consider testing this
kernel version. If it works, please follow up to the bug reports
listed above. If you find any regressions, please report bugs
against the new package version.

Usually I'm monitoring stuff with
Icinga (Nagios in the past). But for my small network, I primary needed monitoring of bandwidth.
In our commercial environment we are using a closed source software for accounting traffic. There is also a license for testing purpose with a reduced number of sensors available. But I'm neither running windows in this network nor feeling happy with this.
Cacti is a bit bloated for this small network and
zabbix is (caused by what?)
removed in
wheezy, beside that I'm not getting the concept behind it. So I thought I could give
munin a try and on the first view it doesn't look so bad. Monitoring my half dozens
openwrt devices works like a charm by installing
muninlite just the
package.
One central part of the network is a QNAP TS-459 Pro+, hosting a
BackupPC and TimeMachine service, proving SMB/AFS data store and running
SqueezeBox Server for another half dozen streaming devices. Unfortunately there is no
optware package to provide a munin node. So I just copied the shell script of muninlite and the xinet config over from an openwrt device. At first it looked not bad, but than munin wasn't able to collect the data. After a while I realized, that munin was failing when collecting the network informations. A look into the muninlite script revealed that it was failing when trying to discover the interface speed of eth1 via ethtool.
In my setup the QNAP is just connected with with one network interface, the second one is unconnected. Unfortunately all network interfaces on QNAP devices are up and therefore listed in /proc/net/dev where muninlite is discovering the network interfaces:
[~] # grep '^ *\(ppp\ eth\ wlan\ ath\ ra\ ipsec\ tap\ br-\)\([^:]\)\ 1,\ :' /proc/net/dev   cut -f1 -d:   sed 's/ //g
> s/\-/_/g'
eth1
eth0
Let's look into it:
[~] # ethtool eth0  grep Speed:
    Speed: 1000Mb/s
[~] # ethtool eth0  grep "Link detected:"
    Link detected: yes
[~] # ethtool eth1  grep Speed:
    Speed: Unknown! (65535)
[~] # ethtool eth1  grep "Link detected:"
    Link detected: no
Maybe you see .. the interface eth1 is up but has no link, so there is no speed negotiated and muninlite is failing. Thus I hacked the scripted and now it's working like a charme.
<notextile><figure class="code"><figcaption>
(muninlite_fix-unused-up_interface.diff) download</figcaption>
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
| --- /opt/sbin/munin-node.orig 2013-01-27 15:13:51.869007214 +0100
+++ /opt/sbin/munin-node 2013-01-27 16:11:20.536006950 +0100
@@ -133,7 +133,7 @@
if [ -n "$(which ethtool)" ]; then
if [ -x "$(which ethtool)" ]; then
if ethtool $1 grep -q Speed; then
- MAX=$(($(ethtool $1 grep Speed sed -e 's/[[:space:]]\ 1,\ / /g' -e 's/^ //' -e 's/M.*//' cut -d\ -f2) * 1000000))
+ MAX=$(($(ethtool $1 grep Speed sed -e 's/[[:space:]]\ 1,\ / /g' -e 's/^ //' -e 's/M.*//' sed -e 's/Unknown\!/0/' cut -d\ -f2) * 1000000))
echo "up.max $MAX"
echo "down.max $MAX"
fi
@@ -535,19 +535,31 @@
for INTER in $(grep '^ *\(ppp\ eth\ wlan\ ath\ ra\ ipsec\ tap\ br-\)\([^:]\)\ 1,\ :' /proc/net/dev cut -f1 -d: sed 's/ //g
s/\-/_/g');
do
- INTERRES=$(echo $INTER sed 's/\./VLAN/')
- RES="$RES if_$INTERRES"
- eval "fetch_if_$ INTERRES () fetch_if $INTER $@; ;"
- eval "config_if_$ INTERRES () config_if $INTER $@; ;"
+ if [ -n "$(which ethtool)" ]; then
+ if [ -x "$(which ethtool)" ]; then
+ if [ -n "$(ethtool $INTER grep 'Link detected: yes')" ]; then
+ INTERRES=$(echo $INTER sed 's/\./VLAN/')
+ RES="$RES if_$INTERRES"
+ eval "fetch_if_$ INTERRES () fetch_if $INTER $@; ;"
+ eval "config_if_$ INTERRES () config_if $INTER $@; ;"
+ fi
+ fi
+ fi
done
elif [ "$PLUG" = "if_err_" ]; then
for INTER in $(grep '^ *\(ppp\ eth\ wlan\ ath\ ra\ ipsec\ tap\ br-\)\([^:]\)\ 1,\ :' /proc/net/dev cut -f1 -d: sed 's/ //g
s/\-/_/g');
do
- INTERRES=$(echo $INTER sed 's/\./VLAN/')
- RES="$RES if_err_$INTERRES"
- eval "fetch_if_err_$ INTERRES () fetch_if_err $INTER $@; ;"
- eval "config_if_err_$ INTERRES () config_if_err $INTER $@; ;"
+ if [ -n "$(which ethtool)" ]; then
+ if [ -x "$(which ethtool)" ]; then
+ if [ -n "$(ethtool $INTER grep 'Link detected: yes')" ]; then
+ INTERRES=$(echo $INTER sed 's/\./VLAN/')
+ RES="$RES if_err_$INTERRES"
+ eval "fetch_if_err_$ INTERRES () fetch_if_err $INTER $@; ;"
+ eval "config_if_err_$ INTERRES () config_if_err $INTER $@; ;"
+ fi
+ fi
+ fi
done
elif [ "$PLUG" = "netstat" ]; then
if netstat -s >/dev/null 2>&1; then
|
</figure></notextile>

yeah, the RC bug count is going down, mostly due to the
bug squashing
party taking place in cambridge, uk, this weekend (with participation of
some release team members).
here are my contributions during the last week:
#677054 nut-client: "nut-client: prompting due to modified conffiles which were not modified by the user"
add some information to the bug log, later NMUd by Ivo De Decker/Andreas Beckmann#695710 src:adplug: "adplug: includes non-free documentation (GFDL with unmodifiable sections)"
repack again, upload to DELAYED/5- #696144 spamassassin: "20_head_tests.cf: regex for illegal IP address contains valid network 5/8"
add a comment to the bug report, then marked as fixed in wheezy+sid by other contributor
#698764 libio-compress-perl: "libio-compress-perl: breaks "debmirror" and possibly other packages."
some investigation (pkg-perl), later closed as user error- #698979 src:libmail-cclient-perl: "libmail-cclient-perl: FTBFS with DEB_BUILD_OPTIONS=nocheck"
fix debian/rules (pkg-perl), severity later downgraded by release team
Whenever I have mentioned Erlang to students here, most of them haven t even heard of such a language. I had given a Seminar on Concurrent Programming in Erlang hoping to get some people interested in this language though I am not aware of anyone working on this after the seminar. I almost convinced one guy but then he found pthreads much easier :(
Anyways the
presentation is available online. Click on the full screen button and follow the arrows, the slides are bidirectional.
Also, I might propose a talk/hands-on session on this at
FOSSMeet 2013.
PS : Being the Debian fan boy that I am, I have to mention this even though it is irrelevant to the article. We have
Mini DebConf at FOSSMeet this year. Now excuse me!
LCA 2013 [1] is starting so it seems like time to finish my write-up of LCA 2012.
As usual it was a great conference, although I got sick immediately after getting there which reduced my ability to attend.
Android
A major unofficial theme of the conference was Android. Most delegates seemed to have Android phones, the Samsung
Galaxy S and
Galaxy Nexus seemed to be the most popular phones. Many delegates had two or more phones for development purposes. A large portion of the casual conversation at the conference concerned Android.
There were a couple of really interesting talks about the
Serval mesh networking project [2] which involves Android phones running in ad-hoc Wifi mode for long range communication without any official base station. Serval allows transferring messages, pictures, and voice calls. If you need to get longer range you can mount one phone in a convenient place and other phones will decide to use it as a relay there is no need to have a dedicated relay device (such as a mobile phone tower or Wifi access point). Serval is supposed to work with Wifi access points but due to Java not exposing some networking details to the higher levels of software the code that was available at the time of the conference didn t support networks other than a /24, which meant that the conference Wifi network didn t work with Serval. As an aside most people at the conference who installed Serval were using a development version that was newer than the version on the Android market. I can t remember what the extra features were though.
Serval was designed for emergency situations, it can be installed on phones (and pushed to other phones via Wifi) in the field and allow communications when the infrastructure is broken. Also it s designed with some aim of circumventing censorship which among other things means that there are no facilities for tracking use. I think it would be really handy to be able to in some way track viewing of or interest in images that are transported via the mesh (maybe by something similar in concept to Google +1). Then in a crowd sourced environment people who take photos would be encouraged in their work by audience appreciation.
One thing that interests me is the possibility of using Serval on a cruise ship. A cruise ship is an environment where mobile phone calls are unreasonably expensive, cabin phones aren t much use (who pays for a cruise and hangs out in their cabin?), and where there is usually a Wifi network installed. If a ship has a single bridged Wifi network that allows connecting to Wifi before authenticating for Internet access (which is probably the common case) then you could transport VOIP over that network without paying and without incurring any expense on the cruise company. One of the Serval developers assured me that this should be possible, of course a cruise ship with 3,000 passengers probably doesn t use a /24 for their Wifi so the current versions of Serval won t work
At the geek my dinner event (a party where everyone brought $20 of food/drink which was cooked by volunteers) an artist showed me some art work that she created on her Samsung Galaxy Note (which was the biggest phone on sale at the time), it was very impressive. She recommended
Picasso Mirror Draw,
Sketch Free,
Sketch Book Mobile Express, and
Freenote as free graphical programs for Android.
Samsung has a Noteworthy Project advertising campaign based on the artistic uses of the Galaxy Note which has some good videos of artists [3].
Chris Neugebauer and Paris Buttfield-Addison gave an informative and amusing talk about Android UI development (this link has the video) [4]. It s a pity that I missed seeing that one live but fortunately the video is of high quality.
Accommodation

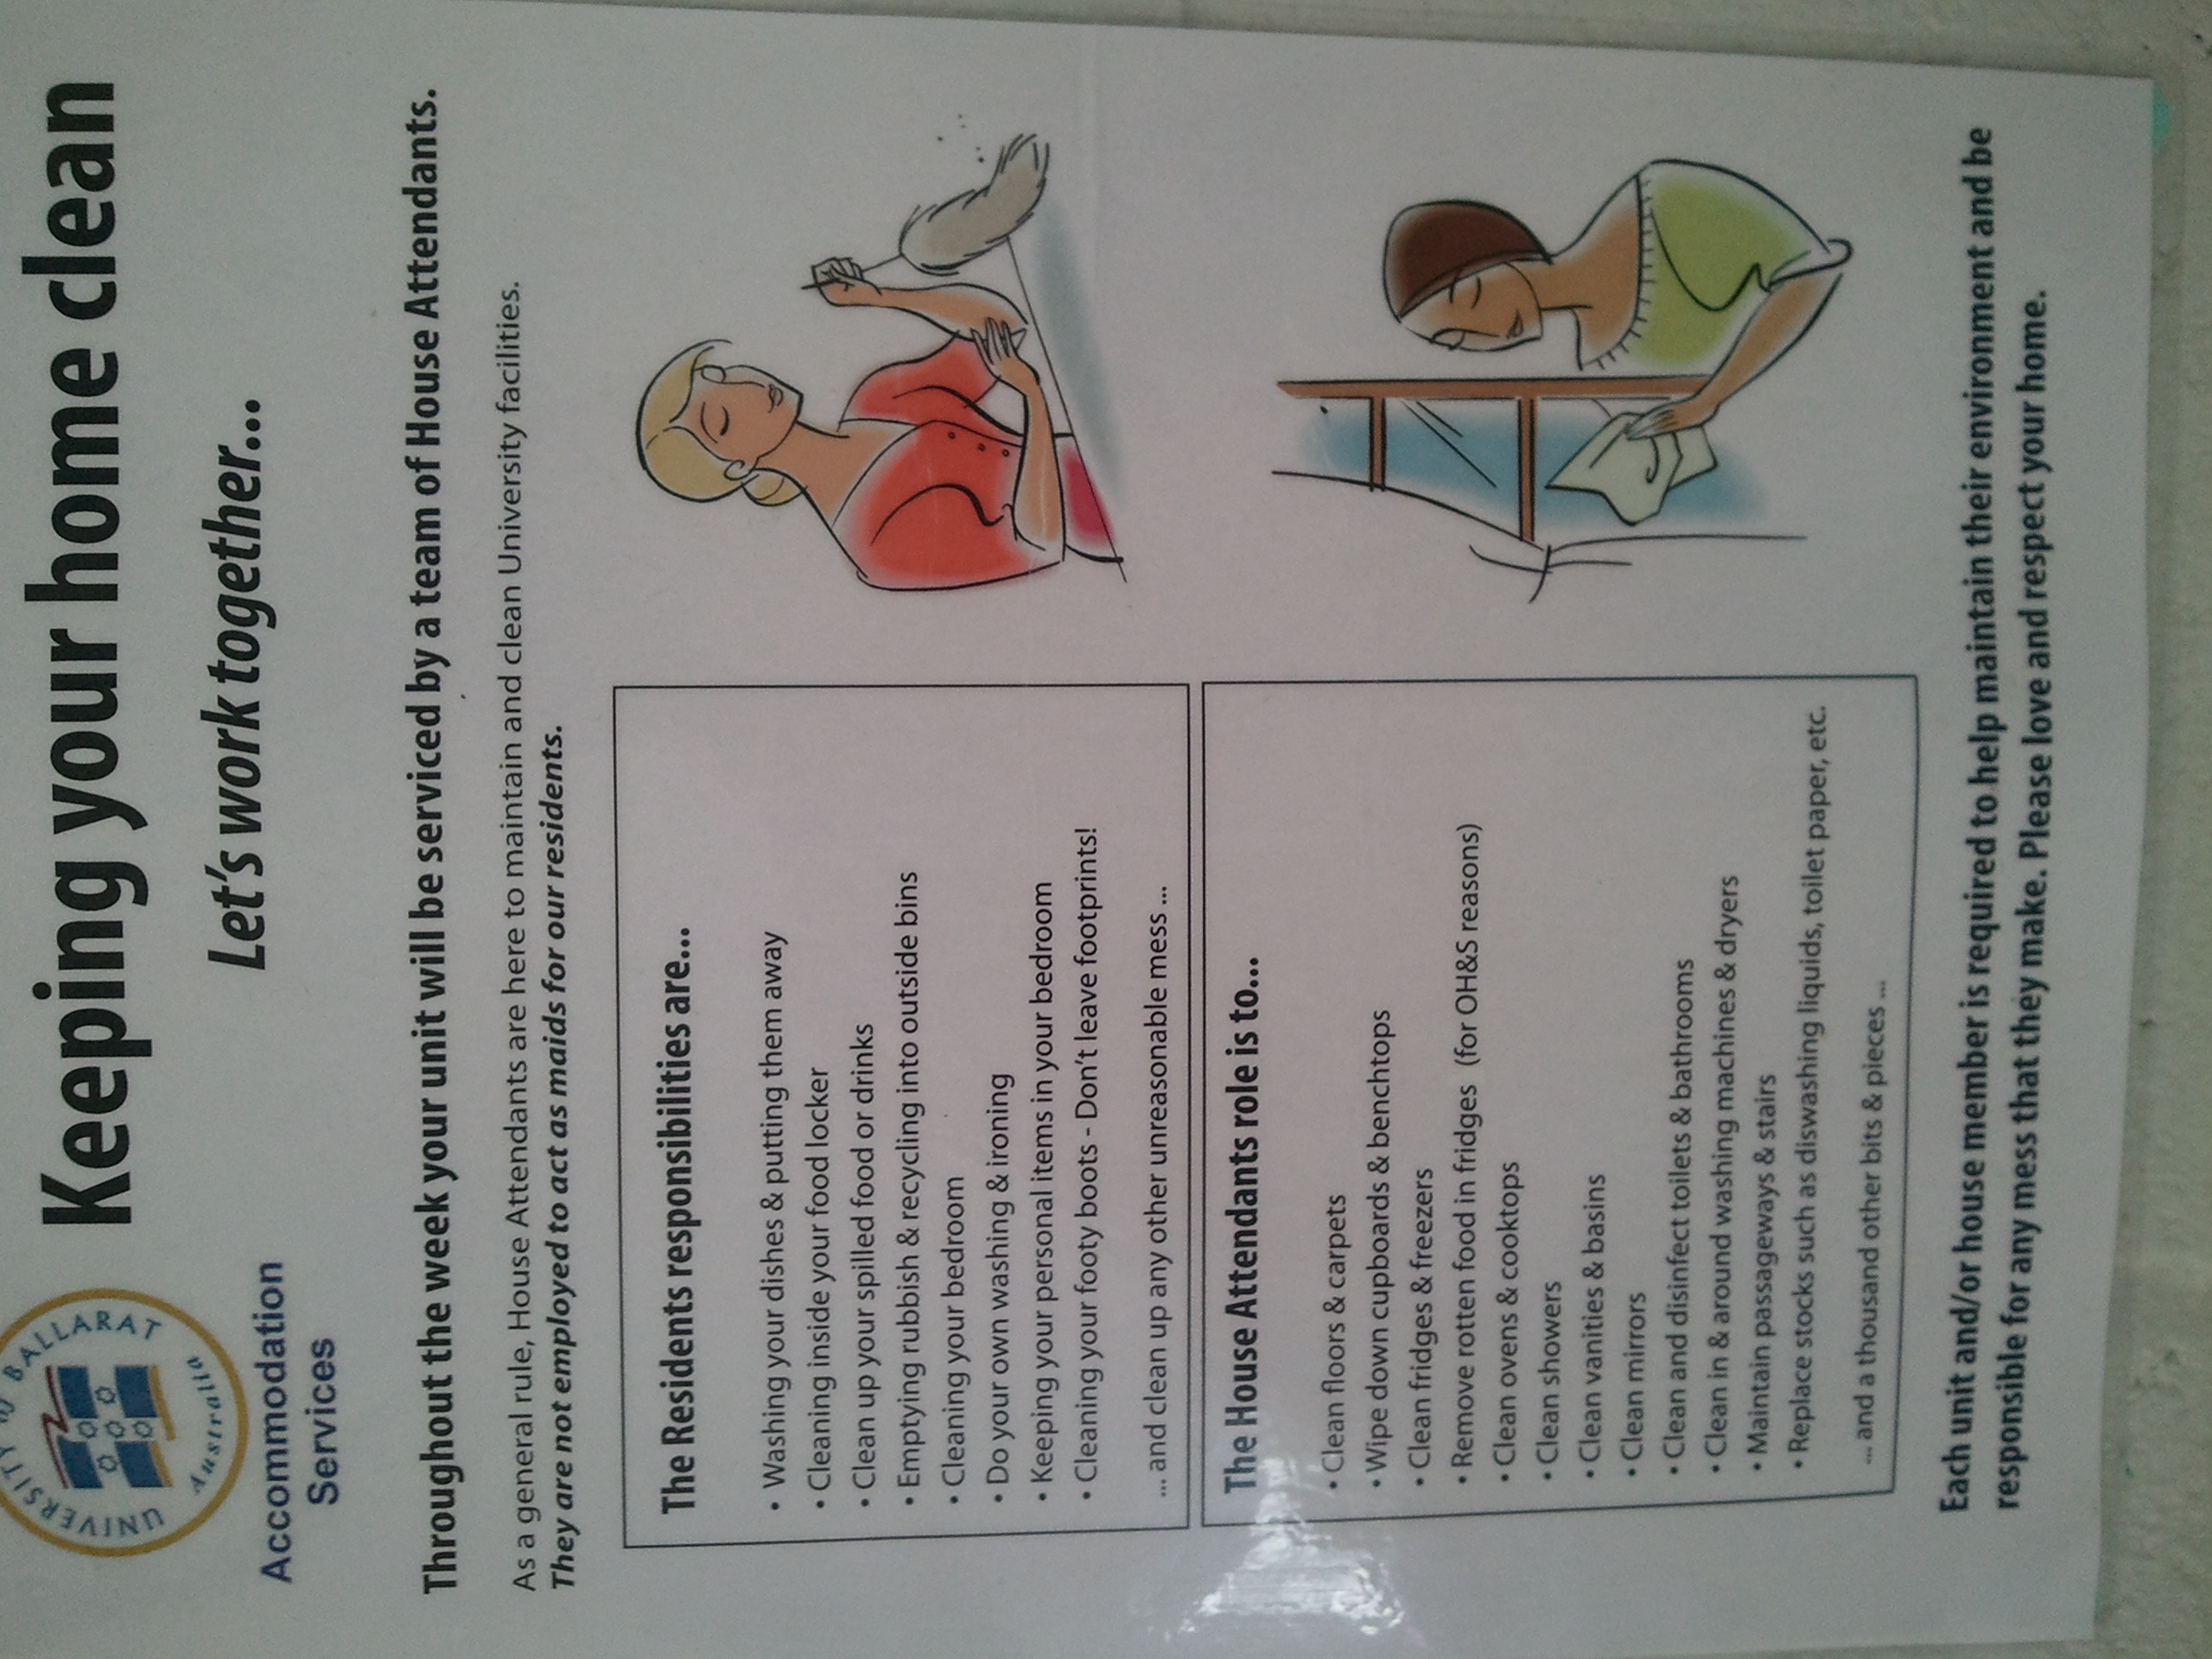
As I ve become interested in Sociology I couldn t help but notice the pictures that accompanied the rules about cleaning the dormitory (which were displayed over the kitchen sink), it seems to imply that cleaning is only women s work. I wonder whether the people who created that poster deliberately chose pictures of women or whether they just chose the first available pictures from a collection of stock photos.
Someone who was near my dorm room seemed to not realise how their alarm impacts other people. For the first two mornings I was woken repeatedly after 6AM by someone who was pressing the snooze button on their alarm. When sleeping in close proximity to other people the reasonable options involve some combination of having no loud alarm, immediately turning the alarm off and getting up (not pressing snooze to have it go off repeatedly), and setting the alarm for a time when almost everyone wants to get up (EG 1 hour before the first session).
Networking
Chris Neugebauer organised the Unprofessional Delegates Networking Session which was a great event. It was an event held at the same time as the Professional Delegates Networking Session with the difference being that you had to pay $5 for food and there was no free drink. A lot of great people attended the UPDNS so I m glad I don t pay for the PDNS. It seems that we won t have a UPDNS this year unfortunately.
Conclusion
LCA is always great fun and very educational. I recommend attending every year.
We had our tech leads retreat on Friday, including the discussion about
"why," and I thought it was excellent, although I'm still trying to
understand some parts of it.
Part of why I'm still working on that is, well, you know that
introversion thing? I had
five and a half hours of meetings on Friday, and the tail end was an
intense four and a half hour retreat, during which I was a major
participant the whole time. And tried to say some difficult and intense
things, both about the "why" conversation that I posted about and about
why the tail end of last year was particularly difficult for me.
All that went very well. I was very happy with the overall meeting.
Sometimes, I half-convince myself that I'm overstating the degree that
introversion or that interpersonal interaction affects me, or that I'm
using it as an excuse to duck out of things that aren't really what I want
to be working on. Then I do something like this, and find myself
completely dead on my feet at the end of the meeting. Not physically
tired, but utterly and completely drained. I went home and did something
completely right-brain and creative and needed that so desperately that I
stayed with it until two in the morning, slept in today until past noon,
and still have, despite a couple of minor attempts, absolutely no
capability to write code or focus on accomplishing anything. I'm fairly
sure I'll still be feeling the after-effects on Monday and Tuesday.
I'm a little annoyed at having both missed a day of releasing something to
the world (I'd managed to post something every day this year until
yesterday) and blowing off exercising yesterday evening for only the
second time this year. But I think part of coming to terms with what
introversion means is being kind to myself about this. That's something
Cain talked a lot about in her book, and it's the advice I'd give to any
other introvert, but it's something I'm not applying as well as I could.
Being an introvert doesn't mean to not do meetings. It means to pick the
ones that are important, do them with all your heart, and then be kind to
yourself afterwards just as if you'd put in extreme effort to do something
quite energetic and difficult. Because you have.
So, I'm trying not to be annoyed at myself. And I think we need to be
better about teaching people about this, because apart from Susan Cain, I
don't remember many people writing about this, or understanding it.
Occasionally there are screeds against meetings, but not a lot of
discussion about when it's worth expending the energy, and about how to be
kind to oneself and recharge after putting one's energy into the social
interactions that are important.
I did want to mention that while retreats seem to have a bad reputation in
tech circles (and I've heard of a lot of retreats that I would hate), the
ones that we do in our group are great. We spent about an hour talking
about the things I posted about on Thursday, then a couple of hours
talking about the larger organizational roadmap and searching out things
that aren't on our upcoming work roadmap that feel like large missing
pieces, and then a couple of hours identifying and enumerating our
technical debt and deciding what major pieces of technical debt we're
going to tackle in the next six months. It's a lot of concrete, specific
discussion of what we're going to spend time on and what we're going to
defend resources for by pushing back against other priorities. If I had
to sum it up in a sentence, I'd say that these retreats are all about
listing vaguely equal things that exceed our total capacity and making the
decisions about which of them we're going to do and which of them we're
not going to do so that we don't have to keep wasting time on revisiting
unresolved decisions.
The actual mission discussion turned into a discussion by each of us of
what we most value in work, stated in terms very similar to what I used in
my post, and that was wonderful. I found out things about my co-workers
that I didn't know, and which will help me a great deal in improving their
enjoyment of their work. I think we came away with a better idea of how
to support each other in creating that engagement and excitement, and I
think that's the best possible outcome. Since, like I said, I think
that's the only real mission statement a group should have.
We did, still, talk about having a mission statement anyway. Apparently
having a shared statement is really important to people who aren't me.
I'm still struggling with this, since it doesn't make sense to me and
doesn't feel useful to me. But maybe it's a sort of validation and
confirmation that we're allowed to focus on what we care about?
But the group mission statement we came away with isn't about any specific
technology and focuses on exactly the things that I care about: elegance,
robustness, durability, and solving whatever problems the university has.
As part of that discussion, we reached a surprising and really satisfying
unanimity of opinion about what values we care deeply about. It's a value
statement as opposed to a distillation of job descriptions, so if a
mission statement is valuable for other people, that's one I'm quite happy
with. Even if I don't understand why people want to have one.
I'm less satisfied with the roadmap and strategic plan for our larger
organization, but I'm starting to realize that's because I'm utterly not
the target audience and it's not going to engage or interest me. It's
more of a marketing statement that's focused externally, and my proper
role in that is to try to help ensure that it reflects the enthusiasms and
engagement of the line staff, not to try to turn it into a document that
will be inspiring for the line staff. Which ties into what I was writing
about previously: in my ideal world, these sorts of focuses flow upwards
from the people who will be doing the work, not downward from a high-level
manager deciding on an inspirational direction.
configure, Makefile.in, config.guess & config.sub
Are static, included copies of code that should always be rebuild during build. If they are not rebuild at build time, it should be documented/automated the relevant helpers that are needed to rebuild the package. If they are failing to rebuild it's RC since source code is provided that is effectively cannot be modified in the preferred form. They also should not be modified in patch form, as editing generated code is not preferred form of modification. Also it constantly hurts us when bringing up new kernels and architectures (recently kfreebsd, armhf, aarch64). dh_autoreconf is a great tool to achieve thiis s.
no native packages
Generally if software is useful in Debian Project it can be useful for other debian-like and unlike projects. In particular native packages do not offer the same patching flexibility as 3.0 (quilt), thus forcing downstream distributions to inline modify packages without DEP-3 headers. This hurts us, when trying to merge useful stuff from derivatives back into Debian, as changes are not split into individual patches.
shared maintainership
I'd like to put all my packages under "Debian Developers <debian-devel d.o="">" maintainership. There is no need for NMU, QA, TEAM upload. If you have a patch, I don't want a bug in BTS nor commits, I'd like you to simply upload it into the archive. Especially blanket changes must be welcomed across the whole archive: translations, unit tests, porting to new debhelper versions, FTBFS fixes against next versions of compilers and interpreters, multiarch & cross-building fixes, porting to latest best packaging practices.</debian-devel>
ps. comments are turned off. All further discussion is redirected to your choice of: debian-devel or my personal email.