Search Results: "spa"

3 June 2022

Raphaël Hertzog: Freexian s report about Debian Long Term Support, April 2022

A Debian LTS logo
Like each month, have a look at the work funded by Freexian s Debian LTS offering. Debian project funding Two projects are currently in the pipeline: Gradle enterprise and Tryton update. Progress is quite slow on the Gradle one, there are technical difficulties. The tryton one was stalled because the developer had not enough time but seems to progress smoothly in the last weeks. In April, we put aside 2635 EUR to fund Debian projects. We re looking forward to receive more projects from various Debian teams! Learn more about the rationale behind this initiative in this article. Debian LTS contributors In April, 11 contributors have been paid to work on Debian LTS, their reports are available: Evolution of the situation In April we released 30 DLAs and we were glad to welcome a new customer with Alter Way. The security tracker currently lists 72 packages with a known CVE and the dla-needed.txt file has 71 packages needing an update. It is worth pointing out that we are getting close to the end of the LTS period for Debian 9. After June 30th, no new security updates will be made available on security.debian.org. But Freexian and its team of paid Debian contributors will continue to maintain Debian 9 going forward for the customers of the Extended LTS offer. If you have Debian 9 servers to keep secure, it s time to subscribe! You might not have noticed, but Freexian formalized a mission statement where we explain that our purpose is to help improve Debian. For this, we want to fund work time for the Debian developers that recently joined Freexian as collaborators. The Extended LTS and the PHP LTS offers are built following a model that will help us to achieve this if we manage to have enough customers for those offers. So consider subscribing: you help your organization but you also help Debian! Thanks to our sponsors Sponsors that joined recently are in bold.

1 June 2022

Daniel Lange: Get Youtube Channel ID from username

Youtube has a really nice RSS feature that is extremely well hidden. If you postfix a Channel ID to
https://www.youtube.com/feeds/videos.xml?channel_id=<id goes here>
you get a really nice Atom 1.0 (~RSS) feed for your feedreader. Unfortunately the Channel ID is hard to find while you are navigating Youtube with usernames in the URL. E.g. https://www.youtube.com/c/TED is TED's channel, full of interesting and worth-to-watch content (and some assorted horse toppings, of course). But you have to read a lot of ugly HTML / JSON in that page to find and combine https://www.youtube.com/feeds/videos.xml?channel_id=UCAuUUnT6oDeKwE6v1NGQxug which is the related RSS feed. Jeff Keeling wrote a simple Youtube RSS Extractor that does well if you have a ../playlist?... or a .../channel/... URL but it will (currently) fail on user name channels or Youtube landing pages. So how do we get the Channel ID for a Youtube user we are interested to follow? Youtube has a great API but that is gated by API keys even for the most simple calls (that came only with v3 of the API but the previous version is depreciated since 2015)1:
dl@laptop:~$ curl 'https://www.googleapis.com/youtube/v3/channels?part=contentDetails&forUsername=DebConfVideos'

"error":
"code": 403,
"message": "The request is missing a valid API key.",
"errors": [

"message": "The request is missing a valid API key.",
"domain": "global",
"reason": "forbidden"

],
"status": "PERMISSION_DENIED"

Luckily we can throw the same (example) user name DebConfVideos at curl and grep:
dl@laptop:~$ curl -s "https://www.youtube.com/c/DebConfVideos/videos" grep -Po '"channelId":".+?"'
"channelId":"UC7SbfAPZf8SMvAxp8t51qtQ"
So https://www.youtube.com/feeds/videos.xml?channel_id=UC7SbfAPZf8SMvAxp8t51qtQ is the RSS feed for DebConfVideos. We can use individual Youtube video URLs as well. With the hack above, it'll work to find us the Chanel ID from a Youtube video URL: Working around the Youtube API restrictions to still make use of their RSS feed Now, some user pages may have multiple valid RSS feeds because they contain multiple channels. Remember the TED page from above? Well run:
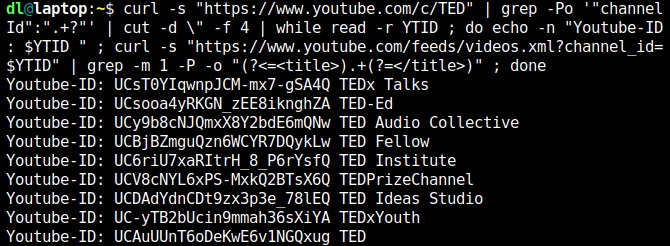
dl@laptop:~$ curl -s "https://www.youtube.com/c/TED" grep -Po '"channelId":".+?"' cut -d \" -f 4 while read -r YTID ; do echo -n "Youtube-ID: $YTID " ; curl -s "https://www.youtube.com/feeds/videos.xml?channel_id=$YTID" grep -m 1 -P -o "(?<=<title>).+(?=</title>)" ; done
This will iterate through the Channel IDs found and show you the titles. That way you can assess which one you want to add to your feedreader. screenshot of the above You probably want the last Channel ID listed above, the non-selective "TED" one. And that's the one from the example above. Update 02.06.2022: smpl wrote in and has the much better solution for the most frequent use cases:
You can also use get a feed directly with a username:
https://www.youtube.com/feeds/videos.xml?user=<username>
The one I use most is the one for playlists (if creators remember to
use them).
https://www.youtube.com/feeds/videos.xml?playlist_id=<playlist id>
For the common case you don't even need the channel ID that way. But it is also conveniently given in a <yt:channelId> tag (or the topmost <id> tag) within the Atom XML document. Thanks, smpl!

  1. Actually it is even more complicated as some channels, like our DebConfVideos example, will only get you an incomplete result, cf. this StackOverflow entry. I.e. the forUsername iterator may not even work and the "best practice" seems to be mucking around with the search call.

31 May 2022

Paul Wise: FLOSS Activities May 2022

Focus This month I didn't have any particular focus. I just worked on issues in my info bubble.

Changes

Issues

Review
  • Spam: reported 1 Debian bug reports and 41 Debian mailing list posts
  • Patches: reviewed gt patches
  • Debian packages: sponsored psi-notify
  • Debian wiki: RecentChanges for the month
  • Debian BTS usertags: changes for the month
  • Debian screenshots:
    • approved cppcheck-gui eta flpsed fluxbox p7zip-full pampi pyqso xboard
    • rejected p7zip (help output), openshot (photo of a physical library), clamav-daemon (movie cartoon character), aptitude (screenshot of random launchpad project), laditools (screenshot of tracker.d.o for src:hello), weboob-qt/chromium-browser/supercollider-vim ((NSFW) selfies), node-split (screenshot of screenshots site), libc6 (Chinese characters alongside a photo of man and bottle)

Administration
  • Debian servers: investigate etckeeper cron mail
  • Debian wiki: investigate account existence, approve accounts

Communication
  • Respond to queries from Debian users and contributors on the mailing lists and IRC

Sponsors The gensim and libpst work was sponsored. All other work was done on a volunteer basis.

30 May 2022

Gunnar Wolf: On to the next journey

Last Wednesday my father, Kurt Bernardo Wolf Bogner, took the steps towards his next journey, the last that would start in this life. I cannot put words to this so just sharing this with the world will have to suffice. Goodbye to my teacher, my friend, the person I have always looked up to. Some of his friends were able to put in words more than what I can come up with. If you can read Spanish, you can read the eulogy from the Science Academy of Morelos. His last project, enjoyable by anybody who reads Spanish, is the book with his account of his youth travels Asia, Africa and Europe, beteen 1966 and 1970. You can read it online. And I have many printed copies, in case you want one as well. We will always remember you with love.

29 May 2022

Russ Allbery: Review: Kleptopia

Review: Kleptopia, by Tom Burgis
Publisher: Harper
Copyright: 2020
Printing: September 2021
ISBN: 0-06-323613-3
Format: Kindle
Pages: 340
Kleptopia is a nonfiction chronicle of international financial corruption and money laundering told via a focus on the former Soviet republic of Kazakhstan. The primary characters are a British banker named Nigel Wilkins (at the start of the story, the head of compliance in the London office of the Swiss bank BSI), a group of businessmen from Kyrgyzstan and Uzbekistan called the Trio, and a Kazakh oligarch and later political dissident named Mukhtar Ablyazov, although the story spreads beyond them. It is partly a detailed example of what money laundering looks like in practice: where the money comes from, who has it, what they want to do with it, who they hire to move it, and what countries welcome it. But it is more broadly about the use of politics for financial plunder, and what stories we tell about the results. The title of this book feels a bit like clickbait, and I was worried it would be mostly opinion and policy discussion. It is the exact opposite. Tom Burgis is an investigations correspondent at the Financial Times, and this is a detailed piece of investigative journalism (backed by a hundred pages of notes and detailed attributions). Burgis has a clear viewpoint and expresses it when it seems relevant, but the vast majority of this book is the sort of specific account of people, dates, times, and events that one would expect from a full-length investigative magazine piece, except maintained at book length. Even aside from the subject matter, I love that writing like this exists. It's often best in magazines, newspapers, and on-line articles for timeliness, since book publishing is slow, but some subjects require the length of a book. Burgis is the sort of reporter who travels the world to meet with sources in person, and who, before publication, presents his conclusions to everyone mentioned for their rebuttals (many of which are summarized or quoted in detail in the notes so that the reader can draw their own credibility conclusions). Whether or not one agrees with his specific conclusions or emphasis, we need more of this sort of journalism in the world. I knew essentially nothing about Kazakhstan or its politics before reading this book. I also had not appreciated the degree to which exploitation of natural resources is the original source of the money for international money laundering. In both Kazakhstan and Africa (a secondary setting for this book), people get rich largely because of things dug or pumped out of the ground. That money, predictably, does not go to the people doing the hard work of digging and pumping, who work in appalling conditions and are put down with violence if they try to force change. (In one chapter, Burgis tells the harrowing and nightmarish story of Roza Tuletayeva, a striker at the oil field in Zhanaozen.) It's gathered up by the already rich and politically connected, who gained control of former state facilities during the post-Soviet collapse and then maintained their power with violence and corruption. And once they have money, they try to convert it into holdings in European banks, London real estate, and western corporations. The primary thing I will remember from this book is the degree to which oligarchs rely on being able to move between two systems. They make their money in unstable or authoritarian countries with high degrees of political corruption and violence, and are adept at navigating that world (although sometimes it turns on them; more on that in a moment). But they don't want to leave their money in that world. Someone else could betray them, undermine them, or gain the ear of the local dictator. They rely instead on western countries with strong property rights, stable financial institutions, and vast legal systems devoted to protecting the wealth of people who are already rich. In essence, they play both rule sets against each other: make money through techniques that would be illegal in London, and then move their money to London so that the British government and legal system will protect it against others who are trying to do the same. What they get out of this is obvious. What London gets out of it is another theme of this book: it's a way for a lot of people to share the wealth without doing any of the crimes. Money laundering is a very lossy activity. Lots of money falls out of the cart along the way, where it is happily scooped up by bankers, lawyers, accountants, public relations consultants, and the rest of the vast machinery of theoretically legitimate business. Everyone wins, except the people the money is being stolen from in the first place. (And the planet; Burgis doesn't talk much about the environment, but I found the image of one-way extraction of irreplaceable natural resources haunting and disturbing.) Donald Trump does make an appearance here, although not as significant of one as I was expecting given the prominent appearance of Trump crony Felix Sater. Trump is part of the machinery that allows oligarch money to become legally-protected business investment, but it's also clear from Burgis's telling that he is (at least among the money flows Burgis is focused on) a second-tier player with delusions of grandeur. He's more notable for his political acumen and ability to craft media stories than his money-laundering skills. The story-telling is a third theme of this book. The electorate of the societies into which oligarchs try to move their money aren't fond of crime, mob activity, political corruption, or authoritarian exploitation of workers. If public opinion turns sufficiently strongly against specific oligarchs, the normally friendly mechanisms of law and business regulation may have to take action. The primary defense of laundered money is hiding its origins sufficiently that it's too hard to investigate or explain to a jury, but there are limits to how completely the money can hide given that oligarchs still want to spend it. They need to tell a story about how they are modernizing businessmen, aghast at the lingering poor conditions of their home countries but working earnestly to slowly improve them. And they need to defend those stories against people who might try to draw a clearer link between them and criminal activity. The competing stories between dissident oligarch Mukhtar Ablyazov and the Kazakh government led by Nursultan Nazarbayev are a centerpiece of this book. Ablyazov is in some sense a hero of the story, someone who attempted to expose the corruption of Nazerbayev's government and was jailed by Nazerbayev for corruption in retaliation. But Burgis makes clear the tricky fact that Ablyazov likely is guilty of at least some (and possibly a lot) of the money laundering of which he was accused. It's a great illustration of the perils of simple good or bad labels when trying to understand this world from the outside. All of these men are playing similar games, and all of them are trying to tell stories where they are heroes and their opponents are corrupt thieves. And yet, there is not a moral equivalency. Ablyazov is not a good person, but what Nazerbayev attempted to do to his family is appalling, far worse than anything Ablyazov did, and the stories about Ablyazov that have prevailed to date in British courts are not an attempt to reach the truth. The major complaint that I have about Kleptopia is that this is a highly complex story with a large number of characters, but Burgis doesn't tell it in chronological order. He jumps forward and backward in time to introduce new angles of the story, and I'm not sure that was the right structural choice. Maybe a more linear story would have been even more confusing, but I got lost in the chronology at several points. Be prepared to put in some work as a reader in keeping the timeline straight. I also have to warn that this is not in any way a hopeful book. Burgis introduces Nigel Wilkins and his quixotic quest to expose the money laundering activities of European banks early in the book. In a novel that would set up a happy ending in which Wilkins brings down the edifice, or at least substantial portions of it. We do not live in a novel, sadly. Kleptopia is not purely depressing, but by and large the bad guys win. This is not a history of corruption that we've exposed and overcome. It's a chronicle of a problem that is getting worse, and that the US and British governments are failing to address. Burgis's publishers successfully defended a libel suit in British courts brought by the Eurasian Natural Resources Corporation, the primary corporate entity of the Trio who are the primary villains of this book. I obviously haven't done my own independent research, but after reading this book, including the thorough notes, this looks to me like the type of libel suit that should serve as an advertisement for its target. I can't say I enjoyed reading this, particularly at the end when the arc becomes clear. Understanding how little governments and institutions care about stopping money laundering is not a pleasant experience. But it's an important book, well and vividly told (except for the chronology), and grounded in solid investigative journalism. Recommended; I'm glad I read it. Rating: 7 out of 10

28 May 2022

kpcyrd: auth-tarball-from-git: Verifying tarballs with signed git tags

I noticed there s a common anti-pattern in some PKGBUILDs, the short scripts that are used to build Arch Linux packages. Specifically we re looking at the part that references the source code used when building a package:
source=("git+https://github.com/alacritty/alacritty.git#tag=v$ pkgver ?signed")
validpgpkeys=('4DAA67A9EA8B91FCC15B699C85CDAE3C164BA7B4'
              'A56EF308A9F1256C25ACA3807EA8F8B94622A6A9')
sha256sums=('SKIP')
This does: In contrast consider this PKGBUILD:
source=($pkgname-$pkgver.tar.gz::https://github.com/alacritty/alacritty/archive/refs/tags/v$pkgver.tar.gz)
sha256sums=('e48d4b10762c2707bb17fd8f89bd98f0dcccc450d223cade706fdd9cfaefb308')
Personally - if I had to decide between these two - I d prefer the later because I can always try to authenticate the pinned tarball later on, but it s impossible to know for sure which source code has been used if all I know is something that had a valid signature on it . This set could be infinitely large for all we know! But is there a way to get both? Consider this PKGBUILD:
makedepends=('auth-tarball-from-git')
source=($pkgname-$pkgver.tar.gz::https://github.com/alacritty/alacritty/archive/refs/tags/v$pkgver.tar.gz
        chrisduerr.pgp
        kchibisov.pgp)
sha256sums=('e48d4b10762c2707bb17fd8f89bd98f0dcccc450d223cade706fdd9cfaefb308'
            '19573dc0ba7a2f003377dc49986867f749235ecb45fe15eb923a74b2ab421d74'
            '5b866e6cb791c58cba2e7fc60f647588699b08abc2ad6b18ba82470f0fd3db3b')
prepare()  
  cd "$pkgname-$pkgver"
  auth-tarball-from-git --keyring ../chrisduerr.pgp --keyring ../kchibisov.pgp \
    --tag v$pkgver --prefix $pkgname-$pkgver \
    https://github.com/alacritty/alacritty.git ../$pkgname-$pkgver.tar.gz
 
In this case sha256sums= is the primary line of defense against tampering with build inputs and the git tag is only used to document authorship. For more infos on how this works you can have a look at the auth-tarball-from-git repo, there s also a section about attacks on signed git tags that you should probably know about.

Thanks This work is currently crowd-funded on github sponsors. I d like to thank @SantiagoTorres, @repi and @rgacogne for their support in particular.

26 May 2022

Sergio Talens-Oliag: New Blog Config

As promised, on this post I m going to explain how I ve configured this blog using hugo, asciidoctor and the papermod theme, how I publish it using nginx, how I ve integrated the remark42 comment system and how I ve automated its publication using gitea and json2file-go. It is a long post, but I hope that at least parts of it can be interesting for some, feel free to ignore it if that is not your case

Hugo Configuration

Theme settingsThe site is using the PaperMod theme and as I m using asciidoctor to publish my content I ve adjusted the settings to improve how things are shown with it. The current config.yml file is the one shown below (probably some of the settings are not required nor being used right now, but I m including the current file, so this post will have always the latest version of it):
config.yml
baseURL: https://blogops.mixinet.net/
title: Mixinet BlogOps
paginate: 5
theme: PaperMod
destination: public/
enableInlineShortcodes: true
enableRobotsTXT: true
buildDrafts: false
buildFuture: false
buildExpired: false
enableEmoji: true
pygmentsUseClasses: true
minify:
  disableXML: true
  minifyOutput: true
languages:
  en:
    languageName: "English"
    description: "Mixinet BlogOps - https://blogops.mixinet.net/"
    author: "Sergio Talens-Oliag"
    weight: 1
    title: Mixinet BlogOps
    homeInfoParams:
      Title: "Sergio Talens-Oliag Technical Blog"
      Content: >
        ![Mixinet BlogOps](/images/mixinet-blogops.png)
    taxonomies:
      category: categories
      tag: tags
      series: series
    menu:
      main:
        - name: Archive
          url: archives
          weight: 5
        - name: Categories
          url: categories/
          weight: 10
        - name: Tags
          url: tags/
          weight: 10
        - name: Search
          url: search/
          weight: 15
outputs:
  home:
    - HTML
    - RSS
    - JSON
params:
  env: production
  defaultTheme: light
  disableThemeToggle: false
  ShowShareButtons: true
  ShowReadingTime: true
  disableSpecial1stPost: true
  disableHLJS: true
  displayFullLangName: true
  ShowPostNavLinks: true
  ShowBreadCrumbs: true
  ShowCodeCopyButtons: true
  ShowRssButtonInSectionTermList: true
  ShowFullTextinRSS: true
  ShowToc: true
  TocOpen: false
  comments: true
  remark42SiteID: "blogops"
  remark42Url: "/remark42"
  profileMode:
    enabled: false
    title: Sergio Talens-Oliag Technical Blog
    imageUrl: "/images/mixinet-blogops.png"
    imageTitle: Mixinet BlogOps
    buttons:
      - name: Archives
        url: archives
      - name: Categories
        url: categories
      - name: Tags
        url: tags
  socialIcons:
    - name: CV
      url: "https://www.uv.es/~sto/cv/"
    - name: Debian
      url: "https://people.debian.org/~sto/"
    - name: GitHub
      url: "https://github.com/sto/"
    - name: GitLab
      url: "https://gitlab.com/stalens/"
    - name: Linkedin
      url: "https://www.linkedin.com/in/sergio-talens-oliag/"
    - name: RSS
      url: "index.xml"
  assets:
    disableHLJS: true
    favicon: "/favicon.ico"
    favicon16x16:  "/favicon-16x16.png"
    favicon32x32:  "/favicon-32x32.png"
    apple_touch_icon:  "/apple-touch-icon.png"
    safari_pinned_tab:  "/safari-pinned-tab.svg"
  fuseOpts:
    isCaseSensitive: false
    shouldSort: true
    location: 0
    distance: 1000
    threshold: 0.4
    minMatchCharLength: 0
    keys: ["title", "permalink", "summary", "content"]
markup:
  asciidocExt:
    attributes:  
    backend: html5s
    extensions: ['asciidoctor-html5s','asciidoctor-diagram']
    failureLevel: fatal
    noHeaderOrFooter: true
    preserveTOC: false
    safeMode: unsafe
    sectionNumbers: false
    trace: false
    verbose: false
    workingFolderCurrent: true
privacy:
  vimeo:
    disabled: false
    simple: true
  twitter:
    disabled: false
    enableDNT: true
    simple: true
  instagram:
    disabled: false
    simple: true
  youtube:
    disabled: false
    privacyEnhanced: true
services:
  instagram:
    disableInlineCSS: true
  twitter:
    disableInlineCSS: true
security:
  exec:
    allow:
      - '^asciidoctor$'
      - '^dart-sass-embedded$'
      - '^go$'
      - '^npx$'
      - '^postcss$'
Some notes about the settings:
  • disableHLJS and assets.disableHLJS are set to true; we plan to use rouge on adoc and the inclusion of the hljs assets adds styles that collide with the ones used by rouge.
  • ShowToc is set to true and the TocOpen setting is set to false to make the ToC appear collapsed initially. My plan was to use the asciidoctor ToC, but after trying I believe that the theme one looks nice and I don t need to adjust styles, although it has some issues with the html5s processor (the admonition titles use <h6> and they are shown on the ToC, which is weird), to fix it I ve copied the layouts/partial/toc.html to my site repository and replaced the range of headings to end at 5 instead of 6 (in fact 5 still seems a lot, but as I don t think I ll use that heading level on the posts it doesn t really matter).
  • params.profileMode values are adjusted, but for now I ve left it disabled setting params.profileMode.enabled to false and I ve set the homeInfoParams to show more or less the same content with the latest posts under it (I ve added some styles to my custom.css style sheet to center the text and image of the first post to match the look and feel of the profile).
  • On the asciidocExt section I ve adjusted the backend to use html5s, I ve added the asciidoctor-html5s and asciidoctor-diagram extensions to asciidoctor and adjusted the workingFolderCurrent to true to make asciidoctor-diagram work right (haven t tested it yet).

Theme customisationsTo write in asciidoctor using the html5s processor I ve added some files to the assets/css/extended directory:
  1. As said before, I ve added the file assets/css/extended/custom.css to make the homeInfoParams look like the profile page and I ve also changed a little bit some theme styles to make things look better with the html5s output:
    custom.css
    /* Fix first entry alignment to make it look like the profile */
    .first-entry   text-align: center;  
    .first-entry img   display: inline;  
    /**
     * Remove margin for .post-content code and reduce padding to make it look
     * better with the asciidoctor html5s output.
     **/
    .post-content code   margin: auto 0; padding: 4px;  
  2. I ve also added the file assets/css/extended/adoc.css with some styles taken from the asciidoctor-default.css, see this blog post about the original file; mine is the same after formatting it with css-beautify and editing it to use variables for the colors to support light and dark themes:
    adoc.css
    /* AsciiDoctor*/
    table  
        border-collapse: collapse;
        border-spacing: 0
     
    .admonitionblock>table  
        border-collapse: separate;
        border: 0;
        background: none;
        width: 100%
     
    .admonitionblock>table td.icon  
        text-align: center;
        width: 80px
     
    .admonitionblock>table td.icon img  
        max-width: none
     
    .admonitionblock>table td.icon .title  
        font-weight: bold;
        font-family: "Open Sans", "DejaVu Sans", sans-serif;
        text-transform: uppercase
     
    .admonitionblock>table td.content  
        padding-left: 1.125em;
        padding-right: 1.25em;
        border-left: 1px solid #ddddd8;
        color: var(--primary)
     
    .admonitionblock>table td.content>:last-child>:last-child  
        margin-bottom: 0
     
    .admonitionblock td.icon [class^="fa icon-"]  
        font-size: 2.5em;
        text-shadow: 1px 1px 2px var(--secondary);
        cursor: default
     
    .admonitionblock td.icon .icon-note::before  
        content: "\f05a";
        color: var(--icon-note-color)
     
    .admonitionblock td.icon .icon-tip::before  
        content: "\f0eb";
        color: var(--icon-tip-color)
     
    .admonitionblock td.icon .icon-warning::before  
        content: "\f071";
        color: var(--icon-warning-color)
     
    .admonitionblock td.icon .icon-caution::before  
        content: "\f06d";
        color: var(--icon-caution-color)
     
    .admonitionblock td.icon .icon-important::before  
        content: "\f06a";
        color: var(--icon-important-color)
     
    .conum[data-value]  
        display: inline-block;
        color: #fff !important;
        background-color: rgba(100, 100, 0, .8);
        -webkit-border-radius: 100px;
        border-radius: 100px;
        text-align: center;
        font-size: .75em;
        width: 1.67em;
        height: 1.67em;
        line-height: 1.67em;
        font-family: "Open Sans", "DejaVu Sans", sans-serif;
        font-style: normal;
        font-weight: bold
     
    .conum[data-value] *  
        color: #fff !important
     
    .conum[data-value]+b  
        display: none
     
    .conum[data-value]::after  
        content: attr(data-value)
     
    pre .conum[data-value]  
        position: relative;
        top: -.125em
     
    b.conum *  
        color: inherit !important
     
    .conum:not([data-value]):empty  
        display: none
     
  3. The previous file uses variables from a partial copy of the theme-vars.css file that changes the highlighted code background color and adds the color definitions used by the admonitions:
    theme-vars.css
    :root  
        /* Solarized base2 */
        /* --hljs-bg: rgb(238, 232, 213); */
        /* Solarized base3 */
        /* --hljs-bg: rgb(253, 246, 227); */
        /* Solarized base02 */
        --hljs-bg: rgb(7, 54, 66);
        /* Solarized base03 */
        /* --hljs-bg: rgb(0, 43, 54); */
        /* Default asciidoctor theme colors */
        --icon-note-color: #19407c;
        --icon-tip-color: var(--primary);
        --icon-warning-color: #bf6900;
        --icon-caution-color: #bf3400;
        --icon-important-color: #bf0000
     
    .dark  
        --hljs-bg: rgb(7, 54, 66);
        /* Asciidoctor theme colors with tint for dark background */
        --icon-note-color: #3e7bd7;
        --icon-tip-color: var(--primary);
        --icon-warning-color: #ff8d03;
        --icon-caution-color: #ff7847;
        --icon-important-color: #ff3030
     
  4. The previous styles use font-awesome, so I ve downloaded its resources for version 4.7.0 (the one used by asciidoctor) storing the font-awesome.css into on the assets/css/extended dir (that way it is merged with the rest of .css files) and copying the fonts to the static/assets/fonts/ dir (will be served directly):
    FA_BASE_URL="https://cdnjs.cloudflare.com/ajax/libs/font-awesome/4.7.0"
    curl "$FA_BASE_URL/css/font-awesome.css" \
      > assets/css/extended/font-awesome.css
    for f in FontAwesome.otf fontawesome-webfont.eot \
      fontawesome-webfont.svg fontawesome-webfont.ttf \
      fontawesome-webfont.woff fontawesome-webfont.woff2; do
        curl "$FA_BASE_URL/fonts/$f" > "static/assets/fonts/$f"
    done
  5. As already said the default highlighter is disabled (it provided a css compatible with rouge) so we need a css to do the highlight styling; as rouge provides a way to export them, I ve created the assets/css/extended/rouge.css file with the thankful_eyes theme:
    rougify style thankful_eyes > assets/css/extended/rouge.css
  6. To support the use of the html5s backend with admonitions I ve added a variation of the example found on this blog post to assets/js/adoc-admonitions.js:
    adoc-admonitions.js
    // replace the default admonitions block with a table that uses a format
    // similar to the standard asciidoctor ... as we are using fa-icons here there
    // is no need to add the icons: font entry on the document.
    window.addEventListener('load', function ()  
      const admonitions = document.getElementsByClassName('admonition-block')
      for (let i = admonitions.length - 1; i >= 0; i--)  
        const elm = admonitions[i]
        const type = elm.classList[1]
        const title = elm.getElementsByClassName('block-title')[0];
    	const label = title.getElementsByClassName('title-label')[0]
    		.innerHTML.slice(0, -1);
        elm.removeChild(elm.getElementsByClassName('block-title')[0]);
        const text = elm.innerHTML
        const parent = elm.parentNode
        const tempDiv = document.createElement('div')
        tempDiv.innerHTML =  <div class="admonitionblock $ type ">
        <table>
          <tbody>
            <tr>
              <td class="icon">
                <i class="fa icon-$ type " title="$ label "></i>
              </td>
              <td class="content">
                $ text 
              </td>
            </tr>
          </tbody>
        </table>
      </div> 
        const input = tempDiv.childNodes[0]
        parent.replaceChild(input, elm)
       
     )
    and enabled its minified use on the layouts/partials/extend_footer.html file adding the following lines to it:
     - $admonitions := slice (resources.Get "js/adoc-admonitions.js")
        resources.Concat "assets/js/adoc-admonitions.js"   minify   fingerprint  
    <script defer crossorigin="anonymous" src="  $admonitions.RelPermalink  "
      integrity="  $admonitions.Data.Integrity  "></script>

Remark42 configurationTo integrate Remark42 with the PaperMod theme I ve created the file layouts/partials/comments.html with the following content based on the remark42 documentation, including extra code to sync the dark/light setting with the one set on the site:
comments.html
<div id="remark42"></div>
<script>
  var remark_config =  
    host:   .Site.Params.remark42Url  ,
    site_id:   .Site.Params.remark42SiteID  ,
    url:   .Permalink  ,
    locale:   .Site.Language.Lang  
   ;
  (function(c)  
    /* Adjust the theme using the local-storage pref-theme if set */
    if (localStorage.getItem("pref-theme") === "dark")  
      remark_config.theme = "dark";
      else if (localStorage.getItem("pref-theme") === "light")  
      remark_config.theme = "light";
     
    /* Add remark42 widget */
    for(var i = 0; i < c.length; i++) 
      var d = document, s = d.createElement('script');
      s.src = remark_config.host + '/web/' + c[i] +'.js';
      s.defer = true;
      (d.head   d.body).appendChild(s);
     
   )(remark_config.components   ['embed']);
</script>
In development I use it with anonymous comments enabled, but to avoid SPAM the production site uses social logins (for now I ve only enabled Github & Google, if someone requests additional services I ll check them, but those were the easy ones for me initially). To support theme switching with remark42 I ve also added the following inside the layouts/partials/extend_footer.html file:
 - if (not site.Params.disableThemeToggle)  
<script>
/* Function to change theme when the toggle button is pressed */
document.getElementById("theme-toggle").addEventListener("click", () =>  
  if (typeof window.REMARK42 != "undefined")  
    if (document.body.className.includes('dark'))  
      window.REMARK42.changeTheme('light');
      else  
      window.REMARK42.changeTheme('dark');
     
   
 );
</script>
 - end  
With this code if the theme-toggle button is pressed we change the remark42 theme before the PaperMod one (that s needed here only, on page loads the remark42 theme is synced with the main one using the code from the layouts/partials/comments.html shown earlier).

Development setupTo preview the site on my laptop I m using docker-compose with the following configuration:
docker-compose.yaml
version: "2"
services:
  hugo:
    build:
      context: ./docker/hugo-adoc
      dockerfile: ./Dockerfile
    image: sto/hugo-adoc
    container_name: hugo-adoc-blogops
    restart: always
    volumes:
      - .:/documents
    command: server --bind 0.0.0.0 -D -F
    user: $ APP_UID :$ APP_GID 
  nginx:
    image: nginx:latest
    container_name: nginx-blogops
    restart: always
    volumes:
      - ./nginx/default.conf:/etc/nginx/conf.d/default.conf
    ports:
      -  1313:1313
  remark42:
    build:
      context: ./docker/remark42
      dockerfile: ./Dockerfile
    image: sto/remark42
    container_name: remark42-blogops
    restart: always
    env_file:
      - ./.env
      - ./remark42/env.dev
    volumes:
      - ./remark42/var.dev:/srv/var
To run it properly we have to create the .env file with the current user ID and GID on the variables APP_UID and APP_GID (if we don t do it the files can end up being owned by a user that is not the same as the one running the services):
$ echo "APP_UID=$(id -u)\nAPP_GID=$(id -g)" > .env
The Dockerfile used to generate the sto/hugo-adoc is:
Dockerfile
FROM asciidoctor/docker-asciidoctor:latest
RUN gem install --no-document asciidoctor-html5s &&\
 apk update && apk add --no-cache curl libc6-compat &&\
 repo_path="gohugoio/hugo" &&\
 api_url="https://api.github.com/repos/$repo_path/releases/latest" &&\
 download_url="$(\
  curl -sL "$api_url"  \
  sed -n "s/^.*download_url\": \"\\(.*.extended.*Linux-64bit.tar.gz\)\"/\1/p"\
 )" &&\
 curl -sL "$download_url" -o /tmp/hugo.tgz &&\
 tar xf /tmp/hugo.tgz hugo &&\
 install hugo /usr/bin/ &&\
 rm -f hugo /tmp/hugo.tgz &&\
 /usr/bin/hugo version &&\
 apk del curl && rm -rf /var/cache/apk/*
# Expose port for live server
EXPOSE 1313
ENTRYPOINT ["/usr/bin/hugo"]
CMD [""]
If you review it you will see that I m using the docker-asciidoctor image as the base; the idea is that this image has all I need to work with asciidoctor and to use hugo I only need to download the binary from their latest release at github (as we are using an image based on alpine we also need to install the libc6-compat package, but once that is done things are working fine for me so far). The image does not launch the server by default because I don t want it to; in fact I use the same docker-compose.yml file to publish the site in production simply calling the container without the arguments passed on the docker-compose.yml file (see later). When running the containers with docker-compose up (or docker compose up if you have the docker-compose-plugin package installed) we also launch a nginx container and the remark42 service so we can test everything together. The Dockerfile for the remark42 image is the original one with an updated version of the init.sh script:
Dockerfile
FROM umputun/remark42:latest
COPY init.sh /init.sh
The updated init.sh is similar to the original, but allows us to use an APP_GID variable and updates the /etc/group file of the container so the files get the right user and group (with the original script the group is always 1001):
init.sh
#!/sbin/dinit /bin/sh
uid="$(id -u)"
if [ "$ uid " -eq "0" ]; then
  echo "init container"
  # set container's time zone
  cp "/usr/share/zoneinfo/$ TIME_ZONE " /etc/localtime
  echo "$ TIME_ZONE " >/etc/timezone
  echo "set timezone $ TIME_ZONE  ($(date))"
  # set UID & GID for the app
  if [ "$ APP_UID " ]   [ "$ APP_GID " ]; then
    [ "$ APP_UID " ]   APP_UID="1001"
    [ "$ APP_GID " ]   APP_GID="$ APP_UID "
    echo "set custom APP_UID=$ APP_UID  & APP_GID=$ APP_GID "
    sed -i "s/^app:x:1001:1001:/app:x:$ APP_UID :$ APP_GID :/" /etc/passwd
    sed -i "s/^app:x:1001:/app:x:$ APP_GID :/" /etc/group
  else
    echo "custom APP_UID and/or APP_GID not defined, using 1001:1001"
  fi
  chown -R app:app /srv /home/app
fi
echo "prepare environment"
# replace  % REMARK_URL %  by content of REMARK_URL variable
find /srv -regex '.*\.\(html\ js\ mjs\)$' -print \
  -exec sed -i "s % REMARK_URL % $ REMARK_URL  g"   \;
if [ -n "$ SITE_ID " ]; then
  #replace "site_id: 'remark'" by SITE_ID
  sed -i "s 'remark' '$ SITE_ID ' g" /srv/web/*.html
fi
echo "execute \"$*\""
if [ "$ uid " -eq "0" ]; then
  exec su-exec app "$@"
else
  exec "$@"
fi
The environment file used with remark42 for development is quite minimal:
env.dev
TIME_ZONE=Europe/Madrid
REMARK_URL=http://localhost:1313/remark42
SITE=blogops
SECRET=123456
ADMIN_SHARED_ID=sto
AUTH_ANON=true
EMOJI=true
And the nginx/default.conf file used to publish the service locally is simple too:
default.conf
server   
 listen 1313;
 server_name localhost;
 location /  
    proxy_pass http://hugo:1313;
    proxy_set_header Host $http_host;
    proxy_set_header X-Real-IP $remote_addr;
    proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
    proxy_set_header X-Forwarded-Proto $scheme;
    proxy_set_header Upgrade $http_upgrade;
    proxy_set_header Connection "upgrade";
  
 location /remark42/  
    rewrite /remark42/(.*) /$1 break;
    proxy_pass http://remark42:8080/;
    proxy_set_header Host $http_host;
    proxy_set_header X-Real-IP $remote_addr;
    proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
    proxy_set_header X-Forwarded-Proto $scheme;


Production setupThe VM where I m publishing the blog runs Debian GNU/Linux and uses binaries from local packages and applications packaged inside containers. To run the containers I m using docker-ce (I could have used podman instead, but I already had it installed on the machine, so I stayed with it). The binaries used on this project are included on the following packages from the main Debian repository:
  • git to clone & pull the repository,
  • jq to parse json files from shell scripts,
  • json2file-go to save the webhook messages to files,
  • inotify-tools to detect when new files are stored by json2file-go and launch scripts to process them,
  • nginx to publish the site using HTTPS and work as proxy for json2file-go and remark42 (I run it using a container),
  • task-spool to queue the scripts that update the deployment.
And I m using docker and docker compose from the debian packages on the docker repository:
  • docker-ce to run the containers,
  • docker-compose-plugin to run docker compose (it is a plugin, so no - in the name).

Repository checkoutTo manage the git repository I ve created a deploy key, added it to gitea and cloned the project on the /srv/blogops PATH (that route is owned by a regular user that has permissions to run docker, as I said before).

Compiling the site with hugoTo compile the site we are using the docker-compose.yml file seen before, to be able to run it first we build the container images and once we have them we launch hugo using docker compose run:
$ cd /srv/blogops
$ git pull
$ docker compose build
$ if [ -d "./public" ]; then rm -rf ./public; fi
$ docker compose run hugo --
The compilation leaves the static HTML on /srv/blogops/public (we remove the directory first because hugo does not clean the destination folder as jekyll does). The deploy script re-generates the site as described and moves the public directory to its final place for publishing.

Running remark42 with dockerOn the /srv/blogops/remark42 folder I have the following docker-compose.yml:
docker-compose.yml
version: "2"
services:
  remark42:
    build:
      context: ../docker/remark42
      dockerfile: ./Dockerfile
    image: sto/remark42
    env_file:
      - ../.env
      - ./env.prod
    container_name: remark42
    restart: always
    volumes:
      - ./var.prod:/srv/var
    ports:
      - 127.0.0.1:8042:8080
The ../.env file is loaded to get the APP_UID and APP_GID variables that are used by my version of the init.sh script to adjust file permissions and the env.prod file contains the rest of the settings for remark42, including the social network tokens (see the remark42 documentation for the available parameters, I don t include my configuration here because some of them are secrets).

Nginx configurationThe nginx configuration for the blogops.mixinet.net site is as simple as:
server  
  listen 443 ssl http2;
  server_name blogops.mixinet.net;
  ssl_certificate /etc/letsencrypt/live/blogops.mixinet.net/fullchain.pem;
  ssl_certificate_key /etc/letsencrypt/live/blogops.mixinet.net/privkey.pem;
  include /etc/letsencrypt/options-ssl-nginx.conf;
  ssl_dhparam /etc/letsencrypt/ssl-dhparams.pem;
  access_log /var/log/nginx/blogops.mixinet.net-443.access.log;
  error_log  /var/log/nginx/blogops.mixinet.net-443.error.log;
  root /srv/blogops/nginx/public_html;
  location /  
    try_files $uri $uri/ =404;
   
  include /srv/blogops/nginx/remark42.conf;
 
server  
  listen 80 ;
  listen [::]:80 ;
  server_name blogops.mixinet.net;
  access_log /var/log/nginx/blogops.mixinet.net-80.access.log;
  error_log  /var/log/nginx/blogops.mixinet.net-80.error.log;
  if ($host = blogops.mixinet.net)  
    return 301 https://$host$request_uri;
   
  return 404;
 
On this configuration the certificates are managed by certbot and the server root directory is on /srv/blogops/nginx/public_html and not on /srv/blogops/public; the reason for that is that I want to be able to compile without affecting the running site, the deployment script generates the site on /srv/blogops/public and if all works well we rename folders to do the switch, making the change feel almost atomic.

json2file-go configurationAs I have a working WireGuard VPN between the machine running gitea at my home and the VM where the blog is served, I m going to configure the json2file-go to listen for connections on a high port using a self signed certificate and listening on IP addresses only reachable through the VPN. To do it we create a systemd socket to run json2file-go and adjust its configuration to listen on a private IP (we use the FreeBind option on its definition to be able to launch the service even when the IP is not available, that is, when the VPN is down). The following script can be used to set up the json2file-go configuration:
setup-json2file.sh
#!/bin/sh
set -e
# ---------
# VARIABLES
# ---------
BASE_DIR="/srv/blogops/webhook"
J2F_DIR="$BASE_DIR/json2file"
TLS_DIR="$BASE_DIR/tls"
J2F_SERVICE_NAME="json2file-go"
J2F_SERVICE_DIR="/etc/systemd/system/json2file-go.service.d"
J2F_SERVICE_OVERRIDE="$J2F_SERVICE_DIR/override.conf"
J2F_SOCKET_DIR="/etc/systemd/system/json2file-go.socket.d"
J2F_SOCKET_OVERRIDE="$J2F_SOCKET_DIR/override.conf"
J2F_BASEDIR_FILE="/etc/json2file-go/basedir"
J2F_DIRLIST_FILE="/etc/json2file-go/dirlist"
J2F_CRT_FILE="/etc/json2file-go/certfile"
J2F_KEY_FILE="/etc/json2file-go/keyfile"
J2F_CRT_PATH="$TLS_DIR/crt.pem"
J2F_KEY_PATH="$TLS_DIR/key.pem"
# ----
# MAIN
# ----
# Install packages used with json2file for the blogops site
sudo apt update
sudo apt install -y json2file-go uuid
if [ -z "$(type mkcert)" ]; then
  sudo apt install -y mkcert
fi
sudo apt clean
# Configuration file values
J2F_USER="$(id -u)"
J2F_GROUP="$(id -g)"
J2F_DIRLIST="blogops:$(uuid)"
J2F_LISTEN_STREAM="172.31.31.1:4443"
# Configure json2file
[ -d "$J2F_DIR" ]   mkdir "$J2F_DIR"
sudo sh -c "echo '$J2F_DIR' >'$J2F_BASEDIR_FILE'"
[ -d "$TLS_DIR" ]   mkdir "$TLS_DIR"
if [ ! -f "$J2F_CRT_PATH" ]   [ ! -f "$J2F_KEY_PATH" ]; then
  mkcert -cert-file "$J2F_CRT_PATH" -key-file "$J2F_KEY_PATH" "$(hostname -f)"
fi
sudo sh -c "echo '$J2F_CRT_PATH' >'$J2F_CRT_FILE'"
sudo sh -c "echo '$J2F_KEY_PATH' >'$J2F_KEY_FILE'"
sudo sh -c "cat >'$J2F_DIRLIST_FILE'" <<EOF
$(echo "$J2F_DIRLIST"   tr ';' '\n')
EOF
# Service override
[ -d "$J2F_SERVICE_DIR" ]   sudo mkdir "$J2F_SERVICE_DIR"
sudo sh -c "cat >'$J2F_SERVICE_OVERRIDE'" <<EOF
[Service]
User=$J2F_USER
Group=$J2F_GROUP
EOF
# Socket override
[ -d "$J2F_SOCKET_DIR" ]   sudo mkdir "$J2F_SOCKET_DIR"
sudo sh -c "cat >'$J2F_SOCKET_OVERRIDE'" <<EOF
[Socket]
# Set FreeBind to listen on missing addresses (the VPN can be down sometimes)
FreeBind=true
# Set ListenStream to nothing to clear its value and add the new value later
ListenStream=
ListenStream=$J2F_LISTEN_STREAM
EOF
# Restart and enable service
sudo systemctl daemon-reload
sudo systemctl stop "$J2F_SERVICE_NAME"
sudo systemctl start "$J2F_SERVICE_NAME"
sudo systemctl enable "$J2F_SERVICE_NAME"
# ----
# vim: ts=2:sw=2:et:ai:sts=2
Warning: The script uses mkcert to create the temporary certificates, to install the package on bullseye the backports repository must be available.

Gitea configurationTo make gitea use our json2file-go server we go to the project and enter into the hooks/gitea/new page, once there we create a new webhook of type gitea and set the target URL to https://172.31.31.1:4443/blogops and on the secret field we put the token generated with uuid by the setup script:
sed -n -e 's/blogops://p' /etc/json2file-go/dirlist
The rest of the settings can be left as they are:
  • Trigger on: Push events
  • Branch filter: *
Warning: We are using an internal IP and a self signed certificate, that means that we have to review that the webhook section of the app.ini of our gitea server allows us to call the IP and skips the TLS verification (you can see the available options on the gitea documentation). The [webhook] section of my server looks like this:
[webhook]
ALLOWED_HOST_LIST=private
SKIP_TLS_VERIFY=true
Once we have the webhook configured we can try it and if it works our json2file server will store the file on the /srv/blogops/webhook/json2file/blogops/ folder.

The json2file spooler scriptWith the previous configuration our system is ready to receive webhook calls from gitea and store the messages on files, but we have to do something to process those files once they are saved in our machine. An option could be to use a cronjob to look for new files, but we can do better on Linux using inotify we will use the inotifywait command from inotify-tools to watch the json2file output directory and execute a script each time a new file is moved inside it or closed after writing (IN_CLOSE_WRITE and IN_MOVED_TO events). To avoid concurrency problems we are going to use task-spooler to launch the scripts that process the webhooks using a queue of length 1, so they are executed one by one in a FIFO queue. The spooler script is this:
blogops-spooler.sh
#!/bin/sh
set -e
# ---------
# VARIABLES
# ---------
BASE_DIR="/srv/blogops/webhook"
BIN_DIR="$BASE_DIR/bin"
TSP_DIR="$BASE_DIR/tsp"
WEBHOOK_COMMAND="$BIN_DIR/blogops-webhook.sh"
# ---------
# FUNCTIONS
# ---------
queue_job()  
  echo "Queuing job to process file '$1'"
  TMPDIR="$TSP_DIR" TS_SLOTS="1" TS_MAXFINISHED="10" \
    tsp -n "$WEBHOOK_COMMAND" "$1"
 
# ----
# MAIN
# ----
INPUT_DIR="$1"
if [ ! -d "$INPUT_DIR" ]; then
  echo "Input directory '$INPUT_DIR' does not exist, aborting!"
  exit 1
fi
[ -d "$TSP_DIR" ]   mkdir "$TSP_DIR"
echo "Processing existing files under '$INPUT_DIR'"
find "$INPUT_DIR" -type f   sort   while read -r _filename; do
  queue_job "$_filename"
done
# Use inotifywatch to process new files
echo "Watching for new files under '$INPUT_DIR'"
inotifywait -q -m -e close_write,moved_to --format "%w%f" -r "$INPUT_DIR"  
  while read -r _filename; do
    queue_job "$_filename"
  done
# ----
# vim: ts=2:sw=2:et:ai:sts=2
To run it as a daemon we install it as a systemd service using the following script:
setup-spooler.sh
#!/bin/sh
set -e
# ---------
# VARIABLES
# ---------
BASE_DIR="/srv/blogops/webhook"
BIN_DIR="$BASE_DIR/bin"
J2F_DIR="$BASE_DIR/json2file"
SPOOLER_COMMAND="$BIN_DIR/blogops-spooler.sh '$J2F_DIR'"
SPOOLER_SERVICE_NAME="blogops-j2f-spooler"
SPOOLER_SERVICE_FILE="/etc/systemd/system/$SPOOLER_SERVICE_NAME.service"
# Configuration file values
J2F_USER="$(id -u)"
J2F_GROUP="$(id -g)"
# ----
# MAIN
# ----
# Install packages used with the webhook processor
sudo apt update
sudo apt install -y inotify-tools jq task-spooler
sudo apt clean
# Configure process service
sudo sh -c "cat > $SPOOLER_SERVICE_FILE" <<EOF
[Install]
WantedBy=multi-user.target
[Unit]
Description=json2file processor for $J2F_USER
After=docker.service
[Service]
Type=simple
User=$J2F_USER
Group=$J2F_GROUP
ExecStart=$SPOOLER_COMMAND
EOF
# Restart and enable service
sudo systemctl daemon-reload
sudo systemctl stop "$SPOOLER_SERVICE_NAME"   true
sudo systemctl start "$SPOOLER_SERVICE_NAME"
sudo systemctl enable "$SPOOLER_SERVICE_NAME"
# ----
# vim: ts=2:sw=2:et:ai:sts=2

The gitea webhook processorFinally, the script that processes the JSON files does the following:
  1. First, it checks if the repository and branch are right,
  2. Then, it fetches and checks out the commit referenced on the JSON file,
  3. Once the files are updated, compiles the site using hugo with docker compose,
  4. If the compilation succeeds the script renames directories to swap the old version of the site by the new one.
If there is a failure the script aborts but before doing it or if the swap succeeded the system sends an email to the configured address and/or the user that pushed updates to the repository with a log of what happened. The current script is this one:
blogops-webhook.sh
#!/bin/sh
set -e
# ---------
# VARIABLES
# ---------
# Values
REPO_REF="refs/heads/main"
REPO_CLONE_URL="https://gitea.mixinet.net/mixinet/blogops.git"
MAIL_PREFIX="[BLOGOPS-WEBHOOK] "
# Address that gets all messages, leave it empty if not wanted
MAIL_TO_ADDR="blogops@mixinet.net"
# If the following variable is set to 'true' the pusher gets mail on failures
MAIL_ERRFILE="false"
# If the following variable is set to 'true' the pusher gets mail on success
MAIL_LOGFILE="false"
# gitea's conf/app.ini value of NO_REPLY_ADDRESS, it is used for email domains
# when the KeepEmailPrivate option is enabled for a user
NO_REPLY_ADDRESS="noreply.example.org"
# Directories
BASE_DIR="/srv/blogops"
PUBLIC_DIR="$BASE_DIR/public"
NGINX_BASE_DIR="$BASE_DIR/nginx"
PUBLIC_HTML_DIR="$NGINX_BASE_DIR/public_html"
WEBHOOK_BASE_DIR="$BASE_DIR/webhook"
WEBHOOK_SPOOL_DIR="$WEBHOOK_BASE_DIR/spool"
WEBHOOK_ACCEPTED="$WEBHOOK_SPOOL_DIR/accepted"
WEBHOOK_DEPLOYED="$WEBHOOK_SPOOL_DIR/deployed"
WEBHOOK_REJECTED="$WEBHOOK_SPOOL_DIR/rejected"
WEBHOOK_TROUBLED="$WEBHOOK_SPOOL_DIR/troubled"
WEBHOOK_LOG_DIR="$WEBHOOK_SPOOL_DIR/log"
# Files
TODAY="$(date +%Y%m%d)"
OUTPUT_BASENAME="$(date +%Y%m%d-%H%M%S.%N)"
WEBHOOK_LOGFILE_PATH="$WEBHOOK_LOG_DIR/$OUTPUT_BASENAME.log"
WEBHOOK_ACCEPTED_JSON="$WEBHOOK_ACCEPTED/$OUTPUT_BASENAME.json"
WEBHOOK_ACCEPTED_LOGF="$WEBHOOK_ACCEPTED/$OUTPUT_BASENAME.log"
WEBHOOK_REJECTED_TODAY="$WEBHOOK_REJECTED/$TODAY"
WEBHOOK_REJECTED_JSON="$WEBHOOK_REJECTED_TODAY/$OUTPUT_BASENAME.json"
WEBHOOK_REJECTED_LOGF="$WEBHOOK_REJECTED_TODAY/$OUTPUT_BASENAME.log"
WEBHOOK_DEPLOYED_TODAY="$WEBHOOK_DEPLOYED/$TODAY"
WEBHOOK_DEPLOYED_JSON="$WEBHOOK_DEPLOYED_TODAY/$OUTPUT_BASENAME.json"
WEBHOOK_DEPLOYED_LOGF="$WEBHOOK_DEPLOYED_TODAY/$OUTPUT_BASENAME.log"
WEBHOOK_TROUBLED_TODAY="$WEBHOOK_TROUBLED/$TODAY"
WEBHOOK_TROUBLED_JSON="$WEBHOOK_TROUBLED_TODAY/$OUTPUT_BASENAME.json"
WEBHOOK_TROUBLED_LOGF="$WEBHOOK_TROUBLED_TODAY/$OUTPUT_BASENAME.log"
# Query to get variables from a gitea webhook json
ENV_VARS_QUERY="$(
  printf "%s" \
    '(.             @sh "gt_ref=\(.ref);"),' \
    '(.             @sh "gt_after=\(.after);"),' \
    '(.repository   @sh "gt_repo_clone_url=\(.clone_url);"),' \
    '(.repository   @sh "gt_repo_name=\(.name);"),' \
    '(.pusher       @sh "gt_pusher_full_name=\(.full_name);"),' \
    '(.pusher       @sh "gt_pusher_email=\(.email);")'
)"
# ---------
# Functions
# ---------
webhook_log()  
  echo "$(date -R) $*" >>"$WEBHOOK_LOGFILE_PATH"
 
webhook_check_directories()  
  for _d in "$WEBHOOK_SPOOL_DIR" "$WEBHOOK_ACCEPTED" "$WEBHOOK_DEPLOYED" \
    "$WEBHOOK_REJECTED" "$WEBHOOK_TROUBLED" "$WEBHOOK_LOG_DIR"; do
    [ -d "$_d" ]   mkdir "$_d"
  done
 
webhook_clean_directories()  
  # Try to remove empty dirs
  for _d in "$WEBHOOK_ACCEPTED" "$WEBHOOK_DEPLOYED" "$WEBHOOK_REJECTED" \
    "$WEBHOOK_TROUBLED" "$WEBHOOK_LOG_DIR" "$WEBHOOK_SPOOL_DIR"; do
    if [ -d "$_d" ]; then
      rmdir "$_d" 2>/dev/null   true
    fi
  done
 
webhook_accept()  
  webhook_log "Accepted: $*"
  mv "$WEBHOOK_JSON_INPUT_FILE" "$WEBHOOK_ACCEPTED_JSON"
  mv "$WEBHOOK_LOGFILE_PATH" "$WEBHOOK_ACCEPTED_LOGF"
  WEBHOOK_LOGFILE_PATH="$WEBHOOK_ACCEPTED_LOGF"
 
webhook_reject()  
  [ -d "$WEBHOOK_REJECTED_TODAY" ]   mkdir "$WEBHOOK_REJECTED_TODAY"
  webhook_log "Rejected: $*"
  if [ -f "$WEBHOOK_JSON_INPUT_FILE" ]; then
    mv "$WEBHOOK_JSON_INPUT_FILE" "$WEBHOOK_REJECTED_JSON"
  fi
  mv "$WEBHOOK_LOGFILE_PATH" "$WEBHOOK_REJECTED_LOGF"
  exit 0
 
webhook_deployed()  
  [ -d "$WEBHOOK_DEPLOYED_TODAY" ]   mkdir "$WEBHOOK_DEPLOYED_TODAY"
  webhook_log "Deployed: $*"
  mv "$WEBHOOK_ACCEPTED_JSON" "$WEBHOOK_DEPLOYED_JSON"
  mv "$WEBHOOK_ACCEPTED_LOGF" "$WEBHOOK_DEPLOYED_LOGF"
  WEBHOOK_LOGFILE_PATH="$WEBHOOK_DEPLOYED_LOGF"
 
webhook_troubled()  
  [ -d "$WEBHOOK_TROUBLED_TODAY" ]   mkdir "$WEBHOOK_TROUBLED_TODAY"
  webhook_log "Troubled: $*"
  mv "$WEBHOOK_ACCEPTED_JSON" "$WEBHOOK_TROUBLED_JSON"
  mv "$WEBHOOK_ACCEPTED_LOGF" "$WEBHOOK_TROUBLED_LOGF"
  WEBHOOK_LOGFILE_PATH="$WEBHOOK_TROUBLED_LOGF"
 
print_mailto()  
  _addr="$1"
  _user_email=""
  # Add the pusher email address unless it is from the domain NO_REPLY_ADDRESS,
  # which should match the value of that variable on the gitea 'app.ini' (it
  # is the domain used for emails when the user hides it).
  # shellcheck disable=SC2154
  if [ -n "$ gt_pusher_email##*@"$ NO_REPLY_ADDRESS " " ] &&
    [ -z "$ gt_pusher_email##*@* " ]; then
    _user_email="\"$gt_pusher_full_name <$gt_pusher_email>\""
  fi
  if [ "$_addr" ] && [ "$_user_email" ]; then
    echo "$_addr,$_user_email"
  elif [ "$_user_email" ]; then
    echo "$_user_email"
  elif [ "$_addr" ]; then
    echo "$_addr"
  fi
 
mail_success()  
  to_addr="$MAIL_TO_ADDR"
  if [ "$MAIL_LOGFILE" = "true" ]; then
    to_addr="$(print_mailto "$to_addr")"
  fi
  if [ "$to_addr" ]; then
    # shellcheck disable=SC2154
    subject="OK - $gt_repo_name updated to commit '$gt_after'"
    mail -s "$ MAIL_PREFIX $ subject " "$to_addr" \
      <"$WEBHOOK_LOGFILE_PATH"
  fi
 
mail_failure()  
  to_addr="$MAIL_TO_ADDR"
  if [ "$MAIL_ERRFILE" = true ]; then
    to_addr="$(print_mailto "$to_addr")"
  fi
  if [ "$to_addr" ]; then
    # shellcheck disable=SC2154
    subject="KO - $gt_repo_name update FAILED for commit '$gt_after'"
    mail -s "$ MAIL_PREFIX $ subject " "$to_addr" \
      <"$WEBHOOK_LOGFILE_PATH"
  fi
 
# ----
# MAIN
# ----
# Check directories
webhook_check_directories
# Go to the base directory
cd "$BASE_DIR"
# Check if the file exists
WEBHOOK_JSON_INPUT_FILE="$1"
if [ ! -f "$WEBHOOK_JSON_INPUT_FILE" ]; then
  webhook_reject "Input arg '$1' is not a file, aborting"
fi
# Parse the file
webhook_log "Processing file '$WEBHOOK_JSON_INPUT_FILE'"
eval "$(jq -r "$ENV_VARS_QUERY" "$WEBHOOK_JSON_INPUT_FILE")"
# Check that the repository clone url is right
# shellcheck disable=SC2154
if [ "$gt_repo_clone_url" != "$REPO_CLONE_URL" ]; then
  webhook_reject "Wrong repository: '$gt_clone_url'"
fi
# Check that the branch is the right one
# shellcheck disable=SC2154
if [ "$gt_ref" != "$REPO_REF" ]; then
  webhook_reject "Wrong repository ref: '$gt_ref'"
fi
# Accept the file
# shellcheck disable=SC2154
webhook_accept "Processing '$gt_repo_name'"
# Update the checkout
ret="0"
git fetch >>"$WEBHOOK_LOGFILE_PATH" 2>&1   ret="$?"
if [ "$ret" -ne "0" ]; then
  webhook_troubled "Repository fetch failed"
  mail_failure
fi
# shellcheck disable=SC2154
git checkout "$gt_after" >>"$WEBHOOK_LOGFILE_PATH" 2>&1   ret="$?"
if [ "$ret" -ne "0" ]; then
  webhook_troubled "Repository checkout failed"
  mail_failure
fi
# Remove the build dir if present
if [ -d "$PUBLIC_DIR" ]; then
  rm -rf "$PUBLIC_DIR"
fi
# Build site
docker compose run hugo -- >>"$WEBHOOK_LOGFILE_PATH" 2>&1   ret="$?"
# go back to the main branch
git switch main && git pull
# Fail if public dir was missing
if [ "$ret" -ne "0" ]   [ ! -d "$PUBLIC_DIR" ]; then
  webhook_troubled "Site build failed"
  mail_failure
fi
# Remove old public_html copies
webhook_log 'Removing old site versions, if present'
find $NGINX_BASE_DIR -mindepth 1 -maxdepth 1 -name 'public_html-*' -type d \
  -exec rm -rf   \; >>"$WEBHOOK_LOGFILE_PATH" 2>&1   ret="$?"
if [ "$ret" -ne "0" ]; then
  webhook_troubled "Removal of old site versions failed"
  mail_failure
fi
# Switch site directory
TS="$(date +%Y%m%d-%H%M%S)"
if [ -d "$PUBLIC_HTML_DIR" ]; then
  webhook_log "Moving '$PUBLIC_HTML_DIR' to '$PUBLIC_HTML_DIR-$TS'"
  mv "$PUBLIC_HTML_DIR" "$PUBLIC_HTML_DIR-$TS" >>"$WEBHOOK_LOGFILE_PATH" 2>&1  
    ret="$?"
fi
if [ "$ret" -eq "0" ]; then
  webhook_log "Moving '$PUBLIC_DIR' to '$PUBLIC_HTML_DIR'"
  mv "$PUBLIC_DIR" "$PUBLIC_HTML_DIR" >>"$WEBHOOK_LOGFILE_PATH" 2>&1  
    ret="$?"
fi
if [ "$ret" -ne "0" ]; then
  webhook_troubled "Site switch failed"
  mail_failure
else
  webhook_deployed "Site deployed successfully"
  mail_success
fi
# ----
# vim: ts=2:sw=2:et:ai:sts=2

23 May 2022

Arturo Borrero Gonz lez: Toolforge Jobs Framework

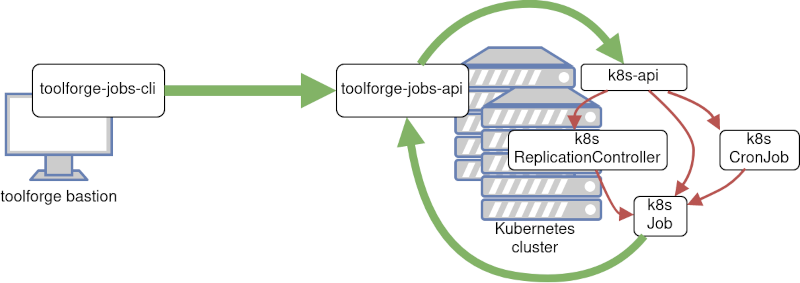
Toolforge jobs framework diagram This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez. This post continues the discussion of Toolforge updates as described in a previous post. Every non-trivial task performed in Toolforge (like executing a script or running a bot) should be dispatched to a job scheduling backend, which ensures that the job is run in a suitable place with sufficient resources. Jobs can be scheduled synchronously or asynchronously, continuously, or simply executed once. The basic principle of running jobs is fairly straightforward: So far, if a tool developer wanted to work with jobs, the Toolforge Grid Engine backend was the only suitable choice. This is despite the fact that Kubernetes supports this kind of workload natively. The truth is that we never prepared our Kubernetes environment to work with jobs. Luckily that has changed.

We no longer want to run Grid Engine In a previous blog post we shared information about our desired future for Grid Engine in Toolforge. Our intention is to discontinue our usage of this technology.

Convenient way of running jobs on Toolforge Kubernetes Some advanced Toolforge users really wanted to use Kubernetes. They were aware of the lack of abstractions or helpers, so they were forced to use the raw Kubernetes API. Eventually, they figured everything out and managed to succeed. The result of this move was in the form of [docs on Wikitech][raws] and a few dozen jobs running on Kubernetes for the first time. We were aware of this, and this initiative was much in sync with our ultimate goal: to promote Kubernetes over Grid Engine. We rolled up our sleeves and started thinking of a way to abstract and make it easy to run jobs without having to deal with lots of YAML and the raw Kubernetes API. There is a precedent: the webservice command does exactly that. It hides all the details behind a simple command line interface to start/stop a web app running on Kubernetes. However, we wanted to go even further, be more flexible and prepare ourselves for more situations in the future: we decided to create a complete new REST API to wrap the jobs functionality in Toolforge Kubernetes. The Toolforge Jobs Framework was born.

Toolforge Jobs Framework components The new framework is a small collection of components. As of this writing, we have three:
  • The REST API responsible for creating/deleting/listing jobs on the Kubernetes system.
  • A command line interface to interact with the REST API above.
  • An emailer to notify users about their jobs activity in the Kubernetes system.
Toolforge jobs framework diagram There were a couple of challenges that weren t trivial to solve. The authentication and authorization against the Kubernetes API was one of them. The other was deciding on the semantics of the new REST API itself. If you are curious, we invite you to take a look at the documentation we have in wikitech.

Open beta phase Once we gained some confidence with the new framework, in July 2021 we decided to start a beta phase. We suggested some advanced Toolforge users try out the new framework. We tracked this phase in Phabricator, where our collaborators quickly started reporting some early bugs, helping each other, and creating new feature requests. Moreover, when we launched the Grid Engine migration from Debian 9 Stretch to Debian 10 Buster we took a step forward and started promoting the new jobs framework as a viable replacement for the grid. Some official documentation pages were created on wikitech as well. As of this writing the framework continues in beta phase. We have solved basically all of the most important bugs, and we already started thinking on how to address the few feature requests that are missing. We haven t yet established yet the criteria for leaving the beta phase, but it would be good to have:
  • Critical bugs fixed and most feature requests addressed (or at least somehow planned).
  • Proper automated test coverage. We can do better on testing the different software components to ensure they are as bug free as possible. This also would make sure that contributing changes is easy.
  • REST API swagger integration.
  • Deployment automation. Deploying the REST API and the emailer is tedious. This is tracked in Phabricator.
  • Documentation, documentation, documentation.

Limitations One of the limitations we bear in mind since early on in the development process of this framework was the support for mixing different programming languages or runtime environments in the same job. Solving this limitation is currently one of the WMCS team priorities, because this is one of the key workflows that was available on Grid Engine. The moment we address it, the framework adoption will grow, and it will pretty much enable the same workflows as in the grid, if not more advanced and featureful. Stay tuned for more upcoming blog posts with additional information about Toolforge. This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez.

22 May 2022

Sergio Talens-Oliag: New Blog

Welcome to my new Blog for Technical Stuff. For a long time I was planning to start publishing technical articles again but to do it I wanted to replace my old blog based on ikiwiki by something more modern. I ve used Jekyll with GitLab Pages to build the Intranet of the ITI and to generate internal documentation sites on Agile Content, but, as happened with ikiwiki, I felt that things were kind of slow and not as easy to maintain as I would like. So on Kyso (the Company I work for right now) I switched to Hugo as the Static Site Generator (I still use GitLab Pages to automate the deployment, though), but the contents are written using the Markdown format, while my personal preference is the Asciidoc format. One thing I liked about Jekyll was that it was possible to use Asciidoctor to generate the HTML simply by using the Jekyll Asciidoc plugin (I even configured my site to generate PDF documents from .adoc files using the Asciidoctor PDF converter) and, luckily for me, that is also possible with Hugo, so that is what I plan to use on this blog, in fact this post is written in .adoc. My plan is to start publishing articles about things I m working on to keep them documented for myself and maybe be useful to someone else. The general intention is to write about Container Orchestration (mainly Kubernetes), CI/CD tools (currently I m using GitLab CE for that), System Administration (with Debian GNU/Linux as my preferred OS) and that sort of things. My next post will be about how I build, publish and update the Blog, but probably I will not finish it until next week, once the site is fully operational and the publishing system is tested.
Spoiler Alert: This is a personal site, so I m using Gitea to host the code instead of GitLab. To handle the deployment I ve configured json2file-go to save the data sent by the hook calls and process it asynchronously using inotify-tools. When a new file is detected a script parses the JSON file using jq and builds and updates the site if appropriate.

Ulrike Uhlig: How do kids conceive the internet? - part 3

I received some feedback on the first part of interviews about the internet with children that I d like to share publicly here. Thank you! Your thoughts and experiences are important to me! In the first interview round there was this French girl.
Asked what she would change if she could, the 9 year old girl advocated for a global usage limit of the internet in order to protect the human brain. Also, she said, her parents spend way too much time on their phones and people should rather spend more time with their children.
To this bit, one person reacted saying that they first laughed when reading her proposal, but then felt extremely touched by it. Another person reacted to the same bit of text:
That s just brilliant. We spend so much time worrying about how the internet will affect children while overlooking how it has already affected us as parents. It actively harms our relationship with our children (keeping us distracted from their amazing life) and sets a bad example for them. Too often, when we worry about children, we should look at our own behavior first. Until about that age (9-10+) at least, they are such a direct reflection of us that it s frightening
Yet another person reacted to the fact that many of the interviewees in the first round seemed to believe that the internet is immaterial, located somewhere in the air, while being at the same time omnipresent:
It reminds me of one time about a dozen years ago, when i was still working closely with one of the city high schools where i d just had a terrible series of days, dealing with hardware failure, crappy service followthrough by the school s ISP, and overheating in the server closet, and had basically stayed overnight at the school and just managed to get things back to mostly-functional before kids and teachers started showing up again. That afternoon, i d been asked by the teacher of a dystopian fiction class to join them for a discussion of Feed, which they d just finished reading. i had read it the week before, and came to class prepared for their questions. (the book is about a near-future where kids have cybernetic implants and their society is basically on a runaway communications overload; not a bad Y[oung]A[dult] novel, really!) The kids all knew me from around the school, but the teacher introduced my appearance in class as one of the most Internet-connected people and they wanted to ask me about whether i really thought the internet would do this kind of thing to our culture, which i think was the frame that the teacher had prepped them with. I asked them whether they thought the book was really about the Internet, or whether it was about mobile phones. Totally threw off the teacher s lesson plans, i think, but we had a good discussion. At one point, one of the kids asked me if there was some kind of crazy disaster and all the humans died out, would the internet just keep running? what would happen on it if we were all gone? all of my labor even that grueling week was invisible to him! The internet was an immaterial thing, or if not immaterial, a force of nature, a thing that you accounted for the way you accounted for the weather, or traffic jams. It didn t occur to him, even having just read a book that asked questions about what hyperconnectivity does to a culture (including grappling with issues of disparate access, effective discrimination based on who has the latest hardware, etc), it didn t occur to him that this shit all works to the extent that it does because people make it go. I felt lost trying to explain it to him, because where i wanted to get to with the class discussion was about how we might decide collectively to make it go somewhere else that our contributions to it, and our labor to perpetuate it (or not) might actually help shape the future that the network helps us slide into. but he didn t even see that human decisions or labor played a role it in at all, let alone a potentially directive role. We were really starting at square zero, which wasn t his fault. Or the fault of his classmates that matter but maybe a little bit of fault on the teacher, who i thought should have been emphasizing this more but even the teacher clearly thought of the internet as a thing being done to us not as something we might actually drive one way or another. And she s not even wrong most people don t have much control, just like most people can t control the weather, even as our weather changes based on aggregate human activity.
I was quite impressed by seeing the internet perceived as a force of nature, so we continued this discussion a bit:
that whole story happened before we started talking about the cloud , but the cloud really reinforces this idea, i think. not that anyone actually thinks that the cloud is a literal cloud, but language shapes minds in subtle ways.
(Bold emphasis in the texts are mine.) Thanks :) I m happy and touched that these interviews prompted your wonderful reactions, and I hope that there ll be more to come on this topic. I m working on it!

Russ Allbery: Review: On a Sunbeam

Review: On a Sunbeam, by Tillie Walden
Publisher: Tillie Walden
Copyright: 2016-2017
Format: Online graphic novel
Pages: 544
On a Sunbeam is a web comic that was published in installments between Fall 2016 and Spring 2017, and then later published in dead tree form. I read the on-line version, which is still available for free from its web site. It was nominated for an Eisner Award and won a ton of other awards, including the Los Angeles Times Book Prize. Mia is a new high school graduate who has taken a job with a construction crew that repairs old buildings (that are floating in space, but I'll get to that in a moment). Alma, Elliot, and Charlotte have been together for a long time; Jules is closer to Mia's age and has been with them for a year. This is not the sort of job one commutes to: they live together on a spaceship that travels to the job sites, share meals together, and are more of an extended family than a group of coworkers. It's all a bit intimidating for Mia, but Jules provides a very enthusiastic welcome and some orientation. The story of Mia's new job is interleaved with Mia's school experience from five years earlier. As a new frosh at a boarding school, Mia is obsessed with Lux, a school sport that involves building and piloting ships through a maze to capture orbs. Sent to the principal's office on the first day of school for sneaking into the Lux tower when she's supposed to be at assembly, she meets Grace, a shy girl with sparkly shoes and an unheard-of single room. Mia (a bit like Jules in the present timeline) overcomes Grace's reticence by being persistently outgoing and determinedly friendly, while trying to get on the Lux team and dealing with the typical school problems of bullies and in-groups. On a Sunbeam is science fiction in the sense that it seems to take place in space and school kids build flying ships. It is not science fiction in the sense of caring about technological extrapolation or making any scientific sense whatsoever. The buildings that Mia and the crew repair appear to be hanging in empty space, but there's gravity. No one wears any protective clothing or air masks. The spaceships look (and move) like giant tropical fish. If you need realism in your science fiction graphical novels, it's probably best not to think of this as science fiction at all, or even science fantasy despite the later appearance of some apparently magical or divine elements. That may sound surrealistic or dream-like, but On a Sunbeam isn't that either. It's a story about human relationships, found family, and diversity of personalities, all of which are realistically portrayed. The characters find their world coherent, consistent, and predictable, even if it sometimes makes no sense to the reader. On a Sunbeam is simply set in its own universe, with internal logic but without explanation or revealed rules. I kind of liked this approach? It takes some getting used to, but it's an excuse for some dramatic and beautiful backgrounds, and it's oddly freeing to have unremarked train tracks in outer space. There's no way that an explanation would have worked; if one were offered, my brain would have tried to nitpick it to the detriment of the story. There's something delightful about a setting that follows imaginary physical laws this unapologetically and without showing the author's work. I was, sadly, not as much of a fan of the art, although I am certain this will be a matter of taste. Walden mixes simple story-telling panels with sweeping vistas, free-floating domes, and strange, wild asteroids, but she uses a very limited color palette. Most panels are only a few steps away from monochrome, and the colors are chosen more for mood or orientation in the story (Mia's school days are all blue, the Staircase is orange) than for any consistent realism. There is often a lot of detail in the panels, but I found it hard to appreciate because the coloring confused my eye. I'm old enough to have been a comics reader during the revolution in digital coloring and improved printing, and I loved the subsequent dramatic improvement in vivid colors and shading. I know the coloring style here is an intentional artistic choice, but to me it felt like a throwback to the days of muddy printing on cheap paper. I have a similar complaint about the lettering: On a Sunbeam is either hand-lettered or closely simulates hand lettering, and I often found the dialogue hard to read due to inconsistent intra- and interword spacing or ambiguous letters. Here too I'm sure this was an artistic choice, but as a reader I'd much prefer a readable comics font over hand lettering. The detail in the penciling is more to my liking. I had occasional trouble telling some of the characters apart, but they're clearly drawn and emotionally expressive. The scenery is wildly imaginative and often gorgeous, which increased my frustration with the coloring. I would love to see what some of these panels would have looked like after realistic coloring with a full palette. (It's worth noting again that I read the on-line version. It's possible that the art was touched up for the print version and would have been more to my liking.) But enough about the art. The draw of On a Sunbeam for me is the story. It's not very dramatic or event-filled at first, starting as two stories of burgeoning friendships with a fairly young main character. (They are closely linked, but it's not obvious how until well into the story.) But it's the sort of story that I started reading, thought was mildly interesting, and then kept reading just one more chapter until I had somehow read the whole thing. There are some interesting twists towards the end, but it's otherwise not a very dramatic or surprising story. What it is instead is open-hearted, quiet, charming, and deeper than it looks. The characters are wildly different and can be abrasive, but they invest time and effort into understanding each other and adjusting for each other's preferences. Personal loss drives a lot of the plot, but the characters are also allowed to mature and be happy without resolving every bad thing that happened to them. These characters felt like people I would like and would want to get to know (even if Jules would be overwhelming). I enjoyed watching their lives. This reminded me a bit of a Becky Chambers novel, although it's less invested in being science fiction and sticks strictly to humans. There's a similar feeling that the relationships are the point of the story, and that nearly everyone is trying hard to be good, with differing backgrounds and differing conceptions of good. All of the characters are female or non-binary, which is left as entirely unexplained as the rest of the setting. It's that sort of book. I wouldn't say this is one of the best things I've ever read, but I found it delightful and charming, and it certainly sucked me in and kept me reading until the end. One also cannot argue with the price, although if I hadn't already read it, I would be tempted to buy a paper copy to support the author. This will not be to everyone's taste, and stay far away if you are looking for realistic science fiction, but recommended if you are in the mood for an understated queer character story full of good-hearted people. Rating: 7 out of 10

20 May 2022

Louis-Philippe V ronneau: Introducing metalfinder

After going to an incredible Arch Enemy / Behemoth / Napalm Death / Unto Others concert a few weeks ago, I decided I wanted to go to more concerts. I like music, and I really enjoy concerts. Sadly, I often miss great performances because no one told me about it, or my local newspaper didn't cover the event enough in advance for me to get tickets. Some online services lets you sync your Spotify account to notify you when a new concert is announced, but I don't use Spotify. As a music geek, I have a local music collection and if I need to stream it, I have a supysonic server. Introducing metalfinder, a cli tool to find concerts using your local music collection! At the moment, it scans your music collection, creates a list of artists and queries Bandsintown for concerts in your town. Multiple output formats are supported, but I mainly use the ATOM one, as I'm a heavy feed reader user. Screenshot of the ATOM output in my feed reader The current metalfinder version (1.1.1) is a MVP: it works well enough, but I still have a lot of work to do... If you want to give it a try, the easiest way is to download it from PyPi. metalfinder is also currently in NEW and I'm planning to have something feature complete in time for the Bookworm freeze.

19 May 2022

Agathe Porte: Status update, May 2022

Boing, time for another status update.
Debian work I have finally found how to make my fonts-creep2 package work on my Debian machines. The solution was to not use the TTF file that contains the Bitmap glyphs, but instead generate an OTB file, which is an OpenType format for Bitmap fonts. Creep2 font used in htop command This means that I can close the fonts-creep ITP bug altogether and rely on this fonts-creep2 package instead. Hopefully it will be reviewed and uploaded soon by a certified Debian Developer. This font is too small for daily usage, but imagine the quantity of data you could display on an auxiliary screen with poor resolution (and poor pixel density eventually). Here is a meme I created for the occasion: Hide the pain Harold meme. First: Package software and its gazillion dependencies. Second: Popcon says I'm the only user. Checks out.
Rust work I have obsoleted my most popular Rust crate, gladis. Screenshot of the Gladis Github README Indeed, the GTK folks have managed to develop a similar solution named CompositeTemplate, that is available in both gtk3-macros and gtk4-macros crates. I did not investigate from how long this has been available before I created this crate. Hopefully it did not exist before I developed it. I have learnt a lot about Rust crates development with this crate, and managed to put in place a semi-automated release flow that I will surely use in other future crates. See ya.

18 May 2022

Reproducible Builds: Supporter spotlight: Jan Nieuwenhuizen on Bootstrappable Builds, GNU Mes and GNU Guix

The Reproducible Builds project relies on several projects, supporters and sponsors for financial support, but they are also valued as ambassadors who spread the word about our project and the work that we do. This is the fourth instalment in a series featuring the projects, companies and individuals who support the Reproducible Builds project. We started this series by featuring the Civil Infrastructure Platform project and followed this up with a post about the Ford Foundation as well as a recent ones about ARDC and the Google Open Source Security Team (GOSST). Today, however, we will be talking with Jan Nieuwenhuizen about Bootstrappable Builds, GNU Mes and GNU Guix.
Chris Lamb: Hi Jan, thanks for taking the time to talk with us today. First, could you briefly tell me about yourself? Jan: Thanks for the chat; it s been a while! Well, I ve always been trying to find something new and interesting that is just asking to be created but is mostly being overlooked. That s how I came to work on GNU Guix and create GNU Mes to address the bootstrapping problem that we have in free software. It s also why I have been working on releasing Dezyne, a programming language and set of tools to specify and formally verify concurrent software systems as free software. Briefly summarised, compilers are often written in the language they are compiling. This creates a chicken-and-egg problem which leads users and distributors to rely on opaque, pre-built binaries of those compilers that they use to build newer versions of the compiler. To gain trust in our computing platforms, we need to be able to tell how each part was produced from source, and opaque binaries are a threat to user security and user freedom since they are not auditable. The goal of bootstrappability (and the bootstrappable.org project in particular) is to minimise the amount of these bootstrap binaries. Anyway, after studying Physics at Eindhoven University of Technology (TU/e), I worked for digicash.com, a startup trying to create a digital and anonymous payment system sadly, however, a traditional account-based system won. Separate to this, as there was no software (either free or proprietary) to automatically create beautiful music notation, together with Han-Wen Nienhuys, I created GNU LilyPond. Ten years ago, I took the initiative to co-found a democratic school in Eindhoven based on the principles of sociocracy. And last Christmas I finally went vegan, after being mostly vegetarian for about 20 years!
Chris: For those who have not heard of it before, what is GNU Guix? What are the key differences between Guix and other Linux distributions? Jan: GNU Guix is both a package manager and a full-fledged GNU/Linux distribution. In both forms, it provides state-of-the-art package management features such as transactional upgrades and package roll-backs, hermetical-sealed build environments, unprivileged package management as well as per-user profiles. One obvious difference is that Guix forgoes the usual Filesystem Hierarchy Standard (ie. /usr, /lib, etc.), but there are other significant differences too, such as Guix being scriptable using Guile/Scheme, as well as Guix s dedication and focus on free software.
Chris: How does GNU Guix relate to GNU Mes? Or, rather, what problem is Mes attempting to solve? Jan: GNU Mes was created to address the security concerns that arise from bootstrapping an operating system such as Guix. Even if this process entirely involves free software (i.e. the source code is, at least, available), this commonly uses large and unauditable binary blobs. Mes is a Scheme interpreter written in a simple subset of C and a C compiler written in Scheme, and it comes with a small, bootstrappable C library. Twice, the Mes bootstrap has halved the size of opaque binaries that were needed to bootstrap GNU Guix. These reductions were achieved by first replacing GNU Binutils, GNU GCC and the GNU C Library with Mes, and then replacing Unix utilities such as awk, bash, coreutils, grep sed, etc., by Gash and Gash-Utils. The final goal of Mes is to help create a full-source bootstrap for any interested UNIX-like operating system.
Chris: What is the current status of Mes? Jan: Mes supports all that is needed from R5RS and GNU Guile to run MesCC with Nyacc, the C parser written for Guile, for 32-bit x86 and ARM. The next step for Mes would be more compatible with Guile, e.g., have guile-module support and support running Gash and Gash Utils. In working to create a full-source bootstrap, I have disregarded the kernel and Guix build system for now, but otherwise, all packages should be built from source, and obviously, no binary blobs should go in. We still need a Guile binary to execute some scripts, and it will take at least another one to two years to remove that binary. I m using the 80/20 approach, cutting corners initially to get something working and useful early. Another metric would be how many architectures we have. We are quite a way with ARM, tinycc now works, but there are still problems with GCC and Glibc. RISC-V is coming, too, which could be another metric. Someone has looked into picking up NixOS this summer. How many distros do anything about reproducibility or bootstrappability? The bootstrappability community is so small that we don t need metrics, sadly. The number of bytes of binary seed is a nice metric, but running the whole thing on a full-fledged Linux system is tough to put into a metric. Also, it is worth noting that I m developing on a modern Intel machine (ie. a platform with a management engine), that s another key component that doesn t have metrics.
Chris: From your perspective as a Mes/Guix user and developer, what does reproducibility mean to you? Are there any related projects? Jan: From my perspective, I m more into the problem of bootstrapping, and reproducibility is a prerequisite for bootstrappability. Reproducibility clearly takes a lot of effort to achieve, however. It s relatively easy to install some Linux distribution and be happy, but if you look at communities that really care about security, they are investing in reproducibility and other ways of improving the security of their supply chain. Projects I believe are complementary to Guix and Mes include NixOS, Debian and on the hardware side the RISC-V platform shares many of our core principles and goals.
Chris: Well, what are these principles and goals? Jan: Reproducibility and bootstrappability often feel like the next step in the frontier of free software. If you have all the sources and you can t reproduce a binary, that just doesn t feel right anymore. We should start to desire (and demand) transparent, elegant and auditable software stacks. To a certain extent, that s always been a low-level intent since the beginning of free software, but something clearly got lost along the way. On the other hand, if you look at the NPM or Rust ecosystems, we see a world where people directly install binaries. As they are not as supportive of copyleft as the rest of the free software community, you can see that movement and people in our area are doing more as a response to that so that what we have continues to remain free, and to prevent us from falling asleep and waking up in a couple of years and see, for example, Rust in the Linux kernel and (more importantly) we require big binary blobs to use our systems. It s an excellent time to advance right now, so we should get a foothold in and ensure we don t lose any more.
Chris: What would be your ultimate reproducibility goal? And what would the key steps or milestones be to reach that? Jan: The ultimate goal would be to have a system built with open hardware, with all software on it fully bootstrapped from its source. This bootstrap path should be easy to replicate and straightforward to inspect and audit. All fully reproducible, of course! In essence, we would have solved the supply chain security problem. Our biggest challenge is ignorance. There is much unawareness about the importance of what we are doing. As it is rather technical and doesn t really affect everyday computer use, that is not surprising. This unawareness can be a great force driving us in the opposite direction. Think of Rust being allowed in the Linux kernel, or Python being required to build a recent GNU C library (glibc). Also, the fact that companies like Google/Apple still want to play us vs them , not willing to to support GPL software. Not ready yet to truly support user freedom. Take the infamous log4j bug everyone is using open source these days, but nobody wants to take responsibility and help develop or nurture the community. Not ecosystem , as that s how it s being approached right now: live and let live/die: see what happens without taking any responsibility. We are growing and we are strong and we can do a lot but if we have to work against those powers, it can become problematic. So, let s spread our great message and get more people involved!
Chris: What has been your biggest win? Jan: From a technical point of view, the full-source bootstrap has have been our biggest win. A talk by Carl Dong at the 2019 Breaking Bitcoin conference stated that connecting Jeremiah Orian s Stage0 project to Mes would be the holy grail of bootstrapping, and we recently managed to achieve just that: in other words, starting from hex0, 357-byte binary, we can now build the entire Guix system. This past year we have not made significant visible progress, however, as our funding was unfortunately not there. The Stage0 project has advanced in RISC-V. A month ago, though, I secured NLnet funding for another year, and thanks to NLnet, Ekaitz Zarraga and Timothy Sample will work on GNU Mes and the Guix bootstrap as well. Separate to this, the bootstrappable community has grown a lot from two people it was six years ago: there are now currently over 100 people in the #bootstrappable IRC channel, for example. The enlarged community is possibly an even more important win going forward.
Chris: How realistic is a 100% bootstrappable toolchain? And from someone who has been working in this area for a while, is solving Trusting Trust) actually feasible in reality? Jan: Two answers: Yes and no, it really depends on your definition. One great thing is that the whole Stage0 project can also run on the Knight virtual machine, a hardware platform that was designed, I think, in the 1970s. I believe we can and must do better than we are doing today, and that there s a lot of value in it. The core issue is not the trust; we can probably all trust each other. On the other hand, we don t want to trust each other or even ourselves. I am not, personally, going to inspect my RISC-V laptop, and other people create the hardware and do probably not want to inspect the software. The answer comes back to being conscientious and doing what is right. Inserting GCC as a binary blob is not right. I think we can do better, and that s what I d like to do. The security angle is interesting, but I don t like the paranoid part of that; I like the beauty of what we are creating together and stepwise improving on that.
Chris: Thanks for taking the time to talk to us today. If someone wanted to get in touch or learn more about GNU Guix or Mes, where might someone go? Jan: Sure! First, check out: I m also on Twitter (@janneke_gnu) and on octodon.social (@janneke@octodon.social).
Chris: Thanks for taking the time to talk to us today. Jan: No problem. :)


For more information about the Reproducible Builds project, please see our website at reproducible-builds.org. If you are interested in ensuring the ongoing security of the software that underpins our civilisation and wish to sponsor the Reproducible Builds project, please reach out to the project by emailing contact@reproducible-builds.org.

Louis-Philippe V ronneau: Clojure Team 2022 Sprint Report

This is the report for the Debian Clojure Team remote sprint that took place on May 13-14th. Looking at my previous blog entries, this was my first Debian sprint since July 2020! Crazy how fast time flies... Many thanks to those who participated, namely: Sadly, Utkarsh Gupta although having planned on participating ended up not being able to and worked on DebConf Bursary paperwork instead. rlb Rob mostly worked on creating a dh-clojure tool to help make packaging Clojure libraries easier. At the moment, most of the packaging is done manually, by invoking build tools by hand. Having a tool to automate many of the steps required to build Clojure packages would go a long way in making them more uniform. His work (although still very much a WIP) can be found here: https://salsa.debian.org/rlb/dh-clojure/ ehashman Elana: lavamind It was J r me's first time working on Clojure packages, and things went great! During the sprint, he: allentiak Leandro joined us on Saturday, since he couldn't get off work on Friday. He mostly continued working on replacing our in-house scripts for /usr/bin/clojure by upstream's, a task he had already started during GSoC 2021. Sadly, none of us were familiar with Debian's mechanism for alternatives. If you (yes you, dear reader) are familiar with it, I'm sure he would warmly welcome feedback on his development branch. pollo As for me, I: Overall, it was quite a productive sprint! Thanks to Debian for sponsoring our food during the sprint. It was nice to be able to concentrate on fixing things instead of making food :) Here's a bonus picture of the nice sushi platter I ended up getting for dinner on Saturday night: Picture of a sushi platter

13 May 2022

Antoine Beaupr : NVMe/SSD disk failure

Yesterday, my workstation (curie) was hung when I came in the office. After a "skinny elephant", the box rebooted, but it couldn't find the primary disk (in the BIOS). Instead, it booted on the secondary HDD drive, still running an old Fedora 27 install which somehow survived to this day, possibly because ?BTRFS is incomprehensible. Somehow, I blindly accepted the Fedora prompt asking me to upgrade to Fedora 28, not realizing that:
  1. Fedora is now at release 36, not 28
  2. major upgrades take about an hour...
  3. ... and happen at boot time, blocking the entire machine (I'll remember this next time I laugh at Windows and Mac OS users stuck on updates on boot)
  4. you can't skip more than one major upgrade
Which means that upgrading to latest would take over 4 hours. Thankfully, it's mostly automated and seems to work pretty well (which is not exactly the case for Debian). It still seems like a lot of wasted time -- it would probably be better to just reinstall the machine at this point -- and not what I had planned to do that morning at all. In any case, after waiting all that time, the machine booted (in Fedora) again, and now it could detect the SSD disk. The BIOS could find the disk too, so after I reinstalled grub (from Fedora) and fixed the boot order, it rebooted, but secureboot failed, so I turned that off (!?), and I was back in Debian. I did an emergency backup with ddrescue, from the running system which probably doesn't really work as a backup (because the filesystem is likely to be corrupt) but it was fast enough (20 minutes) and gave me some peace of mind. My offsites backup have been down for a while and since I treat my workstations as "cattle" (not "pets"), I don't have a solid recovery scenario for those situations other than "just reinstall and run Puppet", which takes a while. Now I'm wondering what the next step is: probably replace the disk anyways (the new one is bigger: 1TB instead of 500GB), or keep the new one as a hot backup somehow. Too bad I don't have a snapshotting filesystem on there... (Technically, I have LVM, but LVM snapshots are heavy and slow, and can't atomically cover the entire machine.) It's kind of scary how this thing failed: totally dropped off the bus, just not in the BIOS at all. I prefer the way spinning rust fails: clickety sounds, tons of warnings beforehand, partial recovery possible. With this new flashy junk, you just lose everything all at once. Not fun.

Antoine Beaupr : BTRFS notes

I'm not a fan of BTRFS. This page serves as a reminder of why, but also a cheat sheet to figure out basic tasks in a BTRFS environment because those are not obvious to me, even after repeatedly having to deal with them. Content warning: there might be mentions of ZFS.

Stability concerns I'm worried about BTRFS stability, which has been historically ... changing. RAID-5 and RAID-6 are still marked unstable, for example. It's kind of a lucky guess whether your current kernel will behave properly with your planned workload. For example, in Linux 4.9, RAID-1 and RAID-10 were marked as "mostly OK" with a note that says:
Needs to be able to create two copies always. Can get stuck in irreversible read-only mode if only one copy can be made.
Even as of now, RAID-1 and RAID-10 has this note:
The simple redundancy RAID levels utilize different mirrors in a way that does not achieve the maximum performance. The logic can be improved so the reads will spread over the mirrors evenly or based on device congestion.
Granted, that's not a stability concern anymore, just performance. A reviewer of a draft of this article actually claimed that BTRFS only reads from one of the drives, which hopefully is inaccurate, but goes to show how confusing all this is. There are other warnings in the Debian wiki that are quite scary. Even the legendary Arch wiki has a warning on top of their BTRFS page, still. Even if those issues are now fixed, it can be hard to tell when they were fixed. There is a changelog by feature but it explicitly warns that it doesn't know "which kernel version it is considered mature enough for production use", so it's also useless for this. It would have been much better if BTRFS was released into the world only when those bugs were being completely fixed. Or that, at least, features were announced when they were stable, not just "we merged to mainline, good luck". Even now, we get mixed messages even in the official BTRFS documentation which says "The Btrfs code base is stable" (main page) while at the same time clearly stating unstable parts in the status page (currently RAID56). There are much harsher BTRFS critics than me out there so I will stop here, but let's just say that I feel a little uncomfortable trusting server data with full RAID arrays to BTRFS. But surely, for a workstation, things should just work smoothly... Right? Well, let's see the snags I hit.

My BTRFS test setup Before I go any further, I should probably clarify how I am testing BTRFS in the first place. The reason I tried BTRFS is that I was ... let's just say "strongly encouraged" by the LWN editors to install Fedora for the terminal emulators series. That, in turn, meant the setup was done with BTRFS, because that was somewhat the default in Fedora 27 (or did I want to experiment? I don't remember, it's been too long already). So Fedora was setup on my 1TB HDD and, with encryption, the partition table looks like this:
NAME                   MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINT
sda                      8:0    0 931,5G  0 disk  
 sda1                   8:1    0   200M  0 part  /boot/efi
 sda2                   8:2    0     1G  0 part  /boot
 sda3                   8:3    0   7,8G  0 part  
   fedora_swap        253:5    0   7.8G  0 crypt [SWAP]
 sda4                   8:4    0 922,5G  0 part  
   fedora_crypt       253:4    0 922,5G  0 crypt /
(This might not entirely be accurate: I rebuilt this from the Debian side of things.) This is pretty straightforward, except for the swap partition: normally, I just treat swap like any other logical volume and create it in a logical volume. This is now just speculation, but I bet it was setup this way because "swap" support was only added in BTRFS 5.0. I fully expect BTRFS experts to yell at me now because this is an old setup and BTRFS is so much better now, but that's exactly the point here. That setup is not that old (2018? old? really?), and migrating to a new partition scheme isn't exactly practical right now. But let's move on to more practical considerations.

No builtin encryption BTRFS aims at replacing the entire mdadm, LVM, and ext4 stack with a single entity, and adding new features like deduplication, checksums and so on. Yet there is one feature it is critically missing: encryption. See, my typical stack is actually mdadm, LUKS, and then LVM and ext4. This is convenient because I have only a single volume to decrypt. If I were to use BTRFS on servers, I'd need to have one LUKS volume per-disk. For a simple RAID-1 array, that's not too bad: one extra key. But for large RAID-10 arrays, this gets really unwieldy. The obvious BTRFS alternative, ZFS, supports encryption out of the box and mixes it above the disks so you only have one passphrase to enter. The main downside of ZFS encryption is that it happens above the "pool" level so you can typically see filesystem names (and possibly snapshots, depending on how it is built), which is not the case with a more traditional stack.

Subvolumes, filesystems, and devices I find BTRFS's architecture to be utterly confusing. In the traditional LVM stack (which is itself kind of confusing if you're new to that stuff), you have those layers:
  • disks: let's say /dev/nvme0n1 and nvme1n1
  • RAID arrays with mdadm: let's say the above disks are joined in a RAID-1 array in /dev/md1
  • volume groups or VG with LVM: the above RAID device (technically a "physical volume" or PV) is assigned into a VG, let's call it vg_tbbuild05 (multiple PVs can be added to a single VG which is why there is that abstraction)
  • LVM logical volumes: out of that volume group actually "virtual partitions" or "logical volumes" are created, that is where your filesystem lives
  • filesystem, typically with ext4: that's your normal filesystem, which treats the logical volume as just another block device
A typical server setup would look like this:
NAME                      MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINT
nvme0n1                   259:0    0   1.7T  0 disk  
 nvme0n1p1               259:1    0     8M  0 part  
 nvme0n1p2               259:2    0   512M  0 part  
   md0                     9:0    0   511M  0 raid1 /boot
 nvme0n1p3               259:3    0   1.7T  0 part  
   md1                     9:1    0   1.7T  0 raid1 
     crypt_dev_md1       253:0    0   1.7T  0 crypt 
       vg_tbbuild05-root 253:1    0    30G  0 lvm   /
       vg_tbbuild05-swap 253:2    0 125.7G  0 lvm   [SWAP]
       vg_tbbuild05-srv  253:3    0   1.5T  0 lvm   /srv
 nvme0n1p4               259:4    0     1M  0 part
I stripped the other nvme1n1 disk because it's basically the same. Now, if we look at my BTRFS-enabled workstation, which doesn't even have RAID, we have the following:
  • disk: /dev/sda with, again, /dev/sda4 being where BTRFS lives
  • filesystem: fedora_crypt, which is, confusingly, kind of like a volume group. it's where everything lives. i think.
  • subvolumes: home, root, /, etc. those are actually the things that get mounted. you'd think you'd mount a filesystem, but no, you mount a subvolume. that is backwards.
It looks something like this to lsblk:
NAME                   MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINT
sda                      8:0    0 931,5G  0 disk  
 sda1                   8:1    0   200M  0 part  /boot/efi
 sda2                   8:2    0     1G  0 part  /boot
 sda3                   8:3    0   7,8G  0 part  [SWAP]
 sda4                   8:4    0 922,5G  0 part  
   fedora_crypt       253:4    0 922,5G  0 crypt /srv
Notice how we don't see all the BTRFS volumes here? Maybe it's because I'm mounting this from the Debian side, but lsblk definitely gets confused here. I frankly don't quite understand what's going on, even after repeatedly looking around the rather dismal documentation. But that's what I gather from the following commands:
root@curie:/home/anarcat# btrfs filesystem show
Label: 'fedora'  uuid: 5abb9def-c725-44ef-a45e-d72657803f37
    Total devices 1 FS bytes used 883.29GiB
    devid    1 size 922.47GiB used 916.47GiB path /dev/mapper/fedora_crypt
root@curie:/home/anarcat# btrfs subvolume list /srv
ID 257 gen 108092 top level 5 path home
ID 258 gen 108094 top level 5 path root
ID 263 gen 108020 top level 258 path root/var/lib/machines
I only got to that point through trial and error. Notice how I use an existing mountpoint to list the related subvolumes. If I try to use the filesystem path, the one that's listed in filesystem show, I fail:
root@curie:/home/anarcat# btrfs subvolume list /dev/mapper/fedora_crypt 
ERROR: not a btrfs filesystem: /dev/mapper/fedora_crypt
ERROR: can't access '/dev/mapper/fedora_crypt'
Maybe I just need to use the label? Nope:
root@curie:/home/anarcat# btrfs subvolume list fedora
ERROR: cannot access 'fedora': No such file or directory
ERROR: can't access 'fedora'
This is really confusing. I don't even know if I understand this right, and I've been staring at this all afternoon. Hopefully, the lazyweb will correct me eventually. (As an aside, why are they called "subvolumes"? If something is a "sub" of "something else", that "something else" must exist right? But no, BTRFS doesn't have "volumes", it only has "subvolumes". Go figure. Presumably the filesystem still holds "files" though, at least empirically it doesn't seem like it lost anything so far. In any case, at least I can refer to this section in the future, the next time I fumble around the btrfs commandline, as I surely will. I will possibly even update this section as I get better at it, or based on my reader's judicious feedback.

Mounting BTRFS subvolumes So how did I even get to that point? I have this in my /etc/fstab, on the Debian side of things:
UUID=5abb9def-c725-44ef-a45e-d72657803f37   /srv    btrfs  defaults 0   2
This thankfully ignores all the subvolume nonsense because it relies on the UUID. mount tells me that's actually the "root" (? /?) subvolume:
root@curie:/home/anarcat# mount   grep /srv
/dev/mapper/fedora_crypt on /srv type btrfs (rw,relatime,space_cache,subvolid=5,subvol=/)
Let's see if I can mount the other volumes I have on there. Remember that subvolume list showed I had home, root, and var/lib/machines. Let's try root:
mount -o subvol=root /dev/mapper/fedora_crypt /mnt
Interestingly, root is not the same as /, it's a different subvolume! It seems to be the Fedora root (/, really) filesystem. No idea what is happening here. I also have a home subvolume, let's mount it too, for good measure:
mount -o subvol=home /dev/mapper/fedora_crypt /mnt/home
Note that lsblk doesn't notice those two new mountpoints, and that's normal: it only lists block devices and subvolumes (rather inconveniently, I'd say) do not show up as devices:
root@curie:/home/anarcat# lsblk 
NAME                   MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINT
sda                      8:0    0 931,5G  0 disk  
 sda1                   8:1    0   200M  0 part  
 sda2                   8:2    0     1G  0 part  
 sda3                   8:3    0   7,8G  0 part  
 sda4                   8:4    0 922,5G  0 part  
   fedora_crypt       253:4    0 922,5G  0 crypt /srv
This is really, really confusing. Maybe I did something wrong in the setup. Maybe it's because I'm mounting it from outside Fedora. Either way, it just doesn't feel right.

No disk usage per volume If you want to see what's taking up space in one of those subvolumes, tough luck:
root@curie:/home/anarcat# df -h  /srv /mnt /mnt/home
Filesystem                Size  Used Avail Use% Mounted on
/dev/mapper/fedora_crypt  923G  886G   31G  97% /srv
/dev/mapper/fedora_crypt  923G  886G   31G  97% /mnt
/dev/mapper/fedora_crypt  923G  886G   31G  97% /mnt/home
(Notice, in passing, that it looks like the same filesystem is mounted in different places. In that sense, you'd expect /srv and /mnt (and /mnt/home?!) to be exactly the same, but no: they are entirely different directory structures, which I will not call "filesystems" here because everyone's head will explode in sparks of confusion.) Yes, disk space is shared (that's the Size and Avail columns, makes sense). But nope, no cookie for you: they all have the same Used columns, so you need to actually walk the entire filesystem to figure out what each disk takes. (For future reference, that's basically:
root@curie:/home/anarcat# time du -schx /mnt/home /mnt /srv
124M    /mnt/home
7.5G    /mnt
875G    /srv
883G    total
real    2m49.080s
user    0m3.664s
sys 0m19.013s
And yes, that was painfully slow.) ZFS actually has some oddities in that regard, but at least it tells me how much disk each volume (and snapshot) takes:
root@tubman:~# time df -t zfs -h
Filesystem         Size  Used Avail Use% Mounted on
rpool/ROOT/debian  3.5T  1.4G  3.5T   1% /
rpool/var/tmp      3.5T  384K  3.5T   1% /var/tmp
rpool/var/spool    3.5T  256K  3.5T   1% /var/spool
rpool/var/log      3.5T  2.0G  3.5T   1% /var/log
rpool/home/root    3.5T  2.2G  3.5T   1% /root
rpool/home         3.5T  256K  3.5T   1% /home
rpool/srv          3.5T   80G  3.5T   3% /srv
rpool/var/cache    3.5T  114M  3.5T   1% /var/cache
bpool/BOOT/debian  571M   90M  481M  16% /boot
real    0m0.003s
user    0m0.002s
sys 0m0.000s
That's 56360 times faster, by the way. But yes, that's not fair: those in the know will know there's a different command to do what df does with BTRFS filesystems, the btrfs filesystem usage command:
root@curie:/home/anarcat# time btrfs filesystem usage /srv
Overall:
    Device size:         922.47GiB
    Device allocated:        916.47GiB
    Device unallocated:        6.00GiB
    Device missing:          0.00B
    Used:            884.97GiB
    Free (estimated):         30.84GiB  (min: 27.84GiB)
    Free (statfs, df):        30.84GiB
    Data ratio:               1.00
    Metadata ratio:           2.00
    Global reserve:      512.00MiB  (used: 0.00B)
    Multiple profiles:              no
Data,single: Size:906.45GiB, Used:881.61GiB (97.26%)
   /dev/mapper/fedora_crypt  906.45GiB
Metadata,DUP: Size:5.00GiB, Used:1.68GiB (33.58%)
   /dev/mapper/fedora_crypt   10.00GiB
System,DUP: Size:8.00MiB, Used:128.00KiB (1.56%)
   /dev/mapper/fedora_crypt   16.00MiB
Unallocated:
   /dev/mapper/fedora_crypt    6.00GiB
real    0m0,004s
user    0m0,000s
sys 0m0,004s
Almost as fast as ZFS's df! Good job. But wait. That doesn't actually tell me usage per subvolume. Notice it's filesystem usage, not subvolume usage, which unhelpfully refuses to exist. That command only shows that one "filesystem" internal statistics that are pretty opaque.. You can also appreciate that it's wasting 6GB of "unallocated" disk space there: I probably did something Very Wrong and should be punished by Hacker News. I also wonder why it has 1.68GB of "metadata" used... At this point, I just really want to throw that thing out of the window and restart from scratch. I don't really feel like learning the BTRFS internals, as they seem oblique and completely bizarre to me. It feels a little like the state of PHP now: it's actually pretty solid, but built upon so many layers of cruft that I still feel it corrupts my brain every time I have to deal with it (needle or haystack first? anyone?)...

Conclusion I find BTRFS utterly confusing and I'm worried about its reliability. I think a lot of work is needed on usability and coherence before I even consider running this anywhere else than a lab, and that's really too bad, because there are really nice features in BTRFS that would greatly help my workflow. (I want to use filesystem snapshots as high-performance, high frequency backups.) So now I'm experimenting with OpenZFS. It's so much simpler, just works, and it's rock solid. After this 8 minute read, I had a good understanding of how ZFS worked. Here's the 30 seconds overview:
  • vdev: a RAID array
  • vpool: a volume group of vdevs
  • datasets: normal filesystems (or block device, if you want to use another filesystem on top of ZFS)
There's also other special volumes like caches and logs that you can (really easily, compared to LVM caching) use to tweak your setup. You might also want to look at recordsize or ashift to tweak the filesystem to fit better your workload (or deal with drives lying about their sector size, I'm looking at you Samsung), but that's it. Running ZFS on Linux currently involves building kernel modules from scratch on every host, which I think is pretty bad. But I was able to setup a ZFS-only server using this excellent documentation without too much problem. I'm hoping some day the copyright issues are resolved and we can at least ship binary packages, but the politics (e.g. convincing Debian that is the right thing to do) and the logistics (e.g. DKMS auto-builders? is that even a thing? how about signed DKMS packages? fun-fun-fun!) seem really impractical. Who knows, maybe hell will freeze over (again) and Oracle will fix the CDDL. I personally think that we should just completely ignore this problem (which wasn't even supposed to be a problem) and ship binary packages directly, but I'm a pragmatic and do not always fit well with the free software fundamentalists. All of this to say that, short term, we don't have a reliable, advanced filesystem/logical disk manager in Linux. And that's really too bad.

10 May 2022

Melissa Wen: Multiple syncobjs support for V3D(V) (Part 2)

In the previous post, I described how we enable multiple syncobjs capabilities in the V3D kernel driver. Now I will tell you what was changed on the userspace side, where we reworked the V3DV sync mechanisms to use Vulkan multiple wait and signal semaphores directly. This change represents greater adherence to the Vulkan submission framework. I was not used to Vulkan concepts and the V3DV driver. Fortunately, I counted on the guidance of the Igalia s Graphics team, mainly Iago Toral (thanks!), to understand the Vulkan Graphics Pipeline, sync scopes, and submission order. Therefore, we changed the original V3DV implementation for vkQueueSubmit and all related functions to allow direct mapping of multiple semaphores from V3DV to the V3D-kernel interface. Disclaimer: Here s a brief and probably inaccurate background, which we ll go into more detail later on. In Vulkan, GPU work submissions are described as command buffers. These command buffers, with GPU jobs, are grouped in a command buffer submission batch, specified by vkSubmitInfo, and submitted to a queue for execution. vkQueueSubmit is the command called to submit command buffers to a queue. Besides command buffers, vkSubmitInfo also specifies semaphores to wait before starting the batch execution and semaphores to signal when all command buffers in the batch are complete. Moreover, a fence in vkQueueSubmit can be signaled when all command buffer batches have completed execution. From this sequence, we can see some implicit ordering guarantees. Submission order defines the start order of execution between command buffers, in other words, it is determined by the order in which pSubmits appear in VkQueueSubmit and pCommandBuffers appear in VkSubmitInfo. However, we don t have any completion guarantees for jobs submitted to different GPU queue, which means they may overlap and complete out of order. Of course, jobs submitted to the same GPU engine follow start and finish order. A fence is ordered after all semaphores signal operations for signal operation order. In addition to implicit sync, we also have some explicit sync resources, such as semaphores, fences, and events. Considering these implicit and explicit sync mechanisms, we rework the V3DV implementation of queue submissions to better use multiple syncobjs capabilities from the kernel. In this merge request, you can find this work: v3dv: add support to multiple wait and signal semaphores. In this blog post, we run through each scope of change of this merge request for a V3D driver-guided description of the multisync support implementation.

Groundwork and basic code clean-up: As the original V3D-kernel interface allowed only one semaphore, V3DV resorted to booleans to translate multiple semaphores into one. Consequently, if a command buffer batch had at least one semaphore, it needed to wait on all jobs submitted complete before starting its execution. So, instead of just boolean, we created and changed structs that store semaphores information to accept the actual list of wait semaphores.

Expose multisync kernel interface to the driver: In the two commits below, we basically updated the DRM V3D interface from that one defined in the kernel and verified if the multisync capability is available for use.

Handle multiple semaphores for all GPU job types: At this point, we were only changing the submission design to consider multiple wait semaphores. Before supporting multisync, V3DV was waiting for the last job submitted to be signaled when at least one wait semaphore was defined, even when serialization wasn t required. V3DV handle GPU jobs according to the GPU queue in which they are submitted:
  • Control List (CL) for binning and rendering
  • Texture Formatting Unit (TFU)
  • Compute Shader Dispatch (CSD)
Therefore, we changed their submission setup to do jobs submitted to any GPU queues able to handle more than one wait semaphores. These commits created all mechanisms to set arrays of wait and signal semaphores for GPU job submissions:
  • Checking the conditions to define the wait_stage.
  • Wrapping them in a multisync extension.
  • According to the kernel interface (described in the previous blog post), configure the generic extension as a multisync extension.
Finally, we extended the ability of GPU jobs to handle multiple signal semaphores, but at this point, no GPU job is actually in charge of signaling them. With this in place, we could rework part of the code that tracks CPU and GPU job completions by verifying the GPU status and threads spawned by Event jobs.

Rework the QueueWaitIdle mechanism to track the syncobj of the last job submitted in each queue: As we had only single in/out syncobj interfaces for semaphores, we used a single last_job_sync to synchronize job dependencies of the previous submission. Although the DRM scheduler guarantees the order of starting to execute a job in the same queue in the kernel space, the order of completion isn t predictable. On the other hand, we still needed to use syncobjs to follow job completion since we have event threads on the CPU side. Therefore, a more accurate implementation requires last_job syncobjs to track when each engine (CL, TFU, and CSD) is idle. We also needed to keep the driver working on previous versions of v3d kernel-driver with single semaphores, then we kept tracking ANY last_job_sync to preserve the previous implementation.

Rework synchronization and submission design to let the jobs handle wait and signal semaphores: With multiple semaphores support, the conditions for waiting and signaling semaphores changed accordingly to the particularities of each GPU job (CL, CSD, TFU) and CPU job restrictions (Events, CSD indirect, etc.). In this sense, we redesigned V3DV semaphores handling and job submissions for command buffer batches in vkQueueSubmit. We scrutinized possible scenarios for submitting command buffer batches to change the original implementation carefully. It resulted in three commits more: We keep track of whether we have submitted a job to each GPU queue (CSD, TFU, CL) and a CPU job for each command buffer. We use syncobjs to track the last job submitted to each GPU queue and a flag that indicates if this represents the beginning of a command buffer. The first GPU job submitted to a GPU queue in a command buffer should wait on wait semaphores. The first CPU job submitted in a command buffer should call v3dv_QueueWaitIdle() to do the waiting and ignore semaphores (because it is waiting for everything). If the job is not the first but has the serialize flag set, it should wait on the completion of all last job submitted to any GPU queue before running. In practice, it means using syncobjs to track the last job submitted by queue and add these syncobjs as job dependencies of this serialized job. If this job is the last job of a command buffer batch, it may be used to signal semaphores if this command buffer batch has only one type of GPU job (because we have guarantees of execution ordering). Otherwise, we emit a no-op job just to signal semaphores. It waits on the completion of all last jobs submitted to any GPU queue and then signal semaphores. Note: We changed this approach to correctly deal with ordering changes caused by event threads at some point. Whenever we have an event job in the command buffer, we cannot use the last job in the last command buffer assumption. We have to wait all event threads complete to signal After submitting all command buffers, we emit a no-op job to wait on all last jobs by queue completion and signal fence. Note: at some point, we changed this approach to correct deal with ordering changes caused by event threads, as mentioned before.

Final considerations With many changes and many rounds of reviews, the patchset was merged. After more validations and code review, we polished and fixed the implementation together with external contributions: Also, multisync capabilities enabled us to add new features to V3DV and switch the driver to the common synchronization and submission framework:
  • v3dv: expose support for semaphore imports
    This was waiting for multisync support in the v3d kernel, which is already available. Exposing this feature however enabled a few more CTS tests that exposed pre-existing bugs in the user-space driver so we fix those here before exposing the feature.
  • v3dv: Switch to the common submit framework
    This should give you emulated timeline semaphores for free and kernel-assisted sharable timeline semaphores for cheap once you have the kernel interface wired in.
We used a set of games to ensure no performance regression in the new implementation. For this, we used GFXReconstruct to capture Vulkan API calls when playing those games. Then, we compared results with and without multisync caps in the kernelspace and also enabling multisync on v3dv. We didn t observe any compromise in performance, but improvements when replaying scenes of vkQuake game.

Melissa Wen: Multiple syncobjs support for V3D(V) (Part 1)

As you may already know, we at Igalia have been working on several improvements to the 3D rendering drivers of Broadcom Videocore GPU, found in Raspberry Pi 4 devices. One of our recent works focused on improving V3D(V) drivers adherence to Vulkan submission and synchronization framework. We had to cross various layers from the Linux Graphics stack to add support for multiple syncobjs to V3D(V), from the Linux/DRM kernel to the Vulkan driver. We have delivered bug fixes, a generic gate to extend job submission interfaces, and a more direct sync mapping of the Vulkan framework. These changes did not impact the performance of the tested games and brought greater precision to the synchronization mechanisms. Ultimately, support for multiple syncobjs opened the door to new features and other improvements to the V3DV submission framework.

DRM Syncobjs But, first, what are DRM sync objs?
* DRM synchronization objects (syncobj, see struct &drm_syncobj) provide a
* container for a synchronization primitive which can be used by userspace
* to explicitly synchronize GPU commands, can be shared between userspace
* processes, and can be shared between different DRM drivers.
* Their primary use-case is to implement Vulkan fences and semaphores.
[...]
* At it's core, a syncobj is simply a wrapper around a pointer to a struct
* &dma_fence which may be NULL.
And Jason Ekstrand well-summarized dma_fence features in a talk at the Linux Plumbers Conference 2021:
A struct that represents a (potentially future) event:
  • Has a boolean signaled state
  • Has a bunch of useful utility helpers/concepts, such as refcount, callback wait mechanisms, etc.
Provides two guarantees:
  • One-shot: once signaled, it will be signaled forever
  • Finite-time: once exposed, is guaranteed signal in a reasonable amount of time

What does multiple semaphores support mean for Raspberry Pi 4 GPU drivers? For our main purpose, the multiple syncobjs support means that V3DV can submit jobs with more than one wait and signal semaphore. In the kernel space, wait semaphores become explicit job dependencies to wait on before executing the job. Signal semaphores (or post dependencies), in turn, work as fences to be signaled when the job completes its execution, unlocking following jobs that depend on its completion. The multisync support development comprised of many decision-making points and steps summarized as follow:
  • added to the v3d kernel-driver capabilities to handle multiple syncobj;
  • exposed multisync capabilities to the userspace through a generic extension; and
  • reworked synchronization mechanisms of the V3DV driver to benefit from this feature
  • enabled simulator to work with multiple semaphores
  • tested on Vulkan games to verify the correctness and possible performance enhancements.
We decided to refactor parts of the V3D(V) submission design in kernel-space and userspace during this development. We improved job scheduling on V3D-kernel and the V3DV job submission design. We also delivered more accurate synchronizing mechanisms and further updates in the Broadcom Vulkan driver running on Raspberry Pi 4. Therefore, we summarize here changes in the kernel space, describing the previous state of the driver, taking decisions, side improvements, and fixes.

From single to multiple binary in/out syncobjs: Initially, V3D was very limited in the numbers of syncobjs per job submission. V3D job interfaces (CL, CSD, and TFU) only supported one syncobj (in_sync) to be added as an execution dependency and one syncobj (out_sync) to be signaled when a submission completes. Except for CL submission, which accepts two in_syncs: one for binner and another for render job, it didn t change the limited options. Meanwhile in the userspace, the V3DV driver followed alternative paths to meet Vulkan s synchronization and submission framework. It needed to handle multiple wait and signal semaphores, but the V3D kernel-driver interface only accepts one in_sync and one out_sync. In short, V3DV had to fit multiple semaphores into one when submitting every GPU job.

Generic ioctl extension The first decision was how to extend the V3D interface to accept multiple in and out syncobjs. We could extend each ioctl with two entries of syncobj arrays and two entries for their counters. We could create new ioctls with multiple in/out syncobj. But after examining other drivers solutions to extend their submission s interface, we decided to extend V3D ioctls (v3d_cl_submit_ioctl, v3d_csd_submit_ioctl, v3d_tfu_submit_ioctl) by a generic ioctl extension. I found a curious commit message when I was examining how other developers handled the issue in the past:
Author: Chris Wilson <chris@chris-wilson.co.uk>
Date:   Fri Mar 22 09:23:22 2019 +0000
    drm/i915: Introduce the i915_user_extension_method
    
    An idea for extending uABI inspired by Vulkan's extension chains.
    Instead of expanding the data struct for each ioctl every time we need
    to add a new feature, define an extension chain instead. As we add
    optional interfaces to control the ioctl, we define a new extension
    struct that can be linked into the ioctl data only when required by the
    user. The key advantage being able to ignore large control structs for
    optional interfaces/extensions, while being able to process them in a
    consistent manner.
    
    In comparison to other extensible ioctls, the key difference is the
    use of a linked chain of extension structs vs an array of tagged
    pointers. For example,
    
    struct drm_amdgpu_cs_chunk  
    	__u32		chunk_id;
        __u32		length_dw;
        __u64		chunk_data;
     ;
[...]
So, inspired by amdgpu_cs_chunk and i915_user_extension, we opted to extend the V3D interface through a generic interface. After applying some suggestions from Iago Toral (Igalia) and Daniel Vetter, we reached the following struct:
struct drm_v3d_extension  
	__u64 next;
	__u32 id;
#define DRM_V3D_EXT_ID_MULTI_SYNC		0x01
	__u32 flags; /* mbz */
 ;
This generic extension has an id to identify the feature/extension we are adding to an ioctl (that maps the related struct type), a pointer to the next extension, and flags (if needed). Whenever we need to extend the V3D interface again for another specific feature, we subclass this generic extension into the specific one instead of extending ioctls indefinitely.

Multisync extension For the multiple syncobjs extension, we define a multi_sync extension struct that subclasses the generic extension struct. It has arrays of in and out syncobjs, the respective number of elements in each of them, and a wait_stage value used in CL submissions to determine which job needs to wait for syncobjs before running.
struct drm_v3d_multi_sync  
	struct drm_v3d_extension base;
	/* Array of wait and signal semaphores */
	__u64 in_syncs;
	__u64 out_syncs;
	/* Number of entries */
	__u32 in_sync_count;
	__u32 out_sync_count;
	/* set the stage (v3d_queue) to sync */
	__u32 wait_stage;
	__u32 pad; /* mbz */
 ;
And if a multisync extension is defined, the V3D driver ignores the previous interface of single in/out syncobjs. Once we had the interface to support multiple in/out syncobjs, v3d kernel-driver needed to handle it. As V3D uses the DRM scheduler for job executions, changing from single syncobj to multiples is quite straightforward. V3D copies from userspace the in syncobjs and uses drm_syncobj_find_fence()+ drm_sched_job_add_dependency() to add all in_syncs (wait semaphores) as job dependencies, i.e. syncobjs to be checked by the scheduler before running the job. On CL submissions, we have the bin and render jobs, so V3D follows the value of wait_stage to determine which job depends on those in_syncs to start its execution. When V3D defines the last job in a submission, it replaces dma_fence of out_syncs with the done_fence from this last job. It uses drm_syncobj_find() + drm_syncobj_replace_fence() to do that. Therefore, when a job completes its execution and signals done_fence, all out_syncs are signaled too.

Other improvements to v3d kernel driver This work also made possible some improvements in the original implementation. Following Iago s suggestions, we refactored the job s initialization code to allocate memory and initialize a job in one go. With this, we started to clean up resources more cohesively, clearly distinguishing cleanups in case of failure from job completion. We also fixed the resource cleanup when a job is aborted before the DRM scheduler arms it - at that point, drm_sched_job_arm() had recently been introduced to job initialization. Finally, we prepared the semaphore interface to implement timeline syncobjs in the future.

Going Up The patchset that adds multiple syncobjs support and improvements to V3D is available here and comprises four patches:
  • drm/v3d: decouple adding job dependencies steps from job init
  • drm/v3d: alloc and init job in one shot
  • drm/v3d: add generic ioctl extension
  • drm/v3d: add multiple syncobjs support
After extending the V3D kernel interface to accept multiple syncobjs, we worked on V3DV to benefit from V3D multisync capabilities. In the next post, I will describe a little of this work.

9 May 2022

Robert McQueen: Evolving a strategy for 2022 and beyond

As a board, we have been working on several initiatives to make the Foundation a better asset for the GNOME Project. We re working on a number of threads in parallel, so I wanted to explain the big picture a bit more to try and connect together things like the new ED search and the bylaw changes. We re all here to see free and open source software succeed and thrive, so that people can be be truly empowered with agency over their technology, rather than being passive consumers. We want to bring GNOME to as many people as possible so that they have computing devices that they can inspect, trust, share and learn from. In previous years we ve tried to boost the relevance of GNOME (or technologies such as GTK) or solicit donations from businesses and individuals with existing engagement in FOSS ideology and technology. The problem with this approach is that we re mostly addressing people and organisations who are already supporting or contributing FOSS in some way. To truly scale our impact, we need to look to the outside world, build better awareness of GNOME outside of our current user base, and find opportunities to secure funding to invest back into the GNOME project. The Foundation supports the GNOME project with infrastructure, arranging conferences, sponsoring hackfests and travel, design work, legal support, managing sponsorships, advisory board, being the fiscal sponsor of GNOME, GTK, Flathub and we will keep doing all of these things. What we re talking about here are additional ways for the Foundation to support the GNOME project we want to go beyond these activities, and invest into GNOME to grow its adoption amongst people who need it. This has a cost, and that means in parallel with these initiatives, we need to find partners to fund this work. Neil has previously talked about themes such as education, advocacy, privacy, but we ve not previously translated these into clear specific initiatives that we would establish in addition to the Foundation s existing work. This is all a work in progress and we welcome any feedback from the community about refining these ideas, but here are the current strategic initiatives the board is working on. We ve been thinking about growing our community by encouraging and retaining diverse contributors, and addressing evolving computing needs which aren t currently well served on the desktop. Initiative 1. Welcoming newcomers. The community is already spending a lot of time welcoming newcomers and teaching them the best practices. Those activities are as time consuming as they are important, but currently a handful of individuals are running initiatives such as GSoC, Outreachy and outreach to Universities. These activities help bring diverse individuals and perspectives into the community, and helps them develop skills and experience of collaborating to create Open Source projects. We want to make those efforts more sustainable by finding sponsors for these activities. With funding, we can hire people to dedicate their time to operating these programs, including paid mentors and creating materials to support newcomers in future, such as developer documentation, examples and tutorials. This is the initiative that needs to be refined the most before we can turn it into something real. Initiative 2: Diverse and sustainable Linux app ecosystem. I spoke at the Linux App Summit about the work that GNOME and Endless has been supporting in Flathub, but this is an example of something which has a great overlap between commercial, technical and mission-based advantages. The key goal here is to improve the financial sustainability of participating in our community, which in turn has an impact on the diversity of who we can expect to afford to enter and remain in our community. We believe the existence of this is critically important for individual developers and contributors to unlock earning potential from our ecosystem, through donations or app sales. In turn, a healthy app ecosystem also improves the usefulness of the Linux desktop as a whole for potential users. We believe that we can build a case for commercial vendors in the space to join an advisory board alongside with GNOME, KDE, etc to input into the governance and contribute to the costs of growing Flathub. Initiative 3: Local-first applications for the GNOME desktop. This is what Thib has been starting to discuss on Discourse, in this thread. There are many different threats to free access to computing and information in today s world. The GNOME desktop and apps need to give users convenient and reliable access to technology which works similarly to the tools they already use everyday, but keeps them and their data safe from surveillance, censorship, filtering or just being completely cut off from the Internet. We believe that we can seek both philanthropic and grant funding for this work. It will make GNOME a more appealing and comprehensive offering for the many people who want to protect their privacy. The idea is that these initiatives all sit on the boundary between the GNOME community and the outside world. If the Foundation can grow and deliver these kinds of projects, we are reaching to new people, new contributors and new funding. These contributions and investments back into GNOME represent a true win-win for the newcomers and our existing community. (Originally posted to GNOME Discourse, please feel free to join the discussion there.)

Next.

Previous.