Search Results: "ana"

19 March 2022

Russell Coker: More About the Librem 5

I concluded my previous post about the Purism Librem 5 [1] with the phone working as a Debian/GNOME system with SSH access over the LAN. Before I published that post I managed to render it unbootable, making a new computer unbootable on the first day of owning it isn t uncommon for me. In this case I tried to get SE Linux running on it and changing the kernel commandline parameter security=apparmor to security=selinux caused it to fail the checksum on kernel parameters and halt the boot. That seems to require a fresh install, it seems possible that I could setup my Librem5 to boot a recovery image from a SD card in such situations but that doesn t seem to be well documented and I didn t have any important data to lose. If I do figure out how to recover data by booting from a micro SD card I ll document it. Here s the documentation for reflashing the phone [2], you have to use the --variant luks option for the flashing tool to have an encrypted root filesystem (should default to on to match the default shipping configuration). There is an option --skip-cleanup to allow you to use the same image multiple times, but that probably isn t useful. The image that is available for download today has the latest kernel update that I installed yesterday so it seems that they quickly update the image which makes it convenient to get the latest (dpkg is slow on low power ARM systems). Overall the flash tool is nicely written, does the download and install and instructs you how to get the phone in flashing mode. It is a minor annoyance that the battery has to be removed as part of the flashing process, I will probably end up flashing my phone more often than I want to take the back off the case. A mitigating factor is that the back is well designed and doesn t appear prone to having it s plastic tabs breaking off when removed (as has happened to several other phones I ve owned). The camera doesn t seem to work well at this time, all photos have an unusually low brightness. The audio recording also doesn t work well, speaking clearly into the phone results in quiet recordings. I updated the Debian Wiki page on Mobile devices [3] to include a link to a page about the Librem5 [4] and to also have a section about applications known to work well on mobile devices. Hopefully other people will make some additions to that as most programs in Debian don t work well on mobile devices so we need a list of known good applications as well as applications that can be easily changed to work well. One thing I ve started looking at is the code for the Geary MUA (the default MUA for the Librem5 and the only one in Debian I know to be suitable for a phone). It needs the Thunderbird style autoconfig and it needs the ability to select which IMAP folders to scan as a common practice is to have some large IMAP folders that aren t used on mobile devices. I believe that Android runs each app in a separate UID to prevent them from messing with each other. The configuration on a standard Linux system and on PureOS is to have all apps running with the same permissions, I think this needs to be improved both for phones and for regular Linux systems which will probably benefit more than phones do. I ll write another blog post about this.

18 March 2022

Bits from Debian: DebConf22 registration and call for proposals are open!

DebConf22 banner open registration Registration for DebConf22 is now open. The the 23rd edition of DebConf will take place from July 17th to 24th, 2022 at the Innovation and Training Park (ITP) in Prizren, Kosovo, and will be preceded by DebCamp, from July 10th to 16th. Along with the registration, the DebConf content team announced the call for proposals. Deadline to submit a proposal to be considered in the main schedule is April 15th, 2022 23:59:59 UTC (Friday). DebConf is an event open to everyone, no matter how you identify yourself or how others perceive you. We want to increase visibility of our diversity and work towards inclusion at Debian Project, drawing our attendees from people just starting their Debian journey, to seasoned Debian Developers or active contributors in different areas like packaging, translation, documentation, artwork, testing, specialized derivatives, user support and many other. In other words, all are welcome. To register for the event, log into the registration system and fill out the form. You will be able to edit and update your registration at any point. However, in order to help the organizers have a better estimate of how many people will attend the event, we would appreciate if you could access the system and confirm (or cancel) your participation in the conference as soon as you know if you will be able to come. The last day to confirm or cancel is July 1st, 2022 23:59:59 UTC. If you don't confirm or you register after this date, you can come to the DebConf22 but we cannot guarantee availability of accommodation, food and swag (t-shirt, bag, and so on). For more information about registration, please visit registration information. Submitting an event You can now submit an event proposal. Events are not limited to traditional presentations or informal sessions (BoFs): we welcome submissions of tutorials, performances, art installations, debates, or any other format of event that you think would be of interest to the Debian community. Regular sessions may either be 20 or 45 minutes long (including time for questions), other kinds of sessions (workshops, demos, lightning talks, and so on) could have different durations. Please choose the most suitable duration for your event and explain any special requests. In order to submit a talk, you will need to create an account on the website. We suggest that Debian Salsa account holders (including DDs and DMs) use their Salsa login when creating an account. However, this isn't required, as you can sign up with an e-mail address and password. Bursary for travel, accommodation and meals In an effort to widen the diversity of DebConf attendees, the Debian Project allocates a part of the financial resources obtained through sponsorships to pay for bursaries (travel, accommodation, and/or meals) for participants who request this support when they register. As resources are limited, we will examine the requests and decide who will receive the bursaries. They will be destined: Giving a talk, organizing an event or helping during DebConf22 is taken intoa account when deciding upon your bursary, so please mention them in your bursary application. For more information about bursaries, please visit applying for a bursary to DebConf. Attention: the registration for DebConf22 will be open until the conference starts, but the deadline to apply for bursaries using the registration form before May 1st, 2022 23:59:59 UTC. This deadline is necessary in order to the organizers use time to analyze the requests, and for successful applicants to prepare for the conference. DebConf would not be possible without the generous support of all our sponsors, especially our Platinum Sponsors Lenovo and Infomaniak. DebConf22 is accepting sponsors; if you are interested, or think you know of others who would be willing to help, please get in touch!

Enrico Zini: Context-dependent logger in Python

This is a common logging pattern in Python, to have loggers related to module names:
import logging
log = logging.getLogger(__name__)
class Bill:
    def load_bill(self, filename: str):
        log.info("%s: loading file", filename)
I often however find myself wanting to have loggers related to something context-dependent, like the kind of file that is being processed. For example, I'd like to log loading of bill loading when done by the expenses module, and not when done by the printing module. I came up with a little hack that keeps the same API as before, and allows to propagate a context dependent logger to the code called:
# Call this file log.py
from __future__ import annotations
import contextlib
import contextvars
import logging
_log: contextvars.ContextVar[logging.Logger] = contextvars.ContextVar('log', default=logging.getLogger())
@contextlib.contextmanager
def logger(name: str):
    """
    Set a default logger for the duration of this context manager
    """
    old = _log.set(logging.getLogger(name))
    try:
        yield
    finally:
        _log.reset(old)
def debug(*args, **kw):
    _log.get().debug(*args, **kw)
def info(*args, **kw):
    _log.get().info(*args, **kw)
def warning(*args, **kw):
    _log.get().warning(*args, **kw)
def error(*args, **kw):
    _log.get().error(*args, **kw)
And now I can do this:
from . import log
#  
    with log.logger("expenses"):
        bill = load_bill(filename)
# This code did not change!
class Bill:
    def load_bill(self, filename: str):
        log.info("%s: loading file", filename)

17 March 2022

Gunnar Wolf: Speaking about the OpenPGP WoT on LibrePlanet this Saturday

So, LibrePlanet, the FSF s conference, is coming! I much enjoyed attending this conference in person in March 2018. This year I submitted a talk again, and it got accepted of course, given the conference is still 100% online, I doubt I will be able to go 100% conference-mode (I hope to catch a couple of other talks, but well, we are all eager to go back to how things were before 2020!)

Anyway, what is my talk about? My talk is titled Current challenges for the OpenPGP keyserver network. Is there a way forward?. The abstract I submitted follows:
Many free projects use OpenPGP encryption or signatures for various important tasks, like defining membership, authenticating participation, asserting identity over a vote, etc. The Web-of-Trust upon which its operation is based is a model many of us hold dear, allowing for a decentralized way to assign trust to the identity of a given person. But both the Web-of-Trust model and the software that serves as a basis for the above mentioned uses are at risk due to attacks on the key distribution protocol (not on the software itself!) With this talk, I will try to bring awareness to this situation, to some possible mitigations, and present some proposals to allow for the decentralized model to continue to thrive towards the future.
I am on the third semester of my PhD, trying to somehow keep a decentralized infrastructure for the OpenPGP Web of Trust viable and usable for the future. While this is still in the early stages of my PhD work (and I still don t have a solution to present), I will talk about what the main problems are and will sketch out the path I intend to develop. What is the relevance? Mainly, I think, that many free software projects use the OpenPGP Web of Trust for their identity definitions Are we anachronistic? Are we using tools unfit for this century? I don t think so. I think we are in time to fix the main sore spots for this great example of a decentralized infrastructure.

When is my talk scheduled? This Saturday, 2022.03.19, at
GMT / UTC time
19:25 20:10
Conference schedule time (EDT/GMT-4)
15:25 16:10
Mexico City time (GMT-6)
13:25 14:10

How to watch it? The streams are open online. I will be talking in the Saturn room, feel free to just appear there and watch! The FSF asks people to [register for the conference](https://my.fsf.org/civicrm/event/info?reset=1&id=99) beforehand, in order to be able to have an active participation (i.e. ask questions and that). Of course, you might be interested in other talks take a look at the schedule! LibrePlanet keeps a video archive of their past conferences, and this talk will be linked from there. Of course, I will link to the recording once it is online. Update: As of 2022.03.30, LibrePlanet has posted the videos for all of their talks, all linked from the program. And of course, for convenience, I copied the talk over here: Current challenges for the OpenPGP keyserver network. Is there a way forward?

Dirk Eddelbuettel: Rcpp 1.0.8.3: Hotfixing Hotfix

rcpp logo An even newer hot-fix release 1.0.8.3 of Rcpp follows the 1.0.8.2 release of a few days ago and got to CRAN this morning. A Debian upload will follow shortly, and Windows and macOS binaries will appear at CRAN in the next few days. This release again breaks with the six-months cycle started with release 1.0.5 in July 2020. When we addressed the CRAN request in 1.0.8.2 we forgot to dial testing down to their desired level (as three-part release numbers do automagically for us, whereas four-part do not). This is now taken care of, along with the hot-fix that was in 1.0.8.2 already. Rcpp has become the most popular way of enhancing R with C or C++ code. Right now, around 2522 packages on CRAN depend on Rcpp for making analytical code go faster and further, along with 239 in BioConductor. The full list of details for these two interim releases (and hence all changes accumulated since the last regular release, 1.0.8 in January) follows.

Changes in Rcpp hotfix release version 1.0.8.3 (2022-03-14)
  • Changes in Rcpp API:
    • Accomodate C++98 compilation by adjusting attributes.cpp (Dirk in #1193 fixing #1192)
    • Accomodate newest compilers replacing deprecated std::unary_function and std::binary_function with std::function (Dirk in #1202 fixing #1201 and CRAN request)
  • Changes in Rcpp Documentation:
    • Adjust one overflowing column (Bill Denney in #1196 fixing #1195)
  • Changes in Rcpp Deployment:
    • Accomodate four digit version numbers in unit test (Dirk)
    • Do not run complete test suite to limit test time to CRAN preference (Dirk)

Thanks to my CRANberries, you can also look at a diff to the previous release. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. Bugs reports are welcome at the GitHub issue tracker as well (where one can also search among open or closed issues); questions are also welcome under rcpp tag at StackOverflow which also allows searching among the (currently) 2843 previous questions. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

12 March 2022

Dirk Eddelbuettel: Rcpp 1.0.8.2: Hotfix release per CRAN request

rcpp logo A new hot-fix release 1.0.8.2 of Rcpp just got to CRAN. It will also be uploaded to Debian shortly, and Windows and macOS binaries will appear at CRAN in the next few days. This release breaks with the six-months cycle started with release 1.0.5 in July 2020 as CRAN desired an update to silence nags from the newest clang version which turned a little loud over a feature deprecated in C++11 (namely std::unary_function() and std::binary_function()). This was easy to replace with std::function() which we did. The release also contains a minor bugfix relative to 1.0.8 and C++98 builds, and minor correction to one pdf vignette. The release was fully tested by us and CRAN as usual against all reverse dependencies. Rcpp has become the most popular way of enhancing R with C or C++ code. Right now, around 2519 packages on CRAN depend on Rcpp for making analytical code go faster and further, along with 239 in BioConductor. The full list of details for this interim release follows.

Changes in Rcpp hotfix release version 1.0.8.2 (2022-03-10)
  • Changes in Rcpp API:
    • Accomodate C++98 compilation by adjusting attributes.cpp (Dirk in #1193 fixing #1192)
    • Accomodate newest compilers replacing deprecated std::unary_function and std::binary_function with std::function (Dirk in #1202 fixing #1201 and CRAN request)
  • Changes in Rcpp Documentation:
    • Adjust one overflowing column (Bill Denney in #1196 fixing #1195)
  • Changes in Rcpp Deployment:
    • Accomodate four digit version numbers in unit test (Dirk)

Thanks to my CRANberries, you can also look at a diff to the previous release. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. Bugs reports are welcome at the GitHub issue tracker as well (where one can also search among open or closed issues); questions are also welcome under rcpp tag at StackOverflow which also allows searching among the (currently) 2843 previous questions. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

3 March 2022

Enrico Zini: Migrating from procmail to sieve

Anarcat's "procmail considered harmful" post convinced me to get my act together and finally migrate my venerable procmail based setup to sieve. My setup was nontrivial, so I migrated with an intermediate step in which sieve scripts would by default pipe everything to procmail, which allowed me to slowly move rules from procmailrc to sieve until nothing remained in procmailrc. Here's what I did. Literature review https://brokkr.net/2019/10/31/lets-do-dovecot-slowly-and-properly-part-3-lmtp/ has a guide quite aligned with current Debian, and could be a starting point to get an idea of the work to do. https://wiki.dovecot.org/HowTo/PostfixDovecotLMTP is way more terse, but more aligned with my intentions. Reading the former helped me in understanding the latter. https://datatracker.ietf.org/doc/html/rfc5228 has the full Sieve syntax. https://doc.dovecot.org/configuration_manual/sieve/pigeonhole_sieve_interpreter/ has the list of Sieve features supported by Dovecot. https://doc.dovecot.org/settings/pigeonhole/ has the reference on Dovecot's sieve implementation. https://raw.githubusercontent.com/dovecot/pigeonhole/master/doc/rfc/spec-bosch-sieve-extprograms.txt is the hard to find full reference for the functions introduced by the extprograms plugin. Debugging tools: Backup of all mails processed One thing I did with procmail was to generate a monthly mailbox with all incoming email, with something like this:
BACKUP="/srv/backupts/test- date +%Y-%m-d .mbox"
:0c
$BACKUP
I did not find an obvious way in sieve to create montly mailboxes, so I redesigned that system using Postfix's always_bcc feature, piping everything to an archive user. I'll then recreate the monthly archiving using a chewmail script that I can simply run via cron. Configure dovecot
apt install dovecot-sieve dovecot-lmtpd
I added this to the local dovecot configuration:
service lmtp  
  unix_listener /var/spool/postfix/private/dovecot-lmtp  
    user = postfix
    group = postfix
    mode = 0666
   
 
protocol lmtp  
  mail_plugins = $mail_plugins sieve
 
plugin  
  sieve = file:~/.sieve;active=~/.dovecot.sieve
 
This makes Dovecot ready to receive mail from Postfix via a lmtp unix socket created in Postfix's private chroot. It also activates the sieve plugin, and uses ~/.sieve as a sieve script. The script can be a file or a directory; if it is a directory, ~/.dovecot.sieve will be a symlink pointing to the .sieve file to run. This is a feature I'm not yet using, but if one day I want to try enabling UIs to edit sieve scripts, that part is ready. Delegate to procmail To make sieve scripts that delegate to procmail, I enabled the sieve_extprograms plugin:
 plugin  
   sieve = file:~/.sieve;active=~/.dovecot.sieve
+  sieve_plugins = sieve_extprograms
+  sieve_extensions +vnd.dovecot.pipe
+  sieve_pipe_bin_dir = /usr/local/lib/dovecot/sieve-pipe
+  sieve_trace_dir = ~/.sieve-trace
+  sieve_trace_level = matching
+  sieve_trace_debug = yes
  
and then created a script for it:
mkdir -p /usr/local/lib/dovecot/sieve-pipe/
(echo "#!/bin/sh'; echo "exec /usr/bin/procmail") > /usr/local/lib/dovecot/sieve-pipe/procmail
chmod 0755 /usr/local/lib/dovecot/sieve-pipe/procmail
And I can have a sieve script that delegates processing to procmail:
require "vnd.dovecot.pipe";
pipe "procmail";
Activate the postfix side These changes switched local delivery over to Dovecot:
--- a/roles/mailserver/templates/dovecot.conf
+++ b/roles/mailserver/templates/dovecot.conf
@@ -25,6 +25,8 @@
 
+auth_username_format = %Ln
+
 
diff --git a/roles/mailserver/templates/main.cf b/roles/mailserver/templates/main.cf
index d2c515a..d35537c 100644
--- a/roles/mailserver/templates/main.cf
+++ b/roles/mailserver/templates/main.cf
@@ -64,8 +64,7 @@ virtual_alias_domains =
 
-mailbox_command = procmail -a "$EXTENSION"
-mailbox_size_limit = 0
+mailbox_transport = lmtp:unix:private/dovecot-lmtp
 
Without auth_username_format = %Ln dovecot won't be able to understand usernames sent by postfix in my specific setup. Moving rules over to sieve This is mostly straightforward, with the luxury of being able to do it a bit at a time. The last tricky bit was how to call spamc from sieve, as in some situations I reduce system load by running the spamfilter only on a prefiltered selection of incoming emails. For this I enabled the filter directive in sieve:
 plugin  
   sieve = file:~/.sieve;active=~/.dovecot.sieve
   sieve_plugins = sieve_extprograms
-  sieve_extensions +vnd.dovecot.pipe
+  sieve_extensions +vnd.dovecot.pipe +vnd.dovecot.filter
   sieve_pipe_bin_dir = /usr/local/lib/dovecot/sieve-pipe
+  sieve_filter_bin_dir = /usr/local/lib/dovecot/sieve-filter
   sieve_trace_dir = ~/.sieve-trace
   sieve_trace_level = matching
   sieve_trace_debug = yes
  
Then I created a filter script:
mkdir -p /usr/local/lib/dovecot/sieve-filter/"
(echo "#!/bin/sh'; echo "exec /usr/bin/spamc") > /usr/local/lib/dovecot/sieve-filter/spamc
chmod 0755 /usr/local/lib/dovecot/sieve-filter/spamc
And now what was previously:
:0 fw
  /usr/bin/spamc
:0
* ^X-Spam-Status: Yes
.spam/
Can become:
require "vnd.dovecot.filter";
require "fileinto";
filter "spamc";
if header :contains "x-spam-level" "**************"  
    discard;
  elsif header :matches "X-Spam-Status" "Yes,*"  
    fileinto "spam";
 
Updates Ansgar mentioned that it's possible to replicate the monthly mailbox using the variables and date extensions, with a hacky trick from the extensions' RFC:
require "date"
require "variables"
if currentdate :matches "month" "*"   set "month" "$ 1 ";  
if currentdate :matches "year" "*"   set "year" "$ 1 ";  
fileinto :create "$ month -$ year ";

Jamie McClelland: LVM Cache Surprises

By far the biggest LVM Cache surprise is just how well it works. Between 2010 and 2020, my single, biggest and most consistent headache managing servers at May First has been disk i/o. We run a number of physical hosts with encrypted disks, with each providing a dozen or so sundry KVM guests. And they consume a lot of disk i/o. This problem kept me awake at night and made me want to put my head on the table and cry during the day as I monitored the output of vmstat 1 and watched each disk i/o death spiral unfold. We tried everything. Turned off fsck s, turned off RAID monthly checks. Switched to less intensive backup systems. Added solid state drives and tried to stragically distribute them to our database partitions and other read/write heavy services. Added tmpfs file systems where it was possible. But, the sad truth was: we simply did not have the resources to pay for the infrastructure that could support the disk i/o our services demanded. Then, we discovered LVM caching (cue Hallelujah). We starting provisioning SSD partitions to back up our busiest spinning disk logical volumes and presto. Ten years of agony gone like a poof of smoke! I don t know which individuals are responsible for writing the LVM caching code but if you see this: THANK YOU! Your contributions to the world are noticed, appreciated and have had an enormous impact on at least one individual.

Some surprises

Filters For the last two years, with the exception of one little heart attack, LVM caches have gone very smoothly. Then, last week we upgraded 13 physical servers straight through from stretch to bullseye. It went relatively smoothly for the first half of our servers (the old ones hosting fewer resources). But, after rebooting our first server with lvm caching going on, we noticed that the cached disk wasn t accessible. No problem, we reasoned. We ll just uncache it. Except that didn t work either. We tried every argument we could find on the Internet but lvm insisted that the block device from the SSD volume group (that provides the caching device) was not available. Running pvs showed an unknown device and vgs reported similar errors. Now I started to panic a bit. There was a clean shutdown of the server, so surely all the data had been flushed to the disk. But, how can we get that data? We started a restore from backup process because we really thought that data was gone for ever. Then we had a really great theory: the caching logical volume comes from the SSD volume group, which gets decrypted after the spinning disk volume group. Maybe there s a timing issue? When the spinning disk volume group comes online, the caching logical volume is not yet available. So, we booted into busybox, and manually decrypted the SSD volume first, followed by the spinning disk volume. Alas, no dice. Now that we were fully desperate, we decided to restore the lvm configuration file for the entire spinning disk volume group. This felt kinda risky since we might be damaging all the currently working logical volumes, but it seemed like the only option we had. The main problem was that busybox didn t seem to have the lvm config tool we needed to restore the configuration from our backup (I think it might be there but it was late and we couldn t figure it out). And, our only readily available live install media was a Debian stretch disk via debirf. Debian stretch is pretty old and we really would have preferred to have the most modern tools available, but we decided to go with what we had. And, that was a good thing, because as soon as we booted into stretch and decrypted the disks, the lvm volume suddenly appeared, happy as ever. We uncached it and booted into the host system and there it was. We went to bed confused but relieved. The next morning my co-worker figured it out: filtering. During the stretch days we occassionally ran into an annoying problem: the logical volumes from guests would suddenly pop up on the host. This was mostly annoying but also it made possible some serious mistakes if you accidentally took a volume from a guest and used it on the host. The LVM folks seemed to have noticed this problem and introduced a new default filter that tries to only show you the devices that you should be seeing. Unfortunately for us, this new filter removed logical volumes from the list of available physical volumes. That does make sense for most people. But, not for us. It sounds a bit weird, but our setup looks like this:
  • One volume group derived from the spinning disks
  • One volume group derived from the SSD disks
Then we carve out logical volumes from each for each guest. Once we discovered LVM caching, we carved out SSD logical volumes to be used as caches for the spinning logical volumes. In restrospect, if we could start over, we would probably do it differently. In any event, once we discovered the problem, we used the handy configuration options in lvm.conf to tweak the filters to include our cache disks and once again, everything is back to working.

Saturated SSDs The other surprise seems unrelated to the upgrade. We have a phsyical server that has been suffering from disk i/o problems despite our use of LVM caching. Our answer, of course, was to add more LVM caches to the spinning logical volumes that seemed to be suffering. But somehow this was making things even worse. Then, we finally just removed the LVM caches from all the spinning disks and presto, disk i/o problems seemed to go away. What? Isn t that the opposite of what s supposed to happen? We re still trying to figure this one out, but it seems that our SSDs are saturated, in which case adding them as a caching volume really is going to make things worse. We re still not sure why they are saturated when none of the SSDs on our other hosts are saturated, but a few theories include:
  • They are doing more writing and/or it s a different kind of writing. I m still not sure I quite have the right tool to compare this host with other hosts. And, this host is our only MySQL network database server, hosting hundreds of GBs of database - all writing/reading direclty onto the SSDs.
  • They are broken or substanard SSDs (smartctl doesn t uncover any problems but maybe it s a bad model?)
I ll update this post as we learn more but welcome any suggestions in the comments. Update: 2022-03-07 Two more possible causes:
  • Our use of the write back feature: LVM cache has a nice feature that caches writes to smooth out writes to the underlying disk. Maybe our disks are simply writing more then can be handled and not using write back is our solution. This server supports a guest with an unusually large disk.
  • Maybe we haven t allocated a big enough LVM cache for the given volume so the contents are constantly being ejected?

2 March 2022

Antoine Beaupr : procmail considered harmful

TL;DR: procmail is a security liability and has been abandoned upstream for the last two decades. If you are still using it, you should probably drop everything and at least remove its SUID flag. There are plenty of alternatives to chose from, and conversion is a one-time, acceptable trade-off.

Procmail is unmaintained procmail is unmaintained. The "Final release", according to Wikipedia, dates back to September 10, 2001 (3.22). That release was shipped in Debian since then, all the way back from Debian 3.0 "woody", twenty years ago. Debian also ships 25 uploads on top of this, with 3.22-21 shipping the "3.23pre" release that has been rumored since at least the November 2001, according to debian/changelog at least:
procmail (3.22-1) unstable; urgency=low
  * New upstream release, which uses the  standard' format for Maildir
    filenames and retries on name collision. It also contains some
    bug fixes from the 3.23pre snapshot dated 2001-09-13.
  * Removed  sendmail' from the Recommends field, since we already
    have  exim' (the default Debian MTA) and  mail-transport-agent'.
  * Removed suidmanager support. Conflicts: suidmanager (<< 0.50).
  * Added support for DEB_BUILD_OPTIONS in the source package.
  * README.Maildir: Do not use locking on the example recipe,
    since it's wrong to do so in this case.
 -- Santiago Vila <sanvila@debian.org>  Wed, 21 Nov 2001 09:40:20 +0100
All Debian suites from buster onwards ship the 3.22-26 release, although the maintainer just pushed a 3.22-27 release to fix a seven year old null pointer dereference, after this article was drafted. Procmail is also shipped in all major distributions: Fedora and its derivatives, Debian derivatives, Gentoo, Arch, FreeBSD, OpenBSD. We all seem to be ignoring this problem. The upstream website (http://procmail.org/) has been down since about 2015, according to Debian bug #805864, with no change since. In effect, every distribution is currently maintaining its fork of this dead program. Note that, after filing a bug to keep Debian from shipping procmail in a stable release again, I was told that the Debian maintainer is apparently in contact with the upstream. And, surprise! they still plan to release that fabled 3.23 release, which has been now in "pre-release" for all those twenty years. In fact, it turns out that 3.23 is considered released already, and that the procmail author actually pushed a 3.24 release, codenamed "Two decades of fixes". That amounts to 25 commits since 3.23pre some of which address serious security issues, but none of which address fundamental issues with the code base.

Procmail is insecure By default, procmail is installed SUID root:mail in Debian. There's no debconf or pre-seed setting that can change this. There has been two bug reports against the Debian to make this configurable (298058, 264011), but both were closed to say that, basically, you should use dpkg-statoverride to change the permissions on the binary. So if anything, you should immediately run this command on any host that you have procmail installed on:
dpkg-statoverride --update --add root root 0755 /usr/bin/procmail
Note that this might break email delivery. It might also not work at all, thanks to usrmerge. Not sure. Yes, everything is on fire. This is fine. In my opinion, even assuming we keep procmail in Debian, that default should be reversed. It should be up to people installing procmail to assign it those dangerous permissions, after careful consideration of the risk involved. The last maintainer of procmail explicitly advised us (in that null pointer dereference bug) and other projects (e.g. OpenBSD, in [2]) to stop shipping it, back in 2014. Quote:
Executive summary: delete the procmail port; the code is not safe and should not be used as a basis for any further work.
I just read some of the code again this morning, after the original author claimed that procmail was active again. It's still littered with bizarre macros like:
#define bit_set(name,which,value) \
  (value?(name[bit_index(which)] =bit_mask(which)):\
  (name[bit_index(which)]&=~bit_mask(which)))
... from regexp.c, line 66 (yes, that's a custom regex engine). Or this one:
#define jj  (aleps.au.sopc)
It uses insecure functions like strcpy extensively. malloc() is thrown around gotos like it's 1984 all over again. (To be fair, it has been feeling like 1984 a lot lately, but that's another matter entirely.) That null pointer deref bug? It's fixed upstream now, in this commit merged a few hours ago, which I presume might be in response to my request to remove procmail from Debian. So while that's nice, this is the just tip of the iceberg. I speculate that one could easily find an exploitable crash in procmail if only by running it through a fuzzer. But I don't need to speculate: procmail had, for years, serious security issues that could possibly lead to root privilege escalation, remotely exploitable if procmail is (as it's designed to do) exposed to the network. Maybe I'm overreacting. Maybe the procmail author will go through the code base and do a proper rewrite. But I don't think that's what is in the cards right now. What I expect will happen next is that people will start fuzzing procmail, throw an uncountable number of bug reports at it which will get fixed in a trickle while never fixing the underlying, serious design flaws behind procmail.

Procmail has better alternatives The reason this is so frustrating is that there are plenty of modern alternatives to procmail which do not suffer from those problems. Alternatives to procmail(1) itself are typically part of mail servers. For example, Dovecot has its own LDA which implements the standard Sieve language (RFC 5228). (Interestingly, Sieve was published as RFC 3028 in 2001, before procmail was formally abandoned.) Courier also has "maildrop" which has its own filtering mechanism, and there is fdm (2007) which is a fetchmail and procmail replacement. Update: there's also mailprocessing, which is not an LDA, but processing an existing folder. It was, however, specifically designed to replace complex Procmail rules. But procmail, of course, doesn't just ship procmail; that would just be too easy. It ships mailstat(1) which we could probably ignore because it only parses procmail log files. But more importantly, it also ships:
  • lockfile(1) - conditional semaphore-file creator
  • formail(1) - mail (re)formatter
lockfile(1) already has a somewhat acceptable replacement in the form of flock(1), part of util-linux (which is Essential, so installed on any normal Debian system). It might not be a direct drop-in replacement, but it should be close enough. formail(1) is similar: the courier maildrop package ships reformail(1) which is, presumably, a rewrite of formail. It's unclear if it's a drop-in replacement, but it should probably possible to port uses of formail to it easily.
Update: the maildrop package ships a SUID root binary (two, even). So if you want only reformail(1), you might want to disable that with:
dpkg-statoverride --update --add root root 0755 /usr/bin/lockmail.maildrop 
dpkg-statoverride --update --add root root 0755 /usr/bin/maildrop
It would be perhaps better to have reformail(1) as a separate package, see bug 1006903 for that discussion.
The real challenge is, of course, migrating those old .procmailrc recipes to Sieve (basically). I added a few examples in the appendix below. You might notice the Sieve examples are easier to read, which is a nice added bonus.

Conclusion There is really, absolutely, no reason to keep procmail in Debian, nor should it be used anywhere at this point. It's a great part of our computing history. May it be kept forever in our museums and historical archives, but not in Debian, and certainly not in actual release. It's just a bomb waiting to go off. It is irresponsible for distributions to keep shipping obsolete and insecure software like this for unsuspecting users. Note that I am grateful to the author, I really am: I used procmail for decades and it served me well. But now, it's time to move, not bring it back from the dead.

Appendix

Previous work It's really weird to have to write this blog post. Back in 2016, I rebuilt my mail setup at home and, to my horror, discovered that procmail had been abandoned for 15 years at that point, thanks to that LWN article from 2010. I would have thought that I was the only weirdo still running procmail after all those years and felt kind of embarrassed to only "now" switch to the more modern (and, honestly, awesome) Sieve language. But no. Since then, Debian shipped three major releases (stretch, buster, and bullseye), all with the same vulnerable procmail release. Then, in early 2022, I found that, at work, we actually had procmail installed everywhere, possibly because userdir-ldap was using it for lockfile until 2019. I sent a patch to fix that and scrambled to remove get rid of procmail everywhere. That took about a day. But many other sites are now in that situation, possibly not imagining they have this glaring security hole in their infrastructure.

Procmail to Sieve recipes I'll collect a few Sieve equivalents to procmail recipes here. If you have any additions, do contact me. All Sieve examples below assume you drop the file in ~/.dovecot.sieve.

deliver mail to "plus" extension folder Say you want to deliver user+foo@example.com to the folder foo. You might write something like this in procmail:
MAILDIR=$HOME/Maildir/
DEFAULT=$MAILDIR
LOGFILE=$HOME/.procmail.log
VERBOSE=off
EXTENSION=$1            # Need to rename it - ?? does not like $1 nor 1
:0
* EXTENSION ?? [a-zA-Z0-9]+
        .$EXTENSION/
That, in sieve language, would be:
require ["variables", "envelope", "fileinto", "subaddress"];
########################################################################
# wildcard +extension
# https://doc.dovecot.org/configuration_manual/sieve/examples/#plus-addressed-mail-filtering
if envelope :matches :detail "to" "*"  
  # Save name in $ name  in all lowercase
  set :lower "name" "$ 1 ";
  fileinto "$ name ";
  stop;
 

Subject into folder This would file all mails with a Subject: line having FreshPorts in it into the freshports folder, and mails from alternc.org mailing lists into the alternc folder:
:0
## mailing list freshports
* ^Subject.*FreshPorts.*
.freshports/
:0
## mailing list alternc
* ^List-Post.*mailto:.*@alternc.org.*
.alternc/
Equivalent Sieve:
if header :contains "subject" "FreshPorts"  
    fileinto "freshports";
  elsif header :contains "List-Id" "alternc.org"  
    fileinto "alternc";
 

Mail sent to root to a reports folder This double rule:
:0
* ^Subject: Cron
* ^From: .*root@
.rapports/
Would look something like this in Sieve:
if header :comparator "i;octet" :contains "Subject" "Cron"  
  if header :regex :comparator "i;octet"  "From" ".*root@"  
        fileinto "rapports";
   
 
Note that this is what the automated converted does (below). It's not very readable, but it works.

Bulk email I didn't have an equivalent of this in procmail, but that's something I did in Sieve:
if header :contains "Precedence" "bulk"  
    fileinto "bulk";
 

Any mailing list This is another rule I didn't have in procmail but I found handy and easy to do in Sieve:
if exists "List-Id"  
    fileinto "lists";
 

This or that I wouldn't remember how to do this in procmail either, but that's an easy one in Sieve:
if anyof (header :contains "from" "example.com",
           header :contains ["to", "cc"] "anarcat@example.com")  
    fileinto "example";
 
You can even pile up a bunch of options together to have one big rule with multiple patterns:
if anyof (exists "X-Cron-Env",
          header :contains ["subject"] ["security run output",
                                        "monthly run output",
                                        "daily run output",
                                        "weekly run output",
                                        "Debian Package Updates",
                                        "Debian package update",
                                        "daily mail stats",
                                        "Anacron job",
                                        "nagios",
                                        "changes report",
                                        "run output",
                                        "[Systraq]",
                                        "Undelivered mail",
                                        "Postfix SMTP server: errors from",
                                        "backupninja",
                                        "DenyHosts report",
                                        "Debian security status",
                                        "apt-listchanges"
                                        ],
           header :contains "Auto-Submitted" "auto-generated",
           envelope :contains "from" ["nagios@",
                                      "logcheck@",
                                      "root@"])
     
    fileinto "rapports";
 

Automated script There is a procmail2sieve.pl script floating around, and mentioned in the dovecot documentation. It didn't work very well for me: I could use it for small things, but I mostly wrote the sieve file from scratch.

Progressive migration Enrico Zini has progressively migrated his procmail setup to Sieve using a clever way: he hooked procmail inside sieve so that he could deliver to the Dovecot LDA and progressively migrate rules one by one, without having a "flag day". See this explanatory blog post for the details, which also shows how to configure Dovecot as an LMTP server with Postfix.

Other examples The Dovecot sieve examples are numerous and also quite useful. At the time of writing, they include virus scanning and spam filtering, vacation auto-replies, includes, archival, and flags.

Harmful considered harmful I am aware that the "considered harmful" title has a long and controversial history, being considered harmful in itself (by some people who are obviously not afraid of contradictions). I have nevertheless deliberately chosen that title, partly to make sure this article gets maximum visibility, but more specifically because I do not have doubts at this moment that procmail is, clearly, a bad idea at this moment in history.

Developing story I must also add that, incredibly, this story has changed while writing it. This article is derived from this bug I filed in Debian to, quite frankly, kick procmail out of Debian. But filing the bug had the interesting effect of pushing the upstream into action: as mentioned above, they have apparently made a new release and merged a bunch of patches in a new git repository. This doesn't change much of the above, at this moment. If anything significant comes out of this effort, I will try to update this article to reflect the situation. I am actually happy to retract the claims in this article if it turns out that procmail is a stellar example of defensive programming and survives fuzzing attacks. But at this moment, I'm pretty confident that will not happen, at least not in scope of the next Debian release cycle.

1 March 2022

Paul Wise: FLOSS Activities February 2022

Focus This month I didn't have any particular focus. I just worked on issues in my info bubble.

Changes

Issues

Review

Administration
  • Debian BTS: fix usertags for some users, unarchive/reopen/triage bugs for reintroduced packages: horae dh-haskell shutter logging-tree openstreetmap-carto gnome-commander
  • Debian servers: restore wiki data from backup, restarted bacula director for TLS cert update
  • Debian wiki: restore wiki account from backup, approve accounts

Communication
  • Respond to queries from Debian users and contributors on the mailing lists and IRC

Sponsors The purple-discord, gensim, DiskANN, SPTAG, wsproto work was sponsored by my employer. All other work was done on a volunteer basis.

Abiola Ajadi: Career Interest!

Hi, Welcome back. In this blog, I will be discussing my career interests and what I plan to pursue after my internship.

What comes next after the internship After working a while with Debci project, I was able to learn better software development practices and love the open source community. I will love to build my career path around open-source.

What I am looking for Prior to starting my internship, I have worked as a front-end developer with react and javascript. During my internship with Debci I learn Ruby and also how to write tests . I am also passionate about community which is one of my core-values, I build and organize communities. I am looking for opportunities in areas of front-end development, Ruby, React. i am also open to opportunities in developer relations/community management where i can be part of building or managing a community, Interacting with developers, meeting new people. I am based in lagos, Nigeria and can work remotely, but also open to relocation. You can connect with me on linkedin

26 February 2022

Daniel Silverstone: Subplot and FOSDEM 2022 talk

As many of you may be aware, I work with Lars Wirzenius on a project we call Subplot which is a tool for writing documentation which helps all stakeholders involved with a proejct to understand how the project meets its requirements. At the start of February we had FOSDEM which was once again online, and I decided to give a talk in the Safety and open source devroom to introduce the concepts of safety argumentation and to bring some attention to how I feel that Subplot could be used in that arena. You can view the talk on the FOSDEM website at some point in the future when they manage to finish transcoding all the amazing talks from the weekend, or if you are more impatient, on Youtube, whichever you prefer. If, after watching the talk, or indeed just reading about Subplot on our website, you are interested in learning more about Subplot, or talking with us about how it might fit into your development flow, then you can find Lars and myself in the Subplot Matrix Room or else on any number of IRC networks where I hang around as kinnison.

24 February 2022

Charles Plessy: New media types in 2022

At the beginning of this year I updated a hundred of media types associated with file name extensions in the file called /etc/mime.types, distributed by the media-types package. Most changes are additions originating from recent submissions to the IANA. Amon the themes that caught my attention, there are telecommunications, computer security, commerce, healthcare and industrial automation. The vast majority of the update come from western provenance. Did the rest of the World decide to move ahead without us?

23 February 2022

Ian Jackson: Rooting an Eos Fairphone 4

Last week I received (finally) my Fairphone 4, supplied with a de-googled operating system, which I had ordered from the E Foundation s shop in December. (I m am very hard on hardware and my venerable Fairphone 2 is really on its last legs.) I expect to have full control over the software on any computing device I own which is as complicated, capable, and therefore, hazardous, as a mobile phone. Unfortunately the Eos image (they prefer to spell it /e/ os , srsly!) doesn t come with a way to get root without taking fairly serious measures including unlocking the bootloader. Unlocking the bootloader wouldn t be desirable for me but I can t live without root. So. I started with these helpful instructions: https://forum.xda-developers.com/t/fairphone-4-root.4376421/ I found the whole process a bit of a trial, and I thought I would write down what I did. But, it s not straightforward, at least for someone like me who only has a dim understanding of all this Android stuff. Unfortunately, due to the number of missteps and restarts, what I actually did is not really a sensible procedure. So here is a retcon of a process I think will work: Unlock the bootloader The E Foundation provide instructions for unlocking the bootloader on a stock FP4, here https://doc.e.foundation/devices/FP4/install and they seem applicable to the Murena phone supplied with Eos pre-installed, too. NB tht unlocking the bootloader wipes the phone. So we do it first. So:
  1. Power on the phone, with no SIM installed
  2. You get a welcome screen.
  3. Skip all things on startup including wifi
  4. Go to the very end of the settings, tap a gazillion times on the phone s version until you re a developer
  5. In the developer settings, allow usb debugging
  6. In the developer settings, allow oem bootloader unlocking
  7. Connect a computer via a USB cable, say yes on phone to USB debugging
  8. adb reboot bootloader
  9. The phone will reboot into a texty kind of screen, the bootloader
  10. fastboot flashing unlock
  11. The phone will reboot, back to the welcome screen
  12. Repeat steps 3-9 (maybe not all are necessary)
  13. fastboot flashing unlock_critical
  14. The phone will reboot, back to the welcome screen
Note that although you are running fastboot, you must run this command with the phone in bootloader mode, not fastboot (aka fastbootd ) mode. If you run fastboot flashing unlcok from fastboot you just get a don t know what you re talking about . I found conflicting instructions on what kind of Vulcan nerve pinches could be used to get into which boot modes, and had poor experiences with those. adb reboot bootloader always worked reliably for me. Some docs say to run fastboot oem unlock; I used flashing. Maybe this depends on the Android tools version. Initial privacy prep and OTA update We want to update the supplied phone OS. The build mine shipped with is too buggy to run Magisk, the application we are going to use to root the phone. (With the pre-installed phone OS, Magisk crashes at the patch boot image step.) But I didn t want to let the phone talk to Google, even for the push notifications registration.
  1. From the welcome screen, skip all things except location, date, time. Notably, do not set up wifi
  2. In settings, microg section
    1. turn off cloud messaging
    2. turn off google safetynet
    3. turn off google registration (NB you must do this after the other two, because their sliders become dysfunctional after you turn google registration off)
    4. turn off both location modules
  3. In settings, location section, turn off allowed location for browser and magic earth
  4. Now go into settings and enable wifi, giving it your wifi details
  5. Tell the phone to update its operating system. This is a big download.
Install Magisk, the root manager (As a starting point I used these instructions https://www.xda-developers.com/how-to-install-magisk/ and a lot of random forum posts.) You will need the official boot.img. Bizarrely there doesn t seem to be a way to obtain this from the phone. Instead, you must download it. You can find it by starting at https://doc.e.foundation/devices/FP4/install which links to https://images.ecloud.global/stable/FP4/. At the time of writing, the most recent version, whose version number seemed to correspond to the OS update I installed above, was IMG-e-0.21-r-20220123158735-stable-FP4.zip.
  1. Download the giant zipfile to your computer
  2. Unzip it to extract boot.img
  3. Copy the file to your phone s storage . Eg, via adb: with the phone booted into the main operating system, using USB debugging, adb push boot.img /storage/self/primary/Download.
  4. On the phone, open the browser, and enter https://f-droid.org. Click on the link to install f-droid. You will need to enable installing apps from the browser (follow the provided flow to the settings, change the setting, and then use Back, and you can do the install). If you wish, you can download the f-droid apk separately on a computer, and verify it with pgp.
  5. Using f-droid, install Magisk. You will need to enable installing apps from f-droid. (I installed Magisk from f-droid because 1. I was going to trust f-droid anyway 2. it has a shorter URL than Magisk s.)
  6. Open the Magisk app. Tell Magisk to install (Magisk, not the app). There will be only one option: patch boot file. Tell it to patch the boot.img file from before.
  7. Transfer the magisk_patched-THING.img back to your computer (eg via adb pull).
  8. adb reboot bootloader
  9. fastboot boot magisk_patched-THING.img (again, NB, from bootloader mode, not from fastboot mode)
  10. In Magisk you ll see it shows as installed. But it s not really; you ve just booted from an image with it. Ask to install Magisk with Direct install .
After you have done all this, I believe that each time you do an over-the-air OS update, you must, between installing the update and rebooting the phone, ask Magisk to Install to inactive slot (after OTA) . Presumably if you forget you must do the fastboot boot dance again. After all this, I was able to use tsu in Termux. There s a strange behaviour with the root prompt you get apropos Termux s request for root; I found that it definitely worked if Termux wasn t the foreground app You have to leave the bootloader unlocked. Howwever, as I understand it, the phone s encryption will still prevent an attacker from hoovering the data out of your phone. The bootloader lock is to prevent someone tricking you into entering the decryption passkey into a trojaned device. Other things to change There are probably other things to change. I have not yet transferred my Signal account from my old phone. It is possible that Signal will require me to re-enable the google push notifications, but I hope that having disabled them in microg it will be happy to use its own system, as it does on my old phone.

comment count unavailable comments

Jonathan McDowell: Upgrading my home internet; a story of yak shaving

RB5009 This has ended up longer than I expected. I ll write up posts about some of the individual steps with some more details at some point, but this is an overview of the yak shaving I engaged in. The TL;DR is:

The desire for a faster connection When I migrated my home connection to FTTP I kept the same 80M/20M profile I d had on FTTC. I didn t have a pressing need for faster, and I saved money because I was no longer paying for the phone line portion. I wanted more, but at the time I think the only option was for a 160M/30M profile instead and I didn t need it and it wasn t enough better to convince me. Time passed and BT rolled out their GigE (really 900M) download option. And again, I didn t need it, but I wanted it. My provider, Aquiss, initially didn t offer this (I think they had up to 330M download options available by this point). So I stayed on 80M/20M. And the only time I really wanted it to be faster was when pushing off-site backups to rsync.net. Of course, we ve had the pandemic, and that s involved 2 adults working from home with plenty of video calls throughout the day. The 80M/20M connection has proved rock solid for this, so again, I didn t feel an upgrade was justified. We got a 4K capable TV last year and while the bandwidth usage for 4K streaming is noticeably higher, again the connection can handle it no problem. At some point last year I noticed Aquiss had added speed options all the way to 900M down. At the end of the year I accepted a new role, which is fully remote, so I had a bit of an acceptance about the fact that I wasn t going back into an office any time soon. The combination (and the desire for the increased upload speed) finally allowed me to justify the upgrade to myself.

Testing the current setup for bottlenecks The first thing to do was see whether my internal network could cope with an upgrade. I m mostly running Cat6 GigE so I wasn t worried about that side of things. However I m using an RB3011 as my core router, and while it has some coprocessors for routing acceleration they re not supported under mainline Linux (and unlikely to be any time soon). So I had to benchmark what it was capable of routing. I run a handful of VLANs within my home network, with stateful firewalling between them, so I felt that would be a good approximation of the maximum speed to the outside world I might be able to get if I had the external connection upgraded. I went for the easy approach and fired up iPerf3 on 2 hosts, both connected via ethernet but on separate networks, so routed through the RB3011. That resulted in slightly more than a 300Mb/s throughput. Ok. I confirmed that I could get 900Mb/s+ on 2 hosts both on the same network, just to be sure there wasn t some other issue I was missing. Nope, so unsurprisingly the router was the bottleneck. So. To upgrade my internet speed I need to upgrade my router. I could just buy something off the shelf, but I like being able to run Debian (or OpenWRT) on the router rather than some horrible vendor firmware. Lucky MikroTik launched the RB5009 towards the end of last year. RouterOS is probably more than capable, but what really interested me was the fact it s an ARM64 platform based on an Armada 7040, which is pretty well supported in mainline kernels already. There s a 10G connection from the internal switch to the CPU, as well as a 2.5Gb/s ethernet port and a 10G SFP+ cage. All good stuff. I ordered one just before the New Year. Thankfully the OpenWRT folk had done all of the hard work on getting a mainline kernel booting on the device; Sergey Sergeev and Robert Marko in particular fighting RouterBoot and producing a suitable device tree file to get everything up and running. I ended up soldering a serial console connection up to aid debugging, and lightly patching Rob s u-boot to fix the incorrect RAM size reported by RouterBoot. A few kernel tweaks were necessary to make the networking entirely happy and at that point it was time to think about actually doing a replacement.

Upgrading to Debian 11 (bullseye) My RB3011 is currently running Debian 10 (buster); an upgrade has been on my todo list, but with the impending replacement I decided I d hold off and create a new Debian 11 (bullseye) image for the RB5009. Additionally, I don t actually run off the internal NAND in the RB3011; I have a USB flash drive for the rootfs and just the kernel booting off internal NAND. Originally this was for ease of testing, then a combination of needing to figure out a good read-only root solution and a small enough image to fit in the 120M available. For the upgrade I decided to finally look at these pieces. I ve ended up with a script that will build me a squashfs image, and the initial rootfs takes care of mounting this and then a tmpfs as an overlay fs. That means I can easily see what pieces are being written to. The RB5009 has a total of 1G NAND so I m not as space constrained, but the squashfs ends up under 50M. I ve added some additional pieces to allow me to pre-populate the overlay fs with updates rather than always needing to rebuild the squashfs image. With that done I decided to try it out on the RB3011; I tweaked the build script to be able to build for armhf (the RB3011) or arm64 (the RB5009) and to deal with some slight differences in configuration between the two (e.g. interface naming). The idea here was to ensure I d got all the appropriate configuration sorted for the RB5009, in the known-good existing environment. Everything is still on a USB stick at this stage and the new device has an armhf busybox root meaning it can be used on either device, and the init script detects the architecture to select the appropriate squashfs to mount.

A problem with ESP8266 home automation devices Everything seemed to work fine - a few niggles with the watchdog, which is overly sensitive on the RB3011, but I got those sorted (and the build script updated) and the device came up and successfully did the PPPoE dance to bring up external connectivity. And then I noticed that my home automation devices were having problems connecting to the mosquitto MQTT server. It turned out it was only the ESP8266 based devices that were failing, and examining the serial debug output on one of my test devices revealed it was hitting an out of memory issue (displaying E:M 280) when establishing the TLS MQTT connection. I rolled back to the Debian 10 image and set about creating a test environment to look at the ESP8266 issues. My first action was to try and reduce my RAM footprint to try and ensure there was enough spare to establish the connection. I moved a few functions that were still sitting in IRAM into flash. I cleaned up a couple of buffers that are on the stack to be more correctly sized. I tried my new image, and I didn t get the memory issue. Instead I progressed a bit further and got a watchdog reset. Doh! It was obviously something related to the TLS connection, but I couldn t easily see what the difference was; the same x509 cert was in use, it looked like the initial handshake was the same (and trying with openssl s_client looked pretty similar too). I set about instrumenting the ancient Mbed TLS used in the Espressif SDK and discovered that whatever had changed between buster + bullseye meant the EPS8266 was now trying a TLS-DHE-RSA-WITH-AES-256-CBC-SHA256 handshake instead of a TLS-RSA-WITH-AES-256-CBC-SHA256 handshake and that was causing enough extra CPU usage that it couldn t complete in time and the watchdog kicked in. So I commented out MBEDTLS_KEY_EXCHANGE_DHE_RSA_ENABLED in the config_esp.h for mbedtls and rebuilt things. Hacky, but I ll go back to trying to improve this generally at some point.

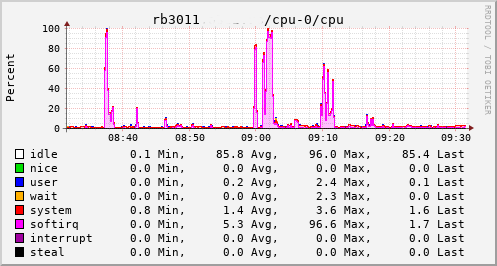
A detour into interrupt load Now, my testing of the RB3011 image is generally done at weekends, when I have enough time to tear down and rebuild the connection rather than doing it in the evening and having limited time to get things working again in time for work in the morning. So at the point I had an image ready to go I pulled the trigger on the line upgrade. I went with the 500M/75M option rather than the full 900M - I suspect I d have difficulty actually getting that most of the time and 75M of upload bandwidth seems fairly substantial for now. It only took a couple of days from the order to the point the line was regraded (which involved no real downtime - just a reconnection in the night). Of course this happened just after the weekend I d discovered the ESP8266 issue. collectd CPU usage for RB3011 This provided an opportunity to see just what the RB3011 could actually manage. In the configuration I had it turned out to be not much more than the 80Mb/s speeds I had previously seen. The upload jumped from a solid 20Mb/s to 75Mb/s, so I knew the regrade had actually happened. Looking at CPU utilisation clearly showed the problem; softirqs were using almost 100% of a CPU core. Now, the way the hardware is setup on the RB3011 is that there are two separate 5 port switches, each connected back to the CPU via a separate GigE interface. For various reasons I had everything on a single switch, which meant that all traffic was boomeranging in and out of the same CPU interface. The IPQ8064 has dual cores, so I thought I d try moving the external connection to the other switch. That puts it on its own GigE CPU interface, which then allows binding the interrupts to a different CPU core. That helps; throughput to the outside world hits 140Mb/s+. Still a long way from the expected max, but proof we just need more grunt.

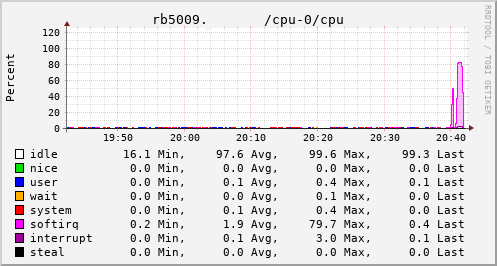
Success collectd CPU usage for RB5009 Which brings us to this past weekend, when, having worked out all the other bits, I tried the squashfs root image again on the RB3011. Success! The home automation bits connected to it, the link to the outside world came up, everything seemed happy. So I double checked my bootloader bits on the RB5009, brought it down to the comms room and plugged it in instead. And, modulo my failing to update the nftables config to allow it to do forwarding, it all came up ok. Some testing with iperf3 internally got a nice 912Mb/s sustained between subnets, and some less scientific testing with wget + speedtest-cli saw speeds of over 460Mb/s to the outside world. Time from ordering the router until it was in service? Just under 8 weeks

22 February 2022

Russ Allbery: Review: Children of Earth and Sky

Review: Children of Earth and Sky, by Guy Gavriel Kay
Publisher: New American Library
Copyright: 2016
ISBN: 0-698-18327-4
Format: Kindle
Pages: 572
Nine hundred years have passed since the events of Lord of Emperors. Twenty-five years ago, Sarantium, queen of cities, fell to the Osmanlis, who have renamed it Asharias in honor of their Asherite faith. The repercussions are still echoing through the western world, as the Osmanlis attempt each spring to push farther west and the forces of Rodolfo, Holy Emperor in Obravic and defender of the Jaddite faith, hold them back. Seressa and Dubrava are city-state republics built on the sea trade. Seressa is the larger and most renown, money-lenders to Rodolfo and notorious for their focus on business and profit, including willingness to trade with the Osmanlis. Dubrava has a more tenuous position: smaller, reliant on trade and other assistance from Seressa, but also holding a more-favored trading position with Asharias. Both are harassed by piracy from Senjan, a fiercely Jaddite raiding city north up the coast from Dubrava and renown for its bravery against the Asherites. The Senjani are bad for business. Seressa would love to wipe them out, but they have the favor of the Holy Emperor. They settled for attempting to starve the city with a blockade. As Children of Earth and Sky opens, Seressa is sending out new spies. One is a woman named Leonora Valeri, who will present herself as the wife of a doctor that Seressa is sending to Dubrava. She is neither his wife nor Seressani, but this assignment gets her out of the convent to which her noble father exiled her after an unapproved love affair. The other new spy is the young artist Pero Villani, a minor painter whose only notable work was destroyed by the woman who commissioned it for being too revealing. Pero's destination is farther east: Grand Khalif Gur u the Destroyer, the man whose forces took Sarantium, wants to be painted in the western style. Pero will do so, and observe all he can, and if the opportunity arises to do more than that, well, so much the better. Pero and Leonora are traveling on a ship owned by Marin Djivo, the younger son of a wealthy Dubravan merchant family, when their ship is captured by Senjani raiders. Among the raiders is Danica Gradek, the archer who broke the Seressani blockade of Senjan. This sort of piracy, while tense, should be an economic transaction: some theft, some bargaining, some ransom, and everyone goes on their way. That is not what happens. Moments later, two men lie dead, and Danica's life has become entangled with Dubravan merchants and Seressani spies. Children of Earth and Sky is in some sense a sequel to the Sarantine Mosaic, and knowing the events of that series adds some emotional depth and significant moments to this story, but you can easily read it as a stand-alone novel. (That said, I recommend the Sarantine Mosaic regardless.) As with nearly all of Kay's work, it's historical fiction with the names changed (less this time than in most of this books) and a bit of magic added. The setting is the middle of the 15th century. Seressa is, of course, Venice. The Osmanlis are the Ottoman Turks, and Asharias is Istanbul, the captured Constantinople. Rodolfo is a Habsburg Holy Roman Emperor, holding court in an amalgam of northern cities that (per the afterward) is primarily Prague. Dubrava, which is central to much of this book, is Dubrovnik in Croatia. As usual with Kay's novels, you don't need to know this to enjoy the story, but it may spark some fun secondary reading. The touch of magic is present in several places, but comes primarily from Danica, whose grandfather resides as a voice in her head. He is the last of her family that she is in contact with. Her father and older brother were killed by Osmanli raiders, and her younger brother taken as a slave to be raised as a djanni warrior in the khalif's infantry. (Djannis are akin to Mamluks in our world.) Damaz, as he is now known, is the remaining major viewpoint character I've not mentioned. There are a couple of key events in the book that have magic at the center, generally involving Danica or Damaz, but most of the story is straight historical fiction (albeit with significant divergences from our world). I'd talked myself out of starting this novel several times before I finally picked it up. Like most of Kay's, it's a long book, and I wasn't sure if I was in the mood for epic narration and a huge cast. And indeed, I found it slow at the start. Once the story got underway, though, I was as enthralled as always. There is a bit of sag in the middle of the book, in part because Kay didn't follow up on some relationships that I wish were more central to the plot and in part because he overdoes the narrative weight in one scene, but the ending is exceptional. Guy Gavriel Kay is the master of a specific type of omniscient tight third person narration, one in which the reader sees what a character is thinking but also gets narrative commentary, foreshadowing, and emotional emphasis apart from the character's thoughts. It can feel heavy-handed; if something is important, Kay tells you, explicitly and sometimes repetitively, and the foreshadowing frequently can be described as portentous. But in return, Kay gets fine control of pacing and emphasis. The narrative commentary functions like a soundtrack in a movie. It tells you when to pay close attention and when you can relax, what moments are important, where to slow down, when to brace yourself, and when you can speed up. That in turn requires trust; if you're not in the mood for the author to dictate your reading pace to the degree Kay is attempting, it can be irritating. If you are in the mood, though, it makes his novels easy to relax into. The narrator will ensure that you don't miss anything important, and it's an effective way to build tension. Kay also strikes just the right balance between showing multiple perspectives on a single moment and spending too much time retelling the same story. He will often switch viewpoint characters in the middle of a scene, but he avoids the trap of replaying the scene and thus losing the reader's interest. There is instead just a moment of doubled perspective or retrospective commentary, just enough information for the reader to extrapolate the other character's experience backwards, and then the story moves on. Kay has an excellent feel for when I badly wanted to see another character's perspective on something that just happened. Some of Kay's novels revolve around a specific event or person. Children of Earth and Sky is not one of those. It's a braided novel following five main characters, each with their own story. Some of those stories converge; some of them touch for a while and then diverge again. About three-quarters of the way through, I wasn't sure how Kay would manage a satisfying conclusion for the numerous separate threads that didn't feel rushed, but I need not have worried. The ending had very little of the shape that I had expected, focused more on the small than the large (although there are some world-changing events here), but it was an absolute delight, with some beautiful moments of happiness that took the rest of the novel to set up. This is not the sort of novel with a clear theme, but insofar as it has one, it's a story about how much of the future shape and events of the world are unknowable. All we can control is our own choices, and we may never know their impact. Each individual must decide who they want to be and attempt to live their life in accordance with that decision, hopefully with some grace towards others in the world. The novel does, alas, still have some of Kay's standard weaknesses. There is (at last!) an important female friendship, and I had great hopes for a second one, but sadly it lasted only a scant handful of pages. Men interact with each other and with women; women interact almost exclusively with men. Kay does slightly less awarding of women to male characters than in some previous books (although it still happens), but this world is still weirdly obsessed with handing women to men for sex as a hospitality gesture. None of this is too belabored or central to the story, or I would be complaining more, but as soon as one sees how regressive the gender roles typically are in a Kay novel, it's hard to unsee. And, as always for Kay, the sex in this book is weirdly off-putting to me. I think this goes hand in hand with Kay's ability to write some of the best conversations in fantasy. Kay's characters spar and thrust with every line and read nuance into small details of wording. Frequently, the turn of the story rests on the outcome of a careful conversation. This is great reading; it's the part of Kay's writing I enjoy the most. But I'm not sure he knows how to turn it off between characters who love and trust each other. The characters never fully relax; sex feels like another move in ongoing chess games, which in turn makes it feel weirdly transactional or manipulative instead of open-hearted and intimate. It doesn't help that Kay appears to believe that arousal is a far more irresistible force for men than I do. Those problems did get in the way of my enjoyment occasionally, but I didn't think they ruined the book. The rest of the story is too good. Danica in particular is a wonderful character: thoughtful, brave, determined, and deeply honest with herself in that way that is typical of the best of Kay's characters. I wanted to read the book where Danica's and Leonora's stories stayed more entwined; alas, that's not the story Kay was writing. But I am in awe at Kay's ability to write characters who feel thoughtful and insightful even when working at cross purposes, in a world that mostly avoids simple villains, with a plot that never hinges on someone doing something stupid. I love reading about these people. Their triumphs, when they finally come, are deeply satisfying. Children of Earth and Sky is probably not in the top echelon of Kay's works with the Sarantine Mosaic and Under Heaven, but it's close. If you like his other writing, you will like this as well. Highly recommended. Rating: 9 out of 10

18 February 2022

Colin Watson: Launchpad now supports SSH Ed25519 keys and RSA SHA-2 signatures

As of 2022-02-16, Launchpad supports a couple of features on its SSH endpoints (git.launchpad.net, bazaar.launchpad.net, ppa.launchpad.net, and upload.ubuntu.com) that it previously didn t: Ed25519 public keys (a well-regarded format, supported by OpenSSH since 6.5 in 2014) and signatures with existing RSA public keys using SHA-2 rather than SHA-1 (supported by OpenSSH since 7.2 in 2016). I m hesitant to call these features new , since they ve been around for a long time elsewhere, and people might quite reasonably ask why it s taken us so long. The problem has always been that Launchpad can t really use a normal SSH server such as OpenSSH because it needs features that aren t practical to implement that way, such as virtual filesystems and dynamic user key authorization against the Launchpad database. Instead, we use Twisted Conch, which is a very extensible Python SSH implementation that has generally served us well. The downside is that, because it s an independent implementation and one that occupies a relatively small niche, it often lags behind in terms of newer protocol features. Catching up to this point has been something we ve been working on for around five years, although it s taken a painfully long time for a variety of reasons which I thought some people might find interesting to go into, at least people who have the patience for details of the SSH protocol. Many of the delays were my own responsibility, although realistically we probably couldn t have added Ed25519 support before OpenSSL/cryptography work that landed in 2019. Phew! Thanks to everyone who works on Twisted, cryptography, and OpenSSL - it s been really useful to be able to build on solid lower-level cryptographic primitives - and to those who helped with code review.

16 February 2022

Robert McQueen: Forward the Foundation

Earlier this week, Neil McGovern announced that he is due to be stepping down as the Executive Director as the GNOME Foundation later this year. As the President of the board and Neil s effective manager together with the Executive Committee, I wanted to take a moment to reflect on his achievements in the past 5 years and explain a little about what the next steps would be. Since joining in 2017, Neil has overseen a productive period of growth and maturity for the Foundation, increasing our influence both within the GNOME project and the wider Free and Open Source Software community. Here s a few highlights of what he s achieved together with the Foundation team and the community: Recognizing and appreciating the amazing progress that GNOME has made with Neil s support, the search for a new Executive Director provides the opportunity for the Foundation board to set the agenda and next high-level goals we d like to achieve together with our new Executive Director. In terms of the desktop, applications, technology, design and development processes, whilst there are always improvements to be made, the board s general feeling is that thanks to the work of our amazing community of contributors, GNOME is doing very well in terms of what we produce and publish. Recent desktop releases have looked great, highly polished and well-received, and the application ecosystem is growing and improving through new developers and applications bringing great energy at the moment. From here, our largest opportunity in terms of growing the community and our user base is being able to articulate the benefits of what we ve produced to a wider public audience, and deliver impact which allows us to secure and grow new and sustainable sources of funding. For individuals, we are able to offer an exceedingly high quality desktop experience and a broad range of powerful applications which are affordable to all, backed by a nonprofit which can be trusted to look after your data, digital security and your best interests as an individual. From the perspective of being a public charity in the US, we also have the opportunity to establish programs that draw upon our community, technology and products to deliver impact such as developing employable skills, incubating new Open Source contributors, learning to program and more. For our next Executive Director, we will be looking for an individual with existing experience in that nonprofit landscape, ideally with prior experience establishing and raising funds for programs that deliver impact through technology, and appreciation for the values that bring people to Free, Open Source and other Open Culture organizations. Working closely with the existing members, contributors, volunteers and whole GNOME community, and managing our relationships with the Advisory Board and other key partners, we hope to find a candidate that can build public awareness and help people learn about, use and benefit from what GNOME has built over the past two decades. Neil has agreed to stay in his position for a 6 month transition period, during which he will support the board in our search for a new Executive Director and support a smooth hand-over. Over the coming weeks we will publish the job description for the new ED, and establish a search committee who will be responsible for sourcing and interviewing candidates to make a recommendation to the board for Neil s successor a hard act to follow! I m confident the community will join me and the board in personally thanking Neil for his 5 years of dedicated service in support of GNOME and the Foundation. Should you have any queries regarding the process, or offers of assistance in the coming hiring process, please don t hesitate to join the discussion or reach out directly to the board.

11 February 2022

Ingo Juergensmann: Old Buildd.Net Database

Since March/April 2000 I was deeply involved in Debian m68k and operated multiple m68k autobuilder for over a decade. In fact my Amiga 3000 named arrakis was the second buildd for m68k in addition to the Debian owned Amiga 3000UX named kullervo . Back in that time there was some small website running on Kullervo to display some information about the Debian autobuilder. After some time we (as m68k porters) moved that webpage away from Kullervo to my root server. Step by step this site evolved to Buildd.Net and extended to other archs and suites beside unstable like backports or non-volatile. The project got more and more complex and beyond my ability to do a complete necessary rewrite. So, in 2016 I asked for adoption of the project and in 2018 I shut it down, because (apparently) there was nobody taking over. From November 2005 until January 2018 I do have entries in my PostgreSQL database for Buildd.Net. I think the data in the database might be interesting for those that want to examine that data. You can use the data to see how build times have increased over time, which e.g. led to the expulsion of m68k as release arch, because the arch couldn t keep up anymore. I could imagine that you could do other interesting analysis with that data. For example how new versions of the toolchain increased the build times, maybe even if a specific version of e.g. binutils or gcc had a positive effect on certain archs, but a negative effect on other archs. If there is interest in this data I could open the database to the public or even upload the dump of the database so that you can download and install it on your own.

Holger Levsen: 20220211-inbox-zero-in-2022-and-beyond

Back to the old and new normal: inbox zero So, a long time ago, on the last two days of January 2020 I had reached zero unread mails in my inbox and all mailing lists and then... some stuff kept me distracted for a (too) long time... And then two weeks ago on the 29th of January 2022, I've reached inbox zero again, and again on the 30th and then I had a hardware issue and couldn't really use my computer for two days (one day trying to fix, the other copying data around...) and thus only on February 2nd I've hit zero unread mails again and again and again, every day for the last 9 days up until today. Yay! I'm sure there will be days (and weeks) where I won't manage to deal with all my incoming mail everyday, but I surely hope I'll manage at least once a month. As I did in 2019 when I started tracking this :) Reaching inbox zero every day is good for several reasons and probably the most important one is peace of mind. Even though the incoming flood of email never really stops, by reaching inbox zero I can achieve the feeling that I've dealt with all my emails for the day and that I can put email off my focus, at least for that day and despite emails coming in... ...and then email is too easy to be used as a todo list. Narf. So I guess I need to improve those workflows eventually as well. And offline days, do you remember those? Fully offline even, and by choice?!!

Next.

Previous.