Search Results: "ed"

10 March 2013

Hideki Yamane: great IOPS device and if we'd have it...?


I know some folks work at Fusion IO, maybe you know, one of the leader of PCIe flash storage system. And they say their products are "great", since their device put amazing IOPS as they press released (9,000,000 IOPS, and Wikipedia says "SAS HDDs put 200 IOPS". If you have a SSD in your laptop/desktop, you'd love it. It puts almost 10,000 IOPS or so). Such PCIe SSD can bring "Moon shot", change the rules for managing CPU, Memory, Disk and Network for servers, IMHO.


Then, I'm dreaming - if we Debian would have such MAGICAL device, what is the most efficient way to improve/accelerate/Kaizen our project? To use mailing list server? BTS? UDD? CI?

Dear lazyweb, please let me know what is the bottleneck of our development, and great IOPS capacity will fix it.

(and please don't say about things based on human resource, since PCIe SSD devices cannot improve such things, you know ;)

Axel Beckert: Rendering Markdown, Asciidoc and Friends automatically while Editing

Partially because of Markdown being Github s markup format of choice, I enjoy writing documents in simple markup formats more and more. There s though one common annoyance with these formats compared to writing plain HTML The Annoyance They need to be rendered (i.e. more or less compiled) before you can view your outpourings rendered, e.g. in the web browser. So the workflow usually is:
  1. Saving the current file in your favourite editor
  2. Switch to terminal with commandline
  3. Cursor up, Enter
  4. Switch to your favourite web browser
  5. Hit the reload button
Using a Specialized Editor with Live Preview One choice would be to use a specific editor with live rendering. The one I know in Debian (from Wheezy on) is ReText (Debian package retext). It supports Markdown and reStructuredText. But as with most simple GUI editors, I miss there many of the advanced editing commands possible with Emacs. Using Emacs Markdown Mode Then there is the Markdown Mode for Emacs (part of Debian s emacs-goodies-el package), where you can get a preview by pressing C-c C-c p. But for some reason this takes several seconds, opens a new buffer and window with the rendered HTML code and then starts (hardcoded) Firefox (which is not my preferred web browser). And if you do that a second time without closing Firefox first, it won t just reload the file but will open a new tab. You might think that just hitting reload should suffice. But no, the new tab has a different file name, so reload doesn t help. Additionally it may not use my preferred Markdown implementation. Meh. Well, I probably could fix all those issues with Markdown Mode, it s only Emacs Lisp. Heck, the called command is even configurable. But fixing at least four issues to fix one workflow annoyance? Maybe some other time, but not as long there are other nice choices Using inotifywait to Render on Write So everytime you save the currently edited file, you immediately want to rerender the same HTML file from it. This can be easily automated by using Linux inotify kernel subsystem which notices changes to the filesystem, and reports those to applications which ask for it. One such tool is inotifywait which can either output all or just specific events, or just exit if the first requested event occurs. With the latter it s easy to write a while loop on the commandline which regenerates a file after every write access. I use either Pandoc or Asciidoc for that since both generate full HTML pages including header and footer, but you can use that also with Markdown to render just the HTML body. Most browsers render it correctly anyway:
while inotifywait -q -e modify index.md; do pandoc -s -f markdown -t html -o index.html index.md; done
while inotifywait -q -e modify index.txt; do asciidoc index.txt; done
while inotifywait -q -e modify index.md; do markdown index.md > index.html; done
This solution is even editor- and build-system-agnostic (But not operating-system-agnostic.) inotifywait is part of inotify-tools, a useful set of commandline tools to interface with inotify. They re packaged in Debian as inotify-tools, too. Using mdpress for Markdown plus Impress.js based Slides The ruby-written mdpress is a special case of the previous case. It s a commandline tool to convert Markdown into Impress.js based slide shows and it has an option named --automatic which causes it to keep running and automatically update the presentation as soon as changes are made to the Markdown file. mdpress is not yet in Debian, but there s an ITP for it and Impress.js itself recently entered Debian as libjs-impress. Nevertheless, two dependencies (highlight.js, ITP ed, ruby-launchy, ITP ed) are still missing in Debian.

Axel Beckert: Up to date Aptitude Documentation Online

Aptitude ships documentation in 7 languages as HTML files. However the latest version available online was 0.4.11.2 from 2008 and hosted on the server by the previous, now unfortunately inactive Aptitude maintainer, and only covered 5 languages. This lack of up to date online documentation even caused others to put more up to date versions online. Nevertheless they age, too, and the one I m aware is not up to date for Wheezy. So the idea was born to keep an up to date version online on Aptitude s Alioth webspace (which currently redirects to a subdirectory of the previous maintainer s personal website). But unfortunately we, the current Aptitude Team, are still lacking administrative rights on Aptitude s Alioth project, which would be necessary to assign new team members who could work on that. As an intermediate step, there s now a (currently ;-) up to date Aptitude User s Manual online in all 7 languages at

http://people.debian.org/~abe/aptitude/ and English at

http://people.debian.org/~abe/aptitude/en/ As this location could also suffer from the same MIA issues as any other personal copy, the plan is to move this to somewhere under http://aptitude.alioth.debian.org/ as soon as we have full access to Aptitude s Alioth project. Our plans for then are:

P.S.: Anyone interested in doing a German translation of the Aptitude User s Manual? Sources are in DocBook, i.e. XML, and available via Git.

Lars Wirzenius: Makefiletab plugin for Gedit 3

Micka l Delahaye has a plugin for Gedit 2 to force off spaces-instead-of-tabs for Makefiles. I wrote a similar plugin for Gedit 3, since all the APIs have changed. The source is at git://git.gitano.org.uk/personal/liw/makefiletab3 (no .deb as of this time). I probably did something really stupid in the plugin code, since I have no idea how plugins should really be written: I wasn't very illuminated by the documentation.

9 March 2013

Francesca Ciceri: Female participation in Debian (reloaded)

This dent by M nica Ram rez Arceda finally gave me the energy to update the statistics about female participation in Debian, first published by Margarita Manterola back in 2010. So, here the new graph updated to February 2013. Female participation in Debian graph The necessary caveat is that is not easy (at least for me) to tell the gender just based on first names, so the actual numbers may be higher. In addition, you should be warned that there are some contributions not easily traceable: it's the case of translators, graphic artists and documentation writers, as well as event organizers. For instance, Beatrice Torracca doesn't appear in these stats, and she is the co-coordinator of the Italian translation team and a long term Debian (and free software in general) contributor. There was a proposal to better track non packaging contributors, but no news on that front yet (at least that I'm aware of). Sources: You can find the data used as well as the updated graph here. TODO:

Lars Wirzenius: Can the world be saved by coding?

I love programming. I was born to code. I want to save the world by writing code. I feel very strongly about software freedom. As I get older, and my eyes open to see more of the evil in the world, I become more concerned about freedom in general. Software freedom is, at least traditionally, about permission use, study, modify, and re-distribute software. The Free Software Foundation expresses this as the four essential freedoms. Debian expanded on that, and produced the Debian Free Software Guidelines. This is no longer enough. It is not enough to have all the freedom when you using your own computer, to have the source code to every bit of code that runs on your hardware. We live in the era of the Internet. Much of what we use computers for involves communication over the Internet, and the Internet is being actively used to curtail the freedom of people. For example, governments and corporations do large-scale surveillance of everyone, by eavesdropping on private communications, gathering enormous databases of personal data, and by analysing everything they can in order to find patterns and make conclusions both at the statistical level and about individuals. This ruins privacy. Without privacy, democracy cannot survive. Another example: in the name of various strawmen, such as terrorism, copyright violations, drugs, and child pornography, governments and corporations are collaborating in limiting private people's communications. I'm a Finnish citizen living in the UK. Both countries are among the closest ones to an ideal democractic nation state. Both countries arbitrarily block access to websites based on lists provided by private organisations, assuming that those organisations produce accurate lists of sites that contain copyright violations. As a result, both countries blocked, for example, a site where musical artists promoted their own works, bypassing the large media corporations that fund the list-making organisation. These issues transcend software freedom, though they interact with it. Software freedom is a necessary requirement for freedom, in a world where almost everything is done with, or controlled by, the use of computers. Software freedom is not enough to prevent censorship or surveillance: even if all the software in the world were free, including the national firewalls of China, Finland, and the UK, this would not prevent those countries from censoring and surveilling their citizens. The firewall would run free software, but that does not give the citizens the freedom to disable, or modify, the firewall systems. Fixing these issues is not a coding task. It is a job for politics, and it is going to take a long time, I fear. In the mean time, is there something a hacker can do to improve things? My main hobby project is Obnam, my backup program. Does that help people to protect their freedom? I think it does, in a small way: Obnam supports online, encrypted backups (and de-duplication even for encryption is used), which means they can make backups to servers anywhere on the Internet without having to fear their data gets read and analysed by hostile entities such as their own government, other governments, large corporations, or criminals. Obviously this does not help them if their government prohibits the use of encryption, or requires key escrow, or mandates backdoors to all encryption methods. But it's a step in the right direction. I don't claim Obnam will save the world, but a million small such steps by a thousand individual hackers, even without any particular organisation or guidance, will make a big impact. What step can you take?

8 March 2013

Maximilian Attems: Wrong moves

A bizarre closed user-tracking schism is rebased from shaky grounds to an unexisting target. It is sad to see this continous decline due to unchallenged decisions.

Richard Hartmann: Release Critical Bug report for Week 09

I extended UDD's rcblog historical bug overview table until week 18, which is the last week of April. Let's hope we won't need that long and I will be able to delete half of those. The UDD bugs interface currently knows about the following release critical bugs: How do we compare to the Squeeze release cycle?
Week Squeeze Wheezy Diff
43 284 (213+71) 468 (332+136) +184 (+119/+65)
44 261 (201+60) 408 (265+143) +147 (+64/+83)
45 261 (205+56) 425 (291+134) +164 (+86/+78)
46 271 (200+71) 401 (258+143) +130 (+58/+72)
47 283 (209+74) 366 (221+145) +83 (+12/+71)
48 256 (177+79) 378 (230+148) +122 (+53/+69)
49 256 (180+76) 360 (216+155) +104 (+36/+79)
50 204 (148+56) 339 (195+144) +135 (+47/+90)
51 178 (124+54) 323 (190+133) +145 (+66/+79)
52 115 (78+37) 289 (190+99) +174 (+112/+62)
1 93 (60+33) 287 (171+116) +194 (+111/+83)
2 82 (46+36) 271 (162+109) +189 (+116/+73)
3 25 (15+10) 249 (165+84) +224 (+150/+74)
4 14 (8+6) 244 (176+68) +230 (+168/+62)
5 2 (0+2) 224 (132+92) +222 (+132/+90)
6 release! 212 (129+83) +212 (+129/+83)
7 release+1 194 (128+66) +194 (+128/+66)
8 release+2 206 (144+62) +206 (+144/+62)
9 release+3 174 (105+69) +174 (+105/+62)
Graphical overview of bug stats thanks to azhag:

Richard Hartmann: Release Critical Bug report for Week 10

By using highly advanced and secret analytical tools (i.e. stupid correlation), I am guessing that Wheezy will be released in about six weeks. Week 16... mark my words. The UDD bugs interface currently knows about the following release critical bugs: How do we compare to the Squeeze release cycle?
Week Squeeze Wheezy Diff
43 284 (213+71) 468 (332+136) +184 (+119/+65)
44 261 (201+60) 408 (265+143) +147 (+64/+83)
45 261 (205+56) 425 (291+134) +164 (+86/+78)
46 271 (200+71) 401 (258+143) +130 (+58/+72)
47 283 (209+74) 366 (221+145) +83 (+12/+71)
48 256 (177+79) 378 (230+148) +122 (+53/+69)
49 256 (180+76) 360 (216+155) +104 (+36/+79)
50 204 (148+56) 339 (195+144) +135 (+47/+90)
51 178 (124+54) 323 (190+133) +145 (+66/+79)
52 115 (78+37) 289 (190+99) +174 (+112/+62)
1 93 (60+33) 287 (171+116) +194 (+111/+83)
2 82 (46+36) 271 (162+109) +189 (+116/+73)
3 25 (15+10) 249 (165+84) +224 (+150/+74)
4 14 (8+6) 244 (176+68) +230 (+168/+62)
5 2 (0+2) 224 (132+92) +222 (+132/+90)
6 release! 212 (129+83) +212 (+129/+83)
7 release+1 194 (128+66) +194 (+128/+66)
8 release+2 206 (144+62) +206 (+144/+62)
9 release+3 174 (105+69) +174 (+105/+69)
10 release+4 120 (72+48) +120 (+72/+48)
11 release+5
12 release+6
13 release+7
14 release+8
15 release+9
16 release+10
17 release+11
18 release+12
Graphical overview of bug stats thanks to azhag:

Michael Stapelberg: Replying to Debian BTS messages in notmuch

Previously, my workflow regarding replying to bugreports outside my own packages was very uncomfortable: I first downloaded the mbox archive from the BTS, then imported that in claws-mail, hit reply all, remove submit@, add bugnumber@, then send the email. Therefore, I decided to hack up a little elisp function to automate this process for notmuch. It first downloads the message from the BTS, adds it to the notmuch database, then calls notmuch-mua-reply on the message and fixes the To: header:
;; Removes submit@bugs.debian.org from the recipients of a reply-all message.
(defun debian-remove-submit (recipients)
  (delq nil
	(mapcar (lambda (recipient)
		  (and (not (string-equal (nth 1 recipient) "submit@bugs.debian.org"))
		       recipient))
		recipients)))
(defun debian-add-bugrecipient (recipients bugnumber)
  (let* ((bugaddress (concat bugnumber "@bugs.debian.org"))
	 (addresses (mapcar (lambda (x) (nth 1 x)) recipients))
	 (exists (member bugaddress addresses)))
    (if exists
	recipients
      (append (list (list (concat "Bug " bugnumber) bugaddress)) recipients))))
;; TODO: msg should be made optional and it should default to the latest message in the bugreport.
;; NB: bugnumber and msg are both strings.
(defun debian-bts-reply (bugnumber msg)
  ;; Download the message to ~/mail-copy-fs/imported.
  (let ((msgpath (format "~/mail-copy-fs/imported/bts_%s_msg_%s.msg" bugnumber msg)))
    (let* ((url (format "http://bugs.debian.org/cgi-bin/bugreport.cgi?msg=%s;mbox=yes;bug=%s" msg bugnumber))
	   (download-buffer (url-retrieve-synchronously url)))
      (save-excursion
	(set-buffer download-buffer)
	(goto-char (point-min)) ; just to be safe
	(if (not (string-equal
		  (buffer-substring (point) (line-end-position))
		  "HTTP/1.1 200 OK"))
	    (error "Could not download the message from the Debian BTS"))
	;; Delete the HTTP headers and the first "From" line (in order to
	;; make this a message, not an mbox).
	(re-search-forward "^$" nil 'move)
	(forward-char)
	(forward-line 1)
	(delete-region (point-min) (point))
	;; Store the message on disk.
	(write-file msgpath)
	(kill-buffer)))
    ;; Import the mail into the notmuch database.
    (let ((msgid (with-temp-buffer
		   (call-process "~/.local/bin/notmuch-import.py" nil t nil (expand-file-name msgpath))
		   (buffer-string))))
      (notmuch-mua-reply (concat "id:" msgid) "Michael Stapelberg <stapelberg@debian.org>" t)
      ;; Remove submit@bugs.debian.org, add <bugnumber>@bugs.debian.org.
      (let* ((to (message-fetch-field "To"))
	     (recipients (mail-extract-address-components to t))
	     (recipients (debian-remove-submit recipients))
	     (recipients (debian-add-bugrecipient recipients bugnumber))
	     (recipients-str (mapconcat (lambda (x) (concat (nth 0 x) " <" (nth 1 x) ">")) recipients ", ")))
	(save-excursion
	  (message-goto-to)
	  (message-delete-line)
	  (insert "To: " recipients-str "\n")))
      ;; Our modifications don t count as modifications.
      (set-buffer-modified-p nil))))
In case you want to get updates, you can find the latest version of this code in my configfiles git repository. To add a single message to the notmuch database and get its message ID, I have written this simple python script (using python-notmuch), located in ~/.local/bin/python-import.py:
#!/usr/bin/env python
# vim:ts=4:sw=4:et
import notmuch
import sys
if len(sys.argv) < 2:
    print "Syntax: notmuch-import.py <filename>"
    sys.exit(0)
db = notmuch.Database(mode=notmuch.Database.MODE.READ_WRITE)
(msg, status) = db.add_message(sys.argv[1])
print msg.get_message_id()
If you have any improvements, I d love to hear about it. If it s useful for you, enjoy.

Vasudev Kamath: Multi-Arch lintian check for font packages

I've provided a new patch #701061 for lintian to warn about font packages that are not marked as Multi-Arch foreign or allowed. Its already included in the lintian by Neils Thykier and will be part of version 2.5.12. The following tag has been implemented
font-package-not-multi-arch-foreign
A Bit of History for this implementation is as follows: We got a bug report on one of the fonts in pkg-fonts team that its not been installed in i386 architecture on a amd64 multi-arch system #694864. We were first confused but Daniel Kahn Gillmor pointed that we indeed need to mark all font packages as Multi-Arch foreign. He proposed that we should write a lintian check for this which I volunteered to do and then forgot!. Recently I was checking my QA page and landed into Ubuntu's page of my package where I saw they were patching imported font package and marking them as Multi-Arch: foreign and I suddenly remembered my promise! and this patch was the result of same enlightenment :-). Since there is huge number of font packages maintained by pkg-fonts devel we targeted this for Jessie release.
Here by I request all font package maintainers to consider marking their packages as Multi-Arch foreign. I also request people to join us on pkg-fonts-devel and help us doing this for all font packages maintained by the team, we really lack people in the team.

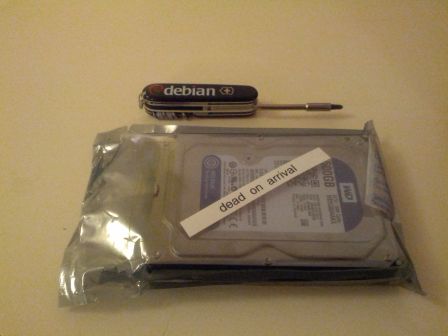
Sylvain Le Gall: Always test your HD first

I just received a WD 500GB Blue, to replace the hard drive of my wife's computer. First thing after unpacking: start to test. And I was right to do it... there are bad blocks on it. WD 500GB DOA The story: I tend to do proactive replacement of hard drive, to avoid losing too much data or be in hurry when the current one fails. There are two ways to monitor a hard drive: Logcheck is pretty straightforward to install. It scans your log every two hours and send you a report of what is happening. It is not a very precise tool and you have to tune it a little bit to just send you what is relevant (install extra rules to ignore what you know is not of interest). Whenever you start to see log entry like that:
Jan 24 18:16:08 foo kernel: [ 1965.343980] ata5.00: exception Emask 0x50 SAct 0x39 SErr 0x800 action 0x6 frozen
Jan 24 18:16:08 foo kernel: [ 1965.343991] ata5.00: irq_stat 0x08000000, interface fatal error
Jan 24 18:16:08 foo kernel: [ 1965.344001] ata5: SError:   HostInt  
Jan 24 18:16:08 foo kernel: [ 1965.344036] ata5.00: failed command: READ FPDMA QUEUED
Jan 24 18:16:08 foo kernel: [ 1965.344055] ata5.00: cmd 60/08:00:18:31:44/00:00:1a:00:00/40 tag 0 ncq 4096 in
Jan 24 18:16:08 foo kernel: [ 1965.344059]          res 40/00:2c:e6:c2:fd/00:00:26:00:00/40 Emask 0x50 (ATA bus error)
Jan 24 18:16:08 foo kernel: [ 1965.344071] ata5.00: status:   DRDY  
Jan 24 18:16:08 foo kernel: [ 1965.344081] ata5.00: failed command: WRITE FPDMA QUEUED
It is a good time to think about changing your hardrive -- but it is maybe too late. Smartmontools (aka smartd) is dedicated tool to monitor hard drives and do a good job. I think it is not installed by default in Debian, but it should be. It scans your hard drive for SMART capabilities and monitor the health of the HD using internal tools. In the case of bad blocks, you will start to see entry like that:
Feb 17 14:05:17 bar smartd[1268]: Device: /dev/sda [SAT], 1 Currently unreadable (pending) sectors
Feb 17 14:35:17 bar smartd[1268]: Device: /dev/sda [SAT], 1 Currently unreadable (pending) sectors
Obviously when you see this log, it is also a good time to change your hard drive. In the case of my wife's HD, I just got data from logcheck. It means that the error is not that important (transient failure, something is wrong but the HD can cope with it). But I still decided to get a new one for my wife. Whenever, I receive a new drive, the first thing I do is to check it for errors. You can do that using the program badblocks in write mode. It takes ages to test (count up to 1 day for 1TB on USB), but at the end you know that you have a good candidate -- where it is worth install your data. You just have to follow this procedure
  1. dmesg grep sd
  2. try to find what drive is the one you want to test in the output of 1.
  3. cfdisk /dev/sdX, sdX being the drive you want to test
  4. check that what you see in cfdisk is what you expect to test: right name and capacity for the drive
  5. sudo badblocks -wvs /dev/sdX
  6. run sudo tail -f /var/log/syslog in parallel just in case
  7. wait
If some errors appears in /var/log/syslog, you know something bad is happening. Whenever you have a single failing block, don't think it is ok. It is NOT ok for a HD to start its life with failing blocks. In this case, repack the drive and send it for replacement ASAP. In the case of my hard drive: smartd mail:
The following warning/error was logged by the smartd daemon:
Device: /dev/sda [SAT], 15 Currently unreadable (pending) sectors
syslog entries:
Mar  2 20:52:57 foo kernel: [ 8317.419715] ata4.00: exception Emask 0x0 SAct 0x1 SErr 0x0 action 0x0
Mar  2 20:52:57 foo kernel: [ 8317.419724] ata4.00: irq_stat 0x40000008
Mar  2 20:52:57 foo kernel: [ 8317.419732] ata4.00: failed command: READ FPDMA QUEUED
Mar  2 20:52:57 foo kernel: [ 8317.419747] ata4.00: cmd 60/80:00:00:af:08/00:00:28:00:00/40 tag 0 ncq 65536 in
Mar  2 20:52:57 foo kernel: [ 8317.419750]          res 41/40:00:65:af:08/00:00:28:00:00/40 Emask 0x409 (media error) <F>
Mar  2 20:52:57 foo kernel: [ 8317.419758] ata4.00: status:   DRDY ERR  
Mar  2 20:52:57 foo kernel: [ 8317.419764] ata4.00: error:   UNC  
Mar  2 20:52:57 foo kernel: [ 8317.423959] ata4.00: configured for UDMA/133
I am not blaming any particular brand (like Western Digital), all computer parts I have ever bought had to follow the same procedure and it is a known fact that computer parts as a non-zero percentage of chance to be DOA (dead on arrival) or after a few weeks. But as a consumer you should be aware of that and take action to avoid spending 10h configuring your computer to see it failing after a week... The waste of time to test is a win on the long term.

Petter Reinholdtsen: First Skolelinux / Debian Edu Squeeze update released

Last Sunday, 2013-03-03,, Holger Levsen announced the first update of Skolelinux / Debian Edu based on Debian Squeeze. This is the first update since the initial release 2012-03-11. This is the release announcement email from Holger:
Hi, it's my pleasure to announce the immediate availability of Debian Edu 6.0.7+r1 ("Debian Edu Squeeze"). Debian Edu 6.0.7+r1 is an incremental update to Debian Edu 6.0.4+r0, containing all the changes between Debian 6.0.4 and 6.0.7 as well Debian Edu specific bugfixes and enhancements. See below (in this mail) for the full list of (edu) changes. Please see http://www.debian.org/News/2012/20120311 for more information on "Debian Edu Squeeze". Images are available for download at http://ftp.skolelinux.org/skolelinux-cd/ md5sums:
1fe79eb4f0f9ae1c58fc318e26cc1e2e debian-edu-6.0.7+r1-CD.iso
a6ddd924a8bd9a1b5ca122e8fe1c34ec debian-edu-6.0.7+r1-DVD.iso
ac6c72cd7925ccec51bfbf58e2a7c69c debian-edu-6.0.7+r1-source-DVD.iso sha1sums:
a4b58233b672a99c7df8dc24fb6de3327654a5c3 debian-edu-6.0.7+r1-CD.iso
9b524915e0ff2aa793f13d93123e5bd2bab2dbaa debian-edu-6.0.7+r1-DVD.iso
43997614893fc5e9e59ad6ce066b05d07fd836fa debian-edu-6.0.7+r1-source-DVD.iso These images are suitable for amd64+i386. Changes for Debian Edu 6.0.7+r1 Codename "Squeeze", released 2013-03-03:
  • sitesummary was updated from 0.1.3 to 0.1.8
    • Make Nagios configuration more robust and efficient
    • Comply with 3.X kernel
  • debian-edu-doc from 1.4~20120310~6.0.4+r0 to 1.4~20130228~6.0.7+r1
    • Minor updates from the wiki
    • Danish translation now complete
  • debian-edu-config from 1.453 to 1.455
    • Fix /etc/hosts for LTSP diskless workstations. Closes: #699880
    • Make ltsp_local_mount script work for multiple devices.
    • Correct Kerberos user policy: don't expire password after 2 days. Closes: #664596
    • Handle '#' characters in the root or first users password. Closes: #664976
    • Fixes for gosa-sync:
      • Don't fail if password contains "
      • Don't disclose new password string in syslog
    • Fixes for gosa-create:
      • Invalidate libnss cache before applying changes
      • Multiple failures during mass user import into GOsa
      • gosa-netgroups plugin: don't erase entries of attribute type "memberNisNetgroup". Closes: #687256
      • First user now uses the same Kerberos policy as all other users
    • Add Danish web page
  • debian-edu-install from 1.528 to 1.530
    • Improve preseeding support and documentation
End-user documentation in English is available at http://wiki.debian.org/DebianEdu/Documentation/Squeeze/ - translations to French, Italian, Danish and German are available in the debian-edu-doc package. (Other languages could use your help!) If you want to contribute to Debian Edu, please join our mailinglist debian-edu@lists.debian.org!
I am very happy to see the fruits of a year of hard work. :)

Timo Jyrinki: Mobile and products from the perspective of Debian

I didn't want to spam Debian Planet with largely Ubuntu related post, but in general I think this is very relevant for Debian Mobile, and I close up the post with Debian :) http://losca.blogspot.fi/2013/03/i-want-products.html

Hideki Yamane: Re: checking package with clang

As I wrote before, I've posted a patch to BTS that add an option use clang compiler to pbuilder. However, pbuilder maintainer Junichi wasn't satisfied with it because he thought it seems to be overhead, introduce complexity and also hook script is enough.

I didn't agree with his opinion since I thought every time we need to add and remove its script, but Thorsten Glaser shows just specifying environment variables can solve it, and moreover, he points other compiler can be supported via hook, too. Sounds good, right? :)

Then I post a new hook script, it works with gcc-4. 4-8 and clang (gcc-4.8 needs experimental apt line for pbuilder). Please test it if you'd be interested.

Paul Tagliamonte: Ubuntu: The Community

Alas. The blogosphere has been slammed with discontent. Count me as one of them. It s been a long time since the last position (I ve held) of significance in Ubuntu, a LoCo Council Member, which I left with a heavy heart. I felt, at the time, that Ubuntu, The Community was no longer in control of Ubuntu The Distro . Technical opinions of Ubuntu community members started to get disregarded (starting with the gawd-awful Yahoo search switch), and it continued to get worse as Canonical stopped becoming a contributor to Ubuntu and started becoming it s sole guiding force. In comes the mess called Ubuntu One which, for the record, is a wrong name, it s not Ubuntu in any sense, it s not Community driven, it just uses Ubuntu as one of it s platforms. Trading on Ubuntu s good name started this mess. Slowly, like the ship of theseus, Canonical started to swap out bit by bit until nothing was left without Canonical assignment. I always assumed it was so that selling the code for another company to use the code for non-free purpose was the reason. Oh well. Look at us now: Starting off on an ill-thought out path because others are unwilling to say they just didn t understand the whole problem. This is a long way of saying: Ex-Ubuntu ers: You re welcome in Debian. I ve set up #ubuntu-expats on oftc. Please join us. You re welcome there. Working in Debian has been an absolute dream; it feels like contributing to Ubuntu in the early days. Come. Have a say. Re-join a Community that isn t just Like us on Facebook . I still consider myself an Ubuntu Community Member, but I don t think there s any community left.

7 March 2013

Pau Garcia i Quiles: Mark s divisive leadership

Mark Shuttleworth recently critized Jonathan Riddell for proposing Xubuntu and others join the Kubuntu community. I thought I could make a few amendments to Mark s writing:

Jonathan Mark says that Canonical Kubuntu is not taking care of the Ubuntu community.

Consider for a minute, Jonathan Mark, the difference between our actions.

Canonical Kubuntu, as one stakeholder in the Ubuntu community, is spending a large amount of energy to evaluate how its actions might impact on all the other stakeholders, and offering to do chunks of work in support of those other stakeholder needs.

You, as one stakeholder in the Ubuntu community, are inviting people to contribute less to the broader project [all the X and Wayland -based desktops], and more to one stakeholder [Unity and Mir].

Hmm. Just because you may not get what you want is no basis for divisive leadership.

Yes, you should figure out what s important to Kubuntu Ubuntu Unity and Mir, and yes, you should motivate folks to help you achieve those goals. But it s simply wrong to suggest that Canonical Kubuntu isn t hugely accommodating to the needs of others, or that it s not possible to contribute or participate in the parts of Ubuntu which Canonical Kubuntu has a particularly strong interest in. Witness the fantastic work being done on both the system and the apps to bring Ubuntu Plasma to the phone and tablet. That may not be your cup of tea, but it s tremendously motivating and exciting and energetic. See Mark? I only needed to do a little search and replace on your words and suddenly, meaning is completely reversed! Canonical started looking only after its own a couple of years ago and totally dumped the community. Many people have noticed this and written about this in the past two years. How dare you say Jonathan or anyone from Kubuntu is proposing contributing less to the broader community? The broader community uses X and/or Wayland. Canonical recently came with Mir, a replacement for X and Wayland, out of thin air. Incompatible with X and Wayland. No mention of it at all to anyone from X or Wayland. No mention of it at FOSDEM one month ago, even though I, as the organizer of the Cross Desktop DevRoom, had been stalking your guy for months because we wanted diversity (and we got it: Gnome, KDE, Razor, XFCE, Enlightenment, etc, we even invided OpenBox, FVWM, CDE and others!). I even wrote a mail to you personally warning you Unity was going to lose its opportunity to be on the stand at FOSDEM. You never answered, of course. Don t you think Mir, a whole new replacement for X and Wayland, which has been in development for 8 months, deserved a mention at the largest open source event in Europe? Come on, man. It is perfectly fine to say yes, Canonical is not so interested in the community. It s our way or the highway . But do not pretend it s anything else or someone else is a bad guy. In fact, is there any bad guy in this story at all!? I think there is not, it s just people with different visions and chosen paths to achieve them. Maybe Mir and Unity are great ideas, much better than X and Wayland. But that s not what we are talking about. We are talking about community, and Canonical has been steadily destroying it for a long time already. If you cannot or do not want to see that, you ve got a huge problem going on.

Daniel Pocock: This blog has upgraded to XCP, IPv6 and Debian 7.0 (wheezy)

If you noticed I hadn't updated the blog for a few days, you may have already anticipated that I've been up to something.... and you would be right. The virtualisation platform that powers this blog (and a lot more, including Lumicall and DruCall) has just been updated to Xen Cloud Platform (XCP) on Debian 7.0 (Wheezy, release candidate 1) The former platform was regular Xen with the xm toolstack on Debian 6.0 (squeeze) (and before that, lenny). The dom0 base system had been running uninterrupted for 720 days at the point I shut it down earlier this week - that is the typical timeframe between two major Debian releases, and it is also a firm endorsement of Debian's stability. Furthermore, the new setup is on new hardware with a new hosting provider, Init7 who offer native IPv6 in a secure Swiss data center. So I've taken the opportunity to add some AAAA records to my DNS, restart Apache and you can now access this blog with pure IPv6 As well as thanking Init7 for making the transition go very smoothly, I'd also like to point out a couple of other things that helped: using provider-independent (PI) IP addresses, and the sheer convenience of using tinc to securely bridge the VLANs in the old and new data centers for a week allowed this change to happen with hardly any downtime at all.

Vincent Sanders: Man cannot discover new oceans unless he has the courage to lose sight of the shore

Continuing with my whirlwind introduction to NetSurf Development now is the time to start examining the code, how its arranged and how to interact with the existing developers.

The way the NetSurf source is structured is around the idea of the frontends each being a native browser. While this implies that there are nine separate browsers that happen to share a common code base the separation is not quite that well defined.

Each frontend provides the OS entry point (the main() function in a c program) and calls out to standard browser initialisation entry function netsurf_init() and then starts running the browsers main dispatch loop with netsurf_main_loop() when that exits the frontend cleans up with netsurf_exit().

The frontends provide a large selection of functions which are called from the core code. These routines run from running the event scheduler through to rendering graphics and text.
Finding your way aroundThe browsers directory layout is fairly shallow consisting of some Makefiles, the nine frontend directories and eleven others.

The Makefiles are GNU make and represent a pretty straightforward linear build system. We do not use recursive make or autotools. There are plans to use the core buildsystem that all the other components use.

The frontend directories contain the code for the frontend and the makefile fragments to build them which are included by the top level Makefile.

In addition there is:
desktop
This contains the non frontend specific code that actually behaves like a browser. For example desktop/netsurf.c contains the three primary functions we outlined in the introduction. You will also find much of the function and data structures interfaces the frontend must provide. It is unlikely someone new to the project will need to change anything in here (there be dragons) but is an important set of routines.
utils
Here you will find the utility and compatibility interfaces, things like url handling, logging, user messages, base64 handling. These are utility interfaces that do not justify splitting out their functionality to a separate library but are useful everywhere. Changing an interface in here would likely result in a major refactor.
For example one quirk is the logging macro was created before varadic C preprocessor macros were universal so it must be called as LOG(("hello %s world", world_type)) e.g. with double brackets. Fixing this and perhaps improving the logging functionality would be "nice" but the changes would be massive and potentially conflict with ongoing work.
content
This contains all the core code to handle contents i.e. html, css, javascript, images. The handling includes retrieval of the resources from URI , correct caching of the received objects and managing the objects state. It should be explicitly stated that the content handlers are separate and use this core functionality. The actual content handlers to deal with object contents such as the routines to decode image files or render html are elsewhere.
image
This is where the content handlers for the various image types are kept. The majority of these image types (jpeg, png, webp, gif, bmp) use a standard library to perform the actual decode (libjpeg, libpng etc.). One special feature used by most image handlers is that of a decoded image cache which is distinct and separate from the content cache.
The decoded image cache manages decoding of the source images (the jpegs and pngs) into frontend specific "render" bitmaps. For example the gtk frontend keeps the decoded images as a cairo surface ready for immediate plotting.
The cache uses a demand based (when the browser actually displays the image) just in time strategy which has been carefully balanced, with real world input, to reduce the overhead of unnecessary image decoding and processing against memory usage for the render bitmaps.
css
The css content handlers provide for the processing of css source text and use the NetSurf libcss library to process into a bytecode suitable for applying style selection at render time.
javascript
The javascript handlers (strictly speaking this should be named the "script" directory as all types of script are handled here) provide basic functionality to bind a javascript engine to the rest of the browser, principally the Document Object Model (DOM) accessed with libdom. The only engine that currently has bindings is Spidermonkey from the Mozilla foundation.
render
This is the heart of the browser containing the content handler for html (and plain text). This handler deals with:
  • Acquiring the html.
  • Running the base parser as data arrives which generates the DOM and hence DOM events from which additional resource (stylesheets etc.) fetches are started.
  • Deal with script loading
  • Constructing the box model used for layout
  • Performing the Layout and rendering of the document.
Because this module has so many jobs to do it has inevitably become very complex and involved, it is also the principle area of core development . Currently NetSurf lacks a dynamic renderer so changes made by scripts post document load event are not visible. This also has the side effect that the render is only started after the DOM has finished construction and all the resources on a page have completed their fetch which can lead to undesirable display latency.
Docs
Documentation about building and using NetSurf. If anyone wants a place to start improving NetSurf, this is it, it is very incomplete. It must be noted this is not where dynamically generated documentation is found. For the current Doxygen output the best place to look is the most recent build on the Continuous Integration system.
resources
These are runtime resources which are common to all frontends. To be strictly correct they may be the sources which get converted into runtime resources e.g. The FatMessages file which is teh message text for all frontends in all languages, this gets processed at build time into separate files ready.
!NetSurf
This is another resources directory and technically the resources for the riscos frontend. The naming and reliance on this directory are historical. To allow the RISC OS frontend to be run directly from the source directory and an inability of RISC OS to process symbolic links most common runtime resources end up in here and linked to from elsewhere.
test
These are some basic canned test programs and files, principally to test elements of the utils and perform specific exercise of various javascript components.
Getting started
Once a developer has a checked out working build environment and can run the executable for their chosen frontend (and maybe done some web browsing :-) it is time to look at contributing.

If a developer does not have a feature or bug in mind when they begin the best way to get started is often to go bug hunting. The NetSurf bugtacker has lots to choose from unfortunately. Do remember to talk to us (IRC is the best bet if you are bug hunting) about what you are up to but do not be impatient. Some of those bugs are dirty great Shelob types and are not being fixed because even the core developers are stumped!

When first getting going I cannot recommend reading the code enough, this seems to be a skill that many inexperienced open source developers have yet to acquire, especially if they are from a predominately proprietary development background. One wonderful feature of open source software is you get to see all of it, all the elegant nice code and all the "what the hell were they thinking" code too.

One important point is to use your tools well the source is in git, if you learn how to use git well you will gain a skill that is readily portable, not just for NetSurf. And not just revision control tools, learn to use your debugger well and tools like valgrind. Those skills will replay the time spent learning them themselves many times over.

When using git one thing to remember is commit early and often, it does not matter if you have lots of junk commits and dead ends, once you have something viable you can use
git rebase --interactive
and rewrite it all into a single sensible set of commits. Also please do remember to develop on a branch, or if you did not
git pull --rebase
is your friend to avoid unnecessary merges.
Playing nicely with othersThe NetSurf community is a small band of unpaid volunteers. On average we manage to collectively put in, perhaps, ten hours a week with the occasional developer weekend where we often manage over twenty hours each.

The result is that developer time is exceptionally valuable, add in a mature codebase with its fair share of technical debt and you get a group who, when they get to work on NetSurf, are incredibly busy. To be fair we are just like every other small open source project in that respect.

What this means to a new contributor is that they should try and do their homework before asking the obvious questions. The documentation is there for a reason and in spite of its obvious shortcomings please read it!

When asking questions it should be noted that currently the majority of active contributors are in the Europe so if you visit the IRC channel or post questions to lists the time difference is something to keep in mind.

I carefully said contributor above and not developer, users trying the CI builds and reporting results are welcome...as long as they report useful bugs to the bug tracker. Simon Tatham has produced an excellent resource on this subject.

Also we are always happy to receive translations to new languages (diff against the FatMessages file would be outstandingly useful but anything is welcome), artwork, documentation. Just recall what I mentioned about busy developers. Surest way to get us to see something is the development mailing list, you will probably get a reply, though I will not promise how fast!

Some of the more common mistakes when interacting with the community are:
In conclusion
Hopefully this has been of some use although I had hoped to cover more and provide deeper insights and advice on the codebase but there is only so much generalisation to be done before it is just easier for the developer to go read the code for themselves.

I look forward to lots of new contributions :-) though I fear this may all end up as more of a crib sheet for next time we do GSOC, time will tell.

Vincent Sanders: The way to get started is to quit talking and begin doing

When Walt Disney said that he almost certainly did not have software developers in mind. However it is still good advice, especially if you have no experience with a piece of software you want to change.

Others have written extensively on the topic of software as more than engineering and the creative aspects, comparing it to a craft, which is a description I am personally most comfortable with. As with any craft though you have to understand the material you have to work with and an existing codebase is often a huge amount of material.

While developing NetSurf we get a lot of people who talk a lot about what we "ought" or "should" do to improve the browser but few who actually get off their collective posteriors and contribute. In fact according to the ohloh analysis of the revision control system there are roughly six of us who contribute significantly on a regular basis and of those only four who have interests beyond a specific frontend.

It has been mentioned by a couple of new people who have recently compiled the browser from source that it is somewhat challenging to get started. To address this criticism I intend to give a whirlwind introduction to getting started with the NetSurf codebase, perhaps we can even get some more contributors!

This first post will cover the mechanics of acquiring and building the source and the next will look at working with the codebase and the Netsurf community.

This is my personal blog, the other developers might disagree with my approach, which is why this is in my blog and not on the NetSurf website. That being said comments are enabled and I am sure they will correct anything I get wrong.
ResourcesNetSurf has a selection of resources which are useful to a new developer:
Build environmentThe first thing a new developer has to consider is their build environment. NetSurf supports nine frontends on several Operating Systems (OS) but is limited on the build environment that can be used.

The developer will require a Unix like system but let's be honest, we have not tried with anything other than Linux distributions in some time or MAC OS X for the cocoa frontend because its a special snowflake.

Traditionally at this point in this kind of introduction it would be traditional to provide the command line for various packaging systems to install the build environment and external libraries. We do have documentation that does this but no one reads it, or at least it feels like that. Instead we have chosen to provide a shell fragment that encodes all the bootstrap knowledge in one place, its kept in the revision control system so it can be updated.

To use: download it, read it (hey running random shell code is always a bad idea), source it into your environment and run ns-apt-get-install on a Debain based system or ns-yum-install on Fedora. The rest of this posting will assume the functionality of this script is available, if you want to do it the hard way please refer to the script for the relevant commands and locations.

For Example:
$ wget http://git.netsurf-browser.org/netsurf.git/plain/Docs/env.sh
$ less env.sh
$ source env.sh
$ ns-apt-get-install

Historically NetSurf built on more platforms natively but the effort to keep these build environments working was extensive and no one was prepared to do the necessary maintenance work. This is strictly a build setup decision and does not impact the supported platforms.

Since the last release NetSurf has moved to the git version control system from SVN. This has greatly improved our development process and allows for proper branching and merging we previously struggled to implement.

In addition to the core requirements external libraries NetSurf depends on will need to be installed. Native frontends where the compiled output is run on the same system it was built on are pretty straightforward in that the native package management system can be used to install the libraries for that system.

For cross building to the less common frontends we provide a toolchain repository which will build the entire cross toolchain and library set (we call this the SDK) direct from source. This is what the CI system uses to generate its output so is well tested.
External LibrariesNetSurf depends upon several external development libraries for image handling, network fetching etc. The libraries for the GTK frontend are installed by default if using the development script previously mentioned.

Generally a minimum of libcurl, libjpeg and libpng are necessary along with whatever libraries are required for the toolkit.
Project Source and Internal Libraries
One important feature of NetSurf is that a lot of functionality is split out into libraries. These are internal libraries and although technically separate projects, releases bundle them all together and for development we assume they will all be built together.

The development script provides the ns-clone function which clones all the project sources directly from their various git repositories. Once cloned the ns-make script can be used to build and install all the internal libraries into a local target ready for building the browser.

For Example:

$ source env.sh
$ ns-clone
$ ns-make-libs install
Frontend selectionAs I have mentioned NetSurf supports several windowing environments (toolkits if you like) however on some OS there is only one toolkit so the two get conflated together.

NetSurf currently has nine frontends to consider:
Building and running NetSurfFor a developer new to the project I recommend that the gtk version be built natively which is what I describe here.

Once the internal libraries have been installed, building NetSurf itself is as simple as running make.

For Example:
$ source env.sh
$ ns-make -C $ TARGET_WORKSPACE /$ NS_BROWSER TARGET=gtk

Though generally most developers would change into the netsurf source directory and run make there. The target (frontend) selection defaults to gtk on Linux systems so that can also be omitted Once the browser is built it can be run from the source tree to test.

For Example:
$ source env.sh
$ cd $ TARGET_WORKSPACE /$ NS_BROWSER
$ ns-make
$ ./nsgtk

The build can be configured by editing a Makefile.config file. An example Makefile.config.example can be copied into place and the configuration settings overridden as required. The default values can be found in Makefile.defaults which should not be edited directly.

Logging is enabled with the command line switch -v and user options can be specified on the command line, options on the command line will override those sourced from a users personal configuration, generally found in ~/.netsurf/Choices although this can be compile time configured.

Next.

Previous.