Search Results: "zed"

5 February 2016

Bernd Zeimetz: bzed-letsencrypt puppet module

With the announcement of the Let s Encrypt dns-01 challenge support we finally had a way to retrieve certificates for those hosts where http challenges won t work. Also it allows to centralize the signing procedure to avoid the installation and maintenance of letsencrypt clients on all hosts. For an implementation I had the following requirements in my mind: After reading trough the source code of various letsencrypt client implementations I decided to use letsencrypt.sh. Mainly because its dependencies are available pretty much everywhere and adding the necessary hook is as simple as writing some lines of code in your favourite (scripting) language. My second favourite was lego, but I wanted to avoid shipping binaries with puppet, so golang was not an option. It took me some days to find enough spare time to write the necessary puppet code, but finally I managed to release a working module today. It is still not perfect, but the basic tasks are implemented and the whole key/csr/signing chain works pretty well. And if your hook can handle it, http-01 challenges are possible, too! Please give the module a try and send patches if you would like to help to improve it!

1 February 2016

Mike Gabriel: My FLOSS activities in January 2016

In January 2016 I was finally able to work on various FLOSS topics again (after two months of heavily focussed local customer work): Upload of MATE 1.12 to Debian testing/unstable At the beginning of the new year, I finalized the bundle upload of MATE 1.12 to Debian unstable [1]. All uploaded packages are available in Debian testing (stretch) and Ubuntu xenial by now. MATE 1.12 will also be the version shipped in Ubuntu MATE 16.04 LTS. Additionally, I finally uploaded caja-dropbox to Debian unstable (non-free), thanks to Vangelis Mouhtsis and Martin Wimpress for doing first steps preparations. The package has already left Debian's NEW queue, but unfortunately has been removed from Debian testing (stretch) again due to build failures in one of its dependencies. Debian LTS work In January 2016 I did my first round of Debian LTS front desk work [2]. Before actually starting with my front desk duty, I worked myself through the documentation and found it difficult to understand the output of the lts-cve-triage.py script. So, I proposed various improvments to the output of that script (all committed by now). During the second week of January then, I triaged the following packages regarding known/open CVE issues: read more

31 January 2016

Chris Lamb: Free software activities in January 2016

Here is my monthly update covering a large part of what I have been doing in the free software world (previously):
Debian
  • Had a talk proposal accepted (Reproducible Builds - fulfilling the original promise of free software) at FOSSASIA 16.
My work in the Reproducible Builds project was also covered in more depth in Lunar's weekly reports (#35, #36, #37, #38, #39)
LTS

This month I have been paid to work 18 hours on Debian Long Term Support (LTS). In that time I did the following:
  • Sevend days of "frontdesk" duties, triaging CVEs, etc.
  • Issued DLA 386-1 for cacti to patch an SQL injection vulnerability.
  • Issued DLA 388-1 for dwarfutils fixing a NULL deference issue.
  • Issued DLA 391-1 for prosody correcting the use of a weak pseudo-random number generator.
  • Issued DLA 404-1 for nginx to prevent against an invalid pointer deference.

Uploads
  • redis (2:3.0.7-1) New upstream stable release, also ensure that test processes are cleaned up and replacing an existing reproducibility patch with a SOURCE_DATE_EPOCH solution.
  • python-django (1.9.1-1) New upstream release.
  • disque (1.0~rc1-4) Make the build reproducible via SOURCE_DATE_EPOCH, ensure that test processes are cleaned up and that the nocheck flag is correctly honoured.
  • gunicorn (19.4.5-1) New upstream release.
  • redis (2:3.2~rc3-1) New upstream RC release (to experimental).


RC bugs


I also filed 100 FTBFS bugs against apache-log4j2, awscli, binutils, brian, ccbuild, coala, commons-beanutils, commons-vfs, composer, cyrus-sasl2, debiandoc-sgml-doc-pt-br, dfvfs, dillo, django-compat, dulwich, git-annex, grpc, hdf-eos5, hovercraft, ideviceinstaller, ircp-tray, isomd5sum, javamail, jhdf, jsonpickle, kivy, klog, libcloud, libcommons-jexl2-java, libdata-objectdriver-perl, libdbd-sqlite3-perl, libpam-krb5, libproc-waitstat-perl, libslf4j-java, libvmime, linuxdcpp, lsh-utils, mailutils, mdp, menulibre, mercurial, mimeo, molds, mugshot, nose, obex-data-server, obexfs, obexftp, orafce, p4vasp, pa-test, pgespresso, pgpool2, pgsql-asn1oid, php-doctrine-cache-bundle, php-net-ldap2, plv8, pngtools, postgresql-mysql-fdw, pyfftw, pylint-common, pylint-django, pylint-django, python-ase, python-axiom, python-biopython, python-dcos, python-falcon, python-instagram, python-markdown, python-pysam, python-requests-toolbelt, python-ruffus, pytsk, pyviennacl, ros-class-loader, ros-ros-comm, ros-roscpp-core, roxterm, ruby-celluloid-extras, ruby-celluloid-fsm, ruby-celluloid-supervision, ruby-eye, ruby-net-scp, ruby-net-ssh, ruby-sidekiq, ruby-sidekiq-cron, ruby-sinatra-contrib, seaview, smc, spatial4j-0.4, swift-plugin-s3, tilecache, typecatcher, ucommon, undertaker, urdfdom, ussp-push, xserver-xorg-video-intel & yt.

FTP Team

As a Debian FTP assistant I ACCEPTed 201 packages: abi-tracker, android-platform-build, android-platform-frameworks-native, android-platform-libcore, android-platform-system-core, animate.css, apitrace, argon2, autosize.js, bagel, betamax, bittorrent, bls-standalone, btfs, caja-dropbox, cegui-mk2, complexity, corebird, courier-authlib, cpopen, ctop, dh-haskell, django-python3-ldap, e2fsprogs1.41, emacs-async, epl, fast5, fastkml, flask-restful, flask-silk, gcc-6, gitlab, golang-github-kolo-xmlrpc, golang-github-kr-fs, golang-github-pkg-sftp, golang-github-prometheus-common, google-auth-library-php, h5py, haskell-aeson-compat, haskell-userid, heroes, hugo, ioprocess, iptables, ivy-debian-helper, ivyplusplus, jquery-timer.js, klaus, kpatch, lazarus, libatteanx-store-sparql-perl, libbrowserlauncher-java, libcgi-test-perl, libdata-sah-normalize-perl, libfsntfs, libjs-fuzzaldrin-plus, libjung-free-java, libmongoc, libmygpo-qt, libnet-nessus-rest-perl, liborcus, libperinci-sub-util-propertymodule-perl, libpodofo, librep, libsodium, libx11-xcb-perl, linux, linux-grsec-base, list.js, lombok, lua-mediator, luajit, maven-script-interpreter, midicsv, mimeo, miniasm, mlpack, mom, mosquitto-auth-plugin, moxie.js, msgpuck, nanopolish, neovim, netcdf, network-manager-applet, network-manager-ssh, node-esprima-fb, node-mocks-http, node-schlock, nomacs, ns3, openalpr, openimageio, openmpi, openms, orafce, pbsim, pd-iemutils, pd-nusmuk, pd-puremapping, pd-purest-json, pg-partman, pg-rage-terminator, pgfincore, pgmemcache, pgsql-asn1oid, php-defaults, php-jwt, php-mf2, php-redis, pkg-info-el, plr, pnmixer, postgresql-multicorn, postgresql-mysql-fdw, powa-archivist, previsat, pylint-flask, pyotherside, python-caldav, python-cookies, python-dcos, python-flaky, python-flickrapi, python-frozendict, python-genty, python-git, python-greenlet, python-instagram, python-ironic-inspector-client, python-manilaclient, python-neutronclient, python-openstackclient, python-openstackdocstheme, python-prometheus-client, python-pymzml, python-pysolr, python-reno, python-requests-toolbelt, python-scales, python-socketio-client, qdox2, qgis, r-cran-biasedurn, rebar.js, repmgr, rfcdiff, rhythmbox-plugin-alternative-toolbar, ripe-atlas-cousteau, ripe-atlas-sagan, ripe-atlas-tools, ros-image-common, ruby-acts-as-list, ruby-allocations, ruby-appraiser, ruby-appraiser-reek, ruby-appraiser-rubocop, ruby-babosa, ruby-combustion, ruby-did-you-mean, ruby-fixwhich, ruby-fog-xenserver, ruby-hamster, ruby-jeweler, ruby-mime-types-data, ruby-monkey-lib, ruby-net-telnet, ruby-omniauth-azure-oauth2, ruby-omniauth-cas3, ruby-puppet-forge, ruby-racc, ruby-reek, ruby-rubinius-debugger, ruby-rubysl, ruby-rubysl-test-unit, ruby-sidekiq-cron, ruby-threach, ruby-wavefile, ruby-websocket-driver, ruby-xmlhash, rustc, s-nail, scrm, select2.js, senlin, skytools3, slurm-llnl, sphinx-argparse, sptk, sunpy, swauth, swift, tdiary, three.js, tiny-initramfs, tlsh, ublock-origin, vagrant-cachier, xapian-core, xmltooling, & yp-tools. I additionally REJECTed 29 packages.

30 January 2016

B lint R czey: Progress report on hardened1-linux-amd64, a potential Debian port with PIE, ASAN, UBSAN and more

It was more that one and a half years ago when I proposed creating a new security &QA focused port for Debian and now I m happy to share the first bits of it. Last year I started the bootstrapping during the holidays and I now have the prototype in the form of cross built packages which can be installed next to amd64 packages using multiarch. The aim of creating the port is still the same, letting people mix fast (amd64) and reasonably hardened (hardened1-linux-amd64) packages on the same system. You can already try the cross-built packages in an amd64 unstable chroot, but be warned that the packages are not stable yet. In the following session I tested curl which seems to be working OK, and groff, which seems to be too buggy even for debugging:
debootstrap --arch=amd64 unstable test-hardened1
# mount /proc for ASAN
mount --bind /proc test-hardened1/proc
chroot test-hardened1/
apt-get install debian-keyring
# this is my key, I'll create one dedicated release key later
gpg --keyring /usr/share/keyrings/debian-keyring.gpg -a --export 0x21E764DF   apt-key add -
echo "deb http://hardened1-debian.s3.amazonaws.com/debian-cross-built hardened1-unstable main" >> \
/etc/apt/sources.list
apt-get update
# update apt and dpkg to versions handling the new port
apt-get upgrade
apt-get update
dpkg --add-architecture hardened1-linux-amd64
apt-get update
apt-get install curl:hardened1-linux-amd64
curl -s https://www.debian.org   tail -n2
</body>
</html>
apt-get install -t hardened1-unstable groff:hardened1-linux-amd64
groff
ASAN:SIGSEGV
=================================================================
==20642==ERROR: AddressSanitizer: SEGV on unknown address 0x000000000000 (pc 0x7f79cd84698a bp 0x619000006980 sp 0x7ffe89b3a930 T0)
ASAN:SIGSEGV
==20642==AddressSanitizer: while reporting a bug found another one. Ignoring.
The next steps are finalizing the changes to apt, dpkg, GCC, glibc and other packages, rebuilding all packages in hardened1-linux-amd64 sbuild chroots and building the rest of the archive.
Some of the patches are not submitted yet but they are available in a temporary fork of rebootstrap
I hope I ll be back soon with the recompiled and finalized packages, but until then feel free to try the cross-compiled ones! Patches fixing crashes are always welcome! :-) update 1: Some packages like dpkg-dev are not installable, I m working on them.
update 2: There is one similar project I know of which aims creating an address sanitized Gentoo variant and Hanno B ck will give a presentation about that at FOSDEM.

29 January 2016

Jan Wagner: Oxidized - silly attempt at (Really Awesome New Cisco confIg Differ)

Since ages I wanted have replaced this freaking backup solution of our Network Equipment based on some hacky shell scripts and expect uploading the configs on a TFTP server. Years ago I stumbled upon RANCID (Really Awesome New Cisco confIg Differ) but had no time to implement it. Now I returned to my idea to get rid of all our old crap.
I don't know where, I think it was at DENOG2, I saw RANCID coupled with a VCS, where the NOC was notified about configuration (and inventory) changes by mailing the configuration diff and the history was indeed in the VCS.
The good old RANCID seems not to support to write into a VCS out of the box. But for the rescue there is rancid-git, a fork that promises git extensions and support for colorized emails. So far so good. While I was searching for a VCS capable RANCID, somewhere under a stone I found Oxidized, a 'silly attempt at rancid'. Looking at it, it seems more sophisticated, so I thought this might be the right attempt. Unfortunately there is no Debian package available, but I found an ITP created by Jonas. Anyway, for just looking into it, I thought the Docker path for a testbed might be a good idea, as no Debian package ist available (yet). For oxidized configuration is only a configfile needed and as nodes source a rancid compatible router.db file can be used (beside SQLite and http backend). A migration into a production environment seems pretty easy. So I gave it a go. I assume Docker is installed already. There seems to be a Docker image on Docker Hub, that looks official, but it seems not maintained (actually). An issue is open for automated building the image.

Creating Oxidized container image The official documentation describes the procedure. I used a slightly different approach.
docking-station:~# mkdir -p /srv/docker/oxidized/  
docking-station:~# git clone https://github.com/ytti/oxidized \  
 /srv/docker/oxidized/oxidized.git
docking-station:~# docker build -q -t oxidized/oxidized:latest \  
 /srv/docker/oxidized/oxidized.git
I thought it might be a good idea to also tag the image with the actual version of the gem.
docking-station:~# docker tag oxidized/oxidized:latest \  
 oxidized/oxidized:0.11.0
docking-station:~# docker images   grep oxidized  
oxidized/oxidized   latest    35a325792078  15 seconds ago  496.1 MB  
oxidized/oxidized   0.11.0    35a325792078  15 seconds ago  496.1 MB  
Create initial default configuration like described in the documentation.
docking-station:~# mkir -p /srv/docker/oxidized/.config/  
docking-station:~# docker run -e CONFIG_RELOAD_INTERVAL=600 \  
 -v /srv/docker/oxidized/.config/:/root/.config/oxidized \
 -p 8888:8888/tcp -t oxidized/oxidized:latest oxidized

Adjusting configuration After this I adjusted the default configuration for writing a log, the nodes config into a bare git, having nodes secrets in router.db and some hooks for debugging.

Creating node configuration
docking-station:~# echo "7204vxr.lab.cyconet.org:cisco:admin:password:enable" >> \  
 /srv/docker/oxidized/.config/router.db
docking-station:~# echo "ccr1036.lab.cyconet.org:routeros:admin:password" >> \  
 /srv/docker/oxidized/.config/router.db

Starting the oxidized beast
docking-station:~# docker run -e CONFIG_RELOAD_INTERVAL=600 \  
 -v /srv/docker/oxidized/.config/:/root/.config/oxidized \
 -p 8888:8888/tcp -t oxidized/oxidized:latest oxidized
Puma 2.16.0 starting...  
* Min threads: 0, max threads: 16
* Environment: development
* Listening on tcp://127.0.0.1:8888
If you want to have the container get started with the docker daemon automatically, you can start the container with --restart always and docker will take care of it. If I wanted to make it running permanent, I would use a systemd unitfile.

Reload configuration immediately If you don't want to wait to automatically reload of the configuration, you can trigger it.
docking-station:~# curl -s http://localhost:8888/reload?format=json \  
 -O /dev/null
docking-station:~# tail -2 /srv/docker/oxidized/.config/log/oxidized.log  
I, [2016-01-29T16:50:46.971904 #1]  INFO -- : Oxidized starting, running as pid 1  
I, [2016-01-29T16:50:47.073307 #1]  INFO -- : Loaded 2 nodes  

Writing nodes configuration
docking-station:/srv/docker/oxidized/.config/oxidized.git# git shortlog  
Oxidizied (2):  
      update 7204vxr.lab.cyconet.org
      update ccr1036.lab.cyconet.org
Writing the nodes configurations into a local bare git repository is neat but far from perfect. It would be cool to have all the stuff in a central VCS. So I'm pushing it every 5 minutes into one with a cron job.
docking-station:~# cat /etc/cron.d/doxidized  
# m h dom mon dow user  command                                                 
*/5 * * * *    root    $(/srv/docker/oxidized/bin/oxidized_cron_git_push.sh)
docking-station:~# cat /srv/docker/oxidized/bin/oxidized_cron_git_push.sh  
#!/bin/bash
DOCKER_OXIDIZED_BASE="/srv/docker/oxidized/"  
OXIDIZED_GIT_DIR=".config/oxidized.git"
cd $ DOCKER_OXIDIZED_BASE /$ OXIDIZED_GIT_DIR   
git push origin master --quiet  
Now having all the nodes configurations in a source code hosting system, we can browse the configurations, changes, history and even establish notifications for changes. Mission accomplished! Now I can test the coverage of our equipment. The last thing that would make me super happy, a oxidized Debian package!

25 January 2016

Antoine Beaupr : Internet in Cuba

A lot has been written about the Internet in Cuba over the years. I have read a few articles, from New York Times' happy support for Google's invasion of Cuba to RSF's dramatic and fairly outdated report about censorship in Cuba. Having written before about Internet censorship in Tunisia, I was curious to see if I could get a feel of what it is like over there, now that a new Castro is in power and the Obama administration has started restoring diplomatic ties with Cuba. With those political changes coming signifying the end of an embargo that has been called genocidal by the Cuban government, it is surprisingly difficult to get fresh information about the current state of affairs. This article aims to fill that gap in clarifying how the internet works in Cuba, what kind of censorship mechanisms are in place and how to work around them. It also digs more technically into the network architecture and performance. It is published in the hope of providing both Cubans and the rest of the world with a better understanding of their network and, if possible, Cubans ways to access the internet more cheaply or without censorship.

"Censorship" and workarounds Unfortunately, I have been connected to the internet only through the the Varadero airport and the WiFi of a "full included" resort near Jibacoa. I have to come to assume that this network is likely to be on a segregated, uncensored internet while the rest of the country suffers the wrath of the Internet censorship in Cuba I have seen documented elsewhere. Through my research, I couldn't find any sort of direct censorship. The Netalyzr tool couldn't find anything significantly wrong with the connection, other than the obvious performance problems related both to the overloaded uplinks of the Cuban internet. I ran an incomplete OONI probe as well, and it seems there was no obvious censorship detected there as well, at least according to folks in the helpful #ooni IRC channel. Tor also works fine, and could be a great way to avoid the global surveillance system described later in this article. Nevertheless, it still remains to be seen how the internet is censored in the "real" Cuban internet, outside of the tourist designated areas - hopefully future visitors or locals can expand on this using the tools mentioned above, using the regular internet. Usual care should be taken when using any workaround tools, mentioned in this post or not, as different regimes over the world have accused, detained, tortured and killed sometimes for the mere fact of using or distributing circumvention tools. For example, a Russian developer was arrested and detained in 2001 by United States' FBI for exposing vulnerabilities in the Adobe e-books copy protection mechanisms. Similarly, people distributing Tor and other tools have been arrested during the period prior to the revolution in Tunisia.

The Cuban captive portal There is, however, a more pernicious and yet very obvious censorship mechanism at work in Cuba: to get access to the internet, you have to go through what seems to be a state-wide captive portal, which I have seen both at the hotel and the airport. It is presumably deployed at all levels of the internet access points. To get credentials through that portal, you need a username and password which you get by buying a Nauta card. Those cards cost 2$CUC and get you an hour of basically unlimited internet access. That may not seem like a lot for a rich northern hotel party-goer, but for Cubans, it's a lot of money, given that the average monthly salary is around 20$CUC. The system is also pretty annoying to use, because it means you do not get continuous network access: every hour, you need to input a new card, which will obviously make streaming movies and other online activities annoying. It also makes hosting servers basically impossible. So while Cuba does not have, like China or Iran, a "great firewall", there is definitely a big restriction to going online in Cuba. Indeed, it seems to be how the government ensures that Cubans do not foment too much dissent online: keep the internet slow and inaccessible, and you won't get too many Arab spring / blogger revolutions.

Bypassing the Cuban captive portal The good news is that it is perfectly possible for Cubans (or at least for a tourist like me with resources outside of the country) to bypass the captive portal. Like many poorly implemented portals, the portal allows DNS traffic to go through, which makes it possible to access the global network for free by using a tool like iodine which tunnels IP traffic over DNS requests. Of course, the bandwidth and reliability of the connection you get through such a portal is pretty bad. I have regularly seen 80% packet loss and over two minutes of latency:
--- 10.0.0.1 ping statistics ---
163 packets transmitted, 31 received, 80% packet loss, time 162391ms
rtt min/avg/max/mdev = 133.700/2669.535/64188.027/11257.336 ms, pipe 65
Still, it allowed me to login to my home server through SSH using Mosh to workaround the reliability issues. Every once in a while, mosh would get stuck and keep on trying to send packets to probe the server, which would clog the connection even more. So I regularly had to restart the whole stack using these commands:
killall iodine # stop DNS tunnel
nmcli n off # turn off wifi to change MAC address
macchanger -A wlan0 # change MAC address
nmcli n on # turn wifi back on
sleep 3 # wait for wifi to settle
iodine-client-start # restart DNS tunnel
The Koumbit Wiki has good instructions on how to setup a DNS tunnel. I am wondering if such a public service could be of use for Cubans, although I am not sure how it could be deployed only for Cubans, and what kind of traffic it could support... The fact is that iodine does require a server to operate, and that server must be run on the outside of the censored perimeter, something that Cubans may not be able to afford in the first place. Another possible way to save money with the captive portal would be to write something that automates connecting and disconnecting from the portal. You would feed that program a list of credentials and it would connect to the portal only on demand, and disconnect as soon as no traffic goes through. There are details on the implementation of the captive portal below that may help future endeavours in that field.

Private information revealed to the captive portal It should be mentioned, however, that the captive portal has a significant amount of information on clients, which is a direct threat to the online privacy of Cuban internet users. Of course the unique identifiers issued with the Nauta cards can be correlated with your identity, right from the start. For example, I had to give my room number to get a Nauta card issued. Then the central portal also knows which access point you are connected to. For example, the central portal I was connected to Wifi_Memories_Jibacoa which, for anyone that cares to research, will give them a location of about 20 square meters where I was located when connected (there is only one access point in the whole hotel). Finally, the central portal also knows my MAC address, a unique identifier for the computer I am using which also reveals which brand of computer I am using (Mac, Lenovo, etc). While this address can be changed, very few people know that, let alone how. This led me to question whether I would be allowed back in Cuba (or even allowed out!) after publishing this blog post, as it is obvious that I can be easily identified based on the time this article was published, my name and other details. Hopefully the Cuban government will either not notice or not care, but this can be a tricky situation, obviously. I have heard that Cuban prisons are not the best hangout place in Cuba, to say the least...

Network configuration assessment This section is more technical and delves more deeply in the Cuban internet to analyze the quality and topology of the network, along with hints as to which hardware and providers are being used to support the Cuban government.

Line quality The internet is actually not so bad in the hotel. Again, this may be because of the very fact that I am in that hotel, and I get a privileged access to the new fiber line to Venezuela, the ALBA-1 link. The line speed I get is around 1mbps, according to speedtest, which selected a server from LIME in George Town, Cayman Islands:
[1034]anarcat@angela:cuba$ speedtest
Retrieving speedtest.net configuration...
Retrieving speedtest.net server list...
Testing from Empresa de Telecomunicaciones de Cuba (152.206.92.146)...
Selecting best server based on latency...
Hosted by LIME (George Town) [391.78 km]: 317.546 ms
Testing download speed........................................
Download: 1.01 Mbits/s
Testing upload speed..................................................
Upload: 1.00 Mbits/s
Latency to the rest of the world is of couse slow:
--- koumbit.org ping statistics ---
122 packets transmitted, 120 received, 1,64% packet loss, time 18731,6ms
rtt min/avg/max/sdev = 127,457/156,097/725,211/94,688 ms
--- google.com ping statistics ---
122 packets transmitted, 121 received, 0,82% packet loss, time 19371,4ms
rtt min/avg/max/sdev = 132,517/160,095/724,971/93,273 ms
--- redcta.org.ar ping statistics ---
122 packets transmitted, 120 received, 1,64% packet loss, time 40748,6ms
rtt min/avg/max/sdev = 303,035/339,572/965,092/97,503 ms
--- ccc.de ping statistics ---
122 packets transmitted, 72 received, 40,98% packet loss, time 19560,2ms
rtt min/avg/max/sdev = 244,266/271,670/594,104/61,933 ms
Interestingly, Koumbit is actually the closest host in the above test. It could be that Canadian hosts are less affected by bandwidth problems compared to US hosts because of the embargo.

Network topology The various traceroutes show a fairly odd network topology, but that is typical of what I would described as "colonized internet users", which have layers and layers of NAT and obscure routing that keep them from the real internet. Just like large corporations are implementing NAT in a large scale, Cuba seems to have layers and layers of private RFC 1918 IPv4 space. A typical traceroute starts with:
traceroute to koumbit.net (199.58.80.33), 30 hops max, 60 byte packets
 1  10.156.41.1 (10.156.41.1)  9.724 ms  9.472 ms  9.405 ms
 2  192.168.134.137 (192.168.134.137)  16.089 ms  15.612 ms  15.509 ms
 3  172.31.252.113 (172.31.252.113)  15.350 ms  15.805 ms  15.358 ms
 4  pos6-0-0-agu-cr-1.mpls.enet.cu (172.31.253.197)  15.286 ms  14.832 ms  14.405 ms
 5  172.31.252.29 (172.31.252.29)  13.734 ms  13.685 ms  14.485 ms
 6  200.0.16.130 (200.0.16.130)  14.428 ms  11.393 ms  10.977 ms
 7  200.0.16.74 (200.0.16.74)  10.738 ms  10.019 ms  10.326 ms
 8  ix-11-3-1-0.tcore1.TNK-Toronto.as6453.net (64.86.33.45)  108.577 ms  108.449 ms
Let's take this apart line by line:
 1  10.156.41.1 (10.156.41.1)  9.724 ms  9.472 ms  9.405 ms
This is my local gateway, probably the hotel's wifi router.
 2  192.168.134.137 (192.168.134.137)  16.089 ms  15.612 ms  15.509 ms
This is likely not very far from the local gateway, probably still in Cuba. It in one bit away from the captive portal IP address (see below) so it is very likely related to the captive portal implementation.
 3  172.31.252.113 (172.31.252.113)  15.350 ms  15.805 ms  15.358 ms
 4  pos6-0-0-agu-cr-1.mpls.enet.cu (172.31.253.197)  15.286 ms  14.832 ms  14.405 ms
 5  172.31.252.29 (172.31.252.29)  13.734 ms  13.685 ms  14.485 ms
All those are withing RFC 1918 space. Interestingly, the Cuban DNS servers resolve one of those private IPs as within Cuban space, on line #4. That line is interesting because it reveals the potential use of MPLS.
 6  200.0.16.130 (200.0.16.130)  14.428 ms  11.393 ms  10.977 ms
 7  200.0.16.74 (200.0.16.74)  10.738 ms  10.019 ms  10.326 ms
Those two lines are the only ones that actually reveal that the route belongs in Cuba at all. Both IPs are in a tiny (/24, or 256 IP addresses) network allocated to ETECSA, the state telco in Cuba:
inetnum:     200.0.16/24
status:      allocated
aut-num:     N/A
owner:       EMPRESA DE TELECOMUNICACIONES DE CUBA S.A. (IXP CUBA)
ownerid:     CU-CUBA-LACNIC
responsible: Rafael L pez Guerra
address:     Ave. Independencia y 19 Mayo, s/n,
address:     10600 - La Habana - CH
country:     CU
phone:       +53 7 574242 []
owner-c:     JOQ
tech-c:      JOQ
abuse-c:     JEM52
inetrev:     200.0.16/24
nserver:     NS1.NAP.ETECSA.NET
nsstat:      20160123 AA
nslastaa:    20160123
nserver:     NS2.NAP.ETECSA.NET
nsstat:      20160123 AA
nslastaa:    20160123
created:     20030512
changed:     20140610
Then the last hop:
 8  ix-11-3-1-0.tcore1.TNK-Toronto.as6453.net (64.86.33.45)  108.577 ms  108.449 ms  108.257 ms
...interestingly, lands directly in Toronto, in this case going later to Koumbit but that is the first hop that varies according to the destination, hops 1-7 being a common trunk to all external communications. It's also interesting that this shoves a good 90 milliseconds extra in latency, showing that a significant distance and number of equipment crossed. Yet a single hop is crossed, not showing the intermediate step of the Venezuelan link or any other links for that matter. Something obscure is going on there... Also interesting to note is the traceroute to the redirection host, which is only one hop away:
traceroute to 192.168.134.138 (192.168.134.138), 30 hops max, 60 byte packets
 1  192.168.134.138 (192.168.134.138)  6.027 ms  5.698 ms  5.596 ms
Even though it is not the gateway:
$ ip route
default via 10.156.41.1 dev wlan0  proto static  metric 1024
10.156.41.0/24 dev wlan0  proto kernel  scope link  src 10.156.41.4
169.254.0.0/16 dev wlan0  scope link  metric 1000
This means a very close coordination between the different access points and the captive portal system. Finally, note that there seems to be only three peers to the Cuban internet: Teleglobe, formerly Canadian, now owned by the Indian [[!wiki Tata group]], and Telef nica, the Spanish Telco that colonized most of Latin America's internet, all the way down to Argentina. This is confirmed by my traceroutes, which show traffic to Koumbit going through Tata and Google's going through Telef nica.

Captive portal implementation The captive portal is https://www.portal-wifi-temas.nauta.cu/ (not accessible outside of Cuba) and uses a self-signed certificate. The domain name resolves to 190.6.81.230 in the hotel. Accessing http://1.1.1.1/ gives you a status page which allows you to disconnect from the portal. It actually redirects you to https://192.168.134.138/logout.user. That is also a self-signed, but different certificate. That certificate actually reveals the implication of Gemtek which is a "world-leading provider of Wireless Broadband solutions, offering a wide range of solutions from residential to business". It is somewhat unclear if the implication of Gemtek here is deliberate or a misconfiguration on the part of Cuban officials, especially since the certificate is self-signed and was issued in 2002. It could be, however, a trace of the supposed involvement of China in the development of Cuba's networking systems, although Gemtek is based in Taiwan, and not in the China mainland. That IP, in turn, redirects you to the same portal but in a page that shows you the statistics:
https://www.portal-wifi-temas.nauta.cu/?mac=0024D1717D18&script=logout.user&remain_time=00%3A55%3A52&session_time=00%3A04%3A08&username=151003576287&clientip=10.156.41.21&nasid=Wifi_Memories_Jibacoa&r=ac%2Fpopup
Notice how you see the MAC address of the machine in the URL (randomized, this is not my MAC address), along with the remaining time, session time, client IP and the Wifi access point ESSID. There may be some potential in defrauding the session time there, I haven't tested it directly. Hitting Actualizar redirects you back to the IP address, which redirects you to the right URL on the portal. The "real" logout is at:
http://192.168.134.138/logout.user?cmd=logout
The login is performed against https://www.portal-wifi-temas.nauta.cu/index.php?r=ac/login with a referer of:
https://www.portal-wifi-temas.nauta.cu/?&nasid=Wifi_Memories_Jibacoa&nasip=192.168.134.138&clientip=10.156.41.21&mac=EC:55:F9:C5:F2:55&ourl=http%3a%2f%2fgoogle.ca%2f&sslport=443&lang=en-US%2cen%3bq%3d0.8&lanip=10.156.41.1
Again, notice the information revealed to the central portal.

Equipment and providers I ran Nmap probes against both the captive portal and the redirection host, in the hope of finding out how they were built and if they could reveal the source of the equipment used. The complete nmap probes are available in nmap, but it seems that the captive portal is running some embedded device. It is confusing because the probe for the captive portal responds as if it was the gateway, which blurs even more the distinction between the hotel's gateway and the captive portal. This raises the distinct possibility that all access points are actually captive portal that authenticate to another central server. The nmap traces do show three distinct hosts however:
  • the captive portal (www.portal-wifi-temas.nauta.cu, 190.6.81.230)
  • some redirection host (192.168.134.138)
  • the hotel's gateway (10.156.41.1)
They do have distinct signatures so the above may be just me misinterpreting traceroute and nmap results. Your comments may help in clarifying the above. Still, the three devices show up as running Linux, in the two last cases versions between 2.4.21 and 2.4.31. Now, to find out which version of Linux it is running is way more challenging, and it is possible it is just some custom Linux distribution. Indeed, the webserver shows up as G4200.GSI.2.22.0155 and the SSH server is running OpenSSH 3.0.2p1, which is basically prehistoric (2002!) which corroborates the idea that this is some Gemtek embedded device. The fact that those devices are running 14 years old software should be a concern to the people responsible for those networks. There is, for example, a remote root vulnerability that affects that specific version of OpenSSH, among many other vulnerabilities.

A note on Nauta card's security Finally, one can note that it is probably trivial to guess card UIDs. All cards i have here start with the prefix 15100, the following digits being 3576 or 4595, presumably depending on the "batch" that was sent to different hotels, which seems to be batches of 1000 cards. You can also correlate the UID with the date at which the card was issued. For example, 15100357XXX cards are all valid until 19/03/2017, and 151004595XXX cards are all valid until 23/03/2017. Here's the list of UIDs I have seen:
151004595313
151004595974
151003576287
151003576105
151003576097
The passwords, on the other hand, do seem fairly random (although my sample size is small). Interestingly, those passwords are also 12 digits long, which is about as strong as a seven-letter password (mixed uppercase and lowercase). If there are no rate-limiting provisions on that captive portal, it could be possible to guess those passwords, since you have free rein on accessing those routers. Depending on the performance of the routers, you could be lucky and find a working password for free...

Conclusion Clearly, Internet access in Cuba needs to be modernized. We can clearly see that Cuba years behind the rest of the Americas, if only through the percentage of the population with internet access, or download speeds. The existence of a centralized captive portal also enables a huge surveillance potential that should be a concern for any Cuban, or for that matter, anyone wishing to live in a free society. The answer, however, lies not in the liberalization of commerce and opening the doors to the US companies and their own systems of surveillance. It should be possible, and even desirable for Cubans to establish their own neutral network, a proposal I have made in the past even for here in Qu bec. This network could be used and improved by Cubans themselves, prioritizing local communities that would establish their own infrastructure according to their own needs. I have been impressed by this article about the El Paquete system - it shows great innovation and initiative from Cubans which are known for engaging in technology in a creative way. This should be leveraged by letting Cubans do what they want with their networks, not telling them what to do. The best the Googles of this world can do to help Cuba is not to colonize Cuba's technological landscape but to cleanup their own and make their own tools more easily accessible and shareable offline. It is something companies can do right now, something I detailed in a previous article.

23 January 2016

Dirk Eddelbuettel: RcppCCTZ 0.0.3

Bradley White from the upstream CCTZ team prepared some more changes in CCTZ itself -- so a new RcppCCTZ version got to CRAN the other day catching up with these changes. CCTZ is a C++ library for translating between absolute and civil times using the rules of a time zone. It requires only a proper C++11 compiler and the standard IANA time zone data base which standard Unix, Linux, OS X, ... computers tend to have in /usr/share/zoneinfo. RcppCCTZ connects this library to R by relying on Rcpp. Changes in this version are summarized here:
Changes in version 0.0.3 (2016-01-17)
  • Synchronized with CCTZ upstream.
We also have a diff to the previous version thanks to CRANberries. More details, issue tickets etc at the GitHub repository.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

21 January 2016

Jonathan Dowland: Network Attached Storage

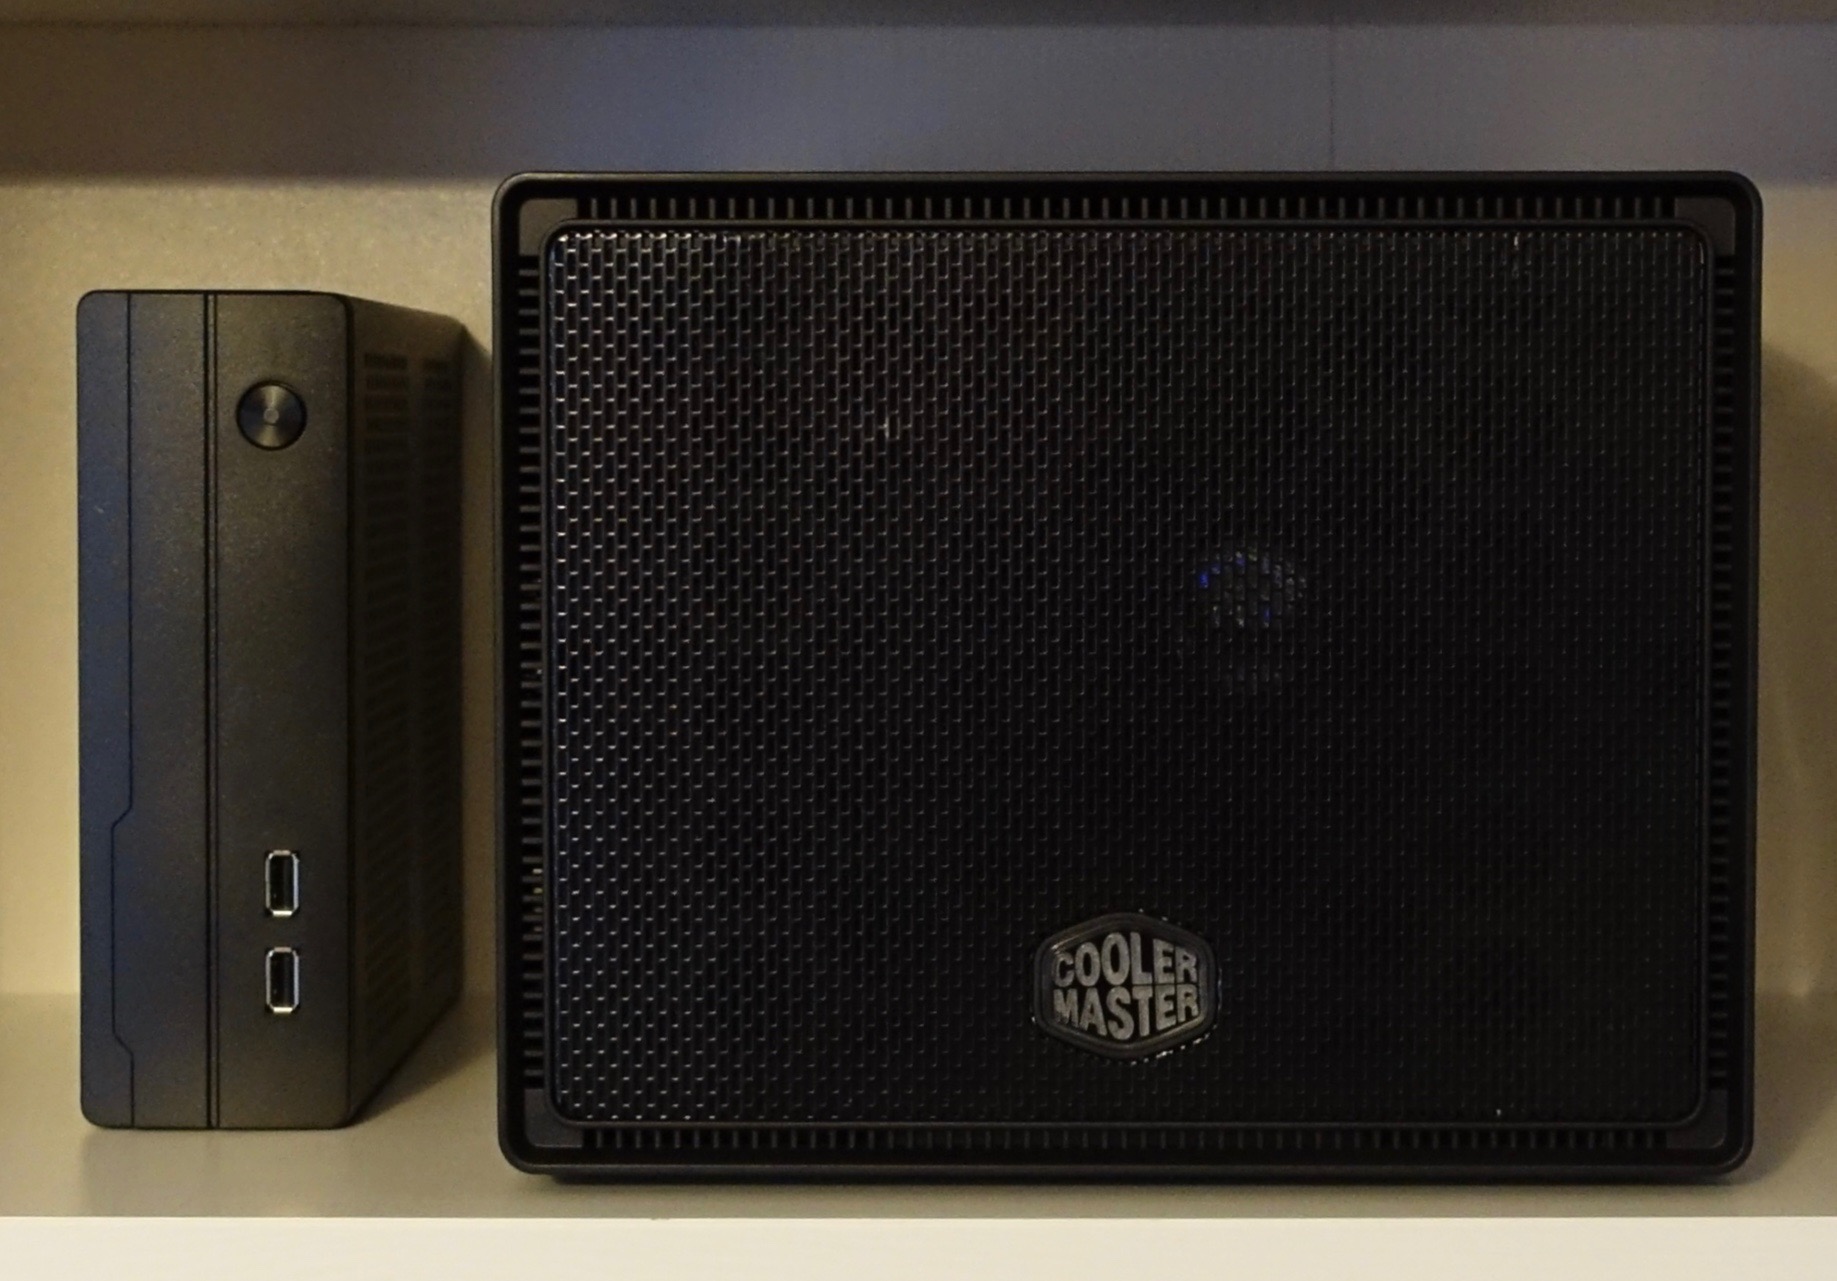
little and large little and large
I've just upgraded my home Network Storage box. Until now, it was very discreet, about the size of a car radio. It lived on one of my bookcases and I was very happy with it but it could only take 2.5" sized hard drives and I've outgrown what you can fit on them. I've ended up moving to 2x4T 3.5" drives, a Coolermaster Elite 110 case and re-using the mainboard/CPU and RAM. This is hopefully enough capacity that I don't need to look at another upgrade for a few years, and the case could take more drives if I need it to. The Elite 110 is - by Mini-ITX case terms - pretty small, but still 6 times larger in volume than the old case. In the consumer NAS market, there are plenty of appliances that takes two 3.5" drives and are much smaller than that (such as the WD MyBook Duo, or Synology DS214). Unfortunately I could not find any cases that were of this size for a DIY build. Did I miss anything obvious? (As to why I choose DIY, that could be the subject for a future post.) The full boring details of the build are on the NAS system page.

Jonas Smedegaard: IT@school

Siri and I are on a journey through India and Nepal, with the aim of learning about needs of Debian derivatives, to improve Debian and encourage closer integration.

Distribution IT@school is a distribution originally based on Debian, later rebased on Ubuntu. Next release will possibly again be a direct derivative of Debian, or maybe even - time will tell - a Debian pure blend.

Aim is education As its name indicates, IT@school is targeted at schools: The system is used in 8th - 10th grades of most (or all?) public primary schools in Kerala, Together with KEK members Anto and Fayad, Siri and I met with former and current key participants in the project where we learned about its history and current status, and discussed some differences between Ubuntu and Debian. IT@school has a strong emphasis on the educational aspect, arguably setting it apart from Skolelinux/DebianEdu which emphasizes the technical aspect of relieving teachers from admin tasks. In the early years of deployment the project faced many hardware issues - e.g. in getting sound cards to work. This was seen not as problems but as beneficial learning for the teachers facing those issues. Kerala public school system has set the standard for other states in India, but sadly political support within the state has been weak in recent years. It is hoped that next election - this April - will bring a positive change.

School book IT@school is accompagnied by a school book written specifically for use of the included tools. No explicit license is applied to the book (which means it defaults to classic copyright). Possibly it will get Creative Commons licensed. If the school book gets a DFSG-free license, several collaboration opportunities emerge: Currently the book is drafted in LibreOffice but then - due to state procedures - finalized with PageMaker. Would be interesting to setup an alternate process using only Free tools - either with Scribus or XeLaTeX. An important detail here is to ensure that the process supports malayalam script.

Curriculum Work is in progress mapping FLOSS tools to the state curriculum. I recommended to share that work publicly with a Free license, to encourage comparisons across countries, and invite collaboration e.g. with Skolelunux/DebianEdu.

Blend for SBCs Some Kerala higher education schools (sorry, don't remember which) have bought some thousands of RaspberryPi2. I suggested to create a Debian Blend for SBCs (Single Board Computers) - we will see what comes of that idea

Blend for education I also suggested to make a Debian blend around IT@school distribution itself, with its strong focus on educational content - i.e. not just as addon to technical tools but the primary purpose pulling in tools as needed.

19 January 2016

Joey Hess: git-annex v6

Version 6 of git-annex, released last week, adds a major new feature; support for unlocked large files that can be edited as usual and committed using regular git commands. For example:
git init
git annex init --version=6
mv ~/foo.iso .
git add foo.iso
git commit -m "added hundreds of megabytes to git annex (not git)"
git remote add origin ssh://sever/dir
git annex sync origin --content # uploads foo.iso
Compare that with how git-annex has worked from the beginning, where git annex add is used to add a file, and then the file is locked, preventing further modifications of it. That is still a very useful way to use git-annex for many kinds of files, and is still supported of course. Indeed, you can easily switch files back and forth between being locked and unlocked. This new unlocked file mode uses git's smudge/clean filters, and I was busy developing it all through December. It started out playing catch-up with git-lfs somewhat, but has significantly surpassed it now in several ways. So, if you had tried git-annex before, but found it didn't meet your needs, you may want to give it another look now.
Now a few thoughts on git-annex vs git-lfs, and different tradeoffs made by them. After trying it out, my feeling is that git-lfs brings an admirable simplicity to using git with large files. File contents are automatically uploaded to the server when a git branch is pushed, and downloaded when a branch is merged, and after setting it up, the user may not need to change their git workflow at all to use git-lfs. But there are some serious costs to that simplicity. git-lfs is a centralized system. This is especially problimatic when dealing with large files. Being a decentralized system, git-annex has a lot more flexability, like transferring large file contents peer-to-peer over a LAN, and being able to choose where large quantities of data are stored (maybe in S3, maybe on a local archive disk, etc). The price git-annex pays for this flexability is you have to configure it, and run some additional commands. And, it has to keep track of what content is located where, since it can't assume the answer is "in the central server". The simplicity of git-lfs also means that the user doesn't have much control over what files are present in their checkout of a repository. git-lfs downloads all the files in the work tree. It doesn't have facilities for dropping the content of some files to free up space, or for configuring a repository to only want to get a subset of files in the first place. On the other hand, git-annex has excellent support for all those things, and this comes largely for free from its decentralized design. If git has showed us anything, it's perhaps that a little added complexity to support a fully distributed system won't prevent people using it. Even if many of them end up using it in a mostly centralized way. And that being decentralized can have benefits beyond the obvious ones.
Oh yeah, one other advantage of git-annex over git-lfs. It can use half as much disk space! A clone of a git-lfs repository contains one copy of each file in the work tree. Since the user can edit that file at any time, or checking out a different branch can delete the file, it also stashes a copy inside .git/lfs/objects/. One of the main reasons git-annex used locked files, from the very beginning, was to avoid that second copy. A second local copy of a large file can be too expensive to put up with. When I added unlocked files in git-annex v6, I found it needed a second copy of them, same as git-lfs does. That's the default behavior. But, I decided to complicate git-annex with a config setting:
git config annex.thin true
git annex fix
Run those two commands, and now only one copy is needed for unlocked files! How's it work? Well, it comes down to hard links. But there is a tradeoff here, which is why this is not the default: When you edit a file, no local backup is preserved of its old content. So you have to make sure to let git-annex upload files to another repository before editing them or the old version could get lost. So it's a tradeoff, and maybe it could be improved. (Only thin out a file after a copy has been uploaded?) This adds a small amount of complexity to git-annex, but I feel it's well worth it to let unlocked files use half the disk space. If the git-lfs developers are reading this, that would probably be my first suggestion for a feature to consider adding to git-lfs. I hope for more opportunities to catch-up to git-lfs in turn.

18 January 2016

David Pashley: NullPointerExceptions in Xerces-J

Xerces is an XML library for several languages, but if a very common library in Java. I recently came across a problem with code intermittently throwing a NullPointerException inside the library:
java.lang.NullPointerException
        at org.apache.xerces.dom.ParentNode.nodeListItem(Unknown Source)
        at org.apache.xerces.dom.ParentNode.item(Unknown Source)
        at com.example.xml.Element.getChildren(Element.java:377)
        at com.example.xml.Element.newChildElementHelper(Element.java:229)
        at com.example.xml.Element.newChildElement(Element.java:180)
         
 
You may also find the NullPointerException in ParentNode.nodeListGetLength() and other locations in ParentNode. Debugging this was not helped by the fact that the xercesImpl.jar is stripped of line numbers, so I couldn t find the exact issue. After some searching, it appeared that the issue was down to the fact that Xerces is not thread-safe. ParentNode caches iterations through the NodeList of children to speed up performance and stores them in the Node s Document object. In multi-threaded applications, this can lead to race conditions and NullPointerExceptions. And because it s a threading issue, the problem is intermittent and hard to track down. The solution is to synchronise your code on the DOM, and this means the Document object, everywhere you access the nodes. I m not certain exactly which methods need to be protected, but I believe it needs to be at least any function that will iterate a NodeList. I would start by protecting every access and testing performance, and removing some if needed.
/**
 * Returns the concatenation of all the text in all child nodes
 * of the current element.
 */
public String getText()  
StringBuilder result = new StringBuilder();
 
synchronized ( m_element.getOwnerDocument())  
NodeList nl = m_element.getChildNodes();
for (int i = 0; i < nl.getLength(); i++)  
Node n = nl.item(i);
 
if (n != null && n.getNodeType() == org.w3c.dom.Node.TEXT_NODE)  
result.append(((CharacterData) n).getData());


return result.toString();
 
Notice the synchronized ( m_element.getOwnerDocument()) block around the section that deals with the DOM. The NPE would normally be thrown on the nl.getLength() or nl.item() calls. Since putting in the synchronized blocks, we ve gone from having 78 NPEs between 2:30am and 3:00am, to having zero in the last 12 hours, so I think it s safe to say, this has drastically reduced the problem. The post NullPointerExceptions in Xerces-J appeared first on David Pashley.com.

13 January 2016

Norbert Preining: Ian Buruma: Wages of Guilt

Since moving to Japan, I got more and more interested in history, especially the recent history of the 20th century. The book I just finished, Ian Buruma (Wiki, home page) Wages of Guilt Memories of War in Germany and Japan (Independent, NYRB), has been a revelation for me. As an Austrian living in Japan, I am experiencing the discrepancy between these two countries with respect to their treatment of war legacy practically daily, and many of my blog entries revolve around the topic of Japanese non-reconciliation.
Willy Brandt went down on his knees in the Warsaw ghetto, after a functioning democracy had been established in the Federal Republic of Germany, not before. But Japan, shielded from the evil world, has grown into an Oskar Matzerath: opportunistic, stunted, and haunted by demons, which it tries to ignore by burying them in the sand, like Oskar s drum.
Ian Buruma, Wages of Guilt, Clearing Up the Ruins
Buruma-Wages_of_Guilt The comparison of Germany and Japan with respect to their recent history as laid out in Buruma s book throws a spotlight on various aspects of the psychology of German and Japanese population, while at the same time not falling into the easy trap of explaining everything with difference in the guilt culture. A book of great depth and broad insights everyone having even the slightest interest in these topics should read.
This difference between (West) German and Japanese textbooks is not just a matter of detail; it shows a gap in perception.
Ian Buruma, Wages of Guilt, Romance of the Ruins
Only thinking about giving a halfway full account of this book is something impossible for me. The sheer amount of information, both on the German and Japanese side, is impressive. His incredible background (studies of Chinese literature and Japanese movie!) and long years as journalist, editor, etc, enriches the book with facets normally not available: In particular his knowledge of both the German and Japanese movie history, and the reflection of history in movies, were complete new aspects for me (see my recent post (in Japanese)). The book is comprised of four parts: The first with the chapters War Against the West and Romance of the Ruins; the second with the chapters Auschwitz, Hiroshima, and Nanking; the third with History on Trial, Textbook Resistance, and Memorials, Museums, and Monuments; and the last part with A Normal Country, Two Normal Towns, and Clearing Up the Ruins. Let us look at the chapters in turn: The boook somehow left me with a bleak impression of Japanese post-war times as well as Japanese future. Having read other books about the political ignorance in Japan (Norma Field s In the realm of a dying emperor, or the Chibana history), Buruma s characterization of Japanese politics is striking. He couldn t foresee the recent changes in legislation pushed through by the Abe government actually breaking the constitution, or the rewriting of history currently going on with respect to comfort women and Nanking. But reading his statement about Article Nine of the constitution and looking at the changes in political attitude, I am scared about where Japan is heading to:
The Nanking Massacre, for leftists and many liberals too, is the main symbol of Japanese militarism, supported by the imperial (and imperialist) cult. Which is why it is a keystone of postwar pacifism. Article Nine of the constitution is necessary to avoid another Nanking Massacre. The nationalist right takes the opposite view. To restore the true identity of Japan, the emperor must be reinstated as a religious head of state, and Article Nine must be revised to make Japan a legitimate military power again. For this reason, the Nanking Massacre, or any other example of extreme Japanese aggression, has to be ignored, softened, or denied.
Ian Buruma, Wages of Guilt, Nanking
While there are signs of resistance in the streets of Japan (Okinawa and the Hanako bay, the demonstrations against secrecy law and reversion of the constitution), we are still to see a change influenced by the people in a country ruled and distributed by oligarchs. I don t think there will be another Nanking Massacre in the near future, but Buruma s books shows that we are heading back to a nationalistic regime similar to pre-war times, just covered with a democratic veil to distract critics.
I close with several other quotes from the book that caught my attention: In the preface and introduction:
[ ] mainstream conservatives made a deliberate attempt to distract people s attention from war and politics by concentrating on economic growth.
The curious thing was that much of what attracted Japanese to Germany before the war Prussian authoritarianism, romantic nationalism, pseudo-scientific racialism had lingered in Japan while becoming distinctly unfashionable in Germany.
In Romance of the Ruins:
The point of all this is that Ikeda s promise of riches was the final stage of what came to be known as the reverse course, the turn away from a leftist, pacifist, neutral Japan a Japan that would never again be involved in any wars, that would resist any form of imperialism, that had, in short, turned its back for good on its bloody past. The Double Your Incomes policy was a deliberate ploy to draw public attention away from constitutional issues.
In Hiroshima:
The citizens of Hiroshima were indeed victims, primarily of their own military rulers. But when a local group of peace activists petitioned the city of Hiroshima in 1987 to incorporate the history of Japanese aggression into the Peace Memorial Museum, the request was turned down. The petition for an Aggressors Corner was prompted by junior high school students from Osaka, who had embarrassed Peace Museum officials by asking for an explanation about Japanese responsibility for the war.
The history of the war, or indeed any history, is indeed not what the Hiroshima spirit is about. This is why Auschwitz is the only comparison that is officially condoned. Anything else is too controversial, too much part of the flow of history .
In Nanking, by the governmental pseudo-historian Tanaka:
Unlike in Europe or China, writes Tanaka, you won t find one instance of planned, systematic murder in the entire history of Japan. This is because the Japanese have a different sense of values from the Chinese or the Westerners.
In History on Trial:
In 1950, Becker wrote that few things have done more to hinder true historical self-knowledge in Germany than the war crimes trials. He stuck to this belief. Becker must be taken seriously, for he is not a right-wing apologist for the Nazi past, but an eminent liberal.
There never were any Japanese war crimes trials, nor is there a Japanese Ludwigsburg. This is partly because there was no exact equivalent of the Holocaust. Even though the behavior of Japanese troops was often barbarous, and the psychological consequences of State Shinto and emperor worship were frequently as hysterical as Nazism, Japanese atrocities were part of a military campaign, not a planned genocide of a people that included the country s own citizens. And besides, those aspects of the war that were most revolting and furthest removed from actual combat, such as the medical experiments on human guinea pigs (known as logs ) carried out by Unit 731 in Manchuria, were passed over during the Tokyo trial. The knowledge compiled by the doctors of Unit 731 of freezing experiments, injection of deadly diseases, vivisections, among other things was considered so valuable by the Americans in 1945 that the doctors responsible were allowed to go free in exchange for their data.
Some Japanese have suggested that they should have conducted their own war crimes trials. The historian Hata Ikuhiko thought the Japanese leaders should have been tried according to existing Japanese laws, either in military or in civil courts. The Japanese judges, he believed, might well have been more severe than the Allied tribunal in Tokyo. And the consequences would have been healthier. If found guilty, the spirits of the defendants would not have ended up being enshrined at Yasukuni. The Tokyo trial, he said, purified the crimes of the accused and turned them into martyrs. If they had been tried in domestic courts, there is a good chance the real criminals would have been flushed out.
After it was over, the Nippon Times pointed out the flaws of the trial, but added that the Japanese people must ponder over why it is that there has been such a discrepancy between what they thought and what the rest of the world accepted almost as common knowledge. This is at the root of the tragedy which Japan brought upon herself.
Emperor Hirohito was not Hitler; Hitler was no mere Shrine. But the lethal consequences of the emperor-worshipping system of irresponsibilities did emerge during the Tokyo trial. The savagery of Japanese troops was legitimized, if not driven, by an ideology that did not include a Final Solution but was as racialist as Hider s National Socialism. The Japanese were the Asian Herrenvolk, descended from the gods.
Emperor Hirohito, the shadowy figure who changed after the war from navy uniforms to gray suits, was not personally comparable to Hitler, but his psychological role was remarkably similar.
In fact, MacArthur behaved like a traditional Japanese strongman (and was admired for doing so by many Japanese), using the imperial symbol to enhance his own power. As a result, he hurt the chances of a working Japanese democracy and seriously distorted history. For to keep the emperor in place (he could at least have been made to resign), Hirohito s past had to be freed from any blemish; the symbol had to be, so to speak, cleansed from what had been done in its name.
In Memorials, Museums, and Monuments:
If one disregards, for a moment, the differences in style between Shinto and Christianity, the Yasukuni Shrine, with its relics, its sacred ground, its bronze paeans to noble sacrifice, is not so very different from many European memorials after World War I. By and large, World War II memorials in Europe and the United States (though not the Soviet Union) no longer glorify the sacrifice of the fallen soldier. The sacrificial cult and the romantic elevation of war to a higher spiritual plane no longer seemed appropriate after Auschwitz. The Christian knight, bearing the cross of king and country, was not resurrected. But in Japan, where the war was still truly a war (not a Holocaust), and the symbolism still redolent of religious exultation, such shrines as Yasukuni still carry the torch of nineteenth-century nationalism. Hence the image of the nation owing its restoration to the sacrifice of fallen soldiers.
In A Normal Country:
The mayor received a letter from a Shinto priest in which the priest pointed out that it was un-Japanese to demand any more moral responsibility from the emperor than he had already taken. Had the emperor not demonstrated his deep sorrow every year, on the anniversary of Japan s surrender? Besides, he wrote, it was wrong to have spoken about the emperor in such a manner, even as the entire nation was deeply worried about his health. Then he came to the main point: It is a common error among Christians and people with Western inclinations, including so-called intellectuals, to fail to grasp that Western societies and Japanese society are based on fundamentally different religious concepts . . . Forgetting this premise, they attempt to place a Western structure on a Japanese foundation. I think this kind of mistake explains the demand for the emperor to bear full responsibility.
In Two Normal Towns:
The bust of the man caught my attention, but not because it was in any way unusual; such busts of prominent local figures can be seen everywhere in Japan. This one, however, was particularly grandiose. Smiling across the yard, with a look of deep satisfaction over his many achievements, was Hatazawa Kyoichi. His various functions and titles were inscribed below his bust. He had been an important provincial bureaucrat, a pillar of the sumo wrestling establishment, a member of various Olympic committees, and the recipient of some of the highest honors in Japan. The song engraved on the smooth stone was composed in praise of his rich life. There was just one small gap in Hatazawa s life story as related on his monument: the years from 1941 to 1945 were missing. Yet he had not been idle then, for he was the man in charge of labor at the Hanaoka mines.
In Clearing Up the Ruins:
But the question in American minds was understandable: could one trust a nation whose official spokesmen still refused to admit that their country had been responsible for starting a war? In these Japanese evasions there was something of the petulant child, stamping its foot, shouting that it had done nothing wrong, because everybody did it.
Japan seems at times not so much a nation of twelve-year-olds, to repeat General MacArthur s phrase, as a nation of people longing to be twelve-year-olds, or even younger, to be at that golden age when everything was secure and responsibility and conformity were not yet required.
For General MacArthur was right: in 1945, the Japanese people were political children. Until then, they had been forced into a position of complete submission to a state run by authoritarian bureaucrats and military men, and to a religious cult whose high priest was also formally chief of the armed forces and supreme monarch of the empire.
I saw Jew S ss that same year, at a screening for students of the film academy in Berlin. This showing, too, was followed by a discussion. The students, mostly from western Germany, but some from the east, were in their early twenties. They were dressed in the international uniform of jeans, anoraks, and work shirts. The professor was a man in his forties, a 68er named Karsten Witte. He began the discussion by saying that he wanted the students to concentrate on the aesthetics of the film more than the story. To describe the propaganda, he said, would simply be banal: We all know the what, so let s talk about the how. I thought of my fellow students at the film school in Tokyo more than fifteen years before. How many of them knew the what of the Japanese war in Asia.

12 January 2016

Antoine Beaupr : The Downloadable Internet

How corporations killed the web I have read with fascination what we would have called before a blog post, except it was featured on The Guardian: Iran's blogfather: Facebook, Instagram and Twitter are killing the web The "blogfather" is Hossein Derakshan or h0d3r, an author from Teheran that was jailed for almost a decade for his blogging. The article is very interesting both because it shows how fast things changed in the last few years, technology-wise, but more importantly, how content-free the web have become, where Facebook's last acquisition, Instagram, is not even censored by Iran. Those platforms have stopped being censored, not because of democratic progress but because they have become totally inoffensive (in the case of Iran) or become a tool of surveillance for the government and targeted advertisement for companies (in the case of, well, most of the world). This struck a chord, personally, at the political level: we are losing control of the internet (if we ever had it). The defeat isn't directly political: we have some institutions like ICANN and the IETF that we can still have an effect on, even if only at the technological level. The defeat is economic, and, of course, through economy comes enormous power. That defeat meant that we have first lost free and open access to the internet (yes, dialup used to be free) and then free hosting of our content (no, Google and Facebook are not free, you are the product). This marked a major change in the way content is treated online. H0d3r explains this as the shift from a link-based internet to a stream-based internet, a "deparure from a books-internet towards a television-internet". I have been warning about this "television-internet" in my talks and conversation for a while and with Netflix taking the crown off Youtube (and making you pay for it, of course), we can assuredly say that H0d3r is right and the television, far from disappearing, is finally being resurrected and taking over the internet.

The Downloadable internet and open standards But I would like to add to that: it is not merely that we had "links" before. We had, and still have, open standards. This made the internet "downloadable" (and by extension, uploadable) and decentralized. (In fact, I still remember my earlier days on the web when I would actually download images (as in "right-click" and "Save as..." images, not just have the browser download and display it on the fly). I would download images because they were big! It could take a minute or sometimes more to download images on older modems. Later, I would do the same with music: I would download WAV files before the rise of the MP3 format, of which I ended up building a significant collection (just fair use copies from friends and owned CDs, of course) and eventually video files.) The downloadable internet is what still allows me to type this article in a text editor, without internet access, while reading H0d3r's blog post on my e-reader, because I downloaded his article off an RSS feed. It is what makes it possible for anyone to download a full copy of this blog post and connected web pages as a git repository and this way get the full history of modifications on all the pages, but also be able to edit it offline and push modifications back in. Wikipedia is downloadable (there are even offline apps for your phone). Open standards like RSS feeds and HTML are downloadable. Heck, even the Internet Archive is downloadable (and I mean, all of it, not just the parts you want), surprisingly enough.

The app-based internet and proprietary software App-based websites like Google Plus and Facebook are not really downloadable. They are meant to be browsed through an app, so what you actually see through your web browser is really more an application, downloaded software than a downloaded piece of content. If you turn off Javascript, you will see that visiting Facebook actually shows no content: everything is downloaded on the fly by an application itself downloaded, on the fly, by your browser. In a way, your browser has become an operating system that runs proprietary, untrusted and unverified applications from the web. (The software is generally completely proprietary, except some frameworks that are published as free software in what looks like the lenient act of a godly king, but is actually more an economic decision of a clever corporation which outsources, for free, R&D and testing to the larger free software community. The real "secret sauce" is basically always proprietary, if only so that we don't freak out on stuff like PRISM that reports everything we do to the government.) Technology is political. This new "app design" is not a simple optimization or an cosmetic accident of a fancy engineer: by moving content through an application, Facebook, Twitter and the like can see exactly what you do on a web page, what you actually read (as opposed to what you click on) and how long. By adding a proprietary interface between you and the content online, the advertisement-surveillance complex can track every move you make online. This is a very fine-tuned surveillance system, and because of the App, you cannot escape it. You cannot share the content outside of Facebook, as you can't download it. Or at least, it's not obvious how you can. Projects like youtube-dl are doing an amazing job reverse-engineering what is becoming the proprietary Youtube streaming protocol, which is constantly changing and is not really documented. But it's a hack: it's a Sisyphus struggle which is bound to fail, and it does, all the time, until we figure out how to either turn those corporations into good netizens respecting and contributing to open standards (unlikely) or destroy those corporations (most likely). You are trapped in their walled garden. No wonder internet.org is Facebook only: for most people nowadays, the internet is the web, and the web is Facebook, Twitter and Google, or an iPad with a bunch of apps, each their own cute little walled garden, crafted just for you. If you think you like the Internet, you should really reconsider what you are watching, what you are consuming, or rather, how it is consuming you. There are alternatives. Facebook is a though nut to crack for free software activists because we lack the critical mass. But Facebook it is also an addiction for a lot of people, and spending less time on that spying machine could be a great improvement for you I am sure. For everything else, we have good free software alternatives and open standards, use them. "Big brother ain't watching you, you're watching him." - CRASS, Nineteen Eighty Bore (audio)

11 January 2016

Norbert Preining: 10 years TeX Live in Debian

I recently dug through my history of involvement with TeX (Live), and found out that in January there are a lot of anniversaries I should celebrate: 14 years ago I started building binaries for TeX Live, 11 years ago I proposed the packaging TeX Live for Debian, 10 years ago the TeX Live packages entered Debian. There are other things to celebrate next year (2017), namely the 10 year anniversary of the (not so new anymore) infrastructure in short tlmgr of TeX Live packaging, but this will come later. In this blog post I want to concentrate on my involvement in TeX Live and Debian. TeX Live/Debian Those of you not interested in boring and melancholic look-back onto history can safely skip reading this one. For those a bit interested in the history of TeX in Debian, please read on. Debian releases and TeX systems The TeX system of choice has been for long years teTeX, curated by Thomas Esser. Digging through the Debian Archive and combining it with changelog entries as well as personal experiences since I joined Debian, here is a time line of TeX in Debian, all to my best knowledge.
Date Version Name teTeX/TeX Live Maintainers
1993-96 <1 ? ? Christoph Martin
6/1996 1.1 Buzz ?
12/1996 1.2 Rec ?
6/1997 1.3 Bo teTeX 0.4
7/1998 2.0 Ham teTeX 0.9
3/1999 2.1 Slink teTeX 0.9.9N
8/2000 2.2 Potato teTeX 1.0
7/2002 3.0 Woody teTeX 1.0
6/2005 3.1 Sarge teTeX 2.0 Atsuhito Kohda
4/2007 4.0 Etch teTeX 3.0, TeX Live 2005 Frank K ster, NP
2/2009 5.0 Lenny TeX Live 2007 NP
2/2011 6.0 Squeeze TeX Live 2009
5/2013 7.0 Whezzy TeX Live 2012
4/2015 8.0 Jessie TeX Live 2014
??? ??? Stretch TeX Live 2015
The history of TeX in Debian is thus split more or less in 10 years teTeX, and 10 years TeX Live. While I cannot check back to the origins, my guesses are that already in the very first releases (te)TeX was included. The first release I can confirm (via the Debian archive) shipping teTeX is the release Bo (June 1997). Maintainership during the first 10 years showed some fluctuation: The first years/releases (till about 2002) were dominated by Christoph Martin with Adrian Bunk and few others, who did most packaging work on teTeX version 1. After this Atsuhito Kohda with help from Hilmar Preusse and some people brought teTeX up to version 2, and from 2004 to 2007 Frank K ster, again with help of Hilmar Preusse and some other, took over most of the work on teTeX. Other names appearing throughout the changelog are (incomplete list) Julian Gilbey, Ralf Stubner, LaMont Jones, and C.M Connelly (and many more bug-reporters and fixers). Looking at the above table I have to mention the incredible amount of work that both Atsuhito Kohda and Frank K ster have put into the teTeX packages, and many of their contributions have been carried over into the TeX Live packages. While there haven t been many releases during their maintainership, their work has inspired and supported the packaging of TeX Live to a huge extend. Start of TeX Live I got involved in TeX Live back in 2002 when I started building binaries for the alpha-linux architecture. I can t remember when I first had the idea to package TeX Live for Debian, but here is a time line from my first email to the Debian Developers mailing list concerning TeX Live, to the first accepted upload:
Date Subject/Link Comment
2005-01-11 binaries for different architectures in debian packages The first question concerning packaging TeX Live, about including pre-built binaries
2005-01-25 Debian-TeXlive Proposal II A better proposal, but still including pre-built binaries
2005-05-17 Proposal for a tex-base package Proposal for tex-base, later tex-common, as basis for both teTeX and TeX live packages
2015-06-10 Bug#312897: ITP: texlive ITP bug for TeX Live
2005-09-17 Re: Take over of texinfo/info packages Taking over texinfo which was somehow orphaned started here
2005-11-28 Re: texlive-basic_2005-1_i386.changes REJECTED My answer to the rejection by ftp-master of the first upload. This email sparked a long discussion about packaging and helped improve the naming of packages (but not really the packaging itself).
2006-01-12 Upload of TeX Live 2005-1 to Debian The first successful upload
2006-01-22 Accepted texlive-base 2005-1 (source all) TeX Live packages accepted into Debian/experimental
One can see from the first emails that at that time I didn t have any idea about Debian packaging and proposed to ship the binaries built within the TeX Live system on Debian. What followed was first a long discussion about whether there is any need for just another TeX system. The then maintainer Frank K ster took a clear stance in favor of including TeX Live, and after several rounds of proposals, tests, rejections and improvements, the first successful upload of TeX Live packages to Debian/experimental happened on 12 January 2006, so exactly 10 years ago. Packaging Right from the beginning I used a meta-packaging approach. That is, instead of working directly with the source packages, I wrote (Perl) scripts that generated the source packages from a set of directives. There were several reasons why I choose to introduce this extra layer: Till now I am not 100% sure whether it was the best idea, but the scripts remain in place till now, only adapted to the new packaging paradigm in TeX Live (without xml) and adding new functionality. This allows me to just kick off one script that does do all the work, including building .orig.tar.gz, source packages, binary packages. For those interested to follow the frantic activity during the first years, there is a file CHANGES.packaging which for the years from 2005 to 2011 documents very extensively the changes I made in these years. I don t want to count the hours the went into all this  Development over the years TeX Live 2005 was just another TeX system but not the preferred one in Debian Etch and beyond. But then in May 2006, Thomas Esser announced the end of development of teTeX, which cleared the path for TeX Live as main TeX system in Debian (and the world!). The next release of Debian, Lenny (1/2009), already carried only TeX Live. Unfortunately it was only TeX Live 2007 and not 2008, mostly due to me having been involved in rewriting the upstream infrastructure based on Debian package files instead of the notorious xml files. This took quite a lot of attention and time from Debian away to upstream development, but this will be discussed in a different post. Similarly, the release of TeX Live included in Debian Squeeze (released 2/2011) was only TeX Live 2009 (instead of 2010), but since then (Wheezy and Jessie) the releases of TeX Live in Debian were always the latest released ones. Current status Since about 2013 I am trying to keep a regular schedule of new TeX Live packages every month. These helps me to keep up with the changes in upstream packaging and reduces the load of packaging a new release of TeX Live. It also bring to users of unstable and testing a very up-to-date TeX system, where packages at most lack 1 month of behind the TeX Live net updates. Future As most of the readers here know, besides caring for TeX (Live) and related packages in Debian, I am also responsible for the TeX Live Manager (tlmgr) and most of upstream s infrastructure including network distribution. Thus, my (spare, outside work) time needs to be distributed between all these projects (and some others) which leaves less and less time for Debian packaging. Fortunately the packaging is in a state that making regular updates once a month is less of a burden, since most steps are automatized. What is still a bit of a struggle is adapting the binary package (src:texlive-bin) to new releases. But also this has become simpler due to less invasive changes over the years. All in all, I don t have many plans for TeX Live in Debian besides keeping the current system running as it is. Search for and advise to future maintainers and collaborators I would be more than happy if new collaborators appear, with fresh ideas and some spare time. Unfortunately, my experience over these 10 years with people showing up and proposing changes (anyone remembers the guy proposing a complete rewrite in ML or so?) is that nobody really wants to invest time and energy, but search for quick solutions. This is not something that will work with a package like TeX Live, sized of several gigabyte (the biggest in the Debian archive), and complicated inner workings. I advise everyone being interested in helping to package TeX Live for Debian, to first install normal TeX Live from TUG, get used to what actions happen during updates (format rebuilds, hyphenation patters, map file updates). One does not need to have a perfect understanding of what exactly happens down there in the guts (I didn t have in the beginning, either), but if you want to help packaging and never heard about what format dumps or map files are, then this might be a slight obstacle. Conclusion TeX Live is the only TeX system in wide use across lots of architectures and operating systems, and the only comparable system, MikTeX, is Windows specific (also there are traces of ports to Unix). Backed by all the big user groups of TeX, TeX Live will remain the prime choice for the foreseeable future, and thus also TeX Live in Debian.

Thadeu Lima de Souza Cascardo: GNU on Smartphones (part II)

Some time ago, I wrote how to get GNU on a smartphone. This is going to be a long discussion on why and how we should work on more operating systems for more devices. On Android So, why should we bother if we already have Android, some might ask? If it's just because of some binary blobs, one could just use Replicant, right? Well, one of the problems is that Android development is done in hiding, and pushed downstream when a new version is launched. There is no community behind that anyone can join. Replicant ends up either following it or staying behind. It could do a fork and have its own innovations. And I am all for it. But the lack of manpower for supporting devices and keeping up with the latest versions and security fixes already takes most of the time for the one or two developers involved. Also, Android has a huge modularity problem, that I will discuss further below. But it's hard to replace many components in the system, unless you replace them all. And that also causes the problem that applications can hardly share extra components. I would rather see Debian running on my devices and supporting good environments and frameworks for all kinds of devices, like phones, tablets, TVs, cars, etc. It's developed by a community I can join, it allows a diverse set of frameworks and environments, and it's much easier to replace single components on such a system. On Copyleft Hardware I get it. Hardware is not free or libre. Its design is. I love the concept of copyleft hardware, where one applies the copyleft principles to a hardware design. Also, there is the concept of Hardware that Respects Your Freedom, that is, one that allows you to use it with only free software. Note that RYF hardware is not necessarily copyleft hardware. In fact, most of the time, the original vendor has not helped at all, and it required reverse engineering efforts by other people to be able to run free software on those systems. My point here is that we should not prevent people from running free software on hardware that does not RYF or that is not copyleft. We should continue the efforts of reverse engineering and of pushing hardware vendors to not only ship free software for their hardware, but also release their design under free licenses. But in the meantime, we need to make free software flourish in the plethora of devices on the hands of so many people around the world. On Diversity I won't go into details on this post about two things. One topic I love is retrocomputing and how Linux supported so many devices, and how many free or quasi-free operating systems ran on so many of them in the past. I could mention ucLinux, Familiar, PDAs, Palmtops, Motorolas, etc. But I will leave it to another time and go from Openmoko and Maemo forward. The other topic is application scalability. Even Debian with so many software available does not ship all free software there is available. And it doesn't support all third-party services out there. How can we solve that? It has to do with platforms, protocols, open protocols, etc. I will not go into that today. Because I believe that either way, it's healthy for our society to have diversity. I believe we should have other operating systems available for our devices. Even if application developers will not develop for all of them. That is already the case today. There are other ways to fix that, when that needs fixing. Sometimes, it's sufficient that you can have your own operating system on your device, that you can customize it, enhance it and share it with friends. And also, that would allow for innovation. It would make possible that some other operating system would have enough market share on some other niche. Other than Android and iOS, for example. But that requires that we can support that operating system on different devices. And that is the scalability that I want to talk about. How to support more devices with less effort. Options But before I go into that, let me write more about the alternatives we have out there. And some of the history around it. Openmoko Openmoko developed a set of devices that had some free design. And it has some free operating systems running on top. The community developed a lot of their own as well. Debian could (still can) run on it. There is SHR, which uses FSO, a mobile middleware based on D-Bus. It even spawned other devices to be developed, like GTA04, a successor board, that can be shipped inside a Neo Freerunner case. Maemo, Moblin, Meego and Tizen I remember the announcement of Nokia N770. During FISL in 2005, I even criticized a lot, because it shipped with proprietary drivers. And applications. But it was the first time we heard of Maemo. It was based on Debian and GNOME. The GNOME Mobile initiative was born from that, I believe, but died later on. But with the launch of N900, and later events, like the merge of Moblin with Maemo, to create Meego, we all had an operating system that was based on community developed components, that had some community participation, and was much more like the systems we were used to. You could run gcc on N900. You could install Das U-Boot and have other operating systems running there. But Nokia has gone a different path. Intel has started Tizen with Samsung. There is so much legacy there, that could still be developed upon. I am just sad that Jolla decided to put proprietary layers on top of that, to create SailfishOS. But we still have Mer, Nemo. But it looks like Cordia is gone. At least, (http://cordiahd.org) seems to have been registered by a domain seller. Not to forget, Neo900, a project to upgrade the board, in the same vein as GTA04. FirefoxOS and Ubuntu What can I say about FirefoxOS and Ubuntu Phone? In summary, I think we need more than Web, and Canonical has a history of not being too community oriented as we'd like. I won't go too much here in what I think about the Web as a platform. But I think we need a system that has more options for platforms. I haven't participated in projects directed by Mozilla either, so I can't say much about that. Ubuntu Phone should be a system more like what we are used to. But Canonical is going to set the directions to the project, it's not a community project. Nonetheless, I think they add to the diversity, and users should be able to try them, or their free parts or versions. But there are challenges there, that I think need to be discussed. So, both of these systems are based on Android. They don't use Dalvik or the application framework. But they use what is below that, which means device drivers in userspaces, like RIL, for the modem drivers, and EGL, for graphics drivers. The reason they do that is to build on top of all the existing vendor support for Android. If a SOC and phone vendor already supports Android, there should be not much needed to do to support FirefoxOS or Ubuntu Phone. In practice, this has not benefited the users or the projects. Porting should be as simple as getting a generic FirefoxOS or Ubuntu Phone image and run it on top of your Android or CyanogenMod port. Porting usually requires doing all the same work as porting Android. Even though one should be able to take advantage of existing ports, it still requires doing a lot of integration work and building an entire image, most of the time, including the upper layers, that should be equal in all devices. This process should require at most creating a new image based on other images and loading it on the device. I will discuss more about this below. I can't forget to mention the Matchstick TV project. It is based on FirefoxOS. I think it would have much more changes to succeed if it was easier for testers to have images available for all of their gadgets capable of running some form of Android. Replicant And then we have Replicant. It has a lot of the problems Android has. Even so, it's a tremendously important project. First, it offers a free version of Android, removing all proprietary pieces. This is very good for the community. But more than that, it tries to free the devices beyond that. What the project has been done is reverse engineer some of the pieces, mostly the modem drivers. That allows other projects to build upon that work, and support those modems. Without that, there is no telephony or celullar data available on any of these devices. Not without proprietary software, that is. They also have been working on free bootloaders, which is another important step for a completely free system. Next steps There are many challenges here, but I believe we should work on a set of steps that make it more palatable and produce intermediary results that can be used by users and other projects. One of the goals should be good modularity. The ability to replace some pieces with the least trouble necessary. The update of a single framework library should be just a package install, instead of building the entire framework again. If there is ABI breakage, users should still be able to have access to binaries (and accompanying source code) and only need to update the library and its reverse dependencies. If one layer does not have these properties, at least it should be possible to update this big chunk without interfering with the other layers. One example is FirefoxOS and Ubuntu Phone. Even if there is a big image with all system userspace and middleware, the porting, install and upgrade process should allow the user to keep the applications and to leverage porting already done by similar projects. Heck, these two projects should be able to share porting efforts without any trouble. So what follows is a quick discussion on Android builds, then suggestions on how to approach some of the challenges. On Android build The big problem with Android build is its non-modularity. You need to build the world and more to get a single image in the end. Instead of packages that could be built independently, that generated modular package images, that could be bundled in a single system image. Better yet would be the ability to pick only those components that matter. Certainly, portability would be just as interesting, being able to build certain components on top a GNU system with GNU libc. At times, it seems like this is done by design, to make it difficult for "fragmentation" and competition. Basically, making it difficult to exercise the freedom to modify the software and share your modifications with others. Imagine the possibilities of being able to: There are some dangers in promoting the use of Android like this. Since it promotes proprietary drivers, relying on such layers instead of better community oriented layers means giving an advantage to the first. So, the best plan would be to replace those layers, when they are used, for things like ofono and Wayland, for example. But, in the meantime, making it easier for users to experiment with FirefoxOS, Ubuntu Phone, Matchstick TV, Replicant on other devices, without resorting to building the entire Android system, would be a very nice thing. It is possible that there are some challenges with respect to API and ABI. That these layers are too intermingled that some changes present in one port would prevent FirefoxOS to run on top of it without changes in either of the layers. I can't confirm that is the case, but can't deny the possibility. Rooting One of the challenges we have that may have trouble in scaling is rooting devices. Unfortunately, most of the devices are owned by the vendor or carrier, not the user. The user is prevented from replacing software components in the system, by removing its permissions from replacing most of the files in the filesystem, or writing to block devices, or change boot parameters or write to the storage devices. Fortunately, there are many documents, guides, howtos, and whatnots out there instructing on how to root a lot of devices. In some cases, it depends on software bugs that can be patched by the users as instructed by vendors. Certainly, favoring devices that are built to allow rooting, hacking, etc, is a good thing. But we should still help those users out there who do not have such devices, and allow them to run free software on them. Booting Then, comes booting, which is a large discussion on its own, and also related to rooting, or how to allow users to replace their software. First, we have the topic of bootloaders, which are usually not free, and embedded in the chip, not on external storage. So, there are those pieces of the bootloader which we can replace more easily and those that we are not, because they would require changing a piece of ROM, for example. Das U-Boot would be one of the preferred options for a system. It supports a lot of hardware platforms out there, a lot of storage devices and filesystems, network booting, USB and serial booting, and a lot of other things. Porting is not an easy task, but it is possible. Meanwhile, using the bootloaders that ship with the system, when possible, would allow a path where other pieces of the system would be free. One of the challenges here is building single images that could boot everywhere. The lack of a single ARM boot environment is a curse and a blessing. It makes it hard to have this single boot image, but, on the other hand, it has allowed so much of the information for such systems to be free, to be embedded in copyleft software, instead of having blobs executed by our free systems, like ACPI encourages. Device trees have pushed this portability issue from the kernel to the bootloaders. Possibily encouraging vendors to now hide and copyright this information in the form of proprietary device trees. But it has made it easier for single images. In practice, we still need to see a lot of devices out there supporting this single kernel scenario. And this mechanism only brings us the possibility of a single kernel. We still need to ship bootable images that have pieces of bootloaders that are not as portable. This has caused lots of operating systems out there to be built for a single board. Or to support just a small set of boards. I struggle with the concept. Why are we not able to mix device-specific pieces with generic pieces and get a resulting image that will boot on our choice of board? Why does every project need to do all the porting work again, repeating the efforts? Or have one entier ISO image for every supported board? Check how Geexbox does it, for an example. Fortunately, I see Debian going in a good direction. Here, one can see how it instructs the user to combine a system-dependent part with a system-independent part. Installation Which brings us to the installation challenge. We should make this easy and also customizable by the user. Every project might have its own method, and that is part of the diversity that we should allow. The great challenge here is handling rooting and booting for the user. But it's also possible to leave that as separate efforts, as it would be nice to have good installers as we have in the desktop and server environments. Linux Linux is one of the most ported kernels out there. Of course, it would be healthy to the diversity I propose that other kernels and systems out there should work on those mobile devices. NetBSD, for example, has a reputation of being very portable and ported to many platforms. And GNU runs on many of them, either together with the original systems, or as the main system on top of other kernels, as proven by the Debian GNU/kFreeBSD port, which uses GNU libc. But, though I would love to see HURD running directly on those devices, Linux and its derivatives are already running on them. Easier to tackle is to get Linux-libre running on those systems. But though this looks like one of the easier tasks at hand, it is not. If you run a derivative version from Linux, provided by the vendor, things should go smooth. But most of the time, the vendor does not provide patches upstream, and leave their fork to rot, if you are lucky, in the earlier 3.x series. And some times, there is not even source code available. There are vendors out there who do not respect the GPL and that is one of the reasons why GPL enforcement is important. I take this opportunity to call attention to the work of Software Freedom Conservancy and its current efforts to raise funds to continue their work. Running an existing binary version of Linux on your device with a free userspace is part of the strategy of replacing pieces one at a time while allowing for good diversity and reaching more users. Drivers Then we have the matter of drivers. And in this case, it's not only Linux drivers, but drivers running in userspace. Though others exist, there are two important and common cases, which are modem and graphics drivers, both of which are usually provided by Android frameworks, and that other systems try to leverage, instead of using alternatives that are more community friendly. In the case of modem drivers, Android uses its RIL. Besides not using a Radio or Modem at all, there are two strategies for free versions. One is using free versions of the drivers for RIL. That's what Replicant does, because, well, it uses the other Android subsystems after all. The other one is using a system that is developed by the community. ofono is one that, even though it's an Intel iniative, looks more community governed or open to community participation than any Android subsystem ever was. As for Graphics, Canonical even built its Mir project with the goal of being able to use Android GPU drivers. Luckily, there has been a lot of reverse engineering efforts out there for a lot of those GPUs shipped with ARM SoCs. Then, we can use Mesa, Wayland and X.org. Other option, until then, is just using a framebuffer driver, possibly one that does not need any initialization, depending on one done by the bootloader, for example. Middleware and Shells Plasma Active, that I just found out now is Plasma Mobile, looks like a great system. Built by folks behind KDE, we can expect great freedom to come from it. Unfortunately, it suffers from what we have been discussing here, which is lack of good device support, or shipping images that run on top of single devices, without leveraging the porting that has come before of other systems. Fortunately, that is just what I want to accomplish with this effort. FSO, that I mentioned before, is a good middleware, that we should try to run on top of these devices. Running GNOME or Unity shell, and use rpm or deb based systems, that's all part of the plan on diversity. You could use systemd, or System V init systems, whatever gives you the kicks. It's not an easy task, since there are so many new things on these new kinds of devices. Besides touch, there is telephony, which as I mentioned, would be a good task for ofono. As for TV sets or dongles, I would love to see OpenFlint, created by the Matchstick TV guys, flourish out there and allow me to flint stuff from my mobile phone running Debian into my TV dongle running Debian. Project So, is there a project out there you can start contributing to? Well, I pointed out a lot of them. All of them make part of this plan. Contributing to reverse engineering GPUs, or to Plasma Mobile, ofono, GNOME, Linux-libre, bootloaders, Debian, and so many other projects. My plans are to contribute in the scope of Debian and make sure it works well on top of semi-liberated devices, and make sure there is a nice user interface and good applications when using either GNOME or Plasma. Integrating ofono is a good next step, but I am running ahead of myself. Right now, I don't think there is need for an integrated effort. If you think otherwise, please let me know. If you are doing something in this direction, I would love to know. Paul Wise reminded me to point out to the Debian Mobile, where I will probably contribute any documentation and other relevant results. Thanks There are some many people to thank, but I would like to remember Ian Murdock, who created Debian, one of the projects who inspires me the most. I think the best way to handle his passing is to celebrate what he has helped create, and move forward, taking more free software to more people in an easy and modular way. I have been wanting to write something like this for a long time, so I thank Chris Webber for inspiring me on doing it.
Alessio Treglia: Filling old bottles with new wine

They are filling old bottles with new wine! This is what the physicist Werner Heisenberg heard exclaiming by his friend and colleague Wolfgang Pauli who, criticizing the approach of the scientists of the time, believed that they had been forcibly glued the notion of quantum on the old theory of the planetary-model of Bohr s atom. Faced with the huge questions introduced by quantum physics, Pauli instead began to observe the new findings from a different point of view, from a new level of reality without the constraints imposed by previous theories.

Newton himself, once he theorized the law of the gravitational field, failing to place it in any of the physical realities of the time, he merely

<Read More...>

Dirk Eddelbuettel: Rcpp 0.12.3: Keep rollin'

The third update in the 0.12.* series of Rcpp arrived on the CRAN network for GNU R earlier today, and has been pushed to Debian. It follows the 0.12.0 release from late July, the 0.12.1 release in September, and the 0.12.2 release in November making it the seventh release at the steady bi-montly release frequency. This release is somewhat more of a maintenance release addressing a number of small bugs and nuisances without adding any new features. Rcpp has become the most popular way of enhancing GNU R with C or C++ code. As of today, 553 packages on CRAN depend on Rcpp for making analytical code go faster and further. That is up by more than fourty packages from the last release in November. Once again, we have new first-time contributors. Kazuki Fukui corrected an issue he encountered when having CLion re-formatted some code for him. Joshua Pritikin corrected a constructor initialization. Of course, we also had several pull reports from regular contributors -- see below for a detailed list of changes extracted from the NEWS file.
Changes in Rcpp version 0.12.3 (2016-01-10)
  • Changes in Rcpp API:
    • Const iterators now CharacterVector now behave like regular iterators (PR #404 by Dan fixing #362).
    • Math operators between matrix and scalars type have been added (PR #406 by Qiang fixing #365).
    • A missing std::hash function interface for Rcpp::String has been addded (PR #408 by Qiang fixing #84).
  • Changes in Rcpp Attributes:
    • Avoid invalid function names when generating C++ interfaces (PR #403 by JJ fixing #402).
    • Insert additional space around & in function interface (PR #400 by Kazuki Fukui fixing #278).
  • Changes in Rcpp Modules:
    • The copy constructor now initialized the base class (PR #411 by Joshua Pritikin fixing #410)
  • Changes in Rcpp Repository:
    • Added a file Contributing.md providing some points to potential contributors (PR #414 closing issue #413)
Thanks to CRANberries, you can also look at a diff to the previous release. As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads page, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

5 January 2016

Benjamin Mako Hill: Celebrate Aaron Swartz in Seattle (or Atlanta, Chicago, Dallas, NYC, SF)

I m organizing an event at the University of Washington in Seattle that involves a reading, the screening of a documentary film, and a Q&A about Aaron Swartz. The event coincides with the third anniversary of Aaron s death and the release of a new book of Swartz s writing that I contributed to. aaronsw-tiob_bwcstw The event is free and open the public and details are below:

WHEN: Wednesday, January 13 at 6:30-9:30 p.m.

WHERE: Communications Building (CMU) 120, University of Washington

We invite you to celebrate the life and activism efforts of Aaron Swartz, hosted by UW Communication professor Benjamin Mako Hill. The event is next week and will consist of a short book reading, a screening of a documentary about Aaron s life, and a Q&A with Mako who knew Aaron well details are below. No RSVP required; we hope you can join us.

Aaron Swartz was a programming prodigy, entrepreneur, and information activist who contributed to the core Internet protocol RSS and co-founded Reddit, among other groundbreaking work. However, it was his efforts in social justice and political organizing combined with his aggressive approach to promoting increased access to information that entangled him in a two-year legal nightmare that ended with the taking of his own life at the age of 26.

January 11, 2016 marks the third anniversary of his death. Join us two days later for a reading from a new posthumous collection of Swartz s writing published by New Press, a showing of The Internet s Own Boy (a documentary about his life), and a Q&A with UW Communication professor Benjamin Mako Hill a former roommate and friend of Swartz and a contributor to and co-editor of the first section of the new book. If you re not in Seattle, there are events with similar programs being organized in Atlanta, Chicago, Dallas, New York, and San Francisco. All of these other events will be on Monday January 11 and registration is required for all of them. I will be speaking at the event in San Francisco.

4 January 2016

Bernd Zeimetz: open-vm-tools updated

In January 2014 the open-vm-tools package was orphaned and I took the chance to take over the maintenance. Unfortunately the package is still not 100% in the shape I d like to see it, but I m getting closer. I have to say Thank You for a lot of good bug reports, especially for those use cases which are hard to test/reproduce for me (running Debian in a Windows-based VMware Workstation Player for example .). At conova communications GmbH, the company I work for, we are using the package on all of our Debian VMs, both for customer and internal use. It is essential for us to have properly working open-vm-tools - not only to be able to shutdown the VM from VMware vCenter, but also because tools like vSphere Data Protection and Veeam depend on it. Good thing is that I can work on and test the package at work and breakages are detected early and fast normally. Getting a good contact to the VMware upstream was easy and the developers there are helpful and reply pretty fast to their emails. Also as it seems there are finally real commits showing up in the open-vm-tools github repository again, not only huge single commits with a full release. It is not only nice to see that they are moving into the right direction again, but also this is really helpful in fixing (urgent) bugs before the next release of open-vm-tools - or to backport a fix to the versoin in stable/oldstable. Since a few days we have open-vm-tools 10.0.5-3227872 in If you are using VMware ESX 5.5 or newer, you should upgrade to the backports versions. Same if you use a recent VMware player version. Please note that since 10.0.0 the open-vm-dkms package is only necessary if you need the legacy vmxnet module. This is only the case if you are using very old VM hardware versions. vmxnet3 is shipped in the Debian kernel, so you don t need to compile extra modules to use it. The vmhgfs module was replaced by a fuse-based implementation. If you d like to help maintaining the package, please send bugs/patches via the Debian BTS or even better - send pull requests for pkg-open-vm-tools. The repository is mirrored to git.bzed.at in case you want to avoid github.

John Goerzen: Hiking a mountain with Ian Murdock

Would you like to hike a mountain? That question caught me by surprise. It was early in 2000, and I had flown to Tucson for a job interview. Ian Murdock was starting a new company, Progeny, and I was being interviewed for their first hire. Well, I thought, hiking will be fun. So we rode a bus or something to the top of the mountain and then hiked down. Our hike was full of well, everything. Ian talked about Tucson and the mountains, about his time as the Debian project leader, about his college days. I asked about the plants and such we were walking past. We talked about the plans for Progeny, my background, how I might fit in. It was part interview, part hike, part two geeks chatting. Ian had no HR telling him you can t go hiking down a mountain with a job candidate, as I m sure HR would have. And I am glad of it, because even 16 years later, that is still by far the best time I ever had at a job interview, despite the fact that it ruined the only pair of shoes I had brought along I had foolishly brought dress shoes for a, well, job interview. I guess it worked, too, because I was hired. Ian wanted to start up the company in Indianapolis, so over the next little while there was the busy work of moving myself and setting up an office. I remember those early days Ian and I went computer shopping at a local shop more than once to get the first workstations and servers for the company. Somehow he had found a deal on some office space in a high-rent office building. I still remember the puzzlement on the faces of accountants and lawyers dressed up in suits riding in the elevators with us in our shorts and sandals, or tie-die, next to them. Progeny s story was to be a complicated one. We set out to rock the world. We didn t. We didn t set out to make lasting friendships, but we often did. We set out to accomplish great things, and we did some of that, too. We experienced a full range of emotions there elation when we got hardware auto-detection working well or when our downloads looked very popular, despair when our funding didn t come through as we had hoped, being lost when our strategy had to change multiple times. And, as is the case everywhere, none of us were perfect. I still remember the excitement after we published our first release on the Internet. Our little server that could got pegged at 100Mb of outbound bandwidth (that was something for a small company in those days.) The moment must have meant something, because I still have the mrtg chart from that day on my computer, 15 years later. Progeny's Bandwidth Chart We made a good Linux distribution, an excellent Debian derivative, but commercial success did not flow from it. In the succeeding months, Ian and the company tried hard to find a strategy that would stick and make our big break. But that never happened. We had several rounds of layoffs when hoped-for funding never materialized. Ian eventually lost control of the company, and despite a few years of Itanium contract work after I left, closed for good. Looking back, Progeny was life compressed. During the good times, we had joy, sense of accomplishment, a sense of purpose at doing something well that was worth doing. I had what was my dream job back then: working on Debian as I loved to do, making the world a better place through Free Software, and getting paid to do it. And during the bad times, different people at Progeny experienced anger, cynicism, apathy, sorrow for the loss of our friends or plans, or simply a feeling to soldier on. All of the emotions, good or bad, were warranted in their own way. Bruce Byfield, one of my co-workers at Progeny, recently wrote a wonderful memoriam of Ian. He wrote, More than anything, he wanted to repeat his accomplishment with Debian, and, naturally he wondered if he could live up to his own expectations of himself. That, I think, was Ian s personal tragedy that he had succeeded early in life, and nothing else he did with his life could quite measure up to his expectations and memories. Ian was not the only one to have some guilt over Progeny. I, for years, wondered if I should have done more for the company, could have saved things by doing something more, or different. But I always came back to the conclusion I had at the time: that there was nothing I could do a terribly sad realization. In the years since, I watched Ubuntu take the mantle of easy-to-install Debian derivative. I saw them reprise some of the ideas we had, and even some of our mistakes. But by that time, Progeny was so thoroughly forgotten that I doubt they even realized they were doing it. I had long looked at our work at Progeny as a failure. Our main goal was never accomplished, our big product never sold many copies, our company eventually shuttered, our rock-the-world plan crumpled and forgotten. And by those traditional measurements, you could say it was a failure. But I have come to learn in the years since that success is a lot more that those things. Success is also about finding meaning and purpose through our work. As a programmer, success is nailing that algorithm that lets the application scale 10x more than before, or solving that difficult problem. As a manager, success is helping team members thrive, watching pieces come together on projects that no one person could ever do themselves. And as a person, success comes from learning from our experiences, and especially our mistakes. As J. Michael Straczynski wrote in a Babylon 5 episode, loosely paraphrased: Maybe this experience will be a good lesson. Too bad it was so painful, but there ain t no other kind. The thing about Progeny is this Ian built a group of people that wanted to change the world for the better. We gave it our all. And there s nothing wrong with that. Progeny did change the world. As us Progeny alumni have scattered around the country, we benefit from the lessons we learned there. And many of us were different , sort of out of place before Progeny, and there we found others that loved C compilers, bootloaders, and GPL licenses just as much as we did. We belonged, not just online but in life, and we went on to pull confidence and skill out of our experience at Progeny and use them in all sorts of ways over the years. And so did Ian. Who could have imagined the founder of Debian and Progeny would one day lead the cause of an old-guard Unix turning Open Source? I run ZFS on my Debian system today, and Ian is partly responsible for that and his time at Progeny is too. So I can remember Ian, and Progeny, as a success. And I leave you with a photo of my best memento from the time there: an original unopened boxed copy of Progeny Linux. IMG_6197_v1

Next.

Previous.