Search Results: "cas"

6 April 2022

Jonathan Dowland: Death from Above

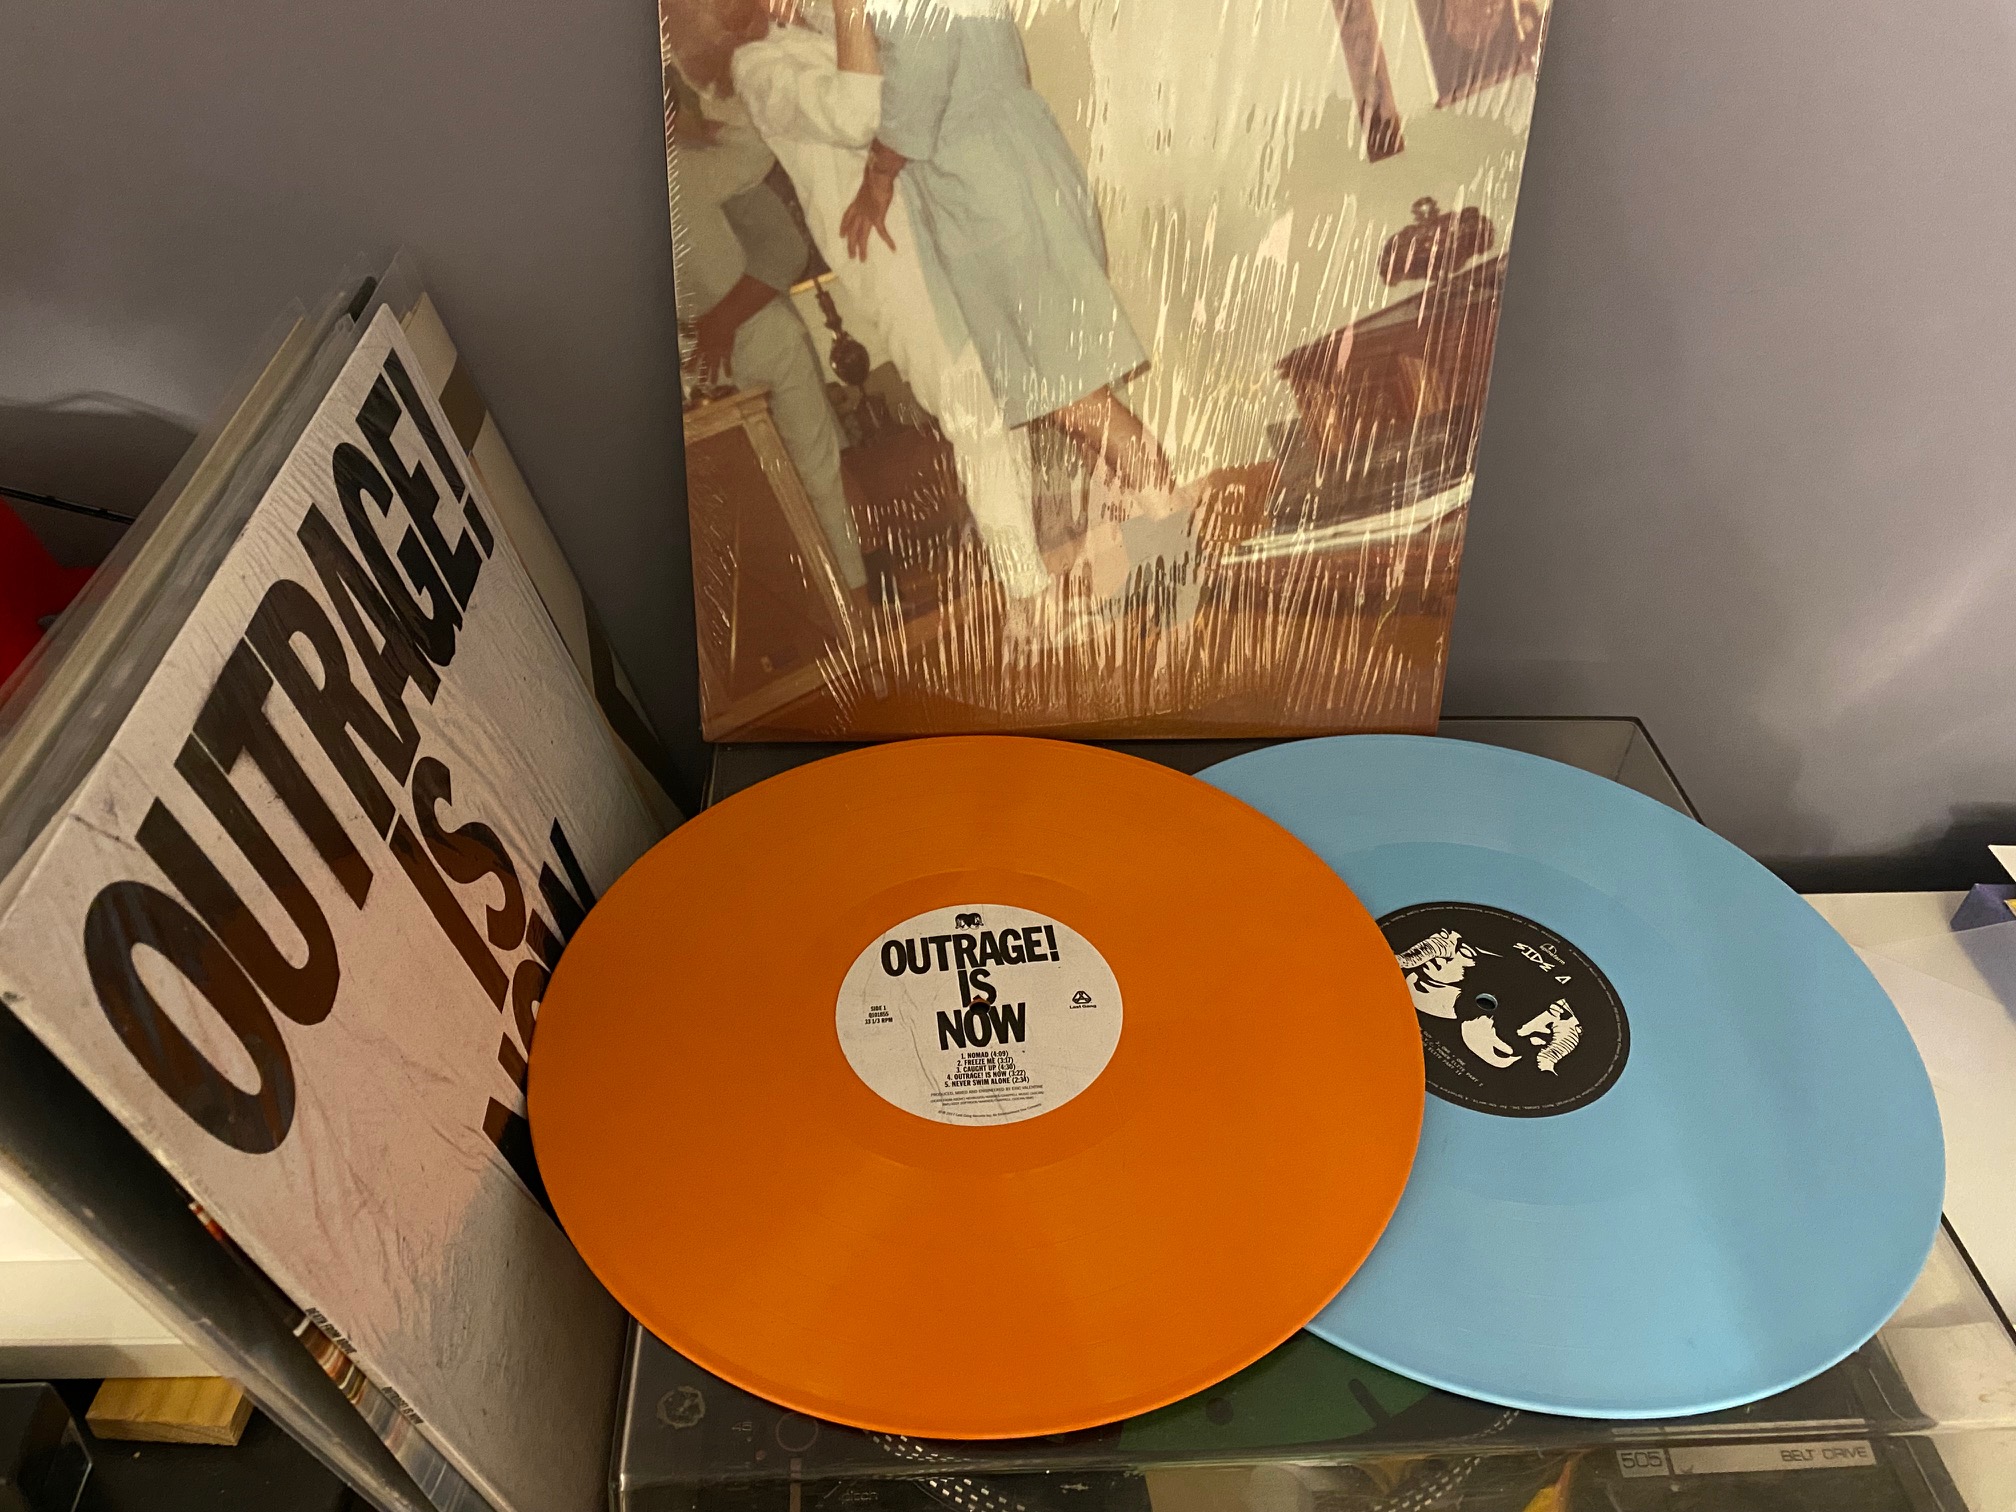
picture of two vinyl records
I received the last two Death From Above albums at Christmas and this weekend managed to give the first (Outrage Is Now) a spin. Pretty colours! They remain one of the best bands to see live. Last time I saw them in a support slot in Newcastle. My friend Rob, a man of few words said I wouldn t want to have to follow them on stage!

5 April 2022

Matthew Garrett: Bearer tokens are just awful

As I mentioned last time, bearer tokens are not super compatible with a model in which every access is verified to ensure it's coming from a trusted device. Let's talk about that in a bit more detail.

First off, what is a bearer token? In its simplest form, it's simply an opaque blob that you give to a user after an authentication or authorisation challenge, and then they show it to you to prove that they should be allowed access to a resource. In theory you could just hand someone a randomly generated blob, but then you'd need to keep track of which blobs you've issued and when they should be expired and who they correspond to, so frequently this is actually done using JWTs which contain some base64 encoded JSON that describes the user and group membership and so on and then have a signature associated with them so whenever the user presents one you can just validate the signature and then assume that the contents of the JSON are trustworthy.

One thing to note here is that the crypto is purely between whoever issued the token and whoever validates the token - as far as the server is concerned, any client who can just show it the token is just fine as long as the signature is verified. There's no way to verify the client's state, so one of the core ideas of Zero Trust (that we verify that the client is in a trustworthy state on every access) is already violated.

Can we make things not terrible? Sure! We may not be able to validate the client state on every access, but we can validate the client state when we issue the token in the first place. When the user hits a login page, we do state validation according to whatever policy we want to enforce, and if the client violates that policy we refuse to issue a token to it. If the token has a sufficiently short lifetime then an attacker is only going to have a short period of time to use that token before it expires and then (with luck) they won't be able to get a new one because the state validation will fail.

Except! This is fine for cases where we control the issuance flow. What if we have a scenario where a third party authenticates the client (by verifying that they have a valid token issued by their ID provider) and then uses that to issue their own token that's much longer lived? Well, now the client has a long-lived token sitting on it. And if anyone copies that token to another device, they can now pretend to be that client.

This is, sadly, depressingly common. A lot of services will verify the user, and then issue an oauth token that'll expire some time around the heat death of the universe. If a client system is compromised and an attacker just copies that token to another system, they can continue to pretend to be the legitimate user until someone notices (which, depending on whether or not the service in question has any sort of audit logs, and whether you're paying any attention to them, may be once screenshots of your data show up on Twitter).

This is a problem! There's no way to fit a hosted service that behaves this way into a Zero Trust model - the best you can say is that a token was issued to a device that was, around that time, apparently trustworthy, and now it's some time later and you have literally no idea whether the device is still trustworthy or if the token is still even on that device.

But wait, there's more! Even if you're nowhere near doing any sort of Zero Trust stuff, imagine the case of a user having a bunch of tokens from multiple services on their laptop, and then they leave their laptop unlocked in a cafe while they head to the toilet and whoops it's not there any more, better assume that someone has access to all the data on there. How many services has our opportunistic new laptop owner gained access to as a result? How do we revoke all of the tokens that are sitting there on the local disk? Do you even have a policy for dealing with that?

There isn't a simple answer to all of these problems. Replacing bearer tokens with some sort of asymmetric cryptographic challenge to the client would at least let us tie the tokens to a TPM or other secure enclave, and then we wouldn't have to worry about them being copied elsewhere. But that wouldn't help us if the client is compromised and the attacker simply keeps using the compromised client. The entire model of simply proving knowledge of a secret being sufficient to gain access to a resource is inherently incompatible with a desire for fine-grained trust verification on every access, but I don't see anything changing until we have a standard for third party services to be able to perform that trust verification against a customer's policy.

Still, at least this means I can just run weird Android IoT apps through mitmproxy, pull the bearer token out of the request headers and then start poking the remote API with curl. It may all be broken, but it's also got me a bunch of bug bounty credit, so, it;s impossible to say if its bad or not,

(Addendum: this suggestion that we solve the hardware binding problem by simply passing all the network traffic through some sort of local enclave that could see tokens being set and would then sequester them and reinject them into later requests is OBVIOUSLY HORRIFYING and is also probably going to be at least three startup pitches by the end of next week)

comment count unavailable comments

Kees Cook: security things in Linux v5.10

Previously: v5.9 Linux v5.10 was released in December, 2020. Here s my summary of various security things that I found interesting: AMD SEV-ES
While guest VM memory encryption with AMD SEV has been supported for a while, Joerg Roedel, Thomas Lendacky, and others added register state encryption (SEV-ES). This means it s even harder for a VM host to reconstruct a guest VM s state. x86 static calls
Josh Poimboeuf and Peter Zijlstra implemented static calls for x86, which operates very similarly to the static branch infrastructure in the kernel. With static branches, an if/else choice can be hard-coded, instead of being run-time evaluated every time. Such branches can be updated too (the kernel just rewrites the code to switch around the branch ). All these principles apply to static calls as well, but they re for replacing indirect function calls (i.e. a call through a function pointer) with a direct call (i.e. a hard-coded call address). This eliminates the need for Spectre mitigations (e.g. RETPOLINE) for these indirect calls, and avoids a memory lookup for the pointer. For hot-path code (like the scheduler), this has a measurable performance impact. It also serves as a kind of Control Flow Integrity implementation: an indirect call got removed, and the potential destinations have been explicitly identified at compile-time. network RNG improvements
In an effort to improve the pseudo-random number generator used by the network subsystem (for things like port numbers and packet sequence numbers), Linux s home-grown pRNG has been replaced by the SipHash round function, and perturbed by (hopefully) hard-to-predict internal kernel states. This should make it very hard to brute force the internal state of the pRNG and make predictions about future random numbers just from examining network traffic. Similarly, ICMP s global rate limiter was adjusted to avoid leaking details of network state, as a start to fixing recent DNS Cache Poisoning attacks. SafeSetID handles GID
Thomas Cedeno improved the SafeSetID LSM to handle group IDs (which required teaching the kernel about which syscalls were actually performing setgid.) Like the earlier setuid policy, this lets the system owner define an explicit list of allowed group ID transitions under CAP_SETGID (instead of to just any group), providing a way to keep the power of granting this capability much more limited. (This isn t complete yet, though, since handling setgroups() is still needed.) improve kernel s internal checking of file contents
The kernel provides LSMs (like the Integrity subsystem) with details about files as they re loaded. (For example, loading modules, new kernel images for kexec, and firmware.) There wasn t very good coverage for cases where the contents were coming from things that weren t files. To deal with this, new hooks were added that allow the LSMs to introspect the contents directly, and to do partial reads. This will give the LSMs much finer grain visibility into these kinds of operations. set_fs removal continues
With the earlier work landed to free the core kernel code from set_fs(), Christoph Hellwig made it possible for set_fs() to be optional for an architecture. Subsequently, he then removed set_fs() entirely for x86, riscv, and powerpc. These architectures will now be free from the entire class of kernel address limit attacks that only needed to corrupt a single value in struct thead_info. sysfs_emit() replaces sprintf() in /sys
Joe Perches tackled one of the most common bug classes with sprintf() and snprintf() in /sys handlers by creating a new helper, sysfs_emit(). This will handle the cases where kernel code was not correctly dealing with the length results from sprintf() calls, which might lead to buffer overflows in the PAGE_SIZE buffer that /sys handlers operate on. With the helper in place, it was possible to start the refactoring of the many sprintf() callers. nosymfollow mount option
Mattias Nissler and Ross Zwisler implemented the nosymfollow mount option. This entirely disables symlink resolution for the given filesystem, similar to other mount options where noexec disallows execve(), nosuid disallows setid bits, and nodev disallows device files. Quoting the patch, it is useful as a defensive measure for systems that need to deal with untrusted file systems in privileged contexts. (i.e. for when /proc/sys/fs/protected_symlinks isn t a big enough hammer.) Chrome OS uses this option for its stateful filesystem, as symlink traversal as been a common attack-persistence vector. ARMv8.5 Memory Tagging Extension support
Vincenzo Frascino added support to arm64 for the coming Memory Tagging Extension, which will be available for ARMv8.5 and later chips. It provides 4 bits of tags (covering multiples of 16 byte spans of the address space). This is enough to deterministically eliminate all linear heap buffer overflow flaws (1 tag for free , and then rotate even values and odd values for neighboring allocations), which is probably one of the most common bugs being currently exploited. It also makes use-after-free and over/under indexing much more difficult for attackers (but still possible if the target s tag bits can be exposed). Maybe some day we can switch to 128 bit virtual memory addresses and have fully versioned allocations. But for now, 16 tag values is better than none, though we do still need to wait for anyone to actually be shipping ARMv8.5 hardware. fixes for flaws found by UBSAN
The work to make UBSAN generally usable under syzkaller continues to bear fruit, with various fixes all over the kernel for stuff like shift-out-of-bounds, divide-by-zero, and integer overflow. Seeing these kinds of patches land reinforces the the rationale of shifting the burden of these kinds of checks to the toolchain: these run-time bugs continue to pop up. flexible array conversions
The work on flexible array conversions continues. Gustavo A. R. Silva and others continued to grind on the conversions, getting the kernel ever closer to being able to enable the -Warray-bounds compiler flag and clear the path for saner bounds checking of array indexes and memcpy() usage. That s it for now! Please let me know if you think anything else needs some attention. Next up is Linux v5.11.

2022, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 4.0 License.
CC BY-SA 4.0

4 April 2022

Arturo Borrero Gonz lez: Wikimedia Toolforge and Grid Engine

Logos This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez. One of the most important and successful products provided by the Wikimedia Cloud Services team at the Wikimedia Foundation is Toolforge, a hosting service commonly known in the industry as Platform as a Service (PaaS). In particular, it is a platform that allows users and developers to run and use a variety of applications with the ultimate goal of helping the Wikimedia mission from the technical side. Toolforge is powered by two different backend engines, Kubernetes and Grid Engine. The two backends have traditionally offered different features for tool developers. But as time moves forward we ve learnt that Kubernetes is the future. Explaining why is the purpose of this blog post: we want to share more information and reasoning behind this mindset. There are a number of reasons that make Grid Engine poorly suitable to remain as execution backend in Toolforge:
  • There has not been a new Grid Engine release (bug fixes, security patches, or otherwise) since 2016. This doesn t feel like a project being actively developed or maintained.
  • The grid has poor support and controls for important aspects such as high availability, fault tolerance and self-recovery.
  • Maintaining a healthy grid requires plenty of manual operations, like manual queue cleanups in case of failures, hand-crafted scripts for pooling/depooling nodes, etc.
  • There is no good or modern monitoring support for the grid, and we need to craft and maintain several monitoring pieces for proper observability, and to be able to do proper maintenance.
  • The grid is also strongly tied to the underlying operating system release version. Migrating from one Debian version to the next is painful (a dedicated blog post about this will follow shortly).
  • The grid imposes a strong dependency on NFS, another old technology. We would like to reduce dependency on NFS overall, and in the future we will explore NFS-free approaches for Toolforge.
  • In general, Grid Engine is old software, old technology, which can be replaced by more modern approaches for providing an equivalent or better service.
As mentioned above, our desire is to cover all our grid-like needs with Kubernetes, a technology which has several benefits:
  • Good high availability, fault tolerance and self-recovery semantics, constructs and facilities.
  • Maintaining a running Kubernetes cluster requires little manual operations.
  • There are good monitoring and observability options for Kubernetes deployments, including seamless integration with industry standards like prometheus.
  • Our current approach to deploying and upgrading Kubernetes is independent of the underlying operating system.
  • While our current Kubernetes deployment uses NFS as a central component, there is support for using other, more modern, approaches for the kind of shared storage needs we have in Toolforge.
  • In general, Kubernetes is a modern technology, with a vibrant and healthy community, that enables new use cases and has enough flexibility to adapt legacy ones.
The relationship between Toolforge and Grid Engine has been interesting over the years. The grid has been used for quite a lot of time, we have plenty of documentation and established good practices. On the other hand, the grid is hard to maintain, imposes a heavy burden on the WMCS team and is a technology we must eventually discontinue. How to accommodate the two realities is a refreshing challenge, one that we hope to tackle together in the near future. A tradeoff exists here, but it is clear to us which option is best. So we will work on deprecating and removing Grid Engine and migrating use cases into Kubernetes. This deprecation, however, will be done with care, as we know our technical community relies on the grid for some import Toolforge tools. And some of these workflows will need some adaptation in order to be fully supported on Kubernetes. Stay tuned for more information on present and next works surrounding the Wikimedia Toolforge service. The next blog post will share more concrete details. This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez.

1 April 2022

Russ Allbery: Review: Princess Floralinda and the Forty-Flight Tower

Review: Princess Floralinda and the Forty-Flight Tower, by Tamsyn Muir
Publisher: Subterranean Press
Copyright: 2020
ISBN: 1-59606-992-9
Format: Kindle
Pages: 111
A witch put Princess Floralinda at the top of a forty-flight tower, but it wasn't personal. This is just what witches do, particularly with princesses with butter-coloured curls and sapphire-blue eyes. Princes would come from miles around to battle up the floors of the tower and rescue the princess. The witch even helpfully provided a golden sword, in case a prince didn't care that much about princesses. Floralinda was provided with water and milk, two loaves of bread, and an orange, all of them magically renewing, to sustain her while she waited. In retrospect, the dragon with diamond-encrusted scales on the first floor may have been a mistake. None of the princely endeavors ever saw the second floor. The diary that Floralinda found in her room indicated that she may not be the first princess to have failed to be rescued from this tower. Floralinda finally reaches the rather astonishing conclusion that she might have to venture down the tower herself, despite the goblins she was warned were on the 39th floor (not to mention all the other monsters). The result of that short adventure, after some fast thinking, a great deal of luck, and an unforeseen assist from her magical food, is a surprising number of dead goblins. Also seriously infected hand wounds, because it wouldn't be a Tamsyn Muir story without wasting illness and body horror. That probably would have been the end of Floralinda, except a storm blew a bottom-of-the-garden fairy in through the window, sufficiently injured that she and Floralinda were stuck with each other, at least temporarily. Cobweb, the fairy, is neither kind nor inclined to help Floralinda (particularly given that Floralinda is not a child whose mother is currently in hospital), but it is an amateur chemist and finds both Floralinda's tears and magical food intriguing. Cobweb's magic is also based on wishes, and after a few failed attempts, Floralinda manages to make a wish that takes hold. Whether she'll regret the results is another question. This is a fairly short novella by the same author as Gideon the Ninth, but it's in a different universe and quite different in tone. This summary doesn't capture the writing style, which is a hard-to-describe mix of fairy tale, children's story, and slightly archaic and long-winded sentence construction. This is probably easier to show with a quote:
"You are displaying a very small-minded attitude," said the fairy, who seemed genuinely grieved by this. "Consider the orange-peel, which by itself has many very nice properties. Now, if you had a more educated brain (I cannot consider myself educated; I have only attempted to better my situation) you would have immediately said, 'Why, if I had some liquor, or even very hot water, I could extract some oil from this orange-peel, which as everyone knows is antibacterial; that may well do my hands some good,' and you wouldn't be in such a stupid predicament."
On balance, I think this style worked. It occasionally annoyed me, but it has some charm. About halfway through, I was finding the story lightly entertaining, although I would have preferred a bit less grime, illness, and physical injury. Unfortunately, the rest of the story didn't work for me. The dynamic between Floralinda and Cobweb turns into a sort of D&D progression through monster fights, and while there are some creative twists to those fights, they become all of a sameness. And while I won't spoil the ending, it didn't work for me. I think I see what Muir was trying to do, and I have some intellectual appreciation for the idea, but it wasn't emotionally satisfying. I think my root problem with this story is that Muir sets up a rather interesting world, one in which witches artistically imprison princesses, and particularly bright princesses (with the help of amateur chemist fairies) can use the trappings of a magical tower in ways the witch never intended. I liked that; it has a lot of potential. But I didn't feel like that potential went anywhere satisfying. There is some relationship and characterization work, and it reached some resolution, but it didn't go as far as I wanted. And, most significantly, I found the end point the characters reached in relation to the world to be deeply unsatisfying and vaguely irritating. I wanted to like this more than I did. I think there's a story idea in here that I would have enjoyed more. Unfortunately, it's not the one that Muir wrote, and since so much of my problem is with the ending, I can't provide much guidance on whether someone else would like this story better (and why). But if the idea of taking apart a fairy-tale tower and repurposing the pieces sounds appealing, and if you get along better with Muir's illness motif than I do, you may enjoy this more than I did. Rating: 5 out of 10

Antoine Beaupr : Salvaged my first Debian package

I finally salvaged my first Debian package, python-invoke. As part of ITS 964718, I moved the package from the Openstack Team to the Python team. The Python team might not be super happy with it, because it's breaking some of its rules, but at least someone (ie. me) is actively working (and using) the package.

Wait what People not familiar with Debian will not understand anything in that first paragraph, so let me expand. Know-it-all Debian developers (you know who you are) can skip to the next section. Traditionally, the Debian project (my Linux-based operating system of choice) has prided itself on the self-managed, anarchistic organisation of its packaging. Each package maintainer is the lord of their little kingdom. Some maintainers like to accumulate lots of kingdoms to rule over. (Yes, it really doesn't sound like anarchism when you put it like that. Yes, it's complicated: there's a constitution and voting involved. And yes, we're old.) Therefore, it's really hard to make package maintainers do something they don't want. Typically, when things go south, someone makes a complaint to the Debian Technical Committee (CTTE) which is established by the Debian constitution to resolve such conflicts. The committee is appointed by the Debian Project leader, elected each year (and there's an election coming up if you haven't heard). Typically, the CTTE will then vote and formulate a decision. But here's the trick: maintainers are still free to do whatever they want after that, in a sense. It's not like the CTTE can just break down doors and force maintainers to type code. (I won't go into the details of the why of that, but it involves legal issues and, I think, something about the Turing halting problem. Or something like that.) Anyways. The point is all that is super heavy and no one wants to go there... (Know-it-all Debian developers, I know you are still reading this anyways and disagree with that statement, but please, please, make it true.) ... but sometimes, packages just get lost. Maintainers get distracted, or busy with something else. It's not that they want to abandon their packages. They love their little fiefdoms. It's just there was a famine or a war or something and everyone died, and they have better things to do than put up fences or whatever. So clever people in Debian found a better way of handling such problems than waging war in the poor old CTTE's backyard. It's called the Package Salvaging process. Through that process, a maintainer can propose to take over an existing package from another maintainer, if a certain set of condition are met and a specific process is followed. Normally, taking over another maintainer's package is basically a war declaration, rarely seen in the history of Debian (yes, I do think it happened!), as rowdy as ours is. But through this process, it seems we have found a fair way of going forward. The process is basically like this:
  1. file a bug proposing the change
  2. wait three weeks
  3. upload a package making the change, with another week delay
  4. you now have one more package to worry about
Easy right? It actually is! Process! It's magic! It will cure your babies and resurrect your cat!

So how did that go? It went well! The old maintainer was actually fine with the change because his team wasn't using the package anymore anyways. He asked to be kept as an uploader, which I was glad to oblige. (He replied a few months after the deadline, but I wasn't in a rush anyways, so that doesn't matter. It was polite for him to answer, even if, technically, I was already allowed to take it over.) What happened next is less shiny for me though. I totally forgot about the ITS, even after the maintainer reminded me of its existence. See, the thing is the ITS doesn't show up on my dashboard at all. So I totally forgot about it (yes, twice). In fact, the only reason I remembered it was that got into the process of formulating another ITS (1008753, trocla) and I was trying to figure out how to write the email. Then I remembered: "hey wait, I think I did this before!" followed by "oops, yes, I totally did this before and forgot for 9 months". So, not great. Also, the package is still not in a perfect shape. I was able to upload the upstream version that was pending 1.5.0 to clear out the ITS, basically. And then there's already two new upstream releases to upload, so I pushed 1.7.0 to experimental as well, for good measure. Unfortunately, I still can't enable tests because everything is on fire, as usual. But at least my kingdom is growing.

Appendix Just in case someone didn't notice the hyperbole, I'm not a monarchist promoting feudalism as a practice to manage a community. I do not intend to really "grow my kingdom" and I think the culture around "property" of "packages" is kind of absurd in Debian. I kind of wish it would go away. (Update: It has also been pointed out that I might have made Debian seem more confrontational than it actually is. And it's kind of true: most work and interactions in Debian actually go fine, it's only a minority of issues that degenerate into conflicts. It's just that they tend to take up a lot of space in the community, and I find that particularly draining. And I think think our "package ownership" culture is part of at least some of those problems.) Team maintenance, the LowNMU process, and low threshold adoption processes are all steps in the good direction, but they are all opt in. At least the package salvaging process is someone a little more ... uh... coercive? Or at least it allows the community to step in and do the right thing, in a sense. We'll see what happens with the coming wars around the recent tech committee decision, which are bound to touch on that topic. (Hint: our next drama is called "usrmerge".) Hopefully, LWN will make a brilliant article to sum it up for us so that I don't have to go through the inevitable debian-devel flamewar to figure it out. I already wrecked havoc on the #debian-devel IRC channel asking newbie questions so I won't stir that mud any further for now. (Update: LWN, of course, did make an article about usrmerge in Debian. I will read it soon and can then tell you know if it's brilliant, but they are typically spot on.)

Paul Wise: FLOSS Activities March 2022

Focus This month I didn't have any particular focus. I just worked on issues in my info bubble.

Changes

Issues

Review
  • Spam: reported 3 Debian bug reports and 53 Debian mailing list posts
  • Debian wiki: RecentChanges for the month
  • Debian BTS usertags: changes for the month
  • Debian screenshots:

Administration
  • Debian servers: investigate wiki mail delivery issue, restart backup director
  • Debian wiki: unblock IP addresses, approve accounts

Communication
  • Forward python-plac test failure issue upstream
  • Participate in Debian Project Leader election discussions
  • Respond to queries from Debian users and contributors on the mailing lists and IRC

Sponsors The oci-python-sdk and plac work was sponsored. All other work was done on a volunteer basis.

31 March 2022

Russell Coker: AMT/MEBX on Debian

I ve just been playing with Intel s Active Management Technology (AMT) [1] which is also known as Management Engine Bios Extension (MEBX). Firstly a disclaimer, using this sort of technology gives remote access to your system at a level that allows in some ways overriding the OS. If this gets broken then you have big problems. Also all the code that matters is non-free. Please don t comment on this post saying that AMT is bad, take it as known that it has issues and that people are forced to use it anyway. I tested this out on a HP Z420 workstation. The first thing it to enable AMT via Intel MEBX , the default password is admin . On first use you are compelled to set a new password which must be 8+ characters containing upper and lower case, number, and punctuation characters. The Debian package amtterm (which needs the package libsoap-lite-perl ) has basic utilities for AMT. The amttool program connects to TCP port 16992 and the amtterm program connects to TCP port 16994. Note that these programs seem a little rough, you can get Perl errors (as opposed to deliberate help messages) if you enter bad command-line parameters. They basically work but could do with some improvement. If you use DHCP for the IP address the DHCP hostname will be DESKTOP-$AssetID and you can find the IP address by requesting an alert be sent to the sysadmin. Here are some examples of amttool usage:
# get AMT info
AMT_PASSWORD="$PASS" amttool $IP
# reset the system and redirect BIOS messages to serial over lan
AMT_PASSWORD="$PASS" amttool reset bios
# access serial over lan console
amtterm -p "$PASS" $IP
The following APT configuration enables the Ubuntu package wsmancli which had some features not in any Debian packages last time I checked.
deb http://us.archive.ubuntu.com/ubuntu/ bionic-updates universe
deb http://us.archive.ubuntu.com/ubuntu/ bionic universe
This Cyberciti article has information on accessing KVM over AMT [2], I haven t tried to do that yet.

Russell Coker: Links March 2022

Anarcat wrote a great blog post about switching from OpenNTP to Chrony which gives a good overview of how NTP works and how accurate the different versions are [1]. Bleeping Computer has an amusing article about criminals who copied a lot of data from NVidia servers including specs of their latest products [2], they are threatening to release all the data if NVidia doesn t stop crippling their GPUs to make them unsuitable for crypto currency mining. I don t support these criminals, but I think NVidia should allow people who buy hardware to use their property as they choose. If cryptocurrency miners buy all the NVidia products then NVidia still makes the sales, they could even auction them to make more money. NPR has a disturbing article about the way execution by lethal injection works in the US [3]. It seems that most people die in an extremely unpleasant way. It makes the North Korean execution by anti-aircraft gun seem civilised. The DirtyPipe vulnerability is the latest serious security issue in the Linux kernel [4]. The report of how it was discovered is very interesting and should be read by all sysadmins. SE Linux will not save you from this as the vulnerability allows writing to read-only files like /etc/passwd. Politico has an insightful analysis of Putin, it s not good news he wants to conquer all territory that had ever been part of a Russian empire at any time in history [5]. The Guardian has an informative article about the EU s attempts to debunk Russian propaganda about Covid19 [6]. Fortunately the sanctions are reducing Russia s ability to do such things now. The Guardian has in interesting article about a project to use literary analysis to predict wars [7]. Funded by the German military but funding was cut after it was proven to work. The Fact Act is a proposal by David Brin for political changes in the US to involve scientists and statisticians in an official advisory role in the legislative process [8], it s an idea with a lot of potential. Technology Review has an interesting interview with the leader of the NSA s Research Directorate [9]. In 2008 the EFF posted a long and informative article about the RIAA s war against music fans [10]. I had followed a lot of the news about this when it was happening, but I still learnt some things from this article that I hadn t known at the time. Also considering past legal battles in the context of the current situation is useful. As an aside all the music I want to listen to is now on YouTube and youtube-dl works really well for me. The 1952 edition of Psychiatry: Journal of Interpersonal Relations has an interesting article On Cooling the Mark Out [11] which starts about how criminal gangs engaged in fraud try to make their victims come to terms with the loss in a way that doesn t involve the police. But it goes on to cover ways of dealing with loss of status in general. The layout is hacky with words broken by hyphens in the middle of lines as it appears to have been scanned from paper, converted to MS-Word, and from there to PDF. But it s worth it. The Internet Heist by Cory Doctorow is an insightful series of 3 articles about the MPAA (MAFIAA) attempts to take over all TV distribution in the US [12]. Wired has an interesting exerpt from the book Spies, Lies, and Algorithms: The History and Future of American Intelligence , by Amy B. Zegart [13]. Interesting summary of the open source intelligence systems (which have nothing to do with open source as free software). But it would be interesting to have an open source intelligence organisation along similar lines to open source software. The guy who tracks billionaire s private jets is an example of this.

29 March 2022

Jeremy Bicha: How to install a bunch of debs

Recently, I needed to check if a regression in Ubuntu 22.04 Beta was triggered by the mesa upgrade. Ok, sounds simple, let me just install the older mesa version. Let s take a look. Oh, wow, there are about 24 binary packages (excluding the packages for debug symbols) included in mesa! Because it s no longer published in Ubuntu 22.04, we can t use our normal apt way to install those packages. And downloading those one by one and then installing them sounds like too much work. Step Zero: Prerequisites If you are an Ubuntu (or Debian!) developer, you might already have ubuntu-dev-tools installed. If not, it has some really useful tools!
$ sudo apt install ubuntu-dev-tools
Step One: Create a Temporary Working Directory Let s create a temporary directory to hold our deb packages. We don t want to get them mixed up with other things.
$ mkdir mesa-downgrade; cd mesa-downgrade
Step Two: Download All the Things One of the useful tools is pull-lp-debs. The first argument is the source package name. In this case, I next need to specify what version I want; otherwise it will give me the latest version which isn t helpful. I could specify a series codename like jammy or impish but that won t give me what I want this time.
$ pull-lp-debs mesa 21.3.5-1ubuntu2
By the way, there are several other variations on pull-lp-debs:
  • pull-lp-source downloads source package from Launchpad.
  • pull-lp-debs downloads debs package(s) from Launchpad.
  • pull-lp-ddebs downloads dbgsym/ddebs package(s) from Launchpad.
  • pull-lp-udebs downloads udebs package(s) from Launchpad.
  • pull-debian-* same as pull-lp-* but for Debian packages.
I use the LP and Debian source versions frequently when I just want to check something in a package but don t need the full git repo. Step Three: Install Only What We Need This command allows us to install just what we need.
$ sudo apt install --only-upgrade --mark-auto ./*.deb
--only-upgrade tells apt to only install packages that are already installed. I don t actually need all 24 packages installed; I just want to change the versions for the stuff I already have. --mark-auto tells apt to keep these packages marked in dpkg as automatically installed. This allows any of these packages to be suggested for removal once there isn t anything else depending on them. That s useful if you don t want to have old libraries installed on your system in case you do manual installation like this frequently. Finally, the apt install syntax has a quirk: It needs a path to a file because it wants an easy way to distinguish from a package name. So adding ./ before filenames works. I guess this is a bug. apt should be taught that libegl-mesa0_21.3.5-1ubuntu2_amd64.deb is a file name not a package name. Step Four: Cleanup Let s assume that you installed old versions. To get back to the current package versions, you can just upgrade like normal.
$ sudo apt dist-upgrade
If you do want to stay on this unsupported version a bit longer, you can specify which packages to hold:
$ sudo apt-mark hold
And you can use apt-mark list and apt-mark unhold to see what packages you have held and release the holds. Remember you won t get security updates or other bug fixes for held packages! And when you re done with the debs we download, you can remove all the files:
$ cd .. ; rm -ri mesa-downgrade
Bonus: Downgrading back to supported What if you did the opposite and installed newer stuff than is available in your current release? Perhaps you installed from jammy-proposed and you want to get back to jammy ? Here s the syntax for libegl-mesa0 Note the /jammy suffix on the package name.
$ sudo apt install libegl-mesa0/jammy
But how do you find these packages? Use apt list Here s one suggested way to find them:
$ apt list --installed --all-versions  grep local] --after-context 1
Finally, I should mention that apt is designed to upgrade packages not downgrade them. You can break things by downgrading. For instance, a database could upgrade its format to a new version but I wouldn t expect it to be able to reverse that just because you attempt to install an older version.

23 March 2022

Matthew Garrett: AMD's Pluton implementation seems to be controllable

I've been digging through the firmware for an AMD laptop with a Ryzen 6000 that incorporates Pluton for the past couple of weeks, and I've got some rough conclusions. Note that these are extremely preliminary and may not be accurate, but I'm going to try to encourage others to look into this in more detail. For those of you at home, I'm using an image from here, specifically version 309. The installer is happy to run under Wine, and if you tell it to "Extract" rather than "Install" it'll leave a file sitting in C:\\DRIVERS\ASUS_GA402RK_309_BIOS_Update_20220322235241 which seems to have an additional 2K of header on it. Strip that and you should have something approximating a flash image.

Looking for UTF16 strings in this reveals something interesting:

Pluton (HSP) X86 Firmware Support
Enable/Disable X86 firmware HSP related code path, including AGESA HSP module, SBIOS HSP related drivers.
Auto - Depends on PcdAmdHspCoreEnable build value
NOTE: PSP directory entry 0xB BIT36 have the highest priority.
NOTE: This option will NOT put HSP hardware in disable state, to disable HSP hardware, you need setup PSP directory entry 0xB, BIT36 to 1.
// EntryValue[36] = 0: Enable, HSP core is enabled.
// EntryValue[36] = 1: Disable, HSP core is disabled then PSP will gate the HSP clock, no further PSP to HSP commands. System will boot without HSP.

"HSP" here means "Hardware Security Processor" - a generic term that refers to Pluton in this case. This is a configuration setting that determines whether Pluton is "enabled" or not - my interpretation of this is that it doesn't directly influence Pluton, but disables all mechanisms that would allow the OS to communicate with it. In this scenario, Pluton has its firmware loaded and could conceivably be functional if the OS knew how to speak to it directly, but the firmware will never speak to it itself. I took a quick look at the Windows drivers for Pluton and it looks like they won't do anything unless the firmware wants to expose Pluton, so this should mean that Windows will do nothing.

So what about the reference to "PSP directory entry 0xB BIT36 have the highest priority"? The PSP is the AMD Platform Security Processor - it's an ARM core on the CPU package that boots before the x86. The PSP firmware lives in the same flash image as the x86 firmware, so the PSP looks for a header that points it towards the firmware it should execute. This gives a pointer to a "directory" - a list of different object types and where they're located in flash (there's a description of this for slightly older AMDs here). Type 0xb is treated slightly specially. Where most types contain the address of where the actual object is, type 0xb contains a 64-bit value that's interpreted as enabling or disabling various features - something AMD calls "soft fusing" (Intel have something similar that involves setting bits in the Firmware Interface Table). The PSP looks at the bits that are set here and alters its behaviour. If bit 36 is set, the PSP tells Pluton to turn itself off and will no longer send any commands to it.

So, we have two mechanisms to disable Pluton - the PSP can tell it to turn itself off, or the x86 firmware can simply never speak to it or admit that it exists. Both of these imply that Pluton has started executing before it's shut down, so it's reasonable to wonder whether it can still do stuff. In the image I'm looking at, there's a blob starting at 0x0069b610 that appears to be firmware for Pluton - it contains chunks that appear to be the reference TPM2 implementation, and it broadly decompiles as valid ARM code. It should be viable to figure out whether it can do anything in the face of being "disabled" via either of the above mechanisms.

Unfortunately for me, the system I'm looking at does set bit 36 in the 0xb entry - as a result, Pluton is disabled before x86 code starts running and I can't investigate further in any straightforward way. The implication that the user-controllable mechanism for disabling Pluton merely disables x86 communication with it rather than turning it off entirely is a little concerning, although (assuming Pluton is behaving as a TPM rather than having an enhanced set of capabilities) skipping any firmware communication means the OS has no way to know what happened before it started running even if it has a mechanism to communicate with Pluton without firmware assistance. In that scenario it'd be viable to write a bootloader shim that just faked up the firmware measurements before handing control to the OS.

The bit 36 disabling mechanism seems more solid? Again, it should be possible to analyse the Pluton firmware to determine whether it actually pays attention to a disable command being sent. But even if it chooses to ignore that, if the PSP is in a position to just cut the clock to Pluton, it's not going to be able to do a lot. At that point we're trusting AMD rather than trusting Microsoft, but given that you're also trusting AMD to execute the code you're giving them to execute, it's hard to avoid placing trust in them.

Overall: I'm reasonably confident that systems that ship with Pluton disabled via setting bit 36 in the soft fuses are going to disable it sufficiently hard that the OS can't do anything about it. Systems that give the user an option to enable or disable it are a little less clear in that respect, and it's possible (but not yet demonstrated) that an OS could communicate with Pluton anyway. However, if that's true, and if the firmware never communicates with Pluton itself, the user could install a stub loader in UEFI that mimicks the firmware behaviour and leaves the OS thinking everything was good when it absolutely is not.

So, assuming that Pluton in its current form on AMD has no capabilities outside those we know about, the disabling mechanisms are probably good enough. It's tough to make a firm statement on this before I have access to a system that doesn't just disable it immediately, so stay tuned for updates.

comment count unavailable comments

22 March 2022

Ulrike Uhlig: Workshops about anger, saying NO, and mapping one s capacities and desires

For the second year in a row, I proposed some workshops at the feminist hackers assembly at the remote C3. I m sharing them here because I believe they might be useful to others.

Anger workshop Based on my readings about the subject and a mediation training, I created a first workshop about dealing with one s own anger for the feminist hackers assembly in 2020. Many women who attended said they recognized themselves in what I was talking about. I created the exercises in the workshop with the goal of getting participants to share and self-reflect in small groups. I m not giving out solutions, instead proposals on how to deal with anger come from the participants themselves. (I added the last two content pages to the file after the workshop.) This is why this workshop is always different, depending on the group and what they want to share. The first time I did this workshop was a huge success and so I created an improved version for the assembly of 2021. Angry womxn* workshop

The act of saying NO We often say yes, despite wanting to say no, out of a sense of duty, or because we learned that we should always be nice and helpful, and that our own needs are best served last. Many people don t really know how to say no. Sarah Cooper, a former Google employee herself, makes fun of this in her fabulous book How to Be Successful Without Hurting Men s Feelings (highly recommended read!): A drawing of a woman who says: How I say yes: I'd love to. How I say no: sure. That s why a discussion space about saying NO did not seem out of place at the feminist hackers assembly :) I based my workshop on the original, created by the Institute of War and Peace Reporting and distributed through their holistic security training manual. I like this workshop because sharing happens in a small groups and has an immediately felt effect. Several people reported that the exercises allowed them to identify the exact moment when they had said yes to something despite really having wanted to say no. The exercises from the workshop can easily be done with a friend or trusted person, and they can even be done alone by writing them down, although the effect in writing might be less pronounced. The act of saying NO workshop

Mapping capacities and desires Based on discussions with a friend, whose company uses SWOT analysis (strengths weaknesses opportunities threats) to regularly check in with their employees, and to allow employees to check in with themselves, I created a similar tool for myself which I thought would be nice to share with others. It s a very simple self-reflection that can help map out what works well, what doesn t work so well and where one wants to go in the future. I find it important to not use this tool narrow-mindedly only regarding work skills and expertise. Instead, I think it s useful to also include soft skills, hobbies, non-work capacities and whatever else comes to mind in order to create a truer map. Fun fact: During the assembly, a bunch of participants reported that they found it hard to distinguish between things they don t like doing and things they don t know how to do. Mapping capacities and desires

Known issues One important feedback point I got is that people felt the time for the exercises in all three workshops could have been longer. In case you want to try out these workshops, you might want to take this into account.

21 March 2022

Gunnar Wolf: Long, long, long live Emacs after 39 years

Reading Planet Debian (see, Sam, we are still having a conversation over there? ), I read Anarcat s 20+ years of Emacs. And.. Well, should I brag contribute to the discussion? Of course, why not? Emacs is the first computer program I can name that I ever learnt to use to do something minimally useful. 39 years ago.
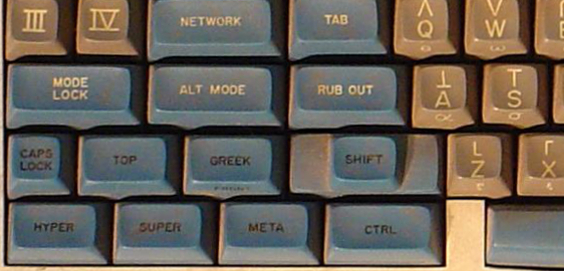
From the Space Cadet keyboard that (obviously ) influenced Emacs early design
The Emacs editor was born, according to Wikipedia, in 1976, same year as myself. I am clearly not among its first users. It was already a well-established citizen when I first learnt it; I am fortunate to be the son of a Physics researcher at UNAM, My father used to take me to his institute after he noticed how I was attracted to computers; we would usually spend some hours there between 7 and 11PM on Friday nights. His institute had a computer room where they had very sweet gear: Some 10 Heathkit terminals quite similar to this one: The terminals were connected (via individual switches) to both a PDP-11 and a Foonly F2 computers. The room also had a beautiful thermal printer, a beautiful Tektronix vectorial graphics output terminal, and some other stuff. The main user for my father was to typeset some books; he had recently (1979) published Integral Transforms in Science and Engineering (that must be my first mention in scientific literature), and I remember he was working on the proceedings of a conference he held in Oaxtepec (the account he used in the system was oax, not his usual kbw, which he lent me). He was also working on Manual de Lenguaje y Tipograf a Cient fica en Castellano, where you can see some examples of TeX; due to a hardware crash, the book has the rare privilege of being a direct copy of the output of the thermal printer: It was not possible to produce a higher resolution copy for several years But it is fun and interesting to see what we were able to produce with in-house tools back in 1985! So, what could he teach me so I could use the computers while he worked? TeX, of course. No, no LaTeX (that was published in 1984). LaTeX is a set of macros developed initially by Leslie Lamport, used to make TeX easier; TeX was developed by Donald Knuth, and if I have this information correct, it was Knuth himself who installed and demonstrated TeX in the Foonly computer, during a visit to UNAM. Now, after 39 years hammering at Emacs buffers Have I grown extra fingers? Nope. I cannot even write decent elisp code, and can barely read it. I do use org-mode (a lot!) and love it; I have written basically five books, many articles and lots of presentations and minor documents with it. But I don t read my mail or handle my git from Emacs. I could say, I m a relatively newbie after almost four decades. Four decades When we got a PC in 1986, my father got the people at the Institute to get him memacs (micro-emacs). There was probably a ten year period I barely used any emacs, but always recognized it. My fingers hve memorized a dozen or so movement commands, and a similar number of file management commands. And yes, Emacs and TeX are still the main tools I use day to day.

19 March 2022

Russell Coker: More About the Librem 5

I concluded my previous post about the Purism Librem 5 [1] with the phone working as a Debian/GNOME system with SSH access over the LAN. Before I published that post I managed to render it unbootable, making a new computer unbootable on the first day of owning it isn t uncommon for me. In this case I tried to get SE Linux running on it and changing the kernel commandline parameter security=apparmor to security=selinux caused it to fail the checksum on kernel parameters and halt the boot. That seems to require a fresh install, it seems possible that I could setup my Librem5 to boot a recovery image from a SD card in such situations but that doesn t seem to be well documented and I didn t have any important data to lose. If I do figure out how to recover data by booting from a micro SD card I ll document it. Here s the documentation for reflashing the phone [2], you have to use the --variant luks option for the flashing tool to have an encrypted root filesystem (should default to on to match the default shipping configuration). There is an option --skip-cleanup to allow you to use the same image multiple times, but that probably isn t useful. The image that is available for download today has the latest kernel update that I installed yesterday so it seems that they quickly update the image which makes it convenient to get the latest (dpkg is slow on low power ARM systems). Overall the flash tool is nicely written, does the download and install and instructs you how to get the phone in flashing mode. It is a minor annoyance that the battery has to be removed as part of the flashing process, I will probably end up flashing my phone more often than I want to take the back off the case. A mitigating factor is that the back is well designed and doesn t appear prone to having it s plastic tabs breaking off when removed (as has happened to several other phones I ve owned). The camera doesn t seem to work well at this time, all photos have an unusually low brightness. The audio recording also doesn t work well, speaking clearly into the phone results in quiet recordings. I updated the Debian Wiki page on Mobile devices [3] to include a link to a page about the Librem5 [4] and to also have a section about applications known to work well on mobile devices. Hopefully other people will make some additions to that as most programs in Debian don t work well on mobile devices so we need a list of known good applications as well as applications that can be easily changed to work well. One thing I ve started looking at is the code for the Geary MUA (the default MUA for the Librem5 and the only one in Debian I know to be suitable for a phone). It needs the Thunderbird style autoconfig and it needs the ability to select which IMAP folders to scan as a common practice is to have some large IMAP folders that aren t used on mobile devices. I believe that Android runs each app in a separate UID to prevent them from messing with each other. The configuration on a standard Linux system and on PureOS is to have all apps running with the same permissions, I think this needs to be improved both for phones and for regular Linux systems which will probably benefit more than phones do. I ll write another blog post about this.

15 March 2022

Russell Coker: Librem 5 First Impression

I just received the Purism Librem 5 that I paid for years ago (I think it was 2018). The process of getting the basic setup done was typical (choosing keyboard language, connecting to wifi, etc). Then I tried doing things. One thing I did was update to the latest PureOS release which gave me a list of the latest Debian packages installed which is nice. The first problem I found was the lack of notification when the phone is trying to do something. I d select to launch an app, nothing would happen, then a few seconds later it would appear. When I go to the PureOS app store and get a list of apps in a category nothing happens for ages (shows a blank list) then it might show actual apps, or it might not. I don t know what it s doing, maybe downloading a list of apps, if so it should display how many apps have had their summary data downloaded or how many KB of data have been downloaded so I know if it s doing something and how long it might take. Running any of the productivity applications requires a GNOME keyring, I selected a keyring password of a few characters and it gave a warning about having no password (does this mean it took 3 characters to be the same as 0 characters?). Then I couldn t unlock it later. I tried deleting the key file and creating a new one with a single character password and got the same result. I think that such keyring apps have little benefit, all processes in the session have the same UID and presumable can use ptrace to get data from each other s memory space. If the keyring program was SETGID and the directory used to store the keyring files was a system directory with execute access only for that group then it might provide some benefit (SETGID means that ptrace is denied). Ptrace is denied for the keyring but relying on a user space prompt for the passphrase to a file that the user can read seems of minimal benefit as a hostile process could read the file and prompt for the passphrase. This is probably more of a Debian issue, and I reproduced the keyring issue with my Debian workstation. The Librem 5 is a large phone (unusually thick by modern phone standards) and is rumoured to be energy hungry. When I tried charging it from the USB port on my PC (HP ML110 Gen9) the charge level went down. I used the same USB port and USB cable that I use to charge my Huawei Mate 10 Pro every day, so other phones can draw more power from that USB port and cable faster than they use it. The on-sceen keyboard for the Librem 5 is annoying, it doesn t have a TAB key and the cursor control keys are unreasonably small. The keyboard used by ConnectBot (the most popular SSH client for Android) is much better, it has it s own keys for CTRL, ESC, TAB, arrows, HOME, and END in addition to the regular on-screen keyboard. The Librem 5 comes with a terminal app by default which is much more difficult to use than it should be due to the lack of TAB filename completion etc. The phone has a specified temperature range of 0C to 35C, that s not great for Australia where even the cooler cities have summer temperatures higher than that. When charging on a fast charger (one that can provide energy faster than the phone uses it) the phone gets quite warm. It feels like more than 10C hotter than the ambient temperature, so I guess I can t charge it on Monday afternoon when the forecast is 31C! Maybe I should put a USB charger by my fridge with a long enough cable that I can charge a phone that s inside the fridge, seriously. Having switches to disable networking is a good security feature and designing the phone with separate components that can t interfere with each other is good too. There are reports that software fixes will reduce the electricity use which will alleviate the problems with charging and temperature. Most of my problems are clearly software related and therefore things that I can fix (in theory at least I don t have unlimited coding time). Overall this wasn t the experience I had hoped for after spending something like $700 and waiting about 4 years (so long that I can t easily find the records of how long and how much money). Getting It Working It seems that the PureOS app store app doesn t work properly. I can visit the app site and then select an app to install which then launches the app store app to do the install, which failed for every app I tried. Then I tried going to the terminal and running the following:
sudo bash
apt update
apt install openssh-server netcat
So I should be able to use APT to install everything I want and use the PureOS web site as a guide to what is expected to work on the phone. As an aside the PureOS apt repository appears to be a mirror or rebuild of the Debian/Bullseye arm64 archive without non-free components that they call Byzanteum. Then I could ssh to my phone via ssh purism@purism (after adding an entry to /etc/hosts with the name purism and a static entry in my DHCP configuration to match) and run sudo bash to get root. To be able to login to root directly I had to install a ssh key (root is setup to login without password) and run usermod --expiredate= root (empty string for expire date) to have direct root logins. I put the following in /etc/ssh/sshd_config.d/local.conf to restrict who can login (I added the users I want to the sshusers group). It also uses the ClientAlive checks because having sessions break due to IP address changes is really common with mobile devices and we don t want disconnected sessions taking up memory forever.
AllowGroups sshusers
PasswordAuthentication no
UseDNS no
ClientAliveInterval 60
ClientAliveCountMax 6
Notifications The GNOME notification system is used for notifications in the phone UI. So if you install the package libnotify-bin you get a utility notify-send that allows sending notifications from shell scripts. Final Result Now it basically works as a Debian workstation with a single-button mouse. So I just need to configure it as I would a Debian system and fix bugs along the way. Presumably any bug fixes I get into Debian will appear in PureOS shortly after the next Debian release.

9 March 2022

Dirk Eddelbuettel: RcppRedis 0.2.0: Major Updates

A new major release of RcppRedis arrived on CRAN today. RcppRedis is one of several packages connecting R to the fabulous Redis in-memory datastructure store (and much more). RcppRedis does not pretend to be feature complete, but it may do some things faster than the other interfaces, and also offers an optional coupling with MessagePack binary (de)serialization via RcppMsgPack. The package has carried production loads for several years now. This release integrates support for pub/sub, a popular messaging pattern in which one or more clients can subscribe to one or more channels . Whenever a client instances publishes, the Redis server immediately updates all clients listening on the given channel. This pattern is fairly common to transmit data to listeners. A there is a bit more to explain about this, I also added a brand-new vignette describing pub/sub with RcppRedis, along with another introductory vignette about Redis itself. We blogged about this exciting new feature and its particular use for market monitoring in R4 #36 recently too. The pub/sub feature was available in package rredis by Bryan Lewis and has now been ported over by Bryan in a truly elegant yet compact implementation. We placed the code for the pub/sub examples, both for a single symbol (SP 500) as well as for a set of (futures) symbols, into a new examples/ subdirectory. Other changes in this release are the removal of the build-dependency on Boost (or, rather, my BH package), an update to the included hiredis library (used if no system-wide version is found), and an updated to the UCRT build for R. That last one is a bit of a sore spot and nobody at CRAN deemed it necessary to tell me they were waiting for me to make this change; communication with the CRAN team can still be challenging (and I am being generous here). Anyway, the package is now on CRAN so all is well now, at long last. The detailed changes list follows.

Changes in version 0.2.0 (2022-03-08)
  • Two simple C++11 features remove needs for BH and lexical_cast() (Dirk in #45 addressing #44).
  • Redis pub/sub is now supported (Dirk in #43, Bryan in #46).
  • Bryan Lewis is now a coauthor.
  • Added pub/sub examples for single and multiple Globex symbols.
  • The included hiredis sources have been updated to release 1.0.2.
  • Two vignettes have been added to introduce Redis and to described a live market-monitoring application included in directory pubsub/.
  • The UCRT build was updated per a suggestion by Tomas.

Courtesy of CRANberries, there is also a diffstat report for this release. More information is on the RcppRedis page. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.
5 March 2022

Reproducible Builds: Reproducible Builds in February 2022

Welcome to the February 2022 report from the Reproducible Builds project. In these reports, we try to round-up the important things we and others have been up to over the past month. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website.
Jiawen Xiong, Yong Shi, Boyuan Chen, Filipe R. Cogo and Zhen Ming Jiang have published a new paper titled Towards Build Verifiability for Java-based Systems (PDF). The abstract of the paper contains the following:
Various efforts towards build verifiability have been made to C/C++-based systems, yet the techniques for Java-based systems are not systematic and are often specific to a particular build tool (eg. Maven). In this study, we present a systematic approach towards build verifiability on Java-based systems.
GitBOM is a flexible scheme to track the source code used to generate build artifacts via Git-like unique identifiers. Although the project has been active for a while, the community around GitBOM has now started running weekly community meetings.
The paper Chris Lamb and Stefano Zacchiroli is now available in the March/April 2022 issue of IEEE Software. Titled Reproducible Builds: Increasing the Integrity of Software Supply Chains (PDF), the abstract of the paper contains the following:
We first define the problem, and then provide insight into the challenges of making real-world software build in a reproducible manner-this is, when every build generates bit-for-bit identical results. Through the experience of the Reproducible Builds project making the Debian Linux distribution reproducible, we also describe the affinity between reproducibility and quality assurance (QA).

In openSUSE, Bernhard M. Wiedemann posted his monthly reproducible builds status report.
On our mailing list this month, Thomas Schmitt started a thread around the SOURCE_DATE_EPOCH specification related to formats that cannot help embedding potentially timezone-specific timestamp. (Full thread index.)
The Yocto Project is pleased to report that it s core metadata (OpenEmbedded-Core) is now reproducible for all recipes (100% coverage) after issues with newer languages such as Golang were resolved. This was announced in their recent Year in Review publication. It is of particular interest for security updates so that systems can have specific components updated but reducing the risk of other unintended changes and making the sections of the system changing very clear for audit. The project is now also making heavy use of equivalence of build output to determine whether further items in builds need to be rebuilt or whether cached previously built items can be used. As mentioned in the article above, there are now public servers sharing this equivalence information. Reproducibility is key in making this possible and effective to reduce build times/costs/resource usage.

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb prepared and uploaded versions 203, 204, 205 and 206 to Debian unstable, as well as made the following changes to the code itself:
  • Bug fixes:
    • Fix a file(1)-related regression where Debian .changes files that contained non-ASCII text were not identified as such, therefore resulting in seemingly arbitrary packages not actually comparing the nested files themselves. The non-ASCII parts were typically in the Maintainer or in the changelog text. [ ][ ]
    • Fix a regression when comparing directories against non-directories. [ ][ ]
    • If we fail to scan using binwalk, return False from BinwalkFile.recognizes. [ ]
    • If we fail to import binwalk, don t report that we are missing the Python rpm module! [ ]
  • Testsuite improvements:
    • Add a test for recent file(1) issue regarding .changes files. [ ]
    • Use our assert_diff utility where we can within the test_directory.py set of tests. [ ]
    • Don t run our binwalk-related tests as root or fakeroot. The latest version of binwalk has some new security protection against this. [ ]
  • Codebase improvements:
    • Drop the _PATH suffix from module-level globals that are not paths. [ ]
    • Tidy some control flow in Difference._reverse_self. [ ]
    • Don t print a warning to the console regarding NT_GNU_BUILD_ID changes. [ ]
In addition, Mattia Rizzolo updated the Debian packaging to ensure that diffoscope and diffoscope-minimal packages have the same version. [ ]

Website updates There were quite a few changes to the Reproducible Builds website and documentation this month as well, including:
  • Chris Lamb:
    • Considerably rework the Who is involved? page. [ ][ ]
    • Move the contributors.sh Bash/shell script into a Python script. [ ][ ][ ]
  • Daniel Shahaf:
    • Try a different Markdown footnote content syntax to work around a rendering issue. [ ][ ][ ]
  • Holger Levsen:
    • Make a huge number of changes to the Who is involved? page, including pre-populating a large number of contributors who cannot be identified from the metadata of the website itself. [ ][ ][ ][ ][ ]
    • Improve linking to sponsors in sidebar navigation. [ ]
    • drop sponsors paragraph as the navigation is clearer now. [ ]
    • Add Mullvad VPN as a bronze-level sponsor . [ ][ ]
  • Vagrant Cascadian:

Upstream patches The Reproducible Builds project attempts to fix as many currently-unreproducible packages as possible. February s patches included the following:

Testing framework The Reproducible Builds project runs a significant testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
  • Daniel Golle:
    • Update the OpenWrt configuration to not depend on the host LLVM, adding lines to the .config seed to build LLVM for eBPF from source. [ ]
    • Preserve more OpenWrt-related build artifacts. [ ]
  • Holger Levsen:
  • Temporary use a different Git tree when building OpenWrt as our tests had been broken since September 2020. This was reverted after the patch in question was accepted by Paul Spooren into the canonical openwrt.git repository the next day.
    • Various improvements to debugging OpenWrt reproducibility. [ ][ ][ ][ ][ ]
    • Ignore useradd warnings when building packages. [ ]
    • Update the script to powercycle armhf architecture nodes to add a hint to where nodes named virt-*. [ ]
    • Update the node health check to also fix failed logrotate and man-db services. [ ]
  • Mattia Rizzolo:
    • Update the website job after contributors.sh script was rewritten in Python. [ ]
    • Make sure to set the DIFFOSCOPE environment variable when available. [ ]
  • Vagrant Cascadian:
    • Various updates to the diffoscope timeouts. [ ][ ][ ]
Node maintenance was also performed by Holger Levsen [ ] and Vagrant Cascadian [ ].

Finally If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

3 March 2022

Joerg Jaspert: Scan for SSH private keys without passphrase

SSH private key scanner (keys without passphrase) So for policy reasons, customer wanted to ensure that every SSH private key in use by a human on their systems has a passphrase set. And asked us to make sure this is the case. There is no way in SSH to check this during connection, so client side needs to be looked at. Which means looking at actual files on the system. Turns out there are multiple formats for the private keys - and I really do not want to implement something able to deal with that on my own. OpenSSH to the rescue, it ships a little tool ssh-keygen, most commonly known for its ability to generate SSH keys. But it can do much more with keys. One action is interesting here for our case: The ability to print out the public key to a given private key. For a key that is unprotected, this will just work. A key with a passphrase instead leads to it asking you for one. So we have our way to check if a key is protected by a passphrase. Now we only need to find all possible keys (note, the requirement is not keys in .ssh/ , but all possible, so we need to scan for them. But we do not want to run ssh-keygen on just any file, we would like to do it when we are halfway sure, that it is actually a key. Well, turns out, even though SSH has multiple formats, they all appear to have the string PRIVATE KEY somewhere very early (usually first line). And they are tiny - even a 16384bit RSA key is just above 12000 bytes long. Lets find every file thats less then 13000 bytes and has the magic string in it, and throw it at ssh-keygen - if we get a public key back, flag it. Also, we supply a random (ohwell, hardcoded) passphrase, to avoid it prompting for any. Scanning the whole system, one will find quite a surprising number of unprotected SSH keys. Well, better description possibly Unprotected RSA private keys , so the output does need to be checked by a human. This, of course, can be done in shell, quite simple. So i wrote some Rust code instead, as I am still on my task to try and learn more of it. If you are interested, you can find sshprivscanner and play with it, patches/fixes/whatever welcome.

Jamie McClelland: LVM Cache Surprises

By far the biggest LVM Cache surprise is just how well it works. Between 2010 and 2020, my single, biggest and most consistent headache managing servers at May First has been disk i/o. We run a number of physical hosts with encrypted disks, with each providing a dozen or so sundry KVM guests. And they consume a lot of disk i/o. This problem kept me awake at night and made me want to put my head on the table and cry during the day as I monitored the output of vmstat 1 and watched each disk i/o death spiral unfold. We tried everything. Turned off fsck s, turned off RAID monthly checks. Switched to less intensive backup systems. Added solid state drives and tried to stragically distribute them to our database partitions and other read/write heavy services. Added tmpfs file systems where it was possible. But, the sad truth was: we simply did not have the resources to pay for the infrastructure that could support the disk i/o our services demanded. Then, we discovered LVM caching (cue Hallelujah). We starting provisioning SSD partitions to back up our busiest spinning disk logical volumes and presto. Ten years of agony gone like a poof of smoke! I don t know which individuals are responsible for writing the LVM caching code but if you see this: THANK YOU! Your contributions to the world are noticed, appreciated and have had an enormous impact on at least one individual.

Some surprises

Filters For the last two years, with the exception of one little heart attack, LVM caches have gone very smoothly. Then, last week we upgraded 13 physical servers straight through from stretch to bullseye. It went relatively smoothly for the first half of our servers (the old ones hosting fewer resources). But, after rebooting our first server with lvm caching going on, we noticed that the cached disk wasn t accessible. No problem, we reasoned. We ll just uncache it. Except that didn t work either. We tried every argument we could find on the Internet but lvm insisted that the block device from the SSD volume group (that provides the caching device) was not available. Running pvs showed an unknown device and vgs reported similar errors. Now I started to panic a bit. There was a clean shutdown of the server, so surely all the data had been flushed to the disk. But, how can we get that data? We started a restore from backup process because we really thought that data was gone for ever. Then we had a really great theory: the caching logical volume comes from the SSD volume group, which gets decrypted after the spinning disk volume group. Maybe there s a timing issue? When the spinning disk volume group comes online, the caching logical volume is not yet available. So, we booted into busybox, and manually decrypted the SSD volume first, followed by the spinning disk volume. Alas, no dice. Now that we were fully desperate, we decided to restore the lvm configuration file for the entire spinning disk volume group. This felt kinda risky since we might be damaging all the currently working logical volumes, but it seemed like the only option we had. The main problem was that busybox didn t seem to have the lvm config tool we needed to restore the configuration from our backup (I think it might be there but it was late and we couldn t figure it out). And, our only readily available live install media was a Debian stretch disk via debirf. Debian stretch is pretty old and we really would have preferred to have the most modern tools available, but we decided to go with what we had. And, that was a good thing, because as soon as we booted into stretch and decrypted the disks, the lvm volume suddenly appeared, happy as ever. We uncached it and booted into the host system and there it was. We went to bed confused but relieved. The next morning my co-worker figured it out: filtering. During the stretch days we occassionally ran into an annoying problem: the logical volumes from guests would suddenly pop up on the host. This was mostly annoying but also it made possible some serious mistakes if you accidentally took a volume from a guest and used it on the host. The LVM folks seemed to have noticed this problem and introduced a new default filter that tries to only show you the devices that you should be seeing. Unfortunately for us, this new filter removed logical volumes from the list of available physical volumes. That does make sense for most people. But, not for us. It sounds a bit weird, but our setup looks like this:
  • One volume group derived from the spinning disks
  • One volume group derived from the SSD disks
Then we carve out logical volumes from each for each guest. Once we discovered LVM caching, we carved out SSD logical volumes to be used as caches for the spinning logical volumes. In restrospect, if we could start over, we would probably do it differently. In any event, once we discovered the problem, we used the handy configuration options in lvm.conf to tweak the filters to include our cache disks and once again, everything is back to working.

Saturated SSDs The other surprise seems unrelated to the upgrade. We have a phsyical server that has been suffering from disk i/o problems despite our use of LVM caching. Our answer, of course, was to add more LVM caches to the spinning logical volumes that seemed to be suffering. But somehow this was making things even worse. Then, we finally just removed the LVM caches from all the spinning disks and presto, disk i/o problems seemed to go away. What? Isn t that the opposite of what s supposed to happen? We re still trying to figure this one out, but it seems that our SSDs are saturated, in which case adding them as a caching volume really is going to make things worse. We re still not sure why they are saturated when none of the SSDs on our other hosts are saturated, but a few theories include:
  • They are doing more writing and/or it s a different kind of writing. I m still not sure I quite have the right tool to compare this host with other hosts. And, this host is our only MySQL network database server, hosting hundreds of GBs of database - all writing/reading direclty onto the SSDs.
  • They are broken or substanard SSDs (smartctl doesn t uncover any problems but maybe it s a bad model?)
I ll update this post as we learn more but welcome any suggestions in the comments. Update: 2022-03-07 Two more possible causes:
  • Our use of the write back feature: LVM cache has a nice feature that caches writes to smooth out writes to the underlying disk. Maybe our disks are simply writing more then can be handled and not using write back is our solution. This server supports a guest with an unusually large disk.
  • Maybe we haven t allocated a big enough LVM cache for the given volume so the contents are constantly being ejected?

Ian Jackson: 3D printed hard case for Fairphone 4

About 4 years ago, I posted about making a 3D printed case for my then-new phone. The FP2 was already a few years old when I got one and by now, some spares are unavailable - which is a problem, because I'm terribly hard on hardware. Indeed, that's why I need a very sturdy case for my phone - a case which can be ablative when necessary. With the arrival of my new Fairphone 4, I've updated my case design. Sadly the FP4 doesn't have a notification LED - I guess we're supposed to be glued to the screen and leaving the phone ignored in a corner unless it lights up is forbidden. But that does at least make the printing simpler, as there's no need for a window for the LED. Source code: https://www.chiark.greenend.org.uk/ucgi/~ianmdlvl/git?p=reprap-play.git;a=blob;f=fairphone4-case.scad;h=1738612c2aafcd4ee4ea6b8d1d14feffeba3b392;hb=629359238b2938366dc6e526d30a2a7ddec5a1b0 And the diagrams (which are part of the source, although I didn't update them for the FP4 changes: https://www.chiark.greenend.org.uk/ucgi/~ianmdlvl/git?p=reprap-diagrams.git;a=tree;f=fairphone-case;h=65f423399cbcfd3cf24265ed3216e6b4c0b26c20;hb=07e1723c88a294d68637bb2ca3eac388d2a0b5d4 ( big pictures )

comment count unavailable comments

Next.

Previous.