Search Results: "reg"

17 April 2026

Russell Coker: Home Battery

Prices On the 19th of March I got a home battery system installed. The government has a rebate scheme so it had a list price of about $22k for a 40kWh setup and cost me about $12k. It seems that 40KWh is the minimum usable size for the amount of electricity I use, I have 84 cores running BOINC when they have nothing better to do which is 585W of TDP according to Intel. While the CPUs are certainly using less than the maximum TDP (both due to design safety limits and the fact that I have disabled hyper-threading on all systems due to it providing minimal benefits and potential security issues) given some power usage by cooling fans and some inefficiency in PSUs I think that assuming that 585W is accounted for 24*7 by CPUs is reasonable. So my home draws between 800W and 1KW when no-one is home and with an electric car and all electric cooking a reasonable amount of electricity can be used. My bills prior to the battery installation were around $200/month which was based on charging my car only during sunny times as my electricity provider (Amber Electric) has variable rates based on wholesale prices. Also the feed in rates if my solar panels produce too much electricity in sunny times often go negative so if I don t use enough electricity. I haven t had the electric car long enough to find out what the bills might be in winter without a home battery. Before getting the battery my daily bills according to the Amber app were usually between $5 and $10. After getting it the daily bills have almost always been below $5. The only day where it s been over $5 since the battery installation was when electricity was cheap and I fully charged the home battery and my car which used 50KWh in one day and cost $7.87 which is 16 cents per KWh. 16 cents isn t the cheapest price (sometimes it gets as low as 10 cents) but is fairly cheap, sometimes even in the cheap parts of the day it doesn t get that low (the cheapest price on the day I started writing this was 20 cents). So it looks like this may save me $100 per month, if so there will be a 10% annual return on investment on the $12K I spent. This makes it a good investment, better than repaying a mortgage (which is generally under 6%) and almost as good as the long term results of index tracker funds. However if it cost $22K (the full price without subsidy) then it would still be ok but wouldn t be a great investment. The government subsidised batteries because the huge amount of power generated by rooftop solar systems was greater than the grid could use during the day in summer and batteries are needed to use that power when it s dark. Android App The battery system is from Fox ESS and the FoxCloud 2.0 Android app is a bit lacking in functionality. It has a timer for mode setting with options Self-use (not clearly explained), Feed-in Priority (not explained but testing shows feeding everything in to the grid), Back Up , Forced Charge , and Forced Discharge . Currently I have Forced Charge setup for most sunny 5 hours of the day for a maximum charge power of 5KW. I did that because about 25KW/day is what I need to cover everything and while the system can do almost 10KW that would charge the battery fully in a few hours and then electricity would be exported to the grid which would at best pay me almost nothing and at worst bill me for supplying electricity when they don t want it. There doesn t seem to be a never put locally generated power into the grid unless the battery is full option. The force charge mode allows stopping at a certain percentage, but when that is reached there is no fallback to another option. It would be nice if the people who designed the configuration could take as a baseline assumption that the macro programming in office suites and functions in spreadsheets are things that regular people are capable of using when designing the configuration options. I don t think we need a Turing complete programming language in the app to control batteries (although I would use it if there was one), but I think we need clauses like if battery is X% full then end this section . There is no option to say force charge until 100% or force charge for the next X minutes as a one-off thing. If I came home in the afternoon with my car below 50% battery and a plan to do a lot of driving the next day then I d want to force charge it immediately to allow charging the car overnight. But I can t do that without entering a schedule . For Unix people imagine having to do everything via a cron job and no option to run something directly from the command-line. It s a little annoying that they appear to have spent more development time on animations for the app than some of what should be core functionality. Management Amber has an option to allow my battery to be managed by them based on wholesale pries but I haven t done that as the feed-in prices are very low. So I just charge my battery when electricity is cheap and use it for the rest of the day. There is usually a factor of 2 or more price difference between the middle of the day and night time so that saves money. It also means I don t have to go out of my way to try and charge my car in the middle of the day. There is some energy lost in charging and discharging the batteries but it s not a lot. I configured the system to force charge for the 5 sunniest hours every day for 5KW as that s enough to keep it charged overnight and 5KW is greater than the amount of solar electricity produced on my house since I ve been monitoring it so that forces it to all be used for the battery. In summer I might have to change that to 6KW for the sunniest 2 or 3 hours and then 4KW or 5KW surrounding that which will be a pain to manage. Instead of charging the car every day during sunny times I charge it once or twice a week, I have a 3.3KW charger and the car has a 40KWh battery so usually it takes me less than 10 hours to fully charge it and I get at least 5 hours of good sunlight in the process. There are people hacking on these devices which is interesting to get direct control from computers [1], and apparently not banned from the official community for doing so. I m not enthusiastic enough to do this, I ve got plenty of other free software things to work on. But it s good that others are doing so.

16 April 2026

Sahil Dhiman: What is Life (to you)?

It started with a thought: to understand people s perspectives on life and its meaning. So I texted folks, What is life (to you)? . Each of the following list items (-) is a response from a different individual, mostly verbatim.
- A lot
- Everyone has a few universal basic qualities, and some special qualities. To me life is pursuit of exploring world based on those qualities and maturing those qualities as one goes on about exploring world/life with those qualities.
Discovering and enhancing experiences as one goes through them.
- life is endless suffering
- my answer might change daily, but this is what I ve noticed and feel recently. Life is a spectrum with two distinct ends: what we control and what we don t. At birth, the spectrum is largely tilted toward control, but throughout our lives, it gradually shifts toward the other side. Ultimately, as we approach death, we lose all control over any aspect of our existence, reaching the other end of the spectrum.
tho this isn t universal, privilege plays a huge part in what you control tho i believe it holds true for the majority
but yeah man, meaning and purpose are dynamic, it s in their nature to change i can give you a different answer this evening itself xD
- Funeral Monologue from Synecdoche, New York. https://www.youtube.com/watch?v=Z9PzSNy3xj0
- Zindagi ek nadiya hai, Aur mujhe tairna nahi aata
(translation - Life is a river, and I don t know how to swim)
On a more serious note, Life is what you make it out for yourself. The only established truth is that it will end. We can never know if there is something after or if there was something before. So try to live a life that you feel aspired by? But this question was beautifully answered by that book which you had about that dying professor
(Me - He was talking about Tuesday s with Morrie)
- My answer is 42
- One, it s living on your own terms, you define everything for yourself, success, normal, whatever. You get to curate your version of it no matter the societal norms.
It s an accumulation of experiences - friends, parents, work, activities, doing shit loads. Sab try karo- travel, zumba, art, music, workout, sports, dil kara ye karna hai karlo. (translation - If your heart wants to do it, just do it.)
Then I think relationships - all that you ve nurtured, people forget maintaining people because of work. It takes efforts to keep people in your life, everyone that comes has a place in yours, how well thats stays is upto you. You also get to curate your people, who stays who don t. Family toh hai hi (translation - family is there) but everyone else that comes along can make it pretty good.
So I don t want to be 50 and be like chalo ab kuch apne liye karte hai (translation - Come on, now let s do something for ourselves) Do whatever shit you want today. Not everything costs money, and if it does get thrifty
But do keep healthy while doing all of that
- Being alive so that my daughter can grow up and i can help raising her kids as well. Raising kids without mother is tough :P
- Definitively, I feel like Life is a by product of proteins and energy working together. But in a more personal sense, Life is a dumb joke played onto us. It s a rat race. But rats exists because of life and then it becomes a chicken-egg problem
Honestly, I don t give good answers to life questions. I m generally the one asking
Life can be like a box of chocolates, you don t know what you re gonna get untill you experience the chocolate(assuming the chocolates are heterogenous and contains a mix of everything)
Camus once said, Life is a revolt , and one of his students added more spice to it like Life is a revolt against the meaninglessness of existence"
I kinda feel like Life is the pursuit of every person s search for meaning
- Imprisonment waiting for execution
I have one more thought while we are on the topic , game with pre defined starting position and predefined destination , path to reach is a maze
- A phase where you can have a really good time or really bad one, usually the mix of both. A phase where you are prisoner to responsibility and materialistic wants.
It s a hell for you, where you try to create heaven for others. Being born was never your choice, but ending is always in your hands but you are a prisoner. You fear that leaving this world behind will destroy the heavens you created for others and they will be back to hell. But eventually everyone moves on watching the hourglass of their life.
Once you are left with no desires or no one to create heavens for, you look arround yourself. You see everyone chasing something, everyone scared of their limitted life time sliping away yet you want it to end sooner.
Doesn t matter if it was all good till now, or all bad. The other half is waiting for redemption. If it was all good, it s best time to die don t wait for the bad to start. If was all bad, it s still the best time to die what if it was the good one and more worst is waiting for you. We desire to be remembered, yet we want to free from this loop of suffering.
Someone once said, life is a suffering, chose your sufferings.
- Life to me is to live without regrets and live with freedom.
Life is always unpredictable and this unpredictability makes it more interesting and worth it.
- As of now, for the state of mind that I am in , I think for me life is about subtle struggle, subtle inconveniences and yet moving forward cause that s all I know.
I am not sure if any of this has any meaning, but sometimes I feel I was born of a purpose and that the universe has my back.
For me it s about raising my consciousness, understanding people to their depths, gaining moderate material success and helping people to some extend.
I have tried to seek a grander meaning but I have failed.
Life for me is what I make out it.
In my times of great success i rarely think about life for I am busy enjoying it, whatever you may call that state of mind.
- For me its the little things that you enjoy with YOUR people
- Life to me is about living and loving, and doing it in a way that sustains. It s the people who shape you, the work you get absorbed in, the quiet moments in between. There s also the wanting, the drive to figure out what s worth going after and how to get there, but that s just one part of it, not the point of it. And none of it happens in a vacuum. I m aware of the privileges that let me live this way, and I try to hold on to that gratitude. In the end, life has both a material and a non-material side, and a lot of what we do is chasing material things in an attempt to satisfy something non-material within us
- Mere liye (translation - for me) life is staying at my home and studying random economics papers. That s when I enjoy myself the most.
- Very complicated
Some days I wish this life never ended and some time I feel it would be better if it stopped at that moment.
It all depends on the events that happen in the so called life .
So life to me is a string of events that happen anyway and you get to make some decisions which can turn it in any direction and then you wonder how did that happen.
- not forgetting to breathe, learn, eat, game, take a good shit, love, sleep.
- To be honest it changed with time! At 19 it was about freedom, wasn t sure what freedom meant but i wanted that! To be free from everything, maybe because parents still controlled a part of my life. Then came 22-24 where i was working, trying to figure out what i want, the meaning changed from freedom to living for myself. To earn more, to be greedy about myself and pursue whatever would help me gain more steps in my career.
Came my mba life, switched my life from doing for myself to trying everything out to have no regrets. Life meaning was just about living with no regrets, invested, gambled, did everything to earn that tag of yeah, have tried that . Now it has all switched to, it was all just a fake facade. Life turned to having a meaningful life rather than finding meaning in what i am doing. Living for people around me, chhoti chhoti cheezo m khushi (translation - happiness in small things(?)) isn t really a topic of conversation but more of happy thing for me. So it changed, and m quite happy to be honest. Life did show me a lot of failures, but was privileged enough to face those failures. Gained a lot of learnings if not money
Hopeful for more learnings and change meaning of life with time
- A task.
- You have different answers at different times You learn different meanings at different times When you are studying, basically it is about job, finding a partner then it becomes, house, car other things based on your income in between, there can be passion too
Free Software was a passion, electoral politics too, but both kind of faded and I want cooperative and user driven development now (prav - something that motivates me every day) and these days learning Chinese and watching Cdrama takes a huge part of my leisure time it is heavily subjective and also influences by previous experiences people around you, how much influence they have on you
it also depends on if they had to struggle in their life or not, for some life did not give much troubles and trouble itself can be relative people who never had to struggle may find even smallest challenges as troubles like if you own a car, your worry is finding a parking slot
- I am too young to think about lyfe
- A ticket to see the show on earth, I guess
I guess life is different depending on the mood. It is a very broad question.
(Me - What is it in this present mood?)
Learning stuff (like I am learning a new language) and being happy but also to regulate emotions in a world where being optimistic is getting harder each day.
Life is also having a unique set of glasses you wear. Both in terms of looking from your eyeballs and your psychological perspective. Both are unique and cannot be replicated.
It is interesting what people on their deathbed think of life. If I know I am dying, my perspective would change a whole lot.
Life is finishing reading books while we are alive
Life is sleeping after a good XMPP chat
- Dukh dard peeda (translation - surrow pain suffering)
- uhh to word it? life is just like a journey from A to somewhere and its all about what paths you take and what line you get on to me, just a series of short adventures that all connect to a larger sequence until you can t have any more adventures-
(Me - eee, THE END. drop dead, like a coin)
yeaaaah- I am not really for spirituality of an afterlife, to me life just ends at some point, after which point there fails to remain a discernable you, and some X time after which, you will be last remembered, try to make that last time a good one I guess?
(Me - no soul?)
uhhh not in the way most people think of it i guess?
theres just a lot of yous, theres the physical you, there is the idea of you, there is the expectation of you, and one of the undefinable you I would label as the soul maybe? like the part thats not physically you, but also certainly you
(Me - can t say I understood part, but I get you in this sense)
mhm- well its about just questioning who you are more so questioning what life is-, I have sadly spent way too much time trying to figure that out
- Making the best of the time you have
- living a full range of experiences and embracing the good ones, seeing all that the world has to offer. In the end we were always just stardust. Might as well enjoy it when we are stardust with a consciousness of our own.
- For some reason or the Universe s /dev/random I was born here as a biological being, and from my experience I understood living is hard and the best way to live is by embracing it. Loving everyone and everything around you. Be happy and joyful until you naturally say good bye to this world.
- Life is being fucked by everything and you just have to figure out and try to stick to the things worth being fucked for
Note: Following was transcribed from a audio message.
- There are five conditions to become a life to survive in the environment. I think there s five conditions by the biological definitions and reproduction is one of the factor virus is not considered a life form because it cannot reproduce on its own but technically it s kind of a life because it reproduces using the DNA ability this is the biological definition. Do you want a philosophical definition?
My definition is kind of the same except that you get life experiences along with it as a human. Extra benefits is that you are not an NPC. All other organisms are NPCs. But humans can interpret the world and change it to their liking. That is life in the case of a human. But then many humans are mostly NPCs. But they still can change the life. Okay, fuck this. Where is this even going?
A human is an exception in the case of life, because human is not an NPC. Human can interrupt the world, human can change it to its liking, which is why we are such a successful organism on this planet. That is life to me. That s a human. But all of this is kind of meaningless, because the biological impurity of a human being still exists, so you still have the urges to reproduce, which kind of makes it like just another organism. But then, humans are yet to evolve to overcome that biological imperative.
I m grateful for all the replies, outlooks, and subsequent conversations I got to have after this question with everyone. After all, it was a deeply personal question. It does fit in nicely with my definition of life:
Life is all about experiences and all the transient relationships one gets to have with folks we meet on the way.

15 April 2026

Paul Tagliamonte: designing arf, an sdr iq encoding format

Interested in future updates? Follow me on mastodon at @paul@soylent.green. Posts about hz.tools will be tagged #hztools.

Want to jump right to the draft? I'll be maintaining ARF going forward at /draft-tagliamonte-arf-00.txt.
It s true processing data from software defined radios can be a bit complex which tends to keep all but the most grizzled experts and bravest souls from playing with it. While I wouldn t describe myself as either, I will say that I ve stuck with it for longer than most would have expected of me. One of the biggest takeaways I have from my adventures with software defined radio is that there s a lot of cool crossover opportunity between RF and nearly every other field of engineering. Fairly early on, I decided on a very light metadata scheme to track SDR captures, called rfcap. rfcap has withstood my test of time, and I can go back to even my earliest captures and still make sense of what they are IQ format, capture frequencies, sample rates, etc. A huge part of this was the simplicity of the scheme (fixed-lengh header, byte-aligned to supported capture formats), which made it roughly as easy to work with as a raw file of IQ samples. However, rfcap has a number of downsides. It s only a single, fixed-length header. If the frequency of operation changed during the capture, that change is not represented in the capture information. It s not possible to easily represent mulit-channel coherent IQ streams, and additional metadata is condemned to adjacent text files.

ARF (Archive of RF) A few years ago, I needed to finally solve some of these shortcomings and tried to see if a new format would stick. I sat down and wrote out my design goals before I started figuring out what it looked like. First, whatever I come up with must be capable of being streamed and processed while being streamed. This includes streaming across the network or merely written to disk as it s being created. No post-processing required. This is mostly an artifact of how I ve built all my tools and how I intereact with my SDRs. I use them extensively over the network (both locally, as well as remotely by friends across my wider lan). This decision sometimes even prompts me to do some crazy things from time to time. I need actual, real support for multiple IQ channels from my multi-channel SDRs (Ettus, Kerberos/Kracken SDR, etc) for playing with things like beamforming. My new format must be capable of storing multiple streams in a single capture file, rather than a pile of files in a directory (and hope they re aligned). Finally, metadata must be capable of being stored in-band. The initial set of metadata I needed to formalize in-stream were Frequency Changes and Discontinuities. Since then, ARF has grown a few more. After getting all that down, I opted to start at what I thought the simplest container would look like, TLV (tag-length-value) encoded packets. This is a fairly well trodden path, and used by a bunch of existing protocols we all know and love. Each ARF file (or stream) was a set of encoded packets (sometimes called data units in other specs). This means that unknown packet types may be skipped (since the length is included) and additional data can be added after the existing fields without breaking existing decoders.
tag
length
value
Heads up! Once this is posted, I'm not super likely to update this page. Once this goes out, the latest stable copy of the ARF spec is maintained at draft-tagliamonte-arf-00.txt. This page may quickly become out of date, so if you're actually interested in implementing this, I've put a lot of effort into making the draft comprehensive, and I plan to maintain it as I edit the format.
Unlike a traditional TLV structure, I opted to add flags to the top-level packet. This gives me a bit of wiggle room down the line, and gives me a feature that I like from ASN.1 a critical bit. The critical bit indicates that the packet must be understood fully by implementers, which allows future backward incompatible changes by marking a new packet type as critical. This would only really be done if something meaningfully changed the interpretation of the backwards compatible data to follow.
Flag Description
0x01Critical (tag must be understood)
Within each Packet is a tag field. This tag indicates how the contents of the value field should be interpreted.
Tag ID Description
0x01Header
0x02Stream Header
0x03Samples
0x04Frequency Change
0x05Timing
0x06Discontinuity
0x07Location
0xFEVendor Extension
In order to help with checking the basic parsing and encoding of this format, the following is an example packet which should parse without error.
 00, // tag (0; no subpacket is 0 yet)
 00, // flags (0; no flags)
 00, 00 // length (0; no data)
 // data would go here, but there is none
Additionally, throughout the rest of the subpackets, there are a few unique and shared datatypes. I document them all more clearly in the draft, but to quickly run through them here too:

UUID This field represents a globally unique idenfifer, as defined by RFC 9562, as 16 raw bytes.

Frequency Data encoded in a Frequency field is stored as microhz (1 Hz is stored as 1000000, 2 Hz is stored as 2000000) as an unsigned 64 bit integer. This has a minimum value of 0 Hz, and a maximum value of 18446744073709551615 uHz, or just above 18.4 THz. This is a bit of a tradeoff, but it s a set of issues that I would gladly contend with rather than deal with the related issues with storing frequency data as a floating point value downstream. Not a huge factor, but as an aside, this is also how my current generation SDR processing code (sparky) stores Frequency data internally, which makes conversion between the two natural.

IQ samples ARF supports IQ samples in a number of different formats. Part of the idea here is I want it to be easy for capturing programs to encode ARF for a specific radio without mandating a single iq format representation. For IQ types with a scalar value which takes more than a single byte, this is always paired with a Byte Order field, to indicate if the IQ scalar values are little or big endian.
ID Name Description
0x01f32interleaved 32 bit floating point scalar values
0x02i8 interleaved 8 bit signed integer scalar values
0x03i16interleaved 16 bit signed integer scalar values
0x04u8 interleaved 8 bit unsigned integer scalar values
0x05f64interleaved 64 bit floating point scalar values
0x06f16interleaved 16 bit floating point scalar values

Stream Header Immediately after the arf Header, some number of Stream Headers follow. There must be exactly the same number of Stream Header packets as are indicated by the num streams field of the Header. This has the nice effect of enabling clients to read all the stream headers without requiring buffering of unread packets from the stream.
id
flags
fmt
bo
rate
freq
guid
site
In order to help with checking the basic parsing and encoding of this format, the following is an example stream header subpacket (when encoded or decoded this will be found inside an ARF packet as described above) which should parse without error, with known values.
00, 01, // id (1)
00, 00, 00, 00, 00, 00, 00, 00, // flags
01, // format (float32)
01, // byte order (Little Endian)
00, 00, 01, d1, a9, 4a, 20, 00, // rate (2 MHz)
00, 00, 5a, f3, 10, 7a, 40, 00, // frequency (100 MHz)

// guid (7b98019d-694e-417a-8f18-167e2052be4d)
7b, 98, 01, 9d, 69, 4e, 41, 7a,
8f, 18, 16, 7e, 20, 52, be, 4d,

// site_id (98c98dc7-c3c6-47fe-bc05-05fb37b2e0db)
98, c9, 8d, c7, c3, c6, 47, fe,
bc, 05, 05, fb, 37, b2, e0, db,

Samples Block of IQ samples in the format indicated by this stream s format and byte_order field sent in the related Stream Header.
id
iq samples
In order to help with checking the basic parsing and encoding of this format, the following is an samples subpacket (when encoded or decoded this will be found inside an ARF packet as described above). The IQ values here are notional (and are either 2 8 bit samples, or 1 16 bit sample, depending on what the related Stream Header was).
01, // id
ab, cd, ab, cd, // iq samples

Frequency Change The center frequency of the IQ stream has changed since the Stream Header or last Frequency Change has been sent. This is useful to capture IQ streams that are jumping around in frequency during the duration of the capture, rather than starting and stopping them.
id
frequency
In order to help with checking the basic parsing and encoding of this format, the following is a frequency change subpacket (when encoded or decoded this will be found inside an ARF packet as described above).
01, // id
00, 00, b5, e6, 20, f4, 80, 00 // frequency (200 MHz)

Discontinuity Since the last Samples packet for this stream, samples have been dropped or not encoded to this stream. This can be used for a stream that has dropped samples for some reason, a large gap (radio was needed for something else), or communicating iq snippits .
id
In order to help with checking the basic parsing and encoding of this format, the following is a discontinuity subpacket (when encoded or decoded this will be found inside an ARF packet as described above).
01, // id

Location Up-to-date location as of this moment of the IQ stream, usually from a GPS. This allows for in-band geospatial information to be marked in the IQ stream. This can be used for all sorts of things (detected IQ packet snippits aligned with a time and location or a survey of rf noise in an area)
flags
sys
lat
long
el
accuracy
The sys field indicates the Geodetic system to be used for the provided latitude, longitude and elevation fields. The full list of supported geodetic systems is currently just WGS84, but in case something meaningfully changes in the future, it d be nice to migrate forward. Unfortunately, being a bit of a coward here, the accuracy field is a bit of a cop-out. I d really rather it be what we see out of kinematic state estimation tools like a kalman filter, or at minimum, some sort of ellipsoid. This is neither of those - it s a perfect sphere of error where we pick the largest error in any direction and use that. Truthfully, I can t be bothered to model this accurately, and I don t want to contort myself into half-assing something I know I will half-ass just because I know better.
System Description
0x01 WGS84 - World Geodetic System 1984
In order to help with checking the basic parsing and encoding of this format, the following is a location subpacket (when encoded or decoded this will be found inside an ARF packet as described above).
00, 00, 00, 00, 00, 00, 00, 00, // flags
01, // system (wgs84)
3f, f3, be, 76, c8, b4, 39, 58, // latitude (1.234)
40, 02, c2, 8f, 5c, 28, f5, c3, // longitude (2.345)
40, 59, 00, 00, 00, 00, 00, 00, // elevation (100)
40, 24, 00, 00, 00, 00, 00, 00 // accuracy (10)

Vendor Extension In addition to the fields I put in the spec, I expect that I may need custom packet types I can t think of now. There s all sorts of useful data that could be encoded into the stream, so I d rather there be an officially sanctioned mechanism that allows future work on the spec without constraining myself. Just an example, I ve used a custom subpacket to create test vectors, the data is encoded into a Vendor Extension, followed by the IQ for the modulated packet. If the demodulated data and in-band original data don t match, we ve regressed. You could imagine in-band speech-to-text, antenna rotator azimuth information, or demodulated digital sideband data (like FM HDR data) too. Or even things I can t even think of!
id
data
In order to help with checking the basic parsing and encoding of this format, the following is a vendor extension subpacket (when encoded or decoded this will be found inside an ARF packet as described above).
// extension id (b24305f6-ff73-4b7a-ae99-7a6b37a5d5cd)
b2, 43, 05, f6, ff, 73, 4b, 7a,
ae, 99, 7a, 6b, 37, a5, d5, cd,

// data (0x01, 0x02, 0x03, 0x04, 0x05)
01, 02, 03, 04, 05

Tradeoffs The biggest tradeoff that I m not entirely happy with is limiting the length of a packet to u16 65535 bytes. Given the u8 sample header, this limits us to 8191 32 bit sample pairs at a time. I wound up believing that the overhead in terms of additional packet framing is worth it because always encoding 4 byte lengths felt like overkill, and a dynamic length scheme ballooned codepaths in the decoder that I was trying to keep as easy to change as possible as I worked with the format.

Freexian Collaborators: Debian Contributions: Debusine projects in GSoC, Debian CI updates, Salsa CI maintenance and more! (by Anupa Ann Joseph)

Debian Contributions: 2026-03 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Debusine projects in Google s Summer of Code While Freexian initiated Debusine, and is investing a lot of resources in the project, we manage it as a true free software project that can and should have a broader community. We always had documentation for new contributors and we aim to be reactive with them when they interact via the issue tracker or via merge requests. We decided to put those intentions under stress tests by proposing five projects for Google s Summer of Code as part of Debian s participation in that program. Given that at least 11 candidates managed to get their merge request accepted in the last 30 days (interacting with the development team is part of the pre-requisites to apply to Google Summer of Code projects these days), the contributing experience must not be too bad. If you want to try it out, we maintain a list of quick fixes that are accessible to newcomers. And as always, we welcome your feedback!

Debian CI: incus backend and upgrade to Bootstrap 5, by Antonio Terceiro debci 3.14 was released on March 4th, with a followup 3.14.1 release with regression fixes a few days afterwards. Those releases were followed by new development and maintenance work that will provide extra capabilities and stability to the platform. This month saw the initial version of an incus backend land in Debian CI. The transition into the new backend will be done carefully so as to not disrupt testing migration. Each package will be running jobs with both the current lxc backend and with incus. Packages that have the same result on both backends will be migrated over, and packages that exhibit different results will be investigated further, resulting in bug reports and/or other communication with the maintainers. On the frontend side, the code has been ported to Bootstrap 5 over from the now ancient Bootstrap 3. This need has been originally reported back in 2024 based on the lack of security support for Bootstrap 3. Beyond improving maintainability, this upgrade also enables support for dark mode in debci, which is still work in progress. Both updates mentioned in this section will be available in a following debci release.

Salsa CI maintenance by Santiago Ruano Rinc n et al. Santiago reviewed some Salsa CI issues and reviewed associated merge requests. For example, he investigated a regression (#545), introduced by the move to sbuild, on the use of extra repositories configured as .source files; and reviewed the MR (!712) that fixes it. Also, there were conflicts with changes made in debci 3.14 and debci 3.14.1 (those updates are mentioned above), and different people have contributed to fix the subsequent issues, in a long-term way. This includes Rapha l who proposed MR !707 and who also suggested Antonio to merge the Salsa CI patches to avoid similar errors in the future. This happened shortly after. Those fixes finally required the unrelated MR !709, which will prevent similar problems when building images. To identify bugs related to the autopkgtest support in the backport suites as early as possible, Santiago proposed MR !708. Finally, Santiago, in collaboration with Emmanuel Arias also had exchanges with GSoC candidates for the Salsa CI project, including the contributions they have made as merge requests. It is important to note that there are several very good candidates interested in participating. Thanks a lot to them for their work so far!

Miscellaneous contributions
  • Rapha l reported a zim bug affecting Debian Unstable users, which was already fixed in git apparently. He could thus cherry-pick the fix and update the package in Debian Unstable.
  • Carles created a new page on the InstallingDebianOn in Debian Wiki.
  • Carles submitted translation errors in the debian-installer Weblate.
  • Carles, using po-debconf-manager, improved Catalan translations: reviewed and submitted 3 packages. Also improved error handling when forking or submitting an MR if the fork already existed.
  • Carles kept improving check-relations: code base related general improvements (added strict typing, enabled pre-commit). Also added DebPorts support, virtual packages support and added commands for reporting missing relations and importing bugs from bugs.debian.org.
  • Antonio handled miscellaneous Salsa support requests.
  • Antonio improved the management of MiniDebConf websites by keeping all non-secret settings in git and fixed exporting these sites as static HTML.
  • Stefano uploaded routine updates to hatchling, python-mitogen, python-virtualenv, python-discovery, dh-python, pypy3, python-pipx, and git-filter-repo.
  • Faidon uploaded routine updates to crun, libmaxminddb, librdkafka, lowdown, platformdirs, python-discovery, sphinx-argparse-cli, tox, tox-uv.
  • Stefano and Santiago continued to help with DebConf 26 preparations.
  • Stefano reviewed some contributions to debian-reimbursements and handled admin for reimbursements.debian.net.
  • Stefano attended the Debian Technical Committee meeting.
  • Helmut sent 8 patches for cross build failures.
  • Building on the work of postmarketOS, Helmut managed to cross build systemd for musl in rebootstrap and sent several patches in the process.
  • Helmut reviewed several MRs of Johannes Schauer Marin Rodrigues expanding support for DPKG_ROOT to support installing hurd.
  • Helmut incorporated a final round of feedback for the Multi-Arch documentation in Debian policy, which finally made it into unstable together with documentation of Build-Profiles.
  • In order to fix python-memray, Helmut NMUed libunwind generally disabling C++ exception support as being an incompatible duplication of the gcc implementation. Unfortunately, that ended up breaking suricata on riscv64. After another NMU, python-memray finally migrated.
  • Thorsten uploaded new upstream versions of epson-inkjet-printer-escpr and sane-airscan. He also fixed a packaging bug in printer-driver-oki. As of systemd 260.1-1 the configuration of lpadmin has been added to the sysusers.d configuration. All printing packages can now simply depend on the systemd-sysusers package and don t have to take care of its creation in maintainer scripts anymore.
  • In collaboration with Emmanuel Arias, Santiago had exchanges with GSoC candidates and reviewed the proposals of the Linux livepatching GSoC 2026 project.
  • Colin helped to fix CVE-2026-3497 in openssh and CVE-2026-28356 in multipart.
  • Colin upgraded tango and pytango to new upstream releases and packaged pybind11-stubgen (needed for pytango), thanks to a Freexian customer. Tests of reproducible builds revealed that pybind11-stubgen didn t generate imports in a stable order; this is now fixed upstream.
  • Lucas fixed CVE-2025-67733 and CVE-2026-21863 affecting src:valkey in unstable and testing. Also reviewed the same fixes targeting stable proposed by Peter Wienemann.
  • Faidon worked with upstream and build-dep Debian maintainers on resolving blockers in order to bring pyHanko into Debian, starting with the adoption of python-pyhanko-certvalidator. pyHanko is a suite for signing and stamping PDF files, and one of the few libraries that can be leveraged to sign PDFs with eIDAS Qualified Electronic Signatures.
  • Anupa co-organized MiniDebConf Kanpur and attended the event with many others from all across India. She handled the accommodation arrangements along with the registration team members, worked on the budget and expenses. She was also a speaker at the event.
  • Lucas helped with content review/schedule for the MiniDebConf Campinas. Thanks Freexian for being a Gold sponsor!
  • Lucas organized and took part in a one-day in-person sprint to work on Ruby 3.4 transition. It was held in a coworking space in Brasilia - Brazil on April 6th. There were 5 DDs and they fixed multiple packages FTBFSing against Ruby 3.4 (coming to unstable soon hopefully). Lucas has been postponing a blog post about this sprint since then :-)

14 April 2026

Petter Reinholdtsen: Talking to the Computer, and Getting Some Nonsense Back...

At last, I can run my own large language model artificial idiocy generator at home on a Debian testing host using Debian packages directly from the Debian archive. After months of polishing the llama.cpp, whisper.cpp and ggml packages, and their dependencies, I was very happy to see today that they all entered Debian testing this morning. Several release-critical issues in dependencies have been blocking the migration for the last few weeks, and now finally the last one of these has been fixed. I would like to extend a big thanks to everyone involved in making this happen. I've been running home-build editions of whisper.cpp and llama.cpp packages for a while now, first building from the upstream Git repository and later, as the Debian packaging progressed, from the relevant Salsa Git repositories for the ROCM packages, GGML, whisper.cpp and llama.cpp. The only snag with the official Debian packages is that the JavaScript chat client web pages are slightly broken in my setup, where I use a reverse proxy to make my home server visible on the public Internet while the included web pages only want to communicate with localhost / 127.0.0.1. I suspect it might be simple to fix by making the JavaScript code dynamically look up the URL of the current page and use that to determine where to find the API service, but until someone fixes BTS report #1128381, I just have to edit /usr/share/llama.cpp-tools/llama-server/themes/simplechat/simplechat.js every time I upgrade the package. I start my server like this on my machine with a nice AMD GPU (donated to me as a Debian developer by AMD two years ago, thank you very much):
  LC_ALL=C llama-server \
    -ngl 256  \
    -c $(( 42 * 1024)) \
    --temp 0.7 \
    --repeat_penalty 1.1 \
    -n -1 \
    -m Qwen3-Coder-30B-A3B-Instruct-Q5_K_S.gguf
It only takes a few minutes to load the model for the first time and prepare a nice API server for me at https://my.reverse.proxy.example.com:8080/v1/, available (note, this sets up the server up without authentication; use a reverse proxy with authentication if you need it) for all the API clients I care to test. I switch models regularly to test different new ones, the Qwen3-Coder one just happen to be the one I use at the moment. Perhaps these packages is something for you to have fun with too? As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Russell Coker: Furilabs FLX1s Finally Working

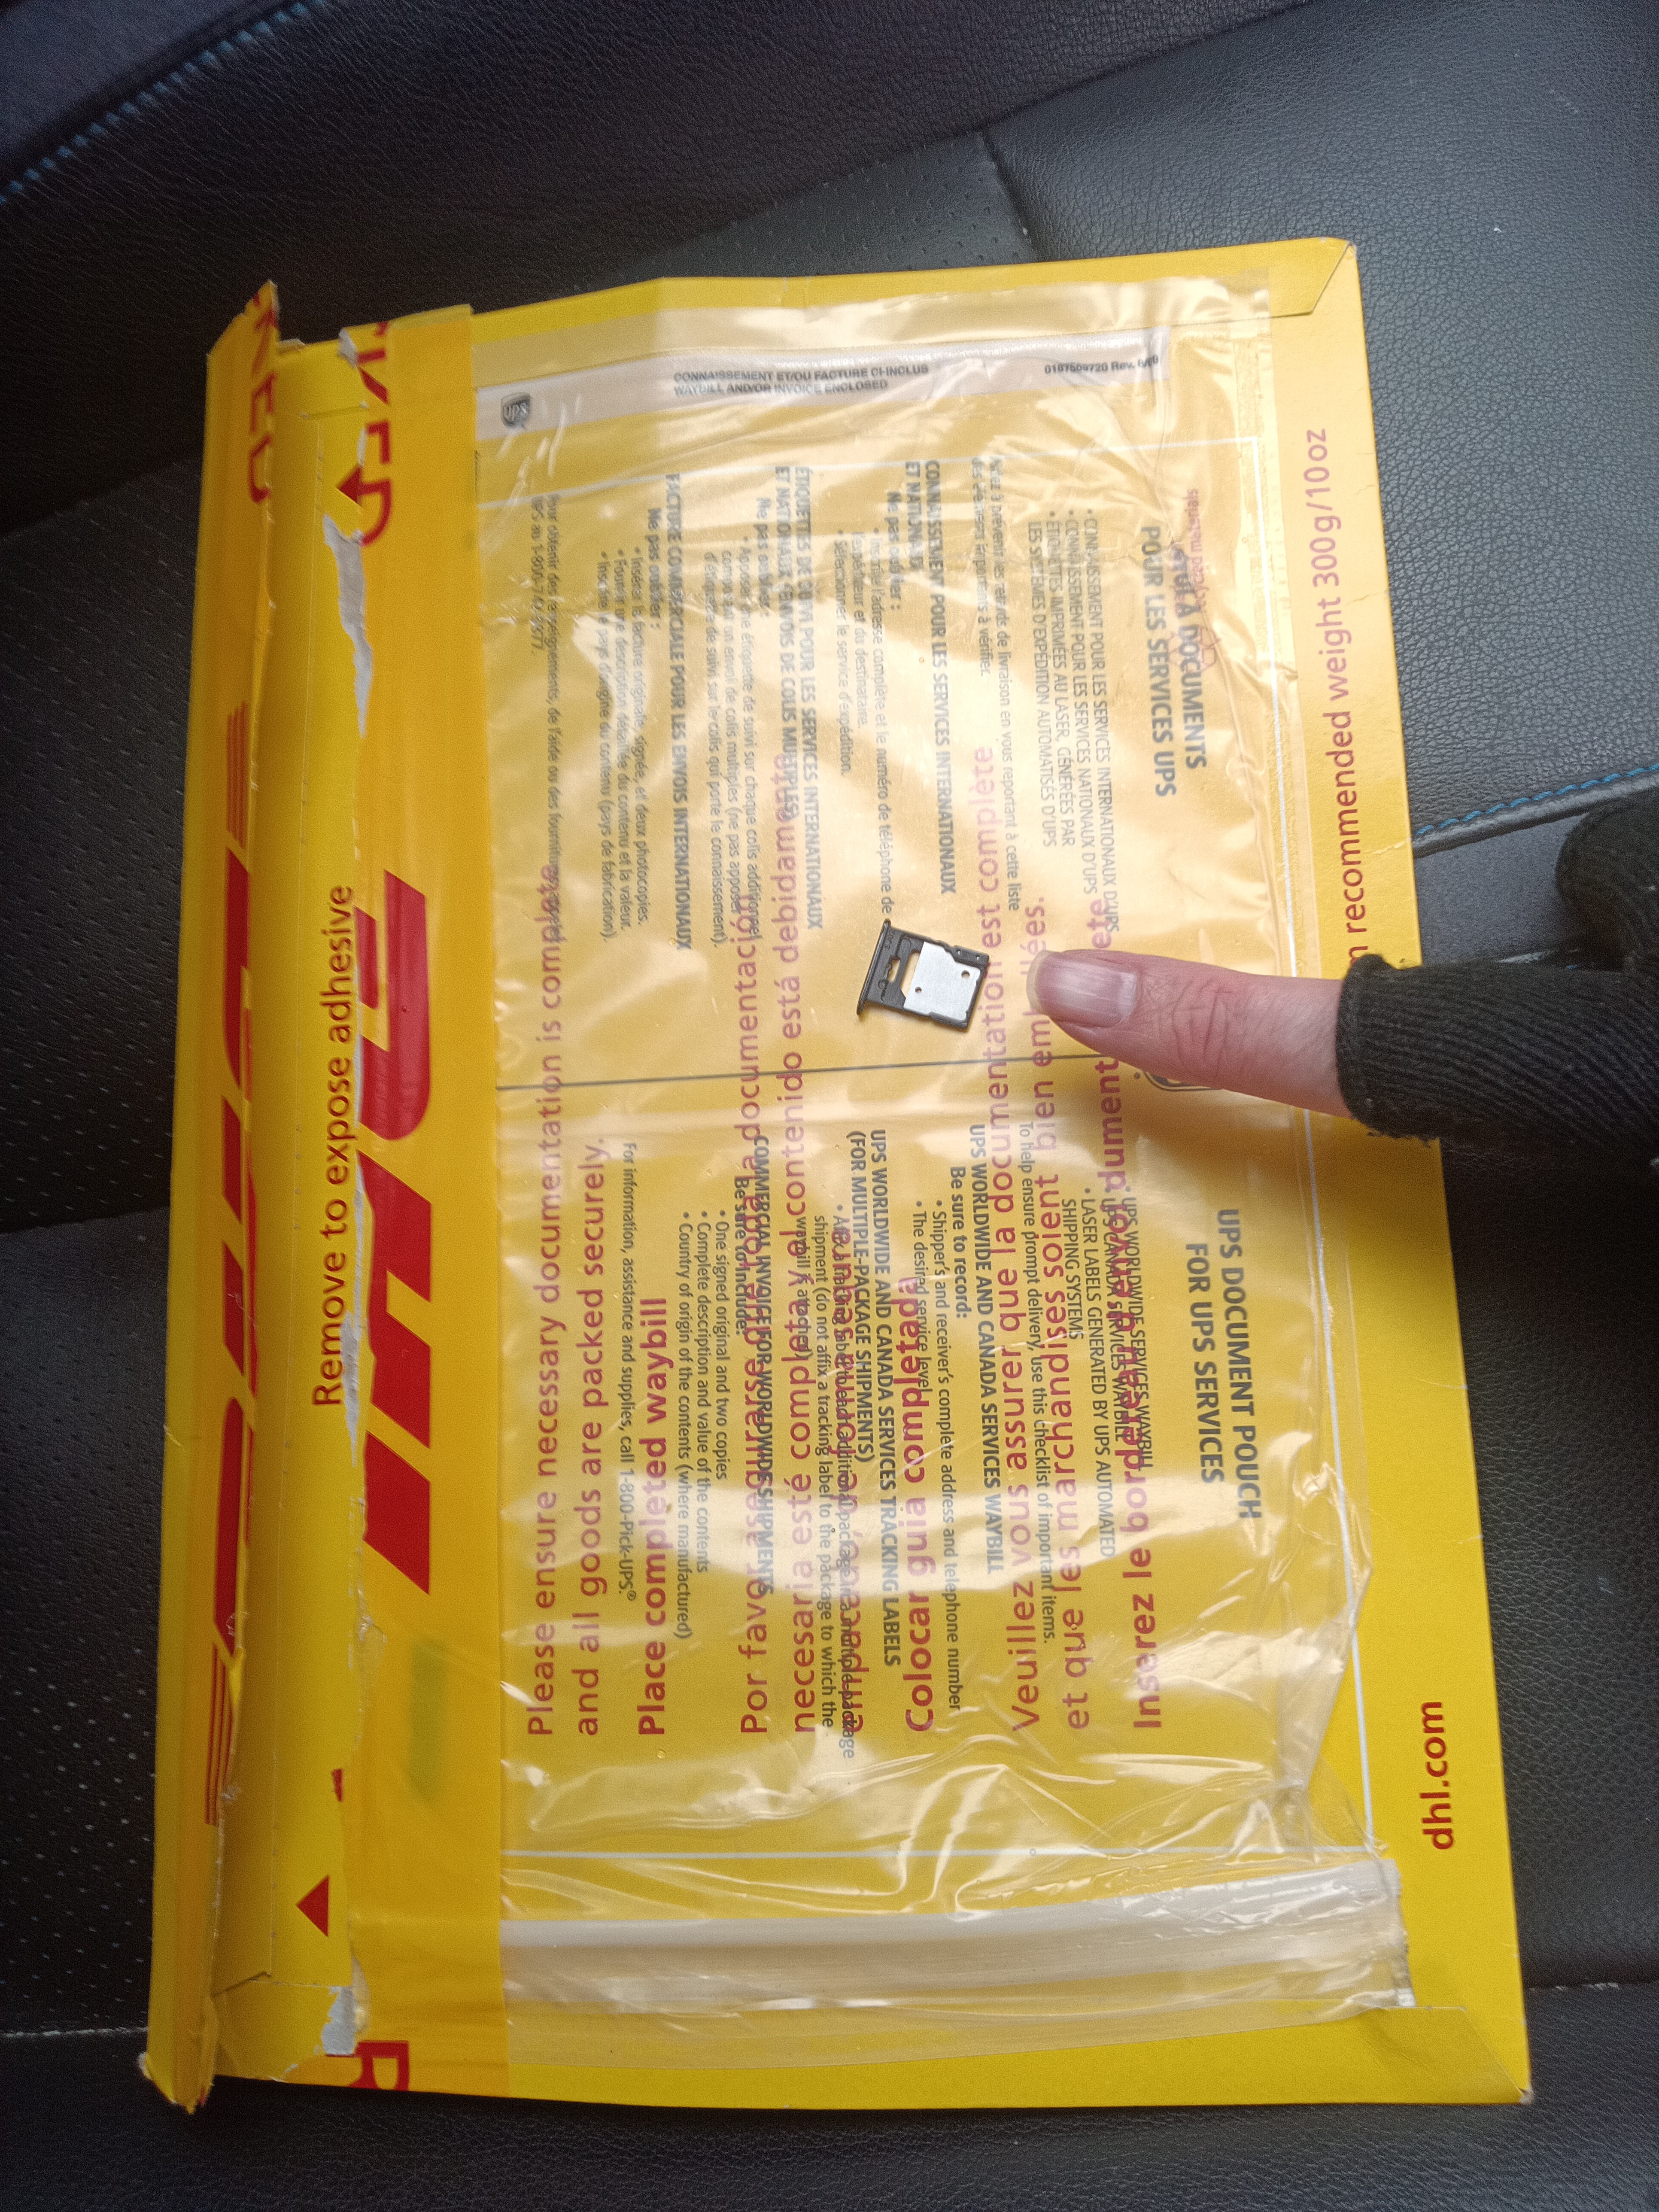
I ve been using the Furilabs FLX1s phone [1] as my daily driver for 6 weeks, it s a decent phone, not as good as I hoped but good enough to use every day and rely on for phone calls about job interviews etc. I intend to keep using it as my main phone and as a platform to improve phone software in Debian as you really can t effectively find bugs unless you use the platform for important tasks. Support Problems I previously wrote about the phone after I received it without a SIM caddy on the 13th of Jan. I had a saga with support about this, on the 16th of Jan one support person said that they would ship it immediately but didn t provide a tracking number or any indication of when it would arrive. On the 5th of Feb I contacted support again and asked how long it would be, the new support person seemed to have no record of my previous communication but said that they would send it. On the 17th of Feb I made another support request including asking for a way of direct communication as the support email came from an address that wouldn t accept replies, I was asked for a photo showing where the problem is. The support person also said that they might have to send a replacement phone! The last support request I sent included my disappointment at the time taken to resolve the issue and the proposed solution of replacing the entire phone (why have two international shipments of a fragile and expensive phone when a single letter with a cheap SIM caddy would do?). I didn t receive a reply but the SIM caddy arrived on the 2nd of Mar. Here is a pic of the SIM caddy and the package it came in: One thing that should be noted is that some of the support people seemed to be very good at their jobs and they were all friendly. It was the system that failed here, turning a minor issue of a missing part into a 6 week saga. Furilabs needs to do the following to address this issue:
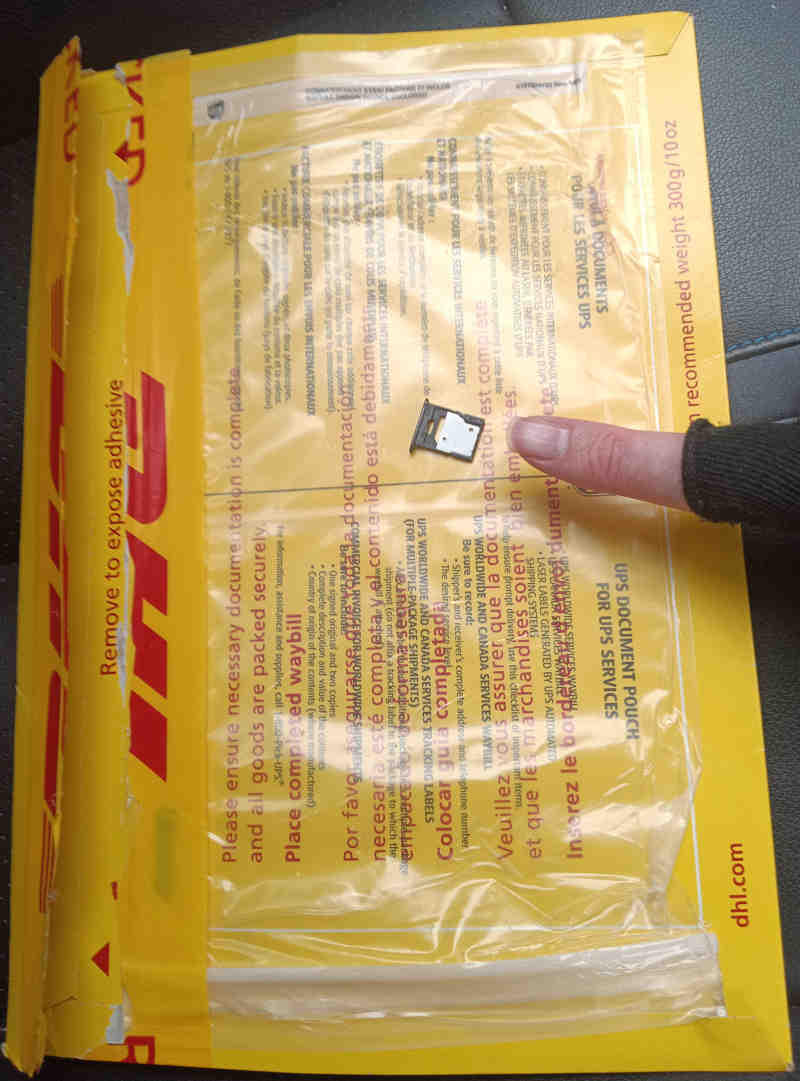
  1. Make it possible to reply directly to a message from a support person. Accept email with a custom subject to sort it, give a URL for a web form, anything. Collating discussions with a customer allows giving better support while taking less time for the support people.
  2. Have someone monitor every social media address that is used by the company. When someone sends a support request in a public Mastodon post it indicates that something has gone wrong and you want to move quickly to resolve it.
  3. Take care of the little things, like sending a tracking number for every parcel. If it s something too small for a parcel (the SIM caddy could have fit in a regular letter) then just tell the customer what date it was posted and where it was posted from so they have some idea of when it will arrive.
This is not just a single failure of Furilabs support, it s a systemic failure of their processes. Problems I Will Fix Unless Someone Beats Me to it Here are some issues I plan to work on. Smart Watch Support I need to port one of the smart watch programs to Debian. Also I want to make one of them support the Colmi P80 [2]. A smart watch significantly increases the utility of a phone even though IMHO they aren t doing nearly all the things that they could and should do. When we get Debian programs talking to the PineTime it will make a good platform for development of new smart phone and OS features. Nextcloud I have ongoing issues of my text Nextcloud installation on a Debian VM not allowing connection from the Linux desktop app (as packaged in Debian) and from the Android client (from f-droid). The desktop client works with a friend s Nextcloud installation on Ubuntu so I may try running it on an Ubuntu VM I run while waiting for the Debian issue to get resolved. There was a bug recently fixed in Nextcloud that appears related so maybe the next release will fix it. For the moment I ve been running without these features and I call and SMS people from knowing their number or just returning calls. Phone calls generally aren t very useful for me nowadays except when applying for jobs. If I could deal with recruiters and hiring managers via video calls then I would consider just not having a phone number. Wifi IPv6 Periodically IPv6 support just stops working, I can t ping the gateway. I turn wifi off and on again and it works. This might be an issue with my wifi network configuration. This might be an issue with the way I have configured my IPv6 networking, although that problem doesn t happen with any of my laptops. Chatty Sorting Chatty is the program for SMS that is installed by default (part of the phosh/phoc setup), it also does Jabber. Version 0.8.7 is installed which apparently has some Furios modifications and it doesn t properly support sorting SMS/Jabber conversations. Version 0.8.9 from Debian sorts in the same way as most SMS and Jabber programs with the most recent at the top. But the Debian version doesn t support Jabber (only SMS and Matrix). When I went back to the Furilabs version of Chatty it still sorted for a while but then suddenly stopped. Killing Chatty (not just closing the window and reopening it) seems to make it sort the conversations sometimes. Problems for Others to Fix Here are the current issues I have starting with the most important. Important The following issues seriously reduce the usability of the device. Hotspot The Wifi hotspot functionality wasn t working for a few weeks, this Gitlab issue seems to match it [3]. It started working correctly for a day and I was not sure if an update I applied fixed the bug or if it s some sort of race condition that worked for this boot and will return next time I reboot it. Later on I rebooted it and found that it s somewhat random whether it works or now. Also while it is mostly working it seemed to stop working about every 25 minutes or so and I had to turn it off and on again to get it going. On another day it went to a stage where it got repeated packet loss when I pinged the phone as a hotspot from my laptop. A pattern of 3 ping responses and 3 Destination Host Unreachable messages was often repeated. I don t know if this is related to the way Android software is run in a container to access the hardware. 4G Reliability Sometimes 4G connectivity has just stopped, sometimes I can stop and restart the 4G data through software to fix it and sometimes I need to use the hardware switch. I haven t noticed this for a week or two so there is a possibility that one fix addressed both Hotspot and 4G. One thing that I will do is setup monitoring to give an alert on the phone if it can t connect to the Internet. I don t want it to just quietly stop doing networking stuff and not tell me! On-screen Keyboard The compatibility issues of the GNOME and KDE on-screen keyboards are getting me. I use phosh/phoc as the login environment as I want to stick to defaults at first to not make things any more difficult than they need to be. When I use programs that use QT such as Nheko the keyboard doesn t always appear when it should and it forgets the setting for word completion (which means spelling correction). The spelling correction system doesn t suggest replacing dont with don t which is really annoying as a major advantage for spelling checkers on touch screens is inserting an apostrophy. An apostrophy takes at least 3* longer than a regular character and saving that delay makes a difference to typing speed. The spelling correction doesn t correct two words run together. Medium Priority These issues are ongoing annoyances. Delay on Power Button In the best case scenario this phone has a much slower response to pressing the power button than the Android phones I tested (Huawei Mate 10 Pro and Samsung Galaxy Note 9) and a much slower response than my recollection of the vast majority of Android phones I ve ever used. For testing pressing buttons on the phones simultaneously resulted in the Android phone screens lighting up much sooner. Something like 200ms vs 600ms I don t have a good setup to time these things but it s very obvious when I test. In a less common case scenario (the phone having been unused for some time) the response can be something like 5 seconds. The worst case scenario is something in excess of 20 seconds. For UI designers, if you get multiple press events from a button that can turn the screen on/off please make your UI leave the screen on and ignore all the stacked events. Having the screen start turning on and off repeatedly when the phone recovers and processes all the button presses isn t good, especially when each screen flash takes half a second. Notifications Touching on a notification for a program often doesn t bring it to the foreground. I haven t yet found a connection between when it does and when it doesn t. Also the lack of icons in the top bar on the screen to indicate notifications is annoying, but that seems to be an issue of design not the implementation. Charge Delay When I connect the phone to a power source there is a delay of about 22 seconds before it starts to charge. Having it miss 22 seconds of charge time is no big deal, having to wait 22 seconds to be sure it s charging before leaving it is really annoying. Also the phone makes an audible alert when it gets to 0% charge which woke me up one night when I had failed to push the USB-C connector in hard enough. This phone requires a slightly deeper connector than most phones so with some plugs it s easy to not quite insert them far enough. Torch aka Flash The light for the torch or flash for camera is not bright at all. In a quick test staring into the light from 40cm away wasn t unpleasant compared to my Huawei Mate 10 Pro which has a light bright enough that it hurts to look at it from 4 meters away. Because of this photos at night are not viable, not even when photographing something that s less than a meter away. The torch has a brightness setting which doesn t seem to change the brightness, so it seems likely that this is a software issue and the brightness is set at a low level and the software isn t changing it. Audio When I connect to my car the Lollypop player starts playing before the phone directs audio to the car, so the music starts coming from the phone for about a second. This is an annoying cosmetic error. Sometimes audio playing pauses for no apparent reason. It doesn t support the phone profile with Bluetooth so phone calls can t go through the car audio system. Also it doesn t always connect to my car when I start driving, sometimes I need to disable and enable Bluetooth to make it connect. When I initially set the phone up Lollypop would send the track name when playing music through my car (Nissan LEAF) Bluetooth connection, after an update that often doesn t happen so the car doesn t display the track name or whether the music is playing but the pause icon works to pause and resume music (sometimes it does work). About 30 seconds into a phone call it switches to hands-free mode while the icon to indicate hands-free is not highlighted, so I have to press the hands-free button twice to get it back to normal phone mode. Low Priority I could live with these things remaining as-is but it s annoying. Ticket Mode There is apparently some code written to display tickets on screen without unlocking. I want to get this working and store screen-caps of the Android barcode screens of the different loyalty cards so I can scan them without unlocking. My threat model does not include someone trying to steal my phone to get a free loaf of bread on the bakery loyalty program. Camera The camera app works with both the back and front cameras, which is nice, and sadly based on my experience with other Debian phones it s noteworthy. The problem is that it takes a long time to take a photo, something like a second after the button is pressed long enough for you to think that it just silently took a photo and then move the phone. The UI of the furios-camera app is also a little annoying, when viewing photos there is an icon at the bottom left of the screen for a video camera and an icon at the bottom right with a cross. Which every time makes me think record videos and leave this screen not return to taking photos and delete current photo . I can get used to the surprising icons, but being so slow is a real problem. GUI App Installation The program for managing software doesn t work very well. It said that there were two updates for Mesa package needed, but didn t seem to want to install them. I ran flatpak update as root to fix that. The process of selecting software defaults to including non-free, and most of the available apps are for desktop/laptop with no way to search for phone/tablet apps. Generally I think it s best to just avoid this and use apt and flatpak directly from the command-line. Being able to ssh to my phone from a desktop or laptop is good! Android Emulation The file /home/furios/.local/share/andromeda/data/system/uiderrors.txt is created by the Andromeda system which runs Android apps in a LXC container and appears to grow without end. After using the phone for a month it was 3.5G in size. The disk space usage isn t directly a problem, out of the 110G storage space only 17G is used and I don t have a need to put much else on it, even if I wanted to put backups of /home from my laptop on it when travelling that would still leave plenty of free space. But that sort of thing is a problem for backing up the phone and wasting 3.5G out of 110G total is a fairly significant step towards breaking the entire system. Also having lots of logging messages from a subsystem that isn t even being used is a bad sign. I just tried using it and it doesn t start from either the settings menu or from the f-droid icon. Android isn t that important to me as I want to get away from the proprietary app space so I won t bother trying this any more. Unfixable Problems Unlocking After getting used to fingerprint unlocking going back to a password is a pain. I think that the hardware isn t sufficient for modern quality face recognition that can t be fooled by a photo and there isn t fingerprint hardware. When I first used an Android phone using a pin to unlock didn t seem like a big deal, but after getting used to fingerprint unlock it s a real drag to go without. This is a real annoyance when doing things like checking Wikipedia while watching TV. This phone would be significantly improved with a fingerprint sensor or a camera that worked well enough for face unlock. Plasma Mobile According to Reddit Plasma Mobile (KDE for phones) doesn t support Halium and can never work on this phone because of it [4]. This is one of a number of potential issues with the phone, running on hardware that was never designed for open OSs is always going to have issues. Wifi MAC Address The MAC keeps changing on reboot so I can t assign a permanent IPv4 address to the phone. It appears from the MAC prefix of 00:08:22 that the network hardware is made in InPro Comm which is well known for using random addresses in the products it OEMs. They apparently have one allocation of 2^24 addresses and each device randomly chooses a MAC from that range on boot. In the settings for a Wifi connection the Identity tab has a field named Cloned Address which can be set to Stable for SSID that prevents it from changing and allows a static IP address allocation from DHCP. It s not ideal but it works. Network Manager can be configured to have a permanent assigned MAC address for all connections or for just some connections. In the past for such things I have copied MAC addresses from ethernet devices that were being discarded and used them for such things. For the moment the Stable for SSID setting does what I need but I will consider setting a permanent address at some future time. Docks Having the ability to connect to a dock is really handy. The PinePhonePro and Librem5 support it and on the proprietary side a lot of Samsung devices do it with a special desktop GUI named Dex and some Huawei devices also have a desktop version of the GUI. It s unfortunate that this phone can t do it. The Good Things It s good to be able to ssh in to my phone, even if the on-screen keyboard worked as well as the Android ones it would still be a major pain to use when compared to a real keyboard. The phone doesn t support connecting to a dock (unlike Samsung phones I ve used for which I found Dex to be very useful with a 4K monitor and proper keyboard) so ssh is the best way to access it. This phone has very reliable connections to my home wifi. I ve had ssh sessions from my desktop to my phone that have remained open for multiple days. I don t really need this, I ve just forgotten to logout and noticed days later that the connection is still running. None of the other phones running Debian could do that. Running the same OS on desktop and phone makes things easier to test and debug. Having support for all the things that Linux distributions support is good. For example none of the Android music players support all the encodings of audio that comes from YouTube so to play all of my music collection on Android I would need to transcode most of them which means either losing quality, wasting storage space, or both. While Lollypop plays FLAC0, mp3, m4a, mka, webm, ogg, and more. Conclusion This is a step towards where I want to go but it s far from the end goal. The PinePhonePro and Librem5 are more open hardware platforms which have some significant benefits. But the battery life issues make them unusable for me. Running Mobian on a OnePlus 6 or Droidian on a Note 9 works well for the small tablet features but without VoLTE. While the telcos have blocked phones without VoLTE data devices still work so if recruiters etc would stop requiring phone calls then I could make one of them an option. The phone works well enough that it could potentially be used by one of my older relatives. If I could ssh in to my parents phones when they mess things up that would be convenient. I ve run this phone as my daily driver since the 3rd of March and it has worked reasonably well. 6 weeks compared to my previous use of the PinePhonePro for 3 days. This is the first time in 15 years that a non-Android phone has worked for me personally. I have briefly used an iPhone 7 for work which basically did what it needed to do, it was at the bottom of the pile of unused phones at work and I didn t want to take a newer iPhone that could be used by someone who s doing more than the occasional SMS or Slack message. So this is better than it might have been, not as good as I hoped, but a decent platform to use it while developing for it.


10 April 2026

Reproducible Builds: Reproducible Builds in March 2026

Welcome to the March 2026 report from the Reproducible Builds project! These reports outline what we ve been up to over the past month, highlighting items of news from elsewhere in the increasingly-important area of software supply-chain security. As ever, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website.

  1. Linux kernel hash-based integrity checking proposed
  2. Distribution work
  3. Tool development
  4. Upstream patches
  5. Documentation updates
  6. Two new academic papers
  7. Misc news

Linux kernel hash-based integrity checking proposed Eric Biggers posted to the Linux Kernel Mailing List in response to a patch series posted by Thomas Wei schuh to introduce a calculated hash-based system of integrity checking to complement the existing signature-based approach. Thomas original post mentions:
The current signature-based module integrity checking has some drawbacks in combination with reproducible builds. Either the module signing key is generated at build time, which makes the build unreproducible, or a static signing key is used, which precludes rebuilds by third parties and makes the whole build and packaging process much more complicated.
However, Eric s followup message goes further:
I think this actually undersells the feature. It s also much simpler than the signature-based module authentication. The latter relies on PKCS#7, X.509, ASN.1, OID registry, crypto_sig API, etc in addition to the implementations of the actual signature algorithm (RSA / ECDSA / ML-DSA) and at least one hash algorithm.

Distribution work In Debian this month,
  • Lucas Nussbaum announced Debaudit, a new service to verify the reproducibility of Debian source packages :
    debaudit complements the work of the Reproducible Builds project. While reproduce.debian.net focuses on ensuring that binary packages can be bit-for-bit reproduced from their source packages, debaudit focuses on the preceding step: ensuring that the source package itself is a faithful and reproducible representation of its upstream source or Vcs-Git repository.
  • kpcyrd filed a bug against the librust-const-random-dev package reporting that the compile-time-rng feature of the ahash crate uses the const-random crate in turn, which uses a macro to read/generate a random number generator during the build. This issue was also filed upstream.
  • 60 reviews of Debian packages were added, 4 were updated and 16 were removed this month adding to our knowledge about identified issues. One new issue types was added, pkgjs_lock_json_file_issue.
Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their work there.

Tool development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions, 314 and 315 to Debian.
  • Chris Lamb:
    • Don t run test_code_is_black_clean test in the autopkgtests. (#1130402). [ ]
    • Add some debugging info for PyPI debugging. [ ]
  • Jelle van der Waa:
    • Fix compatibility with LLVM version 22. [ ]
    • Adjust the PGP file detection regular expression. [ ]
  • Michael R. Crusoe:
    • Reformat the source code using Black version 26.1.0 [ ][ ]
In addition, Vagrant Cascadian updated diffoscope in GNU Guix to version 315.
rebuilderd, our server designed monitor the official package repositories of Linux distributions and attempt to reproduce the observed results there; it powers, amongst other things, reproduce.debian.net. A new version, 0.26.0, was released this month, with the following improvements:
  • Much smoother onboarding/installation.
  • Complete database redesign with many improvements.
  • New REST HTTP API.
  • It s now possible to artificially delay the first reproduce attempt. This gives archive infrastructure more time to catch up.
  • And many, many other changes.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Documentation updates Once again, there were a number of improvements made to our website this month including:
  • kpcyrd:
    • Add a new page about Rust specifics. [ ][ ][ ]
  • Robin Candau:
    • Add link to the diffoci Arch Linux package on the Tools page. [ ]
  • Timo Pohl:

Two new academic papers Marc Ohm, Timo Pohl, Ben Swierzy and Michael Meier published a paper on the threat of cache poisoning in the Python ecosystem: Attacks on software supply chains are on the rise, and attackers are becoming increasingly creative in how they inject malicious code into software components. This paper is the first to investigate Python cache poisoning, which manipulates bytecode cache files to execute malicious code without altering the human-readable source code. We demonstrate a proof of concept, showing that an attacker can inject malicious bytecode into a cache file without failing the Python interpreter s integrity checks. In a large-scale analysis of the Python Package Index, we find that about 12,500 packages are distributed with cache files. Through manual investigation of cache files that cannot be reproduced automatically from the corresponding source files, we identify classes of reasons for irreproducibility to locate malicious cache files. While we did not identify any malware leveraging this attack vector, we demonstrate that several widespread package managers are vulnerable to such attacks. A PDF of the paper is available online.
Mario Lins of the University of Linz, Austria, has published their PhD doctoral thesis on the topic of Software supply chain transparency: We begin by examining threats to the software distribution stage the point at which artifacts (e.g., mobile apps) are delivered to end users with an emphasis on mobile ecosystems [and] we next focus on the operating system on mobile devices, with an emphasis on mitigating bootloader-targeted attacks. We demonstrate how to compensate lost security guarantees on devices with an unlocked bootloader. This allows users to flash custom operating systems on devices that no longer receive security updates from the original manufacturer without compromising security. We then move to the source code stage. [Also,] we introduce a new architecture to ensure strong source-to-binary correspondence by leveraging the security guarantees of Confidential Computing technology. Finally, we present The Supply Chain Game, an organizational security approach that enhances standard risk-management methods. We demonstrate how game-theoretic techniques, combined with common risk management practices, can derive new criteria to better support decision makers. A PDF of the paper is available online.

Misc news On our mailing list this month:
  • Holger Levsen announced that this year s Reproducible Builds summit will almost certainly be held in Gothenburg, Sweden, from September 22 until 24, followed by two days of hacking. However, these dates are preliminary and not 100% final an official announcement is forthcoming.
  • Mark Wielaard posted to our list asking a question on the difference between debugedit and relative debug paths based on a comment on the Build path page: Have people tried more modern versions of debugedit to get deterministic (absolute) DWARF paths and found issues with it?


Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

4 April 2026

Dirk Eddelbuettel: Sponsor me for Tour de Shore 2026 to support MFA

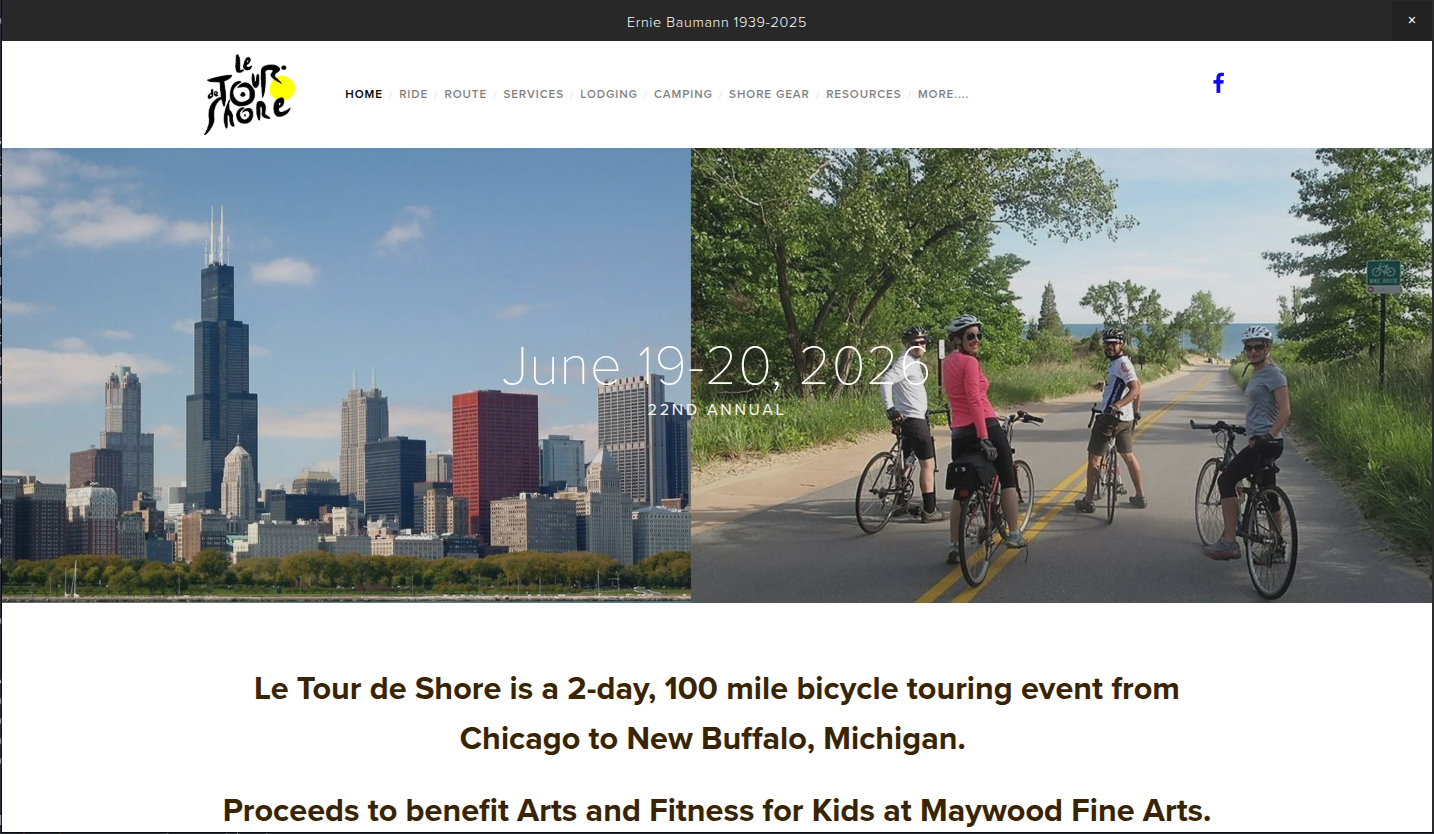
tour de shore 2026 On June 19 and 20, I will cycle a little over 100 miles from downtown Chicago and its wonderful Millenium Park to New Buffalo, Michigan, as part of the Tour de Shore 2026. The ride passes through northwest Indiana and the extended Indiana Dunes National Park ending the next morning in the southwestern Michigan town of New Buffalo. I rode Tour de Shore once before in 2024 and had a generally wonderful time (even considering some soreness after a century of miles over 1 1/2 days). Tour de Shore is riding in support of Maywood Fine Arts Center, a local arts and sports center in Maywood, Illinois, a suburb one over from where I live and hence just a few good miles west of downtown. Maywood, Illinois is home to legends such as the late John Prine as well as several NBA players such as player and coach Doc Rivers. tour de shore 2026 donation page But Maywood, Illinois is also little less well off than other western suburbs. The Maywood Fine Arts Center is simply legendary is what they do for this community (and surrounding communities), and especially the youth support. They can use a dollar a two. Their story about Tour de Shore is worth a read too for background and motivation. I have bootstrapped my donation page page with a dollar for each mile to be cycled. It would be simply terrific if you could join me. A nickel, a dime, or a quarter per mile cycled would help. Multiples of that help too: More is of course still always better. Anything you can afford will go a long way towards a worthy goal in a community that could use the help. Of and if you are local to the area, I believe you can still register for Tour de Shore 2026. So see you out there in June? And if not, maybe help with a dollar or two?

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog.

2 April 2026

Joerg Jaspert: Building a house - 1 year in

Haven t written here about it, but last March we finally started on our journey to get our own house build, so we can move out of the rented flat here. That will be a big step, both the actual building, but also the moving - I am living at this one single place for 36 years now. If you can read german there is a dedicated webpage where I sometimes write about the process. Will have much more details (and way more ramblings) than the following part. If you can t read german, a somewhat short summary follows. Yes, still a lot of text, but shortened, still.

What? Why now? Current flat has 83m - which simply isn t enough space. And the number of rooms also doesn t fit anymore. But it is hard to find a place that fits our requirements (which do include location). Moving to a different rented place would also mean changed amount of rent. And nowadays that would be huge increase (my current rent is still the price from about 30 years ago!). So if we go and pay more - we could adjust and pay for something we own instead. And both, my wife and I had changes in our jobs that made it possible for us now, so we started looking.

Market Brrrr, looking is good, actually finding something that fits - not so. We never found an offer that fit. Space wise, sure. But then location was off, or price was idiotically high. Location fit, but then size was a joke, and guess about the price Who needs 200 square meters with 3 rooms? Entirely stupid design choices there. Or how about 40 square meters of hallway - with 50m of tiny rooms around. What are they smoking? Oh, there, useful size, good rooms - but now you want more money than a kidney is worth, or something. Thanks, no.

New place In February 2025 we finally got lucky and found a (newly opened) area with a large number of places to build a house on. Had multiple talks with someone from on of the companies developing that area (there are two you can select from), then talked with banks and signed a contract in March 2025. We got promised that actual house construction would be first quarter of 2026, finished in second quarter.

House type There are basically 2 ways of building a new house (that matter here). First is called Massivhaus , second is called Fertighaus in german, roughly translating to solid and prefabricated. The latter commonly a wood based construction, though it doesn t need to be. The important part of it is the prefabrication, walls and stuff get assembled in a factory somewhere and then transported to your place, where they play big kid lego for a day and suddenly a house is there. A common thought is prefabricated is faster, but that is only a half true. Sure, the actual work on side is way shorter - usually one or two days and the house is done - while a massive construction usually takes weeks to build up. But that is only a tiny part of the time needed, the major part goes of into planning and waiting and in there it doesn t matter what material you end up with.

Money fun Last year already wasn t the best time to start a huge loan - but isn t it always a few years ago would have been better ? So we had multiple talks with different banks and specialised consultants until we found something that we thought is good for us. Thinking about it now - we should have put even more money on top as reserve , but who could have thought that 2026 turns into such a shitshow? Does not help at all, quite the contrary. And that damn lotto game always ends up with the wrong numbers, meh.

Plans and plans and more plans - and rules For whichever reason you can not just go and put something on your ground and be happy. At least not if you are part of the normal people and not enormously rich. There is a large set of rules to follow. Usually that is a good thing, even though some rules are sometimes hard to understand. In Germany, besides the usual laws, we have something that is called Bebauungsplan , which translates to development plan (don t know if that carries the right meaning, it s a plan on what and how may be build, which can have really detailed specifications in). It basically tells you every aspect on top of the normal law that you have to keep in mind. In our case we have the requirement of 2 full floors and CAN have a third smaller on top, it limits how high the house can be and also how high our ground floor may be compared to the street. It regulates where on the property we may build and how much ground we may cover with the house, it gives a set of colors we are allowed to use, it demands a flat roof that we must have as a green roof and has a number of things more that aren t important enough to list here. If you do want to see the full list, my german post on it has all the details that matter to us. With all that stuff in mind - off to plans. Wouldn t have believed how many details there are to take in. Room sizes are simple, but how to arrange them for ideal usage of the sun, useful ways inside the house, but also keeping in mind that water needs to flow through and out. Putting a bath room right atop a living room means a water pipe needs to go down there. Switch the bath room side in the house, and it suddenly is above the kitchen - means you can connect the pipes from it to the ones from kitchen, which is much preferred than going through the living room. And lots more such things. It took us until nearly end of October to finalize the plans! And we learned a whole load from it. We started with a lot of wishes. The planner tried to make them work. Then we changed our minds. Plans changed. Minds changed again. Comparing the end result with the first draft we changed most of the ground floor around, with only the stairs and the entrance door at the same position. Less changes for the upper floor, but still enough.

Side quests The whole year was riddled with something my son named side quests. We visited a construction exhibition near us, we went to the house builders factory and took a look on how they work. We went to many different other companies that do SOME type of work which we need soon, say inside floors, painters, kitchen and more stuff. Of course the most important side quest was a visit to the notary to finalize the contracts, especially for the plot of land (in Germany you must have a notary for that to get entered into the governments books). Creates lots of fees, of course, for the notary and also the government (both fees and taxes here).

Building permit We had been lucky and only needed a small change to the plans to get the building permit - and the second part, the wastewater permit (yes, you need a separate one for this) also got through without trouble.

Choices, so many of them So in January we finally had an appointment for something that s called Bemusterung which badly translates to Sampling . Basically two days at the house builders factory to select all of what s needed for the house that you don t do in the plans. Doors, inside and out and their type and color and handles. Same things for the windows and the blinds and the protection level you want the windows to have. Decide about stairs, design for the sanitary installations - and also the height of the toilet! - and the tiles to put into the bathrooms. Decisions on all the tech needed (heating system, ventilation and whatnot. Two days, busy ones - and you can easily spend a lot of extra money here if you aren t careful. We managed to get out of it with only about 4000 extra, so pretty good.

Electro and automation Now, here I am special. Back when I was young the job I learned is electrician. So here I have very detailed wishes. I am also running lots of automatism in my current flat - obviously the new house should be better than that. So I have a lot of ideas and thoughts on it, so this is entirely extra and certainly out of the ordinary the house builder usually see. Which means I do all of that on my own. Well, the planning and some of the work, I must have a company at hand for certain tasks, it is required by some rules. But they will do what I planned, as long as I don t violate regulations. Which means the whole electrical installation is different. Entirely planned for automatisms and using KNX for it. I am so happy to ditch Homeassistant and the load of Homematic, Zigbee and ZWave based wireless things. Ok, Homeassistant is a nice thing - it can do a lot. And it can bridge between about any system you can find. But it is a central single point of failure. And it is a system that needs constant maintenance. Not touched for a while? Plan for a few hours playing update whack-a-mole. And often enough a component here or there breaks with an update. Can be fixed, but takes another hour or two. So I change. Away from wireless based stuff. To wires. To a system thats a standard for decades already. And works entirely without a SPOF. (Yes, you can add one here too). And, most important, should I ever die - can easily be maintained by anyone out there dealing with KNX, which is a large number of people and companies. Without digging through dozens of specialised integrations and whatnot. I may even end up with Homeassistant again - but that will entirely be as a client. It won t drive automations. It won t be the central point to do anything for the house. It will be a logging and data collecting thing that enables me to put up easy visualizations. It may be an easy interface for smartphones or tablets to control parts of the house, for those parts where one wants this to happen. Not the usual day-to-day stuff, extras on top.

Actual work happening Since march there finally is action visible. The base of the house is getting build. Wednesday the 1st April we finally got the base slab poured on the construction site and in another 10 days the house is getting delivered and build up. A 40ton mobile crane will be there.

1 April 2026

Ben Hutchings: FOSS activity in March 2026

Matthew Garrett: Self hosting as much of my online presence as practical

Because I am bad at giving up on things, I ve been running my own email server for over 20 years. Some of that time it s been a PC at the end of a DSL line, some of that time it s been a Mac Mini in a data centre, and some of that time it s been a hosted VM. Last year I decided to bring it in house, and since then I ve been gradually consolidating as much of the rest of my online presence as possible on it. I mentioned this on Mastodon and a couple of people asked for more details, so here we are. First: my ISP doesn t guarantee a static IPv4 unless I m on a business plan and that seems like it d cost a bunch more, so I m doing what I described here: running a Wireguard link between a box that sits in a cupboard in my living room and the smallest OVH instance I can, with an additional IP address allocated to the VM and NATted over the VPN link. The practical outcome of this is that my home IP address is irrelevant and can change as much as it wants - my DNS points at the OVH IP, and traffic to that all ends up hitting my server. The server itself is pretty uninteresting. It s a refurbished HP EliteDesk which idles at 10W or so, along 2TB of NVMe and 32GB of RAM that I found under a pile of laptops in my office. We re not talking rackmount Xeon levels of performance, but it s entirely adequate for everything I m doing here. So. Let s talk about the services I m hosting.

Web This one s trivial. I m not really hosting much of a website right now, but what there is is served via Apache with a Let s Encrypt certificate. Nothing interesting at all here, other than the proxying that s going to be relevant later.

Email Inbound email is easy enough. I m running Postfix with a pretty stock configuration, and my MX records point at me. The same Let s Encrypt certificate is there for TLS delivery. I m using Dovecot as an IMAP server (again with the same cert). You can find plenty of guides on setting this up. Outbound email? That s harder. I m on a residential IP address, so if I send email directly nobody s going to deliver it. Going via my OVH address isn t going to be a lot better. I have a Google Workspace, so in the end I just made use of Google s SMTP relay service. There s various commerical alternatives available, I just chose this one because it didn t cost me anything more than I m already paying.

Blog My blog is largely static content generated by Hugo. Comments are Remark42 running in a Docker container. If you don t want to handle even that level of dynamic content you can use a third party comment provider like Disqus.

Mastodon I m deploying Mastodon pretty much along the lines of the upstream compose file. Apache is proxying /api/v1/streaming to the websocket provided by the streaming container and / to the actual Mastodon service. The only thing I tripped over for a while was the need to set the X-Forwarded-Proto header since otherwise you get stuck in a redirect loop of Mastodon receiving a request over http (because TLS termination is being done by the Apache proxy) and redirecting to https, except that s where we just came from. Mastodon is easily the heaviest part of all of this, using around 5GB of RAM and 60GB of disk for an instance with 3 users. This is more a point of principle than an especially good idea.

Bluesky I m arguably cheating here. Bluesky s federation model is quite different to Mastodon - while running a Mastodon service implies running the webview and other infrastructure associated with it, Bluesky has split that into multiple parts. User data is stored on Personal Data Servers, then aggregated from those by Relays, and then displayed on Appviews. Third parties can run any of these, but a user s actual posts are stored on a PDS. There are various reasons to run the others, for instance to implement alternative moderation policies, but if all you want is to ensure that you have control over your data, running a PDS is sufficient. I followed these instructions, other than using Apache as the frontend proxy rather than nginx, and it s all been working fine since then. In terms of ensuring that my data remains under my control, it s sufficient.

Backups I m using borgmatic, backing up to a local Synology NAS and also to my parents home (where I have another HP EliteDesk set up with an equivalent OVH IPv4 fronting setup). At some point I ll check that I m actually able to restore them.

Conclusion Most of what I post is now stored on a system that s happily living under a TV, but is available to the rest of the world just as visibly as if I used a hosted provider. Is this necessary? No. Does it improve my life? In no practical way. Does it generate additional complexity? Absolutely. Should you do it? Oh good heavens no. But you can, and once it s working it largely just keeps working, and there s a certain sense of comfort in knowing that my online presence is carefully contained in a small box making a gentle whirring noise.

30 March 2026

Utkarsh Gupta: FOSS Activites in March 2026

Here s my monthly but brief update about the activities I ve done in the FOSS world.

Debian
Whilst I didn t get a chance to do much, here are still a few things that I worked on:
  • A quick exchange with Xavier about node-lodash fixes for stable releases.
  • Uploaded ruby-rack to CVE-2026-25500 & CVE-2026-22860 to sid, trixie, and bookworm.
  • Started to work on the DebConf Bursary team along with PEB.
  • Assited a few folks in getting their patches submitted via Salsa.
  • Mentoring for newcomers.
  • Moderation of -project mailing list.

Ubuntu
I joined Canonical to work on Ubuntu full-time back in February 2021. Whilst I can t give a full, detailed list of things I did, here s a quick TL;DR of what I did:
  • Successfully released 26.04 LTS Beta!
  • Worked further on the whole artifact signing story for cdimage.
  • Assisted a bunch of folks with my Archive Admin and Release team hats to:
    • Review and grant FFes.
    • Coordinating weekly syncs.
    • Promoting/demoting binaries to/from main.
    • Taking care of package removals and so on.
  • Was pretty occupied with the new release processs architecture and design.
  • Preparing for the 26.04 LTS final release.

Debian (E)LTS
This month I have worked 50 hours on Debian Long Term Support (LTS) and on its sister Extended LTS project and did the following things:

Released Security Updates

Work in Progress
  • knot-resolver: Affected by CVE-2023-26249, CVE-2023-46317, and CVE-2022-40188, leading to Denial of Service.
  • node-lodash: Affected by CVE-2025-13465, prototype pollution in the baseUnset function.
    • [stable]: Xavier from the JS team ACK d the patch. The trixie and bookworm uploads will follow.
    • [LTS]: The bullseye test and upload will follow in April once the stable uploads are in and ACK d by the SRMs.
  • vlc: Affected by CVE-2025-51602, an out-of-bounds read and denial of service via a crafted 0x01 response from an MMS server.
    • [LTS]: 3.0.23 backport is ready but not tested. I ll get this over the line in March.
    • [ELTS]: 3.0.23 backport is ready but not very clean. Would like to complete LTS and get back to this.

Other Activities
  • [ELTS] Continued to review ruby-rack for ELTS it has since received about 13 new CVEs, making it even more chaotic. Might consider releasing in batches.
  • [E/LTS] Monitored discussions on mailing lists, IRC, and all the documentation updates.
  • [E/LTS] Attended the monthly LTS meeting on IRC. Summary here.
  • [Other] Spent quite some time debugging a bug in debusine. Filed https://salsa.debian.org/freexian-team/debusine/-/issues/1412 for the same. Have worked on a preliminary patch but would like to submit something for Colin to review. Will follow up in April.

Until next time.
:wq for today.

29 March 2026

Samuel Henrique: Latest NVIDIA Drivers for Debian (Packaged with AI)

Two terminal windows side-by-side, on the left there's the Debian logo in ASCII art, and on the right it's the output of nvidia-smi, showing the driver version 595.58.03 running on a machine that has an NVIDIA RTS 5080

tl;dr This is not an official package, it's good enough for me and it might be good enough for you, confirmed as working in Debian Testing but I don't have a Stable machine to test there. You can use my custom repo to install the latest NVIDIA drivers on Debian Stable, Testing or Unstable (install from Sid repository): https://deb.debusine.debian.net/debian/r-samueloph-nvidia-ai/ The page above contains the APT sources you need, just add the one for your release to /etc/apt/sources.list.d/r-samueloph-nvidia-ai.sources, run sudo apt update and install the packages, you might need to disable Secure Boot.

This is not about AI Discussions about AI are quite divisive in the Free Software communities, and there's so much to be said about it that I'm not willing to go into in this blog post. This is rather just me telling people that if they need up-to-date NVIDIA packages for Debian, they could check if my custom repository gets the job done. The AI part is a means to an end, I've been careful to note in the repository names that the packages were produced with AI to respect people who do not want to run it for any reason.

RTX 5000 series support Back in May 2025 I opened a bug report asking for the NVIDIA drivers on Debian to be updated to support the RTX 5000 series. The Nouveau drivers might be good enough for some people, but I need the NVIDIA drivers because I want to play games and do experiments with open weight models. Opening a bug report doesn't guarantee anything, at the end of the day Debian Developers are volunteers, so if I really wanted the newer drivers, I would have to do something about it, ideally submitting a merge request. I briefly looked into the NVIDIA packaging, which involves 3 source packages (and one extra git repo for tarballs), unfortunately this was going to take more time and effort than what I was willing to spend.

What I Did After a few weeks of lamenting that I wasn't running the NVIDIA drivers, I figured I was willing to put in more effort than I originally thought, just enough to instruct the Claude Code agent to package the latest releases. I'm skilled enough with agentic tools that I knew how to use it to save time; providing a clear instruction on how to build the package and explaining the packaging layout, then letting the agent iterate until it gets a working build. The agent was running inside a VM that didn't have any of my credentials. After a little bit of back and forth, where I was reviewing the changes guiding the agent into how to fix certain issues, I ended up with a working set of packages. Once I installed it on my machine and confirmed they worked, I set up a debusine repository to make it easier to install future updates, and let others test it out. Debusine is analogous to Ubuntu's famous PPA, or Fedora's EPEL, it's a relatively new project but it has been working fine for this. Matheus Polkorny helped me test the packages and did spot a few issues which are fixed now. The Debusine developers were also always quick to respond to my questions and bug reports.

How Good Is It? Short answer: good enough for daily use, but not a substitute for an official Debian package. The whole point of doing this is because I don't have enough free time to maintain the package myself. All of this work was done as a volunteer, on my personal time. This means I'm trusting the agent to some degree; I review its commits but I don't go too deep into it, the quality will be dictated by the fact that I'm a Debian Developer and so by how easily I can spot issues without double checking everything. I only have a single machine with an NVIDIA GPU, this machine runs Debian Testing and so I don't have a way to test the Stable packages. I can do my best to address problems but at this point there is a risk that new updates break something. Installing NVIDIA drivers has always been a bit risky regardless, if you're comfortable with reverting updates and handling a system without a graphical interface (in case you end up in a tty), you will be fine. You will likely need to disable Secure Boot in order to use them, or set up your BIOS so that a MOK can be used to sign the DKMS modules. When choosing the version strings for the packages, I was careful enough to pick something that would sort lower than an official Debian package, meaning that whenever that same version is packaged in Debian, your system will see it as an upgrade. If you have any other methods of installing the NVIDIA drivers on your Debian system that is working for you, you should likely stick to that. I have a strong preference for installing them through .deb packages, making the package sort out configuration changes and dependency updates, besides handling the DKMS modules. Ultimately I'm not happy with the amount of difficulty that Debian users have in installing up-to-date NVIDIA drivers, and I hope this makes it easier for some.

How To Install Head over to the Debusine page that contains both repos for Trixie (Debian Stable) and Sid (for Debian Testing and Unstable): https://deb.debusine.debian.net/debian/r-samueloph-nvidia-ai/ If you are running Debian Testing, then pick the Sid repository. That page contains the contents of the apt .sources file you need, create the file /etc/apt/sources.list.d/r-samueloph-nvidia-ai.sources with the sources for your release. Run sudo apt update and install the packages you need, if you already have a previous version installed, sudo apt upgrade --update would update them. If there are no upgrades, meaning you don't have a previous version installed, then you need to explicitly install them.
sudo apt install nvidia-open-kernel-dkms nvidia-driver
If you run into issues in Debian Stable, consider using the Linux kernel package from the backports repository, if you need an up-to-date NVIDIA driver, you likely should also be running the backports kernel package (if you can't upgrade to Debian Testing).

Future Plans I currently have no means of measuring how many people are using the debusine repositories, so if you do end up using it feel free to let me know somehow. I don't know for how long I will keep managing this repository, and how much effort I will spend, but my machine needs it and for now I will keep it up-to-date with the latest production-grade NVIDIA drivers.

Sources The sources of the packages are available under a namespace in Salsa (Debian's GitLab instance): https://salsa.debian.org/samueloph-forks-team/nvidia-drivers-forks-with-ai You can also get the exact sources used in the repositories from debusine: https://debusine.debian.net/debian/r-samueloph-nvidia-ai/collection/debian:suite/sid-nvidia-ai/search/?category=debian:source-package https://debusine.debian.net/debian/r-samueloph-nvidia-ai/collection/debian:suite/trixie-nvidia-ai/search/?category=debian:source-package

28 March 2026

Russell Coker: Communication and Hostile AIs

We seem to be entering an AI apocalypse of sorts, they aren t going to kill us or even take our jobs. What they are doing is destroying the Internet commons by filling it with rubbish. This isn t even real AI, just pattern matching and prediction systems, mostly LLMs. The Problem Scott Shambaugh s saga of being attacked and defamed by an OpenClaw AI bot is interesting and raises some disturbing possibilities for future online discussion [1]. Imagine what it would be like if everyone who was in any way notable for free software work had 100 such bots going after them. Dania Dumas wrote an insightful blog post about why OpenClaw is impossible to secure and why it won t go away [2]. Bruce Schneier and Nathan E. Sanders wrote an insightful article about the AI generated text arms race [3] primarily concentrating on situations in which text that was assumed to be written by humans but was actually written in bulk by bots was performing a DOS attack on people who were reviewing it. There are many situations such as book publishing and publishing letters to the editor of newspapers where getting new material from unknown people is an important part of the job but where there are also people making low quality submissions that are almost a DOS attack at the best of times. Currently the email spam problem continues to get worse and when LLM use increases it will get significantly worse. Email encryption isn t viable [4]. The PGP web of trust never really worked well as it s too difficult for most users. The amount of AI generated content that s being recommended to users on platforms like YouTube and Facebook is steadily increasing and the amount of LLM generated commentary that purports to be from real people on Twitter and Facebook is also increasing. Here s an informative blog post by Erich Schubert about this [5]. Potential Solutions Surrender? One option and possibly the default option is to surrender to this and just let everything we built on the Internet over decades get destroyed. Whether to surrender is a decision that can be made on a per-service basis. Twitter is pretty much useless anyway, I quit Twitter because Elon deliberately made it suck [6]. In my opinion this is not surrendering to what s being done there, I m just stopping wasting time on it and using better options. I used to have about 300 followers on Twitter and I don t think that many of them would ever choose to stop following me, so I presume that about 1/3 of the people following me have decided to totally quit Twitter and delete their accounts. I also presume that some of the remainder have done the same as me and just kept a mostly inactive account. If Elon suddenly stopped being a stupid asshole it probably wouldn t change anything as the value of the system was connections to others. Some people will consider my abandonment of Twitter as surrender and I accept that it s not an unreasonable opinion. I think that the possibly 100 Twitter followers of mine who deleted their accounts surrendered. Facebook has been becoming a worse service, it s business model is becoming increasingly exploitative and it s interface is designed to be addictive. It s probably best avoided unless you really need it. The only good thing about Facebook at the moment is that Facebook Marketplace doesn t take a cut on sales and there are some really good deals on computers if you know what to look for. Unfortunately Facebook has a large number of users who are from marginalised communities and have no other alternatives for communication. It would be good to get them migrated to other platforms. We could just give up on a lot of general communications services and have everyone accept that good content is drowned out by rubbish and have the Internet become divided between people who accept the rubbish and those who cease using large portions of the Internet environment to avoid it. Using Non Commercial Services Lemmy is a good FOSS federated alternative to Reddit which also covers some of the uses of Facebook. It needs more users to get critical mass but is still quite usable. A post that might get a dozen comments on Reddit may get 1 comment on Lemmy but that one comment will be a good one. Reddit doesn t appear to be attacked much by LLM generated content at least not yet. Even if the Reddit model proves to be resilient to LLM attack the Lemmy software can be used to replace some things that are done on Facebook, Mastodon is a good FOSS federated replacement for Twitter, it has a decent user-base including some VIPs. While it is aimed at the Twitter use case it can also cover a significant part of the Facebook use case. There are some other FOSS social media programs which could take over other parts of the commercial social media environment. Generally commercially run Internet services will have a financial incentive to allow the problems to get worse so we need to rely on FOSS software, non-commercial implementations, and government services. Web Search For a long time Google has had a monopoly on web search, but now they default to including an AI Overview at the start of the results which is sometimes useful but also sometimes very wrong. You can use the search URL https://www.google.com/search?q=%s&udm=web to get google results without rubbish. But I presume that they will break that if it gets too popular. Searxng is a AGPL licensed metasearch engine that aggregates results from other engines, here s the Searxng source [7] and here s a list of Searxng instances if you want to try one [8]. Even using meta search engines like Searxng won t help if the original data is overloaded with spam, but alleviating the problem is a good temporary measure. Web of Trust for the Web? I ve idly considered the possibility of having some sort of rating system for web pages that uses a web of trust so that you can securely use trust ratings of friends of friends etc. But given all the difficulties in using a web of trust for signing GPG key for software developers (the demographic that is most skilled at doing such things) it doesn t seem viable. Should we surrender the idea of having a usable public web? In the early days of the web (before Google) it was standard practice to rely on recommendations from other people or from trusted sites to find other sites, that could be considered to be an informal web of trust. We could go back to that sort of usage pattern if Google and many of the big sites get overwhelmed by LLM generated spam. Wikipedia I believe that Wikipedia will be at the front lines of this battle. It s model has always included anonymous contributions. Benjamin Mako Hill wrote an interesting blog post about research he did with Kaylea Champion into Wikipedia pages on taboo topics which have a larger portion of contributors choosing to be anonymous than non-taboo pages [9]. Wikipedia also has a long history of being abused for various reasons, one that I witnessed was someone putting false content into Wikipedia pages to immediately cite them in support of their facebook arguments. That sort of thing can be dealt with at human scale but a large scale attack by bots is a different problem to solve. Also with the recent developments in AI developing multiple web sites entirely populated for the purpose of supporting one fake entry in Wikipedia is plausible. The upside of these attacks that I predict is that they will attract the attention of all the people who have skills related to developing counter-measures. While LLM bots are filling the inboxes of publishers with rubbish and messing up the stackoverflow comments section not a lot of people are bothered, but once the attacks on Wikipedia get serious everyone will take notice. National AI Bruce Schneier and Nathan E. Sanders wrote an interesting blog post about nationalised public AI [10]. While that won t directly address this issue it will get the right technology in the hands of people who can use it in the right way. Conclusion This is going to be a difficult problem to solve, more difficult than the email spam problem we have been unable to solve after 30 years of working on it. This is also a very important problem, we are currently in an age where we have access to information that most people couldn t even dream of 30 years ago. We also have disinformation that combines some of the worst aspects of authoritarian regimes throughout history combined with the worst aspects of cult brainwashing. If we lose access to the information but the disinformation remains (or get worse) then the result will be terrible. I don t have great ideas for solving this. I have outlined some small ideas to mitigate things and I hope that others can expand on them. Please write comments with any good ideas you have, or even ideas that don t totally suck. A problem this difficult is not going to be solved in a blog comment, but a blog comment might point in the right direction.

27 March 2026

Samuel Henrique: I use curl with ECH btw (in Debian)

tl;dr This is an experimental feature that, for the first time, brings full ECH support to curl on Debian using OpenSSL. Starting with curl 8.19.0-3+exp2 (Debian Experimental), you can now use ECH, with HTTPS-RR and DoH for maximum privacy. curl 8.19.0-3+exp2 is quite fresh at the time of writing, bear in mind that your repository might not have synced the package yet, all mirrors should have it by March 27th 14:00 UTC.
# defo.ie is a test server that confirms whether ECH was successfully used
curl -v --ech hard https://defo.ie/ech-check.php
# For Encrypted Client Hello (ECH) + DNS over HTTPS (DoH)
curl -v --ech hard --doh-url https://1.1.1.1/dns-query https://defo.ie/ech-check.php
"--ech hard" tells curl to refuse the connection entirely if ECH cannot be negotiated. Or, if you would like to try it out in a container:
podman run debian:experimental /bin/bash -c 'apt install --update -t experimental -y curl && curl -v --ech hard --doh-url https://1.1.1.1/dns-query https://defo.ie/ech-check.php'
(in case you haven't noticed, apt now has the --update option for the upgrade and install commands)

For Privacy CloudFlare calls it "the last puzzle piece to privacy" in their must-read announcement: https://blog.cloudflare.com/announcing-encrypted-client-hello/. Encrypted Client Hello (rfc9849) encrypts the "which website are you connecting to?" part of the TLS handshake that was previously visible in plaintext. HTTPS-RR (rfc9460) is a DNS record type that publishes connection parameters for a service, including the public key clients need to perform ECH. DNS Over HTTPS (rfc8484) encrypts DNS queries by tunneling them over HTTPS, hiding what domains you're looking up from network observers. When all three operate together over a CDN with shared IP space, the target domain name is hidden from passive observers; the HTTPS-RR record is queried over DoH in order to retrieve the ECH key (rfc9848) for the TLS handshake. Seems like quite an important feature, and in fact the major browsers have it enabled for some time now, the trick is that they do not use OpenSSL (Chrome uses BoringSSL and Firefox uses NSS). For everyone else, the only option is to patch OpenSSL or wait until 4.0.0 is released, and so part of the reason Debian is the first distro to enable it (curl + OpenSSL + ECH) is that the OpenSSL maintainer (Sebastian Andrzej Siewior) packaged the alpha release just 3 days after it was published. Do not forget that ECH support is experimental and currently relies on the alpha release of OpenSSL.

wcurl Gets It Too Considering wcurl is just a wrapper on curl, it gets the feature for free:
wcurl --curl-options="--ech hard --doh-url https://1.1.1.1/dns-query" $URL
If you're using wcurl, you don't want to have to set parameters, this is just to show that the feature is there and if you have a .curlrc file, it can enable the feature seamlessly.

Other Debian Releases Given the ECH feature requires OpenSSL >= 4, it will not make it to Debian 13, having a small chance of going to Debian 13 Backports (emphasis on small). It should get to Debian Unstable and Debian Testing within the next couple of months as the OpenSSL GA release happens and gets packaged, but you should be able to install the package from Experimental in your Unstable and Testing systems without issues. It will also be in Debian 14 once it becomes the new Stable.

Shoulders of Giants Stephen Farrell's presentation from OpenSSL Conference 2025 has a lot of background on the work involved: Encrypted Client Hello Lessons learned from trying to do something that was probably too complicated They have been working on implementing ECH in open-source projects for years, something as big as this doesn't happen without lots of people dedicating both their paid and free times over it. I ended up being the person who enabled it on Debian, which was pretty much the least amount of work between everyone involved, but hey it's fun flipping the switch and telling you about it.

Background Since 2025, the curl developers started organizing an yearly meeting with all maintainers of curl in Operating Systems. The 2026 edition happened in March 26th: https://github.com/curl/curl/wiki/curl-distro-discussion-2026. Attendance was really good, and as you can imagine one of the topics of discussion was ECH, in which it was pointed out that having OpenSSL 4 was the main requirement but besides it nothing unusual was needed. In Debian Experimental, we have been enabling HTTPS-RR since March 2025, and OpenSSL 4.0.0 alpha was packaged just recently (2026-03-13) by Sebastian Andrzej Siewior, it's time for the next step. The curl distro meeting was just the motivation I needed to go ahead and enable it in Debian Experimental, so as part of our Debian Brasil Weekly Meetings I've prepared and uploaded the changes, while Carlos Henrique Lima Melara worked on addressing a recent test regression for Debian Unstable. Unfortunately sergiodj couldn't join and I'm sure he's jealous of the hacking session now.

Appendix While writing this, I've noticed one of the authors of the CloudFlare blogpost is the previous curl maintainer on Debian; Alessandro Ghedini let me take over the maintenance back in 2021 and today curl is maintained by a team of 4 people, it's nice to see Alessandro's involvement.

21 March 2026

Ravi Dwivedi: Vietnam Trip

Before reaching Vietnam Continuing from the last post, Badri and I took a flight from the Brunei International Airport to Kuala Lumpur on the 12th of December 2024. We reached Kuala Lumpur in the evening. After arriving at the airport, we went through immigration. In a previous post, I mentioned that we had put our stuff in lockers at the TBS bus terminal in Kuala Lumpur. Therefore, we had to go there. The locker was automated and required us to enter the PIN we had set. Upon entering the PIN, the locker wasn t getting unlocked. After trying this for 10-15 minutes without any luck, we tried getting some help as there the lockers weren t under supervision. So, I roamed around and found a staff member, reporting that our lockers weren t getting unlocked. They called the person who was in-charge of the lockers. He came to us in a few minutes and used their admin access to open the locker. We were supposed to pay for using the lockers by putting the banknotes inside through a slot. However, as the machine wasn t working, we gave the amount for the use of our locker service to that person instead. We soon went back to the KL airport to catch our morning flight to Ho Chi Minh City in Vietnam. At the flight counter, we were afraid we would have to pay extra as our luggage surpassed the allowed weight limit. This one was also a budget airline AirAsia and our tickets didn t include a check-in bag. Generally, passengers from countries requiring a visa to visit Vietnam (such as India) require going to the airline and showing their visa to get the boarding pass. However, when we went to the AirAsia counter at the Kuala Lumpur airport, they didn t weigh our bags and asked us to get our boarding passes from an automated kiosk. So, we got our boarding passes printed and proceeded to the airport security. While clearing the airport security, a lotion I bought from Singapore was confiscated because it was 200 mL, exceeding the limit of 100 mL per bottle. Had that 200 mL liquid been in two different bottles of 100 mL each, I would have been allowed to take it in my carry-on bag, but a single 200 mL bottle wasn t! I was allowed to keep it in the check-in bag, but I didn t have it included in my ticket. Huh, airports and their weird rules :( The lotion was an expensive one, so having it thrown away did ruin my mood.

Overview We started our Vietnam trip from Ho Chi Minh City in the south on the 13th of December 2024 and finished it in Hanoi in the north on the 20th of December. We traveled from Ho Chi Minh City to Hanoi mostly by train, except for a hundred or so kilometers by bus, in chunks. On the way, we visited Nha Trang, Hoi An, and Hue. The distance between Ho Chi Minh City and Hanoi is 1700 km. For your reference, here are those places labeled on Vietnam s map.
Vietnam map with Ho Chi Minh City, Nha Trang, Hoi An, Hue and Hanoi labeled. A map of Vietnam with points of places we went to labeled. CARTO MAPTILER OPENSTREETMAP
Ho Chi Minh City We landed in Ho Chi Minh City early morning on the 13th of December 2024. I was tired and sleepy as I hadn t gotten a good night s sleep. After going through immigration, we went to a currency exchange counter to get Vietnamese Dong. Unlike other countries on this trip, money exchange counters in Vietnam didn t accept Indian rupees. Therefore, we exchanged euros to get Vietnamese dong at the airport. After getting out of the airport, we took a bus to the city center. It was 15,000 dongs approximately 50 Indian rupees. Our plan was to meet Badri s friend and stay the night at his apartment. So we went to a caf nearby and bought a coffee for each of us for 75,000 dongs. We went upstairs and sat for a while. The Wi-Fi password was mentioned on our bill. During the trip, I found out about the caf culture of Vietnam. They have their own coffee brands (such as Highlands Coffee), and you can sit down at any of the caf s for work or wait for the rain to stop. It rained a lot while we were there, so we did use these caf s for that purpose. Badri s friend met us there, and we roamed around the area a bit, which included roaming inside a beautiful park. Then Badri s friend took us to a restaurant. Because I do not eat meat, he took us to a vegan restaurant. Having been to four Southeast Asian countries at this point (excluding Vietnam), I was under the impression that there wouldn t be a lot of things for my diet in Vietnam.
A picture of the park we roamed around in Ho Chi Minh City. A picture of the park we roamed around in Ho Chi Minh City. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
However, I was pleasantly surprised at the restaurant. I found all the dishes to be tasty, especially their signature noodles called Pho. I liked another dish so much that I tracked down the restaurant again with Badri using the geotagged image of the bill I had taken earler to have it again. As a tip for vegans coming to Vietnam, the places having the letters Chay (without any accented letters) in their name are vegan only.
A building This is the restaurant Badri s friend took us to. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
An item in the restaurant One of the dishes we had in the restaurant. This one was especially tasty. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
One of the dishes we had in the restaurant. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. One of the dishes we had in the restaurant. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Noodles in a bowl dipped in soup These noodles are called Pho and are very popular in Vietnam. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
In the night, we went to a supermarket where I got myself some oranges and guavas. Then, we went to a Japanese restaurant where I didn t have anything, as there was no vegetarian option available for me. Then we took a free bus to the place to Badri s friend s apartment. The construction company that built the apartment also runs this free bus service from their residential area to different parts of the city as a way of promoting their apartments. Anyone can take the bus, not just residents. The next day, we took the free bus back to the city center and checked in to a hostel for a night. We took two beds in dormitories, which were 88,000 dongs (270 rupees) for each bed for a night. In Vietnam, if you can spend around 300 rupees per night, you can get a bed in a decent hostel.

Train from Ho Chi Minh City to Nha Trang On the night of the 15th of December 2024, we boarded a train from Ho Chi Minh City to Nha Trang. The ticket for each of us was 519,000 dongs (1600 Indian rupees). The train name was SNT2. When we reached the Ho Chi Minh City train station, we noticed that the station was rather small by Indian standards. After entering the train station, we went inside to the first platform, where the tickets were checked by a staff member. Ho Chi Minh City was the originating station for our train, so our train was already standing at the station. We had to cross the railway tracks on foot to reach the platform our train was on. Then we located our coach, where a ticket inspector was standing at the gate. He let us in after checking our tickets. In all these instances, we just had to show our digital boarding pass which we had received by email. Unlike Indian trains, the train didn t have side berths. Additionally, I liked the fact that it had a dedicated space to put our bags in, which was very convenient. The train departed from Ho Chi Minh City at 21:05 and arrived in Nha Trang at 05:30 in the morning.
Interior of our train coach. Trains in Vietnam don’t have side berths, unlike India. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Interior of our train coach. Trains in Vietnam don t have side berths, unlike India. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
A picture of the berths from our coach. It had three tiers, similar to a 3 AC coach in Indian trains. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. A picture of the berths from our coach. It had three tiers, similar to a 3 AC coach in Indian trains. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
The train had a cabin to put the bags in. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. The train had a cabin to put the bags in. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Nha Trang train station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Nha Trang train station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Nha Trang Nha Trang is a coastal place, and we planned to go to a beach. We figured out that the bus to the airport goes can drop us near the beach. Therefore, we went to the bus station to get to the airport bus. The bus station was walking distance from the railway station. So, we decided to walk. On the way, we stopped at a small shop for a coffee. The shop also gave a complimentary cup of green tea along with the coffee. I found out later that it is common for local shops to give a cup of complimentary green tea in Vietnam.
A cup of coffee and a cup of green tea. I got a complimentary cup of green tea along with coffee in Nha Trang. In this trip, Badri and I found out that this is customary at local places in Vietnam. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Soon we reached the bus station and took a bus to the beach. It was 65,000 dongs ( 200). After getting down from the bus, I had coconut water and some eggs at a small local place.
Eggs on a pan. Eggs being cooked on a pan for my order. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Then we went to the beach, but nobody else was there. We spent some time there and went back to the place where the bus dropped us as it started raining. We couldn t find a bus for some time. A taxi driver approached us and agreed to take us to the city center for 200,000 dongs ( 650). For reference, the place where he dropped us was 35 km from the place we took the taxi. Taxi fares in Vietnam were also cheap!
The beach we went to in Nha Trang. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. The beach we went to in Nha Trang. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Nha Trang was a beautiful place, and so we roamed around for a while. Then we stopped at a Highlands Coffee branch for a while. Since Christmas was coming up, the caf had a Christmas tree, and I liked the Christmas vibes. They were playing Mariah Carey s All I Want for Christmas Is You.
This one was shot in the city center. In this trip, Badri and I found out that this is customary at local places in Vietnam. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. This one was shot in the city center. In this trip, Badri and I found out that this is customary at local places in Vietnam. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Inside a Highlands Coffee cafe in Nha Trang. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Inside a Highlands Coffee cafe in Nha Trang. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
A coffee I got from Highlands Coffee in Nha Trang. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. A coffee I got from Highlands Coffee in Nha Trang. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
During the evening, we went to a local place to eat. The place mentioned Chay in its name, and you know what it means it was a vegan place. There was a man there and no other customers. I don t remember the names of the dishes we ordered, but it was a bowl of soupy noodles and a bowl of dry noodles. They were very tasty. To top that off, the meal was a total of 55,000 dongs ( 180) for both of us. The host was welcoming and friendly. We had a nice conversation with the host. In Vietnam, restaurants give chopsticks to eat noodles. While Badri was good at using them, I wasn t. So, the host of this restaurant helped me in using chopsticks. Although my technique was not perfect and I take a bit of time, I could now eat solely with chopsticks.
The restaurant we went to in Nha Trang. The word Chay in the name means it was a vegan restaurant. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. The restaurant we went to in Nha Trang. The word Chay in the name means it was a vegan restaurant. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Soupy noodles we got at that restaurant. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Soupy noodles we got at that restaurant. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Dry noodles we got at that restaurant. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Dry noodles we got at that restaurant. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Our plan was to take a night bus to Hoi An, and we were hoping to find a bus stand. However, we couldn t find one. Asking around about the pickup location of the Hoi An bus led us to many different locations. Finally, we ended up at a bus booking agency s office where we found out that there were no tickets available for Hoi An. At this point, we gave up on booking the bus and searched for trains instead. As we didn t have a local SIM, we asked the agency to let us connect to their Wi-Fi so that we could look for trains. They were kind enough to let us do that. It also seemed like they were going to close the office in like 10 minutes. Unfortunately, all the sleeper berths were booked from Nha Trang till Hoi An on the next train with only seating berths being available. It takes around 10 hours, so I wasn t comfortable traveling on seating berths. Here I came up with the idea to look for sleeper berths from an intermediate stop. Fortunately, there were sleeper berths available from the next stop, Ninh H a. Therefore, we booked a seating berth from Nha Trang to Ninh H a and a sleeper berth from Ninh H a to Tr Ki u (the nearest railway station from Hoi An). The train name was SE6, and it was a total of 500,000 dongs per person ( 1600 per person). So, we went to the Nha Trang railway station and boarded the train. We had to spend 40 minutes seated for the train to reach the next stop before we could go to our sleeper berths. Badri had some friendly co-passengers on that trip who gave him Saigon beer and some crispy papad-like thing. They offered me as well, but I thought it was non-veg, so I declined it.

Hoi An On the morning of 17th December 2024, we got down at the Tr Ki u station at around 09:30. Our hostel was in Hoi An, which was around 22 km from the station. There was no public transport to get there. Instead, there was a taxi driver at the train platform. We told him the name of our hostel, and he quoted 270,000 dongs (around 850). We said it was too expensive for us, so he agreed to bargain at 250,000 dongs. At this point, we told him that we could give him no more than 200,000 dongs, but he didn t agree. Badri tried a trick. He asked the driver to show us prices in the Grab app (a popular taxi booking app in Southeast Asia). Unfortunately, the Grab app showed 258,000 dongs, which was more than the fare the driver agreed to. So we walked away as if we had so many options (we didn t!) to reach the hostel. We got out of the station and stopped at a small shop outside to have some coffee. As is customary in Vietnam, we got a complimentary green tea here as well.
This was the place we had our coffee in Tra Kieu. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. This was the place we had our coffee in Tra Kieu. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
That taxi driver also joined us and sat in that shop. He started talking with the locals in the shop in the local language. The taxi driver was insistent on taking us to Hoi An for 250,000 dongs. At this point, Badri told the taxi driver (by the use of translation software) that we usually use public transport during our trips, and we aren t used to paying high prices to get around. So, he can drop us somewhere in Hoi An for 200,000 dongs as we don t mind walking a bit to reach our hotel. After reading this, the taxi driver agreed to take us to our hostel for 200,000 dongs ( 660). He also had me take a picture with Badri after this. I think such a bargain tactic would not work in India.
Photo of Badri with taxi driver. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Photo of Badri with taxi driver. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
The nice thing we noticed in Vietnam is, once bargaining is done and the deal is settled, people don t try to bargain more or keep on talking about the subject. Before the deal, the driver was being somewhat insistent and argumentative, but after the deal was done, it was as if no argument had happened at all.
A picture of Tra Kieu area near the train station we got down at. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. A picture of Tra Kieu area near the train station we got down at. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
We were treated to some beautiful scenery on the way to our hostel. Soon we reached our place and completed all the formalities for checking-in. During the time our room was being prepared for check-in, we had an egg sandwich with coffee in the hotel. I found the egg sandwich very tasty. The bread looked like the French baguette. The hostel was 240 per night for each of us. The name of the hostel was Bana Spa. We liked staying here and we can recommend it if you find yourself there. It is operated by a family.
Our breakfast in Hoi An. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Our breakfast in Hoi An. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
A photo of the hostel we stayed in Hoi An. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. A photo of the hostel we stayed in Hoi An. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
We also rented a bicycle for each of us 25,000 dongs per day ( 80) and explored the old town during the evening. Hoi An is popular for Vietnamese silk. Tourists come here to buy fabric and get it done by the tailor. The buildings here looked old, and they were painted in yellow with a gabled roof.
Typical yellow house with gabled roof in Hoi An old town. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Typical yellow house with gabled roof in Hoi An old town. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Here, I also had egg coffee for the first time, and I liked it. Egg coffee is a delicacy of Hanoi, but you can get it in other parts of Vietnam. If you find yourself in Vietnam, then I recommend you try egg coffee. We also bought some cool T-shirts and other souvenirs, such as a Vietnamese hat, from here.
Egg coffee I had in Hoi An. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Egg coffee I had in Hoi An. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Hue The next day the 18th of December 2024 we went to Hue by bus. As we could not take a bus on our own in Nha Trang, we asked the hostel to book it for us this time. We booked it a day before, and they told us to be ready by 07:00 in the morning. At 07:00, a minibus arrived, which took us to a bus agency s office. There we waited for a few minutes and got into the bus to Hue. The bus had sleeper seats, so I took the opportunity to catch some sleep. The ride was comfortable, so I am assuming the roads were good. In a couple of hours, we reached Hue. Again, we went to Highlands Coffee to have some coffee, charge our phones, and use the internet, not to mention using the bathrooms. During the afternoon, we went to a local restaurant named Qu n Chay Thanh Li u. It was a vegan restaurant (remember the thing I mentioned earlier about Chay being in the name?). On the way, we had a steamed dumpling shaped like a momo called banh bao from a street vendor. It wasn t very good, but I found it worthwhile.
Bahn Bao in Hue. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Bahn Bao in Hue. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
At the restaurant, we ordered a hot pot. First, they brought noodles and a gas stove. Then came the stock and our gas stove was turned on. The stock was kept simmering on the stove. Then, we had it bit by bit with the noodles. A big hot pot at this place costs 50,000 dongs ( 170). Then we had b nh cu n. These were steamed rolls made of rice flour for 10,000 dongs ( 33).
Hot Pot. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Hot Pot. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Added soup to the noodles. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Added soup to the noodles. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Steamed rolls made of rice flour. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Steamed rolls made of rice flour. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Restaurants in Vietnam usually add photos of the meals in their menu or write a description in English. So, even though the dish names were Vietnamese, we had no problems in ordering food there. In addition, all the places we went to provided free Wi-Fi. They either mention the Wi-Fi password on the bill, on the menu or paste it on the wall. This made our trip smoother without getting a local SIM.
Menu from a restaurant in Ho Chi Minh City with detailed description of the food. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Menu from a restaurant in Ho Chi Minh City with detailed description of the food. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Then we slowly walked towards the railway station, as we had a night train to Hanoi. We had egg coffee in a cafe. Near the railway station, we had a b nh m (egg sandwich). As for sightseeing, we had plans to visit a couple of places in Hue, but we ended up spending all our time inside sheltered spaces due to heavy rain. We had booked the train SE20 for Hanoi, which had a departure time of 20:41 from Hue. This one was 948,000 dongs ( 3100) for myself and 870,000 dongs ( 2900) for Badri. My ticket was pricier than Badri s because I got a lower berth. Our train was late by half an hour, so we waited in the common area of the station. After the train arrived, we got inside and took our seats. The cabin had four berths two upper and two lower, similar to India s First AC class. The ticket inspector came to us and offered us the whole cabin (two additional berths) for 300,000 dongs ( 1,000), which we declined. However, this hinted at the other two seats not being reserved. Eventually, we had the whole cabin to ourselves, as nobody else showed up for the other two berths. It was a 14-hour journey, and I got a good sleep.
Our berths in the train. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Our berths in the train. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Hanoi On the morning of the 19th of December 2024, we reached Vietnam s capital, Hanoi. We had booked a private hotel room for 800. It was 1 km from the Hanoi Airport. However, it was pretty far from the railway station. So, we roamed around in the city and went to the hotel in the evening. First, we walked to a place and had egg coffee with egg sandwiches. Then we went to Hanoi Train Street, which was walking distance from the train station. After clicking some pictures at the train street, we went to a museum nearby. Upon reaching there, we found out that it was closed.
Egg coffee in Hanoi. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Egg coffee in Hanoi. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Hanoi train street is a tourist attraction in Hanoi. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Hanoi train street is a tourist attraction in Hanoi. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Then we went shopping for jackets, as Hanoi was cold compared to other parts of Vietnam we had been to, and since many of them are manufactured in Vietnam, we thought they would be cheaper. I liked some jackets, but they were not my size. Eventually, we didn t buy anything at the clothes shop. In the evening, I bought a Vietnamese-styled phin coffee filter and coffee powder from Highlands Coffee. We spent a lot of time in their cafes, so it made sense to buy some souvenirs from there. Badri bought a few coffee filters for his family at Trung Nguyen, where I also bought another filter. We had dinner at a local place where we had pho and banh it. Bahn it was served packed in banana leaves and it was made of sticky rice.
A picture of pho we had in Hanoi. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. A picture of pho we had in Hanoi. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Bahn it is served packed in banana leaves. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Bahn it is served packed in banana leaves. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Bahn it. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0. Bahn it. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Next, we went to Hanoi railway station to catch a bus to the airport since our hotel was 1 km from the airport. The locals there helped us take the bus. It took like an hour to get to the airport. We saw on OpenStreetMap that we can take a bus from there to the hotel, but we could not find it. So we walked to our hotel instead. It was a decent hotel room for 800 for a night. We went outside to explore the area and had egg sandwiches and egg coffee at a local place. Again, we were given a complimentary green tea. We went to this place like three times. We had practically become regulars by the time we left. The next day 20th of December 2024 we took a bus to the airport and boarded our flight to Delhi. Credits: Thanks Badri, Kishy and Richard for proofreading.

C.J. Collier: The WWW::Mechanize::Chrome Saga: A Comprehensive Narrative of PR #104

The
WWW::Mechanize::Chrome Saga: A Comprehensive Narrative of PR #104 This document synthesizes the extensive work performed from March
13th to March 20th, 2026, to harden, stabilize, and refactor the
WWW::Mechanize::Chrome library and its test suite. This
effort involved deep dives into asynchronous programming,
platform-specific bug hunting, and strategic architectural
decisions.

Part I:
The Quest for Cross-Platform Stability (March 13 16) The initial phase of work focused on achieving a green test suite
across a variety of Linux distributions and preparing for a new release.
This involved significant hardening of the library to account for
different browser versions, OS-level security restrictions, and
filesystem differences.

Key Milestones &
Engineering Decisions:
  • Fedora & RHEL-family Success: A major effort
    was undertaken to achieve a 100% pass rate on modern Fedora 43 and
    CentOS Stream 10. This required several key engineering decisions to
    handle modern browser behavior:
    • Decision: Implement Asynchronous DOM Serialization
      Fallback. Synchronous fallbacks in an async context are
      dangerous. To prevent Resource was not cached errors during
      saveResources, we implemented a fully asynchronous fallback
      in _saveResourceTree. By chaining
      _cached_document with DOM.getOuterHTML
      messages, we can reconstruct document content without blocking the event
      loop, even if Chromium has evicted the resource from its cache. This
      also proved resilient against Fedora s security policies, which often
      block file:// access.
    • Decision: Truncate Filenames for Cross-Platform
      Safety. To avoid File name too long errors,
      especially on Windows where the MAX_PATH limit is 260
      characters, filenameFromUrl was hardened. The filename
      truncation was reduced to a more conservative 150
      characters, leaving ample headroom for deeply nested CI
      temporary directories. Logic was also added to preserve file extensions
      during truncation and to sanitize backslashes from URI paths.
    • Decision: Expand Browser Discovery Paths. To
      support RHEL-based systems out-of-the-box, the
      default_executable_names was expanded to include
      headless_shell and search paths were updated to include
      /usr/lib64/chromium-browser/.
    • Decision: Mitigate Race Conditions with Stabilization Waits
      and Resilient Fetching. On fast systems,
      DOM.documentUpdated events could invalidate
      nodeIds immediately after navigation, causing XPath queries
      to fail with Could not find node with given id . A small stabilization
      sleep(0.25s) was added after page loads to ensure the DOM
      is settled. Furthermore, the asynchronous DOM fetching loop was hardened
      to gracefully handle these errors by catching protocol errors and
      returning an empty string for any node that was invalidated during
      serialization, ensuring the overall process could complete.
  • Windows Hardening:
    • Decision: Adopt Platform-Aware Watchdogs. The test
      suite s reliance on ualarm was a blocker for Windows, where
      it is not implemented. The t::helper::set_watchdog function
      was refactored to use standard alarm() (seconds) on Windows
      and ualarm (microseconds) on Unix-like systems, enabling
      consistent test-level timeout enforcement.
  • Version 0.77 Release:
    • Decision: Adopt SOP for Version Synchronization.
      The project maintains duplicate version strings across 24+ files. A
      Standard Operating Procedure was adopted to use a batch-replacement tool
      to update all sub-modules in lib/ and to always run
      make clean and perl Makefile.PL to ensure
      META.json and META.yml reflect the new
      version. After achieving stability on Linux, the project version was
      bumped to 0.77.
  • Infrastructure & Strategic Work:
    • The ad2 Windows Server 2025 instance was restored and
      optimized, with Active Directory demoted and disk I/O performance
      improved.
    • A strategic proposal for the Heterogeneous Directory
      Replication Protocol (HDRP) was drafted and published.

Part II: The
Great Async Refactor (March 17 18) Despite success on Linux, tests on the slow ad2 Windows
host were still plagued by intermittent, indefinite hangs. This
triggered a fundamental architectural shift to move the library s core
from a mix of synchronous and asynchronous code to a fully non-blocking
internal API.

Key Milestones &
Engineering Decisions:
  • Decision: Expose a _future API.
    Instead of hardcoding timeouts in the library, the core strategy was to
    refactor all blocking methods (xpath, field,
    get, etc.) into thin wrappers around new non-blocking
    ..._future counterparts. This moved timeout management to
    the test harness, allowing for flexible and explicit handling of
    stalls.
    # Example library implementation
    sub xpath($self, $query, %options)  
        return $self->xpath_future($query, %options)->get;
     
    
    sub xpath_future($self, $query, %options)  
        # Async implementation using $self->target->send_message(...)
     
  • Decision: Centralize Test Hardening in a Helper.
    A dedicated test library, t/lib/t/helper.pm, was created to
    contain all stabilization logic. Safe wrappers (safe_get,
    safe_xpath) were implemented there, using
    Future->wait_any to race asynchronous operations against
    a timeout, preventing tests from hanging.
    # Example test helper implementation
    sub safe_xpath  
        my ($mech, $query, %options) = @_;
        my $timeout = delete $options timeout    5;
        my $call_f = $mech->xpath_future($query, %options);
        my $timeout_f = $mech->sleep_future($timeout)->then(sub   Future->fail("Timeout")  );
        return Future->wait_any($call_f, $timeout_f)->get;
     
  • Decision: Refactor Node Attribute Cache.
    Investigations into flaky checkbox tests (t/50-tick.t)
    revealed that WWW::Mechanize::Chrome::Node was storing
    attributes as a flat list ([key, val, key, val]), which was
    inefficient for lookups and individual updates. The cache was refactored
    to definitively use a HashRef, providing O(1) lookups
    and enabling atomic dual-updates where both the browser property (via
    JS) and the internal library attribute are synchronized
    simultaneously.
  • Decision: Implement Self-Cancelling Socket
    Watchdog. On Windows, traditional watchdog processes often
    failed to detect parent termination, leading to 60-second hangs after
    successful tests. We implemented a new socket-based watchdog in
    t::helper that listens on an ephemeral port; the background
    process terminates immediately when the parent socket closes,
    eliminating these cumulative delays.
  • Decision: Deep Recursive Refactoring & Form
    Selection. To make the API truly non-blocking, the entire
    internal call stack had to be refactored. For example, making
    get_set_value_future non-blocking required first making its
    dependency, _field_by_name, asynchronous. This culminated
    in refactoring the entire form selection API (form_name,
    form_id, etc.) to use the new asynchronous
    _future lookups, which was a key step in mitigating the
    Windows deadlocks.
  • Decision: Fix Critical Regressions & Memory
    Cycles.
    • Evaluation Normalization: Implemented a
      _process_eval_result helper to centralize the parsing of
      results from Runtime.evaluate. This ensures consistent
      handling of return values and exceptions between synchronous
      (eval_in_page) and asynchronous (eval_future)
      calls.
    • Memory Cycle Mitigation: A significant memory
      leak was discovered where closures attached to CDP event futures (like
      for asynchronous body retrieval) would capture strong references to
      $self and the $response object, creating a
      circular reference. The established rule is to now always use
      Scalar::Util::weaken on both $self and any
      other relevant objects before they are used inside a
      ->then block that is stored on an object.
    • Context Propagation (wantarray): A
      major regression was discovered where Perl s wantarray
      context, which distinguishes between scalar and list context, was lost
      inside asynchronous Future->then blocks. This caused
      methods like xpath to return incorrect results (e.g., a
      count instead of a list of nodes). The solution was to adopt the Async
      Context Pattern : capture wantarray in the synchronous
      wrapper, pass it as an option to the _future method, and
      then use that captured value inside the future s final resolution
      block.
      # Synchronous Wrapper
      sub xpath($self, $query, %options)  
          $options  wantarray   = wantarray; # 1. Capture
          return $self->xpath_future($query, %options)->get; # 2. Pass
       
      
      # Asynchronous Implementation
      sub xpath_future($self, $query, %options)  
          my $wantarray = delete $options  wantarray  ; # 3. Retrieve
          # ... async logic ...
          return $doc->then(sub  
              if ($wantarray)   # 4. Respect
                  return Future->done(@results);
                else  
                  return Future->done($results[0]);
               
           );
       
    • Asynchronous Body Retrieval & Robust Content
      Fallbacks: Fixed a bug where decoded_content()
      would return empty strings by ensuring it awaited a
      __body_future. This was implemented by storing the
      retrieval future directly on the response object
      ($response-> __body_future ). To make this more robust,
      a tiered strategy was implemented: first try to get the content from the
      network response, but if that fails (e.g., for about:blank
      or due to cache eviction), fall back to a JavaScript
      XMLSerializer to get the live DOM content.
    • Signature Hardening: Fixed Too few arguments
      errors when using modern Perl signatures with
      Future->then. Callbacks were updated to use optional
      parameters (sub($result = undef) ... ) to gracefully
      handle futures that resolve with no value.
    • XHTML Split-Brain Bug: Resolved a
      long-standing Chromium bug (40130141) where content provided via
      setDocumentContent is parsed differently than content
      loaded from a URL. A workaround was implemented: for XHTML documents,
      WMC now uses a JavaScript-based XPath evaluation
      (document.evaluate) against the live DOM, bypassing the
      broken CDP search mechanism.

Derived Architectural Rules
& SOPs:
  • Rule: Always provide _future variants.
    Every library method that interacts with the browser via CDP must have a
    non-blocking asynchronous counterpart.
  • Rule: Centralize stabilization in the test layer.
    All timeout and retry logic should reside in the test harness
    (t/lib/t/helper.pm), not in the core library.
  • Rule: Explicitly propagate wantarray
    context. Synchronous wrappers must capture the caller s context
    and pass it down the Future chain to ensure correct
    scalar/list behavior.
  • Rule: The entire call chain must be asynchronous.
    To enable non-blocking timeouts, even a single hidden blocking call in
    an otherwise asynchronous method will cause a stall.
  • SOP: Reduce Library Noise. Diagnostic messages
    (warn, note, diag) should be
    removed from library code before commits. All such messages should be
    converted to use the internal $self->log('debug', ...)
    mechanism, ensuring a clean TAP output for CI systems.

Part III: The
MutationObserver Saga (March 19) With most of the library refactored to be asynchronous, one stubborn
test, t/65-is_visible.t, continued to fail with timeouts.
This led to an ambitious, but ultimately unsuccessful, attempt to
replace the wait_until_visible polling logic with a more
modern MutationObserver.

Key Milestones & Challenges:
  • The Theory: The goal was to replace an inefficient
    repeat sleep loop with an event-driven
    MutationObserver in JavaScript that would notify Perl
    immediately when an element s visibility changed.
  • Implementation & Cascade Failure: The
    implementation proved incredibly difficult and introduced a series of
    new, hard-to-diagnose bugs:
    1. An incorrect function signature for
      callFunctionOn_future.
    2. A critical unit mismatch, passing seconds from Perl to JavaScript s
      setTimeout, which expected milliseconds.
    3. A fundamental hang where the MutationObserver s
      JavaScript Promise would never resolve, even after the
      underlying DOM element changed.
  • Debugging Maze: Multiple attempts to fix the
    checkVisibility JavaScript logic inside the observer
    callback, including making it more robust by adding DOM tree traversal
    and extensive console.log tracing, failed to resolve the
    hang. This highlighted the opacity and difficulty of debugging complex,
    cross-language asynchronous interactions, especially when dealing with
    low-level browser APIs.

Procedural Learning:
Granular Edits The effort was plagued by procedural missteps in using automated
file-editing tools. Initial attempts to replace large code blocks in a
single operation led to accidental code loss and match failures.
  • Decision: Adopt Delete, then Add Workflow.
    Following forceful user correction, a new SOP was established for all
    future modifications:
    1. Isolate: Break the file into small, manageable
      chunks (e.g., 250 lines).
    2. Delete: Perform a delete operation by replacing
      the old code block with an empty string.
    3. Add: Perform an add operation by inserting the
      new code into the empty space.
    4. Verify: Verifying each atomic step before
      proceeding. This granular process, while slower, ensured surgical
      precision and regained technical control over the large
      Chrome.pm module.
The consistent failure of the MutationObserver approach
eventually led to the decision to abandon it in favor of stabilizing the
original, more transparent implementation.

Part IV:
Reversion and Final Stabilization (March 20) After exhausting all reasonable attempts to fix the
MutationObserver, a strategic decision was made to revert
to the simpler, more transparent polling implementation and fix it
correctly. This proved to be the correct path to a stable solution.

Key Milestones &
Engineering Decisions:
  • Decision: Perform Strategic Reversion. The
    MutationObserver implementation, when integrated via
    callFunctionOn_future with awaitPromise,
    proved fundamentally unstable. Its JavaScript promise would consistently
    fail to resolve, causing indefinite hangs. A decision was made to
    revert all MutationObserver code from
    WWW::Mechanize::Chrome.pm and restore the original
    repeat sleep polling mechanism. A stable,
    understandable solution was prioritized over an elegant but broken
    one.
  • Decision: Correct Timeout Delegation in the
    Harness. The root cause of the original timeout failure was
    identified as a race condition in the t/lib/t/helper.pm
    test harness. The safe_wait_until_* wrappers were
    implementing their own timeout (via wait_any and
    sleep_future) that raced against the underlying polling
    function s internal timeout. This led to intermittent failures on slow
    machines. The helpers were refactored to delegate all timeout
    management to the library s polling functions, ensuring a
    single, authoritative timer controlled the operation.
  • Decision: Optimize Polling Performance. At the
    user s request, the polling interval was reduced from 300ms to
    150ms. This modest performance improvement reduced the
    test suite s wallclock execution time by over a second while maintaining
    stability.
  • Decision: Tune Test Watchdogs. The global watchdog
    timeout was adjusted to 12 seconds, specifically calculated as 1.5x the
    observed real execution time of the optimized test. This provides a
    data-driven safety margin for CI.

Part
V: The Last Bug A Platform-Specific Memory Leak (March 20) With all other tests passing, a single memory leak failure in
t/78-memleak.t persisted, but only on the Windows
ad2 environment. This required a different approach than
the timeout fixes.

Key Milestones:
  • The Bug: A strong reference cycle involving the
    on_dialog event listener was not being broken on Windows,
    despite multiple attempts to fix it. Fixes that worked on Linux (such as
    calling on_dialog(undef) in DESTROY) were not
    sufficient on the Windows host.
  • The Diagnosis: The issue was determined to be a
    deep, platform-specific interaction between Perl s garbage collector,
    the IO::Async event loop implementation on Windows, and the
    Test::Memory::Cycle module. The cycle report was identical
    on both platforms, but the cleanup behavior was different.
  • Failed Attempts: A series of increasingly
    aggressive fixes were attempted to break the cycle, including:
    1. Moving the on_dialog(undef) call from
      close() to DESTROY().
    2. Explicitly deleteing the listener and callback
      properties from the object hash in DESTROY.
    3. Swapping between $self->remove_listener and
      $self->target->unlisten in a mistaken attempt to find
      the correct un-registration method.
  • Pragmatic Solution: After exhausting all reasonable
    code-level fixes without a resolution on Windows, the user opted to mark
    the failing test as a known issue for that specific platform.
  • Final Fix: The single failing test in
    t/78-memleak.t was wrapped in a conditional
    TODO block that only executes on Windows
    (if ($^O =~ /MSWin32/i)), formally acknowledging the bug
    without blocking the build. This allows the test suite to pass in CI
    environments while flagging the issue for future, deeper
    investigation.

Part VI: CI Hardening (March
20) A final failure in the GitHub Actions CI environment revealed one
last configuration flaw.

Key Milestones:
  • The Bug: The CI was running
    prove --nocount --jobs 3 -I local/ -bl xt t directly. This
    command was missing the crucial -It/lib include path, which
    is necessary for test files to locate the t::helper module.
    This resulted in nearly all tests failing with
    Can't locate t/helper.pm in @INC.
  • The Investigation: An analysis of
    Makefile.PL revealed a custom MY::test block
    specifically designed to inject the -It/lib flag into the
    make test command. This confirmed that
    make test is the correct, canonical way to run the test
    suite for this project.
  • The Fix: The
    .github/workflows/linux.yml file was modified to replace
    the direct prove call with make test in the
    Run Tests step. This ensures the CI environment runs the
    tests in the exact same way as a local developer, with all necessary
    include paths correctly configured by the project s build system.

Final Outcome After this long and arduous journey, the
WWW::Mechanize::Chrome test suite is now stable and
passing on all targeted platforms, with known
platform-specific issues clearly documented in the code. The project is
in a vastly more robust and reliable state.

20 March 2026

Dirk Eddelbuettel: RcppSpdlog 0.0.28 on CRAN: Micro-Maintenance

Version 0.0.28 of RcppSpdlog arrived on CRAN today, has been uploaded to Debian and built for r2u. The (nice) documentation site has been refreshed too. RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovich. You can learn more at the nice package documention site. This release contains a rebuild RcppExports.cpp to aid Rcpp in the transition towards Rcpp::stop() and away from Rf_error() in its user packages. No othe The NEWS entry for this release follows.

Changes in RcppSpdlog version 0.0.28 (2026-03-19)
  • Regenerate RcppExports.cpp to switch to (Rf_error) aiding in Rcpp transition to Rcpp::stop()

Courtesy of my CRANberries, there is also a diffstat report detailing changes. More detailed information is on the RcppSpdlog page, or the package documention site.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Reproducible Builds (diffoscope): diffoscope 315 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 315. This version includes the following changes:
[ Jelle van der Waa ]
* Adjust PGP file detection regex.
You find out more by visiting the project homepage.

19 March 2026

Otto Kek l inen: Automated security validation: How 7,000+ tests shaped MariaDB's new AppArmor profile

Featured image of post Automated security validation: How 7,000+ tests shaped MariaDB's new AppArmor profileLinux kernel security modules provide a good additional layer of security around individual programs by restricting what they are allowed to do, and at best block and detect zero-day security vulnerabilities as soon as anyone tries to exploit them, long before they are widely known and reported. However, the challenge is how to create these security profiles without accidentally also blocking legitimate actions. For MariaDB in Debian and Ubuntu, a new AppArmor profile was recently created by leveraging the extensive test suite with 7000+ tests, giving good confidence that AppArmor is unlikely to yield false positive alerts with it. AppArmor is a Mandatory Access Control (MAC) system, meaning that each process controlled by AppArmor has a sort of an allowlist called profile that defines all capabilities and file paths a program can access. If a program tries to do something not covered by the rules in its AppArmor profile, the action will be denied on the Linux kernel level and a warning logged in the system journal. This additional security layer is valuable because even if a malicious user found a security vulnerability some day in the future, the AppArmor profile severely restricts the ability to exploit it and gain access to the operating system. AppArmor was originally developed by Novell for use in SUSE Linux, but nowadays the main driver is Canonical and AppArmor is extensively used in Ubuntu and Debian, and many of their derivatives (e.g. Linux Mint, Pop!_OS, Zorin OS) and in Arch. AppArmor s benefit compared to the main alternative SELinux (used mainly in the RedHat/Fedora ecosystem) is that AppArmor is easier to manage. AppArmor continues to be actively developed, with new major version 5.0 expected to arrive soon. I also have some personal history contributing some notification handler scripts in Python and I also created the website that AppArmor.net still runs.

Regular review of denials in the system log required Any system administrator using Debian/Ubuntu needs to know how to check for AppArmor denials. The point of using AppArmor is kind of moot if nobody is checking the denials. When AppArmor blocks an action, it logs the event to the system audit or kernel logs. Understanding these logs is crucial for troubleshooting custom configurations or identifying potential security incidents. To view recent denials, check /var/log/audit/audit.log or run journalctl -ke --grep=apparmor. A typical denial entry for MariaDB will look like this (split across multiple lines for legibility):
msg=audit(1700000000.123:456): apparmor="DENIED" operation="open"
profile="/usr/sbin/mariadbd" name="/custom/data/path/test.ibd" pid=1234
comm="mariadbd" requested_mask="r" denied_mask="r" fsuid=1000 ouid=0
How to interpret this output:
  • msg=audit( ): The audit timestamp and event serial number.
  • apparmor= DENIED : Indicates AppArmor blocked the action.
  • operation: The action being attempted (e.g., open, mknod, file_mmap, file_perm).
  • profile: The specific AppArmor profile that triggered the denial (in this case the /usr/sbin/mariadbd profile).
  • name: The file path or resource that was blocked. In the example above, a custom data path was denied access because it wasn t defined in the profile s allowed abstractions.
  • comm: The command name that triggered the denial (here mariadbd).
  • requested_mask / denied_mask: Shows the permissions requested (e.g., r for read, w for write).
  • pid: The process ID.
  • fsuid: The user ID of the process attempting the action.
  • ouid: The owner user ID of the target file.
If an action seems legit and should not be denied, the sysadmin needs to update the existing rules at /etc/apparmor.d/ or drop a local customization file in at /etc/apparmor.d/local/. If the denied action looks malicious, the sysadmin should start a security investigation and if needed report a suspected zero-day vulnerability to the upstream software vendor (e.g. Ubuntu customers to Canonical, or MariaDB customers to MariaDB).

AppArmor in MariaDB - not a novel thing, and not easy to implement well Based on old bug reports, there was an AppArmor profile already back in 2011, but it was removed in MariaDB 5.1.56 due to backlash from users running into various issues. A new profile was created in 2015, but kept opt-in only due to the risk of side effects. It likely had very few users and saw minimal maintenance, getting only a handful of updates in the past 10 years. The primary challenge in using mandatory access control systems with MariaDB lies in the sheer breadth of MariaDB s operational footprint with diverse storage engines and plugins. Also the code base in MariaDB assumes that system calls to Linux always work which they do under normal circumstances and do not handle errors well if AppArmor suddenly denies a system call. MariaDB is also a large and complex piece of software to run and operate, and it can be very challenging for system administrators to root-cause that a misbehavior in their system was due to AppArmor blocking a single syscall. Ironically, AppArmor is most beneficial exactly due to the same reasons for MariaDB. The larger and more complex a software is, the larger are the odds of a security vulnerability arising between the various components. And AppArmor profile helps reduce this complexity down to a single access list. Over the years there has been users requesting to get the AppArmor profile back, such as Debian Bug#875890 since 2017. The need was raised recently again by the Ubuntu security team during the MariaDB Ubuntu main inclusion review in 2025, which prompted a renewed effort by Debian/Ubuntu developers, mainly myself and Aquila Macedo, with upstream MariaDB assistance from Daniel Black.

A fresh approach: leverage the MariaDB test suite for automated testing and the open source community for reviews The key to creating a robust AppArmor profile is the ability to know in detail what is expected and normal behavior of the system. One could in theory read all of the source code in MariaDB, but with over two million lines, it is of course not feasible in practice. However, MariaDB does have a very extensive 7000+ test suite, and running it should trigger most code paths in MariaDB. Utilizing the test suite was key in creating the new AppArmor profile for MariaDB: we installed MariaDB on a Ubuntu system, enabled AppArmor in complain mode and iterated on the allowlist by running the full mariadb-test-run with all MariaDB plugins and features enabled until we had a comprehensive yet clean list of rules. To be extra diligent, we also reworked the autopkgtest for MariaDB in Debian and Ubuntu CI systems to run with the AppArmor profile enabled and to print all AppArmor notices at the end of the run, making it easy to detect now and in the future if the MariaDB test suite triggers any AppArmor denials. If any test fails, the release would not get promoted further, protecting users from regressions. While developing and triggering manual test runs we used the maximal achievable test suite with 7177 tests. The test is however so extensive it takes over two hours to run, and it also has some brittle tests, so the standard test run in Debian and Ubuntu autopkgtest is limited just to MariaDB s main suite with about 1000 tests. Having some tests fail while testing the AppArmor profile was not a problem, because we didn t need all the tests to pass we merely needed them to run as many code paths as possible to see if they run any system calls not accounted for in the AppArmor profile. Note that extending the profile was not just mechanical copying of log messages to the profile. For example, even though a couple of tests involve running the dash shell, we decided to not allow it, as it opens too much of a path for a potential exploit to access the operating system. The result of this effort is a modernized, robust profile that is now production-ready. Those interested in the exact technical details can read the Debian Bug#1130272 and the Merge Request discussions at salsa.debian.org, which hosts the Debian packaging source code.

Now available in Debian unstable, soon Ubuntu feedback welcome! Even though the file is just 200 lines long, the work to craft it spanned several weeks. To minimize risk we also did a gradual rollout by releasing the first new profile version in complain mode, so AppArmor only logs would-be-denials without blocking anything. The AppArmor profile was switched to enforce mode only in the very latest MariaDB revision 1:11.8.6-4 in Debian, and a NEWS item issued to help increase user awareness of this change. It is also slated for the upcoming Ubuntu 26.04 Resolute Raccoon release next month, providing out-of-the-box hardening for the wider ecosystem. While automated testing is extensive, it cannot simulate everything. Most notably various complicated replication topologies and all Galera setups are likely not covered. Thus, I am calling on the community to deploy this profile and monitor for any audit denials in the kernel logs. If you encounter unexpected behavior or legitimate denials, please submit a bug report via the Debian Bug Tracking System. To ensure you are running the latest MariaDB version, run apt install --update --yes mariadb-server. To view the latest profile rules, run cat /etc/apparmor.d/mariadbd and to see if it is enforced review the output of aa-status. To quickly check if there were any AppArmor denials, simply run journalctl -k grep -i apparmor grep -i mariadb.

Systemd hardening also adopted as security features keep evolving For those interested in MariaDB security hardening, note that also new systemd hardening options were rolled out in Debian/Ubuntu recently. Note that Debian and Ubuntu are mainly volunteer-driven open source developer communities, and if you find this topic interesting and you think you have the necessary skills, feel free to submit your improvement ideas as Merge Requests at salsa.debian.org/mariadb-team. If your improvement suggestions are not Debian/Ubuntu specific, please submit them directly to upstream at GitHub.com/MariaDB.

Next.

Previous.