Search Results: "nma"

13 January 2022

Bits from Debian: New Debian Developers and Maintainers (November and December 2021)

The following contributors got their Debian Developer accounts in the last two months: The following contributors were added as Debian Maintainers in the last two months: Congratulations!

4 January 2022

Jelmer Vernooij: Personal Streaming Audio Server

For a while now, I ve been looking for a good way to stream music from my home music collection on my phone. There are quite a few options for music servers that support streaming. However, Android apps that can stream music from one of those servers tend to be unmaintained, clunky or slow (or more than one of those). It is possible to use something that runs in a web server, but that means no offline caching - which can be quite convenient in spots without connectivity, such as the Underground or other random bits of London with poor cell coverage.
Server Most music servers today support some form of the subsonic API. I ve tried a couple, with mixed results:
  • supysonic; Python. Slow. Ran into some issues with subsonic clients. No real web UI.
  • gonic; Go. Works well & fast enough. Minimal web UI, i.e. no ability to play music from a browser.
  • airsonic; Java. Last in a chain of (abandoned) forks. More effort to get to work, and resource intensive.
Eventually, I ve settled on Navidrome. It s got a couple of things going for it:
  • Good subsonic implementation that worked with all the Android apps I used it with.
  • Great Web UI for use in a browser
I run Navidrome in Kubernetes. It s surprisingly easy to get going. Here s the deployment I m using:
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
apiVersion: apps/v1
kind: Deployment
metadata:
 name: navidrome
spec:
 replicas: 1
 selector:
   matchLabels:
     app: navidrome
 template:
   metadata:
     labels:
       app: navidrome
   spec:
     containers:
       - name: navidrome
         image: deluan/navidrome:latest
         imagePullPolicy: Always
         resources:
           limits:
             cpu: ".5"
             memory: "2Gi"
           requests:
             cpu: "0.1"
             memory: "10M"
         ports:
           - containerPort: 4533
         volumeMounts:
           - name: navidrome-data-volume
             mountPath: /data
           - name: navidrome-music-volume
             mountPath: /music
         env:
           - name: ND_SCANSCHEDULE
             value: 1h
           - name: ND_LOGLEVEL
             value: info
           - name: ND_SESSIONTIMEOUT
             value: 24h
           - name: ND_BASEURL
             value: /navidrome
         livenessProbe:
            httpGet:
              path: /navidrome/app
              port: 4533
            initialDelaySeconds: 30
            periodSeconds: 3
            timeoutSeconds: 90
     volumes:
        - name: navidrome-data-volume
          hostPath:
           path: /srv/navidrome
           type: Directory
        - name: navidrome-music-volume
          hostPath:
            path: /srv/media/music
            type: Directory
---
apiVersion: v1
kind: Service
metadata:
  name: navidrome
spec:
  ports:
    - port: 4533
      name: web
  selector:
    app: navidrome
  type: ClusterIP
At the moment, this deployment is still tied to the machine with my music on it since it relies on hostPath volumes, but I m planning to move that to ceph in the future. I then expose this service on /navidrome on my private domain (here replaced with example.com) using an Ingress:
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
apiVersion: networking.k8s.io/v1
kind: Ingress
metadata:
  name: navidrome
spec:
  ingressClassName: nginx
  rules:
  - host: example.com
    http:
      paths:
      - backend:
          service:
            name: navidrome
            port:
              name: web
        path: /navidrome(/ $)(.*)
        pathType: Prefix
Client On the desktop, I usually just use navidrome s web interface. Clementine s support for subsonic is also okay. sublime-music is meant to be a music player specifically for Subsonic, but I ve not really found it stable enough for day-to-day usage. There are various Android clients for Subsonic, but I ve only really considered the Open Source ones that are hosted on F-Droid. Most of those are abandoned, but D-Sub works pretty well - as does my preferred option, Subtracks.

3 January 2022

Ian Jackson: Debian s approach to Rust - Dependency handling

tl;dr: Faithfully following upstream semver, in Debian package dependencies, is a bad idea. Introduction I have been involved in Debian for a very long time. And I ve been working with Rust for a few years now. Late last year I had cause to try to work on Rust things within Debian. When I did, I found it very difficult. The Debian Rust Team were very helpful. However, the workflow and tooling require very large amounts of manual clerical work - work which it is almost impossible to do correctly since the information required does not exist. I had wanted to package a fairly straightforward program I had written in Rust, partly as a learning exercise. But, unfortunately, after I got stuck in, it looked to me like the effort would be wildly greater than I was prepared for, so I gave up. Since then I ve been thinking about what I learned about how Rust is packaged in Debian. I think I can see how to fix some of the problems. Although I don t want to go charging in and try to tell everyone how to do things, I felt I ought at least to write up my ideas. Hence this blog post, which may become the first of a series. This post is going to be about semver handling. I see problems with other aspects of dependency handling and source code management and traceability as well, and of course if my ideas find favour in principle, there are a lot of details that need to be worked out, including some kind of transition plan. How Debian packages Rust, and build vs runtime dependencies Today I will be discussing almost entirely build-dependencies; Rust doesn t (yet?) support dynamic linking, so built Rust binaries don t have Rusty dependencies. However, things are a bit confusing because even the Debian binary packages for Rust libraries contain pure source code. So for a Rust library package, building the Debian binary package from the Debian source package does not involve running the Rust compiler; it s just file-copying and format conversion. The library s Rust dependencies do not need to be installed on the build machine for this. So I m mostly going to be talking about Depends fields, which are Debian s way of talking about runtime dependencies, even though they are used only at build-time. The way this works is that some ultimate leaf package (which is supposed to produce actual executable code) Build-Depends on the libraries it needs, and those Depends on their under-libraries, so that everything needed is installed. What do dependencies mean and what are they for anyway? In systems where packages declare dependencies on other packages, it generally becomes necessary to support versioned dependencies. In all but the most simple systems, this involves an ordering (or similar) on version numbers and a way for a package A to specify that it depends on certain versions of B. Both Debian and Rust have this. Rust upstream crates have version numbers and can specify their dependencies according to semver. Debian s dependency system can represent that. So it was natural for the designers of the scheme for packaging Rust code in Debian to simply translate the Rust version dependencies to Debian ones. However, while the two dependency schemes seem equivalent in the abstract, their concrete real-world semantics are totally different. These different package management systems have different practices and different meanings for dependencies. (Interestingly, the Python world also has debates about the meaning and proper use of dependency versions.) The epistemological problem Consider some package A which is known to depend on B. In general, it is not trivial to know which versions of B will be satisfactory. I.e., whether a new B, with potentially-breaking changes, will actually break A. Sometimes tooling can be used which calculates this (eg, the Debian shlibdeps system for runtime dependencies) but this is unusual - especially for build-time dependencies. Which versions of B are OK can normally only be discovered by a human consideration of changelogs etc., or by having a computer try particular combinations. Few ecosystems with dependencies, in the Free Software community at least, make an attempt to precisely calculate the versions of B that are actually required to build some A. So it turns out that there are three cases for a particular combination of A and B: it is believed to work; it is known not to work; and: it is not known whether it will work. And, I am not aware of any dependency system that has an explicit machine-readable representation for the unknown state, so that they can say something like A is known to depend on B; versions of B before v1 are known to break; version v2 is known to work . (Sometimes statements like that can be found in human-readable docs.) That leaves two possibilities for the semantics of a dependency A depends B, version(s) V..W: Precise: A will definitely work if B matches V..W, and Optimistic: We have no reason to think B breaks with any of V..W. At first sight the latter does not seem useful, since how would the package manager find a working combination? Taking Debian as an example, which uses optimistic version dependencies, the answer is as follows: The primary information about what package versions to use is not only the dependencies, but mostly in which Debian release is being targeted. (Other systems using optimistic version dependencies could use the date of the build, i.e. use only packages that are current .)
Precise Optimistic
People involved in version management Package developers,
downstream developers/users.
Package developers,
downstream developer/users,
distribution QA and release managers.
Package developers declare versions V and dependency ranges V..W so that It definitely works. A wide range of B can satisfy the declared requirement.
The principal version data used by the package manager Only dependency versions. Contextual, eg, Releases - set(s) of packages available.
Version dependencies are for Selecting working combinations (out of all that ever existed). Sequencing (ordering) of updates; QA.
Expected use pattern by a downstream Downstream can combine any
declared-good combination.
Use a particular release of the whole system. Mixing-and-matching requires additional QA and remedial work.
Downstreams are protected from breakage by Pessimistically updating versions and dependencies whenever anything might go wrong. Whole-release QA.
A substantial deployment will typically contain Multiple versions of many packages. A single version of each package, except where there are actual incompatibilities which are too hard to fix.
Package updates are driven by Top-down:
Depending package updates the declared metadata.
Bottom-up:
Depended-on package is updated in the repository for the work-in-progress release.
So, while Rust and Debian have systems that look superficially similar, they contain fundamentally different kinds of information. Simply representing the Rust versions directly into Debian doesn t work. What is currently done by the Debian Rust Team is to manually patch the dependency specifications, to relax them. This is very labour-intensive, and there is little automation supporting either decisionmaking or actually applying the resulting changes. What to do Desired end goal To update a Rust package in Debian, that many things depend on, one need simply update that package. Debian s sophisticated build and CI infrastructure will try building all the reverse-dependencies against the new version. Packages that actually fail against the new dependency are flagged as suffering from release-critical problems. Debian Rust developers then update those other packages too. If the problems turn out to be too difficult, it is possible to roll back. If a problem with a depending packages is not resolved in a timely fashion, priority is given to updating core packages, and the depending package falls by the wayside (since it is empirically unmaintainable, given available effort). There is no routine manual patching of dependency metadata (or of anything else). Radical proposal Debian should not precisely follow upstream Rust semver dependency information. Instead, Debian should optimistically try the combinations of packages that we want to have. The resulting breakages will be discovered by automated QA; they will have to be fixed by manual intervention of some kind, but usually, simply updating the depending package will be sufficient. This no longer ensures (unlike the upstream Rust scheme) that the result is expected to build and work if the dependencies are satisfied. But as discussed, we don t really need that property in Debian. More important is the new property we gain: that we are able to mix and match versions that we find work in practice, without a great deal of manual effort. Or to put it another way, in Debian we should do as a Rust upstream maintainer does when they do the regular update dependencies for new semvers task: we should update everything, see what breaks, and fix those. (In theory a Rust upstream package maintainer is supposed to do some additional checks or something. But the practices are not standardised and any checks one does almost never reveal anything untoward, so in practice I think many Rust upstreams just update and see what happens. The Rust upstream community has other mechanisms - often, reactive ones - to deal with any problems. Debian should subscribe to those same information sources, eg RustSec.) Nobbling cargo Somehow, when cargo is run to build Rust things against these Debian packages, cargo s dependency system will have to be overridden so that the version of the package that is actually selected by Debian s package manager is used by cargo without complaint. We probably don t want to change the Rust version numbers of Debian Rust library packages, so this should be done by either presenting cargo with an automatically-massaged Cargo.toml where the dependency version restrictions are relaxed, or by using a modified version of cargo which has special option(s) to relax certain dependencies. Handling breakage Rust packages in Debian should already be provided with autopkgtests so that ci.debian.net will detect build breakages. Build breakages will stop the updated dependency from migrating to the work-in-progress release, Debian testing. To resolve this, and allow forward progress, we will usually upload a new version of the dependency containing an appropriate Breaks, and either file an RC bug against the depending package, or update it. This can be done after the upload of the base package. Thus, resolution of breakage due to incompatibilities will be done collaboratively within the Debian archive, rather than ad-hoc locally. And it can be done without blocking. My proposal prioritises the ability to make progress in the core, over stability and in particular over retaining leaf packages. This is not Debian s usual approach but given the Rust ecosystem s practical attitudes to API design, versioning, etc., I think the instability will be manageable. In practice fixing leaf packages is not usually really that hard, but it s still work and the question is what happens if the work doesn t get done. After all we are always a shortage of effort - and we probably still will be, even if we get rid of the makework clerical work of patching dependency versions everywhere (so that usually no work is needed on depending packages). Exceptions to the one-version rule There will have to be some packages that we need to keep multiple versions of. We won t want to update every depending package manually when this happens. Instead, we ll probably want to set a version number split: rdepends which want version <X will get the old one. Details - a sketch I m going to sketch out some of the details of a scheme I think would work. But I haven t thought this through fully. This is still mostly at the handwaving stage. If my ideas find favour, we ll have to do some detailed review and consider a whole bunch of edge cases I m glossing over. The dependency specification consists of two halves: the depending .deb s Depends (or, for a leaf package, Build-Depends) and the base .deb Version and perhaps Breaks and Provides. Even though libraries vastly outnumber leaf packages, we still want to avoid updating leaf Debian source packages simply to bump dependencies. Dependency encoding proposal Compared to the existing scheme, I suggest we implement the dependency relaxation by changing the depended-on package, rather than the depending one. So we retain roughly the existing semver translation for Depends fields. But we drop all local patching of dependency versions. Into every library source package we insert a new Debian-specific metadata file declaring the earliest version that we uploaded. When we translate a library source package to a .deb, the binary package build adds Provides for every previous version. The effect is that when one updates a base package, the usual behaviour is to simply try to use it to satisfy everything that depends on that base package. The Debian CI will report the build or test failures of all the depending packages which the API changes broke. We will have a choice, then: Breakage handling - update broken depending packages individually If there are only a few packages that are broken, for each broken dependency, we add an appropriate Breaks to the base binary package. (The version field in the Breaks should be chosen narrowly, so that it is possible to resolve it without changing the major version of the dependency, eg by making a minor source change.) When can then do one of the following: Breakage handling - declare new incompatible API in Debian If the API changes are widespread and many dependencies are affected, we should represent this by changing the in-Debian-source-package metadata to arrange for fewer Provides lines to be generated - withdrawing the Provides lines for earlier APIs. Hopefully examination of the upstream changelog will show what the main compat break is, and therefore tell us which Provides we still want to retain. This is like declaring Breaks for all the rdepends. We should do it if many rdepends are affected. Then, for each rdependency, we must choose one of the responses in the bullet points above. In practice this will often be a mass bug filing campaign, or large update campaign. Breakage handling - multiple versions Sometimes there will be a big API rewrite in some package, and we can t easily update all of the rdependencies because the upstream ecosystem is fragmented and the work involved in reconciling it all is too substantial. When this happens we will bite the bullet and include multiple versions of the base package in Debian. The old version will become a new source package with a version number in its name. This is analogous to how key C/C++ libraries are handled. Downsides of this scheme The first obvious downside is that assembling some arbitrary set of Debian Rust library packages, that satisfy the dependencies declared by Debian, is no longer necessarily going to work. The combinations that Debian has tested - Debian releases - will work, though. And at least, any breakage will affect only people building Rust code using Debian-supplied libraries. Another less obvious problem is that because there is no such thing as Build-Breaks (in a Debian binary package), the per-package update scheme may result in no way to declare that a particular library update breaks the build of a particular leaf package. In other words, old source packages might no longer build when exposed to newer versions of their build-dependencies, taken from a newer Debian release. This is a thing that already happens in Debian, with source packages in other languages, though. Semver violation I am proposing that Debian should routinely compile Rust packages against dependencies in violation of the declared semver, and ship the results to Debian s millions of users. This sounds quite alarming! But I think it will not in fact lead to shipping bad binaries, for the following reasons: The Rust community strongly values safety (in a broad sense) in its APIs. An API which is merely capable of insecure (or other seriously bad) use is generally considered to be wrong. For example, such situations are regarded as vulnerabilities by the RustSec project, even if there is no suggestion that any actually-broken caller source code exists, let alone that actually-broken compiled code is likely. The Rust community also values alerting programmers to problems. Nontrivial semantic changes to APIs are typically accompanied not merely by a semver bump, but also by changes to names or types, precisely to ensure that broken combinations of code do not compile. Or to look at it another way, in Debian we would simply be doing what many Rust upstream developers routinely do: bump the versions of their dependencies, and throw it at the wall and hope it sticks. We can mitigate the risks the same way a Rust upstream maintainer would: when updating a package we should of course review the upstream changelog for any gotchas. We should look at RustSec and other upstream ecosystem tracking and authorship information. Difficulties for another day As I said, I see some other issues with Rust in Debian. Thanks all for your attention!

comment count unavailable comments

1 January 2022

Utkarsh Gupta: FOSS Activites in December 2021

Here s my (twenty-seventh) monthly but brief update about the activities I ve done in the F/L/OSS world.

Debian
This was my 36th month of actively contributing to Debian. I became a DM in late March 2019 and a DD on Christmas 19! \o/ Just churning through the backlog again this month. Ugh. Anyway, I did the following stuff in Debian:

Uploads and bug fixes:
  • ruby2.7 (2.7.5-1) - New upstream version fixing 3 new CVEs.

Other $things:
  • Mentoring for newcomers.
  • Moderation of -project mailing list.

Ubuntu
This was my 11th month of actively contributing to Ubuntu. Now that I ve joined Canonical to work on Ubuntu full-time, there s a bunch of things I do! \o/ I mostly worked on different things, I guess. I was too lazy to maintain a list of things I worked on so there s no concrete list atm. Maybe I ll get back to this section later or will start to list stuff from next year onward, as I was doing before. :D

Debian (E)LTS
Debian Long Term Support (LTS) is a project to extend the lifetime of all Debian stable releases to (at least) 5 years. Debian LTS is not handled by the Debian security team, but by a separate group of volunteers and companies interested in making it a success. And Debian Extended LTS (ELTS) is its sister project, extending support to the Jessie release (+2 years after LTS support). This was my twenty-seventh month as a Debian LTS and eighteenth month as a Debian ELTS paid contributor.
I was assigned 40.00 hours for LTS and 60.00 hours for ELTS and worked on the following things:
(since I had a 3-week vacation, I wanted to wrap things up that were pending and so I worked for 20h more for LTS, which I ll compensate the next month!)

LTS CVE Fixes and Announcements:

ELTS CVE Fixes and Announcements:
  • Issued ELA 525-2, fixing CVE-2021-43527, for nss.
    For Debian 8 jessie, these problems have been fixed in version 2:3.26-1+debu8u15.
  • Issued ELA 530-1, for systemd.
    For Debian 8 jessie, these problems have been fixed in version 215-17+deb8u14.
  • Issued ELA 531-1, fixing CVE-2021-41817 and CVE-2021-41819, for ruby2.1.
    For Debian 8 jessie, these problems have been fixed in version 2.1.5-2+deb8u13.
  • Issued ELA 533-1, fixing CVE-2018-12020, for python-gnupg.
    For Debian 8 jessie, these problems have been fixed in version 0.3.6-1+deb8u2.
  • Issued ELA 536-1, fixing CVE-2021-43818, for lxml.
    For Debian 8 jessie, these problems have been fixed in version Prior to version 4.6.5, the HTML Cleaner in lxml.html lets certain.
  • Started working on src:samba for CVE-2020-25717 to CVE-2020-25722 and CVE-2021-23192 for jessie and stretch, both.
    The version difference b/w the suites are a bit too much for the patch(es) to be easily backported. I ve talked to Anton to work something out. \o/
  • Found the problem w/ libjdom1-java. Will have to roll the regression upload.
    I ve prepared the patch but needs some testing to be finally rolled out. Same for stretch.

Other (E)LTS Work:
  • Front-desk duty from 29-11 to 05-12 and 20-12 to 26-12 for both LTS and ELTS.
  • Triaged ffmpeg, git, gpac, inetutils, mc, modsecurity-crs, node-object-path, php-pear, systemd-cron, node-tar, ruby2.3, gst-plugins-bad0.10, npm, nltk, request-tracker4, ros-ros-comm, mediawiki, ruby2.1, ckeditor, ntfs-3g, tiff, wordpress, and jsoup, udisks2, libgit2, python3.5, python3.4, and openssh.
  • Mark CVE-2021-38171/ffmpeg as postponed for stretch.
  • Mark CVE-2021-40330/git as no-dsa for stretch and jessie.
  • Mark CVE-2020-19481/gpac as ignored for stretch.
  • Mark CVE-2021-40491/inetutils as no-dsa for stretch.
  • Mark CVE-2021-36370/mc as no-dsa for stretch and jessie.
  • Mark CVE-2021-35368/modsecurity-crs as no-dsa for stretch.
  • Mark CVE-2021-23434/node-object-path as end-of-life for stretch.
  • Mark CVE-2021-32610/php-pear as no-dsa for stretch.
  • Mark CVE-2017-9525/systemd-cron as no-dsa for stretch.
  • Mark CVE-2021-37701/node-tar as end-of-life for stretch.
  • Mark CVE-2021-37712/node-tar as end-of-life in stretch.
  • Mark CVE-2021-39201/wordpress as not-affected for jessie.
  • Mark CVE-2020-19143/tiff as not-affected for stretch and jessie.
  • Mark CVE-2021-38562/request-tracker4 as no-dsa for stretch.
  • Mark CVE-2021-37146/ros-ros-comm as no-dsa for stretch.
  • Mark CVE-2021-28965/ruby2.1 as ignored for jessie.
  • Mark CVE-2021-37714/jsoup as ignored for jessie.
  • Mark CVE-2021-41617/openssh as no-dsa for jessie.
  • Auto EOL ed ardour, nltk, request-tracker4, python-scrapy, webkit2gtk, and linux for jessie.
  • Attended monthly Debian LTS meeting.
  • Answered questions (& discussions) on IRC (#debian-lts and #debian-elts).
  • General and other discussions on LTS private and public mailing list.

Debian LTS Survey I ve spent 5 hours on the LTS survey on the following bits:
  • Went through the old content on the previous survey.
  • Reviewed the new content - still more work to do.
  • Discussed the survey bits in the team meeting.
  • Partly reviewing the questions of the survey.
  • Walking through the instance to find the doability of the tasks discussed in the meeting.
  • Segregating and staging questions. More work to do here.

Until next time.
:wq for today.

7 December 2021

Evgeni Golov: The Mocking will continue, until CI improves

One might think, this blog is exclusively about weird language behavior and yelling at computers Well, welcome to another episode of Jackass! Today's opponent is Ruby, or maybe minitest , or maybe Mocha. I'm not exactly sure, but it was a rather amusing exercise and I like to share my nightmares ;) It all started with the classical "you're using old and unmaintained software, please switch to something new". The first attempt was to switch from the ci_reporter_minitest plugin to the minitest-ci plugin. While the change worked great for Foreman itself, it broke the reporting in Katello - the tests would run but no junit.xml was generated and Jenkins rightfully complained that it got no test results. While investigating what the hell was wrong, we realized that Katello was already using a minitest reporting plugin: minitest-reporters. Loading two different reporting plugins seemed like a good source for problems, so I tried using the same plugin for Foreman too. Guess what? After a bit of massaging (mostly to disable the second minitest-reporters initialization in Katello) reporting of test results from Katello started to work like a charm. But now the Foreman tests started to fail. Not fail to report, fail to actually run. WTH The failure was quite interesting too:
test/unit/parameter_filter_test.rb:5:in  block in <class:ParameterFilterTest>':
  Mocha methods cannot be used outside the context of a test (Mocha::NotInitializedError)
Yes, this is a single test file failing, all others were fine. The failing code doesn't look problematic on first glance:
require 'test_helper'
class ParameterFilterTest < ActiveSupport::TestCase
  let(:klass) do
    mock('Example').tap do  k 
      k.stubs(:name).returns('Example')
    end
  end
  test 'something' do
    something
  end
end
The failing line (5) is mock('Example').tap and for some reason Mocha thinks it's not initialized here. This certainly has something to do with how the various reporting plugins inject themselves, but I really didn't want to debug how to run two reporting plugins in parallel (which, as you remember, didn't expose this behavior). So the only real path forward was to debug what's happening here. Calling the test on its own, with one of the working reporter was the first step:
$ bundle exec rake test TEST=test/unit/parameter_filter_test.rb TESTOPTS=-v
 
#<Mocha::Mock:0x0000557bf1f22e30>#test_0001_permits plugin-added attribute = 0.04 s = .
#<Mocha::Mock:0x0000557bf12cf750>#test_0002_permits plugin-added attributes from blocks = 0.49 s = .
 
Wait, what? #<Mocha::Mock: >? Shouldn't this read more like ParameterFilterTest:: as it happens for every single other test in our test suite? It definitely should! That's actually great, as it tells us that there is really something wrong with the test and the change of the reporting plugin just makes it worse. What comes next is sheer luck. Well, that, and years of experience in yelling at computers. We use let(:klass) to define an object called klass and this object is a Mocha::Mock that we'll use in our tests later. Now klass is a very common term in Ruby when talking about classes and needing to store them mostly because one can't use class which is a keyword. Is something else in the stack using klass and our let is overriding that, making this whole thing explode? It was! The moment we replaced klass with klass1 (silly, I know, but there also was a klass2 in that code, so it did fit), things started to work nicely. I really liked Tomer's comment in the PR: "no idea why, but I am not going to dig into mocha to figure that out." Turns out, I couldn't let (HAH!) the code rest and really wanted to understand what happened there. What I didn't want to do is to debug the whole Foreman test stack, because it is massive. So I started to write a minimal reproducer for the issue. All starts with a Gemfile, as we need a few dependencies:
gem 'rake'
gem 'mocha'
gem 'minitest', '~> 5.1', '< 5.11'
Then a Rakefile:
require 'rake/testtask'
Rake::TestTask.new(:test) do  t 
  t.libs << 'test'
  t.test_files = FileList["test/**/*_test.rb"]
end
task :default => :test
And a test! I took the liberty to replace ActiveSupport::TestCase with Minitest::Test, as the test won't be using any Rails features and I wanted to keep my environment minimal.
require 'minitest/autorun'
require 'minitest/spec'
require 'mocha/minitest'
class ParameterFilterTest < Minitest::Test
  extend Minitest::Spec::DSL
  let(:klass) do
    mock('Example').tap do  k 
      k.stubs(:name).returns('Example')
    end
  end
  def test_lol
    assert klass
  end
end
Well, damn, this passed! Is it Rails after all that breaks stuff? Let's add it to the Gemfile!
$ vim Gemfile
$ bundle install
$ bundle exec rake test TESTOPTS=-v
 
#<Mocha::Mock:0x0000564bbfe17e98>#test_lol = 0.00 s = .
Wait, I didn't change anything and it's already failing?! Fuck! I mean, cool! But the test isn't minimal yet. What can we reduce? let is just a fancy, lazy def, right? So instead of let(:klass) we should be able to write def class and achieve a similar outcome and drop that Minitest::Spec.
require 'minitest/autorun'
require 'mocha/minitest'
class ParameterFilterTest < Minitest::Test
  def klass
    mock
  end
  def test_lol
    assert klass
  end
end
$ bundle exec rake test TESTOPTS=-v
 
/home/evgeni/Devel/minitest-wtf/test/parameter_filter_test.rb:5:in  klass': Mocha methods cannot be used outside the context of a test (Mocha::NotInitializedError)
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/railties-6.1.4.1/lib/rails/test_unit/reporter.rb:68:in  format_line'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/railties-6.1.4.1/lib/rails/test_unit/reporter.rb:15:in  record'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:682:in  block in record'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:681:in  each'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:681:in  record'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:324:in  run_one_method'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:311:in  block (2 levels) in run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:310:in  each'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:310:in  block in run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:350:in  on_signal'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:337:in  with_info_handler'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:309:in  run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:159:in  block in __run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:159:in  map'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:159:in  __run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:136:in  run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:63:in  block in autorun'
rake aborted!
Oh nice, this is even better! Instead of the mangled class name, we now get the very same error the Foreman tests aborted with, plus a nice stack trace! But wait, why is it pointing at railties? We're not loading that! Anyways, lets look at railties-6.1.4.1/lib/rails/test_unit/reporter.rb, line 68
def format_line(result)
  klass = result.respond_to?(:klass) ? result.klass : result.class
  "%s#%s = %.2f s = %s" % [klass, result.name, result.time, result.result_code]
end
Heh, this is touching result.klass, which we just messed up. Nice! But quickly back to railties What if we only add that to the Gemfile, not full blown Rails?
gem 'railties'
gem 'rake'
gem 'mocha'
gem 'minitest', '~> 5.1', '< 5.11'
Yepp, same failure. Also happens with require => false added to the line, so it seems railties somehow injects itself into rake even if nothing is using it?! "Cool"! By the way, why are we still pinning minitest to < 5.11? Oh right, this was the original reason to look into that whole topic. And, uh, it's pointing at klass there already! 4 years ago! So lets remove that boundary and funny enough, now tests are passing again, even if we use klass! Minitest 5.11 changed how Minitest::Test is structured, and seems not to rely on klass at that point anymore. And I guess Rails also changed a bit since the original pin was put in place four years ago. I didn't want to go another rabbit hole, finding out what changed in Rails, but I did try with 5.0 (well, 5.0.7.2) to be precise, and the output with newer (>= 5.11) Minitest was interesting:
$ bundle exec rake test TESTOPTS=-v
 
Minitest::Result#test_lol = 0.00 s = .
It's leaking Minitest::Result as klass now, instead of Mocha::Mock. So probably something along these lines was broken 4 years ago and triggered this pin. What do we learn from that?
  • klass is cursed and shouldn't be used in places where inheritance and tooling might decide to use it for some reason
  • inheritance is cursed - why the heck are implementation details of Minitest leaking inside my tests?!
  • tooling is cursed - why is railties injecting stuff when I didn't ask it to?!
  • dependency pinning is cursed - at least if you pin to avoid an issue and then forget about said issue for four years
  • I like cursed things!

6 December 2021

Paul Tagliamonte: Proxying Ethernet Frames to PACKRAT (Part 5/5)

This post is part of a series called "PACKRAT". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
In the last post, we left off at being able to send and recieve PACKRAT frames to and from devices. Since we can transport IPv4 packets over the network, let s go ahead and see if we can read/write Ethernet frames from a Linux network interface, and on the backend, read and write PACKRAT frames over the air. This has the benifit of continuing to allow Linux userspace tools to work (like cURL, as we ll try!), which means we don t have to do a lot of work to implement higher level protocols or tactics to get a connection established over the link. Given that this post is less RF and more Linuxy, I m going to include more code snippits than in prior posts, and those snippits are closer to runable Go, but still not complete examples. There s also a lot of different ways to do this, I ve just picked the easiest one for me to implement and debug given my existing tooling for you, you may find another approach easier to implement! Again, deviation here is very welcome, and since this segment is the least RF centric post in the series, the pace and tone is going to feel different. If you feel lost here, that s OK. This isn t the most important part of the series, and is mostly here to give a concrete ending to the story arc. Any way you want to finish your own journy is the best way for you to finish it!

Implement Ethernet conversion code This assumes an importable package with a Frame struct, which we can use to convert a Frame to/from Ethernet. Given that the PACKRAT frame has a field that Ethernet doesn t (namely, Callsign), that will need to be explicitly passed in when turning an Ethernet frame into a PACKRAT Frame.
...
// ToPackrat will create a packrat frame from an Ethernet frame.
func ToPackrat(callsign [8]byte, frame *ethernet.Frame) (*packrat.Frame, error)  
var frameType packrat.FrameType
switch frame.EtherType  
case ethernet.EtherTypeIPv4:
frameType = packrat.FrameTypeIPv4
default:
return nil, fmt.Errorf("ethernet: unsupported ethernet type %x", frame.EtherType)
 
return &packrat.Frame 
Destination: frame.Destination,
Source: frame.Source,
Type: frameType,
Callsign: callsign,
Payload: frame.Payload,
 , nil
 
// FromPackrat will create an Ethernet frame from a Packrat frame.
func FromPackrat(frame *packrat.Frame) (*ethernet.Frame, error)  
var etherType ethernet.EtherType
switch frame.Type  
case packrat.FrameTypeRaw:
return nil, fmt.Errorf("ethernet: unsupported packrat type 'raw'")
case packrat.FrameTypeIPv4:
etherType = ethernet.EtherTypeIPv4
default:
return nil, fmt.Errorf("ethernet: unknown packrat type %x", frame.Type)
 
// We lose the Callsign here, which is sad.
 return &ethernet.Frame 
Destination: frame.Destination,
Source: frame.Source,
EtherType: etherType,
Payload: frame.Payload,
 , nil
 
Our helpers, ToPackrat and FromPackrat can now be used to transmorgify PACKRAT into Ethernet, or Ethernet into PACKRAT. Let s put them into use!

Implement a TAP interface On Linux, the networking stack can be exposed to userland using TUN or TAP interfaces. TUN devices allow a userspace program to read and write data at the Layer 3 / IP layer. TAP devices allow a userspace program to read and write data at the Layer 2 Data Link / Ethernet layer. Writing data at Layer 2 is what we want to do, since we re looking to transform our Layer 2 into Ethernet s Layer 2 Frames. Our first job here is to create the actual TAP interface, set the MAC address, and set the IP range to our pre-coordinated IP range.
...
import (
"net"
"github.com/mdlayher/ethernet"
"github.com/songgao/water"
"github.com/vishvananda/netlink"
)
...
config := water.Config DeviceType: water.TAP 
config.Name = "rat0"
iface, err := water.New(config)
...
netIface, err := netlink.LinkByName("rat0")
...
// Pick a range here that works for you!
 //
 // For my local network, I'm using some IPs
 // that AMPR (ampr.org) was nice enough to
 // allocate to me for ham radio use. Thanks,
 // AMPR!
 //
 // Let's just use 10.* here, though.
 //
 ip, cidr, err := net.ParseCIDR("10.0.0.1/24")
...
cidr.IP = ip
err = netlink.AddrAdd(netIface, &netlink.Addr 
IPNet: cidr,
Peer: cidr,
 )
...
// Add all our neighbors to the ARP table
 for _, neighbor := range neighbors  
netlink.NeighAdd(&netlink.Neigh 
LinkIndex: netIface.Attrs().Index,
Type: netlink.FAMILY_V4,
State: netlink.NUD_PERMANENT,
IP: neighbor.IP,
HardwareAddr: neighbor.MAC,
 )
 
// Pick a MAC that is globally unique here, this is
 // just used as an example!
 addr, err := net.ParseMAC("FA:DE:DC:AB:LE:01")
...
netlink.LinkSetHardwareAddr(netIface, addr)
...
err = netlink.LinkSetUp(netIface)
var frame = &ethernet.Frame 
var buf = make([]byte, 1500)
for  
n, err := iface.Read(buf)
...
err = frame.UnmarshalBinary(buf[:n])
...
// process frame here (to come)
  
...
Now that our network stack can resolve an IP to a MAC Address (via ip neigh according to our pre-defined neighbors), and send that IP packet to our daemon, it s now on us to send IPv4 data over the airwaves. Here, we re going to take packets coming in from our TAP interface, and marshal the Ethernet frame into a PACKRAT Frame and transmit it. As with the rest of the RF code, we ll leave that up to the implementer, of course, using what was built during Part 2: Transmitting BPSK symbols and Part 4: Framing data.
...
for  
// continued from above

n, err := iface.Read(buf)
...
err = frame.UnmarshalBinary(buf[:n])
...
switch frame.EtherType  
case 0x0800:
// ipv4 packet
 pack, err := ToPackrat(
// Add my callsign to all Frames, for now
 [8]byte 'K', '3', 'X', 'E', 'C' ,
frame,
)
...
err = transmitPacket(pack)
...
 
 
...
Now that we have transmitting covered, let s go ahead and handle the recieve path here. We re going to listen on frequency using the code built in Part 3: Receiving BPSK symbols and Part 4: Framing data. The Frames we decode from the airwaves are expected to come back from the call packratReader.Next in the code below, and the exact way that works is up to the implementer.
...
for  
// pull the next packrat frame from
 // the symbol stream as we did in the
 // last post
 packet, err := packratReader.Next()
...
// check for CRC errors and drop invalid
 // packets
 err = packet.Check()
...
if bytes.Equal(packet.Source, addr)  
// if we've heard ourself transmitting
 // let's avoid looping back
 continue
 
// create an ethernet frame
 frame, err := FromPackrat(packet)
...
buf, err := frame.MarshalBinary()
...
// and inject it into the tap
 err = iface.Write(buf)
...
 
...
Phew. Right. Now we should be able to listen for PACKRAT frames on the air and inject them into our TAP interface.

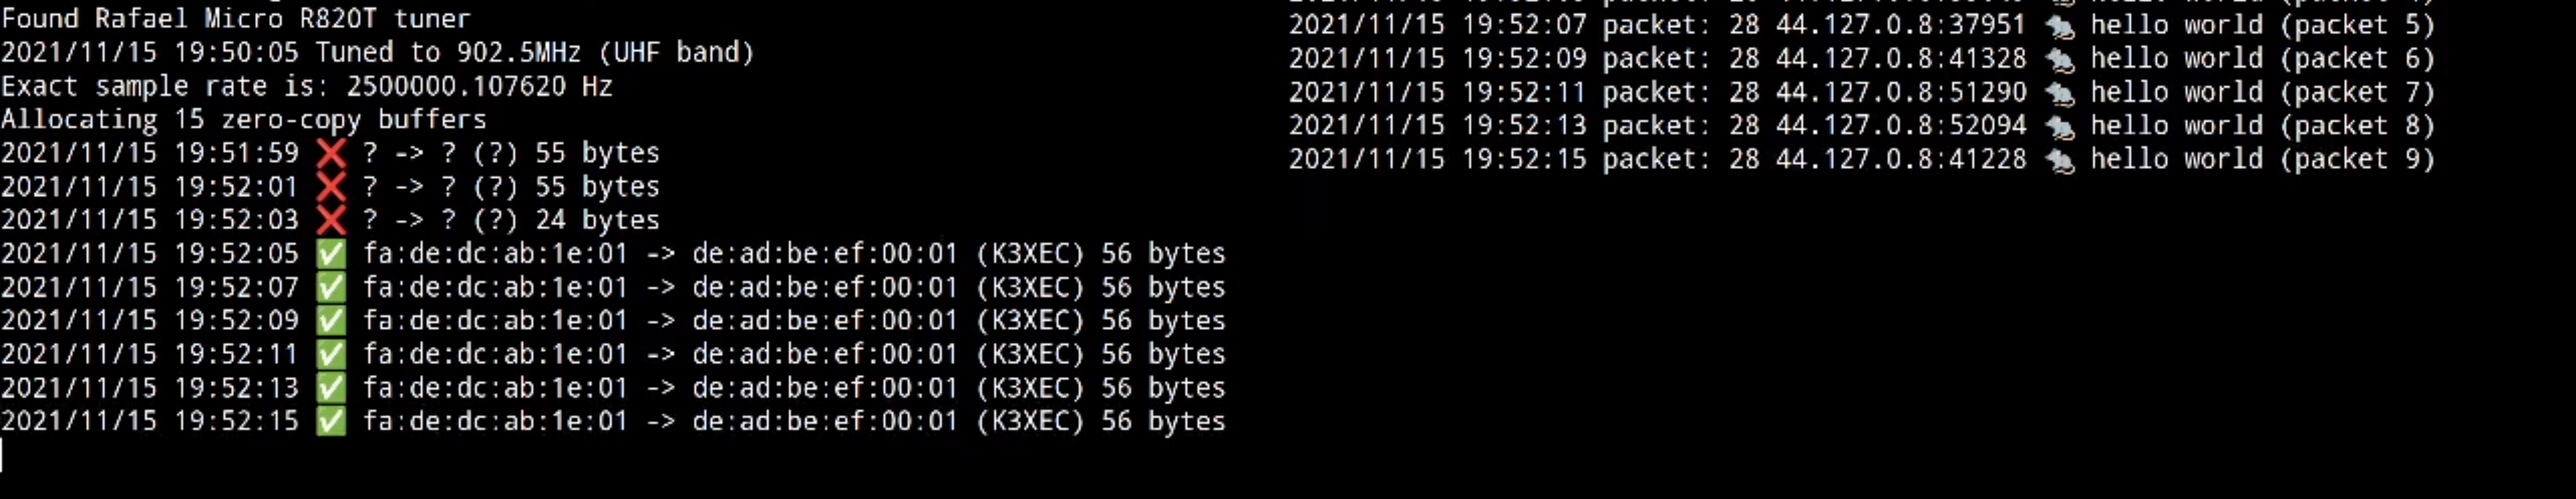
Putting it all Together After all this work weeks of work! we can finally get around to putting some real packets over the air. For me, this was an incredibly satisfying milestone, and tied together months of learning! I was able to start up a UDP server on a remote machine with an RTL-SDR dongle attached to it, listening on the TAP interface s host IP with my defined MAC address, and send UDP packets to that server via PACKRAT using my laptop, /dev/udp and an Ettus B210, sending packets into the TAP interface. Now that UDP was working, I was able to get TCP to work using two PlutoSDRs, which allowed me to run the cURL command I pasted in the first post (both simultaneously listen and transmit on behalf of my TAP interface). It s my hope that someone out there will be inspired to implement their own Layer 1 and Layer 2 as a learning exercise, and gets the same sense of gratification that I did! If you re reading this, and at a point where you ve been able to send IP traffic over your own Layer 1 / Layer 2, please get in touch! I d be thrilled to hear all about it. I d love to link to any posts or examples you publish here!
5 December 2021

Paul Tagliamonte: Framing data (Part 4/5)

This post is part of a series called "PACKRAT". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
In the last post, we we were able to build a functioning Layer 1 PHY where we can encode symbols to transmit, and receive symbols on the other end, we re now at the point where we can encode and decode those symbols as bits and frame blocks of data, marking them with a Sender and a Destination for routing to the right host(s). This is a Layer 2 scheme in the OSI model, which is otherwise known as the Data Link Layer. You re using one to view this website right now I m willing to bet your data is going through an Ethernet layer 2 as well as WiFi or maybe a cellular data protocol like 5G or LTE. Given that this entire exercise is hard enough without designing a complex Layer 2 scheme, I opted for simplicity in the hopes this would free me from the complexity and research that has gone into this field for the last 50 years. I settled on stealing a few ideas from Ethernet Frames namely, the use of MAC addresses to identify parties, and the EtherType field to indicate the Payload type. I also stole the idea of using a CRC at the end of the Frame to check for corruption, as well as the specific CRC method (crc32 using 0xedb88320 as the polynomial). Lastly, I added a callsign field to make life easier on ham radio frequencies if I was ever to seriously attempt to use a variant of this protocol over the air with multiple users. However, given this scheme is not a commonly used scheme, it s best practice to use a nearby radio to identify your transmissions on the same frequency while testing or use a Faraday box to test without transmitting over the airwaves. I added the callsign field in an effort to lean into the spirit of the Part 97 regulations, even if I relied on a phone emission to identify the Frames. As an aside, I asked the ARRL for input here, and their stance to me over email was I d be OK according to the regs if I were to stick to UHF and put my callsign into the BPSK stream using a widely understood encoding (even with no knowledge of PACKRAT, the callsign is ASCII over BPSK and should be easily demodulatable for followup with me). Even with all this, I opted to use FM phone to transmit my callsign when I was active on the air (specifically, using an SDR and a small bash script to automate transmission while I watched for interference or other band users). Right, back to the Frame:
sync
dest
source
callsign
type
payload
crc
With all that done, I put that layout into a struct, so that we can marshal and unmarshal bytes to and from our Frame objects, and work with it in software.
type FrameType [2]byte
type Frame struct  
Destination net.HardwareAddr
Source net.HardwareAddr
Callsign [8]byte
Type FrameType
Payload []byte
CRC uint32
 

Time to pick some consts I picked a unique and distinctive sync sequence, which the sender will transmit before the Frame, while the receiver listens for that sequence to know when it s in byte alignment with the symbol stream. My sync sequence is [3]byte 'U', 'f', '~' which works out to be a very pleasant bit sequence of 01010101 01100110 01111110. It s important to have soothing preambles for your Frames. We need all the good energy we can get at this point.
var (
FrameStart = [3]byte 'U', 'f', '~' 
FrameMaxPayloadSize = 1500
)
Next, I defined some FrameType values for the type field, which I can use to determine what is done with that data next, something Ethernet was originally missing, but has since grown to depend on (who needs Length anyway? Not me. See below!)
FrameType Description Bytes
Raw Bytes in the Payload field are opaque and not to be parsed. [2]byte 0x00, 0x01
IPv4 Bytes in the Payload field are an IPv4 packet. [2]byte 0x00, 0x02
And finally, I decided on a maximum length of the Payload, and decided on limiting it to 1500 bytes to align with the MTU of Ethernet.
var (
FrameTypeRaw = FrameType 0, 1 
FrameTypeIPv4 = FrameType 0, 2 
)
Given we know how we re going to marshal and unmarshal binary data to and from Frames, we can now move on to looking through the bit stream for our Frames.

Why is there no Length field? I was initially a bit surprised that Ethernet Frames didn t have a Length field in use, but the more I thought about it, the more it seemed like a big ole' failure mode without a good implementation outcome. Either the Length is right (resulting in no action and used bits on every packet) or the Length is not the length of the Payload and the driver needs to determine what to do with the packet does it try and trim the overlong payload and ignore the rest? What if both the end of the read bytes and the end of the subset of the packet denoted by Length have a valid CRC? Which is used? Will everyone agree? What if Length is longer than the Payload but the CRC is good where we detected a lost carrer? I decided on simplicity. The end of a Frame is denoted by the loss of the BPSK carrier when the signal is no longer being transmitted (or more correctly, when the signal is no longer received), we know we ve hit the end of a packet. Missing a single symbol will result in the Frame being finalized. This can cause some degree of corruption, but it s also a lot easier than doing tricks like bit stuffing to create an end of symbol stream delimiter.

Finding the Frame start in a Symbol Stream First thing we need to do is find our sync bit pattern in the symbols we re receiving from our BPSK demodulator. There s some smart ways to do this, but given that I m not much of a smart man, I again decided to go for simple instead. Given our incoming vector of symbols (which are still float values) prepend one at a time to a vector of floats that is the same length as the sync phrase, and compare against the sync phrase, to determine if we re in sync with the byte boundary within the symbol stream. The only trick here is that because we re using BPSK to modulate and demodulate the data, post phaselock we can be 180 degrees out of alignment (such that a +1 is demodulated as -1, or vice versa). To deal with that, I check against both the sync phrase as well as the inverse of the sync phrase (both [1, -1, 1] as well as [-1, 1, -1]) where if the inverse sync is matched, all symbols to follow will be inverted as well. This effectively turns our symbols back into bits, even if we re flipped out of phase. Other techniques like NRZI will represent a 0 or 1 by a change in phase state which is great, but can often cascade into long runs of bit errors, and is generally more complex to implement. That representation isn t ambiguous, given you look for a phase change, not the absolute phase value, which is incredibly compelling. Here s a notional example of how I ve been thinking about the phrase sliding window and how I ve been thinking of the checks. Each row is a new symbol taken from the BPSK receiver, and pushed to the head of the sliding window, moving all symbols back in the vector by one.
 var (
sync = []float  ...  
buf = make([]float, len(sync))
incomingSymbols = []float  ...  
)
for _, el := range incomingSymbols  
copy(buf, buf[1:])
buf[len(buf)-1] = el
if compare(sync, buf)  
// we're synced!
 break
 
 
Given the pseudocode above, let s step through what the checks would be doing at each step:
Buffer Sync Inverse Sync
[ ]float 0, ,0 [ ]float -1, ,-1 [ ]float 1, ,1
[ ]float 0, ,1 [ ]float -1, ,-1 [ ]float 1, ,1
[more bits in] [ ]float -1, ,-1 [ ]float 1, ,1
[ ]float 1, ,1 [ ]float -1, ,-1 [ ]float 1, ,1
After this notional set of comparisons, we know that at the last step, we are now aligned to the frame and byte boundary the next symbol / bit will be the MSB of the 0th Frame byte. Additionally, we know we re also 180 degrees out of phase, so we need to flip the symbol s sign to get the bit. From this point on we can consume 8 bits at a time, and re-assemble the byte stream. I don t know what this technique is called or even if this is used in real grown-up implementations, but it s been working for my toy implementation.

Next Steps Now that we can read/write Frames to and from PACKRAT, the next steps here are going to be implementing code to encode and decode Ethernet traffic into PACKRAT, coming next in Part 5!

1 December 2021

Utkarsh Gupta: FOSS Activites in December 2021

Here s my (twenty-sixth) monthly but brief update about the activities I ve done in the F/L/OSS world.

Debian
This was my 35th month of actively contributing to Debian. I became a DM in late March 2019 and a DD on Christmas 19! \o/ Just churning through the backlog again this month. Ugh. Anyway, I did the following stuff in Debian:

Uploads and bug fixes:
  • rails (2:6.1.4.1+dfsg-3) - No-change rebuild for unstable.

Other $things:
  • Mentoring for newcomers.
  • Moderation of -project mailing list.

Ubuntu
This was my 10th month of actively contributing to Ubuntu. Now that I ve joined Canonical to work on Ubuntu full-time, there s a bunch of things I do! \o/ I mostly worked on different things, I guess. I was too lazy to maintain a list of things I worked on so there s no concrete list atm. Maybe I ll get back to this section later or will start to list stuff from next year onward, as I was doing before. :D

Debian (E)LTS
Debian Long Term Support (LTS) is a project to extend the lifetime of all Debian stable releases to (at least) 5 years. Debian LTS is not handled by the Debian security team, but by a separate group of volunteers and companies interested in making it a success. And Debian Extended LTS (ELTS) is its sister project, extending support to the Jessie release (+2 years after LTS support). This was my twenty-sixth month as a Debian LTS and seventeenth month as a Debian ELTS paid contributor.
I was assigned 30.00 hours for LTS and 45.00 hours for ELTS and worked on the following things:

LTS CVE Fixes and Announcements:
  • Issued DLA 2813-1, fixing CVE-2021-33829 and CVE-2021-37695, for ckeditor.
    For Debian 9 stretch, these problems have been fixed in version 4.5.7+dfsg-2+deb9u1.
  • Issued DLA 2817-1, fixing CVE-2021-23214 and CVE-2021-23222, for postgresql-9.6.
    For Debian 9 stretch, these problems have been fixed in version 9.6.24-0+deb9u1.
  • Issued DLA 2836-1, fixing CVE-2021-43527, for nss.
    For Debian 9 stretch, these problems have been fixed in version 2:3.26.2-1.1+deb9u3.
  • Started working on src:samba for CVE-2020-25717 to CVE-2020-25722 and CVE-2021-23192 for jessie and stretch, both.
    The version difference b/w the suites are a bit too much for the patch(es) to be easily backported. I ve talked to Anton to work something out. \o/
  • Found the problem w/ libjdom1-java. Will have to roll the regression upload.
    I ve prepared the patch but needs some testing to be finally rolled out. Same for jessie.
  • Started working on libgit2.

ELTS CVE Fixes and Announcements:

Other (E)LTS Work:
  • Front-desk duty from 29-11 to 05-12 for both LTS and ELTS.
  • Triaged udisk2, wordpress, samba, gmp, nss, ntfs-3g, and openssh.
  • Auto EOL ed dwarfutils, radare2, mongodb, linux for jessie.
  • As FD, did a deep dive into the no-pu-update issue. Will write to list shortly.
  • Attended monthly Debian LTS meeting.
  • Answered questions (& discussions) on IRC (#debian-lts and #debian-elts).
  • General and other discussions on LTS private and public mailing list.

Debian LTS Survey I ve spent 3 hours on the LTS survey on the following bits:
  • Talking to Laura to revive the old a/c on survey.d.net.
  • Setting up stuff there.
  • Discussing the survey questions and other bits w/ Jeremiah.
  • Partly reviewing the questions of the survey.
  • Doing a walkthru of the LimeSurvey instance we have to make sure there are no changes .

Until next time.
:wq for today.

6 November 2021

Reproducible Builds: Reproducible Builds in October 2021

Welcome to the October 2021 report from the Reproducible Builds project!
This month Samanta Navarro posted to the oss-security security mailing on a novel category of exploit in the .tar archive format, where a single .tar file contains different contents depending on the tar utility being used. Naturally, this has consequences for reproducible builds as Samanta goes onto reply:

Arch Linux uses libarchive (bsdtar) in its build environment. The default tar program installed is GNU tar. It is possible to create a source distribution which leads to different files seen by the build environment than compared to a careful reviewer and other Linux distributions.
Samanta notes that addressing the tar utilities themselves will not be a sufficient fix:
I have submitted bug reports and patches to some projects but eventually I had to conclude that the problem itself cannot be fixed by these implementations alone. The best choice for these tools would be to only allow archives which are fully compatible to standards but this in turn would render a lot of archives broken.
Reproducible builds, with its twin ideas of reaching consensus on the build outputs as well as precisely recording and describing the build environment, would help address this problem at a higher level.
Codethink announced that they had achieved ISO-26262 ASIL D Tool Certification, a way of determining specific safety standards for software. Codethink used open source tooling to achieve this, but they also leverage:
Reproducibility, repeatability and traceability of builds, drawing heavily on best-practices championed by the Reproducible Builds project.

Elsewhere on the internet, according to a comment on Hacker News, Microsoft are now comparing NPM Javascript packages with their original source repositories:
I got a PR in my repository a few days ago leading back to a team trying to make it easier for packages to be reproducible from source.

Lastly, Martin Monperrus started an interesting thread on our mailing list about Github, specifically that their autogenerated release tarballs are not deterministic . The thread generated a significant number of replies that are worth reading.

Events and presentations

Community news On our mailing list this month:
There were quite a few changes to the Reproducible Builds website and documentation this month as well, including Feng Chai updating some links on our publications page [ ] and marco updated our project metadata around the Bitcoin Core building guide [ ].
Lastly, we ran another productive meeting on IRC during October. A full set of notes from the meeting is available to view.

Distribution work Qubes was heavily featured in the latest edition of Linux Weekly News, and a significant section was dedicated to discussing reproducibility. For example, it was mentioned that the Qubes project has been working on incorporating reproducible builds into its continuous integration (CI) infrastructure . But the LWN article goes on to describe that:
The current goal is to be able to build the Qubes OS Debian templates solely from packages that can be built reproducibly. Templates in Qubes OS are VM images that can be used to start an application qube quickly based on the template. The qube will have read-only access to the root filesystem of the template, so that the same root filesystem can be shared with multiple application qubes. There are official templates for several variants of both Fedora and Debian, as well as community maintained templates for several other distributions.
You can view the whole article on LWN, and Fr d ric also published a lengthy summary about their work on reproducible builds in Qubes as well for those wishing to learn more.
In Debian this month, 133 reviews of Debian packages were added, 81 were updated and 24 were removed this month, adding to Debian s ever-growing knowledge about identified issues. A number of issues were categorised and added by Chris Lamb and Vagrant Cascadian too [ ][ ][ ]. In addition, work on alternative snapshot service has made progress by Fr d ric Pierret and Holger Levsen this month, including moving from the existing host (snapshot.notset.fr) to snapshot.reproducible-builds.org (more info) thanks to OSUOSL for the machine and hosting and Debian for the disks.
Finally, Bernhard M. Wiedemann posted his monthly reproducible builds status report.

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb made the following changes, including preparing and uploading versions 186, 187, 188 and 189 to Debian
  • New features:
    • Add support for Python Sphinx inventory files (usually named objects.inv on-disk). [ ]
    • Add support for comparing .pyc files. Thanks to Sergei Trofimovich for the inspiration. [ ]
    • Try some alternative suffixes (e.g. .py) to support distributions that strip or retain them. [ ][ ]
  • Bug fixes:
    • Fix Python decompilation tests under Python 3.10+ [ ] and for Python 3.7 [ ].
    • Don t raise a traceback if we cannot unmarshal Python bytecode. This is in order to support Python 3.7 failing to load .pyc files generated with newer versions of Python. [ ]
    • Skip Python bytecode testing where we do not have an expected diff. [ ]
  • Codebase improvements:
    • Use our file_version_is_lt utility instead of accepting both versions of uImage expected diff. [ ]
    • Split out a custom call to assert_diff for a .startswith equivalent. [ ]
    • Use skipif instead of manual conditionals in some tests. [ ]
In addition, Jelle van der Waa added external tool references for Arch Linux for ocamlobjinfo, openssl and ffmpeg [ ][ ][ ] and added Arch Linux as a Continuous Integration (CI) test target. [ ] and Vagrant Cascadian updated the testsuite to skip Python bytecode comparisons when file(1) is older than 5.39. [ ] as well as added external tool references for the Guix distribution for dumppdf and ppudump. [ ][ ]. Vagrant Cascadian also updated the diffoscope package in GNU Guix [ ][ ]. Lastly, Guangyuan Yang updated the FreeBSD package name on the website [ ], Mattia Rizzolo made a change to override a new Lintian warning due to the new test files [ ], Roland Clobus added support to detect and log if the GNU_BUILD_ID field in an ELF binary been modified [ ], Sandro J ckel updated a number of helpful links on the website [ ] and Sergei Trofimovich made the uImage test output support file() version 5.41 [ ].

reprotest reprotest is the Reproducible Build s project end-user tool to build same source code twice in widely differing environments, checking the binaries produced by the builds for any differences. This month, reprotest version 0.7.18 was uploaded to Debian unstable by Holger Levsen, which also included a change by Holger to clarify that Python 3.9 is used nowadays [ ], but it also included two changes by Vasyl Gello to implement realistic CPU architecture shuffling [ ] and to log the selected variations when the verbosity is configured at a sufficiently high level [ ]. Finally, Vagrant Cascadian updated reprotest to version 0.7.18 in GNU Guix.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix unreproducible packages. We try to send all of our patches upstream where appropriate. We authored a large number of such patches this month, including:

Testing framework The Reproducible Builds project runs a testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
  • Holger Levsen:
    • Debian-related changes:
      • Incorporate a fix from bremner into builtin-pho related to binary-NMUs. [ ]
      • Keep bullseye environments around longer, in an attempt to fix a Jenkins issue. [ ]
      • Improve the documentation of buildinfos.debian.net. [ ]
      • Improve documentation for the builtin-pho setup. [ ][ ]
    • OpenWrt-related changes:
      • Also use -j1 for better debugging. [ ]
      • Document that that Python 3.x is now used. [ ]
      • Enable further debugging for the toolchain build. [ ]
    • New snapshot.reproducible-builds.org service:
      • Actually add new node. [ ][ ]
      • Install xfsprogs on snapshot.reproducible-builds.org. [ ]
      • Create account for fpierret on new node. [ ]
      • Run node_health_check job on new node too. [ ]
  • Mattia Rizzolo:
    • Debian-related changes:
      • Handle schroot errors when invoking diffoscope instead of masking them. [ ][ ]
      • Declare and define some variables separately to avoid masking the subshell return code. [ ]
      • Fix variable name. [ ]
      • Improve log reporting. [ ]
      • Execute apt-get update with the -q argument to get more decent logs. [ ]
      • Set the Debian HTTP mirror and proxy for snapshot.reproducible-builds.org. [ ]
      • Install the libarchive-tools package (instead of bsdtar) when updating Jenkins nodes. [ ]
    • Be stricter about errors when starting the node agent [ ] and don t overwrite NODE_NAME so that we can expect Jenkins to properly set for us [ ].
    • Explicitly warn if the NODE_NAME is not a fully-qualified domain name (FQDN). [ ]
    • Document whether a node runs in the future. [ ]
    • Disable postgresql_autodoc as it not available in bullseye. [ ]
    • Don t be so eager when deleting schroot internals, call to schroot -e to terminate the schroots instead. [ ]
    • Only consider schroot underlays for deletion that are over a month old. [ ][ ]
    • Only try to unmount /proc if it s actually mounted. [ ]
    • Move the db_backup task to its own Jenkins job. [ ]
Lastly, Vasyl Gello added usage information to the reproducible_build.sh script [ ].

Contributing If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

1 November 2021

Andreas R nnquist: Debian packages, version numbers and pre-release versions

Getting the latest version of a package into Debian involves checking when there are new versions available fortunately (and not surprisingly) Debian has tools to make this simpler. I have recently ran into the problem when an upstream beta version sorts higher than a newer non-beta version. Which is problematic, of course. This is due to Debian sorting something like 1.0b as later than a pure 1.0 version.
gusnan@debian-i7:~ > dpkg --compare-versions 1.0b lt 1.0 && echo true
gusnan@debian-i7:~ > dpkg --compare-versions 1.0b gt 1.0 && echo true
true
But there s a solution name the beta versions something like 1.0~beta. And you don t need to force upstream to make any changes either. You can use uscan and the watch file to make it interpret an upstream 1.0b version as 1.0~beta in Debian. This is done by using a line like
uversionmangle=s/(\d)[\_\.\-\+]?((RC rc pre dev beta alpha b a)\d*)$/$1~$2/;s/\~b/\~beta/;,\
in uversionmangle in your debian/watch file. In this case i have added on the end something to make the ending ~b into ~beta instead. Full version of the watch file available here.

23 October 2021

Antoine Beaupr : The Neo-Colonial Internet

I grew up with the Internet and its ethics and politics have always been important in my life. But I have also been involved at other levels, against police brutality, for Food, Not Bombs, worker autonomy, software freedom, etc. For a long time, that all seemed coherent. But the more I look at the modern Internet -- and the mega-corporations that control it -- and the less confidence I have in my original political analysis of the liberating potential of technology. I have come to believe that most of our technological development is harmful to the large majority of the population of the planet, and of course the rest of the biosphere. And now I feel this is not a new problem. This is because the Internet is a neo-colonial device, and has been from the start. Let me explain.

What is Neo-Colonialism? The term "neo-colonialism" was coined by Kwame Nkrumah, first president of Ghana. In Neo-Colonialism, the Last Stage of Imperialism (1965), he wrote:
In place of colonialism, as the main instrument of imperialism, we have today neo-colonialism ... [which] like colonialism, is an attempt to export the social conflicts of the capitalist countries. ... The result of neo-colonialism is that foreign capital is used for the exploitation rather than for the development of the less developed parts of the world. Investment, under neo-colonialism, increases, rather than decreases, the gap between the rich and the poor countries of the world.
So basically, if colonialism is Europeans bringing genocide, war, and its religion to the Africa, Asia, and the Americas, neo-colonialism is the Americans (note the "n") bringing capitalism to the world. Before we see how this applies to the Internet, we must therefore make a detour into US history. This matters, because anyone would be hard-pressed to decouple neo-colonialism from the empire under which it evolves, and here we can only name the United States of America.

US Declaration of Independence Let's start with the United States declaration of independence (1776). Many Americans may roll their eyes at this, possibly because that declaration is not actually part of the US constitution and therefore may have questionable legal standing. Still, it was obviously a driving philosophical force in the founding of the nation. As its author, Thomas Jefferson, stated:
it was intended to be an expression of the American mind, and to give to that expression the proper tone and spirit called for by the occasion
In that aging document, we find the following pearl:
We hold these truths to be self-evident, that all men are created equal, that they are endowed by their Creator with certain unalienable Rights, that among these are Life, Liberty and the pursuit of Happiness.
As a founding document, the Declaration still has an impact in the sense that the above quote has been called an:
"immortal declaration", and "perhaps [the] single phrase" of the American Revolutionary period with the greatest "continuing importance." (Wikipedia)
Let's read that "immortal declaration" again: "all men are created equal". "Men", in that context, is limited to a certain number of people, namely "property-owning or tax-paying white males, or about 6% of the population". Back when this was written, women didn't have the right to vote, and slavery was legal. Jefferson himself owned hundreds of slaves. The declaration was aimed at the King and was a list of grievances. A concern of the colonists was that the King:
has excited domestic insurrections amongst us, and has endeavoured to bring on the inhabitants of our frontiers, the merciless Indian Savages whose known rule of warfare, is an undistinguished destruction of all ages, sexes and conditions.
This is a clear mark of the frontier myth which paved the way for the US to exterminate and colonize the territory some now call the United States of America. The declaration of independence is obviously a colonial document, having being written by colonists. None of this is particularly surprising, historically, but I figured it serves as a good reminder of where the Internet is coming from, since it was born in the US.

A Declaration of the Independence of Cyberspace Two hundred and twenty years later, in 1996, John Perry Barlow wrote a declaration of independence of cyberspace. At this point, (almost) everyone has a right to vote (including women), slavery was abolished (although some argue it still exists in the form of the prison system); the US has made tremendous progress. Surely this text will have aged better than the previous declaration it is obviously derived from. Let's see how it reads today and how it maps to how the Internet is actually built now.

Borders of Independence One of the key ideas that Barlow brings up is that "cyberspace does not lie within your borders". In that sense, cyberspace is the final frontier: having failed to colonize the moon, Americans turn inwards, deeper into technology, but still in the frontier ideology. And indeed, Barlow is one of the co-founder of the Electronic Frontier Foundation (the beloved EFF), founded six years prior. But there are other problems with this idea. As Wikipedia quotes:
The declaration has been criticized for internal inconsistencies.[9] The declaration's assertion that 'cyberspace' is a place removed from the physical world has also been challenged by people who point to the fact that the Internet is always linked to its underlying geography.[10]
And indeed, the Internet is definitely a physical object. First controlled and severely restricted by "telcos" like AT&T, it was somewhat "liberated" from that monopoly in 1982 when an anti-trust lawsuit broke up the monopoly, a key historical event that, one could argue, made the Internet possible. (From there on, "backbone" providers could start competing and emerge, and eventually coalesce into new monopolies: Google has a monopoly on search and advertisement, Facebook on communications for a few generations, Amazon on storage and computing, Microsoft on hardware, etc. Even AT&T is now pretty much as consolidated as it was before.) The point is: all those companies have gigantic data centers and intercontinental cables. And those are definitely prioritizing the western world, the heart of the empire. Take for example Google's latest 3,900 mile undersea cable: it does not connect Argentina to South Africa or New Zealand, it connects the US to UK and Spain. Hardly a revolutionary prospect.

Private Internet But back to the Declaration:
Do not think that you can build it, as though it were a public construction project. You cannot. It is an act of nature and it grows itself through our collective actions.
In Barlow's mind, the "public" is bad, and private is good, natural. Or, in other words, a "public construction project" is unnatural. And indeed, the modern "nature" of development is private: most of the Internet is now privately owned and operated. I must admit that, as an anarchist, I loved that sentence when I read it. I was rooting for "us", the underdogs, the revolutionaries. And, in a way, I still do: I am on the board of Koumbit and work for a non-profit that has pivoted towards censorship and surveillance evasion. Yet I cannot help but think that, as a whole, we have failed to establish that independence and put too much trust in private companies. It is obvious in retrospect, but it was not, 30 years ago. Now, the infrastructure of the Internet has zero accountability to traditional political entities supposedly representing the people, or even its users. The situation is actually worse than when the US was founded (e.g. "6% of the population can vote"), because the owners of the tech giants are only a handful of people who can override any decision. There's only one Amazon CEO, he's called Jeff Bezos, and he has total control. (Update: Bezos actually ceded the CEO role to Andy Jassy, AWS and Amazon music founder, while remaining executive chairman. I would argue that, as the founder and the richest man on earth, he still has strong control over Amazon.)

Social Contract Here's another claim of the Declaration:
We are forming our own Social Contract.
I remember the early days, back when "netiquette" was a word, it did feel we had some sort of a contract. Not written in standards of course -- or barely (see RFC1855) -- but as a tacit agreement. How wrong we were. One just needs to look at Facebook to see how problematic that idea is on a global network. Facebook is the quintessential "hacker" ideology put in practice. Mark Zuckerberg explicitly refused to be "arbiter of truth" which implicitly means he will let lies take over its platforms. He also sees Facebook as place where everyone is equal, something that echoes the Declaration:
We are creating a world that all may enter without privilege or prejudice accorded by race, economic power, military force, or station of birth.
(We note, in passing, the omission of gender in that list, also mirroring the infamous "All men are created equal" claim of the US declaration.) As the Wall Street Journal's (WSJ) Facebook files later shown, both of those "contracts" have serious limitations inside Facebook. There are VIPs who systematically bypass moderation systems including fascists and rapists. Drug cartels and human traffickers thrive on the platform. Even when Zuckerberg himself tried to tame the platform -- to get people vaccinated or to make it healthier -- he failed: "vaxxer" conspiracies multiplied and Facebook got angrier. This is because the "social contract" behind Facebook and those large companies is a lie: their concern is profit and that means advertising, "engagement" with the platform, which causes increased anxiety and depression in teens, for example. Facebook's response to this is that they are working really hard on moderation. But the truth is that even that system is severely skewed. The WSJ showed that Facebook has translators for only 50 languages. It's a surprisingly hard to count human languages but estimates range the number of distinct languages between 2500 and 7000. So while 50 languages seems big at first, it's actually a tiny fraction of the human population using Facebook. Taking the first 50 of the Wikipedia list of languages by native speakers we omit languages like Dutch (52), Greek (74), and Hungarian (78), and that's just a few random nations picks from Europe. As an example, Facebook has trouble moderating even a major language like Arabic. It censored content from legitimate Arab news sources when they mentioned the word al-Aqsa because Facebook associates it with the al-Aqsa Martyrs' Brigades when they were talking about the Al-Aqsa Mosque... This bias against Arabs also shows how Facebook reproduces the American colonizer politics. The WSJ also pointed out that Facebook spends only 13% of its moderation efforts outside of the US, even if that represents 90% of its users. Facebook spends three more times moderating on "brand safety", which shows its priority is not the safety of its users, but of the advertisers.

Military Internet Sergey Brin and Larry Page are the Lewis and Clark of our generation. Just like the latter were sent by Jefferson (the same) to declare sovereignty over the entire US west coast, Google declared sovereignty over all human knowledge, with its mission statement "to organize the world's information and make it universally accessible and useful". (It should be noted that Page somewhat questioned that mission but only because it was not ambitious enough, Google having "outgrown" it.) The Lewis and Clark expedition, just like Google, had a scientific pretext, because that is what you do to colonize a world, presumably. Yet both men were military and had to receive scientific training before they left. The Corps of Discovery was made up of a few dozen enlisted men and a dozen civilians, including York an African American slave owned by Clark and sold after the expedition, with his final fate lost in history. And just like Lewis and Clark, Google has a strong military component. For example, Google Earth was not originally built at Google but is the acquisition of a company called Keyhole which had ties with the CIA. Those ties were brought inside Google during the acquisition. Google's increasing investment inside the military-industrial complex eventually led Google to workers organizing a revolt although it is currently unclear to me how much Google is involved in the military apparatus. Other companies, obviously, do not have such reserve, with Microsoft, Amazon, and plenty of others happily bidding on military contracts all the time.

Spreading the Internet I am obviously not the first to identify colonial structures in the Internet. In an article titled The Internet as an Extension of Colonialism, Heather McDonald correctly identifies fundamental problems with the "development" of new "markets" of Internet "consumers", primarily arguing that it creates a digital divide which creates a "lack of agency and individual freedom":
Many African people have gained access to these technologies but not the freedom to develop content such as web pages or social media platforms in their own way. Digital natives have much more power and therefore use this to create their own space with their own norms, shaping their online world according to their own outlook.
But the digital divide is certainly not the worst problem we have to deal with on the Internet today. Going back to the Declaration, we originally believed we were creating an entirely new world:
This governance will arise according to the conditions of our world, not yours. Our world is different.
How I dearly wished that was true. Unfortunately, the Internet is not that different from the offline world. Or, to be more accurate, the values we have embedded in the Internet, particularly of free speech absolutism, sexism, corporatism, and exploitation, are now exploding outside of the Internet, into the "real" world. The Internet was built with free software which, fundamentally, was based on quasi-volunteer labour of an elite force of white men with obviously too much time on their hands (and also: no children). The mythical writing of GCC and Emacs by Richard Stallman is a good example of this, but the entirety of the Internet now seems to be running on random bits and pieces built by hit-and-run programmers working on their copious free time. Whenever any of those fails, it can compromise or bring down entire systems. (Heck, I wrote this article on my day off...) This model of what is fundamentally "cheap labour" is spreading out from the Internet. Delivery workers are being exploited to the bone by apps like Uber -- although it should be noted that workers organise and fight back. Amazon workers are similarly exploited beyond belief, forbidden to take breaks until they pee in bottles, with ambulances nearby to carry out the bodies. During peak of the pandemic, workers were being dangerously exposed to the virus in warehouses. All this while Amazon is basically taking over the entire economy. The Declaration culminates with this prophecy:
We will spread ourselves across the Planet so that no one can arrest our thoughts.
This prediction, which first felt revolutionary, is now chilling.

Colonial Internet The Internet is, if not neo-colonial, plain colonial. The US colonies had cotton fields and slaves, we have disposable cell phones and Foxconn workers. Canada has its cultural genocide, Facebook has his own genocides in Ethiopia, Myanmar, and mob violence in India. Apple is at least implicitly accepting the Uyghur genocide. And just like the slaves of the colony, those atrocities are what makes the empire run. The Declaration actually ends like this, a quote which I have in my fortune cookies file:
We will create a civilization of the Mind in Cyberspace. May it be more humane and fair than the world your governments have made before.
That is still inspiring to me. But if we want to make "cyberspace" more humane, we need to decolonize it. Work on cyberpeace instead of cyberwar. Establish clear code of conduct, discuss ethics, and question your own privileges, biases, and culture. For me the first step in decolonizing my own mind is writing this article. Breaking up tech monopolies might be an important step, but it won't be enough: we have to do a culture shift as well, and that's the hard part.

Appendix: an apology to Barlow I kind of feel bad going through Barlow's declaration like this, point by point. It is somewhat unfair, especially since Barlow passed away a few years ago and cannot mount a response (even humbly assuming that he might read this). But then again, he himself recognized he was a bit too "optimistic" in 2009, saying: "we all get older and smarter":
I'm an optimist. In order to be libertarian, you have to be an optimist. You have to have a benign view of human nature, to believe that human beings left to their own devices are basically good. But I'm not so sure about human institutions, and I think the real point of argument here is whether or not large corporations are human institutions or some other entity we need to be thinking about curtailing. Most libertarians are worried about government but not worried about business. I think we need to be worrying about business in exactly the same way we are worrying about government.
And, in a sense, it was a little naive to expect Barlow to not be a colonist. Barlow is, among many things, a cattle rancher who grew up on a colonial ranch in Wyoming. The ranch was founded in 1907 by his great uncle, 17 years after the state joined the Union, and only a generation or two after the Powder River War (1866-1868) and Black Hills War (1876-1877) during which the US took over lands occupied by Lakota, Cheyenne, Arapaho, and other native American nations, in some of the last major First Nations Wars.

Appendix: further reading There is another article that almost has the same title as this one: Facebook and the New Colonialism. (Interestingly, the <title> tag on the article is actually "Facebook the Colonial Empire" which I also find appropriate.) The article is worth reading in full, but I loved this quote so much that I couldn't resist reproducing it here:
Representations of colonialism have long been present in digital landscapes. ( Even Super Mario Brothers, the video game designer Steven Fox told me last year. You run through the landscape, stomp on everything, and raise your flag at the end. ) But web-based colonialism is not an abstraction. The online forces that shape a new kind of imperialism go beyond Facebook.
It goes on:
Consider, for example, digitization projects that focus primarily on English-language literature. If the web is meant to be humanity s new Library of Alexandria, a living repository for all of humanity s knowledge, this is a problem. So is the fact that the vast majority of Wikipedia pages are about a relatively tiny square of the planet. For instance, 14 percent of the world s population lives in Africa, but less than 3 percent of the world s geotagged Wikipedia articles originate there, according to a 2014 Oxford Internet Institute report.
And they introduce another definition of Neo-colonialism, while warning about abusing the word like I am sort of doing here:
I m loath to toss around words like colonialism but it s hard to ignore the family resemblances and recognizable DNA, to wit, said Deepika Bahri, an English professor at Emory University who focuses on postcolonial studies. In an email, Bahri summed up those similarities in list form:
  1. ride in like the savior
  2. bandy about words like equality, democracy, basic rights
  3. mask the long-term profit motive (see 2 above)
  4. justify the logic of partial dissemination as better than nothing
  5. partner with local elites and vested interests
  6. accuse the critics of ingratitude
In the end, she told me, if it isn t a duck, it shouldn t quack like a duck.
Another good read is the classic Code and other laws of cyberspace (1999, free PDF) which is also critical of Barlow's Declaration. In "Code is law", Lawrence Lessig argues that:
computer code (or "West Coast Code", referring to Silicon Valley) regulates conduct in much the same way that legal code (or "East Coast Code", referring to Washington, D.C.) does (Wikipedia)
And now it feels like the west coast has won over the east coast, or maybe it recolonized it. In any case, Internet now christens emperors.

18 October 2021

Dirk Eddelbuettel: dang 0.0.14: Several Updates

A new release of the dang package arrived at CRAN a couple of hours ago, exactly eight months after the previous release. The dang package regroups a few functions of mine that had no other home as for example lsos() from a StackOverflow question from 2009 (!!), the overbought/oversold price band plotter from an older blog post, the market monitor from the last release as well the checkCRANStatus() function recently tweeted about by Tim Taylor. This release regroups a few small edits to several functions, adds a sample function for character encoding reading and conversion using a library already used by R (hence look Ma, no new depends ), adds a weekday helper, and a sample usage (computing rolling min/max values) of a new simple vector class added to tidyCpp (and the function and class need to get another blog post or study ), and an experimental git sha1sum and date marker (as I am not the fan of autogenerated binaries from repos as opposed to marked released meaning: we may see different binary release with the same version number). The full NEWS entry follows.

Changes in version 0.0.14 (2021-10-17)
  • Updated continuous integration to run on Linux only.
  • Edited checkNonAscii.cpp for readability.
  • More robust title display in intradayMarketMonitor.R.
  • New C++-based function to read and convert encoding via the R-supplied iconv library, noted a potential variability.
  • New function wday returning day of the week as integer.
  • The signature to as.data.table was standardized.
  • A new function rollMinMax was added illustrating use of the NumVec class from tidyCpp.
  • The configure script can record the last commit date and sha1 to automate timestamping builds, but not activated in this release.
  • checkCRANStatus() now works correctly for single-package lookups (Jordan Mark Barbone in #4).

Courtesy of my CRANberries, there is a comparison to the previous release. For questions or comments use the issue tracker off the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

21 September 2021

Russell Coker: Links September 2021

Matthew Garrett wrote an interesting and insightful blog post about the license of software developed or co-developed by machine-learning systems [1]. One of his main points is that people in the FOSS community should aim for less copyright protection. The USENIX ATC 21/OSDI 21 Joint Keynote Address titled It s Time for Operating Systems to Rediscover Hardware has some inssightful points to make [2]. Timothy Roscoe makes some incendiaty points but backs them up with evidence. Is Linux really an OS? I recommend that everyone who s interested in OS design watch this lecture. Cory Doctorow wrote an interesting set of 6 articles about Disneyland, ride pricing, and crowd control [3]. He proposes some interesting ideas for reforming Disneyland. Benjamin Bratton wrote an insightful article about how philosophy failed in the pandemic [4]. He focuses on the Italian philosopher Giorgio Agamben who has a history of writing stupid articles that match Qanon talking points but with better language skills. Arstechnica has an interesting article about penetration testers extracting an encryption key from the bus used by the TPM on a laptop [5]. It s not a likely attack in the real world as most networks can be broken more easily by other methods. But it s still interesting to learn about how the technology works. The Portalist has an article about David Brin s Startide Rising series of novels and his thought s on the concept of Uplift (which he denies inventing) [6]. Jacobin has an insightful article titled You re Not Lazy But Your Boss Wants You to Think You Are [7]. Making people identify as lazy is bad for them and bad for getting them to do work. But this is the first time I ve seen it described as a facet of abusive capitalism. Jacobin has an insightful article about free public transport [8]. Apparently there are already many regions that have free public transport (Tallinn the Capital of Estonia being one example). Fare free public transport allows bus drivers to concentrate on driving not taking fares, removes the need for ticket inspectors, and generally provides a better service. It allows passengers to board buses and trams faster thus reducing traffic congestion and encourages more people to use public transport instead of driving and reduces road maintenance costs. Interesting research from Israel about bypassing facial ID [9]. Apparently they can make a set of 9 images that can pass for over 40% of the population. I didn t expect facial recognition to be an effective form of authentication, but I didn t expect it to be that bad. Edward Snowden wrote an insightful blog post about types of conspiracies [10]. Kevin Rudd wrote an informative article about Sky News in Australia [11]. We need to have a Royal Commission now before we have our own 6th Jan event. Steve from Big Mess O Wires wrote an informative blog post about USB-C and 4K 60Hz video [12]. Basically you can t have a single USB-C hub do 4K 60Hz video and be a USB 3.x hub unless you have compression software running on your PC (slow and only works on Windows), or have DisplayPort 1.4 or Thunderbolt (both not well supported). All of the options are not well documented on online store pages so lots of people will get unpleasant surprises when their deliveries arrive. Computers suck. Steinar H. Gunderson wrote an informative blog post about GaN technology for smaller power supplies [13]. A 65W USB-C PSU that fits the usual wall wart form factor is an interesting development.

13 September 2021

John Goerzen: Facebook s Blocking Decisions Are Deliberate Including Their Censorship of Mastodon

In the aftermath of my report of Facebook censoring mentions of the open-source social network Mastodon, there was a lot of conversation about whether or not this was deliberate. That conversation seemed to focus on whether a human speficially added joinmastodon.org to some sort of blacklist. But that s not even relevant. OF COURSE it was deliberate, because of how Facebook tunes its algorithm. Facebook s algorithm is tuned for Facebook s profit. That means it s tuned to maximize the time people spend on the site engagement. In other words, it is tuned to keep your attention on Facebook. Why do you think there is so much junk on Facebook? So much anti-vax, anti-science, conspiracy nonsense from the likes of Breitbart? It s not because their algorithm is incapable of surfacing the good content; we already know it can because they temporarily pivoted it shortly after the last US election. They intentionally undid its efforts to make high-quality news sources more prominent twice. Facebook has said that certain anti-vax disinformation posts violate its policies. It has an extremely cumbersome way to report them, but it can be done and I have. These reports are met with either silence or a response claiming the content didn t violate their guidelines. So what algorithm is it that allows Breitbart to not just be seen but to thrive on the platform, lets anti-vax disinformation survive even a human review, while banning mentions of Mastodon? One that is working exactly as intended. We may think this algorithm is busted. Clearly, Facebook does not. If their goal is to maximize profit by maximizing engagement, the algorithm is working exactly as designed. I don t know if joinmastodon.org was specifically blacklisted by a human. Nor is it relevant. Facebook s choice to tolerate and promote the things that service its greed for engagement and money, even if they are the lowest dregs of the web, is deliberate. It is no accident that Breitbart does better than Mastodon on Facebook. After all, which of these does its algorithm detect keep people engaged on Facebook itself more? Facebook removes the ban You can see all the screenshots of the censorship in my original post. Now, Facebook has reversed course: We also don t know if this reversal was human or algorithmic, but that still is beside the point. The point is, Facebook intentionally chooses to surface and promote those things that drive engagement, regardless of quality. Clearly many have wondered if tens of thousands of people have died unnecessary deaths over COVID as a result. One whistleblower says I have blood on my hands and President Biden said they re killing people before walking back his comments slightly . I m not equipped to verify those statements. But what do they think is going to happen if they prioritize engagement over quality? Rainbows and happiness?
11 September 2021

John Goerzen: Facebook Is Censoring People For Mentioning Open-Source Social Network Mastodon

Update: Facebook has reversed itself over this censorship, but I maintain that whether the censorship was algorithmic or human, it was intentional either way. Details in my new post. Last November, I made a brief post to Facebook about Mastodon. Mastodon is an open-source and open social network, which is decentralized and all about user control instead of corporate control. I ve blogged about Mastodon and the dangers of Facebook before, but rarely mentioned Mastodon on Facebook itself. Today, I received this notice that Facebook had censored my post about Mastodon: Facebook censoring a post Wonder with me for a second what this one-off post I composed myself might have done to trip Facebook s filter . and it is probably obvious that what tripped the filter was the mention of an open source competitor, even though Facebook is much more enormous than Mastodon. I have been a member of Facebook for many years, and this is the one and only time anything like that has happened. Why they decided today to take down that post I have no idea. In case you wondered about their sincerity towards stamping out misinformation which, on the rare occasions they do something about, they deprioritize rather than remove as they did here this probably answers your question. Or, are they sincere about thinking they re such a force for good by connecting the world s people? Well, only so long as the world s people don t say nice things about alternatives to Facebook, I guess. Well, you might be wondering, Why not appeal, since they obviously made a mistake? Because, of course, you can t: Indeed I did tick a box that said I disagreed, but there was no place to ask why or to question their action. So what would cause a non-controversial post from a long-time Facebook member that has never had anything like this happen, to disappear? Greed. Also fear. Maybe I d feel sorry for them if they weren t acting like a bully. Edit: There are reports from several others on Mastodon of the same happening this week. I am trying to gather more information. It sounds like it may be happening on Twitter as well. Edit 2: And here are some other reports from both Facebook and Twitter. Definitely not just me. Edit 3: While trying to reply to someone on Facebook, that was trying to defend Facebook, I mentioned joinmastodon.org and got this: Anyone else seeing it? Edit 4: It is far more than just me, clearly. More reports are out there; for instance, this one and that one.
6 September 2021

Dirk Eddelbuettel: tidyCpp 0.0.4 on CRAN: Adding a Simple Numeric Vector Class

Another release of the tidyCpp package arrived on CRAN earlier today. The packages offers a clean C++ layer on top of the C API for R which aims to make its use a little easier and more consistent. The vignette has been extended once more with a new example, and added a table of contents. The package now supports a (truly minimal) C++ class for a numeric vector which is the most likely use case. The NEWS entry follows and includes the 0.0.3 release earlier in the year which did not get the usual attention of post-release blog post.

Changes in tidyCpp version 0.0.4 (2021-09-05)
  • Minor updates to DESCRIPTION
  • New snippet rollminmaxExample with simple vector use
  • New class NumVec motivated from rolling min/max example
  • Expand the vignette with C++ example based on NumVec
  • Add a table of contents to the vignette

Changes in tidyCpp version 0.0.3 (2021-03-07)
  • Switch CI use to r-ci
  • Protect nil object definition

Thanks to my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

2 September 2021

Norbert Preining: Reducing (sparsifying) qcow2 image of Windows10

Since joining Fujitsu I am permanently running a VM (kvm/qemu) with Windows 10 (unfortunately necessary). While the usaged disk space is about 50G, the actual qcow2 file had grown to over 180G, not good. Searching the web the very promising virt-sparsify is mentioned again and again, and the man page gives hope, but as it turns out it is broken and calls qemu-img with incorrect/not-working arguments (see this bug). Another problem seems to be that by default the discard mode seems not to be set to unmap. So here are the stages how I reduced the size of the qcow2 image back down to around 60G.
  1. Turn off the VM
  2. Make sure you are using VirtIO for the disk, select Discard mode: unmap
  3. Boot into Windows, and from an elevated prompt run: Optimize-Volume -DriveLetter C -ReTrim -Verbose
  4. Shut down the VM
  5. Run a dummy conversion which sparsifies the image: qemu-img convert -O qcow2 orig.qcow2 sparse.qcow2
  6. Rename/Backup the images and boot back into Windows.
That helped in my case, without any consequences (till now) for the Windows installation.

1 September 2021

Utkarsh Gupta: FOSS Activites in August 2021

Here s my (twenty-third) monthly but brief update about the activities I ve done in the F/L/OSS world.

Debian
This was my 32nd month of actively contributing to Debian. I became a DM in late March 2019 and a DD on Christmas 19! \o/ Tough month but I mostly spent on it churning through the immense backlog. But that somewhat backfired and I have even more backlog than ever. :D Anyway, I did the following stuff in Debian:

Uploads and bug fixes:
  • ruby3.0 (3.0.0-2) - Upload to unstable! \o/

Other $things:
  • Mentoring for newcomers.
  • Moderation of -project mailing list.

Ubuntu
This was my 7th month of actively contributing to Ubuntu. Now that I ve joined Canonical to work on Ubuntu full-time, there s a bunch of things I do! \o/ I mostly worked on different things, I guess. But mostly on packaging keylime and some Google Agents upload(s) and SRU(s). Also did a lot of reviewing, et al. I was too lazy to maintain a list of things I worked on so there s no concrete list atm. Maybe I ll get back to this section later or will start to list stuff from next month onward, as I ve been doing before. :D

Debian (E)LTS
Debian Long Term Support (LTS) is a project to extend the lifetime of all Debian stable releases to (at least) 5 years. Debian LTS is not handled by the Debian security team, but by a separate group of volunteers and companies interested in making it a success. And Debian Extended LTS (ELTS) is its sister project, extending support to the Jessie release (+2 years after LTS support). This was my twenty-third month as a Debian LTS and eleventh month as a Debian ELTS paid contributor.
I was assigned 23.75 hours for LTS and 40.00 hours for ELTS and worked on the following things:
(however, I only worked for 23.75h on ELTS work, thereby, carrying the rest to next month)

LTS CVE Fixes and Announcements:

ELTS CVE Fixes and Announcements:

Other (E)LTS Work:
  • Front-desk duty from 26-07 until 01-08 and from 30-08 until 05-09 for both LTS and ELTS.
  • Triaged haproxy, ntfs-3g, and cyrus-imapd, and exiv2, ffmpeg, git, gpac, inetutils, mc, modsecurity-crs, node-object-path, php-pear, systemd-cron, node-tar, ruby2.3, gst-plugins-bad0.10, jsoup, libxstream-java, qemu, tomcat7, ruby2.1, prototypejs, pillow, cpio, and qtbase-opensource-src, and amd64-microcode.
  • Mark CVE-2021-39240/haproxy as not-affected for stretch and jessie.
  • Mark CVE-2021-39241/haproxy as not-affected for stretch and jessie.
  • Mark CVE-2021-39242/haproxy as not-affected for stretch and jessie.
  • Mark CVE-2021-33582/cyrus-imapd as no-dsa for stretch.
  • Mark CVE-2020-18771/exiv2 as no-dsa for exiv2 for stretch.
  • Mark CVE-2020-18899/exiv2 as no-dsa for exiv2 for stretch.
  • Mark CVE-2021-38171/ffmpeg as postponed for stretch.
  • Mark CVE-2021-40330/git as no-dsa for stretch and jessie.
  • Mark CVE-2020-19481/gpac as ignored for stretch.
  • Mark CVE-2021-40491/inetutils as no-dsa for stretch.
  • Mark CVE-2021-36370/mc as no-dsa for stretch and jessie.
  • Mark CVE-2021-35368/modsecurity-crs as no-dsa for stretch.
  • Mark CVE-2021-23434/node-object-path as end-of-life for stretch.
  • Mark CVE-2021-32610/php-pear as no-dsa for stretch.
  • Mark CVE-2017-9525/systemd-cron as no-dsa for stretch.
  • Mark CVE-2021-37701/node-tar as end-of-life for stretch.
  • Mark CVE-2021-37712/node-tar as end-of-life in stretch.
  • Mark CVE-2021-3750/qemu as postponsed for jessie.
  • Mark CVE-2021-27511/prototypejs as postponsed for jessie.
  • Mark CVE-2021-23437/pillow as postponed for stretch and jessie.
  • Auto EOL ed gpac, cacti, openscad, cgal, cyrus-imapd-2.4, libsolv, mosquitto, atomicparsley, gtkpod, node-tar, libapache2-mod-auth-openidc, neutron, inetutils and linux for jessie.
  • Drop cpio from ela-needed; open issues don t warrant an ELA.
  • Attended monthly Debian LTS meeting.
  • Answered questions (& discussions) on IRC (#debian-lts and #debian-elts).
  • General and other discussions on LTS private and public mailing list.

Until next time.
:wq for today.

20 June 2021

Mike Gabriel: BBB Packaging for Debian, a short Heads-Up

Over the past days, I have received tons of positive feedback on my previous blog post about forming the Debian BBB Packaging Team [1]. Feedback arrived via mail, IRC, [matrix] and Mastodon. Awesome. Thanks for sharing your thoughts, folks... Therefore, here comes a short ... Heads-Up on the current Ongoings ... around packaging BigBlueButton for Debian: Credits light+love
Mike Gabriel

[1] https://sunweavers.net/blog/node/133
[2] https://bigbluebutton.org/event-page/
[3] https://docs.google.com/document/d/1kpYJxYFVuWhB84bB73kmAQoGIS59ari1_hn2...

5 June 2021

Utkarsh Gupta: FOSS Activites in May 2021

Here s my (twentieth) monthly update about the activities I ve done in the F/L/OSS world.

Debian
This was my 29th month of actively contributing to Debian. I became a DM in late March 2019 and a DD on Christmas 19! \o/ Interesting month, surprisingly. Lots of things happening and lots of moving parts; becoming the new normal , I believe. Anyhow, working on Ubuntu full-time has its own advantage and one of them is being able to work on Debian stuff! So whilst I couldn t upload a lot of packages because of the freeze, here s what I worked on:

Uploads and bug fixes:

Other $things:
  • Mentoring for newcomers and assisting people in BSP.
  • Moderation of -project mailing list.

Ubuntu
This was my 4th month of actively contributing to Ubuntu. Now that I ve joined Canonical to work on Ubuntu full-time, there s a bunch of things I do! \o/ This month, by all means, was dedicated mostly to PHP 8.0, transitioning from PHP 7.4 to 8.0. Naturally, it had so many moving parts and moments of utmost frustration, shared w/ Bryce. :D So even though I can t upload anything, I worked on the following stuff & asked for sponsorship.
But before, I d like to take a moment to stress how kind and awesome Gianfranco Costamagna, a.k.a. LocutusOfBorg is! He s been sponsoring a bunch of my things & helping with re-triggers, et al. Thanks a bunch, Gianfranco; beers on me whenever we meet!

Merges:

Uploads & Syncs:

MIRs:

Seed Operations:

Debian (E)LTS
Debian Long Term Support (LTS) is a project to extend the lifetime of all Debian stable releases to (at least) 5 years. Debian LTS is not handled by the Debian security team, but by a separate group of volunteers and companies interested in making it a success. And Debian Extended LTS (ELTS) is its sister project, extending support to the Jessie release (+2 years after LTS support). This was my twentieth month as a Debian LTS and eleventh month as a Debian ELTS paid contributor.
I was assigned 29.75 hours for LTS and 40.00 hours for ELTS and worked on the following things:

LTS CVE Fixes and Announcements:

ELTS CVE Fixes and Announcements:

Other (E)LTS Work:
  • Front-desk duty from 24-05 until 30-05 for both LTS and ELTS.
  • Triaged rails, libimage-exiftool-perl, hivex, graphviz, glibc, libexosip2, impacket, node-ws, thunar, libgrss, nginx, postgresql-9.6, ffmpeg, composter, and curl.
  • Mark CVE-2019-9904/graphviz as ignored for stretch and jessie.
  • Mark CVE-2021-32029/postgresql-9.6 as not-affected for stretch.
  • Mark CVE-2020-24020/ffmpeg as not-affected for stretch.
  • Mark CVE-2020-22020/ffmpeg as postponed for stretch.
  • Mark CVE-2020-22015/ffmpeg as ignored for stretch.
  • Mark CVE-2020-21041/ffmpeg as postponed for stretch.
  • Mark CVE-2021-33574/glibc as no-dsa for stretch & jessie.
  • Mark CVE-2021-31800/impacket as no-dsa for stretch.
  • Mark CVE-2021-32611/libexosip2 as no-dsa for stretch.
  • Mark CVE-2016-20011/libgrss as ignored for stretch.
  • Mark CVE-2021-32640/node-ws as no-dsa for stretch.
  • Mark CVE-2021-32563/thunar as no-dsa for stretch.
  • [LTS] Help test and review bind9 update for Emilio.
  • [LTS] Suggest and add DEP8 tests for bind9 for stretch.
  • [LTS] Sponsored upload of htmldoc to buster for Havard as a consequence of #988289.
  • [ELTS] Fix triage order for jetty and graphviz.
  • [ELTS] Raise issue upstream about cloud-init; mock tests instead.
  • [ELTS] Write to private ELTS list about triage ordering.
  • [ELTS] Review Emilio s new script and write back feedback, mentioning extra file created, et al.
  • [ELTS/LTS] Raise upgrade problems from LTS -> LTS+1 to the list. Thread here.
    • Further help review and raise problems that could occur, et al.
  • [LTS] Help explain path forward for firmware-nonfree update to Ola. Thread here.
  • [ELTS] Revert entries of TEMP-0000000-16B7E7 and TEMP-0000000-1C4729; CVEs assigned & fix ELTS tracker build.
  • Auto EOL ed linux, libgrss, node-ws, and inspircd for jessie.
  • Attended monthly Debian LTS meeting, which didn t happen, heh.
  • Answered questions (& discussions) on IRC (#debian-lts and #debian-elts).
  • General and other discussions on LTS private and public mailing list.

Until next time.
:wq for today.

Next.

Previous.