Search Results: "tar"

2 March 2008

Eddy Petrișor: pbuilder - /etc/pbuilderrc no longer a conffile (333294)

I have just finished a completely functional patch for pbuilder's bug #333294. I started this during debconf7, to be more precise, just after Junichi's talk about pbuilder. This patch makes pbuilder smarter smarter about the information it places in the MIRRORSITE variable of the /etc/pbuilderrc.

And now that file is no longer a conffile[1], and it asks some questions via debconf. And since debconf is translatable, there is a Romanian translation, too.

I have published my changes in my pbuilder git repo on alioth.

Anyone interested in the changes can pull from that repo:

git://git.debian.org/git/users/eddyp-guest/pbuilder.git
or
http://git.debian.org/git/users/eddyp-guest/pbuilder.git


[1] this was the main reason the patch wasn't good enough, since modifying a conffile is RC.

1 March 2008

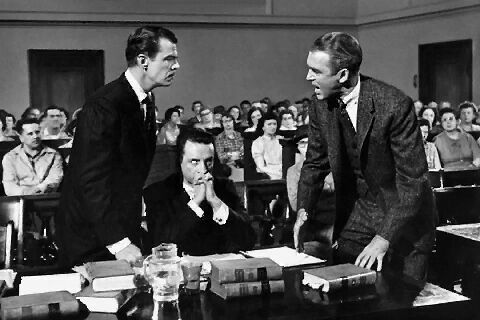
Adam Rosi-Kessel: The Best Movie to Start at 11pm at the End of a Long Trial

Anatomy of a Murder. David Denby put it best:
Otto Preminger s Anatomy of a Murder, from 1959, is still the best courtroom drama ever made in this country, and, in its occasional forays out of the court, among the finest evocations of place an Upper Peninsula Michigan resort area in the off-season, leafless, underpopulated, alcoholic, and forlorn. James Stewart, in one of his wonderful melancholy late performances, plays a former county prosecutor named Biegler, a lifelong bachelor who now spends his time with a non-practicing lawyer (Arthur O Connell) and an unpaid secretary (Eve Arden), who sticks around for the wisecracks. The movie is leisurely, detailed, realistic, intensely companionable; you get a sense of how people exist at the margins of a profession without losing their dignity.
Although there are some distinctions between a murder defense in the 1950’s in the Upper Peninsula of Michigan and modern-day patent litigation, the essence of trial technique is really not all that different. Highly recommended.
Prosecutor: Lieutenant Manion, wasn’t your action against Barney Quill much the same thing as your action against Miller or the Lieutenant you slapped at the cocktail party — all done in the heat of anger, with a willful, conscious desire to hurt or kill?
Defendant: I don’t remember my action against Quill.
Prosecutor: How long had you known your wife was stepping out with Quill?
Defendant: I never knew anything like that. I trust my wife.
Prosecutor: You just occasionally beat her up for the fun of it, I suppose?
Defense Counsel: There has been nothing established to permit a question like that. He keeps trying to insinuate without ever coming to the point. Let him ask the Lieutenant, did he ever beat his wife.
Judge: I will sustain the objection. Do you want to re-phrase your question, Mr. Dancer?
Prosecutor: No thank you, Your Honor. I’ve finished.
Technorati Tags: , ,

Anthony Towns: Been a while...

So, sometime over the past few weeks I clocked up ten years as a Debian developer:
From: Anthony Towns <aj@humbug.org.au>
Subject: Wannabe maintainer.
Date: Sun, 8 Feb 1998 18:35:28 +1000 (EST)
To: new-maintainer@debian.org
Hello world,
I'd like to become a debian maintainer.
I'd like an account on master, and for it to be subscribed to the
debian-private list.
My preferred login on master would have been aj, but as that's taken
ajt or atowns would be great.
I've run a debian system at home for half a year, and a system at work
for about two months. I've run Linux for two and a half years at home,
two years at work. I've been active in my local linux users' group for
just over a year. I've written a few programs, and am part way through
packaging the distributed.net personal proxy for Debian (pending
approval for non-free distribution from distributed.net).
I've read the Debian Social Contract.
My PGP public key is attached, and also available as
<http://azure.humbug.org.au/~aj/aj_key.asc>.
If there's anything more you need to know, please email me.
Thanks in advance.
Cheers,
aj
-- 
Anthony Towns <aj@humbug.org.au> <http://azure.humbug.org.au/~aj/>
I don't speak for anyone save myself. PGP encrypted mail preferred.
On Netscape GPLing their browser:  How can you trust a browser that
ANYONE can hack? For the secure choice, choose Microsoft.''
        -- <oryx@pobox.com> in a comment on slashdot.org
Apparently that also means I’ve clocked up ten and a half years as a Debian user; I think my previous two years of Linux (mid-95 to mid-97) were split between Slackware and Red Hat, though I couldn’t say for sure at this point. There’s already been a few other grand ten-year reviews, such as Joey Hess’s twenty-part serial, or LWN’s week-by-week review, or ONLamp’s interview with Bruce Perens, Eric Raymond and Michael Tiemann on ten years of “open source”. I don’t think I’m going to try matching that sort of depth though, so here are some of my highlights (after the break).
Hrm, this is going on longer than I’d hoped. Oh well, to be continued!

David Moreno Garza: As it was expected, I moved from MovableType crazyness into Tumblr. Ha, so this is now a tumblelog...

As it was expected, I moved from MovableType crazyness into Tumblr. Ha, so this is now a tumblelog (the world of Intenet sometimes amazes me :P). And as it was expected I brough Blog::Normalize::Tumblr into life. Blog::Normalize is becoming a nice little toy I like to play with. My imported data came from MovableType which was came from Wordpress. Cleanly enough, I d be able to export Tumblr posts (or categories/tags or anything else in the future) into Wordpress again and that d be a nice circle. B::N::Tumblr was made, differently from the other blogging systems modules I created before, by scrapping, that s the transparency that the model of B::N would give users and developers. After I made the whole scrapping work, and by tracing my HTTP traffic, I realized that Tumblr has an API which allows to read and write posts, lol. I d be starting using it soonish and creating WWW::Tumblr, maybe even today. TextMotion support is also on the way. B::N 0.0rc2 should be mirrored by CPAN soon.

Neil Williams: Emdebian TDebs

A few clarifications on TDebs in Emdebian:

  1. Emdebian needs TDebs now and although discussed in Debian, there is no implementation at this time. Therefore, Emdebian has had to go ahead and implement what we need from TDebs in a manner that should be compatible with Debian TDebs when they eventually arrive.

  2. .mo files are architecture dependent and this is a problem for embedded devices, therefore the Emdebian TDeb support must take account of these problems whether or not Debian does so as well.

  3. Emdebian will continue to need to cross-build existing Debian packages and if that means regenerating the TDebs to ensure compatibility with embedded devices, that will be done too. It is quite likely as Emdebian will certainly be dropping translated manpages and other content of the proposed Debian TDebs.

  4. Emdebian TDebs - as the only implementation currently available - do not support anything except gettext. Again, Debian is likely to provide such support but it is not important to Emdebian because packages that do not use gettext are not in the package set likely to be useful on an embedded device.

  5. Tests on non-embedded boxes are irrelevant - yes, .mo files work on any Debian architecture that you care to mention. The problem is that the conversion that is so invisible on a desktop machine becomes a real problem on an iPAQ.

  6. I started off thinking that Emdebian TDebs could be Arch:all and the existing packages are Architecture: all but this is set to change. Please don't make the same mistake again and again.


I'm grateful to Frans for his comments during my FOSDEM talk - it will involve extra work to fix the Emdebian TDeb support but it is worthwhile.
Emdebian TDebs are just like Emdebian debs - they are customised versions using Emdebian methods that turn a stock Debian package into something suitable for embedded devices. Debian debs differ from Emdebian debs. Debian TDebs will (when they exist) differ from Emdebian TDebs but the principles of splitting out the .mo files and handling installation etc. are similar.
Packages files
Emdebian needs a different solution to the Debian method, at least initially - principally so that we can have a solution that works now, without extensive changes to the rest of Debian. That solution is available in Emdebian.
Selecting languages
The Debian TDeb proposed method is not implemented currently and GLib includes simple support for retrieving the list of languages selected. Again, Emdebian has implemented a solution that works now, not something that is only a proposal on a wiki page.
Eddy, AFAICT almost nothing has happened to bring TDebs to Debian since Debconf7 and until something concrete exists in Debian, Emdebian simply needs something that works - now.
So:
Q: Are .mo files architecture dependent?
A: Yes.

Q: Does it matter?
A: Yes, for embedded devices.

Q: What about this test or that test?
A: Irrelevant because the tests are done on Debian boxes that convert the data transparently, not an embedded device where the time delay would be problematic.

Q: The packages fill will explode!
A: Yes, it would but both Emdebian and Debian have solutions for this problem.

Q: How to select languages?
A: Normal methods using dpkg and locales, but these are also likely to be customised for embedded usage.

Q: Do tdebs support anything else than gettext?
A: No. Emdebian TDebs only support gettext until such time as Debian has a fully implemented solution that can be customised for embedded devices during the normal Emdebian cross builds.

Patrick Winnertz: First pics from CLT08 online

After nearly 2 days I'll put some fotos of the CLT08 online. It's a quite cool event which many nice people and I'm pleased to meet them (again). :) In some minutes is the start of the social event, I'll hope it will be as good as the last year, which many very cool drinks ;-) Have fun to view the fotos! (Sorry for some not so good pictures :))

29 February 2008

Eddy Petri&#537;or: sarge + cowbuilder = love

Update:
A disclaimer/warning is needed: UNLESS you KNOW what you're doing, you probably are better off building packages for each of the supported Debian distros.


I know it sounds cheesy, but I couldn't find a better name.


At my workplace we are packaging software to work for as many distros as possible at one time. As a consequence the .deb packages we produce should work fine on all Debian distros: oldstable, stable, testing, sid.

To make sure we achieve that, we are building them in an oldstable chroot. OTOH, using pbuilder is very demanding on I/O, especially when entering the chroot and when exiting it. That slows down a lot the build system and is time to change that.


One reliable alternative is to use cowbuilder (part of cowdancer package). What is interesting is that cowbuilder relies on the existance of /usr/bin/cow-shell inside the chroot, so the cowdancer package needs to be installed both in the chroot and the host machine.

But cowdancer was not a part of sarge, so, if you try to create a new sarge cow directory with cowbuilder, it will fail at the end saying it didn't found the cowdancer package. Also trying to login via cowbuilder --login will complain it didn't found /usr/bin/cow-shell.


The fix for this is simple, once you figured it out and saw that cowdancer is available in sarge as a backport:
cowbuilder --create --distribution sarge --basepath /var/cache/pbuilder/sarge.cow --othermirror 'deb http://www.backports.org/debian sarge-backports main'
You may prefer to be sure that the only thing from backports is cowdancer and use a more hands-on approach[1]. Also, this will eliminate the need to correct later the apt sources to exclude backports[2].

Write the same command as before, but omit everything starting with --othermirror. Then install by hand the package in the chroot.
twix:/home/eddy# cowbuilder --create --distribution sarge --basepath /var/cache/pbuilder/sarge.cow
twix:/home/eddy# chroot /var/cache/pbuilder/sarge.cow
twix:/# wget http://ftp.de.debian.org/backports.org/pool/main/c/cowdancer/cowdancer_0.23~bpo.1_i386.deb
twix:/# dpkg -i cowdancer_0.23~bpo.1_i386.deb
twix:/# rm cowdancer_0.23~bpo.1_i386.deb
twix:/# exit
twix:/home/eddy# cowbuilder --update


Since after the bootstrap all .deb packages will be in the apt cache in the chroot, you might want to save some disk space:
twix:/home/eddy# cowbuilder --login --save-after-login
twix:/# aptitude clean
twix:/# exit

That's it!


If anything is broken somehow, missing or whatnot, cowbuilder --login --save-after-login is your friend.

[1] the initial bootstrap does not pull from backport anything else but cowdancer
[2] since you want to compile for plain sarge, not sarge+backports ;-)

Ben Armstrong: Using wiki.debian.org for project management

From the start of the DebianEeePC project, we have used a combination of the irc channel and our wiki site to our great advantage. The DebianEeePC/HowTo/Install document has been actively maintained as we go, serving not only as a good reference for new users, but also for existing users and developers to see where improvements are being made and what is left to work out. Recently, we’ve started using the wiki for task management as well. Patterned after DebianInstaller/Bugs, we now have DebianEeePC/Bugs where we link to reports on the BTS for packages we maintain and our own usertags on packages we don’t maintain. As well, we are keeping a DebianEeePC/Todo to manage our tasks. I see from a search through the wiki that lots of other Debian subprojects keep Todo lists, but most of them have little more structure than point-form lists. A few, though, have structured these pages a bit more carefully. For instance, some of these use tables listing who each task is assigned to, when it was assigned, and when it is completed. Our point-form list is a bit more free-form regarding task assignments. Participants can register their interest in a given task and what they are doing as a subpoint of the task. As for state changes over time, we rely on the revision history on “info” page for people to be able to see state changes for particular Todo items. When something is done, it just gets dropped from the list. I haven’t exhaustively reviewed everyone’s Todo page, but from my brief survey I haven’t seen a couple of things I’ve added to try to help people choose what to do next. The first is to tag items with six difficulty/importance pairs, rating each actionable item from Easy/Urgent to Hard/Wishlist. The second is to state dependencies between items using anchors. It would be nice to see any of you are doing something similar and hear about whether it has worked out well for you. I’m happy with how the irc/wiki combination has helped with project management. In the past with a different project I’ve made an abortive attempt to use the task management system at Alioth, but it just seemed too cumbersome and nobody ended up using it. With the wiki, it appears barriers to participation in task management are sufficiently lowered that everyone is willing to help keep it up. And with irc, we can keep on top of defining and assigning (or more usually volunteering to do) various tasks, and making sure the wiki is kept completely up to date. It takes a bit of discipline to do, but after the habits are established, it gets easier, and the rewards are well worth it.

28 February 2008

Andrew Pollock: [debian] It's all Bob's fault (or 3 years of maintaining dhcp3)

So today is the third anniversary of my first upload of the ISC DHCP v3 package to Debian. It all started back in the days of the linux.conf.au 2005 organising committee. Bob Edwards, who ran the ANU Department of Computer Science computer labs (which ran on Debian at the time), was constantly complaining about bugs like #286011, once he'd found out I was a Debian developer. So I figured I'd try and do something about it, so I think I emailed the maintainers, who had been fairly inactive (the last upload before mine was in July the year before), and asked if they'd like me to NMU the package. I think Matt Zimmerman emailed me back and told me to knock myself out, and add myself as an uploader while I was at it, and well, the rest is history... I've had fun fixing bugs, trying to clean things up, deal with a pretty archaic upstream build system and get the package up to current Debian standards compliance. One of the highlights was being able to finally get rid of Debian Installer's dependence on the v2 DHCP client package, so we could finally jettison the v2 packages for Lenny (which reminds me, I still have to figure out how to handle the transition from Etch with respect to that). I've been working hard to try and get as many of the patches in Debian's DHCP packages incorporated upstream. Unfortunately, they have a totally unpredictable release cycle, and they have feature releases and bug fix releases. The feature releases are very few and far between, and they won't introduce new features into a bugfix release. Speaking of patches, my personal philosophy is that distribution packages shouldn't differ radically in behaviour or functionality from their upstream source, so I've resisted incorporating some of the more deviant patches from Ubuntu, instead forwarding them directly upstream. There's still a bit of work to be done with the package. The ISC released version 3.1.0 a while ago, and that's the version I'm trying to standardise on for Lenny. It's got new support for a domain-search option, which means people can stop abusing the domain-name option to set a domain search list in their clients. The domain-search option is also honoured by Mac OS X (Leopard), and I dare say Windows Vista probably supports it as well, but I haven't checked. Unfortunately the client-side support for the domain-search option is a bit flaky in 3.1.0, so I'm hoping the ISC will release 3.1.1 real soon now, as I believe most of the flakiness issues are addressed in it. Of course, for Lenny to do the right thing consistently with this new option, #460609 and #465158 need to be resolved also. The last thing I'm trying to sort out for Lenny is the reasonably in-demand LDAP patch. It's been floating around out-of-tree for longer than I've been maintaining the package. Jos L. Redrejo Rodr guez has been kind enough to clean up the patch for me, so that rather than bastardising the standard DHCP package to build a dhcp3-server package that has LDAP support, it basically builds DHCP twice, once with the patch and once without, and the dhcp3-server-ldap package just diverts /usr/sbin/dhcpd3 out of the way and plonks in the LDAP-enabled binary in its place. I hope to upload a new revision of the package that builds this new binary package within the next week (hopefully this weekend). After that's done, and hopefully 3.1.1 has been released, and Lenny is out of the way, I'm going to focus on transitioning away from a versioned set of DHCP packages. The whole "3" in everything was to allow the v2 and v3 packages to coexist. I've sought advice from the release team about this, and they said not to bother, but it feels really gross to have the version 4 package (4.0.0 has been released by the ISC for a while now as well) be still called dhcp3, and to install into /etc/dhcp3 and other such versioned directories. The final thing I want to look into is collaborative maintenance. I've been wanting to do this for a while, but I wanted to get the package into a revision control system (shock horror, it's not currently) and I've been baulking at how to do it the "right" way. I'm pretty sold on using Git for the revision control system, I just haven't figured out the right approach yet. Martin Krafft's articles about it have been interesting, but feel a bit overly advanced, and don't quite suit my situation. I've been hesitant to start using Git, then discover I've done it all wrong, and have to start again. I need to just bite the bullet. My upstream also doesn't use Git, and doesn't make their revision control system publicly available, so I just get the tarballs when they're released. Speaking of upstream, I made the discovery last year that they're just down the road from me in Redwood City, so I've been trying to improve relations by getting the main folks who work on DHCP at ISC to pop up to Google for lunch every now and then, which so far has happened twice, and been good a opportunity to have a chat. In fact, they're keen for Debian to join the DHCP Forum (Debian is already a member of the BIND Forum) and I think they've started talking to the Debian folks responsible for our BIND Forum membership about extending that to cover the DHCP Forum as well. So that's about it. I think after three years of being the sole uploader, I'll formally put myself in as the maintainer and Eloy as an uploader until I get around to implementing collaborative maintenance.

John Goerzen: Trac & Git

For quite some time now, I've been running Trac over at software.complete.org. Most of my free software projects -- well, the ones where I actually go to the effort to make formal releases -- have a Trac instance. This Trac instance provides a wiki, bug tracker, downloads area, timeline (with RSS feeds), and VCS integration.

Trac is a nice program, but one thing has bugged me about it all this time:

Every trac instance is its own island.

I have 17 trac instances out there for my projects. To see what bugs are out there on my own server, I have to check 17 websites (or 17 RSS feeds or whatnot). Publishing a new program is not a lightweight process.

So today I started poking around looking for something better. I really like Trac's way of integrating the wiki with the BTS and the commits; wiki markup can refer to a bug or a changeset, and bugs can use wiki markup too.

I looked at Redmine, Mantis, and Roundup, and I also have experience with RT.

Of these, Redmine looks the most interesting. Multiple projects support, per project wiki and forums, gantt charting even, and support for SVN, CVS, Mercurial, Bazaar, and Darcs -- with Git support out there as patches to their development tree already too. Oh, and I saw references to a Trac importer as well. One thing that makes me nervous, though, is that they have no links to sites that use Redmine (except one in the news section), and Google isn't turning up users either. Does nobody use this thing?

What else should I be looking at?

Over on the Git side, I'm still liking Git. I have now migrated several Mercurial projects over to git (see git.complete.org). I am also playing with Darcs to git migration using darcs2git, which also is going well. Sometimes gitk shows a nicer representation of a Git repo converted from Darcs than I was able to get from Darcs.

Filip Van Raemdonck: PyGTK/glade object reuse

Someone asked on the PyGTK mailinglist if it is possible to reuse certain parts of a libglade window several times within an application.
It certainly is, and it's not even hard to do!

I've quickly written a demo application to show how it's done.
The user interface designed in glade is really simple, a textbox with two toggle buttons underneath. Activating one button will display a second, disparate textbox beside the original one. Deactivating it will remove that second textarea.
The other button will display and remove a copy of the first textbox which was there from application startup.
The full widget tree of this interface is shown in the first screenshot. Glade widget tree The actual code to the demo application is rather brief.
The main point to keep in mind is that you can't actually reuse the same widget, more than once, at one time. You could reuse it if you'd make sure it's never used more than once at the same time, and keep track of it (you also have to make certain it doesn't get accidentally destroyed along the way!)

What the demo really does, and what libglade allows you to do, is use (parts of) the same interface definition over and over again to build distinct PyGTK objects and add them to the existing interface. At least the PyGTK implementation of libglade, and possibly the native C libglade as well, actually caches the interface definition in case you'd want to reuse parts of it for additional object creation.

Let's have a closer look at how it's done:
import gtk, gtk.glade
class ReuseDemo:
  def __init__ (self):
    self.gladefile = 'glade-reuse-demo.glade'
    self.xml = gtk.glade.XML (self.gladefile)
    self.win = self.xml.get_widget ('firstWindow')
    self.theContainer = self.xml.get_widget ('theHBox')
    self.xml.signal_autoconnect (
                     dict (gtk_main_quit=gtk.main_quit,
                     btn1_toggled=self.toggle1,
                     btn2_toggled=self.toggle2))
    self.buttons = (self.xml.get_widget ('tbtn1'), self.xml.get_widget ('tbtn2'))
    self.childTree = None
    self.win.show_all()
Demo application window First step is to import the gtk and gtk.glade modules.
The actual demo is in a little class; it's constructor starts by storing the name of the glade file, because it's needed later to construct the additional objects from (even if the caching should mean it isn't really re-read anymore). The xml tree from this file is parsed by pyglade and the window object is retrieved from the first of the two windows defined in it. At this point the window is already a PyGTK object!

The container that needs to have objects added to and removed from is also retrieved and stored as a class attribute. The signals for the two toggle buttons and to allow a graceful exit by means of the windowmanager close button are connected to their handlers, and the two togglebuttons' objects are also retrieved and stored away for later reference. Finally, a variable to hold a reference to the secondary textbox objects is initiated, and the window is shown.
  def toggle1 (self, btn):
    self.toggle (btn, 'txtContent', 1)
  def toggle2 (self, btn):
    self.toggle (btn, 'txtOther', 2)
The two toggle button callbacks call a single method, with the gladeXML tagname for the respective textbox object each one needs to display or remove and an index number for arguments (in addition to the togglebutton object reference that the callback received as it's first argument).
  def toggle (self, btn, tagname, idx):
    self.buttons[(idx%2)].set_sensitive (not btn.get_active())
    if not btn.get_active():
      if self.childTree:
        self.theContainer.remove (self.childTree)
        self.childTree = None
    else:
      objXML = gtk.glade.XML (self.gladefile, root=tagname)
      self.childTree = objXML.get_widget (tagname)
      self.theContainer.pack_end (self.childTree)
The important logic is in the final method. First, the button which is not toggled is disabled or enabled for user interaction, depending on the activated state of the toggled button. Because the indices passed on by the two toggle buttons' callbacks were one-based, while the python tuple that holds references to the toggle buttons is zero-based, the remainder of a division by two of the callback index will automatically point to the button that was not toggled. Alternatively the values 1 and 0, in that order, and thus pointing directly to the tuple indices could also have been used as index arguments for the two callbacks.

The necessity of disabling the other button when one is activated, and therefore two textboxes are displayed, is because the demo isn't written to support displaying more than two textboxes at the same time, but especially removing the correct textbox when three would be visible. If it were extended in that sense, the need to disable the other button would disappear.

Next the activated state is tested; if the button is deactivated, the second textbox is removed from the container and the reference to it removed, while if it's activated, a new object is instantiated from the gladeXML description and added to the container.
Here's where the gladeXML tagnames come in: to recreate only part of the widget tree, and retrieve the actual widget from the parsed tree. Note that you must reconstruct the parse tree here; retrieving the same object from the original parsetree and trying to add it a second time to the container will result in a GTK+ warning (on the console) and nothing being added at all.

That's all there is to it, really. All that is left is to instantiate a class instance and start the GTK+ mainloop:
if __name__ == '__main__':
  ReuseDemo()
  gtk.main()
The second screenshot is an example of how the application might look in one specific state.

A tarball with the glade and python code is available from the sysfs download area.

Adeodato Sim : Oh really?

To make sure we achieve that, we are building them in an oldstable chroot.
My eyes stare at that sentence in disbelief. Eddy, I’m sure it must be working out for you nicely (otherwise you wouldn’t blog about it), but could you at least be so kind as to include a disclaimer saying this method is not guaranteed to work, and why? (eg. soname bumps). TIA, WTF, HAND.

Eddy Petri&#537;or: Postfix - (almost) a satellite system

When installing postfix and configuring it to act as a "Satellite system", all mails, including messages to root, will go to the remote mail delivery system. Also, there might be a local user account that absolutely doesn't exist on the remote MTA and should stay on the local machine, but, by default, this doesn't happen.

This is not good.

What is needed in such a case is virtual_alias_maps and a /etc/postfix/virtual file such as:

root root@localhost
root@fqdn.domain.name root@localhost
eddy eddy@localhost
eddy@fqdn.domain.name eddy@localhost

Don't forget to run postmap /etc/postfix/virtual, after restarting the system.


This tip is particularly useful on laptops.

MJ Ray: Current Issues / Council Chief Exec Online Chats

The council chief executive is currently open for online chats for another 30 minutes at the council web site.  You need a fully tricked-out browser and will probably have to wait some time.  It's not really an online question time - you can't see anyone else's questions being answered.  I'll post here about my experience later.

MJ Ray: SPI Meeting Wed 27 Feb 1900Z irc.oftc.net/#spi

The SPI meeting mentioned took place on Wed 27 Feb 2008 1900Z. I've posted the highlights and log to spi-general. I wasn't there because I was moderating the local cycle forum's meeting. It's a little disappointing that the announcement was so late, but at least it happened. It seems very disappointing that correspondence isn't being reported by the secretary, but maybe there's some innocent explanation that will come out now I've asked the question on-list.

MJ Ray: Current Issues / NS Cycle Forum 2008-02-27

I was at the North Somerset Cycle Forum yesterday.  There wasn't any feature presentation, but there were still several interesting topics.

We reviewed last year's work and were introduced to the 08/09 work programme. Lots of last year's work was completed, or is nearly done and the funding for the couple of failed projects was transferred elsewhere.

Among things that have been improved but not completed last year was Hewish rail bridge. That bridge on NCN 33 is single-track with "temporary" lights which are dangerous because they don't detect cyclists accurately. There is now a cycle bypass of the lights along a shared surface, but Network Rail do want to fix it before it collapses and they want a fairly large contribution from NSCouncil to make it take 40 tonnes instead of 7 tonnes. That's been put forward for 09/10 year funding, because it will remove lorries from a long diversion through residential areas in Ebdon, Ebdon Grounds and North Worle.

On the Strawberry Line (NCN 26), work on Winscombe to Shute Shelf and Congresbury station are about to go out to tender now. Sandford ramp should be built late spring. The River Yeo crossing at Tutshill (which will take 7 miles and Congresbury off Weston-Clevedon rides) will be investigated independently of the tidal trail walk.  The town end of the current Locking Road WsM cycle lanes are up for improvement, as is New Bristol Road Worle.

We looked at the latest draft of the North Somerset Cycle Map and suggested changes.  My contributions were to suggest remapping part of North Worle and marking Clevedon Road WsM as a suggested route, because I think that will have benefits when the Tropicana is rebuilt.

North Somerset are applying for Weston-super-Mare to be one of the new cycling demonstration towns.

Combining two of my hats, I agreed to take up the loss of (council?) cycle stands from the Cooperative Food store (ex-LocalPlus) in Long Ashton and see if we can behave better. 

Future meetings: Thu 24 Apr, Tue 24 June (both 6pm), Wed 10 Sep, Thu 13 Nov, Tue 6 Jan, all Locking Castle Campus Room 2 unless changed.

Any comments or questions?

27 February 2008

John Goerzen: Finally

About a week and a half ago, I had to call in to work. The conversation went about like this:

Me: I'm going to be a little late today. I'm stuck in the mud, but I'm still on the road.

Other end: (Laughter).. *ahem* I'm sorry, but that sounded really funny.

From our house, we can take either the south road or the north road to lead to the highway. The north road always has at least some rock or sand on it. The south road is just dirt. And at the corner where it meets our road, it's dirt in a flood area with lots of trees around it. Meaning that is is often impassible.

But the south road saves me 1.3 miles each way on my drive in to work. So I like to take it when I can.

Lately we've had moisture, but since it's winter, the mud and water on the south road freezes overnight sometimes. Generally I figure that if the mud all over on our own yard is frozen, it's safe to take the south road.

Last week, our yard was frozen. The mud was solid and there were patches of ice. So I started heading towards the south road. I got to the corner, and there was ice and solid-looking frozen mud. So I went ahead. And promptly fell through the ice and landed in the water -- and mud -- beneath it.

Not good. I figured I'd try to get out of it. I actually was able to move the car, and got to within 5 feet of the solid ground, but there was just no going past there. So I called a neighbor with a tractor, and called in to work while he made his way over. He wasn't sure if he wanted to pull our car out from the front, so, due to his location, he had almost a 3-mile tractor drive.

Meanwhile, I worked to get the car as far back as I could. He pulled me out with no problems. I offered to pay, but he wouldn't accept anything. I stopped at home for a quick change of clothes and shoes (I had hopped out in the mud to try to find any sort of debris or something that could provide better traction), then went in to work -- only an hour late.

I got several comments from co-workers. And some "helpful advice" regarding which road I ought to be taking for the next few days. All in good fun, of course.

Terah and I always knew it was just a matter of time before something like this happened.

So, finally, it has. What a relief!

Terah made some buried cherry cookies for me to take over to our neighbors that weekend as a thank-you. He's been pulling people out of that corner for decades, and from the sound of it, I'm just about the most boring one yet.

John Goerzen: Church Choir

Every year on Good Friday, our church choir joins with the other church choir in the area for an evening choir program.

This year we are performing The Seven Last Words of Christ by Theodore Dubois. It's a challenging and beautiful piece. We'll have our combined choir, plus pipe organ and various other instruments.

Easter starts with a sunrise service, then breakfast at church. During the service, we'll sing a number of additional songs. I think the list includes The heavens are telling by Haydn, Ave Verum (KV 618) by Mozart, Love Is Come Again arr. by Parker & Shaw, Praise the Lord by Handel, Alleluia (from Veni Sancte Spiritus, K 47) by Mozart, and Thanks Be to Thee by Handel.

It's a lot of fun to be in the choir, and also quite a joyful time. I'm looking forward to Easter.

Sergio Talens-Oliag: Tips &#x26; Tricks: plone, nginx and path rewriting

The problem On a couple of Debian Etch systems we have a plone-site that is published using a backport of the nginx web server. The Zope instance is running on the standard port and serves the Plone contents under the /plone path. Initially we were publishing the site to the external world using an https site served by nginx using the following entry on the configuration:
  location /plone/  
    proxy_pass http://plone:9673;
    include    /etc/nginx/proxy.conf;
   
The proxy.conf contents are quite standard:
  # proxy.conf
  proxy_redirect                  off;
  proxy_set_header                Host $host;
  proxy_set_header                X-Real-IP $remote_addr;
  proxy_set_header                X-Forwarded-For $proxy_add_x_forwarded_for;
  client_max_body_size            0;
  client_body_buffer_size         128k;
  proxy_connect_timeout           90;
  proxy_send_timeout              90;
  proxy_read_timeout              90;
  proxy_buffer_size               4k;
  proxy_buffers                   4 32k;
  proxy_busy_buffers_size         64k;
  proxy_temp_file_write_size      64k;
With this settings we see the /plone contents using the same path that is used by the Zope instance, but after testing we have decided to change the /plone path and server the contents under the /web path. The Wrong Solution The fist option I though about was quite simple, rename the Zope's plone object to web. Seems reasonable and simple for someone without Zope experience (I don't administer the internals of the Zope/Plone site), but now I know that it is a very big mistake, because renaming objects in Zope in not cheap, as it implies that the server has to modify all the contents of the renamed object and the operation can take a very long time. With my ignorance I tried to rename the plone object using the Zope administrative interface and after a minute or so I cancelled the page loading that was running on my browser, thinking that I had cancelled the rename operation. To make a long story short I'll tell you that the operation was still running and after several hours the folder was renamed (in fact I noticed when the good solution broke, as I had already solved the problem using the next method), but something went wrong and part of the site functionality was broken... the final solution to the debacle has been to recover a backup of the Zope instance older than the rename operation and continue from that copy. The Right Solution (TM) It seems that Zope has a couple of systems to do Virtual Hosting and the best option is the use of the product called Virtual Host Monster, a weird and confusing system (IMHO, of course), that does the job once the right configuration settings are in place. The best solution to our problem was to modify the requests done by the reverse proxy without touching anything on the Plone site (the original one already had a Virtual Host Monster object installed and that was the only thing that we needed to add). The nginx configuration for the new /web path is the following:
  location /web/  
    proxy_pass http://plone:9673/plone/VirtualHostRoot/_vh_web/;
    include    /etc/nginx/proxy.conf;
   
With this change, when the user asks for anything under the /web/ path the Zope server gets the contents traversing the /plone object and adding to it the elements that appear after the VirtualHostRoot component, ignoring components that start with the _vh_ prefix (the protocol and host name of the requests are not modified, as we did not touched that). Once the object is found, the server rewrites the URLs included on the HTML files using the path components that appear after the VirtualHostRoot one, including the suffix of the components that start with the prefix _vh_. For example, when the Zope server receives a request for an URL like:
  http://plone:9673/plone/VirtualHostRoot/_vh_web/home
it publishes the content found on:
  http://plone:9673/plone/home
but the HTML files returned assume that their base URL is:
  http://plone:9673/web/home

Martin F. Krafft: The Cure is back

I just saw The Cure, supported by 65daysofstatic, to which we arrived late. But the organisers had a reason why they started early. True to the concept of a Cure concert, the band played three hours, and two minutes more. And boy was it good. It felt like they were having the time of their lives on stage. Flawless. If you have a chance, see them.

Next.

Previous.