Search Results: "ag"

22 October 2012

Petter Reinholdtsen: Amazon steal books from customer and throw out her out without any explanation

A blog post from Martin Bekkelund today tell the story of how Amazon erased the books from a customer's kindle, locked the account and refuse to tell the customer why. If a real book store did this to a customer, it would be called breaking into private property and theft. The story has spread around the net today. A bit more background information is available in Norwegian from digi.no. It is no surprise that digital restriction mechanisms (DRM) are used this way, as it has been warned about such abuse since DRM was introduced many years back. And Amazon proved in 2009 that it was willing to break into customers equipment and remove the books people had bought, when it removed the book 1984 by George Orwell from all the customers who had bought it. From the official comments, it even sounded like Amazon would never do that again. And here we are, three years later. And thought this action is against Norwegian regulations and law, it is according to the terms of use as written by Amazon, and it is hard to hold Amazon accountable to Norwegian laws. It is just yet another example of unacceptable terms of use on the web, and how they are used to remove customer rights. Luckily for electronic books, there are alternatives without unacceptable terms. For example Project Gutenberg (about 40,000 books), Project Runenberg (1,652 books) and The Internet Archive (3,641,797 books) have heaps of books without DRM, which can read by anyone and shared with anyone. Update 2012-10-23: This story broke in the morning on Monday. In the evening after the story had spread all across the Internet, Amazon restored the account of the user, as reported by digi.no and NRK. Apparently public pressure work. The story from Martin have seen several twitter messages per minute the last 24 hours, which is quite a lot, and is still drawing a lot of attention. But even when the account is restored, the fundamental problem still exist. I recommend reading two opinions from Simon Phipps and Glen Moody if you want to learn more about the fundamentals and more details about the original story.

Erich Schubert: Changing Gnome 3 colors

One thing that many people dislike about Gnome 3, in my opinion is that the authors/maintainers impose a lot of decisions on you. They are in fact not really hard coded, but I found documentation to be really inaccessble on how to change them.
For example colors. I found it extremely badly documented on how to customize GTK colors. And at the same time, a lot of the themes do not work reliably across different Gnome versions. For example the unico engine in Debian experimental is currently incompatible with the main GTK version there (and even worse, GTK does not realize this and refuse to load the incompatible engine). A lot of the themes you can get on gnome-look.org for example use unico. So it's pretty easy to get stuck with a non-working GTK 3, this really should not happen that easily. (I do not blame the Debian maintainers to not have worked around this using package conflicts yet - it's in experimental after all. But upstream should know when they are breaking APIs!)
For my work on the ELKI data mining framework I do a lot of work in Eclipse. And here GTK3 really is annoying, in particular the default theme. Next to unusable, actually, as code documentation tooltips show up black-on-black.
Recently, Gnome seems to be mostly driven by a mix of design and visual motivation. Gnome shell is a good example. No classic Linux user I've met likes it, even my dad immediately asked me how to get the classic panels back. It is only the designers that seem to love it. I'm concerned that they are totally off on their audience, they seem to target the mac OSX users instead of the Linux users. This is a pity, and probably much more a reason why Gnome so far does not succeed on the Desktop: it keeps on forgetting the users it already has. They by now seem to move to XFCE and LXDE because neither the KDE nor the Gnome crowd care about classic Linux users in the hunt for copying OSX & Co.
Anyway, enough ranting. Here is a simple workaround -- that hopefully is more stable across GTK/Gnome versions than all those themes out there -- that just slightly adjusts the default theme:
$ gsettings set \
org.gnome.desktop.interface gtk-color-scheme '
os_chrome_fg_color:black;
os_chrome_bg_color:#FED;
os_chrome_selected_fg_color:black;
os_chrome_selected_bg_color:#f5a089;
selected_fg_color:white;
selected_bg_color:#c50039;
theme_selected_fg_color:black;
theme_selected_bg_color:#c50039;
tooltip_fg_color:black;
tooltip_bg_color:#FFC;
'
This will turn your panel from a designer-hip black back to a regular grayish work panel. If you are working a lot with Eclipse, you'll love the last two options. That part makes the tooltips readable again! Isn't that great? Instead of caring about what is the latest hipster colors, we now have readable tooltips for developers again instead of all that fancy-schmanzy designer orgasms!
Alternatively, you can use dconf-editor to set and edit the value. The tricky part was to find out which variables to set. The (undocumented?) os_chrome stuff seems to be responsible for the panel. Feel free to change the colors to whatever you prefer!
GTK is quite customizable. And the gsettings mechanism actually is quite nice for this. It just seems to be really badly documented. The Adwaita theme in particular seems to have quite some hard-coded relationships also for the colors. And I havn't found a way (without doing a complete new theme) to just reduce padding, for example. In particular, as there probably are a hundred of CSS parameters that one would need to override to get it into everywhere (and with the next Gnome, there will be again two dozen to add?)
Above method just seems to be the best way to tweak the looks. At least the colors, since that is all that you can do this way. If you want to customize more, you probably have to do a complete theme. At which point, you probably have to redo this at every new version. And to pick on Miguel de Icaza: the kernel APIs are extremely stable, in particular compared to the mess that Gnome has been across versions. And at every new iteration, they manage to offend a lot of their existing users (and end up looking more and more like Apple - maybe we should copy more from where we are good at, instead of copying OSX and .NET?).

Benjamin Mako Hill: Lookalikes

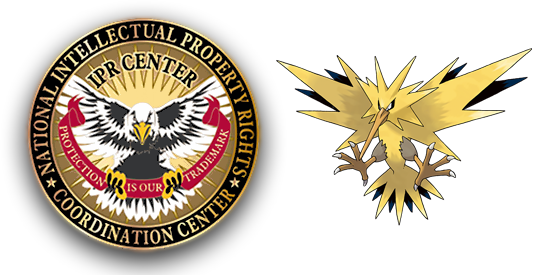
The seal of the National Intellectual Property Rights Coordination Center declares "Protection is Our Trademark." But, is the same seal violating Nintendo's trademark for the Pok mon Zapdos? I'll let you decide. /copyrighteous/images/niprc_zapdos_lookalike.png Thanks to Tomas Reimers for catching this one. Previous lookalikes here and here.

Craig Small: jqGridWidget in Turbogears

Turbogears 2 uses Toscawidgets 2 for a series of very clever widgets and base objects that you can use in your projects. One I have been playing with is the jqGridWidget which uses jquery to display a grid. The idea with jquery is creating a grid or other object and then using javascript to call back to the webserver to obtain the data which usually comes from a database using the very excellent SQLAlchemy framework. I found it a bit fiddly to get going and it is unforgiving, you get one thing wrong and you end up with an empty grid but when it works, it works very well.
from tw2.jqplugins.jqgrid import jqGridWidget
from tw2.jqplugins.jqgrid.base import word_wrap_css
 
class ItemsWidget(jqGridWidget):
    def prepare(self):
        self.resources.append(word_wrap_css)
        super(ItemsWidget, self).prepare()
    options =  
            'pager': 'item-list-pager2',
            'url': '/items/jqgrid',
            'datatype': 'json',
            'colNames': ['Date', 'Type', 'Area', 'Description'],
The code above is a snippet of the widget I use to make the graph. This is the visual side of the graph and shows just the graph with nothing in it. You need the datatype and url lines in the options which tell the code the url to get the data. I have an items controller and within it there is a jqgrid method. Note the number of columns I have, the data sent by the jqgrid method has to match this. Deep inside the items controller is a jqgrid method. The idea is to return some rows of data back to the grid in the exact way the grid expects it otherwise you get, yep more empty grids.
   @expose('json')
    def jqgrid(self, page=1, rows=30, sidx=1, soid='asc', _search='false',
            searchOper=u'', searchField=u'', searchString=u'', **kw):
 
        qry = DBSession.query(Item)
        qry = qry.filter()
        qry = qry.order_by()
        result_count = qry.count()
        rows = int(rows)
 
        offset = (int(page)-1) * rows
        qry = qry.offset(offset).limit(rows)
 
        records = [ 'id': rw.id,
           'cell': [ rw.created.strftime('%d %b %H:%M:%S'), rw.item_type.display_name), rw.display_name, rw.text()]  for rw in qry]
        total = int(math.ceil(result_count / float(rows)))
        return dict(page=int(page), total=total, records=result_count, rows=records)
The four items in the value for the cell in the dictionary must equal the number defined for the colNames. I found it was useful to have firebug looking at my gets and another widget based upon SQLAjqGridWidget which is a lot simpler to setup but much less flexible too.

Julien Danjou: Inside Synaps, a CloudWatch-like implementation for OpenStack

A few days ago, Samsung released the source code of Synaps, an implementation of the Amazon Web Service CloudWatch API for OpenStack. Being a developer on the Ceilometer project, I've been curious to look on this project and how it could overlap with Ceilometer or other projects like Heat. What is CloudWatch? CloudWatch is a monitoring system provided by Amazon on its Web Services platform to monitor services. This allows you get notifications and trigger an action on certain threshold. For example, this can be used to scale your architecture by monitoring the number of requests you get on it and its general load by starting new servers. Synaps Synaps is written in around 7k lines of Python (with 28 % of which are comments), reuses at least one common module of OpenStack (openstack.common.cfg) and copy some modules from Nova. One thing that strikes me, is that there seems to be only a few unit tests compared to most OpenStack projects. Also, many parts of the code and documentation contains text written in korean, which won't be very helpful for most people! :-) It uses some external technologies, like Storm, Cassandra to store its persistent data and Pandas to do data analysis. The API server provides an EC2 compatible API only: no OpenStack specific API. This is probably not a bad thing for now, since I am not aware of any work in this direction. The API access directly the Cassandra back-end for read operation, but relies on RPC to do writes. This way, a set of daemon handles the write using the Storm part of Synaps and do data aggregation. The authentication only supports LDAP, but it should still be possible to add a driver for Keystone. A Java and a Python SDK are provided to record metrics into Synaps, but there's not enough documentation for it to be useful. Overlap with Heat For now, there's not a lot of overlap with Heat, because Heat does not implement completely the CloudWatch API. Heat actually still misses a lot of the CloudWatch functions. But as soon as it will implement the CloudWatch API completely, the overlap will be complete with Synaps in this regard. One divergence point however, is that Heat uses RPC to access data from the storage back-end via its engine (the central daemon), whereas Synaps directly connects to Cassandra. Also, Heat relies on SQLAlchemy, like most OpenStack projects needing a database. Overlap with Ceilometer One of the goal of Ceilometer is to provide data probes and pollsters for all OpenStack components (Nova, Swift, Quantum ) whereas Synaps let the OpenStack users to put any kind of metric inside it, and therefore doesn't provide anything for now. But the storage of metrics is the main common point between Synaps and Ceilometer. Synaps chose only one technology, Cassandra, to store its metrics, whereas Ceilometer took care of building an abstraction layer for the storage engine. Ceilometer currently allows an operator to use SQL or MongoDB, but Cassandra could likely be added. Data metric consolidation is done by Synaps. This makes sense, since Synaps don't need to have the full data history to trigger alarms. On the opposite, Ceilometer needs to have a full history to allow things like billing, and don't do any aggregation on data. Also, in Synaps, the data analysis is done using Pandas. This means the data used are retrieved from the Cassandra back-end, and then transformed by Pandas inside Synaps in something else. It's likely that in such a case, Synaps should use CQL to achieve that. Ceilometer manipulates the data near their storage: it means that the computation are done by back-end to be efficient (SQL, mapreduce ). Conclusion Considering Samsung open-sourced Synaps late in the development process, I don't feel like they aimed to have it becoming a core component. This is always sad, because the effort put into this implementation are big and it would have probably little to add some abstraction layers to follow what other OpenStack projects do. But this takes time and energy, and it's understandable that Samsung didn't want to achieve this in a short time frame. There's a part of the code and architecture that overlaps with Ceilometer and Heat. Ceilometer is becoming a specialized point to store data metrics from any source: so it's sad, but understandable, that Synaps did not tried to reuse it. Fortunately, Heat is working with Ceilometer to achieve exactly that. This means OpenStack would have only one metrics storage point, used for billing, for monitoring and alarming. Therefore, I think Synaps is an implementation of CloudWatch that should be looked at as an inspiration for Heat and Ceilometer to build a better and more integrated solution!

Riku Voipio: F-droid store for android

Christopher complained that in android, you need a user account to install software. That is not true, there is F-droid which is a catalog of Free/Open Source Software, no user account needed. Lack of multitasking is yes annoying sometimes, yes, but that is really a poweruser problem. Most users don't load web pages in background while playing. Most users will simply not bother with web pages that take too long to load. Given the choice, most users will prefer a snappy UI over a UI that allows proper multitasking. N900 was never snappy, stutters were common, and it would often hang for long times if you had too many apps or browser windows open at the same time. Even for Android there are way more complaints about non-fluid UI than lack of proper multitasking. It is thus only logical for the Android developers to concentrate in developing a snappier UI over improving multitasking. The fact that Android has given 400+ million Linux computers out in the hands of consumers is one of the MOST AMAZING THINGS ever. But it seems others on FOSS community seem to consider Android a rather unfortunate event, because it's not "Real Linux" or "100% free software" or "because it's not bug free". Err, like Maemo or MeeGo ever is any of those... It is fair to complain about usability quirks Android as enduser. But if you believe Free Software, you should also see the opportunity the open source parts of Android provides to you fix it to your needs. After all, the point of Free Software is that you don't need to depend on the upstream to fix you everything? Christoph complains that the stock email app is lacking. Android Email app is Open Source (Maemo and N9 email apps are not). Android email has been forked as K-9 Mail. The app lifecycle is fixable allowing you to return from browser to the mail you were at - at least a plenty of other apps manage to do that. The question is, are we consumers or creators. If we are just sitting waiting to Google provide us a perfect shrinkwrapped Android, we could just as well use iPhone or Windows phone. We should instead see Android as an opportunity - when it's 90% open source, fix the remaining closed source bits like open source 3D drivers and open source replacements for proprietary interfaces.

Yves-Alexis Perez: Debian, Xfce 4.10 and Xfce 4.11

It's been six months since Xfce 4.10 has been released. And it's been four months since Wheezy is frozen. Due to this timing (and the fact Squeeze has 4.6 and doing a 4.6 4.10 upgrade needed some tuning in various packages), it was decided to not try to push 4.10 into Wheezy that late in the release cycle. So Xfce 4.10 was uploaded to experimental instead, and as it needs a full rebuild of all panel plugins against 4.10 panel (another reason for not trying to push it to Wheezy), those have not been uploaded. You can try Xfce 4.10 using experimental, but you'll need to remove the xfce4-goodies metapackage and the various depending plugin (since they'll just crash if you try to load them on 4.10 panel). Multiple people asked me (either on IRC, by private or public mail) when 4.10 will be uploaded to unstable and transition to testing. Like last time, the answer is : not before Wheezy is released. Right now, we're more interested in stabilizing Wheezy and squashing the bugs there than adding new ones in unstable. So, if you want to have Xfce 4.10 in Debian sid/testing sooner, then the easiest and fastest way is to fix some release critical bugs so we can release sooner, and then start breaking sid by uploading a whole lot of new stuff there. Note that this is true also for other software like GNOME, KDE stack (I have no idea how to call it these days), the Linux kernel, strongswan or whatever. About development releases of Xfce 4.11 (like the recently released exo 0.9 and Thunar 1.5), well, since we already use experimental for 4.10, there's not much chance they get uploaded anytime soon. We could try to package them and let people build it themselves, or I could host it somewhere on my server for people to try. But as I already said, we're more interested in fixing bug in Wheezy right now, and people interested in finding bugs in Xfce development releases (so they are fixed for the final one) should build it themselves and report everything they find on the Xfce bugzilla. TL;DR: if you care about new, shiny stuff, please help fixing RC bugs in Wheezy.

21 October 2012

Jon Dowland: Dropbox and drive letters

For long-winded reasons I'd rather not explain nor defend, my partner uses Dropbox for a large set of important files (~70G), which are stored on a removable drive. She is also a Windows user. Recently, by introducing a few new drives, I inadvertently changed the drive letter that is assigned to her portable device, which stopped Dropbox from working. Solving this properly is rather finicky so I thought I'd write down what I did. The end goal is to try and ensure that the portable drive always gets the same drive letter and that Dropbox is configured to use that drive letter, but before I can get that far I need to get Dropbox syncing again. It used to be F:, and I opted for U: going forward. Luckily the extra letters I'd introduced were all partitions on a separate hard drive from the OS, so I powered the machine down, unplugged the extra hard drive and booted back up. This freed up the stolen drive letters, but the portable drive did not re-inherit them. Running regedit as an administrative user and renaming keys in HKEY_LOCAL_MACHINE\SYSTEM\MountedDevices moved the USB drive back to the correct letter, but I suspected the extra hard drive would take precedence when it was back, so this was only an interim solution. With the portable drive back on F:, the Dropbox client was happy once again. However I needed to reconfigure the Dropbox client to use a different letter. I wasn't happy with the idea of altering the Dropbox client's configuration database under its feet, so I had to do everything "by the book". Luckily, the client supports the notion of moving your Dropbox folder. Combined with the command-prompt subst command (run as the local user rather than as an admin this time), I was able to clone the F: drive to a virtual U: drive, and then ask Dropbox to move the folder.
subst U: F:\
This was pretty awkward. F:\Dropbox and U:\Dropbox are in fact the same folder, so I needed to ask Dropbox to move it from F: to something other than U:. I opted for U:\tmp. The move took a long time (~2 hours). The proper solution is to try and get a stable drive letter for her device. This can be achieved using a tool called 'USB Drive letter Manager', or USBDLM. USBDLM is free for educational use, and my partner is a teacher, which is lucky. Once that's all sorted, reboot, insert portable device, ensure it's on the right drive letter, and move the Dropbox folder back down to U:. This time the move was near instantaneous.

Gregor Herrmann: RC bugs 2012/42

as zack has mentioned earlier today, the count of RC bugs is falling. & the release team is again proposing RC buggy packages for removal from testing.

these were my RC bug related activities during the last week:

Jonas Smedegaard: How I (don't) use Facebook images

Dear Facebook friend, I like you and I am happy that you take/tag/share photos of me, just not on Facebook! I have a Facebook account but don't hang out there. Please share your photos in public, not (only) inside Facebook. And please consider allowing Free reuse of your photos, by licensing them with a Free license like CC-BY-SA or CC0.

Here & Now My suggestion for now is to use Flickr, and license all images as "Attribution, share alike".

The Perfect Way Ideally you would publish the photos on some server that you control, like the Freedombox, but those are unfortunately not yet easy to find or use.

Why not Facebook? Facebook is a closed system: all activities happen at one central place. Maybe you don't care who is spying on the photo gallery that you share. That's fine - but please respect those of your friends who do care, by putting a copy of your photos somewhere with less thirdparty control. Regards, Jonas

Christian Perrier: [life] Running update: nearly qualified for Boston marathon...

That was not my target in today's marathon (my second one in the year). The target was breaking my 3h38'45" record, set on June 10th in Caen. And, well, I did it. By more than 5 minutes \o/. Of course, the Seine-Eure marathon is the perfect place for this: My target was running 5'06"/km, so 3h35'11" (but the target was running this as long as possible and see what happens after km 35). I did this nearly perfectly in the first half, reaching the half-marathon in 1h47'30". Double this and you get 3h35'..:-) "However", I slightly accelerated in the second half, first without noticing, then because....I just could do it..:-). So I managed to run the second half at an average 5'/km, with even the last 2 kilometers around 4'50" and an amazing sprint at the end. Usain bubulle. The outcome is 3h33'35". Doh. Never thought I could do this. It seems that my unusual preparation (remember the "let's run a marathon when coming back from work, at night", in September? or the 5 half-marathons in a row....culminating in a 3/4 marathon in the 6th week-end?)...was not so bad. I'm now very close to qualifying times for Boston, my dream marathon (much more than NYC) as they are 3h30' for my age category. Well, another option is to wait turning 55, where the qualifying time is then 3h40..:-)...but it woudl be quite good to complete one under 3h30. Now, it doesn't look like a dream. We'll see at the end of next year as I will only run one marathon, in autumn, more focusing Spring on ultra running (and, technically, a marathon, but that will be the Mont-Blanc marathon, just before Debconf13....and these 42.195km are quite different from those in Normandy!

20 October 2012

Ritesh Raj Sarraf: Debian Boot time

<iframe frameborder="0" height="350" src="http://www.youtube.com/embed/cTK3aIZbe2A" width="425"></iframe> In case, the video doesn't show on the page, http://www.youtube.com/watch?v=cTK3aIZbe2A This blog post is to show-off the impressive performance I saw with my machine.
I recently switched to a ThinkPad W530 laptop. It is a fairly recent machine with the following hardware config:
  • Intel(R) Core(TM) i7-3720QM CPU @ 2.60GHz
  • 8 GiB RAM
  • nVIDIA Optimus
  • Samsung SSD Drive
On the software front, I decided to take my chances. Hence:
  • BTRFS File System
  • SystemD Init
The rest is in the video. It is impressive to see how drastically the experience has changed with this combination.
From my limited time spent exploring the machine, all credit goes to the SSD technology.

Vincent Bernat: Network lab with KVM

To experiment with network stuff, I was using UML-based network labs. Many alternatives exist, like GNS3, Netkit, Marionnet or Cloonix. All of them are great viable solutions but I still prefer to stick to my minimal home-made solution with UML virtual machines. Here is why: The use of UML had some drawbacks: However, UML features HostFS, a filesystem providing access to any part of the host filesystem. This is the killer feature which allows me to not use any virtual disk image and to get access to my home directory right from the guest. I discovered recently that KVM provided 9P, a similar filesystem on top of VirtIO, the paravirtualized IO framework.
Setting up the lab The setup of the lab is done with a single self-contained shell file. The layout is similar to what I have done with UML. I will only highlight here the most interesting steps.

Booting KVM with a minimal kernel My initial goal was to experiment with Nicolas Dichtel s IPv6 ECMP patch. Therefore, I needed to configure a custom kernel. I have started from make defconfig, removed everything that was not necessary, added what I needed for my lab (mostly network stuff) and added the appropriate options for VirtIO drivers:
CONFIG_NET_9P_VIRTIO=y
CONFIG_VIRTIO_BLK=y
CONFIG_VIRTIO_NET=y
CONFIG_VIRTIO_CONSOLE=y
CONFIG_HW_RANDOM_VIRTIO=y
CONFIG_VIRTIO=y
CONFIG_VIRTIO_RING=y
CONFIG_VIRTIO_PCI=y
CONFIG_VIRTIO_BALLOON=y
CONFIG_VIRTIO_MMIO=y
No modules. Grab the complete configuration if you want to have a look. From here, you can start your kernel with the following command ($LINUX is the appropriate bzImage):
kvm \
  -m 256m \
  -display none \
  -nodefconfig -no-user-config -nodefaults \
  \
  -chardev stdio,id=charserial0,signal=off \
  -device isa-serial,chardev=charserial0,id=serial0 \
  \
  -chardev socket,id=con0,path=$TMP/vm-$name-console.pipe,server,nowait \
  -mon chardev=con0,mode=readline,default \
  \
  -kernel $LINUX \
  -append "init=/bin/sh console=ttyS0"
Of course, since there is no disk to boot from, the kernel will panic when trying to mount the root filesystem. KVM is configured to not display video output (-display none). A serial port is defined and uses stdio as a backend1. The kernel is configured to use this serial port as a console (console=ttyS0). A VirtIO console could have been used instead but it seems this is not possible to make it work early in the boot process. The KVM monitor is setup to listen on an Unix socket. It is possible to connect to it with socat UNIX:$TMP/vm-$name-console.pipe -.

Initial ramdisk UPDATED: I was initially unable to mount the host filesystem as the root filesystem for the guest directly by the kernel. In a comment, Josh Triplett told me to use /dev/root as the mount tag to solve this problem. I keep using an initrd in this post but the lab on Github has been updated to not use one. Here is how to build a small initial ramdisk:
# Setup initrd
setup_initrd()  
    info "Build initrd"
    DESTDIR=$TMP/initrd
    mkdir -p $DESTDIR
    # Setup busybox
    copy_exec $($WHICH busybox) /bin/busybox
    for applet in $($ DESTDIR /bin/busybox --list); do
        ln -s busybox $ DESTDIR /bin/$ applet 
    done
    # Setup init
    cp $PROGNAME $ DESTDIR /init
    cd "$ DESTDIR " && find .   \
       cpio --quiet -R 0:0 -o -H newc   \
       gzip > $TMP/initrd.gz
 
The copy_exec function is stolen from the initramfs-tools package in Debian. It will ensure that the appropriate libraries are also copied. Another solution would have been to use a static busybox. The setup script is copied as /init in the initial ramdisk. It will detect it has been invoked as such. If it was omitted, a shell would be spawned instead. Remove the cp call if you want to experiment manually. The flag -initrd allows KVM to use this initial ramdisk.

Root filesystem Let s mount our root filesystem using 9P. This is quite easy. First KVM needs to be configured to export the host filesystem to the guest:
kvm \
  $ PREVIOUS_ARGS  \
  -fsdev local,security_model=passthrough,id=fsdev-root,path=$ ROOT ,readonly \
  -device virtio-9p-pci,id=fs-root,fsdev=fsdev-root,mount_tag=rootshare
$ ROOT can either be / or any directory containing a complete filesystem. Mounting it from the guest is quite easy:
mkdir -p /target/ro
mount -t 9p rootshare /target/ro -o trans=virtio,version=9p2000.u
You should find a complete root filesystem inside /target/ro. I have used version=9p2000.u instead of version=9p2000.L because the later does not allow a program to mount() a host mount point2. Now, you have a read-only root filesystem (because you don t want to mess with your existing root filesystem and moreover, you did not run this lab as root, did you?). Let s use an union filesystem. Debian comes with AUFS while Ubuntu and OpenWRT have migrated to overlayfs. I was previously using AUFS but got errors on some specific cases. It is still not clear which one will end up in the kernel. So, let s try overlayfs. I didn t find any patchset ready to be applied on top of my kernel tree. I was working with David Miller s net-next tree. Here is how I have applied the overlayfs patch on top of it:
$ git remote add torvalds git://git.kernel.org/pub/scm/linux/kernel/git/torvalds/linux-2.6.git
$ git fetch torvalds
$ git remote add overlayfs git://git.kernel.org/pub/scm/linux/kernel/git/mszeredi/vfs.git
$ git fetch overlayfs
$ git merge-base overlayfs.v15 v3.6
4cbe5a555fa58a79b6ecbb6c531b8bab0650778d
$ git checkout -b net-next+overlayfs
$ git cherry-pick 4cbe5a555fa58a79b6ecbb6c531b8bab0650778d..overlayfs.v15
Don t forget to enable CONFIG_OVERLAYFS_FS in .config. Here is how I configured the whole root filesystem:
info "Setup overlayfs"
mkdir /target
mkdir /target/ro
mkdir /target/rw
mkdir /target/overlay
# Version 9p2000.u allows to access /dev, /sys and mount new
# partitions over them. This is not the case for 9p2000.L.
mount -t 9p        rootshare /target/ro      -o trans=virtio,version=9p2000.u
mount -t tmpfs     tmpfs     /target/rw      -o rw
mount -t overlayfs overlayfs /target/overlay -o lowerdir=/target/ro,upperdir=/target/rw
mount -n -t proc  proc /target/overlay/proc
mount -n -t sysfs sys  /target/overlay/sys
info "Mount home directory on /root"
mount -t 9p homeshare /target/overlay/root -o trans=virtio,version=9p2000.L,access=0,rw
info "Mount lab directory on /lab"
mkdir /target/overlay/lab
mount -t 9p labshare /target/overlay/lab -o trans=virtio,version=9p2000.L,access=0,rw
info "Chroot"
export STATE=1
cp "$PROGNAME" /target/overlay
exec chroot /target/overlay "$PROGNAME"
You have to export your $ HOME and the lab directory from host:
kvm \
  $ PREVIOUS_ARGS  \
  -fsdev local,security_model=passthrough,id=fsdev-root,path=$ ROOT ,readonly \
  -device virtio-9p-pci,id=fs-root,fsdev=fsdev-root,mount_tag=rootshare \
  -fsdev local,security_model=none,id=fsdev-home,path=$ HOME  \
  -device virtio-9p-pci,id=fs-home,fsdev=fsdev-home,mount_tag=homeshare \
  -fsdev local,security_model=none,id=fsdev-lab,path=$(dirname "$PROGNAME") \
  -device virtio-9p-pci,id=fs-lab,fsdev=fsdev-lab,mount_tag=labshare

Network You know what is missing from our network lab? Network setup. For each LAN that I will need, I spawn a VDE switch:
# Setup a VDE switch
setup_switch()  
    info "Setup switch $1"
    screen -t "sw-$1" \
        start-stop-daemon --make-pidfile --pidfile "$TMP/switch-$1.pid" \
        --start --startas $($WHICH vde_switch) -- \
        --sock "$TMP/switch-$1.sock"
    screen -X select 0
 
To attach an interface to the newly created LAN, I use:
mac=$(echo $name-$net   sha1sum   \
            awk ' print "52:54:" substr($1,0,2) ":" substr($1, 2, 2) ":" substr($1, 4, 2) ":" substr($1, 6, 2) ')
kvm \
  $ PREVIOUS_ARGS  \
  -net nic,model=virtio,macaddr=$mac,vlan=$net \
  -net vde,sock=$TMP/switch-$net.sock,vlan=$net
The use of a VDE switch allows me to run the lab as a non-root user. It is possible to give Internet access to each VM, either by using -net user flag or using slirpvde on a special switch. I prefer the latest solution since it will allow the VM to speak to each others.

Debugging This lab was mostly done to debug both the kernel and Quagga. Each of them can be debugged remotely.

Kernel debugging While the kernel features KGDB, its own debugger, compatible with GDB, it is easier to use the remote GDB server built inside KVM.
kvm \
  $ PREVIOUS_ARGS  \
  -gdb unix:$TMP/vm-$name-gdb.pipe,server,nowait
To connect to the remote GDB server from the host, first locate the vmlinux file at the root of the source tree and run GDB on it. The kernel has to be compiled with CONFIG_DEBUG_INFO=y to get the appropriate debugging symbols. Then, use socat with the Unix socket to attach to the remote debugger:
$ gdb vmlinux
GNU gdb (GDB) 7.4.1-debian
Reading symbols from /home/bernat/src/linux/vmlinux...done.
(gdb) target remote   socat UNIX:$TMP/vm-$name-gdb.pipe -
Remote debugging using   socat UNIX:/tmp/tmp.W36qWnrCEj/vm-r1-gdb.pipe -
native_safe_halt () at /home/bernat/src/linux/arch/x86/include/asm/irqflags.h:50
50   
(gdb)
You can now set breakpoints and resume the execution of the kernel. It is easier to debug the kernel if optimizations are not enabled. However, it is not possible to disable them globally. You can however disable them for some files. For example, to debug net/ipv6/route.c, just add CFLAGS_route.o = -O0 to net/ipv6/Makefile, remove net/ipv6/route.o and type make.

Userland debugging To debug a program inside KVM, you can just use gdb as usual. Your $HOME directory is available and it should be therefore straightforward. However, if you want to perform some remote debugging, that s quite easy. Add a new serial port to KVM:
kvm \
  $ PREVIOUS_ARGS  \
  -chardev socket,id=charserial1,path=$TMP/vm-$name-serial.pipe,server,nowait \
  -device isa-serial,chardev=charserial1,id=serial1
Starts gdbserver in the guest:
$ libtool execute gdbserver /dev/ttyS1 zebra/zebra
Process /root/code/orange/quagga/build/zebra/.libs/lt-zebra created; pid = 800
Remote debugging using /dev/ttyS1
And from the host, you can attach to the remote process:
$ libtool execute gdb zebra/zebra
GNU gdb (GDB) 7.4.1-debian
Reading symbols from /home/bernat/code/orange/quagga/build/zebra/.libs/lt-zebra...done.
(gdb) target remote   socat UNIX:/tmp/tmp.W36qWnrCEj/vm-r1-serial.pipe
Remote debugging using   socat UNIX:/tmp/tmp.W36qWnrCEj/vm-r1-serial.pipe
Reading symbols from /lib64/ld-linux-x86-64.so.2...(no debugging symbols found)...done.
Loaded symbols for /lib64/ld-linux-x86-64.so.2
0x00007ffff7dddaf0 in ?? () from /lib64/ld-linux-x86-64.so.2
(gdb)

Demo For a demo, have a look at the following video (it is also available as an Ogg Theora video).
<iframe frameborder="0" height="270" src="http://www.dailymotion.com/embed/video/xuglsg" width="480"></iframe>

  1. stdio is configured such that signals are not enabled. KVM won t stop when receiving SIGINT. This is important for the usage we want to have.
  2. Therefore, it is not possible to mound a fresh /proc on top of the existing one. I have searched a bit but didn t find why. Any comments on this is welcome.

Christoph Egger: Android

Hardware To make things clear: I'm having a Android 4.0.$recent tablet with considerably more horse-power than my Nokia n900 smartphone so don't tell me this is due to under-powered hardware the android is 3 years newer both in hardware and software.

Background Tasks Being somewhere with my Android Tablet. Network is kind of crappy and this site takes minutes again to load. So the most natural thing to do would be doing something else while the site continues loading in the background. This works really well on the n900. It might work with android. But of course when you switch to another Program the browser might also be shut down while you're doing something else and randomly when you switch back to your browser, not only the site hasn't loaded but the browser also forgot where you were heading. Now if you followed e.g. a link in a email you might have closed the mail program long ago (or the mail program has decided to stop) and you have to find the link again, wait again for the site to load. And remember not to background the browser or you might have to start over again. With the n900 Maemo smartphone I was able to load several pages in the background with whatever application in the foreground (like playing tuxracer) so don't tell me android has to do this to give enough power to the foreground process. If a Meamo device can load 5 pages in the background while a OpenGL game is running in the foreground there is no reason Android, with more CPU and RAM, can't load a single page in the background while I check email.

Software installation Can you imagine a system where you are unable to install software from your standard repository without registering an account first? Like after nearly two decades of Linux distributions? Maemo had this for mobile devices more than five years ago. Plus, on Maemo you'll easily find tons of good, free (as in freedom) and banner-add-free software try this on androids "Play Store".

Ian Wienand: Blog format update

7 years, 8 months, 17 days, 22 hours and 25 minutes ago I wrote the first post for this blog, inspired by a talk by Andrew Tridgell at linux.conf.au 2004 on the value of a personal "junkcode" repository. I know this because I've recently gone through considerable effort to change the format of the blog and keeping the timestamps in sync was one challenge. I've now updated to use Pelican, massaged all the old posts into reStructuredText, done a fair bit of HTML and CSS hacking and hopefully redirected all the old URLs to the correct place. Old comments didn't make the cut, but there wasn't much value there and I'm happy to outsouce to Disqus. How things have changed! As I was writing the CSS to round the corners of some elements, I remembered back to cribbing from Slashdot HTML to do the same thing -- except in those days you used a table with blank elements in each corner with 4 different rounded-corner gif files! Yet I'm still writing in emacs, so some things will forever remain the same I guess.

Maximilian Attems: Basic understanding^Wmisconception of quantum physics

According to the release manager of Ubuntu the 10.12 release features the most minimal improvements: ''Doing is a quantum leap from imagining. Anyone having a minimal quantum physics exposure should be aware that a quantum leap is a very tiny leap. So according to the paraphrased intro this release should not even contain 'stable updates?!

19 October 2012

Ritesh Raj Sarraf: Reporting bugs with Apport - III

Hello World. This is the follow-up to the last 2 updates on the state of apport in Debian.
A lot has changed since the last update on Apport. Currently, in Experimental, we have version 2.6.1-2. With this version, and going forward, there will be no hacks to make it work for Debian. Thanks to Martin Pitt, with his assistance, Apport now has a very basic crashdb in place for Debian. The Debian crashdb provides Apport the interface to interact with the Debian BTS.
This change is already upstream as part of the 2.6.1 release. So for Debian, the packaging is a mere change of the crashdb from 'default' to 'debian'. Being Just Another CrashDB inside Apport, it leverage full support of future Apport releases, fixes and enhancements.
I would like to highlight some points, and some concerns, I have heard in my previous blog posts.
  • Direct email reports to the developer: This was a concern from the last blog post. There will be no such pop-up anymore. It has been knocked off.
  • Useless/Incomplete bug reports: With no proper backtrace, it is worried that the bug report will be useless. Apport has intellignece to check if the backtrace is complete. If it is not, it will not report the bug.

Pop-up for Incomplete backtrace

  • Opt-Out: What if the maintainer is not interested in apport reports? The maintainer can ship a blacklist hook into /etc/apport/blacklist.d/. See /etc/apport/blacklist.d/README.blacklist for details.
Keywords:

Sylvain Le Gall: Book review: Puppet 2.7 Cookbook

I recently read this book and it was enlightening -- that is the least I can say. It is organized into a set of recipes addressing the most common problems you have with puppet. I think the whole point is about being practical and it gives you various ways to achieve the same goal, depending if you want to do a quick and dirty hack or pick a long term solution. The whole book aims at being practical and it achieves this goal pretty well. However, it is not for beginners. Puppet itself is not for beginner and you should already have written and run into problem to really take advantage of this book. I read the book in 5 days (only while commuting), and at each page I thought : "OMG, they do that like this" or "of course, you should use git + that" and wait impatiently coming back home to test all this stuff. The book is really about technical details and how to organize yourself to write nice Puppet classes. I have been an "irregular" user of Puppet since 4 years. I was mainly running it to distribute files on all my computers. Since 3 weeks, I am applying the recipes found in this book and it is just like discovering that you own something worth a million euros. Let look at some example: Before: Replace the whole file. Now: Use Augeas to just change the value and don't touch to the rest of the file. The book makes me discover Augeas and it rocks !!! Before:_ Loosy darcs repository inside /etc/ and edit directly the master. Now: Shiny git repository in my home directory, using a Makefile to validate Puppet syntax, simulate applying it and effectively apply it to the current node before deploying it through git push. Before: Nothing because I didn't think it was possible. Now: Generate a configuration file using a template, install it, run the exim4 update script and restart the service. Before: Copy a file and restart it. Now: Use Augeas and a template with a loop to change what is needed for each node depending on which user I want to allow to connect on this node. Use different SSH port for every vserver that share the same IP and distribute an /etc/ssh_config to propagate the default ports set for all the vservers... (just being able to do that is worth the price of the book). Before: Complain, whine and give up. Now: Go to Puppet Forge, take inspiration for similar module, re-read part of the book, find an idea and apply it. And so forth and so on. This book made me love puppets again. I warmly recommend it to you.

Lior Kaplan: LibreOffice conference 2012 (day 2)

I ve started the morning with the easy hacks for non developers talks, which for my opinion lacked some code related tasks that even non developers can do like fixing translation problems in the source (in the English strings), fixing some simple logic bugs which doesn t require reading complex code (e.g. traversing records and first/last special cases). The other options mentioned in the talk aren t less important, but I think people shouldn t be afraid reading/touching the code to some level even with very limited coding skills. Later I ve used Rene s 3.7/master builds for Debian to verify two RTL bugs (fdo#43210, fdo#44925) fixed by the Motah guys from Saudi Arabia. After the verification, I pushed the changes to the 3.6 branch (should appear in 3.6.4).
Katya, which I ve met in the last conference, told me see watched my talked remotely, and took interest in RTL ui forcing right alignment to non aligned text. While reproducing the bug on her computer we were able to narrow the problem a bit, to be related to the locale and not only to the RTL interface. Till the end of the day she d identified the problem in the odp file and I hope a fix will be available by tomorrow. Jan (kendy) had a good progress with fdo#44657 (RTL problem #1). Checking the fix is quite confusing, and we had to use two laptops to understand and compare the right and desired behavior. Hopefully this problem will end soon, which will make coming to the conference worthwhile (as for the RTL status and efforts). Later I started working on moving the RTL status page from a wiki in Hebrew to the TDF wiki RTL Bugs page in English . By this I hope to get more visibility to the current status, and as a base to collaboration, let others help with RTL more easily. During one of the breaks I heard Lionel encourages someone to do builds on his own, and I decided that after avoiding this tasks for two years, it s about time. By the evening I got a build running according to the native build guide in the wiki (which took half the night on my laptop). There are still a few things to learn how to do with this build, but I how to now be more active in testing things without waiting for official Debian builds (which are quite hard when Debian is frozen). Thanks to Lionel for the encouragement. http://cgit.freedesktop.org/libreoffice/core/commit/?id=a662d6d8c00f5a1cff724db51b0914aab36e201b
Filed under: LibreOffice

Martin F. Krafft: Digital picture frames and random image order

I am moving into an office. And as any proud husband and father, I want to have photos of my wife and daughter on my desk. The year being 2012, I did not hike to the photo shop to get a print framed, but instead thought to myself that I should put a digital photo frame onto my table. This idea exposed me to the ridiculous world of consumer electronics. It led me to conclude that digital picture frame designers need to be whacked with cluebats. Step by step Once accepted, the thought of a digital photo frame developed into a product definition along the following lines: my idea photo frame would connect to my Wifi-network, and obtain the photos on-the-go from a folder exposed via HTTP or CIFS, and then go on to display them in random order, incorporating new photos as it encounters them. With this in mind, I went to the shops, and since I believe in specialised retailers and want to support them, my first stop was Foto Sauter at Sendlinger Tor. Unfortunately, none of the frames they had came with Wifi, so I decided to look further. I vehemently oppose to the business practices of the Metro group, thus skipped Saturn and MediaMarkt, and eventually ended up at Conrad. They had a frame with Wifi! I jumped for joy, until I read the manual: pictures can be obtained from Flickr and Picasa. Period. All other models on the Internet seem to be similarly limited, including the new Sony S-frame. The night before, Penny had researched the field a bit and came to the conclusion that the S-frame would be the best product available. This led me to scratch Wifi off my requirements list and get a model that would read photos off a USB stick. I went back to the photo store and bought a "Sony S-frame", only to discover that it cannot show photos in random order. It has three viewing modes (single photo, collage, single photo with clock), and a random mode, but guess what: the random mode randomly switches the viewing modes, which then display the photos in lexicographical order. How stupid is that??? I returned the product and left the store after discovering that none of their products could do random playback. I went back to Conrad and found an "Intenso MediaCreator" (what media does it create???), which displayed the photos seemingly randomly. But at home I found out that the "random" order is always the same, probably because the bright engineer that programmed this thought it was better to sort filenames by last letter and call it random, than to figure out a way to roll a dice on the device. I wrote to the support team and asked them. The response was that the desired functionality (random selection) is not possible and won't be made available. So I am returning the product. Gah! Would someone please tell me about a digital picture frame (8 inch or so) that can display images in random order, ideally loading them off a CIFS share via Wifi? Or is it really the case that consumer electronics are completely useless these days, by which I mean that "consumers" have dumbed down so far to buy this crap? Update: a lot of people wrote in suggesting to invest in a cheap Android tablet. Some suggested Raspberry Pis in USB host mode (emulating the USB stick and hence the source of the images, provided that the frame doesn't cache). Other suggestions included the Samsung SPF-85V which can display images according to an RSS feed but needs Microsoft for that (or maybe not), and the community-developed, Linux-based Joggler. Regarding the non-random order on the Intenso frame, Paul Hedderly postulated that the order comes from the filesystems (FAT order) and can be changed by writing the files differently.

Next.

Previous.