Search Results: "xam"

18 September 2020

Daniel Lange: Fixing the Nextcloud menu to show more than eight application icons

I have been late to adopt an on-premise cloud solution as the security of Owncloud a few years ago wasn't so stellar (cf. my comment from 2013 in Encryption files ... for synchronization across the Internet). But the follow-up product Nextcloud has matured quite nicely and we use it for collaboration both in the company and in FLOSS related work at multiple nonprofit organizations. There is a very annoying "feature" in Nextcloud though that the designers think menu items for apps at the top need to be limited to eight or less to prevent information overload in the header. The whole item discussion is worth reading as it it an archetypical example of design prevalence vs. user choice. And of course designers think they are right. That's a feature of the trade.
And because they know better there is no user configurable option to extend that 8 items to may be 12 or so which would prevent the annoying overflow menu we are seeing with 10 applications in use: Screenshot of stock Nextcloud menu Luckily code can be changed and there are many comments floating around the Internet to change const minAppsDesktop = 8. In this case it is slightly complicated by the fact that the javascript code is distributed in compressed form (aka "minified") as core/js/dist/main.js and you probably don't want to build the whole beast locally to change one constant. Basically
const breakpoint_mobile_width = 1024;

const resizeMenu = () =>
const appList = $('#appmenu li')
const rightHeaderWidth = $('.header-right').outerWidth()
const headerWidth = $('header').outerWidth()
const usePercentualAppMenuLimit = 0.33
const minAppsDesktop = 8
let availableWidth = headerWidth - $('#nextcloud').outerWidth() - (rightHeaderWidth > 210 ? rightHeaderWidth : 210)
const isMobile = $(window).width() < breakpoint_mobile_width
if (!isMobile)
availableWidth = availableWidth * usePercentualAppMenuLimit

let appCount = Math.floor((availableWidth / $(appList).width()))
if (isMobile && appCount > minAppsDesktop)
appCount = minAppsDesktop

if (!isMobile && appCount < minAppsDesktop)
appCount = minAppsDesktop


// show at least 2 apps in the popover
if (appList.length - 1 - appCount >= 1)
appCount--


$('#more-apps a').removeClass('active')
let lastShownApp
for (let k = 0; k < appList.length - 1; k++)
const name = $(appList[k]).data('id')
if (k < appCount)
$(appList[k]).removeClass('hidden')
$('#apps li[data-id=' + name + ']').addClass('in-header')
lastShownApp = appList[k]
else
$(appList[k]).addClass('hidden')
$('#apps li[data-id=' + name + ']').removeClass('in-header')
// move active app to last position if it is active
if (appCount > 0 && $(appList[k]).children('a').hasClass('active'))
$(lastShownApp).addClass('hidden')
$('#apps li[data-id=' + $(lastShownApp).data('id') + ']').removeClass('in-header')
$(appList[k]).removeClass('hidden')
$('#apps li[data-id=' + name + ']').addClass('in-header')


// show/hide more apps icon
if ($('#apps li:not(.in-header)').length === 0)
$('#more-apps').hide()
$('#navigation').hide()
else
$('#more-apps').show()

gets compressed during build time to become part of one 15,000+ character line. The relevant portion reads:
var f=function() var e=s()("#appmenu li"),t=s()(".header-right").outerWidth(),n=s()("header").outerWidth()-s()("#nextcloud").outerWidth()-(t>210?t:210),i=s()(window).width()<1024;i (n*=.33);var r,o=Math.floor(n/s()(e).width());i&&o>8&&(o=8),!i&&o<8&&(o=8),e.length-1-o>=1&&o--,s()("#more-apps a").removeClass("active");for(var a=0;a<e.length-1;a++) var l=s()(e[a]).data("id");a<o?(s()(e[a]).removeClass("hidden"),s()("#apps li[data-id="+l+"]").addClass("in-header"),r=e[a]):(s()(e[a]).addClass("hidden"),s()("#apps li[data-id="+l+"]").removeClass("in-header"),o>0&&s()(e[a]).children("a").hasClass("active")&&(s()(r).addClass("hidden"),s()("#apps li[data-id="+s()(r).data("id")+"]").removeClass("in-header"),s()(e[a]).removeClass("hidden"),s()("#apps li[data-id="+l+"]").addClass("in-header"))) 0===s()("#apps li:not(.in-header)").length?(s()("#more-apps").hide(),s()("#navigation").hide()):s()("#more-apps").show()
Well, we can still patch that, can we? Continue reading "Fixing the Nextcloud menu to show more than eight application icons"

17 September 2020

Dirk Eddelbuettel: RcppSpdlog 0.0.1: New and Exciting Logging Package

Very thrilled to announce a new package RcppSpdlog which is now on CRAN in its first release 0.0.1. We had tweeted once about the earliest version which had already caught the eyes of Gabi upstream. RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovic. I had meant to package this for a few years now but didn t find an (easy, elegant) way to completely lift stdout / stderr and related uses which R wants us to remove for smoother operations from R itself including synchronized input/output. It was only a few weeks ago that I realized I should subclass a logger (or, more concretely, a sink for a logger) which could then use R input/output. With the right idea the implementaton was easy, and [Gabi]((https://github.com/gabime) was most helpful in making sure R CMD check would not see one or two remaining C++ i/o operations (which we currently do by not activating a default logger, and substituing REprintf() in one call). So this is now clean and sween and a simple use is included in an example in the package we can show here too (in slightly shorter form minus the documentation header):
// this portmanteau include also defines the r_sink we use below, and which
// diverts all logging to R via the Rcpp::Rcout replacement for std::cout
#include <RcppSpdlog>

// [[Rcpp::export]]
void exampleRsink()  

    std::string logname = "fromR";                          // fix a name for this logger
    auto sp = spdlog::get(logname);                         // retrieve existing one
    if (sp == nullptr) sp = spdlog::r_sink_mt(logname);     // or create new one if needed

    // change log pattern (changed from [%H:%M:%S %z] [%n] [%^---%L---%$] )
    sp->set_pattern("[%H:%M:%S.%f] [%n] [%^%L%$] [thread %t] %v");

    sp->info("Welcome to spdlog!");
    sp->error("Some error message with arg:  ", 1);

    sp->warn("Easy padding in numbers like  :08d ", 12);
    sp->critical("Support for int:  0:d ;  hex:  0:x ;  oct:  0:o ; bin:  0:b ", 42);
    sp->info("Support for floats  :03.2f ", 1.23456);
    sp->info("Positional args are  1   0 ..", "too", "supported");
    sp->info(" :<30 ", "left aligned");

 
The NEWS entry for the first release follows.

Changes in RcppSpdlog version 0.0.1 (2020-09-08)
  • Initial release with added R/Rcpp logging sink example

The only sour grapes, if any, are over the CRAN processing. This was originally uploaded three weeks ago. As a new package, it got extra attention and some truly idiosyncratic attention to two details that were already supplied in the first uploaded version. Yet it needed two rounds of going back and forth for really no great net gain, yet wasting a week each time. I am not all that impressed by this, and not particularly pleased either, but I presume is the tax we all pay in order to enjoy the unsurpassed richness of the CRAN repository system which continues to work just flawlessly. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

16 September 2020

Steve Kemp: Implementing a FORTH-like language ..

Four years ago somebody posted a comment-thread describing how you could start writing a little reverse-polish calculator, in C, and slowly improve it until you had written a minimal FORTH-like system: At the time I read that comment I'd just hacked up a simple FORTH REPL of my own, in Perl, and I said "thanks for posting". I was recently reminded of this discussion, and decided to work through the process. Using only minimal outside resources the recipe worked as expected! The end-result is I have a working FORTH-lite, or FORTH-like, interpreter written in around 2000 lines of golang! Features include: To give a flavour here we define a word called star which just outputs a single start-character:
: star 42 emit ;
Now we can call that (NOTE: We didn't add a newline here, so the REPL prompt follows it, that's expected):
> star
*>
To make it more useful we define the word "stars" which shows N stars:
> : stars dup 0 > if 0 do star loop else drop then ;
> 0 stars
> 1 stars
*> 2 stars
**> 10 stars
**********>
This example uses both if to test that the parameter on the stack was greater than zero, as well as do/loop to handle the repetition. Finally we use that to draw a box:
> : squares 0 do over stars cr loop ;
> 4 squares
****
****
****
****
> 10 squares
**********
**********
**********
**********
**********
**********
**********
**********
**********
**********
For fun we allow decompiling the words too:
> #words 0 do dup dump loop
..
Word 'square'
 0: dup
 1: *
Word 'cube'
 0: dup
 1: square
 2: *
Word '1+'
 0: store 1.000000
 2: +
Word 'test_hot'
  0: store 0.000000
  2: >
  3: if
  4: [cond-jmp 7.000000]
  6: hot
  7: then
..
Anyway if that is at all interesting feel free to take a peak. There's a bit of hackery there to avoid the use of return-stacks, etc. Compared to gforth this is actually more featureful in some areas: Find the code here:

15 September 2020

Molly de Blanc: Actions, Inactions, and Consequences: Doctrine of Doing and Allowing W. Quinn

There are a lot of interesting and valid things to say about the philosophy and actual arguments of the Actions, Inactions, and Consequences: Doctrine of Doing and Allowing by Warren Quinn. Unfortunately for me, none of them are things I feel particularly inspired by. I m much more attracted to the many things implied in this paper. Among them are the role of social responsibility in making moral decisions. At various points in the text, Quinn makes brief comments about how we have roles that we need to fulfill for the sake of society. These roles carry with them responsibilities that may supersede our regular moral responsibilities. Examples Quinn makes include being a private life guard (and being responsible for the life of one particular person) and being a trolley driver (and your responsibility is to make sure the train doesn t kill anyone). This is part of what has led to me brushing Quinn off as another classist. Still, I am interested in the question of whether social responsibilities are more important than moral ones or whether there are times when this might occur. One of the things I maintain is that we cannot be the best versions of ourselves because we are not living in societies that value our best selves. We survive capitalism. We negotiate climate change. We make decisions to trade the ideal for the functional. For me, this frequently means I click through terms of service, agree to surveillance, and partake in the use and proliferation of oppressive technology. I also buy an iced coffee that comes in a single use plastic cup; I shop at the store with questionable labor practices; I use Facebook. But also, I don t give money to panhandlers. I see suffering and I let it pass. I do not get involved or take action in many situations because I have a pass to not. These things make society work as it is, and it makes me work within society. This is a self-perpetuating, mutually-abusive, co-dependent relationship. I must tell myself stories about how it is okay that I am preferring the status quo, that I am buying into the system, because I need to do it to survive within it and that people are relying on the system as it stands to survive, because that is how they know to survive. Among other things, I am worried about the psychic damage this causes us. When we view ourselves as social actors rather than moral actors, we tell ourselves it is okay to take non-moral actions (or in-actions); however, we carry within ourselves intuitions and feelings about what is right, just, and moral. We ignore these in order to act in our social roles. From the perspective of the individual, we re hurting ourselves and suffering for the sake of benefiting and perpetuating an caustic society. From the perspective of society, we are perpetuating something that is not just less than ideal, but actually not good because it is based on allowing suffering.[1] [1] This is for the sake of this text. I don t know if I actually feel that this is correct. My goal was to make this only 500 words, so I am going to stop here.

14 September 2020

Russ Allbery: Review: Who Do You Serve, Who Do You Protect?

Review: Who Do You Serve, Who Do You Protect?, edited by Maya Schenwar, et al.
Editor: Maya Schenwar
Editor: Joe Macar
Editor: Alana Yu-lan Price
Publisher: Haymarket Books
Copyright: June 2016
ISBN: 1-60846-684-1
Format: Kindle
Pages: 250
Who Do You Serve, Who Do You Protect? is an anthology of essays about policing in the United States. It's divided into two sections: one that enumerates ways that police are failing to serve or protect communities, and one that describes how communities are building resistance and alternatives. Haymarket Books (a progressive press in Chicago) has made it available for free in the aftermath of the George Floyd killing and resulting protests in the United States. I'm going to be a bit unfair to this book, so let me start by admitting that the mismatch between it and the book I was looking for is not entirely its fault. My primary goal was to orient myself in the discussion on the left about alternatives to policing. I also wanted to sample something from Haymarket Books; a free book was a good way to do that. I was hoping for a collection of short introductions to current lines of thinking that I could selectively follow in longer writing, and an essay collection seemed ideal for that. What I had not realized (which was my fault for not doing simple research) is that this is a compilation of articles previously published by Truthout, a non-profit progressive journalism site, in 2014 and 2015. The essays are a mix of reporting and opinion but lean towards reporting. The earliest pieces in this book date from shortly after the police killing of Michael Brown, when racist police violence was (again) reaching national white attention. The first half of the book is therefore devoted to providing evidence of police abuse and violence. This is important to do, but it's sadly no longer as revelatory in 2020, when most of us have seen similar things on video, as it was to white America in 2014. If you live in the United States today, while you may not be aware of the specific events described here, you're unlikely to be surprised that Detroit police paid off jailhouse informants to provide false testimony ("Ring of Snitches" by Aaron Miguel Cant ), or that Chicago police routinely use excessive deadly force with no consequences ("Amid Shootings, Chicago Police Department Upholds Culture of Impunity" by Sarah Macaraeg and Alison Flowers), or that there is a long history of police abuse and degradation of pregnant women ("Your Pregnancy May Subject You to Even More Law Enforcement Violence" by Victoria Law). There are about eight essays along those lines. Unfortunately, the people who excuse or disbelieve these stories are rarely willing to seek out new evidence, let alone read a book like this. That raises the question of intended audience for the catalog of horrors part of this book. The answer to that question may also be the publication date; in 2014, the base of evidence and example for discussion had not been fully constructed. This sort of reporting is also obviously relevant in the original publication context of web-based journalism, where people may encounter these accounts individually through social media or other news coverage. In 2020, they offer reinforcement and rhetorical evidence, but I'm dubious that the people who would benefit from this knowledge will ever see it in this form. Those of us who will are already sickened, angry, and depressed. My primary interest was therefore in the second half of the book: the section on how communities are building resistance and alternatives. This is where I'm going to be somewhat unfair because the state of that conversation may have been different in 2015 than it is now in 2020. But these essays were lacking the depth of analysis that I was looking for. There is a human tendency, when one becomes aware of an obvious wrong, to simply publicize the horrible thing that is happening and expect someone to do something about it. It's obviously and egregiously wrong, so if more people knew about it, certainly it would be stopped! That has happened repeatedly with racial violence in the United States. It's also part of the common (and school-taught) understanding of the Civil Rights movement in the 1960s: activists succeeded in getting the violence on the cover of newspapers and on television, people were shocked and appalled, and the backlash against the violence created political change. Putting aside the fact that this is too simplistic of a picture of the Civil Rights era, it's abundantly clear at this point in 2020 that publicizing racist and violent policing isn't going to stop it. We're going to have to do something more than draw attention to the problem. Deciding what to do requires political and social analysis, not just of the better world that we want to see but of how our current world can become that world. There is very little in that direction in this book. Who Do You Serve, Who Do You Protect? does not answer the question of its title beyond "not us" and "white supremacy." While those answers are not exactly wrong, they're also not pushing the analysis in the direction that I wanted to read. For example (and this is a long-standing pet peeve of mine in US political writing), it would be hard to tell from most of the essays in this book that any country besides the United States exists. One essay ("Killing Africa" by William C. Anderson) talks about colonialism and draws comparisons between police violence in the United States and international treatment of African and other majority-Black countries. One essay talks about US military behavior oversees ("Beyond Homan Square" by Adam Hudson). That's about it for international perspective. Notably, there is no analysis here of what other countries might be doing better. Police violence against out-groups is not unique to the United States. No one has entirely solved this problem, but versions of this problem have been handled with far more success than here. The US has a comparatively appalling record; many countries in the world, particularly among comparable liberal democracies in Europe, are doing far better on metrics of racial oppression by agents of the government and of law enforcement violence. And yet it's common to approach these problems as if we have to develop a solution de novo, rather than ask what other countries are doing differently and if we could do some of those things. The US has some unique challenges, both historical and with the nature of endemic violence in the country, so perhaps such an analysis would turn up too many US-specific factors to copy other people's solutions. But we need to do the analysis, not give up before we start. Novel solutions can lead to novel new problems; other countries have tested, working improvements that could provide a starting framework and some map of potential pitfalls. More fundamentally, only the last two essays of this book propose solutions more complex than "stop." The authors are very clear about what the police are doing, seem less interested in why, and are nearly silent on how to change it. I suspect I am largely in political agreement with most of the authors, but obviously a substantial portion of the country (let alone its power structures) is not, and therefore nothing is changing. Part of the project of ending police violence is understanding why the violence exists, picking apart the motives and potential fracture lines in the political forces supporting the status quo, and building a strategy to change the politics. That isn't even attempted here. For example, the "who do you serve?" question of the book's title is more interesting than the essays give it credit. Police are not a monolith. Why do Black people become police officers? What are their experiences? Are there police forces in the United States that are doing better than others? What makes them different? Why do police act with violence in the moment? What set of cultural expectations, training experiences, anxieties, and fears lead to that outcome? How do we change those factors? Or, to take another tack, why are police not held accountable even when there is substantial public outrage? What political coalition supports that immunity from consequences, what are its fault lines and internal frictions, and what portions of that coalition could be broken off, pealed away, or removed from power? To whom, institutionally, are police forces accountable? What public offices can aspiring candidates run for that would give them oversight capability? This varies wildly throughout the United States; political approaches that work in large cities may not work in small towns, or with county sheriffs, or with the FBI, or with prison guards. To treat these organizations as a monolith and their motives as uniform is bad political tactics. It gives up points of leverage. I thought the best essays of this collection were the last two. "Community Groups Work to Provide Emergency Medical Alternatives, Separate from Police," by Candice Bernd, is a profile of several local emergency response systems that divert emergency calls from the police to paramedics, mental health experts, or social workers. This is an idea that's now relatively mainstream, and it seems to be finding modest success where it has been tried. It's more of a harm mitigation strategy than an attempt to deal with the root problem, but we're going to need both. The last essay, "Building Community Safety" by Ejeris Dixon, is the only essay in this book that is pushing in the direction that I was hoping to read. Dixon describes building an alternative system that can intervene in violent situations without using the police. This is fascinating and I'm glad that I read it. It's also frustrating in context because Dixon's essay should be part of a discussion. Dixon describes spending years learning de-escalation techniques, doing hard work of community discussion and collective decision-making, and making deep investment in the skills required to handle violence without calling in a dangerous outside force. I greatly admire this approach (also common in parts of the anarchist community) and the people who are willing to commit to it. But it's an immense amount of work, and as Dixon points out, that work often falls on the people who are least able to afford it. Marginalized communities, for whom the police are often dangerous, are also likely to lack both time and energy to invest in this type of skill training. And many people simply will not do this work even if they do have the resources to do it. More fundamentally, this approach conflicts somewhat with division of labor. De-escalation and social work are both professional skills that require significant time and practice to hone, and as much as I too would love to live in a world where everyone knows how to do some amount of this work, I find it hard to imagine scaling this approach without trained professionals. The point of paying someone to do this work as their job is that the money frees up their time to focus on learning those skills at a level that is difficult to do in one's free time. But once you have an organized group of professionals who do this work, you have to find a way to keep them from falling prey to the problems that plague the police, which requires understanding the origins of those problems. And that's putting aside the question of how large the residual of dangerous crime that cannot be addressed through any form of de-escalation might be, and what organization we should use to address it. Dixon's essay is great; I wouldn't change anything about it. But I wanted to see the next essay engaging with Dixon's perspective and looking for weaknesses and scaling concerns, and then the next essay that attempts to shore up those weaknesses, and yet another essay that grapples with the challenging philosophical question of a government monopoly on force and how that can and should come into play in violent crime. And then essays on grass-roots organizing in the context of police reform or abolition, and on restorative justice, and on the experience of attempting police reform from the inside, and on how to support public defenders, and on the merits and weaknesses of focusing on electing reform-minded district attorneys. Unfortunately, none of those are here. Overall, Who Do You Serve, Who Do You Protect? was a disappointment. It was free, so I suppose I got what I paid for, and I may have had a different reaction if I read it in 2015. But if you're looking for a deep discussion on the trade-offs and challenges of stopping police violence in 2020, I don't think this is the place to start. Rating: 3 out of 10

13 September 2020

Enrico Zini: Travel links

A few interesting places to visit. Traveling could be complicated, and internet searches could be interesting enough. For example, churches: Or fascinating urbanistic projects, for which it's worth to look up photos: Or nature, like Get Lost in Mega-Tunnels Dug by South American Megafauna

Russell Coker: Setting Up a Dell T710 Server with DRAC6

I ve just got a Dell T710 server for LUV and I ve been playing with the configuration options. Here s a list of what I ve done and recommendations on how to do things. I decided not to try to write a step by step guide to doing stuff as the situation doesn t work for that. I think that a list of how things are broken and what to avoid is more useful. BIOS Firstly with a Dell server you can upgrade the BIOS from a Linux root shell. Generally when a server is deployed you won t want to upgrade the BIOS (why risk breaking something when it s working), so before deployment you probably should install the latest version. Dell provides a shell script with encoded binaries in it that you can just download and run, it s ugly but it works. The process of loading the firmware takes a long time (a few minutes) with no progress reports, so best to plug both PSUs in and leave it alone. At the end of loading the firmware a hard reboot will be performed, so upgrading your distribution while doing the install is a bad idea (Debian is designed to not lose data in this situation so it s not too bad). IDRAC IDRAC is the Integrated Dell Remote Access Controller. By default it will listen on all Ethernet ports, get an IP address via DHCP (using a different Ethernet hardware address to the interface the OS sees), and allow connections. Configuring it to be restrictive as to which ports it listens on may be a good idea (the T710 had 4 ports built in so having one reserved for management is usually OK). You need to configure a username and password for IDRAC that has administrative access in the BIOS configuration. Web Interface By default IDRAC will run a web server on the IP address it gets from DHCP, you can connect to that from any web browser that allows ignoring invalid SSL keys. Then you can use the username and password configured in the BIOS to login. IDRAC 6 on the PowerEdge T710 recommends IE 6. To get a ssl cert that matches the name you want to use (and doesn t give browser errors) you have to generate a CSR (Certificate Signing Request) on the DRAC, the only field that matters is the CN (Common Name), the rest have to be something that Letsencrypt will accept. Certbot has the option --config-dir /etc/letsencrypt-drac to specify an alternate config directory, the SSL key for DRAC should be entirely separate from the SSL key for other stuff. Then use the --csr option to specify the path of the CSR file. When you run letsencrypt the file name of the output file you want will be in the format *_chain.pem . You then have to upload that to IDRAC to have it used. This is a major pain for the lifetime of letsencrypt certificates. Hopefully a more recent version of IDRAC has Certbot built in. When you access RAC via ssh (see below) you can run the command racadm sslcsrgen to generate a CSR that can be used by certbot. So it s probably possible to write expect scripts to get that CSR, run certbot, and then put the ssl certificate back. I don t expect to use IDRAC often enough to make it worth the effort (I can tell my browser to ignore an outdated certificate), but if I had dozens of Dells I d script it. SSH The web interface allows configuring ssh access which I strongly recommend doing. You can configure ssh access via password or via ssh public key. For ssh access set TERM=vt100 on the host to enable backspace as ^H. Something like TERM=vt100 ssh root@drac . Note that changing certain other settings in IDRAC such as enabling Smartcard support will disable ssh access. There is a limit to the number of open sessions for managing IDRAC, when you ssh to the IDRAC you can run racadm getssninfo to get a list of sessions and racadm closessn -i NUM to close a session. The closessn command takes a -a option to close all sessions but that just gives an error saying that you can t close your own session because of programmer stupidity. The IDRAC web interface also has an option to close sessions. If you get to the limits of both ssh and web sessions due to network issues then you presumably have a problem. I couldn t find any documentation on how the ssh host key is generated. I Googled for the key fingerprint and didn t get a match so there s a reasonable chance that it s unique to the server (please comment if you know more about this). Don t Use Graphical Console The T710 is an older server and runs IDRAC6 (IDRAC9 is the current version). The Java based graphical console access doesn t work with recent versions of Java. The Debian package icedtea-netx has has the javaws command for running the .jnlp command for the console, by default the web browser won t run this, you download the .jnlp file and pass that as the first parameter to the javaws program which then downloads a bunch of Java classes from the IDRAC to run. One error I got with Java 11 was Exception in thread Timer-0 java.util.ServiceConfigurationError: java.nio.charset.spi.CharsetProvider: Provider sun.nio.cs.ext.ExtendedCharsets could not be instantiated , Google didn t turn up any solutions to this. Java 8 didn t have that problem but had a connection failed error that some people reported as being related to the SSL key, but replacing the SSL key for the web server didn t help. The suggestion of running a VM with an old web browser to access IDRAC didn t appeal. So I gave up on this. Presumably a Windows VM running IE6 would work OK for this. Serial Console Fortunately IDRAC supports a serial console. Here s a page summarising Serial console setup for DRAC [1]. Once you have done that put console=tty0 console=ttyS1,115200n8 on the kernel command line and Linux will send the console output to the virtual serial port. To access the serial console from remote you can ssh in and run the RAC command console com2 (there is no option for using a different com port). The serial port seems to be unavailable through the web interface. If I was supporting many Dell systems I d probably setup a ssh to JavaScript gateway to provide a web based console access. It s disappointing that Dell didn t include this. If you disconnect from an active ssh serial console then the RAC might keep the port locked, then any future attempts to connect to it will give the following error:
/admin1-> console com2
console: Serial Device 2 is currently in use
So far the only way I ve discovered to get console access again after that is the command racadm racreset . If anyone knows of a better way please let me know. As an aside having racreset being so close to racresetcfg (which resets the configuration to default and requires a hard reboot to configure it again) seems like a really bad idea. Host Based Management
deb http://linux.dell.com/repo/community/ubuntu xenial openmanage
The above apt sources.list line allows installing Dell management utilities (Xenial is old but they work on Debian/Buster). Probably the packages srvadmin-storageservices-cli and srvadmin-omacore will drag in enough dependencies to get it going. Here are some useful commands:
# show hardware event log
omreport system esmlog
# show hardware alert log
omreport system alertlog
# give summary of system information
omreport system summary
# show versions of firmware that can be updated
omreport system version
# get chassis temp
omreport chassis temps
# show physical disk details on controller 0
omreport storage pdisk controller=0
RAID Control The RAID controller is known as PERC (PowerEdge Raid Controller), the Dell web site has an rpm package of the perccli tool to manage the RAID from Linux. This is statically linked and appears to have different versions of libraries used to make it. The command perccli show gives an overview of the configuration, but the command perccli /c0 show to give detailed information on controller 0 SEGVs and the kernel logs a vsyscall attempted with vsyscall=none message. Here s an overview of the vsyscall enmulation issue [2]. Basically I could add vsyscall=emulate to the kernel command line and slightly reduce security for the system to allow system calls from perccli that are called from old libc code to work, or I could run code from a dubious source as root. Some versions of IDRAC have a racadm raid command that can be run from a ssh session to perform RAID administration remotely, mine doesn t have that. As an aside the help for the RAC system doesn t list all commands and the Dell documentation is difficult to find so blog posts from other sysadmins is the best source of information. I have configured IDRAC to have all of the BIOS output go to the virtual serial console over ssh so I can see the BIOS prompt me for PERC administration but it didn t accept my key presses when I tried to do so. In any case this requires downtime and I d like to be able to change hard drives without rebooting. I found vsyscall_trace on Github [3], it uses the ptrace interface to emulate vsyscall on a per process basis. You just run vsyscall_trace perccli and it works! Thanks Geoffrey Thomas for writing this! Here are some perccli commands:
# show overview
perccli show
# help on adding a vd (RAID)
perccli /c0 add help
# show controller 0 details
perccli /c0 show
# add a vd (RAID) of level RAID0 (r0) with the drive 32:0 (enclosure:slot from above command)
perccli /c0 add vd r0 drives=32:0
When a disk is added to a PERC controller about 525MB of space is used at the end for RAID metadata. So when you create a RAID-0 with a single device as in the above example all disk data is preserved by default except for the last 525MB. I have tested this by running a BTRFS scrub on a disk from another system after making it into a RAID-0 on the PERC.

12 September 2020

Ryan Kavanagh: Configuring OpenIKED VPNs for Road Warriors

A few weeks ago I configured a road warrior VPN setup. The remote end is on a VPS running OpenBSD and OpenIKED, the VPN is an IKEv2 VPN using x509 authentication, and the local end is StrongSwan. I also configured an IKEv2 VPN between my VPSs. Here are the notes for how to do so. In all cases, to use x509 authentication, you will need to generate a bunch of certificates and keys: Fortunately, OpenIKED provides the ikectl utility to help you do so. Before going any further, you might find it useful to edit /etc/ssl/ikeca.cnf to set some reasonable defaults for your certificates. Begin by creating and installing a CA certificate:
# ikectl ca vpn create
# ikectl ca vpn install
For simplicity, I am going to assume that the you are managing your CA on the same host as one of the hosts that you want to configure for the VPN. If not, see the bit about exporting certificates at the beginning of the section on persistent host-host VPNs. Create and install a key/certificate pair for your server. Suppose for example your first server is called server1.example.org:
# ikectl ca vpn certificate server1.example.org create
# ikectl ca vpn certificate server1.example.org install

Persistent host-host VPNs For each other server that you want to use, you need to also create a key/certificate pair on the same host as the CA certificate, and then copy them over to the other server. Assuming the other server is called server2.example.org:
# ikectl ca vpn certificate server2.example.org create
# ikectl ca vpn certificate server2.example.org export
This last command will produce a tarball server2.example.org.tgz. Copy it over to server2.example.org and install it:
# tar -C /etc/iked -xzpvf server2.example.org.tgz
Next, it is time to configure iked. To do so, you will need to find some information about the certificates you just generated. On the host with the CA, run
$ cat /etc/ssl/vpn/index.txt
V       210825142056Z           01      unknown /C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org
V       210825142208Z           02      unknown /C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org
Pick one of the two hosts to play the active role (in this case, server1.example.org). Using the information you gleaned from index.txt, add the following to /etc/iked.conf, filling in the srcid and dstid fields appropriately.
ikev2 'server1_server2_active' active esp from server1.example.org to server2.example.org \
	local server1.example.org peer server2.example.org \
	srcid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org' \
	dstid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org'
On the other host, add the following to /etc/iked.conf
ikev2 'server2_server1_passive' passive esp from server2.example.org to server1.example.org \
	local server2.example.org peer server1.example.org \
	srcid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org' \
	dstid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org'
Note that the names 'server1_server2_active' and 'server2_server1_passive' in the two stanzas do not matter and can be omitted. Reload iked on both hosts:
# ikectl reload
If everything worked out, you should see the negotiated security associations (SAs) in the output of
# ikectl show sa
On OpenBSD, you should also see some output on success or errors in the file /var/log/daemon.

For a road warrior Add the following to /etc/iked.conf on the remote end:
ikev2 'responder_x509' passive esp \
	from 0.0.0.0/0 to 10.0.1.0/24 \
	local server1.example.org peer any \
	srcid server1.example.org \
	config address 10.0.1.0/24 \
	config name-server 10.0.1.1 \
	tag "ROADW"
Configure or omit the address range and the name-server configurations to suit your needs. See iked.conf(5) for details. Reload iked:
# ikectl reload
If you are on OpenBSD and want the remote end to have an IP address, add the following to /etc/hostname.vether0, again configuring the address to suit your needs:
inet 10.0.1.1 255.255.255.0
Put the interface up:
# ifconfig vether0 up
Now create a client certificate for authentication. In my case, my road-warrior client was client.example.org:
# ikectl ca vpn certificate client.example.org create
# ikectl ca vpn certificate client.example.org export
Copy client.example.org.tgz to client and run
# tar -C /etc/ipsec.d/ -xzf client.example.org.tgz -- \
	./private/client.example.org.key \
	./certs/client.example.org.crt ./ca/ca.crt
Install StrongSwan and add the following to /etc/ipsec.conf, configuring appropriately:
ca example.org
  cacert=ca.crt
  auto=add
conn server1
  keyexchange=ikev2
  right=server1.example.org
  rightid=%server1.example.org
  rightsubnet=0.0.0.0/0
  rightauth=pubkey
  leftsourceip=%config
  leftauth=pubkey
  leftcert=client.example.org.crt
  auto=route
Add the following to /etc/ipsec.secrets:
# space is important
server1.example.org : RSA client.example.org.key
Restart StrongSwan, put the connection up, and check its status:
# ipsec restart
# ipsec up server1
# ipsec status
That should be it. Sources:

Ryan Kavanagh: Configuring OpenIKED VPNs for StrongSwan Clients

A few weeks ago I configured a road warrior VPN setup. The remote end is on a VPS running OpenBSD and OpenIKED, the VPN is an IKEv2 VPN using x509 authentication, and the local end is StrongSwan. I also configured an IKEv2 VPN between my VPSs. Here are the notes for how to do so. In all cases, to use x509 authentication, you will need to generate a bunch of certificates and keys: Fortunately, OpenIKED provides the ikectl utility to help you do so. Before going any further, you might find it useful to edit /etc/ssl/ikeca.cnf to set some reasonable defaults for your certificates. Begin by creating and installing a CA certificate:
# ikectl ca vpn create
# ikectl ca vpn install
For simplicity, I am going to assume that the you are managing your CA on the same host as one of the hosts that you want to configure for the VPN. If not, see the bit about exporting certificates at the beginning of the section on persistent host-host VPNs. Create and install a key/certificate pair for your server. Suppose for example your first server is called server1.example.org:
# ikectl ca vpn certificate server1.example.org create
# ikectl ca vpn certificate server1.example.org install

Persistent host-host VPNs For each other server that you want to use, you need to also create a key/certificate pair on the same host as the CA certificate, and then copy them over to the other server. Assuming the other server is called server2.example.org:
# ikectl ca vpn certificate server2.example.org create
# ikectl ca vpn certificate server2.example.org export
This last command will produce a tarball server2.example.org.tgz. Copy it over to server2.example.org and install it:
# tar -C /etc/iked -xzpvf server2.example.org.tgz
Next, it is time to configure iked. To do so, you will need to find some information about the certificates you just generated. On the host with the CA, run
$ cat /etc/ssl/vpn/index.txt
V       210825142056Z           01      unknown /C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org
V       210825142208Z           02      unknown /C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org
Pick one of the two hosts to play the active role (in this case, server1.example.org). Using the information you gleaned from index.txt, add the following to /etc/iked.conf, filling in the srcid and dstid fields appropriately.
ikev2 'server1_server2_active' active esp from server1.example.org to server2.example.org \
	local server1.example.org peer server2.example.org \
	srcid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org' \
	dstid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org'
On the other host, add the following to /etc/iked.conf
ikev2 'server2_server1_passive' passive esp from server2.example.org to server1.example.org \
	local server2.example.org peer server1.example.org \
	srcid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server2.example.org/emailAddress=rak@example.org' \
	dstid '/C=US/ST=Pennsylvania/L=Pittsburgh/CN=server1.example.org/emailAddress=rak@example.org'
Note that the names 'server1_server2_active' and 'server2_server1_passive' in the two stanzas do not matter and can be omitted. Reload iked on both hosts:
# ikectl reload
If everything worked out, you should see the negotiated security associations (SAs) in the output of
# ikectl show sa
On OpenBSD, you should also see some output on success or errors in the file /var/log/daemon.

For a road warrior Add the following to /etc/iked.conf on the remote end:
ikev2 'responder_x509' passive esp \
	from 0.0.0.0/0 to 10.0.1.0/24 \
	local server1.example.org peer any \
	srcid server1.example.org \
	config address 10.0.1.0/24 \
	config name-server 10.0.1.1 \
	tag "ROADW"
Configure or omit the address range and the name-server configurations to suit your needs. See iked.conf(5) for details. Reload iked:
# ikectl reload
If you are on OpenBSD and want the remote end to have an IP address, add the following to /etc/hostname.vether0, again configuring the address to suit your needs:
inet 10.0.1.1 255.255.255.0
Put the interface up:
# ifconfig vether0 up
Now create a client certificate for authentication. In my case, my road-warrior client was client.example.org:
# ikectl ca vpn certificate client.example.org create
# ikectl ca vpn certificate client.example.org export
Copy client.example.org.tgz to client and run
# tar -C /etc/ipsec.d/ -xzf client.example.org.tgz -- \
	./private/client.example.org.key \
	./certs/client.example.org.crt ./ca/ca.crt
Install StrongSwan and add the following to /etc/ipsec.conf, configuring appropriately:
ca example.org
  cacert=ca.crt
  auto=add
conn server1
  keyexchange=ikev2
  right=server1.example.org
  rightid=%server1.example.org
  rightsubnet=0.0.0.0/0
  rightauth=pubkey
  leftsourceip=%config
  leftauth=pubkey
  leftcert=client.example.org.crt
  auto=route
Add the following to /etc/ipsec.secrets:
# space is important
server1.example.org : RSA client.example.org.key
Restart StrongSwan, put the connection up, and check its status:
# ipsec restart
# ipsec up server1
# ipsec status
That should be it. Sources:

Jelmer Vernooij: Debian Janitor: All Packages Processed with Lintian-Brush

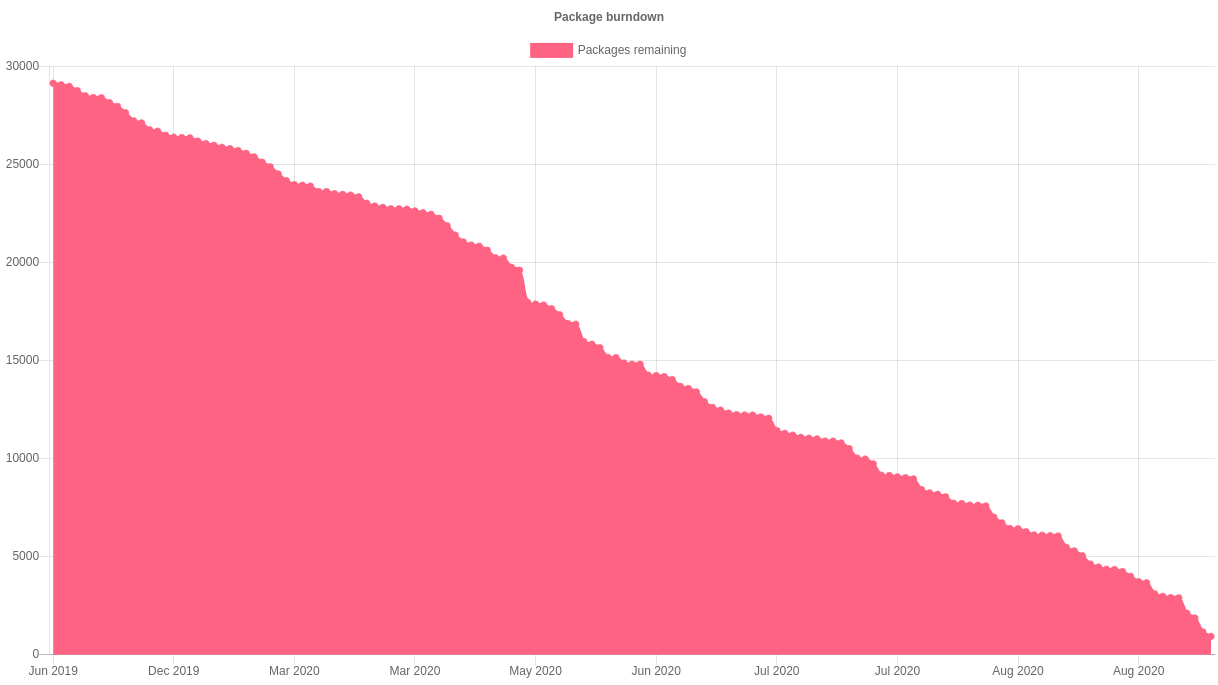
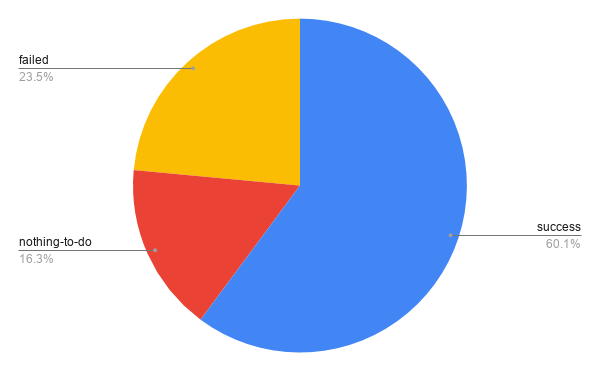
The Debian Janitor is an automated system that commits fixes for (minor) issues in Debian packages that can be fixed by software. It gradually started proposing merges in early December. The first set of changes sent out ran lintian-brush on sid packages maintained in Git. This post is part of a series about the progress of the Janitor. On 12 July 2019, the Janitor started fixing lintian issues in packages in the Debian archive. Now, a year and a half later, it has processed every one of the almost 28,000 packages at least once. Graph with Lintian Fixes Burndown As discussed two weeks ago, this has resulted in roughly 65,000 total changes. These 65,000 changes were made to a total of almost 17,000 packages. Of the remaining packages, for about 4,500 lintian-brush could not make any improvements. The rest (about 6,500) failed to be processed for one of many reasons they are e.g. not yet migrated off alioth, use uncommon formatting that can't be preserved or failed to build for one reason or another. Graph with runs by status (success, failed, nothing-to-do) Now that the entire archive has been processed, packages are prioritized based on the likelihood of a change being made to them successfully. Over the course of its existence, the Janitor has slowly gained support for a wider variety of packaging methods. For example, it can now edit the templates for some of the generated control files. Many of the packages that the janitor was unable to propose changes for the first time around are expected to be correctly handled when they are reprocessed. If you re a Debian developer, you can find the list of improvements made by the janitor in your packages by going to https://janitor.debian.net/m/.
For more information about the Janitor's lintian-fixes efforts, see the landing page.

9 September 2020

Reproducible Builds: Reproducible Builds in August 2020

Welcome to the August 2020 report from the Reproducible Builds project. In our monthly reports, we summarise the things that we have been up to over the past month. The motivation behind the Reproducible Builds effort is to ensure no flaws have been introduced from the original free software source code to the pre-compiled binaries we install on our systems. If you re interested in contributing to the project, please visit our main website.


This month, Jennifer Helsby launched a new reproduciblewheels.com website to address the lack of reproducibility of Python wheels. To quote Jennifer s accompanying explanatory blog post:
One hiccup we ve encountered in SecureDrop development is that not all Python wheels can be built reproducibly. We ship multiple (Python) projects in Debian packages, with Python dependencies included in those packages as wheels. In order for our Debian packages to be reproducible, we need that wheel build process to also be reproducible
Parallel to this, transparencylog.com was also launched, a service that verifies the contents of URLs against a publicly recorded cryptographic log. It keeps an append-only log of the cryptographic digests of all URLs it has seen. (GitHub repo) On 18th September, Bernhard M. Wiedemann will give a presentation in German, titled Wie reproducible builds Software sicherer machen ( How reproducible builds make software more secure ) at the Internet Security Digital Days 2020 conference.

Reproducible builds at DebConf20 There were a number of talks at the recent online-only DebConf20 conference on the topic of reproducible builds. Holger gave a talk titled Reproducing Bullseye in practice , focusing on independently verifying that the binaries distributed from ftp.debian.org are made from their claimed sources. It also served as a general update on the status of reproducible builds within Debian. The video (145 MB) and slides are available. There were also a number of other talks that involved Reproducible Builds too. For example, the Malayalam language mini-conference had a talk titled , ? ( I want to join Debian, what should I do? ) presented by Praveen Arimbrathodiyil, the Clojure Packaging Team BoF session led by Elana Hashman, as well as Where is Salsa CI right now? that was on the topic of Salsa, the collaborative development server that Debian uses to provide the necessary tools for package maintainers, packaging teams and so on. Jonathan Bustillos (Jathan) also gave a talk in Spanish titled Un camino verificable desde el origen hasta el binario ( A verifiable path from source to binary ). (Video, 88MB)

Development work After many years of development work, the compiler for the Rust programming language now generates reproducible binary code. This generated some general discussion on Reddit on the topic of reproducibility in general. Paul Spooren posted a request for comments to OpenWrt s openwrt-devel mailing list asking for clarification on when to raise the PKG_RELEASE identifier of a package. This is needed in order to successfully perform rebuilds in a reproducible builds context. In openSUSE, Bernhard M. Wiedemann published his monthly Reproducible Builds status update. Chris Lamb provided some comments and pointers on an upstream issue regarding the reproducibility of a Snap / SquashFS archive file. [ ]

Debian Holger Levsen identified that a large number of Debian .buildinfo build certificates have been tainted on the official Debian build servers, as these environments have files underneath the /usr/local/sbin directory [ ]. He also filed against bug for debrebuild after spotting that it can fail to download packages from snapshot.debian.org [ ]. This month, several issues were uncovered (or assisted) due to the efforts of reproducible builds. For instance, Debian bug #968710 was filed by Simon McVittie, which describes a problem with detached debug symbol files (required to generate a traceback) that is unlikely to have been discovered without reproducible builds. In addition, Jelmer Vernooij called attention that the new Debian Janitor tool is using the property of reproducibility (as well as diffoscope when applying archive-wide changes to Debian:
New merge proposals also include a link to the diffoscope diff between a vanilla build and the build with changes. Unfortunately these can be a bit noisy for packages that are not reproducible yet, due to the difference in build environment between the two builds. [ ]
56 reviews of Debian packages were added, 38 were updated and 24 were removed this month adding to our knowledge about identified issues. Specifically, Chris Lamb added and categorised the nondeterministic_version_generated_by_python_param and the lessc_nondeterministic_keys toolchain issues. [ ][ ] Holger Levsen sponsored Lukas Puehringer s upload of the python-securesystemslib pacage, which is a dependency of in-toto, a framework to secure the integrity of software supply chains. [ ] Lastly, Chris Lamb further refined his merge request against the debian-installer component to allow all arguments from sources.list files (such as [check-valid-until=no]) in order that we can test the reproducibility of the installer images on the Reproducible Builds own testing infrastructure and sent a ping to the team that maintains that code.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of these patches, including:

diffoscope diffoscope is our in-depth and content-aware diff utility that can not only locate and diagnose reproducibility issues, it provides human-readable diffs of all kinds. In August, Chris Lamb made the following changes to diffoscope, including preparing and uploading versions 155, 156, 157 and 158 to Debian:
  • New features:
    • Support extracting data of PGP signed data. (#214)
    • Try files named .pgp against pgpdump(1) to determine whether they are Pretty Good Privacy (PGP) files. (#211)
    • Support multiple options for all file extension matching. [ ]
  • Bug fixes:
    • Don t raise an exception when we encounter XML files with <!ENTITY> declarations inside the Document Type Definition (DTD), or when a DTD or entity references an external resource. (#212)
    • pgpdump(1) can successfully parse some binary files, so check that the parsed output contains something sensible before accepting it. [ ]
    • Temporarily drop gnumeric from the Debian build-dependencies as it has been removed from the testing distribution. (#968742)
    • Correctly use fallback_recognises to prevent matching .xsb binary XML files.
    • Correct identify signed PGP files as file(1) returns data . (#211)
  • Logging improvements:
    • Emit a message when ppudump version does not match our file header. [ ]
    • Don t use Python s repr(object) output in Calling external command messages. [ ]
    • Include the filename in the not identified by any comparator message. [ ]
  • Codebase improvements:
    • Bump Python requirement from 3.6 to 3.7. Most distributions are either shipping with Python 3.5 or 3.7, so supporting 3.6 is not only somewhat unnecessary but also cumbersome to test locally. [ ]
    • Drop some unused imports [ ], drop an unnecessary dictionary comprehensions [ ] and some unnecessary control flow [ ].
    • Correct typo of output in a comment. [ ]
  • Release process:
    • Move generation of debian/tests/control to an external script. [ ]
    • Add some URLs for the site that will appear on PyPI.org. [ ]
    • Update author and author email in setup.py for PyPI.org and similar. [ ]
  • Testsuite improvements:
    • Update PPU tests for compatibility with Free Pascal versions 3.2.0 or greater. (#968124)
    • Mark that our identification test for .ppu files requires ppudump version 3.2.0 or higher. [ ]
    • Add an assert_diff helper that loads and compares a fixture output. [ ][ ][ ][ ]
  • Misc:
In addition, Mattia Rizzolo documented in setup.py that diffoscope works with Python version 3.8 [ ] and Frazer Clews applied some Pylint suggestions [ ] and removed some deprecated methods [ ].

Website This month, Chris Lamb updated the main Reproducible Builds website and documentation to:
  • Clarify & fix a few entries on the who page [ ][ ] and ensure that images do not get to large on some viewports [ ].
  • Clarify use of a pronoun re. Conservancy. [ ]
  • Use View all our monthly reports over View all monthly reports . [ ]
  • Move a is a suffix out of the link target on the SOURCE_DATE_EPOCH age. [ ]
In addition, Javier Jard n added the freedesktop-sdk project [ ] and Kushal Das added SecureDrop project [ ] to our projects page. Lastly, Michael P hn added internationalisation and translation support with help from Hans-Christoph Steiner [ ].

Testing framework The Reproducible Builds project operate a Jenkins-based testing framework to power tests.reproducible-builds.org. This month, Holger Levsen made the following changes:
  • System health checks:
    • Improve explanation how the status and scores are calculated. [ ][ ]
    • Update and condense view of detected issues. [ ][ ]
    • Query the canonical configuration file to determine whether a job is disabled instead of duplicating/hardcoding this. [ ]
    • Detect several problems when updating the status of reporting-oriented metapackage sets. [ ]
    • Detect when diffoscope is not installable [ ] and failures in DNS resolution [ ].
  • Debian:
    • Update the URL to the Debian security team bug tracker s Git repository. [ ]
    • Reschedule the unstable and bullseye distributions often for the arm64 architecture. [ ]
    • Schedule buster less often for armhf. [ ][ ][ ]
    • Force the build of certain packages in the work-in-progress package rebuilder. [ ][ ]
    • Only update the stretch and buster base build images when necessary. [ ]
  • Other distributions:
    • For F-Droid, trigger jobs by commits, not by a timer. [ ]
    • Disable the Archlinux HTML page generation job as it has never worked. [ ]
    • Disable the alternative OpenWrt rebuilder jobs. [ ]
  • Misc;
Many other changes were made too, including:
  • Chris Lamb:
    • Use <pre> HTML tags when dumping fixed-width debugging data in the self-serve package scheduler. [ ]
  • Mattia Rizzolo:
  • Vagrant Cascadian:
    • Mark that the u-boot Universal Boot Loader should not build architecture independent packages on the arm64 architecture anymore. [ ]
Finally, build node maintenance was performed by Holger Levsen [ ], Mattia Rizzolo [ ][ ] and Vagrant Cascadian [ ][ ][ ][ ]

Mailing list On our mailing list this month, Leo Wandersleb sent a message to the list after he was wondering how to expand his WalletScrutiny.com project (which aims to improve the security of Bitcoin wallets) from Android wallets to also monitor Linux wallets as well:
If you think you know how to spread the word about reproducibility in the context of Bitcoin wallets through WalletScrutiny, your contributions are highly welcome on this PR [ ]
Julien Lepiller posted to the list linking to a blog post by Tavis Ormandy titled You don t need reproducible builds. Morten Linderud (foxboron) responded with a clear rebuttal that Tavis was only considering the narrow use-case of proprietary vendors and closed-source software. He additionally noted that the criticism that reproducible builds cannot prevent against backdoors being deliberately introduced into the upstream source ( bugdoors ) are decidedly (and deliberately) outside the scope of reproducible builds to begin with. Chris Lamb included the Reproducible Builds mailing list in a wider discussion regarding a tentative proposal to include .buildinfo files in .deb packages, adding his remarks regarding requiring a custom tool in order to determine whether generated build artifacts are identical in a reproducible context. [ ] Jonathan Bustillos (Jathan) posted a quick email to the list requesting whether there was a list of To do tasks in Reproducible Builds. Lastly, Chris Lamb responded at length to a query regarding the status of reproducible builds for Debian ISO or installation images. He noted that most of the technical work has been performed but there are at least four issues until they can be generally advertised as such . He pointed that the privacy-oriented Tails operation system, which is based directly on Debian, has had reproducible builds for a number of years now. [ ]

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

7 September 2020

Arturo Borrero Gonz lez: Debconf 2020 online, summary

Debconf2020 logo Debconf2020 took place when I was on personal vacations time. But anyway I m lucky enough that my company, the Wikimedia Foundation, paid the conference registration fee for me and allowed me to take the time (after my vacations) to watch recordings from the conference. This is my first time attending (or watching) a full-online conference, and I was curious to see first hand how it would develop. I was greatly surprised to see it worked pretty nicely, so kudos to the organization, video team, volunteers, etc! What follows is my summary of the conference, from the different sessions and talks I watched (again, none of them live but recordings). The first thing I saw was the Welcome to Debconf 2020 opening session. It is obvious the video was made with lots of love, I found it entertaining and useful. I love it :-) Then I watched the BoF Can Free Software improve social equality. It was introduced and moderated by Hong Phuc Dang. Several participants, about 10 people, shared their visions on the interaction between open source projects and communities. I m pretty much aware of the interesting social advancement that FLOSS can enable in communities, but sometimes is not so easy, it may also present challenges and barriers. The BoF was joined by many people from the Asia Pacific region, and for me, it has been very interesting to take a step back from the usual western vision of this topic. Anyway, about the session itself, I have the feeling the participants may have spent too much time on presentations, sharing their local stories (which are interesting, don t get me wrong), perhaps leaving little room for actual proposal discussions or the like. Next I watched the Bits from the DPL talk. In the session, Jonathan Carter goes over several topics affecting the project, both internally and externally. It was interesting to know more about the status of the project from a high level perspective, as an organization, including subjects such as money, common project problems, future issues we are anticipating, the social aspect of the project, etc. The Lightning Talks session grabbed my attention. It is usually very funny to watch and not as dense as other talks. I m glad I watched this as it includes some interesting talks, ranging from HAM radios (I love them!), to personal projects to help in certain tasks, and even some general reflections about life. Just when I m writing this very sentence, the video for the Come and meet your Debian Publicity team! talk has been uploaded. This team does an incredible work in keeping project information flowing, and social networks up-to-date and alive. Mind that the work of this team is mostly non-engineering, but still, is a vital part of the project. The folks in session explain what the team does, and they also discuss how new people can contribute, the different challenges related to language barriers, etc. I have to admit I also started watching a couple other sessions that turned out to don t be interesting to me (and therefore I didn t finish the video). Also, I tried to watch a couple more sessions that didn t publish their video recording just yet, for example the When We Virtualize the Whole Internet talk by Sam Hartman. Will check again in a couple of days. It is a real pleasure the video recordings from the conference are made available online. One can join the conference anytime (like I m doing!) and watch the sessions at any pace at any time. The video archive is big, I won t be able to go over all of it. I won t lie, I still have some pending videos to watch from last year Debconf2019 :-)

4 September 2020

Dirk Eddelbuettel: nanotime 0.3.2: Tweaks

Another (minor) nanotime release, now at version 0.3.2. This release brings an endianness correction which was kindly contributed in a PR, switches to using the API header exported by RcppCCTZ, and tweaks test coverage a little with respect to r-devel. nanotime relies on the RcppCCTZ package for (efficient) high(er) resolution time parsing and formatting up to nanosecond resolution, and the bit64 package for the actual integer64 arithmetic. Initially implemented using the S3 system, it has benefitted greatly from work by co-author Leonardo who not only rejigged nanotime internals in S4 but also added new S4 types for periods, intervals and durations. The NEWS snippet adds full details.

Changes in version 0.3.2 (2020-09-03)
  • Correct for big endian (Elliott Sales de Andrade in #81).
  • Use the RcppCCTZ_API.h header (Dirk in #82).
  • Conditionally reduce test coverage (Dirk in #83).

Thanks to CRANberries there is also a diff to the previous version. More details and examples are at the nanotime page; code, issue tickets etc at the GitHub repository. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

3 September 2020

Molly de Blanc: All Animals Are Equal, Peter Singer

I recently read Disability Visibility, which opens with a piece by Harriet McBryde Johnson about debating Peter Singer. When I got my first reading for my first class and saw it was Peter Singer, I was dismayed because of his (heinous) stances in disability. I assumed All Animals Are Equal was one of Singer s pieces about animal rights. While I agree with many of the principles Singer discusses around animal rights, I feel as though his work on this front is significantly diminished by his work around disability. To put it simply, I can t take Peter Singer seriously. Because of this I had a lot of trouble reading All Animals Are Equal and taking it in good faith. I judged everything from his arguments to his writing harshly. While I don t disagree with his basic point (all animals have rights) I disagree with how he made the point and the argument supporting it. One of the things I was told to ask when reading any philosophy paper is What is the argument? or What are they trying to convince you of? In this case, you could frame the answer as: Animals have some of) the same rights people do. I think it would be more accurate though to frame it as All animals (including humans) have (some of) the same rights or even Humans are as equally worthy of consideration as animals are. I think when we usually talk about animal rights, we do it from a perspective of wanting to elevate animals to human status. From one perspective, I don t like this approach because I feel as though it turns the framing of rights as something you deserve or earn, privileges you get for being good enough. The point about rights is that they are inherent you get them because they are. The valuable thing I got out of All Animals Are Equal is that rights are not universal. When we talk about things like abortion, for example, we talk about the right to have an abortion. Singer asks whether people who cannot get pregnant have the right to an abortion? What he doesn t dig into is that the right to an abortion is really just an extension of bodily autonomy turning one facet of bodily autonomy into the legal right to have a medical procedure. I think this is worth thinking about more turning high level human rights into the mundane rights, and acknowledging that not everyone can or needs them.

2 September 2020

Kees Cook: security things in Linux v5.6

Previously: v5.5. Linux v5.6 was released back in March. Here s my quick summary of various features that caught my attention: WireGuard
The widely used WireGuard VPN has been out-of-tree for a very long time. After 3 1/2 years since its initial upstream RFC, Ard Biesheuvel and Jason Donenfeld finished the work getting all the crypto prerequisites sorted out for the v5.5 kernel. For this release, Jason has gotten WireGuard itself landed. It was a twisty road, and I m grateful to everyone involved for sticking it out and navigating the compromises and alternative solutions. openat2() syscall and RESOLVE_* flags
Aleksa Sarai has added a number of important path resolution scoping options to the kernel s open() handling, covering things like not walking above a specific point in a path hierarchy (RESOLVE_BENEATH), disabling the resolution of various magic links (RESOLVE_NO_MAGICLINKS) in procfs (e.g. /proc/$pid/exe) and other pseudo-filesystems, and treating a given lookup as happening relative to a different root directory (as if it were in a chroot, RESOLVE_IN_ROOT). As part of this, it became clear that there wasn t a way to correctly extend the existing openat() syscall, so he added openat2() (which is a good example of the efforts being made to codify Extensible Syscall arguments). The RESOLVE_* set of flags also cover prior behaviors like RESOLVE_NO_XDEV and RESOLVE_NO_SYMLINKS. pidfd_getfd() syscall
In the continuing growth of the much-needed pidfd APIs, Sargun Dhillon has added the pidfd_getfd() syscall which is a way to gain access to file descriptors of a process in a race-less way (or when /proc is not mounted). Before, it wasn t always possible make sure that opening file descriptors via /proc/$pid/fd/$N was actually going to be associated with the correct PID. Much more detail about this has been written up at LWN. openat() via io_uring
With my attack surface reduction hat on, I remain personally suspicious of the io_uring() family of APIs, but I can t deny their utility for certain kinds of workloads. Being able to pipeline reads and writes without the overhead of actually making syscalls is pretty great for performance. Jens Axboe has added the IORING_OP_OPENAT command so that existing io_urings can open files to be added on the fly to the mapping of available read/write targets of a given io_uring. While LSMs are still happily able to intercept these actions, I remain wary of the growing syscall multiplexer that io_uring is becoming. I am, of course, glad to see that it has a comprehensive (if out of tree ) test suite as part of liburing. removal of blocking random pool
After making algorithmic changes to obviate separate entropy pools for random numbers, Andy Lutomirski removed the blocking random pool. This simplifies the kernel pRNG code significantly without compromising the userspace interfaces designed to fetch cryptographically secure random numbers. To quote Andy, This series should not break any existing programs. /dev/urandom is unchanged. /dev/random will still block just after booting, but it will block less than it used to. See LWN for more details on the history and discussion of the series. arm64 support for on-chip RNG
Mark Brown added support for the future ARMv8.5 s RNG (SYS_RNDR_EL0), which is, from the kernel s perspective, similar to x86 s RDRAND instruction. This will provide a bootloader-independent way to add entropy to the kernel s pRNG for early boot randomness (e.g. stack canary values, memory ASLR offsets, etc). Until folks are running on ARMv8.5 systems, they can continue to depend on the bootloader for randomness (via the UEFI RNG interface) on arm64. arm64 E0PD
Mark Brown added support for the future ARMv8.5 s E0PD feature (TCR_E0PD1), which causes all memory accesses from userspace into kernel space to fault in constant time. This is an attempt to remove any possible timing side-channel signals when probing kernel memory layout from userspace, as an alternative way to protect against Meltdown-style attacks. The expectation is that E0PD would be used instead of the more expensive Kernel Page Table Isolation (KPTI) features on arm64. powerpc32 VMAP_STACK
Christophe Leroy added VMAP_STACK support to powerpc32, joining x86, arm64, and s390. This helps protect against the various classes of attacks that depend on exhausting the kernel stack in order to collide with neighboring kernel stacks. (Another common target, the sensitive thread_info, had already been moved away from the bottom of the stack by Christophe Leroy in Linux v5.1.) generic Page Table dumping
Related to RISCV s work to add page table dumping (via /sys/fs/debug/kernel_page_tables), Steven Price extracted the existing implementations from multiple architectures and created a common page table dumping framework (and then refactored all the other architectures to use it). I m delighted to have this because I still remember when not having a working page table dumper for ARM delayed me for a while when trying to implement upstream kernel memory protections there. Anything that makes it easier for architectures to get their kernel memory protection working correctly makes me happy. That s in for now; let me know if there s anything you think I missed. Next up: Linux v5.7.

2020, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 4.0 License.
CC BY-SA 4.0

Vincent Bernat: Syncing MySQL tables with a custom Ansible module

The community.mysql collection from Ansible Galaxy provides a mysql_query module to run arbitrary MySQL queries. Unfortunately, it does not support check mode nor the --diff flag. It is also unable to tell if there was a change. Let s write a specific Ansible module to workaround these issues.

Notice I recommend that you read Writing a custom Ansible module as an introduction.

Code The module has the following signature and it executes the provided SQL statements in a single transaction. It needs a list of the affected tables to be able to detect and show the changes.
mysql_sync:
  sql:  
    DELETE FROM rules WHERE name LIKE 'CMDB:%';
    INSERT INTO rules (name, rule) VALUES
      ('CMDB: check for cats', ':is(object, "CAT")'),
      ('CMDB: check for dogs', ':is(object, "DOG")');
    REPLACE INTO webhooks (name, url) VALUES
      ('OpsGenie', 'https://opsgenie/something/token'),
      ('Slack', 'https://slack/something/token');
  user: monitoring
  password: Yooghah5
  database: monitoring
  tables:
    - rules
    - webhooks

Prerequisites The module does not enforce idempotency, but it is expected you provide appropriate SQL queries. In the above example, idempotency is achieved because the content of the rules table is deleted and recreated from scratch while the rows in the webhooks table are replaced if they already exist. You need the PyMySQL package.

Module definition Starting from the skeleton described in the previous article, here is the module definition:
module_args = dict(
    sql=dict(type='str', required=True),
    user=dict(type='str', required=True),
    password=dict(type='str', required=True, no_log=True),
    database=dict(type='str', required=True),
    tables=dict(type='list', required=True, elements='str'),
)
result = dict(
    changed=False
)
module = AnsibleModule(
    argument_spec=module_args,
    supports_check_mode=True
)
The password is marked with no_log to ensure it won t be displayed or stored, notably when ansible-playbook runs in verbose mode. There is no host option as the module is executed on the MySQL host. Strong authentication using certificates is not implemented either. This matches our goal with custom modules: only implement what you strictly need.

Getting the current rows The next step is to retrieve the records currently in the database. The got dictionary is a mapping from table names to the list of rows they contain:
got =  
tables = module.params['tables']
connection = pymysql.connect(
    user=module.params['user'],
    password=module.params['password'],
    db=module.params['database'],
    charset='utf8mb4',
    cursorclass=pymysql.cursors.DictCursor
)
with connection.cursor() as cursor:
    for table in tables:
        cursor.execute("SELECT * FROM  ".format(table))
        got[table] = cursor.fetchall()

Computing the changes Let s now build the wanted dictionary. The trick is to execute the SQL statements in a transaction without issuing a final commit. The changes will be invisible1 to other readers and we can compare the final rows with the rows collected in got:
wanted =  
sql = module.params['sql']
statements = [statement.strip()
              for statement in sql.split(";\n")
              if statement.strip()]
with connection.cursor() as cursor:
    for statement in statements:
        try:
            cursor.execute(statement)
        except pymysql.OperationalError as err:
            code, message = err.args
            result['msg'] = "MySQL error for  :  ".format(
                statement,
                message)
            module.fail_json(**result)
    for table in tables:
        cursor.execute("SELECT * FROM  ".format(table))
        wanted[table] = cursor.fetchall()
The first for loop executes each statement. On error, we return a helpful message containing the faulty one. The second for loop records the final rows of each table in wanted.

Applying changes Back to the skeleton described in the previous article, the last step is to apply the changes if there is a difference between got and wanted when not running with check mode. The diff object is a bit more elaborate as it is built table by table. This enables Ansible to display the name of each table before the diff representation:
if got != wanted:
    result['changed'] = True
    result['diff'] = [dict(
        before_header=table,
        after_header=table,
        before=yaml.safe_dump(got[table]),
        after=yaml.safe_dump(wanted[table]))
                      for table in tables
                      if got[table] != wanted[table]]
if module.check_mode or not result['changed']:
    module.exit_json(**result)
Applying the changes is quite trivial: just commit them! Otherwise, they are lost when the module exits.
connection.commit()

The complete code is available on GitHub. Compared to the mysql_query module, this one supports the check mode, signals correctly if there is a change and displays the differences. However, it should not be used with huge tables, as it would try to load them in memory.

  1. The tables need to use the InnoDB storage engine. Moreover, MySQL does not know how to use transactions with DDL statements: do not modify table definitions!

Vincent Bernat: Syncing SSH keys on Cisco IOS-XR with a custom Ansible module

The cisco.iosxr collection from Ansible Galaxy provides an iosxr_user module to manage local users, along with their SSH keys. However, the module is quite slow, do not display a diff for changed SSH keys, never signal change when a key is modified, and does not delete obsolete keys. Let s write a custom Ansible module managing only the SSH keys while fixing these issues.

Notice I recommend that you read Writing a custom Ansible module as an introduction.

How to add an SSH key to a user Adding SSH keys to users in Cisco IOS-XR is quite undocumented. First, you need to encode the key with the ssh-rsa key ASN.1 format, like an OpenSSH public key, but without the base64-encoding:
$ awk ' print $2 ' id_rsa.pub \
      base64 -d \
    > publickey_vincent.raw
Then, you upload the key with SCP to harddisk:/publickey_vincent.raw and import it for the current user with the following IOS command:
crypto key import authentication rsa harddisk:/publickey_vincent.b64
However, if you want to import a key for another user, you need to be part of the root-system group:
username vincent
 group root-lr
 group root-system
With the following admin command, you can attach a key to another user:
admin crypto key import authentication rsa username cedric harddisk:/publickey_cedric.b64

Code The module has the following signature and it installs the specified key for each user and remove keys from retired users the ones we do not specify.
iosxr_users:
  keys:
    vincent: ssh-rsa AAAAB3NzaC1yc2EAA[ ]ymh+YrVWLZMJR
    cedric:  ssh-rsa AAAAB3NzaC1yc2EAA[ ]RShPA8w/8eC0n

Prerequisites Unlike the iosxr_user module, our custom module only handles SSH keys, one per user. Therefore, the user definitions have to already exist in the running configuration.1 Moreover, the user defined in ansible_user needs to be in the root-system group. The cisco.iosxr collection must also be installed as the module relies on its code. When running the module, ansible_connection needs to be set to network_cli and ansible_network_os to iosxr. These variables are usually defined in the inventory.

Module definition Starting from the skeleton described in the previous article, we define the module:
module_args = dict(
    keys=dict(type='dict', elements='str', required=True),
)
module = AnsibleModule(
    argument_spec=module_args,
    supports_check_mode=True
)
result = dict(
    changed=False
)

Getting the installed keys The next step is to retrieve the keys currently installed. This can be done with the following command:
# show crypto key authentication rsa all
Key label: vincent
Type     : RSA public key authentication
Size     : 2048
Imported : 16:17:08 UTC Tue Aug 11 2020
Data     :
 30820122 300D0609 2A864886 F70D0101 01050003 82010F00 3082010A 02820101
 00D81E5B A73D82F3 77B1E4B5 949FB245 60FB9167 7CD03AB7 ADDE7AFE A0B83174
 A33EC0E6 1C887E02 2338367A 8A1DB0CE 0C3FBC51 15723AEB 07F301A4 B1A9961A
 2D00DBBD 2ABFC831 B0B25932 05B3BC30 B9514EA1 3DC22CBD DDCA6F02 026DBBB6
 EE3CFADA AFA86F52 CAE7620D 17C3582B 4422D24F D68698A5 52ED1E9E 8E41F062
 7DE81015 F33AD486 C14D0BB1 68C65259 F9FD8A37 8DE52ED0 7B36E005 8C58516B
 7EA6C29A EEE0833B 42714618 50B3FFAC 15DBE3EF 8DA5D337 68DAECB9 904DE520
 2D627CEA 67E6434F E974CF6D 952AB2AB F074FBA3 3FB9B9CC A0CD0ADC 6E0CDB2A
 6A1CFEBA E97AF5A9 1FE41F6C 92E1F522 673E1A5F 69C68E11 4A13C0F3 0FFC782D
 27020301 0001
[ ]
ansible_collections.cisco.iosxr.plugins.module_utils.network.iosxr.iosxr contains a run_commands() function we can use:
command = "show crypto key authentication rsa all"
out = run_commands(module, command)
out = out[0].replace(' \n', '\n')
A common library to parse a command output is textfsm: a Python module using a template-based state machine for parsing semi-formatted text.
template = r"""
Value Required Label (\w+)
Value Required,List Data ([A-F0-9 ]+)
Start
 ^Key label: $ Label 
 ^Data\s+: -> GetData
GetData
 ^ $ Data 
 ^$$ -> Record Start
""".lstrip()
re_table = textfsm.TextFSM(io.StringIO(template))
got =  data[0]: "".join(data[1]).replace(' ', '')
       for data in re_table.ParseText(out) 
got is a dictionary associating key labels, considered as usernames, with a hexadecimal representation of the public key currently installed. It looks like this:
>>> pprint(got)
 'alfred': '30820122300D0609[ ]6F0203010001',
 'cedric': '30820122300D0609[ ]710203010001',
 'vincent': '30820122300D0609[ ]270203010001' 

Comparing with the wanted keys Let s now build the wanted dictionary using the same structure. In module.params['keys'], we have a dictionary associating usernames to public SSH keys in the OpenSSH format:
>>> pprint(module.params['keys'])
 'cedric': 'ssh-rsa AAAAB3NzaC1yc2[ ]',
 'vincent': 'ssh-rsa AAAAB3NzaC1yc2[ ]' 
We need to convert these keys in the same hexadecimal representation used by Cisco above. The ssh-keygen command and some glue can do the conversion:2
$ ssh-keygen -f id_rsa.pub -e -mPKCS8 \
     grep -v '^---' \
     base64 -d \
     hexdump -e '4/1 "%0.2X"'
30820122300D06092[ ]782D270203010001
Assuming we have a ssh2cisco() function doing that, we can build the wanted dictionary:
wanted =  k: ssh2cisco(v)
          for k, v in module.params['keys'].items() 

Applying changes Back to the skeleton described in the previous article, the last step is to apply the changes if there is a difference between got and wanted when not running with check mode. The part comparing got and wanted is taken verbatim from the skeleton module:
if got != wanted:
    result['changed'] = True
    result['diff'] = dict(
        before=yaml.safe_dump(got),
        after=yaml.safe_dump(wanted)
    )
if module.check_mode or not result['changed']:
    module.exit_json(**result)
Let s copy the new or changed keys and attach them to their respective users. For this purpose, we reuse the get_connection() and copy_file() functions from ansible_collections.cisco.iosxr.plugins.module_utils.network.iosxr.iosxr.
conn = get_connection(module)
for user in wanted:
    if user not in got or wanted[user] != got[user]:
        dst = f"/harddisk:/publickey_ user .raw"
        with tempfile.NamedTemporaryFile() as src:
            decoded = base64.b64decode(
                module.params['keys'][user].split()[1])
            src.write(decoded)
            src.flush()
            copy_file(module, src.name, dst)
    command = ("admin crypto key import authentication rsa "
               f"username  user   dst ")
    conn.send_command(command, prompt="yes/no", answer="yes")
Then, we remove obsolete keys:
for user in got:
    if user not in wanted:
        command = ("admin crypto key zeroize authentication rsa "
                   f"username  user ")
        conn.send_command(command, prompt="yes/no", answer="yes")

The complete code is available on GitHub. Compared to the iosxr_user module, this one displays a diff when running with --diff, correctly signals a change, is faster, 3 and deletes unwanted SSH keys. However, it is unable to create users and cannot configure passwords or multiple SSH keys.

  1. In our environment, the Ansible playbook pushes a full configuration, including the user definitions. Then, it synchronizes the SSH keys.
  2. Despite the argument provided to ssh-keygen, the format used by Cisco is not PKCS#8. This is the ASN.1 representation of a Subject Public Key Info structure, as defined in RFC 2459. Moreover, PKCS#8 is a format for a private key, not a public one.
  3. The main factors for being faster are:
    • not creating users, and
    • not reuploading existing SSH keys.

Vincent Bernat: Writing a custom Ansible module

Ansible ships a lot of modules you can combine for your configuration management needs. However, the quality of these modules may vary widely. Sometimes, it may be quicker and more robust to write your own module instead of shopping and assembling existing ones.1 In my opinion, a robust module exhibits the following characteristics: In a nutshell, it means the module can run with --diff --check and shows the changes it would apply. When run twice in a row, the second run won t apply or signal changes. The last bullet point suggests the module should be able to delete outdated objects configured during previous runs.2 The module code should be minimal and tailored to your needs. Making the module generic for use by other users is a non-goal. Less code usually means less bugs and easier to understand. I do not cover testing here. It is undeniably a good practice, but it requires a significant effort. In my opinion, it is preferable to have a well written module matching the above characteristics rather than a module that is well tested but without them or a module requiring further (untested) assembly to meet your needs.

Module skeleton Ansible documentation contains instructions to build a module, along with some best practices. As one of our non-goal is to distribute it, we choose to take some shortcuts and skip some of the boilerplate. Let s assume we build a module with the following signature:
custom_module:
  user: someone
  password: something
  data: "some random string"
There are various locations you can put a module in Ansible. A common possibility is to include it into a role. In a library/ subdirectory, create an empty __init__.py file and a custom_module.py file with the following code:3
#!/usr/bin/python
import yaml
from ansible.module_utils.basic import AnsibleModule
def main():
    # Define options accepted by the module.  
    module_args = dict(
        user=dict(type='str', required=True),
        password=dict(type='str', required=True, no_log=True),
        data=dict(type='str', required=True),
    )
    module = AnsibleModule(
        argument_spec=module_args,
        supports_check_mode=True
    )
    result = dict(
        changed=False
    )
    got =  
    wanted =  
    # Populate both  got  and  wanted .  
    # [...]
    if got != wanted:
        result['changed'] = True
        result['diff'] = dict(
            before=yaml.safe_dump(got),
            after=yaml.safe_dump(wanted)
        )
    if module.check_mode or not result['changed']:
        module.exit_json(**result)
    # Apply changes.  
    # [...]
    module.exit_json(**result)
if __name__ == '__main__':
    main()
The first part, in , defines the module, with the accepted options. Refer to the documentation on argument_spec for more details. The second part, in , builds the got and wanted variables. got is the current state while wanted is the target state. For example, if you need to modify records in a database server, got would be the current rows while wanted would be the modified rows. Then, we compare got and wanted. If there is a difference, changed is switched to True and we prepare the diff object. Ansible uses it to display the differences between the states. If we are running in check mode or if no change is detected, we stop here. The last part, in , applies the changes. Usually, it means iterating over the two structures to detect the differences and create the missing items, delete the unwanted ones and update the existing ones.

Documentation Ansible provides a fairly complete page on how to document a module. I advise you to take a more minimal approach by only documenting each option sparingly,4 skipping the examples and only documenting return values if it needs to. I usually limit myself to something like this:
DOCUMENTATION = """
---
module: custom_module.py
short_description: Pass provided data to remote service
description:
  - Mention anything useful for your workmate.
  - Also mention anything you want to remember in 6 months.
options:
  user:
    description:
      - user to identify to remote service
  password:
    description:
      - password for authentication to remote service
  data:
    description:
      - data to send to remote service
"""

Error handling If you run into an error, you can stop the execution with module.fail_json():
module.fail_json(
    msg=f"remote service answered with  code :  message ",
    **result
)
There is no requirement to intercept all errors. Sometimes, not swallowing an exception provides better information than replacing it with a generic message.

Returning additional values A module may return additional information that can be captured to be used in another task through the register directive. For this purpose, you can add arbitrary fields to the result dictionary. Have a look at the documentation for common return values. You should try to add these fields before exiting the module when in check mode. The returned values can be documented.

Examples Here are several examples of custom modules following the previous skeleton. Each example highlight why a custom module was written instead of assembling existing modules.

  1. Also, when using modules from Ansible Galaxy, you introduce a dependency to a third-party. This is not something that should be decided lightly: it may break later, it may only meet 80% of the needs, it may add bugs.
  2. Some declarative systems, like Terraform, exhibits all these behaviors.
  3. Do not worry about the shebang. It is hardcoded to /usr/bin/python. Ansible will modify it to match the chosen interpreter on the remote host. You can write Python 3 code if ansible_python_interpreter evaluates to a Python 3 interpreter.
  4. The main issue I have with this non-programmatic approach to documentation is that it partly repeats the information contained in argument_spec. I think an auto-documenting structure would avoid this.

Norbert Preining: Multiple GPUs for graphics and deep learning

For long time I have been using a good old nvidia GeForce GTX 1050 for my display and deep learning needs. I reported a few times how to get Tensorflow running on Debian/Sid, see here and here. Later on I switched to AMD GPU in the hope that an open source approach to both GPU driver as well as deep learning (ROCm) would improve the general experience. Unfortunately it turned out that AMD GPUs are generally not ready for deep learning usage. The problems with AMD and ROCm are far and wide. First of all, it seems that for anything more complicated then simple stuff, AMD s flagship RX 5700(XT) and all GFX10 (Navi) based cards are not(!!!) supported in ROCm. Yes, you read correct AMD does not support 5700(XT) cards in the ROCm stack. Some simple stuff works, but nothing for real computations. Then, even IF they would support, ROCm as distributed is currently a huge pain in the butt. The source code is a huge mess, and building usable packages from it is probably possible, but quite painful (I am member of the ROCm packaging team in Debian, and have tried many hours). And the packages provided by AMD are not installable on Debian/sid due to library incompatibilities. So that left me with a bit a problem: for work I need to train quite some neural networks, do model selection, etc. Doing this on a CPU is a bit a burden. So at the end I decided to put the nVidia card back into the computer (well, after moving it to a bigger case but that is a different story to tell). Here are the steps I did to get both cards working for their respective target: AMD GPU for driving the console and X (and games!), and the nVidia card doing the deep learning stuff (tensorflow using the GPU). Starting point Starting point was a working AMD GPU installation. The AMD GPU is also the first GPU card (top slot) and thus the one that is used by the BIOS and the Linux console. If you want the video output on the second card you need to trick, and probably don t have console output, etc etc. So not a solution for me. Installing libcuda1 and the nvidia kernel drivers Next step was installing the libcuda1 package:
apt install libcuda1
This installs a lot of stuff, including the nvidia drivers, GLX libraries, alternatives setup, and update-glx tool and package. The kernel module should be built and installed automatically for your kernel. Installing CUDA Follow more or less the instructions here and do
wget -O- https://developer.download.nvidia.com/compute/cuda/repos/ubuntu1804/x86_64/7fa2af80.pub   sudo tee /etc/apt/trusted.gpg.d/nvidia-cuda.asc
echo "deb http://developer.download.nvidia.com/compute/cuda/repos/ubuntu1804/x86_64/ /"   sudo tee /etc/apt/sources.list.d/nvidia-cuda.list
sudo apt-get update
sudo apt-get install cuda-libraries-10-1
Warning! At the moment Tensorflow packages require CUDA 10.1, so don t install the 10.0 version. This might change in the future! This will install lots of libs into /usr/local/cuda-10.1 and add the respective directory to the ld.so path by creating a file /etc/ld.so.conf.d/cuda-10-1.conf. Install CUDA CuDNN One difficult to satisfy dependency are the CuDNN libraries. In our case we need the version 7 library for CUDA 10.1. To download these files one needs to have a NVIDIA developer account, which is quick and painless. After that go to the CuDNN page where one needs to select Archived releases and then Download cuDNN v7.N.N (xxxx NN, YYYY), for CUDA 10.1 and then cuDNN Runtime Library for Ubuntu18.04 (Deb). At the moment (as of today) this will download a file libcudnn7_7.6.5.32-1+cuda10.1_amd64.deb which needs to be installed with dpkg -i libcudnn7_7.6.5.32-1+cuda10.1_amd64.deb. Updating the GLX setting Here now comes the very interesting part one needs to set up the GLX libraries. Reading the output of update-glx --help and then the output of update-glx --list glx:
$ update-glx --help
update-glx is a wrapper around update-alternatives supporting only configuration
of the 'glx' and 'nvidia' alternatives. After updating the alternatives, it
takes care to trigger any follow-up actions that may be required to complete
the switch.
 
It can be used to switch between the main NVIDIA driver version and the legacy
drivers (eg: the 304 series, the 340 series, etc).
 
For users with Optimus-type laptops it can be used to enable running the discrete
GPU via bumblebee.
 
Usage: update-glx <command>
 
Commands:
  --auto <name>            switch the master link <name> to automatic mode.
  --display <name>         display information about the <name> group.
  --query <name>           machine parseable version of --display <name>.
  --list <name>            display all targets of the <name> group.
  --config <name>          show alternatives for the <name> group and ask the
                           user to select which one to use.
  --set <name> <path>      set <path> as alternative for <name>.
 
<name> is the master name for this link group.
  Only 'nvidia' and 'glx' are supported.
<path> is the location of one of the alternative target files.
  (e.g. /usr/lib/nvidia)
 
$ update-glx --list glx
/usr/lib/mesa-diverted
/usr/lib/nvidia
I was tempted into using
update-glx --config glx /usr/lib/mesa-diverted
because at the end the Mesa GLX libraries should be used to drive the display via the AMD GPU. Unfortunately, with this neither the nvidia kernel module was loaded, the nvidia persistenced couldn t run because the library libnvidia-cfg1 wasn t found (not sure it was needed at all ), and with that also no way to run tensorflow on GPU. So what I did I tried
update-glx --auto glx
(which is the same as update-glx --config glx /usr/lib/nvidia), and rebooted, and decided to check afterwards what is broken. To my big surprise, the AMD GPU still worked out of the box, including direct rendering, and the games I tried (Overload, Supraland via Wine) all worked without a hinch. Not that I really understand why the GLX libraries that are seemingly now in use are from nvidia but work the same (if anyone has an explanation, that would be great!), but since I haven t had any problems till now, I am content. Checking GPU usage in tensorflow Make sure that you remove tensorflow-rocm and reinstall tensorflow with GPU support:
pip3 uninstall tensorflow-rocm
pip3 install --upgrade tensorflow-gpu
After that a simple
$ python3 -c "import tensorflow as tf;print(tf.reduce_sum(tf.random.normal([1000, 1000])))"
....(lots of output)
2020-09-02 11:57:04.673096: I tensorflow/core/common_runtime/gpu/gpu_device.cc:1402] Created TensorFlow device (/job:localhost/replica:0/task:0/device:GPU:0 with 3581 MB memory) -> physical GPU (device: 0, name: GeForce GTX 1050 Ti, pci bus id: 0000:05:00.0, compute capability: 6.1)
tf.Tensor(1093.4915, shape=(), dtype=float32)
$
should indicate that the GPU is used by tensorflow! The R Keras package should also work out of the box and pick up the system-wide tensorflow which in turn picks the GPU, see this post for example code to run for tests. Conclusion All in all it was easier than expected, despite the dances one has to do for nvidia to get the correct libraries. What still puzzles me is the selection option in update-glx, and might need a better support for secondary nvidia GPU cards.

31 August 2020

Chris Lamb: Free software activities in August 2020

Here is another monthly update covering what I have been doing in the free software world during August 2020 (previous month): I uploaded Lintian versions 2.86.0, 2.87.0, 2.88.0, 2.89.0, 2.90.0, 2.91.0 and 2.92.0, as well as made the following changes:

Reproducible Builds One of the original promises of open source software is that distributed peer review and transparency of process results in enhanced end-user security. However, whilst anyone may inspect the source code of free and open source software for malicious flaws, almost all software today is distributed as pre-compiled binaries. This allows nefarious third-parties to compromise systems by injecting malicious code into ostensibly secure software during the various compilation and distribution processes. The motivation behind the Reproducible Builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. The project is proud to be a member project of the Software Freedom Conservancy. Conservancy acts as a corporate umbrella allowing projects to operate as non-profit initiatives without managing their own corporate structure. If you like the work of the Conservancy or the Reproducible Builds project, please consider becoming an official supporter. This month, I:

diffoscope I made the following changes to diffoscope, including preparing and uploading versions 155, 156, 157 and 158 to Debian:

Debian Debian LTS This month I have worked 18 hours on Debian Long Term Support (LTS) and 12 hours on its sister Extended LTS project. You can find out more about the project via the following video:


Uploads to Debian

Next.

Previous.