Search Results: "jam"

30 October 2006

Benjamin Mako Hill: Software Freedom Curriculum

About a year ago, I was working on OLPC during most of the time and thinking a lot about software freedom in the context of the project. My blog post on OLPC and Charges of Technological and Cultural Imperialism from last December is a great example of my thinking out loud about some of the issues. The attractive thing to me about OLPC was the idea of students getting a real, free software, free hardware, truly open platform unlike phones, calculators, and eBooks: closed paternalist platforms that seem to be the only real alternatives. This is a goal that OLPC has not achieved yet but has already come quite close to. People say that because modifying technology is often difficult, only a small percentage of users -- especially young users -- will take advantage of the malleability or "hackability" of a product. They are probably right. But part of why this happens is because when computers are employed in education, we use them as tools to accomplish predefined and preprogrammed tasks. Even when students learn to program, it's in a window (quite literally in a box) separate from the rest of the things that the computer does. And for someone working on a project in part so that they can spread technological freedom, this is a problem. Consider the fact that with only a small number of exceptions, the only advocates of software freedom I know are programmers or hackers. I don't think that this is because of some "programmer's sensibility" but rather because programmers understand a set of things about the malleability of software and the nature, effect, and context of computation that gives them perspective to understand how a concept like freedom might apply to something like software. In other words, to understand software freedom, you must first understand -- really understand -- what software is and what it is not, how it makes things possible and impossible, and how changing it can have important effects. The mentality I've described is currently a "hacker's sensibility" but I don't believe that you need to be a hacker to understand why software freedom is important. Proof, I think, is the fact that people think that a free press is important even if they don't publish or write very well. As an exercise, I took it on myself to write the beginning of a curriculum that teachers could use to teach students about software freedom and the concepts that I think are key to understanding it. It tries to come up with models for framing discussions and a series of activities to help teachers teach relatively young (i.e., middle school students) about issues of computation, information goods, and ultimately about software freedom. I wrote the curriculum about a year ago, showed it to a few teachers and colleagues, and then sat on it because I wasn't sure what to do with it and because I was concerned by my own lack of experience teaching outside of Universities. I'm still not entirely sure about incredibly basic things like what form a curriculum should take for this age group. I noticed recently that Wikiversity launched in August and it seems like the perfect place to put my curriculum for consumption by the world and for collaboration, discussion, and further development. You can see what I've got from this page and the pages linked from it:
http://en.wikiversity.org/wiki/Software_Freedom
The project still needs lots of work. It needs to be threshed out on its own terms and it needs to be broken down and integrated into Wikiversity as a series of learning projects, learning activities, etc. I've looked at the documentation around Wikiversity and I can neither understand how to do this nor find examples of large curricula in Wikiversity to which this has already been done. If you have experience on Wikiversity, your help would be welcome. If you are interested in using part of the curriculum, I would love to hear from you and to see your edits on the wiki.

James Morrison: Alumnit

Yeah, I'm back on alumnit. I'm sorry to all those that had to see those same old 4 posts for so long. What happened is that my feed changed and it looks like PlaNit didn't deal too well with redirected feeds.

29 October 2006

James Morrison: Accretion

If anyone could tell me why people on the google image labeller game guess 'accretion' for random pictures, could they please tell me! 'Abrasives' also seems to be used. Today's image with the 'accretion' guess was http://www.batmannews.de/gotham_multimedia/fan_art/pics_big/Batman%20Begins.jpg.

Benjamin Mako Hill: Myopia

Maybe I'm just uncultured but when I first heard the name of the Myopia Hunt Club, my thoughts leaned more toward my vice president than a golf club. Apparently, I wasn't too far off etymologically.

27 October 2006

Benjamin Mako Hill: I MIT Libraries

There are many things at MIT that I find I want to distance myself from (e.g., much of the military related research). Recently though, the MIT Libraries have been giving me a number of reasons to be proud to be an MIT graduate student. MIT has taken the brave step of the being one of the first major research universities to throw a stone at the publishers in the whole Open Access, scholarly publishing debate. The libraries have put up a bunch of information on open access issues and have created a copyright amendment form for all scholarly publication that will allow the institute and its authors to retain copyright over their work for publication in the institute archives, on the author's website, or even in an open access repository like PubMed Central. More importantly, MIT Libraries are offering to do all of the negotiation with the publishers on behalf of the authors. When it is MIT as a whole, and not just the one graduate student, post-doc, or professor on their own, it puts the authors in a much stronger to retain the openness of their work. It's not victory, but it's an important and essential step toward open access for scholarly publishing. But that's not it! The libraries have also recently stood up to Hoover's Online's attempt to hold the libraries responsible for, "activity Hoovers deemed or even suspected was fraudulent." When Hoover's gave the libraries the choice of saying yes to a set of unreasonable terms or walking away from an important research tool, MIT Libraries made the difficult but correct choice and walked away. Making a choice like that will surely get the libraries a lot of flak from MIT scholars who use Hoover's. But MIT made the right decision by standing up for their principles. The effect of large, powerful institution like MIT is usually to maintain the status quo. There's clearly a lot of external pressure from funders, politicians, etc. and internal pressure from academics and students who are doing well by the current system. MIT Libraries are using their power to make the whole system better and I haven't ever been as proud to be an MIT student.

Scott James Remnant: Not That Edgy

Now that Ubuntu 6.10 (“The Edgy Eft”) has been released, we’re starting to see reviews of it; while largely positive, one common theme is that Edgy isn’t quite as edgy as people were expecting. Mark’s original announcement is certainly the likely reason for this expectation. In it he set the scene for a bold, brash, bleeding edge release to counter the boring dapper release. Unfortunately, the simple truth is that reality set in. When planning the release schedule for edgy, we realised that if we wanted to get back to our original six-monthly release schedule, we were only going to have four months in which to develop it. That’s still enough time to throw everything to the wind, and shove out a “release” at the last moment when the CD happens to be installable. It’d be edgy in the extreme sense. Unfortunately while exciting, we felt that such a release would ruin Ubuntu’s reputation. It’d be a release that, for all intents and purposes, would only be interesting to Ubuntu developers. Mark has already touched on this in his blog, citing a conversation he had with Matt (the Ubuntu CTO). Especially noteworthy is the mention that the kinds of itches that developers get are not the same as those users get. We get itches because the installer still relies on devfs-style paths, or because it’s not possible to boot the system without race-conditions. None of these things are noticeable to the end-user. We’re drawing up the list of topics to be discussed at UDS Mountain View in two weeks time, this is as good a guide as any for what we’re thinking about for feisty, the next release. At the end of that summit, we’ll have a list of approved specifications, assigned to developers throughout the community for implementation in the feisty schedule. Obviously some of those won’t make it due to time constraints, but the best thing about a six-monthly release cycle is that they’re not delayed for long.

Scott James Remnant: Having Left Debian

It’s been over a year now since my last proper upload to Debian, and nine months since I announced my intent to put aside working on Debian for a while. With Matthew Garrett’s resignation from Debian, several people have compared it to my own “resignation” from Debian. It has got my thinking about whether I currently intend to ever end my “Sabbatical” and return as an active Debian Developer. I think that the end of my love-affair with Debian started at Debconf last year where several developers treated those of us who also worked on Ubuntu quite rudely. Someone was attacked for wearing an Ubuntu t-shirt at the conference, while someone else was applauded for wearing a “Fuck Ubuntu” t-shirt. That’s where I realised that maybe I didn’t have as much in common with these people as I thought I did. I still don’t understand why Debian singles Ubuntu out for this kind of treatment, we’re still the only derviative distribution that makes all of our patches to Debian available, yet Ubuntu is claimed to not do anything at all. Another example is that Ubuntu is being asked to change the Maintainer field of every package, something no other derivative is being asked to do or has ever been asked to do. Martin Krafft has had some interesting things to say about this strange relationship in the past. If that was the start of my falling out with Debian, I think that Debian considering removing documentation and firmware from the distribution, especially the documentation, was another point I started wondering whether I shared anything in common with the project anymore. Call me strange, but I think that one of the fundamental purposes of a Linux distribution is to be useful to its users. If nobody can use the distribution because it doesn’t support their hardware, and even if it did, all the documentation has been stripped out; I started to wonder what it’s aims are. It became increasingly apparent that the only users Debian was considering a priority were its own developer. And the third thing is simply a matter of Fun. Fun for me, at the moment at least, has been to build a system that fits together extremely nicely with each component doing the right thing. For Ubuntu this has meant being a driving force for it being Linux 2.6 only, with reliance on udev for hardware, etc. Upstart is just a continuation of these goals, getting a system which all “just works”, even if it means throwing out a few things people were previously fond of. All of these things would have been impossible to do in Debian itself. Getting upstart installable required changes to twelve different packages, including sysvinit itself; at a worst case, this would have required the agreement of twelve different maintainers in Debian. It’s often exhausting just persuading one of the reason for the change, persuading a dozen would have been a herculian effort. Perhaps Matthew is right, what Debian lacks is a single leadership. There’s nobody in Debian I could have gone to for approval over the changes I wanted to make, whose decision developers cannot overrule. Ubuntu has such people (the Technical Board and sabdfl), which gives the project an obvious direction instead of a couple of hundred people all pulling in different directions. In a way, I don’t feel that I’ve left Debian. I feel like I was happily going along, only to realise the mob had gone in a different direction and with no easy way of rejoining the group.

Scott James Remnant: Upstart can now replace sysvinit

Today I reached another milestone in the development of upstart, the packages in universe can now replace the existing sysvinit package. Before trying this, make sure your installation is up to date as we’ve had to split out some parts of sysvinit into a new sysvutils package. If you’re up to date, and want to try it out, install the upstart and upstart-compat-sysv packages from universe. Note that the first reboot after you’ve installed the packages (from sysvinit to upstart) will be a little tricky … use reboot -f. If your system boots and shuts down normally, everything’s working just fine. Note that both will be somewhat more quiet than you’re used to, unless you have usplash running. Throughout the rest of this entry, I’ll try to answer some of the questions and comments that I’ve received since the last post. Events As I talked about previously, upstart is an event-based init daemon. Events are the primary force for having your services and tasks started and stopped at the appropriate time and in the appropriate order. So what are events and where do they come from? (Note that this part is under development, so may change in later releases). Events are just simple strings that may be sent by any process when something it is tracking the state of changes. They have no state or longevity, and if, when queued, they do not cause any job state changes, then they have no effect unless they are sent again. Jobs can list which events cause them to be started if they are not already running and which events cause them to be stopped if they are running. Multiple start and stop events may be listed, in which case the first to occur changes the job until the next one occurs. upstart itself generates the following system events: The shutdown tool included in the package also causes one of the following events to be sent once the “shutdown” event has been handled: Jobs also generate events whenever they change state, this is the primary source of events for ordering: And as mentioned, any other process on the system may send events through the control socket or just by using initctl trigger EVENT. For now this is just the event string, however it’s intended that the event may include other details including environment variables and even file descriptors. Typical example To clarify how it all hangs together, here’s an example (using fictional names) of how the tasks and events can be arranged to provide race-free mounting of filesystems. By breaking this job into these small tasks, we can see how the pieces fit together. Because everything is now done on events, there are no race conditions; we know that any filesystem listed in /etc/fstab will be checked and mounted. The only reason they wouldn’t be is if there’s an error of some kind, and that means you have larger problems anyway and the system administrator would have a shell to fix it. Of course, the moment they finish checking the filesystem and mount it, the boot process would carry on. There’s no reason that any of these events need to be generated by the upstart daemon itself, it can receive them from any other daemon on the system such as udev, acpid, etc. This keeps the focus of the init daemon narrow. A large part of the future development will be working out exactly what kinds of events we want init itself to generate, what kinds we want to come from elsewhere, and what the contents of an event can be. Getting Involved If you want to get involved with trying to nudge the direction of upstart development, you can join the upstart-devel mailing list at http://lists.netsplit.com/ Or if you just want to grab the source code, tarballs are published at http://people.ubuntu.com/\scott/software/upstart/ and the bzr archive is at http://bazaar.launchpad.net/\keybuk/upstart/main

Scott James Remnant: Upstart in Universe

upstart is a replacement for the init daemon, the process spawned by the kernel that is responsible for starting, supervising and stopping all other processes on the system. The existing daemon is based on the one found in UNIX System V, and is thus known as sysvinit. It separates jobs into different “run levels” and can either run a job when particular run levels are entered (e.g. /etc/init.d/rc 2) or continually during a particular run level (e.g. /sbin/getty). The /etc/init.d/rc script is also based on the System V one (and is in the sysv-rc package), it simply executes the stop then start scripts found in /etc/rcN.d (where N is the run level) in numerical order. Why change it? Running a fixed set of scripts, one after the other, in a particular order has served us reasonably well until now. However as Linux has got better and better at dealing with modern computing (arguably Linux’s removable device support is better than Windows’ now) this approach has begun to have problems. The old approach works as long as you can guarantee when in the boot sequence things are available, so you can place your init script after that point and know that it will work. Typical ordering requirements are: This worked ten years ago, why doesn’t it work now? The simple answer is that our computer has become far more flexible: We’ve been able to hack the existing system to make much of this possible, however the result is chock-full of race conditions and bugs. It was time to design a new system that can cope with all of these things without any problems. What we needed was an init system that could dynamically order the start up sequence based on the configuration and hardware found as it went along. Design of upstart upstart is an event-based init daemon; events generated by the system cause jobs to be started and running jobs to be stopped. Events can include things such as: In fact, any process on the system may send events to the init daemon over its control socket (subject to security restrictions, of course) so there is no limit. Each job has a life-cycle which is shown in the graph below: The two states shown in red (“waiting” and “running”) are rest states, normally we expect the job to remain in these states until an event comes in, at which point we need to take actual to get the job into the next state. The other states are temporary states; these allow a job to run shell script to prepare for the job itself to be run (“starting”) and clean up afterwards (“stopping”). For services that should be respawned if they terminate before an event that stops them is received, they may run shell script before the process is started again (“respawning”). Jobs leave a state because the process associated with them terminates (or gets killed) and move to the next appropriate state, following the green arrow if the job is to be started or the red arrow if it is to be stopped. When a script returns a non-zero exit status, or is killed, the job will always be stoped. When the main process terminates and the job should not be respawned, the job will also always be stopped. As already covered, events generated by the init daemon or received from other processes cause jobs to be started or stopped; also manual requests to start or stop a job may be received. The communication between the init daemon and other processes is bi-directional, so the status of jobs may be queries and even changes of state to all jobs be received. How does it differ from launchd? launchd is the replacement init system used in MacOS X developed as an “Open Source” project by Apple. For much of its life so far, the licence has actually been entirely non-free and thus it has only become recently interesting with the licence change. Much of the goal of both systems appears initially to be the same; they both start jobs based on system events, however the launchd system severly limits the events to only the following: Therefore it does not actually allow us to directly solve the problems we currently have; we couldn’t mount filesystems once the “filesystem checked” event has been recived, we couldn’t check filesystems when the block device is added and we certainly couldn’t start daemons once the complete filesystem (as described by /etc/fstab) is available and writable. The launchd model expects the job to “sit and wait” if it is unable to start, rather than provide a mechanism for the job to only be started when it doesn’t need to wait. Jobs that need /usr to be mounted would need to spin in a loop waiting for /usr to be available before continuing (or use a file in a tmpfs to indicate it’s available, and use that modification as the event). This is not especially surprising given that Apple have a high degree of control over both their hardware and the actual underlying operating system; they don’t need to deal with the wide array of different configurations that we have in the Linux world. Had the licence been sufficiently free at the point we began development of our own system, we would probably have extended launchd rather than implement our own. At the point Apple changed the licence, our own system was already more suitable for our purposes. How does it differ from initng? Initng by Jimmy Wennlund is another replacement init daemon intended to replace the sysvinit system used by Linux. It is a dependency-based system, where upstart is an event-based system. The notion of a dependency-based system is interesting to talk about at this point. Jobs declare dependencies on other jobs that need to happen before the job itself can be started. Starting the job causes its dependencies to be started first, and their dependencies, and so on. When jobs are stopped, if running jobs have no dependencies, they themselves can be stopped. It’s a neat solution to the problem of ordering a fixed boot sequence and the problem of keeping the number of running processes to a minimum needed. However this means that you need to have goals in mind when you boot the system, you need to have decided that you want gdm to be started in order for it, and its dependencies, to be started. Initng uses run levels to ensure this happens, where a run level is a list of goal jobs that should be running in that run level. It’s also not clear how the dependencies interact with the different types of job, a dependency on Apache would need the daemon to be running where a dependency on “checkroot” would need the script to have finished running. Upstart handles this by using different events (“apache running” vs. “checkroot stopping”). Again while interesting, Initng does not solve the problems that we wanted to solve. It can reorder a fixed set of jobs, but cannot dynamically determine the set of jobs needed for that particular boot. A typical example would be that if the only dependency on the job that configures networking is the mount network filesystems job, then should that job fail or notbe a goal (e.g. because there are no network filesystems to be mounted) the result is that network devices themselves will not be configured. You could make everything a goal, and just use the dependencies to determine the order, however this is less efficient than just ordering the existing sysv-rc scripts (which can be done at install time). Another example is that often you simply don’t know whether something is a dependency or not without reading other configuration, for example the mount network filesystems may be a dependency of everything under /usr or may just be a dependency of anything allowing the user to login if it just mounts /home. The difference in model can be summed up as “initng starts with a list of goals and works out how to get there, upstart starts with nothing and finds out where it gets to.” How does it differ from Solaris SMF? SMF is another approach to replacing init developed by Sun for the Solaris operating system. Like initng it’s a dependency-based system, so see above for the differences between those systems and upstart. SMF’s main focus is serive management; making sure that once services are running, they stay running, and allowing the system administrator to query and modify the states of jobs on the system. Upstart provides the same set of functionality in this regard, services are respawned when they fail and system administrators can at any time query the state of running services and adjust the state to their liking. Will it replace cron, inetd, etc? The goal of upstart is to replace those daemons, so that there is only one place (/etc/event.d) where system administrators need to configure when and how jobs should be run. In fact, the goal is that upstart should also replace the “run event scripts” functionality of any daemon on the system. Daemons such as acpid, apmd and Network Manager would send events to init instead of running scripts themselves with their own perculiar configuration and semantics. A system administrator who only wanted a particular daemon to be run while the computer was on AC power would simply need to edit /etc/event.d/daemon and change “on startup” to “on ac power”. What about compatibility? There’s a lot of systems administrators out there who have learned how Linux works already and will not want to learn again immediately, there’s also a large number of books that cover the existing software and won’t cover upstart for at least a couple of years. For this reason, compatibility is very important. upstart will continue to run the existing scripts for the forseeable future so that packages will not need to be updated until the author wants. Compatibility command-line tools that behave like their existing equivalents will also be implemented, a system administrator would never need to know that crontab -e is actually changing upstart jobs. Does it use D-BUS?
“To D-BUS people, every problem seems like a D-BUS problem.” —Erik Troan
The UNIX philosophy is that something should do just one job, and do it very well. upstart’s one job is starting, supervising and stopping other jobs; D-BUS’s one job is passing messages between other jobs. D-BUS does provide a mechanism for services to be activated when the first message is sent to them, thereby starting other jobs. Some people have taken this idea and extended it to suggest that all a replacement init system need do is register jobs with D-BUS and turn booting into a simple matter of message parsing. This seems wrong to me, D-BUS would need to be extended to supervise these services, provide means for them to be restarted and stopped; as well as deal with being process #1 which means cleaning up after children whose parent’s have died, etc. It seems far simpler to arrange for D-BUS to send an event to init when it needs a service to be started, and focus on being a very good message passing system. The IPC mechanism used by upstart is not currently D-BUS because of various problems, however it’s always been expected that even if init itself doesn’t communicate with D-BUS directly, there would be a D-BUS proxy that would ensure messages about all init jobs and events would be given to D-BUS and D-BUS clients could send messages to init to query and change the state of jobs. What is the implementation plan? Because this is process #1 we are changing, we want to make sure that we get it right. Therefore instead of releasing a fully-featured daemon and configuration to the world, we’re developing it in the following stages:
  1. Principal development; at the end of this stage the daemon has been implemented and can manage jobs as described.
  2. Replacement of /sbin/init while running the existing sysv-rc scripts. This is the shake-down test of the daemon, can it perform the same job as the existing sysvinit daemon without any regressions?
  3. /etc/rcS.d scripts replaced by upstart jobs. These consitute the majority of tasks for booting the system into at least single-user mode, and contain many of the current ordering problems and race conditions. If the daemon solves the problems here, it will be a success.
  4. Other daemon’s scripts replaced by upstart jobs on a package-by-package basis; this will be an ongoing effort during which upstart will continue running the existing sysv-rc scripts as well as its own jobs. During this time the event system may be tweaked to ensure it truly solves the problems we need.
  5. Replcement of cron, atd, anacron and inetd. This will happen alongside the above and result in a single place to configure system jobs.
  6. Modification of other daemons and processes to send events to init instead of trying to run things themselves.
The current plan is that we will be at least part of the way into stage #3 by the time edgy is released, with that release shipping with upstart as the init daemon and the most critical rcS scripts being run by it to correct the major problems For edgy+1 we hope to have completed stage #5 and be at least part of the way into the implementation of stage #6. From the start of development of edgy+2, no new packages will be accepted unless they provide upstart jobs instead of init scripts and init scripts will be considered deprecated. What state is it in now? The init daemon has been written and is able to manage jobs as described above, receiving events on the control socket to start and stop them. This has now been uploaded to the Ubuntu universe component in the upstart package for testing before it becomes the init daemon. We welcome any experienced users who want to help test this; install the package and follow the instructions in /usr/share/doc/upstart/README.Debian to add a boot option that will use upstart instead of init. If your system boots and shut downs normally (other than a slightly more verbose boot without usplash running) then it is working correctly. Other types of events will be added as required during development and testing. Currently only a basic client tool (initctl) has been written, compatibility tools such as shutdown will be written over the next week or two before it replaces our sysvinit package.
Scott James Remnant: Parallel Peer Programming

Here at Canonical Towers we have several staff who worship at the altar of Extreme Programming, and as such many of the methodologies and rituals prescribed by that religion find their way into our day-to-day working practices. A few of these came together in an interesting way a few weeks ago, and it was suggested by a cow-orker that I blog about it so he could give the URL to people. The first ritual is that of the sprint, I don’t think this is orthodox XP but rather something inspired from it that we picked up from the Python community. With all of the Canonical developers scattered across the globe mostly working from their own homes, it’s become a useful tool; particularly for the Launchpad team. The basic idea for those that haven’t heard of it is simple, and perhaps obvious; you get a selection of the team together in one place, sit them around the same table with particular goals to complete. In effect it’s highly compressed facetime and high bandwidth interaction to nail those tasks that need it, before you head off again and work at a more sedate pace. The second is directly from XP doctrine and is that peculiar observance known as pair programming, something that is often coupled with sprints. For anybody who hasn’t encountered this before, it’s something I’ve always found rather odd. You get two programmers together, both itching to code, and you take one of them’s laptop away; and you don’t just force them to fight over the keyboard either, the laptop-less soul isn’t allowed to touch it. The theory here is that it frees the deprived individual of the hassle of coding and allows them to direct the programmer in ways that may not be immediately obbious, or alternately think about the next bit of work that needs doing. Another interesting side-effect is it can be an interesting way to learn code you’ve not worked with before, if you’re the one doing the coding and you’re being guided what to do by a sage who already knows it. I have a funny story here, so I’m going to digress from the main stream for a moment to tell it. A few months ago I was working in the London office, Mark had been up all night coding and had then given me responsibility to get his changes landed onto the Launchpad mainline. I’m not that hot on quite a bit of Launchpad, and fade to utterly clueless the nearer the code gets to the web application itself; and when trying to merge the two there were conflicts which I needed Mark’s help to resolve. Now as anybody who’s met Mark knows, he’s a pretty good example of a Type-A personality, yet he suggested that we do a spot of pair programming to get the code in and I’d be the one with the laptop as it’d help me get to grips with the affected parts. This hilighted something I’ve always seen as a problem with pair programming, dealing with it when the a person with the keyboard has a totally different way of working to you. In particular, I’m an emacs user, whereas Mark is a die-hard vim user; but also right down to the working directory I would work from, how I test results, etc. When you’re the one without the laptop, this can be quite infuriating, as you know exactly how to solve a problem and the idiot with the keyboard is dithering about doing things you don’t understand just to get there. If you’re a Type-A personality, you generally snatch the laptop away at this point and do it yourself; or at least you would, if you could drive the strange editor the other person uses. I swear Mark was sulking as he gave the laptop back and let me do it. Anyway, there is some relevance to that and we’ll come to it in a moment. The third and final methodology is the concept of unit tests and more specifically test driven development. For anyone who hasn’t come across this before, I highly recommend it; I was suspicious too when Robert Collins took it upon himself to teach me the true way, but now I’m sold. Simply the idea is that if you have any code that doesn’t have another piece of code in a test suite that checks that it’s working correctly, that code is broken. More particularly unit testing involves checking just one feature or requirement at a time, and stacking them together to test all of the code paths. I’ve actually found that this improves the APIs I design, as I write the code in small blocks and functions to make them easier to test. Test driven development takes it even further, you write the unit tests first, before you write the code they’re supposed to test; usually one or two at a time. Obviously these tests will fail at first, it’s then your job to write as little code as possible to make them pass. If your code isn’t right, you add a unit test that will fail, and modify the code to make it pass. This really comes into its own when you’re fixing bugs later, once you’ve identified the bug you write a test case or two that cause the problem; these will of course fail. You can then modify the code to make them pass, and at the same time be sure you’ve not broken other functionality because of the existing test suite. I’ve also found it really useful for particularly complicated or tricky pieces of code, especially those intricate algorithms that do particularly heavy lifting. So onto the event itself, this was a sprint in our London office to indoctrinate Gustavo Niemeyer with the various projects he’d be working on. The goal for this sprint was decided to start the conversion of HCT to Bazaar-NG, and to do this Gustavo and I would pair program. Now my last experience of pair programming had been that story with Mark (see, it had some relevance) and I knew I’d be just as bad if I wasn’t allowed to have the keyboard. I was also acutely aware that if Gustavo was just sitting by and watching, he wouldn’t get much benefit from it either, so he needed to be actively involved in the coding so he could learn the things he’d be working on. I came to what I thought was a pretty neat, and obvious, solution to these problems. We set up my laptop with the code we’d be working on, and on my display were two side-by-side terminals both running screen sessions. Gustavo then set up two same-sized terminals on his, ssh’d into my laptop from both of them and joined the screen sessions. In the left-hand one he ran vi, and in the right-hand one I ran emacs. Thus we both had keyboards, and both had editors, yet could see each other working and even steal the keyboard without danger of violence. We didn’t just sit side-by-side and code on different things though, that’s not pair programming and is just ordinary programming with a bit of a voyeuristic twist. What we did was: in my terminal I started writing the test cases for the code we needed, it was Gustavo’s job to write the code that would make them pass. We actually added a third terminal in which we could run the test cases themselves; so I could run them when I’d added something that would fail, and Gustavo could run them when he thought he’d made them pass again. This turned out to be a rather fun way to work, and at one point I was almost able to try and convince myself that the code was writing itself to pass the test cases I was writing. It also got me thinking that it’d be really neat to use genetic algorithms to breed code to pass test cases.

Scott James Remnant: Apologies to Planet Readers

Apologies to anyone reading my blog on a Planet for the sudden dump of old posts from my blog. In fact, as it’s already been pointed out, I should apologise twice as much since I wrote Planet itself and am doubly-responsible for the flood. In order to satisfy the suggestions from the like of Jono Bacon and Matthew Revell and actually blog more about the things that I do, I decided it was time to try some new blog software. Until now I’ve been using PyBlosxom, and while it’s popular with the geek crowd, I’ve never really got on with it. The principal problem is that it’s a pain to actually add blog entries to it, or to manage those that you’ve added previously. I’m slightly ashamed to say that I wanted something with a web interface. Thom May pointed me at Typo which seems pretty neat so far, and it doesn’t require PHP which can only be a good thing! So now when I don’t post, I won’t be able to blame the tools. Damn. Maybe this wasn’t such a good idea, after all?

Scott James Remnant: What I want in edgy+1

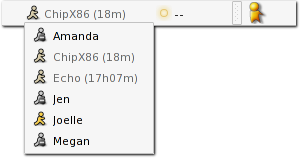
Now that edgy has been frozen for the beta release in a week’s time, and the next developer summit, where the plans for the next release will be discussed, has been announced, I think it’s the perfect time to start thinking about the kinds of features we want to see in that release. At our recent sprint in Wiesbaden, Mark reminded us that when Ubuntu first released we were leading the field in many of the components we installed by default. Many users came to us because we provided Linux 2.6, hotplug/udev and Project Utopia by default; along with the latest GNOME release and development framework. Now everybody does that, butwe led the way. With the dapper release, we produced something that could be supported for a long time. With edgy we’ve scratched our itches and fixed things under the hood that have been causing us problems. edgy+1 seems a good time to integrate the hottest new technologies and lead the way again. So what do I think is exciting, and what do I want in edgy+1? telepathy, farsight and galago Anybody who has used the 2006 software release for the Nokia 770 Internet Tablet will have seen these in action already. They’re, in my opinion, some of the most exciting projects currently being worked on; and ripe for integration into Ubuntu. Telepathy is a communication framework built on DBus that allows any application to establish communication with users all around the world, using any protocol from IRC to MSN to VoIP. It uses Farsight to provide the codecs and protocol support on top of the (GStreamer)[http://gstreamer.freedesktop.org/] media framework. And Galago glues it all together; providing presence information about contacts and allowing users to specify their own status. Galago Presence Applet This means that you’ll be able to contact your contacts. Your calendar alarm tells you that it’s a colleague’s birthday, you’d be able to click their name and see a selection of different ways that you can contact that person right now. From e-mail, opening an MSN or Jabber window or even establishing a VoIP or SIP call to them. The most exciting thing is that because every application on the desktop has easy access to this, people are coming up with fantastic ideas for using it! zeroconf By this, I mean zero configuration networking. Something the OLPC project appears to be going to do very well indeed. Where no existing network infrastructure exists, your computer should still be able to communicate with other nearby computers. It should use ad-hoc wireless networks, link-local IP addresses and server-free DNS resolution with libnss-mdns. Play games with your friends on the train without touching a button. Chat with other people in a lecture hall or at a conference where the existing network is unavailable. Hassle-free home and office networking without any complicated set up. Networking that “just works”. avahi Whether your computer is on an infrastructure or ad-hoc network, it should be able to locate resources on the network and share its own to other people. Avahi allows applications to, via DBus, do this by using a mulicast form of DNS; compatible with Apple’s Bonjour protocol. The immediately obvious benefits of this are that one can locate such things as file servers without any complicated directory; more fun things can be done too, such as sharing your music from RhythmBox with other users on the network. Combine it with telepathy, etc. and you can establish communication with anyone else, with a wide range of different protocols. The immediate problem here is that we currently have a “no open ports” policy, which if we’re going to give the users the opportunity to establish ad-hoc networks is almost certainly a very good thing. We already have exceptions for that policy for DNS and DHCP, it may be that Avahi (mDNS) joins that list. Another option is a “mobile-phone like” interface for enabling and disabling discovery and sharing. Bluetooth I don’t think we should stop discovery and sharing at 802.* networking either. Linux actually has a pretty decent bluetooth stack, it’s something that we should start taking advantage of. Your computer should be able to discover paired or known bluetooth devices when in range without intervention and communicate with them. If I attempt to establish a network connection, and my phone is nearby, that should be offered as a method for getting on the Internet. If possible, it should also be offered through telepathy as a method for contacting people in my address book! Synchronisation These technologies together give us a really big possibility, automatic synchronisation of user’s information. When I bring my laptop home, it should automatically update my desktop with any changes I’ve made to my address book or calendar, and any shared files, etc. Likewise it should be automatically be updated with any changes made on the network, to a company address book on a server, for example. And why stop there? Don’t use share your music, synchronise it so that your laptop, desktop and iPod have the same selection available at all times. Hassle-free backups is an obvious win here. But we’re stopping again. Why is my mobile phone, and PDA excluded from this? Via bluetooth, my address book and calendar should be automatically updated from these and these should be automatically updated themselves. If I add a new number to my phone’s memory, it should appear in my computer address book; and my computer should offer me the ability to contact that person (using VoIP, for example).
Scott James Remnant: Teardown

One of the feature goals for edgy was to make sure that the shutdown process didn’t take any longer than it had to, something we called Teardown. Basically we don’t run any stop scripts for daemons if they don’t do anything more than send the running daemon the TERM signal. These scripts were just wasting time, because part of the shutdown process is to send a TERM signal to all running processes anyway. The savings have been quite amazing, an edgy machine can shutdown in just a few seconds. One of the more amusing consequences of this change was Bug #61530, the new shutdown sound is too long so is still playing when the sound card gets muted and the player process killed. We briefly experimented with fading out the mixer, instead of muting it, but the sound is sufficiently melodious and subtle that the fade had to be several seconds long to sound better than a simple cut-off. Another suggestion was deliberately extending the shutdown sequence (with a sleep or wait) so that the entire shutdown sound was played before the fast shutdown sequence began. This to me seemed like a bit of a backwards step; we got the shutdown sequence fast because the user wants their machine off (or rebooted) – and that is something that should happen as close to immediately as possible. Happily consensus appears to be forming that with the rapid shutdown process, we don’t need any kind of shutdown sound at all.

Scott James Remnant: LCA

Looks like I’ll be heading to linux.conf.au 2007 as well, my paper upstart - an event-based init daemon for Linux has been accepted! Now the difficult part of finding flights that don’t cost an arm and a leg!

26 October 2006

Benjamin Mako Hill: MVS

About a 6 weeks ago, I uploaded a great piece of software into Debian. The package is libwww-mediawiki-client-perl but you can also get it by installing the package mvs. The software seems to be a couple years old -- but it's new to me and I'm been thrilled with it so I thought I would share. The package is a library but its usefulness to me centers around a cute little command-line wrapper to the library called mvs. mvs essentially provides a simple CVS-like interface to an instance of Mediawiki that facilitates offline editing of Mediawiki pages and much more. Here's a quick little walk-through that I wrote for the README.Debian file that might give someone a pretty good description of how the software works:
Step 1: make a directory to store pages from this Mediawiki instance:
mkdir en-wp
cd en-wp
Step 2: log in to the host with your username/password:
mvs login -d wikipedia.org -l en -u 'Benjamin Mako Hill' -p password
Step 3: download a page that you want to edit by adding ".wiki" to the end:
mvs update Granrojo.wiki
Step 4: edit the file to make changes:
vim Granrojo.wiki
Step 5: preview your changes:
mvs preview Granrojo.wiki
Step 6: commit your changes into the wiki:
mvs commit --minor yes -m 'made spelling fix' Granrojo.wiki
And that's all there is to it! It brings a whole series of things that were almost prohibitively difficult through the web interface into reach (e.g., diffing two different pages to see if they've diverged) and its changed the way that I interact with Wikipedia in some exciting ways. Thanks to Mark Jaroski for writing and maintaining the software!

25 October 2006

Benjamin Mako Hill: PyBlosxom Hacks Page

Since my weblog catastrophe a few months ago, I've been spending a little more time getting my PyBlosxom setup on copyrighteous into shape. Initially, my efforts were focused on a series of patches to PyBlosxom and to several important plugins. As I became a little more familiar with the code base, I realized that in an evening or a little bit of downtime, I can pretty easily create my own plugins. I've already managed to accumulate a few of them. I've created a page on my website to hosts these and have put what I've got publishable so far up there. I've got two more that I'm still in the process of vetting on the PyBlosxom mailing list but that I'll post there (and announce on this blog) soon. The first plugin that I've published there is a very simple plugin I wrote to display ads (I am experimenting with Google ads but it should work with other ad providers or even for non-ads) but only to those who get to my old blog entries by searching for them. My thinking was inspired by an old post by my friend Evan where he described setting up Google advertisements in a way that would not affect his core readership but might allow him to use blogging to make his activism financially sustainable. While I suspect (and hope!) that most my own readership's Internet experience is mediated by Adblock and Filterset.G, the plugin will spare even those that don't while showing ads to those I don't know yet.

23 October 2006

Martin F. Krafft: Testing mdadm

The problem with being the mdadm maintainer is that it doesn't make any friends but potentially quite a lot of enemies. Even though it's actually very unlikely that a new mdadm version causes data loss (mdadm is only the remote control into the kernel), people seem to exhibit unexpected reactions when their 500Gb RAID5 array containing everything doesn't want to start anymore (Hi Lars!). In such a case, don't panic, don't do anything without understanding the implications, and consider asking for help. That said, I would appreciate if you guys helped me test the latest mdadm releases a bit more thoroughly before the package is frozen for good. I do extensive tests myself, but as Murphy would be able to predict, the problem only ever occur on other people's machines, and I'd much rather fix them before etch than after. The easiest way to help is by adding my package repository (i386/amd64) to your sources.list file, and configuring the APT pins appropriately:
# cat <<_eof >> /etc/apt/sources.list
deb http://debian.madduck.net/repo sid main
_eof
# cat <<_eof >> /etc/apt/preferences
Package: *
Pin: release a=sid, release o=madduck
Pin-Priority: 50
Package: mdadm
Pin: release a=sid, release o=madduck
Pin-Priority: 600
_eof
# apt-get update; apt-get upgrade
Alternatively, you can just download the package for i386 or amd64. If you're running sarge and are willing to test, that would be great! I've prepared backports, which you can use like so (note how you need backported debconf and lsb-base packages too, the latter of which is already on backports.org):
# cat <<_eof >> /etc/apt/sources.list
deb http://debian.madduck.net/repo sarge-backports main
## unless you have backports already enabled:
deb http://www.backports.org/debian sarge-backports main
_eof
# cat <<_eof >> /etc/apt/preferences
Package: *
Pin: release a=sarge-backports, release o=madduck
Pin-Priority: 50
Package: mdadm
Pin: release a=sarge-backports, release o=madduck
Pin-Priority: 600
Package: debconf
Pin: release a=sarge-backports, release o=madduck
Pin-Priority: 600
Package: lsb-base
Pin: release a=sarge-backports
Pin-Priority: 600
_eof
# apt-get update; apt-get upgrade
The mdadm backport can also be directly downloaded for i386 or amd64, the corresponding debconf package is here, and lsb-base is resides in the backports.org archive. Much appreciated! NP: Barclay James Harvest / Gone to Earth

22 October 2006

James Morrison: March/Protest

So a march/protest went by my window today. They were chanting "No Peace, No Justice", similar to OPSEU's old "No Justice, No Peace". The march was against police brutality. However, the march had a large police escort.

21 October 2006

Benjamin Mako Hill: PLoStitution

I went to two talks yesterday about PLoS ONE, an exciting new project by the Public Library of Science. I'm thrilled to see PLoS moving in this direction. During his talk, Chris Surridge mentioned that the the publishing platform/CMS that PLoS ONE is using is based on Fedora. I mentioned that Fedora, last I checked, wasn't exactly a CMS, a fact that he acknowledged but responded to by saying that I would need to talk to their tech team for details. Today I found out that neither ideological affinity nor geographic proximity to Red Hat kept the University of Virginia from choosing the wrong name for their Institutional Repository (IR) software. But at least yesterday's confusion is put to rest. Also, Surridge had a slide with this quote and challenged the audience to come up with the utterer:
The most valuable commodity I know of is information.
I did a quick "I'm feeling lucky" search and was thrilled to see that I came up with this page informing me that I, "do not have rights to view the article" containing the answer but that the information could be mine for a cool GBP 13.00 (plus a handling charge of GBP 1.50 and VAT where applicable). The phrase, it turns out, belongs to Gordon Gekko, a corporate raider character in the 1987 film Wall Street. Finally, and least importantly, I object to this image:
/copyrighteous/images/openaccess20.gif

20 October 2006

Biella Coleman: The Law in Shambles

Many moons ago, when I started my project on F/OSS I imagined that it would stay within the purview of anthropology, hacking, science and technology studies to bleed only a little bit into legal studies and only because I was dealing with the fraught politics of intellectual property law. As it turned out, the Law, with a capital L, as on object of analysis and site for the production of cultural value, turned out not to be peripheral but utterly central… And since, I have pretty much stayed within the territory of legal studies, vastly interested in the more invisible cultural and political effects of the law. Recent obsessing on this topic has led to a nascent thesis about law, discrimination, politics , and civil rights that I am looking to substantiate (so if anyone has any citations or helpful hints, do pass along) and it is this: When there are positive changes made in the law, it can come with various political costs. And the one I am interested in, is how, given other conducive conditions, legal changes that look awesome on paper, can work to undermine its potential by breeding a type of complacency of (in)action, largely because it seems as if the worst of the problems have been fixed. So if we look to the American legal context of 1960s and 1970s as a prime example, it is clear there was a heck of a lot of turmoil in the arena of civil rights, much of which, many liberals and progressives would say, led to positive legal transformation. During this period the content of many laws were purged of overt discrimination that, for example, which led a lethal blow to segregation and started to dismantle some of the worst pieces of scaffolding of mental health law (just to cite a few examples). At one level while we may easily recognize these changes as laudable and even perhaps “progressive,” the effects of it may be less so. Once legal content is purged of the ugly, this can breed an ugly form of complacency, in which the problem seems (re)solved, so people no longer feel guilt and attention is diverted away from any number of things, like: 1) new problems not necessarily addressed in the law 2) the rise of new laws or 3) the fact that the law is empty unless actively applied. I have yet to read anything directly related to this theory or apply it myself but it is something that has been on my mind for a couple of years now. But after talking about this topic from a friend, I decided to finally take crack at The Law in Shambles a Prickly Paradigm Press pamphlet by Thomas Geogheghan, a labor lawyer from Chicago. While it did not specifically address the issue I am raising (though it got pretty close in a number of places) I got more than I had bargained for; it is truly incisive (though frighteningly depressing) look at the current state of the law, and also, like so many of the PPP’s, much more fun to read than any most academic book or articles. For those who don’t know the PPP publish a series of short pamphlets and it was started by the legendary anthropologist, Marshal Sahlins, who is also known to be a little prickly himself (but it softened by his humor). They are often written by academics on contemporary topics of political interest (read: very biased) in a manner that is a lot looser and free wheeling than any article or book that would come out of an academic journal or publishing house. The PPP allows its authors to unbuckle a few notches off the sometimes uptight, constraining academic belt of writing and the result is often impassioned, funny, and yet remarkably astute essays. If Montaigne were around today, he would surely be proud of his essayistic legacy. The title of the book sums up the the topic at hand. His explanation as to why the (American) law is in disarray has not to do with the law in the abstract but with the total disintegration of a certain class of institutions and a specific class of law (namely unions , the law of trusts etc.). As institutional supports from the New Deal have been thrown out the door, it is the individual, largely through tort law, who has had to wield the fury of the law, in defense of a slew of individual rights and to defend themselves against new forms of attack (the worst being lawsuits brought forth by “charitable institutions” like hospitals). While the law is conceived as something we are all equal under, of course, it is access to the law, which makes all the difference in terms of making it a viable (or not) as social tool. With the demise of the unions, he argues, came the death of certain type of contract law in employment, and the stellar rise of tort law, which conceives of wrongful acts not as breaches of contract (which would apply to all persons under the contract) but as matters of personal injury. Whereas in the past unions would arbitrate contract law, wielding the power of numbers so that individuals were not burdened and burned with the expense (of time and money) of the law, with tort the law becomes formalized, conceived, and imagined in highly individual terms (even when grouped into class actions, it becomes a matter of proving personal injury), the effect of which, he argues is meaner and more complex than contract for four reasons 1) The name of the legal game is to discover motive, which is about as confusing as it can get and thus more arbitrary 2) It is more expensive than old contract law 3) Cases rarely go to trial (didn’t really get the importance of this point) 4) Because its focus is on motive and intense and subjective states, everything is open to scrutiny, so that I can force you to tell me everything what is in your secret heart. Not to mention in your tax returns. The result is torts produced a bitter, dog-eats-dog Hobbesian, legal world, which in turn makes for experiencing the law as an arbitrary force. This individualization of the law through tort also intersects with many other changes such as the demise of regulatory power that add more fire to the disintegration of the law and the subsequent experience of law and life as arbitrary. And it is this chapter (From Administrative Law to No Law, The Rise of the Whistleblower and Trail Lawyer) which got me a little closer to my own point that I brought up above. For example, he writes:
Once, when I filed suite to get the Labor Department to enforce the child labor laws for 16- and 17-year olds, kids whom they do not even pretend to protect, I got nowhere. I met with the Solicitor who told me: Look, suppose I agree with you. How would I ever get the money to enforce it? He was right. If I had won and they had issued regulations, it would have only been worse. In Labor, as in agency after agency, we have a vast complex body of law which would take mandarin to learn that no one enforces.. The law is there. On paper. Indeed, it is a lot of paper. How much paper? Fifty volumes, in paperback in total. I know because I counted. But as to big chunks in these volumes, there is no one there to enforce it. p. 48
Lots of paper I think can make people comfortable in thinking that famous Virginia Slims Slogan, We’ve come a long way, Baby, when it fact, it can often just means what it literally looks like, “Damn, that’s a buttload of paper.” There is a lot more packed into this tiny book, covering the deep gulf between left and right, the stagnation of an old constitution that is impossible to revise, the loss of accountability in all branches of government, the redrawing of districts, and the slight expansion and curbing of of majoritarian voting in the last hundred years. It gets a little shrilly by the end, but you know, it is all pretty upsetting stuff and it is good to shrill from time to time. Though he never refers to neoliberalism, capitalism, or postmodernism, this book is also a great companion to a class of this literature on the rise of fragmentation and instability in social and cultural life brought forth by changes in the economic system (thinking here of David Harvey, Fredric Jameson, etc). In fact, I think it does a much better job than at relaying how it is that vast sectors of society experience fragmentation, instability, and frustration.

Next.

Previous.