Search Results: "cas"

12 June 2022

Russ Allbery: Review: The Shattered Sphere

Review: The Shattered Sphere, by Roger MacBride Allen
Series: Hunted Earth #2
Publisher: Tor
Copyright: July 1994
Printing: September 1995
ISBN: 0-8125-3016-0
Format: Mass market
Pages: 491
The Shattered Sphere is a direct sequel to The Ring of Charon and spoils everything about the plot of the first book. You don't want to start here. Also be aware that essentially everything you can read about this book will spoil the major plot driver of The Ring of Charon in the first sentence. I'm going to review the book without doing that, but it's unlikely anyone else will try. The end of the previous book stabilized matters, but in no way resolved the plot. The Shattered Sphere opens five years later. Most of the characters from the first novel are joined by some new additions, and all of them are trying to make sense of a drastically changed and far more dangerous understanding of the universe. Humanity has a new enemy, one that's largely unaware of humanity's existence and able to operate on a scale that dwarfs human endeavors. The good news is that humans aren't being actively attacked. The bad news is that they may be little more than raw resources, stashed in a safe spot for future use. That is reason enough to worry. Worse are the hints of a far greater danger, one that may be capable of destruction on a scale nearly beyond human comprehension. Humanity may be trapped between a sophisticated enemy to whom human activity is barely more noticeable than ants, and a mysterious power that sends that enemy into an anxious panic. This series is an easily-recognized example of an in-between style of science fiction. It shares the conceptual bones of an earlier era of short engineer-with-a-wrench stories that are full of set pieces and giant constructs, but Allen attempts to add the characterization that those books lacked. But the technique isn't there; he's trying, and the basics of characterization are present, but with none of the emotional and descriptive sophistication of more recent SF. The result isn't bad, exactly, but it's bloated and belabored. Most of the characterization comes through repetition and ham-handed attempts at inner dialogue. Slow plotting doesn't help. Allen spends half of a nearly 500 page novel on setup in two primary threads. One is mostly people explaining detailed scientific theories to each other, mixed with an attempt at creating reader empathy that's more forceful than effective. The other is a sort of big dumb object exploration that failed to hold my attention and that turned out to be mostly irrelevant. Key revelations from that thread are revealed less by the actions of the characters than by dumping them on the reader in an extended monologue. The reading goes quickly, but only because the writing is predictable and light on interesting information, not because the plot is pulling the reader through the book. I found myself wishing for an earlier era that would have cut about 300 pages out of this book without losing any of the major events. Once things finally start happening, the book improves considerably. I grew up reading large-scale scientific puzzle stories, and I still have a soft spot for a last-minute scientific fix and dramatic set piece even if the descriptive detail leaves something to be desired. The last fifty pages are fast-moving and satisfying, only marred by their failure to convince me that the humans were required for the plot. The process of understanding alien technology well enough to use it the right way kept me entertained, but I don't understand why the aliens didn't use it themselves. I think this book falls between two stools. The scientific mysteries and set pieces would have filled a tight, fast-moving 200 page book with a minimum of characterization. It would have been a throwback to an earlier era of science fiction, but not a bad one. Allen instead wanted to provide a large cast of sympathetic and complex characters, and while I appreciate the continued lack of villains, the writing quality is not sufficient to the task. This isn't an awful book, but the quality bar in the genre is so much higher now. There are better investments of your reading time available today. Like The Ring of Charon, The Shattered Sphere reaches a satisfying conclusion but does not resolve the series plot. No sequel has been published, and at this point one seems unlikely to materialize. Rating: 5 out of 10

10 June 2022

Sam Hartman: Flailing to Replace Jack with Pipewire for DJ Audio

I could definitely use some suggestions here, both in terms of things to try or effective places to ask questions about Pipewire audio. The docs are improving, but are still in early stages. Pipewire promises to combine the functionality of PulseAudio and Jack. That would be great for me. I use Jack for my DJ work, and it s somewhat complicated and fragile. However, so far my attempts to replace Jack have been unsuccessful, and I might need to even use PulseAudio instead of Pipewire to get the DJ stuff working correctly. The Setup In the simplest setup I have a DJ controller. It s both a MIDI device and a sound card. It has 4 channel audio, but it s not typical surround sound. Two channels are the main speakers, and two channels are the headphones. Conceptually it might be better to model the controller as two sinks: one for the speakers and one for the headphones. At a hardware level they need to be one device for several reasons, especially including using a common clock. It s really important than only the main mix go out channel 1-2 (the speakers). Random beeps or sound from other applications going out the main speakers is disruptive and unprofessional. However, because I m blind, I need that sound. I especially need the output of Orca (my screen reader) and Emacspeak (another screen reader). So I need that output to go to the headphones. Under Pulse/Jack The DJ card is the Jack primary sound device (system:playback_1 through system:playback_4). I then use themodule-jack-sink Pulse module to connect Pulse to Jack. That becomes the default sink for Pulse, and I link front-left from that sink to system:playback_3. So, I get the system sounds and screen reader mixed into the left channel of my headphones and nowhere else. Enter Pipewire Initially Pipewire sees the DJ card as a 4-channel sound card and assumes it s surround4.0 (so front and rear left and right). It helpfully expands my stereo signal so that everything goes to the front and rear. So, exactly what I don t want to have happen happens: all my system sounds go out the main speakers (channel 1-2). It was easy to override Wireplumber s ALSA configuration and assign different channel positions. I tried assigning something like a1,a2,fl,fr hoping that Pipewire wouldn t mix things into aux channels that weren t part of the typical surround set. No luck. It did correctly reflect the channels in things like pacmd list sinks so my Pipewire config was being applied. But the sound was still wrong. * I tried turning off channelmix.upmix. That didn t help; that appears to be more about mixing stereo into center, rear and LFE. The basic approach of getting a stream to conform to the output node s channels appears to be hurting me here. I d love any ideas about how I can get this to work. I m sure it s simple I m just missing the right mental model or knowledge of how to configure things. Pipewire Not Talking to Jack I thought I could at least use Pipewire the same way I use Pulse. Namely, I can run a real jackd and connect up Pipewire to that server. According to the wiki, Pipewire can be a Jack client. It s disabled by default, because you need to make sure that Wireplumber is using the real Jack libraries rather than the Pipewire replacements. That s the case on Debian, so I enabled the feature. A Jack device appeared in wpctl status as did a Jack sink. Using jack_lsp on that device showed it was talking to the Jack server and connected to system:playback_*. Unfortunately, it doesn t work. The sink does not show up in pacmd list sinks, and pipewire-pulse gives an error about it not being ready. If I select it as the default sink in wpctl set-default I get no sound at all, at least from Pulse applications. Versions of things This is all on debian, approximately testing/bookworm or newer for the relevant libraries.

comment count unavailable comments

8 June 2022

Laura Arjona Reina: Moving to a faster but smaller disk, encrypted setup

My work computer runs Debian 11 bullseye (the current stable release) in a mechanical 500GB disk, and I was provided with a new SDD disk but its size was 480 GB. So I had to shrink my partitions before copying the data to the new disk. It turned out to be a bit difficult because my main partition was encrypted. I write here how I did, maybe there are other simpler ways but I couldn t find them. References: I had three partitions in my old 500GB disk: /dev/sda1 is the EFI partition, /dev/sda2 the boot partition and /dev/sda3 the root partition (encrypted, with LVM, the standard way the Debian installer proposes when you choose a simple encrypted setup). First of all, I made a disk image with Clonezilla to an external USB disk, just in case I mess up things, to be able to return to a safe point and start again. Then I started my computer with a Debian 11 live USB with KDE Plasma desktop and Spanish localisation environment. I opened the KDE Partition manager and copied the non encrypted partitions (sda1, EFI and sda2, /boot) to the new disk. I shrinked the encrypted partition from the terminal with the following commands (I had enough free space so reduced my partition to a total of 300GB): Removed the swap partition and re-created it:
sudo lvremove /dev/larjona-pc-vg/swap_1
sudo pvresize --setphysicalvolumesize 380G /dev/mapper/cryptdisk
sudo pvchange -x y /dev/mapper/cryptdisk
sudo lvcreate -L 4G -n swap_1 larjona-pc-vg
sudo mkswap -L swap_1 /dev/larjona-pc-vg/swap_1
Display information about the physical volume in order to shrink it:
sudo pvs -v --segments --units s /dev/mapper/cryptdisk
sudo cryptsetup -b 838860800 resize cryptdisk
sudo cryptsetup status cryptdisk
sudo vgchange -a n vgroup
sudo vgchange -an
sudo cryptsetup luksClose cryptdisk
Then reduced the sda3 partition with the KDE partition manager (it took a while), and copy it to the new disk. Turned off the computer and unplugged the old disk. Started the computer with the Debian 11 Live USB again, UEFI boot. Now, to make my system boot:
sudo cryptsetup luksOpen /dev/sda3 crypdisk
sudo vgscan --mknodes
sudo vgchange -ay
sudo mount /dev/mapper/larjona--pc--vg-root /mnt
sudo mount /dev/sda2 /mnt/boot
sudo mount /dev/sda1 /mnt/boot/efi
mount --rbind /sys /media/linux/sys
mount -t efivarfs none /sys/firmware/efi/efivars
for i in /dev /dev/pts /proc /run; do sudo mount -B $i /mnt$i; done
sudo chroot /mnt
Then edited /mnt/etc/crypttab to reflect the name of the new encrypted partition, edited /mnt/etc/fstab to paste the UUIDs of the new partitions.
Then ran grub-install and reinstalled the kernels as noted in the reference, rebooted and logged in my Plasma desktop  (Well, the actual process was not so smooth but after several tries and errors and searching for help I managed to get the needed commands to make my system boot from the new disk).

6 June 2022

Reproducible Builds: Reproducible Builds in May 2022

Welcome to the May 2022 report from the Reproducible Builds project. In our reports we outline the most important things that we have been up to over the past month. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website.

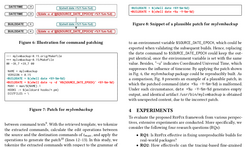
Repfix paper Zhilei Ren, Shiwei Sun, Jifeng Xuan, Xiaochen Li, Zhide Zhou and He Jiang have published an academic paper titled Automated Patching for Unreproducible Builds:
[..] fixing unreproducible build issues poses a set of challenges [..], among which we consider the localization granularity and the historical knowledge utilization as the most significant ones. To tackle these challenges, we propose a novel approach [called] RepFix that combines tracing-based fine-grained localization with history-based patch generation mechanisms.
The paper (PDF, 3.5MB) uses the Debian mylvmbackup package as an example to show how RepFix can automatically generate patches to make software build reproducibly. As it happens, Reiner Herrmann submitted a patch for the mylvmbackup package which has remained unapplied by the Debian package maintainer for over seven years, thus this paper inadvertently underscores that achieving reproducible builds will require both technical and social solutions.

Python variables Johannes Schauer discovered a fascinating bug where simply naming your Python variable _m led to unreproducible .pyc files. In particular, the types module in Python 3.10 requires the following patch to make it reproducible:
--- a/Lib/types.py
+++ b/Lib/types.py
@@ -37,8 +37,8 @@ _ag = _ag()
 AsyncGeneratorType = type(_ag)
 
 class _C:
-    def _m(self): pass
-MethodType = type(_C()._m)
+    def _b(self): pass
+MethodType = type(_C()._b)
Simply renaming the dummy method from _m to _b was enough to workaround the problem. Johannes bug report first led to a number of improvements in diffoscope to aid in dissecting .pyc files, but upstream identified this as caused by an issue surrounding interned strings and is being tracked in CPython bug #78274.

New SPDX team to incorporate build metadata in Software Bill of Materials SPDX, the open standard for Software Bill of Materials (SBOM), is continuously developed by a number of teams and committees. However, SPDX has welcomed a new addition; a team dedicated to enhancing metadata about software builds, complementing reproducible builds in creating a more secure software supply chain. The SPDX Builds Team has been working throughout May to define the universal primitives shared by all build systems, including the who, what, where and how of builds:
  • Who: the identity of the person or organisation that controls the build infrastructure.
  • What: the inputs and outputs of a given build, combining metadata about the build s configuration with an SBOM describing source code and dependencies.
  • Where: the software packages making up the build system, from build orchestration tools such as Woodpecker CI and Tekton to language-specific tools.
  • How: the invocation of a build, linking metadata of a build to the identity of the person or automation tool that initiated it.
The SPDX Builds Team expects to have a usable data model by September, ready for inclusion in the SPDX 3.0 standard. The team welcomes new contributors, inviting those interested in joining to introduce themselves on the SPDX-Tech mailing list.

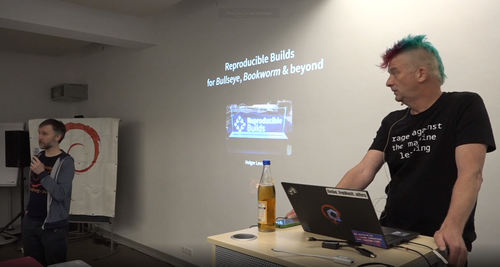
Talks at Debian Reunion Hamburg Some of the Reproducible Builds team (Holger Levsen, Mattia Rizzolo, Roland Clobus, Philip Rinn, etc.) met in real life at the Debian Reunion Hamburg (official homepage). There were several informal discussions amongst them, as well as two talks related to reproducible builds. First, Holger Levsen gave a talk on the status of Reproducible Builds for bullseye and bookworm and beyond (WebM, 210MB): Secondly, Roland Clobus gave a talk called Reproducible builds as applied to non-compiler output (WebM, 115MB):

Supply-chain security attacks This was another bumper month for supply-chain attacks in package repositories. Early in the month, Lance R. Vick noticed that the maintainer of the NPM foreach package let their personal email domain expire, so they bought it and now controls foreach on NPM and the 36,826 projects that depend on it . Shortly afterwards, Drew DeVault published a related blog post titled When will we learn? that offers a brief timeline of major incidents in this area and, not uncontroversially, suggests that the correct way to ship packages is with your distribution s package manager .

Bootstrapping Bootstrapping is a process for building software tools progressively from a primitive compiler tool and source language up to a full Linux development environment with GCC, etc. This is important given the amount of trust we put in existing compiler binaries. This month, a bootstrappable mini-kernel was announced. Called boot2now, it comprises a series of compilers in the form of bootable machine images.

Google s new Assured Open Source Software service Google Cloud (the division responsible for the Google Compute Engine) announced a new Assured Open Source Software service. Noting the considerable 650% year-over-year increase in cyberattacks aimed at open source suppliers, the new service claims to enable enterprise and public sector users of open source software to easily incorporate the same OSS packages that Google uses into their own developer workflows . The announcement goes on to enumerate that packages curated by the new service would be:
  • Regularly scanned, analyzed, and fuzz-tested for vulnerabilities.
  • Have corresponding enriched metadata incorporating Container/Artifact Analysis data.
  • Are built with Cloud Build including evidence of verifiable SLSA-compliance
  • Are verifiably signed by Google.
  • Are distributed from an Artifact Registry secured and protected by Google.
(Full announcement)

A retrospective on the Rust programming language Andrew bunnie Huang published a long blog post this month promising a critical retrospective on the Rust programming language. Amongst many acute observations about the evolution of the language s syntax (etc.), the post beings to critique the languages approach to supply chain security ( Rust Has A Limited View of Supply Chain Security ) and reproducibility ( You Can t Reproduce Someone Else s Rust Build ):
There s some bugs open with the Rust maintainers to address reproducible builds, but with the number of issues they have to deal with in the language, I am not optimistic that this problem will be resolved anytime soon. Assuming the only driver of the unreproducibility is the inclusion of OS paths in the binary, one fix to this would be to re-configure our build system to run in some sort of a chroot environment or a virtual machine that fixes the paths in a way that almost anyone else could reproduce. I say almost anyone else because this fix would be OS-dependent, so we d be able to get reproducible builds under, for example, Linux, but it would not help Windows users where chroot environments are not a thing.
(Full post)

Reproducible Builds IRC meeting The minutes and logs from our May 2022 IRC meeting have been published. In case you missed this one, our next IRC meeting will take place on Tuesday 28th June at 15:00 UTC on #reproducible-builds on the OFTC network.

A new tool to improve supply-chain security in Arch Linux kpcyrd published yet another interesting tool related to reproducibility. Writing about the tool in a recent blog post, kpcyrd mentions that although many PKGBUILDs provide authentication in the context of signed Git tags (i.e. the ability to verify the Git tag was signed by one of the two trusted keys ), they do not support pinning, ie. that upstream could create a new signed Git tag with an identical name, and arbitrarily change the source code without the [maintainer] noticing . Conversely, other PKGBUILDs support pinning but not authentication. The new tool, auth-tarball-from-git, fixes both problems, as nearly outlined in kpcyrd s original blog post.

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb prepared and uploaded versions 212, 213 and 214 to Debian unstable. Chris also made the following changes:
  • New features:
    • Add support for extracting vmlinuz Linux kernel images. [ ]
    • Support both python-argcomplete 1.x and 2.x. [ ]
    • Strip sticky etc. from x.deb: sticky Debian binary package [ ]. [ ]
    • Integrate test coverage with GitLab s concept of artifacts. [ ][ ][ ]
  • Bug fixes:
    • Don t mask differences in .zip or .jar central directory extra fields. [ ]
    • Don t show a binary comparison of .zip or .jar files if we have observed at least one nested difference. [ ]
  • Codebase improvements:
    • Substantially update comment for our calls to zipinfo and zipinfo -v. [ ]
    • Use assert_diff in test_zip over calling get_data with a separate assert. [ ]
    • Don t call re.compile and then call .sub on the result; just call re.sub directly. [ ]
    • Clarify the comment around the difference between --usage and --help. [ ]
  • Testsuite improvements:
    • Test --help and --usage. [ ]
    • Test that --help includes the file formats. [ ]
Vagrant Cascadian added an external tool reference xb-tool for GNU Guix [ ] as well as updated the diffoscope package in GNU Guix itself [ ][ ][ ].

Distribution work In Debian, 41 reviews of Debian packages were added, 85 were updated and 13 were removed this month adding to our knowledge about identified issues. A number of issue types have been updated, including adding a new nondeterministic_ordering_in_deprecated_items_collected_by_doxygen toolchain issue [ ] as well as ones for mono_mastersummary_xml_files_inherit_filesystem_ordering [ ], extended_attributes_in_jar_file_created_without_manifest [ ] and apxs_captures_build_path [ ]. Vagrant Cascadian performed a rough check of the reproducibility of core package sets in GNU Guix, and in openSUSE, Bernhard M. Wiedemann posted his usual monthly reproducible builds status report.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Reproducible builds website Chris Lamb updated the main Reproducible Builds website and documentation in a number of small ways, but also prepared and published an interview with Jan Nieuwenhuizen about Bootstrappable Builds, GNU Mes and GNU Guix. [ ][ ][ ][ ] In addition, Tim Jones added a link to the Talos Linux project [ ] and billchenchina fixed a dead link [ ].

Testing framework The Reproducible Builds project runs a significant testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
  • Holger Levsen:
    • Add support for detecting running kernels that require attention. [ ]
    • Temporarily configure a host to support performing Debian builds for packages that lack .buildinfo files. [ ]
    • Update generated webpages to clarify wishes for feedback. [ ]
    • Update copyright years on various scripts. [ ]
  • Mattia Rizzolo:
    • Provide a facility so that Debian Live image generation can copy a file remotely. [ ][ ][ ][ ]
  • Roland Clobus:
    • Add initial support for testing generated images with OpenQA. [ ]
And finally, as usual, node maintenance was also performed by Holger Levsen [ ][ ].

Misc news On our mailing list this month:

Contact If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

1 June 2022

Daniel Lange: Get Youtube Channel ID from username

Youtube has a really nice RSS feature that is extremely well hidden. If you postfix a Channel ID to
https://www.youtube.com/feeds/videos.xml?channel_id=<id goes here>
you get a really nice Atom 1.0 (~RSS) feed for your feedreader. Unfortunately the Channel ID is hard to find while you are navigating Youtube with usernames in the URL. E.g. https://www.youtube.com/c/TED is TED's channel, full of interesting and worth-to-watch content (and some assorted horse toppings, of course). But you have to read a lot of ugly HTML / JSON in that page to find and combine https://www.youtube.com/feeds/videos.xml?channel_id=UCAuUUnT6oDeKwE6v1NGQxug which is the related RSS feed. Jeff Keeling wrote a simple Youtube RSS Extractor that does well if you have a ../playlist?... or a .../channel/... URL but it will (currently) fail on user name channels or Youtube landing pages. So how do we get the Channel ID for a Youtube user we are interested to follow? Youtube has a great API but that is gated by API keys even for the most simple calls (that came only with v3 of the API but the previous version is depreciated since 2015)1:
dl@laptop:~$ curl 'https://www.googleapis.com/youtube/v3/channels?part=contentDetails&forUsername=DebConfVideos'

"error":
"code": 403,
"message": "The request is missing a valid API key.",
"errors": [

"message": "The request is missing a valid API key.",
"domain": "global",
"reason": "forbidden"

],
"status": "PERMISSION_DENIED"

Luckily we can throw the same (example) user name DebConfVideos at curl and grep:
dl@laptop:~$ curl -s "https://www.youtube.com/c/DebConfVideos/videos" grep -Po '"channelId":".+?"'
"channelId":"UC7SbfAPZf8SMvAxp8t51qtQ"
So https://www.youtube.com/feeds/videos.xml?channel_id=UC7SbfAPZf8SMvAxp8t51qtQ is the RSS feed for DebConfVideos. We can use individual Youtube video URLs as well. With the hack above, it'll work to find us the Chanel ID from a Youtube video URL: Working around the Youtube API restrictions to still make use of their RSS feed Now, some user pages may have multiple valid RSS feeds because they contain multiple channels. Remember the TED page from above? Well run:
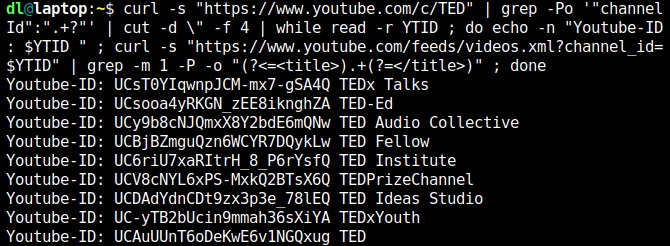
dl@laptop:~$ curl -s "https://www.youtube.com/c/TED" grep -Po '"channelId":".+?"' cut -d \" -f 4 while read -r YTID ; do echo -n "Youtube-ID: $YTID " ; curl -s "https://www.youtube.com/feeds/videos.xml?channel_id=$YTID" grep -m 1 -P -o "(?<=<title>).+(?=</title>)" ; done
This will iterate through the Channel IDs found and show you the titles. That way you can assess which one you want to add to your feedreader. screenshot of the above You probably want the last Channel ID listed above, the non-selective "TED" one. And that's the one from the example above. Update 02.06.2022: smpl wrote in and has the much better solution for the most frequent use cases:
You can also use get a feed directly with a username:
https://www.youtube.com/feeds/videos.xml?user=<username>
The one I use most is the one for playlists (if creators remember to
use them).
https://www.youtube.com/feeds/videos.xml?playlist_id=<playlist id>
For the common case you don't even need the channel ID that way. But it is also conveniently given in a <yt:channelId> tag (or the topmost <id> tag) within the Atom XML document. Thanks, smpl!

  1. Actually it is even more complicated as some channels, like our DebConfVideos example, will only get you an incomplete result, cf. this StackOverflow entry. I.e. the forUsername iterator may not even work and the "best practice" seems to be mucking around with the search call.

Russ Allbery: Review: The Seeress of Kell

Review: The Seeress of Kell, by David Eddings
Series: The Malloreon #5
Publisher: Del Rey
Copyright: May 1991
Printing: May 1992
ISBN: 0-345-37759-1
Format: Mass market
Pages: 374
The Seeress of Kell is the conclusion of the five-book Malloreon series and a direct sequel to Sorceress of Darshiva. You do not want to begin the series here (or, to be honest, at all). We have finally finished the relaxed tour of Mallorea, the second continent of Eddings's remarkably small two-continent world. The heroes have gathered all of their required companions and are headed for Kell, where the seeress Cyradis awaits. From there, they and the new Child of Dark must find their way to the Place Which Is No More for the final confrontation. By "find," I mean please remain seated with your hands, arms, feet, and legs inside the vehicle. The protagonists have about as much to do with the conclusion of this series as the passengers of a roller coaster have control over its steering. I am laughing at my younger self, who quite enjoyed this series (although as I recall found it a bit repetitive) and compared it favorably to the earlier Belgariad series. My memory kept telling me that the conclusion of the series was lots of fun. Reader, it was not. It was hilariously bad. Both of Eddings's first two series, but particularly this one, take place in a fantasy world full of true prophecy. The conceit of the Malloreon in particular (this is a minor spoiler for the early books, but not one that I think interferes with enjoyment) is that there are two competing prophecies that agree on most events but are in conflict over a critical outcome. True prophecy creates an agency problem: why have protagonists if everything they do is fixed in prophecy? The normal way to avoid that is to make the prophecy sufficiently confusing and the mechanism by which it comes true sufficiently subtle that everyone has to act as if there is no prophecy, thus reducing the role of the prophecy to foreshadowing and a game the author plays with the reader. What makes the Malloreon interesting (and I mean this sincerely) is that Eddings instead leans into the idea of a prophecy as an active agent leading the protagonists around by the nose. As a meta-story commentary on fantasy stories, this can be quite entertaining, and it helps that the prophecy appears as a likable character of sorts in the book. The trap that Eddings had mostly avoided before now is that this structure can make the choices of the protagonists entirely pointless. In The Seeress of Kell, he dives head-first into the trap and then pulls it shut behind him. The worst part is Ce'Nedra, who once again spends an entire book either carping at Garion in ways that are supposed to be endearing (but aren't) or being actively useless. The low point is when she is manipulated into betraying the heroes, costing them a significant advantage. We're then told that, rather than being a horrific disaster, this is her important and vital role in the story, and indeed the whole reason why she was in the story at all. The heroes were too far ahead of the villains and were in danger of causing the prophecy to fail. At that point, one might reasonably ask why one is bothering reading a novel instead of a summary of the invented history that Eddings is going to tell whether his characters cooperate or not. The whole middle section of the book is like this: nothing any of the characters do matters because everything is explicitly destined. That includes an extended series of interludes following the other main characters from the Belgariad, who are racing to catch up with the main party but who will turn out to have no role of significance whatsoever. I wouldn't mind this as much if the prophecy were more active in the story, given that it's the actual protagonist. But it mostly disappears. Instead, the characters blunder around doing whatever seems like a good idea at the time, while Cyradis acts like a bizarre sort of referee with a Calvinball rule set and every random action turns out to be the fulfillment of prophecy in the most ham-handed possible way. Zandramas, meanwhile, is trying to break the prophecy, which would have been a moderately interesting story hook if anyone (Eddings included) thought she were potentially capable of doing so. Since no one truly believes there's any peril, this turns into a series of pointless battles the reader has no reason to care about. All of this sets up what has been advertised since the start of the series as a decision between good and evil. Now, at the least minute, Eddings (through various character mouthpieces) tries to claim that the decision is not actually between good and evil, but is somehow beyond morality. No one believes this, including the narrator and the reader, making all of the philosophizing a tedious exercise in page-turning. To pull off a contention like that, the author has to lay some sort of foundation to allow the reader to see the supposed villain in multiple lights. Eddings does none of that, instead emphasizing how evil she is at every opportunity. On top of that, this supposed free choice on which the entire universe rests and for which all of history was pointed depends on someone with astonishing conflicts of interest. While the book is going on about how carefully the prophecy is ensuring that everyone is in the right place at the right time so that no side has an advantage, one side is accruing an absurdly powerful advantage. And the characters don't even seem to realize it! The less said about the climax, the better. Unsurprisingly, it was completely predictable. Also, while I am complaining, I could never get past how this entire series starts off with and revolves around an incredibly traumatic and ongoing event that has no impact whatsoever on the person to whom the trauma happens. Other people are intermittently upset or sad, but not only is that person not harmed, they act, at the end of this book, as if the entire series had never happened. There is one bright spot in this book, and ironically it's the one plot element that Eddings didn't make blatantly obvious in advance and therefore I don't want to spoil it. All I'll say is that one of the companions the heroes pick up along the way turns out to be my favorite character of the series, plays a significant role in the interpersonal dynamics between the heroes, and steals every scene that she's in by being more sensible than any of the other characters in the story. Her story, and backstory, is emotional and moving and is the best part of this book. Otherwise, not only is the plot a mess and the story structure a failure, but this is also Eddings at his most sexist and socially conservative. There is an extended epilogue after the plot resolution that serves primarily as a showcase of stereotypes: baffled men having their habits and preferences rewritten by their wives, cast-iron gender roles inside marriage, cringeworthy jokes, and of course loads and loads of children because that obviously should be everyone's happily ever after. All of this happens to the characters rather than being planned or actively desired, continuing the theme of prophecy and lack of agency, although of course they're all happy about it (shown mostly via grumbling). One could write an entire academic paper on the tension between this series and the concept of consent. There were bits of the Malloreon that I enjoyed, but they were generally in spite of the plot rather than because of it. I do like several of Eddings's characters, and in places I liked the lack of urgency and the sense of safety. But I think endings still have to deliver some twist or punch or, at the very least, some clear need for the protagonists to take an action other than stand in the right room at the right time. Eddings probably tried to supply that (I can make a few guesses about where), but it failed miserably for me, making this the worst book of the series. Unless like me you're revisiting this out of curiosity for your teenage reading habits (and even then, consider not), avoid. Rating: 3 out of 10

31 May 2022

Russ Allbery: Review: Maskerade

Review: Maskerade, by Terry Pratchett
Series: Discworld #18
Publisher: Harper
Copyright: 1995
Printing: February 2014
ISBN: 0-06-227552-6
Format: Mass market
Pages: 360
Maskerade is the 18th book of the Discworld series, but you probably could start here. You'd miss the introduction of Granny Weatherwax and Nanny Ogg, which might be a bit confusing, but I suspect you could pick it up as you went if you wanted. This is a sequel of sorts to Lords and Ladies, but not in a very immediate sense. Granny is getting distracted and less interested in day-to-day witching in Lancre. This is not good; Granny is incredibly powerful, and bored and distracted witches can go to dark places. Nanny is concerned. Granny needs something to do, and their coven needs a third. It's not been the same since they lost their maiden member. Nanny's solution to this problem is two-pronged. First, they'd had their eye on a local girl named Agnes, who had magic but who wasn't interested in being a witch. Perhaps it was time to recruit her anyway, even though she'd left Lancre for Ankh-Morpork. And second, Granny needs something to light a fire under her, something that will get her outraged and ready to engage with the world. Something like a cookbook of aphrodisiac recipes attributed to the Witch of Lancre. Agnes, meanwhile, is auditioning for the opera. She's a sensible person, cursed her whole life by having a wonderful personality, but a part of her deep inside wants to be called Perdita X. Dream and have a dramatic life. Having a wonderful personality can be very frustrating, but no one in Lancre took either that desire or her name seriously. Perhaps the opera is somewhere where she can find the life she's looking for, along with another opportunity to try on the Perdita name. One thing she can do is sing; that's where all of her magic went. The Ankh-Morpork opera is indeed dramatic. It's also losing an astounding amount of money for its new owner, who foolishly thought owning an opera would be a good retirement project after running a cheese business. And it's haunted by a ghost, a very tangible ghost who has started killing people. I think this is my favorite Discworld novel to date (although with a caveat about the ending that I'll get to in a moment). It's certainly the one that had me laughing out loud the most. Agnes (including her Perdita personality aspect) shot to the top of my list of favorite Discworld characters, in part because I found her sensible personality so utterly relatable. She is fascinated by drama, she wants to be in the middle of it and let her inner Perdita goth character revel in it, and yet she cannot help being practical and unflappable even when surrounded by people who use far too many exclamation points. It's one thing to want drama in the abstract; it's quite another to be heedlessly dramatic in the moment, when there's an obviously reasonable thing to do instead. Pratchett writes this wonderfully. The other half of the story follows Granny and Nanny, who are unstoppable forces of nature and a wonderful team. They have the sort of long-standing, unshakable adult friendship between very unlike people that's full of banter and minor irritations layered on top of a deep mutual understanding and respect. Once they decide to start investigating this supposed opera ghost, they divvy up the investigative work with hardly a word exchanged. Planning isn't necessary; they both know each other's strengths. We've gotten a lot of Granny's skills in previous books. Maskerade gives Nanny a chance to show off her skills, and it's a delight. She effortlessly becomes the sort of friendly grandmother who blends in so well that no one questions why she's there, and thus manages to be in the middle of every important event. Granny watches and thinks and theorizes; Nanny simply gets into the middle of everything and talks to everyone until people tell her what she wants to know. There's no real doubt that the two of them are going to get to the bottom of anything they want to get to the bottom of, but watching how they get there is a delight. I love how Pratchett handles that sort of magical power from a world-building perspective. Ankh-Morpork is the Big City, the center of political power in most of the Discworld books, and Granny and Nanny are from the boondocks. By convention, that means they should either be awed or confused by the city, or gain power in the city by transforming it in some way to match their area of power. This isn't how Pratchett writes witches at all. Their magic is in understanding people, and the people in Ankh-Morpork are just as much people as the people in Lancre. The differences of the city may warrant an occasional grumpy aside, but the witches are fully as capable of navigating the city as they are their home town. Maskerade is, of course, a parody of opera and musicals, with Phantom of the Opera playing the central role in much the same way that Macbeth did in Wyrd Sisters. Agnes ends up doing the singing for a beautiful, thin actress named Christine, who can't sing at all despite being an opera star, uses a truly astonishing excess of exclamation points, and strategically faints at the first sign of danger. (And, despite all of this, is still likable in that way that it's impossible to be really upset at a puppy.) She is the special chosen focus of the ghost, whose murderous taunting is a direct parody of the Phantom. That was a sufficiently obvious reference that even I picked up on it, despite being familiar with Phantom of the Opera only via the soundtrack. Apart from that, though, the references were lost on me, since I'm neither a musical nor an opera fan. That didn't hurt my enjoyment of the book in the slightest; in fact, I suspect it's part of why it's in my top tier of Discworld books. One of my complaints about Discworld to date is that Pratchett often overdoes the parody to the extent that it gets in the way of his own (excellent) characters and story. Maybe it's better to read Discworld novels where one doesn't recognize the material being parodied and thus doesn't keep getting distracted by references. It's probably worth mentioning that Agnes is a large woman and there are several jokes about her weight in Maskerade. I think they're the good sort of jokes, about how absurd human bodies can be, not the mean sort? Pratchett never implies her weight is any sort of moral failing or something she should change; quite the contrary, Nanny considers it a sign of solid Lancre genes. But there is some fat discrimination in the opera itself, since one of the things Pratchett is commenting on is the switch from full-bodied female opera singers to thin actresses matching an idealized beauty standard. Christine is the latter, but she can't sing, and the solution is for Agnes to sing for her from behind, something that was also done in real opera. I'm not a good judge of how well this plot line was handled; be aware, going in, if this may bother you. What did bother me was the ending, and more generally the degree to which Granny and Nanny felt comfortable making decisions about Agnes's life without consulting her or appearing to care what she thought of their conclusions. Pratchett seemed to be on their side, emphasizing how well they know people. But Agnes left Lancre and avoided the witches for a reason, and that reason is not honored in much the same way that Lancre refused to honor her desire to go by Perdita. This doesn't seem to be malicious, and Agnes herself is a little uncertain about her choice of identity, but it still rubbed me the wrong way. I felt like Agnes got steamrolled by both the other characters and by Pratchett, and it's the one thing about this book that I didn't like. Hopefully future Discworld books about these characters revisit Agnes's agency. Overall, though, this was great, and a huge improvement over Interesting Times. I'm excited for the next witches book. Followed in publication order by Feet of Clay, and later by Carpe Jugulum in the thematic sense. Rating: 8 out of 10

30 May 2022

Gunnar Wolf: On to the next journey

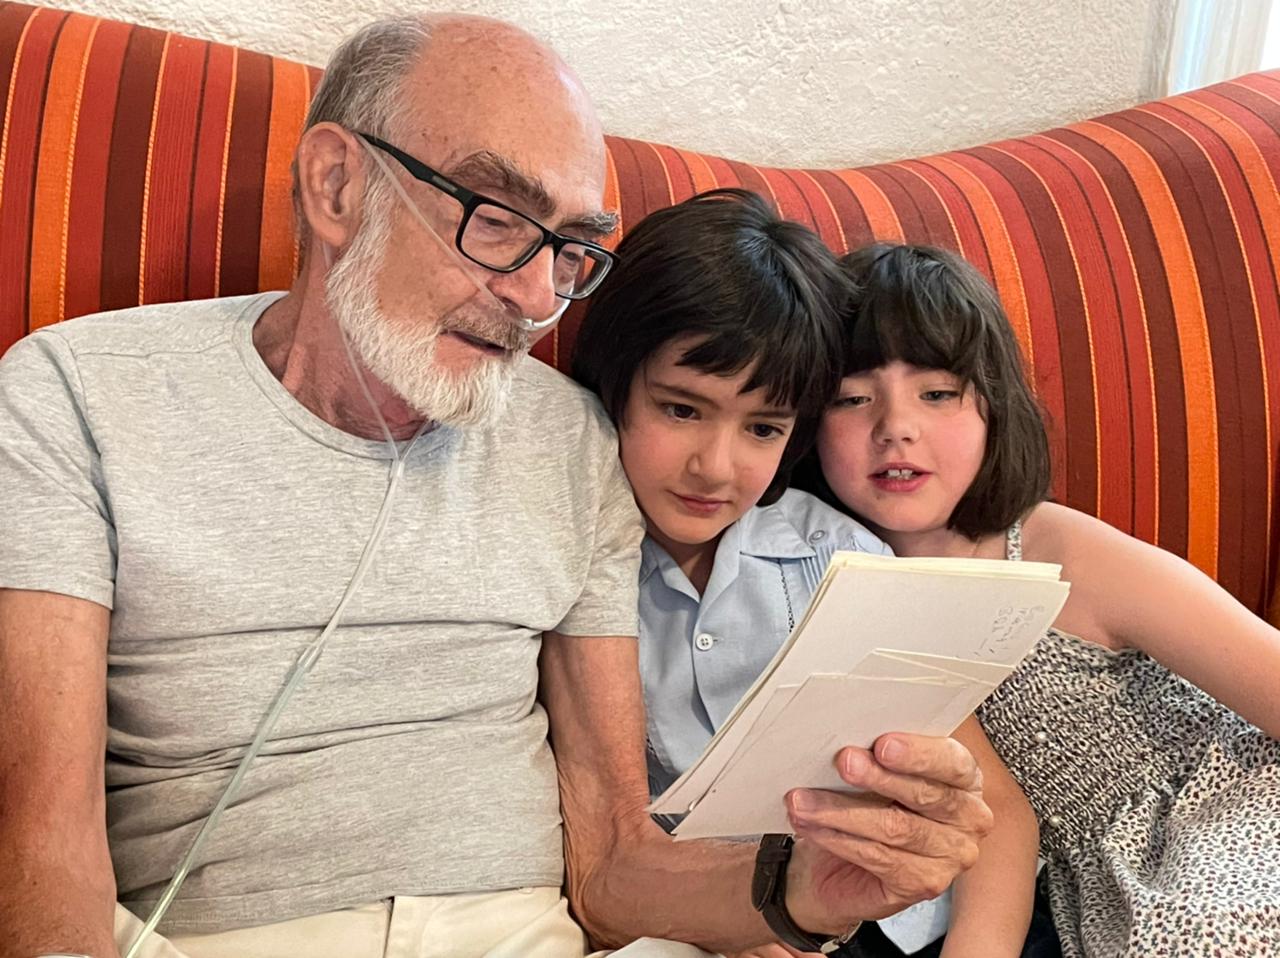
Last Wednesday my father, Kurt Bernardo Wolf Bogner, took the steps towards his next journey, the last that would start in this life. I cannot put words to this so just sharing this with the world will have to suffice. Goodbye to my teacher, my friend, the person I have always looked up to. Some of his friends were able to put in words more than what I can come up with. If you can read Spanish, you can read the eulogy from the Science Academy of Morelos. His last project, enjoyable by anybody who reads Spanish, is the book with his account of his youth travels Asia, Africa and Europe, beteen 1966 and 1970. You can read it online. And I have many printed copies, in case you want one as well. We will always remember you with love.

Russ Allbery: Review: Steles of the Sky

Review: Steles of the Sky, by Elizabeth Bear
Series: Eternal Sky #3
Publisher: Tor
Copyright: April 2014
ISBN: 0-7653-2756-2
Format: Hardcover
Pages: 429
Steles of the Sky is the third book of the Eternal Sky trilogy and a direct sequel to Shattered Pillars. You should not start here, and ideally you should read all three books close together. They form a single story, and Elizabeth Bear is somewhat notorious for not adding extra explanation to her novels. By the end of Shattered Pillars, Bear was (mostly) finished adding new factions to this story. Temur is returning home to fight for his people and his clan. His allies are mostly in place, as are his enemies. The hissable villain has remained hissable and boring, but several of his allies are more ambiguous and therefore more interesting (and get considerably more page time). All that remains is to see how Bear will end the story, and what last-minute twists will be thrown in. Well, that and getting the characters into the right positions, which occupies roughly the first half of the book and dragged a bit. There is an important and long-awaited reunion, Brother Hsiung gets his moment of focus, and the dowager empress gets some valuable character development, all of which did add to the story. But there's also a lot of plodding across the countryside. I also have no idea why the extended detour to Kyiv, began in Shattered Pillars and completed here, is even in this story. It tells us a few new scraps about Erem and its implications, but nothing vital. I felt like everything that happened there could have been done elsewhere or skipped entirely without much loss. The rest of the book is build-up to the epic conclusion, which is, somewhat unsurprisingly, a giant battle. It was okay, as giant battles go, but it also felt a bit like a fireworks display. Bear makes sure all the guns on the mantle go off by the end of the series, but a lot of them go off at the same time. It robs the plot construction of some of its power. There's nothing objectionable about this book. It's well-written, does what it sets out to do, brings the story to a relatively satisfying conclusion, provides some memorable set pieces, and is full of women making significant decisions that shape the plot. And yet, when I finished it, my reaction was "huh, okay" and then "oh, good, I can start another book now." Shattered Pillars won me over during the book. Steles of the Sky largely did not. I think my biggest complaint is one I've had about Bear's world-building before. She hints at some fascinating ideas: curious dragons, skies that vary with the political power currently in control, evil ancient magic, humanoid tigers with their own beliefs and magical system independent from humans, and a sky with a sun so hot that it would burn everything. Over the course of the series, she intrigued me with these ideas and left me eagerly awaiting an explanation. That explanation never comes. The history is never filled in, the tiger society is still only hints, Erem remains a vast mystery, the dragons appear only fleetingly to hint at connections with Erem... and then the book ends. I'm not sure whether Bear did explain some details and I wasn't paying close enough attention, or if she never intended detailed explanations. (Both are possible! Bear's books are often subtle.) But I wanted so much more. For me, half the fun of SFF world-building is the explanation. I love the hints and the mystery and the sense of lost knowledge and hidden depths... but then I want the characters to find the knowledge and plumb the depths, not just solve their immediate conflict. This is as good of a book as the first two books of the series on its own merits, but I enjoyed it less because I was hoping for more revelations before the story ended. The characters are all fine, but only a few of them stood out. Hrahima stole every scene she was in, and I would happily read a whole trilogy about her tiger people. Edene came into her own and had some great moments, but they didn't come with the revelations about Erem that I was hungry for. The rest of the large cast is varied and well-written and features a refreshing number of older women, and it wouldn't surprise me to hear that other readers had favorite characters who carried the series for them. But for me the characters weren't compelling enough to overcome my disappointment in the lack of world-building revelations. The series sadly didn't deliver the payoff that I was looking for, and I can't recommend it given the wealth of excellent fantasy being written today. But if you like Bear's understated writing style and don't need as much world-building payoff as I do, it may still be worth considering. Rating: 6 out of 10

29 May 2022

John Goerzen: Fast, Ordered Unixy Queues over NNCP and Syncthing with Filespooler

It seems that lately I ve written several shell implementations of a simple queue that enforces ordered execution of jobs that may arrive out of order. After writing this for the nth time in bash, I decided it was time to do it properly. But first, a word on the why of it all.

Why did I bother? My needs arose primarily from handling Backups over Asynchronous Communication methods in this case, NNCP. When backups contain incrementals that are unpacked on the destination, they must be applied in the correct order. In some cases, like ZFS, the receiving side will detect an out-of-order backup file and exit with an error. In those cases, processing in random order is acceptable but can be slow if, say, hundreds or thousands of hourly backups have stacked up over a period of time. The same goes for using gitsync-nncp to synchronize git repositories. In both cases, a best effort based on creation date is sufficient to produce a significant performance improvement. With other cases, such as tar or dar backups, the receiving cannot detect out of order incrementals. In those situations, the incrementals absolutely must be applied with strict ordering. There are many other situations that arise with these needs also. Filespooler is the answer to these.

Existing Work Before writing my own program, I of course looked at what was out there already. I looked at celeary, gearman, nq, rq, cctools work queue, ts/tsp (task spooler), filequeue, dramatiq, GNU parallel, and so forth. Unfortunately, none of these met my needs at all. They all tended to have properties like:
  • An extremely complicated client/server system that was incompatible with piping data over existing asynchronous tools
  • A large bias to processing of small web requests, resulting in terrible inefficiency or outright incompatibility with jobs in the TB range
  • An inability to enforce strict ordering of jobs, especially if they arrive in a different order from how they were queued
Many also lacked some nice-to-haves that I implemented for Filespooler:
  • Support for the encryption and cryptographic authentication of jobs, including metadata
  • First-class support for arbitrary compressors
  • Ability to use both stream transports (pipes) and filesystem-like transports (eg, rclone mount, S3, Syncthing, or Dropbox)

Introducing Filespooler Filespooler is a tool in the Unix tradition: that is, do one thing well, and integrate nicely with other tools using the fundamental Unix building blocks of files and pipes. Filespooler itself doesn t provide transport for jobs, but instead is designed to cooperate extremely easily with transports that can be written to as a filesystem or piped to which is to say, almost anything of interest. Filespooler is written in Rust and has an extensive Filespooler Reference as well as many tutorials on its homepage. To give you a few examples, here are some links:

Basics of How it Works Filespooler is intentionally simple:
  • The sender maintains a sequence file that includes a number for the next job packet to be created.
  • The receiver also maintains a sequence file that includes a number for the next job to be processed.
  • fspl prepare creates a Filespooler job packet and emits it to stdout. It includes a small header (<100 bytes in most cases) that includes the sequence number, creation timestamp, and some other useful metadata.
  • You get to transport this job packet to the receiver in any of many simple ways, which may or may not involve Filespooler s assistance.
  • On the receiver, Filespooler (when running in the default strict ordering mode) will simply look at the sequence file and process jobs in incremental order until it runs out of jobs to process.
The name of job files on-disk matches a pattern for identification, but the content of them is not significant; only the header matters. You can send job data in three ways:
  1. By piping it to fspl prepare
  2. By setting certain environment variables when calling fspl prepare
  3. By passing additional command-line arguments to fspl prepare, which can optionally be passed to the processing command at the receiver.
Data piped in is added to the job payload , while environment variables and command-line parameters are encoded in the header.

Basic usage Here I will excerpt part of the Using Filespooler over Syncthing tutorial; consult it for further detail. As a bit of background, Syncthing is a FLOSS decentralized directory synchronization tool akin to Dropbox (but with a much richer feature set in many ways).

Preparation First, on the receiver, you create the queue (passing the directory name to -q):
sender$ fspl queue-init -q ~/sync/b64queue
Now, we can send a job like this:
sender$ echo Hi   fspl prepare -s ~/b64seq -i -   fspl queue-write -q ~/sync/b64queue
Let s break that down:
  • First, we pipe Hi to fspl prepare.
  • fspl prepare takes two parameters:
    • -s seqfile gives the path to a sequence file used on the sender side. This file has a simple number in it that increments a unique counter for every generated job file. It is matched with the nextseq file within the queue to make sure that the receiver processes jobs in the correct order. It MUST be separate from the file that is in the queue and should NOT be placed within the queue. There is no need to sync this file, and it would be ideal to not sync it.
    • The -i option tells fspl prepare to read a file for the packet payload. -i - tells it to read stdin for this purpose. So, the payload will consist of three bytes: Hi\n (that is, including the terminating newline that echo wrote)
  • Now, fspl prepare writes the packet to its stdout. We pipe that into fspl queue-write:
    • fspl queue-write reads stdin and writes it to a file in the queue directory in a safe manner. The file will ultimately match the fspl-*.fspl pattern and have a random string in the middle.
At this point, wait a few seconds (or however long it takes) for the queue files to be synced over to the recipient. On the receiver, we can see if any jobs have arrived yet:
receiver$ fspl queue-ls -q ~/sync/b64queue
ID                   creation timestamp          filename
1                    2022-05-16T20:29:32-05:00   fspl-7b85df4e-4df9-448d-9437-5a24b92904a4.fspl
Let s say we d like some information about the job. Try this:
receiver$ $ fspl queue-info -q ~/sync/b64queue -j 1
FSPL_SEQ=1
FSPL_CTIME_SECS=1652940172
FSPL_CTIME_NANOS=94106744
FSPL_CTIME_RFC3339_UTC=2022-05-17T01:29:32Z
FSPL_CTIME_RFC3339_LOCAL=2022-05-16T20:29:32-05:00
FSPL_JOB_FILENAME=fspl-7b85df4e-4df9-448d-9437-5a24b92904a4.fspl
FSPL_JOB_QUEUEDIR=/home/jgoerzen/sync/b64queue
FSPL_JOB_FULLPATH=/home/jgoerzen/sync/b64queue/jobs/fspl-7b85df4e-4df9-448d-9437-5a24b92904a4.fspl
This information is intentionally emitted in a format convenient for parsing. Now let s run the job!
receiver$ fspl queue-process -q ~/sync/b64queue --allow-job-params base64
SGkK
There are two new parameters here:
  • --allow-job-params says that the sender is trusted to supply additional parameters for the command we will be running.
  • base64 is the name of the command that we will run for every job. It will:
    • Have environment variables set as we just saw in queue-info
    • Have the text we previously prepared Hi\n piped to it
By default, fspl queue-process doesn t do anything special with the output; see Handling Filespooler Command Output for details on other options. So, the base64-encoded version of our string is SGkK . We successfully sent a packet using Syncthing as a transport mechanism! At this point, if you do a fspl queue-ls again, you ll see the queue is empty. By default, fspl queue-process deletes jobs that have been successfully processed.

For more See the Filespooler homepage.
This blog post is also available as a permanent, periodically-updated page.

28 May 2022

kpcyrd: auth-tarball-from-git: Verifying tarballs with signed git tags

I noticed there s a common anti-pattern in some PKGBUILDs, the short scripts that are used to build Arch Linux packages. Specifically we re looking at the part that references the source code used when building a package:
source=("git+https://github.com/alacritty/alacritty.git#tag=v$ pkgver ?signed")
validpgpkeys=('4DAA67A9EA8B91FCC15B699C85CDAE3C164BA7B4'
              'A56EF308A9F1256C25ACA3807EA8F8B94622A6A9')
sha256sums=('SKIP')
This does: In contrast consider this PKGBUILD:
source=($pkgname-$pkgver.tar.gz::https://github.com/alacritty/alacritty/archive/refs/tags/v$pkgver.tar.gz)
sha256sums=('e48d4b10762c2707bb17fd8f89bd98f0dcccc450d223cade706fdd9cfaefb308')
Personally - if I had to decide between these two - I d prefer the later because I can always try to authenticate the pinned tarball later on, but it s impossible to know for sure which source code has been used if all I know is something that had a valid signature on it . This set could be infinitely large for all we know! But is there a way to get both? Consider this PKGBUILD:
makedepends=('auth-tarball-from-git')
source=($pkgname-$pkgver.tar.gz::https://github.com/alacritty/alacritty/archive/refs/tags/v$pkgver.tar.gz
        chrisduerr.pgp
        kchibisov.pgp)
sha256sums=('e48d4b10762c2707bb17fd8f89bd98f0dcccc450d223cade706fdd9cfaefb308'
            '19573dc0ba7a2f003377dc49986867f749235ecb45fe15eb923a74b2ab421d74'
            '5b866e6cb791c58cba2e7fc60f647588699b08abc2ad6b18ba82470f0fd3db3b')
prepare()  
  cd "$pkgname-$pkgver"
  auth-tarball-from-git --keyring ../chrisduerr.pgp --keyring ../kchibisov.pgp \
    --tag v$pkgver --prefix $pkgname-$pkgver \
    https://github.com/alacritty/alacritty.git ../$pkgname-$pkgver.tar.gz
 
In this case sha256sums= is the primary line of defense against tampering with build inputs and the git tag is only used to document authorship. For more infos on how this works you can have a look at the auth-tarball-from-git repo, there s also a section about attacks on signed git tags that you should probably know about.

Thanks This work is currently crowd-funded on github sponsors. I d like to thank @SantiagoTorres, @repi and @rgacogne for their support in particular.

27 May 2022

Reproducible Builds (diffoscope): diffoscope 214 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 214. This version includes the following changes:
[ Chris Lamb ]
* Support both python-argcomplete 1.x and 2.x.
[ Vagrant Cascadian ]
* Add external tool on GNU Guix for xb-tool.
You find out more by visiting the project homepage.

26 May 2022

Sergio Talens-Oliag: New Blog Config

As promised, on this post I m going to explain how I ve configured this blog using hugo, asciidoctor and the papermod theme, how I publish it using nginx, how I ve integrated the remark42 comment system and how I ve automated its publication using gitea and json2file-go. It is a long post, but I hope that at least parts of it can be interesting for some, feel free to ignore it if that is not your case

Hugo Configuration

Theme settingsThe site is using the PaperMod theme and as I m using asciidoctor to publish my content I ve adjusted the settings to improve how things are shown with it. The current config.yml file is the one shown below (probably some of the settings are not required nor being used right now, but I m including the current file, so this post will have always the latest version of it):
config.yml
baseURL: https://blogops.mixinet.net/
title: Mixinet BlogOps
paginate: 5
theme: PaperMod
destination: public/
enableInlineShortcodes: true
enableRobotsTXT: true
buildDrafts: false
buildFuture: false
buildExpired: false
enableEmoji: true
pygmentsUseClasses: true
minify:
  disableXML: true
  minifyOutput: true
languages:
  en:
    languageName: "English"
    description: "Mixinet BlogOps - https://blogops.mixinet.net/"
    author: "Sergio Talens-Oliag"
    weight: 1
    title: Mixinet BlogOps
    homeInfoParams:
      Title: "Sergio Talens-Oliag Technical Blog"
      Content: >
        ![Mixinet BlogOps](/images/mixinet-blogops.png)
    taxonomies:
      category: categories
      tag: tags
      series: series
    menu:
      main:
        - name: Archive
          url: archives
          weight: 5
        - name: Categories
          url: categories/
          weight: 10
        - name: Tags
          url: tags/
          weight: 10
        - name: Search
          url: search/
          weight: 15
outputs:
  home:
    - HTML
    - RSS
    - JSON
params:
  env: production
  defaultTheme: light
  disableThemeToggle: false
  ShowShareButtons: true
  ShowReadingTime: true
  disableSpecial1stPost: true
  disableHLJS: true
  displayFullLangName: true
  ShowPostNavLinks: true
  ShowBreadCrumbs: true
  ShowCodeCopyButtons: true
  ShowRssButtonInSectionTermList: true
  ShowFullTextinRSS: true
  ShowToc: true
  TocOpen: false
  comments: true
  remark42SiteID: "blogops"
  remark42Url: "/remark42"
  profileMode:
    enabled: false
    title: Sergio Talens-Oliag Technical Blog
    imageUrl: "/images/mixinet-blogops.png"
    imageTitle: Mixinet BlogOps
    buttons:
      - name: Archives
        url: archives
      - name: Categories
        url: categories
      - name: Tags
        url: tags
  socialIcons:
    - name: CV
      url: "https://www.uv.es/~sto/cv/"
    - name: Debian
      url: "https://people.debian.org/~sto/"
    - name: GitHub
      url: "https://github.com/sto/"
    - name: GitLab
      url: "https://gitlab.com/stalens/"
    - name: Linkedin
      url: "https://www.linkedin.com/in/sergio-talens-oliag/"
    - name: RSS
      url: "index.xml"
  assets:
    disableHLJS: true
    favicon: "/favicon.ico"
    favicon16x16:  "/favicon-16x16.png"
    favicon32x32:  "/favicon-32x32.png"
    apple_touch_icon:  "/apple-touch-icon.png"
    safari_pinned_tab:  "/safari-pinned-tab.svg"
  fuseOpts:
    isCaseSensitive: false
    shouldSort: true
    location: 0
    distance: 1000
    threshold: 0.4
    minMatchCharLength: 0
    keys: ["title", "permalink", "summary", "content"]
markup:
  asciidocExt:
    attributes:  
    backend: html5s
    extensions: ['asciidoctor-html5s','asciidoctor-diagram']
    failureLevel: fatal
    noHeaderOrFooter: true
    preserveTOC: false
    safeMode: unsafe
    sectionNumbers: false
    trace: false
    verbose: false
    workingFolderCurrent: true
privacy:
  vimeo:
    disabled: false
    simple: true
  twitter:
    disabled: false
    enableDNT: true
    simple: true
  instagram:
    disabled: false
    simple: true
  youtube:
    disabled: false
    privacyEnhanced: true
services:
  instagram:
    disableInlineCSS: true
  twitter:
    disableInlineCSS: true
security:
  exec:
    allow:
      - '^asciidoctor$'
      - '^dart-sass-embedded$'
      - '^go$'
      - '^npx$'
      - '^postcss$'
Some notes about the settings:
  • disableHLJS and assets.disableHLJS are set to true; we plan to use rouge on adoc and the inclusion of the hljs assets adds styles that collide with the ones used by rouge.
  • ShowToc is set to true and the TocOpen setting is set to false to make the ToC appear collapsed initially. My plan was to use the asciidoctor ToC, but after trying I believe that the theme one looks nice and I don t need to adjust styles, although it has some issues with the html5s processor (the admonition titles use <h6> and they are shown on the ToC, which is weird), to fix it I ve copied the layouts/partial/toc.html to my site repository and replaced the range of headings to end at 5 instead of 6 (in fact 5 still seems a lot, but as I don t think I ll use that heading level on the posts it doesn t really matter).
  • params.profileMode values are adjusted, but for now I ve left it disabled setting params.profileMode.enabled to false and I ve set the homeInfoParams to show more or less the same content with the latest posts under it (I ve added some styles to my custom.css style sheet to center the text and image of the first post to match the look and feel of the profile).
  • On the asciidocExt section I ve adjusted the backend to use html5s, I ve added the asciidoctor-html5s and asciidoctor-diagram extensions to asciidoctor and adjusted the workingFolderCurrent to true to make asciidoctor-diagram work right (haven t tested it yet).

Theme customisationsTo write in asciidoctor using the html5s processor I ve added some files to the assets/css/extended directory:
  1. As said before, I ve added the file assets/css/extended/custom.css to make the homeInfoParams look like the profile page and I ve also changed a little bit some theme styles to make things look better with the html5s output:
    custom.css
    /* Fix first entry alignment to make it look like the profile */
    .first-entry   text-align: center;  
    .first-entry img   display: inline;  
    /**
     * Remove margin for .post-content code and reduce padding to make it look
     * better with the asciidoctor html5s output.
     **/
    .post-content code   margin: auto 0; padding: 4px;  
  2. I ve also added the file assets/css/extended/adoc.css with some styles taken from the asciidoctor-default.css, see this blog post about the original file; mine is the same after formatting it with css-beautify and editing it to use variables for the colors to support light and dark themes:
    adoc.css
    /* AsciiDoctor*/
    table  
        border-collapse: collapse;
        border-spacing: 0
     
    .admonitionblock>table  
        border-collapse: separate;
        border: 0;
        background: none;
        width: 100%
     
    .admonitionblock>table td.icon  
        text-align: center;
        width: 80px
     
    .admonitionblock>table td.icon img  
        max-width: none
     
    .admonitionblock>table td.icon .title  
        font-weight: bold;
        font-family: "Open Sans", "DejaVu Sans", sans-serif;
        text-transform: uppercase
     
    .admonitionblock>table td.content  
        padding-left: 1.125em;
        padding-right: 1.25em;
        border-left: 1px solid #ddddd8;
        color: var(--primary)
     
    .admonitionblock>table td.content>:last-child>:last-child  
        margin-bottom: 0
     
    .admonitionblock td.icon [class^="fa icon-"]  
        font-size: 2.5em;
        text-shadow: 1px 1px 2px var(--secondary);
        cursor: default
     
    .admonitionblock td.icon .icon-note::before  
        content: "\f05a";
        color: var(--icon-note-color)
     
    .admonitionblock td.icon .icon-tip::before  
        content: "\f0eb";
        color: var(--icon-tip-color)
     
    .admonitionblock td.icon .icon-warning::before  
        content: "\f071";
        color: var(--icon-warning-color)
     
    .admonitionblock td.icon .icon-caution::before  
        content: "\f06d";
        color: var(--icon-caution-color)
     
    .admonitionblock td.icon .icon-important::before  
        content: "\f06a";
        color: var(--icon-important-color)
     
    .conum[data-value]  
        display: inline-block;
        color: #fff !important;
        background-color: rgba(100, 100, 0, .8);
        -webkit-border-radius: 100px;
        border-radius: 100px;
        text-align: center;
        font-size: .75em;
        width: 1.67em;
        height: 1.67em;
        line-height: 1.67em;
        font-family: "Open Sans", "DejaVu Sans", sans-serif;
        font-style: normal;
        font-weight: bold
     
    .conum[data-value] *  
        color: #fff !important
     
    .conum[data-value]+b  
        display: none
     
    .conum[data-value]::after  
        content: attr(data-value)
     
    pre .conum[data-value]  
        position: relative;
        top: -.125em
     
    b.conum *  
        color: inherit !important
     
    .conum:not([data-value]):empty  
        display: none
     
  3. The previous file uses variables from a partial copy of the theme-vars.css file that changes the highlighted code background color and adds the color definitions used by the admonitions:
    theme-vars.css
    :root  
        /* Solarized base2 */
        /* --hljs-bg: rgb(238, 232, 213); */
        /* Solarized base3 */
        /* --hljs-bg: rgb(253, 246, 227); */
        /* Solarized base02 */
        --hljs-bg: rgb(7, 54, 66);
        /* Solarized base03 */
        /* --hljs-bg: rgb(0, 43, 54); */
        /* Default asciidoctor theme colors */
        --icon-note-color: #19407c;
        --icon-tip-color: var(--primary);
        --icon-warning-color: #bf6900;
        --icon-caution-color: #bf3400;
        --icon-important-color: #bf0000
     
    .dark  
        --hljs-bg: rgb(7, 54, 66);
        /* Asciidoctor theme colors with tint for dark background */
        --icon-note-color: #3e7bd7;
        --icon-tip-color: var(--primary);
        --icon-warning-color: #ff8d03;
        --icon-caution-color: #ff7847;
        --icon-important-color: #ff3030
     
  4. The previous styles use font-awesome, so I ve downloaded its resources for version 4.7.0 (the one used by asciidoctor) storing the font-awesome.css into on the assets/css/extended dir (that way it is merged with the rest of .css files) and copying the fonts to the static/assets/fonts/ dir (will be served directly):
    FA_BASE_URL="https://cdnjs.cloudflare.com/ajax/libs/font-awesome/4.7.0"
    curl "$FA_BASE_URL/css/font-awesome.css" \
      > assets/css/extended/font-awesome.css
    for f in FontAwesome.otf fontawesome-webfont.eot \
      fontawesome-webfont.svg fontawesome-webfont.ttf \
      fontawesome-webfont.woff fontawesome-webfont.woff2; do
        curl "$FA_BASE_URL/fonts/$f" > "static/assets/fonts/$f"
    done
  5. As already said the default highlighter is disabled (it provided a css compatible with rouge) so we need a css to do the highlight styling; as rouge provides a way to export them, I ve created the assets/css/extended/rouge.css file with the thankful_eyes theme:
    rougify style thankful_eyes > assets/css/extended/rouge.css
  6. To support the use of the html5s backend with admonitions I ve added a variation of the example found on this blog post to assets/js/adoc-admonitions.js:
    adoc-admonitions.js
    // replace the default admonitions block with a table that uses a format
    // similar to the standard asciidoctor ... as we are using fa-icons here there
    // is no need to add the icons: font entry on the document.
    window.addEventListener('load', function ()  
      const admonitions = document.getElementsByClassName('admonition-block')
      for (let i = admonitions.length - 1; i >= 0; i--)  
        const elm = admonitions[i]
        const type = elm.classList[1]
        const title = elm.getElementsByClassName('block-title')[0];
    	const label = title.getElementsByClassName('title-label')[0]
    		.innerHTML.slice(0, -1);
        elm.removeChild(elm.getElementsByClassName('block-title')[0]);
        const text = elm.innerHTML
        const parent = elm.parentNode
        const tempDiv = document.createElement('div')
        tempDiv.innerHTML =  <div class="admonitionblock $ type ">
        <table>
          <tbody>
            <tr>
              <td class="icon">
                <i class="fa icon-$ type " title="$ label "></i>
              </td>
              <td class="content">
                $ text 
              </td>
            </tr>
          </tbody>
        </table>
      </div> 
        const input = tempDiv.childNodes[0]
        parent.replaceChild(input, elm)
       
     )
    and enabled its minified use on the layouts/partials/extend_footer.html file adding the following lines to it:
     - $admonitions := slice (resources.Get "js/adoc-admonitions.js")
        resources.Concat "assets/js/adoc-admonitions.js"   minify   fingerprint  
    <script defer crossorigin="anonymous" src="  $admonitions.RelPermalink  "
      integrity="  $admonitions.Data.Integrity  "></script>

Remark42 configurationTo integrate Remark42 with the PaperMod theme I ve created the file layouts/partials/comments.html with the following content based on the remark42 documentation, including extra code to sync the dark/light setting with the one set on the site:
comments.html
<div id="remark42"></div>
<script>
  var remark_config =  
    host:   .Site.Params.remark42Url  ,
    site_id:   .Site.Params.remark42SiteID  ,
    url:   .Permalink  ,
    locale:   .Site.Language.Lang  
   ;
  (function(c)  
    /* Adjust the theme using the local-storage pref-theme if set */
    if (localStorage.getItem("pref-theme") === "dark")  
      remark_config.theme = "dark";
      else if (localStorage.getItem("pref-theme") === "light")  
      remark_config.theme = "light";
     
    /* Add remark42 widget */
    for(var i = 0; i < c.length; i++) 
      var d = document, s = d.createElement('script');
      s.src = remark_config.host + '/web/' + c[i] +'.js';
      s.defer = true;
      (d.head   d.body).appendChild(s);
     
   )(remark_config.components   ['embed']);
</script>
In development I use it with anonymous comments enabled, but to avoid SPAM the production site uses social logins (for now I ve only enabled Github & Google, if someone requests additional services I ll check them, but those were the easy ones for me initially). To support theme switching with remark42 I ve also added the following inside the layouts/partials/extend_footer.html file:
 - if (not site.Params.disableThemeToggle)  
<script>
/* Function to change theme when the toggle button is pressed */
document.getElementById("theme-toggle").addEventListener("click", () =>  
  if (typeof window.REMARK42 != "undefined")  
    if (document.body.className.includes('dark'))  
      window.REMARK42.changeTheme('light');
      else  
      window.REMARK42.changeTheme('dark');
     
   
 );
</script>
 - end  
With this code if the theme-toggle button is pressed we change the remark42 theme before the PaperMod one (that s needed here only, on page loads the remark42 theme is synced with the main one using the code from the layouts/partials/comments.html shown earlier).

Development setupTo preview the site on my laptop I m using docker-compose with the following configuration:
docker-compose.yaml
version: "2"
services:
  hugo:
    build:
      context: ./docker/hugo-adoc
      dockerfile: ./Dockerfile
    image: sto/hugo-adoc
    container_name: hugo-adoc-blogops
    restart: always
    volumes:
      - .:/documents
    command: server --bind 0.0.0.0 -D -F
    user: $ APP_UID :$ APP_GID 
  nginx:
    image: nginx:latest
    container_name: nginx-blogops
    restart: always
    volumes:
      - ./nginx/default.conf:/etc/nginx/conf.d/default.conf
    ports:
      -  1313:1313
  remark42:
    build:
      context: ./docker/remark42
      dockerfile: ./Dockerfile
    image: sto/remark42
    container_name: remark42-blogops
    restart: always
    env_file:
      - ./.env
      - ./remark42/env.dev
    volumes:
      - ./remark42/var.dev:/srv/var
To run it properly we have to create the .env file with the current user ID and GID on the variables APP_UID and APP_GID (if we don t do it the files can end up being owned by a user that is not the same as the one running the services):
$ echo "APP_UID=$(id -u)\nAPP_GID=$(id -g)" > .env
The Dockerfile used to generate the sto/hugo-adoc is:
Dockerfile
FROM asciidoctor/docker-asciidoctor:latest
RUN gem install --no-document asciidoctor-html5s &&\
 apk update && apk add --no-cache curl libc6-compat &&\
 repo_path="gohugoio/hugo" &&\
 api_url="https://api.github.com/repos/$repo_path/releases/latest" &&\
 download_url="$(\
  curl -sL "$api_url"  \
  sed -n "s/^.*download_url\": \"\\(.*.extended.*Linux-64bit.tar.gz\)\"/\1/p"\
 )" &&\
 curl -sL "$download_url" -o /tmp/hugo.tgz &&\
 tar xf /tmp/hugo.tgz hugo &&\
 install hugo /usr/bin/ &&\
 rm -f hugo /tmp/hugo.tgz &&\
 /usr/bin/hugo version &&\
 apk del curl && rm -rf /var/cache/apk/*
# Expose port for live server
EXPOSE 1313
ENTRYPOINT ["/usr/bin/hugo"]
CMD [""]
If you review it you will see that I m using the docker-asciidoctor image as the base; the idea is that this image has all I need to work with asciidoctor and to use hugo I only need to download the binary from their latest release at github (as we are using an image based on alpine we also need to install the libc6-compat package, but once that is done things are working fine for me so far). The image does not launch the server by default because I don t want it to; in fact I use the same docker-compose.yml file to publish the site in production simply calling the container without the arguments passed on the docker-compose.yml file (see later). When running the containers with docker-compose up (or docker compose up if you have the docker-compose-plugin package installed) we also launch a nginx container and the remark42 service so we can test everything together. The Dockerfile for the remark42 image is the original one with an updated version of the init.sh script:
Dockerfile
FROM umputun/remark42:latest
COPY init.sh /init.sh
The updated init.sh is similar to the original, but allows us to use an APP_GID variable and updates the /etc/group file of the container so the files get the right user and group (with the original script the group is always 1001):
init.sh
#!/sbin/dinit /bin/sh
uid="$(id -u)"
if [ "$ uid " -eq "0" ]; then
  echo "init container"
  # set container's time zone
  cp "/usr/share/zoneinfo/$ TIME_ZONE " /etc/localtime
  echo "$ TIME_ZONE " >/etc/timezone
  echo "set timezone $ TIME_ZONE  ($(date))"
  # set UID & GID for the app
  if [ "$ APP_UID " ]   [ "$ APP_GID " ]; then
    [ "$ APP_UID " ]   APP_UID="1001"
    [ "$ APP_GID " ]   APP_GID="$ APP_UID "
    echo "set custom APP_UID=$ APP_UID  & APP_GID=$ APP_GID "
    sed -i "s/^app:x:1001:1001:/app:x:$ APP_UID :$ APP_GID :/" /etc/passwd
    sed -i "s/^app:x:1001:/app:x:$ APP_GID :/" /etc/group
  else
    echo "custom APP_UID and/or APP_GID not defined, using 1001:1001"
  fi
  chown -R app:app /srv /home/app
fi
echo "prepare environment"
# replace  % REMARK_URL %  by content of REMARK_URL variable
find /srv -regex '.*\.\(html\ js\ mjs\)$' -print \
  -exec sed -i "s % REMARK_URL % $ REMARK_URL  g"   \;
if [ -n "$ SITE_ID " ]; then
  #replace "site_id: 'remark'" by SITE_ID
  sed -i "s 'remark' '$ SITE_ID ' g" /srv/web/*.html
fi
echo "execute \"$*\""
if [ "$ uid " -eq "0" ]; then
  exec su-exec app "$@"
else
  exec "$@"
fi
The environment file used with remark42 for development is quite minimal:
env.dev
TIME_ZONE=Europe/Madrid
REMARK_URL=http://localhost:1313/remark42
SITE=blogops
SECRET=123456
ADMIN_SHARED_ID=sto
AUTH_ANON=true
EMOJI=true
And the nginx/default.conf file used to publish the service locally is simple too:
default.conf
server   
 listen 1313;
 server_name localhost;
 location /  
    proxy_pass http://hugo:1313;
    proxy_set_header Host $http_host;
    proxy_set_header X-Real-IP $remote_addr;
    proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
    proxy_set_header X-Forwarded-Proto $scheme;
    proxy_set_header Upgrade $http_upgrade;
    proxy_set_header Connection "upgrade";
  
 location /remark42/  
    rewrite /remark42/(.*) /$1 break;
    proxy_pass http://remark42:8080/;
    proxy_set_header Host $http_host;
    proxy_set_header X-Real-IP $remote_addr;
    proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
    proxy_set_header X-Forwarded-Proto $scheme;


Production setupThe VM where I m publishing the blog runs Debian GNU/Linux and uses binaries from local packages and applications packaged inside containers. To run the containers I m using docker-ce (I could have used podman instead, but I already had it installed on the machine, so I stayed with it). The binaries used on this project are included on the following packages from the main Debian repository:
  • git to clone & pull the repository,
  • jq to parse json files from shell scripts,
  • json2file-go to save the webhook messages to files,
  • inotify-tools to detect when new files are stored by json2file-go and launch scripts to process them,
  • nginx to publish the site using HTTPS and work as proxy for json2file-go and remark42 (I run it using a container),
  • task-spool to queue the scripts that update the deployment.
And I m using docker and docker compose from the debian packages on the docker repository:
  • docker-ce to run the containers,
  • docker-compose-plugin to run docker compose (it is a plugin, so no - in the name).

Repository checkoutTo manage the git repository I ve created a deploy key, added it to gitea and cloned the project on the /srv/blogops PATH (that route is owned by a regular user that has permissions to run docker, as I said before).

Compiling the site with hugoTo compile the site we are using the docker-compose.yml file seen before, to be able to run it first we build the container images and once we have them we launch hugo using docker compose run:
$ cd /srv/blogops
$ git pull
$ docker compose build
$ if [ -d "./public" ]; then rm -rf ./public; fi
$ docker compose run hugo --
The compilation leaves the static HTML on /srv/blogops/public (we remove the directory first because hugo does not clean the destination folder as jekyll does). The deploy script re-generates the site as described and moves the public directory to its final place for publishing.

Running remark42 with dockerOn the /srv/blogops/remark42 folder I have the following docker-compose.yml:
docker-compose.yml
version: "2"
services:
  remark42:
    build:
      context: ../docker/remark42
      dockerfile: ./Dockerfile
    image: sto/remark42
    env_file:
      - ../.env
      - ./env.prod
    container_name: remark42
    restart: always
    volumes:
      - ./var.prod:/srv/var
    ports:
      - 127.0.0.1:8042:8080
The ../.env file is loaded to get the APP_UID and APP_GID variables that are used by my version of the init.sh script to adjust file permissions and the env.prod file contains the rest of the settings for remark42, including the social network tokens (see the remark42 documentation for the available parameters, I don t include my configuration here because some of them are secrets).

Nginx configurationThe nginx configuration for the blogops.mixinet.net site is as simple as:
server  
  listen 443 ssl http2;
  server_name blogops.mixinet.net;
  ssl_certificate /etc/letsencrypt/live/blogops.mixinet.net/fullchain.pem;
  ssl_certificate_key /etc/letsencrypt/live/blogops.mixinet.net/privkey.pem;
  include /etc/letsencrypt/options-ssl-nginx.conf;
  ssl_dhparam /etc/letsencrypt/ssl-dhparams.pem;
  access_log /var/log/nginx/blogops.mixinet.net-443.access.log;
  error_log  /var/log/nginx/blogops.mixinet.net-443.error.log;
  root /srv/blogops/nginx/public_html;
  location /  
    try_files $uri $uri/ =404;
   
  include /srv/blogops/nginx/remark42.conf;
 
server  
  listen 80 ;
  listen [::]:80 ;
  server_name blogops.mixinet.net;
  access_log /var/log/nginx/blogops.mixinet.net-80.access.log;
  error_log  /var/log/nginx/blogops.mixinet.net-80.error.log;
  if ($host = blogops.mixinet.net)  
    return 301 https://$host$request_uri;
   
  return 404;
 
On this configuration the certificates are managed by certbot and the server root directory is on /srv/blogops/nginx/public_html and not on /srv/blogops/public; the reason for that is that I want to be able to compile without affecting the running site, the deployment script generates the site on /srv/blogops/public and if all works well we rename folders to do the switch, making the change feel almost atomic.

json2file-go configurationAs I have a working WireGuard VPN between the machine running gitea at my home and the VM where the blog is served, I m going to configure the json2file-go to listen for connections on a high port using a self signed certificate and listening on IP addresses only reachable through the VPN. To do it we create a systemd socket to run json2file-go and adjust its configuration to listen on a private IP (we use the FreeBind option on its definition to be able to launch the service even when the IP is not available, that is, when the VPN is down). The following script can be used to set up the json2file-go configuration:
setup-json2file.sh
#!/bin/sh
set -e
# ---------
# VARIABLES
# ---------
BASE_DIR="/srv/blogops/webhook"
J2F_DIR="$BASE_DIR/json2file"
TLS_DIR="$BASE_DIR/tls"
J2F_SERVICE_NAME="json2file-go"
J2F_SERVICE_DIR="/etc/systemd/system/json2file-go.service.d"
J2F_SERVICE_OVERRIDE="$J2F_SERVICE_DIR/override.conf"
J2F_SOCKET_DIR="/etc/systemd/system/json2file-go.socket.d"
J2F_SOCKET_OVERRIDE="$J2F_SOCKET_DIR/override.conf"
J2F_BASEDIR_FILE="/etc/json2file-go/basedir"
J2F_DIRLIST_FILE="/etc/json2file-go/dirlist"
J2F_CRT_FILE="/etc/json2file-go/certfile"
J2F_KEY_FILE="/etc/json2file-go/keyfile"
J2F_CRT_PATH="$TLS_DIR/crt.pem"
J2F_KEY_PATH="$TLS_DIR/key.pem"
# ----
# MAIN
# ----
# Install packages used with json2file for the blogops site
sudo apt update
sudo apt install -y json2file-go uuid
if [ -z "$(type mkcert)" ]; then
  sudo apt install -y mkcert
fi
sudo apt clean
# Configuration file values
J2F_USER="$(id -u)"
J2F_GROUP="$(id -g)"
J2F_DIRLIST="blogops:$(uuid)"
J2F_LISTEN_STREAM="172.31.31.1:4443"
# Configure json2file
[ -d "$J2F_DIR" ]   mkdir "$J2F_DIR"
sudo sh -c "echo '$J2F_DIR' >'$J2F_BASEDIR_FILE'"
[ -d "$TLS_DIR" ]   mkdir "$TLS_DIR"
if [ ! -f "$J2F_CRT_PATH" ]   [ ! -f "$J2F_KEY_PATH" ]; then
  mkcert -cert-file "$J2F_CRT_PATH" -key-file "$J2F_KEY_PATH" "$(hostname -f)"
fi
sudo sh -c "echo '$J2F_CRT_PATH' >'$J2F_CRT_FILE'"
sudo sh -c "echo '$J2F_KEY_PATH' >'$J2F_KEY_FILE'"
sudo sh -c "cat >'$J2F_DIRLIST_FILE'" <<EOF
$(echo "$J2F_DIRLIST"   tr ';' '\n')
EOF
# Service override
[ -d "$J2F_SERVICE_DIR" ]   sudo mkdir "$J2F_SERVICE_DIR"
sudo sh -c "cat >'$J2F_SERVICE_OVERRIDE'" <<EOF
[Service]
User=$J2F_USER
Group=$J2F_GROUP
EOF
# Socket override
[ -d "$J2F_SOCKET_DIR" ]   sudo mkdir "$J2F_SOCKET_DIR"
sudo sh -c "cat >'$J2F_SOCKET_OVERRIDE'" <<EOF
[Socket]
# Set FreeBind to listen on missing addresses (the VPN can be down sometimes)
FreeBind=true
# Set ListenStream to nothing to clear its value and add the new value later
ListenStream=
ListenStream=$J2F_LISTEN_STREAM
EOF
# Restart and enable service
sudo systemctl daemon-reload
sudo systemctl stop "$J2F_SERVICE_NAME"
sudo systemctl start "$J2F_SERVICE_NAME"
sudo systemctl enable "$J2F_SERVICE_NAME"
# ----
# vim: ts=2:sw=2:et:ai:sts=2
Warning: The script uses mkcert to create the temporary certificates, to install the package on bullseye the backports repository must be available.

Gitea configurationTo make gitea use our json2file-go server we go to the project and enter into the hooks/gitea/new page, once there we create a new webhook of type gitea and set the target URL to https://172.31.31.1:4443/blogops and on the secret field we put the token generated with uuid by the setup script:
sed -n -e 's/blogops://p' /etc/json2file-go/dirlist
The rest of the settings can be left as they are:
  • Trigger on: Push events
  • Branch filter: *
Warning: We are using an internal IP and a self signed certificate, that means that we have to review that the webhook section of the app.ini of our gitea server allows us to call the IP and skips the TLS verification (you can see the available options on the gitea documentation). The [webhook] section of my server looks like this:
[webhook]
ALLOWED_HOST_LIST=private
SKIP_TLS_VERIFY=true
Once we have the webhook configured we can try it and if it works our json2file server will store the file on the /srv/blogops/webhook/json2file/blogops/ folder.

The json2file spooler scriptWith the previous configuration our system is ready to receive webhook calls from gitea and store the messages on files, but we have to do something to process those files once they are saved in our machine. An option could be to use a cronjob to look for new files, but we can do better on Linux using inotify we will use the inotifywait command from inotify-tools to watch the json2file output directory and execute a script each time a new file is moved inside it or closed after writing (IN_CLOSE_WRITE and IN_MOVED_TO events). To avoid concurrency problems we are going to use task-spooler to launch the scripts that process the webhooks using a queue of length 1, so they are executed one by one in a FIFO queue. The spooler script is this:
blogops-spooler.sh
#!/bin/sh
set -e
# ---------
# VARIABLES
# ---------
BASE_DIR="/srv/blogops/webhook"
BIN_DIR="$BASE_DIR/bin"
TSP_DIR="$BASE_DIR/tsp"
WEBHOOK_COMMAND="$BIN_DIR/blogops-webhook.sh"
# ---------
# FUNCTIONS
# ---------
queue_job()  
  echo "Queuing job to process file '$1'"
  TMPDIR="$TSP_DIR" TS_SLOTS="1" TS_MAXFINISHED="10" \
    tsp -n "$WEBHOOK_COMMAND" "$1"
 
# ----
# MAIN
# ----
INPUT_DIR="$1"
if [ ! -d "$INPUT_DIR" ]; then
  echo "Input directory '$INPUT_DIR' does not exist, aborting!"
  exit 1
fi
[ -d "$TSP_DIR" ]   mkdir "$TSP_DIR"
echo "Processing existing files under '$INPUT_DIR'"
find "$INPUT_DIR" -type f   sort   while read -r _filename; do
  queue_job "$_filename"
done
# Use inotifywatch to process new files
echo "Watching for new files under '$INPUT_DIR'"
inotifywait -q -m -e close_write,moved_to --format "%w%f" -r "$INPUT_DIR"  
  while read -r _filename; do
    queue_job "$_filename"
  done
# ----
# vim: ts=2:sw=2:et:ai:sts=2
To run it as a daemon we install it as a systemd service using the following script:
setup-spooler.sh
#!/bin/sh
set -e
# ---------
# VARIABLES
# ---------
BASE_DIR="/srv/blogops/webhook"
BIN_DIR="$BASE_DIR/bin"
J2F_DIR="$BASE_DIR/json2file"
SPOOLER_COMMAND="$BIN_DIR/blogops-spooler.sh '$J2F_DIR'"
SPOOLER_SERVICE_NAME="blogops-j2f-spooler"
SPOOLER_SERVICE_FILE="/etc/systemd/system/$SPOOLER_SERVICE_NAME.service"
# Configuration file values
J2F_USER="$(id -u)"
J2F_GROUP="$(id -g)"
# ----
# MAIN
# ----
# Install packages used with the webhook processor
sudo apt update
sudo apt install -y inotify-tools jq task-spooler
sudo apt clean
# Configure process service
sudo sh -c "cat > $SPOOLER_SERVICE_FILE" <<EOF
[Install]
WantedBy=multi-user.target
[Unit]
Description=json2file processor for $J2F_USER
After=docker.service
[Service]
Type=simple
User=$J2F_USER
Group=$J2F_GROUP
ExecStart=$SPOOLER_COMMAND
EOF
# Restart and enable service
sudo systemctl daemon-reload
sudo systemctl stop "$SPOOLER_SERVICE_NAME"   true
sudo systemctl start "$SPOOLER_SERVICE_NAME"
sudo systemctl enable "$SPOOLER_SERVICE_NAME"
# ----
# vim: ts=2:sw=2:et:ai:sts=2

The gitea webhook processorFinally, the script that processes the JSON files does the following:
  1. First, it checks if the repository and branch are right,
  2. Then, it fetches and checks out the commit referenced on the JSON file,
  3. Once the files are updated, compiles the site using hugo with docker compose,
  4. If the compilation succeeds the script renames directories to swap the old version of the site by the new one.
If there is a failure the script aborts but before doing it or if the swap succeeded the system sends an email to the configured address and/or the user that pushed updates to the repository with a log of what happened. The current script is this one:
blogops-webhook.sh
#!/bin/sh
set -e
# ---------
# VARIABLES
# ---------
# Values
REPO_REF="refs/heads/main"
REPO_CLONE_URL="https://gitea.mixinet.net/mixinet/blogops.git"
MAIL_PREFIX="[BLOGOPS-WEBHOOK] "
# Address that gets all messages, leave it empty if not wanted
MAIL_TO_ADDR="blogops@mixinet.net"
# If the following variable is set to 'true' the pusher gets mail on failures
MAIL_ERRFILE="false"
# If the following variable is set to 'true' the pusher gets mail on success
MAIL_LOGFILE="false"
# gitea's conf/app.ini value of NO_REPLY_ADDRESS, it is used for email domains
# when the KeepEmailPrivate option is enabled for a user
NO_REPLY_ADDRESS="noreply.example.org"
# Directories
BASE_DIR="/srv/blogops"
PUBLIC_DIR="$BASE_DIR/public"
NGINX_BASE_DIR="$BASE_DIR/nginx"
PUBLIC_HTML_DIR="$NGINX_BASE_DIR/public_html"
WEBHOOK_BASE_DIR="$BASE_DIR/webhook"
WEBHOOK_SPOOL_DIR="$WEBHOOK_BASE_DIR/spool"
WEBHOOK_ACCEPTED="$WEBHOOK_SPOOL_DIR/accepted"
WEBHOOK_DEPLOYED="$WEBHOOK_SPOOL_DIR/deployed"
WEBHOOK_REJECTED="$WEBHOOK_SPOOL_DIR/rejected"
WEBHOOK_TROUBLED="$WEBHOOK_SPOOL_DIR/troubled"
WEBHOOK_LOG_DIR="$WEBHOOK_SPOOL_DIR/log"
# Files
TODAY="$(date +%Y%m%d)"
OUTPUT_BASENAME="$(date +%Y%m%d-%H%M%S.%N)"
WEBHOOK_LOGFILE_PATH="$WEBHOOK_LOG_DIR/$OUTPUT_BASENAME.log"
WEBHOOK_ACCEPTED_JSON="$WEBHOOK_ACCEPTED/$OUTPUT_BASENAME.json"
WEBHOOK_ACCEPTED_LOGF="$WEBHOOK_ACCEPTED/$OUTPUT_BASENAME.log"
WEBHOOK_REJECTED_TODAY="$WEBHOOK_REJECTED/$TODAY"
WEBHOOK_REJECTED_JSON="$WEBHOOK_REJECTED_TODAY/$OUTPUT_BASENAME.json"
WEBHOOK_REJECTED_LOGF="$WEBHOOK_REJECTED_TODAY/$OUTPUT_BASENAME.log"
WEBHOOK_DEPLOYED_TODAY="$WEBHOOK_DEPLOYED/$TODAY"
WEBHOOK_DEPLOYED_JSON="$WEBHOOK_DEPLOYED_TODAY/$OUTPUT_BASENAME.json"
WEBHOOK_DEPLOYED_LOGF="$WEBHOOK_DEPLOYED_TODAY/$OUTPUT_BASENAME.log"
WEBHOOK_TROUBLED_TODAY="$WEBHOOK_TROUBLED/$TODAY"
WEBHOOK_TROUBLED_JSON="$WEBHOOK_TROUBLED_TODAY/$OUTPUT_BASENAME.json"
WEBHOOK_TROUBLED_LOGF="$WEBHOOK_TROUBLED_TODAY/$OUTPUT_BASENAME.log"
# Query to get variables from a gitea webhook json
ENV_VARS_QUERY="$(
  printf "%s" \
    '(.             @sh "gt_ref=\(.ref);"),' \
    '(.             @sh "gt_after=\(.after);"),' \
    '(.repository   @sh "gt_repo_clone_url=\(.clone_url);"),' \
    '(.repository   @sh "gt_repo_name=\(.name);"),' \
    '(.pusher       @sh "gt_pusher_full_name=\(.full_name);"),' \
    '(.pusher       @sh "gt_pusher_email=\(.email);")'
)"
# ---------
# Functions
# ---------
webhook_log()  
  echo "$(date -R) $*" >>"$WEBHOOK_LOGFILE_PATH"
 
webhook_check_directories()  
  for _d in "$WEBHOOK_SPOOL_DIR" "$WEBHOOK_ACCEPTED" "$WEBHOOK_DEPLOYED" \
    "$WEBHOOK_REJECTED" "$WEBHOOK_TROUBLED" "$WEBHOOK_LOG_DIR"; do
    [ -d "$_d" ]   mkdir "$_d"
  done
 
webhook_clean_directories()  
  # Try to remove empty dirs
  for _d in "$WEBHOOK_ACCEPTED" "$WEBHOOK_DEPLOYED" "$WEBHOOK_REJECTED" \
    "$WEBHOOK_TROUBLED" "$WEBHOOK_LOG_DIR" "$WEBHOOK_SPOOL_DIR"; do
    if [ -d "$_d" ]; then
      rmdir "$_d" 2>/dev/null   true
    fi
  done
 
webhook_accept()  
  webhook_log "Accepted: $*"
  mv "$WEBHOOK_JSON_INPUT_FILE" "$WEBHOOK_ACCEPTED_JSON"
  mv "$WEBHOOK_LOGFILE_PATH" "$WEBHOOK_ACCEPTED_LOGF"
  WEBHOOK_LOGFILE_PATH="$WEBHOOK_ACCEPTED_LOGF"
 
webhook_reject()  
  [ -d "$WEBHOOK_REJECTED_TODAY" ]   mkdir "$WEBHOOK_REJECTED_TODAY"
  webhook_log "Rejected: $*"
  if [ -f "$WEBHOOK_JSON_INPUT_FILE" ]; then
    mv "$WEBHOOK_JSON_INPUT_FILE" "$WEBHOOK_REJECTED_JSON"
  fi
  mv "$WEBHOOK_LOGFILE_PATH" "$WEBHOOK_REJECTED_LOGF"
  exit 0
 
webhook_deployed()  
  [ -d "$WEBHOOK_DEPLOYED_TODAY" ]   mkdir "$WEBHOOK_DEPLOYED_TODAY"
  webhook_log "Deployed: $*"
  mv "$WEBHOOK_ACCEPTED_JSON" "$WEBHOOK_DEPLOYED_JSON"
  mv "$WEBHOOK_ACCEPTED_LOGF" "$WEBHOOK_DEPLOYED_LOGF"
  WEBHOOK_LOGFILE_PATH="$WEBHOOK_DEPLOYED_LOGF"
 
webhook_troubled()  
  [ -d "$WEBHOOK_TROUBLED_TODAY" ]   mkdir "$WEBHOOK_TROUBLED_TODAY"
  webhook_log "Troubled: $*"
  mv "$WEBHOOK_ACCEPTED_JSON" "$WEBHOOK_TROUBLED_JSON"
  mv "$WEBHOOK_ACCEPTED_LOGF" "$WEBHOOK_TROUBLED_LOGF"
  WEBHOOK_LOGFILE_PATH="$WEBHOOK_TROUBLED_LOGF"
 
print_mailto()  
  _addr="$1"
  _user_email=""
  # Add the pusher email address unless it is from the domain NO_REPLY_ADDRESS,
  # which should match the value of that variable on the gitea 'app.ini' (it
  # is the domain used for emails when the user hides it).
  # shellcheck disable=SC2154
  if [ -n "$ gt_pusher_email##*@"$ NO_REPLY_ADDRESS " " ] &&
    [ -z "$ gt_pusher_email##*@* " ]; then
    _user_email="\"$gt_pusher_full_name <$gt_pusher_email>\""
  fi
  if [ "$_addr" ] && [ "$_user_email" ]; then
    echo "$_addr,$_user_email"
  elif [ "$_user_email" ]; then
    echo "$_user_email"
  elif [ "$_addr" ]; then
    echo "$_addr"
  fi
 
mail_success()  
  to_addr="$MAIL_TO_ADDR"
  if [ "$MAIL_LOGFILE" = "true" ]; then
    to_addr="$(print_mailto "$to_addr")"
  fi
  if [ "$to_addr" ]; then
    # shellcheck disable=SC2154
    subject="OK - $gt_repo_name updated to commit '$gt_after'"
    mail -s "$ MAIL_PREFIX $ subject " "$to_addr" \
      <"$WEBHOOK_LOGFILE_PATH"
  fi
 
mail_failure()  
  to_addr="$MAIL_TO_ADDR"
  if [ "$MAIL_ERRFILE" = true ]; then
    to_addr="$(print_mailto "$to_addr")"
  fi
  if [ "$to_addr" ]; then
    # shellcheck disable=SC2154
    subject="KO - $gt_repo_name update FAILED for commit '$gt_after'"
    mail -s "$ MAIL_PREFIX $ subject " "$to_addr" \
      <"$WEBHOOK_LOGFILE_PATH"
  fi
 
# ----
# MAIN
# ----
# Check directories
webhook_check_directories
# Go to the base directory
cd "$BASE_DIR"
# Check if the file exists
WEBHOOK_JSON_INPUT_FILE="$1"
if [ ! -f "$WEBHOOK_JSON_INPUT_FILE" ]; then
  webhook_reject "Input arg '$1' is not a file, aborting"
fi
# Parse the file
webhook_log "Processing file '$WEBHOOK_JSON_INPUT_FILE'"
eval "$(jq -r "$ENV_VARS_QUERY" "$WEBHOOK_JSON_INPUT_FILE")"
# Check that the repository clone url is right
# shellcheck disable=SC2154
if [ "$gt_repo_clone_url" != "$REPO_CLONE_URL" ]; then
  webhook_reject "Wrong repository: '$gt_clone_url'"
fi
# Check that the branch is the right one
# shellcheck disable=SC2154
if [ "$gt_ref" != "$REPO_REF" ]; then
  webhook_reject "Wrong repository ref: '$gt_ref'"
fi
# Accept the file
# shellcheck disable=SC2154
webhook_accept "Processing '$gt_repo_name'"
# Update the checkout
ret="0"
git fetch >>"$WEBHOOK_LOGFILE_PATH" 2>&1   ret="$?"
if [ "$ret" -ne "0" ]; then
  webhook_troubled "Repository fetch failed"
  mail_failure
fi
# shellcheck disable=SC2154
git checkout "$gt_after" >>"$WEBHOOK_LOGFILE_PATH" 2>&1   ret="$?"
if [ "$ret" -ne "0" ]; then
  webhook_troubled "Repository checkout failed"
  mail_failure
fi
# Remove the build dir if present
if [ -d "$PUBLIC_DIR" ]; then
  rm -rf "$PUBLIC_DIR"
fi
# Build site
docker compose run hugo -- >>"$WEBHOOK_LOGFILE_PATH" 2>&1   ret="$?"
# go back to the main branch
git switch main && git pull
# Fail if public dir was missing
if [ "$ret" -ne "0" ]   [ ! -d "$PUBLIC_DIR" ]; then
  webhook_troubled "Site build failed"
  mail_failure
fi
# Remove old public_html copies
webhook_log 'Removing old site versions, if present'
find $NGINX_BASE_DIR -mindepth 1 -maxdepth 1 -name 'public_html-*' -type d \
  -exec rm -rf   \; >>"$WEBHOOK_LOGFILE_PATH" 2>&1   ret="$?"
if [ "$ret" -ne "0" ]; then
  webhook_troubled "Removal of old site versions failed"
  mail_failure
fi
# Switch site directory
TS="$(date +%Y%m%d-%H%M%S)"
if [ -d "$PUBLIC_HTML_DIR" ]; then
  webhook_log "Moving '$PUBLIC_HTML_DIR' to '$PUBLIC_HTML_DIR-$TS'"
  mv "$PUBLIC_HTML_DIR" "$PUBLIC_HTML_DIR-$TS" >>"$WEBHOOK_LOGFILE_PATH" 2>&1  
    ret="$?"
fi
if [ "$ret" -eq "0" ]; then
  webhook_log "Moving '$PUBLIC_DIR' to '$PUBLIC_HTML_DIR'"
  mv "$PUBLIC_DIR" "$PUBLIC_HTML_DIR" >>"$WEBHOOK_LOGFILE_PATH" 2>&1  
    ret="$?"
fi
if [ "$ret" -ne "0" ]; then
  webhook_troubled "Site switch failed"
  mail_failure
else
  webhook_deployed "Site deployed successfully"
  mail_success
fi
# ----
# vim: ts=2:sw=2:et:ai:sts=2

22 May 2022

Russ Allbery: Review: On a Sunbeam

Review: On a Sunbeam, by Tillie Walden
Publisher: Tillie Walden
Copyright: 2016-2017
Format: Online graphic novel
Pages: 544
On a Sunbeam is a web comic that was published in installments between Fall 2016 and Spring 2017, and then later published in dead tree form. I read the on-line version, which is still available for free from its web site. It was nominated for an Eisner Award and won a ton of other awards, including the Los Angeles Times Book Prize. Mia is a new high school graduate who has taken a job with a construction crew that repairs old buildings (that are floating in space, but I'll get to that in a moment). Alma, Elliot, and Charlotte have been together for a long time; Jules is closer to Mia's age and has been with them for a year. This is not the sort of job one commutes to: they live together on a spaceship that travels to the job sites, share meals together, and are more of an extended family than a group of coworkers. It's all a bit intimidating for Mia, but Jules provides a very enthusiastic welcome and some orientation. The story of Mia's new job is interleaved with Mia's school experience from five years earlier. As a new frosh at a boarding school, Mia is obsessed with Lux, a school sport that involves building and piloting ships through a maze to capture orbs. Sent to the principal's office on the first day of school for sneaking into the Lux tower when she's supposed to be at assembly, she meets Grace, a shy girl with sparkly shoes and an unheard-of single room. Mia (a bit like Jules in the present timeline) overcomes Grace's reticence by being persistently outgoing and determinedly friendly, while trying to get on the Lux team and dealing with the typical school problems of bullies and in-groups. On a Sunbeam is science fiction in the sense that it seems to take place in space and school kids build flying ships. It is not science fiction in the sense of caring about technological extrapolation or making any scientific sense whatsoever. The buildings that Mia and the crew repair appear to be hanging in empty space, but there's gravity. No one wears any protective clothing or air masks. The spaceships look (and move) like giant tropical fish. If you need realism in your science fiction graphical novels, it's probably best not to think of this as science fiction at all, or even science fantasy despite the later appearance of some apparently magical or divine elements. That may sound surrealistic or dream-like, but On a Sunbeam isn't that either. It's a story about human relationships, found family, and diversity of personalities, all of which are realistically portrayed. The characters find their world coherent, consistent, and predictable, even if it sometimes makes no sense to the reader. On a Sunbeam is simply set in its own universe, with internal logic but without explanation or revealed rules. I kind of liked this approach? It takes some getting used to, but it's an excuse for some dramatic and beautiful backgrounds, and it's oddly freeing to have unremarked train tracks in outer space. There's no way that an explanation would have worked; if one were offered, my brain would have tried to nitpick it to the detriment of the story. There's something delightful about a setting that follows imaginary physical laws this unapologetically and without showing the author's work. I was, sadly, not as much of a fan of the art, although I am certain this will be a matter of taste. Walden mixes simple story-telling panels with sweeping vistas, free-floating domes, and strange, wild asteroids, but she uses a very limited color palette. Most panels are only a few steps away from monochrome, and the colors are chosen more for mood or orientation in the story (Mia's school days are all blue, the Staircase is orange) than for any consistent realism. There is often a lot of detail in the panels, but I found it hard to appreciate because the coloring confused my eye. I'm old enough to have been a comics reader during the revolution in digital coloring and improved printing, and I loved the subsequent dramatic improvement in vivid colors and shading. I know the coloring style here is an intentional artistic choice, but to me it felt like a throwback to the days of muddy printing on cheap paper. I have a similar complaint about the lettering: On a Sunbeam is either hand-lettered or closely simulates hand lettering, and I often found the dialogue hard to read due to inconsistent intra- and interword spacing or ambiguous letters. Here too I'm sure this was an artistic choice, but as a reader I'd much prefer a readable comics font over hand lettering. The detail in the penciling is more to my liking. I had occasional trouble telling some of the characters apart, but they're clearly drawn and emotionally expressive. The scenery is wildly imaginative and often gorgeous, which increased my frustration with the coloring. I would love to see what some of these panels would have looked like after realistic coloring with a full palette. (It's worth noting again that I read the on-line version. It's possible that the art was touched up for the print version and would have been more to my liking.) But enough about the art. The draw of On a Sunbeam for me is the story. It's not very dramatic or event-filled at first, starting as two stories of burgeoning friendships with a fairly young main character. (They are closely linked, but it's not obvious how until well into the story.) But it's the sort of story that I started reading, thought was mildly interesting, and then kept reading just one more chapter until I had somehow read the whole thing. There are some interesting twists towards the end, but it's otherwise not a very dramatic or surprising story. What it is instead is open-hearted, quiet, charming, and deeper than it looks. The characters are wildly different and can be abrasive, but they invest time and effort into understanding each other and adjusting for each other's preferences. Personal loss drives a lot of the plot, but the characters are also allowed to mature and be happy without resolving every bad thing that happened to them. These characters felt like people I would like and would want to get to know (even if Jules would be overwhelming). I enjoyed watching their lives. This reminded me a bit of a Becky Chambers novel, although it's less invested in being science fiction and sticks strictly to humans. There's a similar feeling that the relationships are the point of the story, and that nearly everyone is trying hard to be good, with differing backgrounds and differing conceptions of good. All of the characters are female or non-binary, which is left as entirely unexplained as the rest of the setting. It's that sort of book. I wouldn't say this is one of the best things I've ever read, but I found it delightful and charming, and it certainly sucked me in and kept me reading until the end. One also cannot argue with the price, although if I hadn't already read it, I would be tempted to buy a paper copy to support the author. This will not be to everyone's taste, and stay far away if you are looking for realistic science fiction, but recommended if you are in the mood for an understated queer character story full of good-hearted people. Rating: 7 out of 10

21 May 2022

Dirk Eddelbuettel: #37: Introducing r2u with 2 x 19k CRAN binaries for Ubuntu 22.04 and 20.04

One month ago I started work on a new side project which is now up and running, and deserving on an introductory blog post: r2u. It was announced in two earlier tweets (first, second) which contained the two (wicked) demos below also found at the documentation site. So what is this about? It brings full and complete CRAN installability to Ubuntu LTS, both the focal release 20.04 and the recent jammy release 22.04. It is unique in resolving all R and CRAN packages with the system package manager. So whenever you install something it is guaranteed to run as its dependencies are resolved and co-installed as needed. Equally important, no shared library will be updated or removed by the system as the possible dependency of the R package is known and declared. No other package management system for R does that as only apt on Debian or Ubuntu can and this project integrates all CRAN packages (plus 200+ BioConductor packages). It will work with any Ubuntu installation on laptop, desktop, server, cloud, container, or in WSL2 (but is limited to Intel/AMD chips, sorry Raspberry Pi or M1 laptop). It covers all of CRAN (or nearly 19k packages), all the BioConductor packages depended-upon (currently over 200), and only excludes less than a handful of CRAN packages that cannot be built.

Usage Setup instructions approaches described concisely in the repo README.md and documentation site. It consists of just five (or fewer) simple steps, and scripts are provided too for focal (20.04) and jammy (22.04).

Demos Check out these two demos (also at the r2u site):

Installing the full tidyverse in one command and 18 seconds

Installing brms and its depends in one command and 13 seconds (and show gitpod.io)

Integration via bspm The r2u setup can be used directly with apt (or dpkg or any other frontend to the package management system). Once installed apt update; apt upgrade will take care of new packages. For this to work, all CRAN packages (and all BioConductor packages depended upon) are mapped to names like r-cran-rcpp and r-bioc-s4vectors: an r prefix, the repo, and the package name, all lower-cased. That works but thanks to the wonderful bspm package by I aki car we can do much better. It connects R s own install.packages() and update.packages() to apt. So we can just say (as the demos above show) install.packages("tidyverse") or install.packages("brms") and binaries are installed via apt which is fantastic and it connects R to the system package manager. The setup is really only two lines and described at the r2u site as part of the setup.

History and Motivation Turning CRAN packages into .deb binaries is not a new idea. Albrecht Gebhardt was the first to realize this about twenty years ago (!!) and implemented it with a single Perl script. Next, Albrecht, Stefan Moeller, David Vernazobres and I built on top of this which is described in this useR! 2007 paper. A most excellent generalization and rewrite was provided by Charles Blundell in an superb Google Summer of Code contribution in 2008 which I mentored. Charles and I described it in this talk at useR! 2009. I ran that setup for a while afterwards, but it died via an internal database corruption in 2010 right when I tried to demo it at CRAN headquarters in Vienna. This peaked at, if memory serves, about 5k packages: all of CRAN at the time. Don Armstrong took it one step further in a full reimplemenation which, if I recall correctly, coverd all of CRAN and BioConductor for what may have been 8k or 9k packages. Don had a stronger system (with full RAID-5) but it also died in a crash and was never rebuilt even though he and I could have relied on Debian resources (as all these approaches focused on Debian). During that time, Michael Rutter created a variant that cleverly used an Ubuntu-only setup utilizing Launchpad. This repo is still going strong, used and relied-upon by many, and about 5k packages (per distribution) strong. At one point, a group consisting of Don, Michael, G bor Cs rdi and myself (as lead/PI) had financial support from the RConsortium ISC for a more general re-implementation , but that support was withdrawn when we did not have time to deliver. We should also note other long-standing approaches. Detlef Steuer has been using the openSUSE Build Service to provide nearly all of CRAN for openSUSE for many years. I aki car built a similar system for Fedora described in this blog post. I aki and I also have a arXiv paper describing all this.

Details Please see the the r2u site for all details on using r2u.

Acknowledgements The help of everybody who has worked on this is greatly appreciated. So a huge Thank you! to Albrecht, David, Stefan, Charles, Don, Michael, Detlef, G bor, I aki and whoever I may have omitted. Similarly, thanks to everybody working on R, CRAN, Debian, or Ubuntu it all makes for a superb system. And another big Thank you! goes to my GitHub sponsors whose continued support is greatly appreciated.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

19 May 2022

Agathe Porte: Status update, May 2022

Boing, time for another status update.
Debian work I have finally found how to make my fonts-creep2 package work on my Debian machines. The solution was to not use the TTF file that contains the Bitmap glyphs, but instead generate an OTB file, which is an OpenType format for Bitmap fonts. Creep2 font used in htop command This means that I can close the fonts-creep ITP bug altogether and rely on this fonts-creep2 package instead. Hopefully it will be reviewed and uploaded soon by a certified Debian Developer. This font is too small for daily usage, but imagine the quantity of data you could display on an auxiliary screen with poor resolution (and poor pixel density eventually). Here is a meme I created for the occasion: Hide the pain Harold meme. First: Package software and its gazillion dependencies. Second: Popcon says I'm the only user. Checks out.
Rust work I have obsoleted my most popular Rust crate, gladis. Screenshot of the Gladis Github README Indeed, the GTK folks have managed to develop a similar solution named CompositeTemplate, that is available in both gtk3-macros and gtk4-macros crates. I did not investigate from how long this has been available before I created this crate. Hopefully it did not exist before I developed it. I have learnt a lot about Rust crates development with this crate, and managed to put in place a semi-automated release flow that I will surely use in other future crates. See ya.

18 May 2022

Reproducible Builds: Supporter spotlight: Jan Nieuwenhuizen on Bootstrappable Builds, GNU Mes and GNU Guix

The Reproducible Builds project relies on several projects, supporters and sponsors for financial support, but they are also valued as ambassadors who spread the word about our project and the work that we do. This is the fourth instalment in a series featuring the projects, companies and individuals who support the Reproducible Builds project. We started this series by featuring the Civil Infrastructure Platform project and followed this up with a post about the Ford Foundation as well as a recent ones about ARDC and the Google Open Source Security Team (GOSST). Today, however, we will be talking with Jan Nieuwenhuizen about Bootstrappable Builds, GNU Mes and GNU Guix.
Chris Lamb: Hi Jan, thanks for taking the time to talk with us today. First, could you briefly tell me about yourself? Jan: Thanks for the chat; it s been a while! Well, I ve always been trying to find something new and interesting that is just asking to be created but is mostly being overlooked. That s how I came to work on GNU Guix and create GNU Mes to address the bootstrapping problem that we have in free software. It s also why I have been working on releasing Dezyne, a programming language and set of tools to specify and formally verify concurrent software systems as free software. Briefly summarised, compilers are often written in the language they are compiling. This creates a chicken-and-egg problem which leads users and distributors to rely on opaque, pre-built binaries of those compilers that they use to build newer versions of the compiler. To gain trust in our computing platforms, we need to be able to tell how each part was produced from source, and opaque binaries are a threat to user security and user freedom since they are not auditable. The goal of bootstrappability (and the bootstrappable.org project in particular) is to minimise the amount of these bootstrap binaries. Anyway, after studying Physics at Eindhoven University of Technology (TU/e), I worked for digicash.com, a startup trying to create a digital and anonymous payment system sadly, however, a traditional account-based system won. Separate to this, as there was no software (either free or proprietary) to automatically create beautiful music notation, together with Han-Wen Nienhuys, I created GNU LilyPond. Ten years ago, I took the initiative to co-found a democratic school in Eindhoven based on the principles of sociocracy. And last Christmas I finally went vegan, after being mostly vegetarian for about 20 years!
Chris: For those who have not heard of it before, what is GNU Guix? What are the key differences between Guix and other Linux distributions? Jan: GNU Guix is both a package manager and a full-fledged GNU/Linux distribution. In both forms, it provides state-of-the-art package management features such as transactional upgrades and package roll-backs, hermetical-sealed build environments, unprivileged package management as well as per-user profiles. One obvious difference is that Guix forgoes the usual Filesystem Hierarchy Standard (ie. /usr, /lib, etc.), but there are other significant differences too, such as Guix being scriptable using Guile/Scheme, as well as Guix s dedication and focus on free software.
Chris: How does GNU Guix relate to GNU Mes? Or, rather, what problem is Mes attempting to solve? Jan: GNU Mes was created to address the security concerns that arise from bootstrapping an operating system such as Guix. Even if this process entirely involves free software (i.e. the source code is, at least, available), this commonly uses large and unauditable binary blobs. Mes is a Scheme interpreter written in a simple subset of C and a C compiler written in Scheme, and it comes with a small, bootstrappable C library. Twice, the Mes bootstrap has halved the size of opaque binaries that were needed to bootstrap GNU Guix. These reductions were achieved by first replacing GNU Binutils, GNU GCC and the GNU C Library with Mes, and then replacing Unix utilities such as awk, bash, coreutils, grep sed, etc., by Gash and Gash-Utils. The final goal of Mes is to help create a full-source bootstrap for any interested UNIX-like operating system.
Chris: What is the current status of Mes? Jan: Mes supports all that is needed from R5RS and GNU Guile to run MesCC with Nyacc, the C parser written for Guile, for 32-bit x86 and ARM. The next step for Mes would be more compatible with Guile, e.g., have guile-module support and support running Gash and Gash Utils. In working to create a full-source bootstrap, I have disregarded the kernel and Guix build system for now, but otherwise, all packages should be built from source, and obviously, no binary blobs should go in. We still need a Guile binary to execute some scripts, and it will take at least another one to two years to remove that binary. I m using the 80/20 approach, cutting corners initially to get something working and useful early. Another metric would be how many architectures we have. We are quite a way with ARM, tinycc now works, but there are still problems with GCC and Glibc. RISC-V is coming, too, which could be another metric. Someone has looked into picking up NixOS this summer. How many distros do anything about reproducibility or bootstrappability? The bootstrappability community is so small that we don t need metrics, sadly. The number of bytes of binary seed is a nice metric, but running the whole thing on a full-fledged Linux system is tough to put into a metric. Also, it is worth noting that I m developing on a modern Intel machine (ie. a platform with a management engine), that s another key component that doesn t have metrics.
Chris: From your perspective as a Mes/Guix user and developer, what does reproducibility mean to you? Are there any related projects? Jan: From my perspective, I m more into the problem of bootstrapping, and reproducibility is a prerequisite for bootstrappability. Reproducibility clearly takes a lot of effort to achieve, however. It s relatively easy to install some Linux distribution and be happy, but if you look at communities that really care about security, they are investing in reproducibility and other ways of improving the security of their supply chain. Projects I believe are complementary to Guix and Mes include NixOS, Debian and on the hardware side the RISC-V platform shares many of our core principles and goals.
Chris: Well, what are these principles and goals? Jan: Reproducibility and bootstrappability often feel like the next step in the frontier of free software. If you have all the sources and you can t reproduce a binary, that just doesn t feel right anymore. We should start to desire (and demand) transparent, elegant and auditable software stacks. To a certain extent, that s always been a low-level intent since the beginning of free software, but something clearly got lost along the way. On the other hand, if you look at the NPM or Rust ecosystems, we see a world where people directly install binaries. As they are not as supportive of copyleft as the rest of the free software community, you can see that movement and people in our area are doing more as a response to that so that what we have continues to remain free, and to prevent us from falling asleep and waking up in a couple of years and see, for example, Rust in the Linux kernel and (more importantly) we require big binary blobs to use our systems. It s an excellent time to advance right now, so we should get a foothold in and ensure we don t lose any more.
Chris: What would be your ultimate reproducibility goal? And what would the key steps or milestones be to reach that? Jan: The ultimate goal would be to have a system built with open hardware, with all software on it fully bootstrapped from its source. This bootstrap path should be easy to replicate and straightforward to inspect and audit. All fully reproducible, of course! In essence, we would have solved the supply chain security problem. Our biggest challenge is ignorance. There is much unawareness about the importance of what we are doing. As it is rather technical and doesn t really affect everyday computer use, that is not surprising. This unawareness can be a great force driving us in the opposite direction. Think of Rust being allowed in the Linux kernel, or Python being required to build a recent GNU C library (glibc). Also, the fact that companies like Google/Apple still want to play us vs them , not willing to to support GPL software. Not ready yet to truly support user freedom. Take the infamous log4j bug everyone is using open source these days, but nobody wants to take responsibility and help develop or nurture the community. Not ecosystem , as that s how it s being approached right now: live and let live/die: see what happens without taking any responsibility. We are growing and we are strong and we can do a lot but if we have to work against those powers, it can become problematic. So, let s spread our great message and get more people involved!
Chris: What has been your biggest win? Jan: From a technical point of view, the full-source bootstrap has have been our biggest win. A talk by Carl Dong at the 2019 Breaking Bitcoin conference stated that connecting Jeremiah Orian s Stage0 project to Mes would be the holy grail of bootstrapping, and we recently managed to achieve just that: in other words, starting from hex0, 357-byte binary, we can now build the entire Guix system. This past year we have not made significant visible progress, however, as our funding was unfortunately not there. The Stage0 project has advanced in RISC-V. A month ago, though, I secured NLnet funding for another year, and thanks to NLnet, Ekaitz Zarraga and Timothy Sample will work on GNU Mes and the Guix bootstrap as well. Separate to this, the bootstrappable community has grown a lot from two people it was six years ago: there are now currently over 100 people in the #bootstrappable IRC channel, for example. The enlarged community is possibly an even more important win going forward.
Chris: How realistic is a 100% bootstrappable toolchain? And from someone who has been working in this area for a while, is solving Trusting Trust) actually feasible in reality? Jan: Two answers: Yes and no, it really depends on your definition. One great thing is that the whole Stage0 project can also run on the Knight virtual machine, a hardware platform that was designed, I think, in the 1970s. I believe we can and must do better than we are doing today, and that there s a lot of value in it. The core issue is not the trust; we can probably all trust each other. On the other hand, we don t want to trust each other or even ourselves. I am not, personally, going to inspect my RISC-V laptop, and other people create the hardware and do probably not want to inspect the software. The answer comes back to being conscientious and doing what is right. Inserting GCC as a binary blob is not right. I think we can do better, and that s what I d like to do. The security angle is interesting, but I don t like the paranoid part of that; I like the beauty of what we are creating together and stepwise improving on that.
Chris: Thanks for taking the time to talk to us today. If someone wanted to get in touch or learn more about GNU Guix or Mes, where might someone go? Jan: Sure! First, check out: I m also on Twitter (@janneke_gnu) and on octodon.social (@janneke@octodon.social).
Chris: Thanks for taking the time to talk to us today. Jan: No problem. :)


For more information about the Reproducible Builds project, please see our website at reproducible-builds.org. If you are interested in ensuring the ongoing security of the software that underpins our civilisation and wish to sponsor the Reproducible Builds project, please reach out to the project by emailing contact@reproducible-builds.org.

15 May 2022

Dirk Eddelbuettel: RcppArmadillo 0.11.1.1.0 on CRAN: Updates

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has syntax deliberately close to Matlab and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 978 other packages on CRAN, downloaded over 24 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 469 times according to Google Scholar. This release brings a first new upstream fix in the new release series 11.*. In particular, treatment of ill-conditioned matrices is further strengthened. We once again tested this very rigorously via three different RC releases each of which got a full reverse-dependencies run (for which results are always logged here). A minor issue with old g++ compilers was found once 11.1.0 was tagged to this upstream release is now 11.1.1. Also fixed is an OpenMP setup issue where Justin Silverman noticed that we did not propagate the -fopenmp setting correctly. The full set of changes (since the last CRAN release 0.11.0.0.0) follows.

Changes in RcppArmadillo version 0.11.1.1.0 (2022-05-15)
  • Upgraded to Armadillo release 11.1.1 (Angry Kitchen Appliance)
    • added inv_opts::no_ugly option to inv() and inv_sympd() to disallow inverses of poorly conditioned matrices
    • more efficient handling of rank-deficient matrices via inv_opts::allow_approx option in inv() and inv_sympd()
    • better detection of rank deficient matrices by solve()
    • faster handling of symmetric and diagonal matrices by cond()
  • The configure script again propagates the'found' case again, thanks to Justin Silverman for the heads-up and suggested fix (Dirk and Justin in #376 and #377 fixing #375).

Changes in RcppArmadillo version 0.11.0.1.0 (2022-04-14)
  • Upgraded to Armadillo release 11.0.1 (Creme Brulee)
    • fix miscompilation of inv() and inv_sympd() functions when using inv_opts::allow_approx and inv_opts::tiny options

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

13 May 2022

Antoine Beaupr : NVMe/SSD disk failure

Yesterday, my workstation (curie) was hung when I came in the office. After a "skinny elephant", the box rebooted, but it couldn't find the primary disk (in the BIOS). Instead, it booted on the secondary HDD drive, still running an old Fedora 27 install which somehow survived to this day, possibly because ?BTRFS is incomprehensible. Somehow, I blindly accepted the Fedora prompt asking me to upgrade to Fedora 28, not realizing that:
  1. Fedora is now at release 36, not 28
  2. major upgrades take about an hour...
  3. ... and happen at boot time, blocking the entire machine (I'll remember this next time I laugh at Windows and Mac OS users stuck on updates on boot)
  4. you can't skip more than one major upgrade
Which means that upgrading to latest would take over 4 hours. Thankfully, it's mostly automated and seems to work pretty well (which is not exactly the case for Debian). It still seems like a lot of wasted time -- it would probably be better to just reinstall the machine at this point -- and not what I had planned to do that morning at all. In any case, after waiting all that time, the machine booted (in Fedora) again, and now it could detect the SSD disk. The BIOS could find the disk too, so after I reinstalled grub (from Fedora) and fixed the boot order, it rebooted, but secureboot failed, so I turned that off (!?), and I was back in Debian. I did an emergency backup with ddrescue, from the running system which probably doesn't really work as a backup (because the filesystem is likely to be corrupt) but it was fast enough (20 minutes) and gave me some peace of mind. My offsites backup have been down for a while and since I treat my workstations as "cattle" (not "pets"), I don't have a solid recovery scenario for those situations other than "just reinstall and run Puppet", which takes a while. Now I'm wondering what the next step is: probably replace the disk anyways (the new one is bigger: 1TB instead of 500GB), or keep the new one as a hot backup somehow. Too bad I don't have a snapshotting filesystem on there... (Technically, I have LVM, but LVM snapshots are heavy and slow, and can't atomically cover the entire machine.) It's kind of scary how this thing failed: totally dropped off the bus, just not in the BIOS at all. I prefer the way spinning rust fails: clickety sounds, tons of warnings beforehand, partial recovery possible. With this new flashy junk, you just lose everything all at once. Not fun.

Antoine Beaupr : BTRFS notes

I'm not a fan of BTRFS. This page serves as a reminder of why, but also a cheat sheet to figure out basic tasks in a BTRFS environment because those are not obvious to me, even after repeatedly having to deal with them. Content warning: there might be mentions of ZFS.

Stability concerns I'm worried about BTRFS stability, which has been historically ... changing. RAID-5 and RAID-6 are still marked unstable, for example. It's kind of a lucky guess whether your current kernel will behave properly with your planned workload. For example, in Linux 4.9, RAID-1 and RAID-10 were marked as "mostly OK" with a note that says:
Needs to be able to create two copies always. Can get stuck in irreversible read-only mode if only one copy can be made.
Even as of now, RAID-1 and RAID-10 has this note:
The simple redundancy RAID levels utilize different mirrors in a way that does not achieve the maximum performance. The logic can be improved so the reads will spread over the mirrors evenly or based on device congestion.
Granted, that's not a stability concern anymore, just performance. A reviewer of a draft of this article actually claimed that BTRFS only reads from one of the drives, which hopefully is inaccurate, but goes to show how confusing all this is. There are other warnings in the Debian wiki that are quite scary. Even the legendary Arch wiki has a warning on top of their BTRFS page, still. Even if those issues are now fixed, it can be hard to tell when they were fixed. There is a changelog by feature but it explicitly warns that it doesn't know "which kernel version it is considered mature enough for production use", so it's also useless for this. It would have been much better if BTRFS was released into the world only when those bugs were being completely fixed. Or that, at least, features were announced when they were stable, not just "we merged to mainline, good luck". Even now, we get mixed messages even in the official BTRFS documentation which says "The Btrfs code base is stable" (main page) while at the same time clearly stating unstable parts in the status page (currently RAID56). There are much harsher BTRFS critics than me out there so I will stop here, but let's just say that I feel a little uncomfortable trusting server data with full RAID arrays to BTRFS. But surely, for a workstation, things should just work smoothly... Right? Well, let's see the snags I hit.

My BTRFS test setup Before I go any further, I should probably clarify how I am testing BTRFS in the first place. The reason I tried BTRFS is that I was ... let's just say "strongly encouraged" by the LWN editors to install Fedora for the terminal emulators series. That, in turn, meant the setup was done with BTRFS, because that was somewhat the default in Fedora 27 (or did I want to experiment? I don't remember, it's been too long already). So Fedora was setup on my 1TB HDD and, with encryption, the partition table looks like this:
NAME                   MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINT
sda                      8:0    0 931,5G  0 disk  
 sda1                   8:1    0   200M  0 part  /boot/efi
 sda2                   8:2    0     1G  0 part  /boot
 sda3                   8:3    0   7,8G  0 part  
   fedora_swap        253:5    0   7.8G  0 crypt [SWAP]
 sda4                   8:4    0 922,5G  0 part  
   fedora_crypt       253:4    0 922,5G  0 crypt /
(This might not entirely be accurate: I rebuilt this from the Debian side of things.) This is pretty straightforward, except for the swap partition: normally, I just treat swap like any other logical volume and create it in a logical volume. This is now just speculation, but I bet it was setup this way because "swap" support was only added in BTRFS 5.0. I fully expect BTRFS experts to yell at me now because this is an old setup and BTRFS is so much better now, but that's exactly the point here. That setup is not that old (2018? old? really?), and migrating to a new partition scheme isn't exactly practical right now. But let's move on to more practical considerations.

No builtin encryption BTRFS aims at replacing the entire mdadm, LVM, and ext4 stack with a single entity, and adding new features like deduplication, checksums and so on. Yet there is one feature it is critically missing: encryption. See, my typical stack is actually mdadm, LUKS, and then LVM and ext4. This is convenient because I have only a single volume to decrypt. If I were to use BTRFS on servers, I'd need to have one LUKS volume per-disk. For a simple RAID-1 array, that's not too bad: one extra key. But for large RAID-10 arrays, this gets really unwieldy. The obvious BTRFS alternative, ZFS, supports encryption out of the box and mixes it above the disks so you only have one passphrase to enter. The main downside of ZFS encryption is that it happens above the "pool" level so you can typically see filesystem names (and possibly snapshots, depending on how it is built), which is not the case with a more traditional stack.

Subvolumes, filesystems, and devices I find BTRFS's architecture to be utterly confusing. In the traditional LVM stack (which is itself kind of confusing if you're new to that stuff), you have those layers:
  • disks: let's say /dev/nvme0n1 and nvme1n1
  • RAID arrays with mdadm: let's say the above disks are joined in a RAID-1 array in /dev/md1
  • volume groups or VG with LVM: the above RAID device (technically a "physical volume" or PV) is assigned into a VG, let's call it vg_tbbuild05 (multiple PVs can be added to a single VG which is why there is that abstraction)
  • LVM logical volumes: out of that volume group actually "virtual partitions" or "logical volumes" are created, that is where your filesystem lives
  • filesystem, typically with ext4: that's your normal filesystem, which treats the logical volume as just another block device
A typical server setup would look like this:
NAME                      MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINT
nvme0n1                   259:0    0   1.7T  0 disk  
 nvme0n1p1               259:1    0     8M  0 part  
 nvme0n1p2               259:2    0   512M  0 part  
   md0                     9:0    0   511M  0 raid1 /boot
 nvme0n1p3               259:3    0   1.7T  0 part  
   md1                     9:1    0   1.7T  0 raid1 
     crypt_dev_md1       253:0    0   1.7T  0 crypt 
       vg_tbbuild05-root 253:1    0    30G  0 lvm   /
       vg_tbbuild05-swap 253:2    0 125.7G  0 lvm   [SWAP]
       vg_tbbuild05-srv  253:3    0   1.5T  0 lvm   /srv
 nvme0n1p4               259:4    0     1M  0 part
I stripped the other nvme1n1 disk because it's basically the same. Now, if we look at my BTRFS-enabled workstation, which doesn't even have RAID, we have the following:
  • disk: /dev/sda with, again, /dev/sda4 being where BTRFS lives
  • filesystem: fedora_crypt, which is, confusingly, kind of like a volume group. it's where everything lives. i think.
  • subvolumes: home, root, /, etc. those are actually the things that get mounted. you'd think you'd mount a filesystem, but no, you mount a subvolume. that is backwards.
It looks something like this to lsblk:
NAME                   MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINT
sda                      8:0    0 931,5G  0 disk  
 sda1                   8:1    0   200M  0 part  /boot/efi
 sda2                   8:2    0     1G  0 part  /boot
 sda3                   8:3    0   7,8G  0 part  [SWAP]
 sda4                   8:4    0 922,5G  0 part  
   fedora_crypt       253:4    0 922,5G  0 crypt /srv
Notice how we don't see all the BTRFS volumes here? Maybe it's because I'm mounting this from the Debian side, but lsblk definitely gets confused here. I frankly don't quite understand what's going on, even after repeatedly looking around the rather dismal documentation. But that's what I gather from the following commands:
root@curie:/home/anarcat# btrfs filesystem show
Label: 'fedora'  uuid: 5abb9def-c725-44ef-a45e-d72657803f37
    Total devices 1 FS bytes used 883.29GiB
    devid    1 size 922.47GiB used 916.47GiB path /dev/mapper/fedora_crypt
root@curie:/home/anarcat# btrfs subvolume list /srv
ID 257 gen 108092 top level 5 path home
ID 258 gen 108094 top level 5 path root
ID 263 gen 108020 top level 258 path root/var/lib/machines
I only got to that point through trial and error. Notice how I use an existing mountpoint to list the related subvolumes. If I try to use the filesystem path, the one that's listed in filesystem show, I fail:
root@curie:/home/anarcat# btrfs subvolume list /dev/mapper/fedora_crypt 
ERROR: not a btrfs filesystem: /dev/mapper/fedora_crypt
ERROR: can't access '/dev/mapper/fedora_crypt'
Maybe I just need to use the label? Nope:
root@curie:/home/anarcat# btrfs subvolume list fedora
ERROR: cannot access 'fedora': No such file or directory
ERROR: can't access 'fedora'
This is really confusing. I don't even know if I understand this right, and I've been staring at this all afternoon. Hopefully, the lazyweb will correct me eventually. (As an aside, why are they called "subvolumes"? If something is a "sub" of "something else", that "something else" must exist right? But no, BTRFS doesn't have "volumes", it only has "subvolumes". Go figure. Presumably the filesystem still holds "files" though, at least empirically it doesn't seem like it lost anything so far. In any case, at least I can refer to this section in the future, the next time I fumble around the btrfs commandline, as I surely will. I will possibly even update this section as I get better at it, or based on my reader's judicious feedback.

Mounting BTRFS subvolumes So how did I even get to that point? I have this in my /etc/fstab, on the Debian side of things:
UUID=5abb9def-c725-44ef-a45e-d72657803f37   /srv    btrfs  defaults 0   2
This thankfully ignores all the subvolume nonsense because it relies on the UUID. mount tells me that's actually the "root" (? /?) subvolume:
root@curie:/home/anarcat# mount   grep /srv
/dev/mapper/fedora_crypt on /srv type btrfs (rw,relatime,space_cache,subvolid=5,subvol=/)
Let's see if I can mount the other volumes I have on there. Remember that subvolume list showed I had home, root, and var/lib/machines. Let's try root:
mount -o subvol=root /dev/mapper/fedora_crypt /mnt
Interestingly, root is not the same as /, it's a different subvolume! It seems to be the Fedora root (/, really) filesystem. No idea what is happening here. I also have a home subvolume, let's mount it too, for good measure:
mount -o subvol=home /dev/mapper/fedora_crypt /mnt/home
Note that lsblk doesn't notice those two new mountpoints, and that's normal: it only lists block devices and subvolumes (rather inconveniently, I'd say) do not show up as devices:
root@curie:/home/anarcat# lsblk 
NAME                   MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINT
sda                      8:0    0 931,5G  0 disk  
 sda1                   8:1    0   200M  0 part  
 sda2                   8:2    0     1G  0 part  
 sda3                   8:3    0   7,8G  0 part  
 sda4                   8:4    0 922,5G  0 part  
   fedora_crypt       253:4    0 922,5G  0 crypt /srv
This is really, really confusing. Maybe I did something wrong in the setup. Maybe it's because I'm mounting it from outside Fedora. Either way, it just doesn't feel right.

No disk usage per volume If you want to see what's taking up space in one of those subvolumes, tough luck:
root@curie:/home/anarcat# df -h  /srv /mnt /mnt/home
Filesystem                Size  Used Avail Use% Mounted on
/dev/mapper/fedora_crypt  923G  886G   31G  97% /srv
/dev/mapper/fedora_crypt  923G  886G   31G  97% /mnt
/dev/mapper/fedora_crypt  923G  886G   31G  97% /mnt/home
(Notice, in passing, that it looks like the same filesystem is mounted in different places. In that sense, you'd expect /srv and /mnt (and /mnt/home?!) to be exactly the same, but no: they are entirely different directory structures, which I will not call "filesystems" here because everyone's head will explode in sparks of confusion.) Yes, disk space is shared (that's the Size and Avail columns, makes sense). But nope, no cookie for you: they all have the same Used columns, so you need to actually walk the entire filesystem to figure out what each disk takes. (For future reference, that's basically:
root@curie:/home/anarcat# time du -schx /mnt/home /mnt /srv
124M    /mnt/home
7.5G    /mnt
875G    /srv
883G    total
real    2m49.080s
user    0m3.664s
sys 0m19.013s
And yes, that was painfully slow.) ZFS actually has some oddities in that regard, but at least it tells me how much disk each volume (and snapshot) takes:
root@tubman:~# time df -t zfs -h
Filesystem         Size  Used Avail Use% Mounted on
rpool/ROOT/debian  3.5T  1.4G  3.5T   1% /
rpool/var/tmp      3.5T  384K  3.5T   1% /var/tmp
rpool/var/spool    3.5T  256K  3.5T   1% /var/spool
rpool/var/log      3.5T  2.0G  3.5T   1% /var/log
rpool/home/root    3.5T  2.2G  3.5T   1% /root
rpool/home         3.5T  256K  3.5T   1% /home
rpool/srv          3.5T   80G  3.5T   3% /srv
rpool/var/cache    3.5T  114M  3.5T   1% /var/cache
bpool/BOOT/debian  571M   90M  481M  16% /boot
real    0m0.003s
user    0m0.002s
sys 0m0.000s
That's 56360 times faster, by the way. But yes, that's not fair: those in the know will know there's a different command to do what df does with BTRFS filesystems, the btrfs filesystem usage command:
root@curie:/home/anarcat# time btrfs filesystem usage /srv
Overall:
    Device size:         922.47GiB
    Device allocated:        916.47GiB
    Device unallocated:        6.00GiB
    Device missing:          0.00B
    Used:            884.97GiB
    Free (estimated):         30.84GiB  (min: 27.84GiB)
    Free (statfs, df):        30.84GiB
    Data ratio:               1.00
    Metadata ratio:           2.00
    Global reserve:      512.00MiB  (used: 0.00B)
    Multiple profiles:              no
Data,single: Size:906.45GiB, Used:881.61GiB (97.26%)
   /dev/mapper/fedora_crypt  906.45GiB
Metadata,DUP: Size:5.00GiB, Used:1.68GiB (33.58%)
   /dev/mapper/fedora_crypt   10.00GiB
System,DUP: Size:8.00MiB, Used:128.00KiB (1.56%)
   /dev/mapper/fedora_crypt   16.00MiB
Unallocated:
   /dev/mapper/fedora_crypt    6.00GiB
real    0m0,004s
user    0m0,000s
sys 0m0,004s
Almost as fast as ZFS's df! Good job. But wait. That doesn't actually tell me usage per subvolume. Notice it's filesystem usage, not subvolume usage, which unhelpfully refuses to exist. That command only shows that one "filesystem" internal statistics that are pretty opaque.. You can also appreciate that it's wasting 6GB of "unallocated" disk space there: I probably did something Very Wrong and should be punished by Hacker News. I also wonder why it has 1.68GB of "metadata" used... At this point, I just really want to throw that thing out of the window and restart from scratch. I don't really feel like learning the BTRFS internals, as they seem oblique and completely bizarre to me. It feels a little like the state of PHP now: it's actually pretty solid, but built upon so many layers of cruft that I still feel it corrupts my brain every time I have to deal with it (needle or haystack first? anyone?)...

Conclusion I find BTRFS utterly confusing and I'm worried about its reliability. I think a lot of work is needed on usability and coherence before I even consider running this anywhere else than a lab, and that's really too bad, because there are really nice features in BTRFS that would greatly help my workflow. (I want to use filesystem snapshots as high-performance, high frequency backups.) So now I'm experimenting with OpenZFS. It's so much simpler, just works, and it's rock solid. After this 8 minute read, I had a good understanding of how ZFS worked. Here's the 30 seconds overview:
  • vdev: a RAID array
  • vpool: a volume group of vdevs
  • datasets: normal filesystems (or block device, if you want to use another filesystem on top of ZFS)
There's also other special volumes like caches and logs that you can (really easily, compared to LVM caching) use to tweak your setup. You might also want to look at recordsize or ashift to tweak the filesystem to fit better your workload (or deal with drives lying about their sector size, I'm looking at you Samsung), but that's it. Running ZFS on Linux currently involves building kernel modules from scratch on every host, which I think is pretty bad. But I was able to setup a ZFS-only server using this excellent documentation without too much problem. I'm hoping some day the copyright issues are resolved and we can at least ship binary packages, but the politics (e.g. convincing Debian that is the right thing to do) and the logistics (e.g. DKMS auto-builders? is that even a thing? how about signed DKMS packages? fun-fun-fun!) seem really impractical. Who knows, maybe hell will freeze over (again) and Oracle will fix the CDDL. I personally think that we should just completely ignore this problem (which wasn't even supposed to be a problem) and ship binary packages directly, but I'm a pragmatic and do not always fit well with the free software fundamentalists. All of this to say that, short term, we don't have a reliable, advanced filesystem/logical disk manager in Linux. And that's really too bad.

Next.

Previous.