Search Results: "beh"

3 June 2015

Raphaël Hertzog: My Free Software Activities in May 2015

My monthly report covers a large part of what I have been doing in the free software world. I write it for my donators (thanks to them!) but also for the wider Debian community because it can give ideas to newcomers and it s one of the best ways to find volunteers to work with me on projects that matter to me. Debian LTS This month I have been paid to work 10.25 hours on Debian LTS. In that time I did the following: Other Debian work Package Tracker. The Debian system administrators upgraded the machine hosting tracker.debian.org to jessie and I dealt with the fallout. Fixing the Apache configuration was easy but DACS also broke and I had to disable it (thus breaking login via sso.debian.org). Fortunately Enrico Zini and Martin Zobel-Helas debugged the problem and restored it. Sponsorship. I sponsored a dolibarr upload and many tryton-modules-* uploads to bring Tryton 3.6 to Debian (and granted DM rights on the newly introduced packages to Matthias Behrle who is maintaining those packages). Misc stuff. I discussed multiple feature requests with Dmitry Smirnov for dh-linktree. Packaging. I uploaded a new upstream version of cpputest. I did that twice actually because the first version had failing tests (see #784674). I also filed #784959 on blhc because I saw what looked like a false positive report for a missing hardening flag. I uploaded Django 1.8 to experimental. This is a major upstream release and shall ideally only be uploaded to sid after having reported problems on reverse dependencies. I doubt we will have the time to do this I started working on Publican 4.3.0 but the test suite fails and it s not even the fault of publican for once. It s a bug in libxml apparently. Thanks See you next month for a new summary of my activities.

No comment Liked this article? Click here. My blog is Flattr-enabled.

2 June 2015

Julien Danjou: Get back up and try again: retrying in Python

I don't often write about tools I use when for my daily software development tasks. I recently realized that I really should start to share more often my workflows and weapons of choice. One thing that I have a hard time enduring while doing Python code reviews, is people writing utility code that is not directly tied to the core of their business. This looks to me as wasted time maintaining code that should be reused from elsewhere. So today I'd like to start with retrying, a Python package that you can use to retry anything. It's OK to fail
Often in computing, you have to deal with external resources. That means accessing resources you don't control. Resources that can fail, become flapping, unreachable or unavailable. Most applications don't deal with that at all, and explode in flight, leaving a skeptical user in front of the computer. A lot of software engineers refuse to deal with failure, and don't bother handling this kind of scenario in their code. In the best case, applications usually handle simply the case where the external reached system is out of order. They log something, and inform the user that it should try again later. In this cloud computing area, we tend to design software components with service-oriented architecture in mind. That means having a lot of different services talking to each others over the network. And we all know that networks tend to fail, and distributed systems too. Writing software with failing being part of normal operation is a terrific idea. Retrying
In order to help applications with the handling of these potential failures, you need a plan. Leaving to the user the burden to "try again later" is rarely a good choice. Therefore, most of the time you want your application to retry. Retrying an action is a full strategy on its own, with a lot of options. You can retry only on certain condition, and with the number of tries based on time (e.g. every second), based on a number of tentative (e.g. retry 3 times and abort), based on the problem encountered, or even on all of those. For all of that, I use the retrying library that you can retrieve easily on PyPI. retrying provides a decorator called retry that you can use on top of any function or method in Python to make it retry in case of failure. By default, retry calls your function endlessly until it returns rather than raising an error.
import random
from retrying import retry

@retry
def pick_one():
if random.randint(0, 10) != 1:
raise Exception("1 was not picked")

This will execute the function pick_one until 1 is returned by random.randint. retry accepts a few arguments, such as the minimum and maximum delays to use, which also can be randomized. Randomizing delay is a good strategy to avoid detectable pattern or congestion. But more over, it supports exponential delay, which can be used to implement exponential backoff, a good solution for retrying tasks while really avoiding congestion. It's especially handy for background tasks.
@retry(wait_exponential_multiplier=1000, wait_exponential_max=10000)
def wait_exponential_1000():
print "Wait 2^x * 1000 milliseconds between each retry, up to 10 seconds, then 10 seconds afterwards"
raise Exception("Retry!")

You can mix that with a maximum delay, which can give you a good strategy to retry for a while, and then fail anyway:
# Stop retrying after 30 seconds anyway
>>> @retry(wait_exponential_multiplier=1000, wait_exponential_max=10000, stop_max_delay=30000)
... def wait_exponential_1000():
... print "Wait 2^x * 1000 milliseconds between each retry, up to 10 seconds, then 10 seconds afterwards"
... raise Exception("Retry!")
...
>>> wait_exponential_1000()
Wait 2^x * 1000 milliseconds between each retry, up to 10 seconds, then 10 seconds afterwards
Traceback (most recent call last):
File "<stdin>", line 1, in <module>
File "/usr/local/lib/python2.7/site-packages/retrying.py", line 49, in wrapped_f
return Retrying(*dargs, **dkw).call(f, *args, **kw)
File "/usr/local/lib/python2.7/site-packages/retrying.py", line 212, in call
raise attempt.get()
File "/usr/local/lib/python2.7/site-packages/retrying.py", line 247, in get
six.reraise(self.value[0], self.value[1], self.value[2])
File "/usr/local/lib/python2.7/site-packages/retrying.py", line 200, in call
attempt = Attempt(fn(*args, **kwargs), attempt_number, False)
File "<stdin>", line 4, in wait_exponential_1000
Exception: Retry!

A pattern I use very often, is the ability to retry only based on some exception type. You can specify a function to filter out exception you want to ignore or the one you want to use to retry.
def retry_on_ioerror(exc):
return isinstance(exc, IOError)

@retry(retry_on_exception=retry_on_ioerror)
def read_file():
with open("myfile", "r") as f:
return f.read()

retry will call the function passed as retry_on_exception with the exception raised as first argument. It's up to the function to then return a boolean indicating if a retry should be performed or not. In the example above, this will only retry to read the file if an IOError occurs; if any other exception type is raised, no retry will be performed. The same pattern can be implemented using the keyword argument retry_on_result, where you can provide a function that analyses the result and retry based on it.
def retry_if_file_empty(result):
return len(result) <= 0

@retry(retry_on_result=retry_if_file_empty)
def read_file():
with open("myfile", "r") as f:
return f.read()

This example will read the file until it stops being empty. If the file does not exist, an IOError is raised, and the default behavior which triggers retry on all exceptions kicks-in the retry is therefore performed. That's it! retry is really a good and small library that you should leverage rather than implementing your own half-baked solution!

27 May 2015

Vincent Bernat: Live patching QEMU for VENOM mitigation

CVE-2015-3456, also known as VENOM, is a security vulnerability in QEMU virtual floppy controller:
The Floppy Disk Controller (FDC) in QEMU, as used in Xen [ ] and KVM, allows local guest users to cause a denial of service (out-of-bounds write and guest crash) or possibly execute arbitrary code via the FD_CMD_READ_ID, FD_CMD_DRIVE_SPECIFICATION_COMMAND, or other unspecified commands.
Even when QEMU has been configured with no floppy drive, the floppy controller code is still active. The vulnerability is easy to test1:
#define FDC_IOPORT 0x3f5
#define FD_CMD_READ_ID 0x0a
int main()  
    ioperm(FDC_IOPORT, 1, 1);
    outb(FD_CMD_READ_ID, FDC_IOPORT);
    for (size_t i = 0;; i++)
        outb(0x42, FDC_IOPORT);
    return 0;
 
Once the fix installed, all processes still have to be restarted for the upgrade to be effective. It is possible to minimize the downtime by leveraging virsh save. Another possibility would be to patch the running processes. The Linux kernel attracted a lot of interest in this area, with solutions like Ksplice (mostly killed by Oracle), kGraft (by Red Hat) and kpatch (by Suse) and the inclusion of a common framework in the kernel. The userspace has far less out-of-the-box solutions2. I present here a simple and self-contained way to patch a running QEMU to remove the vulnerability without requiring any sensible downtime. Here is a short demonstration:

Proof of concept First, let s find a workaround that would be simple to implement through live patching: while modifying running code text is possible, it is easier to modify a single variable.

Concept Looking at the code of the floppy controller and the patch, we can avoid the vulnerability by not accepting any command on the FIFO port. Each request would be answered by Invalid command (0x80) and a user won t be able to push more bytes to the FIFO until the answer is read and the FIFO queue reset. Of course, the floppy controller would be rendered useless in this state. But who cares? The list of commands accepted by the controller on the FIFO port is contained in the handlers[] array:
static const struct  
    uint8_t value;
    uint8_t mask;
    const char* name;
    int parameters;
    void (*handler)(FDCtrl *fdctrl, int direction);
    int direction;
  handlers[] =  
      FD_CMD_READ, 0x1f, "READ", 8, fdctrl_start_transfer, FD_DIR_READ  ,
      FD_CMD_WRITE, 0x3f, "WRITE", 8, fdctrl_start_transfer, FD_DIR_WRITE  ,
    /* [...] */
      0, 0, "unknown", 0, fdctrl_unimplemented  , /* default handler */
 ;
To avoid browsing the array each time a command is received, another array is used to map each command to the appropriate handler:
/* Associate command to an index in the 'handlers' array */
static uint8_t command_to_handler[256];
static void fdctrl_realize_common(FDCtrl *fdctrl, Error **errp)
 
    int i, j;
    static int command_tables_inited = 0;
    /* Fill 'command_to_handler' lookup table */
    if (!command_tables_inited)  
        command_tables_inited = 1;
        for (i = ARRAY_SIZE(handlers) - 1; i >= 0; i--)  
            for (j = 0; j < sizeof(command_to_handler); j++)  
                if ((j & handlers[i].mask) == handlers[i].value)  
                    command_to_handler[j] = i;


    /* [...] */
 
Our workaround is to modify the command_to_handler[] array to map all commands to the fdctrl_unimplemented() handler (the last one in the handlers[] array).

Testing with gdb To check if the workaround works as expected, we test it with gdb. Unless you have compiled QEMU yourself, you need to install a package with debug symbols. Unfortunately, on Debian, they are not available, yet3. On Ubuntu, you can install the qemu-system-x86-dbgsym package after enabling the appropriate repositories. The following function for gdb maps every command to the unimplemented handler:
define patch
  set $handler = sizeof(handlers)/sizeof(*handlers)-1
  set $i = 0
  while ($i < 256)
   set variable command_to_handler[$i++] = $handler
  end
  printf "Done!\n"
end
Attach to the vulnerable process (with attach), call the function (with patch) and detach of the process (with detach). You can check that the exploit is not working anymore. This could be easily automated.

Limitations Using gdb has two main limitations:
  1. It needs to be installed on each host to be patched.
  2. The debug packages need to be installed as well. Moreover, it can be difficult to fetch previous versions of those packages.

Writing a custom patcher To overcome those limitations, we can write a customer patcher using the ptrace() system call without relying on debug symbols being present.

Finding the right memory spot Before being able to modify the command_to_handler[] array, we need to know its location. The first clue is given by the symbol table. To query it, use readelf -s:
$ readelf -s /usr/lib/debug/.build-id/09/95121eb46e2a4c13747ac2bad982829365c694.debug   \
>   sed -n -e 1,3p -e /command_to_handler/p
Symbol table '.symtab' contains 27066 entries:
   Num:    Value          Size Type    Bind   Vis      Ndx Name
  8485: 00000000009f9d00   256 OBJECT  LOCAL  DEFAULT   26 command_to_handler
This table is usually stripped out of the executable to save space, like shown below:
$ file -b /usr/bin/qemu-system-x86_64   tr , \\n
ELF 64-bit LSB shared object
 x86-64
 version 1 (SYSV)
 dynamically linked
 interpreter /lib64/ld-linux-x86-64.so.2
 for GNU/Linux 2.6.32
 BuildID[sha1]=0995121eb46e2a4c13747ac2bad982829365c694
 stripped
If your distribution provides a debug package, the debug symbols are installed in /usr/lib/debug. Most modern distributions are now relying on the build ID4 to map an executable to its debugging symbols, like the example above. Without a debug package, you need to recompile the existing package without stripping debug symbols in a clean environment5. On Debian, this can be done by setting the DEB_BUILD_OPTIONS environment variable to nostrip. We have now two possible cases:
  • the easy one, and
  • the hard one.

The easy case On x86, here is the standard layout of a regular Linux process in memory6: Memory layout of a regular process on x86 The random gaps (ASLR) are here to prevent an attacker from reliably jumping to a particular exploited function in memory. On x86-64, the layout is quite similar. The important point is that the base address of the executable is fixed. The memory mapping of a process is also available through /proc/PID/maps. Here is a shortened and annotated example on x86-64:
$ cat /proc/3609/maps
00400000-00401000         r-xp 00000000 fd:04 483  not-qemu [text segment]
00601000-00602000         r--p 00001000 fd:04 483  not-qemu [data segment]
00602000-00603000         rw-p 00002000 fd:04 483  not-qemu [BSS segment]
[random gap]
02419000-0293d000         rw-p 00000000 00:00 0    [heap]
[random gap]
7f0835543000-7f08356e2000 r-xp 00000000 fd:01 9319 /lib/x86_64-linux-gnu/libc-2.19.so
7f08356e2000-7f08358e2000 ---p 0019f000 fd:01 9319 /lib/x86_64-linux-gnu/libc-2.19.so
7f08358e2000-7f08358e6000 r--p 0019f000 fd:01 9319 /lib/x86_64-linux-gnu/libc-2.19.so
7f08358e6000-7f08358e8000 rw-p 001a3000 fd:01 9319 /lib/x86_64-linux-gnu/libc-2.19.so
7f08358e8000-7f08358ec000 rw-p 00000000 00:00 0
7f08358ec000-7f083590c000 r-xp 00000000 fd:01 5138 /lib/x86_64-linux-gnu/ld-2.19.so
7f0835aca000-7f0835acd000 rw-p 00000000 00:00 0
7f0835b08000-7f0835b0c000 rw-p 00000000 00:00 0
7f0835b0c000-7f0835b0d000 r--p 00020000 fd:01 5138 /lib/x86_64-linux-gnu/ld-2.19.so
7f0835b0d000-7f0835b0e000 rw-p 00021000 fd:01 5138 /lib/x86_64-linux-gnu/ld-2.19.so
7f0835b0e000-7f0835b0f000 rw-p 00000000 00:00 0
[random gap]
7ffdb0f85000-7ffdb0fa6000 rw-p 00000000 00:00 0    [stack]
With a regular executable, the value given in the symbol table is an absolute memory address:
$ readelf -s not-qemu   \
>   sed -n -e 1,3p -e /command_to_handler/p
Symbol table '.dynsym' contains 9 entries:
   Num:    Value          Size Type    Bind   Vis      Ndx Name
    47: 0000000000602080   256 OBJECT  LOCAL  DEFAULT   25 command_to_handler
So, the address of command_to_handler[], in the above example, is just 0x602080.

The hard case To enhance security, it is possible to load some executables at a random base address, just like a library. Such an executable is called a Position Independent Executable (PIE). An attacker won t be able to rely on a fixed address to find some helpful function. Here is the new memory layout: Memory layout of a PIE process on x86 With a PIE process, the value in the symbol table is now an offset from the base address.
$ readelf -s not-qemu-pie   sed -n -e 1,3p -e /command_to_handler/p
Symbol table '.dynsym' contains 17 entries:
   Num:    Value          Size Type    Bind   Vis      Ndx Name
    47: 0000000000202080   256 OBJECT  LOCAL  DEFAULT   25 command_to_handler
If we look at /proc/PID/maps, we can figure out where the array is located in memory:
$ cat /proc/12593/maps
7f6c13565000-7f6c13704000 r-xp 00000000 fd:01 9319  /lib/x86_64-linux-gnu/libc-2.19.so
7f6c13704000-7f6c13904000 ---p 0019f000 fd:01 9319  /lib/x86_64-linux-gnu/libc-2.19.so
7f6c13904000-7f6c13908000 r--p 0019f000 fd:01 9319  /lib/x86_64-linux-gnu/libc-2.19.so
7f6c13908000-7f6c1390a000 rw-p 001a3000 fd:01 9319  /lib/x86_64-linux-gnu/libc-2.19.so
7f6c1390a000-7f6c1390e000 rw-p 00000000 00:00 0
7f6c1390e000-7f6c1392e000 r-xp 00000000 fd:01 5138  /lib/x86_64-linux-gnu/ld-2.19.so
7f6c13b2e000-7f6c13b2f000 r--p 00020000 fd:01 5138  /lib/x86_64-linux-gnu/ld-2.19.so
7f6c13b2f000-7f6c13b30000 rw-p 00021000 fd:01 5138  /lib/x86_64-linux-gnu/ld-2.19.so
7f6c13b30000-7f6c13b31000 rw-p 00000000 00:00 0
7f6c13b31000-7f6c13b33000 r-xp 00000000 fd:04 4594  not-qemu-pie [text segment]
7f6c13cf0000-7f6c13cf3000 rw-p 00000000 00:00 0
7f6c13d2e000-7f6c13d32000 rw-p 00000000 00:00 0
7f6c13d32000-7f6c13d33000 r--p 00001000 fd:04 4594  not-qemu-pie [data segment]
7f6c13d33000-7f6c13d34000 rw-p 00002000 fd:04 4594  not-qemu-pie [BSS segment]
[random gap]
7f6c15c46000-7f6c15c67000 rw-p 00000000 00:00 0     [heap]
[random gap]
7ffe823b0000-7ffe823d1000 rw-p 00000000 00:00 0     [stack]
The base address is 0x7f6c13b31000, the offset is 0x202080 and therefore, the location of the array is 0x7f6c13d33080. We can check with gdb:
$ print &command_to_handler
$1 = (uint8_t (*)[256]) 0x7f6c13d33080 <command_to_handler>

Patching a memory spot Once we know the location of the command_to_handler[] array in memory, patching it is quite straightforward. First, we start tracing the target process:
/* Attach to the running process */
static int
patch_attach(pid_t pid)
 
    int status;
    printf("[.] Attaching to PID %d...\n", pid);
    if (ptrace(PTRACE_ATTACH, pid, NULL, NULL) == -1)  
        fprintf(stderr, "[!] Unable to attach to PID %d: %m\n", pid);
        return -1;
     
    if (waitpid(pid, &status, 0) == -1)  
        fprintf(stderr, "[!] Error while attaching to PID %d: %m\n", pid);
        return -1;
     
    assert(WIFSTOPPED(status)); /* Tracee may have died */
    if (ptrace(PTRACE_GETSIGINFO, pid, NULL, &si) == -1)  
        fprintf(stderr, "[!] Unable to read siginfo for PID %d: %m\n", pid);
        return -1;
     
    assert(si.si_signo == SIGSTOP); /* Other signals may have been received */
    printf("[*] Successfully attached to PID %d\n", pid);
    return 0;
 
Then, we retrieve the command_to_handler[] array, modify it and put it back in memory7.
static int
patch_doit(pid_t pid, unsigned char *target)
 
    int ret = -1;
    unsigned char *command_to_handler = NULL;
    size_t i;
    /* Get the table */
    printf("[.] Retrieving command_to_handler table...\n");
    command_to_handler = ptrace_read(pid,
                                     target,
                                     QEMU_COMMAND_TO_HANDLER_SIZE);
    if (command_to_handler == NULL)  
        fprintf(stderr, "[!] Unable to read command_to_handler table: %m\n");
        goto out;
     
    /* Check if the table has already been patched. */
    /* [...] */
    /* Patch it */
    printf("[.] Patching QEMU...\n");
    for (i = 0; i < QEMU_COMMAND_TO_HANDLER_SIZE; i++)  
        command_to_handler[i] = QEMU_NOT_IMPLEMENTED_HANDLER;
     
    if (ptrace_write(pid, target, command_to_handler,
           QEMU_COMMAND_TO_HANDLER_SIZE) == -1)  
        fprintf(stderr, "[!] Unable to patch command_to_handler table: %m\n");
        goto out;
     
    printf("[*] QEMU successfully patched!\n");
    ret = 0;
out:
    free(command_to_handler);
    return ret;
 
Since ptrace() only allows to read or write a word at a time, ptrace_read() and ptrace_write() are wrappers to read or write arbitrary large chunks of memory8. Here is the code for ptrace_read():
/* Read memory of the given process */
static void *
ptrace_read(pid_t pid, void *address, size_t size)
 
    /* Allocate the buffer */
    uword_t *buffer = malloc((size/sizeof(uword_t) + 1)*sizeof(uword_t));
    if (!buffer) return NULL;
    /* Read word by word */
    size_t readsz = 0;
    do  
        errno = 0;
        if ((buffer[readsz/sizeof(uword_t)] =
                ptrace(PTRACE_PEEKTEXT, pid,
                       (unsigned char*)address + readsz,
                       0)) && errno)  
            fprintf(stderr, "[!] Unable to peek one word at address %p: %m\n",
                    (unsigned char *)address + readsz);
            free(buffer);
            return NULL;
         
        readsz += sizeof(uword_t);
      while (readsz < size);
    return (unsigned char *)buffer;
 

Putting the pieces together The patcher is provided with the following information:
  • the PID of the process to be patched,
  • the command_to_handler[] offset from the symbol table, and
  • the build ID of the executable file used to get this offset (as a safety measure).
The main steps are:
  1. Attach to the process with ptrace().
  2. Get the executable name from /proc/PID/exe.
  3. Parse /proc/PID/maps to find the address of the text segment (it s the first one).
  4. Do some sanity checks:
    • check there is a ELF header at this location (4-byte magic number),
    • check the executable type (ET_EXEC for regular executables, ET_DYN for PIE), and
    • get the build ID and compare with the expected one.
  5. From the base address and the provided offset, compute the location of the command_to_handler[] array.
  6. Patch it.
You can find the complete patcher on GitHub.
$ ./patch --build-id 0995121eb46e2a4c13747ac2bad982829365c694 \
>         --offset 9f9d00 \
>         --pid 16833
[.] Attaching to PID 16833...
[*] Successfully attached to PID 16833
[*] Executable name is /usr/bin/qemu-system-x86_64
[*] Base address is 0x7f7eea912000
[*] Both build IDs match
[.] Retrieving command_to_handler table...
[.] Patching QEMU...
[*] QEMU successfully patched!

  1. The complete code for this test is on GitHub.
  2. An interesting project seems to be Katana. But there are also some insightful hacking papers on the subject.
  3. Some packages come with a -dbg package with debug symbols, some others don t. Fortunately, a proposal to automatically produce debugging symbols for everything is near completion.
  4. The Fedora Wiki contains the rationale behind the build ID.
  5. If the build is incorrectly reproduced, the build ID won t match. The information provided by the debug symbols may or may not be correct. Debian currently has a reproducible builds effort to ensure that each package can be reproduced.
  6. Anatomy of a program in memory is a great blog post explaining in more details how a program lives in memory.
  7. Being an uninitialized static variable, the variable is in the BSS section. This section is mapped to a writable memory segment. If it wasn t the case, with Linux, the ptrace() system call is still allowed to write. Linux will copy the page and mark it as private.
  8. With Linux 3.2 or later, process_vm_readv() and process_vm_writev() can be used to transfer data from/to a remote process without using ptrace() at all. However, ptrace() would still be needed to reliably stop the main thread.

24 May 2015

Russ Allbery: Catch-up haul

As always, even though I've not been posting much, I'm still buying books. This is a catch-up post listing a variety of random purchases. Katherine Addison The Goblin Emperor (sff)
Milton Davis From Here to Timbuktu (sff)
Mark Forster How to Make Your Dreams Come True (non-fiction)
Angela Highland Valor of the Healer (sff)
Marko Kloos Terms of Enlistment (sff)
Angela Korra'ti Faerie Blood (sff)
Cixin Liu The Three-Body Problem (sff)
Emily St. John Mandel Station Eleven (sff)
Sydney Padua The Thrilling Adventures of Lovelace and Babbage (graphic novel)
Melissa Scott & Jo Graham The Order of the Air Omnibus (sff)
Andy Weir The Martian (sff) Huh, for some reason I thought I'd bought more than that. I picked up the rest of the Hugo nominees that aren't part of a slate, and as it happens have already read all the non-slate nominees at the time of this writing (although I'm horribly behind on reviews). I also picked up the first book of Marko Kloos's series, since he did the right thing and withdrew from the Hugos once it became clear what nonsense was going on this year. The rest is a pretty random variety of on-line recommendations, books by people who made sense on the Internet, and books by authors I like.

23 May 2015

Eddy Petri&#537;or: Linksys NSLU2 adventures into the NetBSD land passed through JTAG highlands - part 1

About 2 months ago I set a goal to run some kind of BSD on the spare Linksys NSLU2 I had. This was driven mostly by curiosity, after listening to a few BSDNow episodes and becoming a regular listener, but it was a really interesting experience (it was also somewhat frustrating, mostly due to lacking documentation or proprietary code).

Looking for documentation on how to install any BSD flavour on the Linksys NSLU2, I have found what appears to be some too-incomplete-to-be-useful-for-a-BSD-newbie information about installing FreeBSD, no information about OpenBSD and some very detailed information about NetBSD on the Linksys NSLU2.

I was very impressed by the NetBSD build.sh script which can be used to cross-compile the entire NetBSD system - to do that, it also builds the appropriate toolchain - NetBSD kernel and the base system, even when ran on a Linux host. Having some experience with cross compilation for GNU/Linux embedded systems I can honestly say this is immensely impressive, well done NetBSD!

Gone were a few failed attempts to properly follow the instruction and lots of hours of (re)building, but then I had the kernel and the sets (the NetBSD system is split into several parts which are grouped by functionality, these are the sets), so I was in the position to have to set things up to be able to net boot - kernel loading via TFTP and rootfs on NFS.

But it wouldn't be challenging if the instructions were followed to the letter, so the first thing I wanted to change was that I didn't want to run dhcpd just to pass the DHCP boot configuration to the NSLU2, that seemed like a waste of resources since I already had dnsmasq running.

After some effort and struggling with missing documentation, I managed to use dnsmasq to pass DHCP boot parameters to the slug, but also use it as TFTP server - after some time I documented this for future reference on my blog and expect to refer to it in the future.

Setting up NFS wasn't a problem, but, when trying to boot, I found that I managed to misread at least 3 or 4 times some of the NSLU2 related information on the NetBSD wiki. To be able to debug what was happening I concluded the slug should have a serial console attached to it, which helped a lot.

Still the result was that I wasn't able to boot the trunk version of the NetBSD code on my NSLU2.

Long story short, with the help of some people from the #netbsd IRC channel on Freenode and from the port-arm NetBSD mailing list I found out that I might have a better chance with specific older versions. In practice what really worked was the code from the netbsd_6_1 branch.

Discussions on the port-arm mailing list, some digging into the (recently found) PR (problem reports), and a successful execution of the trunk kernel (at the time, version 7.99.4) together with 6.1.5 userspace lead me to the conclusion the NetBSD userspace for armbe was broken in the trunk branch.

And since I concluded this would be a good occasion to learn a few details about NetBSD, I set out to git bisect through the trunk history to identify when this happened. But that meant being able to easily load kernels and run them from TFTP, which was not how the RedBoot bootloader flashed into the slug behaves by default.

Be default, the RedBoot bootloader flashed into the NSLU2 waits for 2 seconds for a manual interaction (it waits for a ^C) on the serial console or on the telnet RedBoot prompt, then, if no such event happens, it copies the Linux image it has in flash starting with adress 0x50060000 into RAM at address 0x01d00000 (after stripping the Sercomm header) and then executes the copied code from RAM.

Of course, this is not a very handy way to try to boot things from TFTP, so my first idea to overcome this limitation was to use a second stage bootloader which would do the loading via TFTP of the NetBSD kernel, then execute it from RAM. Flashing this second stage bootloader instead of the Linux kernel at 0x50060000 would make sure that no manual intervention except power on would be necessary when a new kernel+userspace pair is ready to be tested.

Another advantage was that I would not risk bricking the NSLU2 since I would not be changing RedBoot, the original bootloader.

I knew Apex was used as the second stage bootloader in Debian, so I started configuring my own version of the APEX bootloader to make it work for the netbsd-nfs.bin image to be loaded via TFTP.

My first disappointment was that Apex was did not support receiving the boot parameters via DHCP, but only via RARP (it was clear it was less tested with BOOTP or DHCP) and TFTP was documented in the code as being problematic. That meant that I would have to hard code the boot configuration or configure RARP, but that wasn't too bad.

Later I found out that I wasted time on that avenue because the network driver in Apex was some Intel code (NPE Access Library) which can't be freely distributed, but could have been downloaded from Intel's site back in 2008-2009. The bad news was that current versions did not work at all with the old patch work that was done in Apex to allow for the driver made for Linux to compile in a world of its own so it could be incorporated in Apex.

I was stuck and the only options I were:
  1. Fight with the available Intel code and make it compile in Apex
  2. Incorporate the NPE driver from NetBSD into a rump kernel which will be included in Apex, since I knew the NetBSD driver only needed a very easily obtainable binary blob, instead of the entire driver as was in Apex before
  3. Hack together an Apex version that simulates the typing of the necessary commands to load the netbsd-nfs.bin image inside RedBoot, or in other words, call from Apex the RedBoot functions necessary to load from TFTP and execute NetBSD.
Option 1 did not look that appealing after looking into the horrible Intel build system and its endless dependencies into a specific Linux kernel version.

Option 2 was more appealing, but since I didn't knew NetBSD and only tried once to build and run a NetBSD rump kernel, it seemed like a doable project only for an experienced NetBSD developer or at least an experienced NetBSD user, which I was not.

So I was left with option 3, which meant I had to do some reverse engineering of the code, because, although RedBoot is GPL, Linksys did not publish the source from which the running RedBoot was built from.


(continues here)

19 May 2015

Thorsten Alteholz: alpine and UTF-8 and Debian lists

This is a note for my future self: When writing an email with only charset=US-ASCII , alpine creates an email with:

Content-Type: TEXT/PLAIN; format=flowed; charset=US-ASCII

and everything is fine. In case of UTF-8 characters inside the text, alpine creates something like:

Content-Type: MULTIPART/MIXED; BOUNDARY="705298698-1667814148-1432049085=:28313"

and the only available part contains:

Content-Type: TEXT/PLAIN; format=flowed; charset=UTF-8
Content-Transfer-Encoding: 8BIT
Google tells me that the reason for this is:
Alpine uses a single part MULTIPART/MIXED to apply a protection wrapper around QUOTED-PRINTABLE and BASE64 content to prevent it from being corrupted by various mail delivery systems that append little (typically advertising) things at the end of the message.
Ok, this behavior might come from bad experiences and it seems to work most of the time. Unfortunately if one sends a signed email to a Debian list that checks whether the signature is valid (like for example debian-lts-announce), such an email will be rejected with:
Failed to understand the email or find a signature: UDFormatError:
Cannot handle multipart messages not of type multipart/signed
*sigh*

13 May 2015

Lucas Nussbaum: systemd: Type=simple and avoiding forking considered harmful?

(This came up in a discussion on debian-user-french@l.d.o) When converting from sysvinit scripts to systemd init files, the default practice seems to be to start services without forking, and to use Type=simple in the service description. What Type=simple does is, well, simple. from systemd.service(5):

If set to simple (the default value if neither Type= nor BusName= are specified), it is expected that the process configured with ExecStart= is the main process of the service. In this mode, if the process offers functionality to other processes on the system, its communication channels should be installed before the daemon is started up (e.g. sockets set up by systemd, via socket activation), as systemd will immediately proceed starting follow-up units. In other words, systemd just runs the command described in ExecStart=, and it s done: it considers the service is started. Unfortunately, this causes a regression compared to the sysvinit behaviour, as described in #778913: if there s a configuration error, the process will start and exit almost immediately. But from systemd s point-of-view, the service will have been started successfully, and the error only shows in the logs:

root@debian:~# systemctl start ssh
root@debian:~# echo $?
0
root@debian:~# systemctl status ssh
  ssh.service - OpenBSD Secure Shell server
 Loaded: loaded (/lib/systemd/system/ssh.service; enabled)
 Active: failed (Result: start-limit) since mer. 2015-05-13 09:32:16 CEST; 7s ago
 Process: 2522 ExecStart=/usr/sbin/sshd -D $SSHD_OPTS (code=exited, status=255)
 Main PID: 2522 (code=exited, status=255)
mai 13 09:32:16 debian systemd[1]: ssh.service: main process exited, code=exited, status=255/n/a
mai 13 09:32:16 debian systemd[1]: Unit ssh.service entered failed state.
mai 13 09:32:16 debian systemd[1]: ssh.service start request repeated too quickly, refusing to start.
mai 13 09:32:16 debian systemd[1]: Failed to start OpenBSD Secure Shell server.
mai 13 09:32:16 debian systemd[1]: Unit ssh.service entered failed state.
With sysvinit, this error is detected before the fork(), so it shows during startup:
root@debian:~# service ssh start
 [....] Starting OpenBSD Secure Shell server: sshd/etc/ssh/sshd_config: line 4: Bad configuration option: blah
 /etc/ssh/sshd_config: terminating, 1 bad configuration options
 failed!
 root@debian:~#
It s not trivial to fix that. The implicit behaviour of sysvinit is that fork() sort-of signals the end of service initialization. The systemd way to do that would be to use Type=notify, and have the service signals that it s ready using systemd-notify(1) or sd_notify(3) (or to use socket activation, but that s another story). However that requires changes to the service. Returning to the sysvinit behaviour by using Type=forking would help, but is not really a solution: but what if some of the initialization happens *after* the fork? This is actually the case for sshd, where the socket is bound after the fork (see strace -f -e trace=process,network /usr/sbin/sshd), so if another process is listening on port 22 and preventing sshd to successfully start, it would not be detected. I wonder if systemd shouldn t do more to detect problems during services initialization, as the transition to proper notification using sd_notify will likely take some time. A possibility would be to wait 100 or 200ms after the start to ensure that the service doesn t exit almost immediately. But that s not really a solution for several obvious reasons. A more hackish, but still less dirty solution could be to poll the state of processes inside the cgroup, and assume that the service is started only when all processes are sleeping. Still, that wouldn t be entirely satisfying

11 May 2015

Craig Small: procps using GitLab CI

procps-ciThe procps project for a few years has been hosted at Gitorious. With the announcement that Gitorious has been acquired by GitLab and that all repositories need to move there, procps moved along to GitLab. At first I thought it would just be a like for like thing, but then I noticed that GitLab has this GitLab CI feature and had to try it out. CI here stands for Continuous Integration and is a way of automatically testing your program builds using a bunch of test scripts. procps already has a set of tests, with some a level of coverage that has room for improvement, so it was a good candidate to use for CI. The way GitLab works is they have a central control point that is linked to the git repo and you create runners, which are the systems that actually compile the programs and run the tests. The runners then feed back their results and GitLab CI shows it all in pretty red or green. The first problem was building this runner. Most of the documentation assumes you are building testing for Ruby. procps is built using C with the test scripts in TCL, so there was going to be some need to make some adjustments. I chose to use docker containers so that there was at least some isolation between the runners and the base system. I soon found the docker container I used (ruby:2.6 as suggested by GitLab) didn t have autopoint which mean autogen.sh failed so I had no configure script so no joy there. Now my second problem was I had never used docker before and beyond that it was some sort of container thing so like virtual machines lite, I didn t know much about it. The docker docs are very good and soon I had built my own custom docker image that had all the programs I need to compile and test procps. It s basically a cut-down Debian image with a few things like gettext-bin and dejagnu added in. Docker is not a full system With that all behind me and a few oh I need that too (don t forget you need git) moments we had a working CI runner. This was a Good Thing. You then find that your assumptions for your test cases may not always be correct. This is especially noticeable when testing something like procps which needs to work of the proc filesystem. A good example is, what uses session ID 1? Generally its init or systemd, but in Docker this is what everything runs as. A test case which assumes things about SID=1 will fail, as it did. This probably won t be a problem for testing a lot of normal programs that don t need to dig a deep into the host system as procps does, but it is something to remember. The docker environment looks a lot like a real system from the inside, but there are differences, so the lesson here is to write better tests (or fix the ones that failed, like I did). The runner and polling Now, there needs to be communication between the CI website and the runner, so the runner knows there is something for it to do. The gitlab runner has this setup rather well, except the runner is rather aggressive about its polling, hitting the website every 3 seconds. For someone on some crummy Australian Internet with low speeds and download quotas, this can get expensive in network resources. As there is on average an update once a week or so these seems rather excessive. My fix is pretty manual, actually its totally manual. I stop the daemon, then if I notice there are pending jobs I start the daemon, let it do its thing, then shut it down again. This is certainly not an optimal solution but works for now. I will look into doing something more clever later, possibly with webhooks.

Zlatan Todori : Reboot to roots

I am working in software development field for more then 5 years. During that period I came across of other developers which vast majority can be described as terrible people. That is what sets probably difference between hacker mind and average software engineer. People tend to think if they have position of software developer they are god-like and should be treated like that. Hackers know who they are and tend to be Socrates-wise "I know that I know nothing". As student of mechanical engineering (majoring in mechatronics) I didn't have much of programming so naturally I had some personal difficulties to grasp software field but once I got in I stopped almost totally doing my student duties as it didn't cross path with my love towards hacking. And now after that many years in software field, in which I mostly worked as freelancer for other people and companies (where it wasn't unusual that I got hired personally by a guy who couldn't or didn't know how to finish his work, I hand the code which he would present as his own work, but I don't mind as I needed the money to get on) and my work ended as proprietary - I am just fed up with all this nonsense. Someone would think what is problem there - well for me it is, as being part of Debian and wider Free software ecosystem I know proprietary software is not fostering better society in all together so it made me a bit unhappy about it. The thing that actually is really annoying me are asshole so-called software engineers and the most - bad behavior towards users. Users should be treated as supporters of your software and if proprietary company treats their users as shit then it's obvious that they don't care for the users but rather for the money and only money. Proprietary isn't here the only bad thing, open source community has it share of terrible responses - which comes naturally if you take the sheer amount of people in open source. I for instance was called on Debian IRC a peasant and even I sheep in my early days - but Debian as all communities has its bad seeds and sometimes even non-Debianities trolls hop on our channels. I didn't let myself put down because I personally got the chance to meet many of them and they change the flow of my life at that point. I am unhappy at the current state of things worldwide and personally but I have now made a decision that I am shifting towards being technical customer support engineer or for me better named as Happiness Hero. Why, one would ask because as software engineer you would make more? Well, firstly I don't care that much about money (or to be even more precise, as capitalism has made a sick money-grabbing society, you can never pay me enough as I am more worth then entire capitalistic system so in the end I don't care that much how I am paid) and secondly happiness hero can earn more then software engineer which latest #talkpay hashtag on Twitter showed. I have made IMHO many good pieces of code that will never be contributed as mine, but I achieved no happiness and rather achieved few months ago a rather bad burnout. My shift towards happiness hero should look like this - I am pretty well prepared technically for that position, I have experience with helping users and in general with people and I tend to be pretty good at that (but that we would need to ask them) and with part that I enjoy helping people to debug their technical problem so they can spend more time on others things (read family, creativity, hobbies) is something I believe will put me well into position to achieve happiness so I can create for myself time to finish damn faculty (where TBH professors showed that they can be one of the worst enemies of their students - and I am highly doubting in this generic way of schooling for centuries) and if I get some decent paycheck with this capitalistic system I will have a chance to sponsor a poor family that has child talented in artistic field - or to say SHARE something material for cultural and emotional gain. Take that capitalism! And the best part, I will start to believe more in myself so I have already few offers for that kind of position but am waiting for few more and I am screening companies to find one that fits me best - shares values with mine and has a great interaction with their users. One of the companies that makes me want to screen more companies is Buffer. When you read this and this you will see their way of life and perks are really something every company should do - then you will understand why I want to give my self a chance which I believe I finally deserved. And, no, I didn't apply for Buffer as I don't use their service nor did have time to read the two books needed for applying (which I think is really a great thing to foster people into getting more knowledge). I can only wish them best luck in future. I am currently doing one small software development thing (freelance) for next two weeks and after that I am hoping to get enough good offer to start with happiness job and retreat from software development for some good amount of time. That doesn't mean I will cease my Free software activities - on contrary I think I will have more time and even more will to work on Free software development in my spare time. So if anyone or any company that works with open source community has a position for happiness hero, get in touch with me and we will have a good talk. End point - I want to grow and become who am I, and not who I should be according to others.

10 May 2015

Eduard Sanou: Reproducible builds on Debian for GSoC 2015

This is the first blog post of a series I will be writing about my experiences contributing to Debian for Google Summer of Code 2015.

A bit about myself I m a Spanish student doing a master s in Computer Science in Barcelona. I graduated on Electrical Engineering (we call it Telecommunications here). I ve always been interested in computing and programming and I have worked on several projects on my own using C, python and go. My main interests in the field are programming languages, security, cryptography, distributed and decentralized systems and embedded systems. I m an advocate of free software, I try to use it as much as I m able to in my devices and also try to convince my friends and family of its benefits. I have been using GNU/Linux for nearly ten years as my main operating system and I have tried several *BSD s recently. One of my latest personal projects is a gameboy emulator written in C (still work in progress) which already plays many games (without sound though) . You can find other minor projects in my github page (I try to publish all the code I write online, under free software licence) After so many years of using free software and benefiting from it, I thought it was about time to contribute back! That s why I gave GSoC a try and applied to work on the Reproducible Builds project for Debian :) And I got accepted!

Reproducible Builds The idea behind this project is that currently many packages aren t built in a reproducible manner; that is, they contain timestamps, building machine name, unique IDs, and results from other processes that happen differently between machines, like file ordering in compressed files. The project aims to patch all the Debian packages / the building scripts in order to generate the same binary (bit by bit) independently of the machine, timezone, etc where it is built. This way, a cryptographic hash of the built package can be distributed and many people can rebuild the package to verify that the binary in the repositories indeed corresponds to the right source code by means of comparing the hash.

Motivation One of the main advantages of the free software is that source code is available for peer review. This makes it easier for users to trust their software, as they can check the source to verify that the program is not doing anything bad. Even if the user doesn t do that, they can trust the wider community with that task. But many distributions serve packages in binary form, so how do we know that the binary comes from the publicly available source code? The current solution is that the developers who build the packages sign them cryptographically; but this lands all the trust to the developer and the machines used for building. I became interested in this topic with a very nice talk given at 31c3 by Mike Perry from Tor and Seth Schoen from the EFF. They focused on reproducible builds applied to the tor browser bundle, showing a small demo of how a building machine could be compromised to add hidden functionalities when compiling code (so that the developer could be signing a compromised package without their knowledge).

Benefits There are two main groups who benefit with reproducible builds:

For users The user can be more secure when installing packages in binary form since they don t need to trust a specific developer or building machine. Even if they don t rebuild the package by themselves to verify it, there would be others doing so, who will easily alert the community when the binary doesn t match the source code.

For developers The developer no longer has the responsibility of using his identity to sign the package for wide distribution, nor is that much responsible of the damage to users if their machine is compromised to alter the building process, since the community will easily detect it and alert them. This later point is specially useful with secure and privacy aware software. The reason is that there are many powerful organizations around the world with interest on having backdoors in widely used software, be it to spy on users or to target specific groups of people. Considering the amount of money these organizations have for such purposes, it s not hard to imagine that they could try to blackmail developers into adding such backdoors on the built packages. Or they could try to compromise the building machine. With reproducible builds the developer is safer, as such attack is no longer useful.

Reproducible Builds in Debian The project kicked-off at Debian at mid 2013 , leaded by Lunar and soon followed by many other developers (h01ger, deki, mapreri, ). Right now about 80% of the packages in the unstable branch of Debian can be built reproducibly. The project is very active, with many developers sending patches every week. A machine running Jenkins (which was set up at the end of 2012 for other purposes) is being used since late 2014 to continuously build packages in different settings to check if they are built reproducibly or not. In order to analyze why packages fail to build reproducibly, a tool called debbindiff has been developed, which is able to output in text or html form a smart diff of two builds. Another tool called strip-nondeterminism has been developed to remove non-determinism from files during the building process. For this GSoC I plan on helping improving these tools (mainly debbindiff), write many patches to achieve reproducibility in more packages and write documentation about it. Some of the packages fail to build reproducibly due to specifics of their building processes, whereas others fail due to the usage of toolchains that add non-determinism. I ll focus more on the later ones in order to improve the state more packages. akira will also be working on this project for this GSoC. Finally, I just want to add that I m looking forward to contribute to Debian, meet the community and learn more about the internals of this awesome distribution!

6 May 2015

C.J. Adams-Collier: A harowing upgrade

I just dist-upgraded the blog server to jessie. A couple of errors from code with checks for which modules are enabled from .htaccess (deprecated and now obsolete behavior). Nothing all that rocky. Go team Debian!

5 May 2015

Jamie McClelland: Docker networking... private range or not?

Am I missing something? I installed docker and noticed that it created a virtual interface named docker0 with the IP address 172.17.42.1. This behavior is consistent with the Docker networking documentation. However, I was confused by this statement:
It randomly chooses an address and subnet from the private range defined by RFC 1918 that are not in use on the host machine, and assigns it to docker0. Docker made the choice 172.17.42.1/16 when I started it a few minutes ago...
It seems like RFC 1918 defines: How is 172.17.42.1/16 from the private ranges listed above? Is 172.17.42.1 a potentially public IP address?

4 May 2015

Lunar: Reproducible builds: first week in Stretch cycle

Debian Jessie has been released on April 25th, 2015. This has opened the Stretch development cycle. Reactions to the idea of making Debian build reproducibly have been pretty enthusiastic. As the pace is now likely to be even faster, let's see if we can keep everyone up-to-date on the developments. Before the release of Jessie The story goes back a long way but a formal announcement to the project has only been sent in February 2015. Since then, too much work has happened to make a complete report, but to give some highlights: Lunar did a pretty improvised lightning talk during the Mini-DebConf in Lyon. This past week It seems changes were pilling behind the curtains given the amount of activity that happened in just one week. Toolchain fixes We also rebased the experimental version of debhelper twice to merge the latest set of changes. Lunar submitted a patch to add a -creation-date to genisoimage. Reiner Herrmann opened #783938 to request making -notimestamp the default behavior for javadoc. Juan Picca submitted a patch to add a --use-date flag to texi2html. Packages fixed The following packages became reproducible due to changes of their build dependencies: apport, batctl, cil, commons-math3, devscripts, disruptor, ehcache, ftphs, gtk2hs-buildtools, haskell-abstract-deque, haskell-abstract-par, haskell-acid-state, haskell-adjunctions, haskell-aeson, haskell-aeson-pretty, haskell-alut, haskell-ansi-terminal, haskell-async, haskell-attoparsec, haskell-augeas, haskell-auto-update, haskell-binary-conduit, haskell-hscurses, jsch, ledgersmb, libapache2-mod-auth-mellon, libarchive-tar-wrapper-perl, libbusiness-onlinepayment-payflowpro-perl, libcapture-tiny-perl, libchi-perl, libcommons-codec-java, libconfig-model-itself-perl, libconfig-model-tester-perl, libcpan-perl-releases-perl, libcrypt-unixcrypt-perl, libdatetime-timezone-perl, libdbd-firebird-perl, libdbix-class-resultset-recursiveupdate-perl, libdbix-profile-perl, libdevel-cover-perl, libdevel-ptkdb-perl, libfile-tail-perl, libfinance-quote-perl, libformat-human-bytes-perl, libgtk2-perl, libhibernate-validator-java, libimage-exiftool-perl, libjson-perl, liblinux-prctl-perl, liblog-any-perl, libmail-imapclient-perl, libmocked-perl, libmodule-build-xsutil-perl, libmodule-extractuse-perl, libmodule-signature-perl, libmoosex-simpleconfig-perl, libmoox-handlesvia-perl, libnet-frame-layer-ipv6-perl, libnet-openssh-perl, libnumber-format-perl, libobject-id-perl, libpackage-pkg-perl, libpdf-fdf-simple-perl, libpod-webserver-perl, libpoe-component-pubsub-perl, libregexp-grammars-perl, libreply-perl, libscalar-defer-perl, libsereal-encoder-perl, libspreadsheet-read-perl, libspring-java, libsql-abstract-more-perl, libsvn-class-perl, libtemplate-plugin-gravatar-perl, libterm-progressbar-perl, libterm-shellui-perl, libtest-dir-perl, libtest-log4perl-perl, libtext-context-eitherside-perl, libtime-warp-perl, libtree-simple-perl, libwww-shorten-simple-perl, libwx-perl-processstream-perl, libxml-filter-xslt-perl, libxml-writer-string-perl, libyaml-tiny-perl, mupen64plus-core, nmap, openssl, pkg-perl-tools, quodlibet, r-cran-rjags, r-cran-rjson, r-cran-sn, r-cran-statmod, ruby-nokogiri, sezpoz, skksearch, slurm-llnl, stellarium. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues but not all of them: Patches submitted which did not make their way to the archive yet: Improvements to reproducible.debian.net Mattia Rizzolo has been working on compressing logs using gzip to save disk space. The web server would uncompress them on-the-fly for clients which does not accept gzip content. Mattia Rizzolo worked on a new page listing various breakage: missing or bad debbindiff output, missing build logs, unavailable build dependencies. Holger Levsen added a new execution environment to run debbindiff using dependencies from testing. This is required for packages built with GHC as the compiler only understands interfaces built by the same version. debbindiff development Version 17 has been uploaded to unstable. It now supports comparing ISO9660 images, dictzip files and should compare identical files much faster. Documentation update Various small updates and fixes to the pages about PDF produced by LaTeX, DVI produced by LaTeX, static libraries, Javadoc, PE binaries, and Epydoc. Package reviews Known issues have been tagged when known to be deterministic as some might unfortunately not show up on every single build. For example, two new issues have been identified by building with one timezone in April and one in May. RD and help2man add current month and year to the documentation they are producing. 1162 packages have been removed and 774 have been added in the past week. Most of them are the work of proper automated investigation done by Chris West. Summer of code Finally, we learned that both akira and Dhole were accepted for this Google Summer of Code. Let's welcome them! They have until May 25th before coding officialy begins. Now is the good time to help them feel more comfortable by sharing all these little bits of knowledge on how Debian works.

Mike Hommey: Gnome shell Hello world

Gnome Shell, besides providing the main user interface for GNOME 3, is a Javascript shell with bindings to many native interfaces that allow e.g. Window manipulation, graphics rendering and animations, compositing, etc. It also allows developers to write extensions changing Gnome Shell s behavior. Less known is that it is possible to replace the entire Javascript code base that Gnome Shell uses. It can be useful to hack on Gnome Shell itself (no need to fiddle with system files, or, since 3.12, no need to rebuild libgnome-shell.so), but it can also be used to implement a completely new User Interface in Javascript. I m starting to experiment with the latter, because I want to try building a window manager that fits my needs, while keeping away the boring details of EWMH, xinerama, and other X11 things. And because it s fun. But baby steps, first: let s bootstrap a Hello world with Gnome shell. I tested this with Gnome Shell 3.14. Trying various older versions, I got different results for reasons I don t know. 3.4 doesn t display anything unless, paradoxically, global.stage.show() is removed, and 3.8 doesn t display anything no matter what. I guess the next step is to go through some Clutter tutorials and transpose them to Javascript. Update: On the other hand, a lot of the window managing is still done by mutter under the hood, which doesn t leave a lot of space for something really different.

27 April 2015

Matthew Garrett: Reducing power consumption on Haswell and Broadwell systems

Edit to add: These patches on their own won't enable this functionality, they just give us a better set of options. Once they're merged we can look at changing the defaults so people get the benefit of this out of the box.

Haswell and Broadwell (Intel's previous and current generations of x86) both introduced a range of new power saving states that promised significant improvements in battery life. Unfortunately, the typical experience on Linux was an increase in power consumption. The reasons why are kind of complicated and distinctly unfortunate, and I'm at something of a loss as to why none of the companies who get paid to care about this kind of thing seemed to actually be caring until I got a Broadwell and looked unhappy, but here we are so let's make things better.

Recent Intel mobile parts have the Platform Controller Hub (Intel's term for the Southbridge, the chipset component responsible for most system i/o like SATA and USB) integrated onto the same package as the CPU. This makes it easier to implement aggressive power saving - the CPU package already has a bunch of hardware for turning various clock and power domains on and off, and these can be shared between the CPU, the GPU and the PCH. But that also introduces additional constraints, since if any component within a power management domain is active then the entire domain has to be enabled. We've pretty much been ignoring that.

The tldr is that Haswell and Broadwell are only able to get into deeper package power saving states if several different components are in their own power saving states. If the CPU is active, you'll stay in a higher-power state. If the GPU is active, you'll stay in a higher-power state. And if the PCH is active, you'll stay in a higher-power state. The last one is the killer here. Having a SATA link in a full-power state is sufficient to keep the PCH active, and that constrains the deepest package power savings state you can enter.

SATA power management on Linux is in a kind of odd state. We support it, but we don't enable it by default. In fact, right now we even remove any existing SATA power management configuration that the firmware has initialised. Distributions don't enable it by default because there are horror stories about some combinations of disk and controller and power management configuration resulting in corruption and data loss and apparently nobody had time to investigate the problem.

I did some digging and it turns out that our approach isn't entirely inconsistent with the industry. The default behaviour on Windows is pretty much the same as ours. But vendors don't tend to ship with the Windows AHCI driver, they replace it with the Intel Rapid Storage Technology driver - and it turns out that that has a default-on policy. But to make things even more awkwad, the policy implemented by Intel doesn't match any of the policies that Linux provides.

In an attempt to address this, I've written some patches. The aim here is to provide two new policies. The first simply inherits whichever configuration the firmware has provided, on the assumption that the system vendor probably didn't configure their system to corrupt data out of the box[1]. The second implements the policy that Intel use in IRST. With luck we'll be able to use the firmware settings by default and switch to the IRST settings on Intel mobile devices.

This change alone drops my idle power consumption from around 8.5W to about 5W. One reason we'd pretty much ignored this in the past was that SATA power management simply wasn't that big a win. Even at its most aggressive, we'd struggle to see 0.5W of saving. But on these new parts, the SATA link state is the difference between going to PC2 and going to PC7, and the difference between those states is a large part of the CPU package being powered up.

But this isn't the full story. There's still work to be done on other components, especially the GPU. Keeping the link between the GPU and an internal display panel active is both a power suck and requires additional chipset components to be powered up. Embedded Displayport 1.3 introduced a new feature called Panel Self-Refresh that permits the GPU and the screen to negotiate dropping the link, leaving it up to the screen to maintain its contents. There's patches to enable this on Intel systems, but it's still not turned on by default. Doing so increases the amount of time spent in PC7 and brings corresponding improvements to battery life.

This trend is likely to continue. As systems become more integrated we're going to have to pay more attention to the interdependencies in order to obtain the best possible power consumption, and that means that distribution vendors are going to have to spend some time figuring out what these dependencies are and what the appropriate default policy is for their users. Intel's done the work to add kernel support for most of these features, but they're not the ones shipping it to end-users. Let's figure out how to make this right out of the box.

[1] This is not necessarily a good assumption, but hey, let's see

comment count unavailable comments

Gunnar Wolf: Worthy weekend

(No, I'm not talking about a future Ubuntu release... After all, what kind of weird animal would a weekend be?) This weekend we took the kids outside for the first time (not counting, of course, visits to the pediatrician). We were quite anxious... Of course, they were born somewhat under weight and at 7 months of gestation. But this Saturday we feelt adventurous, and took the kids out for a day among people! It might not sound like a big deal, but... Well, we took a not such beautiful or scenic route: We took them to the supermarket, and had a small lunch out. For the first time in the already two months they have been with us. Dinner with friends at home, having a very good time, and as expected a... Very hard night for us. All that excitement had the babies very nervous. Today again, for the first time we took the children out to visit some friends of ours. Again, it was great, they behaved very nicely, and were lovely all around. Lets see what this night holds in place for us. Anyway, with them growing slowly but steadily... We are very happy, thankful parents. For the first time since Regina is with me in Mexico, this time we decided we would not have a birthday party (yes, I'm 30 minutes away from being 39 year old). I cannot imagine a fuller, better celebration than what we are having. This two babies are the real event in our lives. Oh... And by the way, this weekend also saw the release of a great new Debian release: Debian 8, codenamed Jessie. Thanks, folks, for such a great birthday present ;-) For reasons that should by now be obvious, I wasn't able to go to either of the release parties I knew of in Mexico City (even one of them was ~500m from home!)

23 April 2015

Jonathan Dowland: Deterministic Doom

What happens if you remove randomness from Doom? For some reason, recently I have been thinking about Doom. This evening I was wanting to explore some behaviour in an old version of Doom and to do so, I hex-edited the binary and replaced the random number lookup table with static values. Rather than consume system randomness, Doom has a fixed 256-value random number table from which numbers are pulled by aspects of the game logic. By replacing the whole table with a constant value, you essentially make the game entirely deterministic. What does it play like? I tried two values, 0x00 and 0xFF. With either value, the screen "melt" effect that is used at the end of levels is replaced with a level vertical wipe: the randomness was used to offset each column. Monsters do not make different death noises at different times; only one is played for each category of monster. The bullet-based (hitscan) weapons have no spread at all: the shotgun becomes like a sniper rifle, and the chain-gun is likewise always true. You'd think this would make the super-shotgun a pretty lethal weapon, but it seems to have been nerfed: the spread pattern is integral to its function. With 0x00, monsters never make their idle noises (breathing etc.) On the other hand, with 0xFF, they always do: so often, that each sample collides with the previous one, and you just get a sort-of monster drone. This is quite overwhelming with even a small pack of monsters. With 0xFF, any strobing sectors (flickering lights etc.), are static. However, with 0x00, they strobe like crazy. With 0x00, monsters seem to choose to attack much more frequently than usual. Damage seems to be worst-case. The most damaging floor type ("super hellslime"/20%) can hurt you even if you are wearing a radiation suit: There was a very low chance of it hurting whilst wearing the suit (~2.6%) each time the game checked; this is rounded up to 100%. Various other aspects of the game become weird. A monster may always choose to use a ranged attack, regardless of how close you are. They might give up pursuing you. I've seen them walk aimlessly in circles if they are obstructed by another thing. The chance of monster in-fighting is never, or a certainty. The player is either mute, or cries in pain whenever he's hurt. If you want to try this yourself, the easiest way is to hack the m_random.c file in the source, but you can hex-edit a binary. Look for a 256-byte sequence beginning beginning ['0x0', '0x8', '0x6d', '0xdc', '0xde', '0xf1'] and ending ['0x78', '0xa3', '0xec', '0xf9'].
22 April 2015

Jonathan Wiltshire: Jessie Countdown: 3

Three is the new number for continuing oldstable security support: thanks to the efforts of those behind the Long-Term Support initiative, the full stable lifecycle of a release has therefore become five years (source: https://www.debian.org/News/2014/20140424). Where do those numbers come from? 2 years as stable, 1 year overlap support as oldstable, plus 2 new years under LTS = 5 years. Having been successful for Squeeze (6), LTS is widely anticipated to follow a similar pattern for Wheezy (7) and Jessie (8) for the same lifetimes. Some reduction in coverage is unavoidable (for example, Squeeze only covers the most popular amd64 and i386 architectures), but for a majority of users this reduces the need to follow a three-year upgrade cycle invaluable when you are managing hundreds or thousands of servers and can t achieve that in a single year.
Jessie Countdown: 3 is a post from: jwiltshire.org.uk Flattr

John Goerzen: Today I FLEW A PLANE

DJI00694
For once you have tasted flight,
You will walk the earth with your eyes turned skyward;
For there you have been,
And there you long to return. Leonardo da Vinci
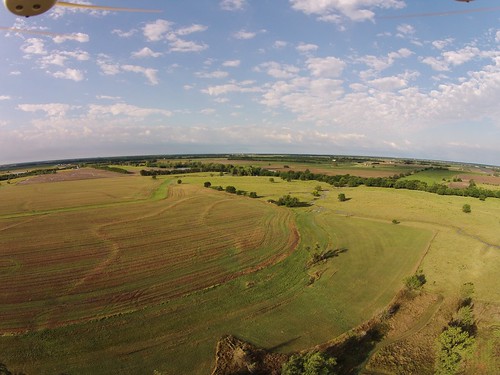
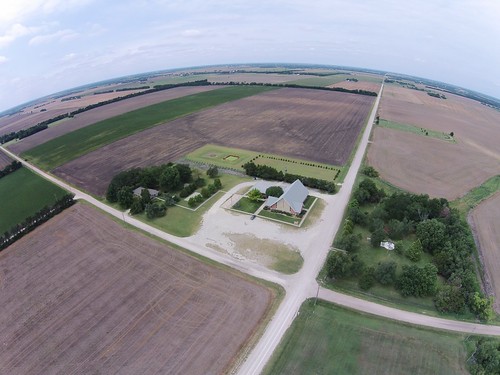
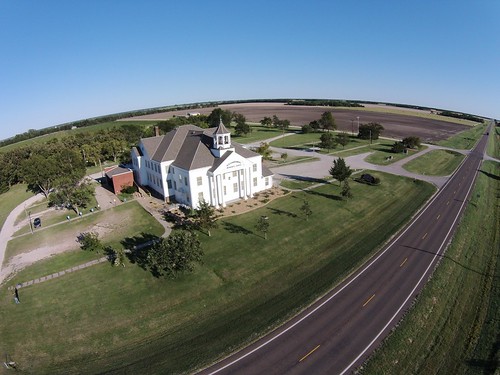
There is something of a magic to flight, to piloting. I remember the first flight I ever took, after years of dreaming of flying in a plane: my grandma had bought me a plane ticket. In one of the early morning flights, I witnessed a sunrise above cumulus clouds. Although I was just 10 or so at the time, that still is a most beautiful image seared into my memory. I have become meh about commercial flight over the years. The drive to the airport, the security lines, the lack of scenery at 35,000 feet. And yet, there is much more to flight than that. When I purchased what was essentially a flying camera, I saw a whole new dimension of the earth s amazing beauty. All the photos in this post, in fact, are ones I took. I then got a RC airplane, because flying the quadcopter was really way too easy. DJI00620
It s wonderful to climb the liquid mountains of the sky.
Behind me and before me is God, and I have no fears. Helen Keller
Start talking to pilots, and you notice a remarkable thing: this group of people that tends to be cool and logical, methodical and precise, suddenly finds themselves using language almost spiritual. Many have told me that being a pilot brings home how much all humans have in common, the unifying fact of sharing this beautiful planet together. Many volunteer with organizations such as Angel Flight. And having been up in small planes a few times, I start to glimpse this. Flying over my home at 1000 up, or from lake to lake in Seattle with a better view than the Space Needle, seeing places familiar and new, but from a new perspective, drives home again and again the beauty of our world, the sheer goodness of it, and the wonderful color of the humanity that inhabits it. DJI00120
The air up there in the clouds is very pure and fine, bracing and delicious. And why shouldn t it be? It is the same the angels breathe. Mark Twain
The view from 1000 feet, or 3000, is often so much more spectacular than the view from 35,000 ft as you get on a commercial flight. The flexibility is too; there are airports all over the country that smaller planes can use which the airlines never touch. Here is one incredible video from a guy that is slightly crazy but does ground-skimming, flying just a few feet off the ground: (try skipping to 9:36) So what comes next is something I blame slightly on my dad and younger brother. My dad helped get me interested in photography as a child, and that interest has stuck. It s what caused me to get into quadcopters ( a flying camera for less than the price of a nice lens! ). And my younger brother started mentioning airplanes to me last year for some reason, as if he was just trying to get me interested. Eventually, it worked. I started talking to the pilots I know (I know quite a few; there seems to be a substantial overlap between amateur radio and pilots). I started researching planes, flight, and especially safety the most important factor. And eventually I decided I wanted to be a pilot. I ve been studying feverishly, carrying around textbooks and notebooks in the car, around the house, and even on a plane. There is a lot to learn. And today, I took my first flight with a flight instructor. Today I actually flew a plane for awhile. Wow! There is nothing quite like that experience. Seeing a part of the world I am familiar with from a new perspective, and then actually controlling this amazing machine I really fail to find the words to describe it. I have put in many hours of study already, and there will be many more studying and flying, but it is absolutely worth it. Here is one final video about one of the most unique places you can fly to in Kansas. And a blog with lots of photos of a flight to Beaumont called Horse on the runway .

21 April 2015

Jonathan Wiltshire: Jessie Countdown: 4

Four architectures types of computing device that you can use to run Debian didn t make it through architecture qualification for Jessie and won t be part of the official stable release this weekend. It s always difficult to see architectures go, particularly when there is still a community interested in maintaining support for them. Nevertheless, sometimes a port just doesn t have enough momentum behind it or sufficient upstream interest from the toolchain to be economical. Whether a port is of sufficient quality for stable is a complex decision involving several different teams Debian System Administration, the security team, those who maintain the auto-builder network, the release team, and so on and will continue to affect them for several years. It s not all gloom though: new architectures in Jessie include arm64, ppc64el (a 64-bit version of powerpc) and s390x (replacing Wheezy s s390). Architecture rotation can be healthy. (source: https://release.debian.org/jessie/arch_qualify.html. ia64 and s390 were planned retirements following Wheezy, leaving hurd-i386, kfreebsd-i386, kfreebsd-amd64 and sparc which didn t satisfy all qualification criteria by the time decisions had to be taken.)
Jessie Countdown: 4 is a post from: jwiltshire.org.uk Flattr

Next.

Previous.