Search Results: "ana"

2 July 2022

Russ Allbery: Review: Overdue

Review: Overdue, by Amanda Oliver
Publisher: Chicago Review Press
Copyright: 2022
ISBN: 1-64160-534-0
Format: Kindle
Pages: 190
Like many lifetime readers, I adored the public library. I read my way through three different children's libraries at the rate of a grocery sack of books per week, including numerous re-readings, and then moved on to the adult section as my introduction to science fiction. But once I had a regular job, I discovered the fun of filling shelves with books without having to return them or worry about what the library had available. I've always supported my local library, but it's been decades since I spent much time in it. When I last used one heavily, the only computers were at the checkout desk and the only books were physical, normally hardcovers. Overdue: Reckoning with the Public Library therefore caught my eye when I saw a Twitter thread about it before publication. It promised to be a picture of the modern public library and its crises from the perspective of the librarian. The author's primary topic was the drafting of public libraries as de facto homeless service centers, but I hoped it would also encompass technological change, demand for new services, and the shifting meaning of what a public library is for. Overdue does... some of that. The author was a children's librarian in a Washington DC public school and then worked at a downtown branch of the Washington DC public library, and the book includes a few anecdotes from both experiences. Most of the book, though, is Oliver's personal memoir of how she got into field, why she chose to leave it, and how she is making sense of her feelings about the profession. Intermixed with that memoir is wide-ranging political commentary on topics ranging from gentrification to mental health care. This material is relevant to the current challenges libraries face, but it wandered far afield from what I was hoping to get from the book. I think of non-fiction books as coming in a few basic shapes. One is knowledge from an expert: the author has knowledge about a topic that is not widely shared, and they write a book to share it. Another is popularization: an author, possibly without prior special expertise in the topic, does research the reader could have done but doesn't have time to do and then summarizes the results in a format that's easier to understand than the original material. And a third is memoir, in which the author tells the story of their own life. This is a variation of the first type, since the author is obviously an expert in their own life, but most people's lives are not interesting. (Mine certainly isn't!) Successful memoir therefore depends on either having an unusual life or being a compelling storyteller, and ideally both. Many non-fiction books fall into multiple categories, but it's helpful for an author to have a clear idea of which of these goals they're pursuing since they result in different books. If the author is writing primarily from a position of special expertise, the book should focus on that expertise. I am interested in librarians and libraries and would like to know more about that job, so I will read with interest your personal stories about being a librarian. I am somewhat interested in your policy suggestions for how to make libraries work better, although more so if you can offer context and analysis beyond your personal experiences. I am less interested in your opinions on, say, gentrification. That's not because I doubt it is a serious problem (it is) or that it impacts libraries (it does). It's because working in a library doesn't provide any special expertise in gentrification beyond knowing that it exists, something that I can see by walking around the corner. If I want to know more, I will read books by urban planners, sociologists, and housing rights activists. This is a long-winded way of saying that I wish Overdue had about four times as many stories about libraries, preferably framed by general research and background that extended beyond the author's personal experience, or at least more specific details of the politics of the Washington DC library system. The personal memoir outside of the library stories failed to hold my interest. This is not intended as a slam on the author. Oliver seems like a thoughtful and sincere person who is struggling with how to do good in the world without burning out, which is easy for me to sympathize with. I suspect I broadly agree with her on many political positions. But I have read all of this before, and personally lived through some of the same processing, and I don't think Oliver offered new insight. The library stories were memorable enough to form the core of a good book, but the memoir structure did nothing for them and they were strangled by the unoriginal and too-general political analysis. At the risk of belaboring a negative review, there are two other things in Overdue that I've also seen in other writing and seem worth commenting on. The first is the defensive apology that the author may not have the best perspective to write the book. It's important to be clear: I am glad that the Oliver has thought about the ways her experiences as a white woman may not be representative of other people. This is great; the world is a better place when more people consider that. I'm less fond of putting that observation in the book, particularly at length. As the author, rather than writing paragraphs vaguely acknowledging that other people have different experiences, she could instead fix the problem: go talk to librarians of other ethnic and social backgrounds and put their stories in this book. The book would then represent broader experiences and not require the apology. Overdue desperately needed more library-specific content, so that would have improved the book in more than one way. Or if Oliver is ideologically opposed to speaking for other people (she makes some comments to that effect), state up-front, once, that this is a personal memoir and, as a memoir, represents only her own experience. But the author should do something with this observation other than dump its awkwardness on the reader, if for no other reason than that lengthy disclaimers about the author's limited perspective are boring. The second point is about academic jargon and stock phrasing. I work in a field that relies on precise distinctions of meaning (between identity, authentication, and authorization, for example), and therefore I rely on jargon. Its purpose is to make those types of fine distinctions. But authors who read heavily in fields with jargon tend to let that phrasing slip into popular writing where it's not necessary. The result is, to quote Orwell, "gumming together long strips of words which have already been set in order by someone else." The effect may be small in a single sentence but, when continued throughout a book, the overuse of jargon is leaden, belabored, and confusing. Any example I choose will be minor since the effect is cumulative, but one of several I noticed in Overdue is "lived experience." This is jargon from philosophy that, within the field, draws a useful distinction between one's direct experiences of living in the world, and academic or scientific experience with a field. Both types of experience are valuable in different situations, but they're not equivalent. This is a useful phrase when the distinction matters and is unclear. When the type of experience one is discussing is obvious in context (the case in at least three of the four uses in this book), the word "lived" adds nothing but verbosity. If too much of this creeps into writing, it becomes clunky and irritating to read. The best (and not coincidentally the least clunky) part of this book is Oliver's stories of the patrons and other employees of the Northwest One branch of the Washington DC library system and her experiences with them. The picture was not as vivid as I was hoping for, but I came away with some new understanding of typical interactions and day-to-day difficulties. The same was true to a lesser extent for her experiences as a school librarian. For both, I wish there had been more context and framing so that I could see how her experiences fit into a whole system, but those parts of the book were worth reading. Unfortunately, they weren't enough of those parts in the book for me to recommend Overdue. But I'm still interested in reading the book I hoped I was getting! Rating: 5 out of 10

30 June 2022

Russell Coker: Links June 2022

Google did some interesting research on the impact of discrimination on code reviers [1]. It turns out that this is a bigger problem than most white men would have ever suspected and it even has an adverse effect on Asian people. nothello.net is an amusing site to make the point that you shouldn t use IM to say hello separately from asking the question [2]. A good link to share on your corporate IM system. TechCrunch has an amusing article about the Facebook farewell to Sheryl Sandburg [3]. BleepingComputer has an interesting article about a bug-bunty program from a crime syndicate offering up to $1M in crypto-currency [4]. Among other things finding the real first and last names of the crime lord gets you $1M. BleepingComputer has an interesting article about how deepfakes are being used to apply for work from home jobs [5]. I wonder whether the people doing that intend to actually do any of the work or just get paid for doing nothing while delaying getting sacked for as long as possible. I have read about people getting a job they don t want to do that has a long training period so that they can quit at the end of training without working apparently call center work is a good option for this. BleepingComputer has an interesting article about phishing attacks that use a VNC remote desktop connection to trick a user into authenticating using the attacker s PC [6]. The real problem here is getting humans to do things that computers do better, which is recognising the correct foreign party. Fortune has an interesting article about the problems with Tesla self-driving and the possibility of a recall [7]. The main issue is apparently Teslas driving at full speed into emergency services vehicles that are parked while attending an incident. Having a police car unexpectedly occupying a lane of traffic is something you just have to deal with, either stop or change lanes. Teslas have been turning off autopilot less than one second before impact so Telsa can claim that it didn t happen with autopilot engaged but in reality a human can t take over in less than one second, a pilot I know says it takes 2-3 seconds to take over the controls in a plane. BonAppetit has an interesting and amusing article about protest foods [8] which starts by explaining why Ukrainians are throwing pasta at the Russian consulate. The NVidia blog has an informative post about how Pony.ai optimised their pipeline for sensor data for autonomous cars [9]. Matt Crump wrote an educational and amusing blog post about his battle with cheaters in university tests he administered [10]. The Cricket Monthly has an insightful article about how a batsman manages to see and hit a cricket ball that s going well in excess of 100KM/h [11]. One particularly noteworthy part of this article is the comparison of what amateur cricketers do with what anyone who wants to be a contender for the national team must do. Darker Shades of Blue is an insightful paper by Tony Kern about the needless crash of a B52 at Fairchild air base in 1994 [12]. This is specifically written to teach people about correct and effective leadership.

29 June 2022

Aigars Mahinovs: Long travel in an electric car

Since the first week of April 2022 I have (finally!) changed my company car from a plug-in hybrid to a fully electic car. My new ride, for the next two years, is a BMW i4 M50 in Aventurine Red metallic. An ellegant car with very deep and memorable color, insanely powerful (544 hp/795 Nm), sub-4 second 0-100 km/h, large 84 kWh battery (80 kWh usable), charging up to 210 kW, top speed of 225 km/h and also very efficient (which came out best in this trip) with WLTP range of 510 km and EVDB real range of 435 km. The car also has performance tyres (Hankook Ventus S1 evo3 245/45R18 100Y XL in front and 255/45R18 103Y XL in rear all at recommended 2.5 bar) that have reduced efficiency. So I wanted to document and describe how was it for me to travel ~2000 km (one way) with this, electric, car from south of Germany to north of Latvia. I have done this trip many times before since I live in Germany now and travel back to my relatives in Latvia 1-2 times per year. This was the first time I made this trip in an electric car. And as this trip includes both travelling in Germany (where BEV infrastructure is best in the world) and across Eastern/Northen Europe, I believe that this can be interesting to a few people out there. Normally when I travelled this trip with a gasoline/diesel car I would normally drive for two days with an intermediate stop somewhere around Warsaw with about 12 hours of travel time in each day. This would normally include a couple bathroom stops in each day, at least one longer lunch stop and 3-4 refueling stops on top of that. Normally this would use at least 6 liters of fuel per 100 km on average with total usage of about 270 liters for the whole trip (or about 540 just in fuel costs, nowadays). My (personal) quirk is that both fuel and recharging of my (business) car inside Germany is actually paid by my employer, so it is useful for me to charge up (or fill up) at the last station in Gemany before driving on. The plan for this trip was made in a similar way as when travelling with a gasoline car: travelling as fast as possible on German Autobahn network to last chargin stop on the A4 near G rlitz, there charging up as much as reasonable and then travelling to a hotel in Warsaw, charging there overnight and travelling north towards Ionity chargers in Lithuania from where reaching the final target in north of Latvia should be possible. How did this plan meet the reality? Travelling inside Germany with an electric car was basically perfect. The most efficient way would involve driving fast and hard with top speed of even 180 km/h (where possible due to speed limits and traffic). BMW i4 is very efficient at high speeds with consumption maxing out at 28 kWh/100km when you actually drive at this speed all the time. In real situation in this trip we saw consumption of 20.8-22.2 kWh/100km in the first legs of the trip. The more traffic there is, the more speed limits and roadworks, the lower is the average speed and also the lower the consumption. With this kind of consumption we could comfortably drive 2 hours as fast as we could and then pick any fast charger along the route and in 26 minutes at a charger (50 kWh charged total) we'd be ready to drive for another 2 hours. This lines up very well with recommended rest stops for biological reasons (bathroom, water or coffee, a bit of movement to get blood circulating) and very close to what I had to do anyway with a gasoline car. With a gasoline car I had to refuel first, then park, then go to bathroom and so on. With an electric car I can do all of that while the car is charging and in the end the total time for a stop is very similar. Also not that there was a crazy heat wave going on and temperature outside was at about 34C minimum the whole day and hitting 40C at one point of the trip, so a lot of power was used for cooling. The car has a heat pump standard, but it still was working hard to keep us cool in the sun. The car was able to plan a charging route with all the charging stops required and had all the good options (like multiple intermediate stops) that many other cars (hi Tesla) and mobile apps (hi Google and Apple) do not have yet. There are a couple bugs with charging route and display of current route guidance, those are already fixed and will be delivered with over the air update with July 2022 update. Another good alterantive is the ABRP (A Better Route Planner) that was specifically designed for electric car routing along the best route for charging. Most phone apps (like Google Maps) have no idea about your specific electric car - it has no idea about the battery capacity, charging curve and is missing key live data as well - what is the current consumption and remaining energy in the battery. ABRP is different - it has data and profiles for almost all electric cars and can also be linked to live vehicle data, either via a OBD dongle or via a new Tronity cloud service. Tronity reads data from vehicle-specific cloud service, such as MyBMW service, saves it, tracks history and also re-transmits it to ABRP for live navigation planning. ABRP allows for options and settings that no car or app offers, for example, saying that you want to stop at a particular place for an hour or until battery is charged to 90%, or saying that you have specific charging cards and would only want to stop at chargers that support those. Both the car and the ABRP also support alternate routes even with multiple intermediate stops. In comparison, route planning by Google Maps or Apple Maps or Waze or even Tesla does not really come close. After charging up in the last German fast charger, a more interesting part of the trip started. In Poland the density of high performance chargers (HPC) is much lower than in Germany. There are many chargers (west of Warsaw), but vast majority of them are (relatively) slow 50kW chargers. And that is a difference between putting 50kWh into the car in 23-26 minutes or in 60 minutes. It does not seem too much, but the key bit here is that for 20 minutes there is easy to find stuff that should be done anyway, but after that you are done and you are just waiting for the car and if that takes 4 more minutes or 40 more minutes is a big, perceptual, difference. So using HPC is much, much preferable. So we put in the Ionity charger near Lodz as our intermediate target and the car suggested an intermediate stop at a Greenway charger by Katy Wroclawskie. The location is a bit weird - it has 4 charging stations with 150 kW each. The weird bits are that each station has two CCS connectors, but only one parking place (and the connectors share power, so if two cars were to connect, each would get half power). Also from the front of the location one can only see two stations, the otehr two are semi-hidden around a corner. We actually missed them on the way to Latvia and one person actually waited for the charger behind us for about 10 minutes. We only discovered the other two stations on the way back. With slower speeds in Poland the consumption goes down to 18 kWh/100km which translates to now up to 3 hours driving between stops. At the end of the first day we drove istarting from Ulm from 9:30 in the morning until about 23:00 in the evening with total distance of about 1100 km, 5 charging stops, starting with 92% battery, charging for 26 min (50 kWh), 33 min (57 kWh + lunch), 17 min (23 kWh), 12 min (17 kWh) and 13 min (37 kW). In the last two chargers you can see the difference between a good and fast 150 kW charger at high battery charge level and a really fast Ionity charger at low battery charge level, which makes charging faster still. Arriving to hotel with 23% of battery. Overnight the car charged from a Porsche Destination Charger to 87% (57 kWh). That was a bit less than I would expect from a full power 11kW charger, but good enough. Hotels should really install 11kW Type2 chargers for their guests, it is a really significant bonus that drives more clients to you. The road between Warsaw and Kaunas is the most difficult part of the trip for both driving itself and also for charging. For driving the problem is that there will be a new highway going from Warsaw to Lithuanian border, but it is actually not fully ready yet. So parts of the way one drives on the new, great and wide highway and parts of the way one drives on temporary roads or on old single lane undivided roads. And the most annoying part is navigating between parts as signs are not always clear and the maps are either too old or too new. Some maps do not have the new roads and others have on the roads that have not been actually build or opened to traffic yet. It's really easy to loose ones way and take a significant detour. As far as charging goes, basically there is only the slow 50 kW chargers between Warsaw and Kaunas (for now). We chose to charge on the last charger in Poland, by Suwalki Kaufland. That was not a good idea - there is only one 50 kW CCS and many people decide the same, so there can be a wait. We had to wait 17 minutes before we could charge for 30 more minutes just to get 18 kWh into the battery. Not the best use of time. On the way back we chose a different charger in Lomza where would have a relaxed dinner while the car was charging. That was far more relaxing and a better use of time. We also tried charging at an Orlen charger that was not recommended by our car and we found out why. Unlike all other chargers during our entire trip, this charger did not accept our universal BMW Charging RFID card. Instead it demanded that we download their own Orlen app and register there. The app is only available in some countries (and not in others) and on iPhone it is only available in Polish. That is a bad exception to the rule and a bad example. This is also how most charging works in USA. Here in Europe that is not normal. The normal is to use a charging card - either provided from the car maker or from another supplier (like PlugSufring or Maingau Energy). The providers then make roaming arrangements with all the charging networks, so the cards just work everywhere. In the end the user gets the prices and the bills from their card provider as a single monthly bill. This also saves all any credit card charges for the user. Having a clear, separate RFID card also means that one can easily choose how to pay for each charging session. For example, I have a corporate RFID card that my company pays for (for charging in Germany) and a private BMW Charging card that I am paying myself for (for charging abroad). Having the car itself authenticate direct with the charger (like Tesla does) removes the option to choose how to pay. Having each charge network have to use their own app or token bring too much chaos and takes too much setup. The optimum is having one card that works everywhere and having the option to have additional card or cards for specific purposes. Reaching Ionity chargers in Lithuania is again a breath of fresh air - 20-24 minutes to charge 50 kWh is as expected. One can charge on the first Ionity just enough to reach the next one and then on the second charger one can charge up enough to either reach the Ionity charger in Adazi or the final target in Latvia. There is a huge number of CSDD (Road Traffic and Safety Directorate) managed chargers all over Latvia, but they are 50 kW chargers. Good enough for local travel, but not great for long distance trips. BMW i4 charges at over 50 kW on a HPC even at over 90% battery state of charge (SoC). This means that it is always faster to charge up in a HPC than in a 50 kW charger, if that is at all possible. We also tested the CSDD chargers - they worked without any issues. One could pay with the BMW Charging RFID card, one could use the CSDD e-mobi app or token and one could also use Mobilly - an app that you can use in Latvia for everything from parking to public transport tickets or museums or car washes. We managed to reach our final destination near Aluksne with 17% range remaining after just 3 charging stops: 17+30 min (18 kWh), 24 min (48 kWh), 28 min (36 kWh). Last stop we charged to 90% which took a few extra minutes that would have been optimal. For travel around in Latvia we were charging at our target farmhouse from a normal 3 kW Schuko EU socket. That is very slow. We charged for 33 hours and went from 17% to 94%, so not really full. That was perfectly fine for our purposes. We easily reached Riga, drove to the sea and then back to Aluksne with 8% still in reserve and started charging again for the next trip. If it were required to drive around more and charge faster, we could have used the normal 3-phase 440V connection in the farmhouse to have a red CEE 16A plug installed (same as people use for welders). BMW i4 comes standard with a new BMW Flexible Fast Charger that has changable socket adapters. It comes by default with a Schucko connector in Europe, but for 90 one can buy an adapter for blue CEE plug (3.7 kW) or red CEE 16A or 32A plugs (11 kW). Some public charging stations in France actually use the blue CEE plugs instead of more common Type2 electric car charging stations. The CEE plugs are also common in camping parking places. On the way back the long distance BEV travel was already well understood and did not cause us any problem. From our destination we could easily reach the first Ionity in Lithuania, on the Panevezhis bypass road where in just 8 minutes we got 19 kWh and were ready to drive on to Kaunas, there a longer 32 minute stop before the charging desert of Suwalki Gap that gave us 52 kWh to 90%. That brought us to a shopping mall in Lomzha where we had some food and charged up 39 kWh in lazy 50 minutes. That was enough to bring us to our return hotel for the night - Hotel 500W in Strykow by Lodz that has a 50kW charger on site, while we were having late dinner and preparing for sleep, the car easily recharged to full (71 kWh in 95 minutes), so I just moved it from charger to a parking spot just before going to sleep. Really easy and well flowing day. Second day back went even better as we just needed an 18 minute stop at the same Katy Wroclawskie charger as before to get 22 kWh and that was enough to get back to Germany. After that we were again flying on the Autobahn and charging as needed, 15 min (31 kWh), 23 min (48 kWh) and 31 min (54 kWh + food). We started the day on about 9:40 and were home at 21:40 after driving just over 1000 km on that day. So less than 12 hours for 1000 km travelled, including all charging, bio stops, food and some traffic jams as well. Not bad. Now let's take a look at all the apps and data connections that a technically minded customer can have for their car. Architecturally the car is a network of computers by itself, but it is very secured and normally people do not have any direct access. However, once you log in into the car with your BMW account the car gets your profile info and preferences (seat settings, navigation favorites, ...) and the car then also can start sending information to the BMW backend about its status. This information is then available to the user over multiple different channels. There is no separate channel for each of those data flow. The data only goes once to the backend and then all other communication of apps happens with the backend. First of all the MyBMW app. This is the go-to for everything about the car - seeing its current status and location (when not driving), sending commands to the car (lock, unlock, flash lights, pre-condition, ...) and also monitor and control charging processes. You can also plan a route or destination in the app in advance and then just send it over to the car so it already knows where to drive to when you get to the car. This can also integrate with calendar entries, if you have locations for appointments, for example. This also shows full charging history and allows a very easy export of that data, here I exported all charging sessions from June and then trimmed it back to only sessions relevant to the trip and cut off some design elements to have the data more visible. So one can very easily see when and where we were charging, how much power we got at each spot and (if you set prices for locations) can even show costs. I've already mentioned the Tronity service and its ABRP integration, but it also saves the information that it gets from the car and gathers that data over time. It has nice aspects, like showing the driven routes on a map, having ways to do business trip accounting and having good calendar view. Sadly it does not correctly capture the data for charging sessions (the amounts are incorrect). Update: after talking to Tronity support, it looks like the bug was in the incorrect value for the usable battery capacity for my car. They will look into getting th eright values there by default, but as a workaround one can edit their car in their system (after at least one charging session) and directly set the expected battery capacity (usable) in the car properties on the Tronity web portal settings. One other fun way to see data from your BMW is using the BMW integration in Home Assistant. This brings the car as a device in your own smart home. You can read all the variables from the car current status (and Home Asisstant makes cute historical charts) and you can even see interesting trends, for example for remaining range shows much higher value in Latvia as its prediction is adapted to Latvian road speeds and during the trip it adapts to Polish and then to German road speeds and thus to higher consumption and thus lower maximum predicted remaining range. Having the car attached to the Home Assistant also allows you to attach the car to automations, both as data and event source (like detecting when car enters the "Home" zone) and also as target, so you could flash car lights or even unlock or lock it when certain conditions are met. So, what in the end was the most important thing - cost of the trip? In total we charged up 863 kWh, so that would normally cost one about 290 , which is close to half what this trip would have costed with a gasoline car. Out of that 279 kWh in Germany (paid by my employer) and 154 kWh in the farmhouse (paid by our wonderful relatives :D) so in the end the charging that I actually need to pay adds up to 430 kWh or about 150 . Typically, it took about 400 in fuel that I had to pay to get to Latvia and back. The difference is really nice! In the end I believe that there are three different ways of charging:
  • incidental charging - this is wast majority of charging in the normal day-to-day life. The car gets charged when and where it is convinient to do so along the way. If we go to a movie or a shop and there is a chance to leave the car at a charger, then it can charge up. Works really well, does not take extra time for charging from us.
  • fast charging - charging up at a HPC during optimal charging conditions - from relatively low level to no more than 70-80% while you are still doing all the normal things one would do in a quick stop in a long travel process: bio things, cleaning the windscreen, getting a coffee or a snack.
  • necessary charging - charging from a whatever charger is available just enough to be able to reach the next destination or the next fast charger.
The last category is the only one that is really annoying and should be avoided at all costs. Even by shifting your plans so that you find something else useful to do while necessary charging is happening and thus, at least partially, shifting it over to incidental charging category. Then you are no longer just waiting for the car, you are doing something else and the car magically is charged up again. And when one does that, then travelling with an electric car becomes no more annoying than travelling with a gasoline car. Having more breaks in a trip is a good thing and makes the trips actually easier and less stressfull - I was more relaxed during and after this trip than during previous trips. Having the car air conditioning always be on, even when stopped, was a godsend in the insane heat wave of 30C-38C that we were driving trough. Final stats: 4425 km driven in the trip. Average consumption: 18.7 kWh/100km. Time driving: 2 days and 3 hours. Car regened 152 kWh. Charging stations recharged 863 kWh. Questions? You can use this i4talk forum thread or this Twitter thread to ask them to me.

Tim Retout: Git internals and SHA-1

LWN reminds us that Git still uses SHA-1 by default. Commit or tag signing is not a mitigation, and to understand why you need to know a little about Git s internal structure. Git internally looks rather like a content-addressable filesystem, with four object types: tags, commits, trees and blobs. Content-addressable means changing the content of an object changes the way you address or reference it, and this is achieved using a cryptographic hash function. Here is an illustration of the internal structure of an example repository I created, containing two files (./foo.txt and ./bar/bar.txt) committed separately, and then tagged: Graphic showing an example Git internal structure featuring tags, commits, trees and blobs, and how these relate to each other. You can see how trees represent directories, blobs represent files, and so on. Git can avoid internal duplication of files or directories which remain identical. The hash function allows very efficient lookup of each object within git s on-disk storage. Tag and commit signatures do not directly sign the files in the repository; that is, the input to the signature function is the content of the tag/commit object, rather than the files themselves. This is analogous to the way that GPG signatures actually sign a cryptographic hash of your email, and there was a time when this too defaulted to SHA-1. An attacker who can break that hash function can bypass the guarantees of the signature function. A motivated attacker might be able to replace a blob, commit or tree in a git repository using a SHA-1 collision. Replacing a blob seems easier to me than a commit or tree, because there is no requirement that the content of the files must conform to any particular format. There is one key technical mitigation to this in Git, which is the SHA-1DC algorithm; this aims to detect and prevent known collision attacks. However, I will have to leave the cryptanalysis of this to the cryptographers! So, is this in your threat model? Do we need to lobby GitHub for SHA-256 support? Either way, I look forward to the future operational challenge of migrating the entire world s git repositories across to SHA-256.

28 June 2022

Jonathan Dowland: WadC 3.1

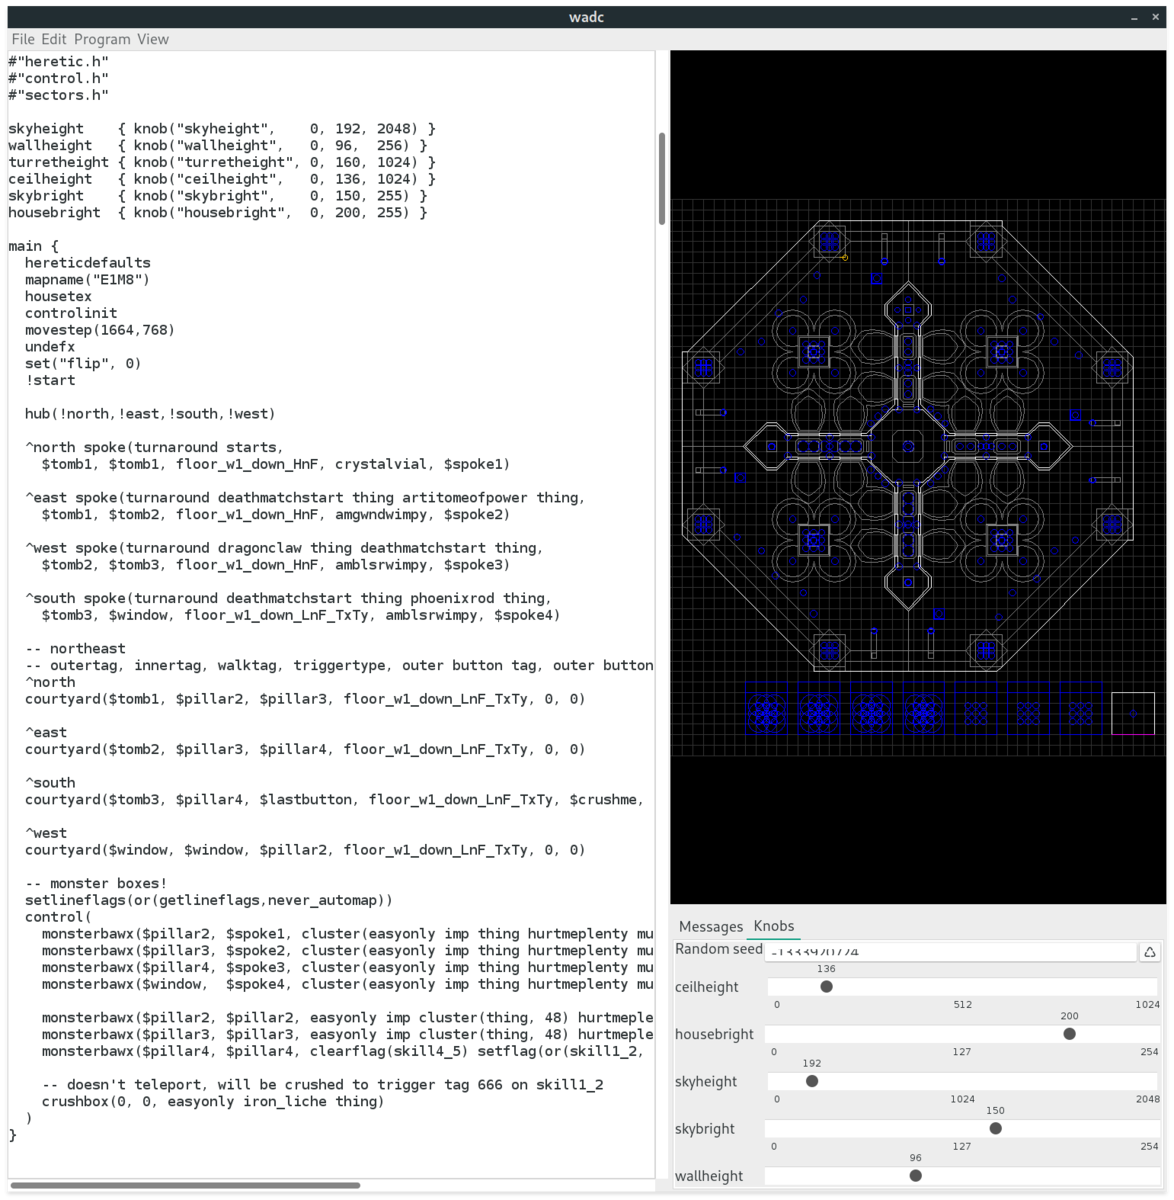
Example map with tuneables on the right Example map with tuneables on the right
WadC the procedural programming environment for generating Doom maps version 3.1 has been released. The majority of this was done a long time ago, but I've dragged my feet in releasing it. I've said this before, but this is intended to be the last release I do of WadC. The headline feature for this release is the introduction of a tuning concept I had for the UI. It occurred to me that a beginner to WadC might want to load up an example program which is potentially very complex and hard to unpick to figure out how it works. If the author could mark certain variables as "tuneable", the UI could provide an easy way for someone to tweak parameters and then see what happened. I had in mind the walls of patch panels and knobs you see with analog synthesizers: tweak this thing over here and see what happens over there. I think this kind of feature would be useful in other, similar programming environments, like OpenSCAD: I don't think they do yet, but I could be wrong.
Kayvan and Me, riding horse statues, somewhere in Germany, in the 1990s
This release of WadC is dedicated to the memory of Kayvan Walker (1983-2022). Kayvan was a childhood friend who committed suicide in March this year. Back in the nineties, Kayvan was responsible for introducing me to Doom in the first place: I used to visit his house on the way home to mine, as it was on the walk back from School. His mum works in IT and always encouraged us into it. Doom was so far ahead, in technical terms, of any other computer game I'd ever seen, and was the closest thing we had to virtual reality: we could create our own worlds. It's in no small part thanks to Kayvan and his Mum that I'm still creating worlds, nearly thirty years later. I owe my career and most of my hobbies to those pivotal moments. Thank you both. Kayvan did a lot more for me than just introduce me to Doom, or computing. He was one of a set of friends that I had every confidence that, no matter what, we would always be friends, through thick and thin. I miss him terribly. Please, if you reading this, are suffering, talk to someone. In the UK you can talk to Samaritans on 116 123.

25 June 2022

Ryan Kavanagh: Routable network addresses with OpenIKED and systemd-networkd

I ve been using OpenIKED for some time now to configure my VPN. One of its features is that it can dynamically assign addresses on the internal network to clients, and clients can assign these addresses and routes to interfaces. However, these interfaces must exist before iked can start. Some months ago I switched my Debian laptop s configuration from the traditional ifupdown to systemd-networkd. It took me some time to figure out how to have systemd-networkd create dummy interfaces on which iked can install addresses, but also not interfere with iked by trying to manage these interfaces. Here is my working configuration. First, I have systemd create the interface dummy1 by creating a systemd.netdev(5) configuration file at /etc/systemd/network/20-dummy1.netdev:
[NetDev]
Name=dummy1
Kind=dummy 
Then I tell systemd not to manage this interface by creating a systemd.network(5) configuration file at /etc/systemd/network/20-dummy1.network:
[Match]
Name=dummy1
Unmanaged=yes
Restarting systemd-networkd causes these interfaces to get created, and we can then check their status using networkctl(8):
$ systemctl restart systemd-networkd.service
$ networkctl
IDX LINK     TYPE     OPERATIONAL SETUP
  1 lo       loopback carrier     unmanaged
  2 enp2s0f0 ether    off         unmanaged
  3 enp5s0   ether    off         unmanaged
  4 dummy1   ether    degraded    configuring
  5 dummy3   ether    degraded    configuring
  6 sit0     sit      off         unmanaged
  8 wlp3s0   wlan     routable    configured
  9 he-ipv6  sit      routable    configured

8 links listed.
Finally, I configure my flows in /etc/iked.conf, making sure to assign the received address to the interface dummy1.
ikev2 'hades' active esp \
        from dynamic to 10.0.1.0/24 \
        peer hades.rak.ac \
        srcid '/CN=asteria.rak.ac' \
        dstid '/CN=hades.rak.ac' \
        request address 10.0.1.103 \
        iface dummy1
Restarting openiked and checking the status of the interface reveals that it has been assigned an address on the internal network and that it is routable:
$ systemctl restart openiked.service
$ networkctl status dummy1
  4: dummy1
                     Link File: /usr/lib/systemd/network/99-default.link
                  Network File: /etc/systemd/network/20-dummy1.network
                          Type: ether
                          Kind: dummy
                         State: routable (configured)
                  Online state: online
                        Driver: dummy
              Hardware Address: 22:50:5f:98:a1:a9
                           MTU: 1500
                         QDisc: noqueue
  IPv6 Address Generation Mode: eui64
          Queue Length (Tx/Rx): 1/1
                       Address: 10.0.1.103
                                fe80::2050:5fff:fe98:a1a9
                           DNS: 10.0.1.1
                 Route Domains: .
             Activation Policy: up
           Required For Online: yes
             DHCP6 Client DUID: DUID-EN/Vendor:0000ab11aafa4f02d6ac68d40000
I d be happy to hear if there are simpler or more idiomatic ways to configure this under systemd.

24 June 2022

Reproducible Builds: Supporter spotlight: Hans-Christoph Steiner of the F-Droid project

The Reproducible Builds project relies on several projects, supporters and sponsors for financial support, but they are also valued as ambassadors who spread the word about our project and the work that we do. This is the fifth instalment in a series featuring the projects, companies and individuals who support the Reproducible Builds project. We started this series by featuring the Civil Infrastructure Platform project and followed this up with a post about the Ford Foundation as well as a recent ones about ARDC, the Google Open Source Security Team (GOSST) and Jan Nieuwenhuizen on Bootstrappable Builds, GNU Mes and GNU Guix. Today, however, we will be talking with Hans-Christoph Steiner from the F-Droid project.

Chris: Welcome, Hans! Could you briefly tell me about yourself? Hans: Sure. I spend most of my time trying to private communications software usable by everyone, designing interactive software with a focus on human perceptual capabilities and building networks with free software. I ve been involved in Debian since approximately 2008 and became an official Debian developer in 2011. In the little time left over from that, I sometimes compose music with computers from my home in Austria.
Chris: For those who have not heard of it before, what is the F-Droid project? Hans: F-Droid is a community-run app store that provides free software applications for Android phones. First and foremost our goal is to represent our users. In particular, we review all of the apps that we distribute, and these reviews not only check for whether something is definitely free software or not, we additionally look for ethical problems with applications as well issues that we call Anti-Features . Since the project began in 2010, F-Droid now offers almost 4,000 free-software applications. F-Droid is also a app store kit as well, providing all the tools that are needed to operate an free app store of your own. It also includes complete build and release tools for managing the process of turning app source code into published builds.
Chris: How exactly does F-Droid differ from the Google Play store? Why might someone use F-Droid over Google Play? Hans: One key difference to the Google Play Store is that F-Droid does not ship proprietary software by default. All apps shipped from f-droid.org are built from source on our own builders. This is partly because F-Droid is backed by the free software community; that is, people who have engaged in the free software community long before Android was conceived, and, in particular, share many if not all of its values. Using F-Droid will therefore feel very familiar to anyone familiar with a modern Linux distribution.
Chris: How do you describe reproducibility from the F-Droid point of view? Hans: All centralised software repositories are extremely tempting targets for exploitation by malicious third parties, and the kinds of personal or otherwise sensitive data on our phones only increase this risk. In F-Droid s case, not only could the software we distribute be theoretically replaced with nefarious copies, the build infrastructure that generates that software could be compromised as well. F-Droid having reproducible builds is extremely important as it allows us to verify that our build systems have not been compromised and distributing malware to our users. In particular, if an independent build infrastructure can produce precisely the same results from a build, then we can be reasonably sure that they haven t been compromised. Technically-minded users can also validate their builds on their own systems too, further increasing trust in our build infrastructure. (This can be performed using fdroid verify command.) Our signature & trust scheme means that F-Droid can verify that an app is 100% free software whilst still using the developer s original .APK file. More details about this may be found in our reproducibility documentation and on the page about our Verification Server.
Chris: How do you see F-Droid fitting into the rest of the modern security ecosystem? Hans: Whilst F-Droid inherits all of the social benefits of free software, F-Droid takes special care to respect your privacy as well we don t attempt to track your device in any way. In particular, you don t need an account to use the F-Droid client, and F-Droid doesn t send any device-identifying information to our servers other than its own version number. What is more, we mark all apps in our repository that track you, and users can choose to hide any apps that has been tagged with a specific Anti-Feature in the F-Droid settings. Furthermore, any personal data you decide to give us (such as your email address when registering for a forum account) goes no further than us as well, and we pledge that it will never be used for anything beyond merely maintaining your account.
Chris: What would fully reproducible mean to F-Droid? What it would look like if reproducibility was a solved problem ? Or, rather, what would be your ultimate reproducibility goals? Hans: In an ideal world, every application submitted to F-Droid would not only build reproducibly, but would come with a cryptographically-signed signature from the developer as well. Then we would only distribute an compiled application after a build had received a number of matching signatures from multiple, independent third parties. This would mean that our users were not placing their trust solely in software developers machines, and wouldn t be trusting our centralised build servers as well.
Chris: What are the biggest blockers to reaching this state? Are there any key steps or milestones to get there? Hans: Time is probably the main constraint to reaching this goal. Not only do we need system administrators on an ongoing basis but we also need to incorporate reproducibly checks into our Continuous Integration (CI) system. We are always looking for new developers to join our effort, as well as learning about how to better bring them up to speed. Separate to this, we often experience blockers with reproducibility-related bugs in the Android build tooling. Luckily, upstreams do ultimately address these issues, but in some cases this has taken three or four years to reach end-users and developers. Unfortunately, upstream is not chiefly concerned with the security aspects of reproducibility builds; they care more about how it can minimise and optimise download size and speed.
Chris: Are you tracking any statistics about reproducibility in F-Droid over time? If so, can you share them? Does F-Droid track statistics about its own usage? Hans: To underline a topic touched on above, F-Droid is dedicated to preserving the privacy of its users; we therefore do not record usage statistics. This is, of course, in contrast to other application stores. However, we are in a position to track whether packages in F-Droid are reproducible or not. As in: what proportion of APKs in F-Droid have been independently verified over time? Unfortunately, due to time constraints, we do not yet automatically publish charts for this. We do publish some raw data that is related, though, and we naturally welcome contributions of visualizations based on any and all of our data. The All our APIs page on our wiki is a good place to start for someone wanting to contribute, everything about reproducible F-Droid apps is available in JSON format, what s missing are apps or dashboards making use of the available raw data.
Chris: Many thanks for this interview, Hans, and for all of your work on F-Droid and elsewhere. If someone wanted to get in touch or learn more about the project, where might someone go? Hans: The best way to find out about F-Droid is, of course, the main F-Droid homepage, but we are also on Twitter @fdroidorg. We have many avenues to participate and to learn more! We have an About page on our website and a thriving forum. We also have part of our documentation specifically dedicated to reproducible builds.


For more information about the Reproducible Builds project, please see our website at reproducible-builds.org. If you are interested in ensuring the ongoing security of the software that underpins our civilisation and wish to sponsor the Reproducible Builds project, please reach out to the project by emailing contact@reproducible-builds.org.

Russ Allbery: Review: A Dead Djinn in Cairo

Review: A Dead Djinn in Cairo, by P. Dj l Clark
Publisher: Tordotcom
Copyright: May 2016
ASIN: B01DJ0NALI
Format: Kindle
Pages: 47
Fatma el-Sha'arawi is a special investigator with the Egyptian Ministry of Alchemy, Enchantments, and Supernatural Entities in an alternate 1912 Egypt. In Fatma's world, the mystic al-Jahiz broke through to the realm of the djinn in the late 1800s, giving Egypt access to magic and the supernatural and the djinn access to Egypt. It is now one of the great powers of the world, able to push off the Europeans and control its own politics. This is a Tor.com original novelette, so you can read it on-line for free or drop $2 on a Kindle version for convenience. It's the first story in the "Dead Djinn" universe, in which Clark has also written a novella and a novel (the latter of which won the Nebula Award for best novel in 2022). There are three things here I liked. Fatma is a memorable character, both for her grumpy demeanor as a rare female investigator having to put up with a sexist pig of a local police liaison, and for her full British attire (including a bowler hat) and its explanation. (The dynamics felt a bit modern for a story set in 1912, but not enough to bother me.) The setting is Arabian-inspired fantasy, which is a nice break from the normal European or Celtic stuff. And there are interesting angels (Fatma: "They're not really angels"), which I think have still-underused potential, particularly when they can create interesting conflicts with Coptic Christianity and Islam. Clark's version are energy creatures of some sort inside semi-mechanical bodies with visuals that reminded me strongly of Diablo III (which in this context is a compliment). I'm interested to learn more about them, although I hope there's more going on than the disappointing explanation we get at the end of this story. Other than those elements, there's not much here. As hinted by the title, the story is structured as a police investigation and Fatma plays the misfit detective. But there's no real mystery; the protagonists follow obvious clue to obvious clue to obvious ending. The plot structure is strictly linear and never surprised me. Aasim is an ass, which gives Fatma something to react to but never becomes real characterization. The world-building is the point, but most of it is delivered in infodumps, and the climax is a kind-of-boring fight where the metaphysics are explained rather than discovered. I'm possibly being too harsh. There's space for novelettes that tell straightforward stories without the need for a twist or a sting. But I admit I found this boring. I think it's because it's not tight enough to be carried by the momentum of a simple plot, and it's also not long enough for either the characters or the setting to breathe and develop. The metaphysics felt rushed and the characterization cramped. I liked Siti and the dynamic between Siti and Fatma at the end of the story, but there wasn't enough of it. As a world introduction, it does its job, and the non-European fantasy background is interesting enough that I'd be willing to read more, even without the incentive of reading all award winning novels. But "A Dead Djinn in Cairo" doesn't do more than its job. It might be worth skipping (I'll have to read the subsequent works to know for certain), but it won't take long to read and the price is right. Followed by The Haunting of Tram Car 015. Rating: 6 out of 10

23 June 2022

Raphaël Hertzog: Freexian s report about Debian Long Term Support, May 2022

A Debian LTS logo
Like each month, have a look at the work funded by Freexian s Debian LTS offering. Debian project funding Two [1, 2] projects are in the pipeline now. Tryton project is in a final phase. Gradle projects is fighting with technical difficulties. In May, we put aside 2233 EUR to fund Debian projects. We re looking forward to receive more projects from various Debian teams! Learn more about the rationale behind this initiative in this article. Debian LTS contributors In May, 14 contributors have been paid to work on Debian LTS, their reports are available: Evolution of the situation In May we released 49 DLAs. The security tracker currently lists 71 packages with a known CVE and the dla-needed.txt file has 65 packages needing an update. The number of paid contributors increased significantly, we are pleased to welcome our latest team members: Andreas R nnquist, Dominik George, Enrico Zini and Stefano Rivera. It is worth pointing out that we are getting close to the end of the LTS period for Debian 9. After June 30th, no new security updates will be made available on security.debian.org. We are preparing to overtake Debian 10 Buster for the next two years and to make this process as smooth as possible. But Freexian and its team of paid Debian contributors will continue to maintain Debian 9 going forward for the customers of the Extended LTS offer. If you have Debian 9 servers to keep secure, it s time to subscribe! You might not have noticed, but Freexian formalized a mission statement where we explain that our purpose is to help improve Debian. For this, we want to fund work time for the Debian developers that recently joined Freexian as collaborators. The Extended LTS and the PHP LTS offers are built following a model that will help us to achieve this if we manage to have enough customers for those offers. So consider subscribing: you help your organization but you also help Debian! Thanks to our sponsors Sponsors that joined recently are in bold.

21 June 2022

Louis-Philippe V ronneau: Montreal's Debian & Stuff - June 2022

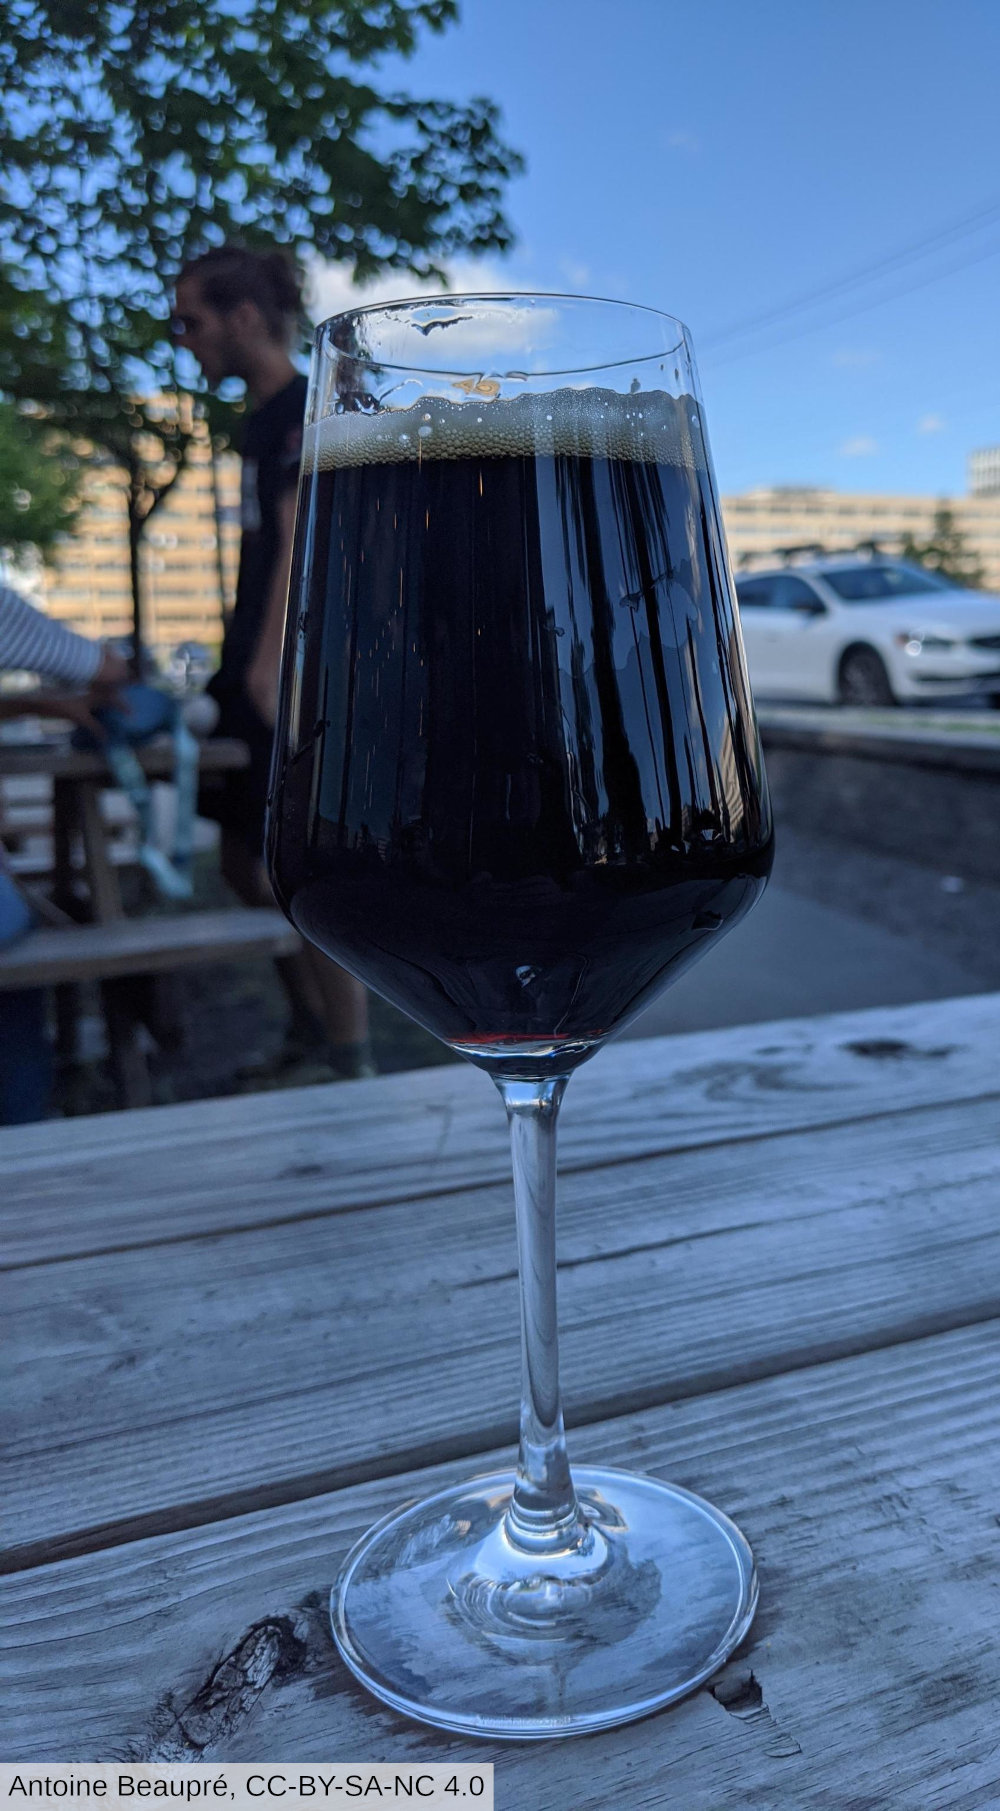
As planned, we held our second local Debian meeting of the year last Sunday. We met at the lovely Eastern Bloc (an artists' hacklab) to work on Debian (and other stuff!), chat and socialise. Although there were fewer people than at our last meeting1, we still did a lot of work! I worked on fixing a bunch of bugs in Clojure packages2, LeLutin worked on podman and packaged libinfluxdb-http-perl and anarcat worked on internetarchive, trocla and moneta. Olivier also came by and worked on debugging his Kali install. We are planning to have our next meeting at the end of August. If you are interested, the best way to stay in touch is either to subscribe to our mailing list or to join our IRC channel (#debian-quebec on OFTC). Events are also posted on Quebec's Agenda du libre. Many thanks to Debian for providing us a budget to rent the venue for the day and for the pizza! Here is a nice picture anarcat took of (one of) the glasses of porter we had afterwards, at the next door brewery: A glass of English Porter from Silo Brewery
  1. Summer meetings are always less populous and it also happened to be Father's Day...
  2. #1012824, #1011856, #1011837, #1011844, #1011864 and #1011967.

20 June 2022

Iustin Pop: Experiment: A week of running

My sports friends know that I wasn t able to really run in many, many years, due to a recurring injury that was not fully diagnosed and which, after many sessions with the doctor, ended up with OK-ish state for day-to-day life but also with these words: Maybe, running is just not for you? The year 2012 was my running year . I went to a number of races, wrote blog posts, then slowly started running only rarely, then a few years later I was really only running once in a while, and coupled with a number of bad ideas of the type lets run today after a long break, but a lot , I started injuring my foot. Add a few more years, some more kilograms on my body, a one event of jumping with a kid on my shoulders and landing on my bad foot, and the setup was complete. Doctor visits, therapy, slow improvements, but not really solving the problem. 6 months breaks, small attempts at running, pain again, repeat, pain again, etc. It ended up with me acknowledging that yes, maybe running is not for me, and I should really give it up. Incidentally, in 2021, as part of me trying to improve my health/diet, I tried some thing that is not important for this post and for the first time in a long time, I was fully, 100%, pain free in my leg during day-to-day activities. Huh, maybe this is not purely related to running? From that point on, my foot became, very slowly, better. I started doing short runs (2-3km), especially on holidays where I can t bike, and if I was careful, it didn t go too bad. But I knew I can t run, so these were rare events. In April this year, on vacation, I run a couple of times - 20km distance. In May, 12km. Then, there was a Garmin Badge I really wanted, so against my good judgement, I did a run/walk (2:1 ratio) the previous weekend, and to my surprise, no unwanted side-effect. And I got an idea: what if I do short run/walks an entire week? When does my foot break ? I mean, by now I knew that a short (3-4, maybe 5km) run that has pauses doesn t negatively impact my foot. What about the 2nd one? Or the 3rd one? When does it break? Is it distance, or something else? The other problem was - when to run? I mean, on top of hybrid work model. When working from home, all good, but when working from the office? So the other, somewhat more impossible task for me, was to wake up early and run before 8 AM. Clearly destined to fail! But, the following day (Monday), I did wake up and 3km. Then Tuesday again, 3.3km (and later, one hour of biking). Wed - 3.3km. Thu - 4.40km, at 4:1 ratio (2m:30s). Friday, 3.7km (4:1), plus a very long for me (112km) bike ride. By this time, I was physically dead. Not my foot, just my entire body. On Saturday morning, Training Peaks said my form is -52, and it starts warning below -15. I woke up late and groggy, and I had to extra motivate myself to go for the last, 5.3km run, to round up the week. On Friday and Saturday, my problem leg did start to how to say, remind me it is problematic? But not like previously, no waking in the morning with a stiff tendon. No, just not fully happy. And, to my surprise, correlated again with my consumption of problematic food (I was getting hungrier and hungrier, and eating too much of things I should keep an eye on). At this point, with the week behind me: Did my experiment make me wiser? Not really. Happier? Yes, 100%. I plan to buy some new running clothes, my current ones are really old. But did I really understand how my body function? A loud no. Sigh. The next challenge will be, how to manage my time across multiple sports (and work, and family, and other hobbies). Still, knowing that I can anytime go for 25-35 minutes of running, without preparation, is very reassuring. Freedom, health and injury-free sports to everyone!

Petter Reinholdtsen: My free software activity of late (2022)

I guess it is time to bring some light on the various free software and open culture activities and projects I have worked on or been involved in the last year and a half. First, lets mention the book releases I managed to publish. The Cory Doctorow book "Hvordan knuse overv kningskapitalismen" argue that it is not the magic machine learning of the big technology companies that causes the surveillance capitalism to thrive, it is the lack of trust busting to enforce existing anti-monopoly laws. I also published a family of dictionaries for machinists, one sorted on the English words, one sorted on the Norwegian and the last sorted on the North S mi words. A bit on the back burner but not forgotten is the Debian Administrators Handbook, where a new edition is being worked on. I have not spent as much time as I want to help bring it to completion, but hope I will get more spare time to look at it before the end of the year. With my Debian had I have spent time on several projects, both updating existing packages, helping to bring in new packages and working with upstream projects to try to get them ready to go into Debian. The list is rather long, and I will only mention my own isenkram, openmotor, vlc bittorrent plugin, xprintidle, norwegian letter style for latex, bs1770gain, and recordmydesktop. In addition to these I have sponsored several packages into Debian, like audmes. The last year I have looked at several infrastructure projects for collecting meter data and video surveillance recordings. This include several ONVIF related tools like onvifviewer and zoneminder as well as rtl-433, wmbusmeters and rtl-wmbus. In parallel with this I have looked at fabrication related free software solutions like pycam and LinuxCNC. The latter recently gained improved translation support using po4a and weblate, which was a harder nut to crack that I had anticipated when I started. Several hours have been spent translating free software to Norwegian Bokm l on the Weblate hosted service. Do not have a complete list, but you will find my contributions in at least gnucash, minetest and po4a. I also spent quite some time on the Norwegian archiving specification Noark 5, and its companion project Nikita implementing the API specification for Noark 5. Recently I have been looking into free software tools to do company accounting here in Norway., which present an interesting mix between law, rules, regulations, format specifications and API interfaces. I guess I should also mention the Norwegian community driven government interfacing projects Mimes Br nn and Fiksgatami, which have ended up in a kind of limbo while the future of the projects is being worked out. These are just a few of the projects I have been involved it, and would like to give more visibility. I'll stop here to avoid delaying this post. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Jamie McClelland: A very liberal spam assassin rule

I just sent myself a test message via Powerbase (a hosted CiviCRM project for community organizers) and it didn t arrive. Wait, nope, there it is in my junk folder with a spam score of 6!
X-Spam-Status: Yes, score=6.093 tagged_above=-999 required=5
	tests=[BAYES_00=-1.9, DKIM_SIGNED=0.1, DKIM_VALID=-0.1,
	DKIM_VALID_AU=-0.1, DKIM_VALID_EF=-0.1, DMARC_MISSING=0.1,
	HTML_MESSAGE=0.001, KAM_WEBINAR=3.5, KAM_WEBINAR2=3.5,
	NO_DNS_FOR_FROM=0.001, SPF_HELO_NONE=0.001, ST_KGM_DEALS_SUB_11=1.1,
	T_SCC_BODY_TEXT_LINE=-0.01] autolearn=no autolearn_force=no
What just happened? A careful look at the scores suggest that the KAM_WEBINAR and KAM_WEBINAR2 rules killed me. I ve never heard of them (this email came through a system I m not administering). So, I did some searching and found a page with the rules:
# SEMINARS AND WORKSHOPS SPAM
header   __KAM_WEBINAR1 From =~ /education career manage learning webinar project efolder/i
header   __KAM_WEBINAR2 Subject =~ /last chance increase productivity workplace morale payroll dept trauma.training case.study issues follow.up service.desk vip.(lunch breakfast) manage.your private.business professional.checklist customers.safer great.timesaver prep.course crash.course hunger.to.learn (keys tips).(to for).smarter/i
header   __KAM_WEBINAR3 Subject =~ /webinar strateg seminar owners.meeting webcast our.\d.new sales.video/i
body     __KAM_WEBINAR4 /executive.education contactid register now \d+.minute webinar management.position supervising.skills discover.tips register.early take.control marketing.capabilit drive.more.sales leveraging.cloud solution.provider have.a.handle plan.to.divest being.informed upcoming.webinar spearfishing.email increase.revenue industry.podcast \d+.in.depth.tips early.bird.offer pmp.certified lunch.briefing/i

meta     KAM_WEBINAR (__KAM_WEBINAR1 + __KAM_WEBINAR2 + __KAM_WEBINAR3 + __KAM_WEBINAR4 >= 3)
describe KAM_WEBINAR Spam for webinars
score    KAM_WEBINAR 3.5

meta     KAM_WEBINAR2 (__KAM_WEBINAR1 + __KAM_WEBINAR2 + __KAM_WEBINAR3 + __KAM_WEBINAR4 >= 4)
describe KAM_WEBINAR2 Spam for webinars
score    KAM_WEBINAR2 3.5
For those of you who don t care to parse those regular expressions, here s a summary: Hm. I m glad I can now fix our email, but this doesn t work so well for people with a name that includes project that like to organize webinars for which you have to register.

19 June 2022

Dirk Eddelbuettel: #38: Faster Feedback Systems

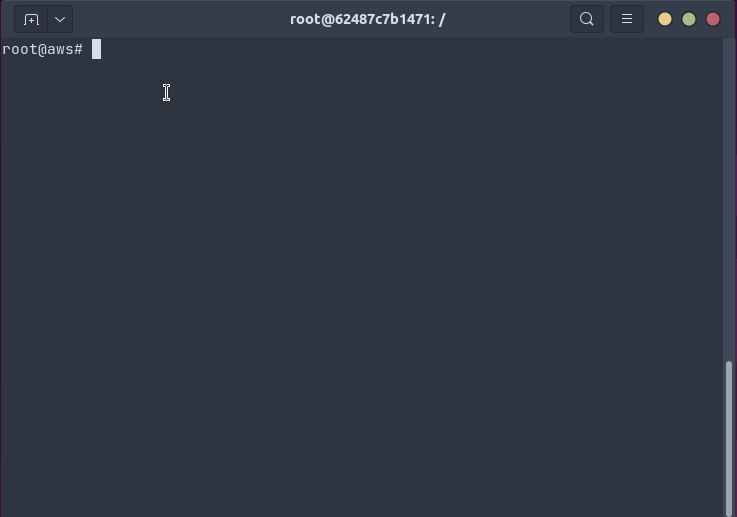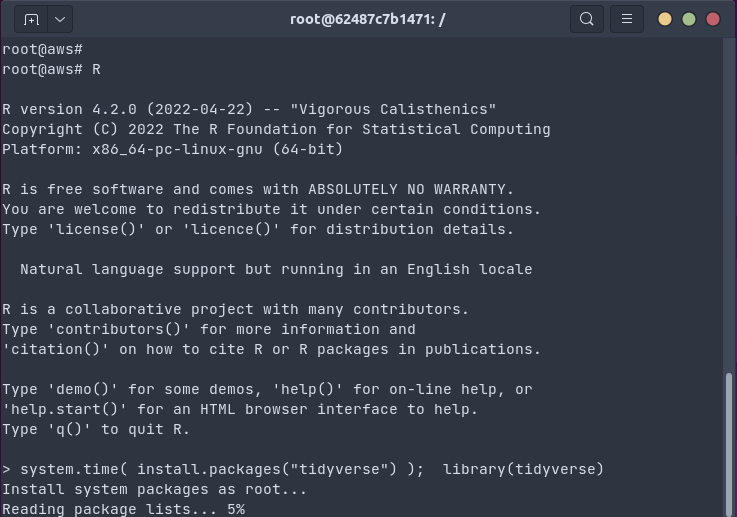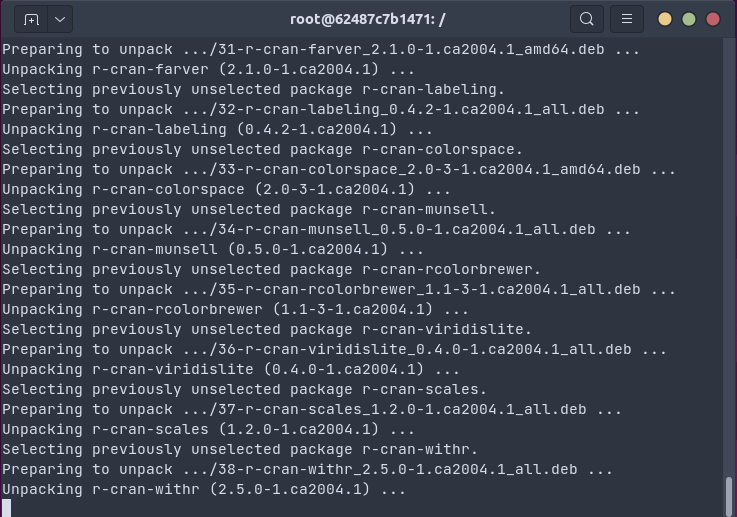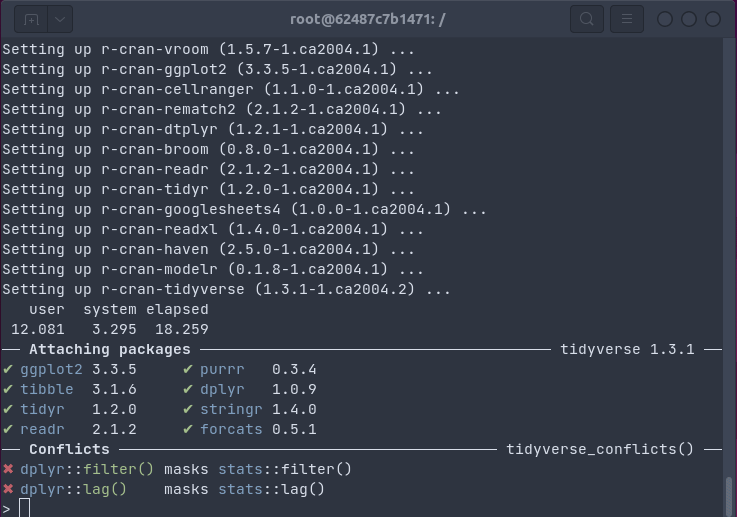
Engineers build systems. Good engineers always stress and focus efficiency of these systems. Two recent examples of engineering thinking follow. One was in a video / podcast interview with Martin Thompson (who is a noted high-performance code expert) I came across recently. The overall focus of the hour-long interview is on managing software complexity . Around minute twenty-two, the conversation turns to feedback loops and systems, and a strong preference for simple and fast systems for more immediate feedback. An important topic indeed. The second example connects to this and permeates many tweets and other writings by Erik Bernhardsson. He had an earlier 2017 post on Optimizing for iteration speed , as well as a 17 May 2022 tweet on minimizing feedback loop size, another 28 Mar 2022 tweet reply on shorter feedback loops, then a 14 Feb 2022 post on problems with slow feedback loops, as well as a 13 Jan 2022 post on a priority for tighter feedback loops, and lastly a 23 Jul 2021 post on fast feedback cycles. You get the idea: Erik really digs faster feedback loops. Nobody likes to wait: immediatecy wins each time. A few years ago, I had touched on this topic with two posts on how to make (R) package compilation (and hence installation) faster. One idea (which I still use whenever I must compile) was in post #11 on caching compilation. Another idea was in post #13: make it faster by not doing it, in this case via binary installation which skip the need for compilation (and which is what I aim for with, say, CI dependencies). Several subsequent posts can be found by scrolling down the r^4 blog section: we stressed the use of the amazing Rutter PPA c2d4u for CRAN binaries (often via Rocker containers, the (post #28) promise of RSPM, and the (post #29) awesomeness of bspm. And then in the more recent post #34 from last December we got back to a topic which ties all these things together: Dependencies. We quoted Mies van der Rohe: Less is more. Especially when it comes to dependencies as these elongate the feedback loop and thereby delay feedback. Our most recent post #37 on r2u connects these dots. Access to a complete set of CRAN binaries with full-dependency resolution accelerates use and installation. This of course also covers testing and continuous integration. Why wait minutes to recompile the same packages over and over when you can install the full Tidyverse in 18 seconds or the brms package and all it needs in 13 seconds as shown in the two gifs also on the r2u documentation site. You can even power up the example setup of the second gif via this gitpod link giving you a full Ubuntu 22.04 session in your browser to try this: so go forth and install something from CRAN with ease! The benefit of a system such our r2u CRAN binaries is clear: faster feedback loops. This holds whether you work with few or many dependencies, tiny or tidy. Faster matters, and feedback can be had sooner. And with the title of this post we now get a rallying cry to advocate for faster feedback systems: FFS .

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

John Goerzen: Pipes, deadlocks, and strace annoyingly fixing them

This is a complex tale I will attempt to make simple(ish). I ve (re)learned more than I cared to about the details of pipes, signals, and certain system calls and the solution is still elusive. For some time now, I have been using NNCP to back up my files. These backups are sent to my backup system, which effectively does this to process them (each ZFS send is piped to a shell script that winds up running this):
gpg -q -d   zstdcat -T0   zfs receive -u -o readonly=on "$STORE/$DEST"
This processes tens of thousands of zfs sends per week. Recently, having written Filespooler, I switched to sending the backups using Filespooler over NNCP. Now fspl (the Filespooler executable) opens the file for each stream and then connects it to what amounts to this pipeline:
bash -c 'gpg -q -d 2>/dev/null   zstdcat -T0'   zfs receive -u -o readonly=on "$STORE/$DEST"
Actually, to be more precise, it spins up the bash part of it, reads a few bytes from it, and then connects it to the zfs receive. And this works well almost always. In something like 1/1000 of the cases, it deadlocks, and I still don t know why. But I can talk about the journey of trying to figure it out (and maybe some of you will have some ideas). Filespooler is written in Rust, and uses Rust s Command system. Effectively what happens is this:
  1. The fspl process has a File handle, which after forking but before invoking bash, it dup2 s to stdin.
  2. The connection between bash and zfs receive is a standard Unix pipe.
I cannot get the problem to duplicate when I run the entire thing under strace -f. So I am left trying to peek at it from the outside. What happens if I try to attach to each component with strace -p? So the plot thickens! Why would connecting to zstdcat and zfs receive cause them to actually change behavior? strace works by using the ptrace system call, and ptrace in a number of cases requires sending SIGSTOP to a process. In a complicated set of circumstances, a system call may return EINTR when a SIGSTOP is received, with the idea that the system call should be retried. I can t see, from either zstdcat or zfs, if this is happening, though. So I thought, how about having Filespooler manually copy data from bash to zfs receive in a read/write loop instead of having them connected directly via a pipe? That is, there would be two pipes going there: one where Filespooler reads from the bash command, and one where it writes to zfs. If nothing else, I could instrument it with debugging. And so I did, and I found that when it deadlocked, it was deadlocking on write but with no discernible pattern as to where or when. So I went back to directly connected. In analyzing straces, I found a Rust bug which I reported in which it is failing to close the read end of a pipe in the parent post-fork. However, having implemented a workaround for this, it doesn t prevent the deadlock so this is orthogonal to the issue at hand. Among the two strange things here are things returning to normal when I attach strace to zstdcat, and things crashing when I attach strace to zfs. I decided to investigate the latter. It turns out that the ZFS code that is reading from stdin during zfs receive is in the kernel module, not userland. Here is the part that is triggering the imcomplete stream error:
                int err = zfs_file_read(fp, (char *)buf + done,
                    len - done, &resid);
                if (resid == len - done)  
                        /*
                         * Note: ECKSUM or ZFS_ERR_STREAM_TRUNCATED indicates
                         * that the receive was interrupted and can
                         * potentially be resumed.
                         */
                        err = SET_ERROR(ZFS_ERR_STREAM_TRUNCATED);
                 
resid is an output parameter with the number of bytes remaining from a short read, so in this case, if the read produced zero bytes, then it sets that error. What s zfs_file_read then? It boils down to a thin wrapper around kernel_read(). This winds up calling __kernel_read(), which calls read_iter on the pipe, which is pipe_read(). That s where I don t have the knowledge to get into the weeds right now. So it seems likely to me that the problem has something to do with zfs receive. But, what, and why does it only not work in this one very specific situation, and only so rarely? And why does attaching strace to zstdcat make it all work again? I m indeed puzzled! Update 2022-06-20: See the followup post which identifies this as likely a kernel bug and explains why this particular use of Filespooler made it easier to trigger.

17 June 2022

Antoine Beaupr : Matrix notes

I have some concerns about Matrix (the protocol, not the movie that came out recently, although I do have concerns about that as well). I've been watching the project for a long time, and it seems more a promising alternative to many protocols like IRC, XMPP, and Signal. This review may sound a bit negative, because it focuses on those concerns. I am the operator of an IRC network and people keep asking me to bridge it with Matrix. I have myself considered just giving up on IRC and converting to Matrix. This space is a living document exploring my research of that problem space. The TL;DR: is that no, I'm not setting up a bridge just yet, and I'm still on IRC. This article was written over the course of the last three months, but I have been watching the Matrix project for years (my logs seem to say 2016 at least). The article is rather long. It will likely take you half an hour to read, so copy this over to your ebook reader, your tablet, or dead trees, and lean back and relax as I show you around the Matrix. Or, alternatively, just jump to a section that interest you, most likely the conclusion.

Introduction to Matrix Matrix is an "open standard for interoperable, decentralised, real-time communication over IP. It can be used to power Instant Messaging, VoIP/WebRTC signalling, Internet of Things communication - or anywhere you need a standard HTTP API for publishing and subscribing to data whilst tracking the conversation history". It's also (when compared with XMPP) "an eventually consistent global JSON database with an HTTP API and pubsub semantics - whilst XMPP can be thought of as a message passing protocol." According to their FAQ, the project started in 2014, has about 20,000 servers, and millions of users. Matrix works over HTTPS but over a special port: 8448.

Security and privacy I have some concerns about the security promises of Matrix. It's advertised as a "secure" with "E2E [end-to-end] encryption", but how does it actually work?

Data retention defaults One of my main concerns with Matrix is data retention, which is a key part of security in a threat model where (for example) an hostile state actor wants to surveil your communications and can seize your devices. On IRC, servers don't actually keep messages all that long: they pass them along to other servers and clients as fast as they can, only keep them in memory, and move on to the next message. There are no concerns about data retention on messages (and their metadata) other than the network layer. (I'm ignoring the issues with user registration, which is a separate, if valid, concern.) Obviously, an hostile server could log everything passing through it, but IRC federations are normally tightly controlled. So, if you trust your IRC operators, you should be fairly safe. Obviously, clients can (and often do, even if OTR is configured!) log all messages, but this is generally not the default. Irssi, for example, does not log by default. IRC bouncers are more likely to log to disk, of course, to be able to do what they do. Compare this to Matrix: when you send a message to a Matrix homeserver, that server first stores it in its internal SQL database. Then it will transmit that message to all clients connected to that server and room, and to all other servers that have clients connected to that room. Those remote servers, in turn, will keep a copy of that message and all its metadata in their own database, by default forever. On encrypted rooms those messages are encrypted, but not their metadata. There is a mechanism to expire entries in Synapse, but it is not enabled by default. So one should generally assume that a message sent on Matrix is never expired.

GDPR in the federation But even if that setting was enabled by default, how do you control it? This is a fundamental problem of the federation: if any user is allowed to join a room (which is the default), those user's servers will log all content and metadata from that room. That includes private, one-on-one conversations, since those are essentially rooms as well. In the context of the GDPR, this is really tricky: who is the responsible party (known as the "data controller") here? It's basically any yahoo who fires up a home server and joins a room. In a federated network, one has to wonder whether GDPR enforcement is even possible at all. But in Matrix in particular, if you want to enforce your right to be forgotten in a given room, you would have to:
  1. enumerate all the users that ever joined the room while you were there
  2. discover all their home servers
  3. start a GDPR procedure against all those servers
I recognize this is a hard problem to solve while still keeping an open ecosystem. But I believe that Matrix should have much stricter defaults towards data retention than right now. Message expiry should be enforced by default, for example. (Note that there are also redaction policies that could be used to implement part of the GDPR automatically, see the privacy policy discussion below on that.) Also keep in mind that, in the brave new peer-to-peer world that Matrix is heading towards, the boundary between server and client is likely to be fuzzier, which would make applying the GDPR even more difficult. Update: this comment links to this post (in german) which apparently studied the question and concluded that Matrix is not GDPR-compliant. In fact, maybe Synapse should be designed so that there's no configurable flag to turn off data retention. A bit like how most system loggers in UNIX (e.g. syslog) come with a log retention system that typically rotate logs after a few weeks or month. Historically, this was designed to keep hard drives from filling up, but it also has the added benefit of limiting the amount of personal information kept on disk in this modern day. (Arguably, syslog doesn't rotate logs on its own, but, say, Debian GNU/Linux, as an installed system, does have log retention policies well defined for installed packages, and those can be discussed. And "no expiry" is definitely a bug.

Matrix.org privacy policy When I first looked at Matrix, five years ago, Element.io was called Riot.im and had a rather dubious privacy policy:
We currently use cookies to support our use of Google Analytics on the Website and Service. Google Analytics collects information about how you use the Website and Service. [...] This helps us to provide you with a good experience when you browse our Website and use our Service and also allows us to improve our Website and our Service.
When I asked Matrix people about why they were using Google Analytics, they explained this was for development purposes and they were aiming for velocity at the time, not privacy (paraphrasing here). They also included a "free to snitch" clause:
If we are or believe that we are under a duty to disclose or share your personal data, we will do so in order to comply with any legal obligation, the instructions or requests of a governmental authority or regulator, including those outside of the UK.
Those are really broad terms, above and beyond what is typically expected legally. Like the current retention policies, such user tracking and ... "liberal" collaboration practices with the state set a bad precedent for other home servers. Thankfully, since the above policy was published (2017), the GDPR was "implemented" (2018) and it seems like both the Element.io privacy policy and the Matrix.org privacy policy have been somewhat improved since. Notable points of the new privacy policies:
  • 2.3.1.1: the "federation" section actually outlines that "Federated homeservers and Matrix clients which respect the Matrix protocol are expected to honour these controls and redaction/erasure requests, but other federated homeservers are outside of the span of control of Element, and we cannot guarantee how this data will be processed"
  • 2.6: users under the age of 16 should not use the matrix.org service
  • 2.10: Upcloud, Mythic Beast, Amazon, and CloudFlare possibly have access to your data (it's nice to at least mention this in the privacy policy: many providers don't even bother admitting to this kind of delegation)
  • Element 2.2.1: mentions many more third parties (Twilio, Stripe, Quaderno, LinkedIn, Twitter, Google, Outplay, PipeDrive, HubSpot, Posthog, Sentry, and Matomo (phew!) used when you are paying Matrix.org for hosting
I'm not super happy with all the trackers they have on the Element platform, but then again you don't have to use that service. Your favorite homeserver (assuming you are not on Matrix.org) probably has their own Element deployment, hopefully without all that garbage. Overall, this is all a huge improvement over the previous privacy policy, so hats off to the Matrix people for figuring out a reasonable policy in such a tricky context. I particularly like this bit:
We will forget your copy of your data upon your request. We will also forward your request to be forgotten onto federated homeservers. However - these homeservers are outside our span of control, so we cannot guarantee they will forget your data.
It's great they implemented those mechanisms and, after all, if there's an hostile party in there, nothing can prevent them from using screenshots to just exfiltrate your data away from the client side anyways, even with services typically seen as more secure, like Signal. As an aside, I also appreciate that Matrix.org has a fairly decent code of conduct, based on the TODO CoC which checks all the boxes in the geekfeminism wiki.

Metadata handling Overall, privacy protections in Matrix mostly concern message contents, not metadata. In other words, who's talking with who, when and from where is not well protected. Compared to a tool like Signal, which goes through great lengths to anonymize that data with features like private contact discovery, disappearing messages, sealed senders, and private groups, Matrix is definitely behind. (Note: there is an issue open about message lifetimes in Element since 2020, but it's not at even at the MSC stage yet.) This is a known issue (opened in 2019) in Synapse, but this is not just an implementation issue, it's a flaw in the protocol itself. Home servers keep join/leave of all rooms, which gives clear text information about who is talking to. Synapse logs may also contain privately identifiable information that home server admins might not be aware of in the first place. Those log rotation policies are separate from the server-level retention policy, which may be confusing for a novice sysadmin. Combine this with the federation: even if you trust your home server to do the right thing, the second you join a public room with third-party home servers, those ideas kind of get thrown out because those servers can do whatever they want with that information. Again, a problem that is hard to solve in any federation. To be fair, IRC doesn't have a great story here either: any client knows not only who's talking to who in a room, but also typically their client IP address. Servers can (and often do) obfuscate this, but often that obfuscation is trivial to reverse. Some servers do provide "cloaks" (sometimes automatically), but that's kind of a "slap-on" solution that actually moves the problem elsewhere: now the server knows a little more about the user. Overall, I would worry much more about a Matrix home server seizure than a IRC or Signal server seizure. Signal does get subpoenas, and they can only give out a tiny bit of information about their users: their phone number, and their registration, and last connection date. Matrix carries a lot more information in its database.

Amplification attacks on URL previews I (still!) run an Icecast server and sometimes share links to it on IRC which, obviously, also ends up on (more than one!) Matrix home servers because some people connect to IRC using Matrix. This, in turn, means that Matrix will connect to that URL to generate a link preview. I feel this outlines a security issue, especially because those sockets would be kept open seemingly forever. I tried to warn the Matrix security team but somehow, I don't think this issue was taken very seriously. Here's the disclosure timeline:
  • January 18: contacted Matrix security
  • January 19: response: already reported as a bug
  • January 20: response: can't reproduce
  • January 31: timeout added, considered solved
  • January 31: I respond that I believe the security issue is underestimated, ask for clearance to disclose
  • February 1: response: asking for two weeks delay after the next release (1.53.0) including another patch, presumably in two weeks' time
  • February 22: Matrix 1.53.0 released
  • April 14: I notice the release, ask for clearance again
  • April 14: response: referred to the public disclosure
There are a couple of problems here:
  1. the bug was publicly disclosed in September 2020, and not considered a security issue until I notified them, and even then, I had to insist
  2. no clear disclosure policy timeline was proposed or seems established in the project (there is a security disclosure policy but it doesn't include any predefined timeline)
  3. I wasn't informed of the disclosure
  4. the actual solution is a size limit (10MB, already implemented), a time limit (30 seconds, implemented in PR 11784), and a content type allow list (HTML, "media" or JSON, implemented in PR 11936), and I'm not sure it's adequate
  5. (pure vanity:) I did not make it to their Hall of fame
I'm not sure those solutions are adequate because they all seem to assume a single home server will pull that one URL for a little while then stop. But in a federated network, many (possibly thousands) home servers may be connected in a single room at once. If an attacker drops a link into such a room, all those servers would connect to that link all at once. This is an amplification attack: a small amount of traffic will generate a lot more traffic to a single target. It doesn't matter there are size or time limits: the amplification is what matters here. It should also be noted that clients that generate link previews have more amplification because they are more numerous than servers. And of course, the default Matrix client (Element) does generate link previews as well. That said, this is possibly not a problem specific to Matrix: any federated service that generates link previews may suffer from this. I'm honestly not sure what the solution is here. Maybe moderation? Maybe link previews are just evil? All I know is there was this weird bug in my Icecast server and I tried to ring the bell about it, and it feels it was swept under the rug. Somehow I feel this is bound to blow up again in the future, even with the current mitigation.

Moderation In Matrix like elsewhere, Moderation is a hard problem. There is a detailed moderation guide and much of this problem space is actively worked on in Matrix right now. A fundamental problem with moderating a federated space is that a user banned from a room can rejoin the room from another server. This is why spam is such a problem in Email, and why IRC networks have stopped federating ages ago (see the IRC history for that fascinating story).

The mjolnir bot The mjolnir moderation bot is designed to help with some of those things. It can kick and ban users, redact all of a user's message (as opposed to one by one), all of this across multiple rooms. It can also subscribe to a federated block list published by matrix.org to block known abusers (users or servers). Bans are pretty flexible and can operate at the user, room, or server level. Matrix people suggest making the bot admin of your channels, because you can't take back admin from a user once given.

The command-line tool There's also a new command line tool designed to do things like:
  • System notify users (all users/users from a list, specific user)
  • delete sessions/devices not seen for X days
  • purge the remote media cache
  • select rooms with various criteria (external/local/empty/created by/encrypted/cleartext)
  • purge history of theses rooms
  • shutdown rooms
This tool and Mjolnir are based on the admin API built into Synapse.

Rate limiting Synapse has pretty good built-in rate-limiting which blocks repeated login, registration, joining, or messaging attempts. It may also end up throttling servers on the federation based on those settings.

Fundamental federation problems Because users joining a room may come from another server, room moderators are at the mercy of the registration and moderation policies of those servers. Matrix is like IRC's +R mode ("only registered users can join") by default, except that anyone can register their own homeserver, which makes this limited. Server admins can block IP addresses and home servers, but those tools are not easily available to room admins. There is an API (m.room.server_acl in /devtools) but it is not reliable (thanks Austin Huang for the clarification). Matrix has the concept of guest accounts, but it is not used very much, and virtually no client or homeserver supports it. This contrasts with the way IRC works: by default, anyone can join an IRC network even without authentication. Some channels require registration, but in general you are free to join and look around (until you get blocked, of course). I have seen anecdotal evidence (CW: Twitter, nitter link) that "moderating bridges is hell", and I can imagine why. Moderation is already hard enough on one federation, when you bridge a room with another network, you inherit all the problems from that network but without the entire abuse control tools from the original network's API...

Room admins Matrix, in particular, has the problem that room administrators (which have the power to redact messages, ban users, and promote other users) are bound to their Matrix ID which is, in turn, bound to their home servers. This implies that a home server administrators could (1) impersonate a given user and (2) use that to hijack the room. So in practice, the home server is the trust anchor for rooms, not the user themselves. That said, if server B administrator hijack user joe on server B, they will hijack that room on that specific server. This will not (necessarily) affect users on the other servers, as servers could refuse parts of the updates or ban the compromised account (or server). It does seem like a major flaw that room credentials are bound to Matrix identifiers, as opposed to the E2E encryption credentials. In an encrypted room even with fully verified members, a compromised or hostile home server can still take over the room by impersonating an admin. That admin (or even a newly minted user) can then send events or listen on the conversations. This is even more frustrating when you consider that Matrix events are actually signed and therefore have some authentication attached to them, acting like some sort of Merkle tree (as it contains a link to previous events). That signature, however, is made from the homeserver PKI keys, not the client's E2E keys, which makes E2E feel like it has been "bolted on" later.

Availability While Matrix has a strong advantage over Signal in that it's decentralized (so anyone can run their own homeserver,), I couldn't find an easy way to run a "multi-primary" setup, or even a "redundant" setup (even if with a single primary backend), short of going full-on "replicate PostgreSQL and Redis data", which is not typically for the faint of heart.

How this works in IRC On IRC, it's quite easy to setup redundant nodes. All you need is:
  1. a new machine (with it's own public address with an open port)
  2. a shared secret (or certificate) between that machine and an existing one on the network
  3. a connect block on both servers
That's it: the node will join the network and people can connect to it as usual and share the same user/namespace as the rest of the network. The servers take care of synchronizing state: you do not need to worry about replicating a database server. (Now, experienced IRC people will know there's a catch here: IRC doesn't have authentication built in, and relies on "services" which are basically bots that authenticate users (I'm simplifying, don't nitpick). If that service goes down, the network still works, but then people can't authenticate, and they can start doing nasty things like steal people's identity if they get knocked offline. But still: basic functionality still works: you can talk in rooms and with users that are on the reachable network.)

User identities Matrix is more complicated. Each "home server" has its own identity namespace: a specific user (say @anarcat:matrix.org) is bound to that specific home server. If that server goes down, that user is completely disconnected. They could register a new account elsewhere and reconnect, but then they basically lose all their configuration: contacts, joined channels are all lost. (Also notice how the Matrix IDs don't look like a typical user address like an email in XMPP. They at least did their homework and got the allocation for the scheme.)

Rooms Users talk to each other in "rooms", even in one-to-one communications. (Rooms are also used for other things like "spaces", they're basically used for everything, think "everything is a file" kind of tool.) For rooms, home servers act more like IRC nodes in that they keep a local state of the chat room and synchronize it with other servers. Users can keep talking inside a room if the server that originally hosts the room goes down. Rooms can have a local, server-specific "alias" so that, say, #room:matrix.org is also visible as #room:example.com on the example.com home server. Both addresses refer to the same room underlying room. (Finding this in the Element settings is not obvious though, because that "alias" are actually called a "local address" there. So to create such an alias (in Element), you need to go in the room settings' "General" section, "Show more" in "Local address", then add the alias name (e.g. foo), and then that room will be available on your example.com homeserver as #foo:example.com.) So a room doesn't belong to a server, it belongs to the federation, and anyone can join the room from any serer (if the room is public, or if invited otherwise). You can create a room on server A and when a user from server B joins, the room will be replicated on server B as well. If server A fails, server B will keep relaying traffic to connected users and servers. A room is therefore not fundamentally addressed with the above alias, instead ,it has a internal Matrix ID, which basically a random string. It has a server name attached to it, but that was made just to avoid collisions. That can get a little confusing. For example, the #fractal:gnome.org room is an alias on the gnome.org server, but the room ID is !hwiGbsdSTZIwSRfybq:matrix.org. That's because the room was created on matrix.org, but the preferred branding is gnome.org now. As an aside, rooms, by default, live forever, even after the last user quits. There's an admin API to delete rooms and a tombstone event to redirect to another one, but neither have a GUI yet. The latter is part of MSC1501 ("Room version upgrades") which allows a room admin to close a room, with a message and a pointer to another room.

Spaces Discovering rooms can be tricky: there is a per-server room directory, but Matrix.org people are trying to deprecate it in favor of "Spaces". Room directories were ripe for abuse: anyone can create a room, so anyone can show up in there. It's possible to restrict who can add aliases, but anyways directories were seen as too limited. In contrast, a "Space" is basically a room that's an index of other rooms (including other spaces), so existing moderation and administration mechanism that work in rooms can (somewhat) work in spaces as well. This enables a room directory that works across federation, regardless on which server they were originally created. New users can be added to a space or room automatically in Synapse. (Existing users can be told about the space with a server notice.) This gives admins a way to pre-populate a list of rooms on a server, which is useful to build clusters of related home servers, providing some sort of redundancy, at the room -- not user -- level.

Home servers So while you can workaround a home server going down at the room level, there's no such thing at the home server level, for user identities. So if you want those identities to be stable in the long term, you need to think about high availability. One limitation is that the domain name (e.g. matrix.example.com) must never change in the future, as renaming home servers is not supported. The documentation used to say you could "run a hot spare" but that has been removed. Last I heard, it was not possible to run a high-availability setup where multiple, separate locations could replace each other automatically. You can have high performance setups where the load gets distributed among workers, but those are based on a shared database (Redis and PostgreSQL) backend. So my guess is it would be possible to create a "warm" spare server of a matrix home server with regular PostgreSQL replication, but that is not documented in the Synapse manual. This sort of setup would also not be useful to deal with networking issues or denial of service attacks, as you will not be able to spread the load over multiple network locations easily. Redis and PostgreSQL heroes are welcome to provide their multi-primary solution in the comments. In the meantime, I'll just point out this is a solution that's handled somewhat more gracefully in IRC, by having the possibility of delegating the authentication layer.

Delegations If you do not want to run a Matrix server yourself, it's possible to delegate the entire thing to another server. There's a server discovery API which uses the .well-known pattern (or SRV records, but that's "not recommended" and a bit confusing) to delegate that service to another server. Be warned that the server still needs to be explicitly configured for your domain. You can't just put:
  "m.server": "matrix.org:443"  
... on https://example.com/.well-known/matrix/server and start using @you:example.com as a Matrix ID. That's because Matrix doesn't support "virtual hosting" and you'd still be connecting to rooms and people with your matrix.org identity, not example.com as you would normally expect. This is also why you cannot rename your home server. The server discovery API is what allows servers to find each other. Clients, on the other hand, use the client-server discovery API: this is what allows a given client to find your home server when you type your Matrix ID on login.

Performance The high availability discussion brushed over the performance of Matrix itself, but let's now dig into that.

Horizontal scalability There were serious scalability issues of the main Matrix server, Synapse, in the past. So the Matrix team has been working hard to improve its design. Since Synapse 1.22 the home server can horizontally scale to multiple workers (see this blog post for details) which can make it easier to scale large servers.

Other implementations There are other promising home servers implementations from a performance standpoint (dendrite, Golang, entered beta in late 2020; conduit, Rust, beta; others), but none of those are feature-complete so there's a trade-off to be made there. Synapse is also adding a lot of feature fast, so it's an open question whether the others will ever catch up. (I have heard that Dendrite might actually surpass Synapse in features within a few years, which would put Synapse in a more "LTS" situation.)

Latency Matrix can feel slow sometimes. For example, joining the "Matrix HQ" room in Element (from matrix.debian.social) takes a few minutes and then fails. That is because the home server has to sync the entire room state when you join the room. There was promising work on this announced in the lengthy 2021 retrospective, and some of that work landed (partial sync) in the 1.53 release already. Other improvements coming include sliding sync, lazy loading over federation, and fast room joins. So that's actually something that could be fixed in the fairly short term. But in general, communication in Matrix doesn't feel as "snappy" as on IRC or even Signal. It's hard to quantify this without instrumenting a full latency test bed (for example the tools I used in the terminal emulators latency tests), but even just typing in a web browser feels slower than typing in a xterm or Emacs for me. Even in conversations, I "feel" people don't immediately respond as fast. In fact, this could be an interesting double-blind experiment to make: have people guess whether they are talking to a person on Matrix, XMPP, or IRC, for example. My theory would be that people could notice that Matrix users are slower, if only because of the TCP round-trip time each message has to take.

Transport Some courageous person actually made some tests of various messaging platforms on a congested network. His evaluation was basically:
  • Briar: uses Tor, so unusable except locally
  • Matrix: "struggled to send and receive messages", joining a room takes forever as it has to sync all history, "took 20-30 seconds for my messages to be sent and another 20 seconds for further responses"
  • XMPP: "worked in real-time, full encryption, with nearly zero lag"
So that was interesting. I suspect IRC would have also fared better, but that's just a feeling. Other improvements to the transport layer include support for websocket and the CoAP proxy work from 2019 (targeting 100bps links), but both seem stalled at the time of writing. The Matrix people have also announced the pinecone p2p overlay network which aims at solving large, internet-scale routing problems. See also this talk at FOSDEM 2022.

Usability

Onboarding and workflow The workflow for joining a room, when you use Element web, is not great:
  1. click on a link in a web browser
  2. land on (say) https://matrix.to/#/#matrix-dev:matrix.org
  3. offers "Element", yeah that's sounds great, let's click "Continue"
  4. land on https://app.element.io/#/room%2F%23matrix-dev%3Amatrix.org and then you need to register, aaargh
As you might have guessed by now, there is a specification to solve this, but web browsers need to adopt it as well, so that's far from actually being solved. At least browsers generally know about the matrix: scheme, it's just not exactly clear what they should do with it, especially when the handler is just another web page (e.g. Element web). In general, when compared with tools like Signal or WhatsApp, Matrix doesn't fare so well in terms of user discovery. I probably have some of my normal contacts that have a Matrix account as well, but there's really no way to know. It's kind of creepy when Signal tells you "this person is on Signal!" but it's also pretty cool that it works, and they actually implemented it pretty well. Registration is also less obvious: in Signal, the app confirms your phone number automatically. It's friction-less and quick. In Matrix, you need to learn about home servers, pick one, register (with a password! aargh!), and then setup encryption keys (not default), etc. It's a lot more friction. And look, I understand: giving away your phone number is a huge trade-off. I don't like it either. But it solves a real problem and makes encryption accessible to a ton more people. Matrix does have "identity servers" that can serve that purpose, but I don't feel confident sharing my phone number there. It doesn't help that the identity servers don't have private contact discovery: giving them your phone number is a more serious security compromise than with Signal. There's a catch-22 here too: because no one feels like giving away their phone numbers, no one does, and everyone assumes that stuff doesn't work anyways. Like it or not, Signal forcing people to divulge their phone number actually gives them critical mass that means actually a lot of my relatives are on Signal and I don't have to install crap like WhatsApp to talk with them.

5 minute clients evaluation Throughout all my tests I evaluated a handful of Matrix clients, mostly from Flathub because almost none of them are packaged in Debian. Right now I'm using Element, the flagship client from Matrix.org, in a web browser window, with the PopUp Window extension. This makes it look almost like a native app, and opens links in my main browser window (instead of a new tab in that separate window), which is nice. But I'm tired of buying memory to feed my web browser, so this indirection has to stop. Furthermore, I'm often getting completely logged off from Element, which means re-logging in, recovering my security keys, and reconfiguring my settings. That is extremely annoying. Coming from Irssi, Element is really "GUI-y" (pronounced "gooey"). Lots of clickety happening. To mark conversations as read, in particular, I need to click-click-click on all the tabs that have some activity. There's no "jump to latest message" or "mark all as read" functionality as far as I could tell. In Irssi the former is built-in (alt-a) and I made a custom /READ command for the latter:
/ALIAS READ script exec \$_->activity(0) for Irssi::windows
And yes, that's a Perl script in my IRC client. I am not aware of any Matrix client that does stuff like that, except maybe Weechat, if we can call it a Matrix client, or Irssi itself, now that it has a Matrix plugin (!). As for other clients, I have looked through the Matrix Client Matrix (confusing right?) to try to figure out which one to try, and, even after selecting Linux as a filter, the chart is just too wide to figure out anything. So I tried those, kind of randomly:
  • Fractal
  • Mirage
  • Nheko
  • Quaternion
Unfortunately, I lost my notes on those, I don't actually remember which one did what. I still have a session open with Mirage, so I guess that means it's the one I preferred, but I remember they were also all very GUI-y. Maybe I need to look at weechat-matrix or gomuks. At least Weechat is scriptable so I could continue playing the power-user. Right now my strategy with messaging (and that includes microblogging like Twitter or Mastodon) is that everything goes through my IRC client, so Weechat could actually fit well in there. Going with gomuks, on the other hand, would mean running it in parallel with Irssi or ... ditching IRC, which is a leap I'm not quite ready to take just yet. Oh, and basically none of those clients (except Nheko and Element) support VoIP, which is still kind of a second-class citizen in Matrix. It does not support large multimedia rooms, for example: Jitsi was used for FOSDEM instead of the native videoconferencing system.

Bots This falls a little aside the "usability" section, but I didn't know where to put this... There's a few Matrix bots out there, and you are likely going to be able to replace your existing bots with Matrix bots. It's true that IRC has a long and impressive history with lots of various bots doing various things, but given how young Matrix is, there's still a good variety:
  • maubot: generic bot with tons of usual plugins like sed, dice, karma, xkcd, echo, rss, reminder, translate, react, exec, gitlab/github webhook receivers, weather, etc
  • opsdroid: framework to implement "chat ops" in Matrix, connects with Matrix, GitHub, GitLab, Shell commands, Slack, etc
  • matrix-nio: another framework, used to build lots more bots like:
    • hemppa: generic bot with various functionality like weather, RSS feeds, calendars, cron jobs, OpenStreetmaps lookups, URL title snarfing, wolfram alpha, astronomy pic of the day, Mastodon bridge, room bridging, oh dear
    • devops: ping, curl, etc
    • podbot: play podcast episodes from AntennaPod
    • cody: Python, Ruby, Javascript REPL
    • eno: generic bot, "personal assistant"
  • mjolnir: moderation bot
  • hookshot: bridge with GitLab/GitHub
  • matrix-monitor-bot: latency monitor
One thing I haven't found an equivalent for is Debian's MeetBot. There's an archive bot but it doesn't have topics or a meeting chair, or HTML logs.

Working on Matrix As a developer, I find Matrix kind of intimidating. The specification is huge. The official specification itself looks somewhat digestable: it's only 6 APIs so that looks, at first, kind of reasonable. But whenever you start asking complicated questions about Matrix, you quickly fall into the Matrix Spec Change specification (which, yes, is a separate specification). And there are literally hundreds of MSCs flying around. It's hard to tell what's been adopted and what hasn't, and even harder to figure out if your specific client has implemented it. (One trendy answer to this problem is to "rewrite it in rust": Matrix are working on implementing a lot of those specifications in a matrix-rust-sdk that's designed to take the implementation details away from users.) Just taking the latest weekly Matrix report, you find that three new MSCs proposed, just last week! There's even a graph that shows the number of MSCs is progressing steadily, at 600+ proposals total, with the majority (300+) "new". I would guess the "merged" ones are at about 150. That's a lot of text which includes stuff like 3D worlds which, frankly, I don't think you should be working on when you have such important security and usability problems. (The internet as a whole, arguably, doesn't fare much better. RFC600 is a really obscure discussion about "INTERFACING AN ILLINOIS PLASMA TERMINAL TO THE ARPANET". Maybe that's how many MSCs will end up as well, left forgotten in the pits of history.) And that's the thing: maybe the Matrix people have a different objective than I have. They want to connect everything to everything, and make Matrix a generic transport for all sorts of applications, including virtual reality, collaborative editors, and so on. I just want secure, simple messaging. Possibly with good file transfers, and video calls. That it works with existing stuff is good, and it should be federated to remove the "Signal point of failure". So I'm a bit worried with the direction all those MSCs are taking, especially when you consider that clients other than Element are still struggling to keep up with basic features like end-to-end encryption or room discovery, never mind voice or spaces...

Conclusion Overall, Matrix is somehow in the space XMPP was a few years ago. It has a ton of features, pretty good clients, and a large community. It seems to have gained some of the momentum that XMPP has lost. It may have the most potential to replace Signal if something bad would happen to it (like, I don't know, getting banned or going nuts with cryptocurrency)... But it's really not there yet, and I don't see Matrix trying to get there either, which is a bit worrisome.

Looking back at history I'm also worried that we are repeating the errors of the past. The history of federated services is really fascinating:. IRC, FTP, HTTP, and SMTP were all created in the early days of the internet, and are all still around (except, arguably, FTP, which was removed from major browsers recently). All of them had to face serious challenges in growing their federation. IRC had numerous conflicts and forks, both at the technical level but also at the political level. The history of IRC is really something that anyone working on a federated system should study in detail, because they are bound to make the same mistakes if they are not familiar with it. The "short" version is:
  • 1988: Finnish researcher publishes first IRC source code
  • 1989: 40 servers worldwide, mostly universities
  • 1990: EFnet ("eris-free network") fork which blocks the "open relay", named Eris - followers of Eris form the A-net, which promptly dissolves itself, with only EFnet remaining
  • 1992: Undernet fork, which offered authentication ("services"), routing improvements and timestamp-based channel synchronisation
  • 1994: DALnet fork, from Undernet, again on a technical disagreement
  • 1995: Freenode founded
  • 1996: IRCnet forks from EFnet, following a flame war of historical proportion, splitting the network between Europe and the Americas
  • 1997: Quakenet founded
  • 1999: (XMPP founded)
  • 2001: 6 million users, OFTC founded
  • 2002: DALnet peaks at 136,000 users
  • 2003: IRC as a whole peaks at 10 million users, EFnet peaks at 141,000 users
  • 2004: (Facebook founded), Undernet peaks at 159,000 users
  • 2005: Quakenet peaks at 242,000 users, IRCnet peaks at 136,000 (Youtube founded)
  • 2006: (Twitter founded)
  • 2009: (WhatsApp, Pinterest founded)
  • 2010: (TextSecure AKA Signal, Instagram founded)
  • 2011: (Snapchat founded)
  • ~2013: Freenode peaks at ~100,000 users
  • 2016: IRCv3 standardisation effort started (TikTok founded)
  • 2021: Freenode self-destructs, Libera chat founded
  • 2022: Libera peaks at 50,000 users, OFTC peaks at 30,000 users
(The numbers were taken from the Wikipedia page and Netsplit.de. Note that I also include other networks launch in parenthesis for context.) Pretty dramatic, don't you think? Eventually, somehow, IRC became irrelevant for most people: few people are even aware of it now. With less than a million users active, it's smaller than Mastodon, XMPP, or Matrix at this point.1 If I were to venture a guess, I'd say that infighting, lack of a standardization body, and a somewhat annoying protocol meant the network could not grow. It's also possible that the decentralised yet centralised structure of IRC networks limited their reliability and growth. But large social media companies have also taken over the space: observe how IRC numbers peak around the time the wave of large social media companies emerge, especially Facebook (2.9B users!!) and Twitter (400M users).

Where the federated services are in history Right now, Matrix, and Mastodon (and email!) are at the "pre-EFnet" stage: anyone can join the federation. Mastodon has started working on a global block list of fascist servers which is interesting, but it's still an open federation. Right now, Matrix is totally open, but matrix.org publishes a (federated) block list of hostile servers (#matrix-org-coc-bl:matrix.org, yes, of course it's a room). Interestingly, Email is also in that stage, where there are block lists of spammers, and it's a race between those blockers and spammers. Large email providers, obviously, are getting closer to the EFnet stage: you could consider they only accept email from themselves or between themselves. It's getting increasingly hard to deliver mail to Outlook and Gmail for example, partly because of bias against small providers, but also because they are including more and more machine-learning tools to sort through email and those systems are, fundamentally, unknowable. It's not quite the same as splitting the federation the way EFnet did, but the effect is similar. HTTP has somehow managed to live in a parallel universe, as it's technically still completely federated: anyone can start a web server if they have a public IP address and anyone can connect to it. The catch, of course, is how you find the darn thing. Which is how Google became one of the most powerful corporations on earth, and how they became the gatekeepers of human knowledge online. I have only briefly mentioned XMPP here, and my XMPP fans will undoubtedly comment on that, but I think it's somewhere in the middle of all of this. It was co-opted by Facebook and Google, and both corporations have abandoned it to its fate. I remember fondly the days where I could do instant messaging with my contacts who had a Gmail account. Those days are gone, and I don't talk to anyone over Jabber anymore, unfortunately. And this is a threat that Matrix still has to face. It's also the threat Email is currently facing. On the one hand corporations like Facebook want to completely destroy it and have mostly succeeded: many people just have an email account to register on things and talk to their friends over Instagram or (lately) TikTok (which, I know, is not Facebook, but they started that fire). On the other hand, you have corporations like Microsoft and Google who are still using and providing email services because, frankly, you still do need email for stuff, just like fax is still around but they are more and more isolated in their own silo. At this point, it's only a matter of time they reach critical mass and just decide that the risk of allowing external mail coming in is not worth the cost. They'll simply flip the switch and work on an allow-list principle. Then we'll have closed the loop and email will be dead, just like IRC is "dead" now. I wonder which path Matrix will take. Could it liberate us from these vicious cycles? Update: this generated some discussions on lobste.rs.

  1. According to Wikipedia, there are currently about 500 distinct IRC networks operating, on about 1,000 servers, serving over 250,000 users. In contrast, Mastodon seems to be around 5 million users, Matrix.org claimed at FOSDEM 2021 to have about 28 million globally visible accounts, and Signal lays claim to over 40 million souls. XMPP claims to have "millions" of users on the xmpp.org homepage but the FAQ says they don't actually know. On the proprietary silo side of the fence, this page says
    • Facebook: 2.9 billion users
    • WhatsApp: 2B
    • Instagram: 1.4B
    • TikTok: 1B
    • Snapchat: 500M
    • Pinterest: 480M
    • Twitter: 397M
    Notable omission from that list: Youtube, with its mind-boggling 2.6 billion users... Those are not the kind of numbers you just "need to convince a brother or sister" to grow the network...

11 June 2022

Louis-Philippe V ronneau: Updating a rooted Pixel 3a

A short while after getting a Pixel 3a, I decided to root it, mostly to have more control over the charging procedure. In order to preserve battery life, I like my phone to stop charging at around 75% of full battery capacity and to shut down automatically at around 12%. Some Android ROMs have extra settings to manage this, but LineageOS unfortunately does not. Android already comes with a fairly complex mechanism to handle the charge cycle, but it is mostly controlled by the kernel and cannot be easily configured by end-users. acc is a higher-level "systemless" interface for the Android kernel battery management, but one needs root to do anything interesting with it. Once rooted, you can use the AccA app instead of playing on the command line to fine tune your battery settings. Sadly, having a rooted phone also means I need to re-root it each time there is an OS update (typically each week). Somehow, I keep forgetting the exact procedure to do this! Hopefully, I will be able to use this post as a reference in the future :) Note that these instructions might not apply to your exact phone model, proceed with caution! Extract the boot.img file This procedure mostly comes from the LineageOS documentation on extracting proprietary blobs from the payload.
  1. Download the latest LineageOS image for your phone.
  2. unzip the image to get the payload.bin file inside it.
  3. Clone the LineageOS scripts git repository: $ git clone https://github.com/LineageOS/scripts
  4. extract the boot image (requires python3-protobuf): $ mkdir extracted-payload $ python3 scripts/update-payload-extractor/extract.py payload.bin --output_dir extracted-payload
You should now have a boot.img file. Patch the boot image file using Magisk
  1. Upload the boot.img file you previously extracted to your device.
  2. Open Magisk and patch the boot.img file.
  3. Download the patched file back on your computer.
Flash the patched boot image
  1. Enable ADB debug mode on your phone.
  2. Reboot into fastboot mode. $ adb reboot fastboot
  3. Flash the patched boot image file: $ fastboot flash boot magisk_patched-foo.img
  4. Disable ADB debug mode on your phone.
Troubleshooting In an ideal world, you would do this entire process each time you upgrade to a new LineageOS version. Sadly, this creates friction and makes updating much more troublesome. To simplify things, you can try to flash an old patched boot.img file after upgrading, instead of generating it each time. In my experience, it usually works. When it does not, the device behaves weirdly after a reboot and things that require proprietary blobs (like WiFi) will stop working. If that happens:
  1. Download the latest LineageOS version for your phone.
  2. Reboot into recovery (Power + Volume Down).
  3. Click on "Apply Updates"
  4. Sideload the ROM: $ adb sideload lineageos-foo.zip

9 June 2022

Enrico Zini: Updating cbqt for bullseye

Back in 2017 I did work to setup a cross-building toolchain for QT Creator, that takes advantage of Debian's packaging for all the dependency ecosystem. It ended with cbqt which is a little script that sets up a chroot to hold cross-build-dependencies, to avoid conflicting with packages in the host system, and sets up a qmake alternative to make use of them. Today I'm dusting off that work, to ensure it works on Debian bullseye. Resetting QT Creator To make things reproducible, I wanted to reset QT Creator's configuration. Besides purging and reinstalling the package, one needs to manually remove: Updating cbqt Easy start, change the distribution for the chroot:
-DIST_CODENAME = "stretch"
+DIST_CODENAME = "bullseye"
Adding LIBDIR Something else does not work:
Test$ qmake-armhf -makefile
Info: creating stash file  /Test/.qmake.stash
Test$ make
[...]
/usr/bin/arm-linux-gnueabihf-g++ -Wl,-O1 -Wl,-rpath-link, /armhf/lib/arm-linux-gnueabihf -Wl,-rpath-link, /armhf/usr/lib/arm-linux-gnueabihf -Wl,-rpath-link, /armhf/usr/lib/ -o Test main.o mainwindow.o moc_mainwindow.o    /armhf/usr/lib/arm-linux-gnueabihf/libQt5Widgets.so  /armhf/usr/lib/arm-linux-gnueabihf/libQt5Gui.so  /armhf/usr/lib/arm-linux-gnueabihf/libQt5Core.so -lGLESv2 -lpthread
/usr/lib/gcc-cross/arm-linux-gnueabihf/10/../../../../arm-linux-gnueabihf/bin/ld: cannot find -lGLESv2
collect2: error: ld returned 1 exit status
make: *** [Makefile:146: Test] Error 1
I figured that now I also need to set QMAKE_LIBDIR and not just QMAKE_RPATHLINKDIR:
--- a/cbqt
+++ b/cbqt
@@ -241,18 +241,21 @@ include(../common/linux.conf)
 include(../common/gcc-base-unix.conf)
 include(../common/g++-unix.conf)
+QMAKE_LIBDIR +=  chroot.abspath /lib/arm-linux-gnueabihf
+QMAKE_LIBDIR +=  chroot.abspath /usr/lib/arm-linux-gnueabihf
+QMAKE_LIBDIR +=  chroot.abspath /usr/lib/
 QMAKE_RPATHLINKDIR +=  chroot.abspath /lib/arm-linux-gnueabihf
 QMAKE_RPATHLINKDIR +=  chroot.abspath /usr/lib/arm-linux-gnueabihf
 QMAKE_RPATHLINKDIR +=  chroot.abspath /usr/lib/
Now it links again:
Test$ qmake-armhf -makefile
Test$ make
/usr/bin/arm-linux-gnueabihf-g++ -Wl,-O1 -Wl,-rpath-link, /armhf/lib/arm-linux-gnueabihf -Wl,-rpath-link, /armhf/usr/lib/arm-linux-gnueabihf -Wl,-rpath-link, /armhf/usr/lib/ -o Test main.o mainwindow.o moc_mainwindow.o   -L /armhf/lib/arm-linux-gnueabihf -L /armhf/usr/lib/arm-linux-gnueabihf -L /armhf/usr/lib/  /armhf/usr/lib/arm-linux-gnueabihf/libQt5Widgets.so  /armhf/usr/lib/arm-linux-gnueabihf/libQt5Gui.so  /armhf/usr/lib/arm-linux-gnueabihf/libQt5Core.so -lGLESv2 -lpthread
Making it work in Qt Creator Time to try it in Qt Creator, and sadly it fails:
 /armhf/usr/lib/arm-linux-gnueabihf/qt5/mkspecs/features/toolchain.prf:76: Variable QMAKE_CXX.COMPILER_MACROS is not defined.
QMAKE_CXX.COMPILER_MACROS is not defined I traced it to this bit in armhf/usr/lib/arm-linux-gnueabihf/qt5/mkspecs/features/toolchain.prf (nonrelevant bits deleted):
isEmpty($$ target_prefix .COMPILER_MACROS)  
    msvc  
        #  
      else: gcc ghs  
        vars = $$qtVariablesFromGCC($$QMAKE_CXX)
     
    for (v, vars)  
        #  
        $$ target_prefix .COMPILER_MACROS += $$v
     
    cache($$ target_prefix .COMPILER_MACROS, set stash)
  else  
    #  
 
It turns out that qmake is not able to realise that the compiler is gcc, so vars does not get set, nothing is set in COMPILER_MACROS, and qmake fails. Reproducing it on the command line When run manually, however, qmake-armhf worked, so it would be good to know how Qt Creator is actually running qmake. Since it frustratingly does not show what commands it runs, I'll have to strace it:
strace -e trace=execve --string-limit=123456 -o qtcreator.trace -f qtcreator
And there it is:
$ grep qmake- qtcreator.trace
1015841 execve("/usr/local/bin/qmake-armhf", ["/usr/local/bin/qmake-armhf", "-query"], 0x56096e923040 /* 54 vars */) = 0
1015865 execve("/usr/local/bin/qmake-armhf", ["/usr/local/bin/qmake-armhf", " /Test/Test.pro", "-spec", "arm-linux-gnueabihf", "CONFIG+=debug", "CONFIG+=qml_debug"], 0x7f5cb4023e20 /* 55 vars */) = 0
I run the command manually and indeed I reproduce the problem:
$ /usr/local/bin/qmake-armhf Test.pro -spec arm-linux-gnueabihf CONFIG+=debug CONFIG+=qml_debug
 /armhf/usr/lib/arm-linux-gnueabihf/qt5/mkspecs/features/toolchain.prf:76: Variable QMAKE_CXX.COMPILER_MACROS is not defined.
I try removing options until I find the one that breaks it and... now it's always broken! Even manually running qmake-armhf, like I did earlier, stopped working:
$ rm .qmake.stash
$ qmake-armhf -makefile
 /armhf/usr/lib/arm-linux-gnueabihf/qt5/mkspecs/features/toolchain.prf:76: Variable QMAKE_CXX.COMPILER_MACROS is not defined.
Debugging toolchain.prf I tried purging and reinstalling qtcreator, and recreating the chroot, but qmake-armhf is staying broken. I'll let that be, and try to debug toolchain.prf. By grepping gcc in the mkspecs directory, I managed to figure out that: Sadly, I failed to find reference documentation for QMAKE_COMPILER's syntax and behaviour. I also failed to find why qmake-armhf worked earlier, and I am also failing to restore the system to a situation where it works again. Maybe I dreamt that it worked? I had some manual change laying around from some previous fiddling with things? Anyway at least now I have the fix:
--- a/cbqt
+++ b/cbqt
@@ -248,7 +248,7 @@ QMAKE_RPATHLINKDIR +=  chroot.abspath /lib/arm-linux-gnueabihf
 QMAKE_RPATHLINKDIR +=  chroot.abspath /usr/lib/arm-linux-gnueabihf
 QMAKE_RPATHLINKDIR +=  chroot.abspath /usr/lib/
-QMAKE_COMPILER          =  chroot.arch_triplet -gcc
+QMAKE_COMPILER          = gcc  chroot.arch_triplet -gcc
 QMAKE_CC                = /usr/bin/ chroot.arch_triplet -gcc
Fixing a compiler mismatch warning In setting up the kit, Qt Creator also complained that the compiler from qmake did not match the one configured in the kit. That was easy to fix, by pointing at the host system cross-compiler in qmake.conf:
 QMAKE_COMPILER          =  chroot.arch_triplet -gcc
-QMAKE_CC                =  chroot.arch_triplet -gcc
+QMAKE_CC                = /usr/bin/ chroot.arch_triplet -gcc
 QMAKE_LINK_C            = $$QMAKE_CC
 QMAKE_LINK_C_SHLIB      = $$QMAKE_CC
-QMAKE_CXX               =  chroot.arch_triplet -g++
+QMAKE_CXX               = /usr/bin/ chroot.arch_triplet -g++
 QMAKE_LINK              = $$QMAKE_CXX
 QMAKE_LINK_SHLIB        = $$QMAKE_CXX
Updated setup instructions Create an armhf environment:
sudo cbqt ./armhf --create --verbose
Create a qmake wrapper that builds with this environment:
sudo ./cbqt ./armhf --qmake -o /usr/local/bin/qmake-armhf
Install the build-dependencies that you need:
# Note: :arch is added automatically to package names if no arch is explicitly specified
sudo ./cbqt ./armhf --install libqt5svg5-dev libmosquittopp-dev qtwebengine5-dev
Build with qmake Use qmake-armhf instead of qmake and it works perfectly:
qmake-armhf -makefile
make
Set up Qt Creator Configure a new Kit in Qt Creator:
  1. Tools/Options, then Kits, then Add
  2. Name: armhf (or anything you like)
  3. In the Qt Versions tab, click Add then set the path of the new Qt to /usr/local/bin/qmake-armhf. Click Apply.
  4. Back in the Kits, select the Qt version you just created in the Qt version field
  5. In Compilers, select the ARM versions of GCC. If they do not appear, install crossbuild-essential-armhf, then in the Compilers tab click Re-detect and then Apply to make them available for selection
  6. Dismiss the dialog with "OK": the new kit is ready
Now you can choose the default kit to build and run locally, and the armhf kit for remote cross-development. I tried looking at sdktool to automate this step, and it requires a nontrivial amount of work to do it reliably, so these manual instructions will have to do. Credits This has been done as part of my work with Truelite.

8 June 2022

Laura Arjona Reina: Moving to a faster but smaller disk, encrypted setup

My work computer runs Debian 11 bullseye (the current stable release) in a mechanical 500GB disk, and I was provided with a new SDD disk but its size was 480 GB. So I had to shrink my partitions before copying the data to the new disk. It turned out to be a bit difficult because my main partition was encrypted. I write here how I did, maybe there are other simpler ways but I couldn t find them. References: I had three partitions in my old 500GB disk: /dev/sda1 is the EFI partition, /dev/sda2 the boot partition and /dev/sda3 the root partition (encrypted, with LVM, the standard way the Debian installer proposes when you choose a simple encrypted setup). First of all, I made a disk image with Clonezilla to an external USB disk, just in case I mess up things, to be able to return to a safe point and start again. Then I started my computer with a Debian 11 live USB with KDE Plasma desktop and Spanish localisation environment. I opened the KDE Partition manager and copied the non encrypted partitions (sda1, EFI and sda2, /boot) to the new disk. I shrinked the encrypted partition from the terminal with the following commands (I had enough free space so reduced my partition to a total of 300GB): Removed the swap partition and re-created it:
sudo lvremove /dev/larjona-pc-vg/swap_1
sudo pvresize --setphysicalvolumesize 380G /dev/mapper/cryptdisk
sudo pvchange -x y /dev/mapper/cryptdisk
sudo lvcreate -L 4G -n swap_1 larjona-pc-vg
sudo mkswap -L swap_1 /dev/larjona-pc-vg/swap_1
Display information about the physical volume in order to shrink it:
sudo pvs -v --segments --units s /dev/mapper/cryptdisk
sudo cryptsetup -b 838860800 resize cryptdisk
sudo cryptsetup status cryptdisk
sudo vgchange -a n vgroup
sudo vgchange -an
sudo cryptsetup luksClose cryptdisk
Then reduced the sda3 partition with the KDE partition manager (it took a while), and copy it to the new disk. Turned off the computer and unplugged the old disk. Started the computer with the Debian 11 Live USB again, UEFI boot. Now, to make my system boot:
sudo cryptsetup luksOpen /dev/sda3 crypdisk
sudo vgscan --mknodes
sudo vgchange -ay
sudo mount /dev/mapper/larjona--pc--vg-root /mnt
sudo mount /dev/sda2 /mnt/boot
sudo mount /dev/sda1 /mnt/boot/efi
mount --rbind /sys /media/linux/sys
mount -t efivarfs none /sys/firmware/efi/efivars
for i in /dev /dev/pts /proc /run; do sudo mount -B $i /mnt$i; done
sudo chroot /mnt
Then edited /mnt/etc/crypttab to reflect the name of the new encrypted partition, edited /mnt/etc/fstab to paste the UUIDs of the new partitions.
Then ran grub-install and reinstalled the kernels as noted in the reference, rebooted and logged in my Plasma desktop  (Well, the actual process was not so smooth but after several tries and errors and searching for help I managed to get the needed commands to make my system boot from the new disk).
6 June 2022

Reproducible Builds: Reproducible Builds in May 2022

Welcome to the May 2022 report from the Reproducible Builds project. In our reports we outline the most important things that we have been up to over the past month. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website.

Repfix paper Zhilei Ren, Shiwei Sun, Jifeng Xuan, Xiaochen Li, Zhide Zhou and He Jiang have published an academic paper titled Automated Patching for Unreproducible Builds:
[..] fixing unreproducible build issues poses a set of challenges [..], among which we consider the localization granularity and the historical knowledge utilization as the most significant ones. To tackle these challenges, we propose a novel approach [called] RepFix that combines tracing-based fine-grained localization with history-based patch generation mechanisms.
The paper (PDF, 3.5MB) uses the Debian mylvmbackup package as an example to show how RepFix can automatically generate patches to make software build reproducibly. As it happens, Reiner Herrmann submitted a patch for the mylvmbackup package which has remained unapplied by the Debian package maintainer for over seven years, thus this paper inadvertently underscores that achieving reproducible builds will require both technical and social solutions.

Python variables Johannes Schauer discovered a fascinating bug where simply naming your Python variable _m led to unreproducible .pyc files. In particular, the types module in Python 3.10 requires the following patch to make it reproducible:
--- a/Lib/types.py
+++ b/Lib/types.py
@@ -37,8 +37,8 @@ _ag = _ag()
 AsyncGeneratorType = type(_ag)
 
 class _C:
-    def _m(self): pass
-MethodType = type(_C()._m)
+    def _b(self): pass
+MethodType = type(_C()._b)
Simply renaming the dummy method from _m to _b was enough to workaround the problem. Johannes bug report first led to a number of improvements in diffoscope to aid in dissecting .pyc files, but upstream identified this as caused by an issue surrounding interned strings and is being tracked in CPython bug #78274.

New SPDX team to incorporate build metadata in Software Bill of Materials SPDX, the open standard for Software Bill of Materials (SBOM), is continuously developed by a number of teams and committees. However, SPDX has welcomed a new addition; a team dedicated to enhancing metadata about software builds, complementing reproducible builds in creating a more secure software supply chain. The SPDX Builds Team has been working throughout May to define the universal primitives shared by all build systems, including the who, what, where and how of builds:
  • Who: the identity of the person or organisation that controls the build infrastructure.
  • What: the inputs and outputs of a given build, combining metadata about the build s configuration with an SBOM describing source code and dependencies.
  • Where: the software packages making up the build system, from build orchestration tools such as Woodpecker CI and Tekton to language-specific tools.
  • How: the invocation of a build, linking metadata of a build to the identity of the person or automation tool that initiated it.
The SPDX Builds Team expects to have a usable data model by September, ready for inclusion in the SPDX 3.0 standard. The team welcomes new contributors, inviting those interested in joining to introduce themselves on the SPDX-Tech mailing list.

Talks at Debian Reunion Hamburg Some of the Reproducible Builds team (Holger Levsen, Mattia Rizzolo, Roland Clobus, Philip Rinn, etc.) met in real life at the Debian Reunion Hamburg (official homepage). There were several informal discussions amongst them, as well as two talks related to reproducible builds. First, Holger Levsen gave a talk on the status of Reproducible Builds for bullseye and bookworm and beyond (WebM, 210MB): Secondly, Roland Clobus gave a talk called Reproducible builds as applied to non-compiler output (WebM, 115MB):

Supply-chain security attacks This was another bumper month for supply-chain attacks in package repositories. Early in the month, Lance R. Vick noticed that the maintainer of the NPM foreach package let their personal email domain expire, so they bought it and now controls foreach on NPM and the 36,826 projects that depend on it . Shortly afterwards, Drew DeVault published a related blog post titled When will we learn? that offers a brief timeline of major incidents in this area and, not uncontroversially, suggests that the correct way to ship packages is with your distribution s package manager .

Bootstrapping Bootstrapping is a process for building software tools progressively from a primitive compiler tool and source language up to a full Linux development environment with GCC, etc. This is important given the amount of trust we put in existing compiler binaries. This month, a bootstrappable mini-kernel was announced. Called boot2now, it comprises a series of compilers in the form of bootable machine images.

Google s new Assured Open Source Software service Google Cloud (the division responsible for the Google Compute Engine) announced a new Assured Open Source Software service. Noting the considerable 650% year-over-year increase in cyberattacks aimed at open source suppliers, the new service claims to enable enterprise and public sector users of open source software to easily incorporate the same OSS packages that Google uses into their own developer workflows . The announcement goes on to enumerate that packages curated by the new service would be:
  • Regularly scanned, analyzed, and fuzz-tested for vulnerabilities.
  • Have corresponding enriched metadata incorporating Container/Artifact Analysis data.
  • Are built with Cloud Build including evidence of verifiable SLSA-compliance
  • Are verifiably signed by Google.
  • Are distributed from an Artifact Registry secured and protected by Google.
(Full announcement)

A retrospective on the Rust programming language Andrew bunnie Huang published a long blog post this month promising a critical retrospective on the Rust programming language. Amongst many acute observations about the evolution of the language s syntax (etc.), the post beings to critique the languages approach to supply chain security ( Rust Has A Limited View of Supply Chain Security ) and reproducibility ( You Can t Reproduce Someone Else s Rust Build ):
There s some bugs open with the Rust maintainers to address reproducible builds, but with the number of issues they have to deal with in the language, I am not optimistic that this problem will be resolved anytime soon. Assuming the only driver of the unreproducibility is the inclusion of OS paths in the binary, one fix to this would be to re-configure our build system to run in some sort of a chroot environment or a virtual machine that fixes the paths in a way that almost anyone else could reproduce. I say almost anyone else because this fix would be OS-dependent, so we d be able to get reproducible builds under, for example, Linux, but it would not help Windows users where chroot environments are not a thing.
(Full post)

Reproducible Builds IRC meeting The minutes and logs from our May 2022 IRC meeting have been published. In case you missed this one, our next IRC meeting will take place on Tuesday 28th June at 15:00 UTC on #reproducible-builds on the OFTC network.

A new tool to improve supply-chain security in Arch Linux kpcyrd published yet another interesting tool related to reproducibility. Writing about the tool in a recent blog post, kpcyrd mentions that although many PKGBUILDs provide authentication in the context of signed Git tags (i.e. the ability to verify the Git tag was signed by one of the two trusted keys ), they do not support pinning, ie. that upstream could create a new signed Git tag with an identical name, and arbitrarily change the source code without the [maintainer] noticing . Conversely, other PKGBUILDs support pinning but not authentication. The new tool, auth-tarball-from-git, fixes both problems, as nearly outlined in kpcyrd s original blog post.

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb prepared and uploaded versions 212, 213 and 214 to Debian unstable. Chris also made the following changes:
  • New features:
    • Add support for extracting vmlinuz Linux kernel images. [ ]
    • Support both python-argcomplete 1.x and 2.x. [ ]
    • Strip sticky etc. from x.deb: sticky Debian binary package [ ]. [ ]
    • Integrate test coverage with GitLab s concept of artifacts. [ ][ ][ ]
  • Bug fixes:
    • Don t mask differences in .zip or .jar central directory extra fields. [ ]
    • Don t show a binary comparison of .zip or .jar files if we have observed at least one nested difference. [ ]
  • Codebase improvements:
    • Substantially update comment for our calls to zipinfo and zipinfo -v. [ ]
    • Use assert_diff in test_zip over calling get_data with a separate assert. [ ]
    • Don t call re.compile and then call .sub on the result; just call re.sub directly. [ ]
    • Clarify the comment around the difference between --usage and --help. [ ]
  • Testsuite improvements:
    • Test --help and --usage. [ ]
    • Test that --help includes the file formats. [ ]
Vagrant Cascadian added an external tool reference xb-tool for GNU Guix [ ] as well as updated the diffoscope package in GNU Guix itself [ ][ ][ ].

Distribution work In Debian, 41 reviews of Debian packages were added, 85 were updated and 13 were removed this month adding to our knowledge about identified issues. A number of issue types have been updated, including adding a new nondeterministic_ordering_in_deprecated_items_collected_by_doxygen toolchain issue [ ] as well as ones for mono_mastersummary_xml_files_inherit_filesystem_ordering [ ], extended_attributes_in_jar_file_created_without_manifest [ ] and apxs_captures_build_path [ ]. Vagrant Cascadian performed a rough check of the reproducibility of core package sets in GNU Guix, and in openSUSE, Bernhard M. Wiedemann posted his usual monthly reproducible builds status report.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Reproducible builds website Chris Lamb updated the main Reproducible Builds website and documentation in a number of small ways, but also prepared and published an interview with Jan Nieuwenhuizen about Bootstrappable Builds, GNU Mes and GNU Guix. [ ][ ][ ][ ] In addition, Tim Jones added a link to the Talos Linux project [ ] and billchenchina fixed a dead link [ ].

Testing framework The Reproducible Builds project runs a significant testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
  • Holger Levsen:
    • Add support for detecting running kernels that require attention. [ ]
    • Temporarily configure a host to support performing Debian builds for packages that lack .buildinfo files. [ ]
    • Update generated webpages to clarify wishes for feedback. [ ]
    • Update copyright years on various scripts. [ ]
  • Mattia Rizzolo:
    • Provide a facility so that Debian Live image generation can copy a file remotely. [ ][ ][ ][ ]
  • Roland Clobus:
    • Add initial support for testing generated images with OpenQA. [ ]
And finally, as usual, node maintenance was also performed by Holger Levsen [ ][ ].

Misc news On our mailing list this month:

Contact If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Next.

Previous.