Search Results: "ed"

16 June 2013

Daniel Pocock: Monitoring with Ganglia: an O'Reilly community book project

I recently had the opportunity to contribute to an O'Reilly community book project, developing the book Monitoring with Ganglia in collaboration with other members of the Ganglia team

The project itself, as a community book, pays no royalties back to the contributors, as we have chosen to donate all proceeds to charity. People who contributed to the book include
Robert Alexander, Jeff Buchbinder, Frederiko Costa, Alex Dean, Dave Josephsen, Bernard Li, Matt Massie, Brad Nicholes, Peter Phaal and Vladimir Vuksan and we also had generous assistance from various members of the open source community who assisted in the review process. Ganglia itself started at University of California, Berkeley as an initiative of Matt Massie, for monitoring HPC cloud infrastructure My own contact with Ganglia only began in 2008 when I was offered the opportunity to work full-time on the enterprise-wide monitoring systems for a large investment bank. Ganglia had been chosen for this huge project due to it's small footprint, support for many platforms and it's ability to work on a heterogeneous network as well as providing dedicated features for the bank's HPC grid. This brings me to one important point about Ganglia: it's not just about HPC any more. While it is extremely useful for clusters, grids and clouds, it is also quite suitable for a mixed network of web servers, mail servers, databases and all the other applications you may find in a small business, education or ISP environment. Instantly up and running with packages One of the most compelling features, even for small sites with less than 10 nodes, is the ease of installation: install the packages on Debian, Ubuntu, Fedora, OpenCSW and some other platforms, and it just works. Ganglia nodes will find each other over multicast, instantly, no manual configuration changes necessary. On one of the nodes, the web interface must be installed for viewing the statistics. Dare I say it: it is so easy, you hardly even need the book for a small installation. Where the book is really compelling is if you have hundreds or thousands of nodes, if you want custom charts or custom metrics or anything else beyond just installing the package. If monitoring is more than 10% of your job, the book is probably a must-have. Excellent open source architecture Ganglia's simplicity is largely thanks to the way it leverages other open source projects such as Tobi Oetiker's RRDtool and PHP Anybody familiar with these tools will find Ganglia is particularly easy to work with and customise. Custom metrics: IO service times One of my own contributions to the project has been the creation of ganglia-modules-linux, some plugins for Linux-specific metrics and ganglia-modules-solaris providing some similar metrics for Solaris. These projects on github provide an excellent base for people to fork and implement their own custom metrics in C or C++ The book provides a more detailed account of how to work with the various APIs for Python, C/C++, gmetric (command line/shell scripts) and Java. The new web interface For people who had tried earlier versions of Ganglia (and for those people who installed versions < 3.3.0 and still haven't updated), the new web interface is a major improvement and well worth the effort to install. It is available on the most recent packages (for example, it is in Debian 7 (wheezy) but not in Debian 6.) It was originally promoted as a standalone project (code-named gweb2) but was adopted as the official Ganglia web interface around the release of Ganglia 3.3.0. This web page provides a useful overview of what has changed and here is the original release announcement.

Joey Hess: little disasters

Interesting times.. While the big disasters are ongoing, little ones have been spicing up my life lately. A pleasant week by the beach ended with a tropical storm passing over the beach house. I've never experienced this before, and though Andrea was diminished by passing over land, it was still more wind than I've ever seen. I love wind, and this was thrilling, right on the edge of danger but not quite there. At least, if you have sense to stay out of the water. Leaving the beach, I heard of someone who tried to go surfing that day, and drowned. The night before last, I was startled to find nearly an inch of water seeping up from underneath the tile floor of the kitchen. Probably it has something to do with the pressure tank pumping system, which was repaired while I was away, and means I actually have indoor running water here. (Overrated.) This saw me scrambling to close every water valve, and out with a flashlight at 2 am closing the cutoff at the 1000 gallon water reservoir before it all drained into the house. While sopping up dozens of gallons of water from the floor at 3 am probably doesn't sound like fun, I found myself going through the motions elatedly.. Because this means I finally am coming to understand the source of the damp that infests the most earth-sheltered corner of this house. It's not condensation. It's bad plumbing! Then yesterday, I went out to try a dip in the river, stopped by the neighborhood eatery and bait shop, and ended up sitting out on the back deck eating ribs and listening to a band with "possum playboys" in their name (which makes the full name fairly irrelevant), while looking out over the river and the old-timey green metal bridge. Which was unexpected fun, and the kind of thing you have to take in when it happens, but getting stuck in a newly installed hole in my driveway was not. My car was spinning, and I gave up and called it a night. Here's the thing. I could feel my brain working on this stupid "underpowered car is stuck in a small rut" issue all night long. Same mental pathways activating that chew over bugs and design issues. Got up this morning with a set of plans and contingency plans all ready to go. The first one, of jacking it up and putting something under the tire was stymied; it seems I am missing a jack. But the second, of digging out all around the tire, and then filling in with gravel and cat litter (a tip from some offroading website I blearily surfed last night), and then riding the gas while releasing the bake, worked great. All of which is to say, bring em on! But I still prefer my disasters in the form of software bugs.

15 June 2013

C.J. Adams-Collier: Need help from Debian Developers, please.

Hi folks, I used to work at F5, and I pulled a bunch of equipment out of the recycle bin while I was there in order to help me populate the customer end premesis device inventory for a carrier network / ISP I am setting up. They decided to terminate my employment at the end of August last year, and I ve been wondering what to do with all of this equipment. I figured that it s been long enough that I can give them a call, so I did. I asked them whether I should consider buying BIG-IP hardware off of e-Bay if it said that it did not come with a license. The customer service agent told me that I should probably not consider doing any such thing, since I would have to pay a hefty fee to F5 before they would even provide a license. It looks like I d have to shell out fifty thousand dollars to get a proper F5 Networks Inc. license for these many surplus BIG-IP devices I have. I guess I ll just have to go with an improper (or maybe I mean not for profit) operating system like Debian. I wonder if I can get the current linux kernel to pick up these broadcom 10GE chips or whether I ll have to wait for someone to release Free as in speech firmware for them that I can make use of. Do any of you DDs want a shell on a linux box with a 10-port 10GE switch attached by PCI-e? I bet I could get a Debian chroot environment running in the system s stock rescue firmware. I bet I could then determine why the watchdog timer keeps tripping when I boot with other kernels If you decide to accept the offer of a shell on this box, please try to avoid rebooting it. It tends to pop my breakers and I have to run to the shop before the UPSs run out of juice.

Daniel Pocock: Girls Around Me and the NSA

When the Girls Around Me app was released in 2012, it received massive criticism on the basis that it could enable stalking and undermine privacy. Nonetheless, the existence of this app may well be an even bigger problem for the NSA right now than it is for single women. US Government officials in damage control mode over the NSA surveillance leaks have sought to deny that it is even possible to monitor people in the way that The Guardian reported the matter. Leaders of Internet giants such as Google and Facebook have also tried to deny and downplay the possibilities of PRISM. In my view, a company like Google is no more likely to admit hiving off customer data than a bank is likely to admit a liquidity crisis, for fear of starting a self-fulfulling bank run. User trust is as existential with data as it is with bank deposits. So my question is, if the NSA with an $8 billion annual budget can't track people in real-time, how come a small team of app developers could do much the same thing so easily in Girls Around Me? One possibility is that some companies may be accurate in what they have reported: they are not letting data out the back door. The scary thing is, they are letting it out the front door and it is just as possible for third-party commercial operators and foreign powers to harvest a lot of this data in the same way as Girls Around Me In one of the most remarkable cases, the chief of British MI6 (the team that James Bond plays for) may have been compromised by his wife's Facebook posts - if Facebook really is an outsourced NSA operation, then that is a remarkable case of friendly fire Both the scandals around Girls Around Me and the NSA spying leaks only serve to confirm one thing: that people need to think twice every time they fill in some form or submit some data that could be used to identify or track them.

Benjamin Mako Hill: Indian Veg

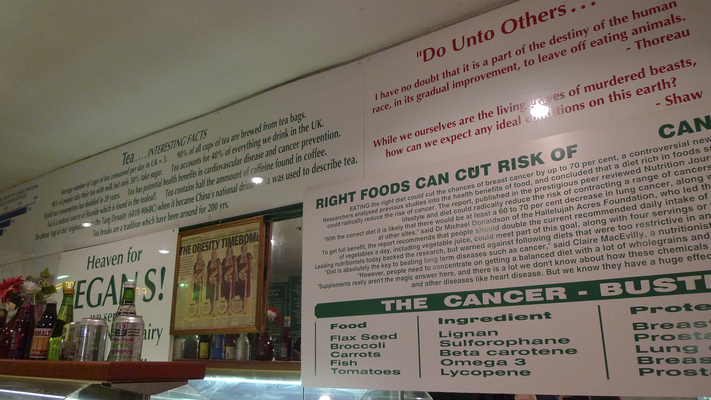
Recently, I ate at the somewhat famous London vegetarian restaurant Indian Veg Bhelpoori House in Islington (often referred to simply as Indian Veg ).

I couldn t help but imagine that the restaurant had hired Emanuel Bronner as their interior decorator.Indian Veg Signage (2)

Signs on the wall at Indian Veg

Ingo Juergensmann: Debian-ports mirror on Buildd.Net

As a more or less unrelated side effect of the Debian m68k port resurrection I decided to give back something to debian-ports.org as we are relying on that service for our port. So I set up a debian-ports.org mirror: The mirror is running on a fast Gigabit connection and is reachable via IPv4 and (native) IPv6. It carries all current archs. Enjoy!
Kategorie:

Ingo Juergensmann: First m68k buildd relocated to FU Berlin

It's already been some days ago, but our first m68k buildd, elgar.buildd.net, has been relocated to its new hosting facility in Berlin on June 2nd. Its new home is located at the Physics Department of Freie Universit t (FU) Berlin. So a big thank you to FU Berlin and John Paul Adrian Glaubitz to make this happen! With Elgar being now hosted in Berlin the resurrection of the m68k port is steadily ongoing. More machines will be follow Elgar: while Elgar will be accompanied in Berlin by Akire (akire.buildd.net), Kullervo and Crest will hopefully be hosted at their old hosting donator NMMN in Hamburg somewhat later. The m68k port itself is doing fine and coped well with the all the new packages after the release of Wheezy:
  wanna-build statistics - Sat Jun 15 16:51:13 CEST 2013
  -----------------------------------------------------
Distribution unstable:
---------------------
Installed       :  7041 (buildd_m68k-ara5: 1016, buildd_m68k-arrakis: 157,
                         buildd_m68k-elgar: 201, buildd_m68k-kullervo: 238,
                         buildd_m68k-vivaldi: 153, tg: 53, unknown: 5223)
Needs-Build     :   780
Building        :     9 (buildd_m68k-ara5: 1, buildd_m68k-arrakis: 3,
                         buildd_m68k-elgar: 2, buildd_m68k-kullervo: 2,
                         buildd_m68k-vivaldi: 1)
Built           :     1 (buildd_m68k-elgar: 1)
Uploaded        :     0
Failed          :    73 (buildd_m68k-ara5: 51, buildd_m68k-kullervo: 10,
                         tg: 12)
Dep-Wait        :     3 (tg: 3)
Reupload-Wait   :     0
Install-Wait    :     0
Failed-Removed  :     0
Dep-Wait-Removed:     0
BD-Uninstallable:  1977
Auto-Not-For-Us :   192
Not-For-Us      :    50
total           : 10227
 68.85% (7041) up-to-date,  68.85% (7041) including uploaded
  7.63% (780) need building
  0.09% (  9) currently building
  0.01% (  1) already built, but not uploaded
  0.74% ( 76) failed/dep-wait
  0.00% (  0) old failed/dep-wait
 19.33% (1977) not installable, because of missing build-dep
  1.88% (192) need porting or cause the buildd serious grief (Auto)
  0.49% ( 50) need porting or cause the buildd serious grief
We are now constantly above 7000 packages installed, which is great considering the fact that we were at 10% keeping up by December 2012. Now we are approx 70% with just 5 buildds. Of course we would like to get more buildds up & running, but currently there is the SCSI driver for the NCR53C9XF(espfast) chip missing for m68k. Sadly this chip is used on several accelerator cards for Amiga. With a working SCSI driver we could easily double our number of buildds. But I hope that this will just be a matter of time... :-)
Kategorie:

Paul Tagliamonte: dput-ng 1.5

If all goes well, a new release of dput-ng will hit the archive this week (depending on when I can find time to close the last 2 bigger bugs) - anyone interested in getting a new feature into dput-ng should email me (or file a reportbug bug at dput-ng) Small list of changes so far: * Add per-host loading of command files by partially parsing command line arguments. * Add disallowed_distributions. * Add codename groupping support. * Add codename groups to vital targets, limit security uploads to the right servers (Closes: #708575). * Implement dcut commands for Deb-o-Matic. * Add an override and a unset option to dput which overrules any profile key. This is an experimental option. * Be more precise about our configuration file inheritance in dput(5). * Fix dcut: manpage and help talk about -U and upload by replacing those parts in the text by the upload command (Closes: #699812) * Make the login name determination more portable (Closes: #709831) * Fix Allow to give out dm permissions without using local keyring by * documenting the force option in the man page (Closes: #711057) * Allow uploads to mentors to target every distribution * Add a space in debug s help message. * Fixed a typo (DEBNAME DEBFULLNAME) in the dcut(1) manpage. Thanks, y all!

Lars Wirzenius: "Um, I know I should": talking about backups

... backups? did someone talk about backups? I'm sure I heard someone mention backups here somewhere. Backups! BACKUPS! BACKUPS ARE AWESOME!
That's a direct quote from my recent IRC history. I find backups quite interesting, particularly from an implementation point of view, and I may sometimes obsess about them a little bit. This is why I've written my own backup software. I'm unusual: most people find backups boring at best, and tedious most of the time. When I talk with people about backups, the usual reaction is "um, I know I should". There are a lot of reasons for this. One is that backups are a lot like insurance: you have to spend time, effort, money, up front, to have any use for them. Another is that the whole topic is scary: you have to think about when things go wrong, and that puts people off. A third reason is that while there are lots of backup tools and methods, it's not always easy. After all, backups are about answering the question, "what can I do to keep my data safe, whatever happens in the future?". I've spent a fair bit of the past several years thinking about backups. This is the first in a series of blog posts about backups, where I share my thinking about the topic. Perhaps it can be of some use to others. At least people will poke holes in my delusions. In this post, I'll define some terminology. I am not a backup scholar, and I may have invented some of these terms myself, and they may be different from what real sysadmins use. I'll define the words I use, so we can understand each other. Live data is the data you work with or keep. It's the files on your hard drive: the documents you write, the photos you save, the unfinished novels you wish you'd finish. A backup is a spare copy of your live data. If you lose some or all of your live data, you can get it back ("restore") from your backup. The backup copy is, by practical necessity, older than your live data, but if you made the backup recently enough, you won't lose much. Sometimes it's useful to have more than one old backup copy of your live data. You can have a sequence of backups, made at different times, giving you a backup history. Each copy of your live data in your backup history is a generation. This lets you retrieve a file you deleted a long time ago, but didn't realise you needed until now. If you only keep one backup version, you can't get it back, but if you keep, say, a daily backup for a month, you have a month to realise you need it, before it's lost forever. The place your backups are stored is the backup repository. You can use many kinds of backup media for backup storage: hard drives, tapes, optical disks (DVD-R, DVD-RW, etc), USB flash drives, online storage, etc. Each type of medium has different characteristics: size, speed, convenicence, reliability, price, which you'll need to balance for a backup solution that's reasonable for you. You may need multiple backup repositories or media, with one of them located off-site, away from where your computers normally live. Otherwise, if you house burns down, you'll lose all your backups too. You need to verify that your backups work. It would be awkward to go to the effort and expense of making backups and then not be able to restore your data when you need to. You may even want to test your disaster recovery by pretending that all your computer stuff is gone, except for the backup media. Can you still recover? You'll want to do this periodically, to make sure your backup system keeps working. Most live data is precious in that you'll be upset if you lose it. Some live data is not precious: your web browser cache probably isn't, for example. This distinction can let you limit the amount of data you need to back up, which can significantly reduce your backup costs. There is a very large variety of backup tools. They can be very simple and manual: you can copy files to a USB drive using your file manager, once a blue moon. They can also be very complex: enterprise backup products that cost huge amounts of money and come with a multi-day training package for your sysadmin team, and which require that team to function properly. You'll need to define a backup strategy to tie everything together: what live data to back up, to what medium, using what tools, what kind of backup history to keep, and how to verify that they work. That's the groundwork. In the next episode, I'll blather about what is a backup, and what isn't.

Wouter Verhelst: The end of an era

I've been singing for a long time. The first time I was a member of a choir was when I was around 6-7 years old, and it was as a member of the children's choir 'De Lambertijnen' in Ekeren, Belgium. Not by coincidence, Ekeren is where I grew up. However, I didn't remain a member of 'De Lambertijnen' for very long. After a year or two, I was over the maximum age for members of that choir, and "promoted" to Carmina, another children's choir of the same association. I didn't like that choir as much, though, and only remained a member for about a year or so, before I left that choir; and for a few years, choral music was no longer part of my interests. Then, when I turned sixteen, I was in a school where choral music was part of the curriculum; and through class, I found out that singing in a choir is something I actually love. By that time I was too old to join Carmina again, so I joined the C-koren's youth choir "Cantilene" under Luc Anthonis, instead. Luc is one of Belgium's finest choir conductors, and so I remained a member until my 26th birthday when, again, I was deemed too old to remain a member of that choir. At this point, the next choir in line was "Con Amore", a choir that does not have an age limit, but which in practice consists of mostly people who are retired (or nearly so, at least). As a result, most people who leave Cantilene do not join Con Amore, instead ending their foray into choral music. I was no exception. However, a year and a half (or so) later, the C-koren were extended with a new choir, "Caljent ", who jumpstarted their membership by contacting ex-Cantilene members (me amongst them), inviting them to join this new choir. I have been a member since the first official rehearsal of Caljent , and have always enjoyed it; enough so that when I moved out of Ekeren some five years ago, into a flat in Mechelen (a 30 minute car trip away), I did not quit the choir. I can, however, not deny that since moving out, my connection to Ekeren has become fairly strained, and that there have been times when I felt it difficult to motivate myself into driving all the way there for a rehearsal on friday night. I felt that to be unfair towards the conductor and towards the other members of the choir, and so it is with mixed feelings that I decided a month or so ago to remain a member only until the last rehearsal before the summer break this year. That last rehearsal was today (well, technically yesterday by now); and so, after a "career" of almost 20 years of nearly uninterrupted membership (including one 5-year stint as a member of Cantilene's governing board), I am now no longer a member of the C-koren. That's not to say I won't be singing anymore in fact, I've already joined a different choir whose rehearsal location just happens to be right around the corner from where I live but it does certainly feel weird to be putting an end to my C-koren membership. Ah well, we'll see what the future brings.

Gregor Herrmann: should I feel dirty now?

I've set up a windows machine yesterday (& today since this takes so long). on my own old laptop. at home. & it's running in my apartment. feels strange after living in windows-free apartments for quite some years. & I'm still not sure how I feel about it. the purpose of resurrecting my old laptop is to run a CPAN smoke tester. there are constant complaints in the perl community about the low amount of test reports from windows installations (& for older distributions, so I'm running CPAN::Reporter::Smoker with 'reverse' => 1, at least once). for the time being, I'm using non-free software to improve free software. let's see how this develops ps: I'm also running a CPAN smoke tester on my raspberry pi (under raspbian with a perlbrewed perl) since a few days. it's a bit slow but well :)

14 June 2013

Steve Kemp: Debian is missing a tool, want to write it?

Seeing this piece in the news, about how Debian-Multimedia.org is now unsafe, I was reminded we don't have a tool to manipulate sources.lists entries. For example:
$ apt-sources list
..
deb http://ftp.uk.debian.org/debian/ squeeze main non-free contrib
deb-src http://ftp.uk.debian.org/debian/ squeeze main
deb http://security.debian.org/ squeeze/updates main
deb-src http://security.debian.org/ squeeze/updates main
..
How about listing only my repos?
$ apt-sources list steve.org.uk
deb-src http://packages.steve.org.uk/firefox-wrapper/squeeze/ ./
deb     http://packages.steve.org.uk/firefox-wrapper/squeeze/ ./
deb     http://packages.steve.org.uk/meta/squeeze/ ./
deb-src http://packages.steve.org.uk/meta/squeeze/ ./
deb-src http://packages.steve.org.uk/minidlna/squeeze/ ./
deb     http://packages.steve.org.uk/minidlna/squeeze/ ./
Now add in a command to delete lines matching a given pattern:
# apt-sources delete debian-multimedia.org
Doesn't that seem like a tool that should exist? I've added this quick hack to this repository which you can submit pull requests against, or use as a base. TODO: Write the "add" handler. Neaten. Ever felt jealous that Ubuntu users can add PPAs? Nows your chance to do something like this:
# apt-sources add "deb http://packages.steve.org.uk/lumail/wheezy/ ./"

13 June 2013

Daniel Pocock: Skype Scandal and the Jedi Council

Normally Skype isn't mentioned by name on this blog, but today I'm making an exception. When a new scandal broke out in the Australian Army today, one of the first questions asked was how does it compare to the Skype Scandal which had everybody talking (and blushing) in 2011. A concise military reply direct from the General: "I'd say it's worse than the Skype matter" (the original Skype Scandal cadets are going on trial in six weeks) Jedi Council brings cultural change in the Army: from Skype to email Since the original scandal, there have been plenty of PR-orchestrated headlines about cultural change in the Army. Sadly, it seems that several ranking officers believed that was a cue to simply start using email instead of live feeds Operating under the operational code name Jedi Council, they've apparently been swapping annotated images of female colleagues and members of the public service. A more detailed account summarises it: "They were calling themselves the Jedi Council but they were doing the exact opposite of what Jedis are supposed to do" While the Skype scandal involved cadets behaving much like college kids elsewhere, this latest scandal involves the officer corp, the most senior officer implicated is allegedly a Lieutenant Colonel. Senior ranking officers like this have given many years of dedicated service to the country. They are widely respected and the vast majority of officers in these positions are unlikely to ever be implicated in such a scandal. Officers are in leadership roles, it should be no surprise if they have top secret security clearances. After the revelation that Australia has a direct and high-volume data sharing arrangement with the US Government (and in turn Facebook, Google, etc), there are all kinds of questions about whether a couple of rogue officers have access to pursue their private Jedi Council project using tools like PRISM and Boundless Informant. It's already been confirmed that they were keeping their own Jedi database of their victim's names, phone numbers, home addresses and various clothing measurements and if they are already emailing these photos about on Defence computers, does it seem improbable that they would be using PRISM or other sources to cross-reference their data? Behavior described as systematic and predatory It can't be ruled out that some defence computer systems may have direct access to NSA copies of images from those invasive airport body scanners - like these pictures that were not supposed to exist. Just like the British undercover cops stealing the identities of dead children and fully engaging with impressionable young women from environment campaign groups, there are a long list of possible abuses when the security state is over-empowered. While this latest Army example involves private pursuits, it is not hard to imagine many other permutations: perhaps a couple of rogue Government employees making unauthorised use of PRISM data for a commercial objective and gaining the upper hand on private sector competitors who have no such data feed. 100% trust? In every organisation there will always be a few people bending the rules. It's human nature, if it wasn't that way, we'd all be robots (or drones). The Army and the Catholic Church tend to be hammered a lot more in the public eye when these transgressions are discovered although statistically their crime rates are no higher than average. The bottom line is that no organisation is perfect and people have to take some responisbility to object to the excessive growth of the security state and keep our data to ourselves as you just never know who you can trust.
Bits from Debian: Remove unofficial debian-multimedia.org repository from your sources

The unofficial third party repository Debian Multimedia stopped using the domain debian-multimedia.org some months ago. The domain expired and it is now registered again by someone unknown to Debian. (If we're wrong on this point, please sent us an email so we can take over the domain! ;) ) This means that the repository is no longer safe to use, and you should remove the related entries from your sources.list file. After all, the need of an external repository for multimedia related packages has been greatly reduced with the release of Wheezy, which features many new and updated codecs and multimedia players. Not sure if you're using the debian-multimedia repository? You can easily check it by running: grep -i debian-multimedia.org /etc/apt/sources.list /etc/apt/sources.list.d/* If you can see debian-multimedia.org line in output, you should remove all the lines including it.

Richard Hartmann: Another one eats a brick

Dear lazyweb, my Nexus 4 just ate a brick and the screen is so broken that the capacitative sensing stopped working completely. That sucks a bit, especially considering that you can't really replace the screen according to ifixit... What sucks more is this: As my phone is both encrypted and passphrase-protected, I can't access my photos. Yes, yes, I should have set up git-annex on it by now, but that's of no help now. So... How do I get my data off of that phone? Again, I don't really care about much other than my photos.

Michal &#268;iha&#345;: Fund Weblate features

Weblate is now year and half old, has quite many users and almost all features I wanted it to have. Now it's time to push it further to fit also other projects. Therefore I've decided to try crowdfunding on Catincan to see which of requested features are actually wanted most. Yes, you can vote with your money :-). The first set of features to fund is: This is my first experiment with crowdfunding, so I'm looking forward to it's results.

Filed under: English Weblate 0 comments Flattr this!

Dirk Eddelbuettel: inline 0.3.12

Another maintenance release of inline is now on CRAN and in already included in Debian. This release was triggered by a change in the development version of R which removed an argument to package.skeleton(). The complete NEWS entry is below.
Changes in inline version 0.3.12 (2013-06-12)
  • Align package.skeleton with the R-devel version of the function which no longer has a NAMESPACE argument.
  • Remove copy of LGPL in source archive as R CMD check now complains about it. License status continues to be specified in file DESCRIPTION.
Courtesy of CRANberries, there is also a diffstat report for the most recent release. A few more details are available at the R-Forge page.

12 June 2013

Daniel Pocock: When conspiracy theories come true

In a blog attempting to join the dots between Australia's intelligence services and the US PRISM program, I speculated that Australia has had extensive access to data harvested by PRISM. My hunch has just been exposed rather dramatically today: Top secret data center under construction to house all our secrets. "There has been no discussion of the project in Senate estimates committee hearings, and the public reports of Parliament's joint committee on intelligence and security make no reference to it." The news story also suggests that the relationship is bi-directional, with data harvested from Australian ISPs cross referenced against US databases from Facebook and Google. From a human rights perspective, the implications of this data sharing are much more dramatic than the NSA just snooping on US citizens within the US. While Australia often tries to portray the image that it is a safe and happy country, it has a dark side. Police are kept busy investigating politicians and Government officials: Prime Minister and her associates connected to a union slush fund, the central bank's banknote printing agency's chief executive and 8 colleagues on conspiracy charges and even a senator on good old fashioned shoplifting and assault charges Exporting PRISM data to a human rights backwater As an Australian, my own rights and those of my family are more heavily protected and respected living in Europe than if I lived in my country of birth. Australia does not have a bill of rights like the US (where PRISM data is harvested) or the European Convention of Human Rights. Once US data is exported to Australia, it can be used to support sinister programs like the indefinite detention of coloured people in sinister desert camps. Just this week, the Government left over 50 bodies of poor refugees for the sharks to eat. For someone with such a lack of a conscience, can you imagine them thinking twice about using PRISM data for unscrupulous purposes? Is US PRISM data at greater risk? Despite the stench of corruption and lip service to human rights, is there any hard evidence that PRISM data will be at greater risk if allowed into the hands of Australians? Death by SMS One former Australian official (having dual-citizenship with Sri Lanka) is accused of facilitating war crimes in the Sri Lankan civil war. At present he is Sri Lanka's ambassador at the UN, giving him the benefit of diplomatic immunity. When he was working for Australia, how much data did he have access to? Isn't it ludicrous that in the name of stopping terrorism, data may have been collected and handed to war criminals on a silver platter? Behind enemy lines Like James Bond in reverse, an Australian official was exposed unofficially engaging in a relationship with a Vietnamese spy colonel. In addition to the $20 million in bribery to win a bank note printing contract, is data being used as a tool to leverage trade negotiations, officially or otherwise? If an Australian official with top-secret clearance ends up under the control of a foreign agent, what is the risk that they would be exploited to obtain PRISM data? Defence minister resignation in Chinese spy scandal In 2009 Australia's defence minister was identified having close links to a Chinese-Australian business woman including all the usual little luxuries: first class flights, apartment rental and joint business deals with family members. He subsequently resigned. Little details were made public. How much PRISM data was directly available to political officials like the defence minister? Disappearing Prime Ministers The disappearance of a serving Prime Minister, Harold Holt, during the cold war remains an unsolved mystery to this day. People continue to ask was he swept out to sea or voluntarily whisked away in a Chinese or Soviet nuclear submarine. While Australia has traditionally had strong ties to Britain and the US, there have been exceptions to the rule. Fortunately this all happened before PRISM and Harold Holt red submarine rumours are no more well-founded than the UFO theories of his abduction. Where did all the data go? As the music industry has found out the hard way, digital data can be copied at will with the originator having no control. The revelations that Britain and Australia are in on the PRISM shenanigans only confirms that this data is seen as a new form of currency for exchange in geo-political posturing. While used weapons take decades to work their way down the chain, data can spread at the speed of light.

Dominique Dumont: Improving error messages of Dpkg dependency parser

Hello Config::Model::Dpkg project (a Debian source package model based on Config::Model) is partly based on a ParseRec::Descent grammar. This grammar is used to parse the dependency of a Debian source package. This article will show how such a grammar is written, its limitation regarding error handling and how to improve the situation. Debian package main data is described in debian/control file. This file can feature a list of dependencies, i.e. a list of package that must be installed for the package to work. These dependencies are declared in fields like Build-Depends , or Depends as a list of package. For Dpkg model purpose, I needed only to parse one item of a dependency list at a time. This dependency item can be a simple package name: foo or a package name with a version requirement: foo ( > 1.24 ) or a package name with architectures restrictions: foo [alpha amd64 hurd-arm linux-armeb] or both: foo ( > 1.24 ) [alpha amd64 hurd-arm linux-armeb] or a list of alternate choices combining the possibilities above: foo ( > 1.24 ) bar [ linux-any] baz ( << 3.14 ) [ ! hurd-armel !hurd-armeb ] or a variable that is replaced during package build: $ perl-depends Writing a Parse::RecDescent grammar to parse this is relatively straightforward. The first production handles alternate dependencies separated by and raises an error if some text was not consumed by the dependencies:
dependency_item: depend(s /\ /) eofile  
A dependency as explained above is expressed as:
depend: pkg_dep   variable
A variable like $ foo or $ bar -1.24~ is parsed with:
variable: /\$ [\w:\-]+ [\w\.\-~+]*/
This rule handles a package name with optional version or arch restriction:
pkg_dep: pkg_name dep_version(?) arch_restriction(?) 
pkg_name: /[a-z0-9][a-z0-9\+\-\.]+/
The remaining rules are quite simple:
dep_version: '(' oper version ')' 
oper: '<<'   '<='   '='   '>='   '>>'
version: variable   /[\w\.\-~:+]+/
arch_restriction: '[' arch(s) ']'
arch:  /!?[\w-]+/
eofile: /^\Z/
The grammar above works well to parse the dependency. You can test it with this small Perl script:
#!/usr/bin/perl
use strict;
use warnings;
use 5.010 ;
use Parse::RecDescent ;
my $parser = Parse::RecDescent->new(join('',));
my $dep = shift ;
say "parsing '$dep'";
my $ret = $parser->dependency_item($dep) ;
say "result is ", $ret if $ref ;
__DATA__
# insert grammar here !!!
Unfortunately, any error in the optional parts (i.e version requirements and arch restriction) leads to an error message which is not very helpful. The error message only mention that some text could not be parsed:
parsing 'foo ( != 1.24 )   bar'
       ERROR (line 1): Invalid dependency item: Was expecting /\ / but found
                       "( != 1.24 )   bar" instead
or
parsing 'foo [ arm & armel]   bar'
       ERROR (line 1): Invalid dependency item: Was expecting /\ / but found
                       "[ arm & armel]   bar" instead
The problem comes from the fact that version requirements or arch restrictions are optional. For instance if a version requirement has a syntax error, Parse::RecDescent will try to parse it as an arch restriction. This arch restriction rule will also fail and the last terminal ( eofile ) will fail. So the error message does not hint at the actual syntax problem. To generate better error messages, I improved the suggestion made in Parse::RecDescent FAQ. Instead of calling a plain subroutine, I use a sub reference that will store the error messages in a closure. This sub ref is declared in a start-up action. Note that the sub ref explicitly returns undef. I ll explain why later.
 
    my @dep_errors ;
    my $add_error = sub  
        my ($err, $txt) = @_ ;
        push @dep_errors, "$err: '$txt'" ;
        return ;
      ;
 
The following production always fails while ensuring that the error list is reset. This production is always run at the beginning of the dependency parsing:
dependency:   @dep_errors = ();  
Here s the actual dependency production that is run when dependency method is called on the parser. It will return an array ref containing (1, data) if the dependency is valid or (0, errors) otherwise:
dependency: depend(s /\ /) eofile
   
    $return = [ 1 , @ $item[1]  ] ;


    push( @dep_errors, "Cannot parse: '$text'" ) unless @dep_errors ;
    $return =  [ 0, @dep_errors ];
   
The following productions don t change much:
depend: pkg_dep   variable
variable: /\$ [\w:\-]+ [\w\.\-~+]*/
pkg_dep: pkg_name dep_version(?) arch_restriction(?) 
dep_version: '(' oper version ')'
The first rule of this production parses the package name which must be followed by a space, end of string ( or ['. A positive look-ahead assertion is used so only the package name is consumed. If the first rule fails, the second rule provides a meaningful error message. The second rule will match anything which is not a space and create an error message. Since $add_error returns undef, the second rule returns undef and the production fails. So the text stored in the error message is not consumed:
pkg_name: /[a-z0-9][a-z0-9\+\-\.]+(?=\s \Z \( \[)/
      /\S+/   $add_error->("bad package name", $item[1]) ; 
The same trick is used with these productions:
oper: '<<'   '='   '>>'
      /\S+/   $add_error->("bad dependency version operator", $item[1]) ; 
version: variable   /[\w\.\-~:+]+(?=\s \) \Z)/
      /\S+/   $add_error->("bad dependency version", $item[1]) ; 
The action of this production is a little bit more tricky. The action ensures that '!' are either added before all arch or not at all. Otherwise an error message is generated and added to the list of errors:
arch_restriction: '[' osarch(s) ']'
     
        my $mismatch = 0;
        # $ref contains ['!',os,arch] or ['',os,arch]
        my $ref = $item[2] ;
        for (my $i = 0; $i < $#$ref -1 ; $i++ )  
            $mismatch  = ($ref->[$i][0] xor $ref->[$i+1][0]) ;
         
        my @a = map   ($_->[0]   '') . ($_->[1]   '') . $_->[2]   @$ref ;
        if ($mismatch)  
            $add_error->("some names are prepended with '!' while others aren't.", "@a") ;
         
        else  
            $return = 1 ;
         
     
The check above is possible only if the "osarch" production returns an array ref containing something like ('!','linux','any') for "!linux-any' or ('','linux','any') for "linux-any":
osarch: not(?) os(?) arch
     
        $return =  [ $item[1][0], $item[2][0], $item[3] ];
     
      /.?(?=\s \] \Z)/   $add_error->("bad arch specification: ", $item[1]) ;  
not: '!'
Here's the remaining of the grammar:
os: /(any uclibc-linux linux kfreebsd knetbsd etc...)-/
     /\w+/ '-'   $add_error->("bad os in architecture specification", $item[1]) ; 
arch: / (any  alpha amd64  arm\b  arm64  etc... )
        (?=(\]  ))
      /x
        /\w+/   $add_error->("bad arch in architecture specification", $item[1]) ; 
eofile: /^\Z/
That's all for grammar 2.0... Before someone yells: "Show me the message ! ", here are some example of bad dependencies and their error message generated by the parser:
parse 'foo ( != 1.24 )   bar'
result is: 0 bad dependency version operator: '!='
parsing 'foo [ arm & armel]   bar'
result is: 0 bad arch specification: : '&'
parsing 'foo [ arm armel ]   bar [!moo]'
result is: 0 bad arch specification: : ']' bad arch in architecture specification: 'moo'
The 2 first error messages are spot on the actual error. The second one has a false positive (']' is correct) but correctly highlights the wrong arch name ('moo'). Mission accomplished. In order to keep this post (relatively) simple, I've removed the part that actually store parsed data. They don't really matter for error handling. Nevertheless, you may see the whole grammar in Config::Model::Dpkg::Dependency module. All the best
Tagged: Config::Model, debian, dpkg, package, Parse::RecDescent, Perl

Bernhard R. Link: listing your git repositories on git.debian.org

With the new gitweb version available on alioth after the upgrade to wheezy (thanks to the alioth admins for their work on alioth), there is a new feature available I want to advertise a bit here: listing only a subtree of all repositories. Before now one could only either look at a specific repository or get the list of all repositories and the list of all repositories is quite large and slow. With the new feature you can link to all the repositories in your alioth project. For example in reprepro's case that is http://anonscm.debian.org/gitweb/?pf=mirrorer. Much more I missed what is now possible with the link http://anonscm.debian.org/gitweb/?pf=debian-science: getting a list of all debian-science repositories (still slow enough, but much better than the full list).

Next.

Previous.