Search Results: "xam"

5 October 2020

Russ Allbery: California general election

As normal, probably of direct interest only to California residents and apologies to everyone else since my hand-rolled blog software doesn't do cut tags. I'm only going to cover propositions, since the state-wide elections aren't very interesting and I both don't have strong opinions about the local elections and would guess that almost no one cares. See the voter guide for the full details on each proposition. Propositions 16 through 19 were put on the ballot by the legislature and thus were written as well as our regular laws. The remaining propositions are initiatives, which means I default to voting against them because they're usually poorly-written crap. Proposition 14: NO. I reluctantly supported the original proposition to fund stem cell research with state bonds because it was in the middle of the George W. Bush administration and his weird obsession with ending stem cell research. It seemed worth the cost to maintain the research, and I don't regret doing this. But since then we've reached a compromise on ongoing research, and this proposition looks a lot more like pork spending than investment. I am in favor of government support of basic research, but I think that's best done by a single grant institution that can pursue a coherent agenda. The federal government, when sane, does a decent job of this, and the California agency created by the previous proposition looks dodgy. The support for this proposition also comes primarily from research institutions that benefit from it. On top of that, there are way higher priorities right now for public investment than a very specific and limited type of medical research that isn't even the most important type of medical research to do right now. There is nothing magic about stem cells other than the fact that they make a certain type of Republican lose their minds. It's time to stop funding this specific research specially and roll it into general basic research funding. Proposition 15: YES. Yes to anything that repeals Proposition 13 in whole or in part. Repealing it for commercial and industrial real estate is a good first step. A rare exception in my general rule to vote against initiatives. Proposition 16: YES. Reverses a bad law to outlaw affirmative action in California. I am in favor of actual reparations, so I am of course in favor of this, which is far, far more mild. Proposition 17: YES. Restores voting rights to felons after completion of their sentence. I think it's inexcusable that any US citizen cannot vote, including people who are currently incarcerated, so of course I'm in favor of this more mild measure. (You may notice a theme.) When we say everyone should be able to vote, that should mean literally everyone. Proposition 18: YES. Allows 17-year-olds to vote in California (but not federal) elections in some specific circumstances. I'm generally in favor of lowering the voting age, and this seems inoffensive. (And the arguments against it are stupid.) Proposition 19: YES. This is a complicated legislative compromise around property tax that strengthens property tax limits for seniors moving within California while removing exemptions against increases for inherited real estate not used as a primary home. Some progressives are opposed to this because it doesn't go far enough and increases exemptions for seniors. I agree that those exemptions aren't needed and shouldn't be added, but closing the inheritance loophole is huge and worth this compromise. It's a tepid improvement for the somewhat better, but it's still worth approving (and was written by the legislature, so it's somewhat better written than the typical initiative). Proposition 20: NO. Another pile of "anyone who has ever committed a crime deserves to be treated as subhuman" bullshit. Typical harsher sentences and harsher parole nonsense. No to everything like this, always. Proposition 21: YES. This is my other exception of voting for an initiative, and that's because the California state legislature is completely incapable of dealing with any housing problem. This is a proposition that overhauls an ill-conceived state-wide restriction on how rent control can be handled. The problem with rent control is that a sane solution to housing problems in this state requires both rent control and massive new construction, and we only get the former and not the latter because the NIMBYism is endemic. (There's a pile of NIMBY crap on my local ballot this year.) I would much rather be approving those things together, because either of them alone makes things worse for a lot of people. So yes, the opponents of this proposition are right: it will make the housing crisis worse, because everyone refuses to deal with the supply side. That said, we need rent control as part of a humane solution, and the current state-wide rules are bad. For example, they disallow rent control on every property newer than a certain date that's forever fixed. This initiative replaces that with a much saner 15-year rolling window for maximizing profit, which is a better balance. I hate voting for this because the legislature should have done their job and passed comprehensive housing reform. But since they didn't, this is part of what they should have passed, and I'll vote for it. Particularly since it's opposed by all the huge commercial landlords. Proposition 22: NO. The "exclude Uber and Lyft from labor law" proposition, which is just as bullshit as it sounds. They're spending all of their venture capital spamming the crap out of everyone in the state to try to get this passed by lying about it. Just stunningly evil companies. If your business model requires exploiting labor, get a better business model. Proposition 23: NO. So, this is another mess. It appears to be part of some unionization fight between dialysis clinic employees and the for-profit dialysis clinics. I hate everything about this situation, starting from the fact that we have such a thing as for-profit dialysis clinics, which is a crime against humanity. But this proposition requires some very dodgy things, such as having a doctor on staff at every clinic for... reasons? This is very reminiscent of the bullshit laws about abortion clinics, which are designed to make it more expensive to operate a clinic for no justifiable reason. I'm happy to believe there is a bit more justification here, but this sort of regulation is tricky and should be done by the legislature in a normal law-making process. Medical regulation by initiative is just a horrible idea in every way. So while I am doubtless politically on the side of the proponents of the proposition, this is the wrong tool. Take it to the legislature. Proposition 24: NO. A deceptively-written supposed consumer privacy law written by tech companies that actually weakens consumer privacy in some critical ways that are profitable for them. No thanks, without even getting to the point that this sort of thing shouldn't be done by initiative. Proposition 25: YES. Yes, we should eliminate cash bail, which is essentially imprisoning people for being poor. No, this doesn't create a system of government profiling; judges already set bail and can revoke bail for flight risks. (This is not legislation by initiative; the state government already passed this law, but we have a dumb law that lets people oppose legislative action via initiative, so we have to vote to approve the law that our representatives already passed and that should have already gone into effect.)

3 October 2020

Steve Kemp: Writing an assembler.

Recently I've been writing a couple of simple compilers, which take input in a particular format and generate assembly language output. This output can then be piped through gcc to generate a native executable. Public examples include this trivial math compiler and my brainfuck compiler. Of course there's always the nagging thought that relying upon gcc (or nasm) is a bit of a cheat. So I wondered how hard is it to write an assembler? Something that would take assembly-language program and generate a native (ELF) binary? And the answer is "It isn't hard, it is just tedious". I found some code to generate an ELF binary, and after that assembling simple instructions was pretty simple. I remember from my assembly-language days that the encoding of instructions can be pretty much handled by tables, but I've not yet gone into that. (Specifically there are instructions like "add rax, rcx", and the encoding specifies the source/destination registers - with different forms for various sized immediates.) Anyway I hacked up a simple assembler, it can compile a.out from this input:

.hello   DB "Hello, world\n"
.goodbye DB "Goodbye, world\n"
        mov rdx, 13        ;; write this many characters
        mov rcx, hello     ;; starting at the string
        mov rbx, 1         ;; output is STDOUT
        mov rax, 4         ;; sys_write
        int 0x80           ;; syscall
        mov rdx, 15        ;; write this many characters
        mov rcx, goodbye   ;; starting at the string
        mov rax, 4         ;; sys_write
        mov rbx, 1         ;; output is STDOUT
        int 0x80           ;; syscall
        xor rbx, rbx       ;; exit-code is 0
        xor rax, rax       ;; syscall will be 1 - so set to xero, then increase
        inc rax            ;;
        int 0x80           ;; syscall
The obvious omission is support for "JMP", "JMP_NZ", etc. That's painful because jumps are encoded with relative offsets. For the moment if you want to jump:
        push foo     ; "jmp foo" - indirectly.
        ret
:bar
        nop          ; Nothing happens
        mov rbx,33   ; first syscall argument: exit code
        mov rax,1    ; system call number (sys_exit)
        int 0x80     ; call kernel
:foo
        push bar     ; "jmp bar" - indirectly.
        ret
I'll update to add some more instructions, and see if I can use it to handle the output I generate from a couple of other tools. If so that's a win, if not then it was a fun learning experience:

Julian Andres Klode: Google Pixel 4a: Initial Impressions

Yesterday I got a fresh new Pixel 4a, to replace my dying OnePlus 6. The OnePlus had developed some faults over time: It repeatedly loses connection to the AP and the network, and it got a bunch of scratches and scuffs from falling on various surfaces without any protection over the past year.

Why get a Pixel? Camera: OnePlus focuses on stuffing as many sensors as it can into a phone, rather than a good main sensor, resulting in pictures that are mediocre blurry messes - the dreaded oil painting effect. Pixel have some of the best camera in the smartphone world. Sure, other hardware is far more capable, but the Pixels manage consistent results, so you need to take less pictures because they don t come out blurry half the time, and the post processing is so good that the pictures you get are just great. Other phones can shoot better pictures, sure - on a tripod. Security updates: Pixels provide 3 years of monthly updates, with security updates being published on the 5th of each month. OnePlus only provides updates every 2 months, and then the updates they do release are almost a month out of date, not counting that they are only 1st-of-month patches, meaning vendor blob updates included in the 5th-of-month updates are even a month older. Given that all my banking runs on the phone, I don t want it to be constantly behind. Feature updates: Of course, Pixels also get Beta Android releases and the newest Android release faster than any other phone, which is advantageous for Android development and being nerdy. Size and weight: OnePlus phones keep getting bigger and bigger. By today s standards, the OnePlus 6 at 6.18" and 177g is a small an lightweight device. Their latest phone, the Nord, has 6.44" and weighs 184g, the OnePlus 8 comes in at 180g with a 6.55" display. This is becoming unwieldy. Eschewing glass and aluminium for plastic, the Pixel 4a comes in at 144g.

First impressions

Accessories The Pixel 4a comes in a small box with a charger, USB-C to USB-C cable, a USB-OTG adapter, sim tray ejector. No pre-installed screen protector or bumper are provided, as we ve grown accustomed to from Chinese manufacturers like OnePlus or Xiaomi. The sim tray ejector has a circular end instead of the standard oval one - I assume so it looks like the o in Google? Google sells you fabric cases for 45 . That seems a bit excessive, although I like that a lot of it is recycled.

Haptics Coming from a 6.18" phablet, the Pixel 4a with its 5.81" feels tiny. In fact, it s so tiny my thumb and my index finger can touch while holding it. Cute! Bezels are a bit bigger, resulting in slightly less screen to body. The bottom chin is probably impracticably small, this was already a problem on the OnePlus 6, but this one is even smaller. Oh well, form over function. The buttons on the side are very loud and clicky. As is the vibration motor. I wonder if this Pixel thinks it s a Model M. It just feels great. The plastic back feels really good, it s that sort of high quality smooth plastic you used to see on those high-end Nokia devices. The finger print reader, is super fast. Setup just takes a few seconds per finger, and it works reliably. Other phones (OnePlus 6, Mi A1/A2) take like half a minute or a minute to set up.

Software The software - stock Android 11 - is fairly similar to OnePlus' OxygenOS. It s a clean experience, without a ton of added bloatware (even OnePlus now ships Facebook out of box, eww). It s cleaner than OxygenOS in some way - there are no duplicate photos apps, for example. On the other hand, it also has quite a bunch of Google stuff I could not care less about like YT Music. To be fair, those are minor noise once all 130 apps were transferred from the old phone. There are various things I miss coming from OnePlus such as off-screen gestures, network transfer rate indicator in quick settings, or a circular battery icon. But the Pixel has an always on display, which is kind of nice. Most of the cool Pixel features, like call screening or live transcriptions are unfortunately not available in Germany. The display is set to display the same amount of content as my 6.18" OnePlus 6 did, so everything is a bit tinier. This usually takes me a week or two to adjust too, and then when I look at the OnePlus again I ll be like Oh the font is huge , but right now, it feels a bit small on the Pixel. You can configure three colour profiles for the Pixel 4a: Natural, Boosted, and Adaptive. I have mine set to adaptive. I d love to see stock Android learn what OnePlus has here: the ability to adjust the colour temperature manually, as I prefer to keep my devices closer to 5500K than 6500K, as I feel it s a bit easier on the eyes. Or well, just give me the ability to load a ICM profile (though, I d need to calibrate the screen then - work!).

Migration experience Restoring the apps from my old phone only restore settings for a few handful out of 130, which is disappointing. I had to spent an hour or two logging in to all the other apps, and I had to fiddle far too long with openScale to get it to take its data over. It s a mystery to me why people do not allow their apps to be backed up, especially something innocent like a weight tracking app. One of my banking apps restored its logins, which I did not really like. KeePass2Android settings were restored as well, but at least the key file was not restored. I did not opt in to restoring my device settings, as I feel that restoring device settings when changing manufactures is bound to mess up some things. For example, I remember people migrating to OnePlus phones and getting their old DND schedule without any way to change it, because OnePlus had hidden the DND stuff. I assume that s the reason some accounts, like my work GSuite account were not migrated (it said it would migrate accounts during setup). I ve setup Bitwarden as my auto-fill service, so I could login into most of my apps and websites using the stored credentials. I found that often that did not work. Like Chrome does autofill fine once, but if I then want to autofill again, I have to kill and restart it, otherwise I don t get the auto-fill menu. Other apps did not allow any auto-fill at all, and only gave me the option to copy and paste. Yikes - auto-fill on Android still needs a lot of work.

Performance It hangs a bit sometimes, but this was likely due to me having set 2 million iterations on my Bitwarden KDF and using Bitwarden a lot, and then opening up all 130 apps to log into them which overwhelmed the phone a bit. Apart from that, it does not feel worse than the OnePlus 6 which was to be expected, given that the benchmarks only show a slight loss in performance. Photos do take a few seconds to process after taking them, which is annoying, but understandable given how much Google relies on computation to provide decent pictures.

Audio The Pixel has dual speakers, with the earpiece delivering a tiny sound and the bottom firing speaker doing most of the work. Still, it s better than just having the bottom firing speaker, as it does provide a more immersive experience. Bass makes this thing vibrate a lot. It does not feel like a resonance sort of thing, but you can feel the bass in your hands. I ve never had this before, and it will take some time getting used to.

Final thoughts This is a boring phone. There s no wow factor at all. It s neither huge, nor does it have high-res 48 or 64 MP cameras, nor does it have a ton of sensors. But everything it does, it does well. It does not pretend to be a flagship like its competition, it doesn t want to wow you, it just wants to be the perfect phone for you. The build is solid, the buttons make you think of a Model M, the camera is one of the best in any smartphone, and you of course get the latest updates before anyone else. It does not feel like a only 350 phone, but yet it is. 128GB storage is plenty, 1080p resolution is plenty, 12.2MP is you guessed it, plenty. The same applies to the other two Pixel phones - the 4a 5G and 5. Neither are particularly exciting phones, and I personally find it hard to justify spending 620 on the Pixel 5 when the Pixel 4a does job for me, but the 4a 5G might appeal to users looking for larger phones. As to 5G, I wouldn t get much use out of it, seeing as its not available anywhere I am. Because I m on Vodafone. If you have a Telekom contract or live outside of Germany, you might just have good 5G coverage already and it might make sense to get a 5G phone rather than sticking to the budget choice.

Outlook The big question for me is whether I ll be able to adjust to the smaller display. I now have a tablet, so I m less often using the phone (which my hands thank me for), which means that a smaller phone is probably a good call. Oh while we re talking about calls - I only have a data-only SIM in it, so I could not test calling. I m transferring to a new phone contract this month, and I ll give it a go then. This will be the first time I get VoLTE and WiFi calling, although it is Vodafone, so quality might just be worse than Telekom on 2G, who knows. A big shoutout to congstar for letting me cancel with a simple button click, and to @vodafoneservice on twitter for quickly setting up my benefits of additional 5GB per month and 10 discount for being an existing cable customer. I m also looking forward to playing around with the camera (especially night sight), and eSIM. And I m getting a case from China, which was handed over to the Airline on Sep 17 according to Aliexpress, so I guess it should arrive in the next weeks. Oh, and screen protector is not here yet, so I can t really judge the screen quality much, as I still have the factory protection film on it, and that s just a blurry mess - but good enough for setting it up. Please Google, pre-apply a screen protector on future phones and include a simple bumper case. I might report back in two weeks when I have spent some more time with the device.

Ritesh Raj Sarraf: First Telescope

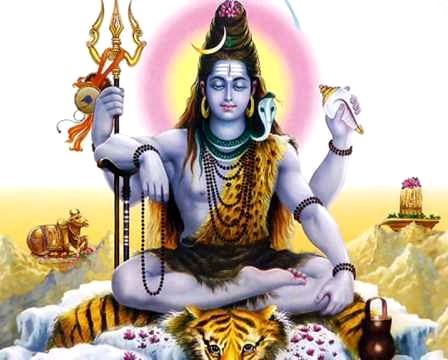
Curiosity I guess this would be common to most of us. While I grew up, right from the childhood itself, the sky was always an intriguing view. The Stars, the Moon, the Eclipses; were all fascinating. As a child, in my region, religion and culture; the mythology also built up stories around it. Lunar Eclipses have a story of its own. During Solar Eclipses, parents still insist that we do not go out. And to be done with the food eating before/after the eclipse. Then there s the Hindu Astrology part, which claims its own theories and drags in mythology along. For example, you ll still find the Hindu Astrology making recommendations to follow certain practices with the planets, to get auspicious personal results. As far as I know, other religions too have similar beliefs about the planets. As a child, we are told the Moon to be addressed as an Uncle ( ). There s also a rhyme around it, that many of us must have heard. And if you look at our god, Lord Mahadev, he s got a crescent on his head
Lord Mahadev
Lord Mahadev

Reality Fast-forward to today, as I grew, so did some of my understanding. It is fascinating how mankind has achieved so much understanding of our surrounding. You could go through the documentaries on Mars Exploration, for example; to see how the rovers are providing invaluable data. As a mere individual, there s a limit to what one can achieve. But the questions flow in free.
  • Is there life beyond us
  • What s out there in the sky
  • Why is all this the way it is

Hobby The very first step, for me, for every such curiosity, has been to do the ground work, with the resources I have. To study on the subject. I have done this all my life. For example, I started into the Software domain as: A curiosity => A Hobby => A profession Same was the case with some of the other hobbies, equally difficult as Astronomy, that I developed a liking for. Just did the ground work, studied on those topics and then applied the knowledge to further improve it and build up some experience. And star gazing came in no different. As a complete noob, had to start with the A B C on the subject of Astronomy. Familiarize myself with the usual terms. As so on PS: Do keep in mind that not all hobbies have a successful end. For example, I always craved to be good with graphic designing, image processing and the likes, where I ve always failed. Never was able to keep myself motivated enough. Similar was my experience when trying to learn playing a musical instrument. Just didn t work out for me, then. There s also a phase in it, where you fail and then learn from the failures and proceed further, and then eventually succeed. But we all like to talk about the successes. :-)

Astronomy So far, my impression has been that this topic/domain will not suit most of the people. While the initial attraction may be strong, given the complexity and perseverance that Astronomy requires, most people would lose interest in it very soon. Then there s the realization factor. If one goes with an expectation to get quick results, they may get disappointed. It isn t like a point and shoot device that d give you results on the spot. There s also the expectation side of things. If you are a person more accustomed to taking pretty selfies, which always come right because the phone manufacturer does heavy processing on the images to ensure that you get to see the pretty fake self, for the most of the times; then star gazing with telescopes could be a frustrating experience altogether. What you get to see in the images on the internet will be very different than what you d be able to see with your eyes and your basic telescope. There s also the cost aspect. The more powerful (and expensive) your telescope, the better your view. And all things aside, it still may get you lose interest, after you ve done all the ground work and spent a good chunk of money on it. Simply because the object you are gazing at is more a still image, which can quickly get boring for many. On the other hand, if none of the things obstruct, then the domain of Astronomy can be quite fascinating. It is a continuous learning domain (reminds me of CI in our software field these days). It is just the beginning for us here, and we hope to have a lasting experience in it.

The Internet I have been indebted to the internet right from the beginning. The internet is what helped me be able to achieve all I wanted. It is one field with no boundaries. If there is a will, there is a way; and often times, the internet is the way.
  • I learnt computers over the internet.
  • Learnt more about gardening and plants over the internet
  • Learnt more about fish care-taking over the internet
And many many more things. Some of the communities over the internet are a great way to participation. They bridge the age gap, the regional gap and many more. For my Astronomy need, I was glad to see so many active communities, with great participants, on the internet.

Telescope While there are multiple options to start star gazing, I chose to start with a telescope. But as someone completely new to this domain, there was a long way to go. And to add to that, the real life: work + family I spent a good 12+ months reading up on the different types of telescopes, what they are, their differences, their costs, their practical availability etc. The good thing is that the market has offerings for everything. From a very basic binocular to a fully automatic Maksutov-Cassegrain scope. It all would depend on your budget.

Automatic vs Manual To make it easy for the users, the market has multiple options in the offering. One could opt-in for a cheap, basic and manually operated telescope; which would require the user to do a lot of ground study. On the other hand, users also have the option of automatic telescopes which do the hard work of locating and tracking the planetary objects. Either option aside, the end result of how much you ll be able to observe the sky, still depends on many many more factors: Enthusiasm over time, Light Pollution, Clear Skies, Timing etc. PS: The planetary objects move at a steady pace. Objects you lock into your view now will be gone out of the FOV in just a matter of minutes.

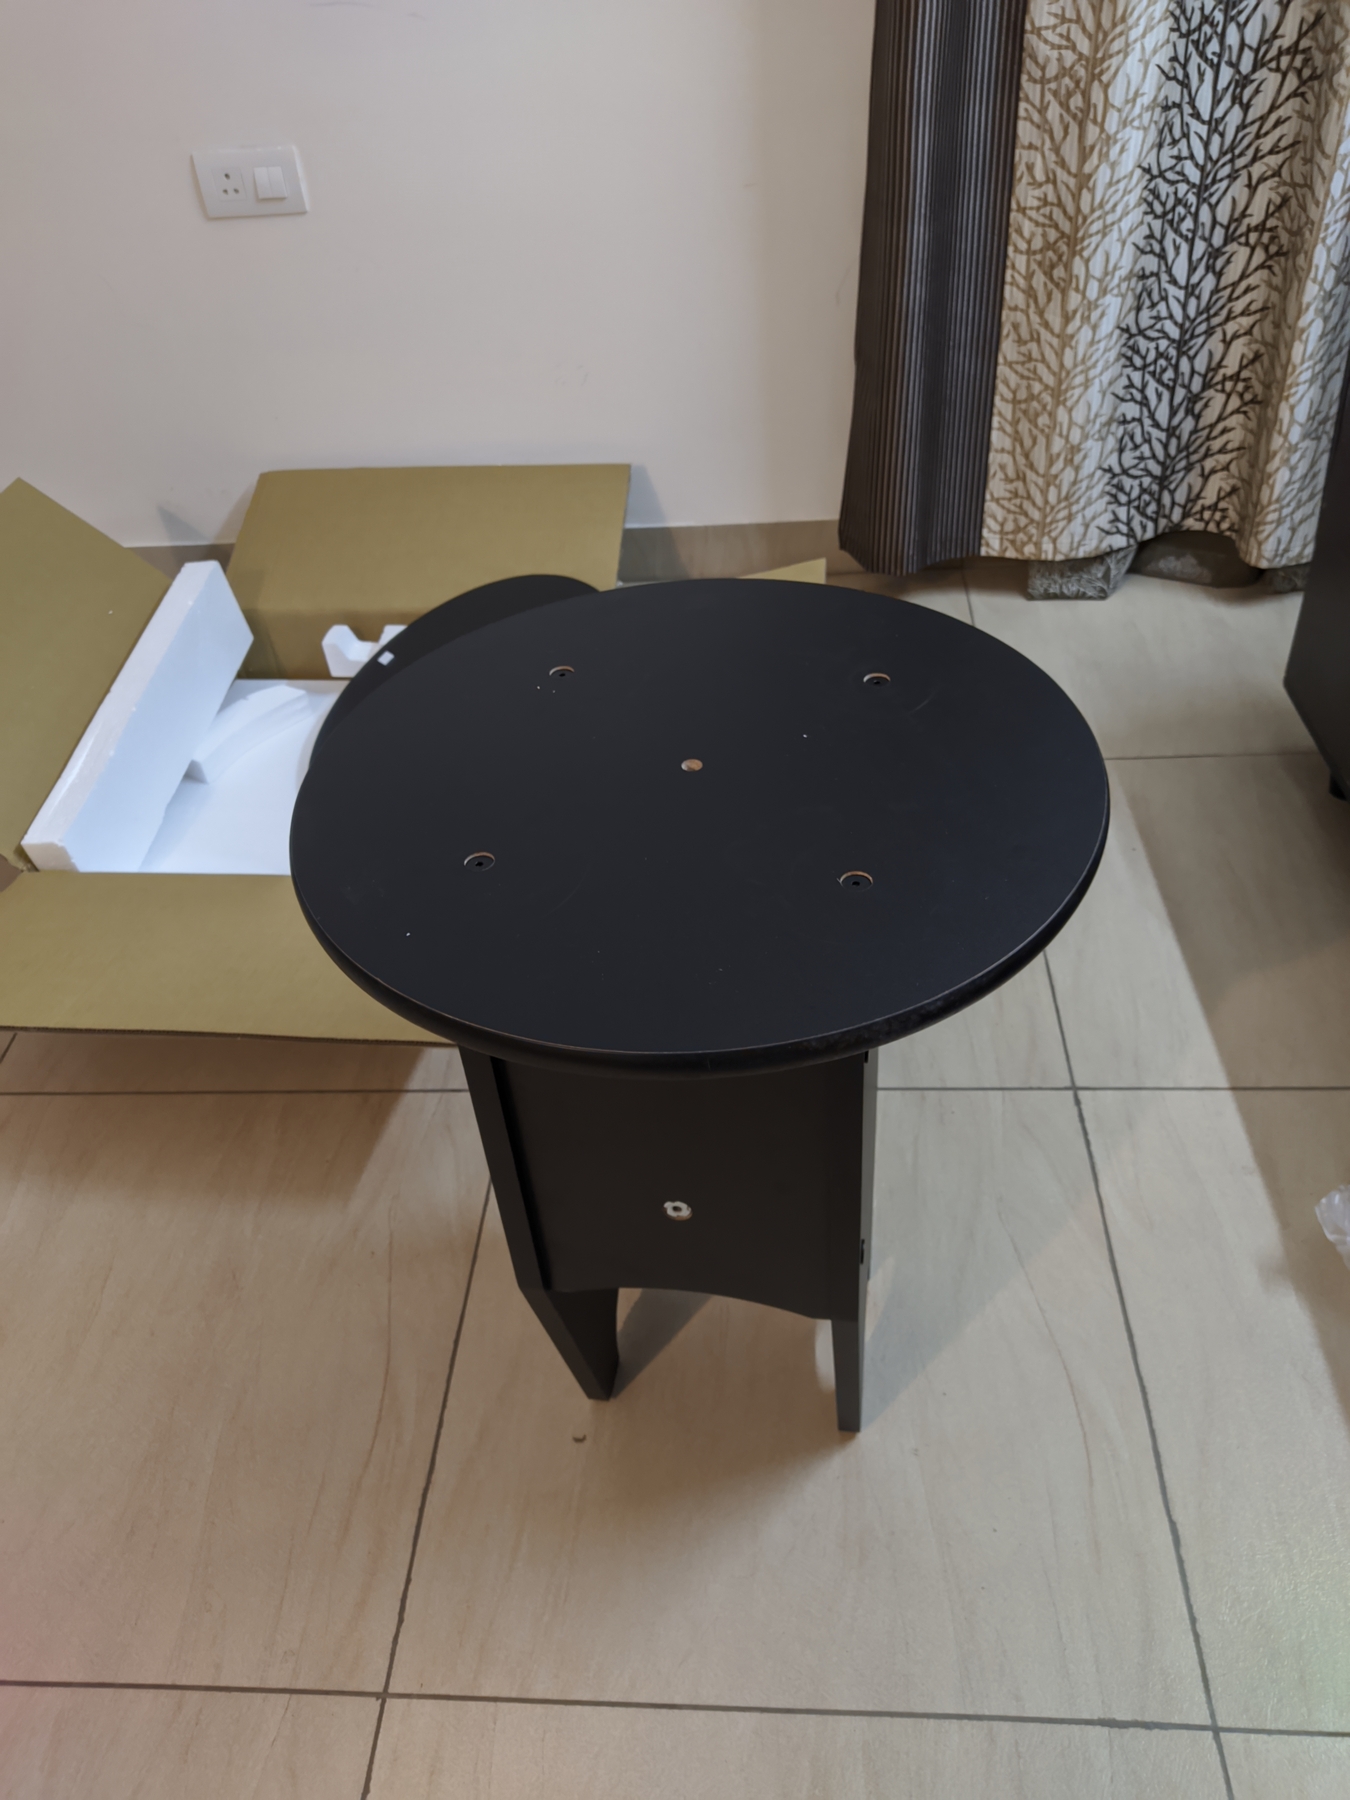
My Telescope After spending so much of the time reading up on types of telescopes, my conclusion was that a scope with high aperture and focal length was the way to go forward. This made me shorten the list to Dobsonians. But the Dobsonians aren t a very cheap telescope, whether manual or automatic. My final decision made me acquire a 6" Dobsonian Telescope. It is a Newtonian Reflecting Telescope with a 1200mm focal length and 150mm diameter. Another thing about this subject is that most of the stuff you do in Astronomy; right from the telescope selection, to installation, to star gazing; most of it is DIY, so your mileage may vary with the end result and experience. For me, installation wasn t very difficult. I was able to assemble the base Dobsonian mount and the scope in around 2 hours. But the installation manual, I had been provided with, was very brief. I ended up with one module in the mount wrongly fit, which I was able to fix later, with the help of online forums.
Dobsonian Mount
Dobsonian Mount
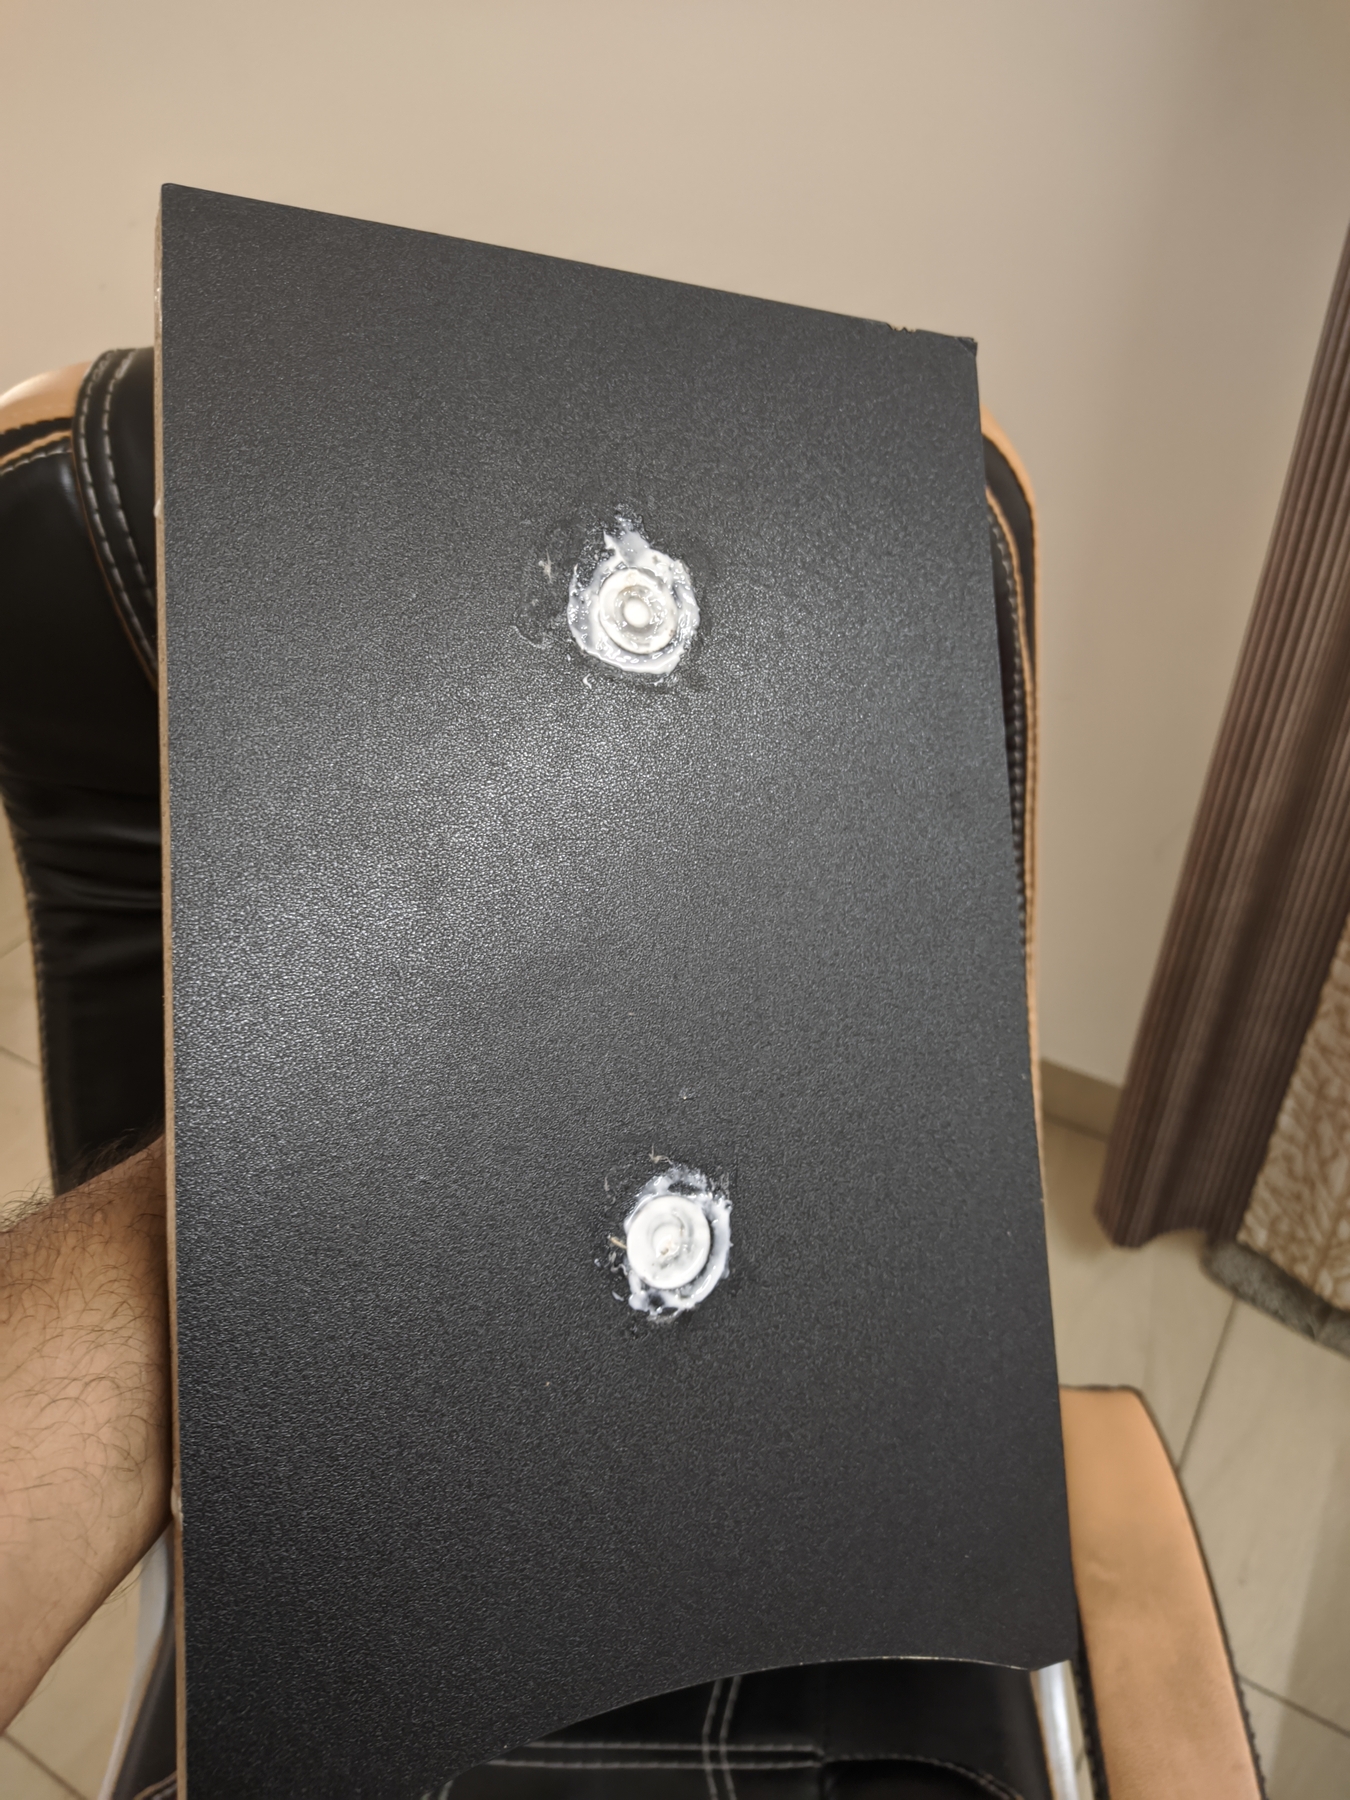
In this image you can see that the side facing out, where the handle will go, is wrong. If fit this way, the handle will not withstand any weight at all.
Correct Panel Side
Correct Panel Side
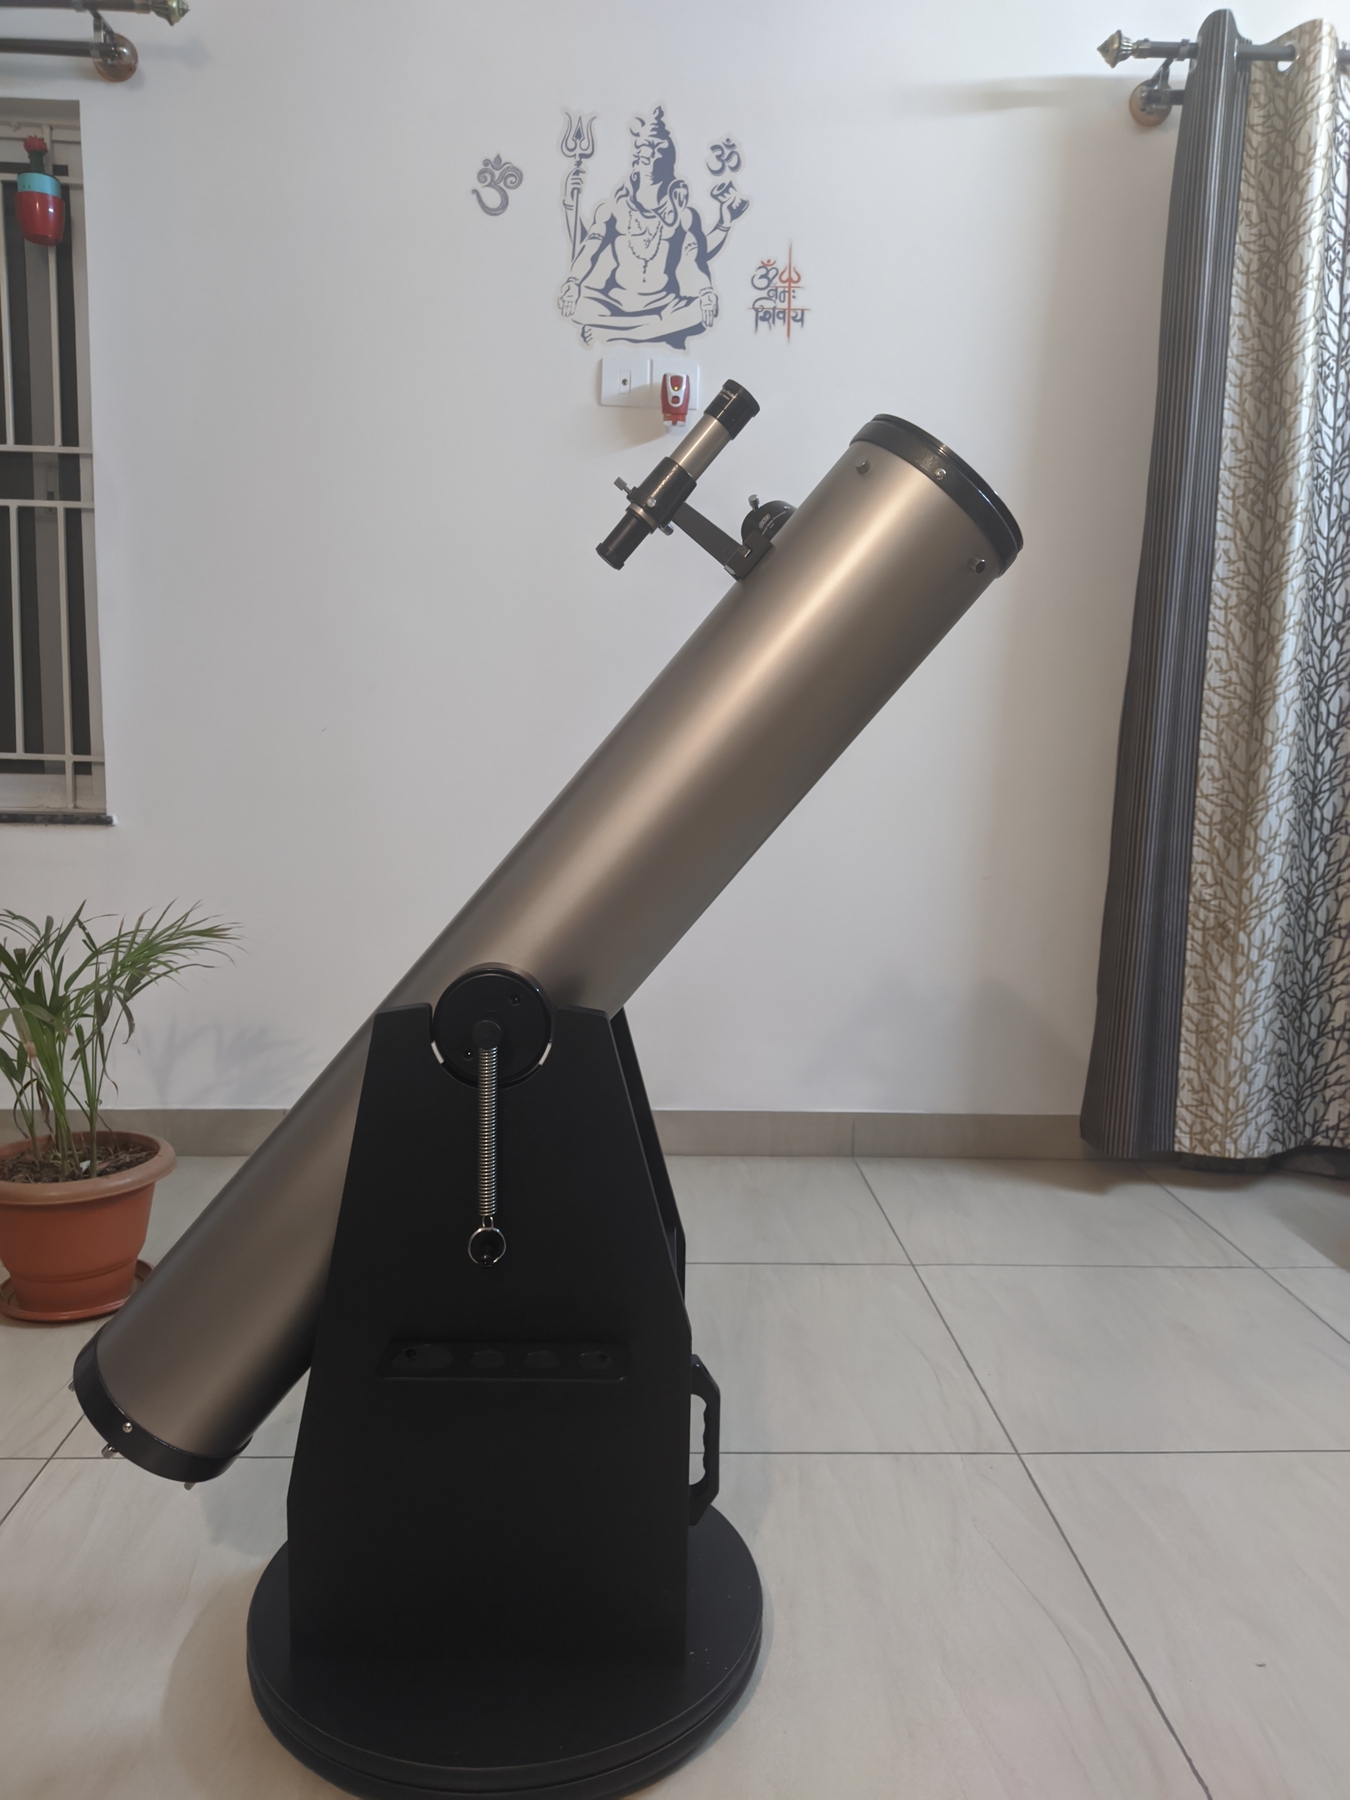
The right fix of the handle base board. In this image, the handle is on the other side that I m holding. Because the initial fit put in some damage to the engineered wood, I fixed it up by sealing with some adhesive. With that, this is what my final telescope looks like.
Final Telescope
Final Telescope

Clear Skies While the telescope was ready, the skies were not. For almost next 10 days, we had no clear skies at all. All I could do was wait. Wait so much that I had forgotten to check on the skies. Luckily, my wife noticed clear skies this week for a single day. Clear enough that we could try out our telescope for the very first time.
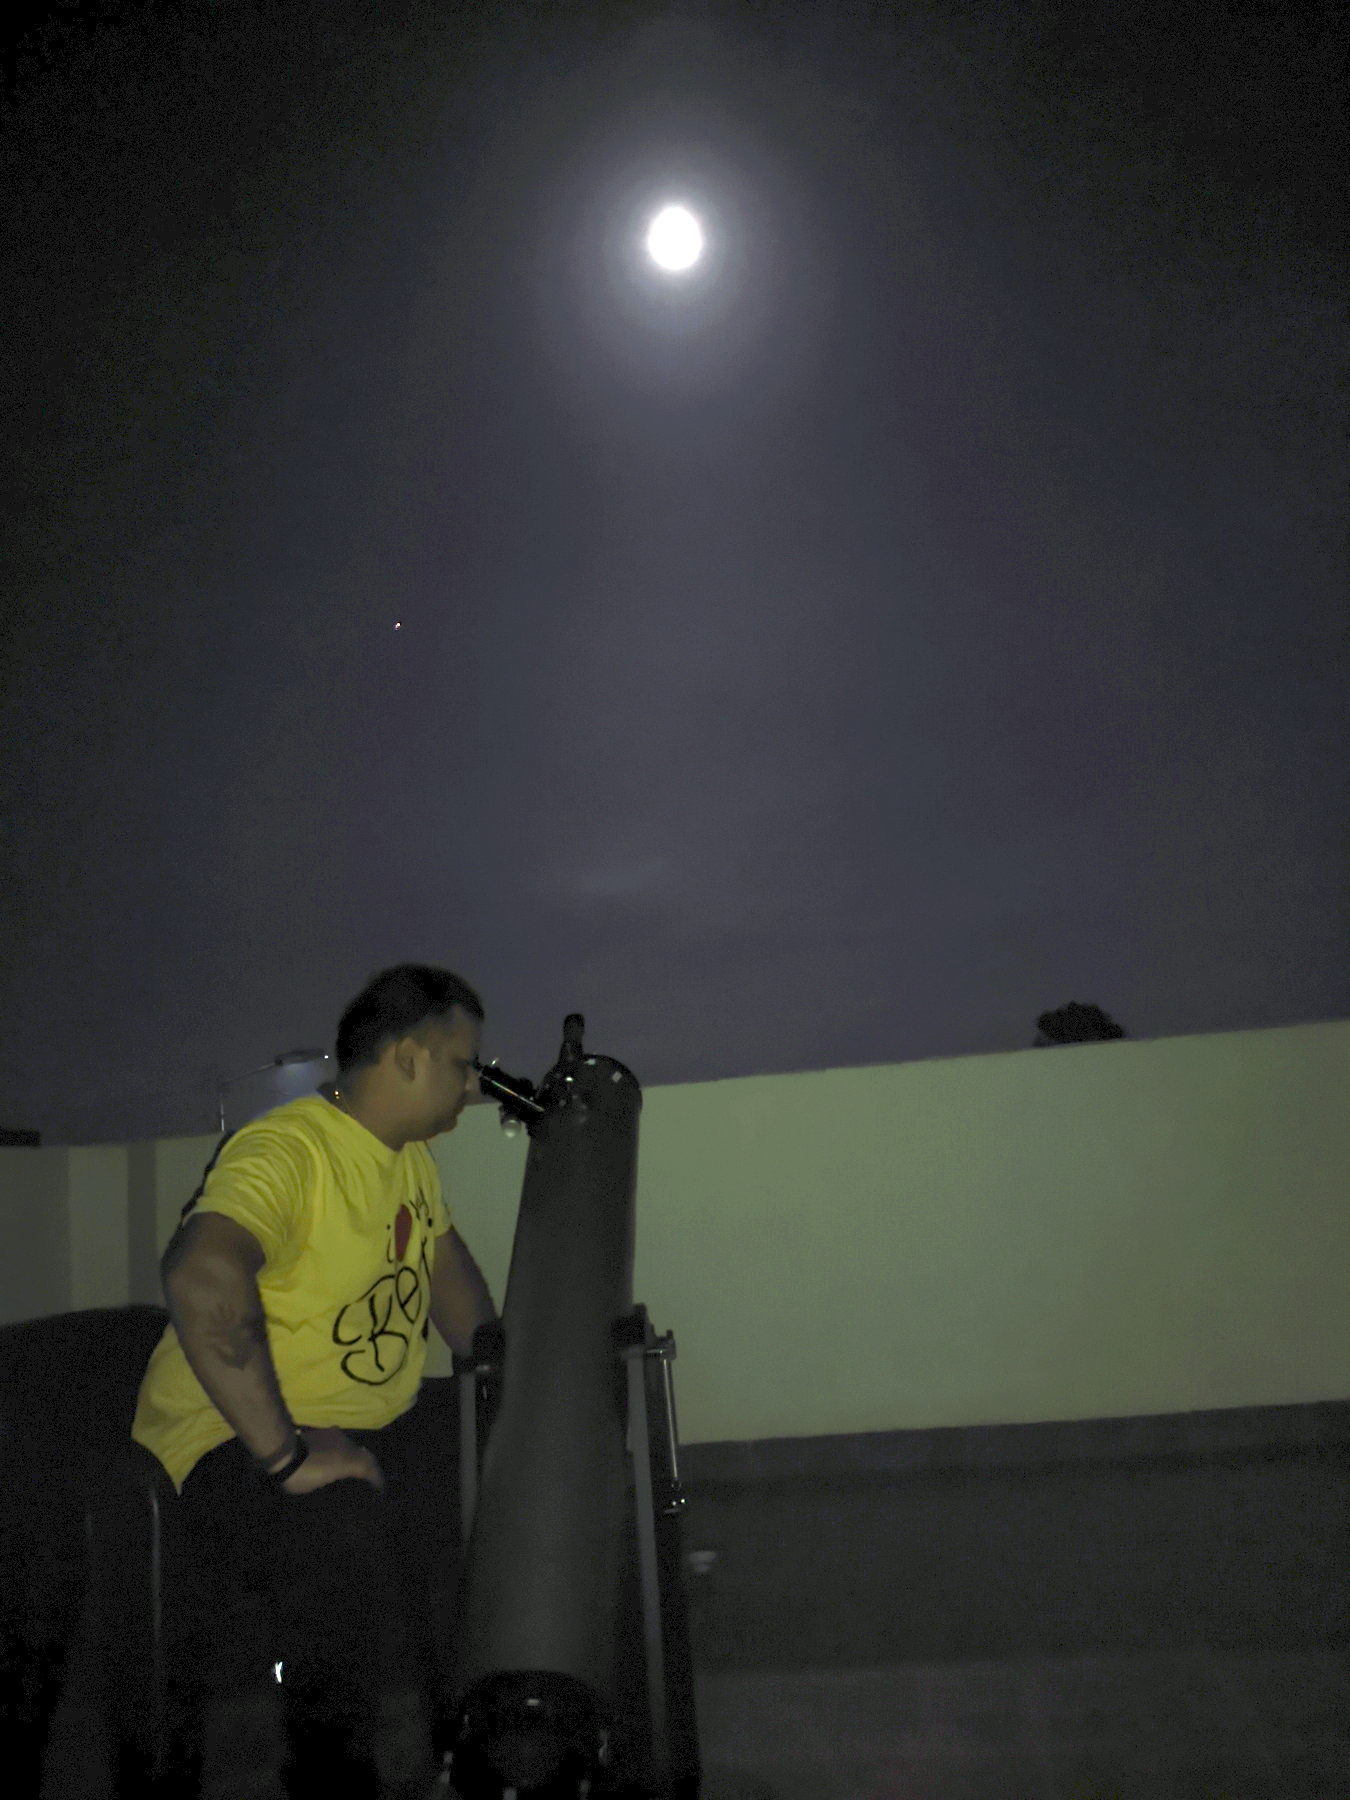
Me posing for a shot

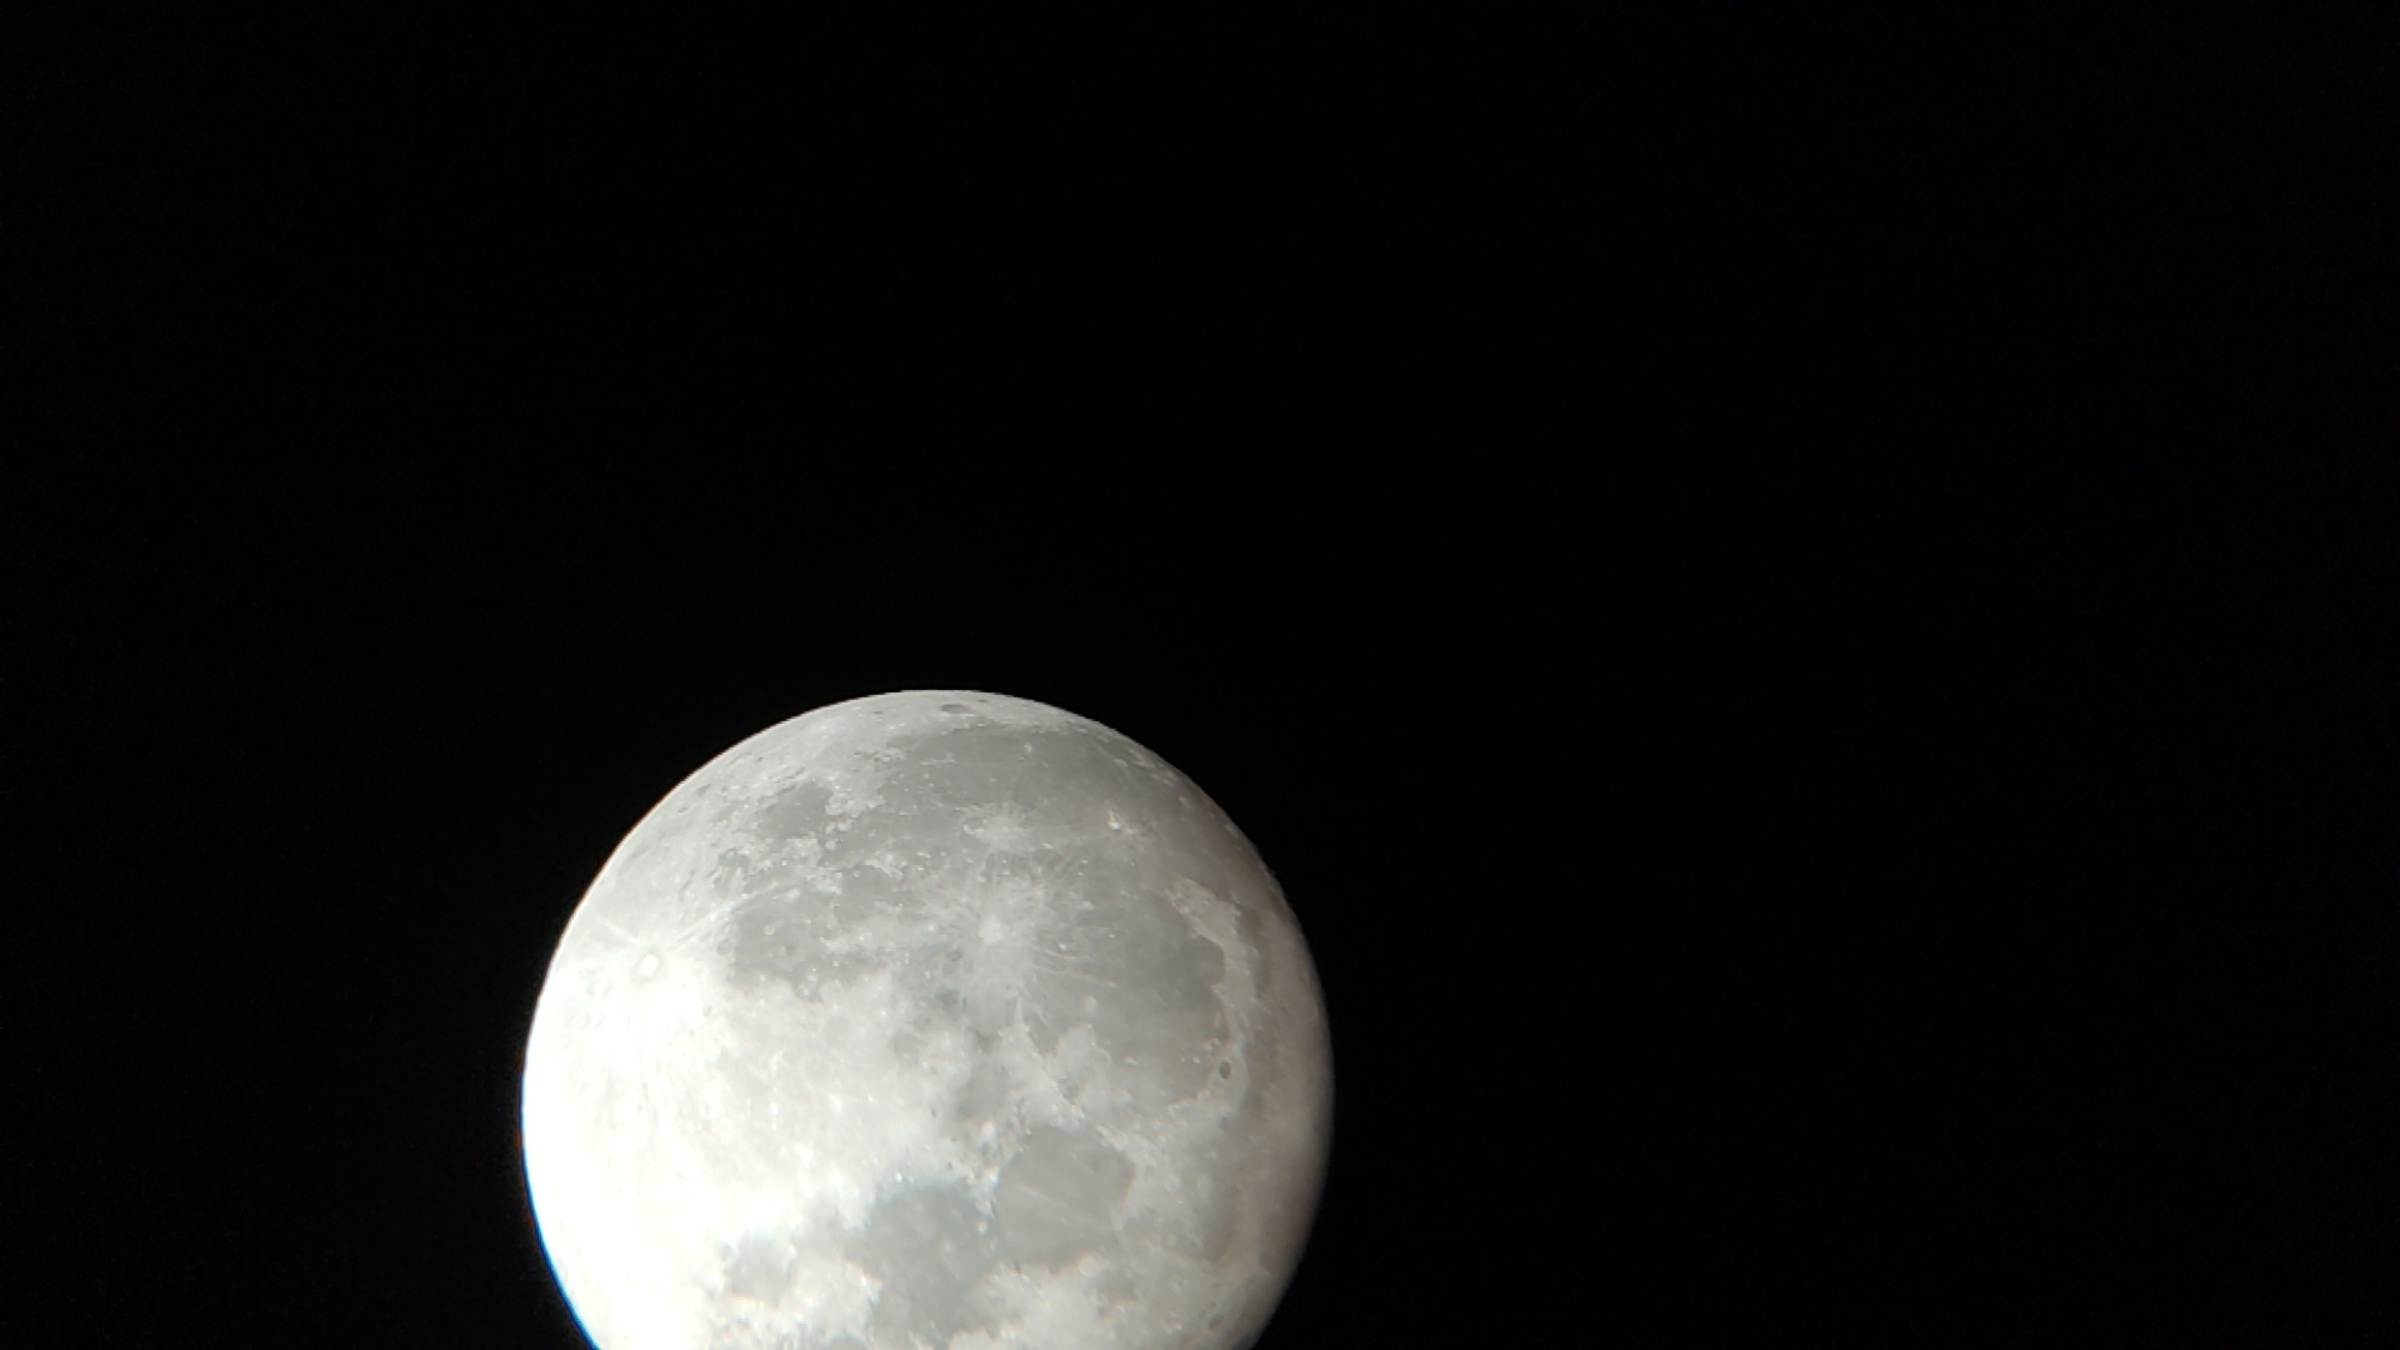
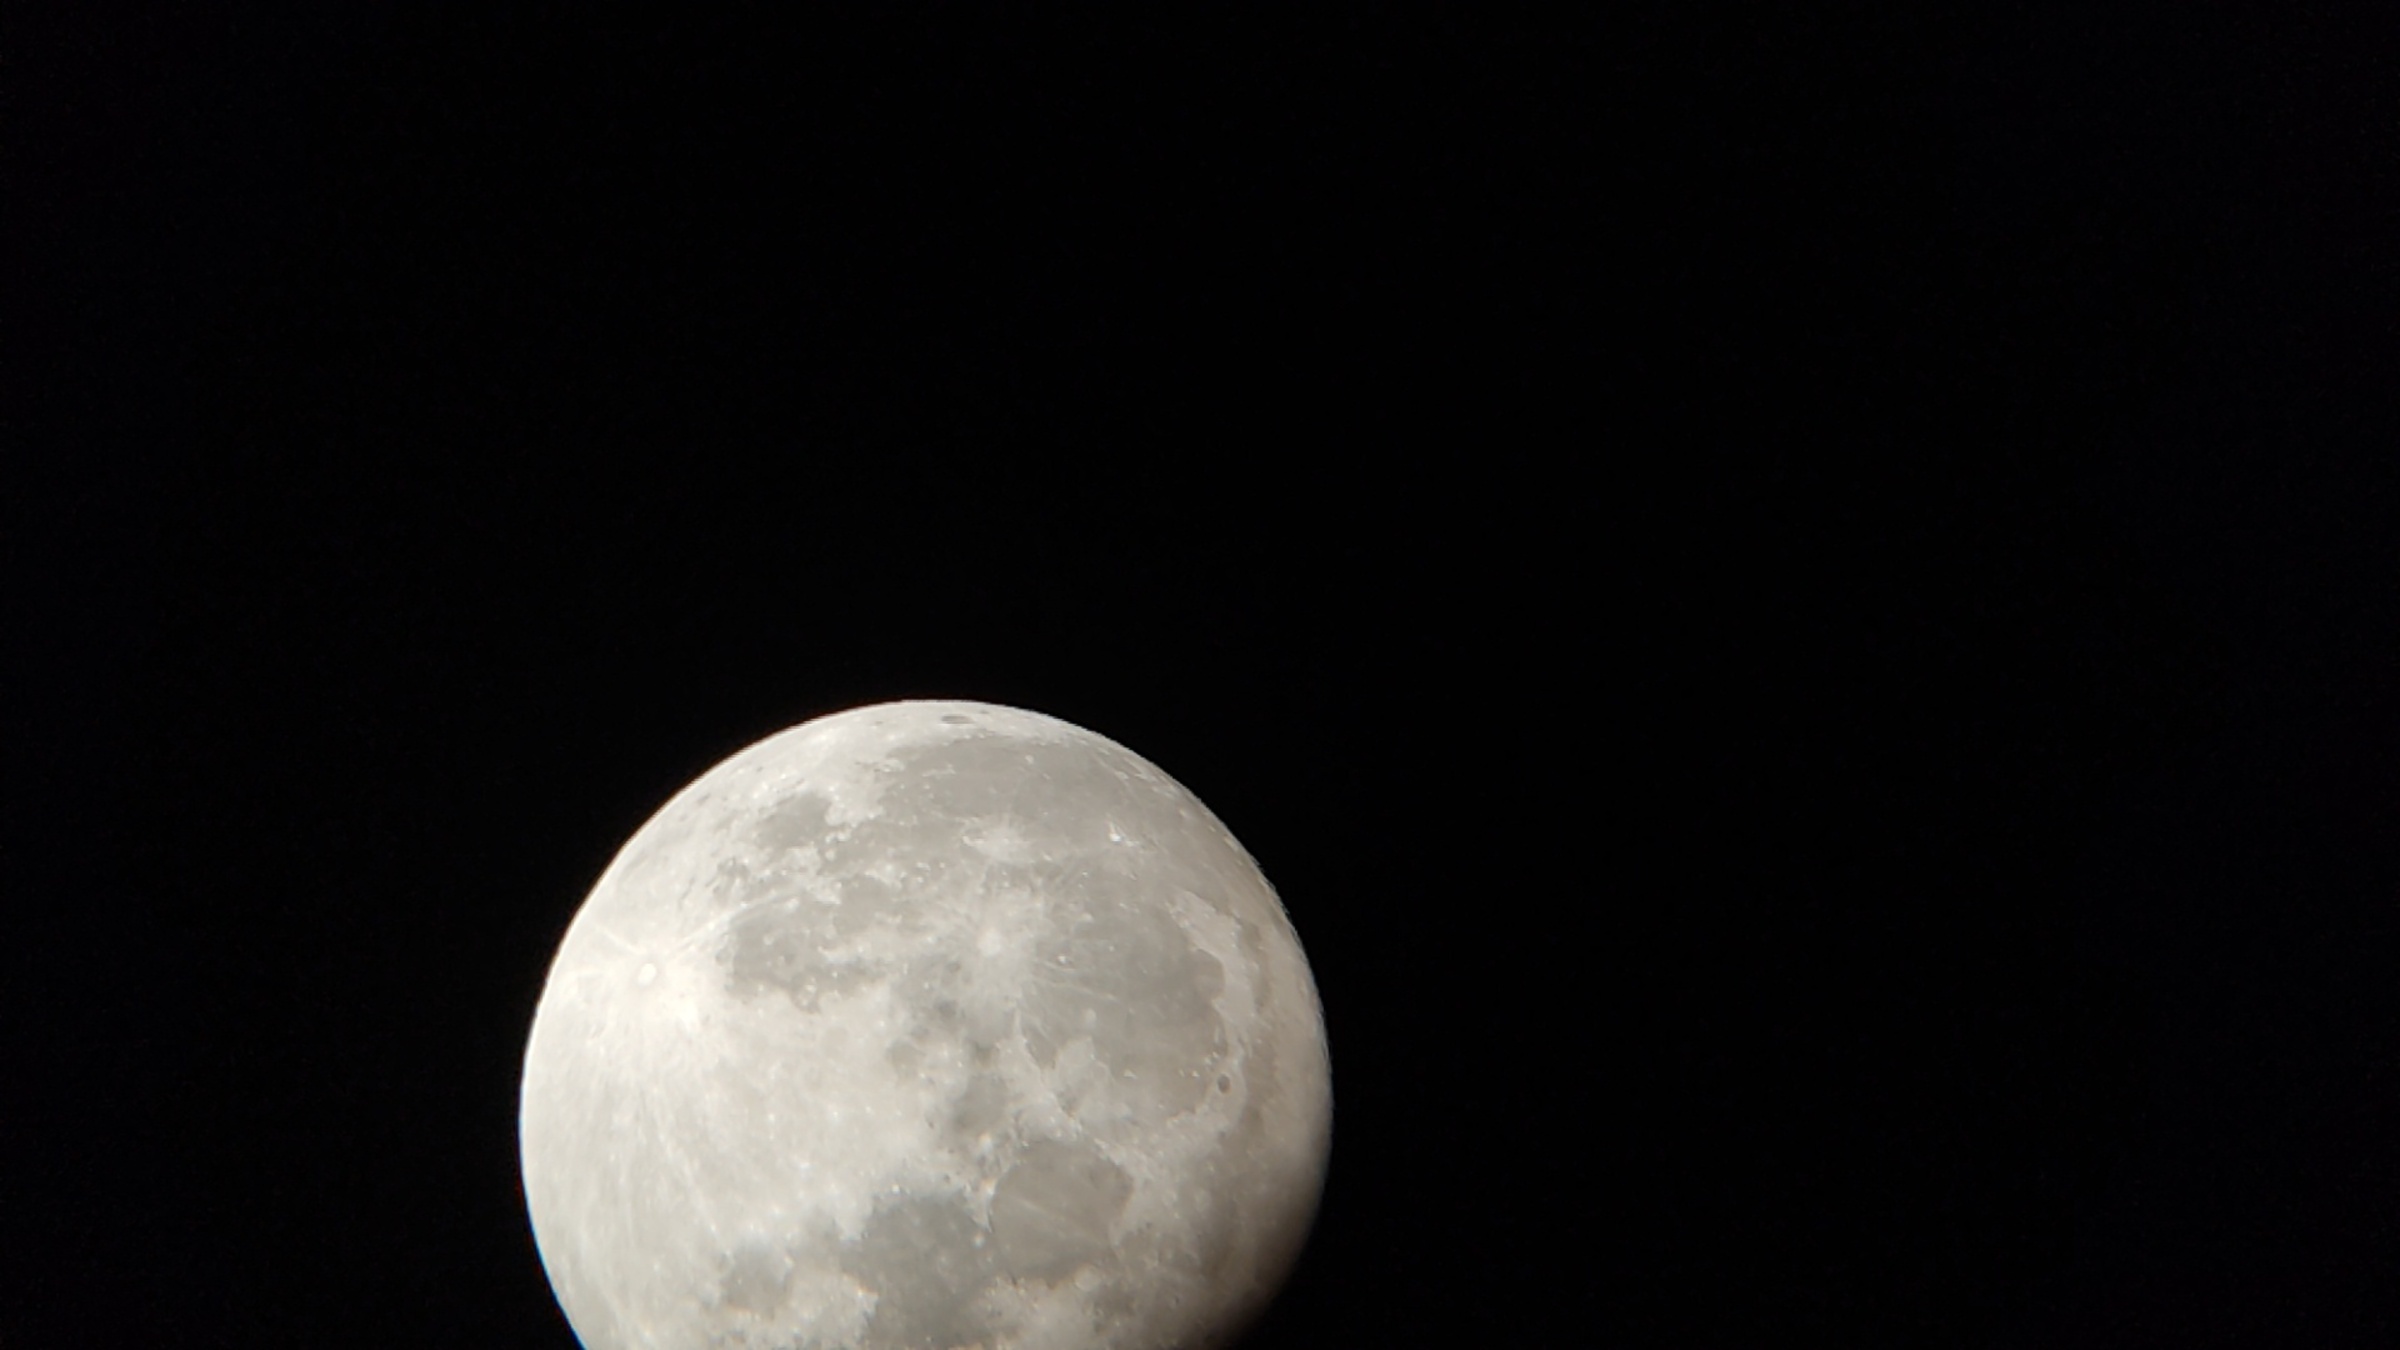
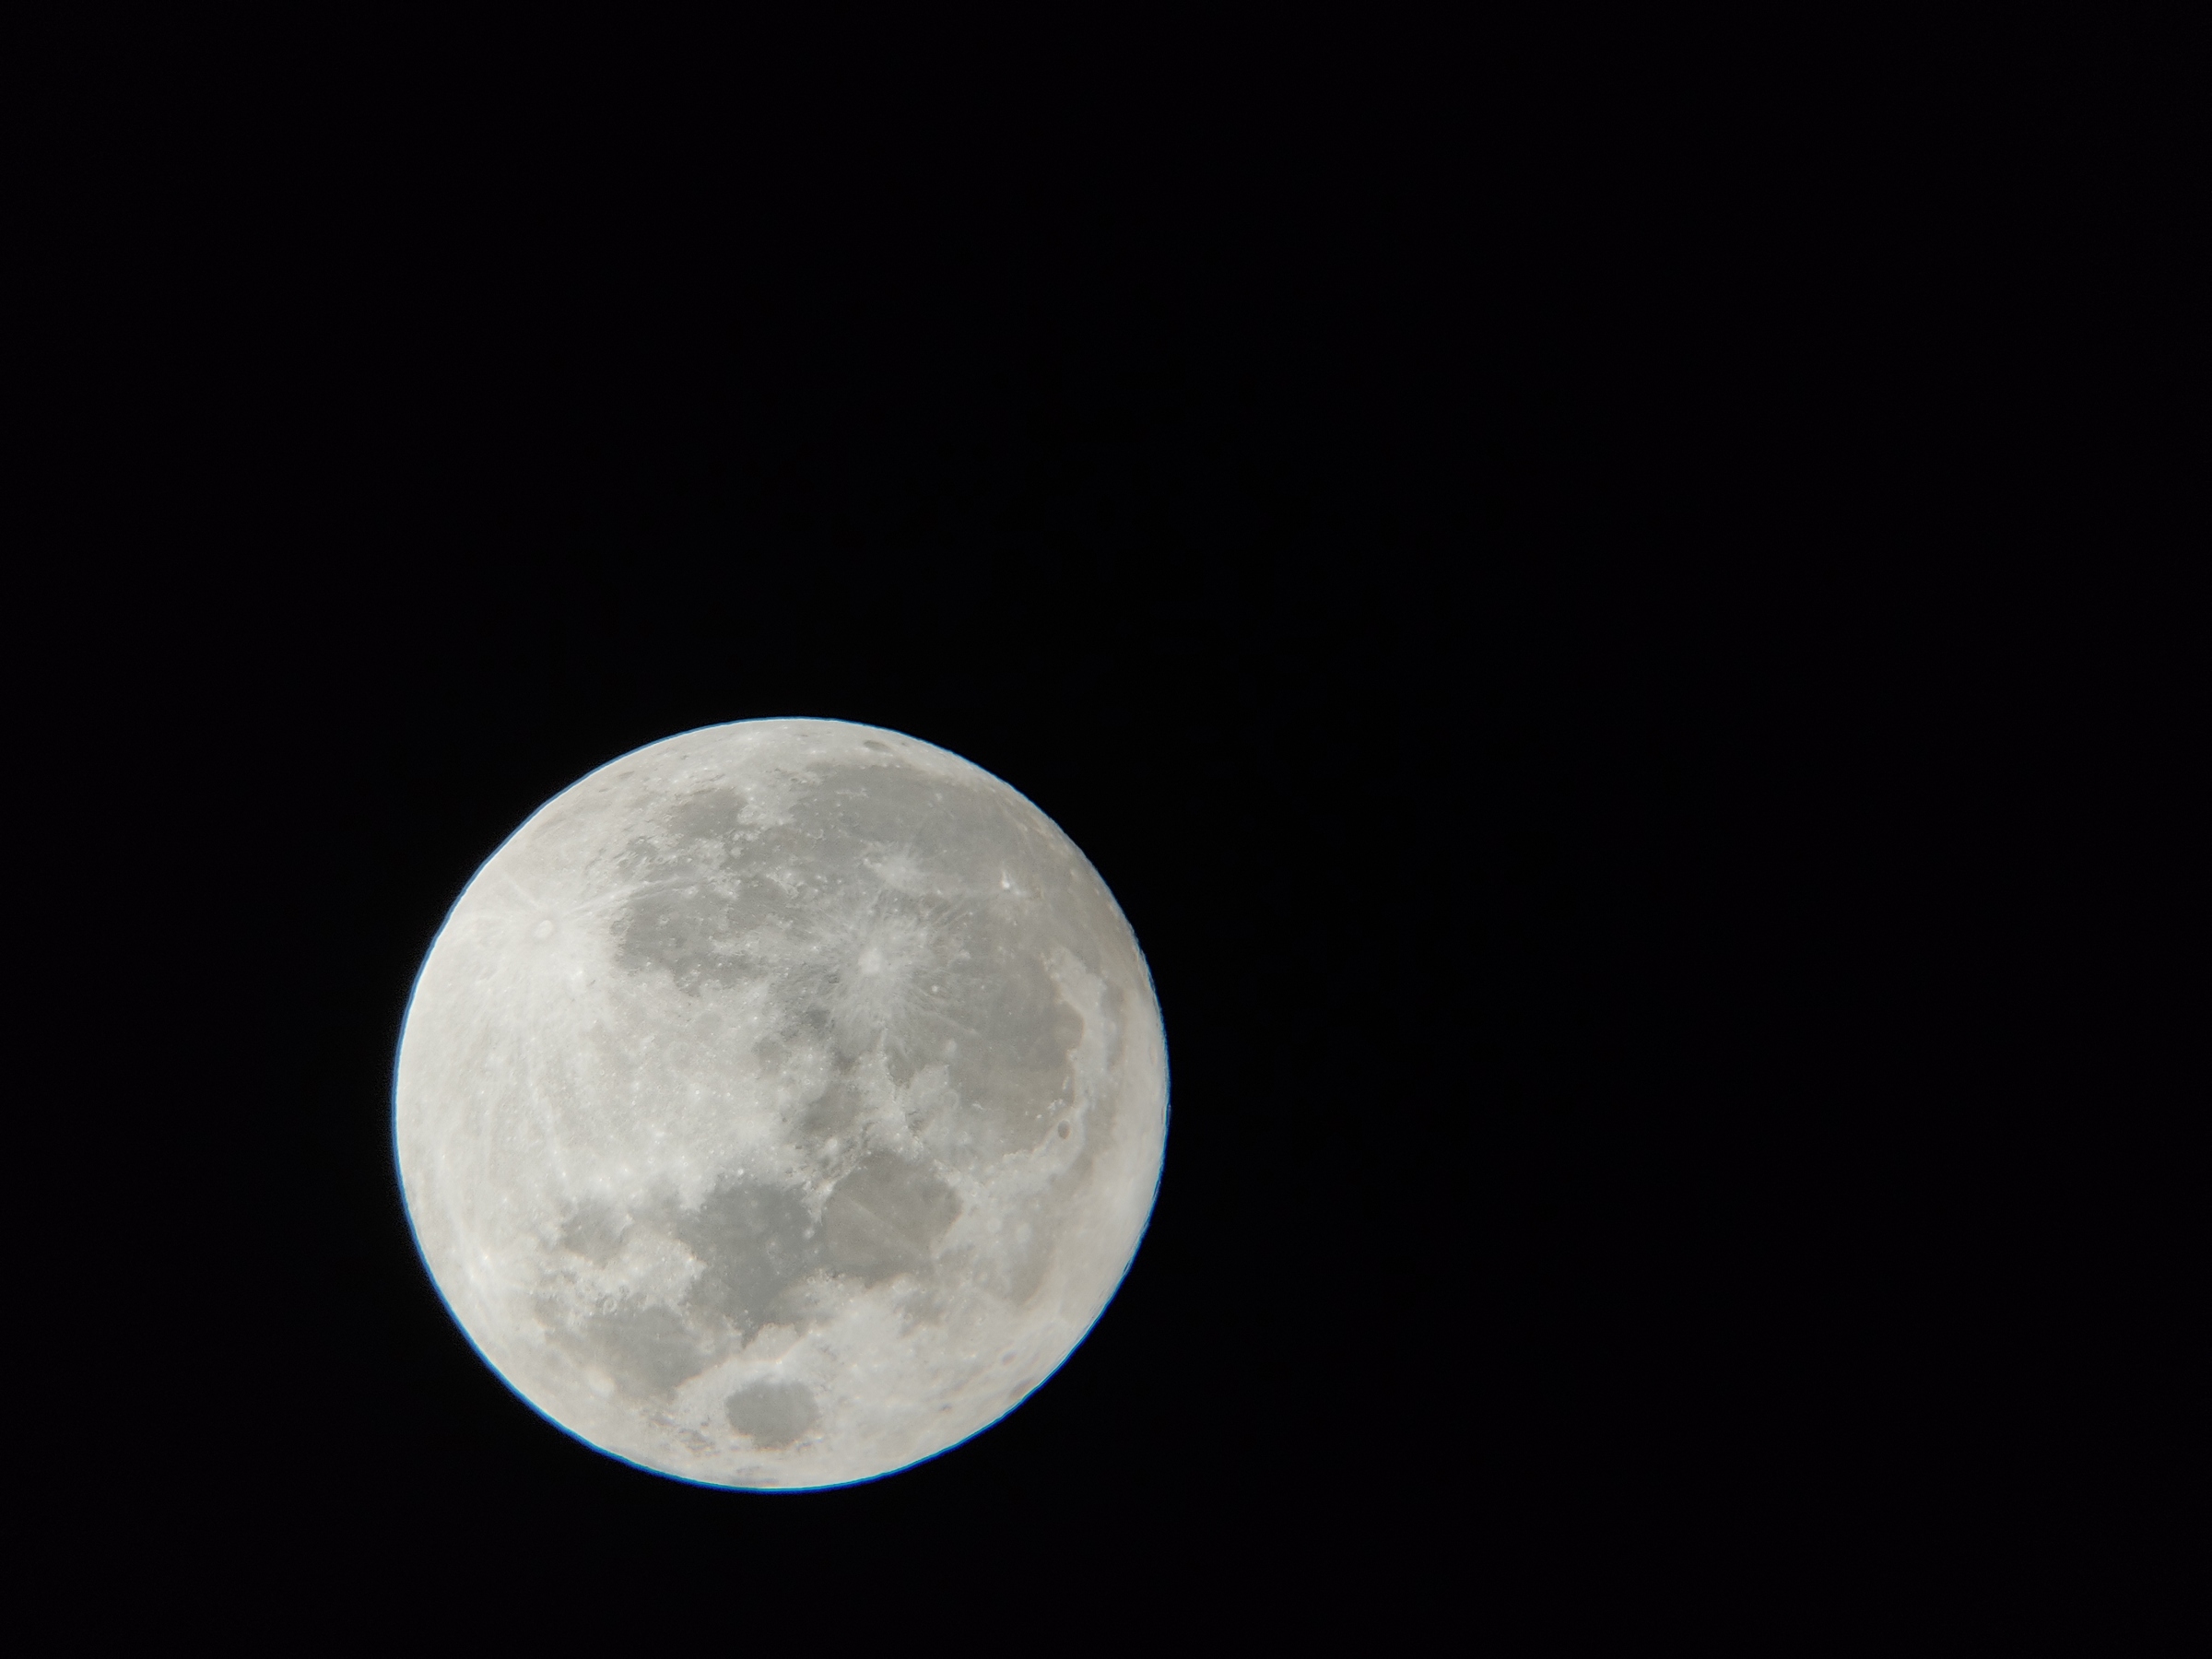
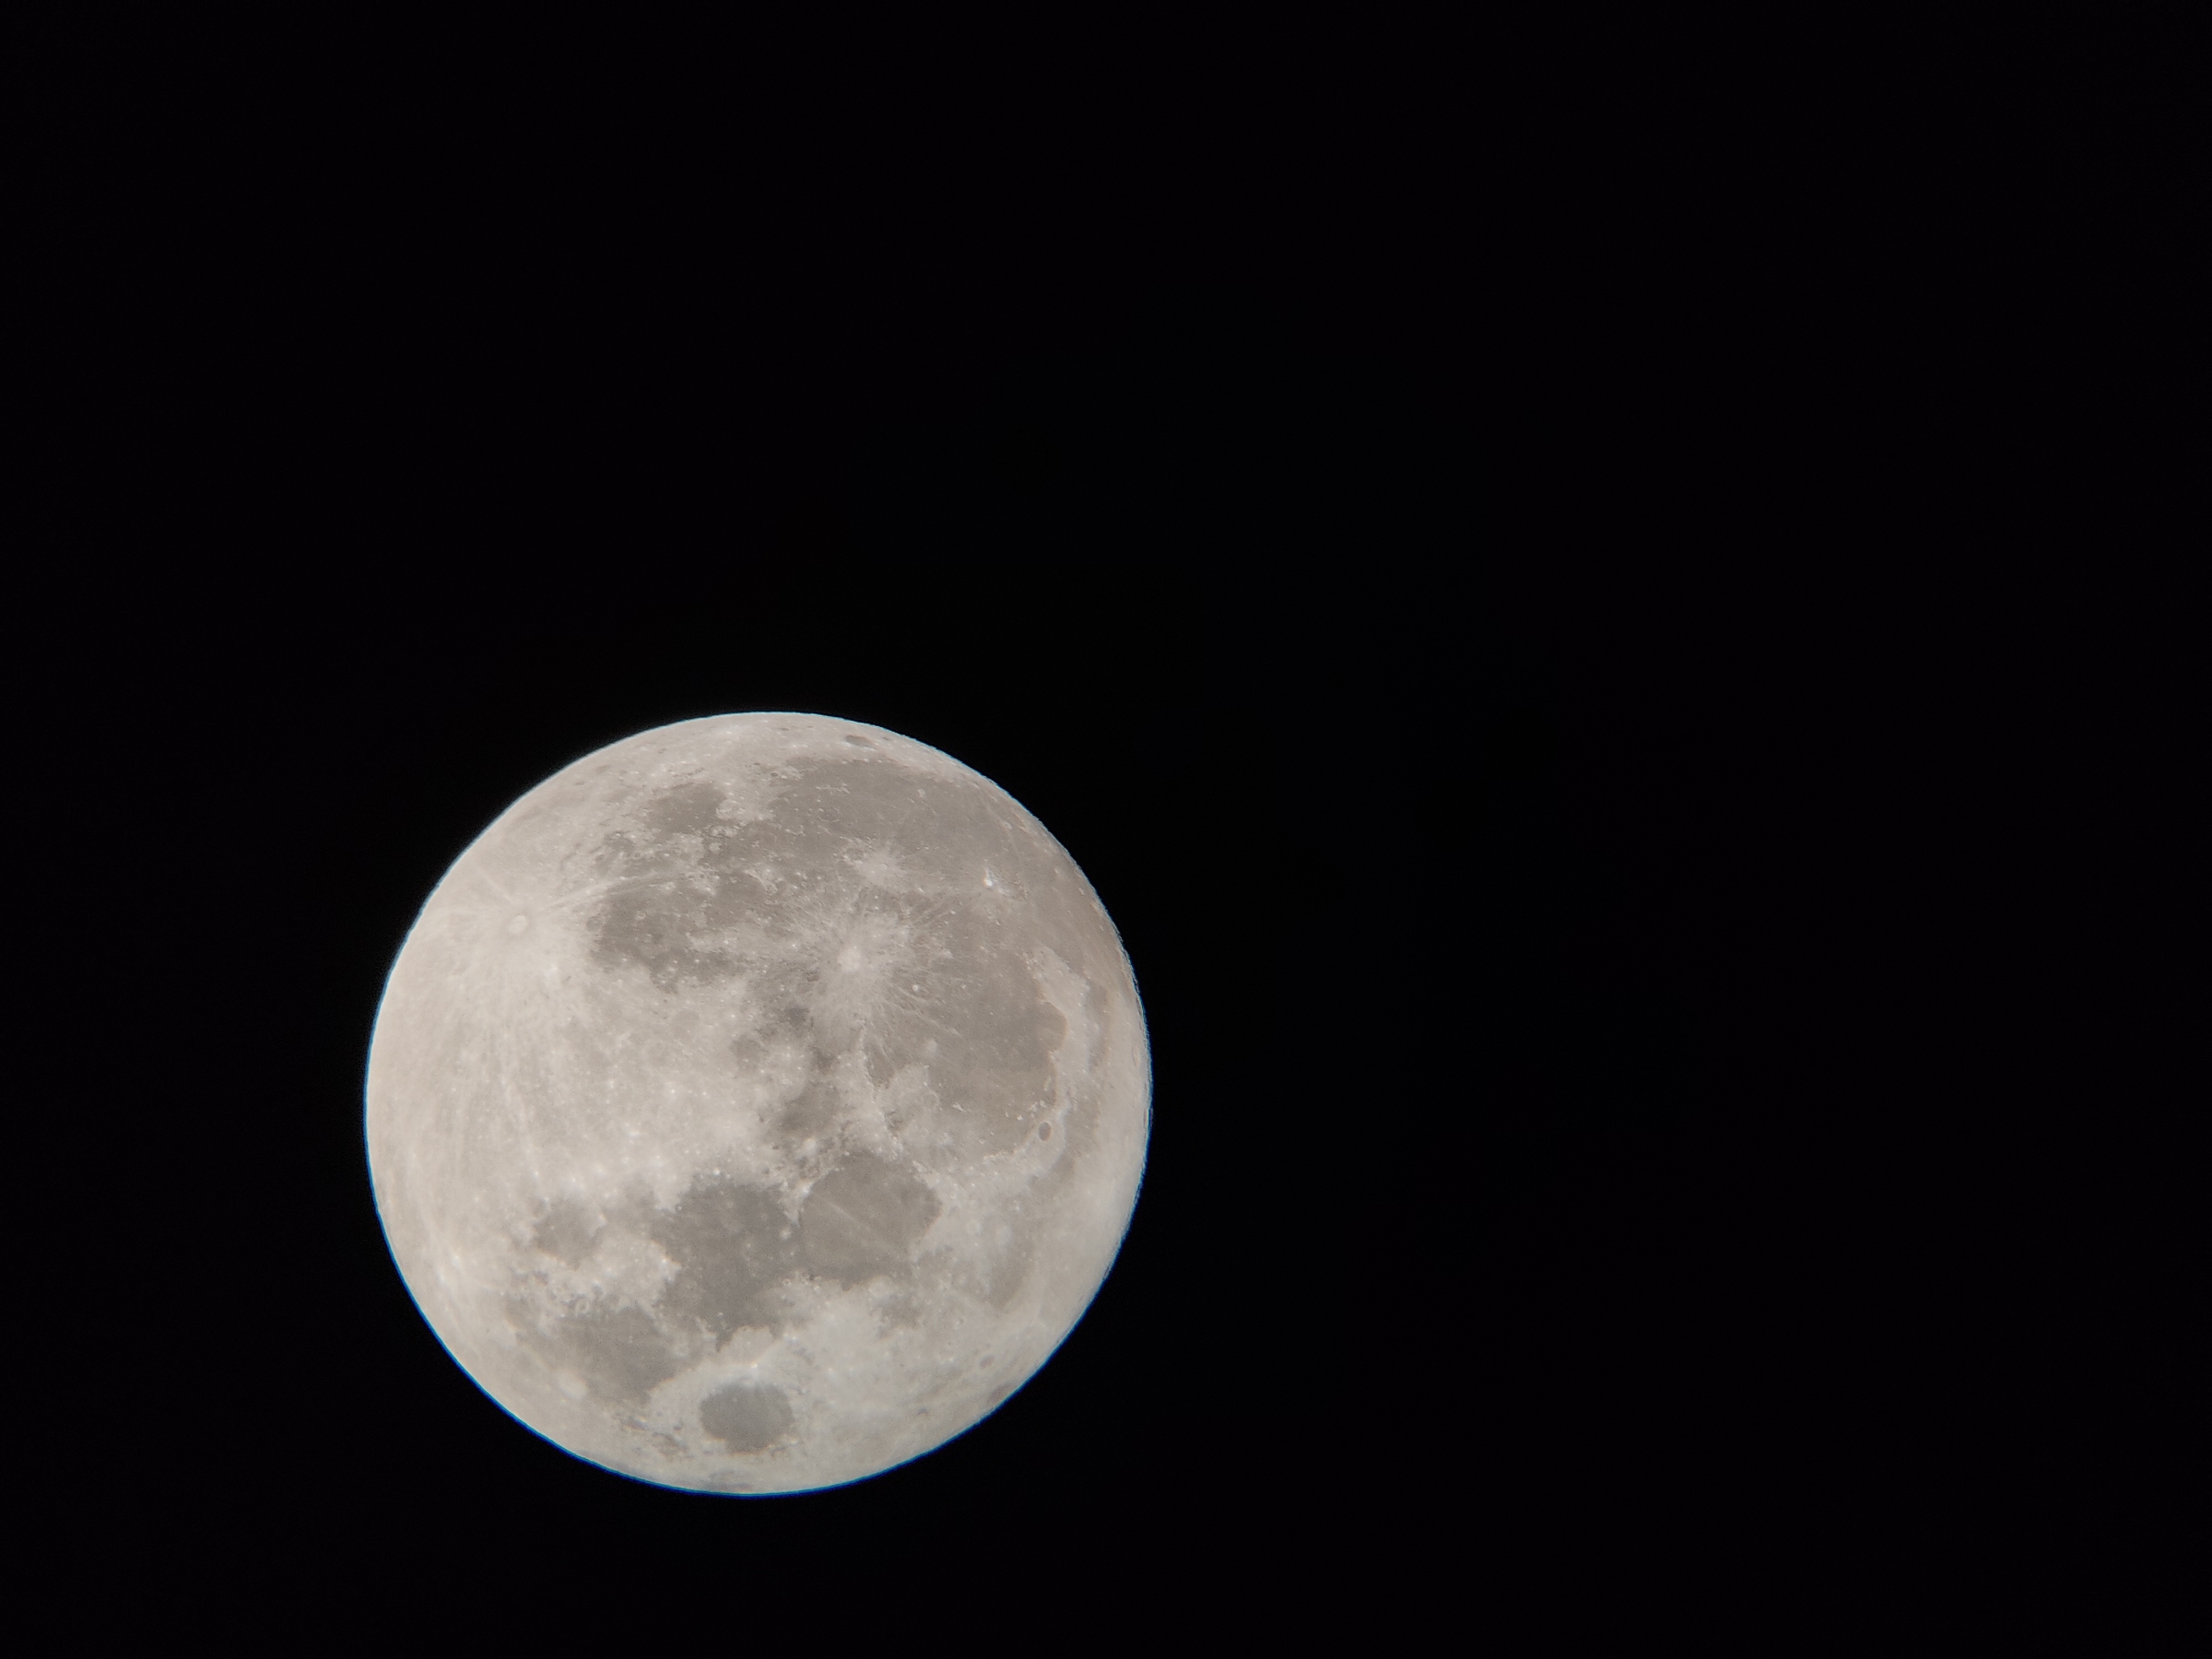
Telescope As I said earlier, in my opinion, it takes a lot of patience and perseverance on this subject. And most of the things here are DIY. To start with, we targeted the Moon. Because it is easy. I pointed the scope to the moon, then looked into the finder scope to center it, and then looked through the eyepiece. And blank. Nothing out there. Turns out, the finder scope and the viewer s angle weren t aligned. This is common and the first DIY step, when you plan to use your telescope for viewing. Since our first attempt was unplanned and just random because we luckily spotted that the skies were clear, we weren t prepared for this. Lucky enough, mapping the difference in the alignment, in the head, is not very difficult. After a couple of minutes, I could make out the point in the finder scope, where the object if projected, would show proper in the viewer. With that done, it was just mesmerizing to see the Moon, in a bit more detail, than what I ve seen all these years of my life.
Moon
Moon
Moon
Moon
Moon
Moon
Moon
Moon
The images are not exactly what we saw with our eyes. The view was much more vivid than these pictures. But as a first timer, I really wanted to capture this first moment of a closer view of the Moon. In the whole process; that of ground work studying about telescopes, installation of the telescope, astronomy basics and many other things; the most difficult part in this entire journey, was to point my phone to the viewing eyepiece, to get a shot of the object. This requirement just introduced me to astrophotography. And then, Dobsonians aren t the best model for astrophotography, to what I ve learnt so far. Hopefully, I ll find my ways to do some DIY astrophotography with the tools I have. Or extend my arsenal over time. But overall, we ve been very pleased with the subject of Astronomy. It is a different feel altogether and we re glad to have forayed into it.

2 October 2020

Ian Jackson: Mailman vs DKIM - a novel solution

tl;dr: Do not configure Mailman to replace the mail domains in From: headers. Instead, try out my small new program which can make your Mailman transparent, so that DKIM signatures survive. Background and narrative DKIM NB: This explanation is going to be somewhat simplified. I am going to gloss over some details and make some slightly approximate statements. DKIM is a new anti-spoofing mechanism for Internet email, intended to help fight spam. DKIM, paired with the DMARC policy system, has been remarkably successful at stemming the flood of joe-job spams. As usually deployed, DKIM works like this: When a message is originally sent, the author's MUA sends it to the MTA for their From: domain for outward delivery. The From: domain mailserver calculates a cryptographic signature of the message, and puts the signature in the headers of the message. Obviously not the whole message can be signed, since at the very least additional headers need to be added in transit, and sometimes headers need to be modified too. The signing MTA gets to decide what parts of the message are covered by the signature: they nominate the header fields that are covered by the signature, and specify how to handle the body. A recipient MTA looks up the public key for the From: domain in the DNS, and checks the signature. If the signature doesn't match, depending on policy (originator's policy, in the DNS, and recipient's policy of course), typically the message will be treated as spam. The originating site has a lot of control over what happens in practice. They get to publish a formal (DMARC) policy in the DNS which advises recipients what they should do with mails claiming to be from their site. As mentioned, they can say which headers are covered by the signature - including the ability to sign the absence of a particular headers - so they can control which headers downstreams can get away with adding or modifying. And they can set a normalisation policy, which controls how precisely the message must match the one that they sent. Mailman Mailman is, of course, the extremely popular mailing list manager. There are a lot of things to like about it. I choose to run it myself not just because it's popular but also because it provides a relatively competent web UI and a relatively competent email (un)subscription interfaces, decent bounce handling, and a pretty good set of moderation and posting access controls. The Xen Project mailing lists also run on mailman. Recently we had some difficulties with messages sent by Citrix staff (including myself), to Xen mailing lists, being treated as spam. Recipient mail systems were saying the DKIM signatures were invalid. This was in fact true. Citrix has chosen a fairly strict DKIM policy; in particular, they have chosen "simple" normalisation - meaning that signed message headers must precisely match in syntax as well as in a semantic sense. Examining the the failing-DKIM messages showed that this was definitely a factor. Applying my Opinions about email My Bayesian priors tend to suggest that a mail problem involving corporate email is the fault of the corporate email. However in this case that doesn't seem true to me. My starting point is that I think mail systems should not not modify messages unnecessarily. None of the DKIM-breaking modifications made by Mailman seemed necessary to me. I have on previous occasions gone to corporate IT and requested quite firmly that things I felt were broken should be changed. But it seemed wrong to go to corporate IT and ask them to change their published DKIM/DMARC policy to accomodate a behaviour in Mailman which I didn't agree with myself. I felt that instead I shoud put (with my Xen Project hat on) my own house in order. Getting Mailman not to modify messages So, I needed our Mailman to stop modifying the headers. I needed it to not even reformat them. A brief look at the source code to Mailman showed that this was not going to be so easy. Mailman has a lot of features whose very purpose is to modify messages. Personally, as I say, I don't much like these features. I think the subject line tags, CC list manipulations, and so on, are a nuisance and not really Proper. But they are definitely part of why Mailman has become so popular and I can definitely see why the Mailman authors have done things this way. But these features mean Mailman has to disassemble incoming messages, and then reassemble them again on output. It is very difficult to do that and still faithfully reassemble the original headers byte-for-byte in the case where nothing actually wanted to modify them. There are existing bug reports[1] [2] [3] [4]; I can see why they are still open. Rejected approach: From:-mangling This situation is hardly unique to the Xen lists. Many other have struggled with it. The best that seems to have been come up with so far is to turn on a new Mailman feature which rewrites the From: header of the messages that go through it, to contain the list's domain name instead of the originator's. I think this is really pretty nasty. It breaks normal use of email, such as reply-to-author. It is having Mailman do additional mangling of the message in order to solve the problems caused by other undesirable manglings! Solution! As you can see, I asked myself: I want Mailman not modify messages at all; how can I get it to do that? Given the existing structure of Mailman - with a lot of message-modifying functionality - that would really mean adding a bypass mode. It would have to spot, presumably depending on config settings, that messages were not to be edited; and then, it would avoid disassembling and reassembling the message at at all, and bypass the message modification stages. The message would still have to be parsed of course - it's just that the copy send out ought to be pretty much the incoming message. When I put it to myself like that I had a thought: couldn't I implement this outside Mailman? What if I took a copy of every incoming message, and then post-process Mailman's output to restore the original? It turns out that this is quite easy and works rather well! outflank-mailman outflank-mailman is a 233-line script, plus documentation, installation instructions, etc. It is designed to run from your MTA, on all messages going into, and coming from, Mailman. On input, it saves a copy of the message in a sqlite database, and leaves a note in a new Outflank-Mailman-Id header. On output, it does some checks, finds the original message, and then combines the original incoming message with carefully-selected headers from the version that Mailman decided should be sent. This was deployed for the Xen Project lists on Tuesday morning and it seems to be working well so far. If you administer Mailman lists, and fancy some new software to address this problem, please do try it out. Matters arising - Mail filtering, DKIM Overall I think DKIM is a helpful contribution to the fight against spam (unlike SPF, which is fundamentally misdirected and also broken). Spam is an extremely serious problem; most receiving mail servers experience more attempts to deliver spam than real mail, by orders of magnitude. But DKIM is not without downsides. Inherent in the design of anything like DKIM is that arbitrary modification of messages by list servers is no longer possible. In principle it might be possible to design a system which tolerated modifications reasonable for mailing lists but it would be quite complicated and have to somehow not tolerate similar modifications in other contexts. So DKIM means that lists can no longer add those unsubscribe footers to mailing list messages. The "new way" (RFC2369, July 1998), to do this is with the List-Unsubscribe header. Hopefully a good MUA will be able to deal with unsubscription semiautomatically, and I think by now an adequate MUA should at least display these headers by default. Sender: There are implications for recipient-side filtering too. The "traditional" correct way to spot mailing list mail was to look for Resent-To:, which can be added without breaking DKIM; the "new" (RFC2919, March 2001) correct way is List-Id:, likewise fine. But during the initial deployment of outflank-mailman I discovered that many subscribers were detecting that a message was list traffic by looking at the Sender: header. I'm told that some mail systems (apparently Microsoft's included) make it inconvenient to filter on List-Id. Really, I think a mailing list ought not to be modifying Sender:. Given Sender:'s original definition and semantics, there might well be reasonable reasons for a mailing list posting to have different From: and and then the original Sender: ought not to be lost. And a mailing list's operation does not fit well into the original definition of Sender:. I suspect that list software likes to put in Sender mostly for historical reasons; notably, a long time ago it was not uncommon for broken mail systems to send bounces to the Sender: header rather than the envelope sender (SMTP MAIL FROM). DKIM makes this more of a problem. Unfortunately the DKIM specifications are vague about what headers one should sign, but they pretty much definitely include Sender: if it is present, and some materials encourage signing the absence of Sender:. The latter is Exim's default configuration when DKIM-signing is enabled. Franky there seems little excuse for systems to not readily support and encourage filtering on List-Id, 20 years later, but I don't want to make life hard for my users. For now we are running a compromise configuration: if there wasn't a Sender: in the original, take Mailman's added one. This will result in (i) misfiltering for some messages whose poster put in a Sender:, and (ii) DKIM failures for messages whose originating system signed the absence of a Sender:. I'm going to mine the db for some stats after it's been deployed for a week or so, to see which of these problems is worst and decide what to do about it. Mail routing For DKIM to work, messages being sent From: a particular mail domain must go through a system trusted by that domain, so they can be signed. Most users tend to do this anyway: their mail provider gives them an IMAP server and an authenticated SMTP submission server, and they configure those details in their MUA. The MUA has a notion of "accounts" and according to the user's selection for an outgoing message, connects to the authenticated submission service (usually using TLS over the global internet). Trad unix systems where messages are sent using the local sendmail or localhost SMTP submission (perhaps by automated systems, or perhaps by human users) are fine too. The smarthost can do the DKIM signing. But this solution is awkward for a user of a trad MUA in what I'll call "alias account" setups: where a user has an address at a mail domain belonging to different people to the system on which they run their MUA (perhaps even several such aliases for different hats). Traditionally this worked by the mail domain forwarding incoming the mail, and the user simply self-declaring their identity at the alias domain. Without DKIM there is nothing stopping anyone self-declaring their own From: line. If DKIM is to be enabled for such a user (preventing people forging mail as that user), the user will have to somehow arrange that their trad unix MUA's outbound mail stream goes via their mail alias provider. For a single-user sending unix system this can be done with tolerably complex configuration in an MTA like Exim. For shared systems this gets more awkward and might require some hairy shell scripting etc.
edited 2020-10-01 21:22 and 21:35 and -02 10:50 +0100 to fix typos and 21:28 to linkify "my small program" in the tl;dr


comment count unavailable comments

1 October 2020

Russ Allbery: Review: Harrow the Ninth

Review: Harrow the Ninth, by Tamsyn Muir
Series: The Locked Tomb #2
Publisher: Tor
Copyright: 2020
ISBN: 1-250-31320-1
Format: Kindle
Pages: 510
Harrow the Ninth is a direct sequel to Gideon the Ninth and under absolutely no circumstances should you start reading here. You would be so lost. If you plan on reading this series, read the books as closely together as you can so that you can remember the details of the previous book. You may still resort to re-reading or searching through parts of the previous book as you go. Muir is doing some complex structural work with Harrow the Ninth, so it's hard to know how much to say about it without spoiling some aspect of it for someone. I think it's safe to say this much: As advertised by the title, we do get a protagonist switch to Harrowhark. However, unlike Gideon the Ninth, it's not a single linear story. The storyline that picks up after the conclusion of Gideon is interwoven with apparent flashbacks retelling the story of the previous book from Harrowhark's perspective. Or at least it might have been the story of the previous book, except that Ortus is Harrowhark's cavalier, Gideon does not appear, and other divergences from the story we previously read become obvious early on. (You can see why memory of Gideon the Ninth is important.) Oh, and one of those storylines is written in the second person. Unlike some books that use this as a gimmick, this is for reasons that are eventually justified and partly explained in the story, but it's another example of the narrative complexity. Harrow the Ninth is dropping a lot of clues (and later revelations) in both story events and story structure, many of which are likely to upend reader expectations from the first book. I have rarely read a novel that is this good at fulfilling the tricky role of the second book of a trilogy. Gideon the Ninth was, at least on the surface, a highly entertaining, linear, and relatively straightforward escape room mystery, set against a dying-world SF background that was more hinted at than fleshed out. Harrow the Ninth revisits and reinterprets that book in ways that add significant depth without feeling artificial. Bits of scenery in the first book take on new meaning and intention. Characters we saw only in passing get a much larger role (and Abigail is worth the wait). And we get a whole ton of answers: about the God Emperor, about Lyctors, about the world, about Gideon and Harrowhark's own pasts and backgrounds, and about the locked tomb that is at the center of the Ninth House. But there is still more than enough for a third book, including a truly intriguing triple cliffhanger ending. Harrow the Ninth is both satisfying in its own right and raises new questions that I'm desperate to see answered in the third book. Also, to respond to my earlier self on setting, this world is not a Warhammer 40K universe, no matter how much it may have appeared in the glimpses we got in Gideon. The God Emperor appears directly in this book and was not at all what I was expecting, if perhaps even more disturbing. Muir is intentionally playing against type, drawing a sharp contrast between the God Emperor and the dramatic goth feel of the rest of the universe and many of the characters, and it's creepily effective and goes in a much different ethical direction than I had thought. (That said, I will warn that properly untangling the ethical dilemmas of this universe is clearly left to the third book.) I mentioned in my review of Gideon the Ninth that I was happy to see more SF pulling unapologetically from fanfic. I'm going to keep beating that drum in this review in part because I think the influence may be less obvious to the uninitiated. Harrow the Ninth is playing with voice, structure, memory, and chronology in ways that I suspect the average reader unfamiliar with fanfic may associate more with literary fiction, but they would be wrongly underestimating fanfic if they did so. If anything, the callouts to fanfic are even clearer. There are three classic fanfic alternate universe premises that appear in passing, the story relies on the reader's ability to hold a canonical narrative and an alternate narrative in mind simultaneously, and the genre inspiration was obvious enough to me that about halfway through the novel I correctly guessed one of the fanfic universes in which Muir has written. (I'm not naming it here since I think it's a bit of a spoiler.) And of course there's the irreverence. There are some structural reasons why the narrative voice isn't quite as good as Gideon the Ninth at the start, but rest assured that Muir makes up for that by the end of the book. My favorite scenes in the series so far happen at the end of Harrow the Ninth: world-building, revelations, crunchy metaphysics, and irreverent snark all woven beautifully together. Muir has her characters use Internet meme references like teenagers, which is a beautiful bit of characterization because they are teenagers. In a world that's heavy on viscera, skeletons, death, and horrific monsters, it's a much needed contrast and a central part of how the characters show defiance and courage. I don't think this will work for everyone, but it very much works for me. There's a Twitter meme reference late in the book that had me laughing out loud in delight. Harrow the Ninth is an almost perfect second book, in that if you liked Gideon the Ninth, you will probably love Harrow the Ninth and it will make you like Gideon the Ninth even more. It does have one major flaw, though: pacing. This was also my major complaint about Gideon, primarily around the ending. I think Harrow the Ninth is a bit better, but the problem has a different shape. The start of the book is a strong "what the hell is going on" experience, which is very effective, and the revelations are worth the build-up once they start happening. In between, though, the story drags on a bit too long. Harrow is sick and nauseated at the start of the book for rather longer than I wanted to read about, there is one too many Lyctor banquets than I think were necessary to establish the characters, and I think there's a touch too much wandering the halls. Muir also interwove two narrative threads and tried to bring them to a conclusion at the same time, but I think she had more material for one than the other. There are moments near the end of the book where one thread is producing all the payoff revelations the reader has been waiting for, and the other thread is following another interminable and rather uninteresting fight scene. You don't want your reader saying "argh, no" each time you cut away to the other scene. It's better than Gideon the Ninth, where the last fifth of the book is mostly a running battle that went on way longer than it needed to, but I still wish Muir had tightened the story throughout and balanced the two threads so that we could stay with the most interesting one when it mattered. That said, I mostly noticed the pacing issues in retrospect and in talking about them with a friend who was more annoyed than I was. In the moment, there was so much going on here, so many new things to think about, and so much added depth that I devoured Harrow the Ninth over the course of two days and then spent the next day talking to other people who had read it, trading theories about what happened and what will happen in the third book. It was the most enjoyable reading experience I've had so far this year. Gideon the Ninth was fun; Harrow the Ninth was both fun and on the verge of turning this series into something truly great. I can hardly wait for Alecto the Ninth (which doesn't yet have a release date, argh). As with Gideon the Ninth, content warning for lots and lots of gore, rather too detailed descriptions of people's skeletons, restructuring bits of the body that shouldn't be restructured, and more about bone than you ever wanted to know. Rating: 9 out of 10

28 September 2020

Vincent Bernat: Syncing RIPE, ARIN and APNIC objects with a custom Ansible module

Internet is split into five regional Internet registry: AFRINIC, ARIN, APNIC, LACNIC and RIPE. Each RIR maintains an Internet Routing Registry. An IRR allows one to publish information about the routing of Internet number resources.1 Operators use this to determine the owner of an IP address and to construct and maintain routing filters. To ensure your routes are widely accepted, it is important to keep the prefixes you announce up-to-date in an IRR. There are two common tools to query this database: whois and bgpq4. The first one allows you to do a query with the WHOIS protocol:
$ whois -BrG 2a0a:e805:400::/40
[ ]
inet6num:       2a0a:e805:400::/40
netname:        FR-BLADE-CUSTOMERS-DE
country:        DE
geoloc:         50.1109 8.6821
admin-c:        BN2763-RIPE
tech-c:         BN2763-RIPE
status:         ASSIGNED
mnt-by:         fr-blade-1-mnt
remarks:        synced with cmdb
created:        2020-05-19T08:04:58Z
last-modified:  2020-05-19T08:04:58Z
source:         RIPE
route6:         2a0a:e805:400::/40
descr:          Blade IPv6 - AMS1
origin:         AS64476
mnt-by:         fr-blade-1-mnt
remarks:        synced with cmdb
created:        2019-10-01T08:19:34Z
last-modified:  2020-05-19T08:05:00Z
source:         RIPE
The second one allows you to build route filters using the information contained in the IRR database:
$ bgpq4 -6 -S RIPE -b AS64476
NN = [
    2a0a:e805::/40,
    2a0a:e805:100::/40,
    2a0a:e805:300::/40,
    2a0a:e805:400::/40,
    2a0a:e805:500::/40
];
There is no module available on Ansible Galaxy to manage these objects. Each IRR has different ways of being updated. Some RIRs propose an API but some don t. If we restrict ourselves to RIPE, ARIN and APNIC, the only common method to update objects is email updates, authenticated with a password or a GPG signature.2 Let s write a custom Ansible module for this purpose!

Notice I recommend that you read Writing a custom Ansible module as an introduction, as well as Syncing MySQL tables for a more instructive example.

Code The module takes a list of RPSL objects to synchronize and returns the body of an email update if a change is needed:
- name: prepare RIPE objects
  irr_sync:
    irr: RIPE
    mntner: fr-blade-1-mnt
    source: whois-ripe.txt
  register: irr

Prerequisites The source file should be a set of objects to sync using the RPSL language. This would be the same content you would send manually by email. All objects should be managed by the same maintainer, which is also provided as a parameter. Signing and sending the result is not the responsibility of this module. You need two additional tasks for this purpose:
- name: sign RIPE objects
  shell:
    cmd: gpg --batch --user noc@example.com --clearsign
    stdin: "  irr.objects  "
  register: signed
  check_mode: false
  changed_when: false
- name: update RIPE objects by email
  mail:
    subject: "NEW: update for RIPE"
    from: noc@example.com
    to: "auto-dbm@ripe.net"
    cc: noc@example.com
    host: smtp.example.com
    port: 25
    charset: us-ascii
    body: "  signed.stdout  "
You also need to authorize the PGP keys used to sign the updates by creating a key-cert object and adding it as a valid authentication method for the corresponding mntner object:
key-cert:  PGPKEY-A791AAAB
certif:    -----BEGIN PGP PUBLIC KEY BLOCK-----
certif:    
certif:    mQGNBF8TLY8BDADEwP3a6/vRhEERBIaPUAFnr23zKCNt5YhWRZyt50mKq1RmQBBY
[ ]
certif:    -----END PGP PUBLIC KEY BLOCK-----
mnt-by:    fr-blade-1-mnt
source:    RIPE
mntner:    fr-blade-1-mnt
[ ]
auth:      PGPKEY-A791AAAB
mnt-by:    fr-blade-1-mnt
source:    RIPE

Module definition Starting from the skeleton described in the previous article, we define the module:
module_args = dict(
    irr=dict(type='str', required=True),
    mntner=dict(type='str', required=True),
    source=dict(type='path', required=True),
)
result = dict(
    changed=False,
)
module = AnsibleModule(
    argument_spec=module_args,
    supports_check_mode=True
)

Getting existing objects To grab existing objects, we use the whois command to retrieve all the objects from the provided maintainer.
# Per-IRR variations:
# - whois server
whois =  
    'ARIN': 'rr.arin.net',
    'RIPE': 'whois.ripe.net',
    'APNIC': 'whois.apnic.net'
 
# - whois options
options =  
    'ARIN': ['-r'],
    'RIPE': ['-BrG'],
    'APNIC': ['-BrG']
 
# - objects excluded from synchronization
excluded = ["domain"]
if irr == "ARIN":
    # ARIN does not return these objects
    excluded.extend([
        "key-cert",
        "mntner",
    ])
# Grab existing objects
args = ["-h", whois[irr],
        "-s", irr,
        *options[irr],
        "-i", "mnt-by",
        module.params['mntner']]
proc = subprocess.run("whois", *args, capture_output=True)
if proc.returncode != 0:
    raise AnsibleError(
        f"unable to query whois:  args ")
output = proc.stdout.decode('ascii')
got = extract(output, excluded)
The first part of the code setup some IRR-specific constants: the server to query, the options to provide to the whois command and the objects to exclude from synchronization. The second part invokes the whois command, requesting all objects whose mnt-by field is the provided maintainer. Here is an example of output:
$ whois -h whois.ripe.net -s RIPE -BrG -i mnt-by fr-blade-1-mnt
[ ]
inet6num:       2a0a:e805:300::/40
netname:        FR-BLADE-CUSTOMERS-FR
country:        FR
geoloc:         48.8566 2.3522
admin-c:        BN2763-RIPE
tech-c:         BN2763-RIPE
status:         ASSIGNED
mnt-by:         fr-blade-1-mnt
remarks:        synced with cmdb
created:        2020-05-19T08:04:59Z
last-modified:  2020-05-19T08:04:59Z
source:         RIPE
[ ]
route6:         2a0a:e805:300::/40
descr:          Blade IPv6 - PA1
origin:         AS64476
mnt-by:         fr-blade-1-mnt
remarks:        synced with cmdb
created:        2019-10-01T08:19:34Z
last-modified:  2020-05-19T08:05:00Z
source:         RIPE
[ ]
The result is passed to the extract() function. It parses and normalizes the results into a dictionary mapping object names to objects. We store the result in the got variable.
def extract(raw, excluded):
    """Extract objects."""
    # First step, remove comments and unwanted lines
    objects = "\n".join([obj
                         for obj in raw.split("\n")
                         if not obj.startswith((
                                 "#",
                                 "%",
                         ))])
    # Second step, split objects
    objects = [RPSLObject(obj.strip())
               for obj in re.split(r"\n\n+", objects)
               if obj.strip()
               and not obj.startswith(
                   tuple(f" x :" for x in excluded))]
    # Last step, put objects in a dict
    objects =  repr(obj): obj
               for obj in objects 
    return objects
RPSLObject() is a class enabling normalization and comparison of objects. Look at the module code for more details.
>>> output="""
... inet6num:       2a0a:e805:300::/40
... [ ]
... """
>>> pprint( k: str(v) for k,v in extract(output, excluded=[]) )
 '<Object:inet6num:2a0a:e805:300::/40>':
   'inet6num:       2a0a:e805:300::/40\n'
   'netname:        FR-BLADE-CUSTOMERS-FR\n'
   'country:        FR\n'
   'geoloc:         48.8566 2.3522\n'
   'admin-c:        BN2763-RIPE\n'
   'tech-c:         BN2763-RIPE\n'
   'status:         ASSIGNED\n'
   'mnt-by:         fr-blade-1-mnt\n'
   'remarks:        synced with cmdb\n'
   'source:         RIPE',
 '<Object:route6:2a0a:e805:300::/40>':
   'route6:         2a0a:e805:300::/40\n'
   'descr:          Blade IPv6 - PA1\n'
   'origin:         AS64476\n'
   'mnt-by:         fr-blade-1-mnt\n'
   'remarks:        synced with cmdb\n'
   'source:         RIPE' 

Comparing with wanted objects Let s build the wanted dictionary using the same structure, thanks to the extract() function we can use verbatim:
with open(module.params['source']) as f:
    source = f.read()
wanted = extract(source, excluded)
The next step is to compare got and wanted to build the diff object:
if got != wanted:
    result['changed'] = True
    if module._diff:
        result['diff'] = [
            dict(before_header=k,
                 after_header=k,
                 before=str(got.get(k, "")),
                 after=str(wanted.get(k, "")))
            for k in set((*wanted.keys(), *got.keys()))
            if k not in wanted or k not in got or wanted[k] != got[k]]

Returning updates The module does not have a side effect. If there is a difference, we return the updates to send by email. We choose to include all wanted objects in the updates (contained in the source variable) and let the IRR ignore unmodified objects. We also append the objects to be deleted by adding a delete: attribute to each them them.
# We send all source objects and deleted objects.
deleted_mark = f" 'delete:':16 deleted by CMDB"
deleted = "\n\n".join([f" got[k].raw \n deleted_mark "
                       for k in got
                       if k not in wanted])
result['objects'] = f" source \n\n deleted "
module.exit_json(**result)

The complete code is available on GitHub. The module supports both --diff and --check flags. It does not return anything if no change is detected. It can work with APNIC, RIPE and ARIN. It is not perfect: it may not detect some changes,3 it is not able to modify objects not owned by the provided maintainer4 and some attributes cannot be modified, requiring to manually delete and recreate the updated object.5 However, this module should automate 95% of your needs.

  1. Other IRRs exist without being attached to a RIR. The most notable one is RADb.
  2. ARIN is phasing out this method in favor of IRR-online. RIPE has an API available, but email updates are still supported and not planned to be deprecated. APNIC plans to expose an API.
  3. For ARIN, we cannot query key-cert and mntner objects and therefore we cannot detect changes in them. It is also not possible to detect changes to the auth mechanisms of a mntner object.
  4. APNIC do not assign top-level objects to the maintainer associated with the owner.
  5. Changing the status of an inetnum object requires deleting and recreating the object.

27 September 2020

Joachim Breitner: Learn Haskell on CodeWorld writing Sokoban

Two years ago, I held the CIS194 minicourse on Haskell at the University of Pennsylvania. In that installment of the course, I changed the first four weeks to teach the basics of Haskell using the online Haskell environment CodeWorld, and lead the students towards implementing the game Sokoban. As it is customary for CIS194, I put my lecture notes and exercises online, and this has been used as a learning resources by people from all over the world. But since I have left the University of Pennsylvania, I lost the ability to update the text, and as the CodeWorld API has evolved, some of the examples and exercises no longer work. Some recent complains about that, in bug reports against CodeWorld and in unrealistically flattering tweets ( Shame, this was the best Haskell course ever!!! ) motivated me to extract that material and turn it into an updated stand-alone tutorial that I can host myself. So if you feel like learning Haskell without worrying about local installation, and while creating a reasonably fun game, head over to https://haskell-via-sokoban.nomeata.de/ and get started! Improvements can now also be contributed at https://github.com/nomeata/haskell-via-sokoban. Credits go to Brent Yorgey, Richard Eisenberg and Noam Zilberstein, who held the previous installments of the course, and Chris Smith for creating the CodeWorld environment.

26 September 2020

Dirk Eddelbuettel: #30: Easy, Reliable, Fast and Portable Linux and macOS Continuous Integration

Welcome to the 30th post in the rarified R recommendation resources series or R4 for short. The last post introduced BSPM. In the four weeks since, we have worked some more on BSPM to bring it to the point where it is ready for use with continuous integration. Building on this, it is now used inside the run.sh script that driven our CI use for many years (via the r-travis repo). Which we actually use right now on three different platforms: All three use the exact same script facilitating this, and run a matrix over Linux and macOS. You read this right: one CI setup that is portable and which you can take to your CI provider of choice. No lock-in or tie-in. Use what works, change at will. Or run on all three if you like burning extra cycles. This is already used by handful of my repos as well as by at least two repos of friends also deploying r-travis. How does it work? In a nutshell we are There are several customizations that are possible via environment variables We find this setup compelling. The scheme is simple: there really is just one shell script behind it which can also be downloaded and altered. The scheme is also portable as we can (as shown) rotate between CI provides. The scheme is also more flexible: in case of debugging needs one can simply run the script on a local Docker or VM instance. Lastly, the scheme moves away from single points of failure or breakage. Currently the script uses only BSPM as I had the hunch that it would a) work and b) be compelling. Adding support for RSPM would be equally easy, but I have no immediate need to do so. Adding BioConductor installation may be next. That is easy when BioConductor uses r-release; it may be little more challenging under r-devel to but it should work too. Stay tuned. In the meantime, if the above sounds compelling, give run.sh from r-travis a go! If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

25 September 2020

Reproducible Builds: ARDC sponsors the Reproducible Builds project

The Reproducible Builds project is pleased to announce a donation from Amateur Radio Digital Communications (ARDC) in support of its goals. ARDC s contribution will propel the Reproducible Builds project s efforts in ensuring the future health, security and sustainability of our increasingly digital society.

About Amateur Radio Digital Communications (ARDC) Amateur Radio Digital Communications (ARDC) is a non-profit that was formed to further research and experimentation with digital communications using radio, with a goal of advancing the state of the art of amateur radio and to educate radio operators in these techniques. It does this by managing the allocation of network resources, encouraging research and experimentation with networking protocols and equipment, publishing technical articles and number of other activities to promote the public good of amateur radio and other related fields. ARDC has recently begun to contribute funding to organisations, groups, individuals and projects towards these and related goals, and their grant to the Reproducible Builds project is part of this new initiative. Amateur radio is an entirely volunteer activity performed by knowledgeable hobbyists who have proven their ability by passing the appropriate government examinations. No remuneration is permitted. Ham radio, as it is also known, has proven its value in advancements of the state of the communications arts, as well as in public service during disasters and in times of emergency. For more information about ARDC, please see their website at ampr.org.

About the Reproducible Builds project One of the original promises of open source software was that peer review would result in greater end-user security and stability of our digital ecosystem. However, although it is theoretically possible to inspect and build the original source code in order to avoid maliciously-inserted flaws, almost all software today is distributed in prepackaged form. This disconnect allows third-parties to compromise systems by injecting code into seemingly secure software during the build process, as well as by manipulating copies distributed from app stores and other package repositories. In order to address this, Reproducible builds are a set of software development practices, ideas and tools that create an independently-verifiable path from the original source code, all the way to what is actually running on our machines. Reproducible builds can reveal the injection of backdoors introduced by the hacking of developers own computers, build servers and package repositories, but can also expose where volunteers or companies have been coerced into making changes via blackmail, government order, and so on. A world without reproducible builds is a world where our digital infrastructure cannot be trusted and where online communities are slower to grow, collaborate less and are increasingly fragile. Without reproducible builds, we leave space for greater encroachments on our liberties both by individuals as well as powerful, unaccountable actors such as governments, large corporations and autocratic regimes. The Reproducible Builds project began as a project within the Debian community, but is now working with many crucial and well-known free software projects such as Coreboot, openSUSE, OpenWrt, Tails, GNU Guix, Arch Linux, Tor, and many others. It is now an entirely Linux distribution independent effort and serves as the central clearing house for all issues related to securing build systems and software supply chains of all kinds. For more about the Reproducible Builds project, please see their website at reproducible-builds.org.
If you are interested in ensuring the ongoing security of the software that underpins our civilisation, and wish to sponsor the Reproducible Builds project, please reach out to the project by emailing contact@reproducible-builds.org.

23 September 2020

Vincent Fourmond: Tutorial: analyze Km data of CODHs

This is the first post of a series in which we will provide the readers with simple tutorial approaches to reproduce the data analysis of some of our published papers. All our data analysis is performed using QSoas. Today, we will show you how to analyze the experiments we used to characterize the behaviour of an enzyme, the Nickel-Iron CO dehydrogenase IV from Carboxytothermus hydrogenoformans. The experiments we analyze here are described in much more details in the original publication, Domnik et al, Angewandte Chemie, 2017. The only things you need to know for now are the following: This means that we expect a response of the type: $$i(t) = \frac i_m 1 + \frac K_m [\mathrm CO ](t) $$ in which $$[\mathrm CO ](t) = \begin cases 0, & \text for t < t_0 \\ C_0 \exp \frac t_0 - t \tau , & \text for t\geq t_0 %> \end cases $$ To begin this tutorial, first download the files from the github repository (direct links: data, parameter file and ruby script). Start QSoas, go to the directory where you saved the files, load the data file, and remove spikes in the data using the following commands:
QSoas> cd
QSoas> l Km-CODH-IV.dat
QSoas> R
First fitThen, to fit the above equation to the data, the simplest is to take advantage of the time-dependent parameters features of QSoas. Run simply:
QSoas> fit-arb im/(1+km/s) /with=s:1,exp
This simply launches the fit interface to fit the exact equations above. The im/(1+km/s) is simply the translation of the Michaelis-Menten equation above, and the /with=s:1,exp specifies that s is the result of the sum of 1 exponential like for the definition of above. Then, load the Km-CODH-IV.params parameter files (using the "Parameters.../Load from file" action at the bottom, or the Ctrl+L keyboard shortcut). Your window should now look like this:
To fit the data, just hit the "Fit" button ! (or Ctrl+F). Including an offset The fit is not bad, but not perfect. In particular, it is easy to see why: the current predicted by the fit goes to 0 at large times, but the actual current is below 0. We need therefore to include an offset to take this into consideration. Close the fit window, and re-run a fit, but now with this command:
QSoas> fit-arb im/(1+km/s)+io /with=s:1,exp
Notice the +io bit that corresponds to the addition of an offset current. Load again the base parameters, run the fit again... Your fit window show now look like:
See how the offset current is now much better taken into account. Let's talk a bit more about the parameters: Taking into account mass-transport limitations However, the fit is still unsatisfactory: the predicted curve fails to reproduce the curvature at the beginning and at the end of the decrease. This is due to issues linked to mass-transport limitations, which are discussed in details in Merrouch et al, Electrochimica Acta, 2017. In short, what you need to do is to close the fit window again, load the transport.rb Ruby file that contains the definition of the itrpt function, and re-launch the fit window using:
QSoas> ruby-run transport.rb
QSoas> fit-arb itrprt(s,km,nFAm,nFAmu)+io /with=s:1,exp
Load again the parameter file... but this time you'll have to play a bit more with the starting parameters for QSoas to find the right values when you fit. Here are some tips: A successful fit should look like this:
Here you are ! I hope you enjoyed analyzing our data, and that it will help you analyze yours ! Feel free to comment and ask for clarifications.

About QSoasQSoas is a powerful open source data analysis program that focuses on flexibility and powerful fitting capacities. It is released under the GNU General Public License. It is described in Fourmond, Anal. Chem., 2016, 88 (10), pp 5050 5052. Current version is 2.2. You can download its source code or buy precompiled versions for MacOS and Windows there.

Vincent Fourmond: Define a function with inline Ruby code in QSoas

QSoas can read and execute Ruby code directly, while reading command files, or even at the command prompt. For that, just write plain Ruby code inside a ruby...ruby end block. Probably the most useful possibility is to define elaborated functions directly from within QSoas, or, preferable, from within a script; this is an alternative to defining a function in a completely separated Ruby-only file using ruby-run. For instance, you can define a function for plain Michaelis-Menten kinetics with a file containing:

ruby
def my_func(x, vm, km)
  return vm/(1 + km/x)
end
ruby end

This defines the function my_func with three parameters, , (vm) and (km), with the formula:

You can then test that the function has been correctly defined running for instance:

QSoas> eval my_func(1.0,1.0,1.0)
 => 0.5
QSoas> eval my_func(1e4,1.0,1.0)
 => 0.999900009999

This yields the correct answer: the first command evaluates the function with x = 1.0, vm = 1.0 and km = 1.0. For , the result is (here 0.5). For , the result is almost . You can use the newly defined my_func in any place you would use any ruby code, such as in the optional argument to generate-buffer, or for arbitrary fits:

QSoas> generate-buffer 0 10 my_func(x,3.0,0.6)
QSoas> fit-arb my_func(x,vm,km)

To redefine my_func, just run the ruby code again with a new definition, such as:
ruby
def my_func(x, vm, km)
  return vm/(1 + km/x**2)
end
ruby end
The previous version is just erased, and all new uses of my_func will refer to your new definition.


See for yourselfThe code for this example can be found there. Browse the qsoas-goodies github repository for more goodies !

About QSoasQSoas is a powerful open source data analysis program that focuses on flexibility and powerful fitting capacities. It is released under the GNU General Public License. It is described in Fourmond, Anal. Chem., 2016, 88 (10), pp 5050 5052. Current version is 2.1. You can download its source code or buy precompiled versions for MacOS and Windows there.

22 September 2020

Russ Allbery: Review: Unconquerable Sun

Review: Unconquerable Sun, by Kate Elliott
Series: Sun Chronicles #1
Publisher: Tor
Copyright: 2020
ISBN: 1-250-19725-2
Format: Kindle
Pages: 526
Sun is the daughter and heir of the mercurial Queen-Marshal Eirene, ruler of the Republic of Chaonia. Chaonia, thanks to Eirene and her ancestors, has carved out a fiercely independent position between the Yele League and the Phene Empire. Sun's father, Prince Jo o, is one of Eirene's three consorts, all chosen for political alliances to shore up that fragile position. Jo o is Gatoi, a civilization of feared fighters and supposed barbarians from outside Chaonia who normally ally with the Phene, which complicates Sun's position as heir. Sun attempts to compensate for that by winning battles for the Republic, following in the martial footsteps of her mother. The publisher's summary of this book is not great (I'm a huge fan of Princess Leia, but that is... not the analogy that comes to mind), so let me try to help. This is gender-swapped Alexander the Great in space. However, it is gender-swapped Alexander the Great in space with her Companions, which means the DNA of this novel is half space opera and half heist story (without, to be clear, an actual heist, although there are some heist-like maneuvers). It's also worth mentioning that Sun, like Alexander, is not heterosexual. The other critical thing to know before reading, mostly because it will get you through the rather painful start, is that the most interesting viewpoint character in this book is not Sun, the Alexander analogue. It's Persephone, who isn't introduced until chapter seven. Significant disclaimer up front: I got a reasonably typical US grade school history of Alexander the Great, which means I was taught that he succeeded his father, conquered a whole swath of the middle of the Eurasian land mass at a very young age, and then died and left his empire to his four generals who promptly divided it into four uninteresting empires that no one's ever heard of, and that's why Rome is more important than Greece. (I put in that last bit to troll one specific person.) I am therefore not the person to judge the parallels between this story and known history, or to notice any damage done to Greek pride, or to pick up on elements that might cause someone with a better grasp of that history to break out in hives. I did enough research to know that one scene in this book is lifted directly out of Alexander's life, but I'm not sure how closely the other parallels track. Yele is probably southern Greece and Phene is probably Persia, but I'm not certain even of that, and some of the details don't line up. If I had to hazard a guess, I'd say that Elliott has probably mangled history sufficiently to make it clear that this isn't intended to be a retelling, but if the historical parallels are likely to bother you, you may want to do more research before reading. What I can say is that the space opera setup, while a bit stock, has all the necessary elements to make me happy. Unconquerable Sun is firmly in the "lost Earth" tradition: The Argosy fleet fled the now-mythical Celestial Empire and founded a new starfaring civilization without any contact with their original home. Eventually, they invented (or discovered; the characters don't know) the beacons, which allow for instantaneous travel between specific systems without the long (but still faster-than-light) journeys of the knnu drive. More recently, the beacon network has partly collapsed, cutting off the characters' known world from the civilization that was responsible for the beacons and guarded their secrets. It's a fun space opera history with lots of lost knowledge to reference and possibly discover, and with plot-enabling military choke points at the surviving beacons that link multiple worlds. This is all background to the story, which is the ongoing war between Chaonia and the Phene Empire mixed with cutthroat political maneuvering between the great houses of the Chaonian Republic. This is where the heist aspects come in. Each house sends one representative to join the household of the Queen-Marshal and (more to the point for this story) another to join her heir. Sun has encouraged the individual and divergent talents of her Companions and their cee-cees (an unfortunate term that I suspect is short for Companion's Companion) and forged them into a good working team. A team that's about to be disrupted by the maneuverings of a rival house and the introduction of a new team member whom no one wants. A problem with writing tactical geniuses is that they often aren't good viewpoint characters. Sun's tight third-person chapters, which is a little less than half the book, advance the plot and provide analysis of the interpersonal dynamics of the characters, but aren't the strength of the story. That lies with the interwoven first-person sections that follow Persephone, an altogether more interesting character. Persephone is the scion of the house that is Sun's chief rival, but she has no interest in being part of that house or its maneuverings. When the story opens, she's a cadet in a military academy for recruits from the commoners, having run away from home, hidden her identity, and won a position through the open entrance exams. She of course doesn't stay there; her past catches up with her and she gets assigned to Sun, to a great deal of mutual suspicion. She also is assigned an impeccably dressed and stunningly beautiful cee-cee, Tiana, who has her own secrets and who was my favorite character in the book. Somewhat unusually for the space opera tradition, this is a book that knows that common people exist and have interesting lives. It's primarily focused on the ruling houses, but that focus is not exclusive and the rulers do not have a monopoly on competence. Elliott also avoids narrowing the political field too far; the Gatoi are separate from the three rival powers, and there are other groups with traditions older than the Chaonian Republic and their own agendas. Sun and her Companions are following a couple of political threads, but there is clearly more going on in this world than that single plot. This is exactly the kind of story I think of when I think space opera. It's not doing anything that original or groundbreaking, and it's not going to make any of my lists of great literature, but it's a fun romp with satisfyingly layered bits of lore, a large-scale setting with lots of plot potential, and (once we get through the confusing and somewhat tedious process of introducing rather too many characters in short succession) some great interpersonal dynamics. It's the kind of book in which the characters are in the middle of decisive military action in an interstellar war and are also near-teenagers competing for ratings in an ad hoc reality TV show, primarily as an excuse to create tactical distractions for Sun's latest scheme. The writing is okay but not great, and the first few chapters have some serious infodumping problems, but I thoroughly enjoyed the whole book and will pre-order the sequel. One Amazon review complained that Unconquerable Sun is not a space opera like Hyperion or Use of Weapons. That is entirely true, but if that's your standard for space opera, the world may be a disappointing place. This is a solid entry in a subgenre I love, with some great characters, sarcasm, competence porn, plenty of pages to keep turning, a few twists, and the promise of more to come. Recommended. Followed by the not-yet-published Furious Heaven. Rating: 7 out of 10

21 September 2020

Kees Cook: security things in Linux v5.7

Previously: v5.6 Linux v5.7 was released at the end of May. Here s my summary of various security things that caught my attention: arm64 kernel pointer authentication
While the ARMv8.3 CPU Pointer Authentication (PAC) feature landed for userspace already, Kristina Martsenko has now landed PAC support in kernel mode. The current implementation uses PACIASP which protects the saved stack pointer, similar to the existing CONFIG_STACKPROTECTOR feature, only faster. This also paves the way to sign and check pointers stored in the heap, as a way to defeat function pointer overwrites in those memory regions too. Since the behavior is different from the traditional stack protector, Amit Daniel Kachhap added an LKDTM test for PAC as well. BPF LSM
The kernel s Linux Security Module (LSM) API provide a way to write security modules that have traditionally implemented various Mandatory Access Control (MAC) systems like SELinux, AppArmor, etc. The LSM hooks are numerous and no one LSM uses them all, as some hooks are much more specialized (like those used by IMA, Yama, LoadPin, etc). There was not, however, any way to externally attach to these hooks (not even through a regular loadable kernel module) nor build fully dynamic security policy, until KP Singh landed the API for building LSM policy using BPF. With this, it is possible (for a privileged process) to write kernel LSM hooks in BPF, allowing for totally custom security policy (and reporting). execve() deadlock refactoring
There have been a number of long-standing races in the kernel s process launching code where ptrace could deadlock. Fixing these has been attempted several times over the last many years, but Eric W. Biederman and Ernd Edlinger decided to dive in, and successfully landed the a series of refactorings, splitting up the problematic locking and refactoring their uses to remove the deadlocks. While he was at it, Eric also extended the exec_id counter to 64 bits to avoid the possibility of the counter wrapping and allowing an attacker to send arbitrary signals to processes they normally shouldn t be able to. slub freelist obfuscation improvements
After Silvio Cesare observed some weaknesses in the implementation of CONFIG_SLAB_FREELIST_HARDENED s freelist pointer content obfuscation, I improved their bit diffusion, which makes attacks require significantly more memory content exposures to defeat the obfuscation. As part of the conversation, Vitaly Nikolenko pointed out that the freelist pointer s location made it relatively easy to target too (for either disclosures or overwrites), so I moved it away from the edge of the slab, making it harder to reach through small-sized overflows (which usually target the freelist pointer). As it turns out, there were a few assumptions in the kernel about the location of the freelist pointer, which had to also get cleaned up. RISCV page table dumping
Following v5.6 s generic page table dumping work, Zong Li landed the RISCV page dumping code. This means it s much easier to examine the kernel s page table layout when running a debug kernel (built with PTDUMP_DEBUGFS), visible in /sys/kernel/debug/kernel_page_tables. array index bounds checking
This is a pretty large area of work that touches a lot of overlapping elements (and history) in the Linux kernel. The short version is: C is bad at noticing when it uses an array index beyond the bounds of the declared array, and we need to fix that. For example, don t do this:
int foo[5];
...
foo[8] = bar;
The long version gets complicated by the evolution of flexible array structure members, so we ll pause for a moment and skim the surface of this topic. While things like CONFIG_FORTIFY_SOURCE try to catch these kinds of cases in the memcpy() and strcpy() family of functions, it doesn t catch it in open-coded array indexing, as seen in the code above. GCC has a warning (-Warray-bounds) for these cases, but it was disabled by Linus because of all the false positives seen due to fake flexible array members. Before flexible arrays were standardized, GNU C supported zero sized array members. And before that, C code would use a 1-element array. These were all designed so that some structure could be the header in front of some data blob that could be addressable through the last structure member:
/* 1-element array */
struct foo  
    ...
    char contents[1];
 ;
/* GNU C extension: 0-element array */
struct foo  
    ...
    char contents[0];
 ;
/* C standard: flexible array */
struct foo  
    ...
    char contents[];
 ;
instance = kmalloc(sizeof(struct foo) + content_size);
Converting all the zero- and one-element array members to flexible arrays is one of Gustavo A. R. Silva s goals, and hundreds of these changes started landing. Once fixed, -Warray-bounds can be re-enabled. Much more detail can be found in the kernel s deprecation docs. However, that will only catch the visible at compile time cases. For runtime checking, the Undefined Behavior Sanitizer has an option for adding runtime array bounds checking for catching things like this where the compiler cannot perform a static analysis of the index values:
int foo[5];
...
for (i = 0; i < some_argument; i++)  
    ...
    foo[i] = bar;
    ...
 
It was, however, not separate (via kernel Kconfig) until Elena Petrova and I split it out into CONFIG_UBSAN_BOUNDS, which is fast enough for production kernel use. With this enabled, it's now possible to instrument the kernel to catch these conditions, which seem to come up with some regularity in Wi-Fi and Bluetooth drivers for some reason. Since UBSAN (and the other Sanitizers) only WARN() by default, system owners need to set panic_on_warn=1 too if they want to defend against attacks targeting these kinds of flaws. Because of this, and to avoid bloating the kernel image with all the warning messages, I introduced CONFIG_UBSAN_TRAP which effectively turns these conditions into a BUG() without needing additional sysctl settings. Fixing "additive" snprintf() usage
A common idiom in C for building up strings is to use sprintf()'s return value to increment a pointer into a string, and build a string with more sprintf() calls:
/* safe if strlen(foo) + 1 < sizeof(string) */
wrote  = sprintf(string, "Foo: %s\n", foo);
/* overflows if strlen(foo) + strlen(bar) > sizeof(string) */
wrote += sprintf(string + wrote, "Bar: %s\n", bar);
/* writing way beyond the end of "string" now ... */
wrote += sprintf(string + wrote, "Baz: %s\n", baz);
The risk is that if these calls eventually walk off the end of the string buffer, it will start writing into other memory and create some bad situations. Switching these to snprintf() does not, however, make anything safer, since snprintf() returns how much it would have written:
/* safe, assuming available <= sizeof(string), and for this example
 * assume strlen(foo) < sizeof(string) */
wrote  = snprintf(string, available, "Foo: %s\n", foo);
/* if (strlen(bar) > available - wrote), this is still safe since the
 * write into "string" will be truncated, but now "wrote" has been
 * incremented by how much snprintf() *would* have written, so "wrote"
 * is now larger than "available". */
wrote += snprintf(string + wrote, available - wrote, "Bar: %s\n", bar);
/* string + wrote is beyond the end of string, and availabe - wrote wraps
 * around to a giant positive value, making the write effectively 
 * unbounded. */
wrote += snprintf(string + wrote, available - wrote, "Baz: %s\n", baz);
So while the first overflowing call would be safe, the next one would be targeting beyond the end of the array and the size calculation will have wrapped around to a giant limit. Replacing this idiom with scnprintf() solves the issue because it only reports what was actually written. To this end, Takashi Iwai has been landing a bunch scnprintf() fixes. That's it for now! Let me know if there is anything else you think I should mention here. Next up: Linux v5.8.

2020, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 4.0 License.
CC BY-SA 4.0

Russ Allbery: Review: Lower Ed

Review: Lower Ed, by Tressie McMillan Cottom
Publisher: The New Press
Copyright: 2017
Printing: 2018
ISBN: 1-62097-472-X
Format: Kindle
Pages: 217
Lower Ed (subtitled The Troubling Rise of For-Profit Colleges in the New Economy) is the first book by sociologist Tressie McMillan Cottom. (I previously reviewed her second book, the excellent essay collection Thick.) It is a deep look at the sociology of for-profit higher education in the United States based on interviews with students and executives, analysis of Wall Street filings, tests of the admissions process, and her own personal experiences working for two of the schools. One of the questions that McMillan Cottom tries to answer is why students choose to enroll in these institutions, particularly the newer type of institution funded by federal student loans and notorious for being more expensive and less valuable than non-profit colleges and universities. I was hesitant to read this book because I find for-profit schools depressing. I grew up with the ubiquitous commercials, watched the backlash develop, and have a strongly negative impression of the industry, partly influenced by having worked in traditional non-profit higher education for two decades. The prevailing opinion in my social group is that they're a con job. I was half-expecting a reinforcement of that opinion by example, and I don't like reading infuriating stories about people being defrauded. I need not have worried. This is not that sort of book (nor, in retrospect, do I think McMillan Cottom would approach a topic from that angle). Sociology is broader than reporting. Lower Ed positions for-profit colleges within a larger social structure of education, credentialing, and changes in workplace expectations; takes a deep look at why they are attractive to their students; and humanizes and complicates the motives and incentives of everyone involved, including administrators and employees of for-profit colleges as well as the students. McMillan Cottom does of course talk about the profit motive and the deceptions surrounding that, but the context is less that of fraud that people are unable to see through and more a balancing of the drawbacks of a set of poor choices embedded in institutional failures. One of my metrics for a good non-fiction book is whether it introduces me to a new idea that changes how I analyze the world. Lower Ed does that twice. The first idea is the view of higher education through the lens of risk shifting. It used to be common for employers to hire people without prior job-specific training and do the training in-house, possibly through an apprenticeship structure. More notably, once one was employed by a particular company, the company routinely arranged or provided ongoing training. This went hand-in-hand with a workplace culture of long tenure, internal promotion, attempts to avoid layoffs, and some degree of mutual loyalty. Companies expected to invest significantly in an employee over their career and thus also had an incentive to retain that employee rather than train someone for a competitor. However, from a purely financial perspective, this is a risk and an inefficiency, similar to the risk of carrying a large inventory of parts and components. Companies have responded to investor-driven focus on profits and efficiency by reducing overhead and shifting risk. This leads to the lean supply chain, where no one pays for parts to sit around in warehouses and companies aren't caught with large stockpiles of now-useless components, but which is more sensitive to any disruption (such as from a global pandemic). And, for employment, it leads to a desire to hire pre-trained workers, retain only enough workers to do the current amount of work, and replace them with new workers who already have appropriate training rather than retrain them. The effect of the corporate decision to only hire pre-trained employees is to shift the risk and expense of training from the company to the prospective employee. The individual has to seek out training at their own expense in the hope (not guarantee) that at the conclusion of that training they will get or retain a job. People therefore turn to higher education to both provide that training and to help them decide what type of training will eventually be valuable. This has a long history with certain professional fields (doctors and lawyers, for example), but the requirements for completing training in those fields are relatively clear (a professional license to practice) and the compensation reflects the risk. What's new is the shift of training risk to the individual in more mundane jobs, without any corresponding increase in compensation. This, McMillan Cottom explains, is the background for the growth in demand for higher education in general and the the type of education offered by for-profit colleges in particular. Workers who in previous eras would be trained by their employers are now responsible for their own training. That training is no longer judged by the standards of a specific workplace, but is instead evaluated by a hiring process that expects constant job-shifting. This leads to increased demand by both workers and employers for credentials: some simple-to-check certificate of completion of training that says that this person has the skills to immediately start doing some job. It also leads to a demand for more flexible class hours, since the student is now often someone older with a job and a family to balance. Their ongoing training used to be considered a cost of business and happen during their work hours; now it is something they have to fit around the contours of their life because their employer has shifted that risk to them. The risk-shifting frame makes sense of the "investment" language so common in for-profit education. In this job economy, education as investment is not a weird metaphor for the classic benefits of a liberal arts education: broadened perspective, deeper grounding in philosophy and ethics, or heightened aesthetic appreciation. It's an investment in the literal financial sense; it is money that you spend now in order to get a financial benefit (a job) in the future. People have to invest in their own training because employers are no longer doing so, but still require the outcome of that investment. And, worse, it's primarily a station-keeping investment. Rather than an optional expenditure that could reap greater benefits later, it's a mandatory expenditure to prevent, at best, stagnation in a job paying poverty wages, and at worst the disaster of unemployment. This explains renewed demand for higher education, but why for-profit colleges? We know they cost more and have a worse reputation (and therefore their credentials have less value) than traditional non-profit colleges. Flexible hours and class scheduling explains some of this but not all of it. That leads to the second perspective-shifting idea I got from Lower Ed: for-profit colleges are very good at what they focus time and resources on, and they focus on enrolling students. It is hard to enroll in a university! More precisely, enrolling in a university requires bureaucracy navigation skills, and those skills are class-coded. The people who need them the most are the least likely to have them. Universities do not reach out to you, nor do they guide you through the process. You have to go to them and discover how to apply, something that is often made harder by the confusing state of many university web sites. The language and process is opaque unless other people in your family have experience with universities and can explain it. There might be someone you can reach on the phone to ask questions, but they're highly unlikely to proactively guide you through the remaining steps. It's your responsibility to understand deadlines, timing, and sequence of operations, and if you miss any of the steps (due to, for example, the overscheduled life of someone in need of better education for better job prospects), the penalty in time and sometimes money can be substantial. And admission is just the start; navigating financial aid, which most students will need, is an order of magnitude more daunting. Community colleges are somewhat easier (and certainly cheaper) than universities, but still have similar obstacles (and often even worse web sites). It's easy for people like me, who have long professional expertise with bureaucracies, family experience with higher education, and a support network of people to nag me about deadlines, to underestimate this. But the application experience at a for-profit college is entirely different in ways far more profound than I had realized. McMillan Cottom documents this in detail from her own experience working for two different for-profit colleges and from an experiment where she indicated interest in multiple for-profit colleges and then stopped responding before signing admission paperwork. A for-profit college is fully invested in helping a student both apply and get financial aid, devotes someone to helping them through that process, does not expect them to understand how to navigate bureaucracies or decipher forms on their own, does not punish unexpected delays or missed appointments, and goes to considerable lengths to try to keep anyone from falling out of the process before they are enrolled. They do not expect their students to already have the skills that one learns from working in white-collar jobs or from being surrounded by people who do. They provide the kind of support that an educational institution should provide to people who, by definition, don't understand something and need to learn. Reading about this was infuriating. Obviously, this effort to help people enroll is largely for predatory reasons. For-profit schools make their money off federal loans and they don't get that money unless they can get someone to enroll and fill out financial paperwork (and to some extent keep them enrolled), so admissions is their cash cow and they act accordingly. But that's not why I found it infuriating; that's just predictable capitalism. What I think is inexcusable is that nothing they do is that difficult. We could being doing the same thing for prospective community college students but have made the societal choice not to. We believe that education is valuable, we constantly advocate that people get more job training and higher education, and yet we demand prospective students navigate an unnecessarily baroque and confusing application process with very little help, and then stereotype and blame them for failing to do so. This admission support is not a question of resources. For-profit colleges are funded almost entirely by federally-guaranteed student loans. We are paying them to help people apply. It is, in McMillan Cottom's term, a negative social insurance program. Rather than buffering people against the negative effects of risk-shifting of employers by helping them into the least-expensive and most-effective training programs (non-profit community colleges and universities), we are spending tax dollars to enrich the shareholders of for-profit colleges while underfunding the alternatives. We are choosing to create a gap that routes government support to the institution that provides worse training at higher cost but is very good at helping people apply. It's as if the unemployment system required one to use payday lenders to get one's unemployment check. There is more in this book I want to talk about, but this review is already long enough. Suffice it to say that McMillan Cottom's analysis does not stop with market forces and the admission process, and the parts of her analysis that touch on my own personal experience as someone with a somewhat unusual college path ring very true. Speaking as a former community college student, the discussion of class credit transfer policies and the way that institutional prestige gatekeeping and the desire to push back against low-quality instruction becomes a trap that keeps students in the for-profit system deserves another review this length. So do the implications of risk-shifting and credentialism on the morality of "cheating" on schoolwork. As one would expect from the author of the essay "Thick" about bringing context to sociology, Lower Ed is personal and grounded. McMillan Cottom doesn't shy away from including her own experiences and being explicit about her sources and research. This is backed up by one of the best methodological notes sections I've seen in a book. One of the things I love about McMillan Cottom's writing is that it's solidly academic, not in the sense of being opaque or full of jargon (the text can be a bit dense, but I rarely found it hard to follow), but in the sense of being clear about the sources of knowledge and her methods of extrapolation and analysis. She brings her receipts in a refreshingly concrete way. I do have a few caveats. First, I had trouble following a structure and line of reasoning through the whole book. Each individual point is meticulously argued and supported, but they are not always organized into a clear progression or framework. That made Lower Ed feel at times like a collection of high-quality but somewhat unrelated observations about credentials, higher education, for-profit colleges, their student populations, their business models, and their relationships with non-profit schools. Second, there are some related topics that McMillan Cottom touches on but doesn't expand sufficiently for me to be certain I understood them. One of the big ones is credentialism. This is apparently a hot topic in sociology and is obviously important to this book, but it's referenced somewhat glancingly and was not satisfyingly defined (at least for me). There are a few similar places where I almost but didn't quite follow a line of reasoning because the book structure didn't lay enough foundation. Caveats aside, though, this was meaty, thought-provoking, and eye-opening, and I'm very glad that I read it. This is a topic that I care more about than most people, but if you have watched for-profit colleges with distaste but without deep understanding, I highly recommend Lower Ed. Rating: 8 out of 10

20 September 2020

Dirk Eddelbuettel: RcppSpdlog 0.0.2: New upstream, awesome new stopwatch

Following up on the initial RcppSpdlog 0.0.1 release earlier this week, we are pumped to announce release 0.0.2. It contains upstream version 1.8.0 for spdlog which utilizes (among other things) a new feature in the embedded fmt library, namely completely automated formatting of high resolution time stamps which allows for gems like this (taken from this file in the package and edited down for brevity):
    spdlog::stopwatch sw;                                   // instantiate a stop watch

    // some other code

    sp->info("Elapsed time:  ", sw);
What we see is all there is: One instantiates a stopwatch object, and simply references it. The rest, as they say, is magic. And we get tic / toc alike behaviour in modern C++ at essentially no cost us (as code authors). So nice. Output from the (included in the package) function exampleRsink() (again edited down just a little):
R> RcppSpdlog::exampleRsink()
[13:03:23.845114] [fromR] [I] [thread 793264] Welcome to spdlog!
[...]
[13:03:23.845205] [fromR] [I] [thread 793264] Elapsed time: 0.000103611
[...]
[13:03:23.845281] [fromR] [I] [thread 793264] Elapsed time: 0.00018203
R> 
We see that the two simple logging instances come 10 and 18 microseconds into the call. RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovic. The NEWS entry for this release follows.

Changes in RcppSpdlog version 0.0.2 (2020-09-17)
  • Upgraded to upstream release 1.8.0
  • Switched Travis CI to using BSPM, also test on macOS
  • Added 'stopwatch' use to main R sink example

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppSpdlog page. The only sour grapes, again, are once more over the CRAN processing. And just how 0.0.1 was delayed for no good reason for three weeks, 0.0.2 was delayed by three days just because well that is how CRAN rules sometimes. I d be even more mad if I had an alternative but I don t. We remain grateful for all they do but they really could have let this one through even at one-day update delta. Ah well, now we re three days wiser and of course nothing changed in the package. If you like this or other open-source work I do, you can now sponsor me at GitHub. For the first year, GitHub will match your contributions.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Andy Simpkins: Using an IP camera in conference calls

My webcam has broken, something that I have been using a lot during the last few months for some reason. A friend of mine suggested that I use the mic and camera on my mobile phone instead. There is a simple app droidcam that makes the phone behave as a simple webcam, it also has a client application to run on your PC to capture the web-stream and present it as a video device. All well and good but I would like to keep propitiatory software off my PCs (I have a hard enough time accepting it on a phone but I have to draw a line somewhere). I decided that there had to be a simple way to ingest that stream and present it as a local video device on a Linux box. It turns out that it is a lot simpler than I thought it would be. I had it working within 10 minutes! Packages needed: ffmpeg, v4l2loopback-utils
sudo apt-get install ffmpeg v4l2loopback-utils
Start the loop-back device:
sudo modprobe v4l2loopback
Ingest video and present on loop-back device:
ffmpeg -re -i <URL_VideoStream> -vcodec rawvideo -pix_fmt yuv420p -f v4l2 /dev/video0
Where

-re
Read input at native frame rate. Mainly used to simulate a grab
device, or live input stream (e.g. when reading from a file). Should
not be used with actual grab devices or live input streams (where it
can cause packet loss). By default ffmpeg attempts to read the
input(s) as fast as possible. This option will slow down the reading
of the input(s) to the native frame rate of the input(s). It is
useful for real-time output (e.g. live streaming).
-i <source>
In this case my phone running droidcam http://10.14.1.100:4747/video
-vcodec rawvideo
Select the output video codec to raw video (as expected for /dev/video#)
-pix_fmt yuv420p
Set pixel format. in this example tell ffmpeg that the video will
be yuv colour space at 420p resolution
-f v4l2 /dev/video0
Force the output to be in video for Linux 2 (v4l2) format bound to
device /dev/video0

19 September 2020

Vincent Bernat: Syncing NetBox with a custom Ansible module

The netbox.netbox collection from Ansible Galaxy provides several modules to update NetBox objects:
- name: create a device in NetBox
  netbox_device:
    netbox_url: http://netbox.local
    netbox_token: s3cret
    data:
      name: to3-p14.sfo1.example.com
      device_type: QFX5110-48S
      device_role: Compute Switch
      site: SFO1
However, if NetBox is not your source of truth, you may want to ensure it stays in sync with your configuration management database1 by removing outdated devices or IP addresses. While it should be possible to glue together a playbook with a query, a loop and some filtering to delete unwanted elements, it feels clunky, inefficient and an abuse of YAML as a programming language. A specific Ansible module solves this issue and is likely more flexible.

Notice I recommend that you read Writing a custom Ansible module as an introduction, as well as Syncing MySQL tables for a first simpler example.

Code The module has the following signature and it syncs NetBox with the content of the provided YAML file:
netbox_sync:
  source: netbox.yaml
  api: https://netbox.example.com
  token: s3cret
The synchronized objects are:
  • sites,
  • manufacturers,
  • device types,
  • device roles,
  • devices, and
  • IP addresses.
In our environment, the YAML file is generated from our configuration management database and contains a set of devices and a list of IP addresses:
devices:
  ad2-p6.sfo1.example.com:
     datacenter: sfo1
     manufacturer: Cisco
     model: Catalyst 2960G-48TC-L
     role: net_tor_oob_switch
  to1-p6.sfo1.example.com:
     datacenter: sfo1
     manufacturer: Juniper
     model: QFX5110-48S
     role: net_tor_gpu_switch
# [ ]
ips:
  - device: ad2-p6.example.com
    ip: 172.31.115.18/21
    interface: oob
  - device: to1-p6.example.com
    ip: 172.31.115.33/21
    interface: oob
  - device: to1-p6.example.com
    ip: 172.31.254.33/32
    interface: lo0.0
# [ ]
The network team is not the sole tenant in NetBox. While adding new objects or modifying existing ones should be relatively safe, deleting unwanted objects can be risky. The module only deletes objects it did create or modify. To identify them, it marks them with a specific tag, cmdb. Most objects in NetBox accept tags.

Module definition Starting from the skeleton described in the previous article, we define the module:
module_args = dict(
    source=dict(type='path', required=True),
    api=dict(type='str', required=True),
    token=dict(type='str', required=True, no_log=True),
    max_workers=dict(type='int', required=False, default=10)
)
result = dict(
    changed=False
)
module = AnsibleModule(
    argument_spec=module_args,
    supports_check_mode=True
)
It contains an additional optional arguments defining the number of workers to talk to NetBox and query the existing objects in parallel to speedup the execution.

Abstracting synchronization We need to synchronize different object types, but once we have a list of objects we want in NetBox, the grunt work is always the same:
  • check if the objects already exist,
  • retrieve them and put them in a form suitable for comparison,
  • retrieve the extra objects we don t want anymore,
  • compare the two sets, and
  • add missing objects, update existing ones, delete extra ones.
We code these behaviours into a Synchronizer abstract class. For each kind of object, a concrete class is built with the appropriate class attributes to tune its behaviour and a wanted() method to provide the objects we want. I am not explaining the abstract class code here. Have a look at the source if you want.

Synchronizing tags and tenants As a starter, here is how we define the class synchronizing the tags:
class SyncTags(Synchronizer):
    app = "extras"
    table = "tags"
    key = "name"
    def wanted(self):
        return  "cmdb": dict(
            slug="cmdb",
            color="8bc34a",
            description="synced by network CMDB") 
The app and table attributes defines the NetBox objects we want to manipulate. The key attribute is used to determine how to lookup for existing objects. In this example, we want to lookup tags using their names. The wanted() method is expected to return a dictionary mapping object keys to the list of wanted attributes. Here, the keys are tag names and we create only one tag, cmdb, with the provided slug, color and description. This is the tag we will use to mark the objects we create or modify. If the tag does not exist, it is created. If it exists, the provided attributes are updated. Other attributes are left untouched. We also want to create a specific tenant for objects accepting such an attribute (devices and IP addresses):
class SyncTenants(Synchronizer):
    app = "tenancy"
    table = "tenants"
    key = "name"
    def wanted(self):
        return  "Network": dict(slug="network",
                                description="Network team") 

Synchronizing sites We also need to synchronize the list of sites. This time, the wanted() method uses the information provided in the YAML file: it walks the devices and builds a set of datacenter names.
class SyncSites(Synchronizer):
    app = "dcim"
    table = "sites"
    key = "name"
    only_on_create = ("status", "slug")
    def wanted(self):
        result = set(details["datacenter"]
                     for details in self.source['devices'].values()
                     if "datacenter" in details)
        return  k: dict(slug=k,
                        status="planned")
                for k in result 
Thanks to the use of the only_on_create attribute, the specified attributes are not updated if they are different. The goal of this synchronizer is mostly to collect the references to the different sites for other objects.
>>> pprint(SyncSites(**sync_args).wanted())
 'sfo1':  'slug': 'sfo1', 'status': 'planned' ,
 'chi1':  'slug': 'chi1', 'status': 'planned' ,
 'nyc1':  'slug': 'nyc1', 'status': 'planned' 

Synchronizing manufacturers, device types and device roles The synchronization of manufacturers is pretty similar, except we do not use the only_on_create attribute:
class SyncManufacturers(Synchronizer):
    app = "dcim"
    table = "manufacturers"
    key = "name"
    def wanted(self):
        result = set(details["manufacturer"]
                     for details in self.source['devices'].values()
                     if "manufacturer" in details)
        return  k:  "slug": slugify(k) 
                for k in result 
Regarding the device types, we use the foreign attribute linking a NetBox attribute to the synchronizer handling it.
class SyncDeviceTypes(Synchronizer):
    app = "dcim"
    table = "device_types"
    key = "model"
    foreign =  "manufacturer": SyncManufacturers 
    def wanted(self):
        result = set((details["manufacturer"], details["model"])
                     for details in self.source['devices'].values()
                     if "model" in details)
        return  k[1]: dict(manufacturer=k[0],
                           slug=slugify(k[1]))
                for k in result 
The wanted() method refers to the manufacturer using its key attribute. In this case, this is the manufacturer name.
>>> pprint(SyncManufacturers(**sync_args).wanted())
 'Cisco':  'slug': 'cisco' ,
 'Dell':  'slug': 'dell' ,
 'Juniper':  'slug': 'juniper' 
>>> pprint(SyncDeviceTypes(**sync_args).wanted())
 'ASR 9001':  'manufacturer': 'Cisco', 'slug': 'asr-9001' ,
 'Catalyst 2960G-48TC-L':  'manufacturer': 'Cisco',
                           'slug': 'catalyst-2960g-48tc-l' ,
 'MX10003':  'manufacturer': 'Juniper', 'slug': 'mx10003' ,
 'QFX10002-36Q':  'manufacturer': 'Juniper', 'slug': 'qfx10002-36q' ,
 'QFX10002-72Q':  'manufacturer': 'Juniper', 'slug': 'qfx10002-72q' ,
 'QFX5110-32Q':  'manufacturer': 'Juniper', 'slug': 'qfx5110-32q' ,
 'QFX5110-48S':  'manufacturer': 'Juniper', 'slug': 'qfx5110-48s' ,
 'QFX5200-32C':  'manufacturer': 'Juniper', 'slug': 'qfx5200-32c' ,
 'S4048-ON':  'manufacturer': 'Dell', 'slug': 's4048-on' ,
 'S6010-ON':  'manufacturer': 'Dell', 'slug': 's6010-on' 
The device roles are defined like this:
class SyncDeviceRoles(Synchronizer):
    app = "dcim"
    table = "device_roles"
    key = "name"
    def wanted(self):
        result = set(details["role"]
                     for details in self.source['devices'].values()
                     if "role" in details)
        return  k: dict(slug=slugify(k),
                        color="8bc34a")
                for k in result 

Synchronizing devices A device is mostly a name with references to a role, a model, a datacenter and a tenant. These references are declared as foreign keys using the synchronizers defined previously.
class SyncDevices(Synchronizer):
    app = "dcim"
    table = "devices"
    key = "name"
    foreign =  "device_role": SyncDeviceRoles,
               "device_type": SyncDeviceTypes,
               "site": SyncSites,
               "tenant": SyncTenants 
    remove_unused = 10
    def wanted(self):
        return  name: dict(device_role=details["role"],
                           device_type=details["model"],
                           site=details["datacenter"],
                           tenant="Network")
                for name, details in self.source['devices'].items()
                if  "datacenter", "model", "role"  <= set(details.keys()) 
The remove_unused attribute is a safety implemented to fail if we have to delete more than 10 devices: this may be the indication there is a bug somewhere, unless one of your datacenter suddenly caught fire.
>>> pprint(SyncDevices(**sync_args).wanted())
 'ad2-p6.sfo1.example.com':  'device_role': 'net_tor_oob_switch',
                             'device_type': 'Catalyst 2960G-48TC-L',
                             'site': 'sfo1',
                             'tenant': 'Network' ,
 'to1-p6.sfo1.example.com':  'device_role': 'net_tor_gpu_switch',
                             'device_type': 'QFX5110-48S',
                             'site': 'sfo1',
                             'tenant': 'Network' ,
[ ]

Synchronizing IP addresses The last step is to synchronize IP addresses. We do not attach them to a device.2 Instead, we specify the device names in the description of the IP address:
class SyncIPs(Synchronizer):
    app = "ipam"
    table = "ip-addresses"
    key = "address"
    foreign =  "tenant": SyncTenants 
    remove_unused = 1000
    def wanted(self):
        wanted =  
        for details in self.source['ips']:
            if details['ip'] in wanted:
                wanted[details['ip']]['description'] = \
                    f" details['device']  (and others)"
            else:
                wanted[details['ip']] = dict(
                    tenant="Network",
                    status="active",
                    dns_name="",        # information is present in DNS
                    description=f" details['device'] :  details['interface'] ",
                    role=None,
                    vrf=None)
        return wanted
There is a slight difficulty: NetBox allows duplicate IP addresses, so a simple lookup is not enough. In case of multiple matches, we choose the best by preferring those tagged with cmdb, then those already attached to an interface:
def get(self, key):
    """Grab IP address from NetBox."""
    # There may be duplicate. We need to grab the "best".
    results = super(Synchronizer, self).get(key)
    if len(results) == 0:
        return None
    if len(results) == 1:
        return results[0]
    scores = [0]*len(results)
    for idx, result in enumerate(results):
        if "cmdb" in result.tags:
            scores[idx] += 10
        if result.interface is not None:
            scores[idx] += 5
    return sorted(zip(scores, results),
                  reverse=True, key=lambda k: k[0])[0][1]

Getting the current and wanted states Each synchronizer is initialized with a reference to the Ansible module, a reference to a pynetbox s API object, the data contained in the provided YAML file and two empty dictionaries for the current and expected states:
source = yaml.safe_load(open(module.params['source']))
netbox = pynetbox.api(module.params['api'],
                      token=module.params['token'])
sync_args = dict(
    module=module,
    netbox=netbox,
    source=source,
    before= ,
    after= 
)
synchronizers = [synchronizer(**sync_args) for synchronizer in [
    SyncTags,
    SyncTenants,
    SyncSites,
    SyncManufacturers,
    SyncDeviceTypes,
    SyncDeviceRoles,
    SyncDevices,
    SyncIPs
]]
Each synchronizer has a prepare() method whose goal is to compute the current and wanted states. It returns True in case of a difference:
# Check what needs to be synchronized
try:
    for synchronizer in synchronizers:
        result['changed']  = synchronizer.prepare()
except AnsibleError as e:
    result['msg'] = e.message
    module.fail_json(**result)

Applying changes Back to the skeleton described in the previous article, the last step is to apply the changes if there is a difference between these states. Each synchronizer registers the current and wanted states in sync_args["before"][table] and sync_args["after"][table] where table is the name of the table for a given NetBox object type. The diff object is a bit elaborate as it is built table by table. This enables Ansible to display the name of each table before the diff representation:
# Compute the diff
if module._diff and result['changed']:
    result['diff'] = [
        dict(
            before_header=table,
            after_header=table,
            before=yaml.safe_dump(sync_args["before"][table]),
            after=yaml.safe_dump(sync_args["after"][table]))
        for table in sync_args["after"]
        if sync_args["before"][table] != sync_args["after"][table]
    ]
# Stop here if check mode is enabled or if no change
if module.check_mode or not result['changed']:
    module.exit_json(**result)
Each synchronizer also exposes a synchronize() method to apply changes and a cleanup() method to delete unwanted objects. Order is important due to the relation between the objects.
# Synchronize
for synchronizer in synchronizers:
    synchronizer.synchronize()
for synchronizer in synchronizers[::-1]:
    synchronizer.cleanup()
module.exit_json(**result)

The complete code is available on GitHub. Compared to using netbox.netbox collection, the logic is written in Python instead of trying to glue Ansible tasks together. I believe this is both more flexible and easier to read, notably when trying to delete outdated objects. While I did not test it, it should also be faster. An alternative would have been to reuse code from the netbox.netbox collection, as it contains similar primitives. Unfortunately, I didn t think of it until now.

  1. In my opinion, a good option for a source of truth is to use YAML files in a Git repository. You get versioning for free and people can get started with a text editor.
  2. This limitation is mostly due to laziness: we do not really care about this information. Our main motivation for putting IP addresses in NetBox is to keep track of the used IP addresses. However, if an IP address is already attached to an interface, we leave this association untouched.

Russell Coker: Burning Lithium Ion Batteries

I had an old Nexus 4 phone that was expanding and decided to test some of the theories about battery combustion. The first claim that often gets made is that if the plastic seal on the outside of the battery is broken then the battery will catch fire. I tested this by cutting the battery with a craft knife. With every cut the battery sparked a bit and then when I levered up layers of the battery (it seems to be multiple flat layers of copper and black stuff inside the battery) there were more sparks. The battery warmed up, it s plausible that in a confined environment that could get hot enough to set something on fire. But when the battery was resting on a brick in my backyard that wasn t going to happen. The next claim is that a Li-Ion battery fire will be increased with water. The first thing to note is that Li-Ion batteries don t contain Lithium metal (the Lithium high power non-rechargeable batteries do). Lithium metal will seriously go off it exposed to water. But lots of other Lithium compounds will also react vigorously with water (like Lithium oxide for example). After cutting through most of the center of the battery I dripped some water in it. The water boiled vigorously and the corners of the battery (which were furthest away from the area I cut) felt warmer than they did before adding water. It seems that significant amounts of energy are released when water reacts with whatever is inside the Li-Ion battery. The reaction was probably giving off hydrogen gas but didn t appear to generate enough heat to ignite hydrogen (which is when things would really get exciting). Presumably if a battery was cut in the presence of water while in an enclosed space that traps hydrogen then the sparks generated by the battery reacting with air could ignite hydrogen generated from the water and give an exciting result. It seems that a CO2 fire extinguisher would be best for a phone/tablet/laptop fire as that removes oxygen and cools it down. If that isn t available then a significant quantity of water will do the job, water won t stop the reaction (it can prolong it), but it can keep the reaction to below 100C which means it won t burn a hole in the floor and the range of toxic chemicals released will be reduced. The rumour that a phone fire on a plane could do a China syndrome type thing and melt through the Aluminium body of the plane seems utterly bogus. I gave it a good try and was unable to get a battery to burn through it s plastic and metal foil case. A spare battery for a laptop in checked luggage could be a major problem for a plane if it ignited. But a battery in the passenger area seems unlikely to be a big problem if plenty of water is dumped on it to prevent the plastic case from burning and polluting the air. I was not able to get a result that was even worthy of a photograph. I may do further tests with laptop batteries.

Jelmer Vernooij: Debian Janitor: Expanding Into Improving Multi-Arch

The Debian Janitor is an automated system that commits fixes for (minor) issues in Debian packages that can be fixed by software. It gradually started proposing merges in early December. The first set of changes sent out ran lintian-brush on sid packages maintained in Git. This post is part of a series about the progress of the Janitor. As of dpkg 1.16.2 and apt 0.8.13, Debian has full support for multi-arch. To quote from the multi-arch implementation page:

Multiarch lets you install library packages from multiple architectures on the same machine. This is useful in various ways, but the most common is installing both 64 and 32- bit software on the same machine and having dependencies correctly resolved automatically. In general you can have libraries of more than one architecture installed together and applications from one architecture or another installed as alternatives.
The Multi-Arch specification describes a new Multi-Arch header which can be used to indicate how to resolve cross-architecture dependencies. The existing Debian Multi-Arch hinter is a version of dedup.debian.net that compares binary packages between architectures and suggests fixes to resolve multi-arch problems. It provides hints as to what Multi- Arch fields can be set, allowing the packages to be safely installed in a Multi-Arch world. The full list of almost 10,000 hints generated by the hinter is available at https://dedup.debian.net/static/multiarch-hints.yaml. Recent versions of lintian-brush now include a command called apply-multiarch-hints that downloads and locally caches the hints and can apply them to a package maintained in Git. For example, to apply multi-arch hints to autosize.js:
 $ debcheckout autosize.js
 declared git repository at https://salsa.debian.org/js-team/autosize.js.git
 git clone https://salsa.debian.org/js-team/autosize.js.git autosize.js ...
 Cloning into 'autosize.js'...
 [...]
 $ cd autosize.js
 $ apply-multiarch-hints
 Downloading new version of multi-arch hints.
 libjs-autosize: Add Multi-Arch: foreign.
 node-autosize: Add Multi-Arch: foreign.
 $ git log -p
 commit 3f8d1db5af4a87e6ebb08f46ddf79f6adf4e95ae (HEAD -> master)
 Author: Jelmer Vernoo  <jelmer@debian.org>
 Date:   Fri Sep 18 23:37:14 2020 +0000
     Apply multi-arch hints.
     + libjs-autosize, node-autosize: Add Multi-Arch: foreign.
     Changes-By: apply-multiarch-hints
 diff --git a/debian/changelog b/debian/changelog
 index e7fa120..09af4a7 100644
 --- a/debian/changelog
 +++ b/debian/changelog
 @@ -1,3 +1,10 @@
 +autosize.js (4.0.2~dfsg1-5) UNRELEASED; urgency=medium
 +
 +  * Apply multi-arch hints.
 +    + libjs-autosize, node-autosize: Add Multi-Arch: foreign.
 +
 + -- Jelmer Vernoo  <jelmer@debian.org>  Fri, 18 Sep 2020 23:37:14 -0000
 +
  autosize.js (4.0.2~dfsg1-4) unstable; urgency=medium
    * Team upload
 diff --git a/debian/control b/debian/control
 index 01ca968..fbba1ae 100644
 --- a/debian/control
 +++ b/debian/control
 @@ -20,6 +20,7 @@ Architecture: all
  Depends: $ misc:Depends 
  Recommends: javascript-common
  Breaks: ruby-rails-assets-autosize (<< 4.0)
 +Multi-Arch: foreign
  Description: script to automatically adjust textarea height to fit text - NodeJS
   Autosize is a small, stand-alone script to automatically adjust textarea
   height to fit text. The autosize function accepts a single textarea element,
 @@ -32,6 +33,7 @@ Package: node-autosize
  Architecture: all
  Depends: $ misc:Depends 
   , nodejs
 +Multi-Arch: foreign
  Description: script to automatically adjust textarea height to fit text - Javascript
   Autosize is a small, stand-alone script to automatically adjust textarea
   height to fit text. The autosize function accepts a single textarea element,
The Debian Janitor also has a new multiarch-fixes suite that runs apply-multiarch-hints across packages in the archive and proposes merge requests. For example, you can see the merge request against autosize.js here.

For more information about the Janitor's lintian-fixes efforts, see the landing page.

Next.

Previous.