Search Results: "ag"

2 February 2025

Bits from Debian: Bits from the DPL

Dear Debian community, this is bits from DPL for January. Sovereign Tech Agency I was recently pointed to Technologies and Projects supported by the Sovereign Tech Agency which is financed by the German Federal Ministry for Economic Affairs and Climate Action. It is a subsidiary of the Federal Agency for Disruptive Innovation, SPRIND GmbH. It is worth sending applications there for distinct projects as that is their preferred method of funding. Distinguished developers can also apply for a fellowship position that pays up to 40hrs / week (32hrs when freelancing) for a year. This is esp. open to maintainers of larger numbers of packages in Debian (or any other Linux distribution). There might be a chance that some of the Debian-related projects submitted to the Google Summer of Code that did not get funded could be retried with those foundations. As per the FAQ of the project: "The Sovereign Tech Agency focuses on securing and strengthening open and foundational digital technologies. These communities working on these are distributed all around the world, so we work with people, companies, and FOSS communities everywhere." Similar funding organizations include the Open Technology Fund and FLOSS/fund. If you have a Debian-related project that fits these funding programs, they might be interesting options. This list is by no means exhaustive just some hints I ve received and wanted to share. More suggestions for such opportunities are welcome. Year of code reviews On the debian-devel mailing list, there was a long thread titled "Let's make 2025 a year when code reviews became common in Debian". It initially suggested something along the lines of: "Let's review MRs in Salsa." The discussion quickly expanded to include patches that have been sitting in the BTS for years, which deserve at least the same attention. One idea I'd like to emphasize is that associating BTS bugs with MRs could be very convenient. It s not only helpful for documentation but also the easiest way to apply patches. I d like to emphasize that no matter what workflow we use BTS, MRs, or a mix it is crucial to uphold Debian s reputation for high quality. However, this reputation is at risk as more and more old issues accumulate. While Debian is known for its technical excellence, long-standing bugs and orphaned packages remain a challenge. If we don t address these, we risk weakening the high standards that Debian is valued for. Revisiting old issues and ensuring that unmaintained packages receive attention is especially important as we prepare for the Trixie release. Debian Publicity Team will no longer post on X/Twitter The Press Team has my full support in its decision to stop posting on X. As per the Publicity delegation: the team once decided to join Twitter, but circumstances have since changed. The current Press delegates have the institutional authority to leave X, just as their predecessors had the authority to join. I appreciate that the team carefully considered the matter, reinforced by the arguments developed on the debian-publicity list, and communicated its reasoning openly. Kind regards, Andreas.

Dirk Eddelbuettel: RcppUUID 1.1.2 on CRAN: Newly Adopted Package

The RcppUUID package on CRAN has been providing UUIDs (based on the underlying Boost library) for several years. Written by Artem Klemsov and maintained in this gitlab repo, the package is a very nice example of clean and straightforward library binding. When we did our annual BH upgrade to 1.87.0 and check reverse dependencies, we noticed the RcppUUID needed a small and rather minor update which we showed as a short diff in an issue filed. Neither I nor CRAN heard from Artem, so the packaged ended up being archived last week. Which in turn lead me to make this minimal update to 1.1.2 to resurrect it, which CRAN processed more or less like a regular update given this explanation and so it arrived last Friday. Courtesy of my CRANberries, there is also a a new package note (no diffstat report yet). More detailed information is on the RcppUUID page, or the github repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Dave Hibberd: SOTA Trip Reports: Feb 02, 2025 - Bennachie

This was originally posted on SOTA Forums. It s here for completeness of my writing.
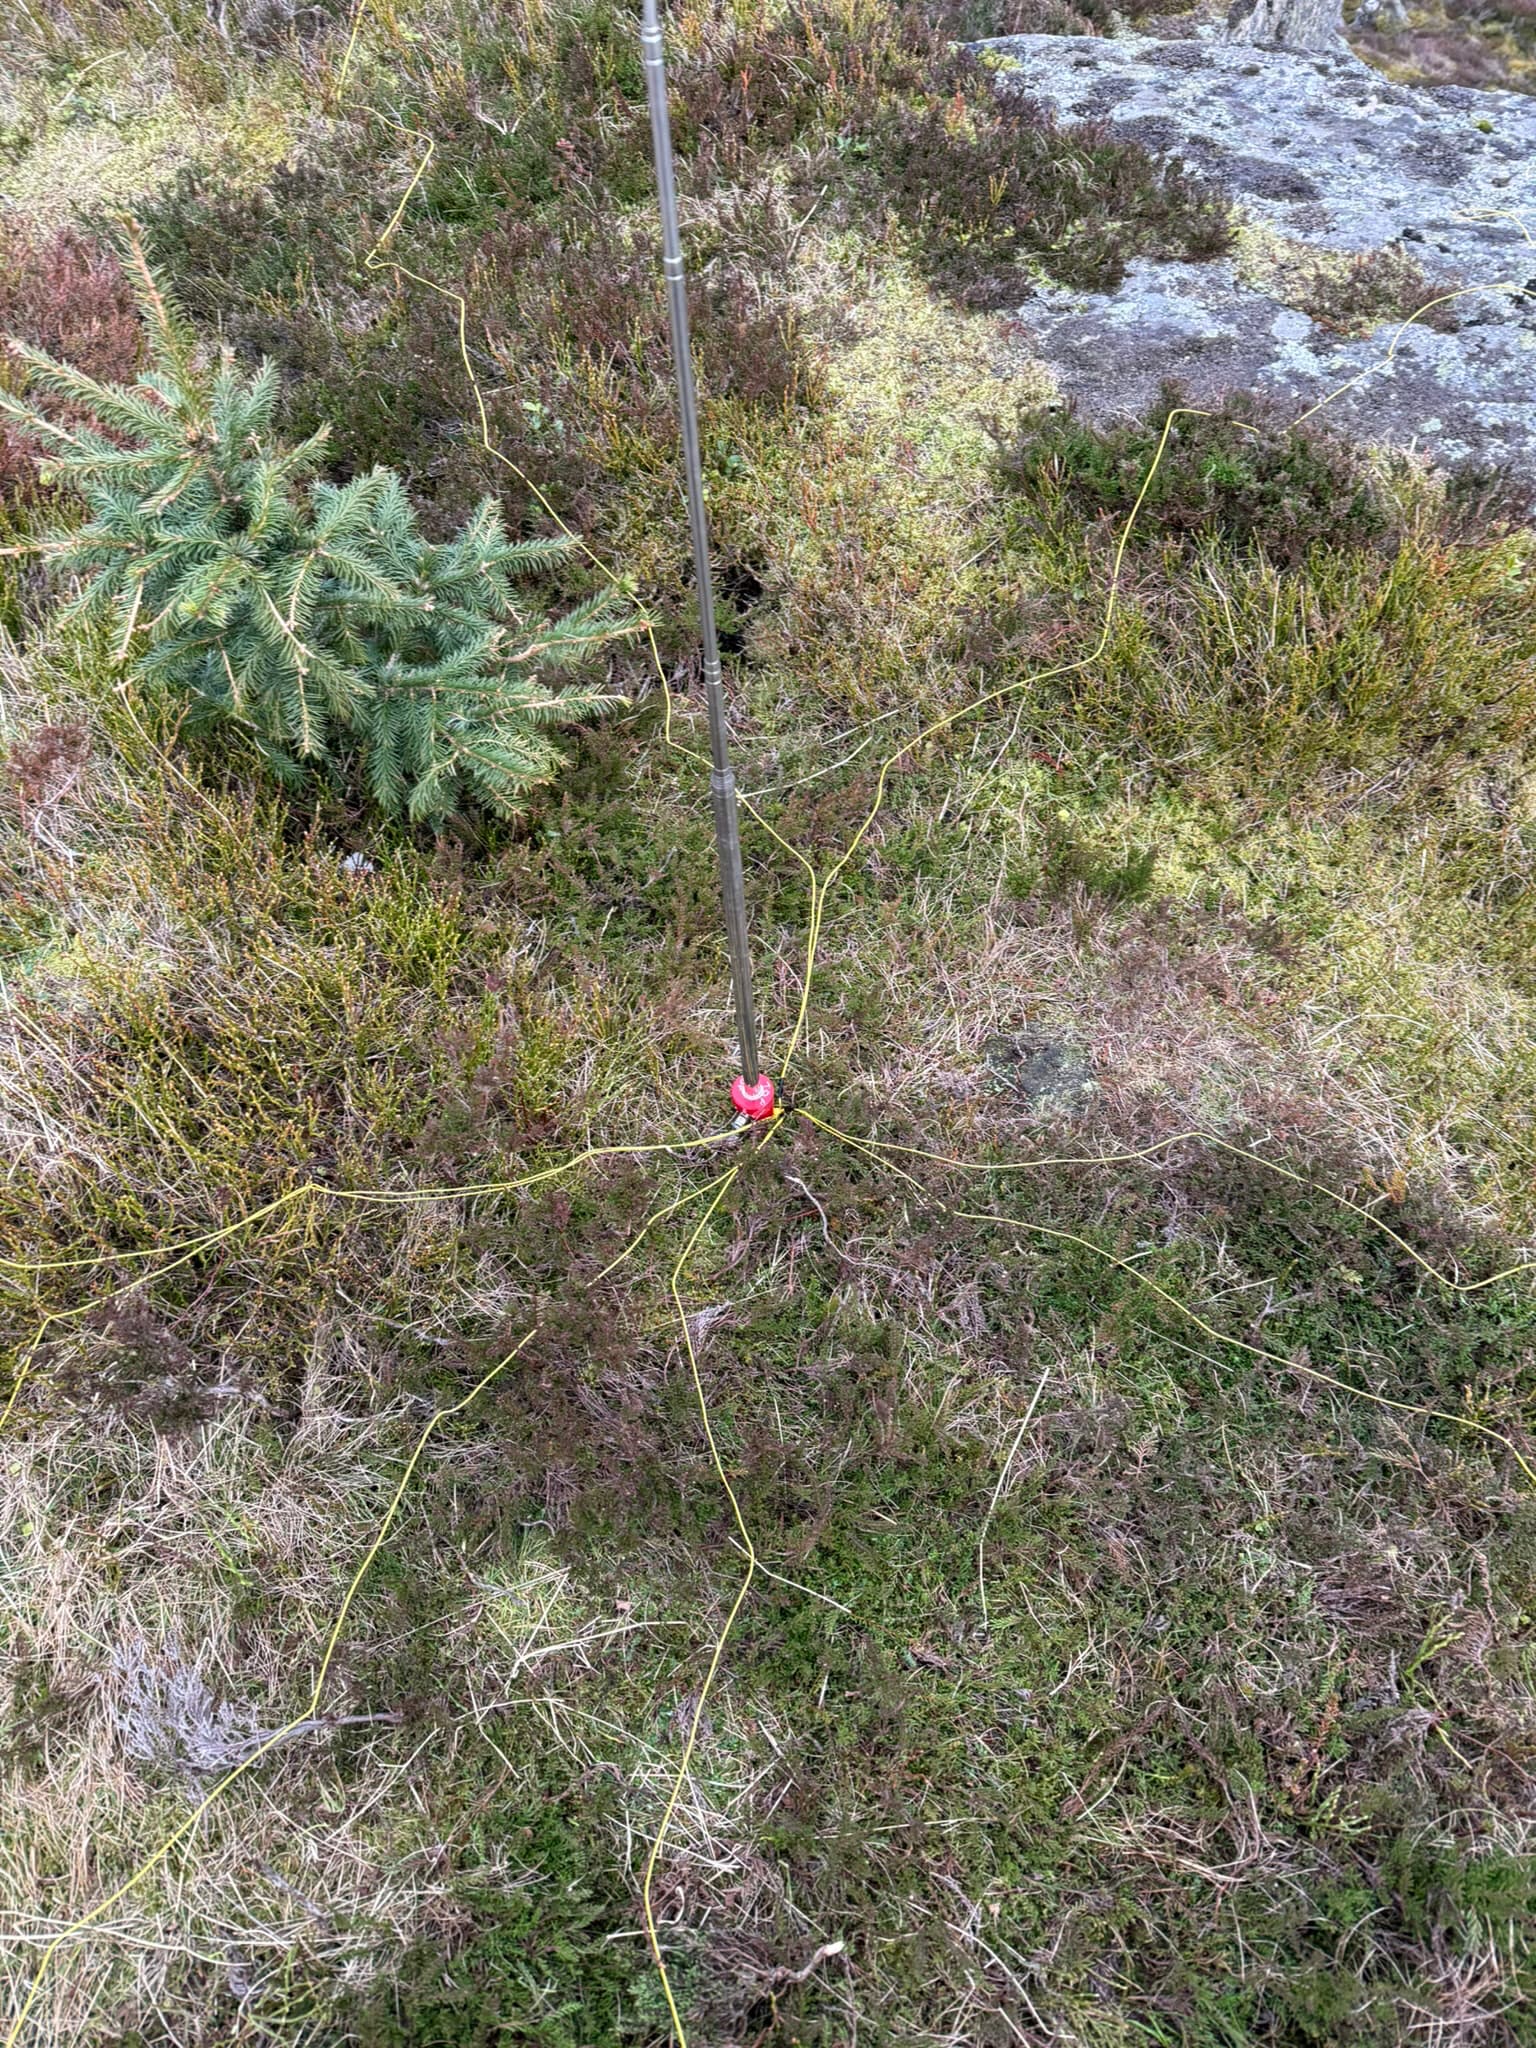
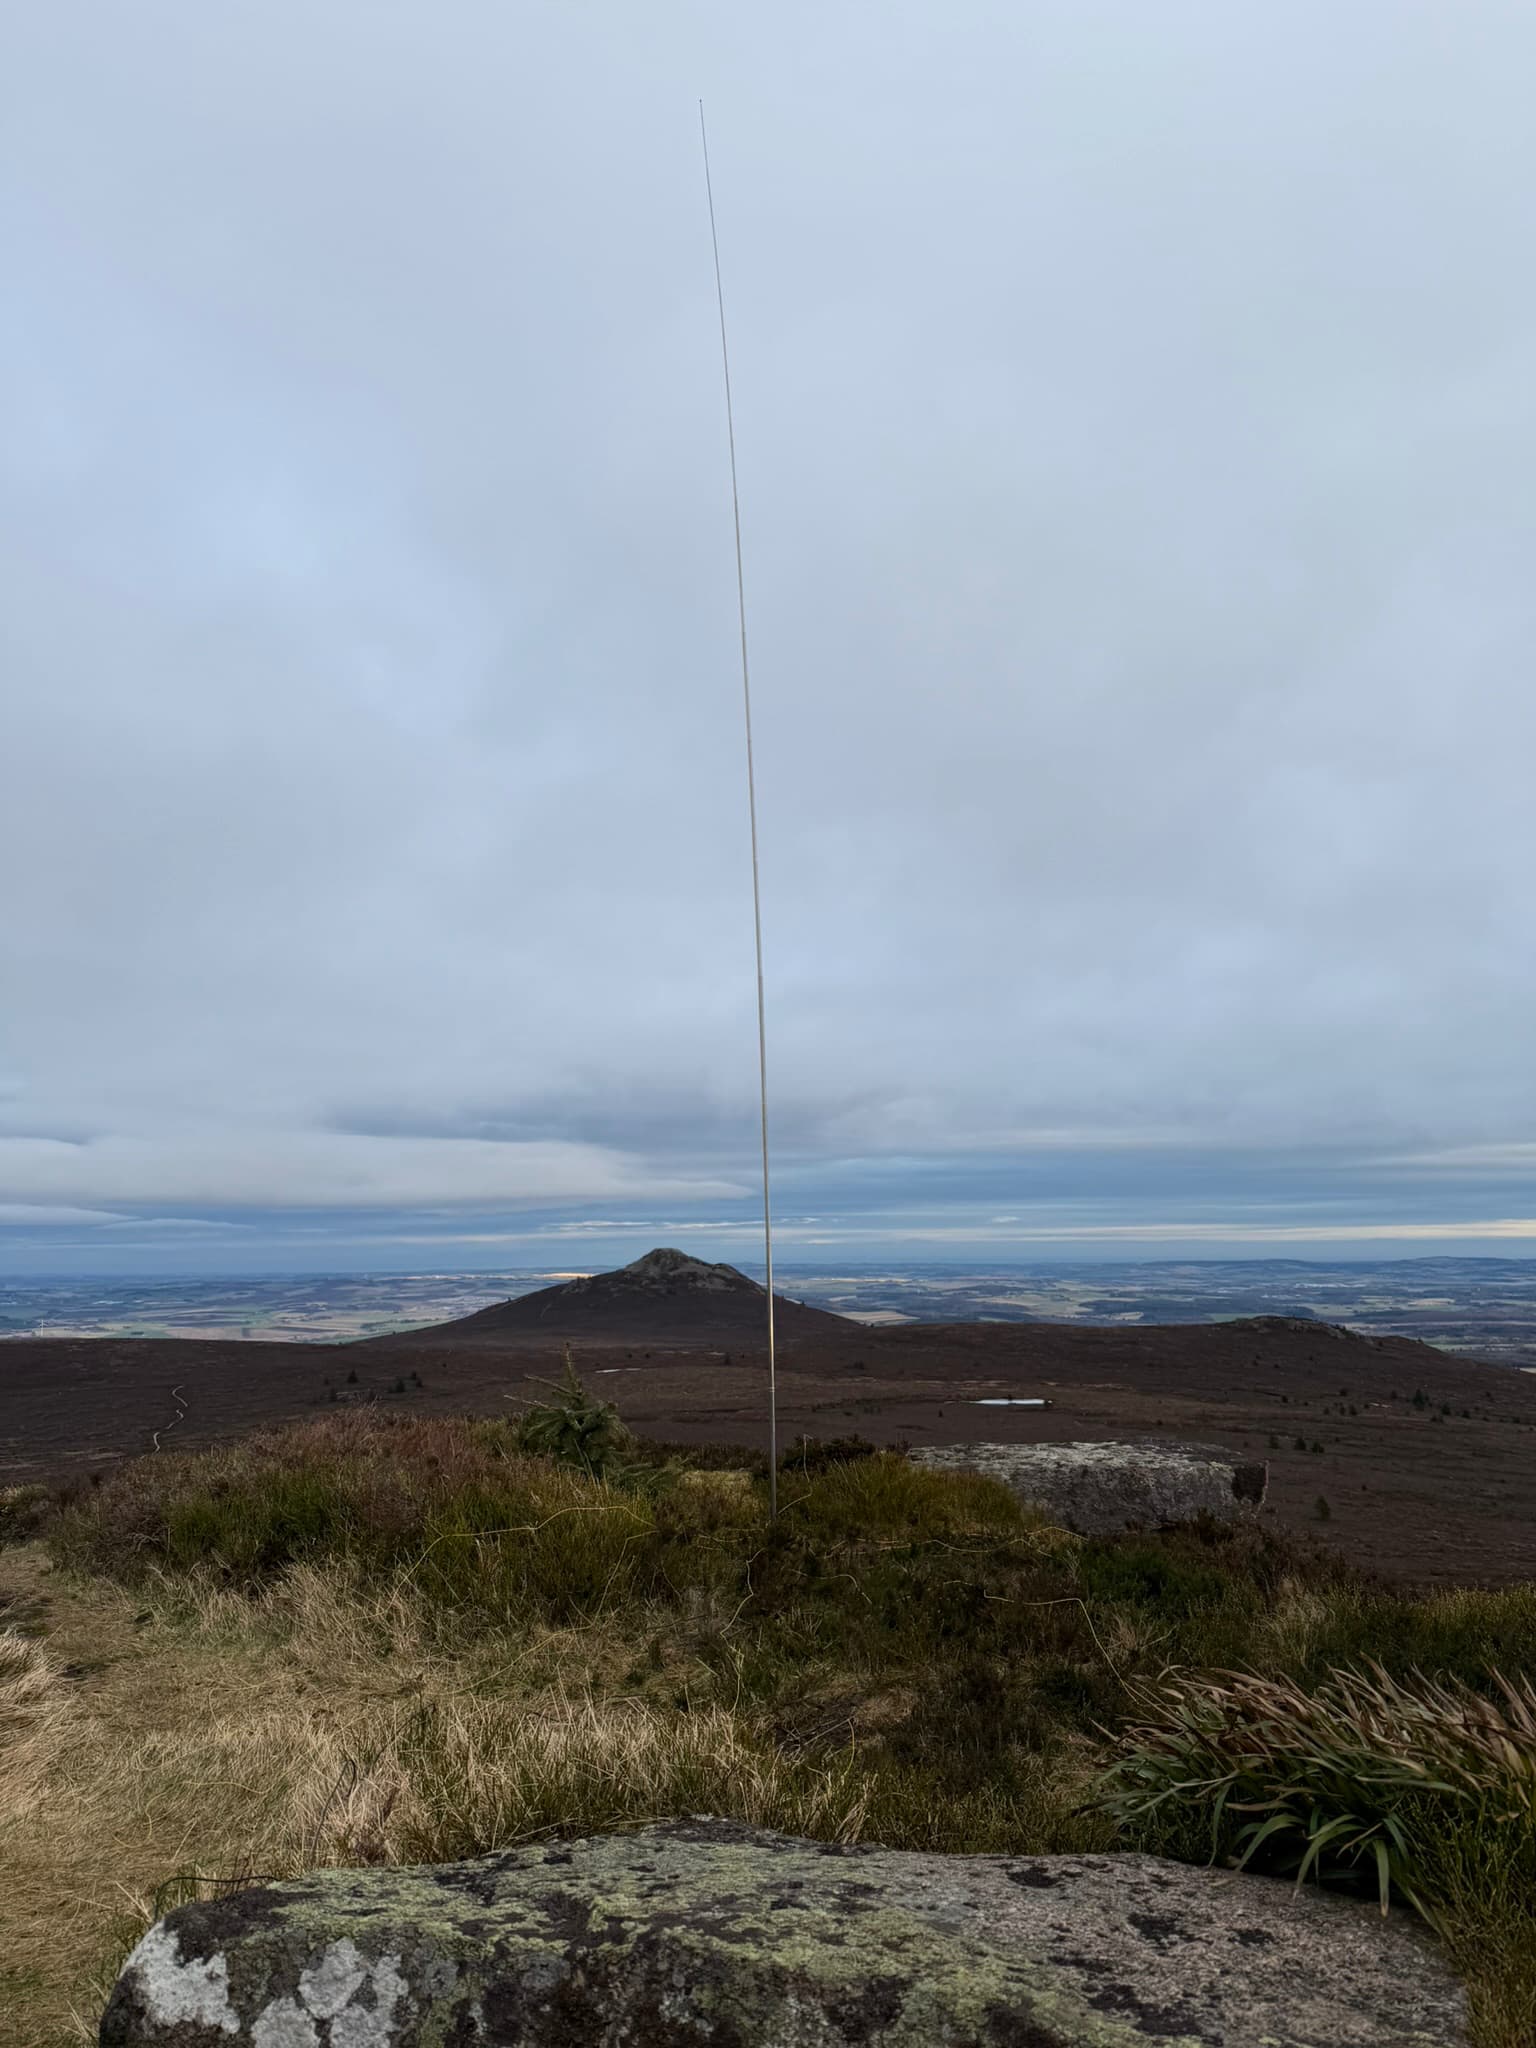
To Quote @MM0EFI and the GM0ESS gang, today was a particularly Amateur showing! Having spent all weekend locked in the curling rink ruining my knees and inflicting mild liver damage in the Aberdeen City Open competition, I needed some outside time away from people to stretch the legs and loosen my knees. With my teammates/guests shipped off early on account of our quality performance and the days fair drawin out now, I found myself with a free afternoon to have a quick run up something nearby before a 1640 sunset! Up the back of Bennachie is a quick steady ascent and in 13 years of living up here I ve never summited the big hill! Now is as good a time as any. In SOTA terms, this hill is GM/ES-061. In Geographical terms, it s around 20 miles inland from Aberdeen city here. I ve been experimenting with these Aliexpress whips since the end of last year and the forecast wind was low enough to take one into the hills. I cut and terminated 8x 2.5m radials for an effective ground plane last week and wanted to try that against the flat ribbon that it came with. The ascent was pleasant enough, got to the summit in good time, and out came my Quansheng radio to get the GM/ES-Society on 2m. First my Nagoya whip - called CQ and heard nothing, with general poor reports in WhatsApp I opted to get the slim-g up my aliexpress fibreglass mast. In an amateur showing last week, I broke the tip of the mast on Cat Law helping 2M0HSK do his first activation due to the wind, and had forgotten this until I summited this week. Squeezing my antenna on was tough, and after many failed attempts to get it up (the mast kept collapsing as I was rushing and not getting the friction hold on each section correctly) and still not hearing anything at all, I changed location and tried again. In my new position, I received 2M0RVZ 4/4 at best, but he was hearing my 5/9. Similarly GM5ALX and GM4JXP were patiently receiving me loud and clear but I couldn t hear them at all. I fiddled with settings and decided the receive path of the Quansheng must be fried or sad somehow, but I don t yet have a full set of diagnostics run. I ll take my Anytone on the next hill and compare them against each other I think. I gave up and moved to HF, getting my whip and new radials into the ground: 295B58E1-BA43-4348-A4C7-0B1E013C4006_1_102_o 375x500 Quick to deploy which is what I was after. My new 5m of coax with a choke fitted attached to the radio and we were off to the races - A convenient thing of beauty when it s up: 33C35D56-F470-46BB-B31E-F66361504A1C_1_102_o 375x500 I ve made a single guy with a sotabeams top insulator to brace against wind if need be, but that didn t need to be used today. I hit tune, and the G90 spent ages clicking away. In fact, tuning to 14.074, I could only see the famed FT8 signals at S2. What could be wrong here? Was it my new radials? the whip has behaved before Minutes turned into tens of minutes playing with everything, and eventually I worked out what was up - my coax only passed signal when I the PL259 connector at the antenna juuuust right. Once I did that, I could take the tuner out the system and work 20 spectacularly well. Until now, I d been tuning the coax only. Another Quality Hibby Build Job . That s what s wrong! I managed to struggle my way through a touch of QRM and my wonky cable woes to make enough contacts with some very patient chasers and a summit to summit before my frustration at the situation won out, and down the hill I went after a quick pack up period. I managed to beat the sunset - I think if the system had worked fine, I d have stayed on the hill for sunset. I think it s time for a new mast and a coax retermination!

Colin Watson: Free software activity in January 2025

Most of my Debian contributions this month were sponsored by Freexian. If you appreciate this sort of work and are at a company that uses Debian, have a look to see whether you can pay for any of Freexian s services; as well as the direct benefits, that revenue stream helps to keep Debian development sustainable for me and several other lovely people. You can also support my work directly via Liberapay. Python team We finally made Python 3.13 the default version in testing! I fixed various bugs that got in the way of this: As with last month, I fixed a few more build regressions due to the removal of a deprecated intersphinx_mapping syntax in Sphinx 8.0: I ported a few packages to Django 5.1: I ported python-pypump to IPython 8.0. I fixed python-datamodel-code-generator to handle isort 6, and contributed that upstream. I fixed some packages to tolerate future versions of dh-python that will drop their dependency on python3-setuptools: I removed the old python-celery-common transitional package from celery, since nothing in Debian needs it any more. I fixed or helped to fix various other build/test failures: I upgraded these packages to new upstream versions: Rust team I fixed rust-pyo3-ffi to avoid explicit Python version dependencies that were getting in the way of making Python 3.13 the default version. Security tools packaging team I uploaded libevt to fix a build failure on i386 and to tolerate future versions of dh-python that will drop their dependency on python3-setuptools. Installer team I helped with some testing of a debian-installer-utils patch as part of the /usr move. I need to get around to uploading this, since it looks OK now. Other small things Helmut Grohne reached out for help debugging a multi-arch coinstallability problem (you know it s going to be complicated when even Helmut can t figure it out on his own ) in binutils, and we had a call about that. I reviewed and applied a new Romanian translation of debconf s manual pages. I did my twice-yearly refresh of debmirror s mirror_size documentation, and applied a contribution to improve the example debmirror.conf. I fixed an arguable preprocessor string handling bug in man-db, and applied a fix for out-of-tree builds.

Joachim Breitner: Coding on my eInk Tablet

For many years I wished I had a setup that would allow me to work (that is, code) productively outside in the bright sun. It s winter right now, but when its summer again it s always a bit. this weekend I got closer to that goal. TL;DR: Using code-server on a beefy machine seems to be quite neat.
Passively lit coding Passively lit coding

Personal history Looking back at my own old blog entries I find one from 10 years ago describing how I bought a Kobo eBook reader with the intent of using it as an external monitor for my laptop. It seems that I got a proof-of-concept setup working, using VNC, but it was tedious to set up, and I never actually used that. I subsequently noticed that the eBook reader is rather useful to read eBooks, and it has been in heavy use for that every since. Four years ago I gave this old idea another shot and bought an Onyx BOOX Max Lumi. This is an A4-sized tablet running Android and had the very promising feature of an HDMI input. So hopefully I d attach it to my laptop and it just works . Turns out that this never worked as well as I hoped: Even if I set the resolution to exactly the tablet s screen s resolution I got blurry output, and it also drained the battery a lot, so I gave up on this. I subsequently noticed that the tablet is rather useful to take notes, and it has been in sporadic use for that. Going off on this tangent: I later learned that the HDMI input of this device appears to the system like a camera input, and I don t have to use Boox s monitor app but could other apps like FreeDCam as well. This somehow managed to fix the resolution issues, but the setup still wasn t as convenient to be used regularly. I also played around with pure terminal approaches, e.g. SSH ing into a system, but since my usual workflow was never purely text-based (I was at least used to using a window manager instead of a terminal multiplexer like screen or tmux) that never led anywhere either.

VSCode, working remotely Since these attempts I have started a new job working on the Lean theorem prover, and working on or with Lean basically means using VSCode. (There is a very good neovim plugin as well, but I m using VSCode nevertheless, if only to make sure I am dogfooding our default user experience). My colleagues have said good things about using VSCode with the remote SSH extension to work on a beefy machine, so I gave this a try now as well, and while it s not a complete game changer for me, it does make certain tasks (rebuilding everything after a switching branches, running the test suite) very convenient. And it s a bit spooky to run these work loads without the laptop s fan spinning up. In this setup, the workspace is remote, but VSCode still runs locally. But it made me wonder about my old goal of being able to work reasonably efficient on my eInk tablet. Can I replicate this setup there? VSCode itself doesn t run on Android directly. There are project that run a Linux chroot or in termux on the Android system, and then you can VNC to connect to it (e.g. on Andronix) but that did not seem promising. It seemed fiddly, and I probably should take it easy on the tablet s system.

code-server, running remotely A more promising option is code-server. This is a fork of VSCode (actually of VSCodium) that runs completely on the remote machine, and the client machine just needs a browser. I set that up this weekend and found that I was able to do a little bit of work reasonably.

Access With code-server one has to decide how to expose it safely enough. I decided against the tunnel-over-SSH option, as I expected that to be somewhat tedious to set up (both initially and for each session) on the android system, and I liked the idea of being able to use any device to work in my environment. I also decided against the more involved reverse proxy behind proper hostname with SSL setups, because they involve a few extra steps, and some of them I cannot do as I do not have root access on the shared beefy machine I wanted to use. That left me with the option of using a code-server s built-in support for self-signed certificates and a password:
$ cat .config/code-server/config.yaml
bind-addr: 1.2.3.4:8080
auth: password
password: xxxxxxxxxxxxxxxxxxxxxxxx
cert: true
With trust-on-first-use this seems reasonably secure. Update: I noticed that the browsers would forget that I trust this self-signed cert after restarting the browser, and also that I cannot install the page (as a Progressive Web App) unless it has a valid certificate. But since I don t have superuser access to that machine, I can t just follow the official recommendation of using a reverse proxy on port 80 or 431 with automatic certificates. Instead, I pointed a hostname that I control to that machine, obtained a certificate manually on my laptop (using acme.sh) and copied the files over, so the configuration now reads as follows:
bind-addr: 1.2.3.4:3933
auth: password
password: xxxxxxxxxxxxxxxxxxxxxxxx
cert: .acme.sh/foobar.nomeata.de_ecc/foobar.nomeata.de.cer
cert-key: .acme.sh/foobar.nomeata.de_ecc/foobar.nomeata.de.key
(This is getting very specific to my particular needs and constraints, so I ll spare you the details.)

Service To keep code-server running I created a systemd service that s managed by my user s systemd instance:
~ $ cat ~/.config/systemd/user/code-server.service
[Unit]
Description=code-server
After=network-online.target
[Service]
Environment=PATH=/home/joachim/.nix-profile/bin:/nix/var/nix/profiles/default/bin:/usr/local/bin:/usr/bin:/bin:/usr/local/games:/usr/games
ExecStart=/nix/var/nix/profiles/default/bin/nix run nixpkgs#code-server
[Install]
WantedBy=default.target
(I am using nix as a package manager on a Debian system there, hence the additional PATH and complex ExecStart. If you have a more conventional setup then you do not have to worry about Environment and can likely use ExecStart=code-server. For this to survive me logging out I had to ask the system administrator to run loginctl enable-linger joachim, so that systemd allows my jobs to linger.

Git credentials The next issue to be solved was how to access the git repositories. The work is all on public repositories, but I still need a way to push my work. With the classic VSCode-SSH-remote setup from my laptop, this is no problem: My local SSH key is forwarded using the SSH agent, so I can seamlessly use that on the other side. But with code-server there is no SSH key involved. I could create a new SSH key and store it on the server. That did not seem appealing, though, because SSH keys on Github always have full access. It wouldn t be horrible, but I still wondered if I can do better. I thought of creating fine-grained personal access tokens that only me to push code to specific repositories, and nothing else, and just store them permanently on the remote server. Still a neat and convenient option, but creating PATs for our org requires approval and I didn t want to bother anyone on the weekend. So I am experimenting with Github s git-credential-manager now. I have configured it to use git s credential cache with an elevated timeout, so that once I log in, I don t have to again for one workday.
$ nix-env -iA nixpkgs.git-credential-manager
$ git-credential-manager configure
$ git config --global credential.credentialStore cache
$ git config --global credential.cacheOptions "--timeout 36000"
To login, I have to https://github.com/login/device on an authenticated device (e.g. my phone) and enter a 8-character code. Not too shabby in terms of security. I only wish that webpage would not require me to press Tab after each character This still grants rather broad permissions to the code-server, but at least only temporarily

Android setup On the client side I could now open https://host.example.com:8080 in Firefox on my eInk Android tablet, click through the warning about self-signed certificates, log in with the fixed password mentioned above, and start working! I switched to a theme that supposedly is eInk-optimized (eInk by Mufanza). It s not perfect (e.g. git diffs are unhelpful because it is not possible to distinguish deleted from added lines), but it s a start. There are more eInk themes on the official Visual Studio Marketplace, but because code-server is a fork it cannot use that marketplace, and for example this theme isn t on Open-VSX. For some reason the F11 key doesn t work, but going fullscreen is crucial, because screen estate is scarce in this setup. I can go fullscreen using VSCode s command palette (Ctrl-P) and invoking the command there, but Firefox often jumps out of the fullscreen mode, which is annoying. I still have to pay attention to when that s happening; maybe its the Esc key, which I am of course using a lot due to me using vim bindings. A more annoying problem was that on my Boox tablet, sometimes the on-screen keyboard would pop up, which is seriously annoying! It took me a while to track this down: The Boox has two virtual keyboards installed: The usual Google ASOP keyboard, and the Onyx Keyboard. The former is clever enough to stay hidden when there is a physical keyboard attached, but the latter isn t. Moreover, pressing Shift-Ctrl on the physical keyboard rotates through the virtual keyboards. Now, VSCode has many keyboard shortcuts that require Shift-Ctrl (especially on an eInk device, where you really want to avoid using the mouse). And the limited settings exposed by the Boox Android system do not allow you configure that or disable the Onyx keyboard! To solve this, I had to install the KISS Launcher, which would allow me to see more Android settings, and in particular allow me to disable the Onyx keyboard. So this is fixed. I was hoping to improve the experience even more by opening the web page as a Progressive Web App (PWA), as described in the code-server FAQ. Unfortunately, that did not work. Firefox on Android did not recognize the site as a PWA (even though it recognizes a PWA test page). And I couldn t use Chrome either because (unlike Firefox) it would not consider a site with a self-signed certificate as a secure context, and then code-server does not work fully. Maybe this is just some bug that gets fixed in later versions. Now that I use a proper certificate, I can use it as a Progressive Web App, and with Firefox on Android this starts the app in full-screen mode (no system bars, no location bar). The F11 key still does t work, and using the command palette to enter fullscreen does nothing visible, but then Esc leaves that fullscreen mode and I suddenly have the system bars again. But maybe if I just don t do that I get the full screen experience. We ll see. I did not work enough with this yet to assess how much the smaller screen estate, the lack of colors and the slower refresh rate will bother me. I probably need to hide Lean s InfoView more often, and maybe use the Error Lens extension, to avoid having to split my screen vertically. I also cannot easily work on a park bench this way, with a tablet and a separate external keyboard. I d need at least a table, or some additional piece of hardware that turns tablet + keyboard into some laptop-like structure that I can put on my, well, lap. There are cases for Onyx products that include a keyboard, and maybe they work on the lap, but they don t have the Trackpoint that I have on my ThinkPad TrackPoint Keyboard II, and how can you live without that?

Conclusion After this initial setup chances are good that entering and using this environment is convenient enough for me to actually use it; we will see when it gets warmer. A few bits could be better. In particular logging in and authenticating GitHub access could be both more convenient and more safe I could imagine that when I open the page I confirm that on my phone (maybe with a fingerprint), and that temporarily grants access to the code-server and to specific GitHub repositories only. Is that easily possible?

Anuradha Weeraman: DeepSeek-R1, at the cusp of an open revolution

DeepSeek-R1, at the cusp of an open revolutionDeepSeek R1, the new entrant to the Large Language Model wars has created quite a splash over the last few weeks. Its entrance into a space dominated by the Big Corps, while pursuing asymmetric and novel strategies has been a refreshing eye-opener.GPT AI improvement was starting to show signs of slowing down, and has been observed to be reaching a point of diminishing returns as it runs out of data and compute required to train, fine-tune increasingly large models. This has turned the focus towards building "reasoning" models that are post-trained through reinforcement learning, techniques such as inference-time and test-time scaling and search algorithms to make the models appear to think and reason better. OpenAI&aposs o1-series models were the first to achieve this successfully with its inference-time scaling and Chain-of-Thought reasoning.

Intelligence as an emergent property of Reinforcement Learning (RL)Reinforcement Learning (RL) has been successfully used in the past by Google&aposs DeepMind team to build highly intelligent and specialized systems where intelligence is observed as an emergent property through rewards-based training approach that yielded achievements like AlphaGo (see my post on it here - AlphaGo: a journey to machine intuition).DeepMind went on to build a series of Alpha* projects that achieved many notable feats using RL:
  • AlphaGo, defeated the world champion Lee Seedol in the game of Go
  • AlphaZero, a generalized system that learned to play games such as Chess, Shogi and Go without human input
  • AlphaStar, achieved high performance in the complex real-time strategy game StarCraft II.
  • AlphaFold, a tool for predicting protein structures which significantly advanced computational biology.
  • AlphaCode, a model designed to generate computer programs, performing competitively in coding challenges.
  • AlphaDev, a system developed to discover novel algorithms, notably optimizing sorting algorithms beyond human-derived methods.
All of these systems achieved mastery in its own area through self-training/self-play and by optimizing and maximizing the cumulative reward over time by interacting with its environment where intelligence was observed as an emergent property of the system.
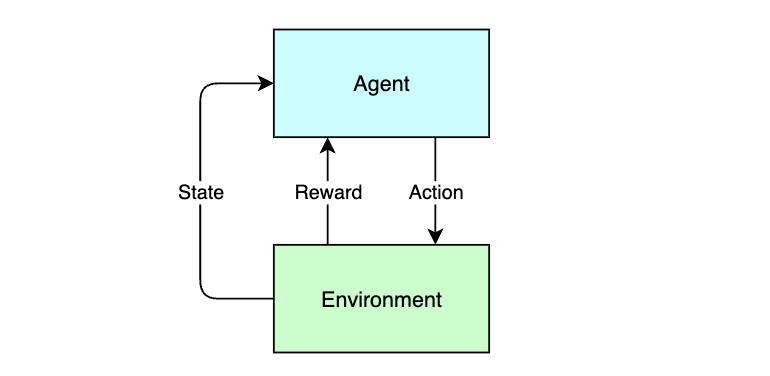
DeepSeek-R1, at the cusp of an open revolutionThe RL feedback loop
RL mimics the process through which a baby would learn to walk, through trial, error and first principles.

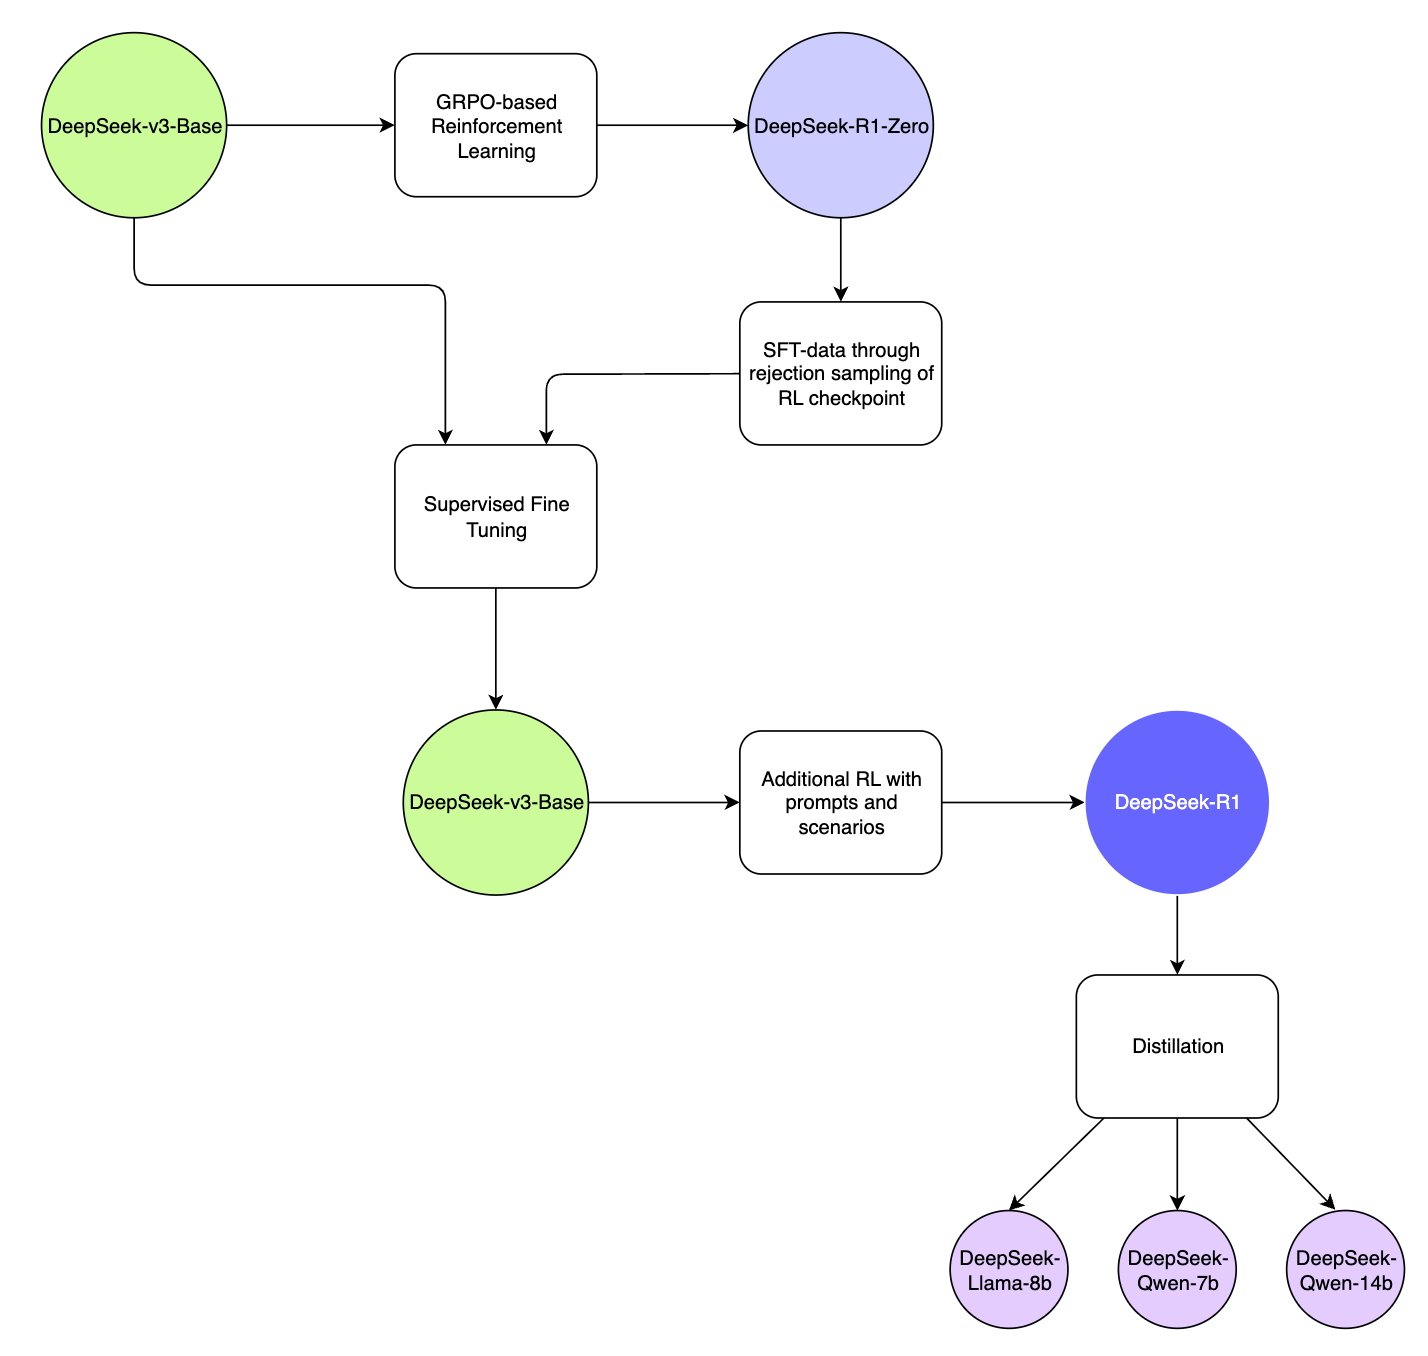
R1 model training pipelineAt a technical level, DeepSeek-R1 leverages a combination of Reinforcement Learning (RL) and Supervised Fine-Tuning (SFT) for its training pipeline:
DeepSeek-R1, at the cusp of an open revolutionDeepSeek-R1 Model Training Pipeline
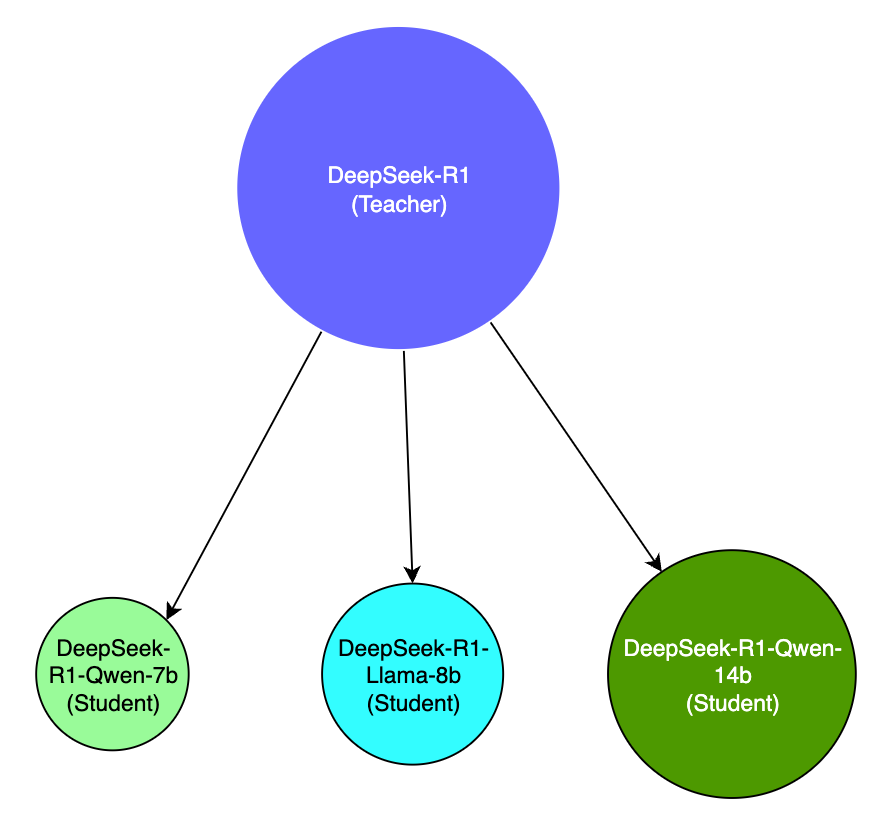
Using RL and DeepSeek-v3, an interim reasoning model was built, called DeepSeek-R1-Zero, purely based on RL without relying on SFT, which demonstrated superior reasoning capabilities that matched the performance of OpenAI&aposs o1 in certain benchmarks such as AIME 2024.The model was however affected by poor readability and language-mixing and is only an interim-reasoning model built on RL principles and self-evolution.DeepSeek-R1-Zero was then used to generate SFT data, which was combined with supervised data from DeepSeek-v3 to re-train the DeepSeek-v3-Base model.The new DeepSeek-v3-Base model then underwent additional RL with prompts and scenarios to come up with the DeepSeek-R1 model.The R1-model was then used to distill a number of smaller open source models such as Llama-8b, Qwen-7b, 14b which outperformed bigger models by a large margin, effectively making the smaller models more accessible and usable.

Key contributions of DeepSeek-R1
  1. RL without the need for SFT for emergent reasoning capabilities
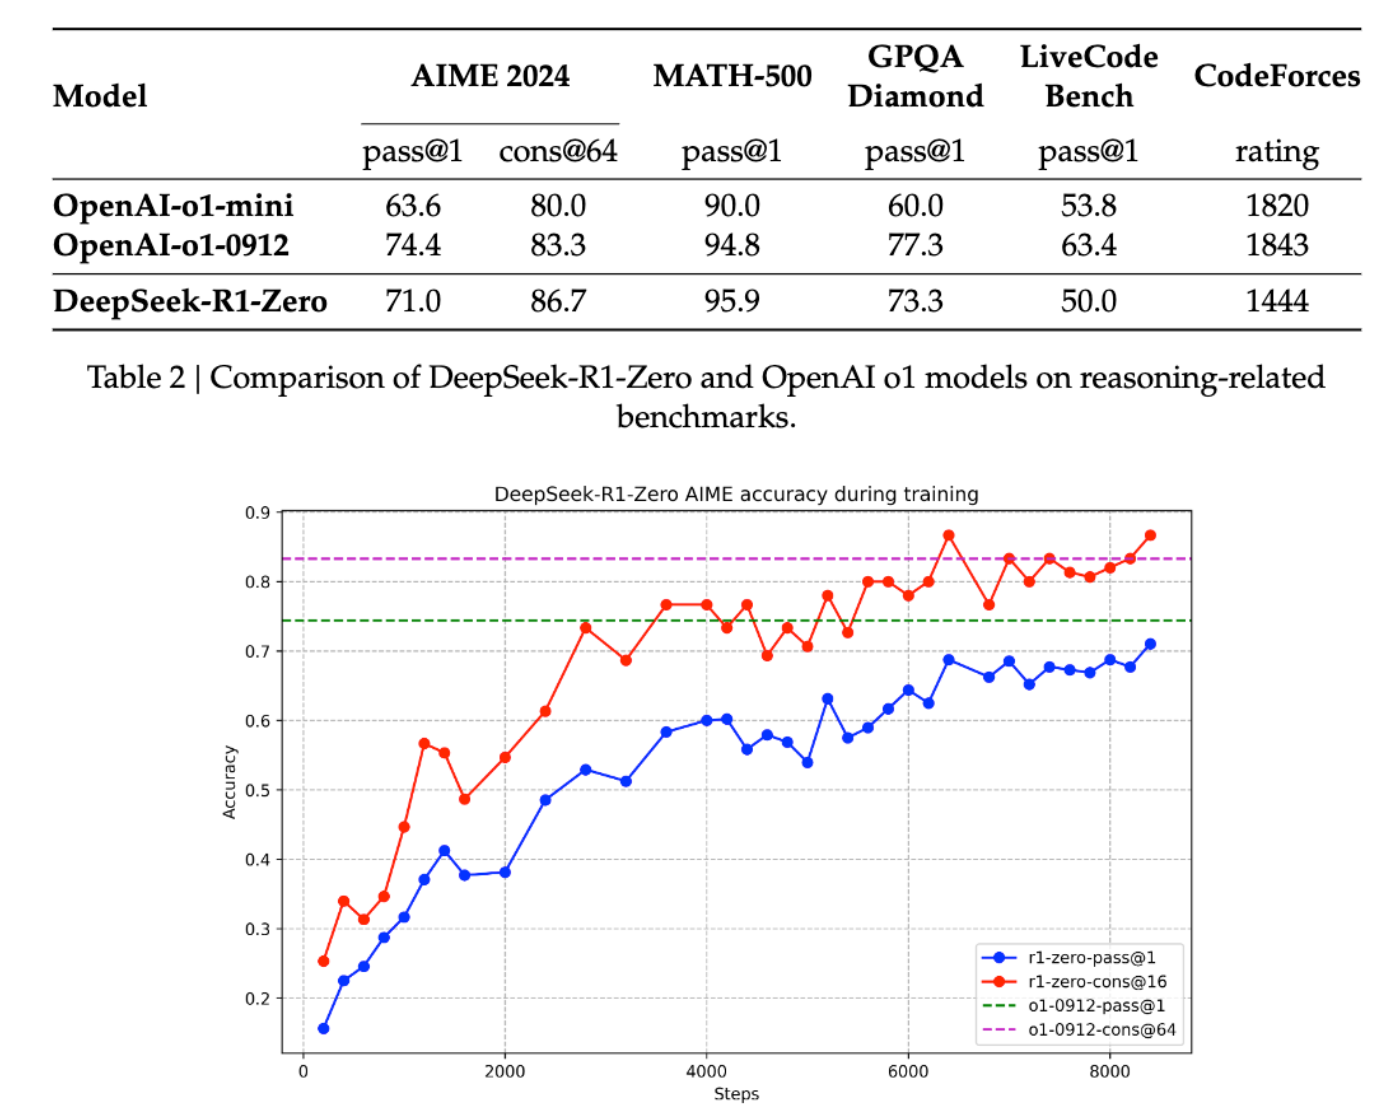
R1 was the first open research project to validate the efficacy of RL directly on the base model without relying on SFT as a first step, which resulted in the model developing advanced reasoning capabilities purely through self-reflection and self-verification.Although, it did degrade in its language capabilities during the process, its Chain-of-Thought (CoT) capabilities for solving complex problems was later used for further RL on the DeepSeek-v3-Base model which became R1. This is a significant contribution back to the research community.The below analysis of DeepSeek-R1-Zero and OpenAI o1-0912 shows that it is viable to attain robust reasoning capabilities purely through RL alone, which can be further augmented with other techniques to deliver even better reasoning performance.
DeepSeek-R1, at the cusp of an open revolutionSource: https://github.com/deepseek-ai/DeepSeek-R1
Its quite interesting, that the application of RL gives rise to seemingly human capabilities of "reflection", and arriving at "aha" moments, causing it to pause, ponder and focus on a specific aspect of the problem, resulting in emergent capabilities to problem-solve as humans do.
  1. Model distillation
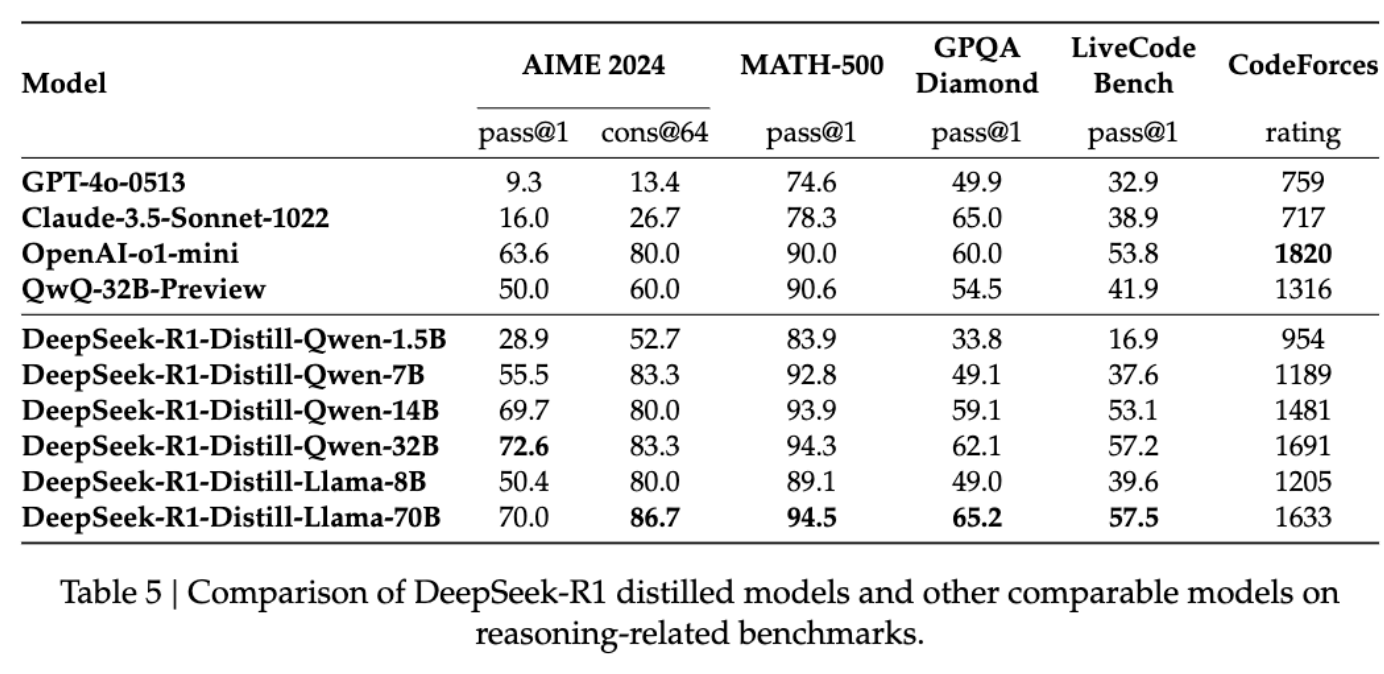
DeepSeek-R1 also demonstrated that larger models can be distilled into smaller models which makes advanced capabilities accessible to resource-constrained environments, such as your laptop. While its not possible to run a 671b model on a stock laptop, you can still run a distilled 14b model that is distilled from the larger model which still performs better than most publicly available models out there. This enables intelligence to be brought closer to the edge, to allow faster inference at the point of experience (such as on a smartphone, or on a Raspberry Pi), which paves way for more use cases and possibilities for innovation.
DeepSeek-R1, at the cusp of an open revolutionSource: https://github.com/deepseek-ai/DeepSeek-R1
Distilled models are very different to R1, which is a massive model with a completely different model architecture than the distilled variants, and so are not directly comparable in terms of capability, but are instead built to be more smaller and efficient for more constrained environments. This technique of being able to distill a larger model&aposs capabilities down to a smaller model for portability, accessibility, speed, and cost will bring about a lot of possibilities for applying artificial intelligence in places where it would have otherwise not been possible. This is another key contribution of this technology from DeepSeek, which I believe has even further potential for democratization and accessibility of AI.
DeepSeek-R1, at the cusp of an open revolution

Why is this moment so significant?DeepSeek-R1 was a pivotal contribution in many ways.
  1. The contributions to the state-of-the-art and the open research helps move the field forward where everybody benefits, not just a few highly funded AI labs building the next billion dollar model.
  2. Open-sourcing and making the model freely available follows an asymmetric strategy to the prevailing closed nature of much of the model-sphere of the larger players. DeepSeek should be commended for making their contributions free and open.
  3. It reminds us that its not just a one-horse race, and it incentivizes competition, which has already resulted in OpenAI o3-mini a cost-effective reasoning model which now shows the Chain-of-Thought reasoning. Competition is a good thing.
  4. We stand at the cusp of an explosion of small-models that are hyper-specialized, and optimized for a specific use case that can be trained and deployed cheaply for solving problems at the edge. It raises a lot of exciting possibilities and is why DeepSeek-R1 is one of the most pivotal moments of tech history.
Truly exciting times. What will you build?

Dirk Eddelbuettel: RcppSpdlog 0.0.20 on CRAN: New Upstream, New Features

Version 0.0.20 of RcppSpdlog arrived on CRAN early this morning and has been uploaded to Debian. RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovich. You can learn more at the nice package documention site. This release updates the code to the version 1.15.1 of spdlog which was released this morning as well. It also contains a contributed PR which illustrates logging in a multithreaded context. The NEWS entry for this release follows.

Changes in RcppSpdlog version 0.0.20 (2025-02-01)
  • New multi-threaded logging example (Young Geun Kim and Dirk via #22)
  • Upgraded to upstream release spdlog 1.15.1

Courtesy of my CRANberries, there is also a diffstat report. More detailed information is on the RcppSpdlog page, or the package documention site.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

1 February 2025

Guido G nther: Free Software Activities January 2025

Another short status update of what happened on my side last month. Mostly focused on quality of life improvements in phosh and cleaning up and improving phoc this time around (including catching up with wlroots git) but some improvements for other things like phosh-osk-stub happened on the side line too. phosh phoc phosh-osk-stub xdg-desktop-portal-phosh phosh-recipes libcmatrix phrog Debian git-buildpackage livi feedbackd Wayland protocols Wlroots Bug reports Reviews This is not code by me but reviews on other peoples code. The list is incomplete, but I hope to improve on this in the upcoming months. Thanks for the contributions! Help Development If you want to support my work see donations. Comments? Join the Fediverse thread

31 January 2025

Gunnar Wolf: ChatGPT is bullshit

This post is an unpublished review for ChatGPT is bullshit
As people around the world understand how LLMs behave, more and more people wonder as to why these models hallucinate, and what can be done about to reduce it. This provocatively named article by Michael Townsen Hicks, James Humphries and Joe Slater bring is an excellent primer to better understanding how LLMs work and what to expect from them. As humans carrying out our relations using our language as the main tool, we are easily at awe with the apparent ease with which ChatGPT (the first widely available, and to this day probably the best known, LLM-based automated chatbot) simulates human-like understanding and how it helps us to easily carry out even daunting data aggregation tasks. It is common that people ask ChatGPT for an answer and, if it gets part of the answer wrong, they justify it by stating that it s just a hallucination. Townsen et al. invite us to switch from that characterization to a more correct one: LLMs are bullshitting. This term is formally presented by Frankfurt [1]. To Bullshit is not the same as to lie, because lying requires to know (and want to cover) the truth. A bullshitter not necessarily knows the truth, they just have to provide a compelling description, regardless of what is really aligned with truth. After introducing Frankfurt s ideas, the authors explain the fundamental ideas behind LLM-based chatbots such as ChatGPT; a Generative Pre-trained Transformer (GPT) s have as their only goal to produce human-like text, and it is carried out mainly by presenting output that matches the input s high-dimensional abstract vector representation, and probabilistically outputs the next token (word) iteratively with the text produced so far. Clearly, a GPT s ask is not to seek truth or to convey useful information they are built to provide a normal-seeming response to the prompts provided by their user. Core data are not queried to find optimal solutions for the user s requests, but are generated on the requested topic, attempting to mimic the style of document set it was trained with. Erroneous data emitted by a LLM is, thus, not equiparable with what a person could hallucinate with, but appears because the model has no understanding of truth; in a way, this is very fitting with the current state of the world, a time often termed as the age of post-truth [2]. Requesting an LLM to provide truth in its answers is basically impossible, given the difference between intelligence and consciousness: Following Harari s definitions [3], LLM systems, or any AI-based system, can be seen as intelligent, as they have the ability to attain goals in various, flexible ways, but they cannot be seen as conscious, as they have no ability to experience subjectivity. This is, the LLM is, by definition, bullshitting its way towards an answer: their goal is to provide an answer, not to interpret the world in a trustworthy way. The authors close their article with a plea for literature on the topic to adopt the more correct bullshit term instead of the vacuous, anthropomorphizing hallucination . Of course, being the word already loaded with a negative meaning, it is an unlikely request. This is a great article that mixes together Computer Science and Philosophy, and can shed some light on a topic that is hard to grasp for many users. [1] Frankfurt, Harry (2005). On Bullshit. Princeton University Press. [2] Zoglauer, Thomas (2023). Constructed truths: truth and knowledge in a post-truth world. Springer. [3] Harari, Yuval Noah (2023. Nexus: A Brief History of Information Networks From the Stone Age to AI. Random House.

Dirk Eddelbuettel: zigg 0.0.1 on CRAN: New Package!

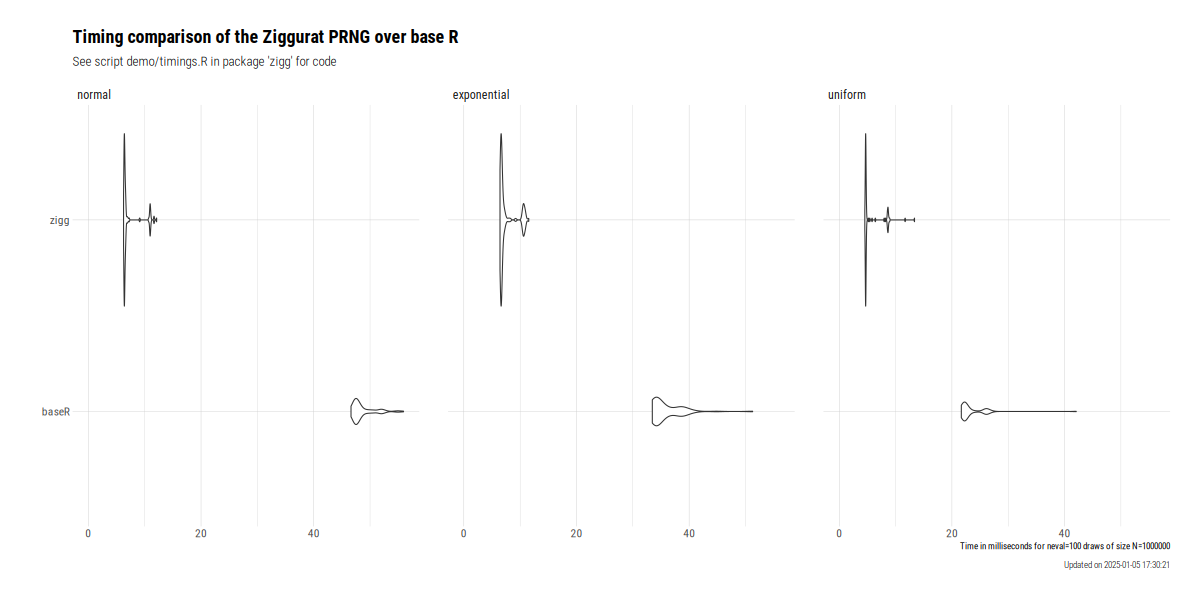
Thrilled to announce a new package: zigg. It arrived on CRAN today after a few days of review in the newbies queue. zigg provides the Ziggurat pseudo-random number generator for Normal, Exponential and Uniform draws proposed by Marsaglia and Tsang (JSS, 2000), and extended by Leong et al. (JSS, 2005). I had picked up their work in package RcppZiggurat and updated its code for the 64-buit world we now live in. That package alredy provided the Normal generator along with several competing implementations which it compared rigorously and timed them. As one of the generators was based on the GNU GSL via the implementation of Voss, we always ended up with a run-time dependency on the GSL too. No more: this new package is zero-depedency, zero-suggsts and hence very easy to deploy. Moreover, we also include a demonstration of four distinct ways of accessing the compiled code from another R package: pure and straight-up C, similarly pure C++, inclusion of the header in C++ as well as via Rcpp. The other advance is the resurrection of the second generator for the Exponential distribution. And following Burkardt we expose the Uniform too. The main upside of these generators is their excellent speed as can be seen in the comparison the default R generators generated by the example script timings.R: Needless to say, speed is not everything. This PRNG comes the time of 32-bit computing so the generator period is likely to be shorter than that of newer high-quality generators. If in doubt, forgo speed and stick with the high-quality default generators. The short NEWS entry follows.

Changes in version 0.0.1 (2021-01-30)
  • Initial version and CRAN upload

For more, see the package page or the git repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Daniel Lange: Seagate old hard disks sold as new, smartmontools v7.4 for Debian Bullseye and Bookworm

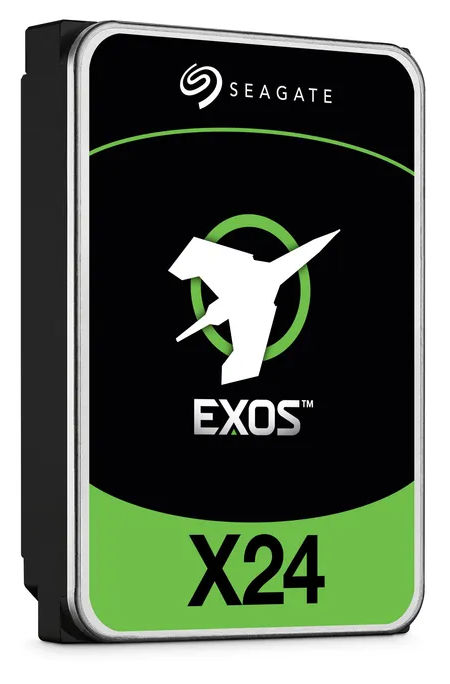
Apparently somebody managed to resell Seagate hard disks that have 2-5 years of operations on them as brand new. They did this by using some new shrink wrap bags and resetting the used hard disk SMART attributes to factory-new values. Image of Seagate Exos X24 hard disk Luckily Seagate has a proprietary extension "Seagate FARM (Field Access Reliability Metrics)" implemented in their disks that ... the crooks did not reset. Luckily ... because other manufacturers do not have that extension. And you think the crooks only re-sell used Seagate disks? Lol. The get access to the Seagate FARM extension, you need smartctl from smartmontools v7.4 or later. For Debian 12 (Bookworm) you can add the backports archive and then install with apt install smartmontools/bookworm-backports. For Debian 11 (Bullseye) you can use a backport we created at my company:
File sha256
smartmontools_7.4-2~bpo11+1_amd64.deb e09da1045549d9b85f2cd7014d1f3ca5d5f0b9376ef76f68d8d303ad68fdd108
You can also download static builds from https://builds.smartmontools.org/ which keeps the latest CI builds of the current development branch (v7.5 at the time of writing). To check the state of your drives, compare the output from smartctl -x and smartctl -l farm. Double checking Power_On_Hours vs. "Power on Hours" is the obvious. But the other values around "Head Flight Hours" and "Power Cycle Count" should also roughly match what you expect from a hard disk of a certain age. All near zero, of course, for a factory-new hard disk. This is what it looks like for a hard disk that has gracefully serviced 4 years and 8 months so far. The smartctl -x and smartctl -l farm data match within some small margins:
$ smartctl -x /dev/sda

smartctl 7.4 2023-08-01 r5530 [x86_64-linux-6.1.0-30-amd64] (local build)
Copyright (C) 2002-23, Bruce Allen, Christian Franke, www.smartmontools.org

=== START OF INFORMATION SECTION ===
Model Family: Seagate Exos X14
Device Model: ST10000NM0568-2H5110
[..]
Vendor Specific SMART Attributes with Thresholds:
ID# ATTRIBUTE_NAME FLAGS VALUE WORST THRESH FAIL RAW_VALUE
[..]
4 Start_Stop_Count -O--CK 100 100 020 - 26
[..]
9 Power_On_Hours -O--CK 054 054 000 - 40860
10 Spin_Retry_Count PO--C- 100 100 097 - 0
12 Power_Cycle_Count -O--CK 100 100 020 - 27
[..]
192 Power-Off_Retract_Count -O--CK 100 100 000 - 708
193 Load_Cycle_Count -O--CK 064 064 000 - 72077
[..]
240 Head_Flying_Hours ------ 100 253 000 - 21125h+51m+45.748s
$ smartctl -l farm /dev/sda

smartctl 7.4 2023-08-01 r5530 [x86_64-linux-6.1.0-30-amd64] (local build)
Copyright (C) 2002-23, Bruce Allen, Christian Franke, www.smartmontools.org

Seagate Field Access Reliability Metrics log (FARM) (GP Log 0xa6)
FARM Log Page 0: Log Header
FARM Log Version: 2.9
Pages Supported: 6
Log Size: 98304
Page Size: 16384
Heads Supported: 24
Number of Copies: 0
Reason for Frame Capture: 0
FARM Log Page 1: Drive Information
[..]
Power on Hours: 40860
Spindle Power on Hours: 34063
Head Flight Hours: 24513
Head Load Events: 72077
Power Cycle Count: 28
Hardware Reset Count: 193
You may like to run the command below on your systems to capture the state. Remember FARM is only supported on Seagate drives.
for i in /dev/sd a,b,c,d,e,f,g,h ; do smartctl -x $i ; smartctl -l farm $i ; >> $(date +'%y%m%d')_smartctl_$(basename $i).txt ; done

Russell Coker: Links January 2025

Aaron Quigley s Everything Open lecture about Intelligent Interfaces is one of the most interesting research reports I ve seen in a long time [1]. This one can be understood and appreciated by people who don t have a strong background in computer science. Statites (satellites that don t orbit the sun but use solar sails to hover in place) could be used to catch up to interstellar objects [2]. Slashgear has an interesting article about an AI piloted F16 beating a human piloted F16 [3]. Given the serious handicaps of flying a plane designed for humans and flying to minimise risk to itself and other crewed aircraft this is a serious victory. Hopefully crewed military aircraft will be obsolete soon. Amusing video about the performance of cats with MMORPG style descriptions [4]. John Goerzen wrote an interesting blog post about censorship and the changes to Facebook [5]. Ron Garret wrote an interesting blog post 15 years ago when going through what he now describes as an existential crisis [6]. A comment on Ron s post is references Alan Crowe s blog post about whether the self exists which is an interesting philosophical post [7]. But I m still going to think of myself as a person. Another comment on Ron s post references Aaron Swartz blog post about Noam Chomsky etc [8]. I have to watch Manufacturing Consent: Noam Chomsky and the Media. Ron Garret wrote an interesting blog post about his failed attempts to start a company and how it all worked out well for him any way [9]. Amusing video about a failed crowdfunded e-bike [10]. Cory Doctorow wrote an insightful article about how Enshittification is not caused by VCs but by lack of controls [11].

Divine Attah-Ohiemi: Seeking Opportunities: Building a Career in Software Engineering and Beyond

My journey in CS has always been driven by curiosity, determination, and a deep love for understanding software solutions at its tiniest, most complex levels. Taking ALX Africa Software Engineer track after High school was where it all started for me. During the 1-year intensive bootcamp, I delved into the intricacies of Linux programming and low-level programming with C, which solidified my foundational knowledge. This experience not only enhanced my technical skills but also taught me the importance of adaptability and self-directed learning. I discovered how to approach challenges with curiosity, igniting a passion for exploring software solutions in their most intricate forms. Each module pushed me to think critically and creatively, transforming my understanding of technology and its capabilities. Let s just say that I have always been drawn to asking, How does this happen?" And I just go on and on until I find an answer eventually and sometimes I don t but that s okay. That curiosity, combined with a deep commitment to learning, has guided my journey. Debian Webmaster My drive has led me to get involved in open-source contributions, where I can put my knowledge to the test while helping my community. Engaging with real-world experts and learning from my mistakes has been invaluable. One of the highlights of this journey was joining the Debian Webmasters team as an intern through Outreachy. Here, I have the honor of working on redesigning and migrating the old Debian webpages to make them more user-friendly. This experience not only allows me to apply my skills in a practical setting but also deepens my understanding of collaborative software development. Building My Skills: The Foundation of My Experience Throughout my academic and professional journey, I have taken on many roles that have shaped my skills and prepared me for what s ahead I believe. I am definitely not a one-trick pony, and maybe not completely a jack of all trade either but I am a bit diverse I d like to think. Here are the key roles that have defined my journey so far: Volunteer Developer at Yoris Africa (June 2022 - August 2023) I began my career by volunteering at Yoris, where I collaborated with a talented team to design and build the frontend for a mobile app. My contributions extended beyond just the frontend; I also worked on backend solutions and microservices, gaining hands-on experience in full-stack development. This role was instrumental in shaping my understanding of software architecture, allowing me to contribute meaningfully to projects while learning from experienced developers in a dynamic environment. Freelance Academics Software Developer (September 2023 - October 2024) I freelanced as an academic software developer, where I pitched and developed software solutions for universities in my community. One of my most notable projects was creating a Computer-Based Testing (CBT) software for a medical school, which featured a unique questionnaire and scoring system tailored to their specific needs. This experience not only allowed me to apply my technical skills in a real-world setting but also deepened my understanding of educational software requirements and user experience, ultimately enhancing the learning process for students. Open Source Intern at Debian Webmaster Team (November 2024 -) Perhaps the most transformative experience has been my role as an intern at Debian Webmasters. This opportunity allowed me to delve into the fascinating world of open source. As an intern, I have the chance to work on a project where we are redesigning and migrating the Debian webpages to utilize a new and faster technology: Go templates with Hugo. For a detailed look at the work and progress I made during my internship, as well as information on this project and how to get involved, you can check out the wiki. My ultimate goal with this role is to build a vibrant community for Debian in Africa and, if given the chance, to host a debian-cd mirror for faster installations in my region. You can connect with me through LinkedIn, or X (formerly Twitter), or reach out via email.

Reproducible Builds (diffoscope): diffoscope 287 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 287. This version includes the following changes:
[ Chris Lamb ]
* Drop an unused subprocess import.
* Update copyright years.
[ fridtjof ]
* Add ASAR comparator.
You find out more by visiting the project homepage.

30 January 2025

Daniel Lange: Printing labels with the DYMO LabelWriter Wireless (and LabelWriter 5xx) on Debian Linux

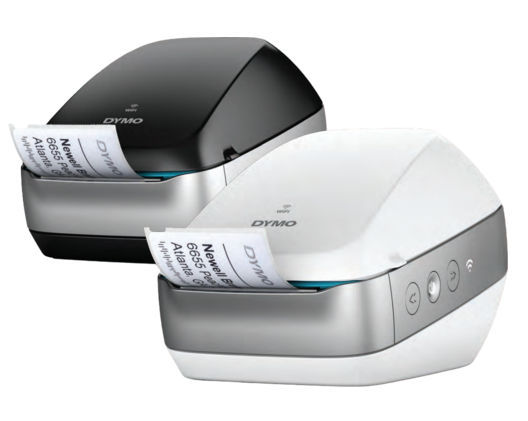
In 2020 my company bought a DYMO LabelWriter Wireless. It is an awesome little device for thermal printing a wide variety of labels. The labels are easily available both from DYMO and from third parties so the pricing is quite acceptable. Unfortunately DYMO supplies their DYMO Connect Software only for Microsoft Windows and MacOSX. A mobile app of the same name for Android and Apple iOS devices is available in the app stores. There is a SDK for Linux and there are drivers published for Linux but the LabelWriter Wireless was not supported on Linux when I tried to get it running for Debian in 2020. Image of the DYMO LabelWriter Wireless in the white and black versions This year I have had a new look at the situation as we still use the LabelWriter Wireless printers a lot and the company runs fully on Linux. So it is always a chore to run a Windows VM just to run DYMO Connect. Continue reading "Printing labels with the DYMO LabelWriter Wireless (and LabelWriter 5xx) on Debian Linux"

Dirk Eddelbuettel: RcppStreams 0.1.4: Maintenance

Streamulus A new maintenance release of RcppStreams is now on CRAN marking the first release in almost six years. RcppStreams brings the excellent Streamulus C++ template library for event stream processing to R. Streamulus, written by Irit Katriel, uses clever template meta-programming (via Boost Fusion) to implement an embedded domain-specific event language created specifically for event stream processing. This release covers only package and CRAN-specific updates. The NEWS file entries follows below:

Changes in version 0.1.4 (2024-01-29)
  • Package maintenance with updates to DESCRIPTION and README.md
  • Continunous integration has been update multiple times
  • No longer set a C++ compilation standard

Courtesy of my CRANberries, there is also a diffstat report for this release. More detailed information is on the RcppStreams page page and of course on the Streamulus page. For questions, suggestions, or issues please use the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

29 January 2025

Keith Packard: picolibc-i18n

Internationalization support in Picolibc There are two major internationalization APIs in the C library: locales and iconv. Iconv is an isolated component which only performs charset conversion in ways that don't interact with anything else in the library. Locales affect pretty much every API that deals with strings and covers charset conversion along with a huge range of localized information from character classification to formatting of time, money, people's names, addresses and even standard paper sizes. Picolibc inherits it's implementation of both of these from newlib. Given that embedded applications rarely need advanced functionality from either these APIs, I hadn't spent much time exploring this space. Newlib locale code When run on Cygwin, Newlib's locale support is quite complete as it leverages the underlying Windows locale support. Without Windows support, everything aside from charset conversion and character classification data is stubbed out at the bottom of the stack. Because the implementation can support full locale functionality, the implementation is designed for that, with large data structures and lots of code. Charset conversion and character classification data for locales is all built-in; none of that can be loaded at runtime. There is support for all of the ISO-8859 charsets, three JIS variants, a bunch of Windows code pages and a few other single-byte encodings. One oddity in this code is that when using a JIS locale, wide characters are stored in EUC-JP rather than Unicode. Every other locale uses Unicode. This means APIs like wctype are implemented by mapping the JIS-encoded character to Unicode and then using the underlying Unicode character classification tables. One consequence of this is that there isn't any Unicode to JIS mapping provided as it isn't necessary. When testing the charset conversion and Unicode character classification data, I found numerous minor errors and a couple of pretty significant ones. The JIS conversion code had the most serious issue I found; most of the conversions are in a 2d array which is manually indexed with the wrong value for the length of each row. This led to nearly every translated value being incorrect. The charset conversion tables and Unicode classification data are now generated using python charset support and the standard Unicode data files. In addition, tests have been added which compare Picolibc to the system C library for every supported charset. Newlib iconv code The iconv charset support is completely separate from the locale charset support with a much wider range of supported targets. It also supports loading charset data from files at runtime, which reduces the size of application images. Because the iconv and locale implementations are completely separate, the charset support isn't the same. Iconv supports a lot more charsets, but it doesn't support all of those available to locales. For example, Iconv has Big5 support which locale lacks. Conversely, locale has Shift-JIS support which iconv does not. There's also a difference in how charset names are mapped in the two APIs. The locale code has a small fixed set of aliases, which doesn't include things like US-ASCII or ANSI X3.4. In contrast, the iconv code has an extensive database of charset aliases which are compiled into the library. Picolibc has a few tests for the iconv API which verify charset names and perform some translations. Without an external reference, it's hard to know if the results are correct. POSIX vs C internationalization In addition to including the iconv API, POSIX extends locale support in a couple of ways:
  1. Exposing locale objects via the newlocale, uselocale, duplocale and freelocale APIs.
  2. uselocale sets a per-thread locale, rather than the process-wide locale.
Goals for Picolibc internationalization support For charsets, supporting UTF-8 should cover the bulk of embedded application needs, and even that is probably more than what most applications require. Most (all?) compilers use Unicode for wide character and string constants. That means wchar_t needs to be Unicode in every locale. Aside from charset support, the rest of the locale infrastructure is heavily focused on creating human-consumable strings. I don't think it's a stretch to say that none of this is very useful these days, even for systems with sophisticated user interactions. For picolibc, the cost to provide any of this would be high. Having two completely separate charset conversion datasets makes for a confusing and error-prone experience for developers. Replacing iconv with code that leverages the existing locale support for translating between multi-byte and wide-character representations will save a bunch of source code and improve consistency. Embedded systems can be very sensitive to memory usage, both read-only and read-write. Applications not using internationalization capabilities shouldn't pay a heavy premium even when the library binary is built with support. For the most sensitive targets, the library should be configurable to remove unnecessary functionality. Picolibc needs to be conforming with at least the C language standard, and as much of POSIX as makes sense. Fortunately, the requirements for C are modest as it only includes a few locale-related APIs and doesn't include iconv. Finally, picolibc should test these APIs to make sure they conform with relevant standards, especially character set translation and character classification. The easiest way to do this is to reference another implementation of the same API and compare results. Switching to Unicode for JIS wchar_t This involved ripping the JIS to Unicode translations out of all of the wide character APIs and inserting them into the translations between multi-byte and wide-char representations. The missing Unicode to JIS translation was kludged by iterating over all JIS code points until a matching Unicode value was found. That's an obvious place for a performance improvement, but at least it works. Tiny locale This is a minimal implementation of locales which conforms with the C language standard while providing only charset translation and character classification data. It handles all of the existing charsets, but splits things into three levels
  1. ASCII
  2. UTF-8
  3. Extended, including any or all of: a. ISO 8859 b. Windows code pages and other 8-bit encodings c. JIS (JIS, EUC-JP and Shift-JIS)
When built for ASCII-only, all of the locale support is short-circuited, except for error checking. In addition, support in printf and scanf for wide characters is removed by default (it can be re-enabled with the -Dio-wchar=true meson option). This offers the smallest code size. Because the wctype APIs (e.g. iswupper) are all locale-specific, this mode restricts them to ASCII-only, which means they become wrappers on top of the ctype APIs with added range checking. When built for UTF-8, character classification for wide characters uses tables that provide the full Unicode range. Setlocale now selects between two locales, "C" and "C.UTF-8". Any locale name other than "C" selects the UTF-8 version. If the locale name contains "." or "-", then the rest of the locale name is taken to be a charset name and matched against the list of supported charsets. In this mode, only "us_ascii", "ascii" and "utf-8" are recognized. Because a single byte of a utf-8 string with the high-bit set is not a complete character, all of the ctype APIs in this mode can use the same implementation as the ASCII-only mode. This means the small ctype implementation is available. Calling setlocale(LC_ALL, "C.UTF-8") will allow the application to use the APIs which translate between multi-byte and wide-characters to deal with UTF-8 encoded strings. In addition, scanf and printf can read and write UTF-8 strings into wchar_t strings. Locale names are converted into locale IDs, an enumeration which lists the available locales. Each ID implies a specific charset as that's the only thing which differs between them. This means a locale can be encoded in a few bytes rather than an array of strings. In terms of memory usage, applications not using locales and not using the wctype APIs should see only a small increase in code space. That's due to the wchar_t support added to printf and scanf which need to translate between multi-byte and wide-character representations. There aren't any tables required as ASCII and UTF-8 are directly convertible to Unicode. On ARM-v7m, The added code in printf and scanf add up to about 1kB and another 32 bytes of RAM is used. The big difference when enabling extended charset support is that all of the charset conversion and character classification operations become table driven and dependent on the locale. Depending on the extended charsets supported, these can be quite large. With all of the extended charsets included, this adds an additional 30kB of code and static data and uses another 56 bytes of RAM. There are two known gaps in functionality compared with the newlib code:
  1. Locale strings that encode different locales for different categories. That's nominally required by POSIX as LC_ALL is supposed to return a string sufficient to restore the locale, but the only category which actually matters is LC_CTYPE.
  2. No nl_langinfo support. This would be fairly easy to add, returning appropriate constant values for each parameter.
Tiny locale was merged to picolibc main in this PR Tiny iconv Replacing the bulky newlib iconv code was far easier than swapping locale implementations. Essentially all that iconv does is compute two functions, one which maps from multi-byte to wide-char in one locale and another which maps from wide-char to multi-byte in another locale. Once the JIS locales were fixed to use Unicode, the new iconv implementation was straightforward. POSIX doesn't provide any _l version of mbrtowc or wcrtomb, so using standard C APIs would have been clunky. Instead, the implementation uses the internal APIs to compute the correct charset conversion functions. The entire implementation fits in under 200 lines of code. Tiny iconv is in process in this PR Future directions Right now, both of these new bits of code sit in the source tree parallel to the old versions. I'm not seeing any particular reason to keep the old versions around; they have provided a useful point of comparison in developing the new code, but I don't think they offer any compelling benefits going forward.

Sergio Talens-Oliag: Testing DeepSeek with Ollama and Open WebUI

With all the recent buzz about DeepSeek and its capabilities, I ve decided to give it a try using Ollama and Open WebUI on my work laptop which has an NVIDIA GPU:
$ lspci   grep NVIDIA
0000:01:00.0 3D controller: NVIDIA Corporation GA107GLM [RTX A2000 8GB Laptop GPU]
             (rev a1)
For the installation I initially I looked into the approach suggested on this article, but after reviewing it I decided to go for a docker only approach, as it leaves my system clean and updates are easier.

Step 0: Install dockerI already had it on my machine, so nothing to do here.

Step 1: Install the nvidia-container-toolkit packageAs it is needed to use the NVIDIA GPU with docker I followed the instructions to install the package using apt from the NVIDIA website.

Step 2: Run the Open WebUI container bundled with OllamaI could install ollama directly on linux or run it on docker, but I found out that there is a container with Open WebUI bundled with Ollama, so I decided to use it instead. To start the container I ve executed the following command:
docker run -d \
  -e OLLAMA_HOST="0.0.0.0:11434" -p 127.0.0.1:11434:11434 \
  -p 127.0.0.1:3000:8080 \
  -v ollama:/root/.ollama \
  -v open-webui:/app/backend/data \
  --gpus=all --name open-webui --restart always \
  ghcr.io/open-webui/open-webui:ollama
Once the container is up and running, I can access the Open WebUI on http://localhost:3000/ and the Ollama API on http://localhost:11434/ (I added the OLLAMA_HOST environment variable to be bind the server to all the container IPs, as it is needed to export it to the host).

Step 3: Install DeepSeek-R1 model from Open WebUIAfter creating an admin user on the Open WebUI, I went to the select a model button and asked to download the deepseek-r1 model (at the time of writing this it matches version deepseek-r1:7b, which uses 4.7GB of space). After the download was completed I was able to start chatting with the model on my local machine.

Step 4: Ask a questionThe first question I asked was Can you tell me what is Debian? and the answer I got was:
Debian is one of the most popular Linux distributions used worldwide. It is an
open-source operating system that has been around since 1993 and is known for
its stability, security, and reliability. Debian is widely used in servers, data
centers, and enterprise environments because it provides a robust base platform
with excellent documentation, tools, and community support.
### Key Features of Debian:

1. **History**:
   - Debian started as a project called "Pop!!" (Pootle) led by Lars Knutsen, a
     developer from Denmark.
   - It was initially forked from the Linux distribution Red Hat's RH-Debian to
     gain independence and reduce reliance on Red Hat.

2. **Use Cases**:
   - Debian is commonly used as an operating system for servers due to its
     reliability and ease of use in enterprise environments.
   - It is also used for individual user machines (laptops, desktops) because it
     offers a smooth and stable experience.
   - Debian provides the foundation for many popular derivatives like Ubuntu,
     which are designed for consumer use.

3. **Supported Architectures**:
   - Debian supports all major Linux architectures, including 32-bit and 64-bit
     systems, and runs on a wide range of hardware from old servers to modern
     smartphones.

4. **Package Management**:
   - Debian comes with a robust package management system called **Debian Policy
     Language (DPL)**, which allows users to easily install, update, and manage
     software packages.
   - This makes it easy for users to keep their systems up to date without
     needing to download multiple repositories or deal with version conflicts.

5. **Security Focus**:
   - Debian is known for its strong security practices. It has a reputation for
     being one of the most stable Linux distributions, making it a favorite
     among organizations that prioritize security.
   - The distribution regularly updates its software packages to patch
     vulnerabilities and protect against common attacks.

6. **Compatibility with Servers**:
   - Debian is widely used in data centers because it provides a consistent and
     reliable environment for running servers and applications.
   - Many open-source projects are compatible with Debian, making it an ideal
     choice for developers who want to work on servers or distributed systems.

7. **Popularity**:
   - Debian has a large and active community of users and contributors.
   - It is one of the most widely used Linux distributions in the world, with
     many enterprise organizations relying on it as their primary operating
     system.
### Comparison with Other Distributions:
- **Ubuntu**: Ubuntu is based on Debian but adds graphical user interfaces (like
  Gutsy Gibbon), modern tools (like GIMP and LibreOffice), and integrates with
  Microsoft services.
- **RHEL (Red Hat Enterprise Linux)**: RHEL is a derivative of Red Hat's
  distribution, which forked from Debian. It focuses more heavily on enterprise
  security and support compared to Debian.
### Why Debian?
Debian is popular because:
- It is free and open-source, making it accessible to anyone.
- It provides excellent documentation and tools for system administrators.
- It has a strong focus on stability and reliability.
- It supports a wide range of hardware and software needs.
If you're looking for a reliable and flexible Linux distribution that works well
in both personal and enterprise environments, Debian is an excellent choice.
Haven t tried the same question with ChatGPT, but the History, Package Management and Comparison with Other Distributions sections are hilarious, but they provided me with important data:
  • Now I know that APT is the real Debian Project Leader, what don t know is why we have elections each year ;)
  • Linux Distributions are recursive Debian was a fork of Red Hat, which was a fork of Debian, which was a fork of Red Hat,
As everybody is testing the model I will not talk more about the chat and the results, I just thought that this answer was really funny.

Step 5: Install the DeepSeek Coder and DeepSeek Coder v2 models from Open WebUIAs done before, to download the models I went to the select a model button and asked to download the deepseek-coder and deepseek-coder-v2 models (the default version of version one is said to be really quick and small, while version two is supposed to be better but slower and bigger, so I decided to install both for testing).

Step 6: Integrate Ollama with NeovimSince some months ago I ve been using Github Copilot with Neovim; I don t feel it has been very helpful in the general case, but I wanted to try it and it comes handy when you need to perform repetitive tasks when programming. It seems that there are multiple neovim plugins that support ollama, for now I ve installed and configured the codecompanion plugin on my config.lua file using packer:
require('packer').startup(function()
  [...]
  -- Codecompanion plugin
  use  
    "olimorris/codecompanion.nvim",
    requires =  
      "nvim-lua/plenary.nvim",
      "nvim-treesitter/nvim-treesitter",
     
   
  [...]
end)
[...]
-- --------------------------------
-- BEG: Codecompanion configuration
-- --------------------------------
-- Module setup
local codecompanion = require('codecompanion').setup( 
  adapters =  
    ollama = function()
      return require('codecompanion.adapters').extend('ollama',  
        schema =  
          model =  
            default = 'deepseek-coder-v2:latest',
           
         ,
       )
    end,
   ,
  strategies =  
    chat =   adapter = 'ollama',  ,
    inline =   adapter = 'ollama',  ,
   ,
 )
-- --------------------------------
-- END: Codecompanion configuration
-- --------------------------------
I ve tested it a little bit and it seems to work fine, but I ll have to test it more to see if it is really useful, I ll try to do it on future projects.

ConclusionAt a personal level I don t like nor trust AI systems, but as long as they are treated as tools and not as a magical thing you must trust they have their uses and I m happy to see that open source tools like Ollama and models like DeepSeek available for everyone to use.

Russ Allbery: Review: The Sky Road

Review: The Sky Road, by Ken MacLeod
Series: Fall Revolution #4
Publisher: Tor
Copyright: 1999
Printing: August 2001
ISBN: 0-8125-7759-0
Format: Mass market
Pages: 406
The Sky Road is the fourth book in the Fall Revolution series, but it represents an alternate future that diverges after (or during?) the events of The Sky Fraction. You probably want to read that book first, but I'm not sure reading The Stone Canal or The Cassini Division adds anything to this book other than frustration. Much more on that in a moment. Clovis colha Gree is a aspiring doctoral student in history with a summer job as a welder. He works on the platform for the project, which the reader either slowly discovers from the book or quickly discovers from the cover is a rocket to get to orbit. As the story opens, he meets (or, as he describes it) is targeted by a woman named Merrial, a tinker who works on the guidance system. The early chapters provide only a few hints about Clovis's world: a statue of the Deliverer on a horse that forms the backdrop of their meeting, the casual carrying of weapons, hints that tinkers are socially unacceptable, and some division between the white logic and the black logic in programming. Also, because this is a Ken MacLeod novel, everyone is obsessed with smoking and tobacco the way that the protagonists of erotica are obsessed with sex. Clovis's story is one thread of this novel. The other, told in the alternating chapters, is the story of Myra Godwin-Davidova, chair of the governing Council of People's Commissars of the International Scientific and Technical Workers' Republic, a micronation embedded in post-Soviet Kazakhstan. Series readers will remember Myra's former lover, David Reid, as the villain of The Stone Canal and the head of the corporation Mutual Protection, which is using slave labor (sort of) to support a resurgent space movement and its attempt to take control of a balkanized Earth. The ISTWR is in decline and a minor power by all standards except one: They still have nuclear weapons. So, first, we need to talk about the series divergence. I know from reading about this book on-line that The Sky Road is an alternate future that does not follow the events of The Stone Canal and The Cassini Division. I do not know this from the text of the book, which is completely silent about even being part of a series. More annoyingly, while the divergence in the Earth's future compared to The Cassini Division is obvious, I don't know what the Jonbar hinge is. Everything I can find on-line about this book is maddeningly coy. Wikipedia claims the divergence happens at the end of The Sky Fraction. Other reviews and the Wikipedia talk page claim it happens in the middle of The Stone Canal. I do have a guess, but it's an unsatisfying one and I'm not sure how to test its correctness. I suppose I shouldn't care and instead take each of the books on their own terms, but this is the type of thing that my brain obsesses over, and I find it intensely irritating that MacLeod didn't explain it in the books themselves. It's the sort of authorial trick that makes me feel dumb, and books that gratuitously make me feel dumb are less enjoyable to read. The second annoyance I have with this book is also only partly its fault. This series, and this book in particular, is frequently mentioned as good political science fiction that explores different ways of structuring human society. This was true of some of the earlier books in a surprisingly superficial way. Here, I would call it hogwash. This book, or at least the Myra portion of it, is full of people doing politics in a tactical sense, but like the previous books of this series, that politics is mostly embedded in personal grudges and prior romantic relationships. Everyone involved is essentially an authoritarian whose ability to act as they wish is only contested by other authoritarians and is largely unconstrained by such things as persuasion, discussions, elections, or even theory. Myra and most of the people she meets are profoundly cynical and almost contemptuous of any true discussion of political systems. This is the trappings and mechanisms of politics without the intellectual debate or attempt at consensus, turning it into a zero-sum game won by whoever can threaten the others more effectively. Given the glowing reviews I've seen in relatively political SF circles, presumably I am missing something that other people see in MacLeod's approach. Perhaps this level of pettiness and cynicism is an accurate depiction of what it's like inside left-wing political movements. (What an appalling condemnation of left-wing political movements, if so.) But many of the on-line reviews lead me to instead conclude that people's understanding of "political fiction" is stunted and superficial. For example, there is almost nothing Marxist about this book it contains essentially no economic or class analysis whatsoever but MacLeod uses a lot of Marxist terminology and sets half the book in an explicitly communist state, and this seems to be enough for large portions of the on-line commentariat to conclude that it's full of dangerous, radical ideas. I find this sadly hilarious given that MacLeod's societies tend, if anything, towards a low-grade libertarianism that would be at home in a Robert Heinlein novel. Apparently political labels are all that's needed to make political fiction; substance is optional. So much for the politics. What's left in Clovis's sections is a classic science fiction adventure in which the protagonist has a radically different perspective from the reader and the fun lies in figuring out the world-building through the skewed perspective of the characters. This was somewhat enjoyable, but would have been more fun if Clovis had any discernible personality. Sadly he instead seems to be an empty receptacle for the prejudices and perspective of his society, which involve a lot of quasi-religious taboos and an essentially magical view of the world. Merrial is a more interesting character, although as always in this series the romance made absolutely no sense to me and seemed to be conjured by authorial fiat and weirdly instant sexual attraction. Myra's portion of the story was the part I cared more about and was more invested in, aided by the fact that she's attempting to do something more interesting than launch a crewed space vehicle for no obvious reason. She at least faces some true moral challenges with no obviously correct response. It's all a bit depressing, though, and I found Myra's unwillingness to ground her decisions in a more comprehensive moral framework disappointing. If you're going to make a protagonist the ruler of a communist state, even an ironic one, I'd like to hear some real political philosophy, some theory of sociology and economics that she used to justify her decisions. The bits that rise above personal animosity and vibes were, I think, said better in The Cassini Division. This series was disappointing, and I can't say I'm glad to have read it. There is some small pleasure in finishing a set of award-winning genre books so that I can have a meaningful conversation about them, but the awards failed to find me better books to read than I would have found on my own. These aren't bad books, but the amount of enjoyment I got out of them didn't feel worth the frustration. Not recommended, I'm afraid. Rating: 6 out of 10

28 January 2025

Russ Allbery: Review: Moose Madness

Review: Moose Madness, by Mar Delaney
Publisher: Kalikoi
Copyright: May 2021
ASIN: B094HGT1ZB
Format: Kindle
Pages: 68
Moose Madness is a sapphic shifter romance novella (on the short side for a novella) by the same author as Wolf Country. It was originally published in the anthology Her Wild Soulmate, which appears to be very out of print. Maggie (she hates the nickname Moose) grew up in Moose Point, a tiny fictional highway town in (I think) Alaska. (There is, unsurprisingly, an actual Moose Point in Alaska, but it's a geographic feature and not a small town.) She stayed after graduation and is now a waitress in the Moose Point Pub. She's also a shifter; specifically, she is a moose shifter like her mother, the town mayor. (Her father is a fox shifter.) As the story opens, the annual Moose Madness festival is about to turn the entire town into a blizzard of moose kitsch. Fiona Barton was Maggie's nemesis in high school. She was the cool, popular girl, a red-headed wolf shifter whose friend group teased and bullied awkward and uncoordinated Maggie mercilessly. She was also Maggie's impossible crush, although the very idea seemed laughable. Fi left town after graduation, and Maggie hadn't thought about her for years. Then she walks into Moose Point Pub dressed in biker leathers, with piercings and one side of her head shaved, back in town for a wedding in her pack. Much to the shock of both Maggie and Fi, they realize that they're soulmates as soon as their eyes meet. Now what? If you thought I wasn't going to read the moose and wolf shifter romance once I knew it existed, you do not know me very well. I have been saving it for when I needed something light and fun. It seemed like the right palette cleanser after a very disappointing book. Moose Madness takes place in the same universe as Wolf Country, which means there are secret shifters all over Alaska (and presumably elsewhere) and they have the strong magical version of love at first sight. If one is a shifter, one knows immediately as soon as one locks eyes with one's soulmate and this feeling is never wrong. This is not my favorite romance trope, but if I get moose shifter romance out of it, I'll endure. As you can tell from the setup, this is enemies-to-lovers, but the whole soulmate thing shortcuts the enemies to lovers transition rather abruptly. There's a bit of apologizing and air-clearing at the start, but most of the novella covers the period right after enemies have become lovers and are getting to know each other properly. If you like that part of the arc, you will probably enjoy this, but be warned that it's slight and somewhat obvious. There's a bit of tension from protective parents and annoying pack mates, but it's sorted out quickly and easily. If you want the characters to work for the relationship, this is not the novella for you. It's essentially all vibes. I liked the vibes, though! Maggie is easy to like, and Fi does a solid job apologizing. I wish there was quite a bit more moose than we get, but Delaney captures the combination of apparent awkwardness and raw power of a moose and has a good eye for how beautiful large herbivores can be. This is not the sort of book that gives a moment's thought to wolves being predators and moose being, in at least some sense, prey animals, so if you are expecting that to be a plot point, you will be disappointed. As with Wolf Country, Delaney elides most of the messier and more ethically questionable aspects of sometimes being an animal. This is a sweet, short novella about two well-meaning and fundamentally nice people who are figuring out that middle school and high school are shitty and sometimes horrible but don't need to define the rest of one's life. It's very forgettable, but it made me smile, and it was indeed a good palette cleanser. If you are, like me, the sort of person who immediately thought "oh, I have to read that" as soon as you saw the moose shifter romance, keep your expectations low, but I don't think this will disappoint. If you are not that sort of person, you can safely miss this one. Rating: 6 out of 10

Next.

Previous.