Search Results: "zed"

21 June 2016

Ian Wienand: Zuul and Ansible in OpenStack CI

In a prior post, I gave an overview of the OpenStack CI system and how jobs were started. In that I said
(It is a gross oversimplification, but for the purposes of OpenStack CI, Jenkins is pretty much used as a glorified ssh/scp wrapper. Zuul Version 3, under development, is working to remove the need for Jenkins to be involved at all).
Well some recent security issues with Jenkins and other changes has led to a roll-out of what is being called Zuul 2.5, which has indeed removed Jenkins and makes extensive use of Ansible as the basis for running CI tests in OpenStack. Since I already had the diagram, it seems worth updating it for the new reality.
OpenStack CI Overview While previous post was really focused on the image-building components of the OpenStack CI system, overview is the same but more focused on the launchers that run the tests. Overview of OpenStack CI with Zuul and Ansible
  1. The process starts when a developer uploads their code to gerrit via the git-review tool. There is no further action required on their behalf and the developer simply waits for results of their jobs.

  2. Gerrit provides a JSON-encoded "fire-hose" output of everything happening to it. New reviews, votes, updates and more all get sent out over this pipe. Zuul is the overall scheduler that subscribes itself to this information and is responsible for managing the CI jobs appropriate for each change.

  3. Zuul has a configuration that tells it what jobs to run for what projects. Zuul can do lots of interesting things, but for the purposes of this discussion we just consider that it puts the jobs it wants run into gearman for a launcher to consume. gearman is a job-server; as they explain it "[gearman] provides a generic application framework to farm out work to other machines or processes that are better suited to do the work". Zuul puts into gearman basically a tuple (job-name, node-type) for each job it wants run, specifying the unique job name to run and what type of node it should be run on.

  4. A group of Zuul launchers are subscribed to gearman as workers. It is these Zuul launchers that will consume the job requests from the queue and actually get the tests running. However, a launcher needs two things to be able to run a job a job definition (what to actually do) and a worker node (somewhere to do it). The first part what to do is provided by job-definitions stored in external YAML files. The Zuul launcher knows how to process these files (with some help from Jenkins Job Builder, which despite the name is not outputting XML files for Jenkins to consume, but is being used to help parse templates and macros within the generically defined job definitions). Each Zuul launcher gets these definitions pushed to it constantly by Puppet, thus each launcher knows about all the jobs it can run automatically. Of course Zuul also knows about these same job definitions; this is the job-name part of the tuple we said it put into gearman. The second part somewhere to run the test takes some more explaining. To the next point...

  5. Several cloud companies donate capacity in their clouds for OpenStack to run CI tests. Overall, this capacity is managed by a customized management tool called nodepool (you can see the details of this capacity at any given time by checking the nodepool configuration). Nodepool watches the gearman queue and sees what requests are coming out of Zuul. It looks at node-type of jobs in the queue (i.e. what platform the job has requested to run on) and decides what types of nodes need to start and which cloud providers have capacity to satisfy demand. Nodepool will start fresh virtual machines (from images built daily as described in the prior post), monitor their start-up and, when they're ready, put a new "assignment job" back into gearman with the details of the fresh node. One of the active Zuul launchers will pick up this assignment job and register the new node to itself.

  6. At this point, the Zuul launcher has what it needs to actually get jobs started. With an fresh node registered to it and waiting for something to do, the Zuul launcher can advertise its ability to consume one of the waiting jobs from the gearman queue. For example, if a ubuntu-trusty node is provided to the Zuul launcher, the launcher can now consume from gearman any job it knows about that is intended to run on an ubuntu-trusty node type. If you're looking at the launcher code this is driven by the NodeWorker class you can see this being created in response to an assignment via LaunchServer.assignNode. To actually run the job where the "job hits the metal" as it were the Zuul launcher will dynamically construct an Ansible playbook to run. This playbook is a concatenation of common setup and teardown operations along with the actual test scripts the jobs wants to run. Using Ansible to run the job means all the flexibility an orchestration tool provides is now available to the launcher. For example, there is a custom console streamer library that allows us to live-stream the console output for the job over a plain TCP connection, and there is the possibility to use projects like ARA for visualisation of CI runs. In the future, Ansible will allow for better coordination when running multiple-node testing jobs after all, this is what orchestration tools such as Ansible are made for! While the Ansible run can be fairly heavyweight (especially when you're talking about launching thousands of jobs an hour), the system scales horizontally with more launchers able to consume more work easily. When checking your job results on logs.openstack.org you will see a _zuul_ansible directory now which contains copies of the inventory, playbooks and other related files that the launcher used to do the test run.

  7. Eventually, the test will finish. The Zuul launcher will put the result back into gearman, which Zuul will consume (log copying is interesting but a topic for another day). The testing node will be released back to nodepool, which destroys it and starts all over again nodes are not reused and also have no sensitive details on them, as they are essentially publicly accessible. Zuul will wait for the results of all jobs for the change and post the result back to Gerrit; it either gives a positive vote or the dreaded negative vote if required jobs failed (it also handles merges to git, but that is also a topic for another day).

Work will continue within OpenStack Infrastructure to further enhance Zuul; including better support for multi-node jobs and "in-project" job definitions (similar to the https://travis-ci.org/ model); for full details see the spec.

19 June 2016

Iustin Pop: Short trip to Seattle area

After last week's bike ride, I had to pack my bags, and get on Monday morning on a plane to Seattle. The time was so short that I even left the bike mounted on the car. So 8:15, plane to Frankfurt, and then plane to Seattle. To my big surprise, the Lufthansa "extended leg room" seats were overly generous; I could actually extend my foot completely and put it on the back of the seat in front of me. Very good value when travelling in economy The only downside was that these were "standard" not "premium" economy, so the seat had leg room but was very narrow. And with normal sized adults on either side of me, it was somewhat difficult. The leg space allowed me to work on my laptop without fearing the person in front of me will recline their seat and break my screen (almost happened once). The funniest thing when travelling is that food is always tricky: even familiar food can be not what you expect. Case in point, me at the salad buffet, seeing slices of green vegetables, and asking myself: Are those jalapeno slices, or bell pepper slices? Hmm, I'm sure they're bell pepper , which resulted in my first vegetable salad with jalapeno. Would definitely recommend if you like spicy things! Otherwise the trip was as usual, but shorter and more densely packed with meetings with a one day exception: had the opportunity to experience for the first time Whirlyball, which was more fun and more difficult than it first looked. Also spent an afternoon on Whidbey Island, which fortunately was also the nicest day, weather-wise, of the week (all phone pictures, not colour corrected, straight-out-of-phone): from the ferry at the end of Hobbit Trail before dinner A few more pictures here. I keep being amazed by the nature in this area, definitely my preferred place in US from the relatively few I visited. Had a nice dinner as well at Cafe Langley, which surprisingly had reasonably-authentic Mediterranean food; the Baba Ganoush was excellent. Other than that outing, nothing worth describing, except that I really missed my Zwift or outdoor rides. The experience of using the stationary bikes in the hotel does not compare, so I resorted more to running on the treadmill (hmm, Zwift for running, hmm ); if the foot pod calibration is to be trusted, I continued to slightly improve my 1K, 1mi, and 5K times. Not bad, I might want to join some running races as well this summer, but I need to take it easy though and make sure to not get injured again. And finally, week over, flew back home, slept a bit mid-day (which will ruin my jet lag recovery program), unloaded my bike from the car (and checked it still works), and and and got on the trainer and did a Zwift ride. Jet lagged, but managed to beat my Watopia sprint record by a tiny bit, and complete a new workout ( The Gorby ), which was interesting. I can stop any time I want, definitely (I just need to take a trip away from home ).

Elena 'valhalla' Grandi: StickerConstructorSpec compliant swirl

StickerConstructorSpec compliant swirl

This evening I've played around a bit with the Sticker Constructor Specification https://github.com/terinjokes/StickerConstructorSpec and its https://github.com/terinjokes/StickerConstructorSpec/blob/master/assets/hexagonal-sticker_template.svg, and this is the result:

Immagine/fotohttp://social.gl-como.it/photos/valhalla/image/e8ee069635b2823e168c358d2a753f14


Now I just have to:

* find somebody in Europe who prints good stickers and doesn't require illustrator (or other proprietary software) to submit files for non-rectangular shapes
* find out which Debian team I should contact to submit the files so that they can be used by everybody interested.

But neither will happen today, nor probably tomorrow, because lazy O:-)

Edit: now that I'm awake I realized I forgot to thank @Enrico Zini Zini and MadameZou for their help in combining my two proposals in a better design.

Source svg http://social.gl-como.it/attach/3

18 June 2016

Sune Vuorela: R is for Randa

This week I have been gathered with 38 KDE people in Randa, Switzerland. Randa is a place in a valley in the middle of the Alps close to various peaks like Matterhorn. It has been a week of intense hacking, bugfixing, brainstorming and a bit of enjoying the nature. R is for Reproducible builds I spent the first couple of days trying to get the Qt Documentation generation tool to reproducible generate documentation. Some of the fixes were of the usual put data in an randomized datastructure, then iterate over it and create output , where the fix is similar well known: Sort the datastructure first. Others were a bit more severe bugs that lead to the documentation to shuffle around the obsolete bit, and the inheritance chains. Most of these fixes have been reviewed and submitted to the Qt 5.6 branch, one is still pending review, but that hopefully gets fixed soon. Then most of Qt (except things containing copies of (parts) of webkit and derivatives) should be reproducible. R is for Roaming around in the mountains Sleeping, hacking and dining in the same building sometimes leads to a enormous desire for fresh air. Luckily in the middle of the alps, it is readily available, and at least once a day many people went for a walk. To say hi to a sheep. Or to just go uphill until tired and then going back down. Or just finding a circle around. For this area, OpenStreetMap seems to have better maps than Google. We also went on a nice group trip to Zermatt and surroundings, sponsored by our friends in Edeltech. R is for Releasing One of the tasks I set myself for was to get my barcode generation library (prison. you know. being behind bars.) ready for release. A bit of api cleanup, including some future proofing, was done, and all users adapted. Hopefully it will be released as part of the next KDE Frameworks release. R is for Reviewing code When signing up for the sprint, one has to declare a couple of tasks to work on. One of the things I put myself up to was reviewing David Faure s code changes. First, he is very productive, and second, he often gets into creating patches in code areas where many other contributors are scared to look. So someone has to do it, and code never scared me. R is for Running I planned on going running along the river monday, wednesday and friday. Fortunately that happened, but due to Switzerland having a bit more ups and downs than flat Denmark, it didn t go that fast. R is for Random bugfixing When in the hacking mood surrounded by great developers, it is very easy to just fix minor bugs when you encounter them. There is likely someone around who knows the code in question. Or you are just in the mood to actually fix it, rather than living with a missing clock applet or a corner case crash. R is for Rubber ducking I am a brilliant person sized rubber duck. And I did get the opportunity to show off my skills a couple of times, as well as using some of the other people for that. R is for Raising money These sprints in Randa is only possible because of all the nice donations from people and companies around the world. The fundraiser is still running, and can be found at

12 June 2016

Mario Lang: A Raspberry Pi Zero in a Handy Tech Active Star 40 Braille Display

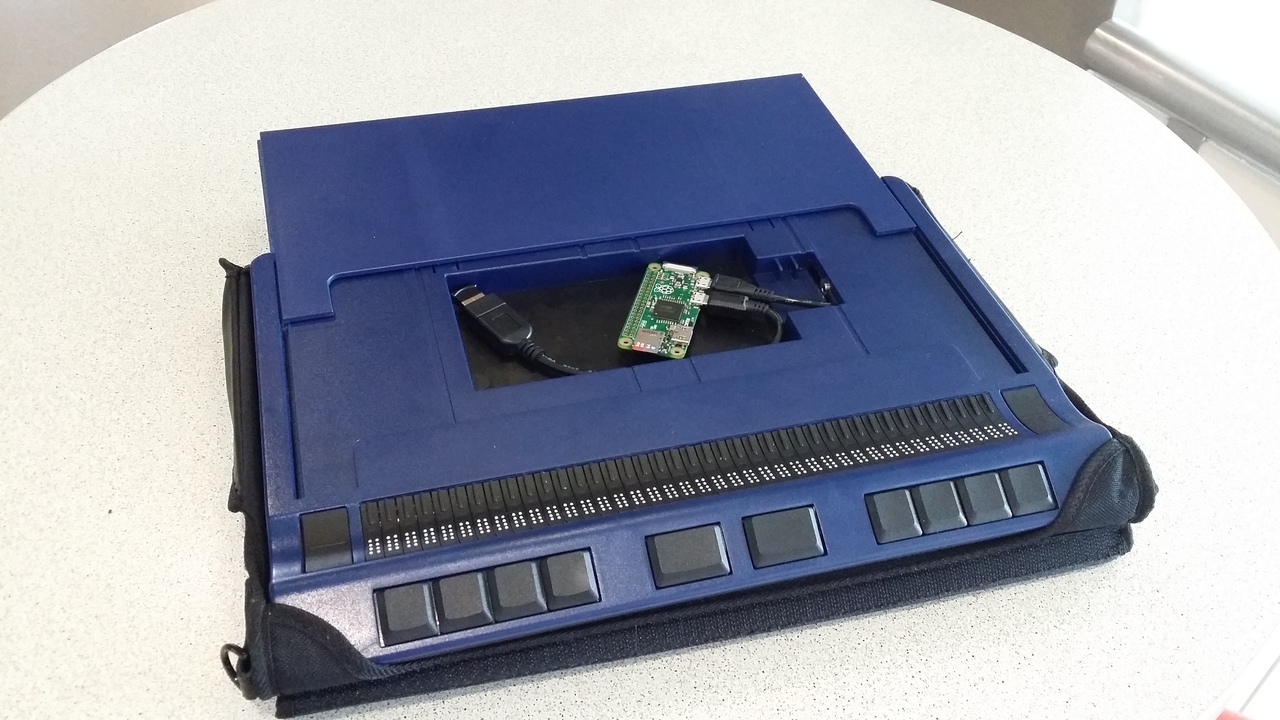
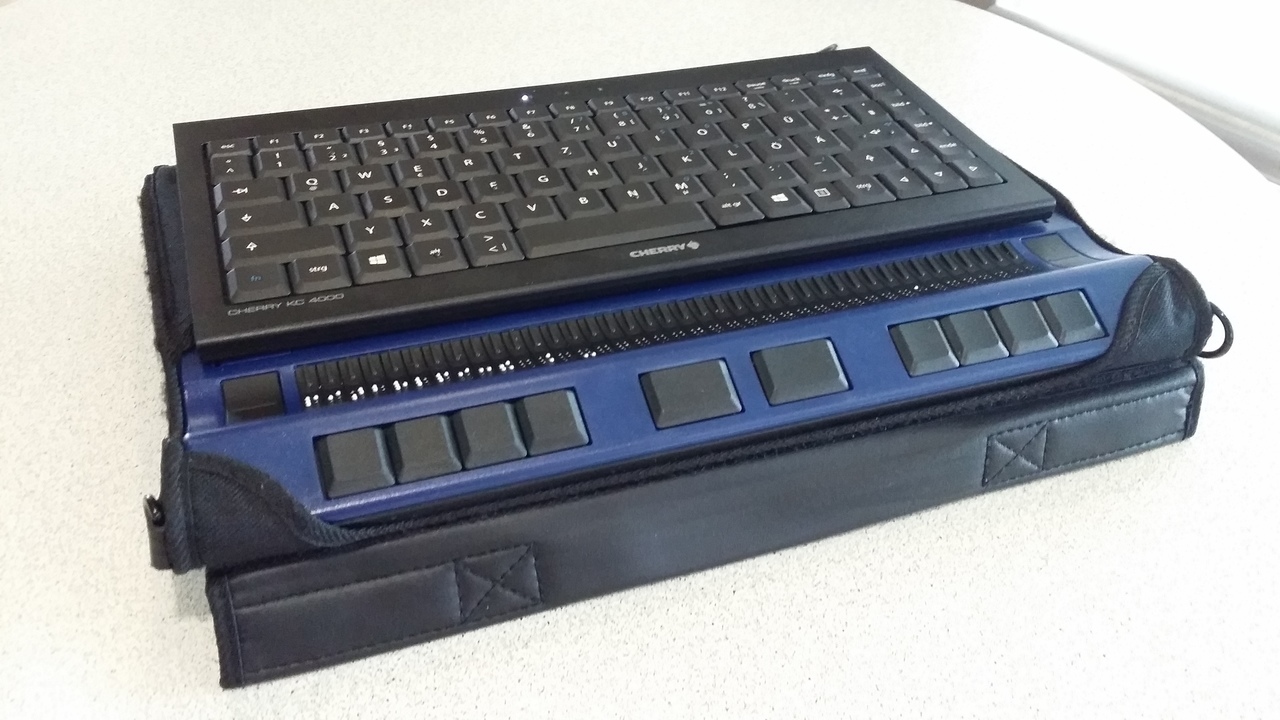
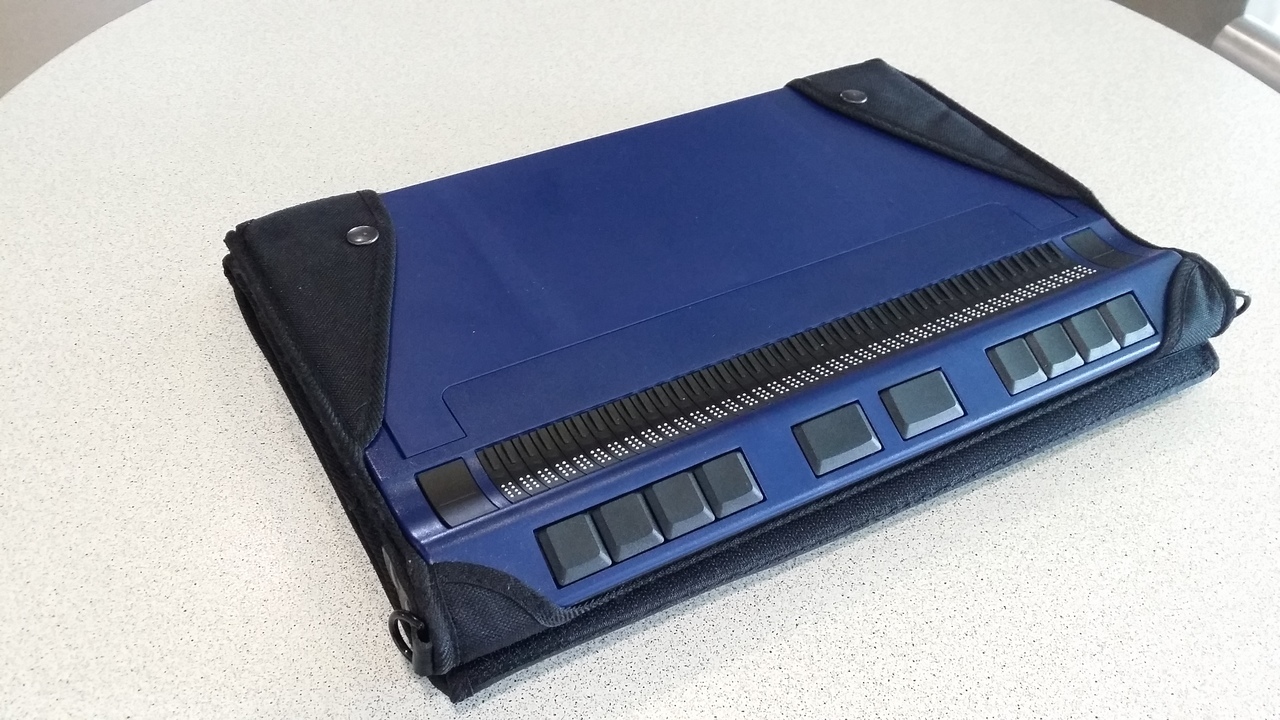
TL;DR: I put a $5 Raspberry Pi Zero, a Bluetooth USB dongle, and the required adapter cable into my new Handy Tech Active Star 40 braille display. An internal USB port provides the power. This has transformed my braille display into an ARM-based, monitorless, Linux laptop that has a keyboard and a braille display. It can be charged/powered via USB so it can also be run from a power bank or a solar charger, thus potentially being able to run for days, rather than just hours, without needing a standard wall-jack. [picture: a Raspberry Pi Zero embedded within an Active Star 40] [picture: a braille display with a keyboard on top and a Raspberry Pi Zero inside]
Some Background on Braille Display Form Factors Braille displays come in various sizes. There are models tailored for desktop use (with 60 cells or more), models tailored for portable use with a laptop (usually with 40 cells), and, nowadays, there are even models tailored for on-the-go use with a smartphone or similar (with something like 14 or 18 cells). Back in the old days, braille displays were rather massive. A 40-cell braille display was typically about the size of a 13" laptop. In modern times, manufacturers have managed to reduce the size of the internals such that a 40-cell display can be placed in front of a laptop or keyboard instead of placing the laptop on top of the braille display. While this is a nice achievement, I personally haven't found it to be very convenient because you now have to place two physically separate devices on your lap. It's OK if you have a real desk, but, at least in my opinion, if you try to use your laptop as its name suggests, it's actually inconvenient to use a small form factor, 40-cell display. For this reason, I've been waiting for a long-promised new model in the Handy Tech Star series. In 2002, they released the Handy Tech Braille Star 40, which is a 40-cell braille display with enough space to put a laptop directly on top of it. To accommodate larger laptop models, they even built in a little platform at the back that can be pulled out to effectively enlarge the top surface. Handy Tech has now released a new model, the Active Star 40, that has essentially the same layout but modernized internals. [picture: a plain Active Star 40] You can still pull out the little platform to increase the space that can be used to put something on top. [picture: an Active Star 40 with extended platform and a laptop on top] But, most conveniently, they've designed in an empty compartment, roughly the size of a modern smartphone, beneath the platform. The original idea was to actually put a smartphone inside, but this has turned out (at least to me) to not be very feasible. Fortunately, they thought about the need for electricity and added a Micro USB cable terminating within the newly created, empty compartment. My first idea was to put a conventional Raspberry Pi inside. When I received the braille display, however, we immediately noticed that a standard-sized rpi is roughly 3mm too high to fit into the empty compartment. Fortunately, though, a co-worker noticed that the Raspberry Pi Zero was available for order. The Raspberry Pi Zero is a lot thinner, and fits perfectly inside (actually, I think there's enough space for two, or even three, of them). So we ordered one, along with some accessories like a 64GB SDHC card, a Bluetooth dongle, and a Micro USB adapter cable. The hardware arrived a few days later, and was immediately bootstrapped with the assistance of very helpful friends. It works like a charm!
Technical Details The backside of the Handy Tech Active Star 40 features two USB host ports that can be used to connect devices such as a keyboard. A small form-factor, USB keyboard with a magnetic clip-on is included. When a USB keyboard is connected, and when the display is used via Bluetooth, the braille display firmware additionally offers the Bluetooth HID profile, and key press/release events received via the USB port are passed through to it. I use the Bluetooth dongle for all my communication needs. Most importantly, BRLTTY is used as a console screen reader. It talks to the braille display via Bluetooth (more precisely, via an RFCOMM channel). The keyboard connects through to Linux via the Bluetooth HID profile. Now, all that is left is network connectivity. To keep the energy consumption as low as possible, I decided to go for Bluetooth PAN. It appears that the tethering mode of my mobile phone works (albeit with a quirk), so I can actually access the internet as long as I have cell phone reception. Additionally, I configured a Bluetooth PAN access point on my desktop machines at home and at work, so I can easily (and somewhat more reliably) get IP connectivity for the rpi when I'm near one of these machines. I plan to configure a classic Raspberry Pi as a mobile Bluetooth access point. It would essentially function as a Bluetooth to ethernet adapter, and should allow me to have network connectivity in places where I don't want to use my phone.
BlueZ 5 and PAN It was a bit challenging to figure out how to actually configure Bluetooth PAN with BlueZ 5. I found the bt-pan python script (see below) to be the only way so far to configure PAN without a GUI. It handles both ends of a PAN network, configuring a server and a client. Once instructed to do so (via D-Bus) in client mode, BlueZ will create a new network device - bnep0 - once a connection to a server has been established. Typically, DHCP is used to assign IP addresses for these interfaces. In server mode, BlueZ needs to know the name of a bridge device to which it can add a slave device for each incoming client connection. Configuring an address for the bridge device, as well as running a DHCP server + IP Masquerading on the bridge, is usually all you need to do.
A Bluetooth PAN Access Point with Systemd I'm using systemd-networkd to configure the bridge device. /etc/systemd/network/pan.netdev:
[NetDev]
Name=pan
Kind=bridge
ForwardDelaySec=0
/etc/systemd/network/pan.network:
[Match]
Name=pan
[Network]
Address=0.0.0.0/24
DHCPServer=yes
IPMasquerade=yes
Now, BlueZ needs to be told to configure a NAP profile. To my surprise, there seems to be no way to do this with stock BlueZ 5.36 utilities. Please correct me if I'm wrong. Luckily, I found a very nice blog post, as well as an accommodating Python script that performs the required D-Bus calls. For convenience, I use a Systemd service to invoke the script and to ensure that its dependencies are met. /etc/systemd/system/pan.service:
[Unit]
Description=Bluetooth Personal Area Network
After=bluetooth.service systemd-networkd.service
Requires=systemd-networkd.service
PartOf=bluetooth.service
[Service]
Type=notify
ExecStart=/usr/local/sbin/pan
[Install]
WantedBy=bluetooth.target
/usr/local/sbin/pan:
#!/bin/sh
# Ugly hack to work around #787480
iptables -F
iptables -t nat -F
iptables -t mangle -F
iptables -t nat -A POSTROUTING -o eth0 -j MASQUERADE
exec /usr/local/sbin/bt-pan --systemd --debug server pan
This last file wouldn't be necessary if IPMasquerade= were supported in Debian right now (see #787480). After the obligatory systemctl daemon-reload and systemctl restart systemd-networkd, you can start your Bluetooth Personal Area Network with systemctl start pan.
Bluetooth PAN Client with Systemd Configuring the client is also quite easy to do with Systemd. /etc/systemd/network/pan-client.network:
[Match]
Name=bnep*
[Network]
DHCP=yes
/etc/systemd/system/pan@.service:
[Unit]
Description=Bluetooth Personal Area Network client
[Service]
Type=notify
ExecStart=/usr/local/sbin/bt-pan --debug --systemd client %I --wait
Now, after the usual configuration reloading, you should be able to connect to a specific Bluetooth access point with:
systemctl start pan@00:11:22:33:44:55
Pairing via the Command Line Of course, the server and client-side service configuration require a pre-existing pairing between the server and each of its clients. On the server, start bluetoothctl and issue the following commands:
power on
agent on
default-agent
scan on
scan off
pair XX:XX:XX:XX:XX:XX
trust XX:XX:XX:XX:XX:XX
Once you've set scan mode to on, wait a few seconds until you see the device you're looking for scroll by. Note its device address, and use it for the pair and (optional) trust commands. On the client, the sequence is essentially the same except that you don't need to issue the trust command. The server needs to trust a client in order to accept NAP profile connections from it without waiting for manual confirmation by the user. I'm actually not sure if this is the optimal sequence of commands. It might be enough to just pair the client with the server and issue the trust command on the server, but I haven't tried this yet.
Enabling Use of the Bluetooth HID Profile Essentially the same as above also needs to be done in order to use the Bluetooth HID profile of the Active Star 40 on Linux. However, instead of agent on, you need to issue the command agent KeyboardOnly. This explicitly tells bluetoothctl that you're specifically looking for a HID profile.
Configuring Bluetooth via the Command Line Feels Vague While I'm very happy that I actually managed to set all of this up, I must admit that the command-line interface to BlueZ feels a bit incomplete and confusing. I initially thought that agents were only for PIN code entry. Now that I've discovered that "agent KeyboardOnly" is used to enable the HID profile, I'm not sure anymore. I'm surprised that I needed to grab a script from a random git repository in order to be able to set up PAN. I remember, with earlier version of BlueZ, that there was a tool called pand that you could use to do all of this from the command-line. I don't seem to see anything like that for BlueZ 5 anymore. Maybe I'm missing something obvious?
Performance The data rate is roughly 120kB/s, which I consider acceptable for such a low power solution. The 1GHz ARM CPU actually feels sufficiently fast for a console/text-mode person like me. I'll rarely be using much more than ssh and emacs on it anyway.
Console fonts and screen dimensions The default dimensions of the framebuffer on the Raspberry Pi Zero are a bit unexpectedly strange. fbset reports that the screen dimension is 656x416 pixels (of course, no monitor connected). With a typical console font of 8x16, I got 82 columns and 26 lines. With a 40 cell braille display, the 82 columns are very inconvenient. Additionally, as a braille user, I would like to be able to view Unicode braille characters in addition to the normal charset on the console. Fortunately, Linux supports 512 glyphs, while most console fonts do only provide 256. console-setup can load and combine two 256-glyph fonts at once. So I added the following to /etc/default/console-setup to make the text console a lot more friendly to braille users:
SCREEN_WIDTH=80
SCREEN_HEIGHT=25
FONT="Lat15-Terminus16.psf.gz brl-16x8.psf"

Note

You need console-braille installed for brl-16x8.psf to be available.

Further Projects There's a 3.5mm audio jack inside the braille display as well. Unfortunately, there are no converters from Mini-HDMI to 3.5mm audio that I know of. It would be very nice to be able to use the sound card that is already built into the Raspberry Pi Zero, but, unfortunately, this doesn't seem possible at the moment. Alternatively, I'm looking at using a Micro USB OTG hub and an additional USB audio adapter to get sound from the Raspberry Pi Zero to the braille display's speakers. Unfortunately, the two USB audio adapters I've tried so far have run hot for some unknown reason. So I have to find some other chipset to see if the problem goes away. A little nuisance, currently, is that you need to manually power off the Raspberry, wait a few seconds, and then power down the braille display. Turning the braille display off cuts power delivery via the internal USB port. If this is accidentally done too soon then the Raspberry Pi Zero is shut down ungracefully (which is probably not the best way to do it). We're looking into connecting a small, buffering battery to the GPIO pins of the rpi, and into notifying the rpi when external power has dropped. A graceful, software-initiated shutdown can then be performed. You can think of it as being like a mini UPS for Micro USB.
The image If you are a happy owner of a Handy Tech Active Star 40 and would like to do something similar, I am happy to share my current (Raspbian Stretch based) image. In fact, if there is enough interest by other blind users, we might even consider putting a kit together that makes it as easy as possible for you to get started. Let me know if this could be of interest to you.
Thanks Thanks to Dave Mielke for reviewing the text of this posting. Thanks to Simon Kainz for making the photos for this article. And I owe a big thank you to my co-workers at Graz University of Technology who have helped me a lot to bootstrap really quickly into the rpi world.
P.S. My first tweet about this topic is just five days ago, and apart from the soundcard not working yet, I feel like the project is already almost complete! By the way, I am editing the final version of this blog posting from my newly created monitorless ARM-based Linux laptop via an ssh connection to my home machine.

10 June 2016

Valerie Young: Week 1 on Reproducible Builds

In this post I m reviewing what I ve done the last 6 days of Outreachy-funded reproducible builds work, outline what I plan to do the next two weeks, and speculate on long term goals. For those of you involved in the Debian reproducible builds project, please provide feedback about future plans and work! Week One review One week of Outreachy completed! What have I done? The change that broke everything was the addition of a directory: tests.reproducible-builds.org/debian The directory was added to contain all Debian-specific pages, in line with the other project s reproducible builds status pages: arch linux, fedora, coreboot, etcs. Previously, all Debian pages we simply served directly out of the DocumentRoot. To fix all the broken things, I m pretty sure I had to find, inspect, and add /debian or change global variables within every file pointer in the entire tests website. Sometime tedious, but chasing down bugs and complaints was mostly fun  I also learned (everything I now know) about Apache websites, redirects, the website/navigation/directory structure of tests.reproducible-builds.org, and the roles of many of the reproducible scripts in jenkins.debian.net/bin. Week Two plan What will or should I do next? In the short term, over the next two weeks, I hope to make useful improvements to the tests website and backend while continuing to get up to speed (as well as learn Python). Have other thoughts about minor improvements to tests.reproducible-builds.org? Please let me know! The above list is not internally prioritized, feel free to ask for things to be bubbled up. Longer-term goals My long term summer goal is to make the Debian test code more easily extensible to show the reproducible results from other projects. This will lower the barrier for new projects to keep track of the reproducibility of their code, for great good. This starts with the reproducible.db database, which presently only tracks reproducible testing results for the Debian project. The reproducible builds project s needs have outgrown the original SQLight database, so this redesigning includes a migration to Postgre. Goals of the redesign include ease of querying/comparing packages across distributions, as well as generalization to include results from projects other than Debian. I ll start on this work in two weeks, when I get to DebCamp!  Redesigning the database will also lead to updating the python script which use that data to produce the Debian tests website. Other project scripts (like Fedora, RedHat and Coreboot) can then be updated to track results in the database as well, instead simply directly producing their own test websites. update: as an intermediate step before redesigned the reproducible.db database to handle multiple projects h01ger recommended I help the FreeBSD project recorded tests to a FreeBSD specific database.

8 June 2016

Gunnar Wolf: University degrees and sysadmin skills

I'll tune in to the post-based conversation being held on Planet Debian: Russell Coker wonders about what's needed to get university graduates with enough skills for a sysadmin job, to which Lucas Nussbaum responds with his viewpoints. They present a very contrasting view of what's needed for students And for a good reason, I'd say: Lucas is an academician; I don't know for sure about Russell, but he seems to be a down-to-the-earth, dirty-handed, proficient sysadmin working on the field. They both contact newcomers to their fields, and will notice different shortcomings. I tend to side with Lucas' view. That does not come as a surprise, as I've been working for over 15 years in an university, and in the last few years I started walking from a mostly-operative sysadmin in an academic setting towards becoming an academician that spends most of his time sysadmining. Subtle but important distinction. I teach at the BSc level at UNAM, and am a Masters student at IPN (respectively, Mexico's largest and second-largest universities). And yes, the lack of sysadmin abilities in both is surprising. But so is a good understanding of programming. And I'm sure that, were I to dig into several different fields, I'd feel the same: Student formation is very basic at each of those fields. But I see that as natural. Of course, if I were to judge people as geneticists as they graduate from Biology, or were I to judge them as topologists as they graduate from Mathematics, or any other discipline in which I'm not an expert, I'd surely not know where to start Given I have about 20 years of professional life on my shoulders, I'm quite skewed as to what is basic for a computing professional. And of course, there are severe holes in my formation, in areas I never used. I know next to nothing of electronics, my mathematical basis is quite flaky, and I'm a poor excuse when talking about artificial intelligence. Where am I going with this? An university degree (BSc in English, would amount to "licenciatura" in Spanish) is not for specialization. It is to have a sufficiently broad panorama of the field, and all of the needed tools to start digging deeper and specializing either by yourself, working on a given field and learning its details as you go, or going through a postgraduate program (Specialization, Masters, Doctorate). Even most of my colleagues at the Masters in Engineering in Security and Information Technology lack of a good formation in fields I consider essential. However, what does information security mean? Many among them are working on legal implications of several laws that touch our field. Many other are working on authenticity issues in images, audios and other such media. Many other are trying to come up with mathematical ways to cheapen the enormous burden of crypto operations (say, "shaving" CPU cycles off a very large exponentiation). Others are designing autonomous learning mechanisms to characterize malware. Were I as a computing professional to start talking about their research, I'd surely reveal I know nothing about it and get laughed at. That's because I haven't specialized in those fields. University education should give a broad universal basis to enter a professional field. It should not focus on teaching tools or specific procedures (although some should surely be presented as examples or case studies). Although I'd surely be happy if my university's graduates were to know everything about administering a Debian system, that would be wrong for a university to aim at; I'd criticize it the same way I currently criticize programs that mix together university formation and industry certification as if they were related.

Francois Marier: Simple remote mail queue monitoring

In order to monitor some of the machines I maintain, I rely on a simple email setup using logcheck. Unfortunately that system completely breaks down if mail delivery stops. This is the simple setup I've come up with to ensure that mail doesn't pile up on the remote machine.

Server setup The first thing I did on the server-side is to follow Sean Whitton's advice and configure postfix so that it keeps undelivered emails for 10 days (instead of 5 days, the default):
postconf -e maximal_queue_lifetime=10d
Then I created a new user:
adduser mailq-check
with a password straight out of pwgen -s 32. I gave ssh permission to that user:
adduser mailq-check sshuser
and then authorized my new ssh key (see next section):
sudo -u mailq-check -i
mkdir ~/.ssh/
cat - > ~/.ssh/authorized_keys

Laptop setup On my laptop, the machine from where I monitor the server's mail queue, I first created a new password-less ssh key:
ssh-keygen -t ed25519 -f .ssh/egilsstadir-mailq-check
cat ~/.ssh/egilsstadir-mailq-check.pub
which I then installed on the server. Then I added this cronjob in /etc/cron.d/egilsstadir-mailq-check:
0 2 * * * francois /usr/bin/ssh -i /home/francois/.ssh/egilsstadir-mailq-check mailq-check@egilsstadir mailq   grep -v "Mail queue is empty"
and that's it. I get a (locally delivered) email whenever the mail queue on the server is non-empty. There is a race condition built into this setup since it's possible that the server will want to send an email at 2am. However, all that does is send a spurious warning email in that case and so it's a pretty small price to pay for a dirt simple setup that's unlikely to break.

6 June 2016

John Goerzen: How git-annex replaces Dropbox + encfs with untrusted providers

git-annex has been around for a long time, but I just recently stumbled across some of the work Joey has been doing to it. This post isn t about it s traditional roots in git or all the features it has for partial copies of large data sets, but rather for its live syncing capabilities like Dropbox. It takes a bit to wrap your head around, because git-annex is just a little different from everything else. It s sort of like a different-colored smell. The git-annex wiki has a lot of great information both low-level reference and a high-level 10-minute screencast showing how easy it is to set up. I found I had to sort of piece together the architecture between those levels, so I m writing this all down hoping it will benefit others that are curious. Ir you just want to use it, you don t need to know all this. But I like to understand how my tools work. Overview git-annex lets you set up a live syncing solution that requires no central provider at all, or can be used with a completely untrusted central provider. Depending on your usage pattern, this central provider could require only a few MBs of space even for repositories containing gigabytes or terabytes of data that is kept in sync. Let s take a look at the high-level architecture of the tool. Then I ll illustrate how it works with some scenarios. Three Layers Fundamentally, git-annex takes layers that are all combined in Dropbox and separates them out. There is the storage layer, which stores the literal data bytes that you are interested in. git-annex indexes the data in storage by a hash. There is metadata, which is for things like a filename-to-hash mapping and revision history. And then there is an optional layer, which is live signaling used to drive the real-time syncing. git-annex has several modes of operation, and the one that enables live syncing is called the git-annex assistant. It runs as a daemon, and is available for Linux/POSIX platforms, Windows, Mac, and Android. I ll be covering it here. The storage layer The storage layer simply is blobs of data. These blobs are indexed by a hash, and can be optionally encrypted at rest at remote backends. git-annex has a large number of storage backends; some examples include rsync, a remote machine with git-annex on it that has ssh installed, WebDAV, S3, Amazon Glacier, removable USB drive, etc. There s a huge list. One of the git-annex features is that each client knows the state of each storage repository, as well as the capability set of each storage repository. So let s say you have a workstation at home and a laptop you take with you to work or the coffee shop. You d like changes on one to be instantly recognized on another. With something like Dropbox or OwnCloud, every file in the set you want synchronized has to reside on a server in the cloud. With git-annex, it can be configured such that the server in the cloud only contains a copy of a file until every client has synced it up, at which point it gets removed. Think about it that is often what you want anyhow, so why maintain an unnecessary copy after it s synced everywhere? (This behavior is, of course, configurable.) git-annex can also avoid storing in the cloud entirely if the machines are able to reach each other directly at least some of the time. The metadata layer Metadata about your files includes a mapping from the file names to the storage location (based on hashes), change history, and information about the status of each machine that participates in the syncing. On your clients, git-annex stores this using git. This detail is very useful to some, and irrelevant to others. Some of the git-annex storage backends can support only storage (S3, for instance). Some can support both storage and metadata (rsync, ssh, local drives, etc.) You can even configure a backend to support only metadata (more on why that may be useful in a bit). When you are working with a git-backed repository for git-annex, it can hold data, metadata, or both. So, to have a working sync system, you must have a way to transport both the data and the metadata. The transport for the metadata is generally rsync or git, but it can also be XMPP in which Git changesets are basically wrapped up in XMPP presence messages. Joey says, however, that there are some known issues with XMPP servers sometimes dropping or reordering some XMPP messages, so he doesn t encourage that method currently. The live signaling layer So once you have your data and metadata, you can already do syncs via git annex sync --contents. But the real killer feature here will be automatic detection of changes, both on the local and the remote. To do that, you need some way of live signaling. git-annex supports two methods. The first requires ssh access to a remote machine where git-annex is installed. In this mode of operation, when the git-annex assistant fires up, it opens up a persistent ssh connection to the remote and runs the git-annex-shell over there, which notifies it of changes to the git metadata repository. When a change is detected, a sync is initiated. This is considered ideal. A substitute can be XMPP, and git-annex actually converts git commits into a form that can be sent over XMPP. As I mentioned above, there are some known reliability issues with this and it is not the recommended option. Encryption When it comes to encryption, you generally are concerned about all three layers. In an ideal scenario, the encryption and decryption happens entirely on the client side, so no service provider ever has any details about your data. The live signaling layer is encrypted pretty trivially; the ssh sessions are, of course, encrypted and TLS support in XMPP is pervasive these days. However, this is not end-to-end encryption; those messages are decrypted by the service provider, so a service provider could theoretically spy on metadata, which may include change times and filenames, though not the contents of files themselves. The data layer also can be encrypted very trivially. In the case of the dumb backends like S3, git-annex can use symmetric encryption or a gpg keypair and all that ever shows up on the server are arbitrarily-named buckets. You can also use a gcrypt-based git repository. This can cover both data and metadata and, if the target also has git-annex installed, the live signalling layer. Using a gcrypt-based git repository for the metadata and live signalling is the only way to accomplish live syncing with 100% client-side encryption. All of these methods are implemented in terms of gpg, and can support symmetric of public-key encryption. It should be noted here that the current release versions of git-annex need a one-character patch in order to fix live syncing with a remote using gcrypt. For those of you running jessie, I recommend the version in jessie-backports, which is presently 5.20151208. For your convenience, I have compiled an amd64 binary that can drop in over /usr/bin/git-annex if you have this version. You can download it and a gpg signature for it. Note that you only need this binary on the clients; the server can use the version from jessie-backports without issue. Putting the pieces together: some scenarios Now that I ve explained the layers, let s look at how they fit together. Scenario 1: Central server In this scenario, you might have a workstation and a laptop that sync up with each other by way of a central server that also has a full copy of the data. This is the scenario that most closely resembles Dropbox, box, or OwnCloud. Here you would basically follow the steps in the git-assistant screencast: install git-annex on a server somewhere, and point your clients to it. If you want full end-to-end encryption, I would recommend letting git-annex generate a gpg keypair for you, which you would then need to copy to both your laptop and workstation (but not the server). Every change you make locally will be synced to the server, and then from the server to your other PC. All three systems would be configured in the client transfer group. Scenario 1a: Central server without a full copy of the data In this scenario, everything is configured the same except the central server is configured with the transfer transfer group. This means that the actual data synced to it is deleted after it has been propagated to all clients. Since git-annex can verify which repository has received a copy of which data, it can easily enough delete the actual file content from the central server after it has been copied to all the clients. Many people use something like Dropbox or OwnCloud as a multi-PC syncing solution anyhow, so once the files have been synced everywhere, it makes sense to remove them from the central server. This is often a good ideal for people. There are some obvious downsides that are sometimes relevant. For instance, to add a third sync client, it must be able to initially copy down from one of the existing clients. Or, if you intend to access the data from a device such as a cell phone where you don t intend for it to have a copy of all data all the time, you won t have as convenient way to download your data. Scenario 1b: Split data/metadata central servers Imagine that you have a shell or rsync account on some remote system where you can run git-annex, but don t have much storage space. Maybe you have a cheap VPS or shell account somewhere, but it s just not big enough to hold your data. The answer to this would be to use this shell or rsync account for the metadata, but put the data elsewhere. You could, for instance, store the data in Amazon S3 or Amazon Glacier. These backends aren t capable of storing the git-annex metadata, so all you need is a shell or rsync account somewhere to sync up the metadata. (Or, as below, you might even combine a fully distributed approach with this.) Then you can have your encrypted data pushed up to S3 or some such service, which presumably will grow to whatever size you need. Scenario 2: Fully distributed Like git itself, git-annex does not actually need a central server at all. If your different clients can reach each other directly at least some of the time, that is good enough. Of course, a given client will not be able to do fully automatic live sync unless it can reach at least one other client, so changes may not propagate as quickly. You can simply set this up by making ssh connections available between your clients. git-annex assistant can automatically generate appropriate ~/.ssh/authorized_keys entries for you. Scenario 2a: Fully distributed with multiple disconnected branches You can even have a graph of connections available. For instance, you might have a couple machines at home and a couple machines at work with no ability to have a direct connection between them (due to, say, firewalls). The two machines at home could sync with each other in real-time, as could the two machines at work. git-annex also supports things like USB drives as a transport mechanism, so you could throw a USB drive in your pocket each morning, pop it in to one client at work, and poof both clients are synced up over there. Repeat when you get home in the evening, and you re synced there. The USB drive s repository can, of course, be of the transport type so data is automatically deleted from it once it s been synced everywhere. Scenario 3: Hybrid git-annex can support LAN sync even if you have a central server. If your laptop, say, travels around but is sometimes on the same LAN as your PC, git-annex can easily sync directly between the two when they are reachable, saving a round-trip to the server. You can assign a cost to each remote, and git-annex will always try to sync first to the lowest-cost path that is available. Drawbacks of git-annex There are some scenarios where git-annex with the assistant won t be as useful as one of the more traditional instant-sync systems. The first and most obvious one is if you want to access the files without the git-annex client. For instance, many of the other tools let you generate a URL that you can email to people, and then they can download files without any special client software. This is not directly possible with git-annex. You could, of course, make something like a public_html directory be managed with git-annex, but it wouldn t provide things like obfuscated URLs, password-protected sharing, time-limited sharing, etc. that you get with other systems. While you can share your repositories with others that have git-annex, you can t share individual subdirectories; for a given repository, it is all or nothing. The Android client for git-annex is a pretty interesting thing: it is mostly a small POSIX environment, providing a terminal, git, gpg, and the same web interface that you get on a standalone machine. This means that the git-annex Android client is fully functional compared to a desktop one. It also has a quick setup process for syncing off your photos/videos. On the other hand, the integration with the Android ecosystem is poor compared to most other tools. Other git-annex features git-annex has a lot to offer besides the git-annex assistant. Besides the things I ve already mentioned, any given git-annex repository including your client repository can have a partial copy of the full content. Say, for instance, that you set up a git-annex repository for your music collection, which is quite large. You want some music on your netbook, but don t have room for it all. You can tell git-annex to get or drop files from the netbook s repository without deleting them remotely. git-annex has quite a few ways to automate and configure this, including making sure that at least a certain number of copies of a file exist in your git-annex ecosystem. Conclusion I initially started looking at git-annex due to the security issues with encfs, and the difficulty with setting up ecryptfs in this way. (I had been layering encfs atop OwnCloud). git-annex certainly ticks the box for me security-wise, and obviously anything encrypted with encfs wasn t going to be shared with others anyhow. I ll be using git-annex more in the future, I m sure.

5 June 2016

Simon McVittie: Flatpak in Debian

Quite a lot has happened in xdg-app since last time I blogged about it. Most noticeably, it isn't called xdg-app any more, having been renamed to Flatpak. It is now available in Debian experimental under that name, and the xdg-app package that was briefly there has been removed. I'm currently in the process of updating Flatpak to the latest version 0.6.4. The privileged part has also spun off into a separate project, Bubblewrap, which recently had its first release (0.1.0). This is intended as a common component with which unprivileged users can start a container in a way that won't let them escalate privileges, like a more flexible version of linux-user-chroot. Bubblewrap has also been made available in Debian, maintained by Laszlo Boszormenyi (also maintainer of linux-user-chroot). Yesterday I sent a patch to update Laszlo's packaging for 0.1.0. I'm hoping to become a co-maintainer to upload that myself, since I suspect Flatpak and Bubblewrap might need to track each other quite closely. For the moment, Flatpak still uses its own internal copy of Bubblewrap, but I consider that to be a bug and I'd like to be able to fix it soon. At some point I also want to experiment with using Bubblewrap to sandbox some of the game engines that are packaged in Debian: networked games are a large attack surface, and typically consist of the sort of speed-optimized C or C++ code that is an ideal home for security vulnerabilities. I've already made some progress on jailing game engines with AppArmor, but making sensitive files completely invisible to the game engine seems even better than preventing them from being opened. Next weekend I'm going to be heading to Toronto for the GTK Hackfest, primarily to to talk to GNOME and Flatpak developers about their plans for sandboxing, portals and Flatpak. Hopefully we can make some good progress there: the more I know about the state of software security, the less happy I am with random applications all being equally privileged. Newer display technologies like Wayland and Mir represent an opportunity to plug one of the largest holes in typical application containerization, which is a major step in bringing sandboxes like Flatpak and Snap from proof-of-concept to a practical improvement in security. Other next steps for Flatpak in Debian:

Jamie McClelland: Signal and Mobile XMPP Update

First, many thanks to Planet Debian readers for your thoughtful and constructive feedback to my Signal and Mobile Instant Messaging blogs. I learned a lot. Particularly useful was the comment directing me to Daniel Gultsch's The State of Mobile in 2016 post. I had previously listed the outstanding technical challenges as: I am now fairly convined that both problems are well-solved on Android via the Conversations app and a well-tuned XMPP server (I had no idea how easy it was to install your own Prosody modulues -- the client state indicator module is only 22 lines of lua code!) I think the current technical challenges could be better summarized as: adding iOS (iPhone) support. Both end-to-end encryption and receiving messages consistently seem to be hurdles. However, it seems that Chris Ballinger and the Chat Secure team are well on their way toward solving the push issue and facing funder skittishness on the encryption front. Nonetheless, but seem to be progressing. With the obvious technical hurdles in progress, we have the luxury of talking about the less obvious ones - particularly the ones requiring trade-offs. In particular: Signal replaces your SMS client. It looks and feels like an SMS client and automatically sends un-encrypted messages to everyone your address book that is not on signal and sends encrypted messages to those that are on signal. The significance of this feature is hard to over-state. It differentiates tools by and for technically minded people and those designed for a mass audience. When I convince people to use Conversations, in contrast, I have to teach them to: For most people who don't (yet) have their friends XMPP addresses or for people who don't have any friends who use XMPP, it means that they will install it, send me a few messages and then never use it again. The price Signal pays for this convenience is steep: Signal seems to synchronize your entire address book to their servers so they can keep a map of cell phone numbers to signal users. It's not only creepy (I get a text message everytime someone in my address book joins Signal) but it's flies in the face of expectations for a privacy-minded application. How could we take advantage of this feature, without the privacy problems? What if... The main downside (which Signal faces as well) is that you have to contend with the complexities of sending SMS messages on top of the work needed to write a well-functioning XMPP client. As I mentioned in my Signal blog, there are no shortage of MMS bugs against Signal. Nobody wants that head-ache. Additinally, we would still lose one Signal feature: with Signal, when a user joins, everyone automatically sends them encrypted messages. With this proposed app, each user would have to manually add the XMPP address and have no way of knowing when one of their friends gets an XMPP address. Any other ideas?

3 June 2016

Simon D saulniers: Google Summer Of Code

I am part of the group of students working with the Debian organization. You can see my profile on the Debian wiki here.

Improving distributed and secure communication using free software This the title of my project for this summer. It sounds good, but what am I going to really do? Well, since I m a student at Universit du Qu bec Montr al, I have had the opportunity to meet with the company Savoir-Faire Linux in Montreal last year and that s when I found out about their exciting project: Ring.
Ring is one of the few projects which bring communication confidentiality and freedom in the hands of the users.

OpenDHT Ring is divided in multiple components as explained here: https://ring.cx/en/about/technical. The component I work on is called OpenDHT. This is the distributed hash table which enables Ring users to communicate in a decentralized network. I have already been working on this project for a year now, so you won t see me posting reports where I say I have to find my way around in this project. In fact, I have contributed to rewriting a major part of the code for better maintainability. In the begining of last summer, I was able to be part of a research association between Savoir-Faire Linux and Universit du Qu bec Montr al. We have been working on adding two major features to OpenDHT.

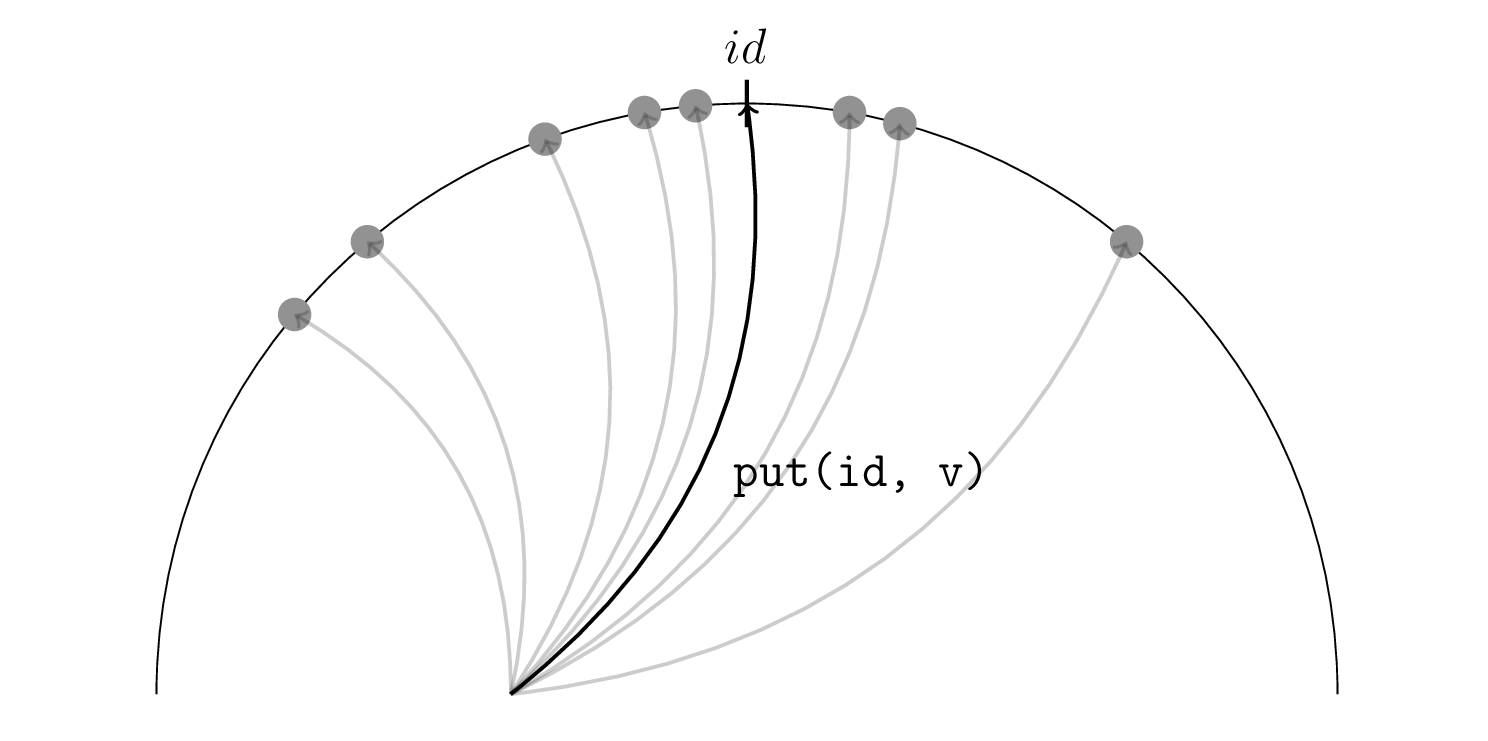
Short introduction to Distributed Hash Tables OpenDHT is based on the Kademlia design. If you know about DHTs, you are aware that they define the notion of distance using the XOR metric. This makes the tuple (H_n, xor) a metric space, where H_n is the space of identifier keys of length n. This way, you can find an identifier be the closest to a target hash than the rest of the nodes in the network.
In order to find some data that is associated with some hash h, you have to find the nodes in the network for which the distance between their hash identifier and the target hash h is minimized. The group of nodes which are the closest to the target hash (OpenDHT allows up to 8 nodes) will hold data for that hash.

Data persistence Let s say you ask a group of 8 nodes to hold some data for a hash and you want the data to hold the whole time until its expiration time as come. If the group of 8 nodes change because that for some reason those nodes leave or others just arrive and have an id that is closer to the target hash than the initial group of 8 nodes. The data would then not be found on the new group of 8 nodes. A first and simple solution was to count on the initial creator of the value to periodically announce the value to the group of 8 nodes. However, what if this node leaves? This is one of the main problem that I ve been working on solving since 2015. A first version of this was produced on September 2015. However, we experienced traffic issues and were forced to redesign the OpenDHT network requests engine. We are presently working on adding a Query feature that would enable filtering of data on remote nodes, hence substantially lowering the overall traffic produced by a response to a get request.

Indexation During the last year, I have also been working on the design of a solution for the use case of indexation. In a more technical way, this is the capability to find data by providing a map where its key is a string field and the mapped value is the value associated to that field, much like in a form. This could help find data for which you don t know the hash, but you have specific information about its content. In other words, this would be a search engine for OpenDHT. I have already created a working, but still in progress, version of this. You can find it on http://opendht.net, on the index branch. Now, Nicolas Reynaud (kaldoran) is contributing to this during the GSOC.

Roadmap As I explained on my page on the Debian Wiki, I am going to work on:
  1. Developing new functionalities in OpenDHT aiming at reducing overall generated traffic.
  2. Maintenance and optimization of the OpenDHT code in general.
  3. Optimizing data persistence solution over the distributed hash table.
  4. Merge (1) in the Ring daemon component in order to benefit from lower traffic in Ring.
  5. Make OpenDHT use TCP protocol instead of UDP. This is going to reduce code complexity and enhance robsutness of the DHT.
For further details, read my reports!

2 June 2016

Jamie McClelland: Mobile Instant Messaging

Now that I've gone down the signal road, when can I get off of it? The two contenders I've found for more politically conscious mobile-friendly instant messaging are Tox and XMPP. And the problems to solve are: The Tox Project has a great design (peer-to-peer) and handles end-to-end encryption as part of its core design. However, the Antox mobile client has not only failed to solve the battery drain problem but seems to also have a serious bandwidth issue as well. Also, what is up with this drama? How about XMPP? For years, XMPP clients have been using OTR - and many instant messaging applications support it, including ChatSecure. And now, there seems to be quite a bit of excitement around implementing a better protocol called OMEMO. Incidentally, the OMEMO protocol uses the same Double Ratchet (previously referred to as the Axolotl Ratchet) protocol that Signal uses. While there are some irritating hiccups around using the available GPL library for Double Ratchet on iPhone apps, it seems like these issues are being sorted out and soon we'll have some kind of standard way for XMPP clients to exchange end-to-end encrypted messages. Let's move on to notifications and battery drain. If you believe the author of the Android Conversations App there doesn't seem to be a problem. However, client state indication seems to be the only issue related to battery drainage he addresses and I couldn't figure out how to easily install that extension on our Debian Jessie prosody instance since it isn't included in the prosody-modules package in Debian and it requires additional modules for it to work. Chris Ballinger, the author of ChatSecure (iOS and Android XMPP app), is less optimistic about this problem in general. In short, he thinks we need a proper "push" mechanism and has even started to implement one. At the same time, a new (and different) XMPP standard called Push Notifications - XEP-0357 has been released and it is even implemented in Prosody (although not yet available in Debian). So the future seems bright, right? Well, not exactly. All of this "push" activity seems to solve this problem: A federated/decentralized application cannot properly use Apple's APNs or Google's GCM. In the words of Chris Ballinger:
The biggest problem is that there is no easy way to send push messages between my app and your app. For me to send a push to one of your app s users on iOS, I must first obtain an APNs SSL certificate/key pair from you, and one of your user s push token that uniquely identifies their device to Apple. These push tokens are potentially sensitive information because they allow Apple to locate your device (in order to send it a push).
So, even if we manage to get one of these two standards for push notifications up and running, we have only succeeded in solving Signal's centralization problem, not the dependence on Google Play Services and Apple Push Network (in fact it's quite mysterious to me how you could even use the Prosody implementation of Push Notifications with GCM or APN). So... what we really would need would be to figure out how to implement one of these two push standards and then get it to work with an alternative to GCM and APN (perhaps MQTT)? Which, I think would require changes to the XMPP client. Geez. I may be on Signal longer than I planned.

1 June 2016

Jamie McClelland: Signal and Google Cloud Services

I just installed Signal on my Android phone. It wasn't an easy decision. I have been running Cyanogenmod, a Google-free version of Android, and installing apps from F-Droid, a repository of free software android apps, for several years now. This setup allows me to run all the applications I need without Google accessing any of my cell phone data. It has been a remarkably successful experiment leaving me with all the phone software I need. And it's consistent with my belief that Google's size, reach and goals are a menace to the left's ability to develop the autonomous communications systems on the Internet that we need to achieve any meaningful political change. However, if I want to install Signal, I have to install Google Play, and the only way to install Google Play is to install Google's base line set of apps and to connect your cell phone to a Gmail account. Why in the world would Signal require Google Play? There is plenty of discussion of the technical debate on this topic, but politically it boils down to this: security is about trade-offs, and the trade-offs you find important are based on your politics. While I consider Signal to be on the same team in the big picture, I think Signal's winning a short term victory for more massively adopted end-to-end encryption at the expense of a longer term and more important struggle for autonomous communication systems specifically for communities fighting corporate power (of which Google itself is an important target) and fighting US hegemony on a global scale. Furthermore, Signal's lead developer's outright hostility to alternate clients connecting to the centralized signal servers demonstrates another political decision that favors central control over any confidence in a broader movement control over what could have become a power new protocol for secure communication. And his refusal to grant an exemption for other developers to use just the encryption algorythm is frustrating to say the least. Given this reasoning, why install Signal? The main reason is because I have yet to convince anyone to remove Google Apps from their phone and Signal, right now, represents a dramatic improvement over most people's current communications habit. And, when it comes down to it, I need to run what I recommend. I'm still running both conversations and Antox which are far better alternatives in the long run. However until they gain more widespread adoption, I'll be experimenting with Signal. Technical Details Oh, and by the way, installing Google Apps nearly bricked my phone. Cyanogenmod's web site conveniently provides instructions for installing Google Apps. However, confusingly, they provide two different links to choose from, one is from OpenGapps which provided my a link to download the zip file to flash on a non-https page (the link itself was over https). The other link was to an https-enabled page on androidfilehost.com that offered a non-https download (but did provide a md5 checksum). I am now sure why people offering software downloads don't enable https from start to finish (well, maybe I do - I haven't yet enabled https on this site...). However, more confusing is that both links were to different files. The OpenGapps one seemed to be a daily build and the androidfilehost was to a file with the date 20140606 in it's name, suggesting it was built nearly 2 years ago. I went with the daily build. When I restarted, I got the error "Unfortunately, Android Keyboard (Aosp) Has Stopped." If you search the web for this error you will see loads of people getting it. However, none of them seem to be using an encrypted disk. Yes, that is a bigger problem since you can't enter your encrypted disk passphrase if your keyboard app has crashed and you can't boot your phone if you can't even hit enter at the passphrase prompt. If you can't boot, you can't clear the keyboard app cache or most of the suggestions. In fact, when you press and hold the power key you don't even get the option to reboot into recovery mode. And, if you connect your device to your USB cable and run the adb tool on your computer, the tool reports that you are not authorized to connect your device. Oh damn. Did I just brick my phone? Fortunately, you can still boot into recovery mode on a Samsung S4 by powering it off. Then, press and hold the up volume button while turning it on. In recovery mode, I as able to convince the adb tool to connect to my device and I copied over the other Gapps zip file from androidfilehost.com and flashing that one seems to have fixed the problem. Once I booted, I ran Google Play and opted to create a new Google Account. I chose the option to not sync my data. Then, I checked in Settings -> Accounts I saw that a Google Account was there and was synchronizing. Great. What was it synchronizing? I clicked the account, then clicked "Accounts and Privacy" and ensured that everything was turned off. Let's hope that works. [Update] Signal's option to take over as your default SMS client and send un-encrypted normal SMS messages while sending encrypted messages to other Signal users is a very good way to smooth adoption. Unfortunately I had some problems with MMS message for which I found a work-around. But sheesh, lots of MMS problems at the moment.

Keerthana Krishnan: Things I wish someone told me about Debian 8 (Jessie) installation

After using Ubuntu for the past 5+ years, I m pretty used to linux. The huge mistake I made was assuming that Debian installation would be as easy as Ubuntu. Truth : It isn t. Ubuntu is much more user friendly and tame. Debian is much more larger with more cuztomisation options, something that might be overwhelming to those used to the slick UX of Unity. Disclaimer : This guide is for people who are used to linux, preferably some other distro like Fedora or Ubuntu and wants to change to Debian. Note : If you want to dual boot Debian with Fedora, install debian first. Fedora is pretty good at the partition adjustment thing. Now go ahead and install all the software you want! A good list is given here. Have fun with your new OS! (Edit: I m still getting used to Debian so any and all comments about the above are welcome!  )

30 May 2016

Daniel Stender: My work for Debian in May

No double posting this time ;-) I've got not so much spare time this month to spend on Debian, but I could work on the following packages: This series of blog postings also includes little introductions of and into new packages in the archive. This month there is: Pyinfra Pyinfra is a new project which is currently still in development state. It has been already pointed out in an interesting German article1, and is now available as package maintained within the Python Applications Team. It's currently a one man production by Nick Barrett, and eagerly developed in the past weeks (we're currently at 0.1~dev24). Pyinfra is a remote server configuration/provisioning/service deployment tool which belongs in the same software category like Puppet or Ansible2. It's for provisioning one or an array of remote servers with software packages and to configure them. Pyinfra runs agentless like Ansible, that means for using it nothing special (like a daemon) has to run on targeted servers. It's written to be used for provisioning POSIX compatible Linux systems and has alternatives when it comes to special features like package managers (e.g. supports apt as well as yum). The documentation could be found in usr/share/doc/pyinfra/html/. Here's a little crash course on how to use Pyinfra: The pyinfra CLI tool is used on the command line like this, deploy scripts, single operations or facts (see below) could be used on a single server or a multitude of remote servers:
$ pyinfra -i <inventory script/single host> <deploy script>
$ pyinfra -i <inventory script/single host> --run <operation>
$ pyinfra -i <inventory script/single host> --facts <fact>
Remote servers which are operated on must provide a working shell and they must be reachable by SSH. For connecting, --port, --user, --password, --key/--key-password and --sudo flags are available, --sudo to gain superuser rights. Root access or sudo rights of course have to be already set up. By the way, localhost could be operated on the same way. Single operations are organized in modules like "apt", "files", "init", "server" etc. With the --run option they could be used individually on servers like follows, e.g. server.user adds a new user on a single targeted system (-v adds verbosity to the pyinfra run):
$ pyinfra -i 192.0.2.10 --run server.user sam --user root --key ~/.ssh/sshkey --key-password 123456 -v
Multiple servers can be grouped in inventories, which hold the targeted hosts and data associated with them, like e.g. an inventory file farm1.py would contain lists like this:
COMPUTE_SERVERS = ['192.0.2.10', '192.0.2.11']
DATABASE_SERVERS = ['192.0.2.20', '192.0.2.21']
Group designators must be all caps. A higher level of grouping are the file names of inventory scripts, thus COMPUTE_SERVERS and DATABASE_SERVERS can be referenced to at the same time by the group designator farm1. Plus, all servers are automatically added to the group all. And, inventory scripts should be stored in the subfolder inventory/ in the project directory. Inventory files then could be used instead of specific IP addresses like this, the single operation then gets performed on all given machines in farm1.py:
$ pyinfra -i inventory/farm1.py  --run server.user sam --user root --key ~/.ssh/sshkey --key-password=123456 -v
Deployment scripts could be used together with group data files in the subfolder group_data/ in the project directory. For example, a group_data/farm1.py designates all servers given in inventory/farm1.py (by the way, all.py designates all servers), and contains the random attribute user_name (attributes must be lowercase), next to authentication data for the whole inventory group:
user_name = 'sam'
ssh_user = 'root'
ssh_key = '~/.ssh/sshkey'
ssh_key_password = '123456'
The random attribute can be picked up by a deployment script using host.data() like follows, user_name could be used again for e.g. server.user(), like this:
from pyinfra import host
from pyinfra.modules import server
server.user(host.data.user_name)
This deploy, the ensemble of inventory file, group data file and deployment script (usually placed top level in the project folder) then could be run that way:
$ pyinfra -i inventory/farm1.py deploy.py
You have guessed it, since deployment scripts are Python scripts they are fully programmable (please regard that Pyinfra is build & runs on Python 3 on Debian), and that's the main advantage point with this piece of software. Quite handy for that come Pyinfra facts, functions which check different things on remote systems and return information as Python data. Like e.g. deb_packages returns a dictionary of installed packages from a remote apt based server:
$ pyinfra -i 192.0.2.10 --fact deb_packages --user root --key ~/.ssh/sshkey --key-password=123456
 
    "192.0.2.10":  
        "libdebconfclient0": "0.192",
        "python-debian": "0.1.27",
        "libavahi-client3": "0.6.31-5",
        "dbus": "1.8.20-0+deb8u1",
        "libustr-1.0-1": "1.0.4-3+b2",
        "sed": "4.2.2-4+b1",
Using facts, Pyinfra reveals its full potential. For example, a deployment script could go like this, linux.distribution() returns a dict containing the installed distribution:
from pyinfra import host
from pyinfra.modules import apt
if host.fact.linux_distribution['name'] == 'Debian':
   apt.packages(packages='gummi', present=True, update=True)
elif host.fact.linux_distribution['name'] == 'CentOS':
   pass
I'll spare more sophisticated examples to keep this introduction simple. Beyond fancy deployment scripts, Pyinfra features an own API by which it could be programmed from the outside, and much more. But maybe that's enough to introduce Pyinfra. That are the usage basics. Pyinfra is a brand new project and it remains to be seen whether the developer can keep on further developing the tool like he does these days. For a private project it's insane to attempt to become a contender for the established "big" free configuration management tools and frameworks, but, if Puppet has become too complex in the meanwhile or not3, I really don't think that's the point here. Pyinfra follows an own approach in being programmable the way which it is. And it's definitely not harm to have it in the toolbox already, not trying to replace nothing. Brainstorm After the first package has been in experimental, the Brainstorm library from Swiss AI research institute IDSIA4 is now available as python3-brainstorm in unstable. Brainstorm is a lean, easy-to-use library for setting up deep learning networks (multiple layered artificial neural networks) for machine learning applications like for image and speech recognition or natural language processing. To set up a working training network for a classifier for handwritten digits like the MNIST dataset (a usual "hello world") just takes a couple of lines, like an example demonstrates. The package is maintained within the Debian Python Modules Team. The Debian package ships a couple of examples in /usr/share/python3-brainstorm/examples (the data/ and examples/ folders of the upstream tarball are combined here). Among them there are5: The current documentation in /usr/share/doc/python3-brainstorm/html/ isn't complete yet (several chapters are under construction), but there's a walkthrough on the CIFAR-10 example. The MNIST example has been extended by Github user pinae, and has been explained in German C't recently6. What are the perspectives for further development? Like Zhou Mo confirmed, there are a couple of deep learning frameworks around having a rather poor outlook since there have been abandoned after being completed as PhD projects. There's really no point for thriving to have them all in Debian, like the ITP of Minerva has been given up partly for this reason, there weren't any commits since 08/2015 (and because cuDNN isn't available and most likely won't). Brainstorm, 0.5 have been released 05/2015, also was a PhD project as IDSIA. It's stated on Github that the project is "under active development", but the rather sparse project page on the other side expresses the "hope the community will help us to further improve Brainstorm". This sentence much often implies that the developers are not actively working on the project. But there are recent commits and it looks that upstream is active and could be reached when there are problems, and that the project is active. So I don't think we're riding a dead horse, here. The downside for Brainstorm in Debian is, it seems that the libraries which are needed for GPU accelerated processing can't be fully provided. Pycuda is available, but scikit-cuda (an additional library which provides wrappers for CUDA features like CUBLAS, CUFFT and CUSOLVER) is not and won't be, because the CULA Dense Toolkit (scikit-cuda also contains wrappers for also that) is not available freely as source. Because of that, a dependency against pycuda, not even as Suggests (it's non-free), has been spared. Without GPU acceleration, Brainstorm computes the matrices on openBLAS using a Cython wrapper on the NumpyHandler, and the PyCudaHandler couldn't be used. openBLAS makes pretty good use of the available hardware (it distributes over all available CPU cores), but it's not yet possible to run Brainstorm full throttle using available floating point devices to reduce training times, which becomes crucial when the projects are getting bigger. Brainstorm belongs to the number of deep learning frameworks already being or becoming available in Debian. Currently there is: I've checked over Microsoft's CNTK, but although it's also set free recently I have my doubts if that could be included. Apparently there are dependencies against non-free software and most likely other issues. So much for a little update on the state of deep learning in Debian, please excuse if my radar misses something.

  1. Tim Sch rmann: "Schlangen l: Automatisiertes Service-Deployment mit Pyinfra". In: IT-Administrator 05/2016, pp. 90-95.
  2. For a comparison of configuration management software like this, see B wetter/Johannsen/Steig: "Baukastensysteme: Konfigurationsmanagement mit Open-Source-Software". In: iX 04/2016, pp. 94-99 (please excuse the prevalence of German articles in the pointers, I've just have them at hand).
  3. On the points of critique on Puppet, see Martin Loschwitz: "David gegen Goliath Zwei Welten treffen aufeinander: Puppet und Ansible". In Linux-Magazin 01/2016, 50-54.
  4. See the interview with IDSIA's deep learning guru J rgen Schmidhuber in German C't 2014/09, p. 148
  5. The examples scripts need some more finetuning. To run the data creation scripts in place the environment variable BRAINSTORM_DATA_DIR could be set, but the trained networks are currently tried to write in place. So please copy the scripts into some workspace if you want to try them out. I'll patch the example scripts to run out-of-the-box, soon.
  6. Johannes Merkert: "Ziffernlerner. Ein k nstliches neuronales Netz selber gebaut". In: C't 2016/06, p. 142-147. Web: http://www.heise.de/ct/ausgabe/2016-6-Ein-kuenstliches-neuronales-Netz-selbst-gebaut-3118857.html.
  7. See Ramon Wartala: "Tiefensch rfe: Deep learning mit NVIDIAs Jetson-TX1-Board und dem Caffe-Framework". In: iX 06/2016, pp. 100-103
  8. https://lists.debian.org/debian-science/2016/03/msg00016.html

Russ Allbery: Review: Empires of EVE

Review: Empires of EVE, by Andrew Groen
Publisher: Andrew Groen
Copyright: 2015
Printing: 2016
ISBN: 0-9909724-0-2
Format: Hardcover
Pages: 171
The version of this book I read was the hardcover Kickstarter campaign reward, since I was a backer. I believe it's the same as the hardcover currently available for sale from the author's site for those who didn't back the project. There are also softcover and Kindle versions. I've lost track of whether they have less sidebar content, or just less high-quality artwork. EVE Online ("EVE" is not an acronym, just the developer's way of writing the name, so you'll also see "Eve" both for the game and for this book) is a massively multiplayer on-line role-playing game (MMORPG) based on interstellar mining, manufacturing, and combat. Its Icelandic developer takes a different, more emergent approach than most MMORPG developers: rather than fill the world exclusively with pre-scripted adventures and enemies (although there is some of that for those who want it), vast regions of EVE's world are left open to the players to govern, exploit, or fight over as they see fit. Player versus player combat plays a large role in that aspect of the game, and many actions that would be prohibited or made impossible in other games (stealing from other players, betrayals, tricking other players into fatal situations) are permitted and sometimes core components of the game. EVE is best-known for its economy, which is almost entirely player-driven and requires extensive mining and manufacturing work by large teams of players to build the largest and most powerful ships in the game. Empires of EVE is an unusual type of book, one that I'm not sure would have been possible ten years ago. Subtitled "a history of the great wars of EVE Online," it's a history of a virtual world, but not one sponsored by the developer or part of the marketing or lore of the game. I love seeing this (which is also why I backed the Kickstarter). Video games have developed beyond just games to play into games to watch other people play (successfully competing, for me and for many others, for the role previously filled by professional sports), and now into emergent events that are complex enough, and dramatic enough, to warrant their own third-party history. I was quite surprised and delighted by how broad the audience for this sort of writing is. And this is not a shallow effort. Andrew Groen is a freelance writer who does not, himself, play EVE. He approaches the complex political and in-game fighting with the attitude of a reporter and historian, cites sources (to the standards I would expect for long-form journalism, if not quite at the level of academic history), discloses where history has been lost or one side of some fight could not be contacted, and puts substantial effort into explaining the political strengths and weaknesses of the shifting in-game alliances. It's a proper political history of an imaginary world, including objective (so far as I can tell) reporting of times when developers were accused of assisting one of the factions. If, like me, you don't play EVE and are primarily interested in this book to get a feel for the game, there are a few caveats to be aware of. EVE is divided into regions with game-enforced security levels. The ones near the center of the game galaxy are heavily policed by the game to prevent most of the player versus player combat and let new players get their feet. Those regions also offer various built-in missions that don't require interacting with other players. As one moves out from that central area, the game-provided security (and I believe the game-provided interactions) drops off. Empires of EVE deals exclusively with nullsec space: the outer regions of the game where the richest resources are, and where there is no law or policing except what's done by the players themselves. The game here, and as described in the book, is relentlessly blood-thirsty, but this isn't representative of the entire game. Second, most of this book is devoted to ship-to-ship combat and missions of conquest and reprisal. But combat is built on top of a vast "civilian" infrastructure of mining and manufacturing, and there are players who focus on those aspects of the game and rarely, if ever, fight. Groen talks about this in passing, since it can have significant influence on the politics of the game, but spends little time describing the day-to-day life in the game for those players. The focus here is on the resulting combat. Finally, Groen starts his history at the EVE beta in 2003 but ends it in 2009. Maneuvering and wars have, of course, continued ever since, but he has to stop somewhere. As he mentioned during the Kickstarter, it takes some years for events to become history, and for people to be willing to talk about them. The developer has kept changing the game, so some of the mechanics here will be mildly stale and the current political alliances are quite likely far different (although many of the players discussed in this book are still playing). With those caveats, though, this is a fascinating book, even if this isn't your sort of game. Personally, I have a deep-seated dislike of games like Diplomacy where alliances, betrayal, and political maneuvering is sanctioned and encouraged by the game. I've never played EVE and I can't imagine ever wanting to, particularly after reading this book. But it's still a fascinating war history and analysis of slightly skew human politics. The alliances and backstabbing are reminiscent of real human history, but the game setting adds some significant twists: players can just quit if they're not having fun, the largest threat to strong alliances is players just not bothering to show up because they're not having fun or because the risk is too high, and without the stability and momentum of real-world institutions, in-game corporations and alliances can collapse overnight when players lose faith in them. From a distance, it's quite entertaining to see how those factors reshape politics and propaganda. (If sadly somewhat reminiscent of the sort of personalities that killed Usenet. I shouldn't have been surprised that organized Internet trolls made an appearance in EVE, although the nature of EVE politics meant they fit right in rather than doing much to spoil other people's fun, at least in nullsec.) I can't speak to the other formats, but the hardcover is also a gorgeous book. The artwork isn't quite my style, and the in-game screen shots are a bit muddy and confusing (not Groen's fault), but the maps are clear and invaluable, the propaganda posters are amazing, and the hardcover printing is clearly of a very high quality. I felt like I got my $50 worth in terms of presentation and quality printing, and have a book that isn't going to fall apart in a few years. The one quibble that I have is that Groen picked a fairly thin and light font for the main text, which my eyes had some trouble with on high-gloss paper. Something thicker and darker may not have looked as good on the page, but it would have been easier to read. The font choice for the sidebars was a lovely high-contrast white on black, but I would have appreciated something a bit larger. If you have vision issues, you may find the ebook more readable, if not as beautiful. Empires of EVE has apparently been very successful within its niche, which makes me happy. I would love to read more books of this type. I know I'm not the only person who grew up with gaming but has been increasingly drawn into watching other people game or reading about other people game. I love watching or reading about people who have put the effort into becoming very good at something they love, and when that comes with emergent history, creative propaganda, and a lot of assholes to root against (although sadly not many people to root for), the history of EVE makes compelling reading, at least for me. Recommended if this is at all your sort of thing; the ebook version of the book is fairly inexpensive. Rating: 8 out of 10

26 May 2016

Norbert Preining: Shotwell vs. digiKam

How to manage your photos? That is probably the biggest question for anyone doing anything with a photo camera. As resolutions of cameras grow, the data we have to manage is growing ever. In my case I am talking about more than 50000 photos and videos measuring up to about 200Gb of disk space, constantly growing. There are several photo management softwares out there, I guess the most commonly used ones are Shotwell for the Gnome desktop, digiKam for the KDE world, and FotoXX. I have not used Shotwell and digiKam for quite some time, and collect here my experiences of strength and weaknesses of the two programs. FotoXX seems to be very powerful, too, but I haven t tested it till now.
shotwell-digikam There is no clear winner here, unfortunately. Both have their strength and their weaknesses. And as a consequence I am using both in parallel. Before I start a clear declaration: I have been using Shotwell for many years, and have myself contributed considerable code to Shotwell, in particular the whole comment system (comments for photos and events), as well as improved the Piwigo upload features. I started using digiKam some month ago when I started to look for offloading parts of my photo library to external devices. Since then I have used both in parallel. Let us start with what these programs say about themselves: Shotwell is declared as a Photo Manager for Gnome 3, with the following features: digiKam says about itself that it is an advanced digital photo management application for Linux, Windows, and Mac-OSX. It has a very long feature page with a short list at the beginning: Now that sounds like they are very similar, but upon using them it turns out that there are huge differences, that can easily be summed up in a short statement:
Shotwell is Gnome 3 that means get rid of functionality. digiKam is KDE that means provide as much functionality as possible.
Now before you run after me with a knife because you do not agree with me on the above, either read on, or stop reading. I am not interested in flame wars over Gnome versus KDE philosophy. I have been using Gnome since many years, and tried to convince myself to G3 for more than a year until I threw out all of it but selected programs but their number is going down. Let us look at those aspects I am using: organization, offline, sharing, editing. Organization In Shotwell, your photos are organized into events, independent from their location on disk. These events can have title and comment and collect a set of related photos. In my case I often have photos from two or more cameras (my camera and mobile, photos of friends), which I keep in separate directories within a main directory for the event. For example I have a folder 2016/05.21-22.Climbing.Tanigakadake with two sub-folders Norbert (for my photos) and Friend (for my friends photos). In Shotwell all the photos are in the same event, which is shown with title 05.21-22 Tanigakawadake Climbing within the 2016 year and May month.
shotwell-events So in short Shotwell distinguishes between disk layout and album/event names. In digiKam there is a strict connection between disk layout and album names 1:1. Albums are directories. One can adjust the viewer to show all photos of sub-albums in the main album, and by this one can achieve the same effect of merging all photos of my friend and myself. The good thing in this approach is that one can easily have sub-albums: Imagine a trip to three different islands of Hawaii during one trip. This is something easy to achieve in digiKam, but hard in Shotwell.
digikam-albums Other organization methods Both Shotwell and digiKam support tags, including hierarchical tags and rating (0-5 stars). Shotwell has in addition a quick flag action that I used quite often for initial selecting photos, as well as accepted and rejected. digiKam also has so called picks (no pick, reject, pending, accepted), and colors (not used by now). Both programs have some face detection support, but also this I haven t used. So in the organization respect there is no clear winner. I like the Event idea of Shotwell, or better, the separation of events from the disk structure. But on the other hand, Shotwell does not allow for sub-albums, which is also a pain. No clear winner draw Offline storage That is simple: Shotwell: forget it, not reasonably possible. One can move parts to an external HD, then unplug it, and Shotwell will tell you that all the photos are missings. And when you plug the external HD in, it will redetect them. But this is not proper support, just a consequence of hash sum storage. Also separation into several libraries (online and offline) is not supported. On the other hand, digiKam supports multiple libraries, partly offline, without a hinch. I would love to have this feature in Shotwell, because I need to free disk space, urgently!!! Clear winner: digiKam Sharing Again here my testing is very restricted I am using my own Piwigo installation exclusively. Here Shotwell is excellent in providing support for various features: upload to existing category, create new category, resize, optionally remove tags, add comments to albums and photos, etc. (partly implemented by me
shotwell-piwigo On the other hand digiKam has a very barebone interface to Piwigo you can upload photos to an existing album and resize them, but that is already everything. One also needs to say that the list of supported services in digiKam is by far longer than the one in Shotwell, but the main services (usual suspects) are supported in both.
digikam-piwigo Clear winner: Shotwell (but I haven t tested other upload services). Editing The editing capabilities of Shotwell are again very restricted: red eyes, resize, levels, .
shotwell-editing digiKam here is more like a photo editor software with loads of tools and features. I haven t even explored all the options maybe I can get rid of GIMP, too?
digikam-editing Clear winner: digiKam Conclusions While I am still working with both, I actually would love to move completely to digiKam. I simply cannot stand the Gnome 3 philosophy of reducing functionality to a minimal for dummy users. There is a market for that, sure, but I am not one of it. Unfortunately, the missing Event support, and much more the completely minimal support for Piwigo sharing in digiKam is a big show stopper at the moment. Even after testing the upcoming digiKam 5.0 version for some time, I didn t see any improvement wrt to sharing. That leaves me with the only option to continue working with both programs, and hope to get a new bigger SSD before the current one runs out of space. Of course I could start hacking into the digiKam source maybe I do this when I have a bit more time to add proper Piwigo support.

19 May 2016

Antoine Beaupr : My free software activities, May 2016

Debian Long Term Support (LTS) This is my 6th month working on Debian LTS, started by Raphael Hertzog at Freexian. This is my largest month so far, for which I had requested 20 hours of work.

Xen work I spent the largest amount of time working on the Xen packages. We had to re-roll the patches because it turned out we originally just imported the package from Ubuntu as-is. This was a mistake because that package forked off the Debian packaging a while ago and included regressions in the packaging itself, not just security fixes. So I went ahead and rerolled the whole patchset and tested it on Koumbit's test server. Brian May then completed the uploaded, which included about 40 new patches, mostly from Ubuntu.

Frontdesk duties Next up was the frontdesk duties I had taken this week. This was mostly uneventful, although I had forgotten how to do some of the work and thus ended up doing extensive work on the contributor's documentation. This is especially important since new contributors joined the team! I also did a lot of Debian documentation work in my non-sponsored work below. The triage work involved chasing around missing DLAs, triaging away OpenJDK-6 (for which, let me remind you, security support has ended in LTS), raised the question of Mediawiki maintenance.

Other LTS work I also did a bunch of smaller stuff. Of importance, I can note that I uploaded two advisories that were pending from April: NSS and phpMyAdmin. I also reviewed the patches for the ICU update, since I built the one for squeeze (but didn't have time to upload before squeeze hit end-of-life). I have tried to contribute to the NTP security support but that was way too confusing to me, and I have left it to the package maintainer which seemed to be on top of things, even if things mean complete chaos and confusion in the world of NTP. I somehow thought that situation had improved with the recent investments in ntpsec and ntimed, but unfortunately Debian has not switched to the ntpsec codebase, so it seems that the NTP efforts have diverged in three different projects instead of closing into a single, better codebase.

Future LTS work This is likely to be my last month of work on LTS until September. I will try to contribute a few hours in June, but July and August will be very busy for me outside of Debian, so it's unlikely that I contribute much to the project during the summer. My backlog included those packages which might be of interest to other LTS contributors:
  • libxml2: no upstream fix, but needs fixing!
  • tiff ,3 : same mess
  • libgd2: maintainer contacted
  • samba regression: mailed bug #821811 to try to revive the effort
  • policykit-1: to be investigated
  • p7zip: same

Other free software work

Debian documentation I wrote an detailed short guide to Debian package development, something I felt was missing from the existing corpus, which seems to be too focus in covering all alternatives. My guide is opinionated: I believe there is a right and wrong way of doing things, or at least, there are best practices, especially when just patching packages. I ended up retroactively publishing that as a blog post - now I can simply tag an item with blog and it shows up in the blog. (Of course, because of a mis-configuration on my side, I have suffered from long delays publishing to Debian planet, so all the posts dates are off in the Planet RSS feed. This will hopefully be resolved around the time this post is published, but this allowed me to get more familiar with the Planet Venus software, as detailed in that other article.) Apart from the guide, I have also done extensive research to collate information that allowed me to create workflow graphs of the various Debian repositories, which I have published in the Debian Release section of the Debian wiki. Here is the graph: It helps me understand how packages flow between different suites and who uploads what where. This emerged after I realized I didn't really understand how "proposed updates" worked. Since we are looking at implementing a similar process for the security queue, I figured it was useful to show what changes would happen, graphically. I have also published a graph that describes the relations between different software that make up the Debian archive. The idea behind this is also to provide an overview of what happens when you upload a package in the Debian archive, but it is more aimed at Debian developers trying to figure out why things are not working as expected. The graphs were done with Graphviz, which allowed me to link to various components in the graph easily, which is neat. I also prefered Graphviz over Dia or other tools because it is easier to version and I don't have to bother (too much) about the layout and tweaking the looks. The downside is, of course, that when Graphviz makes the wrong decision, it's actually pretty hard to make it do the right thing, but there are various workarounds that I have found that made the graphs look pretty good. The source is of course available in git but I feel all this documentation (including the guide) should go in a more official document somewhere. I couldn't quite figure out where. Advice on this would be of course welcome.

Ikiwiki I have made yet another plugin for Ikiwiki, called irker, which enables wikis to send notifications to IRC channels, thanks to the simple irker bot. I had trouble with Irker in the past, since it was not quite reliable: it would disappear from channels and not return when we'd send it a notification. Unfortunately, the alternative, the KGB bot is much heavier: each repository needs a server-side, centralized configuration to operate properly. Irker's design is simpler and more adapted to a simple plugin like this. Let's hope it will work reliably enough for my needs. I have also suggested improvements to the footnotes styles, since they looked like hell in my Debian guide. It turns out this was an issue with the multimarkdown plugin that doesn't use proper semantic markup to identify footnotes. The proper fix is to enable footnotes in the default Discount plugin, which will require another, separate patch. Finally, I have done some improvements (I hope!) on the layout of this theme. I made the top header much lighter and transparent to work around an issue where followed anchors would be hidden under the top header. I have also removed the top menu made out of the sidebar plugin because it was cluttering the display too much. Those links are all on the frontpage anyways and I suspect people were not using them so much. The code is, as before, available in this git repository although you may want to start from the new ikistrap theme that is based on Bootstrap 4 and that may eventually be merged in ikiwiki directly.

DNS diagnostics Through this interesting overview of various *ping tools, I got found out about the dnsdiag tool which currently allows users to do DNS traces, tampering detection and ping over DNS. In the hope of packaging it into Debian, I have requested clarifications regarding a modification to the DNSpython library the tool uses. But I went even further and boldly opened a discussion about replacing DNSstuff, the venerable DNS diagnostic tools that is now commercial. It is somewhat surprising that there is no software that has even been publicly released that does those sanity checks for DNS, given how old DNS is. Incidentally, I have also requested smtpping to be packaged in Debian as well but httping is already packaged.

Link checking In the process of writing this article, I suddenly remembered that I constantly make mistakes in the various links I post on my site. So I started looking at a link checker, another tool that should be well established but that, surprisingly, is not quite there yet. I have found this neat software written in Python called LinkChecker. Unfortunately, it is basically broken in Debian, so I had to do a non-maintainer upload to fix that old bug. I managed to force myself to not take over maintainership of this orphaned package but I may end up doing just that if no one steps up the next time I find issues in the package. One of the problems I had checking links in my blog is that I constantly refer to sites that are hostile to bots, like the Debian bugtracker and MoinMoin wikis. So I published a patch that adds a --no-robots flag to be able to crawl those sites effectively. I know there is the W3C tool but it's written in Perl, and there's probably zero chance for me to convince those guys to bypass robots exclusion rules, so I am sticking to Linkchecker.

Other Debian packaging work At my request, Drush has finally been removed from Debian. Hopefully someone else will pick up that work, but since it basically needs to be redone from scratch, there was no sense in keeping it in the next release of Debian. Similarly, Semanticscuttle was removed from Debian as well. I have uploaded new versions of tuptime, sopel and smokeping. I have also file a Request For Help for Smokeping. I am happy to report there was a quick response and people will be stepping up to help with the maintenance of that venerable monitoring software.

Background radiation Finally, here's the generic background noise of me running around like a chicken with his head cut off: Finally, I should mention that I will be less active in the coming months, as I will be heading outside as the summer finally came! I somewhat feel uncomfortable documenting publicly my summer here, as I am more protective of my privacy than I was before on this blog. But we'll see how it goes, maybe you'll hear non-technical articles here again soon!

Valerie Young: Summer of Reproducible Builds

Hello friend, family, fellow Outreachy participants, and the Debian community!
This blog's primary purpose will be to track the progress of the Outreachy project in which I'm participating this summer    This post is to introduce myself and my project (working on the Debian reproducible builds project).
What is Outreachy? You might not know! Let me empower you: Outreachy is an organization connecting woman and minorities to mentors in the free (as in freedom) software community, /and/ funding for three months to work with the mentors and contribute to a free software project.  If you are a woman or minority human that likes free software, or if you know anyone in this situation, please tell them about Outreachy   Or put them in touch with me, I'd happily tell them more.
So who am I?
My name is Valerie Young. I live in the Boston Metropolitan Area (any other outreachy participants here?) and hella love free software. 
Some bullet pointed Val facts in rough reverse chronological order:
- I run Debian but only began contributing during the Outreachy application process
- If you went to DebConf2015, you might have seen me dye nine people's hair blue, blond or Debian swirl.
- If you stop through Boston I could be easily convinced to dye your hair.
- I worked on electronic medical records web application for the last two years (lotsa Javascriptin' and Perlin' at athenahealth)
- Before that I taught a programming summer program at University of Moratuwain Sri Lanka.
- Before that I got a degrees in physics and computer science at Boston University.
- At BU I helped start a hackerspace where my interest in technology, free software, hacker culture, anarchy, the internet all began.
- I grew up in the very fine San Francisco Bay Area.
What will I be working on?
Reproducible builds!
In the near future I'll write a  What is reproducible builds? Why is it so hot right now?  post.  For now, from a high (and not technical) level, reproducible builds is a broad effort to verify that the computer executable binary programs you run on your computer come from the human readable source code they claim to. It is not presently /impossible/ to do this verification, but it's not easy, and there are a lot of nuanced computer quirks that make it difficult for the most experienced programmer and straight-up impossible for a user with no technical expertise. And without this ability to verify -- the state we are in now -- any executable piece of software could be hiding secret code. 
The first step towards the goal of verifiability is to make reproducibility a essential part of software development. Reproducible builds means this: when you compile a program from the source code, it should always be identical, bit by bit. If the program is always identical, you can compare your version of the software to any trusted programmer with very little effort. If it is identical, you can trust it -- if it's not, you have reason to worry.
The Debian project is undergoing an effort to make the entire Debian operating system verifiable reproducible (hurray!). My outreachy-funded summer contribution involves the improving and updating tests.reproducible-builds.org   a site that presently presently surfaces the results of reproducibility testing of several free software projects (including Debian, Fedora, coreboot, OpenWrt, NetBSD, FreeBSD and ArchLinux). However, the design of test.r-b.org is a bit confusing, making it difficult for a user to find how to check on the reproducibility of a given package for one of the aforementioned projects, or understand the reasons for failure. Additional, the backend test results of Debian are outgrowing the original SQLite database, and many projects do not log the results of package testing at all. I hope, by the end of the summer, we'll have a more beefed-out and pretty site as well as better organized backend data  
This summer there will be 3 other Outreachy participants working on the Debian reproducible builds project! Check out their blogs/projects:
Scarlett
Satyam
Ceridwen
Thanks to our Debian mentors -- Lunar, Holger Levsen, and Mattia Rizzolo -- for taking us on   

Next.

Previous.