Search Results: "ema"

28 December 2021

Russ Allbery: Review: Out of Office

Review: Out of Office, by Charlie Warzel & Anne Helen Petersen
Publisher: Alfred A. Knopf
Copyright: 2021
ISBN: 0-593-32010-7
Format: Kindle
Pages: 260
Out of Office opens with the provocative assertion that you were not working from home during the pandemic, even if you were among the 42% of Americans who were able to work remotely.
You were, quite literally, doing your job from home. But you weren't working from home. You were laboring in confinement and under duress. Others have described it as living at work. You were frantically tapping out an email while trying to make lunch and supervise distance learning. You were stuck alone in a cramped apartment for weeks, unable to see friends or family, exhausted, and managing a level of stress you didn't know was possible. Work became life, and life became work. You weren't thriving. You were surviving.
The stated goal of this book is to reclaim the concept of working from home, not only from the pandemic, but also from the boundary-destroying metastasis of work into non-work life. It does work towards that goal, but the description of what would be required for working from home to live up to its promise becomes a sweeping critique of the organization and conception of work, leaving it nearly as applicable to those who continue working from an office. Turns out that the main problem with working from home is the work part, not the "from home" part. This was a fascinating book to read in conjunction with A World Without Email. Warzel and Petersen do the the structural and political analysis that I sometimes wish Newport would do more of, but as a result offer less concrete advice. Both, however, have similar diagnoses of the core problems of the sort of modern office work that could be done from home: it's poorly organized, poorly managed, and desperately inefficient. Rather than attempting to fix those problems, which is difficult, structural, and requires thought and institutional cooperation, we're compensating by working more. This both doesn't work and isn't sustainable. Newport has a background in productivity books and a love of systems and protocols, so his focus in A World Without Email is on building better systems of communication and organization of work. Warzel and Petersen come from a background of reporting and cultural critique, so they put more focus on power imbalances and power-serving myths about the American dream. Where Newport sees an easy-to-deploy ad hoc work style that isn't fit for purpose, Warzel and Petersen are more willing to point out intentional exploitation of workers in the guise of flexibility. But they arrive at some similar conclusions. The way office work is organized is not leading to more productivity. Tools like Slack encourage the public performance of apparent productivity at the cost of the attention and focus required to do meaningful work. And the process is making us miserable. Out of Office is, in part, a discussion of what would be required to do better work with less stress, but it also shares a goal with Newport and some (but not most) corners of productivity writing: spend less time and energy on work. The goal of Out of Office is not to get more work done. It's to work more efficiently and sustainably and thus work less. To reclaim the promise of flexibility so that it benefits the employee and not the employer. To recognize, in the authors' words, that the office can be a bully, locking people in to commute schedules and unnatural work patterns, although it also provides valuable moments of spontaneous human connection. Out of Office tries to envision a style of work that includes the office sometimes, home sometimes, time during the day to attend to personal chores or simply to take a mental break from an unnatural eight hours (or more) of continuous focus, universal design, real worker-centric flexibility, and an end to the constant productivity ratchet where faster work simply means more work for the same pay. That's a lot of topics for a short book, and structurally this is a grab bag. Some sections will land and some won't. Loom's video messages sound like a nightmare to me, and I rolled my eyes heavily at the VR boosterism, reluctant as it may be. The section on DEI (diversity, equity, and inclusion) was a valiant effort that at least gestures towards the dismal track record of most such efforts, but still left me unconvinced that anyone knows how to improve diversity in an existing organization without far more brute-force approaches than anyone with power is usually willing to consider. But there's enough here, and the authors move through topics quickly enough, that a section that isn't working for you will soon be over. And some of the sections that do work are great. For example, the whole discussion of management.
Many of these companies view middle management as bloat, waste, what David Graeber would call a "bullshit job." But that's because bad management is a waste; you're paying someone more money to essentially annoy everyone around them. And the more people experience that sort of bad management, and think of it as "just the way it is," the less they're going to value management in general.
I admit to a lot of confirmation bias here, since I've been ranting about this for years, but management must be the most wide-spread professional job for which we ignore both training and capability and assume that anyone who can do any type of useful work can also manage people doing that work. It's simply not true, it creates workplaces full of horrible management, and that in turn creates a deep and unhelpful cynicism about all management. There is still a tendency on the left to frame this problem in terms of class struggle, on the reasonable grounds that for decades under "scientific management" of manufacturing that's what it was. Managers were there to overwork workers and extract more profits for the owners, and labor unions were there to fight back against managers. But while some of this does happen in the sort of office work this book is focused on, I think Warzel and Petersen correctly point to a different cause.
"The reason she was underpaid on the team was not because her boss was cackling in the corner. It was because nobody told the boss it was their responsibility to look at the fucking spreadsheet."
We don't train managers, we have no clear expectations for what managers should do, we don't meaningfully measure their performance, we accept a high-overhead and high-chaos workstyle based on ad hoc one-to-one communication that de-emphasizes management, and many managers have never seen good management and therefore have no idea what they're supposed to be doing. The management problem for many office workers is less malicious management than incompetent management, or simply no effective management at all apart from an occasional reorg and a complicated and mind-numbing annual review form. The last section of this book (apart from concluding letters to bosses and workers) is on community, and more specifically on extracting time and energy from work (via the roadmap in previous chapters) and instead investing it in the people around you. Much ink has been spilled about the collapse of American civic life, about how we went from a nation of joiners to a nation of isolated individual workers with weak and failing community institutions. Warzel and Petersen correctly lay some blame for this at the foot of work, and see the reorganization of work and an increase in work from home (and thus a decrease in commutes) as an opportunity to reverse that trend. David Brooks recently filled in for Ezra Klein on his podcast and talked with University of Chicago professor Leon Kass, which I listened to shortly after reading this book. In one segment, they talked about marriage and complained about the decline in marriage rates. They were looking for causes in people's moral upbringing, in their life priorities, in the lack of aspiration for permanence in kids these days, and in any other personal or moral failing that would allow them to be smugly judgmental. It was a truly remarkable thing to witness. Neither man at any point in the conversation mentioned either money or time. Back in the world most Americans live in, real wages have been stagnant for decades, student loan debt is skyrocketing as people desperately try to keep up with the ever-shifting requirements for a halfway-decent job, and work has expanded to fill all hours of the day, even for people who don't have to work multiple jobs to make ends meet. Employers have fully embraced a "flexible" workforce via layoffs, micro-optimizing work scheduling, eliminating benefits, relying on contract and gig labor, and embracing exceptional levels of employee turnover. The American worker has far less of money, time, and stability, three important foundations for marriage and family as well as participation in most other civic institutions. People like Brooks and Kass stubbornly cling to their feelings of moral superiority instead of seeing a resource crisis. Work has stolen the resources that people previously put into those other areas of their life. And it's not even using those resources effectively. That's, in a way, a restatement of the topic of this book. Our current way of organizing work is not sustainable, healthy, or wise. Working from home may be part of a strategy for changing it. The pandemic has already heavily disrupted work, and some of those changes, including increased working from home, seem likely to stick. That provides a narrow opportunity to renegotiate our arrangement with work and try to make those changes stick. I largely agree with the analysis, but I'm pessimistic. I think the authors are as well. We're very bad at social change, and there will be immense pressure for everything to go "back to normal." Those in the best bargaining position to renegotiate work for themselves are not in the habit of sharing that renegotiation with anyone else. But I'm somewhat heartened by how much public discussion there currently is about a more fundamental renegotiation of the rules of office work. I'm also reminded of a deceptively profound aphorism from economist Herbert Stein: "If something cannot go on forever, it will stop." This book is a bit uneven and is more of a collection of related thoughts than a cohesive argument, but if you are hungry for more worker-centric analyses of the dynamics of office work (inside or outside the office), I think it's worth reading. Rating: 7 out of 10

25 December 2021

Russ Allbery: Review: Shattered Pillars

Review: Shattered Pillars, by Elizabeth Bear
Series: Eternal Sky #2
Publisher: Tor
Copyright: March 2013
ISBN: 0-7653-2755-4
Format: Hardcover
Pages: 333
Shattered Pillars is the second book in the Eternal Sky series, which begins with Range of Ghosts. You should read them in order, and ideally close together, since they (along with the next book) form a single continuous story. I made the horrible mistake of reading the first book of an Elizabeth Bear series and then letting four years go by before reading the second one. Bear's trademark style is to underexplain things to the point that it can be hard to follow the plot when you remember it, let alone after more than sufficient time to forget even the general shape of the plot. I therefore spent most of this book (and a bit of Internet searching) trying to dig up pieces of my memory and reconstruct the story. Learn from my error and read the trilogy as one novel if you're going to read it. Please, authors and publishers, put a short plot synopsis at the start of series books. No, your hints about what happened previously that you weave into the first two chapters are not as good as a one-page plot synopsis. No, I don't want to have to re-read the first book; do you have any idea how many books I own but haven't read? No, the Internet doesn't provide plot synopses for every book. Give me a couple of paragraphs and help me enjoy your fiction! Argh. Possible spoiler warnings for the first book are in order because I don't remember the first book well enough to remember what plot details might be a spoiler. As Shattered Pillars opens, Temur, Samarkar, and their companions have reached the western city of Asitaneh, seeking help from Temur's grandfather to rescue Edene from the Nameless. This will require breaching the Nameless fortress of Ala-Din. That, in turn, will entangle Temur and Samarkar in the politics of the western caliphate, where al-Sepehr of the Nameless is also meddling. Far to the east, from where Samarkar came, a deadly plague breaks out in the city of Tsarepheth, one that follows an eerily reliable progression and is even more sinister than it may first appear. Al-Sepehr's plans to sow chaos and war using ancient evil magic and bend the results to his favor continue apace. But one of the chess pieces he thought he controlled has partly escaped his grasp. Behind all of this lurks the powers of Erem and its scorching, blinding, multi-sunned sky. Al-Sepehr believes he understands those powers well enough to use them. He may be wrong. This is entirely the middle book of a trilogy, in that essentially nothing is resolved here. All the pieces in motion at the start of this book are still in motion at the end of this book. We learn a lot more about the characters, get some tantalizing and obscure glances at Erem, and end the book with a firmer idea of the potential sides and powers in play, but there is barely any plot resolution and no proper intermediate climax. This is a book to read as part of a series, not on its own. That said, I enjoyed this book considerably more than I would have expected given how little is resolved. Bear's writing is vivid and engrossing and made me feel like I was present in this world even when nothing apparently significant was happening. And, as usual, her world-building is excellent if you like puzzles, stray hints, and complicated, multi-faceted mythology. This is a world in which the sky literally changes depending on which magical or mythological system reigns supreme in a given area, which in the Erem sections give it a science fiction flavor. If someone told me Bear could merge Silk Road historical fantasy with some of the feel of planetary romance (but far more sophisticated writing), I would have been dubious, but it works. Perhaps the best thing about this book is that all of the characters feel like adults. They make complex, nuanced decisions in pursuit of their goals, thoughtfully adjust to events, rarely make obviously stupid decisions, and generally act like the intelligent and experienced people that they are. This is refreshing in epic fantasy, where the plot tends to steamroll the characters and where often there's a young chosen one at the center of the plot whose courage and raw power overcomes repeated emotional stupidity. Shattered Pillars is careful, precise, and understated where epic fantasy is often brash, reckless, and over-explained. That plus the subtle and deep world-building makes this world feel older and more complex than most series of this sort. There's also a magical horse, who is delightfully uninterested in revealing anything about where it came from or why it's magical, and who was probably my favorite character of the book. Hrahima, the giant tiger-woman, is a close second. I was intrigued to learn more about her complicated relationship with her entirely separate mythology, and hope there's more about that the third book. The villain is still hissable, but a bit less blatantly so on camera. It helps that the scenes from the villains' perspective primarily focus on his more interesting servants. One of the problems with this book, and I think one of the reasons why it feels so transitional and intermediate, is that there are a lot of viewpoint characters and a lot of scene-switching. We're kept up-to-date with four separate threads of events, generally with more than one viewpoint character in each of those threads, and at times (particularly with the wizards of Tsarepheth) I had trouble keeping all the supporting characters straight. Hopefully the third book will quickly merge plot lines and bring some of this complexity together. I wish I'd read this more closely to Range of Ghosts. Either that or a plot synopsis would have helped me enjoy it more. But this is solid epic fantasy by one of SFF's better writers, and now I'm invested in the series again. Some unfortunate logistics are currently between me and the third book, but it won't be four years before I finish the series. Followed by Steles of the Sky. Rating: 7 out of 10

21 December 2021

Joey Hess: Volunteer Responsibility Amnesty Day

Happy solstice, and happy Volunteer Responsibility Amnesty Day! After my inventory of my code today, I have decided it's time to pass on moreutils to someone new. This project remains interesting to people, including me. People still send patches, which are easy to deal with. Taking up basic maintenance of this package will be easy for you, if you feel like stepping forward. People still contribute ideas and code for new tools to add to moreutils. But I have not added any new tools to it since 2016. There is a big collections of ideas that I have done nothing with. The problem, I realized, is that "general-purpose new unix tool" is rather open-ended, and kind of problimatic. Picking new tools to add is an editorial process, or it becomes a mishmash of too many tools that are perhaps not general purpose. I am not a great editor, and so I tightened my requirements for "general-purpose" and "new" so far that I stopped adding anything. If you have ideas to solve that, or fearless good taste in curating a collection, this project is for you. The other reason it's less appealing to me is that unix tools as a whole are less appealing to me now. Now, as a functional programmer, I can get excited about actual general-purpose functional tools. And these are well curated and collected and can be shown to fit because the math says they do. Even a tiny Haskell function like this is really very interesting in how something so maximally trivial is actually usable in so many contexts.
id :: a -> a
id x = x
Anyway, I am not dropping maintenance of moreutils unless and until someone steps up to take it on. As I said, it's easy. But I am laying down the burden of editorial responsibility and won't be thinking about adding new tools to it.
Thanks very much to Sumana Harihareswara for developing and promoting the amnesty day idea!

16 December 2021

Dirk Eddelbuettel: BH 1.78.0-0: New Upstream, Two New Libraries

Boost Boost is a very large and comprehensive set of (peer-reviewed) libraries for the C++ programming language, containing well over 100 individual libraries. The BH package provides a sizeable subset of header-only libraries for (easier, no linking required) use by R. It is fairly widely used: the (partial) CRAN mirror logs (aggregated from the cloud mirrors) show over 28 million package downloads. Version 1.78.0 of Boost was released in a few days ago on their schedule with April, August and December releases. We follow these releases at a lower (annual) cadence, and BH 1.78.0-0 catches up to Boost 1.78 from the 1.75 version packaged last winter. Three reverse-depends checks revealed only minors needs for changes (after I corrected a fat-finger typo, whoops) in a handful of packages whose maintainers I contacted via PRs or emails. With that, CRAN permitted the upload yesterday. My thanks once again to the maintainers of these packages for helping it along promptly, and of course to the CRAN team. This release adds the new header-only library Boost Lambda2 offering simple but functional lambda functions (for C++14 and later), as well as Boost Process to manage system processes.

Changes in version 1.78.0-0 (2020-12-14)

Via my CRANberries, there is a diffstat report relative to the previous release. Comments and suggestions about BH are welcome via the issue tracker at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Raphaël Hertzog: Freexian s report about Debian Long Term Support, November 2021

A Debian LTS logo
Every month we review the work funded by Freexian s Debian LTS offering. Please find the report for November below. Debian project funding We continue to looking forward to hearing about Debian project proposals from various Debian stakeholders. This month has seen work on a survey that will go out to Debian Developers to gather feedback on what they think should be the priorities for funding in the project. Learn more about the rationale behind this initiative in this article. Debian LTS contributors In November 13 contributors were paid to work on Debian LTS, their reports are available below. If you re interested in participating in the LTS or ELTS teams, we welcome participation from the Debian community. Simply get in touch with Jeremiah if you are interested in participating. Evolution of the situation In November we released 31 DLAs. The security tracker currently lists 23 packages with a known CVE and the dla-needed.txt file has 16 packages needing an update. Thanks to our sponsors Sponsors that joined recently are in bold.

12 December 2021

Russell Coker: Some Ideas for Debian Security Improvements

Debian security is pretty good, but there s always scope for improvement. Here are some ideas that I think could be used to improve things.
  1. A security wizard , basically a set of scripts with support for plugins that will investigate your system and look for things that can be improved. It could give suggestions on LSMs that could be used, sysctl settings, lists of daemons running as root that possibly don t need root privs, etc. Plugins could be for different daemons, so there could be a plugin for Apache that looks for potential issues with Apache configuration. It wouldn t be possible to cover everything, but it would be possible to cover many common cases.
    It appears that we used to have a harden package to do some of these things which disappeared. It appears that the only remnant of that is the hardening-runtime package.
  2. Kali Linux [1] is a distribution designed for penetration testing, I recently tried out many of it s features and I was very impressed. While I don t think that the aim should be to copy all Kali features into Debian there are probably some that are worthy of inclusion. Most Kali features run well in a VM, but the Wifi penetration testing tools need access to the hardware, so they could be a good candidate for inclusion in Debian (license permitting).
  3. We have a Securing Debian Manual [2] that is really good. It s a little out of date and needs some contributions, it also needs to be better known.
  4. The Security Management page of the Debian wiki [3] has links to a number of pages about improving system security. It needs some updates, it doesn t have a link to a page about SE Linux so there s some work for me to do there.
  5. Can training help people? I would be happy to run some Debian SE Linux training sessions over Matrix or Jitsi. We can probably find people to offer training on other aspects of Linux security that are implemented in Debian if there is an audience. I don t think that I and other DDs (Debian Developers) can train everyone, but we could train people who then go on to run other training sessions and make the session notes etc available under the GPL.
    There would also be some benefits to training other DDs as probably no-one has a good overview of all the security features that are supported.
Any other ideas? Feel free to comment here or start a thread on a public mailing list. If you start a mailing list discussion please email me or comment here with the URL if it s a list that I m not on so I can track it via the archives. This post was inspired by a discussion on a private list of a related topic. I think it s better to have a public discussion instead.

11 December 2021

Neil Williams: Diversity and gender

As a follow on to a previous blog entry of mine, Free and Open, I feel it worthwhile to do my bit to dismantle the pseudo-science and over simplification in the idea that gender is binary at a biological level.

TL;DR: Science simply does not support binary sexes or binary genders. Truth is a bit more complicated.
There is certainty and there are binary answers in mathematics. Things get less definitive in physics, certainly as soon as quantum is broached. Processes become more of an equilibrium between states in chemistry, never wholly one or the other. Yes, there is the oddity of absolute zero but no experiment has yet achieved that fully. It is accurate to describe physics as a development of applied mathematics and to view chemistry as applied physics. Biology, at the biochemical level, is applied chemistry. The sciences build on each other, "on the shoulders of giants", but at each level, some certainty is lost, some amount of uncertainty is expanded and measurements become probabilities, proportions and percentages. Biology is dependent on biochemistry - chemistry is how a biological change results in a different organism. Physics is how that chemical change occurs - temperature, pressure and physical states are inherent to all chemical changes. Outside laboratory constraints, few chemical reactions, especially in organic chemistry, produce one and only one result from two or more known reagents. In biology, everyone is familiar with genetic mutations but a genetic mutation only happens because a biochemical reaction (hydrogen bonding of nucleobases) does not always produce the expected result. Every cell division, every viral infection, there is a finite probability that a change will occur. It might be a small number but it is never zero and can never be dismissed. This is obvious in the current Covid pandemic - genetic mutations result in new variants. Some variants are inviable, some variants produce no net change in the way that the viral particles infect adjacent cells. Sometimes, a mutation happens that changes everything. These mutations are not mistakes - these are simply changes with undetermined outcomes. Genetic changes are the foundation of biodiversity and variety is what allows lifeforms of all kinds to survive changes in environmental factors and/or changes in prevalent diseases. It is precisely the same in humans, particularly in one of the principle spheres of human life that involves replicating genetic material - the creation of gametes for sexual reproduction. Every single time any DNA is copied, there is a finite chance that a different base will be put in place compared to the original. Copying genetic material is therefore non-binary. Given precisely the same initial conditions, the result is not always predictable and the range of how the results vary from one to another increases with every iteration. Let me stress that - at the molecular level, no genetic operation in any biological lifeform has a truly binary result. Repeat that operation sufficiently often and an unexpected result WILL inevitably occur. It is a mathematical certainty that genetic changes will arise by attempting precisely the same genetic operation enough times. Genetic changes are fundamental to how lifeforms survive changing conditions. Life would likely have died out a long time ago on this planet if every genetic operation was perfect. Diversity is life. Similarity leads to extinction. Viral load is interesting at this point. Someone can be infected with a virus, including coronavirus, by encountering a small number of viral particles. Some viruses, it may be a few hundred, some viruses may need a few thousand particles to infect a vulnerable host. But here's the thing, for that host to be at risk of infecting another host, the virus needs the host to produce billions upon billions of copies of the virus by taking over the genetic machinery within a huge number of cells in the host. This, as is accepted with Covid, is before the virus has been copied enough times to produce symptoms in the host. Before those symptoms become serious, billions more copies will be made. The numbers become unimaginable - and that is within a single host, let alone the 265 million (and counting) hosts in the current Covid19 pandemic. It's also no wonder that viral infections cause tiredness, the infection is diverting huge resources to propagating itself - before even considering the activity of the immune system. It is idiocy of the highest order to expect all those copies to be identical. The rise of variants is inevitable - indeed essential - in all spheres of biology. A single viral particle is absolutely no threat of any kind - it must first get inside and then copy the genetic information in a host cell. This is where the complexity lies in the definition of life itself. A virus can be considered a lifeform but it is only able to reproduce using another, more complex, lifeform. In truth, a viral particle does not and cannot mutate. The infected host mutates the virus. The longer it takes that host to clear the infection, the more mutations that host will create and then potentially spread to others. Now apply this to the creation of gametes in humans. With seven billion humans, the amount of copying of genetic material is not as large as the pandemic but it is still easy for everyone to understand that children do not merely combine the DNA of both parents. Changes happen. Human sexual reproduction is not as simple as 1 + 1 = 2. Sometimes, the copying of the genetic material produces an unexpected result. Sexual reproduction itself is non-binary. Sexual reproduction is not easy or simple for lifeforms to adopt - the diversity which results from the non-binary operations are exactly why so many lifeforms invest so much energy in reproducing in this way. Whilst many genetic changes in humans will be benign or beneficial, I d like to take an example of a genetic disorder that results from the non-binary nature of sex. Humans can be born with the XY phenotype - i.e. at a genetic level, the individual has the same combination of chromosomes as another XY individual but there are changes within the genes in those chromosomes. We accept this, some children of blonde parents do not have blonde hair, etc. There are also genetic changes where an XY phenotype is not binary. Some people, who at a genetic level would be almost identical to another person who is genetically male, have a genetic mutation which makes it impossible for the cells of that individual to respond to androgens (testosterone). (See Androgen insensitivity syndrome). Genetically, that individual has an X and a Y chromosome, just like many other individuals. However, due to a change in how the genes on those chromosomes were copied, that individual is biologically incapable of constructing the secondary sexual characteristics of a male. At a genetic level, the individual has the XY phenotype of a male. At the physical level, the individual has all the sexual characteristics of a female and none of the sexual characteristics of a male. The gender of that individual is not binary. Treatment is centred on supporting the individual and minimising some risks from the inactive genes on the Y chromosome. Human sexual reproduction is non-binary. The results of any sexual reproduction in humans will not always produce the binary option of male or female. It is a lie to claim that human gender is binary. The science is in plain view and cannot be ignored. Identifying as non-binary is not a "cop out" - it can be a biological, genetic, scientific fact. Human sexuality and gender are malleable. Where genetic changes result in symptoms, these can be ameliorated by treatment with human sex hormones, like oestrogen and testosterone. There are valid medical uses for anabolic steroids and hormone replacement therapies to help individuals who, at a genetic level, have non-binary gender. These treatments can help align the physical outer signs with the personality and identity of the individual, whether with or without surgery. It is unacceptable to abandon such people to suffer life long discrimination and harassment by imposing a binary definition that has no basis in science. When a human being has an XY phenotype, that human being is not necessarily male. That individual will be on a spectrum from female (left unaffected by sex hormones in the womb, the foetus will be female, even with an X and a Y chromosome), to various degrees of male. So, at a genetic, biological level, it is a scientific fact that human beings do not have binary gender. There is no evidence that this is new to the modern era, there is no scientific basis for thinking that copying of genetic material was somehow perfectly reliable in earlier history, or that such mutations are specific to homo sapiens. Changes in genetic material provide the diversity to fight infections and adapt to changing environmental factors. Species have and will continue to go extinct if this diversity is absent. With that out of the way, it is no longer a stretch to encompass other aspects of human non-binary genders beyond the known genetic syndromes based on changes in the XY phenotype. Science has not uncovered all of the ways that genes affect personality, behaviour, or identity. How other, less studied, genetic changes affect the much more subtle human facets, especially anything to do with consciousness, identity, personality, sexuality and behaviour, is guesswork. All of these facets can and likely are being affected by genetic factors as well as environmental factors in an endless range of permutations. Personality traits are a beautiful and largely unknowable blend of genes and environment. Genetic information has a finite probability of changes at each and every iteration. Environmental factors are more akin to chaos theory. The idea that the results will fit into binary constructs is laughable. Human society puts huge emphasis on societal norms. Individuals who do not fit into those norms suffer discrimination. The norms themselves have evolved over time as a response to various influences on human civilisation but most are not based on science. It is up to all humans in that society to call out discrimination, to call for changes in the accepted norms and support those who are marginalised. It is a precarious balance, one that humans rarely get right, but it must be based on an acceptance that variation is the natural state. Artificial constraints, like binary genders, must be dismantled because human beings and human sexual reproduction are not binary. To those who think, "well it is for 99%", think again about Covid. 99% (or closer to 98%) of infected humans recover without notable after effects. That has still crippled the nations of the globe and humbled all those who tried to deny it. Five million human beings are dead because "most infected people recover". Just because something only affects a proportion of human beings does not invalidate the suffering of those humans and the discrimination that those humans will face. Societal norms are not necessarily correct. Religious and other influences typically obscure and ignore scientific fact and undermine human kindness. The scientific truth of life on this planet is that gender is not binary. The more complex the lifeform, the more factors will affect where on the spectrum any one individual will appear. Just because we do not yet fully understand how genes affect human personality and sexuality, does not invalidate the science that variation is the natural order. My previous blog about diversity is not just about male vs female, one nationality vs another, one ethnicity compared to another. Diversity is diverse. Diversity requires accepting that every facet of humanity is subject to variation. That leads to tension at times, it is inevitable. Tension against societal norms, tension against discrimination, tension around those individuals who would abuse the tolerance of others for their own gratification or from their own ignorance. None of us are perfect, none of us have any of this fully sorted and all of us will make mistakes. Personally, I try to respect those around me. I will use whatever pronouns and other conventions that the person requests, from their perspective and not mine. To do otherwise is to deny the natural order and to deny the science. Celebrate all diversity, it is the very stuff of life. The discussions around (typically female) bathroom facilities often miss the point. The concern is not about individuals who describe themselves as non-binary. The concern is about individuals who are fully certain of their own sexuality and who act as sexual predators for their own gratification. These people are acting out a lie for their own ends. The problem people are the predators, so stop blaming the victims who are just as at risk as anyone else who identifies as female. Maybe the best people to spot such predators are those who are non-binary, who have had to pretend to fit into societal norms. Just as travel can be a good antidote to racism, openness and discussion can be a tool to undermine the lies of sexual predators and reassure those who are justifiably fearful. There can never be a biological binary test of gender, there can never be any scientific justification for binary division of facilities. Humanity itself is not binary, even life itself has blurry borders around comas, suspended animation and locked-in syndrome. Legal definitions of human death vary around the world. The only common thread I have ever found is: Be kind to each other. If you find anything above objectionable, then I can only suggest that you reconsider the science and learn to be kind to your fellow humans. None of us are getting out of this alive. I Think You ll Find It s a Bit More Complicated Than That - Ben Goldacre ISBN 978-0-00-750514-2 https://www.amazon.co.uk/dp/B00HATQA8K/ https://en.wikipedia.org/wiki/Androgen_insensitivity_syndrome https://www.bbc.co.uk/news/world-51235105 https://en.wikipedia.org/wiki/Nucleobase My degree is in pharmaceutical sciences and I practised community and hospital pharmacy for 20 years before moving into programming. I have direct experience of supporting people who were prescribed hormones to transition their physical characteristics to match their personal identity. I had a Christian upbringing but my work showed me that those religious norms were incompatible with being kind to others, so I rejected religion and I now consider myself a secular humanist.

7 December 2021

Evgeni Golov: The Mocking will continue, until CI improves

One might think, this blog is exclusively about weird language behavior and yelling at computers Well, welcome to another episode of Jackass! Today's opponent is Ruby, or maybe minitest , or maybe Mocha. I'm not exactly sure, but it was a rather amusing exercise and I like to share my nightmares ;) It all started with the classical "you're using old and unmaintained software, please switch to something new". The first attempt was to switch from the ci_reporter_minitest plugin to the minitest-ci plugin. While the change worked great for Foreman itself, it broke the reporting in Katello - the tests would run but no junit.xml was generated and Jenkins rightfully complained that it got no test results. While investigating what the hell was wrong, we realized that Katello was already using a minitest reporting plugin: minitest-reporters. Loading two different reporting plugins seemed like a good source for problems, so I tried using the same plugin for Foreman too. Guess what? After a bit of massaging (mostly to disable the second minitest-reporters initialization in Katello) reporting of test results from Katello started to work like a charm. But now the Foreman tests started to fail. Not fail to report, fail to actually run. WTH The failure was quite interesting too:
test/unit/parameter_filter_test.rb:5:in  block in <class:ParameterFilterTest>':
  Mocha methods cannot be used outside the context of a test (Mocha::NotInitializedError)
Yes, this is a single test file failing, all others were fine. The failing code doesn't look problematic on first glance:
require 'test_helper'
class ParameterFilterTest < ActiveSupport::TestCase
  let(:klass) do
    mock('Example').tap do  k 
      k.stubs(:name).returns('Example')
    end
  end
  test 'something' do
    something
  end
end
The failing line (5) is mock('Example').tap and for some reason Mocha thinks it's not initialized here. This certainly has something to do with how the various reporting plugins inject themselves, but I really didn't want to debug how to run two reporting plugins in parallel (which, as you remember, didn't expose this behavior). So the only real path forward was to debug what's happening here. Calling the test on its own, with one of the working reporter was the first step:
$ bundle exec rake test TEST=test/unit/parameter_filter_test.rb TESTOPTS=-v
 
#<Mocha::Mock:0x0000557bf1f22e30>#test_0001_permits plugin-added attribute = 0.04 s = .
#<Mocha::Mock:0x0000557bf12cf750>#test_0002_permits plugin-added attributes from blocks = 0.49 s = .
 
Wait, what? #<Mocha::Mock: >? Shouldn't this read more like ParameterFilterTest:: as it happens for every single other test in our test suite? It definitely should! That's actually great, as it tells us that there is really something wrong with the test and the change of the reporting plugin just makes it worse. What comes next is sheer luck. Well, that, and years of experience in yelling at computers. We use let(:klass) to define an object called klass and this object is a Mocha::Mock that we'll use in our tests later. Now klass is a very common term in Ruby when talking about classes and needing to store them mostly because one can't use class which is a keyword. Is something else in the stack using klass and our let is overriding that, making this whole thing explode? It was! The moment we replaced klass with klass1 (silly, I know, but there also was a klass2 in that code, so it did fit), things started to work nicely. I really liked Tomer's comment in the PR: "no idea why, but I am not going to dig into mocha to figure that out." Turns out, I couldn't let (HAH!) the code rest and really wanted to understand what happened there. What I didn't want to do is to debug the whole Foreman test stack, because it is massive. So I started to write a minimal reproducer for the issue. All starts with a Gemfile, as we need a few dependencies:
gem 'rake'
gem 'mocha'
gem 'minitest', '~> 5.1', '< 5.11'
Then a Rakefile:
require 'rake/testtask'
Rake::TestTask.new(:test) do  t 
  t.libs << 'test'
  t.test_files = FileList["test/**/*_test.rb"]
end
task :default => :test
And a test! I took the liberty to replace ActiveSupport::TestCase with Minitest::Test, as the test won't be using any Rails features and I wanted to keep my environment minimal.
require 'minitest/autorun'
require 'minitest/spec'
require 'mocha/minitest'
class ParameterFilterTest < Minitest::Test
  extend Minitest::Spec::DSL
  let(:klass) do
    mock('Example').tap do  k 
      k.stubs(:name).returns('Example')
    end
  end
  def test_lol
    assert klass
  end
end
Well, damn, this passed! Is it Rails after all that breaks stuff? Let's add it to the Gemfile!
$ vim Gemfile
$ bundle install
$ bundle exec rake test TESTOPTS=-v
 
#<Mocha::Mock:0x0000564bbfe17e98>#test_lol = 0.00 s = .
Wait, I didn't change anything and it's already failing?! Fuck! I mean, cool! But the test isn't minimal yet. What can we reduce? let is just a fancy, lazy def, right? So instead of let(:klass) we should be able to write def class and achieve a similar outcome and drop that Minitest::Spec.
require 'minitest/autorun'
require 'mocha/minitest'
class ParameterFilterTest < Minitest::Test
  def klass
    mock
  end
  def test_lol
    assert klass
  end
end
$ bundle exec rake test TESTOPTS=-v
 
/home/evgeni/Devel/minitest-wtf/test/parameter_filter_test.rb:5:in  klass': Mocha methods cannot be used outside the context of a test (Mocha::NotInitializedError)
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/railties-6.1.4.1/lib/rails/test_unit/reporter.rb:68:in  format_line'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/railties-6.1.4.1/lib/rails/test_unit/reporter.rb:15:in  record'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:682:in  block in record'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:681:in  each'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:681:in  record'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:324:in  run_one_method'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:311:in  block (2 levels) in run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:310:in  each'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:310:in  block in run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:350:in  on_signal'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:337:in  with_info_handler'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:309:in  run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:159:in  block in __run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:159:in  map'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:159:in  __run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:136:in  run'
    from /home/evgeni/Devel/minitest-wtf/vendor/bundle/ruby/3.0.0/gems/minitest-5.10.3/lib/minitest.rb:63:in  block in autorun'
rake aborted!
Oh nice, this is even better! Instead of the mangled class name, we now get the very same error the Foreman tests aborted with, plus a nice stack trace! But wait, why is it pointing at railties? We're not loading that! Anyways, lets look at railties-6.1.4.1/lib/rails/test_unit/reporter.rb, line 68
def format_line(result)
  klass = result.respond_to?(:klass) ? result.klass : result.class
  "%s#%s = %.2f s = %s" % [klass, result.name, result.time, result.result_code]
end
Heh, this is touching result.klass, which we just messed up. Nice! But quickly back to railties What if we only add that to the Gemfile, not full blown Rails?
gem 'railties'
gem 'rake'
gem 'mocha'
gem 'minitest', '~> 5.1', '< 5.11'
Yepp, same failure. Also happens with require => false added to the line, so it seems railties somehow injects itself into rake even if nothing is using it?! "Cool"! By the way, why are we still pinning minitest to < 5.11? Oh right, this was the original reason to look into that whole topic. And, uh, it's pointing at klass there already! 4 years ago! So lets remove that boundary and funny enough, now tests are passing again, even if we use klass! Minitest 5.11 changed how Minitest::Test is structured, and seems not to rely on klass at that point anymore. And I guess Rails also changed a bit since the original pin was put in place four years ago. I didn't want to go another rabbit hole, finding out what changed in Rails, but I did try with 5.0 (well, 5.0.7.2) to be precise, and the output with newer (>= 5.11) Minitest was interesting:
$ bundle exec rake test TESTOPTS=-v
 
Minitest::Result#test_lol = 0.00 s = .
It's leaking Minitest::Result as klass now, instead of Mocha::Mock. So probably something along these lines was broken 4 years ago and triggered this pin. What do we learn from that?
  • klass is cursed and shouldn't be used in places where inheritance and tooling might decide to use it for some reason
  • inheritance is cursed - why the heck are implementation details of Minitest leaking inside my tests?!
  • tooling is cursed - why is railties injecting stuff when I didn't ask it to?!
  • dependency pinning is cursed - at least if you pin to avoid an issue and then forget about said issue for four years
  • I like cursed things!

6 December 2021

Matthias Klumpp: New things in AppStream 0.15

On the road to AppStream 1.0, a lot of items from the long todo list have been done so far only one major feature is remaining, external release descriptions, which is a tricky one to implement and specify. For AppStream 1.0 it needs to be present or be rejected though, as it would be a major change in how release data is handled in AppStream. Besides 1.0 preparation work, the recent 0.15 release and the releases before it come with their very own large set of changes, that are worth a look and may be interesting for your application to support. But first, for a change that affects the implementation and not the XML format: 1. Completely rewritten caching code Keeping all AppStream data in memory is expensive, especially if the data is huge (as on Debian and Ubuntu with their large repositories generated from desktop-entry files as well) and if processes using AppStream are long-running. The latter is more and more the case, not only does GNOME Software run in the background, KDE uses AppStream in KRunner and Phosh will use it too for reading form factor information. Therefore, AppStream via libappstream provides an on-disk cache that is memory-mapped, so data is only consuming RAM if we are actually doing anything with it. Previously, AppStream used an LMDB-based cache in the background, with indices for fulltext search and other common search operations. This was a very fast solution, but also came with limitations, LMDB s maximum key size of 511 bytes became a problem quite often, adjusting the maximum database size (since it has to be set at opening time) was annoyingly tricky, and building dedicated indices for each search operation was very inflexible. In addition to that, the caching code was changed multiple times in the past to allow system-wide metadata to be cached per-user, as some distributions didn t (want to) build a system-wide cache and therefore ran into performance issues when XML was parsed repeatedly for generation of a temporary cache. In addition to all that, the cache was designed around the concept of one cache for data from all sources , which meant that we had to rebuild it entirely if just a small aspect changed, like a MetaInfo file being added to /usr/share/metainfo, which was very inefficient. To shorten a long story, the old caching code was rewritten with the new concepts of caches not necessarily being system-wide and caches existing for more fine-grained groups of files in mind. The new caching code uses Richard Hughes excellent libxmlb internally for memory-mapped data storage. Unlike LMDB, libxmlb knows about the XML document model, so queries can be much more powerful and we do not need to build indices manually. The library is also already used by GNOME Software and fwupd for parsing of (refined) AppStream metadata, so it works quite well for that usecase. As a result, search queries via libappstream are now a bit slower (very much depends on the query, roughly 20% on average), but can be mmuch more powerful. The caching code is a lot more robust, which should speed up startup time of applications. And in addition to all of that, the AsPool class has gained a flag to allow it to monitor AppStream source data for changes and refresh the cache fully automatically and transparently in the background. All software written against the previous version of the libappstream library should continue to work with the new caching code, but to make use of some of the new features, software using it may need adjustments. A lot of methods have been deprecated too now. 2. Experimental compose support Compiling MetaInfo and other metadata into AppStream collection metadata, extracting icons, language information, refining data and caching media is an involved process. The appstream-generator tool does this very well for data from Linux distribution sources, but the tool is also pretty heavyweight with lots of knobs to adjust, an underlying database and a complex algorithm for icon extraction. Embedding it into other tools via anything else but its command-line API is also not easy (due to D s GC initialization, and because it was never written with that feature in mind). Sometimes a simpler tool is all you need, so the libappstream-compose library as well as appstreamcli compose are being developed at the moment. The library contains building blocks for developing a tool like appstream-generator while the cli tool allows to simply extract metadata from any directory tree, which can be used by e.g. Flatpak. For this to work well, a lot of appstream-generator s D code is translated into plain C, so the implementation stays identical but the language changes. Ultimately, the generator tool will use libappstream-compose for any general data refinement, and only implement things necessary to extract data from the archive of distributions. New applications (e.g. for new bundling systems and other purposes) can then use the same building blocks to implement new data generators similar to appstream-generator with ease, sharing much of the code that would be identical between implementations anyway. 2. Supporting user input controls Want to advertise that your application supports touch input? Keyboard input? Has support for graphics tablets? Gamepads? Sure, nothing is easier than that with the new control relation item and supports relation kind (since 0.12.11 / 0.15.0, details):
<supports>
  <control>pointing</control>
  <control>keyboard</control>
  <control>touch</control>
  <control>tablet</control>
</supports>
3. Defining minimum display size requirements Some applications are unusable below a certain window size, so you do not want to display them in a software center that is running on a device with a small screen, like a phone. In order to encode this information in a flexible way, AppStream now contains a display_length relation item to require or recommend a minimum (or maximum) display size that the described GUI application can work with. For example:
<requires>
  <display_length compare="ge">360</display_length>
</requires>
This will make the application require a display length greater or equal to 300 logical pixels. A logical pixel (also device independent pixel) is the amount of pixels that the application can draw in one direction. Since screens, especially phone screens but also screens on a desktop, can be rotated, the display_length value will be checked against the longest edge of a display by default (by explicitly specifying the shorter edge, this can be changed). This feature is available since 0.13.0, details. See also Tobias Bernard s blog entry on this topic. 4. Tags This is a feature that was originally requested for the LVFS/fwupd, but one of the great things about AppStream is that we can take very project-specific ideas and generalize them so something comes out of them that is useful for many. The new tags tag allows people to tag components with an arbitrary namespaced string. This can be useful for project-internal organization of applications, as well as to convey certain additional properties to a software center, e.g. an application could mark itself as featured in a specific software center only. Metadata generators may also add their own tags to components to improve organization. AppStream gives no recommendations as to how these tags are to be interpreted except for them being a strictly optional feature. So any meaning is something clients and metadata authors need to negotiate. It therefore is a more specialized usecase of the already existing custom tag, and I expect it to be primarily useful within larger organizations that produce a lot of software components that need sorting. For example:
<tags>
  <tag namespace="lvfs">vendor-2021q1</tag>
  <tag namespace="plasma">featured</tag>
</tags>
This feature is available since 0.15.0, details. 5. MetaInfo Creator changes The MetaInfo Creator (source) tool is a very simple web application that provides you with a form to fill out and will then generate MetaInfo XML to add to your project after you have answered all of its questions. It is an easy way for developers to add the required metadata without having to read the specification or any guides at all. Recently, I added support for the new control and display_length tags, resolved a few minor issues and also added a button to instantly copy the generated output to clipboard so people can paste it into their project. If you want to create a new MetaInfo file, this tool is the best way to do it! The creator tool will also not transfer any data out of your webbrowser, it is strictly a client-side application. And that is about it for the most notable changes in AppStream land! Of course there is a lot more, additional tags for the LVFS and content rating have been added, lots of bugs have been squashed, the documentation has been refined a lot and the library has gained a lot of new API to make building software centers easier. Still, there is a lot to do and quite a few open feature requests too. Onwards to 1.0!

Paul Tagliamonte: Proxying Ethernet Frames to PACKRAT (Part 5/5)

This post is part of a series called "PACKRAT". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
In the last post, we left off at being able to send and recieve PACKRAT frames to and from devices. Since we can transport IPv4 packets over the network, let s go ahead and see if we can read/write Ethernet frames from a Linux network interface, and on the backend, read and write PACKRAT frames over the air. This has the benifit of continuing to allow Linux userspace tools to work (like cURL, as we ll try!), which means we don t have to do a lot of work to implement higher level protocols or tactics to get a connection established over the link. Given that this post is less RF and more Linuxy, I m going to include more code snippits than in prior posts, and those snippits are closer to runable Go, but still not complete examples. There s also a lot of different ways to do this, I ve just picked the easiest one for me to implement and debug given my existing tooling for you, you may find another approach easier to implement! Again, deviation here is very welcome, and since this segment is the least RF centric post in the series, the pace and tone is going to feel different. If you feel lost here, that s OK. This isn t the most important part of the series, and is mostly here to give a concrete ending to the story arc. Any way you want to finish your own journy is the best way for you to finish it!

Implement Ethernet conversion code This assumes an importable package with a Frame struct, which we can use to convert a Frame to/from Ethernet. Given that the PACKRAT frame has a field that Ethernet doesn t (namely, Callsign), that will need to be explicitly passed in when turning an Ethernet frame into a PACKRAT Frame.
...
// ToPackrat will create a packrat frame from an Ethernet frame.
func ToPackrat(callsign [8]byte, frame *ethernet.Frame) (*packrat.Frame, error)  
var frameType packrat.FrameType
switch frame.EtherType  
case ethernet.EtherTypeIPv4:
frameType = packrat.FrameTypeIPv4
default:
return nil, fmt.Errorf("ethernet: unsupported ethernet type %x", frame.EtherType)
 
return &packrat.Frame 
Destination: frame.Destination,
Source: frame.Source,
Type: frameType,
Callsign: callsign,
Payload: frame.Payload,
 , nil
 
// FromPackrat will create an Ethernet frame from a Packrat frame.
func FromPackrat(frame *packrat.Frame) (*ethernet.Frame, error)  
var etherType ethernet.EtherType
switch frame.Type  
case packrat.FrameTypeRaw:
return nil, fmt.Errorf("ethernet: unsupported packrat type 'raw'")
case packrat.FrameTypeIPv4:
etherType = ethernet.EtherTypeIPv4
default:
return nil, fmt.Errorf("ethernet: unknown packrat type %x", frame.Type)
 
// We lose the Callsign here, which is sad.
 return &ethernet.Frame 
Destination: frame.Destination,
Source: frame.Source,
EtherType: etherType,
Payload: frame.Payload,
 , nil
 
Our helpers, ToPackrat and FromPackrat can now be used to transmorgify PACKRAT into Ethernet, or Ethernet into PACKRAT. Let s put them into use!

Implement a TAP interface On Linux, the networking stack can be exposed to userland using TUN or TAP interfaces. TUN devices allow a userspace program to read and write data at the Layer 3 / IP layer. TAP devices allow a userspace program to read and write data at the Layer 2 Data Link / Ethernet layer. Writing data at Layer 2 is what we want to do, since we re looking to transform our Layer 2 into Ethernet s Layer 2 Frames. Our first job here is to create the actual TAP interface, set the MAC address, and set the IP range to our pre-coordinated IP range.
...
import (
"net"
"github.com/mdlayher/ethernet"
"github.com/songgao/water"
"github.com/vishvananda/netlink"
)
...
config := water.Config DeviceType: water.TAP 
config.Name = "rat0"
iface, err := water.New(config)
...
netIface, err := netlink.LinkByName("rat0")
...
// Pick a range here that works for you!
 //
 // For my local network, I'm using some IPs
 // that AMPR (ampr.org) was nice enough to
 // allocate to me for ham radio use. Thanks,
 // AMPR!
 //
 // Let's just use 10.* here, though.
 //
 ip, cidr, err := net.ParseCIDR("10.0.0.1/24")
...
cidr.IP = ip
err = netlink.AddrAdd(netIface, &netlink.Addr 
IPNet: cidr,
Peer: cidr,
 )
...
// Add all our neighbors to the ARP table
 for _, neighbor := range neighbors  
netlink.NeighAdd(&netlink.Neigh 
LinkIndex: netIface.Attrs().Index,
Type: netlink.FAMILY_V4,
State: netlink.NUD_PERMANENT,
IP: neighbor.IP,
HardwareAddr: neighbor.MAC,
 )
 
// Pick a MAC that is globally unique here, this is
 // just used as an example!
 addr, err := net.ParseMAC("FA:DE:DC:AB:LE:01")
...
netlink.LinkSetHardwareAddr(netIface, addr)
...
err = netlink.LinkSetUp(netIface)
var frame = &ethernet.Frame 
var buf = make([]byte, 1500)
for  
n, err := iface.Read(buf)
...
err = frame.UnmarshalBinary(buf[:n])
...
// process frame here (to come)
  
...
Now that our network stack can resolve an IP to a MAC Address (via ip neigh according to our pre-defined neighbors), and send that IP packet to our daemon, it s now on us to send IPv4 data over the airwaves. Here, we re going to take packets coming in from our TAP interface, and marshal the Ethernet frame into a PACKRAT Frame and transmit it. As with the rest of the RF code, we ll leave that up to the implementer, of course, using what was built during Part 2: Transmitting BPSK symbols and Part 4: Framing data.
...
for  
// continued from above

n, err := iface.Read(buf)
...
err = frame.UnmarshalBinary(buf[:n])
...
switch frame.EtherType  
case 0x0800:
// ipv4 packet
 pack, err := ToPackrat(
// Add my callsign to all Frames, for now
 [8]byte 'K', '3', 'X', 'E', 'C' ,
frame,
)
...
err = transmitPacket(pack)
...
 
 
...
Now that we have transmitting covered, let s go ahead and handle the recieve path here. We re going to listen on frequency using the code built in Part 3: Receiving BPSK symbols and Part 4: Framing data. The Frames we decode from the airwaves are expected to come back from the call packratReader.Next in the code below, and the exact way that works is up to the implementer.
...
for  
// pull the next packrat frame from
 // the symbol stream as we did in the
 // last post
 packet, err := packratReader.Next()
...
// check for CRC errors and drop invalid
 // packets
 err = packet.Check()
...
if bytes.Equal(packet.Source, addr)  
// if we've heard ourself transmitting
 // let's avoid looping back
 continue
 
// create an ethernet frame
 frame, err := FromPackrat(packet)
...
buf, err := frame.MarshalBinary()
...
// and inject it into the tap
 err = iface.Write(buf)
...
 
...
Phew. Right. Now we should be able to listen for PACKRAT frames on the air and inject them into our TAP interface.

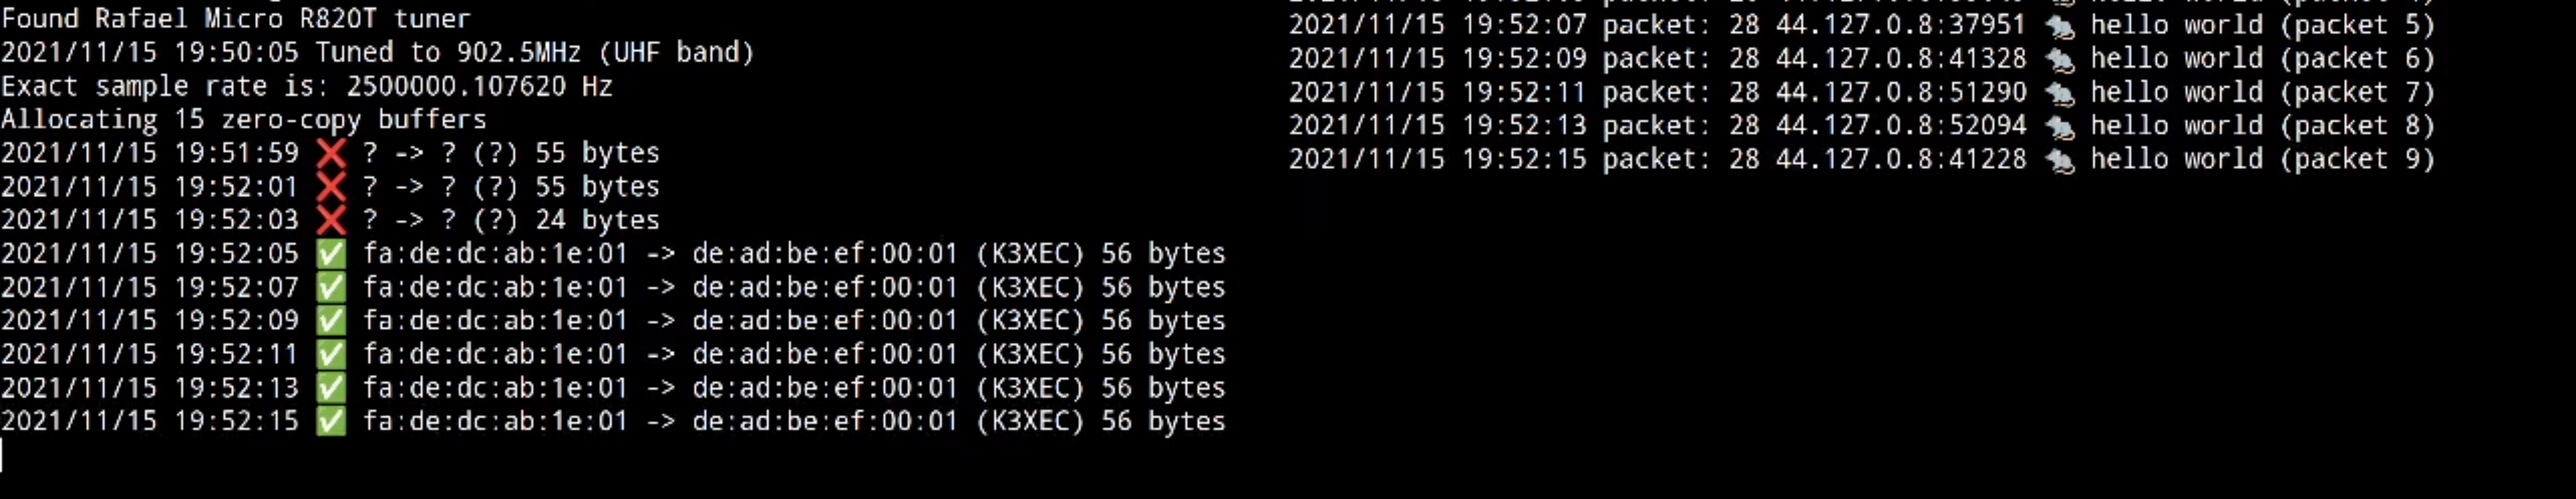
Putting it all Together After all this work weeks of work! we can finally get around to putting some real packets over the air. For me, this was an incredibly satisfying milestone, and tied together months of learning! I was able to start up a UDP server on a remote machine with an RTL-SDR dongle attached to it, listening on the TAP interface s host IP with my defined MAC address, and send UDP packets to that server via PACKRAT using my laptop, /dev/udp and an Ettus B210, sending packets into the TAP interface. Now that UDP was working, I was able to get TCP to work using two PlutoSDRs, which allowed me to run the cURL command I pasted in the first post (both simultaneously listen and transmit on behalf of my TAP interface). It s my hope that someone out there will be inspired to implement their own Layer 1 and Layer 2 as a learning exercise, and gets the same sense of gratification that I did! If you re reading this, and at a point where you ve been able to send IP traffic over your own Layer 1 / Layer 2, please get in touch! I d be thrilled to hear all about it. I d love to link to any posts or examples you publish here!
5 December 2021

Reproducible Builds: Reproducible Builds in November 2021

Welcome to the November 2021 report from the Reproducible Builds project. As a quick recap, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is therefore to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. If you are interested in contributing to our project, please visit our Contribute page on our website.
On November 6th, Vagrant Cascadian presented at this year s edition of the SeaGL conference, giving a talk titled Debugging Reproducible Builds One Day at a Time:
I ll explore how I go about identifying issues to work on, learn more about the specific issues, recreate the problem locally, isolate the potential causes, dissect the problem into identifiable parts, and adapt the packaging and/or source code to fix the issues.
A video recording of the talk is available on archive.org.
Fedora Magazine published a post written by Zbigniew J drzejewski-Szmek about how to Use Diffoscope in packager workflows, specifically around ensuring that new versions of a package do not introduce breaking changes:
In the role of a packager, updating packages is a recurring task. For some projects, a packager is involved in upstream maintenance, or well written release notes make it easy to figure out what changed between the releases. This isn t always the case, for instance with some small project maintained by one or two people somewhere on GitHub, and it can be useful to verify what exactly changed. Diffoscope can help determine the changes between package releases. [ ]

kpcyrd announced the release of rebuilderd version 0.16.3 on our mailing list this month, adding support for builds to generate multiple artifacts at once.
Lastly, we held another IRC meeting on November 30th. As mentioned in previous reports, due to the global events throughout 2020 etc. there will be no in-person summit event this year.

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb made the following changes, including preparing and uploading versions 190, 191, 192, 193 and 194 to Debian:
  • New features:
    • Continue loading a .changes file even if the referenced files do not exist, but include a comment in the returned diff. [ ]
    • Log the reason if we cannot load a Debian .changes file. [ ]
  • Bug fixes:
    • Detect XML files as XML files if file(1) claims if they are XML files or if they are named .xml. (#999438)
    • Don t duplicate file lists at each directory level. (#989192)
    • Don t raise a traceback when comparing nested directories with non-directories. [ ]
    • Re-enable test_android_manifest. [ ]
    • Don t reject Debian .changes files if they contain non-printable characters. [ ]
  • Codebase improvements:
    • Avoid aliasing variables if we aren t going to use them. [ ]
    • Use isinstance over type. [ ]
    • Drop a number of unused imports. [ ]
    • Update a bunch of %-style string interpolations into f-strings or str.format. [ ]
    • When pretty-printing JSON, mark the difference as being reformatted, additionally avoiding including the full path. [ ]
    • Import itertools top-level module directly. [ ]
Chris Lamb also made an update to the command-line client to trydiffoscope, a web-based version of the diffoscope in-depth and content-aware diff utility, specifically only waiting for 2 minutes for try.diffoscope.org to respond in tests. (#998360) In addition Brandon Maier corrected an issue where parts of large diffs were missing from the output [ ], Zbigniew J drzejewski-Szmek fixed some logic in the assert_diff_startswith method [ ] and Mattia Rizzolo updated the packaging metadata to denote that we support both Python 3.9 and 3.10 [ ] as well as a number of warning-related changes[ ][ ]. Vagrant Cascadian also updated the diffoscope package in GNU Guix [ ][ ].

Distribution work In Debian, Roland Clobus updated the wiki page documenting Debian reproducible Live images to mention some new bug reports and also posted an in-depth status update to our mailing list. In addition, 90 reviews of Debian packages were added, 18 were updated and 23 were removed this month adding to our knowledge about identified issues. Chris Lamb identified a new toolchain issue, absolute_path_in_cmake_file_generated_by_meson.
Work has begun on classifying reproducibility issues in packages within the Arch Linux distribution. Similar to the analogous effort within Debian (outlined above), package information is listed in a human-readable packages.yml YAML file and a sibling README.md file shows how to classify packages too. Finally, Bernhard M. Wiedemann posted his monthly reproducible builds status report for openSUSE and Vagrant Cascadian updated a link on our website to link to the GNU Guix reproducibility testing overview [ ].

Software development The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including: Elsewhere, in software development, Jonas Witschel updated strip-nondeterminism, our tool to remove specific non-deterministic results from a completed build so that it did not fail on JAR archives containing invalid members with a .jar extension [ ]. This change was later uploaded to Debian by Chris Lamb. reprotest is the Reproducible Build s project end-user tool to build the same source code twice in widely different environments and checking whether the binaries produced by the builds have any differences. This month, Mattia Rizzolo overhauled the Debian packaging [ ][ ][ ] and fixed a bug surrounding suffixes in the Debian package version [ ], whilst Stefano Rivera fixed an issue where the package tests were broken after the removal of diffoscope from the package s strict dependencies [ ].

Testing framework The Reproducible Builds project runs a testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
  • Holger Levsen:
    • Document the progress in setting up snapshot.reproducible-builds.org. [ ]
    • Add the packages required for debian-snapshot. [ ]
    • Make the dstat package available on all Debian based systems. [ ]
    • Mark virt32b-armhf and virt64b-armhf as down. [ ]
  • Jochen Sprickerhof:
    • Add SSH authentication key and enable access to the osuosl168-amd64 node. [ ][ ]
  • Mattia Rizzolo:
    • Revert reproducible Debian: mark virt(32 64)b-armhf as down - restored. [ ]
  • Roland Clobus (Debian live image generation):
    • Rename sid internally to unstable until an issue in the snapshot system is resolved. [ ]
    • Extend testing to include Debian bookworm too.. [ ]
    • Automatically create the Jenkins view to display jobs related to building the Live images. [ ]
  • Vagrant Cascadian:
    • Add a Debian package set group for the packages and tools maintained by the Reproducible Builds maintainers themselves. [ ]


If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Paul Tagliamonte: Framing data (Part 4/5)

This post is part of a series called "PACKRAT". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
In the last post, we we were able to build a functioning Layer 1 PHY where we can encode symbols to transmit, and receive symbols on the other end, we re now at the point where we can encode and decode those symbols as bits and frame blocks of data, marking them with a Sender and a Destination for routing to the right host(s). This is a Layer 2 scheme in the OSI model, which is otherwise known as the Data Link Layer. You re using one to view this website right now I m willing to bet your data is going through an Ethernet layer 2 as well as WiFi or maybe a cellular data protocol like 5G or LTE. Given that this entire exercise is hard enough without designing a complex Layer 2 scheme, I opted for simplicity in the hopes this would free me from the complexity and research that has gone into this field for the last 50 years. I settled on stealing a few ideas from Ethernet Frames namely, the use of MAC addresses to identify parties, and the EtherType field to indicate the Payload type. I also stole the idea of using a CRC at the end of the Frame to check for corruption, as well as the specific CRC method (crc32 using 0xedb88320 as the polynomial). Lastly, I added a callsign field to make life easier on ham radio frequencies if I was ever to seriously attempt to use a variant of this protocol over the air with multiple users. However, given this scheme is not a commonly used scheme, it s best practice to use a nearby radio to identify your transmissions on the same frequency while testing or use a Faraday box to test without transmitting over the airwaves. I added the callsign field in an effort to lean into the spirit of the Part 97 regulations, even if I relied on a phone emission to identify the Frames. As an aside, I asked the ARRL for input here, and their stance to me over email was I d be OK according to the regs if I were to stick to UHF and put my callsign into the BPSK stream using a widely understood encoding (even with no knowledge of PACKRAT, the callsign is ASCII over BPSK and should be easily demodulatable for followup with me). Even with all this, I opted to use FM phone to transmit my callsign when I was active on the air (specifically, using an SDR and a small bash script to automate transmission while I watched for interference or other band users). Right, back to the Frame:
sync
dest
source
callsign
type
payload
crc
With all that done, I put that layout into a struct, so that we can marshal and unmarshal bytes to and from our Frame objects, and work with it in software.
type FrameType [2]byte
type Frame struct  
Destination net.HardwareAddr
Source net.HardwareAddr
Callsign [8]byte
Type FrameType
Payload []byte
CRC uint32
 

Time to pick some consts I picked a unique and distinctive sync sequence, which the sender will transmit before the Frame, while the receiver listens for that sequence to know when it s in byte alignment with the symbol stream. My sync sequence is [3]byte 'U', 'f', '~' which works out to be a very pleasant bit sequence of 01010101 01100110 01111110. It s important to have soothing preambles for your Frames. We need all the good energy we can get at this point.
var (
FrameStart = [3]byte 'U', 'f', '~' 
FrameMaxPayloadSize = 1500
)
Next, I defined some FrameType values for the type field, which I can use to determine what is done with that data next, something Ethernet was originally missing, but has since grown to depend on (who needs Length anyway? Not me. See below!)
FrameType Description Bytes
Raw Bytes in the Payload field are opaque and not to be parsed. [2]byte 0x00, 0x01
IPv4 Bytes in the Payload field are an IPv4 packet. [2]byte 0x00, 0x02
And finally, I decided on a maximum length of the Payload, and decided on limiting it to 1500 bytes to align with the MTU of Ethernet.
var (
FrameTypeRaw = FrameType 0, 1 
FrameTypeIPv4 = FrameType 0, 2 
)
Given we know how we re going to marshal and unmarshal binary data to and from Frames, we can now move on to looking through the bit stream for our Frames.

Why is there no Length field? I was initially a bit surprised that Ethernet Frames didn t have a Length field in use, but the more I thought about it, the more it seemed like a big ole' failure mode without a good implementation outcome. Either the Length is right (resulting in no action and used bits on every packet) or the Length is not the length of the Payload and the driver needs to determine what to do with the packet does it try and trim the overlong payload and ignore the rest? What if both the end of the read bytes and the end of the subset of the packet denoted by Length have a valid CRC? Which is used? Will everyone agree? What if Length is longer than the Payload but the CRC is good where we detected a lost carrer? I decided on simplicity. The end of a Frame is denoted by the loss of the BPSK carrier when the signal is no longer being transmitted (or more correctly, when the signal is no longer received), we know we ve hit the end of a packet. Missing a single symbol will result in the Frame being finalized. This can cause some degree of corruption, but it s also a lot easier than doing tricks like bit stuffing to create an end of symbol stream delimiter.

Finding the Frame start in a Symbol Stream First thing we need to do is find our sync bit pattern in the symbols we re receiving from our BPSK demodulator. There s some smart ways to do this, but given that I m not much of a smart man, I again decided to go for simple instead. Given our incoming vector of symbols (which are still float values) prepend one at a time to a vector of floats that is the same length as the sync phrase, and compare against the sync phrase, to determine if we re in sync with the byte boundary within the symbol stream. The only trick here is that because we re using BPSK to modulate and demodulate the data, post phaselock we can be 180 degrees out of alignment (such that a +1 is demodulated as -1, or vice versa). To deal with that, I check against both the sync phrase as well as the inverse of the sync phrase (both [1, -1, 1] as well as [-1, 1, -1]) where if the inverse sync is matched, all symbols to follow will be inverted as well. This effectively turns our symbols back into bits, even if we re flipped out of phase. Other techniques like NRZI will represent a 0 or 1 by a change in phase state which is great, but can often cascade into long runs of bit errors, and is generally more complex to implement. That representation isn t ambiguous, given you look for a phase change, not the absolute phase value, which is incredibly compelling. Here s a notional example of how I ve been thinking about the phrase sliding window and how I ve been thinking of the checks. Each row is a new symbol taken from the BPSK receiver, and pushed to the head of the sliding window, moving all symbols back in the vector by one.
 var (
sync = []float  ...  
buf = make([]float, len(sync))
incomingSymbols = []float  ...  
)
for _, el := range incomingSymbols  
copy(buf, buf[1:])
buf[len(buf)-1] = el
if compare(sync, buf)  
// we're synced!
 break
 
 
Given the pseudocode above, let s step through what the checks would be doing at each step:
Buffer Sync Inverse Sync
[ ]float 0, ,0 [ ]float -1, ,-1 [ ]float 1, ,1
[ ]float 0, ,1 [ ]float -1, ,-1 [ ]float 1, ,1
[more bits in] [ ]float -1, ,-1 [ ]float 1, ,1
[ ]float 1, ,1 [ ]float -1, ,-1 [ ]float 1, ,1
After this notional set of comparisons, we know that at the last step, we are now aligned to the frame and byte boundary the next symbol / bit will be the MSB of the 0th Frame byte. Additionally, we know we re also 180 degrees out of phase, so we need to flip the symbol s sign to get the bit. From this point on we can consume 8 bits at a time, and re-assemble the byte stream. I don t know what this technique is called or even if this is used in real grown-up implementations, but it s been working for my toy implementation.

Next Steps Now that we can read/write Frames to and from PACKRAT, the next steps here are going to be implementing code to encode and decode Ethernet traffic into PACKRAT, coming next in Part 5!

4 December 2021

Jonathan Dowland: Haskell mortgage calculator

A few months ago I was trying to compare two mortgage offers, and ended up writing a small mortgage calculator to help me. Both mortgages were fixed-term for the same time period (5 years). One of the mortgages had a lower rate than the other, but much higher arrangement fees. A broker recommended the mortgage with the higher rate but lower fee, on an affordability basis for the fixed term: over all, we would spend less money within the fixed term on that deal than the other. (I thought) this left one bit of information missing: what remaining balance would there be at the end of the term? The mortgages I want to model are defined in terms of a monthly repayment figure and an annual interest rate for the fixed period. I think interest is usually recalculated on a daily basis, so I convert the annual rate down to a daily rate. Repayments only happen once a month. Months are not all the same size. Using mod 30 on the 'day' approximates a monthly payment. Over 5 years, there would be 60 months, meaning 60 repayments. (I'm ignoring leap years)
 > length . filter id .take (5*365) $ [ x mod 30==0   x <- [1..]]
60
Here's what I came up with. I was a little concerned the repayment approximation was too far out so I compared the output with a more precise (but boring) spreadsheet and they agreed to within an acceptable tolerance. The numbers that follow are all made up to illustrate the function and don't reflect my actual mortgage. :)
borrowed = 1000000 -- day 0 amount outstanding
aer   = 0.89
repay = 1000
der   = aer / 36
owed n   n == 0          = borrowed
         n  mod  30 == 0 = last + interest - repay
         otherwise       = last + interest
    where
        last     = owed (n - 1)
        interest = last * der

3 December 2021

Paul Tagliamonte: Transmitting BPSK symbols (Part 2/5)

This post is part of a series called "PACKRAT". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
In the last post, we worked through what IQ is, and different formats that it may be sent or received in. Let s take that and move on to Transmitting BPSK using IQ data! When we transmit and receive information through RF using an SDR, data is traditionally encoded into a stream of symbols which are then used by a program to modulate the IQ stream, and sent over the airwaves. PACKRAT uses BPSK to encode Symbols through RF. BPSK is the act of modulating the phase of a sine wave to carry information. The transmitted wave swaps between two states in order to convey a 0 or a 1. Our symbols modulate the transmitted sine wave s phase, so that it moves between in-phase with the SDR s transmitter and 180 degrees (or radians) out of phase with the SDR s transmitter. The difference between a Bit and a Symbol in PACKRAT is not incredibly meaningful, and I ll often find myself slipping up when talking about them. I ve done my best to try and use the right word at the right stage, but it s not as obvious where the line between bit and symbol is at least not as obvious as it would be with QPSK or QAM. The biggest difference is that there are three meaningful states for PACKRAT over BPSK - a 1 (for In phase ), -1 (for 180 degrees out of phase ) and 0 (for no carrier ). For my implementation, a stream of all zeros will not transmit data over the airwaves, a stream of all 1s will transmit all 1 bits over the airwaves, and a stream of all -1s will transmit all 0 bits over the airwaves. We re not going to cover turning a byte (or bit) into a symbol yet I m going to write more about that in a later section. So for now, let s just worry about symbols in, and symbols out.

Transmitting a Sine wave at 0Hz If we go back to thinking about IQ data as a precisely timed measurements of energy over time at some particular specific frequency, we can consider what a sine wave will look like in IQ. Before we dive into antennas and RF, let s go to something a bit more visual. For the first example, you can see an example of a camera who s frame rate (or Sampling Rate!) matches the exact number of rotations per second (or Frequency!) of the propeller and it appears to stand exactly still. Every time the Camera takes a frame, it s catching the propeller in the exact same place in space, even though it s made a complete rotation. The second example is very similar, it s a light strobing (in this case, our sampling rate, since the darkness is ignored by our brains) at the same rate (frequency) as water dropping from a faucet and the video creator is even nice enough to change the sampling frequency to have the droplets move both forward and backward (positive and negative frequency) in comparison to the faucet. IQ works the same way. If we catch something in perfect frequency alignment with our radio, we ll wind up with readings that are the same for the entire stream of data. This means we can transmit a sine wave by setting all of the IQ samples in our buffer to 1+0i, which will transmit a pure sine wave at exactly the center frequency of the radio.
 var sine []complex 
for i := range sine  
sine[i] = complex(1.0, 0.0)
 
Alternatively, we can transmit a Sine wave (but with the opposite phase) by flipping the real value from 1 to -1. The same Sine wave is transmitted on the same Frequency, except when the wave goes high in the example above, the wave will go low in the example below.
 var sine []complex 
for i := range sine  
sine[i] = complex(-1.0, 0.0)
 
In fact, we can make a carrier wave at any phase angle and amplitude by using a bit of trig.
 // angle is in radians - here we have
 // 1.5 Pi (3 Tau) or 270 degrees.
 var angle = pi * 1.5
// amplitude controls the transmitted
 // strength of the carrier wave.
 var amplitude = 1.0
// output buffer as above
 var sine []complex 
for i := range sine  
sine[i] = complex(
amplitude*cos(angle),
amplitude*sin(angle),
)
 
The amplitude of the transmitted wave is the absolute value of the IQ sample (sometimes called magnitude), and the phase can be computed as the angle (or argument). The amplitude remains constant (at 1) in both cases. Remember back to the airplane propeller or water droplets we re controlling where we re observing the sine wave. It looks like a consistent value to us, but in reality it s being transmitted as a pure carrier wave at the provided frequency. Changing the angle of the number we re transmitting will control where in the sine wave cycle we re observing it at.

Generating BPSK modulated IQ data Modulating our carrier wave with our symbols is fairly straightforward to do we can multiply the symbol by 1 to get the real value to be used in the IQ stream. Or, more simply - we can just use the symbol directly in the constructed IQ data.
 var sampleRate = 2,621,440
var baudRate = 1024
// This represents the number of IQ samples
 // required to send a single symbol at the
 // provided baud and sample rate. I picked
 // two numbers in order to avoid half samples.
 // We will transmit each symbol in blocks of
 // this size.
 var samplesPerSymbol = sampleRate / baudRate
var samples = make([]complex, samplesPerSymbol)
// symbol is one of 1, -1 or 0.
 for each symbol in symbols  
for i := range samples  
samples[i] = complex(symbol, 0)
 
// write the samples out to an output file
 // or radio.
 write(samples)
 
If you want to check against a baseline capture, here s 10 example packets at 204800 samples per second.

Next Steps Now that we can transmit data, we ll start working on a receive path in Part 3, in order to check our work when transmitting the packets, as well as being able to hear packets we transmit from afar, coming up next in Part 3!!

Evgeni Golov: Dependency confusion in the Ansible Galaxy CLI

I hope you enjoyed my last post about Ansible Galaxy Namespaces. In there I noted that I originally looked for something completely different and the namespace takeover was rather accidental. Well, originally I was looking at how the different Ansible content hosting services and their client (ansible-galaxy) behave in regard to clashes in naming of the hosted content. "Ansible content hosting services"?! There are currently three main ways for users to obtain Ansible content:
  • Ansible Galaxy - the original, community oriented, free hosting platform
  • Automation Hub - the place for Red Hat certified and supported content, available only with a Red Hat subscription, hosted by Red Hat
  • Ansible Automation Platform - the on-premise version of Automation Hub, syncs content from there and allows customers to upload own content
Now the question I was curious about was: how would the tooling behave if different sources would offer identically named content? This was inspired by Alex Birsan: Dependency Confusion: How I Hacked Into Apple, Microsoft and Dozens of Other Companies and zofrex: Bundler is Still Vulnerable to Dependency Confusion Attacks (CVE - 2020 - 36327), who showed that the tooling for Python, Node.js and Ruby can be tricked into fetching content from "the wrong source", thus allowing an attacker to inject malicious code into a deployment. For the rest of this article, it's not important that there are different implementations of the hosting services, only that users can configure and use multiple sources at the same time. The problem is that, if the user configures their server_list to contain multiple Galaxy-compatible servers, like Ansible Galaxy and Automation Hub, and then asks to install a collection, the Ansible Galaxy CLI will ask every server in the list, until one returns a successful result. The exact order seems to differ between versions, but this doesn't really matter for the issue at hand. Imagine someone wants to install the redhat.satellite collection from Automation Hub (using ansible-galaxy collection install redhat.satellite). Now if their configuration defines Galaxy as the first, and Automation Hub as the second server, Galaxy is always asked whether it has redhat.satellite and only if the answer is negative, Automation Hub is asked. Today there is no redhat namespace on Galaxy, but there is a redhat user on GitHub, so The canonical answer to this issue is to use a requirements.yml file and setting the source parameter. This parameter allows you to express "regardless which sources are configured, please fetch this collection from here". That's is nice, but I think this not being the default syntax (contrary to what e.g. Bundler does) is a bad approach. Users might overlook the security implications, as the shorter syntax without the source just "magically" works. However, I think this is not even the main problem here. The documentation says: Once a collection is found, any of its requirements are only searched within the same Galaxy instance as the parent collection. The install process will not search for a collection requirement in a different Galaxy instance. But as it turns out, the source behavior was changed and now only applies to the exact collection it is set for, not for any dependencies this collection might have. For the sake of the example, imagine two collections: evgeni.test1 and evgeni.test2, where test2 declares a dependency on test1 in its galaxy.yml. Actually, no need to imagine, both collections are available in version 1.0.0 from galaxy.ansible.com and test1 version 2.0.0 is available from galaxy-dev.ansible.com. Now, given our recent reading of the docs, we craft the following requirements.yml:
collections:
- name: evgeni.test2
  version: '*'
  source: https://galaxy.ansible.com
In a perfect world, following the documentation, this would mean that both collections are fetched from galaxy.ansible.com, right? However, this is not what ansible-galaxy does. It will fetch evgeni.test2 from the specified source, determine it has a dependency on evgeni.test1 and fetch that from the "first" available source from the configuration. Take for example the following ansible.cfg:
[galaxy]
server_list = test_galaxy, release_galaxy, test_galaxy
[galaxy_server.release_galaxy]
url=https://galaxy.ansible.com/
[galaxy_server.test_galaxy]
url=https://galaxy-dev.ansible.com/
And try to install collections, using the above requirements.yml:
% ansible-galaxy collection install -r requirements.yml -vvv                 
ansible-galaxy 2.9.27
  config file = /home/evgeni/Devel/ansible-wtf/collections/ansible.cfg
  configured module search path = ['/home/evgeni/.ansible/plugins/modules', '/usr/share/ansible/plugins/modules']
  ansible python module location = /usr/lib/python3.10/site-packages/ansible
  executable location = /usr/bin/ansible-galaxy
  python version = 3.10.0 (default, Oct  4 2021, 00:00:00) [GCC 11.2.1 20210728 (Red Hat 11.2.1-1)]
Using /home/evgeni/Devel/ansible-wtf/collections/ansible.cfg as config file
Reading requirement file at '/home/evgeni/Devel/ansible-wtf/collections/requirements.yml'
Found installed collection theforeman.foreman:3.0.0 at '/home/evgeni/.ansible/collections/ansible_collections/theforeman/foreman'
Process install dependency map
Processing requirement collection 'evgeni.test2'
Collection 'evgeni.test2' obtained from server explicit_requirement_evgeni.test2 https://galaxy.ansible.com/api/
Opened /home/evgeni/.ansible/galaxy_token
Processing requirement collection 'evgeni.test1' - as dependency of evgeni.test2
Collection 'evgeni.test1' obtained from server test_galaxy https://galaxy-dev.ansible.com/api
Starting collection install process
Installing 'evgeni.test2:1.0.0' to '/home/evgeni/.ansible/collections/ansible_collections/evgeni/test2'
Downloading https://galaxy.ansible.com/download/evgeni-test2-1.0.0.tar.gz to /home/evgeni/.ansible/tmp/ansible-local-133/tmp9uqyjgki
Installing 'evgeni.test1:2.0.0' to '/home/evgeni/.ansible/collections/ansible_collections/evgeni/test1'
Downloading https://galaxy-dev.ansible.com/download/evgeni-test1-2.0.0.tar.gz to /home/evgeni/.ansible/tmp/ansible-local-133/tmp9uqyjgki
As you can see, evgeni.test1 is fetched from galaxy-dev.ansible.com, instead of galaxy.ansible.com. Now, if those servers instead would be Galaxy and Automation Hub, and somebody managed to snag the redhat namespace on Galaxy, I would be now getting the wrong stuff Another problematic setup would be with Galaxy and on-prem Ansible Automation Platform, as you can have any namespace on the later and these most certainly can clash with namespaces on public Galaxy. I have reported this behavior to Ansible Security on 2021-08-26, giving a 90 days disclosure deadline, which expired on 2021-11-24. So far, the response was that this is working as designed, to allow cross-source dependencies (e.g. a private collection referring to one on Galaxy) and there is an issue to update the docs to match the code. If users want to explicitly pin sources, they are supposed to name all dependencies and their sources in requirements.yml. Alternatively they obviously can configure only one source in the configuration and always mirror all dependencies. I am not happy with this and I think this is terrible UX, explicitly inviting people to make mistakes.

2 December 2021

Jonathan McDowell: Building a desktop to improve my work/life balance

ASRock DeskMini X300 It s been over 20 months since the first COVID lockdown kicked in here in Northern Ireland and I started working from home. Even when the strict lockdown was lifted the advice here has continued to be If you can work from home you should work from home . I ve been into the office here and there (for new starts given you need to hand over a laptop and sort out some login details it s generally easier to do so in person, and I ve had a couple of whiteboard sessions that needed the high bandwidth face to face communication), but day to day is all from home. Early on I commented that work had taken over my study. This has largely continued to be true. I set my work laptop on the stand on a Monday morning and it sits there until Friday evening, when it gets switched for the personal laptop. I have a lovely LG 34UM88 21:9 Ultrawide monitor, and my laptops are small and light so I much prefer to use them docked. Also my general working pattern is to have a lot of external connections up and running (build machine, test devices, log host) which means a suspend/resume cycle disrupts things. So I like to minimise moving things about. I spent a little bit of time trying to find a dual laptop stand so I could have both machines setup and switch between them easily, but I didn t find anything that didn t seem to be geared up for DJs with a mixer + laptop combo taking up quite a bit of desk space rather than stacking laptops vertically. Eventually I realised that the right move was probably a desktop machine. Now, I haven t had a desktop machine since before I moved to the US, realising at the time that having everything on my laptop was much more convenient. I decided I didn t want something too big and noisy. Cheap GPUs seem hard to get hold of these days - I m not a gamer so all I need is something that can drive a ~ 4K monitor reliably enough. Looking around the AMD Ryzen 7 5700G seemed to be a decent CPU with one of the better integrated GPUs. I spent some time looking for a reasonable Mini-ITX case + motherboard and then I happened upon the ASRock DeskMini X300. This turns out to be perfect; I ve no need for a PCIe slot or anything more than an m.2 SSD. I paired it with a Noctua NH-L9a-AM4 heatsink + fan (same as I use in the house server), 32GB DDR4 and a 1TB WD SN550 NVMe SSD. Total cost just under 650 inc VAT + delivery (and that s a story for another post). A desktop solves the problem of fitting both machines on the desk at once, but there s still the question of smoothly switching between them. I read Evgeni Golov s article on a simple KVM switch for 30. My monitor has multiple inputs, so that s sorted. I did have a cheap USB2 switch (all I need for the keyboard/trackball) but it turned out to be pretty unreliable at the host detecting the USB change. I bought a UGREEN USB 3.0 Sharing Switch Box instead and it s turned out to be pretty reliable. The problem is that the LG 32UM88 turns out to have a poor DDC implementation, so while I can flip the keyboard easily with the UGREEN box I also have to manually select the monitor input. Which is a bit annoying, but not terrible. The important question is whether this has helped. I built all this at the end of October, so I ve had a month to play with it. Turns out I should have done it at some point last year. At the end of the day instead of either sitting at work for a bit longer, or completely avoiding the study, I m able to lock the work machine and flick to my personal setup. Even sitting in the same seat that disconnect , and the knowledge I won t see work Slack messages or emails come in and feeling I should respond, really helps. It also means I have access to my personal setup during the week without incurring a hit at the start of the working day when I have to set things up again. So it s much easier to just dip in to some personal tech stuff in the evening than it was previously. Also from the point of view I don t need to setup the personal config, I can pick up where I left off. All of which is really nice. It s also got me thinking about other minor improvements I should make to my home working environment to try and improve things. One obvious thing now the winter is here again is to improve my lighting; I have a good overhead LED panel but it s terribly positioned for video calls, being just behind me. So I think I m looking some sort of strip light I can have behind the large monitor to give a decent degree of backlight (possibly bouncing off the white wall). Lots of cheap options I m not convinced about, and I ve had a few ridiculously priced options from photographer friends; suggestions welcome.

Paul Tagliamonte: Intro to PACKRAT (Part 0/5)

Hello! Welcome. I m so thrilled you re here. Some of you may know this (as I ve written about in the past), but if you re new to my RF travels, I ve spent nights and weekends over the last two years doing some self directed learning on how radios work. I ve gone from a very basic understanding of wireless communications, all the way through the process of learning about and implementing a set of libraries to modulate and demodulate data using my now formidable stash of SDRs. I ve been implementing all of the RF processing code from first principals and purely based on other primitives I ve written myself to prove to myself that I understand each concept before moving on. I ve just finished a large personal milestone I was able to successfully send a cURL HTTP request through a network interface into my stack of libraries, through my own BPSK implementation, framed in my own artisanal hand crafted Layer 2 framing scheme, demodulated by my code on the other end, and sent into a Linux network interface. The combination of the Layer 1 PHY and Layer 2 Data Link is something that I ve been calling PACKRAT .
$ curl http://44.127.0.8:8000/
* Connected to 44.127.0.8 (44.127.0.8) port 8000 (#0)
> GET / HTTP/1.1
> Host: localhost:1313
> User-Agent: curl/7.79.1
> Accept: */*
>
* Mark bundle as not supporting multiuse
* HTTP/1.0, assume close after body
< HTTP/1.0 200 OK
< Content-Length: 236
<
____ _ ____ _ ______ _ _____
  _ \ / \ / ___   / / _ \ / \ _ _ 
   _) / _ \      ' /   _)   / _ \    
  __/ ___ \  ___  . \  _ < / ___ \   
 _  /_/ \_\____ _ \_\_  \_\/_/ \_\_ 
* Closing connection 0
In an effort to pay it forward to thank my friends for their time walking me through huge chunks of this, and those who publish their work, I m now spending some time documenting how I was able to implement this protocol. I would never have gotten as far as I did without the incredible patience and kindness of friends spending time working with me, and educators publishing their hard work for the world to learn from. Please accept my deepest thanks and appreciation. The PACKRAT posts are written from the perspective of a novice radio engineer, but experienced software engineer. I ll be leaving out a lot of the technical details on the software end and specific software implementation, focusing on the general gist of the implementation in the radio critical components exclusively. The idea here is this is intended to be a framework a jumping off point for those who are interested in doing this themselves. I hope that this series of blog posts will come to be useful to those who embark on this incredibly rewarding journey after me. This is the first post in the series, and it will contain links to all the posts to follow. This is going to be the landing page I link others to as I publish additional posts, I ll be updating the links on this page. The posts will also grow a tag, which you can check back on, or follow along with here.

Tau Tau ( ) is a much more natural expression of the mathematical constant used for circles which I use rather than Pi ( ). You may see me use Tau in code or text Tau is the same as 2 , so if you see a Tau and don t know what to do, feel free to mentally or textually replace it with 2 . I just hate always writing 2 everywhere and only using (or worse yet 2 /2) .when I mean 1/2 of a circle (or, /2).

Psuedo-code Basicaly none of the code contained in this series is valid on its own. It s very lightly basically Go, and only meant to express concepts in term of software. The examples in the post shouldn t be taken on their own as working snippits to process IQ data, but rather, be used to guide implementations to process the data in question. I d love to invite all readers to try to play at home with the examples, and try and work through the example data captures!

Captures Speaking of captures, I ve included live on-the-air captures of PACKRAT packets, as transmitted from my implementation, in different parts of these posts. This means you can go through the process of building code to parse and receive PACKRAT packets, and then build a transmitter that is validated by your receiver. It s my hope folks will follow along at home and experiment with software to process RF data on their own!

Posts in this series

1 December 2021

Thorsten Alteholz: My Debian Activities in November 2021

FTP master This month I accepted 564 and rejected 93 packages. The overall number of packages that got accepted was 591. Debian LTS This was my eighty-ninth month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. This month my all in all workload has been 40h. During that time I did LTS and normal security uploads of: I also started to work on pgbouncer to get an update for each release and had to process packages from NEW on security-master. Further I worked on a script to automatically publish DLAs on the Debian website, that are posted to debian-lts-announce. The script can be found on salsa. It only publishes stuff from people on a whitelist. At the moment it is running on a computer at home. You might run your own copy, or just send me an email to be put on the whitelist as well. Last but not least I did some days of frontdesk duties. Debian ELTS This month was the forty-first ELTS month. During my allocated time I uploaded: Last but not least I did some days of frontdesk duties. Debian Printing Unfortunately I did not do as much as I wanted this month. At least I looked at some old bugs and uploaded new upstream versions of I hope this will improve in December again. New versions of cups and hplip are on my TODO-list. Debian Astro This month I uploaded new versions of Other stuff I improved packaging or fixed bugs of:

Russ Allbery: Review: A World Without Email

Review: A World Without Email, by Cal Newport
Publisher: Portfolio/Penguin
Copyright: 2021
ISBN: 0-525-53657-4
Format: Kindle
Pages: 264
A World Without Email is the latest book by computer science professor and productivity writer Cal Newport. After a detour to comment on the drawbacks of social media in Digital Minimalism, Newport is back to writing about focus and concentration in the vein of Deep Work. This time, though, the topic is workplace structure and collaborative process rather than personal decisions. This book is a bit hard for me to review because I spoiled myself for the contents by listening to a lot of Newport's podcast, where he covers the same material. I therefore didn't enjoy it as much as I otherwise would have because the ideas were familiar. I recommend the book over the podcast, though; it's tighter, more coherent, and more comprehensive. The core contention of this book is that knowledge work (roughly, jobs where one spends significant time working on a computer processing information) has stumbled into a superficially tempting but inefficient and psychologically harmful structure that Newport calls the hyperactive hive mind. This way of organizing work is a local maxima: it feels productive, it's flexible and very easy to deploy, and most minor changes away from it make overall productivity worse. However, the incentive structure is all wrong. It prioritizes quick responses and coordination overhead over deep thinking and difficult accomplishments. The characteristic property of the hyperactive hive mind is free-flowing, unstructured communication between co-workers. If you need something from someone else, you ask them for it and they send it to you. The "email" in the title is not intended literally; Slack and related instant messaging apps are even more deeply entrenched in the hyperactive hive mind than email is. The key property of this workflow is that most collaborative work is done by contacting other people directly via ad hoc, unstructured messages. Newport's argument is that this workflow has multiple serious problems, not the least of which is that it makes us miserable. If you have read his previous work, you will correctly expect this to tie into his concept of deep work. Ad hoc, unstructured communication creates a constant barrage of unimportant small tasks and interrupts, most of which require several asynchronous exchanges before your brain can stop tracking the task. This creates constant context-shifting, loss of focus and competence, and background stress from ever-growing email inboxes, unread message notifications, and the semi-frantic feeling that you're forgetting something you need to do. This is not an original observation, of course. Many authors have suggested individual ways to improve this workflow: rules about how often to check one's email, filtering approaches, task managers, and other personal systems. Newport's argument is that none of these individual approaches can address the problem due to social effects. It's all well and good to say that you should unplug from distractions and ignore requests while you concentrate, but everyone else's workflow assumes that their co-workers are responsive to ad hoc requests. Ignoring this social contract makes the job of everyone still stuck in the hyperactive hive mind harder. They won't appreciate that, and your brain will not be able to relax knowing that you're not meeting your colleagues' expectations. In Newport's analysis, the necessary solution is a comprehensive redesign of how we do knowledge work, akin to the redesign of factory work that came with the assembly line. It's a collective problem that requires a collective solution. In other industries, organizing work for efficiency and quality is central to the job of management, but in knowledge work (for good historical reasons) employees are mostly left to organize their work on their own. That self-organization has produced a system that doesn't require centralized coordination or decisions and provides a lot of superficial flexibility, but which may be significantly inferior to a system designed for how people think and work. Even if you find this convincing (and I think Newport makes a good case), there are reasons to be suspicious of corporations trying to make people more productive. The assembly line made manufacturing much more efficient, but it also increased the misery of workers so much that Henry Ford had to offer substantial raises to retain workers. As one of Newport's knowledge workers, I'm not enthused about that happening to my job. Newport recognizes this and tries to address it by drawing a distinction between the workflow (how information moves between workers) and the work itself (how individual workers solve problems in their area of expertise). He argues that companies need to redesign the former, but should leave the latter to each worker. It's a nice idea, and it will probably work in industries like tech with substantial labor bargaining power. I'm more cynical about other industries. The second half of the book is Newport's specific principles and recommendations for designing better workflows that don't rely on unstructured email. Some of this will be familiar (and underwhelming) to anyone who works in tech; Newport recommends ticket systems and thinks agile, scrum, and kanban are pointed in the right direction. But there are some other good ideas in here, such as embracing specialization. Newport argues (with some evidence) that the drastic reduction in secretarial jobs, on the grounds that workers with computers can do the same work themselves, was a mistake. Even with new automation, this approach increased the range of tasks required in every other job. Not only was this a drain on the time of other workers, it caused more context switching, which made everyone less efficient and undermined work quality. He argues for reversing that trend: where the work cannot be automated, hire more support workers and more specialized workers in general, stop expecting everyone to be their own generalist admin, and empower support workers to create better systems rather than using the hyperactive hive mind model to answer requests. There's more here, ranging from specifics of how to develop a structured process for a type of work to the importance of enabling sustained concentration on a task. It's a less immediately actionable book than Newport's previous writing, but I welcome the partial shift in focus to more systemic issues. Newport continues to be relentlessly apolitical, but here it feels less like he's eliding important analysis and more like he thinks the interests of workers and good employers are both served by the approach he's advocating. I will warn that Newport leans heavily on evolutionary psychology in his argument that the hyperactive hive mind is bad for us. I think he has some good arguments about the anxiety that comes with not responding to requests from others, but I'm not sure intrusive experiments on spectacularly-unusual remnant hunter-gatherer groups, who are treated like experimental animals, are the best way of making that case. I realize this isn't Newport's research, but I think he could have made his point with more directly relevant experiments. He also continues his obsession with the superiority of in-person conversation over written communication, and while he has a few good arguments, he has a tendency to turn them into sweeping generalizations that are directly contradicted by, well, my entire life. It would be nice if he were more willing to acknowledge that it's possible to express deep emotional nuance and complex social signaling in writing; it simply requires a level of practice and familiarity (and shared vocabulary) that's often missing from the workplace. I was muttering a lot near the start of this book, but thankfully those sections are short, and I think the rest of his argument sits on a stronger foundation. I hope Newport continues moving in the direction of more systemic analysis. If you enjoyed Deep Work, you will probably find A World Without Email interesting. If you're new to Newport, this is not a bad place to start, particularly if you have influence on how communication is organized in your workplace. Those who work in tech will find some bits of this less interesting, but Newport approaches the topic from a different angle than most agile books and covers a broader range if ideas. Recommended if you like reading this sort of thing. Rating: 7 out of 10

Next.

Previous.