Search Results: "ed"

24 March 2025

Arnaud Rebillout: Buid container images with buildah/podman in GitLab CI

Oh no, it broke again! Today, this .gitlab-ci.yml file no longer works in GitLab CI:
build-container-image:
  stage: build
  image: debian:testing
  before_script:
    - apt-get update
    - apt-get install -y buildah ca-certificates
  script:
    - buildah build -t $CI_REGISTRY_IMAGE .
The command buildah build ... fails with this error message:
STEP 2/3: RUN  apt-get update
internal:0:0-0: Error: Could not process rule: No such file or directory
error running container: did not get container start message from parent: EOF
Error: building at STEP "RUN apt-get update": setup network: netavark: nftables error: nft did not return successfully while applying ruleset
After some investigation, it's caused by the recent upload of netavark 1.14.0-2. In this version, netavark switched from iptables to nftables as the default firewall driver. That doesn't really fly on GitLab Saas shared runners. For the complete background, refer to https://discussion.fedoraproject.org/t/125528. Note that the issue with GitLab was reported back in November, but at this point the conversation had died out. Fortunately, it's easy to workaround, we can tell netavark to keep using iptables via the environment variables NETAVARK_FW. The .gitlab-ci.yml file above becomes:
build-container-image:
  stage: build
  image: debian:testing
  variables:
    # Cf. https://discussion.fedoraproject.org/t/125528/7
    NETAVARK_FW: iptables
  before_script:
    - apt-get update
    - apt-get install -y buildah ca-certificates
  script:
    - buildah build -t $CI_REGISTRY_IMAGE .
And everything works again! If you're interested in this issue, feel free to fork https://gitlab.com/arnaudr/gitlab-build-container-image and try it by yourself.

22 March 2025

Dirk Eddelbuettel: RcppZiggurat 0.1.7 on CRAN: New Generators, Many Updates

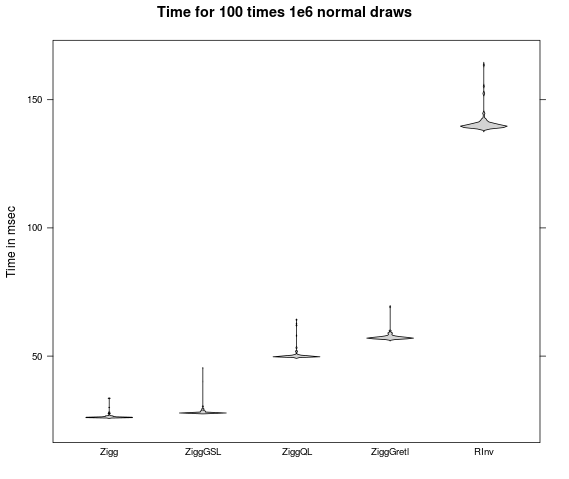
ziggurats A new release 0.1.7 of RcppZiggurat is now on the CRAN network for R. This marks the first release in four and a half years. The RcppZiggurat package updates the code for the Ziggurat generator by Marsaglia and others which provides very fast draws from a Normal distribution. The package provides a simple C++ wrapper class for the generator improving on the very basic macros, and permits comparison among several existing Ziggurat implementations. This can be seen in the figure where Ziggurat from this package dominates accessing the implementations from the GSL, QuantLib and Gretl all of which are still way faster than the default Normal generator in R (which is of course of higher code complexity). This release brings a number of changes. Notably, based on the work we did with the new package zigg (more on that in a second), we now also expose the Exponential generator, and the underlying Uniform generator. Otherwise many aspects of the package have been refreshed: updated builds, updated links, updated CI processes, more use of DOIs and more. The other big news is zigg which should now be the preference for deployment of Ziggurat due to its much lighter-weight and zero-dependency setup. The NEWS file entry below lists all changes.

Changes in version 0.1.7 (2025-03-22)
  • The CI setup was updated to use run.sh from r-ci (Dirk).
  • The windows build was updated to GSL 2.7, and UCRT support was added (Jeroen in #16).
  • Manual pages now use JSS DOIs for references per CRAN request
  • README.md links and badges have been updated
  • Continuous integration actions have been updated several times
  • The DESCRIPTION file now uses Authors@R as mandated
  • Use of multiple cores is eased via a new helper function reflecting option mc.core or architecture defaults, used in tests
  • An inline function has been added to avoid a compiler nag
  • Support for exponential RNG draws zrexp has been added, the internal uniform generator is now also exposed via zruni
  • The vignette bibliography has been updated, and switched to DOIs
  • New package zigg is now mentioned in DESCRIPTION and vignette

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the Rcppziggurat page or the GitHub repository.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Luke Faraone: I'm running for the OSI board... maybe

The Open Source Initiative has two classes of board seats: Affiliate seats, and Individual Member seats. In the upcoming election, each affiliate can nominate a candidate, and each affiliate can cast a vote for the Affiliate candidates, but there's only 1 Affiliate seat available. I initially expressed interest in being nominated as an Affiliate candidate via Debian. But since Bradley Kuhn is also running for an Affiliate seat with a similar platform to me, especially with regards to the OSAID, I decided to run as part of an aligned "ticket" as an Individual Member to avoid contention for the 1 Affiliate seat.Bradley and I discussed running on a similar ticket around 8/9pm Pacific, and I submitted my candidacy around 9pm PT on 17 February. I was dismayed when I received the following mail from Nick Vidal:
Dear Luke,

Thank you for your interest in the OSI Board of Directors election. Unfortunately, we are unable to accept your application as it was submitted after the official deadline of Monday Feb 17 at 11:59 pm UTC. To ensure a fair process, we must adhere to the deadline for all candidates.

We appreciate your enthusiasm and encourage you to stay engaged with OSI s mission. We hope you ll consider applying in the future or contributing in other meaningful ways.

Best regards,
OSI Election Teams
Nowhere on the "OSI s board of directors in 2025: details about the elections" page do they list a timezone for closure of nominations; they simply list Monday 17 February. The OSI's contact address is in California, so it seems arbitrary and capricious to retroactively define all of these processes as being governed by UTC.I was not able to participate in the "potential board director" info sessions accordingly, but people who attended heard that the importance of accommodating differing TZ's was discussed during the info session, and that OSI representatives mentioned they try to accommodate TZ's of everyone. This seems in sharp contrast with the above policy. I urge the OSI to reconsider this policy and allow me to stand for an Individual seat in the current cycle. Upd, N.B.: to people writing about this, I use they/them pronouns

Antoine Beaupr : Minor outage at Teksavvy business

This morning, internet was down at home. The last time I had such an issue was in February 2023, when my provider was Oricom. Now I'm with a business service at Teksavvy Internet (TSI), in which I pay 100$ per month for a 250/50 mbps business package, with a static IP address, on which I run, well, everything: email services, this website, etc.

Mitigation

Email The main problem when the service goes down like this for prolonged outages is email. Mail is pretty resilient to failures like this but after some delay (which varies according to the other end), mail starts to drop. I am actually not sure what the various settings are among different providers, but I would assume mail is typically kept for about 24h, so that's our mark. Last time, I setup VMs at Linode and Digital Ocean to deal better with this. I have actually kept those VMs running as DNS servers until now, so that part is already done. I had fantasized about Puppetizing the mail server configuration so that I could quickly spin up mail exchangers on those machines. But now I am realizing that my Puppet server is one of the service that's down, so this would not work, at least not unless the manifests can be applied without a Puppet server (say with puppet apply). Thankfully, my colleague groente did amazing work to refactor our Postfix configuration in Puppet at Tor, and that gave me the motivation to reproduce the setup in the lab. So I have finally Puppetized part of my mail setup at home. That used to be hand-crafted experimental stuff documented in a couple of pages in this wiki, but is now being deployed by Puppet. It's not complete yet: spam filtering (including DKIM checks and graylisting) are not implemented yet, but that's the next step, presumably to do during the next outage. The setup should be deployable with puppet apply, however, and I have refined that mechanism a little bit, with the run script. Heck, it's not even deployed yet. But the hard part / grunt work is done.

Other The outage was "short" enough (5 hours) that I didn't take time to deploy the other mitigations I had deployed in the previous incident. But I'm starting to seriously consider deploying a web (and caching) reverse proxy so that I endure such problems more gracefully.

Side note on proper servics Typically, I tend to think of a properly functioning service as having four things:
  1. backups
  2. documentation
  3. monitoring
  4. automation
  5. high availability
Yes, I miscounted. This is why you have high availability.

Backups Duh. If data is maliciously or accidentally destroyed, you need a copy somewhere. Preferably in a way that malicious joe can't get to. This is harder than you think.

Documentation I have an entire template for this. Essentially, it boils down to using https://diataxis.fr/ and this "audit" guide. For me, the most important parts are:
  • disaster recovery (includes backups, probably)
  • playbook
  • install/upgrade procedures (see automation)
You probably know this is hard, and this is why you're not doing it. Do it anyways, you'll think it sucks, but you'll be really grateful for whatever scraps you wrote when you're in trouble.

Monitoring If you don't have monitoring, you'll know it fails too late, and you won't know it recovers. Consider high availability, work hard to reduce noise, and don't have machine wake people up, that's literally torture and is against the Geneva convention. Consider predictive algorithm to prevent failures, like "add storage within 2 weeks before this disk fills up". This is harder than you think.

Automation Make it easy to redeploy the service elsewhere. Yes, I know you have backups. That is not enough: that typically restores data and while it can also include configuration, you're going to need to change things when you restore, which is what automation (or call it "configuration management" if you will) will do for you anyways. This also means you can do unit tests on your configuration, otherwise you're building legacy. This is probably as hard as you think.

High availability Make it not fail when one part goes down. Eliminate single points of failures. This is easier than you think, except for storage and DNS (which, I guess, means it's harder than you think too).

Assessment In the above 5 items, I check two:
  1. backups
  2. documentation
And barely: I'm not happy about the offsite backups, and my documentation is much better at work than at home (and even there, I have a 15 year backlog to catchup on). I barely have monitoring: Prometheus is scraping parts of the infra, but I don't have any sort of alerting -- by which I don't mean "electrocute myself when something goes wrong", I mean "there's a set of thresholds and conditions that define an outage and I can look at it". Automation is wildly incomplete. My home server is a random collection of old experiments and technologies, ranging from Apache with Perl and CGI scripts to Docker containers running Golang applications. Most of it is not Puppetized (but the ratio is growing). Puppet itself introduces a huge attack vector with kind of catastrophic lateral movement if the Puppet server gets compromised. And, fundamentally, I am not sure I can provide high availability in the lab. I'm just this one guy running my home network, and I'm growing older. I'm thinking more about winding things down than building things now, and that's just really sad, because I feel we're losing (well that escalated quickly).

Resolution In the end, I didn't need any mitigation and the problem fixed itself. I did do quite a bit of cleanup so that feels somewhat good, although I despaired quite a bit at the amount of technical debt I've accumulated in the lab.

Timeline Times are in UTC-4.
  • 6:52: IRC bouncer goes offline
  • 9:20: called TSI support, waited on the line 15 minutes then was told I'd get a call back
  • 9:54: outage apparently detected by TSI
  • 11:00: no response, tried calling back support again
  • 11:10: confirmed bonding router outage, no official ETA but "today", source of the 9:54 timestamp above
  • 12:08: TPA monitoring notices service restored
  • 12:34: call back from TSI; service restored, problem was with the "bonder" configuration on their end, which was "fighting between Montr al and Toronto"

Antoine Beaupr : Losing the war for the free internet

Warning: this is a long ramble I wrote after an outage of my home internet. You'll get your regular scheduled programming shortly. I didn't realize this until relatively recently, but we're at war. Fascists and capitalists are trying to take over the world, and it's bringing utter chaos. We're more numerous than them, of course: this is only a handful of people screwing everyone else over, but they've accumulated so much wealth and media control that it's getting really, really hard to move around. Everything is surveilled: people are carrying tracking and recording devices in their pockets at all time, or they drive around in surveillance machines. Payments are all turning digital. There's cameras everywhere, including in cars. Personal data leaks are so common people kind of assume their personal address, email address, and other personal information has already been leaked. The internet itself is collapsing: most people are using the network only as a channel to reach a "small" set of "hyperscalers": mind-boggingly large datacenters that don't really operate like the old internet. Once you reach the local endpoint, you're not on the internet anymore. Netflix, Google, Facebook (Instagram, Whatsapp, Messenger), Apple, Amazon, Microsoft (Outlook, Hotmail, etc), all those things are not really the internet anymore. Those companies operate over the "internet" (as in the TCP/IP network), but they are not an "interconnected network" as much as their own, gigantic silos so much bigger than everything else that they essentially dictate how the network operates, regardless of standards. You access it over "the web" (as in "HTTP") but the fabric is not made of interconnected links that cross sites: all those sites are trying really hard to keep you captive on their platforms. Besides, you think you're writing an email to the state department, for example, but you're really writing to Microsoft Outlook. That app your university or border agency tells you to install, the backend is not hosted by those institutions, it's on Amazon. Heck, even Netflix is on Amazon. Meanwhile I've been operating my own mail server first under my bed (yes, really) and then in a cupboard or the basement for almost three decades now. And what for? So I can tell people I can? Maybe! I guess the reason I'm doing this is the same reason people are suddenly asking me about the (dead) mesh again. People are worried and scared that the world has been taken over, and they're right: we have gotten seriously screwed. It's the same reason I keep doing radio, minimally know how to grow food, ride a bike, build a shed, paddle a canoe, archive and document things, talk with people, host an assembly. Because, when push comes to shove, there's no one else who's going to do it for you, at least not the way that benefits the people. The Internet is one of humanity's greatest accomplishments. Obviously, oligarchs and fascists are trying to destroy it. I just didn't expect the tech bros to be flipping to that side so easily. I thought we were friends, but I guess we are, after all, enemies. That said, that old internet is still around. It's getting harder to host your own stuff at home, but it's not impossible. Mail is tricky because of reputation, but it's also tricky in the cloud (don't get fooled!), so it's not that much easier (or cheaper) there. So there's things you can do, if you're into tech. Share your wifi with your neighbours. Build a LAN. Throw a wire over to your neighbour too, it works better than wireless. Use Tor. Run a relay, a snowflake, a webtunnel. Host a web server. Build a site with a static site generator and throw it in the wind. Download and share torrents, and why not a tracker. Run an IRC server (or Matrix, if you want to federate and lose high availability). At least use Signal, not Whatsapp or Messenger. And yes, why not, run a mail server, join a mesh. Don't write new software, there's plenty of that around already. (Just kidding, you can write code, cypherpunk.) You can do many of those things just by setting up a FreedomBox. That is, after all, the internet: people doing their own thing for their own people. Otherwise, it's just like sitting in front of the television and watching the ads. Opium of the people, like the good old time. Let a billion droplets build the biggest multitude of clouds that will storm over this world and rip apart this fascist conspiracy. Disobey. Revolt. Build. We are more than them.

21 March 2025

Jamie McClelland: AI's Actual Impact

Two years after OpenAI launched ChatGPT 3.5, humanity is not on the cusp of extinction and Elon Musk seems more responsible for job loss than any AI agent. However, ask any web administrator and you will learn that large language models are having a significant impact on the world wide web (or, for a less technical account, see Forbes articles on bots). At May First, a membership organization that has been supporting thousands of web site for over 20 years, we have never seen anything like this before.

Now what? So, no, unfortunately, your web site is not suddenly getting really popular. And, you are blessed with a whole new set of strategic decisions. Fortunately, May First has undergone a major infrastructure transition, resulting in centralized logging of all web sites and a fleet of web proxy servers that intercept all web traffic. Centralized logging means we can analyze traffic and identify bots more easily, and a web proxy fleet allows us to more easily implement rules across all web sites. However, even with all of our latest changes and hours upon hours of work to keep out the bots, our members are facing some hard decisions about maintaining an open web. One member of May First provides Google translations of their web site to every language available. But wow, that is now a disaster because instead of having every bot under the sun scrapping all 843 (a made up number) pieces of unique content on their site, the same bots are scraping 843 * (number of available languages) pieces of content on their site. Should they stop providing this translation service in order to ensure people can access their site in the site s primary language? Should web sites turn off their search features that include drop down options of categories to prevent bots from systematically refreshing the search page with every possible combination of search terms? Do we need to alter our calendar software to avoid providing endless links into the future (ok, that is an easy one)?

What s next? Something has to change.
  • Lock down web 2.0. Web 2.0 brought us wonderful dynamic web sites, which Drupal and WordPress and many other pieces of amazing software have supported for over a decade. This is the software that is getting bogged down by bots. Maybe we need to figure out a way to lock down the dynamic aspects of this software to logged in users and provide static content for everyone else?
  • Paywalls and accounts everywhere. There s always been an amazing non-financial reward to providing a web site with high quality movement oriented content for free. It populates the search engines, provides links to inspiring and useful content in moments of crises, and can galvanize movements. But these moments of triumph happen between long periods of hard labor that now seems to mostly feed capitalist AI scumbags. If we add a new set of expenses and labor to keep the sites running for this purpose, how sustainable is that? Will our treasure of free movement content have to move behind paywalls or logins? If we provide logins, will that keep the bots out or just create a small hurdle for them to automate the account creation process? What happens when we can t search for this kind of content via search engines?
  • Cutting deals. What if our movement content providers are forced to cut deals with the AI entrepreneurs to allow the paying scumbags to fund the content creation. Eww. Enough said.
  • Bot detection. Maybe we just need to get better at bot detection? This will surely be an arms race, but would have some good benefits. Bots have also been filling out our forms and populating our databases with spam, testing credit cards against our donation pages, conducting denial of service attacks and all kinds of other irritating acts of vandalism. If we were better at stopping bots automatically it would have a lot of benefits. But what impact would it have on our web sites and the experience of using them? What about good bots (RSS feed readers, payment processors, web hooks, uptime detectors)? Will we cut the legs off any developer trying to automate something?
I m not really sure where this is going, but it seems that the world wide web is about to head in a new direction.

Reproducible Builds (diffoscope): diffoscope 290 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 290. This version includes the following changes:
[ Chris Lamb ]
* Also consider .aar files as APK files for the sake of not falling back to a
  binary diff. (Closes: #1099632)
* Ensure all calls to out_check_output in the ELF comparator have the
  potential CalledProcessError exception caught. (Re: #398)
* Ensure a potential CalledProcessError is caught in the OpenSSL comparator
  as well.
* Update copyright years.
[ Eli Schwartz ]
* Drop deprecated and no longer functional "setup.py test" command.
You find out more by visiting the project homepage.

Reproducible Builds (diffoscope): diffoscope 291 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 291. This version includes the following changes:
[ Chris Lamb ]
* Make two required adjustments for the new version of the src:file package:
  - file(1) version 5.46 now emits "XHTML document" for .xhtml files, such as
    those found nested within our .epub tests. Therefore, match this string
    when detecting XML files. This was causing an FTBFS due to inconsistent
    indentation in diffoscope's output.
  - Require the new, upcoming, version of file(1) for a quine-related
    testcase after adjusting the expected output. Previous versions of
    file(1) had a duplicated "last modified, last modified" string for some
    Zip archives that has now been removed.
* Add a missing subprocess import.
* Bump Standards-Version to 4.7.2.
You find out more by visiting the project homepage.

20 March 2025

C.J. Collier: Installing a desktop environment on the HP Omen

dmidecode grep -A8 ^System Information tells me that the Manufacturer is HP and Product Name is OMEN Transcend Gaming Laptop 14-fb0xxx I m provisioning a new piece of hardware for my eng consultant and it s proving more difficult than I expected. I must admit guilt for some of this difficulty. Instead of installing using the debian installer on my keychain, I dd d the pv block device of the 16 inch 2023 version onto the partition set aside from it. I then rebooted into rescue mode and cleaned up the grub config, corrected the EFI boot partition s path in /etc/fstab, ran the grub installer from the rescue menu, and rebooted. On the initial boot of the system, X or Wayland or whatever is supposed to be talking to this vast array of GPU hardware in this device, it s unable to do more than create a black screen on vt1. It s easy enough to switch to vt2 and get a shell on the installed system. So I m doing that and investigating what s changed in Trixie. It seems like it s pretty significant. Did they just throw out Keith Packard s and Behdad Esfahbod s work on font rendering? I don t understand what s happening in this effort to abstract to a simpler interface. I ll probably end up reading more about it. In an effort to have Debian re-configure the system for Desktop use, I have uninstalled as many packages as I could find that were in the display and human interface category, or were firmware/drivers for devices not present in this Laptop s SoC. Some commands I used to clear these packages and re-install connamon follow:

 
dpkg -S /etc/X11
dpkg -S /usr/lib/firmware
apt-get purge $(dpkg -l   grep -i \
  -e gnome -e gtk -e x11-common -e xfonts- -e libvdpau -e dbus-user-session -e gpg-agent \
  -e bluez -e colord -e cups -e fonts -e drm -e xf86 -e mesa -e nouveau -e cinnamon \
  -e avahi -e gdk -e pixel -e desktop -e libreoffice -e x11 -e wayland -e xorg \
  -e firmware-nvidia-graphics -e firmware-amd-graphics -e firmware-mediatek -e firmware-realtek \
    awk ' print $2 ')
apt-get autoremove
apt-get purge $(dpkg -l   grep '^r'   awk ' print $2 ')
tasksel install cinnamon-desktop
 
And then I rebooted. When it came back up, I was greeted with a login prompt, and Trixie looks to be fully functional on this device, including the attached wifi radio, tethering to my android, and the thunderbolt-attached Marvell SFP+ enclosure. I m also installing libvirt and fetched the DVD iso material for Debian, Ubuntu and Rocky in case we have a need of building VMs during the development process. These are the platforms that I target at work with gcp Dataproc, so I m pretty good at performing maintenance operation on them at this point.

Sven Hoexter: Purpose A Wellbeing Economies Film

The film is centered around the idea of establishing an alternative to the GDP as the metric to measure success of a country/society. The film follows mostly Katherine Trebeck on her journey of convincing countries to look beyond the GDP. I very much enjoyed watching this documentary to get a first impression of the idea itself and the effort involved. I had the chance to watch the german version of it online. But there is now another virtual screening offered by the Permacultur Film Club on the 29th and 30th of March 2025. This screening is on a pay-as-you-like-and-can basis and includes a Q&A session with Kathrine Trebeck. Trailer 1 and Trailer 2 are available on Youtube if you like to get a first impression.

Sven Hoexter: k8s deployment build-in preStop sleep

Seems in the k8s world there are sufficient enough race conditions in shutting down pods and removing those from endpoint slices in time. Thus people started to do all kind of workarounds like adding a statically linked sleep binary to otherwise "distroless" and rather empty OCI images to just run a sleep command on shutdown before really shutting down. Or even base64 encoding the sleep binary and shipping it via configMap. Or whatever else. Eventually the situation was so severe that upstream decided to implement a sleep feature in the deployment resource directly. In short it looks like this:
apiVersion: apps/v1
kind: Deployment
metadata:
  name: foo
spec:
  template:
    spec:
      lifecycle:
        preStop:
          sleep:
            seconds: 10
Maybe highlighting that "feature" helps some more people to get rid of their own preStop sleep commands and make some deployments a tiny bit simpler.

19 March 2025

Mark Brown: Seoul Trail revamp

I regularly visit Seoul, and for the last couple of years I&aposve been doing segments from the Seoul Trail, a series of walks that add up to a 150km circuit around the outskirts of Seoul. If you like hiking I recommend it, it&aposs mostly through the hills and wooded areas surrounding the city or parks within the city and the bits I&aposve done thus far have mostly been very enjoyable. Everything is generally well signposted and easy to follow, with varying degrees of difficulty from completely flat paved roads to very hilly trails.The trail had been divided into eight segments but just after I last visited the trail was reorganised into 21 smaller ones. This was very sensible, the original segments mostly being about 10-20km and taking 3-6 hours (with the notable exception of section 8, which was 36km) which can be a bit much (especially that section 8, or section 1 which had about 1km of ascent in it overall). It does complicate matters if you&aposre trying to keep track of what you&aposve done already though so I&aposve put together a quick table:
OriginalRevised
11-3
24-5
36-8
49-10
511-12
613-14
715-16
817-21
This is all straightforward, the original segments had all been arranged to start and stop at metro stations (which I think explains the length of 8, the metro network is thin around Bukhansan what with it being an actual mountain) and the new segments are all straight subdivisions, but it&aposs handy to have it written down and I figured other people might find it useful.

18 March 2025

Matthew Garrett: Failing upwards: the Twitter encrypted DM failure

Almost two years ago, Twitter launched encrypted direct messages. I wrote about their technical implementation at the time, and to the best of my knowledge nothing has changed. The short story is that the actual encryption primitives used are entirely normal and fine - messages are encrypted using AES, and the AES keys are exchanged via NIST P-256 elliptic curve asymmetric keys. The asymmetric keys are each associated with a specific device or browser owned by a user, so when you send a message to someone you encrypt the AES key with all of their asymmetric keys and then each device or browser can decrypt the message again. As long as the keys are managed appropriately, this is infeasible to break.

But how do you know what a user's keys are? I also wrote about this last year - key distribution is a hard problem. In the Twitter DM case, you ask Twitter's server, and if Twitter wants to intercept your messages they replace your key. The documentation for the feature basically admits this - if people with guns showed up there, they could very much compromise the protection in such a way that all future messages you sent were readable. It's also impossible to prove that they're not already doing this without every user verifying that the public keys Twitter hands out to other users correspond to the private keys they hold, something that Twitter provides no mechanism to do.

This isn't the only weakness in the implementation. Twitter may not be able read the messages, but every encrypted DM is sent through exactly the same infrastructure as the unencrypted ones, so Twitter can see the time a message was sent, who it was sent to, and roughly how big it was. And because pictures and other attachments in Twitter DMs aren't sent in-line but are instead replaced with links, the implementation would encrypt the links but not the attachments - this is "solved" by simply blocking attachments in encrypted DMs. There's no forward secrecy - if a key is compromised it allows access to not only all new messages created with that key, but also all previous messages. If you log out of Twitter the keys are still stored by the browser, so if you can potentially be extracted and used to decrypt your communications. And there's no group chat support at all, which is more a functional restriction than a conceptual one.

To be fair, these are hard problems to solve! Signal solves all of them, but Signal is the product of a large number of highly skilled experts in cryptography, and even so it's taken years to achieve all of this. When Elon announced the launch of encrypted DMs he indicated that new features would be developed quickly - he's since publicly mentioned the feature a grand total of once, in which he mentioned further feature development that just didn't happen. None of the limitations mentioned in the documentation have been addressed in the 22 months since the feature was launched.

Why? Well, it turns out that the feature was developed by a total of two engineers, neither of whom is still employed at Twitter. The tech lead for the feature was Christopher Stanley, who was actually a SpaceX employee at the time. Since then he's ended up at DOGE, where he apparently set off alarms when attempting to install Starlink, and who today is apparently being appointed to the board of Fannie Mae, a government-backed mortgage company.

Anyway. Use Signal.

comment count unavailable comments

Christian Kastner: 15th Anniversary of My First Debian Upload

Time flies! 15 years ago, on 2010-03-18, my first upload to the Debian archive was accepted. Debian had replaced Windows as my primary OS in 2005, but it was only when I saw that package zd1211-firmware had been orphaned that I thought of becoming a contributor. I owned a Zyxel G-202 USB WiFi fob that needed said firmware, and as is so often is with open-source software, I was going to scratch my own itch. Bart Martens thankfully helped me adopt the package, and sponsored my upload. I then joined Javier Fern ndez-Sanguino Pe a as a cron maintainer and upstream, and also worked within the Debian Python Applications, Debian Python Modules, and Debian Science Teams, where Jakub Wilk and Yaroslav Halchenko were kind enough to mentor me and eventually support my application to become a Debian Maintainer. Life intervened, and I was mostly inactive in Debian for the next two years. Upon my return in 2014, I had Vincent Cheng to thank for sponsoring most of my newer work, and for eventually supporting my application to become a Debian Developer. It was around that time that I also attended my first DebConf, in Portland, which remains one of my fondest memories. I had never been to an open-source software conference before, and DebConf14 really knocked it out of the park in so many ways. After another break, I returned in 2019 to work mostly on Python and machine learning libraries. In 2020, I finally completed a process that I had first started in 2012 but had never managed to finish before: converting cron from source format 1.0 (one big diff) to source format 3.0 (quilt) (a series of patches). This was a process where I converted 25 years worth of organic growth into a minimal series of logically grouped changes (more here). This was my white whale. In early 2023, shortly after the launch of ChatGPT which triggered an unprecedented AI boom, I started contributing to the Debian ROCm Team, where over the following year, I bootstrapped our CI at ci.rocm.debian.net. Debian's current tooling lack a way to express dependencies on specific hardware other than CPU ISA, nor does it have the means to run autopkgtests using such hardware. To get autopkgtests to make use of AMD GPUs in QEMU VMs and in containers, I had to fork autopkgtest, debci, and a few other components, as well as create a fair share of new tooling for ourselves. This worked out pretty well, and the CI has grown to support 17 different AMD GPU architectures. I will share more on this in upcoming posts. I have mentioned a few contributors by name, but I have countless others to thank for collaborations over the years. It has been a wonderful experience, and I look forward to many years more.

Dirk Eddelbuettel: RcppArmadillo 14.4.0-1 on CRAN: New Upstream

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1234 other packages on CRAN, downloaded 38.8 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 617 times according to Google Scholar. Conrad released a new minor version 14.4.0 last month. That was preceding by several extensive rounds of reverse-dependency checks covering the 1200+ packages at CRAN. We eventually narrowed the impact down to just eight packages, and I opened issue #462 to manage the transition along with GitHub-only release 14.4.0-0 of RcppArmadillo. Several maintainers responded very promptly and updated within days this is truly appreciated. Yesterday the last package updated at CRAN coinciding nicely with our planned / intended upload to CRAN one month after the release. So this new release, at version -1, is now on CRAN. It brings the usual number of small improvements to Armadillo itself as well as updates to packaging. The changes since the last CRAN release are summarised below.

Changes in RcppArmadillo version 14.4.0-1 (2025-03-17)
  • CRAN release having given a few packages time to catch-up to small upstream change as discussed and managed in #462
  • Updated bibliography, and small edits to sparse matrix vignette
  • Switched continuous integration action to r-ci with implicit bootstrap

Changes in RcppArmadillo version 14.4.0-0 (2025-02-17) (GitHub Only)
  • Upgraded to Armadillo release 14.4.0 (Filtered Espresso)
    • Faster handling of pow() and square() within accu() and sum() expressions
    • Faster sort() and sort_index() for complex matrices
    • Expanded the field class with .reshape() and .resize() member functions
    • More efficient handling of compound expressions by sum(), reshape(), trans()
    • Better detection of vector expressions by pow(), imag(), conj()
  • The package generator helper function now supports additional DESCRIPTIONs
  • This release revealed a need for very minor changes for a handful reverse-dependency packages which will be organized via GitHub issue tracking

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Sergio Talens-Oliag: Using actions to build this site

As promised on my previous post, on this entry I ll explain how I ve set up forgejo actions on the source repository of this site to build it using a runner instead of doing it on the public server using a webhook to trigger the operation.

Setting up the systemThe first thing I ve done is to disable the forgejo webhook call that was used to publish the site, as I don t want to run it anymore. After that I added a new workflow to the repository that does the following things:
  • build the site using my hugo-adoc image.
  • push the result to a branch that contains the generated site (we do this because the server is already configured to work with the git repository and we can use force pushes to keep only the last version of the site, removing the need of extra code to manage package uploads and removals).
  • uses curl to send a notification to an instance of the webhook server installed on the remote server that triggers a script that updates the site using the git branch.

Setting up the webhook serviceOn the server machine we have installed and configured the webhook service to run a script that updates the site. To install the application and setup the configuration we have used the following script:
#!/bin/sh
set -e
# ---------
# VARIABLES
# ---------
ARCH="$(dpkg --print-architecture)"
WEBHOOK_VERSION="2.8.2"
DOWNLOAD_URL="https://github.com/adnanh/webhook/releases/download"
WEBHOOK_TGZ_URL="$DOWNLOAD_URL/$WEBHOOK_VERSION/webhook-linux-$ARCH.tar.gz"
WEBHOOK_SERVICE_NAME="webhook"
# Files
WEBHOOK_SERVICE_FILE="/etc/systemd/system/$WEBHOOK_SERVICE_NAME.service"
WEBHOOK_SOCKET_FILE="/etc/systemd/system/$WEBHOOK_SERVICE_NAME.socket"
WEBHOOK_TML_TEMPLATE="/srv/blogops/action/webhook.yml.envsubst"
WEBHOOK_YML="/etc/webhook.yml"
# Config file values
WEBHOOK_USER="$(id -u)"
WEBHOOK_GROUP="$(id -g)"
WEBHOOK_LISTEN_STREAM="172.31.31.1:4444"
# ----
# MAIN
# ----
# Install binary from releases (on Debian only version 2.8.0 is available, but
# I need the 2.8.2 version to support the systemd activation mode).
curl -fsSL -o "/tmp/webhook.tgz" "$WEBHOOK_TGZ_URL"
tar -C /tmp -xzf /tmp/webhook.tgz
sudo install -m 755 "/tmp/webhook-linux-$ARCH/webhook" /usr/local/bin/webhook
rm -rf "/tmp/webhook-linux-$ARCH" /tmp/webhook.tgz
# Service file
sudo sh -c "cat >'$WEBHOOK_SERVICE_FILE'" <<EOF
[Unit]
Description=Webhook server
[Service]
Type=exec
ExecStart=webhook -nopanic -hooks $WEBHOOK_YML
User=$WEBHOOK_USER
Group=$WEBHOOK_GROUP
EOF
# Socket config
sudo sh -c "cat >'$WEBHOOK_SOCKET_FILE'" <<EOF
[Unit]
Description=Webhook server socket
[Socket]
# Set FreeBind to listen on missing addresses (the VPN can be down sometimes)
FreeBind=true
# Set ListenStream to the IP and port you want to listen on
ListenStream=$WEBHOOK_LISTEN_STREAM
[Install]
WantedBy=multi-user.target
EOF
# Config file
BLOGOPS_TOKEN="$(uuid)" \
  envsubst <"$WEBHOOK_TML_TEMPLATE"   sudo sh -c "cat >$WEBHOOK_YML"
chmod 0640 "$WEBHOOK_YML"
chwon "$WEBHOOK_USER:$WEBHOOK_GROUP" "$WEBHOOK_YML"
# Restart and enable service
sudo systemctl daemon-reload
sudo systemctl stop "$WEBHOOK_SERVICE_NAME.socket"
sudo systemctl start "$WEBHOOK_SERVICE_NAME.socket"
sudo systemctl enable "$WEBHOOK_SERVICE_NAME.socket"
# ----
# vim: ts=2:sw=2:et:ai:sts=2
As seen on the code, we ve installed the application using a binary from the project repository instead of a package because we needed the latest version of the application to use systemd with socket activation. The configuration file template is the following one:
- id: "update-blogops"
  execute-command: "/srv/blogops/action/bin/update-blogops.sh"
  command-working-directory: "/srv/blogops"
  trigger-rule:
    match:
      type: "value"
      value: "$BLOGOPS_TOKEN"
      parameter:
        source: "header"
        name: "X-Blogops-Token"
The version on /etc/webhook.yml has the BLOGOPS_TOKEN adjusted to a random value that has to exported as a secret on the forgejo project (see later). Once the service is started each time the action is executed the webhook daemon will get a notification and will run the following update-blogops.sh script to publish the updated version of the site:
#!/bin/sh
set -e
# ---------
# VARIABLES
# ---------
# Values
REPO_URL="ssh://git@forgejo.mixinet.net/mixinet/blogops.git"
REPO_BRANCH="html"
REPO_DIR="public"
MAIL_PREFIX="[BLOGOPS-UPDATE-ACTION] "
# Address that gets all messages, leave it empty if not wanted
MAIL_TO_ADDR="blogops@mixinet.net"
# Directories
BASE_DIR="/srv/blogops"
PUBLIC_DIR="$BASE_DIR/$REPO_DIR"
NGINX_BASE_DIR="$BASE_DIR/nginx"
PUBLIC_HTML_DIR="$NGINX_BASE_DIR/public_html"
ACTION_BASE_DIR="$BASE_DIR/action"
ACTION_LOG_DIR="$ACTION_BASE_DIR/log"
# Files
OUTPUT_BASENAME="$(date +%Y%m%d-%H%M%S.%N)"
ACTION_LOGFILE_PATH="$ACTION_LOG_DIR/$OUTPUT_BASENAME.log"
# ---------
# Functions
# ---------
action_log()  
  echo "$(date -R) $*" >>"$ACTION_LOGFILE_PATH"
 
action_check_directories()  
  for _d in "$ACTION_BASE_DIR" "$ACTION_LOG_DIR"; do
    [ -d "$_d" ]   mkdir "$_d"
  done
 
action_clean_directories()  
  # Try to remove empty dirs
  for _d in "$ACTION_LOG_DIR" "$ACTION_BASE_DIR"; do
    if [ -d "$_d" ]; then
      rmdir "$_d" 2>/dev/null   true
    fi
  done
 
mail_success()  
  to_addr="$MAIL_TO_ADDR"
  if [ "$to_addr" ]; then
    subject="OK - updated blogops site"
    mail -s "$ MAIL_PREFIX $ subject " "$to_addr" <"$ACTION_LOGFILE_PATH"
  fi
 
mail_failure()  
  to_addr="$MAIL_TO_ADDR"
  if [ "$to_addr" ]; then
    subject="KO - failed to update blogops site"
    mail -s "$ MAIL_PREFIX $ subject " "$to_addr" <"$ACTION_LOGFILE_PATH"
  fi
  exit 1
 
# ----
# MAIN
# ----
ret="0"
# Check directories
action_check_directories
# Go to the base directory
cd "$BASE_DIR"
# Remove the old build dir if present
if [ -d "$PUBLIC_DIR" ]; then
  rm -rf "$PUBLIC_DIR"
fi
# Update the repository checkout
action_log "Updating the repository checkout"
git fetch --all >>"$ACTION_LOGFILE_PATH" 2>&1   ret="$?"
if [ "$ret" -ne "0" ]; then
  action_log "Failed to update the repository checkout"
  mail_failure
fi
# Get it from the repo branch & extract it
action_log "Downloading and extracting last site version using 'git archive'"
git archive --remote="$REPO_URL" "$REPO_BRANCH" "$REPO_DIR" \
    tar xf - >>"$ACTION_LOGFILE_PATH" 2>&1   ret="$?"
# Fail if public dir was missing
if [ "$ret" -ne "0" ]   [ ! -d "$PUBLIC_DIR" ]; then
  action_log "Failed to download or extract site"
  mail_failure
fi
# Remove old public_html copies
action_log 'Removing old site versions, if present'
find $NGINX_BASE_DIR -mindepth 1 -maxdepth 1 -name 'public_html-*' -type d \
  -exec rm -rf   \; >>"$ACTION_LOGFILE_PATH" 2>&1   ret="$?"
if [ "$ret" -ne "0" ]; then
  action_log "Removal of old site versions failed"
  mail_failure
fi
# Switch site directory
TS="$(date +%Y%m%d-%H%M%S)"
if [ -d "$PUBLIC_HTML_DIR" ]; then
  action_log "Moving '$PUBLIC_HTML_DIR' to '$PUBLIC_HTML_DIR-$TS'"
  mv "$PUBLIC_HTML_DIR" "$PUBLIC_HTML_DIR-$TS" >>"$ACTION_LOGFILE_PATH" 2>&1  
    ret="$?"
fi
if [ "$ret" -eq "0" ]; then
  action_log "Moving '$PUBLIC_DIR' to '$PUBLIC_HTML_DIR'"
  mv "$PUBLIC_DIR" "$PUBLIC_HTML_DIR" >>"$ACTION_LOGFILE_PATH" 2>&1  
    ret="$?"
fi
if [ "$ret" -ne "0" ]; then
  action_log "Site switch failed"
  mail_failure
else
  action_log "Site updated successfully"
  mail_success
fi
# ----
# vim: ts=2:sw=2:et:ai:sts=2

The hugo-adoc workflowThe workflow is defined in the .forgejo/workflows/hugo-adoc.yml file and looks like this:
name: hugo-adoc
# Run this job on push events to the main branch
on:
  push:
    branches:
      - 'main'
jobs:
  build-and-push:
    if: $  vars.BLOGOPS_WEBHOOK_URL != '' && secrets.BLOGOPS_TOKEN != ''  
    runs-on: docker
    container:
      image: forgejo.mixinet.net/oci/hugo-adoc:latest
    # Allow the job to write to the repository (not really needed on forgejo)
    permissions:
      contents: write
    steps:
      - name: Checkout the repo
        uses: actions/checkout@v4
        with:
          submodules: 'true'
      - name: Build the site
        shell: sh
        run:  
          rm -rf public
          hugo
      - name: Push compiled site to html branch
        shell: sh
        run:  
          # Set the git user
          git config --global user.email "blogops@mixinet.net"
          git config --global user.name "BlogOps"
          # Create a new orphan branch called html (it was not pulled by the
          # checkout step)
          git switch --orphan html
          # Add the public directory to the branch
          git add public
          # Commit the changes
          git commit --quiet -m "Updated site @ $(date -R)" public
          # Push the changes to the html branch
          git push origin html --force
          # Switch back to the main branch
          git switch main
      - name: Call the blogops update webhook endpoint
        shell: sh
        run:  
          HEADER="X-Blogops-Token: $  secrets.BLOGOPS_TOKEN  "
          curl --fail -k -H "$HEADER" $  vars.BLOGOPS_WEBHOOK_URL  
The only relevant thing is that we have to add the BLOGOPS_TOKEN variable to the project secrets (its value is the one included on the /etc/webhook.yml file created when installing the webhook service) and the BLOGOPS_WEBHOOK_URL project variable (its value is the URL of the webhook server, in my case http://172.31.31.1:4444/hooks/update-blogops); note that the job includes the -k flag on the curl command just in case I end up using TLS on the webhook server in the future, as discussed previously.

ConclusionNow that I have forgejo actions on my server I no longer need to build the site on the public server as I did initially, a good thing when the server is a small OVH VPS that only runs a couple of containers and a web server directly on the host. I m still using a notification system to make the server run a script to update the site because that way the forgejo server does not need access to the remote machine shell, only the webhook server which, IMHO, is a more secure setup.

Petter Reinholdtsen: New theora release 1.2.0beta1 after almost 15 years

When I a few days ago discovered that a security problem reported against the theora library last year was still not fixed, and because I was already up to speed on Xiph development, I decided it was time to wrap up a new theora release. This new release was tagged in the Xiph gitlab theora instance Saturday. You can fetch the new release from the Theora home page. The list of changes since The 1.2.0alpha1 release from the CHANGES file in the tarball look like this:
libteora 1.2.0beta1 (2025 March 15)
  • Bumped minor SONAME versions as methods changed constness of arguments.
  • Updated libogg dependency to version 1.3.4 for ogg_uint64_t.
  • Updated doxygen setup.
  • Updated autotools setup and support scripts (#1467 #1800 #1987 #2318 #2320).
  • Added support for RISC OS.
  • Fixed mingw build (#2141).
  • Improved ARM support.
  • Converted SCons setup to work with Python 3.
  • Introduced new configure options --enable-mem-constraint and --enable-gcc-sanitizers.
  • Fixed all known compiler warnings and errors from gcc and clang.
  • Improved examples for stability and correctness.
  • Variuos speed, bug fixes and code quality improvements.
  • Fixed build problem with Visual Studio (#2317).
  • Avoids undefined bit shift of signed numbers (#2321, #2322).
  • Avoids example encoder crash on bogus audio input (#2305).
  • Fixed musl linking issue with asm enabled (#2287).
  • Fixed some broken clamping in rate control (#2229).
  • Added NULL check _tc and _setup even for data packets (#2279).
  • Fixed mismatched oc_mb_fill_cmapping11 signature (#2068).
  • Updated the documentation for theora_encode_comment() (#726).
  • Adjusted build to Only link libcompat with dump_video (#1587).
  • Corrected an operator precedence error in the visualization code (#1751).
  • Fixed two spelling errors in the comments (#1804).
  • Avoid negative bit shift operation in huffdec.c (CVE-2024-56431).
  • Improved library documentation and specification text.
  • Adjusted library dependencies so libtheoraenc do not depend on libtheoradec.
  • Handle fallout from CVE-2017-14633 in libvorbis, check return value in encoder_example and transcoder_example.
There are a few bugs still being investigated, and my plan is to wrap up a final 1.2.0 release two weekends from now. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Dima Kogan: Eigen macro specializations crashes

There's an issue in the Eigen linear algebra library where linking together objects compiled with different flags causes the resulting binary to crash. Some details are written-up in this mailing list thread. I just encountered a situation where a large application sometimes crashes for unknown reasons, and needed a method to determine whether this Eigen issue could be the cause. I ended up doing this by using the DWARF data to see if the linked binary contains the different incompatible flavors of malloc / free or not. I downloaded the small demo program showing the problem. I built it:
CCXXXFLAGS=-g make
Here if you run ./main, the bug is triggered, and a crash occurs. I looked at the debug info for the code in question:
for o (main lib.so)  
  echo "======== $o";
  readelf --debug-dump=decodedline $o \
    awk \
    '$1 ~ /^Memory.h/
      
       if(180 <= $2 && $2 <= 186)  
         have["malloc_glibc"]=1
        
       if(188 == $2)  
         have["malloc_handmade"]=1
        
       if(201 <= $2 && $2 <= 204)  
         have["free_glibc"]=1
        
       if(206 == $2)  
         have["free_handmade"]=1
        
      
     END
      
       for (var in have)  
         print(var);
        
      '
 
It says:
======== main
free_handmade
======== lib.so
malloc_glibc
free_glibc
Here I looked at main and lib.so (the build products from this little demo). In a real case you'd look at every shared library linked into the binary and the binary itself. On my machine /usr/include/eigen3/Eigen/src/Core/util/Memory.h looks like this, starting on line 174:
174 EIGEN_DEVICE_FUNC inline void* aligned_malloc(std::size_t size)
175  
176   check_that_malloc_is_allowed();
177 
178   void *result;
179   #if (EIGEN_DEFAULT_ALIGN_BYTES==0)   EIGEN_MALLOC_ALREADY_ALIGNED
180 
181     EIGEN_USING_STD(malloc)
182     result = malloc(size);
183 
184     #if EIGEN_DEFAULT_ALIGN_BYTES==16
185     eigen_assert((size<16   (std::size_t(result)%16)==0) && "System's malloc returned an unaligned pointer. Compile with EIGEN_MALLOC_ALREADY_ALIGNED=0 to fallback to handmade aligned memory allocator.");
186     #endif
187   #else
188     result = handmade_aligned_malloc(size);
189   #endif
190 
191   if(!result && size)
192     throw_std_bad_alloc();
193 
194   return result;
195  
196 
197 /** \internal Frees memory allocated with aligned_malloc. */
198 EIGEN_DEVICE_FUNC inline void aligned_free(void *ptr)
199  
200   #if (EIGEN_DEFAULT_ALIGN_BYTES==0)   EIGEN_MALLOC_ALREADY_ALIGNED
201 
202     EIGEN_USING_STD(free)
203     free(ptr);
204 
205   #else
206     handmade_aligned_free(ptr);
207   #endif
208  
The above awk script looks at the two malloc paths and the two free paths, and we can clearly see that it only ever calls malloc_glibc(), but has both flavors of free(). So this can crash. We want to see that the whole executable (shared libraries and all) should only have one type of malloc() and free(), and that would guarantee no crashing. There are a more functions in that header that should be instrumented (realloc() for instance) and the different alignment paths should be instrumented similarly (as described in the mailing list thread above), but here we see that this technique works.

17 March 2025

Sergio Talens-Oliag: Configuring forgejo actions

Last week I decided I wanted to try out forgejo actions to build this blog instead of using webhooks, so I looked the documentation and started playing with it until I had it working as I wanted. This post is to describe how I ve installed and configured a forgejo runner, how I ve added an oci organization to my instance to build, publish and mirror container images and added a couple of additional organizations (actions and docker for now) to mirror interesting actions. The changes made to build the site using actions will be documented on a separate post, as I ll be using this entry to test the new setup on the blog project.

Installing the runnerThe first thing I ve done is to install a runner on my server, I decided to use the OCI image installation method, as it seemed to be the easiest and fastest one. The commands I ve used to setup the runner are the following:
$ cd /srv
$ git clone https://forgejo.mixinet.net/blogops/forgejo-runner.git
$ cd forgejo-runner
$ sh ./bin/setup-runner.sh
The setup-runner.sh script does multiple things:
  • create a forgejo-runner user and group
  • create the necessary directories for the runner
  • create a .runner file with a predefined secret and the docker label
The setup-runner.sh code is available here. After running the script the runner has to be registered with the forgejo server, it can be done using the following command:
$ forgejo forgejo-cli actions register --name "$RUNNER_NAME" \
    --secret "$FORGEJO_SECRET"
The RUNNER_NAME variable is defined on the setup-runner.sh script and the FORGEJO_SECRET must match the value used on the .runner file.

Starting it with docker-composeTo launch the runner I m going to use a docker-compose.yml file that starts two containers, a docker in docker service to run the containers used by the workflow jobs and another one that runs the forgejo-runner itself. The initial version used a TCP port to communicate with the dockerd server from the runner, but when I tried to build images from a workflow I noticed that the containers launched by the runner were not going to be able to execute another dockerd inside the dind one and, even if they were, it was going to be expensive computationally. To avoid the issue I modified the dind service to use a unix socket on a shared volume that can be used by the runner service to communicate with the daemon and also re-shared with the job containers so the dockerd server can be used from them to build images.
Warning: The use of the same docker server that runs the jobs from them has security implications, but this instance is for a home server where I am the only user, so I am not worried about it and this way I can save some resources (in fact, I could use the host docker server directly instead of using a dind service, but just in case I want to run other containers on the host I prefer to keep the one used for the runner isolated from it). For those concerned about sharing the same server an alternative would be to launch a second dockerd only for the jobs (i.e. actions-dind) using the same approach (the volume with its socket will have to be shared with the runner service so it can be re-shared, but the runner does not need to use it).
The final docker-compose.yaml file is as follows:
services:
  dind:
    image: docker:dind
    container_name: 'dind'
    privileged: 'true'
    command: ['dockerd', '-H', 'unix:///dind/docker.sock', '-G', '$RUNNER_GID']
    restart: 'unless-stopped'
    volumes:
      - ./dind:/dind
  runner:
    image: 'data.forgejo.org/forgejo/runner:6.2.2'
    links:
      - dind
    depends_on:
      dind:
        condition: service_started
    container_name: 'runner'
    environment:
      DOCKER_HOST: 'unix:///dind/docker.sock'
    user: $RUNNER_UID:$RUNNER_GID
    volumes:
      - ./config.yaml:/config.yaml
      - ./data:/data
      - ./dind:/dind
    restart: 'unless-stopped'
    command: '/bin/sh -c "sleep 5; forgejo-runner daemon -c /config.yaml"'
There are multiple things to comment about this file:
  1. The dockerd server is started with the -H unix:///dind/docker.sock flag to use the unix socket to communicate with the daemon instead of using a TCP port (as said, it is faster and allows us to share the socket with the containers started by the runner).
  2. We are running the dockerd daemon with the RUNNER_GID group so the runner can communicate with it (the socket gets that group which is the same used by the runner).
  3. The runner container mounts three volumes: the data directory, the dind folder where docker creates the unix socket and a config.yaml file used by us to change the default runner configuration.
The config.yaml file was originally created using the forgejo-runner:
$ docker run --rm data.forgejo.org/forgejo/runner:6.2.2 \
    forgejo-runner generate-config > config.yaml
The changes to it are minimal, the runner capacity has been increased to 2 (that allows it to run two jobs at the same time) and the /dind/docker.sock value has been added to the valid_volumes key to allow the containers launched by the runner to mount it when needed; the diff against the default version is as follows:
@@ -13,7 +13,8 @@
   # Where to store the registration result.
   file: .runner
   # Execute how many tasks concurrently at the same time.
-  capacity: 1
+  # STO: Allow 2 concurrent tasks
+  capacity: 2
   # Extra environment variables to run jobs.
   envs:
     A_TEST_ENV_NAME_1: a_test_env_value_1
@@ -87,7 +88,9 @@
   # If you want to allow any volume, please use the following configuration:
   # valid_volumes:
   #   - '**'
-  valid_volumes: []
+  # STO: Allow to mount the /dind/docker.sock on the containers
+  valid_volumes:
+    - /dind/docker.sock
   # overrides the docker client host with the specified one.
   # If "-" or "", an available docker host will automatically be found.
   # If "automount", an available docker host will automatically be found and ...
To start the runner we export the RUNNER_UID and RUNNER_GID variables and call docker-compose up to start the containers on the background:
$ RUNNER_UID="$(id -u forgejo-runner)" RUNNER_GID="$(id -g forgejo-runner)" \
    docker compose up -d
If the server was configured right we are now able to start using actions with this runner.

Preparing the system to run things locallyTo avoid unnecessary network traffic we are going to create a multiple organizations in our forgejo instance to maintain our own actions and container images and mirror remote ones. The rationale behind the mirror use is that we reduce a lot the need to connect to remote servers to download the actions and images, which is good for performance and security reasons. In fact, we are going to build our own images for some things to install the tools we want without needing to do it over and over again on the workflow jobs.

Mirrored actionsThe actions we are mirroring are on the actions and docker organizations, we have created the following ones for now (the mirrors were created using the forgejo web interface and we have disabled manually all the forgejo modules except the code one for them):
To use our actions by default (i.e., without needing to add the server URL on the uses keyword) we have added the following section to the app.ini file of our forgejo server:
[actions]
ENABLED = true
DEFAULT_ACTIONS_URL = https://forgejo.mixinet.net

Setting up credentials to push imagesTo be able to push images to the oci organization I ve created a token with package:write permission for my own user because I m a member of the organization and I m authorized to publish packages on it (a different user could be created, but as I said this is for personal use, so there is no need to complicate things for now). To allow the use of those credentials on the actions I have added a secret (REGISTRY_PASS) and a variable (REGISTRY_USER) to the oci organization to allow the actions to use them. I ve also logged myself on my local docker client to be able to push images to the oci group by hand, as I it is needed for bootstrapping the system (as I m using local images on the worflows I need to push them to the server before running the ones that are used to build the images).

Local and mirrored imagesOur images will be stored on the packages section of a new organization called oci, inside it we have created two projects that use forgejo actions to keep things in shape:
  • images: contains the source files used to generate our own images and the actions to build, tag and push them to the oci organization group.
  • mirrors: contains a configuration file for the regsync tool to mirror containers and an action to run it.
On the next sections we are going to describe the actions and images we have created and mirrored from those projects.

The oci/images projectThe images project is a monorepo that contains the source files for the images we are going to build and a couple of actions. The image sources are on sub directories of the repository, to be considered an image the folder has to contain a Dockerfile that will be used to build the image. The repository has two workflows:
  • build-image-from-tag: Workflow to build, tag and push an image to the oci organization
  • multi-semantic-release: Workflow to create tags for the images using the multi-semantic-release tool.
As the workflows are already configured to use some of our images we pushed some of them from a checkout of the repository using the following commands:
registry="forgejo.mixinet.net/oci"
for img in alpine-mixinet node-mixinet multi-semantic-release; do
  docker build -t $registry/$img:1.0.0 $img
  docker tag $registry/$img:1.0.0 $registry/$img:latest
  docker push $registry/$img:1.0.0
  docker push $registry/$img:latest
done
On the next sub sections we will describe what the workflows do and will show their source code.

build-image-from-tag workflowThis workflow uses a docker client to build an image from a tag on the repository with the format image-name-v[0-9].[0-9].[0-9]+. As the runner is executed on a container (instead of using lxc) it seemed unreasonable to run another dind container from that one, that is why, after some tests, I decided to share the dind service server socket with the runner container and enabled the option to mount it also on the containers launched by the runner when needed (I only do it on the build-image-from-tag action for now). The action was configured to run using a trigger or when new tags with the right format were created, but when the tag is created by multi-semantic-release the trigger does not work for some reason, so now it only runs the job on triggers and checks if it is launched for a tag with the right format on the job itself. The source code of the action is as follows:
name: build-image-from-tag
on:
  workflow_dispatch:
jobs:
  build:
    # Don't build the image if the registry credentials are not set, the ref is not a tag or it doesn't contain '-v'
    if: $  vars.REGISTRY_USER != '' && secrets.REGISTRY_PASS != '' && startsWith(github.ref, 'refs/tags/') && contains(github.ref, '-v')  
    runs-on: docker
    container:
      image: forgejo.mixinet.net/oci/node-mixinet:latest
      # Mount the dind socket on the container at the default location
      options: -v /dind/docker.sock:/var/run/docker.sock
    steps:
      - name: Extract image name and tag from git and get registry name from env
        id: job_data
        run:  
          echo "::set-output name=img_name::$ GITHUB_REF_NAME%%-v* "
          echo "::set-output name=img_tag::$ GITHUB_REF_NAME##*-v "
          echo "::set-output name=registry::$(
            echo "$  github.server_url  "   sed -e 's%https://%%'
          )"
          echo "::set-output name=oci_registry_prefix::$(
            echo "$  github.server_url  /oci"   sed -e 's%https://%%'
          )"
      - name: Checkout the repo
        uses: actions/checkout@v4
      - name: Export build dir and Dockerfile
        id: build_data
        run:  
          img="$  steps.job_data.outputs.img_name  "
          build_dir="$(pwd)/$ img "
          dockerfile="$ build_dir /Dockerfile"
          if [ -f "$dockerfile" ]; then
            echo "::set-output name=build_dir::$build_dir"
            echo "::set-output name=dockerfile::$dockerfile"
          else
            echo "Couldn't find the Dockerfile for the '$img' image"
            exit 1
          fi
      - name: Login to the Container Registry
        uses: docker/login-action@v3
        with:
          registry: $  steps.job_data.outputs.registry  
          username: $  vars.REGISTRY_USER  
          password: $  secrets.REGISTRY_PASS  
      - name: Set up Docker Buildx
        uses: docker/setup-buildx-action@v3
      - name: Build and Push
        uses: docker/build-push-action@v6
        with:
          push: true
          tags:  
            $  steps.job_data.outputs.oci_registry_prefix  /$  steps.job_data.outputs.img_name  :$  steps.job_data.outputs.img_tag  
            $  steps.job_data.outputs.oci_registry_prefix  /$  steps.job_data.outputs.img_name  :latest
          context: $  steps.build_data.outputs.build_dir  
          file: $  steps.build_data.outputs.dockerfile  
          build-args:  
            OCI_REGISTRY_PREFIX=$  steps.job_data.outputs.oci_registry_prefix  /
Some notes about this code:
  1. The if condition of the build job is not perfect, but it is good enough to avoid wrong uses as long as nobody uses manual tags with the wrong format and expects things to work (it checks if the REGISTRY_USER and REGISTRY_PASS variables are set, if the ref is a tag and if it contains the -v string).
  2. To be able to access the dind socket we mount it on the container using the options key on the container section of the job (this only works if supported by the runner configuration as explained before).
  3. We use the job_data step to get information about the image from the tag and the registry URL from the environment variables, it is executed first because all the information is available without checking out the repository.
  4. We use the job_data step to get the build dir and Dockerfile paths from the repository (right now we are assuming fixed paths and checking if the Dockerfile exists, but in the future we could use a configuration file to get them, if needed).
  5. As we are using a docker daemon that is already running there is no need to use the docker/setup-docker-action to install it.
  6. On the build and push step we pass the OCI_REGISTRY_PREFIX build argument to the Dockerfile to be able to use it on the FROM instruction (we are using it in our images).

multi-semantic-release workflowThis workflow is used to run the multi-semantic-release tool on pushes to the main branch. It is configured to create the configuration files on the fly (it prepares things to tag the folders that contain a Dockerfile using a couple of template files available on the repository s .forgejo directory) and run the multi-semantic-release tool to create tags and push them to the repository if new versions are to be built. Initially we assumed that the tag creation pushed by multi-semantic-release would be enough to run the build-tagged-image-task action, but as it didn t work we removed the rule to run the action on tag creation and added code to trigger the action using an api call for the newly created tags (we get them from the output of the multi-semantic-release execution). The source code of the action is as follows:
name: multi-semantic-release
on:
  push:
    branches:
      - 'main'
jobs:
  multi-semantic-release:
    runs-on: docker
    container:
      image: forgejo.mixinet.net/oci/multi-semantic-release:latest
    steps:
      - name: Checkout the repo
        uses: actions/checkout@v4
      - name: Generate multi-semantic-release configuration
        shell: sh
        run:  
          # Get the list of images to work with (the folders that have a Dockerfile)
          images="$(for img in */Dockerfile; do dirname "$img"; done)"
          # Generate a values.yaml file for the main packages.json file
          package_json_values_yaml=".package.json-values.yaml"
          echo "images:" >"$package_json_values_yaml"
          for img in $images; do
            echo " - $img" >>"$package_json_values_yaml"
          done
          echo "::group::Generated values.yaml for the project"
          cat "$package_json_values_yaml"
          echo "::endgroup::"
          # Generate the package.json file validating that is a good json file with jq
          tmpl -f "$package_json_values_yaml" ".forgejo/package.json.tmpl"   jq . > "package.json"
          echo "::group::Generated package.json for the project"
          cat "package.json"
          echo "::endgroup::"
          # Remove the temporary values file
          rm -f "$package_json_values_yaml"
          # Generate the package.json file for each image
          for img in $images; do
            tmpl -v "img_name=$img" -v "img_path=$img" ".forgejo/ws-package.json.tmpl"   jq . > "$img/package.json"
            echo "::group::Generated package.json for the '$img' image"
            cat "$img/package.json"
            echo "::endgroup::"
          done
      - name: Run multi-semantic-release
        shell: sh
        run:  
          multi-semantic-release   tee .multi-semantic-release.log
      - name: Trigger builds
        shell: sh
        run:  
          # Get the list of tags published on the previous steps
          tags="$(
            sed -n -e 's/^\[.*\] \[\(.*\)\] .* Published release \([0-9]\+\.[0-9]\+\.[0-9]\+\) on .*$/\1-v\2/p' \
              .multi-semantic-release.log
          )"
          rm -f .multi-semantic-release.log
          if [ "$tags" ]; then
            # Prepare the url for building the images
            workflow="build-image-from-tag.yaml"
            dispatch_url="$  github.api_url  /repos/$  github.repository  /actions/workflows/$workflow/dispatches"
            echo "$tags"   while read -r tag; do
              echo "Triggering build for tag '$tag'"
              curl \
                -H "Content-Type:application/json" \
                -H "Authorization: token $  secrets.GITHUB_TOKEN  " \
                -d " \"ref\":\"$tag\" " "$dispatch_url"
            done
          fi
Notes about this code:
  1. The use of the tmpl tool to process the multi-semantic-release configuration templates comes from previous uses, but on this case we could use a different approach (i.e. envsubst could be used) but we left it because it keeps things simple and can be useful in the future if we want to do more complex things with the template files.
  2. We use tee to show and dump to a file the output of the multi-semantic-release execution.
  3. We get the list of pushed tags using sed against the output of the multi-semantic-release execution and for each one found we use curl to call the forgejo API to trigger the build job; as the call is against the same project we can use the GITHUB_TOKEN generated for the workflow to do it, without creating a user token that has to be shared as a secret.
The .forgejo/package.json.tmpl file is the following one:
 
  "name": "multi-semantic-release",
  "version": "0.0.0-semantically-released",
  "private": true,
  "multi-release":  
    "tagFormat": "$ name -v$ version "
   ,
  "workspaces":   .images   toJson  
 
As can be seen it only needs a list of paths to the images as argument (the file we generate contains the names and paths, but it could be simplified). And the .forgejo/ws-package.json.tmpl file is the following one:
 
  "name": "  .img_name  ",
  "license": "UNLICENSED",
  "release":  
    "plugins": [
      [
        "@semantic-release/commit-analyzer",
         
          "preset": "conventionalcommits",
          "releaseRules": [
              "breaking": true, "release": "major"  ,
              "revert": true, "release": "patch"  ,
              "type": "feat", "release": "minor"  ,
              "type": "fix", "release": "patch"  ,
              "type": "perf", "release": "patch"  
          ]
         
      ],
      [
        "semantic-release-replace-plugin",
         
          "replacements": [
             
              "files": [ "  .img_path  /msr.yaml" ],
              "from": "^version:.*$",
              "to": "version: $ nextRelease.version ",
              "allowEmptyPaths": true
             
          ]
         
      ],
      [
        "@semantic-release/git",
         
          "assets": [ "msr.yaml" ],
          "message": "ci(release):   .img_name  -v$ nextRelease.version \n\n$ nextRelease.notes "
         
      ]
    ],
    "branches": [ "main" ]


The oci/mirrors projectThe repository contains a template for the configuration file we are going to use with regsync (regsync.envsubst.yml) to mirror images from remote registries using a workflow that generates a configuration file from the template and runs the tool. The initial version of the regsync.envsubst.yml file is prepared to mirror alpine containers from version 3.21 to 3.29 (we explicitly remove version 3.20) and needs the forgejo.mixinet.net/oci/node-mixinet:latest image to run (as explained before it was pushed manually to the server):
version: 1
creds:
  - registry: "$REGISTRY"
    user: "$REGISTRY_USER"
    pass: "$REGISTRY_PASS"
sync:
  - source: alpine
    target: $REGISTRY/oci/alpine
    type: repository
    tags:
      allow:
        - "latest"
        - "3\\.2\\d+"
        - "3\\.2\\d+.\\d+"
      deny:
        - "3\\.20"
        - "3\\.20.\\d+"

mirror workflowThe mirror workflow creates a configuration file replacing the value of the REGISTRY environment variable (computed by removing the protocol from the server_url), the REGISTRY_USER organization value and the REGISTRY_PASS secret using the envsubst command and running the regsync tool to mirror the images using the configuration file. The action is configured to run daily, on push events when the regsync.envsubst.yml file is modified on the main branch and can also be triggered manually. The source code of the action is as follows:
.forgejo/workflows/mirror.yaml
name: mirror
on:
  schedule:
    - cron: '@daily'
  push:
    branches:
      - main
    paths:
      - 'regsync.envsubst.yml'
  workflow_dispatch:
jobs:
  mirror:
    if: $  vars.REGISTRY_USER != '' && secrets.REGISTRY_PASS != ''  
    runs-on: docker
    container:
      image: forgejo.mixinet.net/oci/node-mixinet:latest
    steps:
      - name: Checkout
        uses: actions/checkout@v4
      - name: Sync images
        run:  
          REGISTRY="$(echo "$  github.server_url  "   sed -e 's%https://%%')" \
          REGISTRY_USER="$  vars.REGISTRY_USER  " \
          REGISTRY_PASS="$  secrets.REGISTRY_PASS  " \
            envsubst <regsync.envsubst.yml >.regsync.yml
          regsync --config .regsync.yml once
          rm -f .regsync.yml

ConclusionWe have installed a forgejo-runner and configured it to run actions for our own server and things are working fine. This approach allows us to have a powerful CI/CD system on a modest home server, something very useful for maintaining personal projects and playing with things without needing SaaS platforms like github or gitlab.

Dirk Eddelbuettel: RcppExamples 0.1.10: New factor Example, Other Updates

A new version 0.1.10 of the RcppExamples package is now on CRAN, and marks the first release in five and half years. RcppExamples provides a handful of short examples detailing by concrete working examples how to set up basic R data structures in C++. It also provides a simple example for packaging with Rcpp. The package provides (generally fairly) simple examples, more (and generally longer) examples are at the Rcpp Gallery. This releases brings a bi-directorial example of factor conversion, updates the Date example, removes the explicitly stated C++ compilation standard (which CRAN now nags about) and brings a number of small fixes and maintenance that accrued since the last release. The NEWS extract follows:

Changes in RcppExamples version 0.1.10 (2025-03-17)
  • Simplified DateExample by removing unused API code
  • Added a new FactorExample with conversion to and from character vectors
  • Updated and modernised continuous integrations multiple times
  • Updated a few documentation links
  • Updated build configuration
  • Updated README.md badges and URLs
  • No longer need to set a C++ compilation standard

Courtesy of my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

Next.

Previous.