Search Results: "tar"

15 June 2008

Jeff Bailey: I need a TV-B-Gone for the gym

Dear CNN,

The US presidential election race between senators McCain and Obama is not a "battleground". Battlegrounds are where people get killed. Using the same words for what passes as democracy in this country as for the military massacres in foreign countries is incredibly sad and disgusting.

That, and it's only vaguely less stupid than Toronto's "War on Fire".

14 June 2008

Romain Francoise: Three things

Totally awesome: Moodstream. Yet another evil Flash-only site, but this one is worth it.

Pretty cool: code_swarm, an experiment in organic software visualization . Check out the Python video.

Sucks big time: having to wait until February 2009 for the end of BSG season four. Not sure I'll have the strength.

Lior Kaplan: The 2nd Debian Openoffice.org bug triage has ended - 300+ bugs processed


The 2nd bug triage began with 285 bugs, which grow to around 310 bugs, since during the 4 months of the triage more bugs were reported.
So, I m glad to announce the beginning of (my) 2nd openoffice.org bug triage. This triage targets 285 bugs out of 330 open oo.org bugs. The selected bug are ones which were reported against versions lower the 2.3.1 or have no version information at all.
At first, the triage advanced quickly with 21% of the bugs processed during the first 24 hours and 40% during the first 10 days. This left a long trail of bugs to handle manually. The triage began for version 2.3.1, but was delayed to let version 2.4.0 to propagate into Lenny, as that was Rene’s preferable version to release with. When the triage resumed in late April, I had a 2.4.0 available in all of our repositories (sid, testing and backprots). Which meant that everyone could verify their bugs against the same oo.org version. Bug triaging heaven (: Two thirds (66%) of the bugs were closed in this triage, most of them after a check from the submitter or myself and a few after the submitter was unresponsive and I couldn’t verify the bug myself. Verifying the bugs myself is the most demanding part of the triage. Reading each report and understanding the problem takes a lot of time. Reproducing the problem usually takes less time than understand it. That’s way have test cases attached to bug reports are so important. In several cases the instructions were so simple I could just open the file, check something and verify the bug. That was done in a robotic manner or in a monkey like one. These kind of attachments enables a lot of people to help with triaging, even if the lake the technical background of the program in subject. So after closing 200 bugs and verifying around 100+, the oo.org bug count is set to 140 outstanding bugs, and 70 bug being forwarded to upstream. Except from about 10 bugs, all of the remaining 130 bugs are relevant for version 2.4.0. No need to wonder if the bug still occurs before reading the report…

Jan Wagner: postfwd 1.10pre7c-1 in experimental

postfwd 1.10pre7c-1 has been accepted and did hit experimental yesterday.
If you using policyd-weight you might want to give it a try, since its active development stoped. If you are annoyed by too much spam, it maybe a good idea as well.
Please have a look on postfwd.cf, there is no default config provided, since the configuration depends heavily on your environment. But maybe you have a look at /usr/share/doc/postfwd/examples, there is what you expect.
If you have any comments, send a mail to the maintainer or if there are bugs I didn’t spotted yet, please fill one!
In case I don’t respond quit fast, maybe I’m in the delivery room or anywhere else in the hospital or something like that, so please give me some extra time.
In case there are no big issues, I plan to upload the package to unstable in a reasonable time.

Russell Coker: What is Appropriate Advertising?

Colin Charles writes about a woman who is selling advertising space on herself [1]. Like Colin I haven’t bought a t-shirt in about 9 years (apart from some Cafepress ones I designed myself). So it seems that the price for getting some significant advertising at a computer conference is to buy a few hundred t-shirts (they cost $7 each when buying one at a time from Cafepress, I assume that the price gets lower than $3 each when buying truck-loads). I have been given boxer-shorts and socks with company logos on them (which I never wore), I think that very few people will show their underwear to enough people to make boxer-shorts a useful advertising mechanism, socks would probably work well in Japan though. It seems to me that many people regard accepting free t-shirts as being an exception to all the usual conventions regarding advertising. Accepting gifts from companies that you do business with is generally regarded as a bad idea, except of course when t-shirts and other apparel are given out then it’s OK. Being paid to wear a placard advertising a product is regarded as degrading by many people, but accepting a free t-shirt (effectively being paid $7 for wearing advertising) is regarded as OK by almost everyone. I don’t mind being a walking advert for a company such as Google. I use many Google products a lot and I can be described as a satisfied customer. There are some companies that have given me shirts which I only wear in winter under a jumper. The Oracle Unbreakable Linux [2] shirt is one that I wear in winter. Now I would not consider accepting an offer to have advertising on my butt (although I’m pretty sure that it doesn’t get enough attention that anyone would make such an offer). I would however be happy to talk with someone who wants to pay me to wear a t-shirt with advertising when giving a lecture at a conference. I am not aware of any conference which has any real dress requirement for speakers (apart from the basic idea of not offending the audience). The standard practice is that if your employer pays you to give a lecture as part of their marketing operation then they give you a shirt to wear (polo more often than t-shirt). I am currently working on some things which could end up as papers for presentation at Linux conferences. If someone wanted to sponsor my work on one of those free software related projects and then get the recognition of having me wear their shirt while giving a lecture and have me listed as being sponsored by that company in the conference proceedings then that seems like a reasonable deal for everyone. One thing that you need to keep in mind when accepting or soliciting for advertising is the effect it has on your reputation. Being known as someone who wants advertising on their butt probably wouldn’t be fun for very long. On the Internet advertising seems to be almost everywhere. It seems that more than half the content on the net (by the number of pages or by the number of hits) either has an option to donate (as Wikipedia does and some blogs are starting to do), has Google advertising (or a similar type of adverts from another company), is a sales site (IE you can buy online), or is a marketing site (IE provides background information and PR to make you want to buy at some other time). Note that my definition of advertising is quite broad, for example the NSA web site [3] has a lot of content that I regard as advertising/marketing - with the apparent aim of encouraging skilled people to apply for jobs. Not that I’m complaining, I’ve visited the National Cryptologic Museum [4] several times and learned many interesting things! I think that Internet advertising that doesn’t intrude on the content (IE no pop-ups, page diversions, or overly large adverts) is fine. If the advertising money either entirely pays people to produce useful content or simply encourages them to do so (as in the case of all the blogs which earn $10 a month) then I’m happy with that. I have previously written about some of my experience advertising on my blog [5] and how I encourage others to do the same. I don’t think that space on a t-shirt is any more or less appropriate for advertising than space on a web site hosting someone’s blog. Finally there is one thing I disagree with in Colin’s post, that is the use of the word “whore“. It’s not uncommon to hear the term “whoring” used as a slang term for doing unreasonable or unworthy things to make money (where “unreasonable” and “unworthy” often merely means doing something that the speaker wouldn’t be prepared to do). But using the term when talking about a woman is quite likely to cause offense and is quite unlikely to do any good. The Wikipedia page about prostitution [6] has some interesting background information.

Robert Collins: 14 Jun 2008

Rethinking annotate: I was recently reminded of Bonsai for querying vcs history. GNOME runs a bonsai instance. This got me thinking about 'bzr annotate', and more generally about the problem of figuring out code. It seems to me that 'bzr annotate', is, like all annotates I've seen pretty poor at really understanding how things came to be - you have to annotate several versions, cross reference revision history and so on. 'bzr gannotate' is helpful, but still not awesome. I wondered whether searching might be a better metaphor for getting some sort of handle on what is going on. Of course, we don't have a fast enough search for bzr to make this plausible. So I wrote one: bzr-search in my hobby time (my work time is entirely devoted to landing shallow-branches for bzr, which will make a huge difference to pushing new branches to hosting sites like Launchpad). bzr-search is alpha quality at the moment (though there are no bugs that I'm aware of). Its mainly missing optimisation, features and capabilities that would be useful, like meaningful phrase searching/stemming/optional case insensitivity on individual searches. That said, I've tried it on some fairly big projects - like my copy of python here:
time bzr search socket inet_pton
(about 30 hits, first one up in 1 second)...
real    0m2.957s
user    0m2.768s
sys     0m0.180s
The index run takes some time (as you might expect, though like I noted - it hasn't been optimised as such). Once indexed, a branch will be kept up to date automatically on push/pull/commit operations. I realise search is a long slope to get good results on, but hey - I'm not trying to compete with Google :). I wanted something that had the following key characteristics: * Worked when offline * Simple to use * Easy to install Which I've achieved - I'm extremely happy with this plugin. Whats really cool though, is that other developers have picked it up and already integrated it into loggerhead and bzr-eclipse. I don't have a screen shot for loggerhead yet, but heres an old one. This old one does not show the path of a hit, nor the content summaries, which current bzr-search versions create.

13 June 2008

Peter Eisentraut: Debian Release Goals

I have been tracking the Debian release goals progress for a while now, through bug-squashing parties and using various iterations of wiki pages. It's time to write down some thoughts.

First of all, I think the concept of release goals is a fantastic idea. It may be one of the most important conceptual moves in Debian of late. It allows developers to implement distribution-wide changes without having to negotiate with every package maintainer individually and without having to go through the vicious no-change-without-policy/no-policy-without-established-practice maze. It moves the focus back on operating system development instead of package hoarding.

In the future, I think we should come up with some "sexier" release goal descriptions. If you look over the current list, many of these tasks are implementation-level, without any obvious benefit to users: double-build support? no unmet recommends? Or they have incomprehensible descriptions. The pretty much only release goal that has a real user benefit, namely the piuparts cleanness, ensuring clean distribution upgrades, is both the most cryptic and actually the most neglected one in terms of development attention. Don't get me wrong, all these goals are very valid. For better or worse, the press has started to pick up these release goals to put in their various Debian release candidate timeline pre-announcement articles, and next time around we should have something cool in there. If armel support or KDE 4 integration had been release goals, the marketing effect would be better.
The next thing is tracking bugs. If you have some time on your hands, how do you find a release goal bug that you can help with? I had worked up this wiki page to help myself, but it is still too weird. The fact that bts.turmzimmer.net exists shows that the BTS is lacking features or is too hard to use or both. I'm thinking, we should regularly copy the whole BTS into an SQL database and make queries from there. Think aggregation, grouping, full-text search! I'm not familiar with the BTS internals or the LDAP gateway, but I know my SQL. So if anyone knows the other end of this deal, I'd love to chat about setting something like this up.

So then, what happens to the release goals after the release? Has this been thought through?

Obviously, some release goals become technically self-enforcing. Python 2.5 and GCC 4.3 are now the default, and anything that doesn't work with these will have permanent trouble in the future.

Release goals that implement a distribution-wide feature, such as the LSB-based init system enhancements, will really need to become part of policy after the release. Otherwise they would revert to being normal bugs without any NMU powers and the other special attention given to release goals. So over time, the support for the former release goals across packages would again decline. To keep it up, you'd either have to repeat the release goal indefinitely, which would be silly, especially when there are no problems right now, or you'd have to make it a part of policy to enforce it in the future. Essentially, you'd have to consider most release goals trial policy changes, which become permanent if successful.

Near-examples of the above are the eternal release goals of IPv6 support and LFS support. We really have these under control quite well now -- although I still wouldn't dare to call Debian or any general-purpose Linux distribution fully IPv6-ready -- but nowadays these problems are almost all upstream code problems that Debian can't really fix very well on the packaging side. So under the current approach these release goals will exist forever, or worse, will be dropped from release goal status.

And then of course, some release goals fail to be reached. These should reapply for the next release, if interest persists. The dash goal comes to mind.

By the way, we had 13 release goals. 3 are completely done, 5 are pretty much done (less than 10 bugs), 1 more looks like it could get pretty much done before the release, and 4 will most likely fail to be accomplished.

Gunnar Wolf: Freedom itches

In this Free Software movement we have many mottos - One of which, describing what motivates us to work writing code, is scratch where it itches.
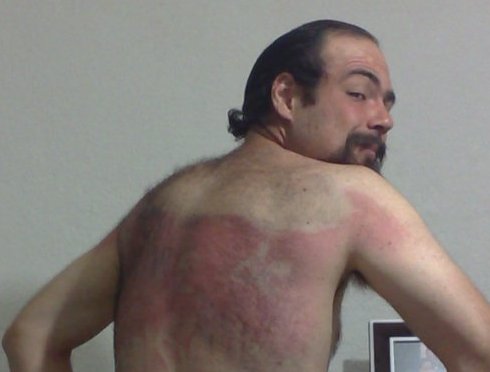
Of course, I could not keep it to myself - Almost a week ago, I took part of the World Naked Bike Ride. What I didn't tell you... Is that it became obvious I cannot reach most of by back - And it's because I'm mostly careless. When the WNBR started, it was still quite cloudy, even starting to rain... so I was mostly careless.
If you opened the newspaper PDF I attached to my previous post, you'll surely remember (not an easy sight to get out of your head, I guess) I had painted on my back "Veh culo libre de emisiones" - Emissions-free vehicle (and yes, it's strictly true: My bike is zero emissions. The animal riding it might not be... But that's a different story). Add incomplete sunblock to the equation, and...

Were it not for the poor lighting conditions under which I took the photo, you'd clearly appreciate the words "libre de" on my back.
And... Well, one week later, my freedom itches.
Badly.

Theodore Ts'o: Learning how to communicate

Pity poor Dr. Ari Jaaksi from Nokia. He gave a talk at the Handsets World conference in Berlin on Tuesday, where according to ZDnet, he lectured Open Source Developers that they needed to learn why DRM and other closed technologies were necessary, because of business issues such as subsidized (device) business models. I suspect he wasn’t prepared for the reaction, which took the form of a major fuss on Slashdot, as well as some declarations from a few people on the maemo-users mailing lists that they would never buy another Nokia device. Dr Jaaski then posted today on his blog an entry entitled, “Some learning to do?”, where he stated that while Nokia needs to learn how the open source world works (not just licenses and legal issues, but also the spirit), that the open source world also needed to learn as well — about WHY things are the way they are. He ended the post with “I’m not a teacher, I’m a learner” — which is fair enough. I actually think that Dr. Jaaksi is right; we all should be interested in learning, and having talked with a number of Nokia employees, I can testify that their hearts are very much in the right place, and there are some strong reasons regarding the demands of carriers, the subsidized business model of handsets in the US, the attitudes of suppliers for components in mobile devices, that very much tie their hands — as well the hands of every other handset company out there. Progress in this space will come slowly, and but I believe there is hope that in the long run things will get better. However, at the same time, I would suggest to Dr. Jaaksi that it’s also important how to communicate with the open source community — or with any community that holds views sometimes with great passion. Many people do not react well to being told that they need to learn something — even if it is true that they do. Admitting that they need to learn is for some people tantamount to admitting ignorance, or even worse admitting stupidity, and so they are loath to do this. Telling them this just makes them defensive and angry. My suggestion for how get people to learn without making them defensive is to use a modified Socratic method. It works especially well with the Open Source crowd, because many of them are engineers, and engineers are by nature problem solvers. So if you give them a problem to solve, they will go to work trying to find potential solutions, and thus start thinking and learning about the problem from a different point of view. Hence, a better approach is to give them a series of business constraints (time to market, the demands of carriers, the fact that most end users prefer to buy subsidized phones with 1-2 year lock-in contracts, the intransigence of suppliers, why a single company can’t afford to create their own chipsets from scratch and have to rely on companies like Broadcom, etc.) and then tell them — we’d love to delight our customers in any way we can, and clearly you are very passionate about DRM, open device drivers, and other OSS issues. We however have to create successful products and sell them at a price such that we don’t go out of business — can you help us work through all of these constraints? Let’s work together so we can make an open source mobile platform that meets the spirit as well as the legal requirements of the open source world! Dr. Jaaksi and his team are struggling with a hard problem, and I am very sympathetic to their issues. And, they have to be commended for investing as much time and effort on the Maemo platform, as well as other Linux and Open Source platforms as they have to date. The strength of the Open Source community is that we work together to solve our mutual problems, while celebrating and giving permission to people to “scratch their own itches”. In order to do that, we need to learn how to better communicate with each other, and that is something that goes in both directions. When I was at MIT as an undergraduate, far too many years ago than I care to admit, I took economics classes and Sloan School of Management classes (even though they were not necessary for a Computer Science degree) for that very reason. I encourage open source advocates to learn how to walk a mile or two in business people’s shoes, since if you want to influence them them to change in the ways that you desire, you need to know where they are coming from — just shouting and throwing rotten tomatoes generally won’t get you very far. On the flip side, people who are on the corporate side of the divide also need to understand that certain ways of engaging the community can be more productive than others. At the end of the day, hopefully we can all agree with Dr. Jaaksi that everyone will benefit if we all commit to learning from each other. Update: I’ve fixed Dr. Jaaksi’s name so it is spelled correctly; my apologies for the error.

Clint Adams: Cayrin

We sat at the round table, decanting the Tokaji. Elkins gave me a quizzical look. Podjad stared at the label on the bottle. Elkins wiggled her nose at me. It was then that I knew I was going to lose. The Scourge of Scranton made his entrance, striding just so to maximize his projection of gravitas. His long, purple velvet cape trailed behind him as his knee-high leather boots clacked on the parlor floor. Podjad studied a word etched on the carafe. Elkins smirked. The Scourge of Scranton stood before the table as beads of sweat collected on his widow's peak. He looked at us. We looked at him. He strode out whence he came.

Miriam Ruiz: Gnash 0.8.3 released

Russ Nelson announces that the newer version of Gnash has been released. I’ve already created newer packages for it, but I cannot upload them to Debian yet, as they’re blocked for the poppler, c-ares and ffmpeg transitions. I hope to have them uploaded soon. In any case, I’ve put them here, if someone wants to try them. As the backends for the rendering, widgets and media must be decided on compile time, there’s not much to do if you want to use the most uncommon ones. The most stable and conservative option is agg and GStreamer, but I’ve also added the possibility of using OpenGL, which would be better for hardware-accelerated machines. Versions for both GTK and KDE widget systems are compiled. In a week or so they will probably be in Debian, in time for Lenny. Improvements since 0.8.2 release are:

Russ Allbery: FAI and Ubuntu

My project for the past three days has been to upgrade our etch-based Debian build system to add support for Ubuntu hardy. We're primarily a Debian shop, but we want to use Ubuntu for the public timeshare systems due to its faster stable update cycle. In that environment, the latest and greatest software and active security support are both important simultaneously, and server-level stability isn't as vital. Ubuntu wins over other options because it's basically Debian and therefore shares with Debian the huge package selection, which is important for university timeshare systems. (We also use the external R package repository; we have a lot of heavy R users.) First, FAI has changed a lot since the etch release and hardy has a far more recent version of fai-client, which means that just bootstrapping an Ubuntu NFS root on an etch system and trying to install it with the etch FAI doesn't work due to the mismatch between the server expectations and the fai-client and fai-nfsroot packages. FAI during the etch release boots with a traditional read-only NFS root and works around the fact that its boot device is read-only. Current FAI does essentially the same trick that a live CD does, using unionfs to allow local modifications to the NFS root with a backing tmpfs file system, which is kind of scary but allows FAI to be much simpler. The first thing I tried was debootstrapping Ubuntu (using the debootstrap from backports.org) and then downgrading its fai-client and fai-nfsroot packages to the etch versions, but changes in other part of the system (particularly mount) makes that not very viable. One of the nice things about FAI is that it's basically a collection of shell scripts, which means that it's architecture-independent and one can easily install the unstable packages on an otherwise-etch system. So I upgraded fai-server to the current Debian sid version of FAI and installed the sid versions of fai-nfsroot and fai-client into the Ubuntu NFS root after generating it with make-fai-nfsroot as normal. That works much better. However, there are a few Ubuntu-specific problems to work around (which are patched in the Ubuntu version of FAI, but I don't want to have to track down an Ubuntu system to generate the NFS roots when the rest of our infrastructure is etch): Other than that, most of the work was upgrading the whole system to using the new boot method (changing to boot=live on the PXE kernel options, including live-initramfs in the NFS root, copying the kernel and initrd out of the NFS root into the tftp area instead of using fai-kernels, and adding initrd to the PXE kernel options). I'm now successfully building etch and hardy systems using our FAI setup and will probably upgrade the production service next week. There is one other fairly serious Ubuntu design misfeature that is only tangentially related but that cost me a lot of time. Ubuntu has modified update-grub to make it use ucf, which breaks the traditional update-grub semantics in extremely strange and confusing ways that took hours for me to diagnose. For those who aren't familiar with the details of how update-grub works, it uses comments in /boot/grub/menu.lst as a template to generate the kernel list at the end of menu.lst. It's not the best design, since it uses the same file as both a template and the active configuration file, but it works, and has worked the same way for many years. It's simple and reliable: you only change the defaults in the comments and then update-grub adds in the kernel-specific information and generates the active menu for you. If you want to edit the kernel list yourself for some reason, don't use update-grub; it's completely optional. To see how using ucf breaks this, remember that ucf's goal is to preserve local changes to a configuration file, but its notion of local changes is fundamentally contrary to how menu.lst works. Suppose that you're a large organization with a lot of systems with a variety of kernel revisions, for one reason or another, but with a desire to have uniform kernel parameters like console speed and timeouts. With update-grub, you can just copy your menu.lst template to all of your systems and run update-grub afterwards, and update-grub will apply your new defaults and generate a new kernel list using them. However, with Ubuntu's update-grub, it generates the initial menu.lst and kernel list, and then when you replace that with a fresh template, ucf sees that you've removed the kernel list. It thinks that's a local modification, and when update-grub generates a new kernel list, it "preserves" your modification and leaves the kernel list out of the new menu.lst. Tada, instant unbootable system. Even worse, this bug is sticky: you can re-run update-grub all you want, it succeeds without errors, and it keeps generating an empty menu.lst. This is a completely mystifying error until you dig into the details of what's going on. To recover, you have to run ucf --purge /var/run/grub/menu.lst (and that path, or for that matter any of the ucf stuff, is completely undocumented in the update-grub man page) and then re-run update-grub, at which point ucf will display a debconf prompt (which doesn't support debconf preseeding, but that's another problem). If you then select three-way merge (not the default) from that prompt, you get a correct menu.lst. I'm not sure why Ubuntu made this change, but as near as I can tell, it's fundamentally architecturally broken. The specific problem I had was that we were copying our template over and re-running update-grub in a post-install script, resulting in a system that always had an empty kernel menu and wouldn't boot. Once I finally figured out what's going on, I worked around it by being very careful to put our template in place before the initial system bootstrap and then never changing menu.lst afterwards, but this is a bad limitation for a large site that scales system administrators by automating configuration file updates. But maybe I'm missing some subtlety. I'll go file a Launchpad bug shortly after posting this and we'll see what happens.

12 June 2008

Russell Coker: Wyndham Resorts is a Persistent Spammer

Over the last week I have received five phone calls from Wyndham Resorts asking if I would like to be surveyed. Every time I tell them that I am not going to do their survey, on all but one call I had to repeatedly state that I would not do the survey for more than two minutes before they would go away. The advantage of phone spam over email spam is that the caller pays, I guess that they have a time limit of three minutes when calling a mobile phone to save on calling costs. There have been a number of proposals for making people pay for email to discourage spam. Even a cost of a few cents a message would make spam cease being economically viable for a mass audience (a smaller number of targeted spams would be easier to block or delete). But such plans to entirely change the way email works have of course failed totally. But for phones it could work. I’d like to have a model where anyone who calls me has to pay an extra dollar per minute which gets added on to their phone bill. When people who I want to talk to call me I could reimburse them (or maybe be able to give my phone company a list of numbers not to bill). This could also seamlessly transition to commercial use. I would be happy to accept calls from people asking for advice about Linux and networking issues for $1 per minute. With all the people who call me about such things for free already it would be good to answer some questions for money.

Enrico Zini: How to autologin X without a display manager

How to autologin X without a display manager Problem: configure a custom Debian box used to drive some industrial machinery. The system should boot directly into the GUI control application, that runs full screen, with root privileges. Everything should respawn if X is killed or the control application dies. In theory, you'd run an X display manager with autologin, then run matchbox-window-manager and the control application as the X session. You wish. At the end of the post is an explanation of why this way failed. So, here is how to get the whole thing to work, without a display manager. Use init to drive the whole thing:
6:23:respawn:/sbin/getty -L -n -l /usr/local/sbin/autologin

This will respawn everything if it dies, stop respawning if it dies all the time, avoid starting it in single user mode, and not ask for a username. /usr/local/sbin/autologin contains:
#!/bin/sh
/bin/login -f root MAINAPP=true

This will autologin as root, setting an extra env variable. Then comes root's ~/.bash_profile, that just starts X if we are doing autologin:
if [ "$MAINAPP" = "true" ]
then
    startx
    logout
fi

If the application was running as a special user, we could have made things simpler and just used startx as the shell for that user; however, we still want root to have bash as the shell, and the above hack does it. Finally, root's ~/.xsession:
#!/bin/sh
matchbox-window-manager &
# If the touch screen is not calibrated, run the calibration
while [ ! -f /etc/touchscreen-calibration ]
do
        calibrate-touchscreen
done
# Run the main application: if it ends, the session ends
main-application

And there we go, no dependencies at all. Why not using a display manager gdm and kdm seem to do autologin, but their dependency list is not acceptable for something that should just respawn an X server in an industrial system that must be kept simple. xdm on the other hand has a small set of dependencies, but its developers seem to have decided that autologin is a ""glitz", and there is no need for it in such a bare-bones display manager". Dict for "glitz" gives "tasteless showiness". What one has to bear... wdm seems however even more disconcerting, as it "doesn't actually support autologin but you can set the default user and default password in /etc/X11/wdm/wdm-config. Now, [...] you only need to press Enter twice [...] to login". Figure how this would look in the manual: "After powering up the unit, attach a USB keyboard and press enter twice to start the system". And this is why we are not using a display manager.

Romain Francoise: Fun with the Flickr API (in Python)

The favorites mosaic shown in my previous post was a good excuse for me to try out Flickr's API, and it turned out to be a lot easier than I thought. So if, like me, you feel like playing with 2.5 billion photos (and 5,000 new uploads every minute), here's a quick guide.

All you need is an API key (get one here) and a set of bindings for your favorite language. I'm a Python person so I had two choices: Beej's Flickr API and flickr.py; the latter seemed to have everything I needed in a single file, so I went with it. It provides classes directly mapped to most of Flickr's concepts: photos, tags, sets, groups, users, etc.

To get started, let's see what Flickr knows about me (if you don't know your Flickr user id, get it from the RSS link in your photo page):
>>> me = flickr.User('99746300@N00')
>>> me.username, me.ispro, me.location, me.photos_count
(u'orebokech', u'1', u'Lyon, France', u'254')
>>>
Sounds right. Now, to create my favorites mosaic I need to get the list of my favorites, actually I only need 36 of them. Easy:
>>> faves = me.getPublicFavorites(per_page=36)
>>> len(faves)
36
>>>
You can iterate over the list and get flickr.Photo objects which have all the information you need, like the available sizes of the image:
>>> photo = faves[0] # let's just get one for this example
>>> for size in photo.getSizes():
... print "%s: %dx%d" % (size['label'], size['width'], size['height'])
Square: 75x75
Thumbnail: 100x67
Small: 240x160
Medium: 500x333
Original: 1024x683
>>>
And for each available size you can get the corresponding photo page, or the URL to the image itself:
>>> photo.getURL() # photo page, default Medium
u'http://www.flickr.com/photos/o0off/2363681897/sizes/m/'
>>> photo.getURL(size='Square', urlType='source') # img
u'http://farm3.static.flickr.com/2107/2363681897_f6528a14a4_s.jpg'
>>>
Add a little bit of HTML formatting around this, and you get a neat mosaic. The concept can trivially be extended to sets, tag searches, etc. It's all very straightforward.

Phew, this post is getting pretty long, so I think I'll leave you to explore the rest for yourself. Have fun!

Adam Jensen: 12 Jun 2008

The GNU C library (packaged as libc6 in Debian) is the bedrock of a lot of code. What are the packages that it depends on? (Yo, DebGraph!) Original image [997 kB] libc6 is one of the well-connected vertices in the lower-left corner (third quadrant, if you like). For graphs like this one, we would like DebGraph to identify dependency cycles (loops). For example, libc6 depends on libgcc1, which in turn depends on libc6. This can be seen in the graph above by applying some careful scrutiny, but why not let the computer work its magic for us? (To be continued.) As a bonus, who depends on arping 2.05-2 for i386?

Russell Coker: ECC RAM is more useful than RAID

A common myth in the computer industry seems to be that ECC (Error Correcting Code - a Hamming Code [0]) RAM is only a server feature. The difference between a server and a desktop machine (in terms of utility) is that a server performs tasks for many people while a desktop machine only performs tasks for one person. Therefore when purchasing a desktop machine you can decide how much you are willing to spend for the safety and continuity of your work. For a server it’s more difficult as everyone has a different idea of how reliable a server should be in terms of uptime and in terms of data security. When running a server for a business there is the additional issue of customer confidence. If a server goes down occasionally customers start wondering what else might be wrong and considering whether they should trust their credit card details to the online ordering system. So it is obviously apparent that servers need a different degree of reliability - and it’s easy to justify spending the money. Desktop machines also need reliability, more so than most people expect. In a business when a desktop machine crashes it wastes employee time. If a crash wastes an hour (which is not unlikely given that previously saved work may need to be re-checked) then it can easily cost the business $100 (the value of the other work that the employee might have done). Two such crashes per week could cost the business as much as $8000. The price difference between a typical desktop machine and a low-end workstation (or deskside server) is considerably less than that (when I investigated the prices almost a year ago desktop machines with server features ranged in price from $800 to $2400 [1]). Some machines in a home environment need significant reliability. For example when students are completing high-school their assignments have a lot of time invested in them. Losing an assignment due to a computer problem shortly before it’s due in could impact their ability to get a place in the university course that they most desire! Then there is also data which is irreplaceable, one example I heard of was of a woman who’s computer had a factory pre-load of Windows, during a storm the machine rebooted and reinstalled itself to the factory defaults - wiping several years of baby photos… In both cases better backups would mostly solve the problem. For business use the common scenario is to have file servers storing all data and have very little data stored on the PC (ideally have no data on the PC). In this case a disk error would not lose any data (unless the swap space was corrupted and something important was paged out when the disk failed). For home use the backup requirements are quite small. If a student is working on an important assignment then they can back it up to removable media whenever they reach a milestone. Probably the best protection against disk errors destroying assignments would be a bulk purchase of USB flash storage sticks. Disk errors are usually easy to detect. Most errors are in the form of data which can not be read back, when that happens the OS will give an error message to the user explaining what happened. Then if you have good backups you revert to them and hope that you didn’t lose too much work in the mean-time (you also hope that your backups are actually readable - but that’s another issue). The less common errors are lost-writes - where the OS writes data to disk but the disk doesn’t store it. This is a little more difficult to discover as the drive will return bad data (maybe an old version of the file data or maybe data from a different file) and claim it to be good. The general idea nowadays is that a filesystem should check the consistency of the data it returns. Two new filesystems, ZFS from Sun [2] and BTRFS from Oracle [3] implement checksums of data stored on disk. ZFS is apparently production ready while BTRFS is apparently not nearly ready. I expect that from now on whenever anyone designs a filesystem for anything but the smallest machines (EG PDAs and phones) they will include data integrity mechanisms in the design. I believe that one such features become commonly used the need for RAID on low-end systems will dramatically decrease. A combination of good backups and knowing when your live data is corrupted will often be a good substitute for preserving the integrity of the live data. Not that RAID will necessarily protect your data - with most RAID configurations if a hard disk returns bad data and claims it to be good (the case of lost writes) then the system will not read data from other disks for checksum validation and the bad data will be accepted. It’s easy to compute checksums of important files and verify them later. One simple way of doing so is to compress the files, every file compression program that I’ve seen has some degree of error detection. Now the real problem with RAM which lacks ECC is that it can lose data without the user knowing. There is no possibility of software checks because any software which checks for data integrity could itself be mislead by memory errors. I once had a machine which experienced filesystem corruption on occasion, eventually I discovered that it had a memory error (memtest86+ reported a problem). I will never know whether some data was corrupted on disk because of this. Sifting through a large amount of stored data for some files which may have been corrupted due to memory errors is almost impossible. Especially when there was a period of weeks of unreliable operation of the machine in question. Checking the integrity of file data by using the verify option of a file compression utility, fsck on a filesystem that stores checksums on data, or any of the other methods is not difficult. I have a lot of important data on machines that don’t have ECC. One reason is that machines which have ECC cost more and have other trade-offs (more expensive parts, more noise, more electricity use, and the small supply makes it difficult to get good deals). Another is that there appear to be no laptops which support ECC (I use a laptop for most of my work). On the other hand RAID is very cheap and simple to implement, just buy a second hard disk and install software RAID - I think that all modern OSs support RAID as a standard installation option. So in spite of the fact that RAID does less good than a combination of ECC RAM and good backups (which are necessary even if you have RAID), it’s going to remain more popular in high-end desktop systems for a long time. The next development that seems interesting is the large portion of the PC market which is designed not to have the space for more than one hard disk. Such compact machines (known as Small Form Factor or SFF) could easily be designed to support ECC RAM. Hopefully the PC companies will add reliability features in one area while removing them in another.

Julien Danjou: One step further for XCB into Debian

I've take some time this morning to work on xcb-util packaging. I've mainly urge that work because Sebastian Dr ge, the sweet cairo maintainer, agreed to enable the cairo XCB backend (#474353), which requires xcb-util. The first upload I've made was built from the latest upstream release which is old (i.e. more than one year old). So I've put a git repository in place this morning and packaged the latest git upstream version, with some good patches from Arnaud (upstream+patches branch), that the upstream XCB developers are still reviewing since several weeks: that is the cost to pay for good code quality Thanks to Sebastian, the new xcb-util targeted for unstable was just arrived in incoming that he already uploaded a new version of the Debian cairo package with XCB backend enabled. Well, that's a very good day for me since it means that building awesome 3 is no more a PITA (hi MadCoder!) since every dependency is available in the Debian archive.

Matthew Palmer: Womble's Word of the Week: Retrofit!

In a perfect world, when we design some aspect of our infrastructure, we'd get it right the first time, and would never have to change our design once it had been deployed. Back in this world, however, we regularly have to change things as we expand our infrastructure. Sometimes we made a mistake originally, other times new requirements pop up. In either case we will end up doing things differently in the future than how it was done in the past. The danger here is that if you only create your new machines or services differently, you've got effectively two separate and different systems to maintain. This may not sound like much, until it happens again... and again... and again... and then suddenly you've got 18 different ways of setting up backups, depending on how long ago you set it up and (if you're really unlucky) who did it and what the phase of the moon was at the time. If you've been here before, you probably remember the pain of having some disaster happen and needing to fix it NOW NOW NOW, only to wade into the setup and realise that it's been done in a way that (you thought) died out six months ago -- and so you don't really remember how it works, and yeah, the documentation's been updated so many times since then that it doesn't mention the old way of doing things, and here comes your boss to ask how long it's going to be until it's all working again... If you haven't had this experience (yet?), you'll have to trust me when I say that it's no fun to hit an older, out-of-date system. It's especially painful because the most common reason you change things is because the old way sucked. So you turn up at a critical moment to fix something in a poorly documented and sub-optimally configured system. Fun, fun, funnity fun. There are only two ways to avoid this problem: never change the way you do anything, or else plan your changes so that retrofitting is part of the plan every time you're modifying an existing service. Assuming that never changing anything isn't an option, you need to plan to retrofit. When you're putting together the design for your system change (you do design your changes, right?) you need to audit what's out there, determine what's needed to bring it all up to date, and put together a plan to make that happen. It's like documentation and testing -- if you don't make an explicit effort to make it happen, it'll never get done. That sounds like a lot of work, and it is. Luckily, if you're already working in a well-maintained infrastructure you should only really have one existing config to upgrade, which shouldn't be too painful. However, if you've got a lot of machines to change there's no way around the fact that they've all got to be changed, and that can take time. If you accept that you don't want configuration skew, you can start to think about how to engineer your systems and processes to make it less of a hassle to keep everything up to date. Putting some extra thought into how you set things up in the first place so that it's easier to update is at the heart of this. Automating deployment is an easy way to take some of the pain away from rolling out new configs, but there's also plenty of smaller decisions that help with updating configs: putting everything in revision control, making extensive use of templating and pulling out common config fragments, and making sure that you've got good notes and records of what has been done where. The more you automate your deployment and maintenance, the less pain you feel when you need to retrofit. With something like Puppet, you can eliminate a lot of the pain because you're describing what you want done for all the relevant machines, and then the machines themselves work out what needs to be done to bring themselves up to date. With an advanced automation system in place, you can say "I want all my mail servers to have setting X turned on" and off they go and set the option. Or you might want to have some of your mail servers to have a different config setting, triggered based on a config setting or class of machine. Of course, you might not already have that config setting or class defined, so you'll need to add it. Don't forget to retrofit that new config setting or class to your existing machines. That might involve finding the config for all the existing machines and modifying them. Yep, no matter how much automation you've got you can't get away from the need to retrofit, but given the choice between editing a bunch of config files on my local machine (with all the power of my text editor to back me up) or logging into dozens of machines all over the globe to edit their configs and restart services (with all the risks of making a mistake) I know which one I'd choose...

11 June 2008

Christian Perrier: [life] Manu en su casa

Yes, Manu Chao was really home yesterday in Paris Bercy. And he was obviously feeling like being home. The concert began at 21:30 and ended up at 00:30. Yes...that makes 3 full hours concert. All that for 25 euros. The crowd support, dance, participation was *amazing*. I often go to concerts in the Bercy arena and never saw the crowd in the upper rows being stood up all concert long. Radio Bemba played their usual tracks first. As usual, the very Manu way to mix songs, themes from all his carreer and mix them up, distord them and make new songs from old ones. This is what always made Mano Negra, then Manu Chao oncerts unique experiences. Just imagine 20,000 people singing Clandestino a capella, most of us not knowing any damn word of Spanish... After about 2 hours of magic without any stop, the very special moments came in. Manu, Gambit, Majiv (what a guitarist when playing rumbas de Barcelona!), Julio (de Barcelona!)...and all others were just feeling like being home with a few friends. So the encores lasted...and lasted...and lasted. They just didn't want to stop (Manu probably said about 3 or 4 times "c'est fini"). Then, they did something I never ever saw in a big 20,000 people concert since my first one back in....long time ago. Manu asked "do you have 5 more minutes?". So, they stopped for 5 minutes to get the guitars re-accorded(sp?)....the crowd just...waited...and the gig re-started again with songs from "Si Sib rie m' tait cont e", the special book-album he made with friends, inspired by the sad winters he spent in Paris in his early years. Soooooo special and, believe me, that *was* special. Seeing all roadies, crew, friends just dancing backstage and partying clearly showed this was not to always happen (this will probably happen again on today's concert). He was just feeling like home. And so were we. Not wanting to leave and shut down the light. Finally, at 00:30, all of us were dead tired and we just hugged around with Manu and left. Just like old friends. I don't know if that will happen everywhere in the upcoming tour (some dates in France, some in Europe, a few in USA....nothing unfortunately in South America as of now)....but if you have the opportunity to go to Radio Bemba concerts, just do it. And (IRC reference), really, Erinn, this was not about "ethnic music for white people" (really wondering where you got this idea...or if you were just kidding me). I dunno what Manu ever did to kill your ears, but just try again and, even more important, go to the gig in your fair city on August 22nd. Radio Bemba concerts will be cheap, about half the price of regular bug size concerts....just use that opportunity.

Next.

Previous.

