Search Results: "will"

28 October 2008

Ondřej Čertík: Google Mentor Summit III

On Sunday I checked out from the hotel and enjoyed the breakfast, basically the same as the first picture here. Which is cool, the best way to start a day is with a good breakfast in the morning.


At Google I finally met with Bart Massey, who works at the Portland State University where I was an intern (in 2005) and also he was sponsoring one SymPy GSoC student in 2007.


Then we started to port SymPy to Jython with Philip Jenvey. I first installed openjdk-6, which is in Debian main, then checked out Jython svn, typed "ant" and it just worked. This is so awesome, that we finally have a truly opensource and fully working java implementation in Debian. Philip fixed some bugs already, so SymPy imports just fine. Most of the tests run, but also quite a lot still fail.

We managed to isolate two bugs: issue 1158 and 1159. Then there was an annoying recursion bug, that took us several hours to dig into and I then had to leave at 6pm without a clue. But Philip kept saying, I just need to look more at the java stacktraces that Jython was generating and I'll figure it out. And he did! The next morning he filed an issue 412 in the PyPy tracker, because they seem to have the same problem. There are subtle differences in how to handle __mul__ and __rmul__ methods that are not well documented, so it works in CPython but fails in Jython/PyPy. I think we can fix that in SymPy too in the meantime, so I am very excited, because it seems SymPy will work on top of Jython soon.

There was also a git vs hg session with both hg and git developers. Since I recently switched from hg to git for all stuff where I can choose the vcs, it was very interesting for me. And I must say I am glad I switched. Mercurial works fine enough and with the recent rebase feature I think it is usable, but git just has a bigger momentum at the moment and it just doesn't get in my way.

During the day Steve sent an email to the GSoC list that Dirk forgot his jacket in the hotel room, so I said to myself, haha, that's a pity. And then I realized, oh shit, I left my jacket there as well. They didn't have it in the evening when I stopped there, but fortunately they sent me an email yesterday that they found it, so I'll stop there on my way back.

We also took couple of group pictures, here is just my lame attempt (I am sure people will soon post better ones):


On Monday morning I met with Fernando Perez, the author of ipython, he know works with Jarrod. Then I rented a car and came to visit Brian Granger and his family in San Luis Obispo.

We went to the beach in the evening:
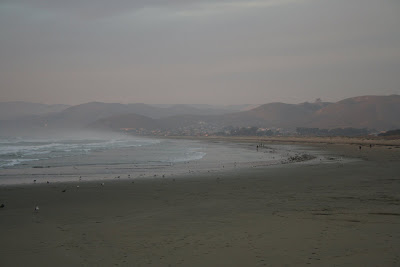


And had a dinner together. Brian showed me his options pricing example he did with SymPy, so I made him create an issue 1175 with the code.
Then we played with the parallel stuff that Brian contributed to ipython and we tried sympy with it and to our disappointment, we found pickling bugs in sympy, it works with protocol 0, but not protocol 2, see the issue 1176 and 1177. This almost smells like a bug in Python itself, but I need to investigate that later more deeply.

Today is Tuesday and we'll work on doing atomic physics calculations with sympy. See also Brian's email to the sympy list about it.

Stefano Zacchiroli: releasing yummy cookies

Cookies, bugs, and releases Christian knows how to be very inspiring and provocative with his blog posts, the APT case is a very good example of how useful that can be. I believe today's post is yet another example of that, many thanks Bubulle! Still, I stopped believing in the incompatibilities among having discussions (possibly heavy, possibly flamish) and releasing. Fact is: The BugSprint has been anticipated well before the inflamatory membership reform proposal, and repeatedly advertised by Joss in various ways (kudos). Still the participation has been way too low. That has nothing to do with other "distractions".

MJ Ray: HOWTO Apache httpd 2.2 PAM Authentication Modules

One consequence of the server outage was that I could finally justify the time to solve an irritating Apache authentication problem. In fact, I had to solve the problem, because I needed to log in to our control panels. (I really love our new control panels, but I wrote them, so I should. I’ll release a new version Real Soon Now. Don’t bother looking for the old version - it’s horribly out-of-date.) The solution had two parts, both related to changes in the Authentication and Access Control of Apache httpd 2.2. In summary, it seems that there are now mod_auth modules which direct authentication (authn) modules and authorisation (authz) or access control modules, and there are some authnz modules which can do both parts. So, the solution: Firstly, mod_authnz_external has become an easier way to do PAM authentication than getting mod_auth_pam to work with the new system. (As an alternative, I could have authenticated directly against the SQL database used by the control panel, but it seems neater to do all authentication through PAM.) So, the modules enabled were auth_basic, authn_file, authz_groupfile, authz_host and authnz_external, but it still gave an error message. Secondly, I found a blog post about the no groups file? error I got then, which suggested re-enabling mod_authz_user. That cured the error, although I don’t yet understand why. The error and the solution don’t seem particularly related. But it works! The above took me about 3 hours of researching, installing, configuring and testing to get working. My guess that it was an awkward job was right. I think TTLLP control panel customers will be glad they’re not paying all of that!

MJ Ray: HOWTO Apache httpd 2.2 PAM Authentication Modules

One consequence of the server outage was that I could finally justify the time to solve an irritating Apache authentication problem. In fact, I had to solve the problem, because I needed to log in to our control panels. (I really love our new control panels, but I wrote them, so I should. I’ll release a new version Real Soon Now. Don’t bother looking for the old version - it’s horribly out-of-date.) The solution had two parts, both related to changes in the Authentication and Access Control of Apache httpd 2.2. In summary, it seems that there are now mod_auth modules which direct authentication (authn) modules and authorisation (authz) or access control modules, and there are some authnz modules which can do both parts. So, the solution: Firstly, mod_authnz_external has become an easier way to do PAM authentication than getting mod_auth_pam to work with the new system. (As an alternative, I could have authenticated directly against the SQL database used by the control panel, but it seems neater to do all authentication through PAM.) So, the modules enabled were auth_basic, authn_file, authz_groupfile, authz_host and authnz_external, but it still gave an error message. Secondly, I found a blog post about the no groups file? error I got then, which suggested re-enabling mod_authz_user. That cured the error, although I don’t yet understand why. The error and the solution don’t seem particularly related. But it works! The above took me about 3 hours of researching, installing, configuring and testing to get working. My guess that it was an awkward job was right. I think TTLLP control panel customers will be glad they’re not paying all of that!

27 October 2008

Joey Hess: I voted

I voted early because Sullivan County, TN is phasing in new voting machines this election. On election day, they will use the old touch screen system, while early voters get to test the "new" paper system. The new system is sure to please fans of paper. However, it has two flaws that were obvious to me. I have no way of knowing that my vote will be counted as I filled it out, and I realized half way through that election officials can determine how I voted. Here's why... You have two pieces of paper during the vote. A registration sheet is signed by the voter. A paper ballot has little rectangles that the votor fills in with a ballpoint pen in the privacy of the voting booth. The instructions say to fill in choices completely. Since the voting booths have a hard top, it's difficult to write on them with a ballpoint, let alone fill in little squares completely. The natural thing to do? Slide your second piece of paper under the ballot, so the pen can dig in better. If you don't think about it, you'll probably do this unconciously. Half-way through, I realized that I was leaving imprints on the registration paper, with my name on it, that corresponded to my choices on the ballot. Due to the two-column layout, and the distinctive spacing between different choices, it's possible to look at those imprints and determine exactly how I voted. The registration paper has to be handed in at the end, so the official who sits there all day collecting these has plenty of time to work this out and determine the votes of anyone. (I moved my ballot around and re-filled in squares to try to confuse things.) (Relatedly, one has to carry the paper ballot around the room to take it to the voting machine. It's difficult to keep the ballot obscured while doing this, since you can't fold it, and since they take the registration paper before the ballot, so you can't keep the ballot covered with it either.) The second obvious flaw is that once I fed my ballot into the voting machine, which presumably scanned it and put it in a safe, there was only a confimation that "you've voted!". There was no way to verify that it had counted my vote as I'd marked it.
Most voting system work seems to be in the direction of advocating paper ballots for paper ballots' sake. This doesn't seem like the right approach to me. Is no-one working on writing down the characteristics that an ideal voting system would have, and trying to make them all requirements? My take on requirements of an ideal voting system are:
  1. Only living people in the set of registered voters may vote.
  2. Each votor can only vote once.
  3. The votor should be able to verify that his vote was counted correctly.
  4. There must be a way for the votor to prove if his vote was not counted.
  5. The votor must not be able to prove which way he voted (to avoid payoffs, intimidation, etc).
  6. Others must not be able to determine how a votor voted.
  7. Individual votes must be retained to allow recounts.
  8. The entire vote data should be published so that the results can be verified by third parties.
  9. The system must scale to many millions of voters.
  10. The correctness of the entire voting system should be formally provable.
The paper ballot system I experienced today fails on at least points #2 [A] , #3 (see above), #4 (I walked away with nothing I can use to prove anything), #5 (I can video my vote), #6 (see above), and #8 [B]. At least it scales well though. The old touch screen system failed most of the same points, though it made at least a small attempt to satisfy #3 (by confirming the vote onscreen) -- and it failed #7, and probably scaled worse. Outside of the American election system, I've participated in voting systems that seem able meet requirements #1 [C], #2, #3, #4, #7, #8, and #10. To me, #10 is the most important point, but it seems to be the one that is neglected most. Some of the points may be worth weakening if they block other points. Is it really worth avoiding giving me something to prove how I've voted, and banning taking cameras into the polling place, in order to meet point #5, if this defeats point #4? I'm curious what requirments I may have left out too. My list is just a rough stab at it. The real point is to analyze voting systems, and reject ones that don't provably meet criteria. Until it becomes accepted practice to do that, our voting systems will not get appreciably less flawed.
[A] If you can get two copies of the ballot, you can vote twice ... fairly easy with a friend on the inside to arrange for the two copies to get "stuck together", and another one at the vote scanner to allow you to scan both. [B] The ballots could be published, but there's no way to prove all of them, or the true ballots would be. And in reality, they're either shredded, or locked away, or tossed in a dumpster, or variously all three. [C] Mostly. Perfectly accomplishing #1 is harder than most of the other points, and may be worth leaving out of scope.

Mark Brown: Getting kernel support

[This is a slight modification of something I posted to the alsa-devel list earlier today.] One of the biggest surprises that people starting to use Linux seem to run into is that you can’t rely on any particular support level from the community - everything is done on a voluntary basis and the responses will depend on a range of factors, including things like how busy the people involved are. People moving to Linux for reasons other than freedom, particularly those using it commercially, often don’t seem to notice this distinction. You can normally help getting a response by providing as much information as possible about your problem and the steps you have taken to resolve it - this makes it very much easier for people to reply since, for example, it’s more likely that something will jump out at them. These web pages contain some suggestions on the sorts of thing to do in your e-mail to help get the best response: How to ask questions the smart way
How to report bugs effectively (this is targeted at end users more than developers). With the kernel community it can also help to send direct copies of your mail to people who have worked on the relevant code since people may either miss postings on mailing lists (there is often a lot of traffic) or in some cases not be subscribed to the lists at all. This doesn’t apply to all free software projects - you should check the normal standards for a given project before doing this. If you need guaranteed responses or more detailed responses than you are able to obtain from the community the usual approach is to work with people with whom you have a commercial relationship - for example, your chip or software vendors, or consultants you have employed.

Raphaël Hertzog: Debian membership reform

Following Ganneff’s post to debian-devel-announce, several discussions have again started on the topic of Debian’s membership and several proposals have been made. Unfortunately none of these proposals try to resolve the underlying trust problem that has been growing over the years. Despite the NM process (or maybe due to it), we managed to give DD status to people who are motivated but whose technical skills are doubtful (at that point people ask for an example, and as much as I hate fingerpointing, here’s an example with #499201. The same maintainer created troubles with libpng during the etch release cycle and tried to take over a base package like mawk recently). With our current model, all DD can sponsor, NMU, introduce/adopt/hijack packages without review. This is fine as long as we trust the body of DD to contain only skilled and reasonable people. I believe that premise to be somewhat broken since Debian has become too big for people to know everybody and since the NM process had no way to grant partial rights to volunteers who were motivated but that clearly had not shown their ability to handle more complex stuff than what they had packaged during their NM period (like some trivial perl modules for example). Thus I strongly believe that any membership reform must provide a convincing answer to that trust problem before being implemented. I took several hours to draft a proposal last Friday and I’ve been somewhat disappointed that nobody commented on it. I hope to draw some attention on it with this blog post. The proposal builds on the idea that we should not have classes of contributors but simply two: a short-term contributor and a long-term contributor (those are called Debian Developers and have the right to vote). But all contributors can be granted privileges as they need them for their work and each privilege requires the contributor to fulfill some conditions. The set of privileges and the conditions associated all need discussions (but I have personal opinions here, see below). There’s however one privilege that is somewhat particular: it’s the right to grant privileges to other contributors. Handling it as a privilege like another is on purpose: it makes it clear that anyone can try to get that privilege and the procedure is clear. In practice, imagine that set of people as a big team encompassing the responsibilities split over DAM/AM/FD/DM-team and where all members can do all the steps required to grant/retire a privilege provided that 2 or 3 members agrees and that nobody opposes (in case of opposition a specific procedure is probably needed). I called that set of people the Debian Community Managers. It should contain only skilled and dedicated developers. One of their main duties would be to retain the trust that the project as a whole must have in all its members. They would have the powers to retire privileges if they discover someone that has not acted according to the (high) expectations of the project. Among the privileges would be limited upload rights (like DM have currently), full upload rights (like DD have currently although it might be that we want to split that privilege further in right to sponsor, right to package new software, right to maintain a package of priority > standard, etc.) and developer status (email + right to vote, once you can prove 6 months of contribution). There’s lots of stuff to discuss in such a proposal (like how to decide who gets what privileges among existing DD) but I think it’s a good basis and need some serious consideration by all the project members. The NM process is there only so that we can collectively trust that new members are as good as we expect them to be and trust can only be built over time so it’s good that we can grant privileges progressively. Some people believe that I’m reinventing a new NM process that will end up to be very similar to the current one. My answer is that the conditions associated to each privilege should be based on the work done by the contributor and the advocations that he managed to collect. It should not be a questionnaire like Task and Skills . This, together with the distribution of the power/work on many people, would render this system very different from today’s NM process. Some people believe that I’m copying Ubuntu when designing this since it’s somewhat similar to the process to become MOTU and/or get upload right to Ubuntu’s main component. Let me say that I’m not copying deliberately at least, I simply took the problem from the most important side. But remember that many aspects of Ubuntu have been designed by Debian developers that tried to avoid known pitfalls of Debian, and maybe they got some things right (or better at least) while doing this. Partagez cet article / Share This

Colin Watson: Totem BBC plugin

A while back, the BBC approached Canonical about providing seamless access to unencumbered BBC content for all Ubuntu users (in the UK and elsewhere). We agreed to approach this by way of a plugin for our primary media player, Totem, and asked Collabora Multimedia to do the plugin development work. The results are in what will shortly be released as Ubuntu 8.10, and are looking really rather good. At the moment the content available from the BBC at present is mostly audio, but support for video is in place and the feed is expected to be fleshed out here over time. We have a genre classification scheme in place, and will see how that scales as the amount of available content grows. The code has been submitted upstream, although there are still a few issues to work out there. This is not the same thing as iPlayer; all the content available here is DRM-free. Some of it is geographically restricted to the UK, and these restrictions are handled on the server side to make sure that the client is free of encumbrances. Christian Schaller from Collabora posted about this a little while ago. Since then, the UI has been improved somewhat and some I/O issues have been fixed to the point where we felt comfortable enabling the BBC plugin (as well as the YouTube plugin) by default in Ubuntu 8.10. Here's a screenshot of the current interface. This is exciting stuff with a lot of potential. To try it out, run Applications -> Sound & Video -> Movie Player and select the "BBC" entry from the drop-down box labelled "Playlist". If you find bugs, please report them!

MJ Ray: We Need Social Network Networks

A recent project was to install a Wordpress plugin that will announce new articles to Twitter. As you might guess, I’m not a big fan of Twitter, or any other closed-source Web 2.0 thing. I use a few social network things, but not Twitter at present because I don’t really want yet another login. So, I decided to solve a more general problem of status updates by using ping.fm and updating a wordpress plugin to work on PHP 4, as well as 5. I know PHP 4’s end-of-life is nigh but the target server still runs it for the forseeable future. While waiting for API key approval, on the same day as our server hiccough, GoDaddy broke ping.fm which broke the communication. Now, while I could set up two ping.fm-like update services to avoid the single point of failure at a closed service, but that would mean that any updates would appear twice. Alternatively, some of the Twitter-like services can be told to watch the Wordpress blogs for updates, but each one would need to be configured in a different way. Finally, there’s already a problem of redundancy and context with ping.fm which makes Adam Darowski and others hate it. Can we solve this? Can we get support for the NoseRub protocol into everything and make a social network network? Will good things come out of the W3C Workshop on the Future of Social Networking, 15-16 January 2009 in Barcelona? Is the ultimate solution to junk all the closed social networks? I wish I knew. In the meantime, at least it keeps me in work, hacking plugins, connecting stuff together. It’s bloody annoying sometimes, though. It seems like a Web 2.0 version of having a carpet that’s too small for the room, so you never get the whole floor covered at once.

MJ Ray: We Need Social Network Networks

A recent project was to install a Wordpress plugin that will announce new articles to Twitter. As you might guess, I’m not a big fan of Twitter, or any other closed-source Web 2.0 thing. I use a few social network things, but not Twitter at present because I don’t really want yet another login. So, I decided to solve a more general problem of status updates by using ping.fm and updating a wordpress plugin to work on PHP 4, as well as 5. I know PHP 4’s end-of-life is nigh but the target server still runs it for the forseeable future. While waiting for API key approval, on the same day as our server hiccough, GoDaddy broke ping.fm which broke the communication. Now, while I could set up two ping.fm-like update services to avoid the single point of failure at a closed service, but that would mean that any updates would appear twice. Alternatively, some of the Twitter-like services can be told to watch the Wordpress blogs for updates, but each one would need to be configured in a different way. Finally, there’s already a problem of redundancy and context with ping.fm which makes Adam Darowski and others hate it. Can we solve this? Can we get support for the NoseRub protocol into everything and make a social network network? Will good things come out of the W3C Workshop on the Future of Social Networking, 15-16 January 2009 in Barcelona? Is the ultimate solution to junk all the closed social networks? I wish I knew. In the meantime, at least it keeps me in work, hacking plugins, connecting stuff together. It’s bloody annoying sometimes, though. It seems like a Web 2.0 version of having a carpet that’s too small for the room, so you never get the whole floor covered at once.

26 October 2008

Christian Perrier: I'm already hearing the laughs...

...of my friends, workmates and colleagues, when I will have to try to explain them that, no, I have no bloody idea of when Debian will release. Mostly because: The project is currently heavily frozen. Our bug report rate during last month was 3000bugs, to be compared to the 5000 bugs/month ratio of the normal development process. So, yes, I'm already hearing the laughs about the trust that can be put in Debian. At some point, we should remember that even our technical excellence will not prevent us from people looking elsewhere for something serious to work with. Again, prove me wrong. Release the damn installer. Stop this nonsense about the so-called freeness of whatever bit in Debian. Postpone the discusion about contributors/maintainers/developers. Release the thing. By the way, thanks to Joss for the cookies contest. From what I've seen during the week-end, it was very successful. And, un surprisingly, those working on it were those not wasting their time in silly games. Ah, and I fixed an RC bug this week-end, too...

Chris Lawrence: Inside baseball

I’ve been remiss in pointing my readers recently to Zachary Schrag’s Institutional Review Blog, which patiently documents the overreach and misapplication of federal regulations regarding the protection of human subjects to the social and behavioral sciences, including research that by federal regulation is exempt from review by IRBs. While Schrag is cautiously optimistic that the new head of the Office of Human Research Protections will be an improvement, the continued domination of the process at most levels by biomedical researchers—along with the general sense that, as Schrag notes, “researchers cannot be trusted to apply the exemptions themselves”—is still troubling to those of us who want to conduct human subjects research, particularly secondary data analysis. Technically speaking (even though I dare say most social scientists observe this requirement in the breach), even the analysis of secondary data collected by others and fully anonymized before we see it (e.g. use of data such as the General Social Survey, American National Election Studies series, the Eurobarometer series, etc.) requires IRB oversight and approval beforehand.

Joerg Jaspert: Archiving sarge AKA oldstable

And finally I started to move our good old release sarge to archive.debian.org. It will actually be visible there whenever it is completly synced, but rsync is running. Tomorrow I will delete the sarge parts in dists/ for ftp.debian.org (and its mirrors) and in the next days all the associated source and binary packages will slowly get moved out of the mirror. Im using a scheme that tells dak to delete about 1000 source packages on one day only, to not have too many files to delete at once. While that will make up a few thousand files going away at once (after the usual deletion delay), it should be under normal deletion limits mirrors have. (The Debian internal mirroring scripts do stop deletions if more than 40000 files are killed.) While doing this, I’m also finally archiving sarge-backports and sarge-amd64. Both will be archived on archive.debian.org too, for the simple reason that both have been very near to Debian. sarge-amd64 for example had security support and backports will, at some not too distant point, surely exist behind backports.debian.org. Comments: 0

Sean Finney: ps3-kboot for debian

now that ps3-utils is packaged, and it seems spufs didn't take much to get to work, i'd like to turn back to the installation procedure, which was admittedly manual and not exactly as "seamless" as i think it could be. the first step as i see it is to get the bootloader working both generally and also specifically for the installer. by "working", i mean the following: the third of these being the most complicated, as will be detailed below. how a linux (kboot) "otheros" bootloader works on the ps3 okay, so i'm not intimately familiar with the powerpc architecture, nor with all the details of cross-compilation, but this is as much as i can tell. how kboot can be used on the installer including support for this "otheros.bld" bootloader on the installer is fairly easy from a technical point of view, whether it's a usb disk or netinst cdrom image. basically, in either case the media should have a directory called "ps3/otheros", in which the file is placed and named "otheros.bld". when running the PS3 in game-os mode, this is where it looks when you tell it to "scan for otheros". how kboot can be used/maintained, generally speaking beyond a kboot.conf file, nothing really needs to be done on the host os to use kboot. of course, it would be nice to be able to issue updates for an image, which should be possible with a package that makes use of ps3-flash-util from the ps3-utils package. nothing too difficult/complicated there. how kboot can be used/built within debian this is the tricky part. in additional to the standard Free Software guidelines which debian is so (in)famous for following, we also have some basic QA rules that are needed from a distribution release management / security perspective. one of these rules is that generally speaking it is considered taboo to include embedded copies of other software within a package, if that software is already available in debian. for example, i don't think it's very likely that the ftp-masters will look very kindly on some new software package that includes a copy of the entire kernel source tree, the gcc compiler, (uc)libc, busybox, coreutils, udev, etc. it may be that a certain subset will require special patches, in which case some convincing/justification will be in order, but for the big ones (i.e. the kernel) there will almost certainly need to be modifications made. ps3-kboot in ubuntu there are already source packages available for ps3-kboot in ubuntu. apart from the fact that i can't stand working with packages that use cdbs, this package can't be used because the package maintainers' solution to the previously mentioned problem is basically to ignore that it exists. it also seems that there's quite a bit of customization in this source package with respect to the initrd generation, which is probably worth some review... so i will likely still use this package as a base point of reference.

Ondřej Čertík: Google Mentor Summit II

On Saturday morning I met Steve McIntyre and Dirk Eddelbuettel, Steve took us by car to Google. Well, it was overwhelming.

For example we met there two other Debian developers, Jeff Bailey and Daniel Burrows. There are developers from all the famous projects, like git, Wine, Turbogears, Jython, ... There are still people I wanted to meet but didn't manage yesterday, need to fix that today. My plan is to get SymPy running on top of Jython, or at least do some more progress to take the advantage, that Philip Jenvey from Jython is here. Also I wanted to fix some RC bugs in Debian when Steve is here, to make some progress on my NM finally. We'll see how it goes.

There was also an excellent presentation from people behind Android. One thing I was curious if it's going to run native C applications, like Python and it seems it will happen eventually, all the sources are out there, so someone just needs to push it forward. Another very cool thing they did that I was always looking for is Gerrit for reviewing patches (see review.source.android.com for example how it looks like) -- basically a fork of Guido's codereview, but it has many nice features, like automatically applying the patch to the git repository as a new topic branch and one can then easily pull it, as well as review it over the web interface. When I get back to Prague I am going to install this for SymPy.

Russell Coker: Links October 2008

Here’s a blog post suggesting that anti-depressant drugs such as Prozac may have helped the US mortgage crisis [1]. Apparently such drugs cause poor impulse control, so it wouldn’t be a good idea to attend a house auction while using them. Here’s an interesting idea about lecturing, give 20 minute talks with something else (practical work or group discussion) in between [2]. Michael Lee wants to “capture the power of that strict time limit, the intensity of a well-crafted 20 minutes”. While I’m not sure that a strict time limit is such a great idea. Having talks broken up into sections sounds like it has the potential to offer some benefits. A bible from the 4th century has been found and is being digitised [3]. When the digitisation is complete (next year) it will be published on the net so everyone can see how the bible has changed over the years. Interesting interview with Jim Gray (of MS Research) about storage [4]. It was conducted in 2003 so technology has moved on, but the concepts remain. His ideas for sharing two terabytes of data by using a courier to deliver an NFS or CIFS file server are interesting, the same thing could be done today with five terabytes for a lower cost. Techtarget has a white paper sponsored by Intel about the price/performance of data centers in low-density and high-density designs [5]. I don’t think I’ll ever be in a position to design a data center, but the background information in the paper is very useful. Google has an interesting set of pages describing their efforts to save power in their data centers [6]. They claim to have the most efficient server rooms ever built, and describe how it saves them a lot of money. One of the interesting things that they do is to use evaporative cooling as the primary cooling method. They also have a RE<C (Renewable Energy cheaper than Coal) project [7]. Here’s a Youtube video of an interesting presentation by Andy Thomson (a psychiatrist at the University of Virginia) about male-bonded coalitionary violence [8]. He shows the evidence of it in chimpanzees, humans, and evidence for it being in the common ancestry of chimps and humans (5-6 million years ago). He also shows a link to modern suicide bombing. It’s widely regarded that Cyrus is the fastest IMAP server. Linux-Magazin.de published an article last year comparing Cyrus, UW-IMAP, Dovecot, and Courier and the conclusion is that Courier and Dovecot are the winners [9]. I used Google Translation but the results were not particularly good so I think I missed some of the points that they were trying to make.

25 October 2008

Ben Armstrong: Wifi roaming on the move

Preface: legal stuff Depending on where you live, use of random open wifi networks might be considered illegal. Although I know of no law in my country against doing this, where you live, things may be different, so educate yourself before following my example. Wifi roaming on the move For the past year I have used my Eee PC on the metro transit bus, as it is the perfect size for this. When I can, I take advantage of open networks to connect back home. In this article I will show how you can actually use such access, will recommend which software works best and will explain how to set it up. So, what can I really do with the net while in motion? How about irc? No kidding! This shell one-liner does the job:
while ! ssh -t 10.9.8.7 'screen -UDr' 2>/dev/null ; do echo -n "." ; sleep .1 ; done
We’re concerned about privacy and security on other people’s networks, so we use ssh. Inside that screen session, keep irssi running for a continuous irc presence. Every 10th of a second, the script tries to resume your session. Once a the net passes by, typing “[Enter]~.” drops you back out to retry again. The row of dots serves as a progress bar. If you want to get fancy, you could replace that with an ASCII ‘spinner’. I leave that as an exercise for the reader. :) Come on, is that really usable? Certainly. As the good folks on #eeepc at irc.freenode.net and #debian-eeepc at irc.oftc.net can attest, even a half dozen brief connections can be enough to provide tech support, rough out some development ideas, or just carry on some friendly chat. If your spouse or housemate is online too, it can even help you make some last-minute grocery-list changes. :) While the script is working, enjoy some offline things such as blogging, reading a cached Planet Debian feed or a PDF book. OK, so what else do I need to make it work? Well, you’ve seen so far we need on a server: On the Eee, you should also have: But what do I need wpasupplicant for if I only use open networks? Well, wpasupplicant is really handy for fast control of networks in Roaming Mode (as per /usr/share/doc/wpasupplicant/README.modes.gz). A GUI is just too slow. For example, you may need to filter out ‘junk’ open wifi nets: pay-per-use hotspots or nets that hide their name. You’ll not only want a “catch-all” stanza for any open network, but also a number of the most commonly found default network names, e.g.
# Catch-all; associates with any open network:
network= 
     key_mgmt=NONE
 
# Commonly found default network names:
network= 
     ssid="default" 
     key_mgmt=NONE
 
network= 
     ssid="linksys" 
     key_mgmt=NONE
 
# etc. by watching scan_results closely you'll find several more
While the connect script is running, keep a separate tab open in gnome-terminal for wpa_cli. Use ‘disable_network 0’ to drop the catch-all and let the other stanzas kick in and ‘enable_network 0’ after filtering is no longer needed. Isn’t it really slow to get connected? Without some tweaks, yes. But here are a few things I have found by trial and error that help. One issue is that dhclient takes too long to retry, so you drop the delay between retries back to 1 second in /etc/dhcp3/dhclient.conf:
backoff-cutoff 1;
initial-interval 1;
If the signal is very weak, you’ll want the transmit power turned up to the maximum value for your hardware. For the Eee PC 4G this is 50mW, so you set this in /etc/network/interfaces for ath0, your wireless interface:
wireless-txpower 50mW
Finally, while you’re in motion you are constantly leaving no-longer-usable access points behind. The driver needs to discard them as quickly as possible and scan for new ones. So again in /etc/network/interfaces for ath0, you bring the default scanvalid 60 seconds down to 10 with:
pre-up /sbin/iwpriv ath0 scanvalid 10
Conclusion The netbook has changed how we use the net. Now that we can take it everywhere, we either pay through the nose for expensive cell network access or else use the patchy wifi coverage blanketing most urban areas. A few lucky cities have such things as municipal wifi nets, but the rest of us have to scrape what access we can wherever we go. You are now equipped to try this out on the bus. If you find any other tips that can help, I’d love to hear from you.

Julian Andres Klode: aufs 0+20081023-1 uploaded to experimental


I just uploaded a new upstream snapshot of aufs (another unionFS) to experimental. But it is really more than just a new upstream snapshot: First of all, this release includes patches written by Jeff Mahoney <jeffm@suse.com>. These patches enable the usage of NFSv2 and NFSv3 file systems as branches, even on the standard Debian kernel. The package does not support NFSv4 yet, but will support it at a later point (but only with a patched kernel) - the code exists, it’s just not enabled yet. This release also removes support for pre-lenny Kernels (<2.6.26) and uses quilt instead of dpatch. It also removes any AppArmor support for the moment, but this may be added back later. Posted in Debian      

David Welton: Slicehost + Ubuntu Intrepid Upgrade

As I wrote previously, I started looking around for a new hosting provider, as Layered Tech is jacking up their prices too much. This isn't something I consider 'fun', as it will involve a lot of time swapping things over, with the potential for problems, but the amount of money disappearing every month is too much to ignore at this point. After some dithering, I finally went ahead and spent some money for a minimal slice at Slicehost. Linode seems pretty competitive too, but I more or less flipped a mental coin. I was actually ready to go ahead the other day, but I stopped to think some more after seeing that Slicehost has been acquired by Rackspace. In terms of seeing hard working people rewarded for their efforts, I am of course happy for the guys at Slicehost, but it also leaves a few questions: Of course, good things could come out of the deal too, so I decided to put my paranoia aside and test the waters. There are a lot of things to like about a system like Slicehost's: it's relatively quick and easy to set up new slices, fiddle with the resources that each slice has, and so on, compared with a physical server. Furthermore, they have a reputation for not 'overbooking' their servers, which is why I wanted to get away from a VPS in the first place, many years ago. Setting up a slice was very quick and easy, but unfortunately got off to a rough start: their "fraud detection" system had a problem with me being in a different place than my billing address. Luckily, they were very fast at correcting the problem. As an aside, I think that fraud detection is probably best left to the credit card companies, although of course I don't really know their business, so maybe that particular check has saved them some money/frustration in the past. Upgrading the Slicehost Ubuntu to Intrepid In any case, once I got it up and running, I wanted to test out the upgrade to Intrepid, as that's going to be out in less than a week, and I might as well upgrade while I have 'fresh' servers to play with, and prior to installing a bunch of stuff. It went very well. I did a do-release-upgrade -d, hit 'yes' to everything, rebooted, and everything was fine! Admittedly, I don't have anything running on the server yet, so that kept things short and sweet, and didn't require the upgrade of various systems which might have had troubles, but so far so good If you'd like to sign up for Slicehost, it looks like they give you a referral code. Mine can be utilized by going here.

Jose Carlos Garcia Sogo: Blackerry in Debian

I have uploaded barry package to Debian some hours ago. It is still waiting for NEW processing, so if you want it you will have to download sources from Debian git repo, and compile the package yourself. It has just been accepted into the archive. Barry is a GPL program that will allow you to charge your Blackberry through the USB port, to make backup copies of your device databases, manage contacts and use your BB as a modem. So if you have a BlackBerry device, you can also enjoy it in Debian. Update 26/10/2008: Barry has just been accepted into the archive, so you can get it in every Sid repository mirror. Thanks!

Next.

Previous.