Search Results: "spa"

12 December 2022

Vasudev Kamath: Installing Debian from GRML Live CD

I had bought a Thinkpad E470 laptop back in 2018 which was lying unused for quite some time. Recently when I wanted to use it, I found that the keyboard is not working, especially some keys and after some time the laptop will hang in Lenovo boot screen. I came back to Bangalore almost after 2 years from my hometown (WFH due to Covid) and thought it was the right time to get my laptop back to normal working state. After getting the keyboard replaced I noticed that 1TB HDD is no longer fast enough for my taste!. I've to admit I never thought I would start disliking HDD so quickly thanks to modern SSD based work laptops. So as a second upgrade I got the HDD removed from my laptop and got a 240G SSD. Yeah I know its reduction from my original size but I intend to continue using my old HDD via USB SATA enclosure as an external HDD which can house the extra data which I need to save. So now that I've a SSD I need to install Debian Unstable again on it and this is where I tried something new. My colleague (name redacted on request) suggested to me use GRML live CD and install Debian via debootstrap. And after giving a thought I decided to try this out. Some reason for going ahead with this are listed below
  1. Debian Installer does not support a proper BTRFS based root file system. It just allows btrfs as root but no subvolume support. Also I'm not sure about the luks support with btrfs as root.
  2. I also wanted to give a try to systemd-boot as my laptop is UEFI capable and I've slowly started disliking Grub.
  3. I really hate installing task-kde-desktop (Yeah you read it right, I've switched to be a KDE user for quite some time) which will pull tons of unwanted stuff and bloat. Well it's not just task-kde-desktop but any other task-desktop package does similar and I don't want to have too much of unused stuff and services running.
Disk Preparation As a first step I went to GRML website and downloaded current pre-release. Frankly, I'm using GRML for first time and I was not sure what to expect. When I booted it up I was bit taken a back to see its console based and I did not have a wired lan just a plain wireless dongle (Jiofi device) and was wondering what it will take to connect. But surprisingly curses based UI was pretty much straight forward to allow me to connect to Wifi AP. Another thing was the rescue CD had non-free firmware as the laptop was using ath10k device and needed non-free blobs to operate. Once I got shell prompt in rescue CD first thing I did was to reconfigure console-setup to increase font size which was very very small on default boot. Once that is done I did the following to create a 1G (FAT32) partition for EFI.
parted -a optimal -s /dev/sda mklabel gpt
parted -a optimal -s /dev/sda mkpart primary vfat 0% 1G
parted -a optimal -s /dev/sda set 1 esp on
mkfs.vfat -n boot_disk -F 32 /dev/sda1
So here is what I did: created a 1G vfat type partition and set the esp flag on it. This will be mounted to /boot/efi for systemd-boot. Next I created a single partition on the rest of the available free disk which will be used as the root file system. Next I encrypted the root parition using LUKS and then created the BTRFS file system on top of it.
cryptsetup luksFormat /dev/sda2
cryptsetup luksOpen /dev/sda2 ENC
mkfs.btrfs -L root_disk /dev/mapper/ENC
Next is to create subvolumes in BTRFS. I followed suggestion by colleague and created a top-level @ as subvolume below which created @/home @/var/log @/opt . Also enabled compression with zstd and level of 1 to avoid battery drain. Finally marked the @ as default subvolume to avoid adding it to fstab entry.
mount -o compress=zstd:1 /dev/mapper/ENC /mnt
btrfs subvol create /mnt/@
cd /mnt/@
btrfs subvol create ./home
btrfs subvol create ./opt
mkdir -p var
btrfs subvol create ./var/log
btrfs suvol set-default /mnt/@
Bootstrapping Debian Now that root disk is prepared next step was to bootstrap the root file system. I used debootstrap for this job. One thing I missed here from installer was ability to preseed. I tried looking around to figure out if we can preseed debootstrap but did not find much. If you know the procedure do point it to me.
cd /mnt/
debootstrap --include=dbus,locales,tzdata unstable @/ http://deb.debian.org/debian
Well this just gets a bare minimal installation of Debian I need to install rest of the things post this step manually by chroot into target folder @/. I like the grml-chroot command for chroot purpose, it does most of the job of mounting all required directory like /dev/ /proc /sys etc. But before entering chroot I need to mount the ESP partition we created to /boot/efi so that I can finalize the installation of kernel and systemd-boot.
umount /mnt
mount -o compress=zstd:1 /dev/mapper/ENC /mnt
mkdir -p /mnt/boot/efi
mount /dev/sda1 /mnt/boot/efi
grml-chroot /mnt /bin/bash
I remounted the root subvolume @ directly to /mnt now, remember I made @ as default subvolume before. I also mounted ESP partition with FAT32 file system to /boot/efi. Finally I used grml-chroot to get into chroot of newly bootstrapped file system. Now I will install the kernel and minimal KDE desktop installation and configure locales and time zone data for the new system. I wanted to use dracut instead of default initramfs-tools for initrd. I also need to install cryptsetup and btrfs-progs so I can decrypt and really boot into my new system.
apt-get update
apt-get install linux-image-amd64 dracut openssh-client \
                        kde-plasma-desktop plasma-workspace-wayland \
                        plasma-nm cryptsetup btrfs-progs sudo
Next is setting up crypttab and fstab entries for new system. Following entry is added to fstab
LABEL="root_disk" / btrfs defaults,compress=zstd:1 0 0
And the crypttab entry
ENCRYPTED_ROOT UUID=xxxx none discard,x-initrd.attach
I've not written actual UUID above this is just for the purpose of showing the content of /etc/crypttab. Once these entries are added we need to recreate initrd. I just reconfigured the installed kernel package for retriggerring the recreation of initrd using dracut. .. Reconfiguration was locales is done by editing /etc/locales.gen to uncomment en_US.UTF-8 and writing /etc/timezone with Asia/Kolkata. I used DEBIAN_FRONTEND=noninteractive to avoid another prompt asking for locale and timezone information.
export DEBIAN_FRONTEND=noninteractive
dpkg-reconfigure locales
dpkg-reconfigure tzdata
Added my user using adduser command and also set the root password as well. Added my user to sudo group so I can use sudo to elevate privileges.
Setting up systemd-boot So now basic usable system is ready last part is enabling the systemd-boot configuration as I'm not gonna use grub. I did following to install systemd-boot. Frankly I'm not expert of this it was colleague's suggestion. Before installing the systemd-boot I had to setup kernel command line. This can be done by writing command line to /etc/kernel/cmdline with following contents.
systemd.gpt_auto=no quiet root=LABEL=root_disk
I'm disabling systemd-gpt-generator to avoid race condition between crypttab entry and auto generated entry by systemd. I faced this mainly because of my stupidity of not adding entry root=LABEL=root_disk
apt-get install -y systemd-boot
bootctl install --make-entry-directory=yes --entry-token=machine-id
dpkg-reconfigure linux-image-6.0.0-5-amd64
Finally exit from the chroot and reboot into the freshly installed system. systemd-boot already ships a hook file zz-systemd-boot under /etc/kernel so its pretty much usable without any manual intervention. Previously after kernel installation we had to manually update kernel image in efi partitions using bootctl
Conclussion Though installing from live image is not new and debian-installer also does the same only difference is more control over installation and doing things which is installer is not letting you do (or should I say is not part of default installation?). If properly automated using scripts we can leverage this to do custom installation in large scale environments. I know there is FAI but I've not explored it and felt there is too much to setup for a simple installations with specific requirements. So finally I've a system with Debian which differs from default Debian installation :-). I should thank my colleague for rekindling nerd inside me who had stopped experimenting quite a long time back.
11 December 2022

Vincent Bernat: Akvorado: a flow collector, enricher, and visualizer

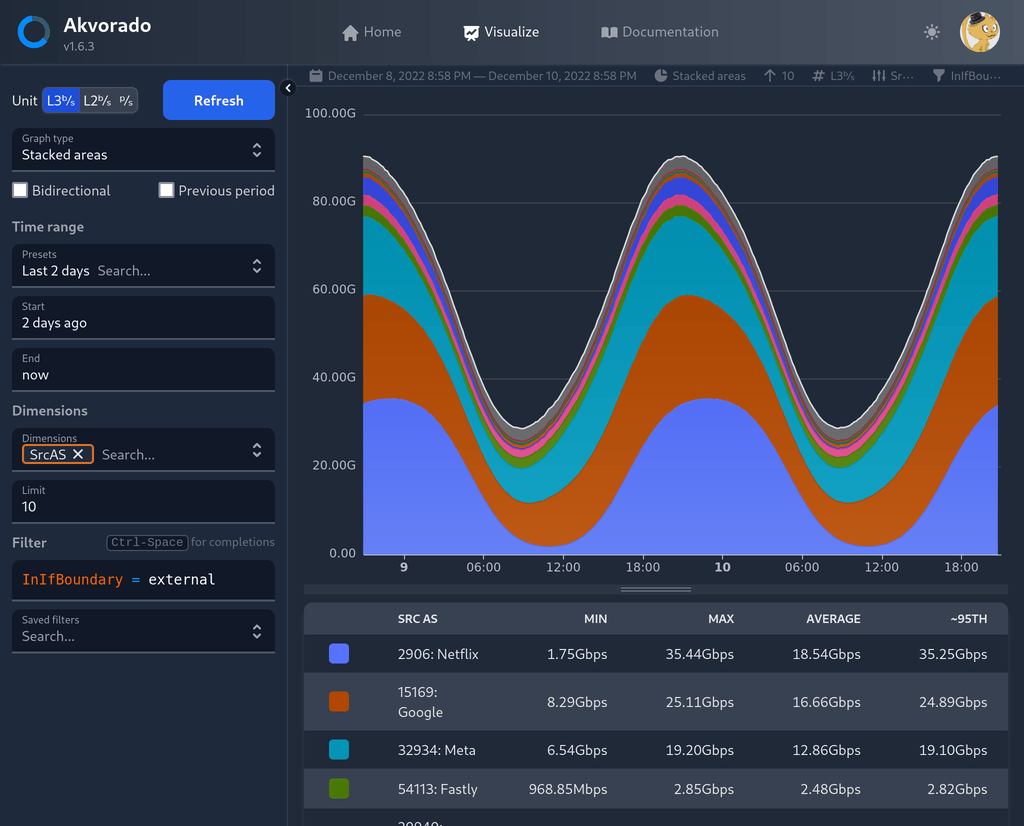
Earlier this year, we released Akvorado, a flow collector, enricher, and visualizer. It receives network flows from your routers using either NetFlow v9, IPFIX, or sFlow. Several pieces of information are added, like GeoIP and interface names. The flows are exported to Apache Kafka, a distributed queue, then stored inside ClickHouse, a column-oriented database. A web frontend is provided to run queries. A live version is available for you to play.
Akvorado web interface displays the result of a simple query using stacked areas
Akvorado s web frontend
Several alternatives exist: Akvorado differentiates itself from these solutions because: The proposed deployment solution relies on Docker Compose to set up Akvorado, Zookeeper, Kafka, and ClickHouse. I hope it should be enough for anyone to get started quickly. Akvorado is performant enough to handle 100 000 flows per second with 64 GB of RAM and 24 vCPU. With 2 TB of disk, you should expect to keep data for a few years. I spent some time writing a fairly complete documentation. It seems redundant to repeat its content in this blog post. There is also a section about its internal design if you are interested in how it is built. I also did a FRnOG presentation earlier this year, and a ClickHouse meetup presentation, which focuses more on how ClickHouse is used. I plan to write more detailed articles on specific aspects of Akvorado. Stay tuned!

  1. While the collector could write directly to the database, the queue buffers flows if the database is unavailable. It also enables you to process flows with another piece of software (like an anti-DDoS system).

Russ Allbery: Review: The Fifth Elephant

Review: The Fifth Elephant, by Terry Pratchett
Series: Discworld #24
Publisher: Harper
Copyright: 2000
Printing: May 2014
ISBN: 0-06-228013-9
Format: Mass market
Pages: 455
The Fifth Elephant is the 24th Discworld and fifth Watch novel, and largely assumes you know who the main characters are. This is not a good place to start. The dwarves are electing a new king. The resulting political conflict is spilling over into the streets of Ankh-Morpork, but that's not the primary problem. First, the replica Scone of Stone, a dwarven artifact used to crown the Low King of the Dwarves, is stolen from the Dwarf Bread Museum. Then, Vimes is dispatched to berwald, ostensibly to negotiate increased fat exports with the new dwarven king. And then Angua disappears, apparently headed towards her childhood home in berwald, which immediately prompts Carrot to resign and head after her. The City Watch is left in the hands of now-promoted Captain Colon. We see lots of Lady Sybil for the first time since Guards! Guards!, and there's a substantial secondary plot with Angua and Carrot and a tertiary plot with Colon making a complete mess of things back home, but this is mostly a Vimes novel. As usual, Vetinari is pushing him outside of his comfort zone, but he's not seriously expecting Vimes to act like an ambassador. He's expecting Vimes to act like a policeman, even though he's way outside his jurisdiction. This time, that means untangling a messy three-sided political situation involving the dwarves, the werewolves, and the vampires. There is some Igor dialogue in this book, but thankfully Pratchett toned it down a lot and it never started to bother me. I do enjoy Pratchett throwing Vimes and his suspicious morality at political problems and watching him go at them sideways. Vimes's definition of crimes is just broad enough to get him fully invested in a problem, but too narrow to give him much patience with the diplomatic maneuvering. It makes him an unpredictable diplomat in a clash of cultures way that's fun to read about. Cheery and Detritus are great traveling companions for this, since both of them also unsettle the dwarves in wildly different ways. I also have to admit that Pratchett is doing more interesting things with the Angua and Carrot relationship than I had feared. In previous books, I was getting tired of their lack of communication and wasn't buying the justifications for it, but I think I finally understand why the communication barriers are there. It's not that Angua refuses to talk to Carrot (although there's still a bit of that going on). It's that Carrot's attitude towards the world is very strange, and gets stranger the closer you are to him. Carrot has always been the character who is too earnest and straightforward and good for Ankh-Morpork and yet somehow makes it work, but Pratchett is doing something even more interesting with the concept of nobility. A sufficiently overwhelming level of heroic ethics becomes almost alien, so contrary to how people normally think that it can make conversations baffling. It's not that Carrot is perfect (sometimes he does very dumb things), it's that his natural behavior follows a set of ethics that humans like to pretend they follow but actually don't and never would entirely. His character should be a boring cliche or an over-the-top parody, and yet he isn't at all. But Carrot's part is mostly a side plot. Even more than Jingo, The Fifth Elephant is establishing Vimes as a force to be reckoned with, even if you take him outside his familiar city. He is in so many ways the opposite of Vetinari, and yet he's a tool that Vetinari is extremely good at using. Colon of course is a total disaster as the head of the Watch, and that's mostly because Colon should never be more than a sergeant, but it's also because even when he's taking the same action as Vimes, he's not doing it for the same reasons or with the same stubborn core of basic morality and loyalty that's under Vimes's suspicious conservatism. The characterization in the Watch novels doesn't seem that subtle or deep at first, but it accumulates over the course of the series in a way that I think is more effective than any of the other story strands. Vetinari, Vimes, and Carrot all represent "right," or at least order, in overlapping stories of right versus wrong, but they do so in radically different ways and with radically different goals. Each time one of them seems ascendant, each time one of their approaches seems more clearly correct, Pratchett throws them at a problem where a different approach is required. It's a great reading experience. This was one of the better Discworld novels even though I found the villains to be a bit tedious and stupid. Recommended. Followed by The Truth in publication order. The next Watch novel is Night Watch. Rating: 8 out of 10

10 December 2022

Timo Jyrinki: Running Cockpit inside ALP

(quoted from my other blog at since a new OS might be interesting for many and this is published in separate planets)
ALP - The Adaptable Linux Platform is a new operating system from SUSE to run containerized and virtualized workloads. It is in early prototype phase, but the development is done completely openly so it s easy to jump in to try it.For this trying out, I used the latest encrypted build as of the writing, 22.1 from ALP images. I imported it in virt-manager as a Generic Linux 2022 image, using UEFI instead of BIOS, added a TPM device (which I m interested in otherwise) and referring to an Ignition JSON file in the XML config in virt-manager.The Ignition part is pretty much fully thanks to Paolo Stivanin who studied the secrets of it before me. But here it goes - and this is required for password login in Cockpit to work in addition to SSH key based login to the VM from host - first, create config.ign file:
 
"ignition": "version": "3.3.0" ,
"passwd":
"users": [

"name": "root",
"passwordHash": "YOURHASH",
"sshAuthorizedKeys": [
"ssh-... YOURKEY"
]

]
,
"systemd":
"units": [
"name": "sshd.service",
"enabled": true
]
,
"storage":
"files": [

"overwrite": true,
"path": "/etc/ssh/sshd_config.d/20-enable-passwords.conf",
"contents":
"source": "data:,PasswordAuthentication%20yes%0APermitRootLogin%20yes%0A"
,
"mode": 420

]


where password SHA512 hash can be obtained using openssl passwd -6 and the ssh key is your public ssh key.That file is put to eg /tmp and referred in the virt-manager s XML like follows:
  <sysinfo type="fwcfg">
<entry name="opt/com.coreos/config" file="/tmp/config.ign"/>
</sysinfo>
Now we can boot up the VM and ssh in - or you could log in directly too but it s easier to copy-paste commands when using ssh.Inside the VM, we can follow the ALP documentation to install and start Cockpit:
podman container runlabel install registry.opensuse.org/suse/alp/workloads/tumbleweed_containerfiles/suse/alp/workloads/cockpit-ws:latest
podman container runlabel --name cockpit-ws run registry.opensuse.org/suse/alp/workloads/tumbleweed_containerfiles/suse/alp/workloads/cockpit-ws:latest
systemctl enable --now cockpit.service
Check your host s IP address with ip -a, and open IP:9090 in your host s browser:Cockpit login screenLogin with root / your password and you shall get the front page:Cockpit front page and many other pages where you can manage your ALP deployment via browser:Cockpit podman pageAll in all, ALP is in early phases but I m really happy there s up-to-date documentation provided and people can start experimenting it whenever they want. The images from the linked directory should be fairly good, and test automation with openQA has been started upon as well.You can try out the other example workloads that are available just as well.

Matthew Garrett: On-device WebAuthn and what makes it hard to do well

WebAuthn improves login security a lot by making it significantly harder for a user's credentials to be misused - a WebAuthn token will only respond to a challenge if it's issued by the site a secret was issued to, and in general will only do so if the user provides proof of physical presence[1]. But giving people tokens is tedious and also I have a new laptop which only has USB-C but does have a working fingerprint reader and I hate the aesthetics of the Yubikey 5C Nano, so I've been thinking about what WebAuthn looks like done without extra hardware.

Let's talk about the broad set of problems first. For this to work you want to be able to generate a key in hardware (so it can't just be copied elsewhere if the machine is compromised), prove to a remote site that it's generated in hardware (so the remote site isn't confused about what security assertions you're making), and tie use of that key to the user being physically present (which may range from "I touched this object" to "I presented biometric evidence of identity"). What's important here is that a compromised OS shouldn't be able to just fake a response. For that to be possible, the chain between proof of physical presence to the secret needs to be outside the control of the OS.

For a physical security token like a Yubikey, this is pretty easy. The communication protocol involves the OS passing a challenge and the source of the challenge to the token. The token then waits for a physical touch, verifies that the source of the challenge corresponds to the secret it's being asked to respond to the challenge with, and provides a response. At the point where keys are being enrolled, the token can generate a signed attestation that it generated the key, and a remote site can then conclude that this key is legitimately sequestered away from the OS. This all takes place outside the control of the OS, meeting all the goals described above.

How about Macs? The easiest approach here is to make use of the secure enclave and TouchID. The secure enclave is a separate piece of hardware built into either a support chip (for x86-based Macs) or directly on the SoC (for ARM-based Macs). It's capable of generating keys and also capable of producing attestations that said key was generated on an Apple secure enclave ("Apple Anonymous Attestation", which has the interesting property of attesting that it was generated on Apple hardware, but not which Apple hardware, avoiding a lot of privacy concerns). These keys can have an associated policy that says they're only usable if the user provides a legitimate touch on the fingerprint sensor, which means it can not only assert physical presence of a user, it can assert physical presence of an authorised user. Communication between the fingerprint sensor and the secure enclave is a private channel that the OS can't meaningfully interfere with, which means even a compromised OS can't fake physical presence responses (eg, the OS can't record a legitimate fingerprint press and then send that to the secure enclave again in order to mimic the user being present - the secure enclave requires that each response from the fingerprint sensor be unique). This achieves our goals.

The PC space is more complicated. In the Mac case, communication between the biometric sensors (be that TouchID or FaceID) occurs in a controlled communication channel where all the hardware involved knows how to talk to the other hardware. In the PC case, the typical location where we'd store secrets is in the TPM, but TPMs conform to a standardised spec that has no understanding of this sort of communication, and biometric components on PCs have no way to communicate with the TPM other than via the OS. We can generate keys in the TPM, and the TPM can attest to those keys being TPM-generated, which means an attacker can't exfiltrate those secrets and mimic the user's token on another machine. But in the absence of any explicit binding between the TPM and the physical presence indicator, the association needs to be up to code running on the CPU. If that's in the OS, an attacker who compromises the OS can simply ask the TPM to respond to an challenge it wants, skipping the biometric validation entirely.

Windows solves this problem in an interesting way. The Windows Hello Enhanced Signin doesn't add new hardware, but relies on the use of virtualisation. The agent that handles WebAuthn responses isn't running in the OS, it's running in another VM that's entirely isolated from the OS. Hardware that supports this model has a mechanism for proving its identity to the local code (eg, fingerprint readers that support this can sign their responses with a key that has a certificate that chains back to Microsoft). Additionally, the secrets that are associated with the TPM can be held in this VM rather than in the OS, meaning that the OS can't use them directly. This means we have a flow where a browser asks for a WebAuthn response, that's passed to the VM, the VM asks the biometric device for proof of user presence (including some sort of random value to prevent the OS just replaying that), receives it, and then asks the TPM to generate a response to the challenge. Compromising the OS doesn't give you the ability to forge the responses between the biometric device and the VM, and doesn't give you access to the secrets in the TPM, so again we meet all our goals.

On Linux (and other free OSes), things are less good. Projects like tpm-fido generate keys on the TPM, but there's no secure channel between that code and whatever's providing proof of physical presence. An attacker who compromises the OS may not be able to copy the keys to their own system, but while they're on the compromised system they can respond to as many challenges as they like. That's not the same security assertion we have in the other cases.

Overall, Apple's approach is the simplest - having binding between the various hardware components involved means you can just ignore the OS entirely. Windows doesn't have the luxury of having as much control over what the hardware landscape looks like, so has to rely on virtualisation to provide a security barrier against a compromised OS. And in Linux land, we're fucked. Who do I have to pay to write a lightweight hypervisor that runs on commodity hardware and provides an environment where we can run this sort of code?


[1] As I discussed recently there are scenarios where these assertions are less strong, but even so

comment count unavailable comments

Russ Allbery: Review: Trust

Review: Trust, by Mary Sisson
Series: Trang #2
Publisher: Mary Sisson
Copyright: 2012
Printing: December 2013
ASIN: B0087KQDQ0
Format: Kindle
Pages: 375
Trust is a direct sequel to Trang and should not be read out of order. Both the primary and secondary plot deal with the consequences of the ending of Trang and thus spoil it heavily. After a dodgy and unethical debriefing under mental probe (which took far too long to become relevant to the story) Philippe Trang is back at work as the human diplomat to a space station full of aliens in intergalactic space. At first, interspecies relations have not changed much, but soon Philippe will be drawn farther into the consequences of Trang's dramatic conclusion than he would have expected. And there are other complications: a new group of Special Forces soldiers, an extremely grumpy alien who disapproves of his species' current culture, and the continuing incomprehensible behavior of the Magic Man. I was hoping this series would be a hidden gem of diplomatic SF, a subgenre that I want to exist. Unfortunately, this entry takes a strong turn towards more conventional territory: a Star Trek plot. One of the merits of the first novel is that Trang, and the humans in general, didn't have much power. Humans were meeting aliens as equals or inferiors, and both sides were attempting to understand. Although the humans became central to the plot (probably unavoidable when they're the protagonists), it was somewhat by accident. I was hoping Sisson would lean into that setup, stress the equal footing, and focus on the complex diplomacy. Instead, Trust puts Trang in a position of considerable authority over one of the alien races. Like most Star Trek plots, this book is primarily about mapping strange alien behavior onto human morality to solve the problem of the week. As an entry in that genre, it's... okay. I still like Trang as a character, Sisson does an adequate job showing how weird aliens can be (although mostly by jumbling together extremes of human behavior instead of finding something truly alien), and the opinions of the aliens continue to matter. But I feel like this series is sliding towards making the humans central to everything, and I was not enthused by a plot that requires Trang sort out complex political problems for an entire alien race he knows next to nothing about. This book also adds more viewpoints, giving us several chapters from the perspective of one of Trang's escort soldiers and one from one of the aliens. I liked the alien perspective; it was probably the best chapter of the book. Seeing the human characters from an external perspective was amusing, and I liked how both the humans and the aliens surprised and confused each other. That said, it also felt like a bit of a cheat to tell the reader about the cultural forces at play that Trang was missing. I already thought Trang was being exceptionally dim about the alien gifts he was given, pocketing them without attempting to understand them and then never studying them later. Being shown more things he should have tried to figure out didn't help. You're a diplomat in an extended first contact situation: please have some basic curiosity about what's going on and talk it over with the people around you, rather than treating aliens like children. The soldier perspective adds a secondary plot that was okay but a bit silly, and I'm not sure why Sisson needed to introduce a second perspective to tell it. I think the same secondary plot would have been more interesting if she'd stuck with Trang's perspective and forced him to reconstruct what had been happening when he wasn't paying attention. As is, the plot relied too much on people being stupid and not talking to each other. There was nothing seriously wrong with this book, but it's also not fulfilling the potential of the first book of the series. It felt like okay self-published science fiction; that's not nothing, but there are a lot of books like that, and I wanted diplomatic science fiction that goes somewhere different. I may give the third book a chance, but I'm feeling less enthused now. Followed by Tribulations. Rating: 6 out of 10

9 December 2022

Matthew Garrett: End-to-end encrypted messages need more than libsignal

(Disclaimer: I'm not a cryptographer, and I do not claim to be an expert in Signal. I've had this read over by a couple of people who are so with luck there's no egregious errors, but any mistakes here are mine)

There are indications that Twitter is working on end-to-end encrypted DMs, likely building on work that was done back in 2018. This made use of libsignal, the reference implementation of the protocol used by the Signal encrypted messaging app. There seems to be a fairly widespread perception that, since libsignal is widely deployed (it's also the basis for WhatsApp's e2e encryption) and open source and has been worked on by a whole bunch of cryptography experts, choosing to use libsignal means that 90% of the work has already been done. And in some ways this is true - the security of the protocol is probably just fine. But there's rather more to producing a secure and usable client than just sprinkling on some libsignal.

(Aside: To be clear, I have no reason to believe that the people who were working on this feature in 2018 were unaware of this. This thread kind of implies that the practical problems are why it didn't ship at the time. Given the reduction in Twitter's engineering headcount, and given the new leadership's espousal of political and social perspectives that don't line up terribly well with the bulk of the cryptography community, I have doubts that any implementation deployed in the near future will get all of these details right)

I was musing about this last night and someone pointed out some prior art. Bridgefy is a messaging app that uses Bluetooth as its transport layer, allowing messaging even in the absence of data services. The initial implementation involved a bunch of custom cryptography, enabling a range of attacks ranging from denial of service to extracting plaintext from encrypted messages. In response to criticism Bridgefy replaced their custom cryptographic protocol with libsignal, but that didn't fix everything. One issue is the potential for MITMing - keys are shared on first communication, but the client provided no mechanism to verify those keys, so a hostile actor could pretend to be a user, receive messages intended for that user, and then reencrypt them with the user's actual key. This isn't a weakness in libsignal, in the same way that the ability to add a custom certificate authority to a browser's trust store isn't a weakness in TLS. In Signal the app key distribution is all handled via Signal's servers, so if you're just using libsignal you need to implement the equivalent yourself.

The other issue was more subtle. libsignal has no awareness at all of the Bluetooth transport layer. Deciding where to send a message is up to the client, and these routing messages were spoofable. Any phone in the mesh could say "Send messages for Bob here", and other phones would do so. This should have been a denial of service at worst, since the messages for Bob would still be encrypted with Bob's key, so the attacker would be able to prevent Bob from receiving the messages but wouldn't be able to decrypt them. However, the code to decide where to send the message and the code to decide which key to encrypt the message with were separate, and the routing decision was made before the encryption key decision. An attacker could send a message saying "Route messages for Bob to me", and then another saying "Actually lol no I'm Mallory". If a message was sent between those two messages, the message intended for Bob would be delivered to Mallory's phone and encrypted with Mallory's key.

Again, this isn't a libsignal issue. libsignal encrypted the message using the key bundle it was told to encrypt it with, but the client code gave it a key bundle corresponding to the wrong user. A race condition in the client logic allowed messages intended for one person to be delivered to and readable by another.

This isn't the only case where client code has used libsignal poorly. The Bond Touch is a Bluetooth-connected bracelet that you wear. Tapping it or drawing gestures sends a signal to your phone, which culminates in a message being sent to someone else's phone which sends a signal to their bracelet, which then vibrates and glows in order to indicate a specific sentiment. The idea is that you can send brief indications of your feelings to someone you care about by simply tapping on your wrist, and they can know what you're thinking without having to interrupt whatever they're doing at the time. It's kind of sweet in a way that I'm not, but it also advertised "Private Spaces", a supposedly secure way to send chat messages and pictures, and that seemed more interesting. I grabbed the app and disassembled it, and found it was using libsignal. So I bought one and played with it, including dumping the traffic from the app. One important thing to realise is that libsignal is just the protocol library - it doesn't implement a server, and so you still need some way to get information between clients. And one of the bits of information you have to get between clients is the public key material.

Back when I played with this earlier this year, key distribution was implemented by uploading the public key to a database. The other end would download the public key, and everything works out fine. And this doesn't sound like a problem, given that the entire point of a public key is to be, well, public. Except that there was no access control on this database, and the filenames were simply phone numbers, so you could overwrite anyone's public key with one of your choosing. This didn't let you cause messages intended for them to be delivered to you, so exploiting this for anything other than a DoS would require another vulnerability somewhere, but there are contrived situations where this would potentially allow the privacy expectations to be broken.

Another issue with this app was its handling of one-time prekeys. When you send someone new a message via Signal, it's encrypted with a key derived from not only the recipient's identity key, but also from what's referred to as a "one-time prekey". Users generate a bunch of keypairs and upload the public half to the server. When you want to send a message to someone, you ask the server for one of their one-time prekeys and use that. Decrypting this message requires using the private half of the one-time prekey, and the recipient deletes it afterwards. This means that an attacker who intercepts a bunch of encrypted messages over the network and then later somehow obtains the long-term keys still won't be able to decrypt the messages, since they depended on keys that no longer exist. Since these one-time prekeys are only supposed to be used once (it's in the name!) there's a risk that they can all be consumed before they're replenished. The spec regarding pre-keys says that servers should consider rate-limiting this, but the protocol also supports falling back to just not using one-time prekeys if they're exhausted (you lose the forward secrecy benefits, but it's still end-to-end encrypted). This implementation not only implemented no rate-limiting, making it easy to exhaust the one-time prekeys, it then also failed to fall back to running without them. Another easy way to force DoS.

(And, remember, a successful DoS on an encrypted communications channel potentially results in the users falling back to an unencrypted communications channel instead. DoS may not break the encrypted protocol, but it may be sufficient to obtain plaintext anyway)

And finally, there's ClearSignal. I looked at this earlier this year - it's avoided many of these pitfalls by literally just being a modified version of the official Signal client and using the existing Signal servers (it's even interoperable with Actual Signal), but it's then got a bunch of other weirdness. The Signal database (I /think/ including the keys, but I haven't completely verified that) gets backed up to an AWS S3 bucket, identified using something derived from a key using KERI, and I've seen no external review of that whatsoever. So, who knows. It also has crash reporting enabled, and it's unclear how much internal state it sends on crashes, and it's also based on an extremely old version of Signal with the "You need to upgrade Signal" functionality disabled.

Three clients all using libsignal in one form or another, and three clients that do things wrong in ways that potentially have a privacy impact. Again, none of these issues are down to issues with libsignal, they're all in the code that surrounds it. And remember that Twitter probably has to worry about other issues as well! If I lose my phone I'm probably not going to worry too much about whether the messages sent through my weird bracelet app being gone forever, but losing all my Twitter DMs would be a significant change in behaviour from the status quo. But that's not an easy thing to do when you're not supposed to have access to any keys! Group chats? That's another significant problem to deal with. And making the messages readable through the web UI as well as on mobile means dealing with another set of key distribution issues. Get any of this wrong in one way and the user experience doesn't line up with expectations, get it wrong in another way and the worst case involves some of your users in countries with poor human rights records being executed.

Simply building something on top of libsignal doesn't mean it's secure. If you want meaningful functionality you need to build a lot of infrastructure around libsignal, and doing that well involves not just competent development and UX design, but also a strong understanding of security and cryptography. Given Twitter's lost most of their engineering and is led by someone who's alienated all the cryptographers I know, I wouldn't be optimistic.

comment count unavailable comments

Russell Coker: USB-PD and GaN

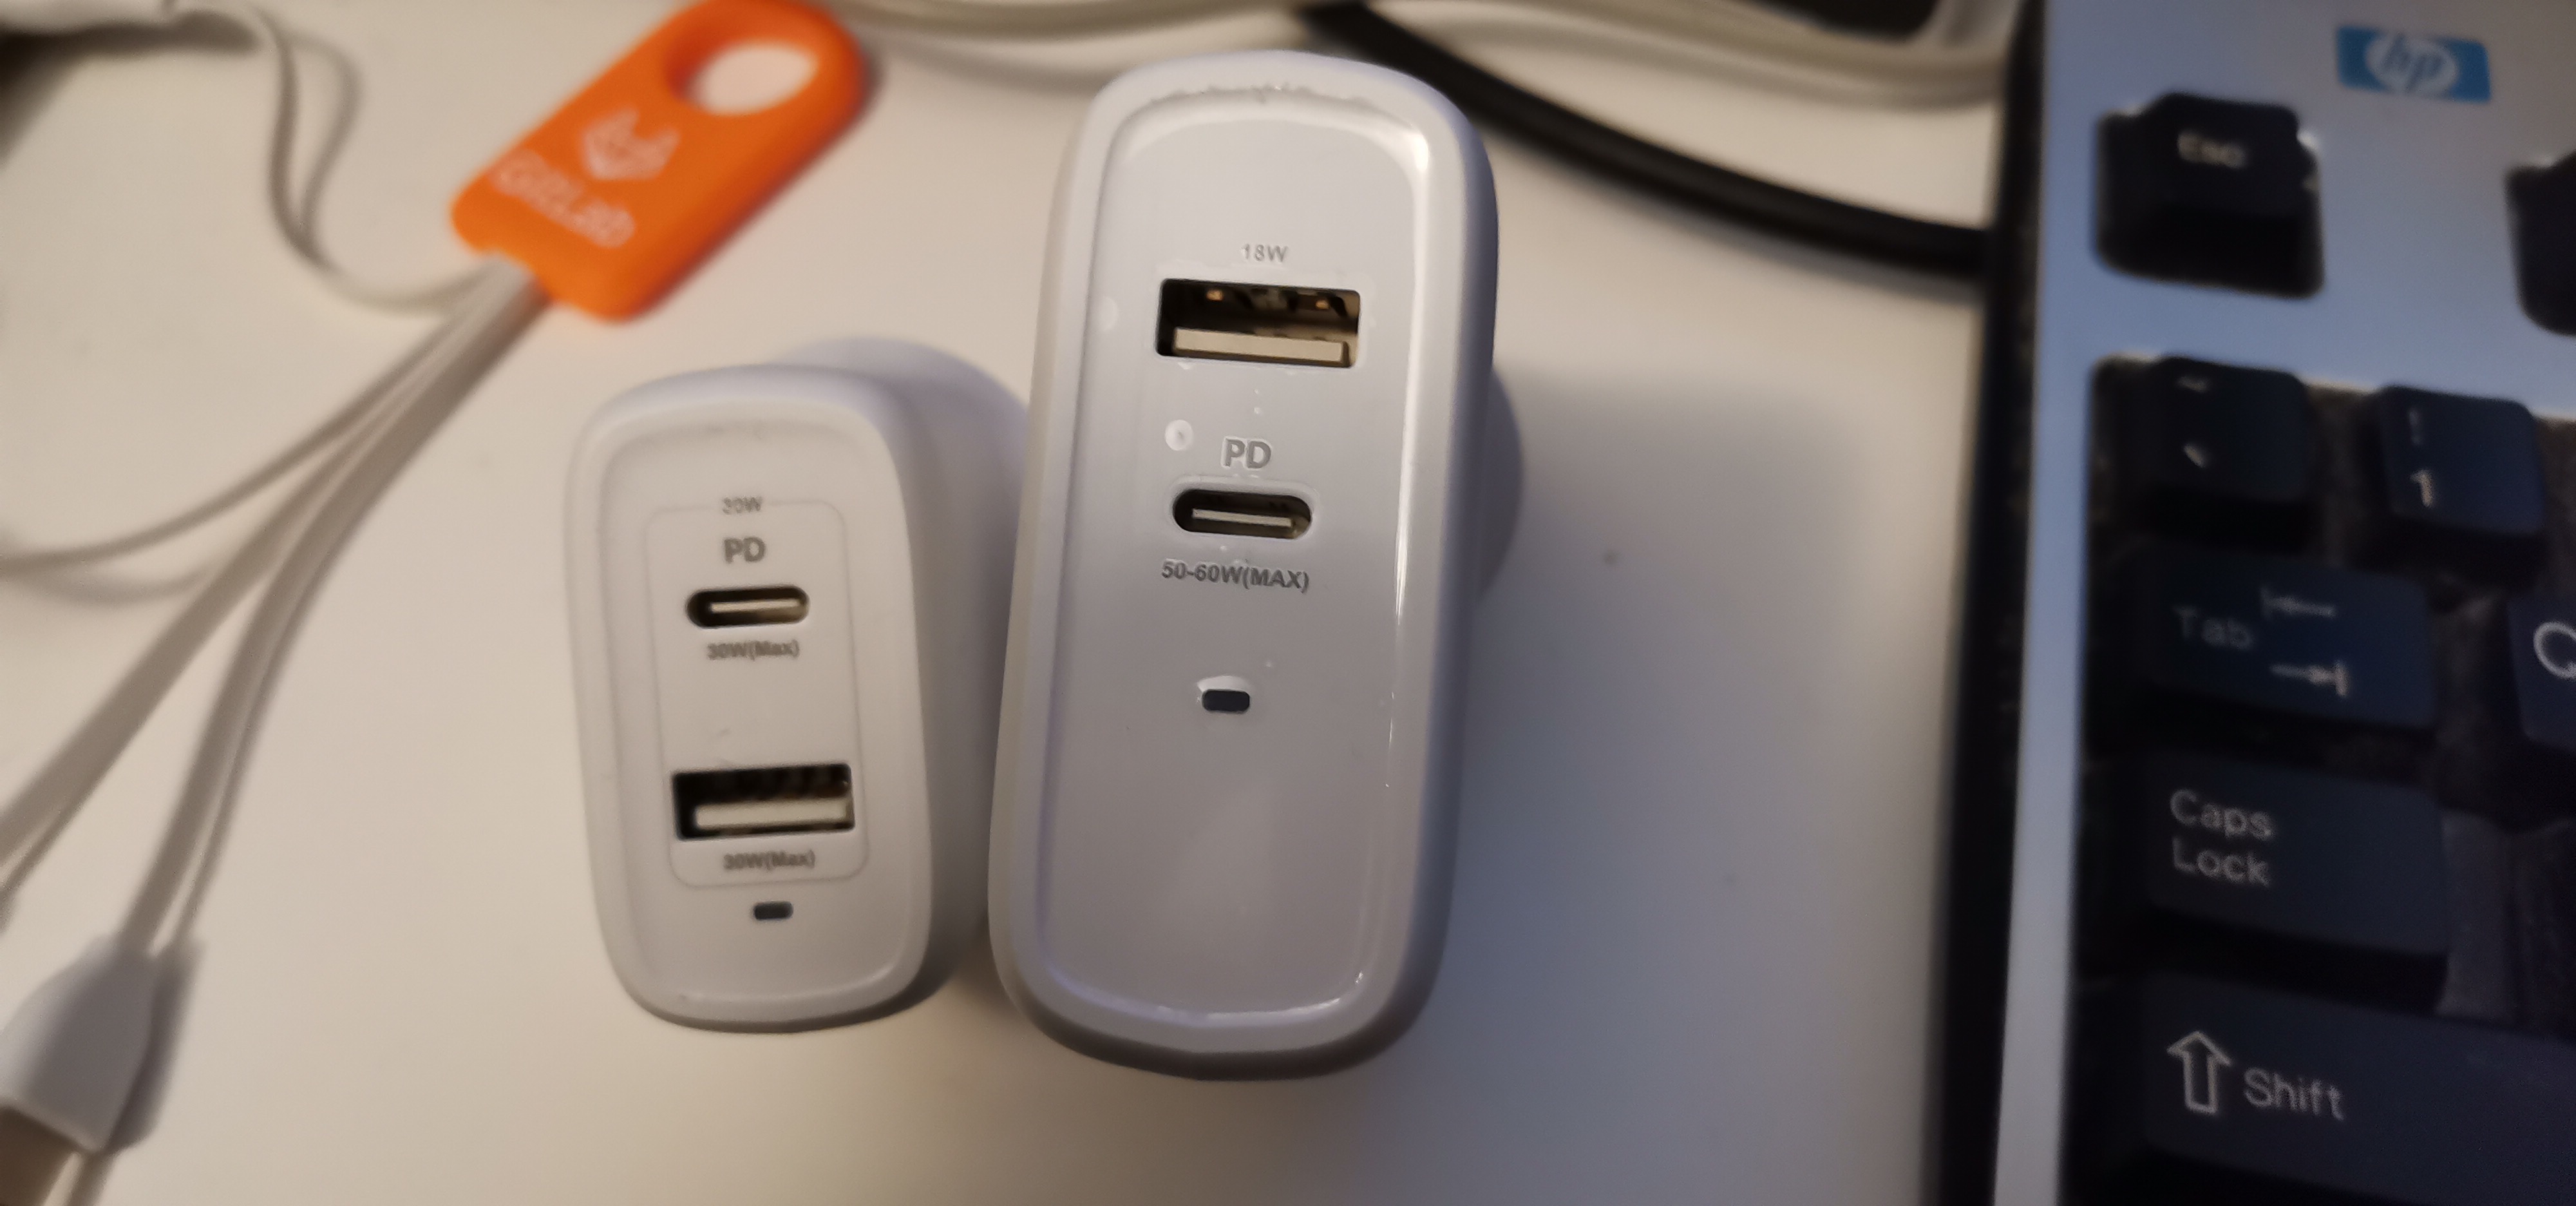
photo of 2 USB-PD chargers A recent development is cheap Gallium Nitride based power supplies that provide better efficiency in a smaller space than other technologies. Kogan recently had a special on such devices so I decided to try them out with my new Thinkpad X1 Carbon Gen 5 [1]. Google searches for power supplies for that Thinkpad included results for 30W PSUs which implies that any 30W USB-C PSU should work. I bought a 30W charger for $10 that can supply 15V/2A or 20V/1.5A on a single USB-C port or 15W on the USB-C port and 15W on the USB-2 port at the same time and expected it to work as a laptop charger. Unfortunately it didn t, I don t know whether the adverts for 30W Thinkpad PSUs were false or whether the claim of the GaN charger I bought being 30W was false, all I know is that the KDE power applet said that the PSU couldn t supply enough power. I then bought a 68W charger for $28 that can supply 20.0V/3.0A on a single USB-C port if the USB-2 port isn t used and 50W on the USB-C port if the USB-2 port is also being used. This worked well which wasn t a great surprise as I had previously run the laptop on 45W PSUs. If I connect a phone to the USB-2 port while the laptop is being charged then the laptop will be briefly cut off, presumably the voltage and current are being renegotiated when that happens. As you can see the 68W charger is significantly larger than the 30W charger, but still small enough to easily fit in a jacket pocket and smaller than a regular laptop charger. One of my uses for this will be to put it in a jacket pocket when I have my laptop in another pocket. Another use will be for charging in my car as the cables from the inverter to convert 12VDC to 240VAC takes enough space. I will probably get a ~50W USB-PD charger that connects to a car cigarette lighter socket when a GaN version of such a charger becomes available.

8 December 2022

Reproducible Builds: Reproducible Builds in November 2022

Welcome to yet another report from the Reproducible Builds project, this time for November 2022. In all of these reports (which we have been publishing regularly since May 2015) we attempt to outline the most important things that we have been up to over the past month. As always, if you interested in contributing to the project, please visit our Contribute page on our website.

Reproducible Builds Summit 2022 Following-up from last month s report about our recent summit in Venice, Italy, a comprehensive report from the meeting has not been finalised yet watch this space! As a very small preview, however, we can link to several issues that were filed about the website during the summit (#38, #39, #40, #41, #42, #43, etc.) and collectively learned about Software Bill of Materials (SBOM) s and how .buildinfo files can be seen/used as SBOMs. And, no less importantly, the Reproducible Builds t-shirt design has been updated

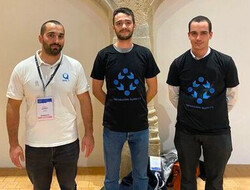
Reproducible Builds at European Cyber Week 2022 During the European Cyber Week 2022, a Capture The Flag (CTF) cybersecurity challenge was created by Fr d ric Pierret on the subject of Reproducible Builds. The challenge consisted in a pedagogical sense based on how to make a software release reproducible. To progress through the challenge issues that affect the reproducibility of build (such as build path, timestamps, file ordering, etc.) were to be fixed in steps in order to get the final flag in order to win the challenge. At the end of the competition, five people succeeded in solving the challenge, all of whom were awarded with a shirt. Fr d ric Pierret intends to create similar challenge in the form of a how to in the Reproducible Builds documentation, but two of the 2022 winners are shown here:

On business adoption and use of reproducible builds Simon Butler announced on the rb-general mailing list that the Software Quality Journal published an article called On business adoption and use of reproducible builds for open and closed source software. This article is an interview-based study which focuses on the adoption and uses of Reproducible Builds in industry, with a focus on investigating the reasons why organisations might not have adopted them:
[ ] industry application of R-Bs appears limited, and we seek to understand whether awareness is low or if significant technical and business reasons prevent wider adoption.
This is achieved through interviews with software practitioners and business managers, and touches on both the business and technical reasons supporting the adoption (or not) of Reproducible Builds. The article also begins with an excellent explanation and literature review, and even introduces a new helpful analogy for reproducible builds:
[Users are] able to perform a bitwise comparison of the two binaries to verify that they are identical and that the distributed binary is indeed built from the source code in the way the provider claims. Applied in this manner, R-Bs function as a canary, a mechanism that indicates when something might be wrong, and offer an improvement in security over running unverified binaries on computer systems.
The full paper is available to download on an open access basis. Elsewhere in academia, Beatriz Michelson Reichert and Rafael R. Obelheiro have published a paper proposing a systematic threat model for a generic software development pipeline identifying possible mitigations for each threat (PDF). Under the Tampering rubric of their paper, various attacks against Continuous Integration (CI) processes:
An attacker may insert a backdoor into a CI or build tool and thus introduce vulnerabilities into the software (resulting in an improper build). To avoid this threat, it is the developer s responsibility to take due care when making use of third-party build tools. Tampered compilers can be mitigated using diversity, as in the diverse double compiling (DDC) technique. Reproducible builds, a recent research topic, can also provide mitigation for this problem. (PDF)

Misc news
On our mailing list this month:

Debian & other Linux distributions Over 50 reviews of Debian packages were added this month, another 48 were updated and almost 30 were removed, all of which adds to our knowledge about identified issues. Two new issue types were added as well. [ ][ ]. Vagrant Cascadian announced on our mailing list another online sprint to help clear the huge backlog of reproducible builds patches submitted by performing NMUs (Non-Maintainer Uploads). The first such sprint took place on September 22nd, but others were held on October 6th and October 20th. There were two additional sprints that occurred in November, however, which resulted in the following progress: Lastly, Roland Clobus posted his latest update of the status of reproducible Debian ISO images on our mailing list. This reports that all major desktops build reproducibly with bullseye, bookworm and sid as well as that no custom patches needed to applied to Debian unstable for this result to occur. During November, however, Roland proposed some modifications to live-setup and the rebuild script has been adjusted to fix the failing Jenkins tests for Debian bullseye [ ][ ].
In other news, Miro Hron ok proposed a change to clamp build modification times to the value of SOURCE_DATE_EPOCH. This was initially suggested and discussed on a devel@ mailing list post but was later written up on the Fedora Wiki as well as being officially proposed to Fedora Engineering Steering Committee (FESCo).

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb prepared and uploaded versions 226 and 227 to Debian:
  • Support both python3-progressbar and python3-progressbar2, two modules providing the progressbar Python module. [ ]
  • Don t run Python decompiling tests on Python bytecode that file(1) cannot detect yet and Python 3.11 cannot unmarshal. (#1024335)
  • Don t attempt to attach text-only differences notice if there are no differences to begin with. (#1024171)
  • Make sure we recommend apksigcopier. [ ]
  • Tidy generation of os_list. [ ]
  • Make the code clearer around generating the Debian substvars . [ ]
  • Use our assert_diff helper in test_lzip.py. [ ]
  • Drop other copyright notices from lzip.py and test_lzip.py. [ ]
In addition to this, Christopher Baines added lzip support [ ], and FC Stegerman added an optimisation whereby we don t run apktool if no differences are detected before the signing block [ ].
A significant number of changes were made to the Reproducible Builds website and documentation this month, including Chris Lamb ensuring the openEuler logo is correctly visible with a white background [ ], FC Stegerman de-duplicated by email address to avoid listing some contributors twice [ ], Herv Boutemy added Apache Maven to the list of affiliated projects [ ] and boyska updated our Contribute page to remark that the Reproducible Builds presence on salsa.debian.org is not just the Git repository but is also for creating issues [ ][ ]. In addition to all this, however, Holger Levsen made the following changes:
  • Add a number of existing publications [ ][ ] and update metadata for some existing publications as well [ ].
  • Hide draft posts on the website homepage. [ ]
  • Add the Warpforge build tool as a participating project of the summit. [ ]
  • Clarify in the footer that we welcome patches to the website repository. [ ]

Testing framework The Reproducible Builds project operates a comprehensive testing framework at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In October, the following changes were made by Holger Levsen:
  • Improve the generation of meta package sets (used in grouping packages for reporting/statistical purposes) to treat Debian bookworm as equivalent to Debian unstable in this specific case [ ] and to parse the list of packages used in the Debian cloud images [ ][ ][ ].
  • Temporarily allow Frederic to ssh(1) into our snapshot server as the jenkins user. [ ]
  • Keep some reproducible jobs Jenkins logs much longer [ ] (later reverted).
  • Improve the node health checks to detect failures to update the Debian cloud image package set [ ][ ] and to improve prioritisation of some kernel warnings [ ].
  • Always echo any IRC output to Jenkins output as well. [ ]
  • Deal gracefully with problems related to processing the cloud image package set. [ ]
Finally, Roland Clobus continued his work on testing Live Debian images, including adding support for specifying the origin of the Debian installer [ ] and to warn when the image has unmet dependencies in the package list (e.g. due to a transition) [ ].
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. You can get in touch with us via:

Shirish Agarwal: Wayland, Hearing aids, Multiverse & Identity

Wayland First up, I read Antoine Beaupr s Wayland to Sway migration with interest. While he said it s done and dusted or something similar, the post shows there s still quite a ways to go. I wouldn t say it s done or whatever till it s integrated so well that a person installs it and doesn t really need to fiddle with config files as an average user. For specific use-cases you may need to, but that should be outside of a normal user (layperson) experience. I have been using mate for a long long time and truth be told been very happy with it. The only thing I found about Wayland on mate is this discussion or rather this entry. The roadmap on Ubuntu Mate is also quite iffy. The Mate Wayland entry on Debian wiki also perhaps need an updation but dunno much as the latest update it shares is 2019 and it s 2022. One thing to note, at least according to Antoine, things should be better as and when it gets integrated even on legacy hardware. I would be interested to know how it would work on old desktops and laptops rather than new or is there some barrier? I, for one would have liked to see or know about why lightdm didn t work on Wayland and if there s support. From what little I know lightdm is much lighter than gdm3 and doesn t require much memory and from what little I have experienced works very well with mate. I have been using it since 2015/16 although the Debian changelog tells me that it has been present since 2011. I was hoping to see if there was a Wayland specific mailing list, something like debian-wayland but apparently there s not :(. Using mate desktop wayland (tried few other variations on the keywords) but search fails to find any meaningful answer :(. FWIW and I don t know the reason why but Archwiki never fails to amaze me. Interestingly, it just says No for mate. I probably would contact upstream in the coming days to know what their plans are and hopefully they will document what their plans are on integrating Wayland in both short-term and long-term with an update, or if there is something more recent they have documented elsewhere, get that update on the Debian wiki so people know. The other interesting thread I read was Russel Coker s Thinkpad X1 Carbon Gen5 entry. I would be in the market in a few months to find/buy a Thinkpad but probably of AMD rather than Intel because part of recent past history with Intel as well as AMD having a bit of an edge over Intel as far as graphics is concerned. I wonder why Russel was looking into Intel and not AMD. Would be interested to know why Intel and not AMD? Any specific reason ???

Hearing Aids I finally bought hearing aids about a couple of weeks back and have been practicing using them. I was able to have quite a few conversations although music is still I m not able to listen clearly but it is still a far cry from before and for the better. I am able to have conversations with people and also reply and they do not have to make that extra effort that they needed to. Make things easier for everybody. The one I bought is at the starting range although the hearing aids go all the way to 8 lakhs for a pair (INR 800,000), the more expensive ones having WiFi, Bluetooth and more channels, it all depends on how much can one afford. And AFAIK there is not a single Indian manufacturer who is known in this business.

One thing I did notice is while the hearing aids are remarkably sturdy if they fall down as they are small, yet you have to be careful of both dust and water . That does makes life a bit difficult as my house and city both gets sand quite a bit everyday. I don t think they made any India-specific changes, if they had, would probably make things better. I haven t yet looked at it, but it may be possible to hack it remotely. There may or may not be security issues involved, probably would try once I ve bit more time am bit more comfortable to try and see what I can find out. If I had bought it before, maybe I would have applied for the Debian event happening in Kerala, if nothing else, would have been to document what happened there in detail.  I probably would have to get a new motherboard for my desktop probably in a year or two as quite a few motherboards also have WiFi (WiFi 6 ?) think on the southbridge. I at least would have a look in new year and know more as to what s been happening. For last at least 2-3 years there has been a rumor which has been confirmed time and again that the Tata Group has been in talks with multiple vendors to set chip fabrication and testing business but to date they haven t been able to find one. They do keep on giving press conferences about the same but that s all they do :(. Just shared the latest one above.

The Long War Terry Pratchett, Stephen Braxter Long Earth Terry Pratchett, Stephen Braxter ISBN13: 9780062067777 Last month there was also a seconds books sale where I was lucky enough to get my hands on the Long War. But before I share about the book itself, I had a discussion with another of my friends and had to re-share part of that conversation. While the gentleman was adamant that non-fiction books are great, my point as always is both are equal. As I shared perhaps on this blog itself, perhaps multiple times, that I had seen a YT video in which a professor shared multiple textbooks of physics and shared how they are wrong and have been wrong and kept them in a specific corner. He took the latest book which he honestly said doesn t have any mistakes as far as he know and yet still kept in that same corner denoting that it is highly possible that future understanding will make the knowledge or understanding we know different. An example of physics in the nano world and how that is different and basically turns our understanding than what we know. Now as far as the book is concerned, remember Michael Crichton s Timeline. Now that book was originally written in the 1960 s while this one was written by both the honorable gentleman in 2013. So almost 50+ years difference between the two books, and that even shows how they think about things. In this book, you no longer need a big machine, but have something called a stepper machine which is say similar to a cellphone, that size and that frame, thickness etc. In this one, the idea of multiverse is also there but done a tad differently. In this, we do not have other humans or copy humans but have multiple earths that may have same or different geography as how evolution happened. None of the multiverse earths have humans but have different species depending on the evolution that happened there. There are something called as trolls but they have a much different meaning and way about them about how most fantasy authors portray trolls. While they are big in this as well, they are as gentle as bears or rabbits. So the whole thing is about real estate and how humans have spread out on multiple earths and the politics therein. Interestingly, the story was trashed or given negative reviews on Goodreads. The sad part is/was that it was written and published in 2013 when perhaps the possibility of war or anything like that was very remote especially in the States, but now we are now in 2022 and just had an insurrection happen and whole lot of Americans are radicalized, whether you see the left or the right depending on your ideology. An American did share few weeks ago how some shares are looking at Proportional Representation and that should make both parties come more towards the center and be a bit more transparent. What was interesting to me is the fact that states have much more rights to do elections and electioneering the way they want rather than a set model which everyone has common which is what happens in India. This also does poke holes into the whole Donald Trump stolen democracy drama but that s a different story altogether. One of the more interesting things I came to know about is that there are 4 books in the long series and this was the second book in itself. I do not want to dwell on the characters themselves as frankly speaking I haven t read all the four books and it would be gross injustice on my part to talk about the characters themselves. Did I enjoy reading the book, for sure. What was interesting and very true of human nature is that even if we have the ability or had the ability to have whole worlds to ourselves, we are bound to mess it up. And in that aspect, I don t think he is too far off the mark. If I had a whole world, wouldn t I try to exploit it to the best or worse of my ability. One of the more interesting topics in the book is the barter system they have thought of that is called as favors. If you are in multiple worlds, then having a currency, even fiat money is of no use and they have to find ways and means to trade with one another. The book also touches a bit on slavery but only just and doesn t really explore it as much as it could have.

Identity Now this has many meanings to it. Couple of weeks ago, saw a transgender meet. For the uninitiated or rather people like me, basically it is about people who are born in one gender but do not identify with it but the other and they express it first through their clothes and expression and the end of the journey perhaps is with having the organs but this may or may not be feasible, as such surgery is expensive and also not available everywhere. After section 377 was repealed few years ago, we do have a third gender on forms as well as have something called a Transgender Act but how much the needle has moved in society is still a question. They were doing a roadshow near my house hence I was able to talk with them with my new hearing aids and while there was lot of traffic was able to understand some of their issues. For e.g. they find it difficult to get houses on rent, but then it is similar for bachelor guys or girls also. One could argue to what degree it is, and that perhaps maybe. Also, there is a myth that they are somehow promiscuous but that I believe is neither here or there. Osho said an average person thinks about the opposite sex every few seconds or a minute. I am sure even Freud would have similar ideas. So, if you look in that way everybody is promiscuous as far as thought is concerned. The other part being opportunity but that again is function of so many other things. Some people are able to attract a lot of people, others might not. And then whether they chose to act on that opportunity or not is another thing altogether. Another word that is or was used is called gender fluid, but that too is iffy as gender fluid may or may not mean transgender. Also, while watching some nature documentary few days/weeks back had come to know that trees have something like 18 odd genders. That just blows me out of the mind and does re-question this whole idea of sexuality and identity to only two which seems somewhat regressive at least to me. If we think humans are part of nature, then we need to be open up perhaps a bit more. But identity as I shared above has more than one meaning. For e.g. citizenship, that one is born in India is even messier to know, understand and define. I had come across this article about couple of months back. Now think about this. Now, there have been studies and surveys about citizenship and it says something like 60% birth registrations are done in metro cities. Now Metro cities are 10 as defined by Indian state. But there are roughly an odd 4k cities in India and probably twice the number of villages and those are conservative numbers as we still don t record things meticulously, maybe due to the Indian oral tradition or just being lazy or both, one part is also that if you document people and villages and towns, then you are also obligated to give them some things as a state and that perhaps is not what the Indian state wants. A small village in India could be anywhere from few hundreds of people to a few thousand. And all the new interventions whether it is PAN, Aadhar has just made holes rather than making things better. They are not inclusive but exclusive. And none of this takes into account Indian character and the way things are done in India. In most households, excluding the celebs (they are in a world of pain altogether when it comes to baby names but then it s big business but that s an entire different saga altogether, so not going to touch that.) I would use or say my individual case as that is and seems to be something which is regular even today. I was given a nickname when I was 3 years old and given a name when I was 5-6 when I was put in school. I also came to know in school few kids who didn t like their names and couple of them cajoled and actually changed their names while they were kids, most of us just stayed with what we got. I do remember sharing about nakushi or something similar a name given to few girls in Maharashtra by their parents and the state intervened and changed their names. But that too is another story in itself. What I find most problematic is that the state seems to be blind, and this seems to be by design rather than a mistake. Couple of years back, Assam did something called NRC (National Register of Citizens) and by the Govt s own account it was a failure of massive proportions. And they still want to bring in CAA, screwing up Assam more. And this is the same Govt. went shown how incorrect it was, blamed it all on the High Court and it s the same Govt. that shopped around for judges to put somebody called Mr. Saibaba (an invalid 90 year adivasi) against whom the Govt. hasn t even a single proof as of date. Apparently, they went to 6 judges who couldn t give what the decision the Govt. wanted. All this info. is in public domain. So the current party ruling, i.e. BJP just wants to make more divisions rather than taking people along as they don t have answers either on economy, inflation or issues that people are facing. One bright light has been Rahul Gandhi who has been doing a padhyatra (walking) from Kanyakumari to Kashmir and has had tremendous success although mainstream media has showed almost nothing what he is doing or why he is doing that. Not only he had people following him, there are and were many who took his example and using the same values of inclusiveness are walking where they can. And this is not to do with just a political party but more with a political thought of inclusiveness, that we are one irrespective of what I believe, eat, wear etc. And that gentleman has been giving press conferences while our dear P.M. even after 8 years doesn t have the guts to do a single press conference. Before closing, I do want to take another aspect, Rahul Gandhi s mother is an Italian or was from Italy before she married. But for BJP she is still Italian. Rishi Sunak, who has become the UK Prime Minister they think of him as Indian and yet he has sworn using the Queen s name. And the same goes for Canada Kumar (Akshay Kumar) and many others. How the right is able to blind and deaf to what it thinks is beyond me. All these people have taken an oath in the name of the Queen and they have to be loyal to her or rather now King Charles III. The disconnect continues.

3 December 2022

Vincent Bernat: Broken commit diff on Cisco IOS XR

TL;DR Never trust show commit changes diff on Cisco IOS XR.

Cisco IOS XR is the operating system running for the Cisco ASR, NCS, and 8000 routers. Compared to Cisco IOS, it features a candidate configuration and a running configuration. In configuration mode, you can modify the first one and issue the commit command to apply it to the running configuration.1 This is a common concept for many NOS. Before committing the candidate configuration to the running configuration, you may want to check the changes that have accumulated until now. That s where the show commit changes diff command2 comes up. Its goal is to show the difference between the running configuration (show running-configuration) and the candidate configuration (show configuration merge). How hard can it be? Let s put an interface down on IOS XR 7.6.2 (released in August 2022):
RP/0/RP0/CPU0:router(config)#int Hu0/1/0/1 shut
RP/0/RP0/CPU0:router(config)#show commit changes diff
Wed Nov 23 11:08:30.275 CET
Building configuration...
!! IOS XR Configuration 7.6.2
+  interface HundredGigE0/1/0/1
+   shutdown
   !
end
The + sign before interface HundredGigE0/1/0/1 makes it look like you did create a new interface. Maybe there was a typo? No, the diff is just broken. If you look at the candidate configuration, everything is like you expect:
RP/0/RP0/CPU0:router(config)#show configuration merge int Hu0/1/0/1
Wed Nov 23 11:08:43.360 CET
interface HundredGigE0/1/0/1
 description PNI: (some description)
 bundle id 4000 mode active
 lldp
  receive disable
  transmit disable
 !
 shutdown
 load-interval 30
Here is a more problematic example on IOS XR 7.2.2 (released in January 2021). We want to unconfigure three interfaces:
RP/0/RP0/CPU0:router(config)#no int GigabitEthernet 0/0/0/5
RP/0/RP0/CPU0:router(config)#int TenGigE 0/0/0/5 shut
RP/0/RP0/CPU0:router(config)#no int TenGigE 0/0/0/28
RP/0/RP0/CPU0:router(config)#int TenGigE 0/0/0/28 shut
RP/0/RP0/CPU0:router(config)#no int TenGigE 0/0/0/29
RP/0/RP0/CPU0:router(config)#int TenGigE 0/0/0/29 shut
RP/0/RP0/CPU0:router(config)#show commit changes diff
Mon Nov  7 15:07:22.990 CET
Building configuration...
!! IOS XR Configuration 7.2.2
-  interface GigabitEthernet0/0/0/5
-   shutdown
   !
+  interface TenGigE0/0/0/5
+   shutdown
   !
   interface TenGigE0/0/0/28
-   description Trunk (some description)
-   bundle id 2 mode active
   !
end
The two first commands are correctly represented by the first two chunks of the diff: we remove GigabitEthernet0/0/0/5 and create TenGigE0/0/0/5. The two next commands are also correctly represented by the last chunk of the diff. TenGigE0/0/0/28 was already shut down, so it is expected that only description and bundle id are removed. However, the diff command forgets about the modifications for TenGigE0/0/0/29. The diff should include a chunk similar to the last one.
RP/0/RP0/CPU0:router(config)#show run int TenGigE 0/0/0/29
Mon Nov  7 15:07:43.571 CET
interface TenGigE0/0/0/29
 description Trunk to other router
 bundle id 2 mode active
 shutdown
!
RP/0/RP0/CPU0:router(config)#show configuration merge int TenGigE 0/0/0/29
Mon Nov  7 15:07:53.584 CET
interface TenGigE0/0/0/29
 shutdown
!
How can the diff be correct for TenGigE0/0/0/28 but incorrect for TenGigE0/0/0/29 while they have the same configuration? How can you trust the diff command if it forgets part of the configuration? Do you remember the last time you ran an Ansible playbook and discovered the whole router ospf block disappeared without a warning? If you use automation tools, you should check how the diff is assembled. Automation tools should build it from the result of show running-config and show configuration merge. This is what NAPALM does. This is not what cisco.iosxr collection for Ansible does. The problem is not limited to the interface directives. You can get similar issues for other parts of the configuration. For example, here is what we get when removing inactive BGP neighbors on IOS XR 7.2.2:
RP/0/RP0/CPU0:router(config)#router bgp 65400
RP/0/RP0/CPU0:router(config-bgp)#vrf public
RP/0/RP0/CPU0:router(config-bgp-vrf)#no neighbor 217.29.66.1
RP/0/RP0/CPU0:router(config-bgp-vrf)#no neighbor 217.29.66.75
RP/0/RP0/CPU0:router(config-bgp-vrf)#no neighbor 217.29.66.110
RP/0/RP0/CPU0:router(config-bgp-vrf)#no neighbor 217.29.66.112
RP/0/RP0/CPU0:router(config-bgp-vrf)#no neighbor 217.29.66.158
RP/0/RP0/CPU0:router(config-bgp-vrf)#show commit changes diff
Tue Aug  2 13:58:02.536 CEST
Building configuration...
!! IOS XR Configuration 7.2.2
   router bgp 65400
    vrf public
-    neighbor 217.29.66.1
-     remote-as 16004
-     use neighbor-group MIX_IPV4_PUBLIC
-     description MIX: MIX-IT
     !
-    neighbor 217.29.66.75
-     remote-as 49367
-     use neighbor-group MIX_IPV4_PUBLIC
     !
-    neighbor 217.29.67.10
-     remote-as 19679
     !
-    neighbor 217.29.67.15
-    neighbor 217.29.66.112
-     remote-as 8075
-     use neighbor-group MIX_IPV4_PUBLIC
-     description MIX: Microsoft
-     address-family ipv4 unicast
-      maximum-prefix 1500 95 restart 5
      !
     !
-    neighbor 217.29.66.158
-     remote-as 24482
-     use neighbor-group MIX_IPV4_PUBLIC
-     description MIX: SG.GS
-     address-family ipv4 unicast
     !
     !
    !
   !
end
The only correct chunk is for neighbor 217.29.66.112. All the others are missing some of the removed lines. 217.29.67.15 is even missing all of them. How bad is the code providing such a diff? I could go all day with examples such as these. Cisco TAC is happy to open a case in DDTS, their bug tracker, to fix specific occurrences of this bug.3 However, I fail to understand why the XR team is not just providing the diff between show run and show configuration merge. The output would always be correct!

  1. IOS XR has several limitations. The most inconvenient one is the inability to change the AS number in the router bgp directive. Such a limitation is a great pain for both operations and automation.
  2. This command could have been just show commit, as show commit changes diff is the only valid command you can execute from this point. Starting from IOS XR 7.5.1, show commit changes diff precise is also a valid command. However, I have failed to find any documentation about it and it seems to provide the same output as show commit changes diff. That s how clunky IOS XR can be.
  3. See CSCwa26251 as an example of a fix for something I reported earlier this year. You need a valid Cisco support contract to be able to see its content.

2 December 2022

Paul Wise: FLOSS Activities November 2022

Focus This month I didn't have any particular focus. I just worked on issues in my info bubble.

Changes

Issues

Review

Administration
  • Debian IRC: setup topic/entrymsg to redirect OFTC #debian-jp to the Debian Japan IRC server, cleaned up #debianppc ChanServ metadata
  • Debian wiki: unblock IP addresses, approve domains, approve accounts

Communication

Sponsors The libemail-outlook-message-perl, purple-discord, sptag, celery work was sponsored. All other work was done on a volunteer basis.

30 November 2022

Enrico Zini: Things I learnt in November 2022

Debian: Python:
>>> name="test"
>>> print(f" name= ")
name='test'
>>> print(f" 3*8= ")
3*8=24
Leaflet:

Russ Allbery: Review: The Fed Unbound

Review: The Fed Unbound, by Lev Menand
Publisher: Columbia Global Reports
Copyright: 2022
ISBN: 1-7359137-1-5
Format: Kindle
Pages: 156
The Fed Unbound is a short non-fiction exploration of US Federal Reserve actions to reducing systemic risk caused by shadow banking. Its particular focus is the role of the Fed from the 2008 financial crisis to the present, including the COVID shock, but it includes a history of what Menand calls the "American Monetary Settlement," the political compromise that gave rise to the Federal Reserve. In Menand's view, a central cause of instability in the US financial system (and, given the influence of the dollar system, the world financial system as well) is shadow banking: institutions that act as banks without being insured like banks or subject to bank regulations. A bank, in this definition, is an organization that takes deposits. I'm simplifying somewhat, but what distinguishes a deposit from a security or an investment is that deposits can be withdrawn at any time, or at least on very short notice. When you want to spend the money in your checking account, you don't have to wait for a three-month maturity period or pay an early withdrawal penalty. You simply withdraw the money, with immediate effect. This property is what makes deposits "money," rather than something that you can (but possibly cannot) sell for money, such as stocks or bonds. Most people are familiar with the basic story of how banks work. Essentially no bank simply takes people's money and puts it in a vault until the person wants it again. If that were the case, you would need to pay the bank to store your money. Instead, a bank takes in deposits and then lends some portion of that money out to others. Those loans, for things like cars or houses or credit card spending, come due over time, with interest. The interest rate the bank charges on the loans is much higher than the rate it has to pay on its deposits, and it pockets the difference. The problem with this model, of course, is that the bank doesn't have your money, so if all the depositors go to the bank at the same time and ask for their money, the bank won't be able to repay them and will collapse. (See, for example, the movie It's a Wonderful Life, or Mary Poppins, or any number of other movies or books.) Retail banks are therefore subject to stringent regulations designed to promote public trust and to ensure that traditional banking is a boring (if still lucrative) business. Banks are also normally insured, which in the US means that if they do experience a run, federal regulators will step in, shut down the bank in an orderly fashion, and ensure every depositor gets their money back (at least up to the insurance limit). Alas, if you thought people would settle for boring work that makes a comfortable profit, you don't know the financial industry. Highly-regulated insured deposits are less lucrative than acting like a bank without all of those restrictions and rules and deposit insurance payments. As Menand relates in his brief history of US banking, financial institutions constantly invent new forms of deposits with similar properties but without all the pesky rules: eurodollars (which have nothing to do with the European currency), commercial paper, repo, and many others. These forms of deposits are primarily used by large institutions like corporations. The details vary, but they tend to be prone to the same fundamental instability as bank deposits: if there's a run on the market, there may not be enough liquidity for everyone to withdraw their money at once. Unlike bank deposits, though, there is no insurance, no federal regulator to step in and make depositors whole, and much less regulation to ensure that runs are unlikely. Instead, there's the Federal Reserve, which has increasingly become the bulwark against liquidity crises among shadow banks. This happened in 2008 during the financial crisis (which Menand argues can be seen as a shadow bank run sparked by losses on mortgage securities), and again at a larger scale in 2020 during the initial COVID crisis. Menand is clear that these interventions from the Federal Reserve were necessary. The alternative would have been an uncontrolled collapse of large sections of the financial system, with unknown consequences. But the Fed was not intended to perform those types of interventions. It has no regulatory authority to reform the underlying financial systems to make them safer, remove executives who failed to maintain sufficient liquidity for a crisis, or (as is standard for all traditional US banks) prohibit combining banking and more speculative investment on the same balance sheet. What the Federal Reserve can do, and did, is function as a buyer of last resort, bailing out shadow banks by purchasing assets with newly-created money. This works, in the sense that it averts the immediate crisis, but it creates other distortions. Most importantly, constant Fed intervention doesn't create an incentive to avoid situations that require that intervention; if anything, it encourages more dangerous risk-taking. The above, plus an all-too-brief history of the politics of US banking, is the meat of this book. It's a useful summary, as far as it goes, and I learned a few new things. But I think The Fed Unbound is confused about its audience. This type of high-level summary and capsule history seems most useful for people without an economics background and who haven't been following macroeconomics closely. But Menand doesn't write for that audience. He assumes definitions of words like "deposits" and "money" that are going to be confusing or even incomprehensible to the lay reader. For example, Menand describes ordinary retail banks as creating money, even saying that a bank loans money by simply incrementing the numbers in a customer's deposit account. This is correct in the technical economic definition of money (fractional reserve banking effectively creates new money), but it's going to sound to someone not well-versed in the terminology as if retail banks can create new dollars out of the ether. That power is, of course, reserved for the Federal Reserve, and indeed is largely the point of its existence. Much of this book relies on a very specific definition of money and money supply that will only be familiar to those with economics training. Similarly, the history of the Federal Reserve is interesting but slight, and at no point does Menand explain clearly how the record-keeping between it and retail banks works, or what the Fed's "balance sheet" means in practice. I realize this book isn't trying to give a detailed description or history of the Federal Reserve system, but the most obvious audience is likely to flounder at the level of detail Menand provides. Perhaps, therefore, this book is aimed at an audience already familiar with macroeconomics? But, if so, I'm not sure it says anything new. I follow macroeconomic policy moderately closely and found most of Menand's observations obvious and not very novel. There were tidbits here and there that I hadn't understood, but my time would probably have been better invested in another book. Menand proposes some reforms, but they mostly consist of "Congress should do its job and not create situations where the Federal Reserve has to act without the right infrastructure and political oversight," and, well, yes. It's hard to disagree with that, and it's also hard to see how it will ever happen. It's far too convenient to outsource such problems to central banking, where they are hidden behind financial mechanics that are incomprehensible to the average voter. This is an important topic, but I don't think this is the book to read about it. If you want a clearer and easier-to-understand role of the Federal Reserve in shadow banking crises, read Crashed instead. If you want to learn more about how retail bank regulation works, and hear a strong case for why the same principles should be applied to shadow banks, see Sheila Bair's Bull by the Horns. I'm still looking for a great history and explainer of the Federal Reserve system as a whole, but that is not this book. Rating: 5 out of 10

29 November 2022

Jonathan McDowell: onak 0.6.2 released

Over the weekend I released a new version of onak, my OpenPGP compatible keyserver. At 2 years since the last release that means I ve at least managed to speed up a bit, but it s fair to say its development isn t a high priority for me at present. This release is largely driven by a collection of minor fixes that have built up, and the knowledge that a Debian freeze is coming in the new year. The fixes largely revolve around the signature verification that was introduced in 0.6.0, which makes it a bit safer to run a keyserver by only accepting key material that can be validated. All of the major items I wanted to work on post 0.6.0 remain outstanding. For the next release I d like to get some basic Stateless OpenPGP Command Line Interface support integrated. That would then allow onak to be tested with the OpenPGP interoperability test suite, which has recently added support for verification only OpenPGP implementations. I realise most people like to dismiss OpenPGP, and the tooling has been fairly dreadful for as long as I ve been using it, but I do think it fills a space that no competing system has bothered to try and replicate. And that s the web of trust, which helps provide some ability to verify keys without relying on (but also without preventing) a central authority to do so. Anyway. Available locally or via GitHub.
0.6.2 - 27th November 2022
  • Don t take creation time from unhashed subpackets
  • Fix ECDSA/SHA1 signature check
  • Fix handling of other signature requirement
  • Fix deletion of keys with PostgreSQL backend
  • Add support for verifying v3 signature packets

Sam Hartman: Introducing Carthage

For the past four years, I ve been working on Carthage, a free-software Infrastructure as Code framework. We ve finally reached a point where it makes sense to talk about Carthage and what it can do. This is the first in a series of blog posts to introduce Carthage, discuss what it can do and show how it works. Why Another IAC Framework It seems everywhere you look, there are products designed to support the IAC pattern. On the simple side, you could check a Containerfile into Git. Products like Terraform and Vagrant allow you to template cloud infrastructure and VMs. There are more commercial offerings than I can keep up with. We were disappointed by what was out there when we started Carthage. Other products have improved, but for many of our applications we re happy with what Carthage can build. The biggest challenge we ran into is that products wanted us to specify things at the wrong level. For some of our cyber training work we wanted to say things like We want 3 blue teams, each with a couple defended networks, a red team, and some neutral infrastructure for red to exploit. Yet the tools we were trying to use wanted to lay things out at the individual machine/container level. We found ourselves contemplating writing a program to generate input for some other IAC tool. Things were worse for our internal testing. Sometimes we d be shipping hardware to a customer. But sometimes we d be virtualizing that build out in a lab. Sometimes we d be doing a mixture. So we wanted to completely separate the descriptions of machines, networks, and software from any of the information about whether that was realized on hardware, VMs, containers, or a mixture. Dimensional Breakdown In discussing Carthage with Enrico Zini, he pointed me at Cognitive Dimensions of notation as a way to think about how Carthage approaches the IAC problem. I m more interested in the idea of breaking down a design along the idea of dimensions that allow examining the design space than I am particular adherence to Green s original dimensions. Low Viscosity, High Abstraction Reuse One of the guiding principles is that we want to be able to reuse different components at different scales and in different environments. These include being able to do things like: Hidden Dependencies To accomplish these abstraction goals, dependencies need to be non-local. For example, a software role might need to integrate with a directory if a directory is present in the environment. When writing the role, no one is going to know which directory to use, nor whether a directory is present. Taking that as an explicit input into the role is error-prone when the role is combined into large abstract units (bigger roles or collections of machines). Instead it is better to have a non-local dependency, and to find the directory if it is available. We accomplish this using dependency injection. In addition to being non-local, dependencies are sometimes hidden. It is very easy to overwhelm our cognitive capacity with even a fairly simple IAC description. An effective notation allows us to focus on the parts that matter when working with a particular part of the description. I ve found hiding dependencies, especially indirect dependencies, to be essential in building complex descriptions. Obviously, tools are required for examining these dependencies as part of debugging. First Class Modeling Clearly one of the goals of IAC descriptions is to actually build and manage infrastructure. It turns out that there are all sorts of things you want to do with the description well before you instantiate the infrastructure. You might want to query the description to build network diagrams, understand interdependencies, or even build inventory/bill of materials. We often find ourselves building Ansible inventory, switch configurations, DNS zones, and all sorts of configuration artifacts. These artifacts may be installed into infrastructure that is instantiated by the description, but they may be consumed in other ways. Allowing the artifacts to be consumed externally means that you can avoid pre-commitment and focus on whatever part of the description you originally want to work on. You may use an existing network at first. Later the IAC description may replace that, or perhaps it never will. As a result, Carthage separates modeling from instantiation. The model can generally be built and queried without needing to interact with clouds, VMs, or containers. We ve actually found it useful to build Carthage layouts that cannot ever be fully instantiated, for example because they never specify details like whether a model should be instantiated on a container or VM, or what kind of technology will realize a modeled network. This allows developing roles before the machines that use them or focusing on how machines will interact and how the network will be laid out before the details of installing on specific hardware. The modeling separation is by far the difference I value most between Carthage and other systems. A Tool for Experts. In Neal Stephenson s essay In the Beginning Was the Command Line , Stephenson points out that the kind of tools experts need are not the same tools that beginners need. The illustration of why a beginner might not be satisfied with a Hole Hog drill caught my attention. Carthage is a tool for experts. Despite what cloud providers will tell you, IAC is not easy. Doubly so when you start making reusable components. Trying to hide that or focus on making things easy to get started can make it harder for experts to efficiently solve the problems they are facing. When we have faced trade offs between making Carthage easy to pick up and making it powerful for expert users, we have chosen to support the experts. That said, Carthage today is harder to pick up than it needs to be. It s a relatively new project with few external users as of this time. Our documentation and examples need improvement, just like every project at this level of maturity. Similarly, as the set of things people try to do expand, we will doubtless run into bugs that our current test cases don t cover. So Carthage absolutely will get easier to learn and use than it is today. Also, we ve already had success building beginner-focused applications on top of Carthage. For our cyber training, we built web applications on top of Carthage that made rebuilding and exploring infrastructure easy. We ve had success using relatively understood tools like Ansible as integration and customization points for Carthage layouts. But in all these cases, when the core layout had significant reusable components and significant complexity in the networking, only an IAC expert was going to be able to maintain and develop that layout. What Carthage can do. Carthage has a number of capabilities today. One of Carthage s strengths is its extensible design. Abstract interfaces make it easy to add new virtualization platforms, cloud services, and support for various ways of managing real hardware. This approach has been validated by incrementally adding support for virtualization architectures and cloud services. As development has progressed, adding new integrations continues to get faster because we are able to reuse existing infrastructure. Today, Carthage can model: Carthage has excellent facilities for dealing with images on which VMs and Containers can be based, although it does have a bit of a Debian/Ubuntu bias in how it thinks about images: When instantiating infrastructure, Carthage can work with: We have also looked at Oracle Cloud and I believe Openstack, although that code is not merged. Future posts will talk about core Carthage concepts and how to use Carthage to build infrastructure.

comment count unavailable comments

28 November 2022

Jelmer Vernooij: Detecting Package Transitions

Larger transitions in Debian are usually announced on e.g. debian-devel, but it s harder to track the current status of all transitions. Having done a lot of QA uploads recently, I have on occasion uploaded packages involved in a transition. This can be unhelpful for the people handling the transition, but there s also often not much point in uploading if your uploads are going to get stuck. Talking to one of the release managers at a recent BSP, it was great to find out that the release team actually publish a data dump with which packages are involved in which transitions. Here s the script I use to find out about the transitions the package in my current working directory is involved in:
 1
 2
 3
 4
 5
 6
 7
 8
 9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
#!/usr/bin/python3
from urllib.request import urlopen
import sys
from debian.deb822 import Deb822
import yaml
with open('debian/control', 'r') as f:
    package = Deb822(f)['Source']
with urlopen("https://release.debian.org/transitions/export/packages.yaml") as f:
    data = yaml.safe_load(f)
def find_transitions(data, package):
    for entry in data:
        if entry['name'] != package:
            continue
        return dict(entry['list'])
    return  
transitions = find_transitions(data, package)
print(transitions)
sys.exit(1 if 'ongoing' in transitions.values() else 0)
In practice, the output looks something like this:
$ debcheckout bctoolbox
git clone https://salsa.debian.org/pkg-voip-team/linphone-stack/bctoolbox.git bctoolbox ...
Cloning into 'bctoolbox'...
...
$ cd bctoolbox
$ in-transition.py
 'auto-upperlimit-libbctoolbox1': 'ongoing' 

26 November 2022

Benjamin Mako Hill: The Financial Times has been printing an obvious error on its Market Data page for 18 months and nobody else seems to have noticed

Market Data section of the Financial Times US Edition print edition from May 5, 2021.
If you ve flipped through printed broadsheet newspapers, you ve probably seen pages full of tiny text listing prices and other market information for stocks and commodities. And you ve almost certainly just turned the page. Anybody interested in this market prices today will turn to the internet where these numbers are available in real time and where you don t need to squint to find what you need. This is presumably why many newspapers have stopped printing these types of pages or dramatically reduced the space devoted to them. Major financial newspapers however like the Financial Times (FT) still print multiple pages of market data daily. But does anybody read them? The answer appears to be no. How do I know? I noticed an error in the FT s Market Data page that anybody looking in the relevant section of the page would have seen. And I have seen it reproduced every single day for the last 18 months. In early May last year, I noticed that the Japanese telecom giant Nippon Telegraph and Telephone (NTT) was listed twice on the FT s list of the 500 largest global companies: once as Nippon T&T and also as Nippon TT. One right above the other. All the numbers are identical. Clearly a mistake.
Reproduction of the FT Market Data section showing a subset of Japanese companies from the FT 500 list of global companies. The duplicate lines are highlighted in yellow. This page is from today s paper (November 26, 2022).
Wondering if it was a one-off error, I looked at a copy of the paper from about a week before and saw that the error did not exist then. I looked at a copy from one day before and saw that it did. Since the issue was apparently recurring, but new at the time, I figured someone at the paper would notice and fix it quickly. I was wrong. It has been 18 months now and the error has been reproduced every single day. Looking through the archives, it seems that the first day the error showed up was May 5, 2021. I ve included a screenshot from the electronic paper version from that day and from the fifth of every month since then (or the sixth if the paper was not printed on the fifth) that shows that the error is reproduced every day. A quick look in the archives suggests it not only appears in the US edition but also in the UK, European, Asian, and Middle East editions. All of them. Why does this matter? The FT prints over 112,000 copies of its paper, six days a week. This duplicate line takes up almost no space, of course, so it s not a big deal on its own. But devoting two full broadsheet pages to market data that is out date as soon as it is printed much of which nobody appears to be reading doesn t seem like a great use of resources. There s an argument to made that papers like the FT print these pages not because they are useful but because doing so is a signal of the publications identities as serious financial papers. But that hardly seems like a good enough reason on its own if nobody is looking at them. It seems well past time for newspapers to stop wasting paper and ink on these pages. I respect that some people think that printing paper newspapers at all is wasteful when one can just read the material online. Plenty of people disagree, of course. But who will disagree with a call to stop printing material that evidence suggests is not being seen by anybody? If an error this obvious can exist for so long, it seems clear that nobody not even anybody at the FT itself is reading it.

25 November 2022

Russ Allbery: podlators 5.00

podlators is my collection of POD formatting modules, which generate *roff or text (possibly with escape sequence markup) from the documentation format used by Perl and some other packages. This is a major release, the biggest since the Pod::Simple rewrite in 2005. The headline news is that after some fairly extensive investigation, this release of Pod::Man finally changes the default output format to Unicode. No more replacement of characters in people's names, or text in non-English languages, with ugly X characters! There is a new encoding option to set the output encoding, and new options groff (which uses the groff extension for Unicode code points and is the default on EBCDIC systmes) and roff (which does the old, broken X substitution). Since this was a major backward-incompatible change, I also finally removed most of the formatting touch-ups that Pod::Man tried to do for troff output but which would be invisible for the (by far more commonly used) nroff output. These have been an endless source of bugs and are very difficult to maintain, most of them were of marginal utility, and I am dubious many people are using troff to print Perl manual pages these days instead of, say, printing the rendered output from one of the many excellent POD to HTML modules. There is some remaining somewhat-Perl-specific guesswork applied to the formatting, which is much simpler, but even that can now be turned off with the new guesswork option. This will allow people using POD to generate manual pages for things other than Perl modules to disable the Perl-specific markup logic. Pod::Text also now supports encoding and gets some major encoding cleanups, including using Encode instead of PerlIO encoding layers for its output. There are also numerous other fixes and improvements: a new language option to Pod::Man to configure (in an unfortunately groff-specific way) the line-breaking rules for languages like Chinese and Japanese, conversion of zero-width spaces to the *roff \: equivalent, a fix for wrapping L<> inside S<>, and various other bug fixes. Perhaps the most interesting is a fix to a long-standing problem with the Pod::Man output where bold and italic text would extend too far if used in combination with C<> fixed-width text. This bug has been around forever without being noticed, and then two different people noticed it while I was preparing this release. You can get the latest release from CPAN or from the podlators distribution page. These changes should be incorporated into Perl core in due course, although given the substantial changes, that may require a baking period.

23 November 2022

Fran ois Marier: Name resolution errors in Ubuntu repositories while building a docker container

I ran into what seemed to be a DNS problem when building a Docker container:
Err http://archive.ubuntu.com jammy Release.gpg
  Could not resolve 'archive.ubuntu.com'
W: Failed to fetch http://archive.ubuntu.com/ubuntu/dists/jammy/Release.gpg  Could not resolve 'archive.ubuntu.com'
W: Some index files failed to download. They have been ignored, or old ones used instead.
I found that many solutions talked about setting the default DNS server explicitly in /etc/docker/daemon.json:
 
    "dns": ["1.1.1.1"]
 
but that didn't work for me. I noticed however that I was having these problems whenever I connected to my VPN. So what did work for me was restarting the docker daemon whenever there is a change in networking (e.g. enabling/disabling VPN) by putting the following in /etc/NetworkManager/dispatcher.d/docker-local:
#!/bin/sh
LOGFILE=/var/log/docker-restarts.log
if [ -z "$1" ]; then
    echo "$0: called with no interface" >> $LOGFILE
    exit 1;
fi
if [ "$1" = lo ]; then
    # Ignoring the loopback interface
    exit 0;
fi
case "$2" in
    up vpn-up down vpn-down)
        echo "$0: restarting docker due to action \ $2' on interface \ $1'" >> $LOGFILE
        /bin/systemctl restart docker.service
        ;;
    *)
        echo "$0: ignoring action \ $2' on interface \ $1'" >> $LOGFILE
        ;;
esac
and then making that new file executable:
chmod +x /etc/NetworkManager/dispatcher.d/docker-local
You can confirm that it's working as intended by watching the logs:
tail -f /var/log/docker-restarts.log
while enabling/disable your VPN or your network connection. If you don't see any output, then something is wrong and the Docker restart isn't happening.

Next.

Previous.