Search Results: "ed"

23 September 2013

Daniel Pocock: PostBooks packages available

A common theme that comes up in free software evangelism is the question of how to tap into the huge expenditure that small to medium-sized businesses make for off-the-shelf licensed software. It is well known that many small companies are paying over the odds compared to the site-license rates given to big business, so why is it that small businesses are not rushing to adopt free and open source solutions? The answer is not likely to be found by fighting a battle on pricing (even though it is a battle that free software is inherently well prepared for). Rather, the most compelling strategy involves helping businesses find better ways to solve their own problems. A problem that every business encounters in every industry is the maintenance of proper financial records. Up until now, packaged solutions like GnuCash and HomeBank, available in many Linux distributions, have only catered for the smallest businesses and household accounting. At the other end of the spectrum, solutions like Compiere/Adempiere and OpenERP require a level of effort to install and maintain that makes them unsuitable for small users and businesses that don't need their full range of features. OpenERP briefly appeared as a Debian package but subsequently dropped out due to difficulties supporting the package. There is another choice, PostBooks. PostBooks has recently been packaged for Debian and this experience leads me to believe it will be supportable in Fedora and other distributions too. PostBooks, which started off as a commercial product, was re-licensed as an open source solution in 2007. In March 2013, PostBooks was project of the month on Sourceforge. Of particular note,
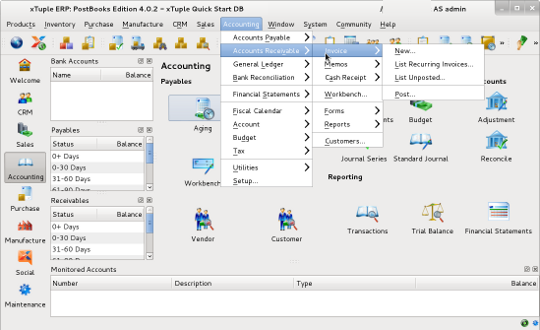
  • PostBooks has a Qt-based GUI where users of equivalent commercial solutions are likely to feel comfortable very quickly
  • PostBooks does not depend on any dedicated server processes other than a PostgreSQL database
  • Using the quickstart database, it can be set up in less than half a day, making it suitable for many consultants and freelancers who may otherwise use a product having a setup wizard (such as QuickBooks).
  • However, with features like inventory, invoicing, a sophisticated data import GUI (known as CSVImp), a true SQL backend, multi-currency and multiple concurrent users, it scales beyond the use cases that Quickbooks and Sage Accounting are capable of servicing.
  • The company behind PostBooks, xTuple, is well established and offers related services such as training and an annual user conference (which takes place in just a few weeks). Many business users are likely to find this style of support very reassuring and familiar, even if they don't plan to immediately take advantage of these things.
Limitations Two particular limitations caught my attention early when evaluating PostBooks: The developers have acknowledged these limitations and offered to complete these solutions with a crowd-funding campaign dubbed Feature Mob 2.

While everybody likes a free lunch, I personally feel that developers are perfectly entitled to request payment for their work. Having already taken a great leap of faith in open-sourcing a product that had previously been developed in-house, companies like xTuple need to look at new ways to generate revenue. Having looked at some of the prices of equivalent solutions, I felt quite comfortable pledging a similar amount based on four things:
  • it is based on the Kickstarter model, they only keep the money if their funding target is reached and feature implementation goes ahead
  • they are releasing the work as open source
  • the desire to have the option of using a highly capable free software solution that will be around well into the future
  • the probability that this is one piece of software that is likely to create more commercial opportunities for free software developers
Next steps People trying the packages and people who potentially want to package PostBooks for other distributions are very welcome to come and ask questions in the xTuple Debian maintainers packaging list or using the xTuple web forums. Please also feel free to report bugs through the Debian bug tracker.

Gunnar Wolf: This week it was an easy one: On picking free licensing schemes #encirc13

The third lesson of the Arte y cultura en circulaci n: crear y compartir en tiempos digitales course was quite easy, at least for me, as it's one of the topics I've been involved with for a long time: Authors' rights and ways to exercise them. This lesson starts by talking about the paradoxes created in the reality beneath copyright mostly due to the zero-cost-for-perfect-copy reality we live in today, and then goes on to introduce the most widely spread licensing schemes for cultural works nowadays: The Creative Commons licensing schemes. What I felt very interesting is that the lesson tackles the most common issues raised by authors choosing CC licensing: The Non-Commercial and Non-Derivatives restrictions. While authors are usually not very hard to convince about the virtues (and their personal benefit) in CC licensing, it's usually hard for authors to accept and relinquish the "locks" on non-derivability and non-commercial-use. Now, as to the homework: This time, I have to admit it was a no-brainer to me. The homework was to take part of a "Licenciat n": Publish some work under a open or free license (a work of any kind; it can be text, photo, video, etc.; it can be a new or a pre-existing work) and argue as to why did you choose said license. Even the act of writing this blog post means I'm releasing some work. The bottom of my blog reads, All the material found at this site is freely available, and you can use it as you wish, except when the document mentions explicitly different conditions. Yes, this is not a widely known, preexisting licensing scheme, and more or less goes along the lines of CC0 There are some good things I have posted in this blog, some things I am proud about. This post goes more towards the average quality: Not adding anything of great value to the world, just reiterating/reposting what is already said. But I know this blog is syndicated over several different places, and its content might be copied over to other places. I don't need to know or be notified about it. I just care for people to be able to reach back if they want to do it. But, of course, if I'm asked to do a homework, I prefer not to have it so self-referential. What else to license? We are over halfway across the Wiki Loves Monuments contest for 2013. This year I am clearly not as active on it as I was last year, but yesterday I uploaded about 60 photos from our recent trips, from historical monuments in some towns/cities within ~150Km of Mexico City: Puebla, Tlaxcala, Cacaxtla, Toluca, Santiago Tianguistenco. I intend to upload more. Those photos are licensed CC-BY-SA. Why? Mainly, because it is the defaul for the contest. One of the lessons learned working on Debian is that the less the license I choose deviates from what the upstream authors of a larger project prefer, the more useful my work will be. And being Wikimedia a host of many related projects, I prefer to completely abide by their recommendations unless there is a real, strong reason not to do so. Also, I know that at least most the photos I am uploading are not of contest quality (although some are quite nice, but we don't take that long to take a shot, and our camera is probably too basic to get a quality shot, if not by mere chance). I am using the WLM contest as an excuse to categorize and upload my pictures Of course, I'm not including personal photos, but... If I found a building, place or landscape interesting enough to take a photo of, why not make said photo available for whoever needs it, in a canonical, easy to reach media repository (as Wikimedia Commons) is)? And finally, I think it's time to start getting more open and forward-going with a project that I have been giving a lot of work during the past year, a project that has been even eating quite a bit of my Debian time: My upcoming book. While this book is not yet freely licensed (it is freely distributed online, but does not yet have an explicit license, and I mention it on my teaching/project page. Why? Because it still has some figures and data which are not mine, and which I have to re-elaborate to be able to legally license it. But anyway I am writing a book on the subject of Operating Systems, and am basing my teaching on it. The first semester was basically hell for me, as I was working almost full time on it, and needed to allocate some time as well to the rest of my formal work. This second semester has been quite smoother. And there is a very important (to me) initiative to which I (or should I now start saying, we) submitted this work: The LATIn Project: An initiative to collaboratively create quality, freely redistributable text books for the university level, natively in Spanish, for their use in Latin American countries. I was not able to propose this book due to some formalities Projects have to be proposed by professors in participant universities, and UNAM is not one of them. However, I offered this work to people in the Universidad Nacional de Rosario, Argentina, and they managed to push the project forward. Together with people from Universidad Aut noma de Aguascalientes (M xico) and Universidad del Cauca (Colombia), the project was approved by LATIn. And this LATIn project can also be seen as a why do you agree to license your work this way? candidate: I have already written most of what I'd be happy to call a full book. Of course, I do expect my colleagues to chime in with more content, and I expect us to produce a true collaborative project. But as I am not part of the member universities, they will get paid for their contribution And not me. What do I have to gain from this? More than anything else, the circulation of my work. I'm sure that, were I to publish from UNAM, I would have a good projection. I was (am!) thinking of looking for opportunities to present the book to teachers on the subject, as well as to computing engineering/science students, but the most attractive part (for me) for LATIn is that part of the prize will be that the book will be used to base work on for teaching at least during 2014 in the three said universities And of course, my/our work will only start then, as we will have to further circulate the work. Anyway... I expected this post to be small. But as you can see, I am happy with important work perspectives :-)

Ben Hutchings: Linux kernel update for wheezy (3.2.51-1)

The upcoming stable update for Debian (7.2) should have a new Linux kernel version, fixing various bugs. I have uploaded version 3.2.51-1 which is now available in wheezy-proposed-updates. I would appreciate any regression testing people can do before this is released. Also, this fixes one of the causes of lock-ups currently seen with newer Intel GPUs, though we don't know exactly which bug reports were due to this. If you've reported this kind of problem, please test whether this version fixes it. Updated 2013-09-23: KiBi reminded me to link to the page about proposed-updates. And the update is now available for all architectures.

22 September 2013

Russ Allbery: podlators 2.5.2

This is a bug-fix release to my POD translator package, which contains Pod::Man and Pod::Text and is used by Perl core to format POD documentation. This is not, alas, the long-awaited overhaul of UTF-8 handling; that's still coming at some point in the future. The primary changes in this release are various performance patches from Dagfinn Ilmari Manns ker from work on profiling all the Perl core modules. I learned from merging those packages that reversing a long string can make regex replacement operations on the tail faster, even with the time required to reverse the string twice. I'm surprised. This release also wraps the Pod::Simple parse_lines and parse_string_document to set the default output to STDOUT, similar to what was already done with parse_file, since some of the one-liners that people were testing would have produced confusing error messages without this. It fixes handling of POD documents with error sections and no other content, thanks to a bug report by Andreas Koenig. And it fixes typos and other documentation issues, thanks to Andreas, David Steinbrunner, and Brian Gottreu. You can get the latest release from the podlators distribution page.

Matthew Garrett: Implementing UEFI Boot to Zork

One of the earlier examples of students using MIT computer resources to lay the groundwork for a later commercial endeavour, Zork was originally written in a LISP derivative called MDL. This was later tuned into the Zork Implementation Language, a domain specific language that was compiled to target the Z-machine rather than a specific piece of hardware. Combined with machine-specific Z-machine interpreters, this allowed rapid porting of games to a wide range of platforms - the only thing that needed to be rewritten was the interpreter, and that could be reused for any future games running on the same hardware. Infocom were eventually acquired and killed off, but fan interest in their games continued. New Z-machine interpreters were written in order to allow their games (including Zork) to be run on platforms that Infocom had never targetted. One of the best known is Frotz. This has the advantage of being (a) portable and (b) including a "dumb" UI that makes no assumptions about the availablity of any vaguely useful functionality. Like, say, a Curses library. So, Frotz seemed like the natural choice when this happened. But despite having a set of functionality that makes it look much more like an OS than a boot environment, UEFI doesn't actually expose a standard C library. The EFI Application Development Kit solves this particular design decision. Porting Frotz ended up involving far more fixing up of Frotz bugs that tripped up -Werror than anything else. One note, though - make sure you include DevShell in the list of required packages at build time, otherwise file i/o will mysteriously fail. The tying of file i/o to the shell protocol unfortunately means that Frotz can't be directly launched by the firmware. The Boot to Zork images therefore contain a UEFI shell in the standard boot location (\EFI\BOOT\BOOTX64.EFI) which is executed when the firmware attempts to boot the device. The shell then looks for a file called "startup.nsh" in the root directory of the boot device and executes it. Unfortunately this doesn't actually set the shell equivalent of the current device, and so just launching Frotz from startup.nsh fails when Frotz can't open the Zork data file. The solution for this is simple, if ugly - the script walks through the list of devices, looking for one that contains ZORK1.DAT in the root directory. It then changes to that device and launches Frotz. If Frotz exits, it then resets the system. This could be avoided by doing some more work and turning Frotz into a more UEFI-native application. Teaching Frotz to make native UEFI calls would avoid the requirement for the shell protocols, and the firmware provides a mechanism to obtain the path of the currently running executable which would avoid the need to explicitly locate the device. But I'm lazy and this was a "I'm spending the day on a plane" project initially inspired by a Sazerac-fuelled conversation during the UEFI plugfest, not a demonstration of UEFI best practices. UEFI Boot To Zork and the source code to the modified Frotz can be downloaded here.

comment count unavailable comments

Niels Thykier: Lintian 2.5.18.1

Today I had to pleasure of releasing Lintian 2.5.18.1. It is a minor bug fix release on top of Lintian 2.5.18 (which I also released today ). When I was about to deploy the new version of Lintian on lintian.debian.org, I noticed a couple of errors in the log file that smelled of bugs. Indeed, when I investigated them I found two bugs, which were both introduced in Lintian 2.5.17.

Due to another bug in 2.5.17 and the some of the false-positives fixes, we are now doing a full run on lintian.debian.org. After having run for 7 hours, Lintian passed cipux . My rough estimate suggests that it will take 8 days at the current rate. For comparision, when we added amd64, Lintian spent 5 days processing all the new binaries (plus their source and the old binaries built from those source packages).

Of course estimate is rather rough. In particular, I am not sure that the heavy duty groups (e.g. linux and libreoffice) are evenly spread out among the letters of the alphabeth. Anyhow, there will be no updates on lintian.debian.org for the next week or so.


Steve Kemp: Some days you just want to do nothing

Today I finally pushed out a new binary release of my slaughter server-automation tool. (Think "CFEngine-lite", with perl. full documetnation is available. Though nobody ever reads it.) Otherwise the weekend is being quiet; we spent last night mostly drinking vodka, until midnight rolled over, and along with some messing around with a camera ("Wow, your arms are getting bigger!") Today has consisted of a Turkish breakfast, an Indonesian dinner, and an ice-cream based tea. I could write more, but I'm hung-over. A rare thing for me.

Russ Allbery: Review: Throne of the Crescent Moon

Review: Throne of the Crescent Moon, by Saladin Ahmed
Series: Crescent Moon Kingdoms #1
Publisher: DAW
Copyright: January 2013
ISBN: 0-7564-0778-8
Format: Mass market
Pages: 367
Doctor Adoulla Makhslood is the last ghul hunter in Dhamsawaat. He's an old man, and tired, and increasingly uncertain whether he wants to continue putting his life in danger to fight one more fight. But there are no replacements; his young and idealistic dervish apprentice, despite obvious skill, is too inexperienced and uninterested in the knowledge and investigation that makes Adoulla so good at what he does. So, when a young boy shows up on his doorstep, a survivor of a vicious ghul attack, he goes hunting once again. And both finds something much darker and stronger than he expected and meets an unexpected ally: a shape-shifting girl who is herself a survivor of something far worse than ghuls. Throne of the Crescent Moon is a first-novel fantasy that has made quite a splash, including a Hugo nomination (although I thought a win was unlikely, and I was right). One of the more interesting comments I've read about it was the observation by Jo Walton that if it had come out in 1980, it would have been an amazing, unusually wonderful, non-normative book. That it isn't is evidence of the changes in fantasy since then. The field has grown. As you might guess from the publisher's insistence on comparing it with The Arabian Nights, and from the names mentioned above, this book is set in an unspecified Middle Eastern culture and draws heavily from its mythology. It does not contain any western characters; the entire story is native to its region. The same is true of the mythology, which gave it a refreshing originality for me. And while I'm not the best one to judge, the presentation of that setting seemed free of the tint of the exotic. People live here, there are factions and multiple cultures, and the supernatural is a backdrop to most of the city. This would be very unusual decades ago. It's a bit less unusual now, and the story itself is a familiar ensemble fantasy, if refreshingly free of extended map exploration journeys. Ahmed brings together five characters with very different backgrounds and throws their varying talents at a problem. A few of those elements are a bit too familiar: female sexuality as a threat to male power is a world-building element that I could do without, for example. I also found the villain completely inadequate in its unidimensional evil (reinforced with a few more torture scenes than I needed to read), and even the attempted complication felt too predictable to me. Except for one touch of perspective, I'd call Throne of the Crescent Moon a competent, enjoyable, but somewhat forgettable fantasy novel, albeit one that's refreshingly concerned with a city instead of countrysides and travel. That touch is in the age of several of the protagonists. We get sections following several of the main characters in tight third person, but Adoulla is the first protagonist and the focus of much of the book. And Adoulla is neither young nor inexperienced, and is not going through the typical fantasy bildungsroman. He's old, experienced, a bit set in his ways, cranky, cantankerous, and deeply in love with his city. In tone, this shifts the story towards Star Wars as seen through the eyes of Obi-Wan Kenobi instead of Luke Skywalker. And that change I really liked, and would be happy to see become more common in fantasy. There was a bit of a downside for me in three of the five main characters being older. At times, Throne of the Crescent Moon has an elegiac tone, a feeling of life, power, and time slipping away and cultures and ways of life being lost. That's not my favorite thematic element. I tend to find it more depressing than I really want in my reading. But, here, the mature perspective more than makes up for some occasional negativity. I particularly liked how the older characters treated the likely budding young romance, which would have been the center of many books in this genre, with bemused detachment and playful encouragement without giving it more significance than it deserves. There's another romance that ends up being more significant, and which needs the weight of time and well-lived lives to become so. I don't think this book deserves a Hugo, but it is an enjoyable fantasy with some interesting characters and a refreshing perspective and setting. The villain really isn't adequate to the story, there's a bit too much torture for my liking, and I could have done without a few of the tropes, but it's a solid entry in its genre and a pleasant few hours of reading. And despite being advertised as the first of a series, it comes to a satisfying conclusion. Rating: 7 out of 10

Paul Tagliamonte: Musings about Debian and Python

On a regular basis, I find myself the odd-man-out when it comes to talking about how to work with Python on Debian systems. I'm going to write this and post it so that I might be able to point people at my thoughts without having to write the same email in response to each thread that pops up. Turns out I don't fit in with the Debian hardliners (which is to say, the mindset that pip sucks and shouldn't exist), nor do I fit in with the Python hardliners (which is to say apt and dpkg are out of date, and neither have a place on a Development machine). I think our discourse on this topic has become petty and stupid in general. Let's all try to step back and drop a bit of the attitude. pip doesn't suck, and neither does apt. The truth is, both sides are wrong. As with any subject, the real answer here is much more nuanced than either side presents it. I'm going to try and present my opinion on this, in the way that both my Pythonista self and my Debianite self see the issue. Hopefully I can keep this short, to the point, and caked with logic. The case for dpkg (the Debianite in me) In defense of dpkg and apt, imagine having to install python-gnome2 on all your systems when you install. It'd be hell on earth. Imagine having a user try to do this. It's insane to assume that end-users will be using pip for this purpose. pip is fun and all, but it's also installing 100% untrusted code to your system (perhaps as root, if you're using pip with sudo for some reason), and hasn't been reviewed for software freeness, which is something Debian (and Debian users) take seriously. This isn't even to mention the hell that pip wreaks on dpkg controlled files / packages. Try to remember how much of your system running (yes, right now) is running because of Python or Python modules. Try to imagine how much of a pain in the ass it'd be if you couldn't boot into GNOME to use nm-applet to connect to wifi to pip install something. I'm sure even the most extreme pip'er understands the need for Operating System level package management. Debian also has a bigger problem scope - we're not maintaining a library in Debian for kicks, we're maintaining it so that end user applications may use the library. When we update something like Django, we have to make sure that we don't break anything using it (although, to be honest, the fact that we package webapps is an entire rant for later) before we get to update it to the newest release. Hell, with a few coffees, I could automate the process of releasing a .deb with a new upstream release, 100% unattended. I won't, however, since this is an insane idea. Let's go over a brief list of things I do before uploading a new package:
  1. Review the entire codebase for simple mistakes.
  2. Review the entire codebase for license issues.
  3. Review the entire codebase for files without source, and track down (and include source for) any sourceless files (such as pickle files, etc).
  4. Get to know the upstream, get to know open bugs, write something using the lib, in case I need to debug later.
  5. Install the package.
  6. Test the package.
  7. Work out any Debian package issues (this is easy).
Now, a brief list of things I do before I update a package:
  1. Review the changes between the last uploaded version (in diff format, if it's sane, otherwise get the VCS and review), ensure all the above are still OK.
  2. Review for Debian-local issues (such as how it will upgrade, using piuparts, and adequate, etc).
  3. Check to make sure it won't break any reverse dependencies.
  4. Review for bugfixes that I might need to bring back to the stable release.
  5. Figure out if I should (or even can) backport the package, if API is stable.
  6. Review for bugs (upstream or in Debian) that I need to mention in the debian/changelog.
Clearly, this isn't a quick-and-dirty task. It's not a matter of getting a package updated (technically), it's a much more detailed process than that. This is also why Debian is so highly regarded for its technical virtuosity, and why the ISS decided to deploy Debian in space, despite other commercial distros such as Red Hat, or Ubuntu, and community distros, such as Fedora or Arch. It's also not Debian's job to package the world in the archive. This is an insane task, and it's not Debian's place to do it. We introduce libraries as things need them, not because we wrote some new library that someone may find slightly useful at some point in the future. maybe. Upstream developers and language communities (not only Python here) tend to lose sight of why we're doing this in the first place, which is our users. This isn't some sort of technical pissing contest to see who can distribute the software in the best way. Debian-folk always keep end users as our highest priority. I quote the Debian Social Contract, when I say that Our priorities are our users and free software. No one's trying to get developers to use dpkg to create software. In fact, as you'll see below, I actively discourage using system modules for development. The case for pip (the Pythonista in me) In defense of pip, the idea that Debian will keep the latest versions of packages is insane. The idea that we can keep pace with upstream releases is nuts, and the idea that every upstream release on pypi is ready to ship is bananas. b-a-n-a-n-a-annas. As a developer, I don't want to support every release, and I surely don't want other people depending on some random snapshot. Often times, I'll put stuff up on pypi as a preview, or to release often, and solicit feedback without having to give out instructions on using a git checkout (it's also easier to have them try a version from pypi so I can cross-ref the git tag to reproduce issues when they file them) pypi is easy, ubiquitous and works regardless of the platform, which means less of my development time is spent packaging stuff up for platforms I don't really care about (Arch, Fedora, OSX, Windows), even though I value feedback from users on those systems. The effort it takes to release something is limited to python setup.py sdist upload, and it's in a place (and in a shape) that anyone can use it without having 10 sets of platform-local instructions. Even ignoring all the above, when I'm writing a new app or bit of code, I want to be sure I'm targeting the latest version of the code I depend on, so that future changes to API won't hit me as hard. By following along with my dependencies' development, I can be sure that my code breaks early, and breaks in development, not production. Upstreams also tend to not like bug reports against old branches, so ensuring I have the latest code from pypi means I can properly file bugs. Lastly, I prefer virtualenv based setups for development, since I'm usually working on many things at once. This often means version mismatches in libraries, which brings in API changes (another whole rant here as well). I don't want to keep installing and uninstalling packages to switch between the two projects, and using a chroot(8) means a lot of overhead and that it's disconnected from my development environment / filesystem, so I resort to virtualenv to isolate my Development environment. Final notes I don't want to keep arguing about this. Just accept that the world's a big place and that there exist use-cases that both apt and pip need to exist and work in the way they're working now. At the very least, try and understand there exist smart people on both sides, and no one is trying to screw anyone over or keep their own little private club to themselves. Hopefully, going forward, we can make sure that the integration between these two tools gets better, not worse. Help make this dream a reality. Contribute to a productive tone, not a destructive one. In short:

21 September 2013

Niels Thykier: Lintian 2.5.18

I have just uploaded Lintian 2.5.18 to unstable. While fixing 22 bugs, it only features 5 new tags. The release also include fixes to some false-positives, such as python:any dependencies triggering python-script-but-no-python-dep, a rewritten README file. We also included a patch to make Lintian accept the Original-Maintainer field by default for non-Debian vendors (even if they do not have a profile and Lintian ends up loading the debian/main profile). We also added support for running Lintian directly from a git checkout or source tree without setting LINTIAN_ROOT (or passing root). Since that was the primary use-case for root that option has now been deprecated. I also had lintian and lintian-info require the include-dir and [no-]user-dir options as the first if given at all. I would like to thank Bastien Roucari s, Gaudenz Steinlin, Gunnar Wolf, J r my Bobbio and Lucas Nussbaum for contributing to Lintian and the many who submitted reports or suggestions for improvements. I would also like to thank Brian hugmeir Fraser, who assisted me in identifying and working around a bug in Perl s glob function when run under threads (filed upstream as RT#119897).

20 September 2013

James Morrison: Penances

I wrote up some potential penances a long time ago, here is what I thought of (or what I've had to do :):

First merge conflict from whitespace: Use a code review tool like gerrit that shows trailing whitespac

First merge conflict from whitespace: Add pre-commit hooks that remove whitespace

First time a feature is broken: Add a test for the feature, including the infrastructure for the test.

First time the client and server releases get out of sync: Run client tests against the released server and server code at top of tree.


James Morrison: Legacy code

I once attended a talk where the main point was that legacy code is any code that wasn't written with tests. Well, I think now legacy code is any code written without both tests and without code review. If you have only one the code is still legacy, it has a bus factor of one.

Vincent Sanders: Man is fully responsible for his nature and his choices.

Well at least he should be according to Sartre though I am not entirely convinced the repercussions of my choice to manufacture another folding chair were entirely thought through.

After my most recent posting the urge to do "just one more iteration" became too great and I succumbed. I therefore present version 4 of my folding chair which corrects all the previously discovered issues.

The popliteal height (420mm) and buttock popliteal length (400mm) are both comfortable for a wide selection of people. The seat slopes a few degrees front to back and the back rest no longer comes further forward than the rear of the seat.

There is a small gap above where the seat folds in when flat but that is only an aesthetic issue when being stored.

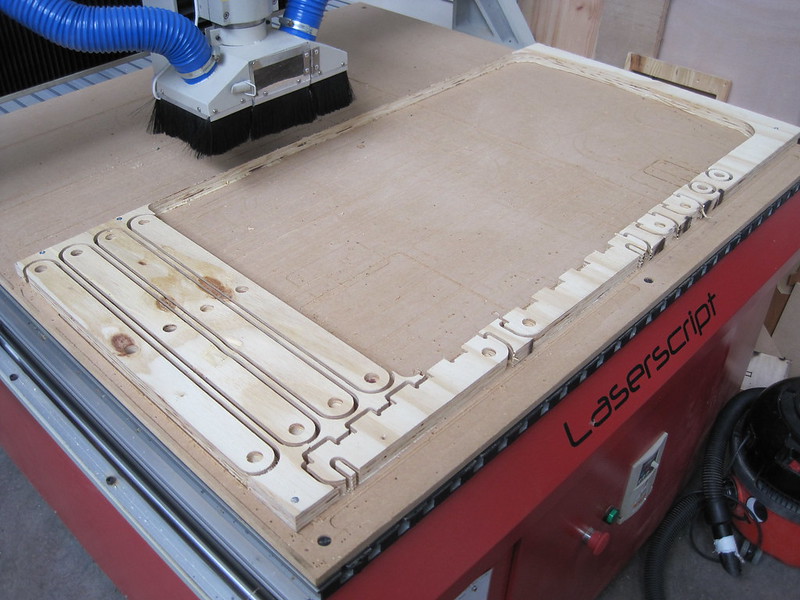
Manufacture wise the design is simple to produce although I really will have to teach our CNC router how to use the round over bit to reduce the finishing steps as currently that takes longer than the CNC operation.

In future if I make more of these I will use this design and, once she is less annoyed at me for making another chair, I am going to consult with my wife on adding some cushioning material to the seat and backrest.

And of course that concludes my furniture making for a while...yeah, right!

there have been comments which have complained about my usage of space on sheets and suggested I waste too much material. That is probably true and in my own defence I have not been working with this machine for very long and am not quite used to what I can "get away with" yet.

Side X folding stool
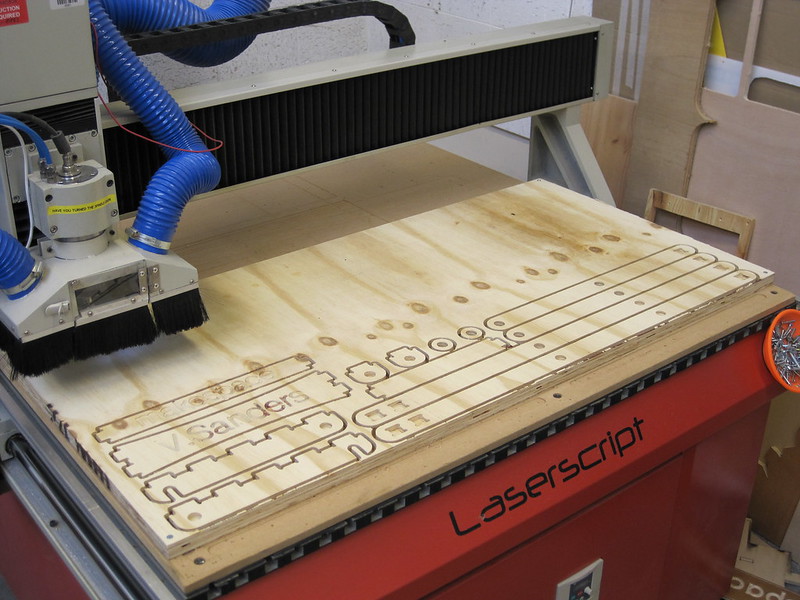
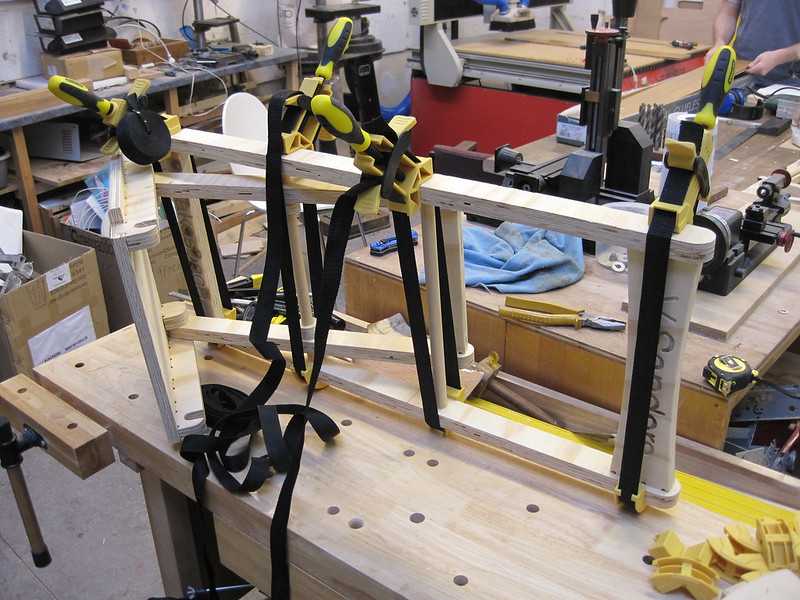
I was looking at the sheet after removing the last chair design and had a thought, I had not attempted a side X type folding design and perhaps I could squeeze one into the offcuts? I kinda got carried away, it roughly went:


Side X folding stool cut from sheet offcut
If all of that sounds like and utterly mad way to design a size X stool, you are of course correct, but it worked, and it was a very fast process taking less than four hours from idea to stool.

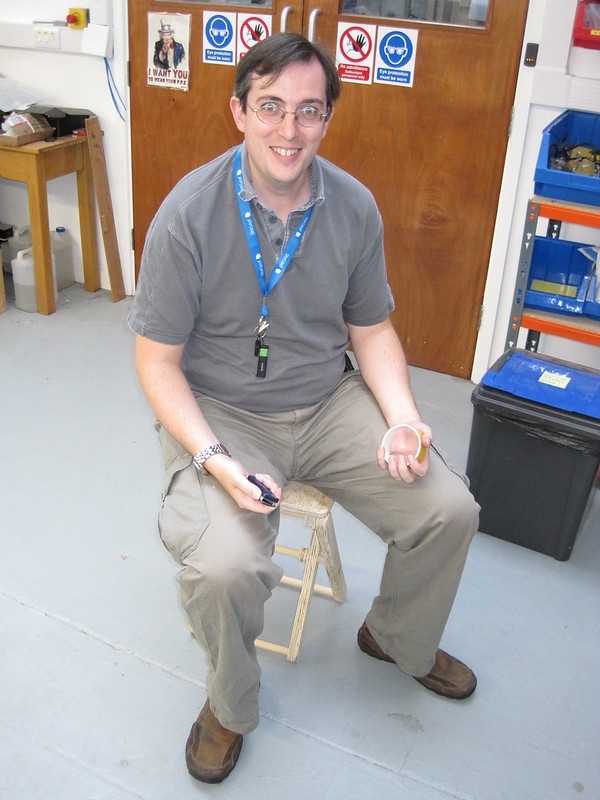
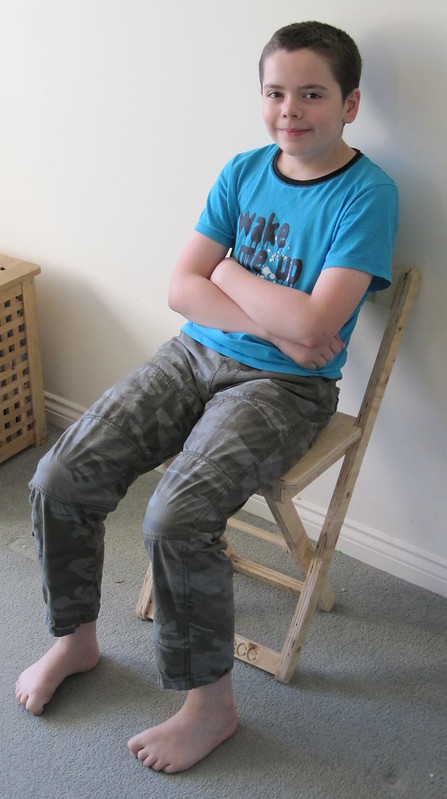
Paul testing the dry fit side X stool
There are a couple of issues:

Clamping stool why the glue drys
The seat went together dry fit and Paul tested it for me, however that last issue soon made me realise that this time I was going to have to resort to glue. Yes, sorry, this design needs to be glued to remain stable (I know plywood contains glue...please stop telling me that).


It is pretty simple to put together and aside from needing half the clamps in makespace to hold it in place while the glue dried, I had no trouble.

Though this is definitely not a case of use glue "sparingly" I put generous amounts in all the dowel joints and all the seat slots and got very little ooze so I guess it could have used more.

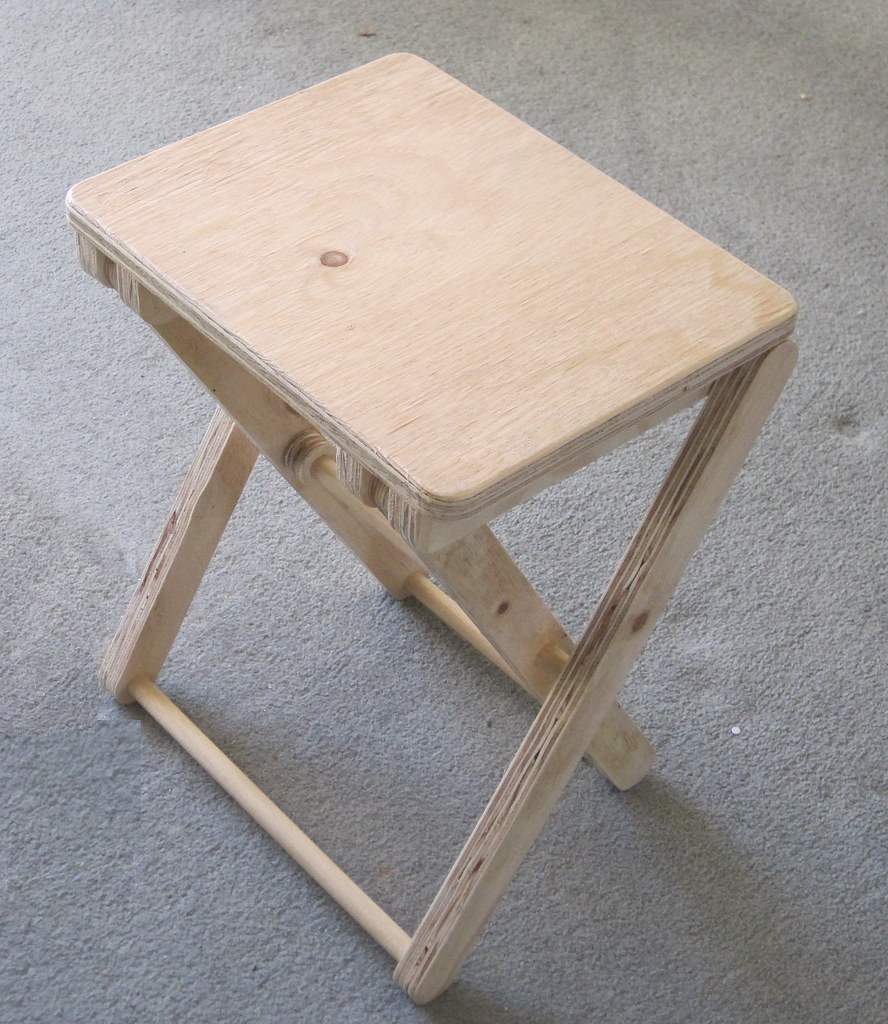
The final varnished stool is pretty robust but folds up nicely the concept of hooking to its own pivot dowel means it stays closed when flat which makes it very portable.

Total cost was an estimated 10.00 ( 4.25 dowel, 2.50 of 24mm ply, 1.75 for 18mm ply, 0.50 tool wear, 1.00 varnish) though the materials in my case could be argued to have cost nothing.

It has been suggested that I could make an entire picnic table and chairs set this way but if I did I would reduce the stool height by 50mm and examine ways to use less dowel.

This is usually the bit where I point you all at the freely usable design files on github and all the photos on flikr and wrap up.

But you know what the Monty Python boys say? "Nobody Expects the Spanish inquisition"

Or in this case my final (and yes I am going to do something else next) chair design. It is based on the stool, in fact it is the stool design with the outer legs extended and a back rest added.

The modified design reduces the dowel requirements to 775mm but requires a bit more sheet material (cannot get this one entirely from offcuts).

Total cost was an estimated 10.50 ( 2.50 dowel, 4.50 of 24mm ply, 1.75 for 18mm ply, 0.50 tool wear, 1.25 varnish).
Because it is based on the stool design it suffers from the height issue and in addition the back rest is a bit far back to be completely comfortable.

Neither of the side X designs have flaws that interest me enough to follow the iterative approach again to solve them. Both the designs work well enough and rounded out my adventures with folding chairs and indeed furniture for now.

As always the design files are on github and the images are on flikr.


Enrico Zini: Explanation of umarell

Explanation of umarell
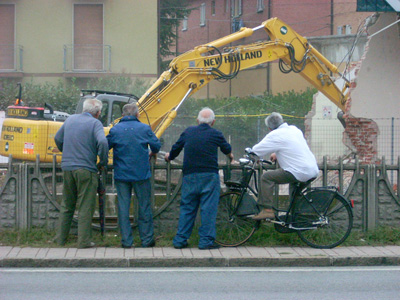
Umarell /uma'r l/ (oo-mah-rell), n; pl. Umarells. People in a community who offer all sorts of comments to those who are trying to get some work done, but who are not doing any work themselves.
Etymology and further details Umarell is a word that entered Italian slang in Bologna and is spreading to nearby towns, occasionally even across Italy. It comes from the Bolognese for "cute/odd little man". "Umarells" are those people, usually retired men, who spend time watching construction works, often holding their hands behind their back, occasionally commenting on what is going on, sometimes trying to tell the workers what to do. It's easy to find examples on the internet; the word was popularised by a blog collecting photos, which has even been published into a book. With some Italian Debian friends, we realised that umarell is the perfect word to describe those people in a community, who offer all sorts of comments to those who are trying to get some work done, but who are not doing any work themselves. I think that it is a word that fits perfectly, and since I'm likely going to use it blissfully anywhere, here is a page that temporarily explains what it means until the Oxford English Dictionary picks it up.

Russell Coker: Qi Phone Charging

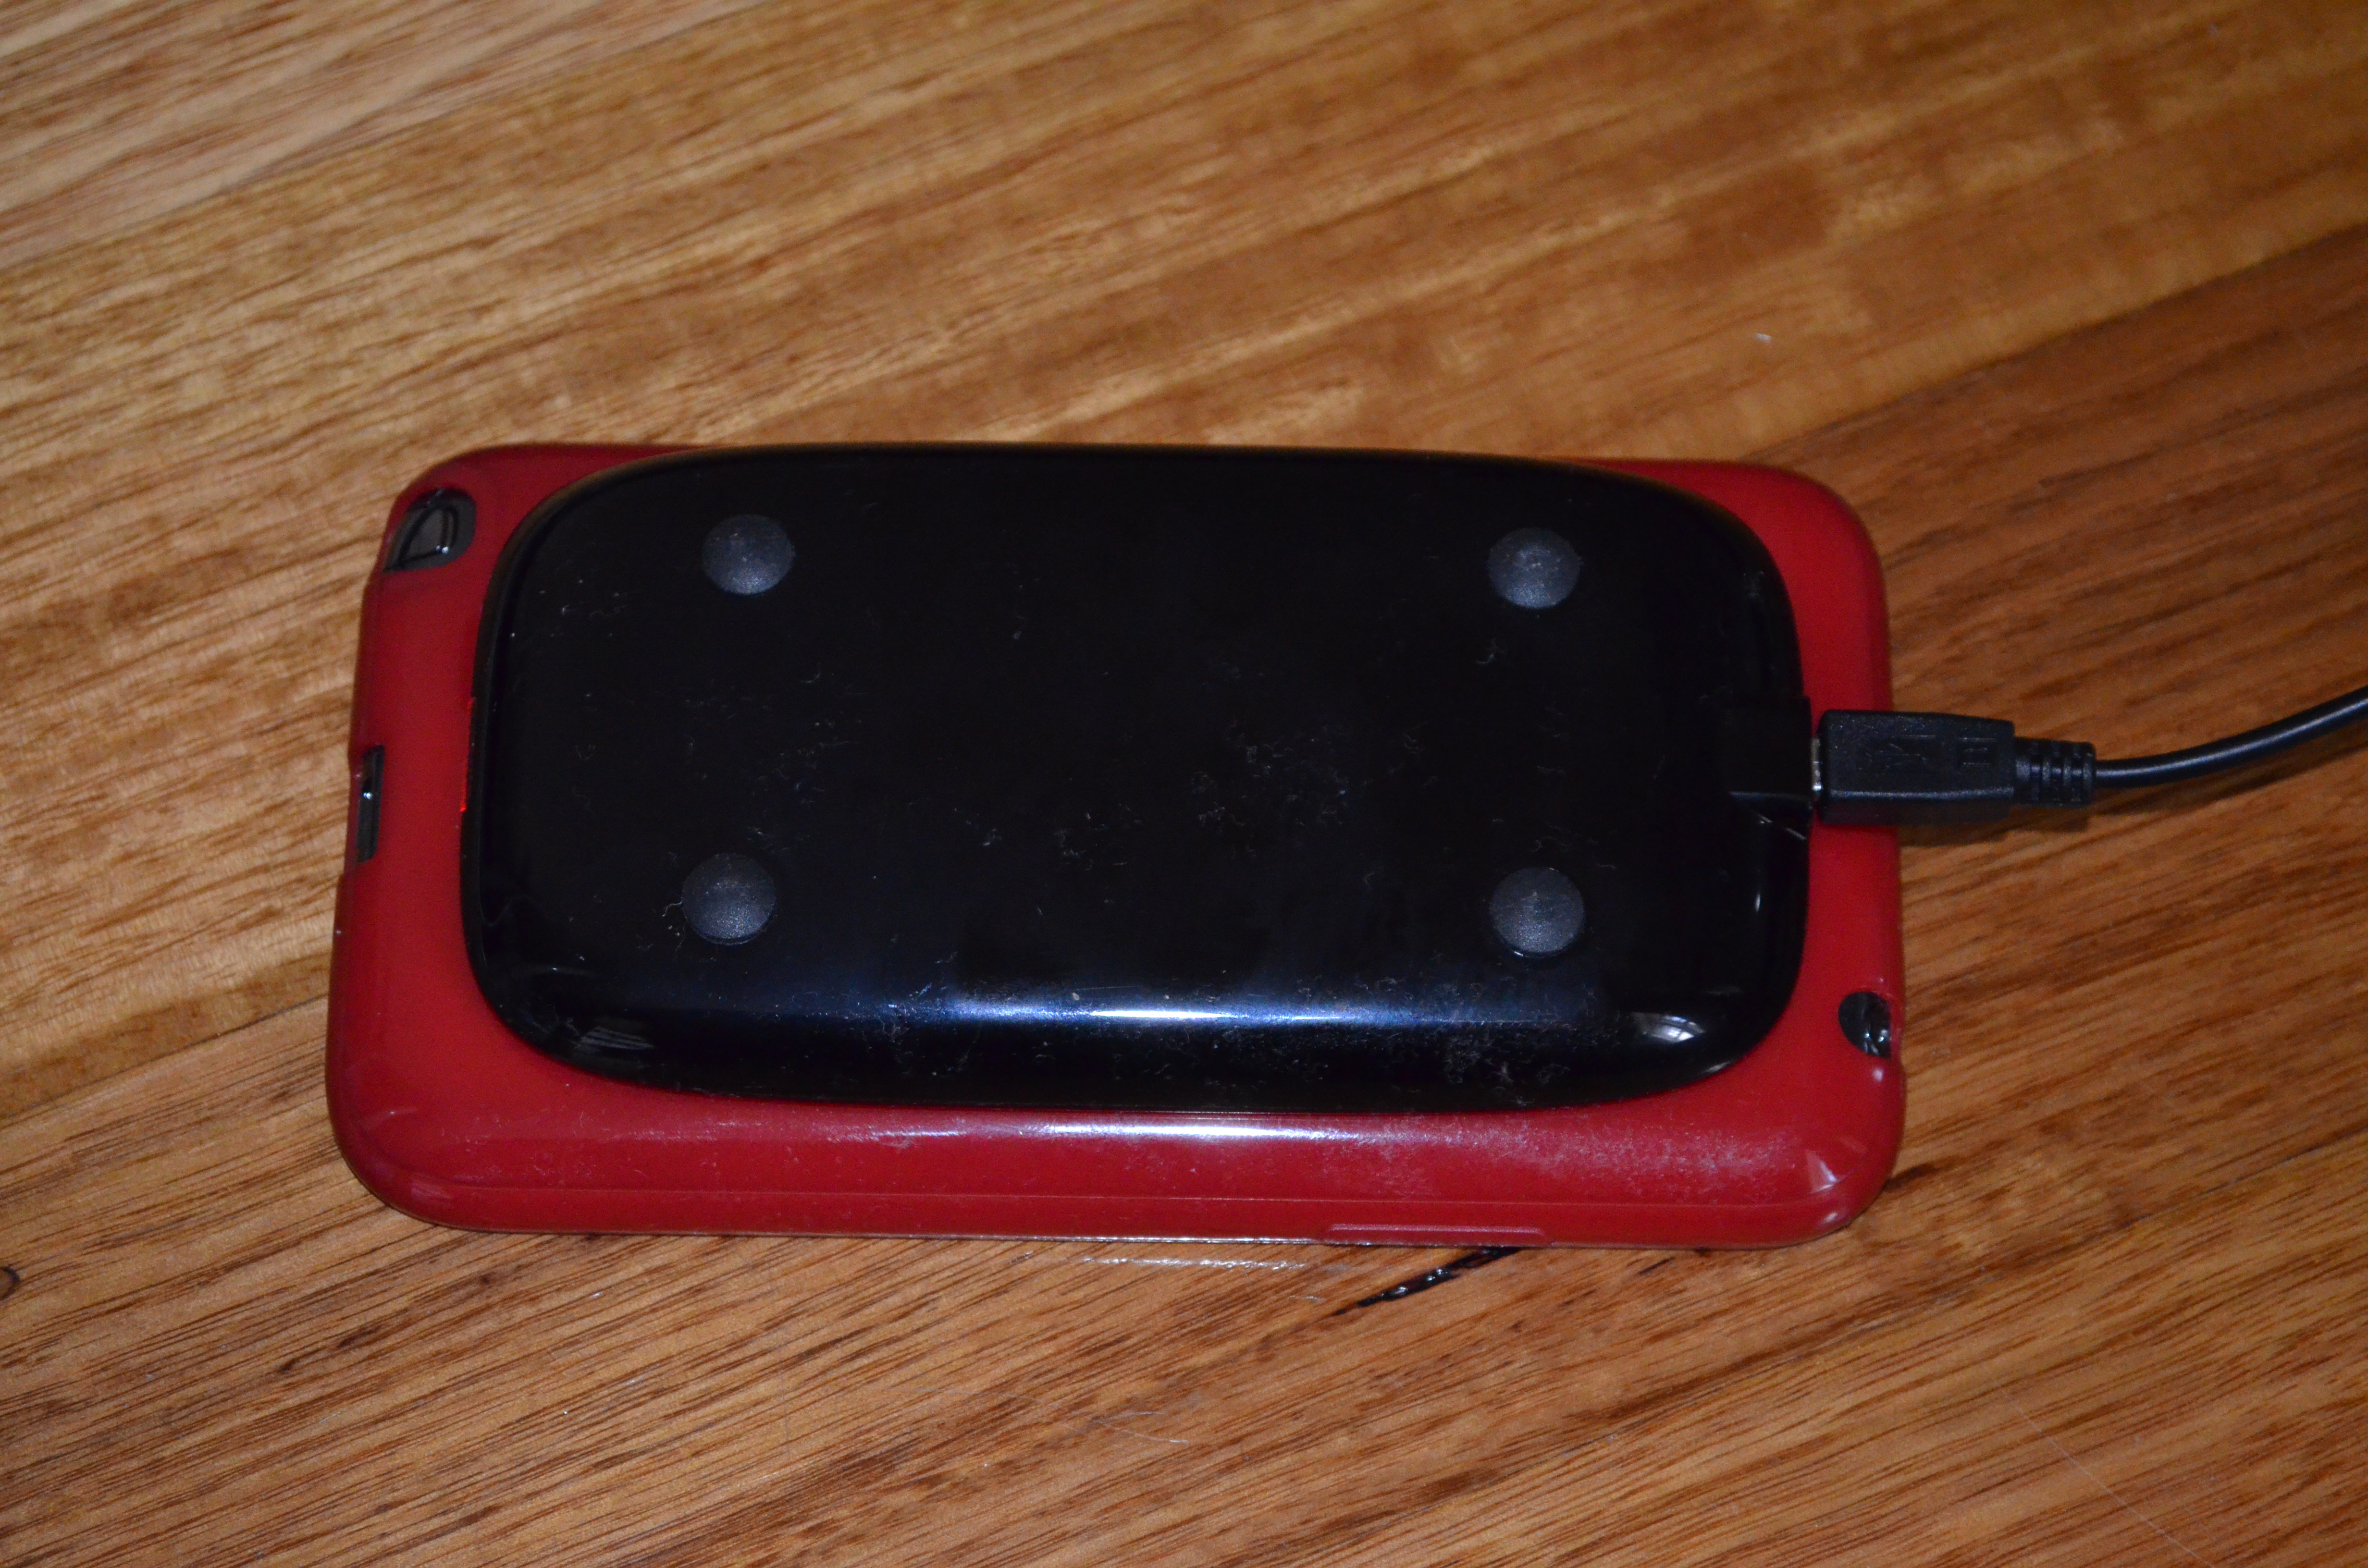
I have just bought a wireless phone charging system based on the Qi Inductive Power Standard. I bought a charging device which connects to a standard micro-USB cable and receivers for the Samsung Galaxy Note 2 and Samsung Galaxy S3 phones I own. Both those phones have contacts in the back of their case that are designed for wireless charging so you can install a charging device inside them. The charging devices make the case fit a little tight, and the charging device is stuck to the phone battery with contact adhesive, this makes it impractical to change the battery on a phone with such a device and makes it a little more difficult to swap out a battery case. One nice feature of the Nexus 4 is that it has Qi charging built in, that saved me $19 and was also more convenient. I believe that the main advantage of a wireless charger is to avoid the risk of damage to the phone if it s dropped while connected to a USB charger. This allows the phone to be charged in situations where you might need to quickly or regularly unplug it to go somewhere. One example of how I might use it is when working at an office so I could charge my phone while at my desk and then quickly take it with me if I had to go to a meeting (sadly I have worked in many offices where they have so many meetings). Another example is for sysadmin work where I have to frequently visit devices to fix them. The wireless charging mat that I bought from Kogan connects to a standard micro-USB plug, the good thing about this is that it s easy to find cables and it can take power from any PC. The bad thing about this is that the resistance of the USB cable is a factor that limits the power that a phone can receive, when using wireless charging you have the limit of the cable resistance as well as some power loss from the wireless transmission. After any extended period of charging the charging mat feels warm to the touch and the phone that s been resting on it feels warmer than usual. The warmth is an indication of energy loss which means longer charging times, a longer charging time isn t necessarily a problem as the convenience of wireless charging can allow longer charging times, but if you want to charge your phone in a hurry before you go somewhere then wireless isn t a good choice. In the past I ve discovered that the battery in a Samsung Galaxy S3 can t be charged if the phone is at 46C [1]. 46C might seem extremely hot to people in some parts of the world (EG northern Europe and Canada) but the temperature in even southern parts of mainland Australia can get that hot and it can be hotter in central and northern parts, so phone temperature can be a real issue. Currently my house is at 21C according to a digital thermometer, the Galaxy S3 and the Note 2 are being charged from USB and report temperatures of 27C and 23C respectively. While the thermometer in my house and those in the phones probably aren t really accurate it seems reasonable to assume that the battery of a relatively idle smart-phone that s being charged will be a few degrees warmer than the ambient temperature. The Qi charger makes things a lot worse as it even feels warm to the touch. So maybe a phone on a Qi charger would be 8 degrees warmer than the ambient temperature or more. That implies that in Australian summer weather a Qi charger won t be useful outside or in any building that lacks air-conditioning. So I think we can give up on the idea of using Qi devices to charge phones at a BBQ. Picture of Qi charger on top of Samsung Galaxy Note 2 The final problem I have is that the Qi device is quite small, I took the above picture with my phone face-down because no part of the charger is visible in normal use. With that size I can t just dump a phone like a Note 2 on top of the charging mat and expect it to work. I have to carefully place it so that it balances and so that the wireless receptor inside the phone matches the transmitter in the mat, if the phone isn t placed correctly then the Qi mat won t detect it and won t supply full power to the transmitter. Conclusion I m fairly disappointed in this device. The waste heat makes it unsuitable for Australian summer conditions and slows charging. The difficulty of correctly placing the phone reduces the convenience which is one of the major features. The price was $19 for each charging card for the Note 2 and the S3 and $29 for the charging mat to give a total of $67. I think it s worth the money for me to cover the risk of one of my phones having it s USB port damaged. Using a Qi charger on occasion will decrease the probability of such damage and allow the phone to be used after receiving certain types of damage. The prices of those phones nowadays are $389 for a Galaxy S3 (Kogan price), $250 for a Nexus 4 (when it was on sale in the Google store), and probably about $500 for a Galaxy Note 2 (last time Kogan offered them). So by paying $67 for Qi charging I believe that I m getting some degree of damage insurance for just over $1100 worth of phones. It seems likely that the Nexus 5 will ship with Qi charging support and that the Galaxy Note 3 will also support an optional Qi charging card (which will probably also be $19 or some similar price) so the charging mat should be useful for a long time. While I m disappointed I don t regret buying the device. But I would be hesitant to recommend it to other people and definitely wouldn t recommend it to someone who doesn t have a significant interest and investment in smart phones.

19 September 2013

Luca Falavigna: So long, and thanks for all the packages!

I ve been running several Deb-o-Matic instances on several servers since ages. This service, meant to provide a way to automate the build of Debian source packages, has been the starting point for a lot of Italian developers to start packaging, and eventually become Debian or Ubuntu developers. I can t exactly tell how many packages Deb-o-Matic servers have built so far, but it has been the primary build and test environment for at least three Debian Developers since four years. This service was hosted for free since the beginning, but the good things always come to an end. My provider decided they cannot keep our servers running (its core business is totally unrelated to hosting servers), and asked me to shut them down. I started with the two kfreebsd-* machines, and soon I will shut down i386 and amd64 as well. When all services will be down, I ll take care of removing the debian.net domains I created for them. Deb-o-Matic development won t stop, but developers who used Deb-o-Matic daily will have to find a different solution to build and test their packages.

Daniel Pocock: Install Debian wheezy and jessie directly with btrfs RAID1

Some time ago, I provided an installation report for installing Debian wheezy onto a btrfs RAID1 filesystem. It is not supported directly from the installer partitioning menu partman, but it is not hard to trick the installer to do it, as described in the bug report. I believe this may be a worthy release goal for Debian 8 (jessie), but it is not something I can commit to facilitate myself so I am sharing my experience with it for those who may want to volunteer. Anybody wanting to test it can easily do so with VirtualBox if they don't want to dedicate a real machine to it or if they don't have two real disks in their test machine. My own testing simply involved creating two VirtualBox virtual disks on a single SATA disk. Procedure Here is an abbreviated version of the procedure from the installation report linked above. Run the Debian installer as normal up to the partitioning menu Use manual partition mode Create one big btrfs partition on one HDD (either on a raw partition or on an LV) Designate the partition on one disk as the root FS, designate the partition on the other as unused/unformatted. Continue through the setup, installing to one disk After rebooting into Debian, follow these steps to add the other disk into a RAID1 A variation of this procedure is to use a shell while the installer is running to make the RAID1 during the installation and observe whether /etc/fstab is created correctly. Potential gotchas: is the default fstab sufficient or does it need to be modified after the conversion to RAID1? Does the initframfs need to be regenerated (and potentially modified by hand?) to make it work? Issues to be discussed / resolved Mixing BTRFS filesystems with Logical Volume Management - how many permutations should the installer support? What do people expect/need/require? How to boot if a disk fails? Can grub boot from either? Warning the user when the FS detects instability or failure in either disk

18 September 2013

Craig Small: Goodbye mygbiz

Google seems to try to invent new and interesting ways for spammers to spam me (and many others). I ve still not worked out a good way to block fake googlegroups which follow this method:
  1. Make new fake gmail login
  2. Make new fake google group
  3. Add lots of people s email addresses to the group
  4. Send lots of junk to these people
  5. Repeat when it gets closed down
I m not sure why groups aren t opt-in. A rather simple and standard way to stop this exact problem. Anyhow, the next new spammer enablement that the nice folks at Google have come up with is the mygbiz.com domain. These are temporary email addresses you can use when setting up Google apps. The only thing I have ever seen from them is spam. So I thought I d try to report some to Google. After looping around several help screens that were, despite their name, very unhelpful, I ve come to the conclusion that Google isn t too serious about fixing this problem. If you have postfix, the solution is very simple:
  1. vi /etc/postfix/access_sender
  2. Add a line like mygbiz.com REJECT
  3. postmap /etc/postfix/access_sender
  4. postfix reload
I find the results to this method far superior to trying to get Google interested in being responsible for a domain they run. If you want to use google apps then spend the $50 and get a domain. Alternatively don t use something that spammers abuse. Does it work? You bet it does!
Sep 18 23:26:38 elmo postfix/smtpd[19013]: NOQUEUE: reject: RCPT from mail-ye0-f208.google.com[209.85.213.208]: 554 5.7.1 <grace@sheiladolan.mygbiz.com>: Sender address rejected: Do not send from mygbiz.com domains; from=<grace@sheiladolan.mygbiz.com> to=<ME@MYDOMAIN> proto=ESMTP helo=<mail-ye0-f208.google.com>

Russell Coker: Advice for Web Editing

A client has recently asked for my advice on web editing software. There are lots of programs out there for editing web sites and according to a quick Google search there are free Windows programs to do most things that you would want to do. The first thing I m wondering about is whether the best option is to just get a Linux PC for web editing. PCs capable of running Linux are almost free nowadays (any system which is too slow for the last couple of Windows versions will do nicely). While some time will have to be spent in learning a new OS someone who uses Linux for such tasks will be able to use fully-featured programs such as the GIMP which are installed as part of the OS. While it is possible to configure a Windows system to run rsync to copy a development site to the production server and to have all the useful tools installed it s much easier to run a few apt-get or yum commands to install the software and then copy some scripts to the user s home directory. The next issue is whether web editing is the best idea. Sites that are manually edited tend to be very simple, inconsistent, or both. Some sort of CMS seems to be the better option. WordPress is a CMS that I m very familiar with so it s easy for me to install it for a client, while I try and resist the temptation to force my favorite software on clients there is the issue that I can install WordPress quickly which therefore saves money for my client. WordPress is a CMS that supports installing different themes (and has a huge repository of free themes). The content that it manages consists of pages and posts , two arbitrary types of document. Supporting two types of document with a common look and feel and common important data in a side-bar seems to describe the core functionality used by most web sites for small businesses. Does anyone have any other ideas for ways of solving this problem? Note that it should be reasonably easy to use for someone who hasn t had much experience at doing such things, it shouldn t take much sysadmin time to install or cost to run.

Raphael Geissert: A bashism a week: testing strings

The bashism of this week deals again with tests. How do you compare two strings to tell which one goes before or after the other in the alphabet in a shell script?
(also know as lexicographic comparison)

If you are familiar with perl and the relationship between its comparison operators and that of shell scripts, you would probably write the test as follows:


$ test bar '<' foo
$ test foo '>' bar


And yes, that would work, but not with all shells. I'm afraid to tell you that the < and > comparison operators are not required by the POSIX:2001 specification and are, therefore, bashisms.

What does this have to do with perl? well, the shell way is the inverse of the perl way.
What? In Perl you test the equality of two numbers with '==', in shell you use '-eq'; in perl the equality of strings is 'eq', in shell it is '='. In shell scripts you can compare two numbers with -gt (test 1 -gt 0) while in perl the equivalent comparison is with > (1 > 0).

So in this case the perl way is "bar lt foo" and based on the above the shell way should be "bar < foo". However, care must be taken when using such operators in shell scripts. Since < and > are used for redirections in shell scripts, one must quote them even when using bash. An alternative is to use the [[ special test function of bash which alters the shell syntax.

This time I didn't write a function to portably (or "somewhat portably") replace such comparisons. Feel free to share your solution in the comments, with bonus points if you come up with a solution without using external commands.

Next.

Previous.