Search Results: "ed"

28 September 2013

Jelmer Vernooij: Book Review: Bazaar Version Control

Packt recently published a book on Version Control using Bazaar written by Janos Gyerik. I was curious what the book was like, and they kindly provided me with a digital copy. The book is split into roughly five sections: an introduction to version control using Bazaar's main commands, an overview of the available workflows, some chapters on the available extensions and integration, some more advanced topics and finally, a quick introduction to programming using bzrlib. It is assumed the reader has no pre-existing knowledge about version control systems. The first chapters introduce the reader to the concept of revision history, branching and merging and finally collaboration. All concepts are first discussed in theory, and then demonstrated using the Bazaar command-line UI and the bzr-explorer tool. The book follows roughly the same track as the official documentation, but it is more extensive and has more fancy drawings of revision graphs. The middle section of the book discusses the modes in which Bazaar can be used - centralized or decentralized - as well as the various ways in which code can be landed in the main branch ("workflows"). The selection of workflows in the book is roughly the same as those in the official Bazaar documentation. The author briefly touches on a number of other software engineering topics such as code reviews, code formatting and automated testing, though not sufficiently to make it useful for people who are unfamiliar with these techniques. Both the official documentation and the book complicate things unnecessarily by listing every possible option. The next chapter is a basic howto on the use of Bazaar with various hosting solutions, such as Launchpad, Redmine and Trac. The Advanced Features chapter covers a wide range of obscure and less obscure features in Bazaar: uncommit, shelves, re-using working trees, lightweight checkouts, stacked branches, signing revisions and using e-mail hooks. The chapter on foreign version control system integration is a more extensive version of the public docs. It has some factual inaccuracies; in particular, it recommends the installation of a 2 year old buggy version of bzr-git. The last chapter provides quite a good introduction to the Bazaar APIs and plugin writing. It is a fair bit better than what is available publically. Overall, it's not a bad book but also not a huge step forward from the official documentation. I might recommend it to people who are interested in learning Bazaar and who do not have any experience with version control yet. Those who are already familiar with Bazaar or another version control system will not find much new. The book misses an opportunity by following the official documentation so closely. It has the same omissions and the same overemphasis on describing every possible feature. I had hoped to read more about Bazaar's data model, its file format and some of the common problems, such as parallel imports, format hell and slowness.

Steve Kemp: Some thoughts ..

It has taken just over two weeks for blogspam to reject 1 million SPAM comments. I'm not sure how paranoid I should be about false-positives now, (I accept false-negatives easily enough). Using node.js is pretty good for making toy servers, and on that basis here's another toy server: This is a small server which is designed to accept HTTP-POSTs containing a payload of a message, these are stored and later retrieved. Seems like a simple thing, right? Imagine how it is used:
root@server1:~# record-log Upgraded mysql
root@server2:~# record-log Tweaked /etc/sysctl.conf
root@server3:~# record-log Added user 'bob'
root@server3:~# record-log Added user 'steve'
Later:
root@server3:~# get-recent
1.2.3.4 2013-09-28T08:08:09.211Z
root:Added user 'bob'
1.2.3.4 2013-09-28T08:08:10.211Z
root:Added user 'steve'
In short it makes it easy to record "activity", and later retrieve it. A host can only fetch the entries it stored, but if you've got access to the remote server then you can get all logs. I suspect a more standard solution is to use syslog-ng, and logger, or similar. But it is a cute hack and I suspect if you've the discipline to record actions then this is actually reasonably useful.

Daniel Kahn Gillmor: RIP Cookiepuss

Yesterday, i said a sad goodbye to an old friend at ABC No Rio. Cookiepuss was a steadfast companion in my volunteer shifts at the No Rio computer center, a cranky yet gregarious presence. I met her soon after moving to New York, and have hung out with her nearly every week for years. [Cookiepuss -- No Dogs No Masters] She had the run of the building at ABC No Rio, and was friends with all sorts of people. She was known and loved by punks and fine artists, by experimental musicians and bike mechanics, computer geeks and librarians, travelers and homebodies, photographers, screenprinters, anarchists, community organizers, zinesters, activists, performers, and weirdos of all stripes. For years, she received postcards from all over the world, including several from people who had never even met her in person. In her younger days, she was a ferocious mouser, and even as she shrank with age and lost some of her teeth she remained excited about food. She was an inveterate complainer; a pants-shredder; a cat remarkably comfortable with dirt; a welcoming presence to newcomers and a friendly old curmudgeon who never seemed to really hold a grudge even when i had to do horrible things like help her trim her nails. After a long life, she died having said her goodbyes, and surrounded by people who loved her. I couldn't have asked for better, but I miss her fiercely.

27 September 2013

Erich Schubert: Big Data madness and reality

"Big Data" has been hyped a lot, and due to this now is burning down to get some reality checking. It's been already overdue, but it is now happening.
I have seen a lot of people be very excited about NoSQL databases; and these databases do have their use cases. However, you just cannot put everything into NoSQL mode and expect it to just work. That is why we have recently seen NewSQL databases, query languages for NoSQL databases etc. - and in fact, they all move towards relational database management again.
Sound new database systems seem to be mostly made up of three aspects: in-memory optimization instead of optimizing for on-disk operation (memory just has become a lot cheaper the last 10 years), the execution of queries on the servers that store the actual data (you may want to call this "stored procedures" if you like SQL, or "map-reduce" if you like buzzwords), and optimized memory layouts (many of the benefits of "colum store" databases come from having a single, often primitive, datatype for the full column to scan, instead of alternating datatypes in records.

However, here is one point you need to consider:
is your data actually this "big"? Big as in: Google scale.
I see people use big data and Hadoop a lot when they just shouldn't. I see a lot of people run Hadoop in a VM on their laptop. Ouch.
The big data technologies are not a one-size-fits-all solution. They are the supersize-me solution, and supersize just does not fit every task.
When you look at the cases where Hadoop is really successful, it is mostly in keeping the original raw data, and enabling people to re-scan the full data again when e.g. their requirements changed. This is where Hadoop is really good at: managing 100 TB of data, and allowing you to quickly filter out the few GB that you really need for your current task.
For the actual analysis - or when you don't have 100 TB, and a large cluster anyway - then just don't try to hadoopify everything.
Here is a raw number from a current experiment. I have a student work on indexing image data; he is implementing some state of the art techniques. For these, a large number of image features are extracted, and then clustering is used to find "typical" features to improve image search.
The benchmarking image set is 56 GB (I have others with 2 TB to use next). The subset the student is currently processing is 13 GB. Extracting 2.3 million 128 dimensional feature vectors reduces this to about 1.4 GB. As you can see, the numbers drop quickly.
State of the art seems to be to load the data into Hadoop, and run clustering (actually, this is more of a vector quantization than clustering) into 1000 groups. Mahout is the obvious candidate to run this on Hadoop.
However, as I've put a lot of effort into the data mining software ELKI, I considered also to try processing it in ELKI.
By cutting the data into 10 MB blocks, Mahout/Hadoop can run the clustering in 52x parallel mappers. k-Means is an iterative algorithm, so it needs multiple processes. I have fixed the number of iterations to 10, which should produce a good enough approximation for my use cases.
K-means is embarrassingly parallel, so one would expect the cluster to really shine at this task. Well, here are some numbers:

So what is happening? Why is ELKI beating Mahout by a factor of 10x?
It's (as always) a mixture of a number of things:
Let me emphasize this: I'm not saying, Hadoop/Mahout is bad. I'm saying: this data set is not big enough to make Mahout beneficial.

Conclusions: As long as your data fits into your main memory and takes just a few hours to compute, don't go for Hadoop.
It will likely be faster on a single node by avoiding the overhead associated with (current) distributed implementations.
Sometimes, it may also be a solution to use the cluster only for preparing the data, then get it to a powerful workstation, and analyze it there. We did do this with the images: for extracting the image features, we used a distributed implementation (not on Hadoop, but on a dozen PCs).
I'm not saying it will stay that way. I have plans for starting "Project HELKI", aka "ELKI on Hadoop". Because I do sometimes hit the barrier of what I can compute on my 8 core CPU in an "reasonable" amount of time. And of course, Mahout will improve over time, and hopefully lose some of its "Java boxing" weight.
But before trying to run everything on a cluster, always try to run it on a single node first. You can still figure out how to scale up later, once you really know what you need.
And last but not least, consider whether scaling up really makes sense. K-means results don't really get better with a larger data set. They are averages, and adding more data will likely only change the last few digits. Now if you have an implementation that doesn't pay attention to numerical issues, you might end up with more numerical error than you gained from that extra data.
In fact, k-means can effectively be accelerated by processing a sample first, and only refining this on the full data set then. And: sampling is the most important "big data" approach. In particular when using statistical methods, consider whether more data can really be expected to improve your quality.
Better algorithms: K-means is a very crude heuristic. It optimizes the sum of squared deviations, which may be not too meaningful for your problem. It is not very noise tolerant, either. And there are thousands of variants. For example bisecting k-means, which no longer is embarrassingly parallel (i.e. it is not as easy to implement on MapReduce), but took just 7 minutes doing 20 iterations for each split. The algorithm can be summarized as starting with k=2, then always splitting the largest cluster in two until you have the desired k. For many use cases, this result will be just as good as the full k-means result.
Don't get me wrong. There are true big data problems. Web scale search, for example. Or product and friend recommendations at Facebook scale. But chances are that you don't have this amount of data. Google probably doesn't employ k-means at that scale either. (actually, Google runs k-means on 5 mio keypoints for vector quantization; which, judging my experience here, can still be done one a single host; in particular with hierarchical approaches such as bisecting k-means)
Don't choose the wrong tool for the wrong problem!

Petter Reinholdtsen: Videos about the Freedombox project - for inspiration and learning

The Freedombox project have been going on for a while, and have presented the vision, ideas and solution several places. Here is a little collection of videos of talks and presentation of the project. A larger list is available from the Freedombox Wiki. On other news, I am happy to report that Freedombox based on Debian Jessie is coming along quite well, and soon both Owncloud and using Tor should be available for testers of the Freedombox solution. :) In a few weeks I hope everything needed to test it is included in Debian. The withsqlite package is already in Debian, and the plinth package is pending in NEW. The third and vital part of that puzzle is the metapackage/setup framework, which is still pending an upload. Join us on IRC (#freedombox on irc.debian.org) and the mailing list if you want to help make this vision come true.

Michal Čihař: Spring in Bohemian-Moravian Highlands

After quite some delay, I got to selecting some photos for my gallery. In spring, we've spend few days in Bohemian-Moravian Highlands with Pentax Friends. On the program there was of course taking some pictures and drinking beer or wine :-). You can find some small but nice waterfalls: In villages, there live wild animals: As the weather was not really nice, we had nice opportunity to shoot some pictures in fog: And last but not least, we've spent almost whole day taking pictures in Pilgrimage Church of Saint John of Nepomuk: The trip was really nice, though we could use better weather as most of the morning there were really no nice conditions for taking pictures.
Filed under: English Photography Travelling 0 comments Flattr this!

26 September 2013

Steve Kemp: Random hacking for fun

Recently I've been playing gtetrinet, against the publicly accessible server at tetrinet.debian.net. If you're unfamiliar with the game it is a multi-player variant of Tetris. You clear many lines and your opponents suffer. Want to make them suffer some more? Use the special blocks you acquire. Special blocks? How about shuffling your opponents playing field? Adding new semi-formed rows? etc. All good stuff. There is support for up to six players. To fire a special block at the player in field 1 you press "1". To fire the special block to the player in field 6 press "6". But to fire a block at yourself, to clear your playing field ("nuke") or remove a single line ("clear") you have to know what player-number you are, which will change from day to day, as it is literally a marker for the order you joined the channel in. It seems obvious that there should be a special-case keybinding "fire to self", and indeed there was bug #291844 filed in 2005 saying as much. I've just submitted a functional patch to resolve this, and already my playing is getting better. Join me sometime.

Martin Pitt: How to watch system D-BUS method calls

The current default D-BUS configuration (at least on Ubuntu) disallows monitoring method calls on the system D-BUS (dbus-monitor --system), which makes debugging rather cumbersome; this has worked years ago, but apparently got changed for security reasons. It took me a half an hour to figure out how to enable this for debugging, and as this has annoyingly little Google juice (I didn t find any solution), let s add some. The trick seems to be to set a global policy to be able to eavesdrop any method call after the individual /etc/dbus-1/system.d/*.conf files applied their restrictions, for which there is already a convenient facility. Create a file /etc/dbus-1/system-local.conf with
<?xml version="1.0" encoding="UTF-8" ?>
<!DOCTYPE busconfig PUBLIC
  "-//freedesktop//DTD D-BUS Bus Configuration 1.0//EN"
  "http://www.freedesktop.org/standards/dbus/1.0/busconfig.dtd">
<busconfig>
  <policy user="root">
    <!-- Allow everything to be sent -->
    <allow send_destination="*" eavesdrop="true"/>
    <!-- Allow everything to be received -->
    <allow eavesdrop="true"/>
    <allow send_type="method_call"/>
  </policy>
</busconfig>
Then sudo dbus-monitor --system displays everything. Needless to say that you don t want this file on any production system! Does anyone know an easier way? My first naive stab was to run dbus-monitor as root, but that doesn t make any difference at all. Update: Turns out this is already described in a better way at https://wiki.ubuntu.com/DebuggingDBus. Yay me for not finding that.. I updated above recipe to limit access to root, which is much better indeed.

Niels Thykier: Lintian 2.5.19

Today, I released Lintian 2.5.19. It is mostly a bug-fix release, but it also features a new tag. The new tag, homepage-in-binary-package, is emitted for packages where the source package has no Homepage-field, but one of its binaries do. The problem is that some tools (e.g. the PTS) only processes the data from the .dsc files (or Sources indices from the mirrors) and would in these cases miss the Homepage of the page. We now also carry a work around for a bug in tool, t1disasm, where it ends up in an infinite recursion (i.e. until the C call stack overflows). That issue is filed as #724571. The work around is to prevent Lintian from exiting with a failure (which causes packages to be auto-rejected when uploaded to Debian archive). These problems are currently reduced to a warning on stderr. In other (Lintian related news), the full run was completed yesterday after only 4 days (rather than the 8, I expected). While that is a pleasant surprise, I cannot find any changes in Lintian since the last run that would explain this difference. My current conjecture is that our last pseudo full run (when we added amd64) included more processing since the amd64 packages would not have any pre-collected information. With the follow up run to catch packages uploaded after the full run, Lintian spent a little more than 3 and half days (~86.5 hours) processing about 20700 package groups. This gives an average of about 240 groups an hour (or ~4 a minute). Though, remember these numbers include some data having been pre-collected from previous run on the majority of packages.

25 September 2013

Daniel Kahn Gillmor: half a minute for science!

A friend is teaching a class on data analysis. She is building a simple and rough data set for the class to examine, and to spur discussion. You can contribute in half a minute! Here's how:
  1. get a stopwatch or other sort of timer (whatever device you're reading this on probably has such a thing).
  2. start the timer, but don't look at it.
  3. wait for what you think is 30 seconds, and then look at the timer
  4. how many actual seconds elapsed?
The data doesn't need to be particularly high-precision (whole second values are fine). The other data points my friend is looking for are age (in years, again, whole numbers are fine) and gender. You can send me your results by e-mail, (i suspect you can find my address if you're reading this blog). Please put "half a minute for science" in the subject line, and make sure you include: Science thanks you!Tags: science

Jon Dowland: Married

Jon and Sarah
I got married! Sarah and I tied the knot on the 10th August this year. We married in a registry office where we live and had an evening reception on Tynemouth beach. A fantastic time was had by all. We honeymooned in Sorrento, Italy, which was fantastic. We spent one day visiting Pompeii (my fourth visit: about 6 hours on our feet this time, and we walked from one side right to the other); another day in Herculaneum (my second visit); one day visiting the village near where we were staying, where we visited a local food festival and bought the nicest Marmelade I've ever tasted; a few day and evenings in Sorrento town itself; but most of the time we just relaxed, swam, snoozed, read.

Lucas Nussbaum: Software for brainstorm / ideas sharing and voting?

Some time ago, Ubuntu had Ubuntu Brainstorm, a website where non-developers could submit ideas of improvements, and other people could comment and vote on them. I was wondering if there was existing software to deploy a similar service, e.g. as a plugin to popular forum software. I ve found ideascale.com, but relying on the Cloud for that is not acceptable for my planned use. (For clarification: my immediate interest for that is unrelated to Debian work)

Raphael Geissert: A bashism a week: aliases

In a response to my blogpost about bashisms in function names, reader Detlef L pointed out in a comment that aliases allow non-standard characters in their names, contrary to functions. They could then be used to, for example, set an alias of the run-parts(1) command (cf. the blog post).

Aliases indeed allow characters such as commas ( , ) to be used in the alias name. However, aliases are an extension to the POSIX:2001 specification and are therefore bashisms. Moreover, the characters set defined by POSIX does not include dashes.

Last but not least, aliases belong to the list of shell features that are usually "disabled" when the shell is run in non-interactive mode. I.e.


$ bash <<EOF
alias true=false;
if true; then echo alias disabled; else echo alias enabled; fi
EOF

alias disabled
$ bash -i <<EOF # force interactive mode
alias true=false;
if true; then echo alias disabled; else echo alias enabled; fi
EOF

$ alias true=false;
$ if true; then echo alias disabled; else echo alias enabled; fi
alias enabled
$ exit


To add to the fun of different behaviours, other shells always expand aliases.

If you decide to play with aliases you should note one thing: they are only enabled from the line after the definition. E.g. note the difference below

$ dash -c 'alias foo="echo foo"; foo'
dash: foo: not found
$ dash -c 'alias foo="echo foo";
foo'
foo

Sylvain Le Gall: OUnit 2.0 progress, September 2013

Continuing last month progress report onOUnit2. The release is just a few days away, I am testing real life application and the core of the work is already in the VCS. The basic features: Still remaining to do, but quite straightforward: Some things that I decided not to do for OUnit 2.0 release: The main development is now done, but before releasing I decided to test it first on a real scale application. The first big migration to OUnit2, will be the OASIS test suite. This is a pretty big test suite (100+ tests) that takes a fair amount of time to run. I hope that during the next week I will be able to port the whole test suite and come back with some timing results. You can follow my progress on porting OASIS to OUnit 2.0, in github. Help wanted If you have a long standing issue with OUnit, this is the time to submit a bug. OUnit BTS If you want to try the dev version of OUnit:
 $> darcs get http://forge.ocamlcore.org/anonscm/darcs/ounit/ounit
Patches always welcome. You can read the documentation of the devel version the website.

24 September 2013

Simon Josefsson: BLURB: Software repository metadata convention

As a maintainer of several software packages I often find myself copying text snippets from the README file into different places (savannah, github, freecode, emails, etc). Recently I had a need to generate a list of software packages that included every project s name, brief summary, license and URL. I could have generated that list manually by copying the text from every project s README and COPYING files. However then I would have to maintain my list manually to keep it in sync with all the projects. This easily leads to stale information, so I thought a better approach would be to put the information I needed into each projects source code version control system. The advantage is that the manual work to extract the information may be automated by a script, since the data is in a usable format. I ll explain here how my solution works. To be able to find the information using only the URL to the repository, I needed a filename convention. The filename I chose was BLURB; for the etymology, see Wikipedia s page about Blurb. The data format in the file is similar to normal email headers. An example illustrate the principles well. Below is the BLURB file for one of my projects.
Author: Yubico
Basename: libyubikey
Homepage: http://opensource.yubico.com/yubico-c/
License: BSD-2-Clause
Name: Yubico C low-level Library
Project: yubico-c
Summary: C library for manipulating Yubico YubiKey One-Time Passwords (OTPs)
The format is simple: UTF-8 text with each line starting with a header followed by a colon ( : ), some whitespace, and some content. If a line starts with whitespace, it is a continuation of the previous line s content (trim leading whitespace). The following table describes the fields that I use. I may update this blog post in the future with new fields or improved explanations (for reference, current date is 2013-09-24).
Header Meaning
Project Short identifier for the project (e.g., gcc , emacs )
Name Official name of the project in English
Summary Brief one-line summary of the project s purpose in English
Author Origin of the project
Homepage URL to the project s website
License License keyword, preferrably using one of the SPDX license identifiers
Basename The tarball basename, if different from the project name
Finally some reflection of the solution. After quick design, I thought that I couldn t be the first one with this problem, and I tried to find other similar efforts. I haven t been able to find any standardization effort that have the following properties: The related efforts that I found were SPDX which at first look seemed to offer what I wanted. However on closer examination it failed to deliver on all the requirements above, and appeared to have somewhat different goals. However I found the SPDX license list useful and refer to it. Another effort is Eric S. Raymond s freecode-submit and shipper but its primary focus is to encode information about each release. The design of the BLURB file is clearly influenced by these tools. Another influence has been Debian s specification for machine-readable copyright information. The Free Software Foundation s list of software projects seemed like another candidate, but it doesn t suggest any way to store the information in the upstream project itself. flattr this!

Raphael Geissert: Worse than no support

You are in need of support and you go ask in project x's forums (mailing list, online board, etc.) and get something worse than no support:

Responses from an incompetent with plenty of time and lots of FUD to spread.

Now that we have "umarell" thanks to Enrico Zini and other Italian folks, we need a name for the above.

Apologies to some readers who might be disappointed by this post. I don't like calling people names but I've seen too many of the above in less than two hours not to be tired.

Tanguy Ortolo: Working with XML using standard Unix tools

Like it or not, XML has been used everywhere, even in cases where text-based formats would have been sufficient. Unfortunately, standard tools such as grep, sed or awk are not really adapted to work with XML. Let us take the following example:
<chapter
    xmlns="http://docbook.org/ns/docbook" version="5.0">
    <title>The Debian distribution</title>
    <para>Debian is a free operating system, describing itself as  the
    universal operating system . It is mostly known as a GNU/Linux
    distribution, but it also exist in other variants such as GNU/Hurd
    and GNU/kFreeBSD </para>
</chapter>
PYX and xml2 There are at least two line-oriented alternative formats for XML: This is what our example would like in PYX:
(chapter
Aversion 5.0
-\n
(title
-The Debian distribution
)title
-\n\n
(para
-Debian is a free operating system, describing itself as
- the\n    universal operating system . It is mostly known as a GNU/Linux\n    distribution, but it also exist in other variants such as GNU/Hurd\n    and GNU/kFreeBSD 
)para
-\n
)chapter
And in the xml2 format:
/chapter/@xmlns=http://docbook.org/ns/docbook
/chapter/@version=5.0
/chapter/title=The Debian distribution
/chapter/para=Debian is a free operating system, describing itself as  the
/chapter/para=    universal operating system . It is mostly known as a GNU/Linux
/chapter/para=    distribution, but it also exist in other variants such as GNU/Hurd
/chapter/para=    and GNU/kFreeBSD 
Examples of use We want to extract the DocBook version number. This is not easy to do in a reliable way using the XML directly, but it appears directly with xml2:
$ xml2 < chapter.xml   grep '^/chapter/@version=' \
      cut -d= -f2
5.0
We want to move the title into an info tag, using PYX:
$ xmlstarlet pyx chapter.xml   sed -e '/^(title$/i\
(info
/^)title$/a\
)info'   xmlstarlet p2x
<chapter version="5.0">
    <info><title>The Debian distribution</title></info>
    [ ]
We could go further, adding a keywords entry in that info tag for instance, but you get the idea: when you want to work with XML in a reliable way, try xmlstarlet pyx or xml2.

23 September 2013

Justus Winter: Final GSoC report

This is my final report :) the GSoC was great, I learned a lot about the Hurd and Mach programming in general. I am also very pleased to announce that I reached my initial goal and almost all of my patches already made it upstream and into Debian :) I spent my last week fixing issues I introduced and splitting up /hurd/init into two programs. This would make it possible to integrate the patch that frees PID 1 for sysvinit into the Hurd upstream sources. I didn't quite finish the separation, but my proof of concept works and I will finish this as my next Hurd project. Looking back at the last fourteen weeks, I accomplished the following: I implemented /proc/mounts, umount, freed up PID 1 for sysvinit, fixed ifupdown, sysvinit and initscripts on Hurd, implemented a proof-of-concept cgroupfs and fixed many small issues along the way. Almost all of my patches are already upstream and in Debian, a Debian/Hurd booting using sysvinit is just a few uploads away. It has been a lot of fun and I will definitively see you around :) Justus

Russell Coker: Hive Bluetooth Stereo Speakers

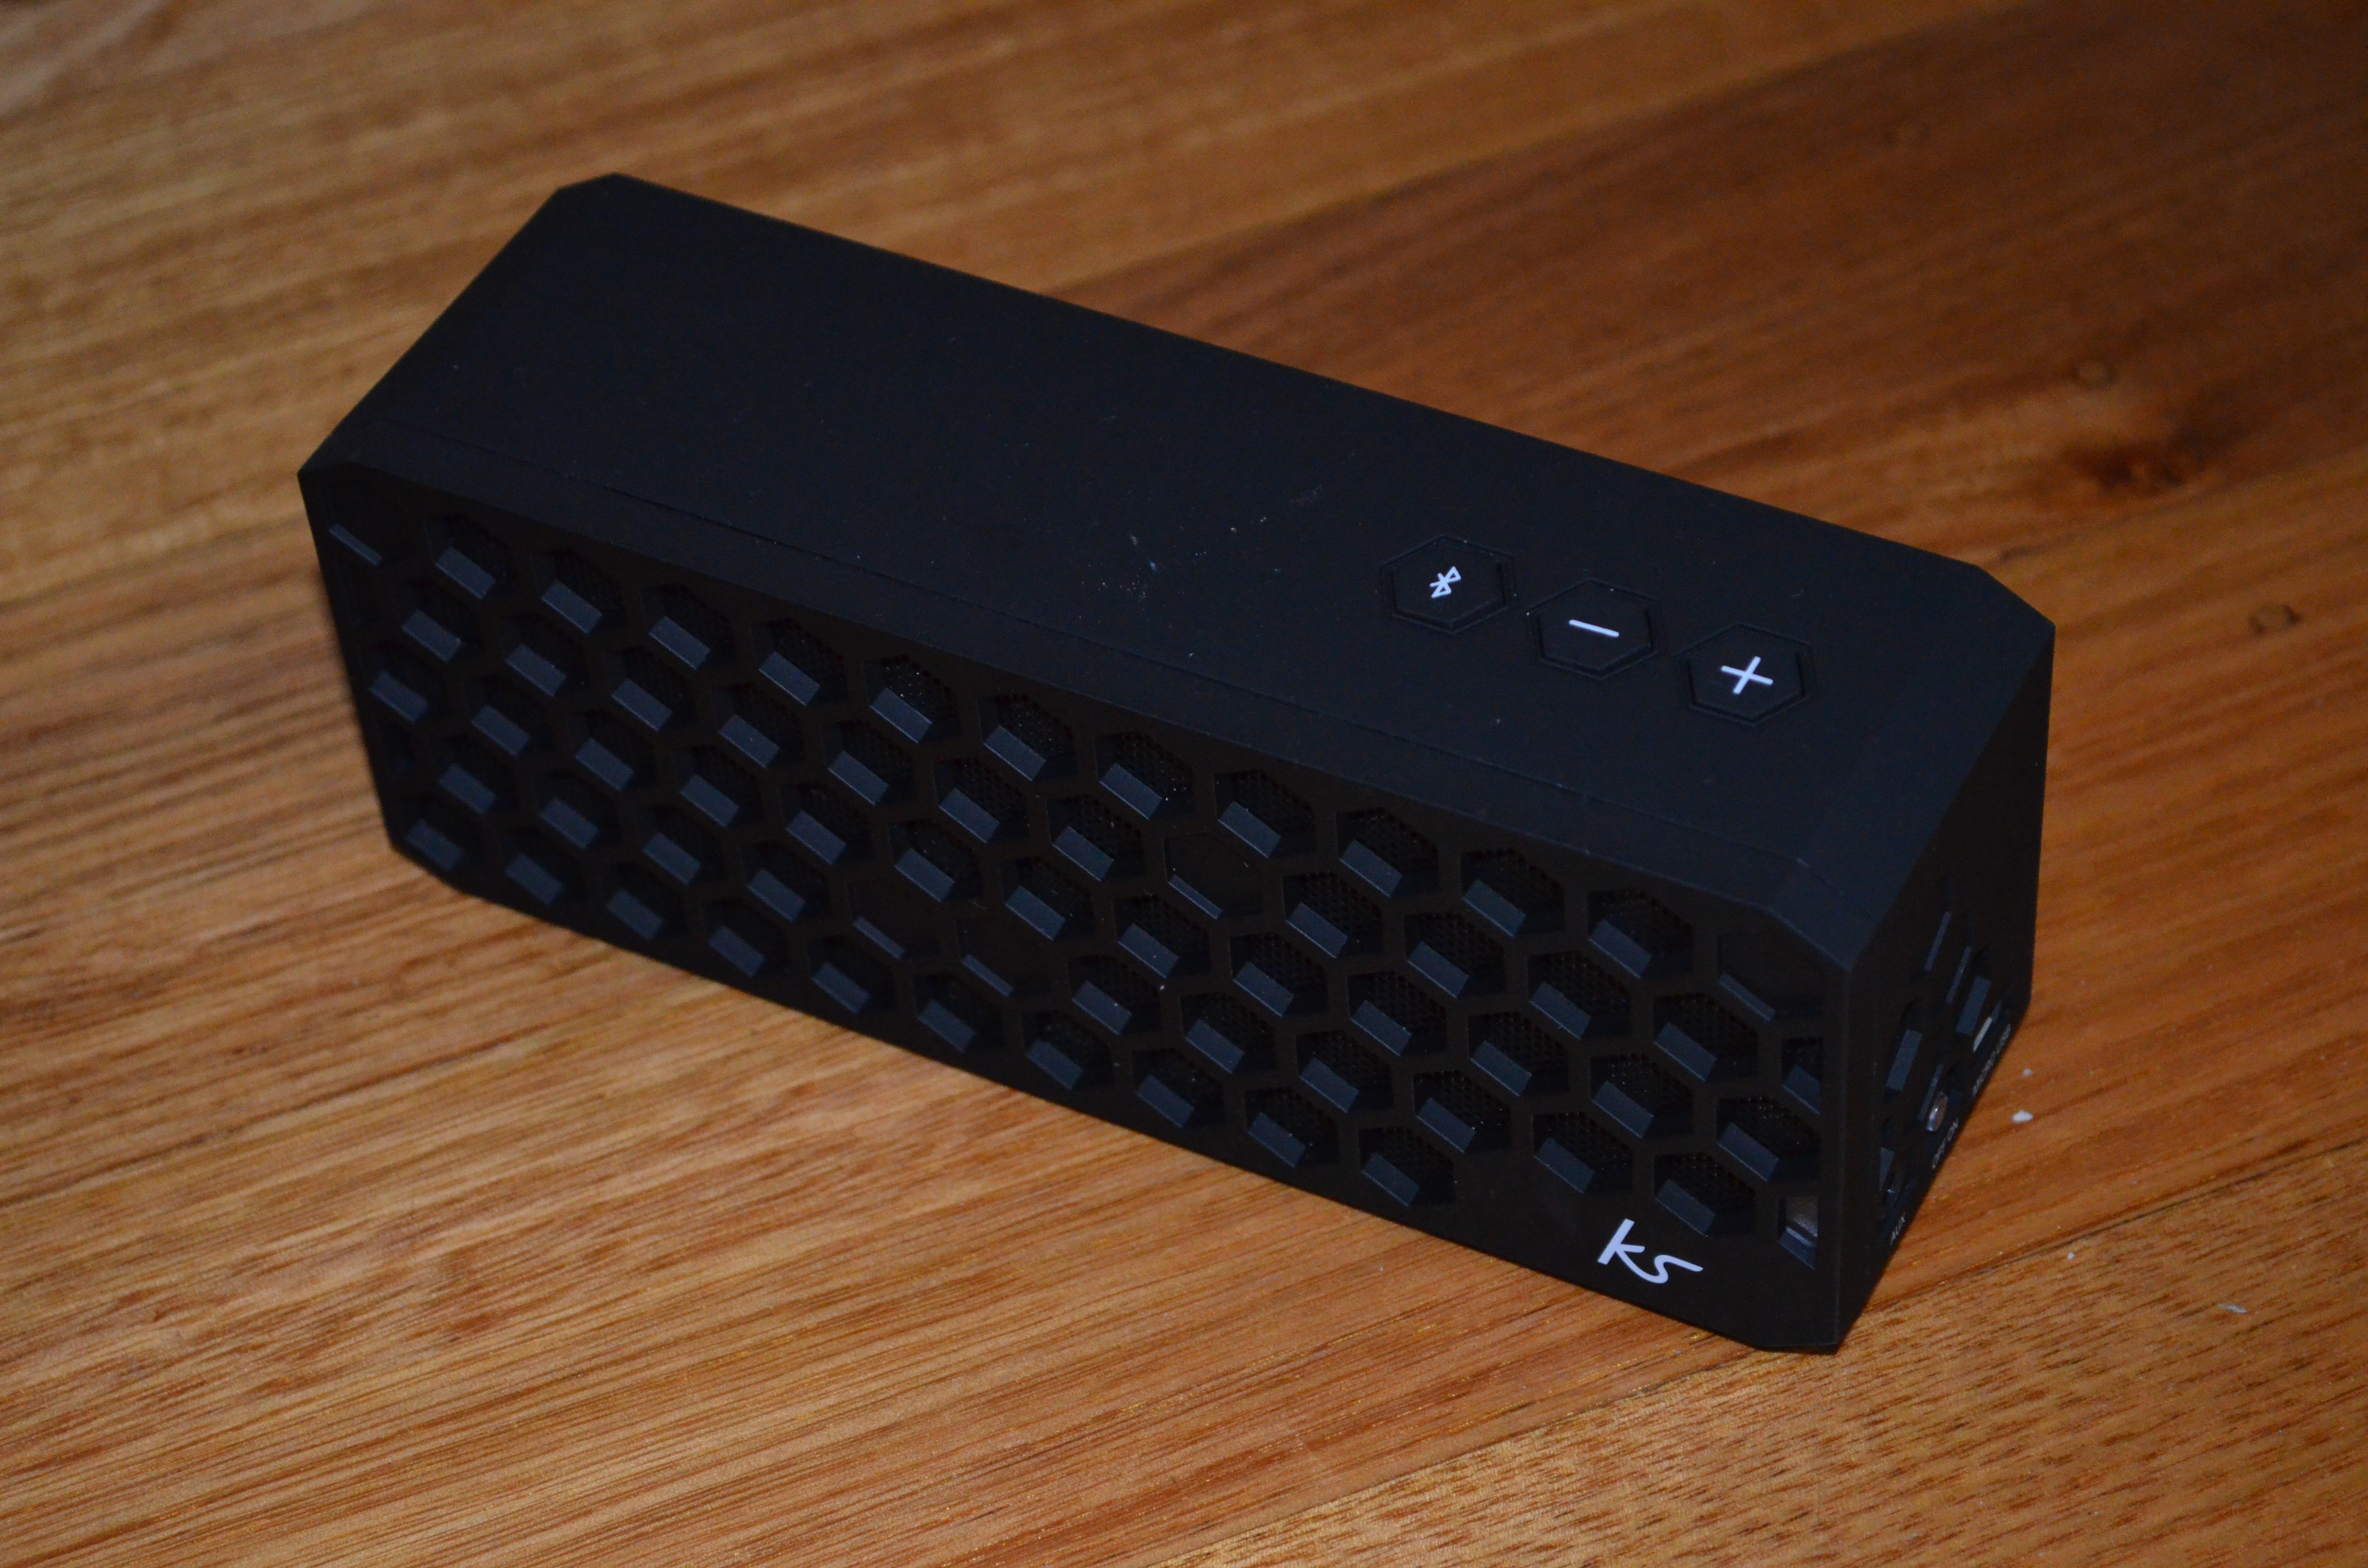
picture of Hive bluetooth speakers I ve just been given a set of Hive Bluetooth speakers by MobileZap (see this link for all their Bluetooth speakers) [1]. The speakers charge by a micro-USB cable so I started charging them in my car immediately after collecting them. To connect them to a phone or other Bluetooth device you just press the Bluetooth button on top and get the phone to be visible and scanning for devices, they identify themselves as Hive , after that they just work. My first test of using them was playing Ingress and the quality of the sound was impressive, I had thought that the Ingress recommendation to use headphones was due to the risk of annoying other people or alerting other players, but the quality of the sound was impressive and the internal speakers of a phone can t do it justice. After getting home I did some tests listening to music. For watching music videos it didn t work so well as the sound was too far removed from the video, but the audio quality was very good. I listened to Vow by Garbage (a good benchmark for stereo sound) and even though the Hive speakers are only 16.5cm wide I could still notice the stereo effect when they were about 1.5m away from me. The audio quality didn t compare well with my Bose QC-15 headphones, but for affordable and portable speakers it was quite good and an obvious improvement over the speakers that are built in to any phone I ve used. According to the Bluetooth Wikipedia page the range of a class 2 device is 10m and the range of a class 3 device is 1m. When my Samsung Galaxy Note 2 is talking to it I get a reliable range of about 5 meters and a mostly working range of 6 or 7 meters (sound randomly drops out and gets choppy). It could be that other phones would support a longer range due to having a higher transmission power (either class 1 or being closer to the limits of class 2) and a more sensitive receiver. But it doesn t seem likely that a 5m range is going to be a problem. Volume and Quality The speakers are rated at 5 Watt, when running at maximum volume (both through the phone volume setting and the volume control on the speakers) the sound is reasonably distortion free, as good as can be expected from playing an MP3 that s not compressed with the highest quality. Sound Meter [2] reports the sound volume as almost 85dB on a Galaxy S3 and as almost 100dB on a Galaxy Note 2, that would be somewhere between the volume of a busy street or alarm clock and the volume of a subway train or blow dryer which seems like a reasonable description, I find it very unpleasant to be within a meter of the speakers at maximum volume. With the typical amount of background noise in my house I can play music on the Hive speakers at one end of my house and hear it clearly at the other end. These speakers are more than capable of supplying the music for any party I d want to host or attend. I m not really into wild parties, but I think that anyone who has a one room party would be more than satisfied with the Hive speakers. Obviously the sound quality of portable speakers in a box that s 16.5cm wide and 6cm high isn t going to equal that of a full size set of speakers, but I think that hardly anyone who attends a party would expect better sound quality than the Hive speakers can provide. The aim of such speakers is to be portable, not really expensive, and to provide good sound quality within those constraints. I think that they meet such aims well. Over the years there have been many occasions when I have used a Thinkpad to provide the music for a party and found it to be quite loud enough. My current Thinkpad is a T420 which can produce 75dB according to my Galaxy S3 or 85dB according to my Galaxy Note 2. So it seems that I only really need about 10dB less than the maximum volume of the Hive speakers. Appearance The designers obviously made an effort on the appearance of the device. They have gone with the Hive concept and used hexagons everywhere. It really looks nice. Unfortunately when I took the photo there was some dust on it which didn t look bad to the eye but caught the camera flash. But with a matte black device there s always the problem of light colored dust. Even with a bit of dust it still looks great as a set of speakers, the dust just detracts from the appearance in photos. Line In One of the features I looked for was an audio line input so I could connect it directly to a non-Bluetooth device. I m assuming that this feature works as it s something that s difficult to stuff up when designing such a product, but I haven t got around to testing it. Once I started using the device I just found that I didn t have a real need for that feature. One thing that it might be useful for is PC desktop speakers that are powered by a USB port on the monitor. Currently I have a bearable (but not great) set of speakers for each PC and I don t need to change anything. But having the option of another set of speakers is very handy in case I suddenly need to make hardware changes. Other People s Reviews When I review a product I generally try and get opinions from random other people if possible. My mother and my mother-in-law were both impressed by the Hive speakers and expressed interest in owning a set. My mother-in-law was particularly interested as she uses her phone to listen to radio stations from outside Australia (I m going to get her onto Aldi for cheap 3G data ASAP so she can listen to Internet radio when travelling). Generally the impression that other people have of this device seems to be very positive. It seems that Bluetooth speakers aren t just a Geek toy. Conclusion While I m very impressed by this product, at this stage I m not sure whether I would pay for this one or something cheaper if I was paying for it. MobileZap offers a range of other products that look appealing at lower price points. It really depends on how much I use it. I ve just got a Makerbot Replicator 3D printer working and I ve found the Hive speakers very useful for the purpose of drowning out it s noise. If I keep doing that sort of thing then I ll get enough use out of the speakers to justify the price.

David Pashley: A New Chapter

It s been a while since I posted anything to my personal site, but I figured I should update with the news that I m leaving Brighton (and the UK) after nearly nine years living by the seaside. I ll be sad to leave this city, which is the greatest place to live in the country, but I have to opportunity to go explore the world and I d be crazy to let it pass me by. So what am I doing? In ten short days, I plan to sell all my possessions bar those I need to live and work day to day and will be moving to Spain for three months. I m renting a flat in Madrid, where I ll continue to work for my software development business and set about improving both my Spanish and my fitness. If you want to follow my adventures, or read about the reasons for my change, then check out the Experimental Nomad website. The post A New Chapter appeared first on David Pashley.com.

Next.

Previous.