Search Results: "tar"

9 August 2008

Wouter Verhelst: Scattergraphs

Debcamp is nice. Talking to people in person rather than having to do IRC to get anything done is a breeze, really. One thing I haven't been particularly happy about is the fact that there aren't any good statistics on what the build capacity of an architecture is; i.e., you don't know you're low on build capacity until you suddenly start backlogging and it's too late. So, since J rg Jaspert, Mark Hymers, and Steve Gran were there, I asked them whether it'd be possible to add some data to the projectb database about installing a binary. One additional column with a default now() option later, and we now have interesting data that I can make statistics of. Of course, since that column was only added four days ago, during one of which the link to ftp-master.debian.org was down (meaning, no uploads), there's not much data there yet; but I can start making some graphs now. Of course, the hard part is trying to figure out how to present the data in a manner that one can actually get useful conclusions from, which is harder than it seems. Anyhow, I'm trying. For now, on my public space on merkel, you can find a (mostly empty) per-architecture scattergraph relating the size of a binary package against the time between the dinstall of a source package and that of its binary for that particular architecture. If the time between a binary upload and a source upload is "often" more than a day for small packages, then it's obvious that the architecture in question is having problems keeping up. It's not very useful (yet), but the graphs will be updated on a daily basis, so that hopefully one or two months from now, they will contain useful data. Note that the scales are fixed to go from 0.1 day to 1000 days, and from 1k packages to 512M packages, so as to make sure one can actually compare graphs. I'm also trying to come up with a useful line-based graph, so that it is possible to compare architectures over time against eachother. This will probably involve something with averages and standard deviations or some such, I guess. Not sure yet.

Lior Kaplan: Problem reading DVDs burnt in Linux


I’ve tried to create a data DVD to backup some files. I’ve used K3B as always to write the DVD, and the process finished OK. The weird part started when I tried to read the DVD on the same machine I created it. I got an error from mount about a wrong file system (the mount has iso9660). Checking dmesg, I found these errors:
Aug 9 01:03:24 desktop kernel: [ 2581.266854] attempt to access beyond end of device
Aug 9 01:03:24 desktop kernel: [ 2581.266854] hdc: rw=0, want=68, limit=4
Aug 9 01:03:24 desktop kernel: [ 2581.266854] isofs_fill_super: bread failed, dev=hdc, iso_blknum=16, block=16
I’ve tried to burn a few more DVD with differest option at K3B, but nothing helps. The funny (or not, depends on your point of view) is that windows and Mac OS X read the DVDs without a problem. Searching the web, I encountred mostly with hardware problems. I’d be happy to get an advise… I’m guessing the DVD isn’t the problem as the write process went fine.

8 August 2008

Michael Schultheiss: Debconf 8 woes

I'm starting my trip to Mar del Plata, Argentina for DebConf 8 for my second DebConf. Although I live in Indianapolis, I'm flying out of Cincinnati since I found a cheaper flight. My trip to DebConf 7 was riddled with delays and I was hoping for my trip to DC8 to be nice and trouble free. I almost got my wish, but 10 miles from CVG the transmission went out on my car. After dealing with AAA for an hour I finally caught a cab to the airport. So far, nothing else bad has happened but I won't hold my breath until I'm safely in MDQ. Hope to see you there!

Randall Donald: Busy Summer


My wife and I have almost settled in our new home now. We start moving the alpacas today. I finally have some time to address the issues with the NVIDIA packages in regards to Lenny. As 2.6.26 is now in unstable I can build kernel modules for the proper kernel target and get a xen patch for 71.86.06. 173.14.12 will go into experimental shortly.

Enrico Zini: Handling concurrent update-apt-xapian-index runs

Handling concurrent update-apt-xapian-index runs So, update-apt-xapian-index takes a bit of a long time to run. When you install the package, if the index isn't there then postinst will rebuild it in background, good. Now, suppose you have an advanced package manager that after installing apt-xapian-index, detects that it's installed, detects that there is no database and runs an update with a nice GUI feedback. If this happened while the update is running in the background, the usual thing to do would be to abort the update; however, the package manager wouldn't be able to know when the indexing has finished and it can enable the advanced features. Let's not do the usual thing, then:
#  progress' is the object that does progress reporting.  Commandline options
# can choose a silent one, a machine readable one or a user readable one.
# Lock the session so that we prevent concurrent updates
lockfd = os.open(XAPIANDBLOCK, os.O_RDWR   os.O_CREAT)
lockpyfd = os.fdopen(lockfd)
try:
    fcntl.lockf(lockpyfd, fcntl.LOCK_EX   fcntl.LOCK_NB)
    #  ServerProgress  is a proxy progress reporter that listens for
    # connections on a Unix socket, and broadcasts progress status updates both
    # to the local progress reporter and to whoever connects to the socket.
    progress = ServerProgress(progress)
except IOError, e:
    if e.errno == errno.EACCES or e.errno == errno.EAGAIN:
        progress.notice("Another update is already running: showing its progress.")
        #  ClientProgress' is another proxy class that connects to the socket
    # forwards progress updates to whatever the user has chosen as the
    # local progress indicator.
        childProgress = ClientProgress(progress)
        childProgress.loop()
        sys.exit(0)
    else:
        raise
What happens here is that if the upload is in progress, the second update-apt-xapian-index will not be able to lock a lockfile. But instead of exiting, it connects to the other indexer via a unix socket, and shows the progress just as if it were the one doing the indexing. So, now, suppose I run update-apt-xapian-index:
# update-apt-xapian-index
Reading Debtags database: done.  
Rebuilding Xapian index... 20%

And suppose I run another one:
# update-apt-xapian-index
Another update is already running: showing its progress.
Rebuilding Xapian index... 20%

And suppose I run yet another one:
# update-apt-xapian-index --batch-mode
notice: Another update is already running: showing its progress.
begin: Rebuilding Xapian index
progress: 19/100
progress: 20/100

And suppose I run yet another one (running with -q shows nothing, but it will wait until the master indexer has finished):
# update-apt-xapian-index -q

This way, the advanced package manager (adept 3 does this) will show a progress indicator and correctly let the user know when indexing has finished... only, if an update is already running, the progress indicator will not start at 0% because the update was already in progress, and the user will think: "wow, I've been lucky!". The server side of the socket only uses nonblocking I/O, so there's no risk of slave indexers causing the master indexer to hang. It's been simple to implement, and brillant. It is in apt-xapian-index 0.15, which I have just uploaded to sid. Shame it's a bit late for lenny.

John Goerzen: Weird Firefox Problem

Once again, I find myself turning to this wonderful series of tubes for help on a weird problem.

I have Firefox (Iceweasel) on all the computers I regularly use. One of these computers has had a persistent problem.

After using it for awhile, it takes a really long time to look up hostnames in DNS. And after upgrading to Firefox 3, it got much worse. Not only did name resolution get slow, but sometimes page loads would get exceptionally slow as well. I could have 5 tabs open, and all of a sudden at the magic moment, nothing would load on any tab. It was as if I was being hit by 75% packet loss. And new pages wouldn't load, either.

tcpdump showed Firefox not even sending out packets at these times. After a few minutes, it might be back to normal. But I could always quit and restart and it would be fine.

Now, here's the weird thing: I've eliminated every possible difference I can think of between this one machine and the others I use Firefox on. My plugins and extensions are the same set with the same versions. My configuration is the same. When this problem is happening, other network-related programs (even other web browsers) on the same machine are working fine. Nobody else here seems to be having this problem.

Any ideas?

7 August 2008

Joachim Breitner: pam-dbus: authentication by bubbles

Imagine you have a device, such as a linux phone, that allows login via ssh, e.g. when on a wireless network. You don t want to set a password with the (limited) phone UI. On the other hand, you don t want to allow passwordless root logins into your phone. But you do want the ability to login via ssh, after all that s why you have bought a linux smartphone. This led me to the idea of a pam module and corresponding UI piece that asks the currently logged in user: Hey, someone tries to login. Is that ok or not? This might also be useful for guest accounts on regular laptops. For more on that, see my last blog post.So I hacked it together (actually twice, due to some unfortunate use of rm at some point), invested most of the time in learning more about the python garbage collector vs. callbacks, explicitly marked global variables and proper automake stuff. In the end I got, well, just what I wanted. A simple pam module, dubbed pam-dbus that sends a request via the dbus system bus and an autostart program (written in python for now, but I might re-implement it in C) that uses notification-daemon to get confirmation from the user.You are welcome to try the sources and binary debian packages or have a look at the darcs repository for pam-dbus (with debian/ directory, repository browser). This will end up in Debian later, I guess.Update: Erik Johansson pointed out that if you want to use this with ssh, you need to set UsePAM yes in /etc/ssh/ssd_config.

Ian Wienand: How to find the current glibc version

A recent post reminded me of a problem I once had; determine the glibc version and its support for various things. There's actually a little known but useful confstr call defined for just this sort of thing. Here's a minimal example:
#include <stdio.h>
#include <unistd.h>
#include <alloca.h>
#include <string.h>
int main (void)
 
        size_t n = confstr (_CS_GNU_LIBC_VERSION, NULL, 0);
        if (n > 0)
         
                char *buf = alloca (n);
                confstr (_CS_GNU_LIBC_VERSION, buf, n);
                printf("%s\n", buf);
         
        return 0;
 
man confstr has all the details. If you don't need it in your program, you can also just run /lib/libc/so.6 and it will print out it's version info, e.g.
$ /lib/libc.so.6
GNU C Library stable release version 2.7, by Roland McGrath et al.
Copyright (C) 2007 Free Software Foundation, Inc.
This is free software; see the source for copying conditions.
There is NO warranty; not even for MERCHANTABILITY or FITNESS FOR A
PARTICULAR PURPOSE.
Compiled by GNU CC version 4.3.1 20080523 (prerelease).
Compiled on a Linux >>2.6.24.4<< system on 2008-06-02.
Available extensions:
	crypt add-on version 2.1 by Michael Glad and others
	GNU Libidn by Simon Josefsson
	Native POSIX Threads Library by Ulrich Drepper et al
	BIND-8.2.3-T5B
For bug reporting instructions, please see:
<http://www.gnu.org/software/libc/bugs.html>.
There's also another glibc trick that often comes in useful; the LD_DEBUG environment variable. Start with help and you can get more details from there.
$ LD_DEBUG=help ls
Valid options for the LD_DEBUG environment variable are:
  libs        display library search paths
  reloc       display relocation processing
  files       display progress for input file
  symbols     display symbol table processing
  bindings    display information about symbol binding
  versions    display version dependencies
  all         all previous options combined
  statistics  display relocation statistics
  unused      determined unused DSOs
  help        display this help message and exit
To direct the debugging output into a file instead of standard output
a filename can be specified using the LD_DEBUG_OUTPUT environment variable.

Frank Lichtenheld: Moving a mailing list from SF.net to another Mailman instance

I had to move a mailing list from SourceForge to a self-hosted Mailman instance while preserving all the user options. Since one has no shell access to these SF's Mailman I decided to extract the information from the Web-Interface, which sadly enough is no easy task. There is no complete list available but only chunked by starting letter and in groups of 30 addresses or less. Since the mailing list in question had about 1500 subscribers manual transcription was really no option. So I wrote a small script that automatically extracts all the information and outputs it in a CSV-like format. I've also hacked Mailman's add_members script to set all these options from this format. In case someone finds this useful, both are available on my git server under free licenses:
grab-subscribers.pl
Extract subscriber information from Mailman Web-Interface with LWP.
add_members
Use the information extracted by grab-subscribers.pl to populate a Mailman mailing list.
DISCLAIMER: This is hacked together really quickly and was used exactly once. Don't expect too much.

Gustavo Noronha Silva: 7 Aug 2008

So it is currently possible to use simple library calls in glib-based code to run something as root, by taking advantage of the gksu policykit mechanism: GksuProcess* gksu_process_new(const gchar *working_directory, const gchar **arguments);

gboolean gksu_process_spawn_async(GksuProcess *process, GError **error);
The DBus service already works; it is able to setup the environment and X authorization correctly. There is still lots to do; startup notification is still not handled, and dealing with the application’s stdandard output and error messages, as well as providing a way for the caller to send stuff into the processe’s standard input. It is already possible to start an application and know that it has been finished, though. As for the code: $ git clone git://kov.eti.br/srv/git/gksu-polkit.git/ Criticism is welcome! In other news… I’d like to ask our dear lazy web if anyone is using some nice way of providing only posts tagged in specific categories in a feed in wordpress. I’d like to use that to provide my posts to planet debian from my wordpress install.

Aigars Mahinovs: Better now!

As soon as my laptop came back from repairs, I started to feel better - being back with 1920×1200 resolution is great! NVidia is much more stable than ATi and Intel wireless is just great! And then last weekend I was in Berlin for the FFII board meeting and used the opportunity to see the city with my girlfriend. I must say that there is a lot of interesting things to see in Berlin.The things I would recommend everyone are: go to the Zoo (5-7 hours of superb fun), then take bus 100 to Alexander Platz (driving by all the main landmarks), go up on the TV tower, then come down and sometime late in the night go to ‘Weekend’ dance club.

Russell Coker: A Basic IPVS Configuration

I have just configured IPVS on a Xen server for load balancing between multiple virtual hosts. The benefit is not load balancing but management. With two virtual machines providing a service I can gracefully shut one down for maintenance and have the other take the load. When there are two machines providing a service a load balancing configuration is much better than a hot-spare, one reason is the fact that there may be application scaling issues that prevent one machine with twice the resources from giving as much performance as two smaller machines. Another is the fact that if you have a machine configured but never used there will always be some doubt as to whether it would work… The first thing to do is to assign the IP address of the service to the front-end machine so that other machines on the segment (IE routers) will be able to send data to it. If the address for the service is 10.0.0.5 then the command “ip addr add dev eth0 10.0.0.5/24 broadcast +” will make it a secondary address on the eth0 interface. On a Debian system you would add the line “up ip addr add dev eth0 10.0.0.5/24 broadcast + true” to the appropriate section of /etc/network/interfaces, for a Red Hat system it seems that /etc/rc.local is the best place for it. I expect that it would be possible to merely advertise the IP address via ARP without adding it to the interface, but the ability to ping the IPVS server on the service address seems useful and there seems no benefit in not assigning the address. There are three methods used by IPVS for forwarding packets, gatewaying/routing (the default), IPIP encapsulation (tunneling), and masquerading. The gatewaying/routing method requires the back-end server to respond to requests on the service address. That would mean assigning the address to the back-end server without advertising it via ARP (which seems likely to have some issues for managing the system). The IPIP encapsulation method requires setting up IPIP which seemed like it would be excessively difficult (although maybe not more than required to set up masquerading). The masquerading option (which I initially chose) rewrites the packets to have the IP address of the real server. So for example if the service address is 10.0.0.5 and the back-end server has the address 10.0.1.5 then it will see packets addresses to 10.0.1.5. A benefit of masquerading is that it allows you to use different ports, so for example you could have a non-virtualised mail server listening on port 25 and a back-end server for a virtual service listening on port 26. While there is no practical limit to the number of private IP addresses that you might use it seems easier to manage servers listening on different ports with the same IP address - and there is the issue of server programs that are not written to support binding to an IP address. ipvsadm -A -t 10.0.0.5:25 -s lblc -p
ipvsadm -a -t 10.0.0.5:25 -r 10.0.1.5 -m The above two commands create an IPVS configuration that listens on port 25 of IP address 10.0.0.5 and then masquerades connections to 10.0.1.5 on port 25 (the default is to use the same port). Now the problem is in getting the packets to return via the IPVS server. If the IPVS server happens to be your default gateway then it’s not a problem and it will already be working after the above two commands (if a service is listening on 10.0.1.5 port 25). If the IPVS server is not the default gateway and you have only one IP address on the back-end server then this will require using netfilter to mark the packets and then route based on the packet matching. Marking via netfilter also seems to be the only well documented way of doing similar things. I spent some time working on this and didn’t get it working. However having multiple IP addresses per server is a recommended practice anyway (a back-end interface for communication between servers as well as a front-end interface for public data). ip rule add from 10.0.1.5 table 1
ip route add default via 10.0.0.1 table 1 I use the above two commands to set up a new routing table for the data for the virtual service. The first line causes any packets from 10.0.1.5 to be sent to routing table 1 (I currently have a rough plan to have table numbers match ethernet device numbers, the data in question is going out device eth1). The second line adds a default router to table 1 which sends all packets to 10.0.0.1 (the private IP address of the IPVS server). Then it SHOULD all be working, but in the network that I’m using (RHEL4 DomU and RHEL5 Dom0 and IPVS) it doesn’t. For some reason the data packets from the DomU are not seen as part of the same TCP stream (both in Net Filter connection tracking and by the TCP code in the kernel). So I get an established connection (3 way handshake completed) but no data transfer. The server sends the SMTP greeting repeatedly but nothing is received. At this stage I’m not sure whether there is something missing in my configuration or whether there’s a bug in IPVS. I would be happy to send tcpdump output to anyone who wants to try and figure it out. My next attempt at this was via routing. I removed the “-m” option from the ipvsadm command and added the service IP address to the back-end with the command “ifconfig lo:0 10.0.0.5 netmask 255.255.255.255” and configured the mail server to bind to port 25 on address 10.0.0.5. Success at last! Now I just have to get Piranha working to remove back-end servers from the list when they fail. Update: It’s quite important that when adding a single IP address to device lo:0 you use a netmask of 255.255.255.255. If you use the same netmask as the front-end device (which would seem like a reasonable thing to do) then (with RHEL4 kernels at least) you get proxy ARPs by default. For example you used netmask 255.255.255.0 to add address 10.0.0.5 to device lo:0 then on device eth0 the machine will start answering ARP requests for 10.0.0.6 etc. Havoc then ensues.

6 August 2008

Clint Adams: NM teaches shameful doublespeak for non-free

The worst thing an idealist can be is practical. I see this problem nearly every day when people are trying to comply with laws, rules, regulations, standards, or what-have-you. You fail to meet the objective, so you smudge reality and make compromises. Well, we cannot reasonably drive under the speed limit so let's arbitrarily make up our own limit (10 mph over) and stick to that. That way we endure the hardship of having to comply with something but not the extreme and unattainable hardship of complying with the real thing. Nevermind that some people actually obey the speed limit; that's just anecdotal evidence or a fluke or some other excuse you can use to disregard the fact that what you are claiming is impossible is actually possible. That's an example of a rule mandated by an external power (the oppressor you theoretically owe your allegiance to or the oppressor you are on loan to). Where idealism really comes into play is when people choose their own oppression, be that a formal religion, moral code that they got from a pamphlet somebody was handing out on the sidewalk, or other voluntarily-adopted standards of behavior. Then you end up with raw-food vegans who eat pepperoni pizza twice a week, environmentalists who drive cars, PETA members who keep pets, feminists who are lapsitters, Christians who sin, people who claim that things are best-effort, and people who claim that things that are obviously part of other things are not really part of those things.

Ingo Juergensmann: 2008 M68k Porter Meeting

Joey mailed lately just another announcement for the m68k port ermeeting. This year in Kiel from August 29th - 31st:

Executive summary:

2008 M68k Linux Porter Meeting
August 29th - 31st
University of Kiel, Germany


This summer we are organising a Linux porter meeting especially
targetting the m68k architecture. During the meeting current problems
of the m68k architecture, its integration in Debian, releases
etc. will be discussed.

The meeting will take place at the last weekend in August (29-31) at
the University of Kiel, Germany. Details and participants are
collected here:

This meeting is evolved from the Oldenburg porter meeting that has
started with the m68k architecture but had to stop two years ago.


Interested developers and supporters are invited to join the meeting
and help develop the m68k port of Linux.

If you are interested to attend this meeting, please drop Christian
(cts) or me a note or add yourself to the Wiki page.

Regards,

Joey


Despite all the problems the m68k faced in the last years, we're still alive and performing fine. Part of the meeting will be discussion about the current changes of the m68k port like Aranym buildds and other stuff.

So, if you're interested in the m68k port or the experience of the m68k porters for your embedded architecture, come to Kiel and visit us! :-)

Christian Perrier: Holidays report

Sure, that sounds fairly formal to send a report for holidays, doesn't it? Anyway, as I have a few (often Debian/FLOSS related) friends around the world who are reading my blog entries, this might interest them so that's indeed a report..:-)...and I have time for it, so... I'm currently going back from Cahors to Maurepas (home), on my way to Debconf. We spent 10 days in Cahors with Elizabeth and the girls, finally joined by Jean-Baptiste on Sunday. We had great time over there, enjoying the richness of Quercy: So, I'm now heading back home, assemble stuff and will take off for Debconf on Thursday 7th (Paris Orly to Madrid, then Buenos Aires via Air Europa: IIRC nobody from Debconf is in the same flight). "Assemble stuff" here also means collecting cheese for the now famous Debconf Cheese&Wine party. That one will be tricky to achieve as most of us are coming from quite far away and...there are only 6 French citizens who attend DC8..:-)). Anyway, I already know that my fellow Nicolas Fran ois (namely nominated as Assistance CheeseMaster recently) will bring some good stuff. I haven't decided yet what to bring. I might be influenced by my holidays, so cheeses from South-West France are highly probable. Cahors wine will be the choice (prepare yourself: that is strong stuff). At Debconf itself, we'll have a quite busy schedule. I intend to mostly work along with Felipe, Nicolas, Grisu and others on i18n.debian.net. I'll have to animate the i18n sessions for which I want to prepare some schedule instead of just "lat's gather and talk" which didn't work so well last year, IMHO. And I have that bloody keynote lecture which, BTW, could be rescheduled if I properly read debconf-discuss as, finally 9am for keynotes seems to be considered too early for the late birds at DC8...:-)... We'll see: I will certainly have something that's not very well cooked and prepared. Expect some improvisation: this year I didn't want to stress myself with a talk, slides and blahblah. Elizabeth will come back from Cahors on Saturday with the kids. She'll have a holiday week at her father's place whil ethe kids will....do their stuff at Maurepas (this is what happens when kids are grown up). We'll gather together again on Aug 18th and I go back to work on 19th. Crazy, I know but I have a very busy and full work schedule for the upcoming next 2 months. September will be a hard time to go through: Jean-Baptiste will start his "Licence Profesionnelle" in Automated and Embarked Systems. He'll do it in shared time: half-time at university for classes and half-time working in a company (which turns out to be Essilor, the world leader for progressive glasses....and the company which Elizabeth is working for). He'll stay at my sister-in-law place during the week (30km away from our place but closer from university and work). Sophie, our 18-year old daughter, will spend the year in Toulouse, to prepare the admission in a Social Workers school. She'll have her own apartment, in the very center of the city, 20 meters away from Place du Capitole. Annoying, isn't it ? :-) So, we'll mostly stay with our "little" Magali, our 16 y.o. who will be attending High School, on her way to Baccalaur at. Tell us about shrinking families.... Now time to work on some slides for the Debconf keynote. Damn.
5 August 2008

Gustavo Noronha Silva: 6 Aug 2008

As far as debcamp work plans go, my own has been making me quite happy. I started the week trying to start implementing gksu policykit mostly in vala, and failing miserably. Vala isn't ready to help me do some of the more weird things I had in mind. The good news is falling back to C worked pretty smoothly, and I have the basic foundation working. There is plenty to be implemented still, but moving forward always feels good. If anyone is interested in discussing the gksu replacement that is being built on top of the PolicyKit framework come talk to me in the hack lab =D. Take a look at this gratuitous screenshot.

Petr Rockai: adept 3.0 alpha 6

Hi, it’s that time again: new alpha version of Adept hits the block. For the unaware, Adept is an APT front-end for KDE. You can do all the cool stuff with it that the other kids can’t. Join the fun! New features since Alpha 5 (the list is a little less staggering than the last time, sorry about that, but it’s only been a week) Where to get I have again prepared binary packages, this time even more of them (a Hardy backport is included). Traditionally, in Debian, you can install alpha 6 from experimental:
apt-get install -t experimental adept
The sources.list goes:
deb http://ftp.debian.org/debian experimental main
If you are on Kubuntu Intrepid, the line is:
deb http://ppa.launchpad.net/mornfall/ubuntu intrepid main
and finally, on Kubuntu Hardy, the lines are (BUT: read below!)
deb http://ppa.launchpad.net/kubuntu-members-kde4/ubuntu hardy main
deb http://ppa.launchpad.net/mornfall/ubuntu hardy main
Big fat warning: Due to somewhat unexpected difficulties, Adept requires newer APT than available in Hardy. This means, adding the above sources.list lines will upgrade your apt to a version from Intrepid, that’s also completely untested on anything resembling a Hardy installation. Be wary. Moreover, installing Adept means means KDE 4.1 for Hardy users. (This does not apply to Intrepid users, they are already on the cutting edge and no extra dangers lie this way.) (For all Kubuntu users, there are more instructions to be found on https://launchpad.net/~mornfall/+archive.) Heroes of Alpha 6 I hereby nominate the “Heroes of Alpha 6”, for their deeds that helped Adept move forward: (And a totally flirtless wink towards Blauzahl, who somehow inspired me to actually do some bugzilla sorting…) And now, it’s easy to join the ranks of these heroes — just test the new alpha version and find bugs. Immortality won’t escape your grasp. Also, please don’t forget to read the next section. Jobs for Alpha 6 Sorting through Launchpad for bugs that have been fixed in alpha 6 (compared to 2.1) would be really awesome. It is a big list and many of them are likely to need testing. (I can take care of that for the KDE bugzilla, but launchpad is a task just too daunting for me and my time possibilities, so help would be very much appreciated). Notifier is still not included. The components to test are (if you have sudo, kdesu for the rest):
sudo adept
sudo adept installer
sudo adept updater
Please give a go to all of them, report rough edges, crashes and all that, either through IRC (mornfall at freenode, oftc) or mail me-at-mornfall-dot-net or use KDE Bugzilla. Known Issues

Russell Coker: A New Strategy for Xen MAC Allocation

When installing Xen servers one issue that arises is how to assign MAC addresses. The Wikipedia page about MAC addresses [1] shows that all addresses that have the second least significant bit of the most significant byte set to 1 are “locally administered”. In practice people just use addresses starting with 02: for this purpose although any number congruent to two mod four used in the first octet would give the same result. I prefer to use 02: because it’s best known and therefore casual observers will be more likely to realise what is happening. Now if you have a Xen bridge that is private to one Dom0 (for communication between Xen DomU’s on the same host) or on a private network (a switch that connects servers owned by one organisation and not connected to machines owned by others) then it’s easy to just pick MAC addresses starting with 02: or 00:16:3e: (the range assigned to the Xen project). But if Xen servers run by other people are likely to be on the same network then there is a problem. Currently I’m setting up some Xen servers that have public and private networks. The private network will either be a local bridge (that doesn’t permit sending data out any Ethernet ports) or a bridge to an Ethernet port that is connected to a private switch, for that I am using MAC addresses starting with 02:. As far as I am aware there is no issue with machine A having a particular MAC address on one VLAN while machine B has the same MAC address on another VLAN. My strategy for dealing with the MAC addresses for the public network at the moment is to copy MAC addresses from machines that will never be in the same network. For example if I use the MAC addresses from Ethernet cards in a P3 desktop system running as a router in a small company in Australia then I can safely use them in a Xen server in a co-location center in the US (there’s no chance of someone taking the PCI ethernet cards from the machine in Australia and sending them to the US - and no-one sells servers that can use such cards anyway). Note that I only do this when I have root on the machine in question and where there is no doubt about who runs the machine, so there should not be any risk. Of course if someone from the ISP analyses the MAC addresses on their network it will look like they have some very old machines in their server room. ;) I wonder if there are any protocols that do anything nasty with MAC addresses. I know that IPv6 addresses can be based on the MAC address, but as long as the separate networks have separate IPv6 ranges that shouldn’t be a problem. I’m certainly not going to try bridging networks between Australia and the US! Another possible way of solving this issue would be to have the people who run a server room assign and manage MAC addresses. One way of doing this would be to specify a mapping of IP addresses to MAC addresses, EG you could have the first two bytes be 02:00: and the next four be the same as the IPv4 address assigned to the DomU in question. In the vast majority of server rooms I’ve encountered the number of public IP addresses has been greater than or equal to the number of MAC addresses with the only exception being corporate server rooms where everything runs on private IP address space (but there’s nothing wrong with 02:00:0a: as the prefix for a MAC address). I also wonder if anyone else is thinking about the potential for MAC collisions. I’ve got Xen servers in a couple of server rooms, I told the relevant people in writing of my precise plans (and was assigned extra IP addresses for all the DomUs) but never had anyone mention any scheme for assigning MAC addresses.

4 August 2008

Russell Coker: New HP Server

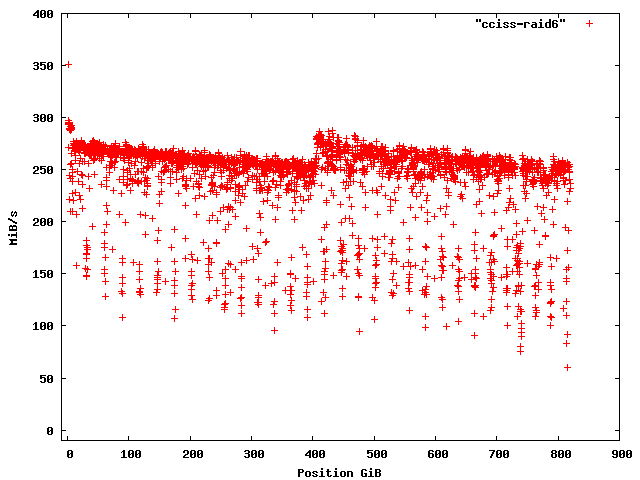
I’ve just started work on a new HP server running RHEL5 AS (needs to be AS to support more than 4 DomU’s). While I still have the Xen issues that made me give up using it on Debian [1] (the killer one being that an AMD64 Xen Dom0 would kernel panic on any serious disk IO) but the Xen implementation in RHEL is quite solid. The first thing I did was run zcav (part of my Bonnie++ benchmark suite) [2] to see how the array performs (as well as ensuring that the entire array actually appears to work). The result is below. For a single disk performance is expected to decrease as you read along the disk (from outer to inner tracks). I don’t know why the performance decreases until the half-way point and then starts with good performance again and again decreases. The next thing was to ensure that the machine had RAID-6 (I have been convinced that that using only RAID-5 verges on professional malpractice). As the machine is rented from a hosting company there was no guarantee that they would follow my clear written instructions involving running RAID-6. The machine is a HP rack-mounted server with a CCISS RAID controller, so to manage the array the command /usr/sbin/hpacucli is used. The command hpacucli controller all show reveals that there is a “Smart Array P400 in Slot 1“. The command hpacucli controller slot=1 show gives the following (amongst a lot of other output):
RAID 6 (ADG) Status: Enabled
Cache Board Present: True
Cache Status: OK
Accelerator Ratio: 25% Read / 75% Write
Drive Write Cache: Disabled
Total Cache Size: 512 MB
Battery Pack Count: 1
Battery Status: OK
SATA NCQ Supported: True So the write-back cache is enabled, 384M of data is for the write-back cache and 128M is for the read cache (hopefully all for read-ahead - the OS should do all the real caching for reads). The command hpacucli controller slot=1 array all show reveals that there is one array: “array A (SAS, Unused Space: 0 MB)“. The command hpacucli controller slot=1 array a show status tells me that the status is “array AOK“. Finally the command hpacucli controller slot=1 show config gives me the data that I really want at this time and says:
Smart Array P400 in Slot 1 (sn: *****)
array A (SAS, Unused Space: 0 MB)
logicaldrive 1 (820.2 GB, RAID 6 (ADG), OK) Then it gives all the data on the disks. It would be nice if there was a command to just dump all that. I would like to be able to show the configuration of all controllers with a single command. Also it would be nice if the fact that hpacucli is the tool to use for managing CCISS RAID arrays when using Linux on HP servers was more widely documented. It took me an unreasonable amount of effort to discover what tool to use for CCISS RAID management.

David Moreno Garza: On phone calls

I've enjoyed reading Sarah Hatter's (from 37signals) blog post about phone support. I can't say anything else that I totally agree about it, and I'd like to share my own experience.

Recently, I bought a ticket for my mom to come to visit us in New York. She finally couldn't do it for the dates we had picked so I had to cancel the airline ticket that I had already paid in Orbitz. I did this through their website, I saw how much of penalties it'd be, and it wasn't too much, so I accepted without too many other alternatives. Basically, from the total cost of the ticket, I'd have to take a small penalty fee for Orbitz and big one for the airline. The rest wouldn't be reimbursed but could be used as credit for another reservation, for the same passenger, of course. None of those tickets are transferrable, which yes, it's OK, it was just a delay of dates on the trip. Now, she is able to come again in a couple of months, so I tried to find a way to use that remaining credit to make a new reservation. I couldn't. After spending a lot of minutes (I should be an idiot, I guess) trying to find their phone number on the website, I called. A nice lady with a very weird accent for me answered, I tried to explain the issue and she was very gentle and told me that I had to do the reservation by phone. I asked if there wasn't any way that I could do the reservation online myself. She said no. I asked how come. She said that in order for me to use that credit I had to do it by phone. She started asking me the preferred days for traveling, whether at morning or at night, etc. All of this was OK, but it was very, very difficult for me to understand what she was saying sometimes, and most of the times I was embarrased to ask her to say things again and again. It was very, very difficult and frustrating to do this over phone for me. I apologized, thanked her and hung up. I couldn't do it.

This could have been easily solved over an online interface or over email (they already have my freaking credit card numbers!). I've been mostly happy with Orbitz and after all they are not guilty on having me as their customer, one that cannot speak to nice ladies with very weird accents, but it'd be easier for everybody to not leave phone support as the last resource for solving an issue. I still have to call and claim my unused credit. I've been avoiding it, both because I still want to find the energy and patience and because I'm waiting for next payroll :)

Paralelly, having spent a couple of weeks with the family in Mexico City I remembered how annoying phone calls to people's houses from companies are. All of us at my family place are economically actives. Because of this, a lot of companies, credit card companies, banks, inssurance companies, etc, annoy at any time offering their products. I almost had forgotten it since my phone activity is not too active here. Those fucking companies (or the representatives rather) call, introduce themselves and start talking saying that you've won an special thing, bonus, award for your records' activities, whatever. This is so impersonal, so cold, so bitter, tacky and so stupidly impolite and annoying that I've reached the point on saying nothing at all but hanging up immediately. Some other times I interrupt saying I was busy, how they dare calling with all their bullcrap without asking me a single question on whether I can or want to receive the call. This is incredibly annoying and find it very unpleasent and impolite. What, as customer, I have to do? Avoid connections with those companies, they don't deserve my attention, they had lost it. I should only maintain a private cell phone for family and friends and try to not give that number to any kind of company.

Die phone support, die!

Next.

Previous.
